1. Introduction and Literature Review
Crude oil refineries transform raw crude feedstocks into a spectrum of finished petroleum products through a coordinated sequence of physicochemical processing steps collectively referred to as refinery unit operations. Variations in process unit configuration, installed capacity, and operational parameters give rise to substantial heterogeneity across refinery systems. To characterize this heterogeneity, the refining industry has developed quantitative classification metrics that reflect capital intensity and upgrading capability. Prominent examples include equivalent distillation capacity, the Nelson complexity index, and the bottom-of-the-barrel index, which are widely used to benchmark structural complexity and conversion depth among refining facilities [
1,
2]. While these indices have proven useful for quantifying structural complexity and assessing refinery suitability for processing different crude oil qualities, they provide limited resolution for detailed refinery modeling applications [
3]. Specifically, such aggregate metrics do not explicitly represent process-level interactions, operational flexibility, or product yield structures required for rigorous systems analysis.
Refinery models play a critical role in evaluating economic performance, energy efficiency, and environmental compliance across refining systems. From a process engineering perspective, they enable systematic exploration of optimal configuration design and operational strategies under prevailing technical, logistical, and market constraints at local, regional, and global scales. Insights derived from these models inform investment planning, downstream diversification strategies, and regulatory policy formulation. Consequently, accurate identification and representation of underlying refinery configurations constitute a foundational requirement for developing reliable, scalable, and policy-relevant refinery modeling frameworks.
Recent advances in machine learning and numerical simulation have increasingly been applied across energy extraction and transformation systems to enhance predictive performance and support decision-making under uncertainty. In subsurface energy applications, data-driven and hybrid modeling approaches have been used to assess carbon dioxide sequestration potential, hydrogen storage in depleted gas reservoirs, and geothermal resource exploitation under varying geological and operational conditions [
4,
5]. These studies illustrate the capability of machine learning techniques to capture complex, nonlinear system behavior where purely mechanistic models may be computationally intensive or constrained by incomplete system characterization. The broader adoption of such approaches across the energy sector underscores their suitability for representing high-dimensional, infrastructure-intensive systems.
Despite these advances in upstream and subsurface domains, comparatively limited work has focused on a comprehensive, data-driven representation of the global crude oil refining landscape. Refinery systems exhibit similarly intricate interactions among feedstock characteristics, process configurations, and product slates, rendering them well-suited to machine learning-based modeling frameworks. Extending these methodologies to refining enables scalable representation of heterogeneous facilities while preserving the structural granularity required for optimization, policy analysis, and energy transition assessment.
Abella et al. [
6] employed a predominantly North American refinery dataset to delineate ten representative refinery configurations for modeling purposes. Their configuration-based framework enabled the development of models for estimating refinery energy consumption and associated greenhouse gas emissions, thereby facilitating systematic evaluation of efficiency improvement and emissions mitigation opportunities [
7]. Such modeling approaches have also been applied to assess crude blending strategies and configuration adjustments aimed at maximizing refinery netback [
8]. Furthermore, configuration-based models have been extended to quantify life cycle environmental impacts of refining systems [
9]. Nevertheless, the reliability of such approaches depends critically on the accurate identification and characterization of refinery process units and their structural attributes.
In 2020, the global refining system comprised 867 crude oil refineries with a combined active capacity of approximately 103.32 million barrels per day (MMb/d), of which nearly 80% were located outside North America [
10]. Systematic identification of distinct refinery configurations across this global landscape would substantially enhance modeling efforts at facility, national, regional, and global scales. By grouping structurally similar refineries, configuration-based approaches reduce the dimensionality of large-scale, multiregional, and multitemporal analyses, thereby streamlining model specification. Such structuring also limits the number of variables required to characterize refinery behavior while enabling aggregation of operational datasets from refineries with comparable process architectures. This aggregation improves statistical robustness and facilitates representation of variability in design capacities and operational practices.
Given the proprietary nature of detailed refinery data, knowledge of applicable configuration classes can also guide the development of representative process simulation models for scenario analysis. Moreover, configuration-based modeling supports benchmarking and dissemination of best practices among refineries operating under similar structural conditions through systematic performance comparisons across operators, countries, and regions. These capabilities are particularly important for integrated global energy system modeling, including assessments of energy transition pathways. In this context, configuration-level representation is essential for evaluating the adaptability of refining systems, especially with respect to increasing petrochemical diversification under scenarios in which electrification reduces long-term demand for transportation fuels.
As multiple jurisdictions advance net-zero emissions commitments—many of which prioritize reductions in greenhouse gas emissions from transportation—the global refining sector is increasingly exploring strategies for deeper petrochemical diversification. In response to anticipated structural changes in fuel demand, the International Energy Agency (IEA) projects that crude oil demand for transportation fuels will peak within the coming decade, with total oil demand stabilizing at approximately 106 MMb/d by 2030 [
11]. In contrast, the Organization of Petroleum Exporting Countries (OPEC) projects continued growth in global oil demand, reaching approximately 116 MMb/d by 2045 [
12]. Notwithstanding these differing outlooks, both organizations anticipate a sustained expansion in crude oil utilization within petrochemical value chains.
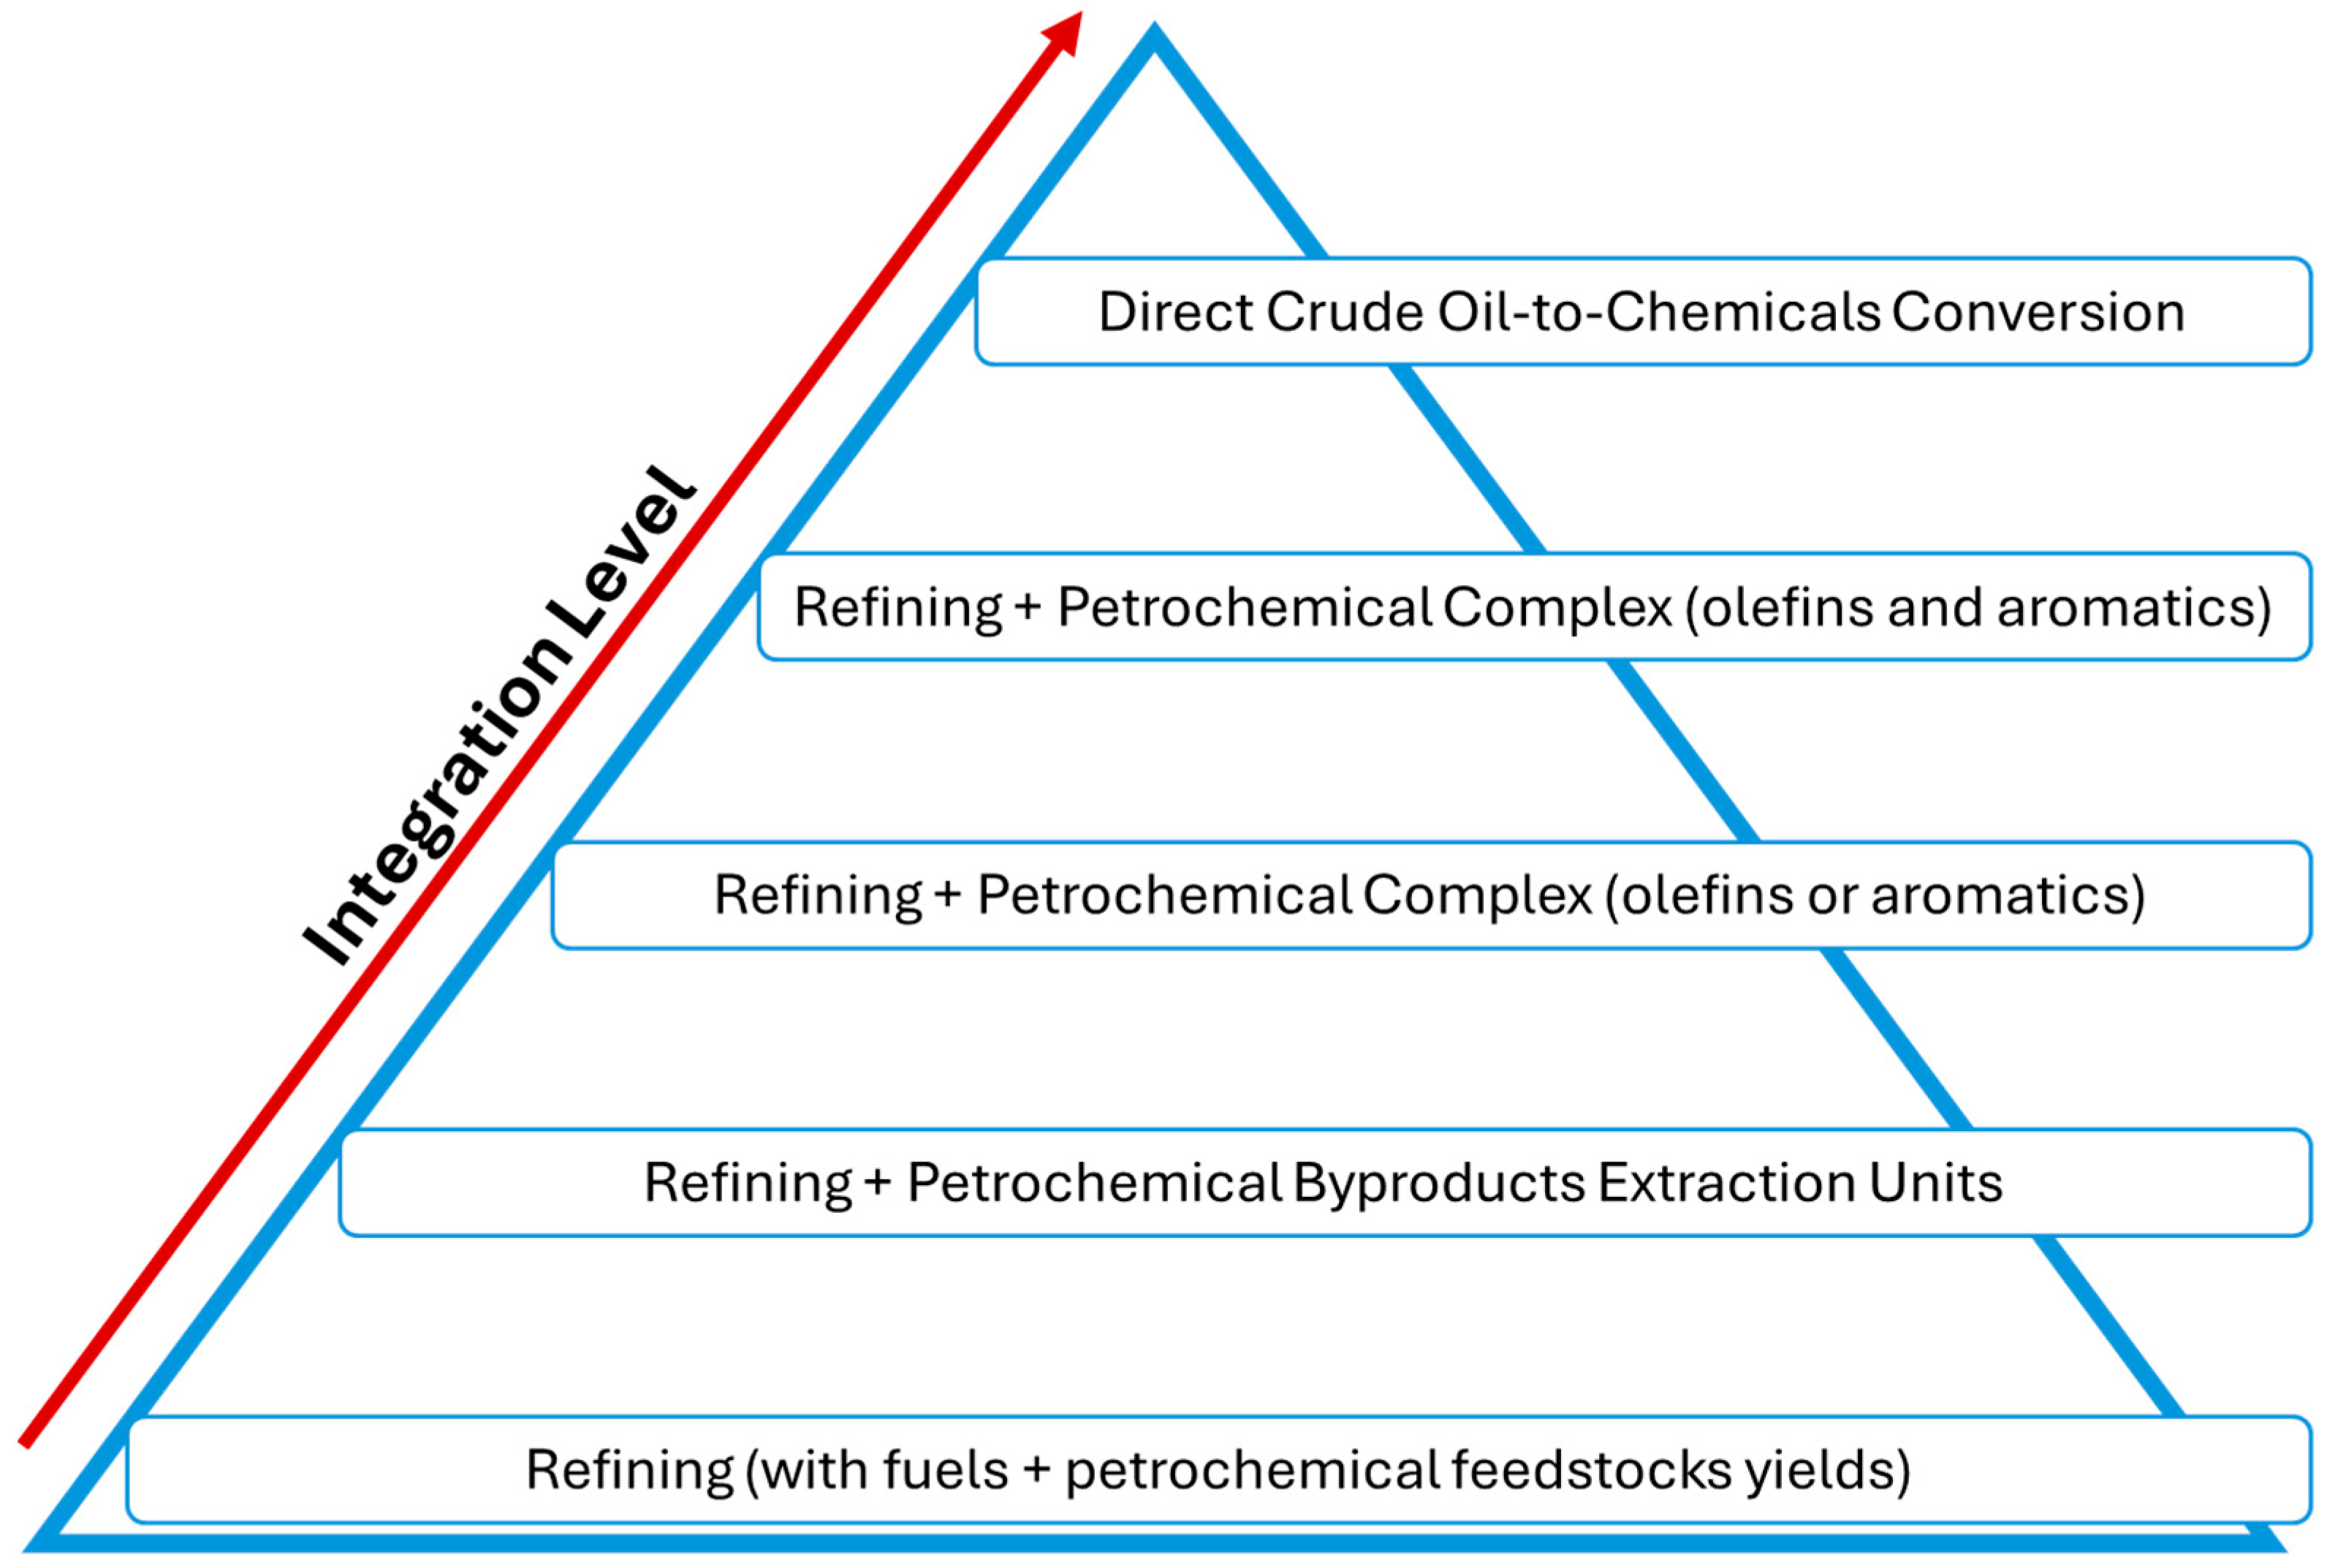
Within this evolving landscape, future refinery development is expected to prioritize configurations and operating strategies that enhance yields of petrochemical feedstocks and related products. Accordingly, refining–petrochemical integration can be conceptualized along a spectrum of increasing structural integration. As illustrated in
Figure 1, five distinct levels can be identified, ranging from conventional refining systems that primarily produce transportation fuels with limited petrochemical co-production to advanced configurations and emerging technologies designed for direct crude-to-chemicals conversion.
At present, uncertainty persists in the literature regarding the attainable limits of petrochemical feedstock yields from existing refining technologies, particularly when assessed within the multiregional and global contexts required for energy transition modeling and policy analysis. The IEA employs a representative global petrochemical yield of approximately 16% in its modeling framework [
11]. However, ongoing industry initiatives aimed at deeper refining–petrochemical integration involve both capacity expansion and operational upgrades intended to increase production of liquefied petroleum gas (LPG), naphtha, and key petrochemical intermediates such as ethylene, propylene, benzene, toluene, and xylenes.
For example, implementation of high-severity or high-olefin fluid catalytic cracking (FCC) technologies can increase propylene yields from roughly 4% to as high as 20%, depending on feedstock and operating conditions. Current global capacity of high-olefin FCC units is estimated at approximately 283 kb/d, primarily located in China, South Korea, and India [
13]. When such upgrading opportunities are considered alongside the baseline global petrochemical yield estimate reported by the IEA, the implied upper bound could approach approximately 32% under favorable integration scenarios. Nevertheless, translating these aggregate estimates into actionable insights requires greater structural and geographic resolution. Petrochemical yield potential varies substantially across facilities and countries due to differences in refinery configuration, feedstock characteristics, and operational practices. Accordingly, configuration-level representation is essential to assess realistic yield limits at facility, national, and regional scales.
Industry projections suggest that increasing the level of refining–petrochemical integration through higher-complexity process configurations could raise chemical yields from approximately 10% to as much as 50% per barrel of crude processed [
14,
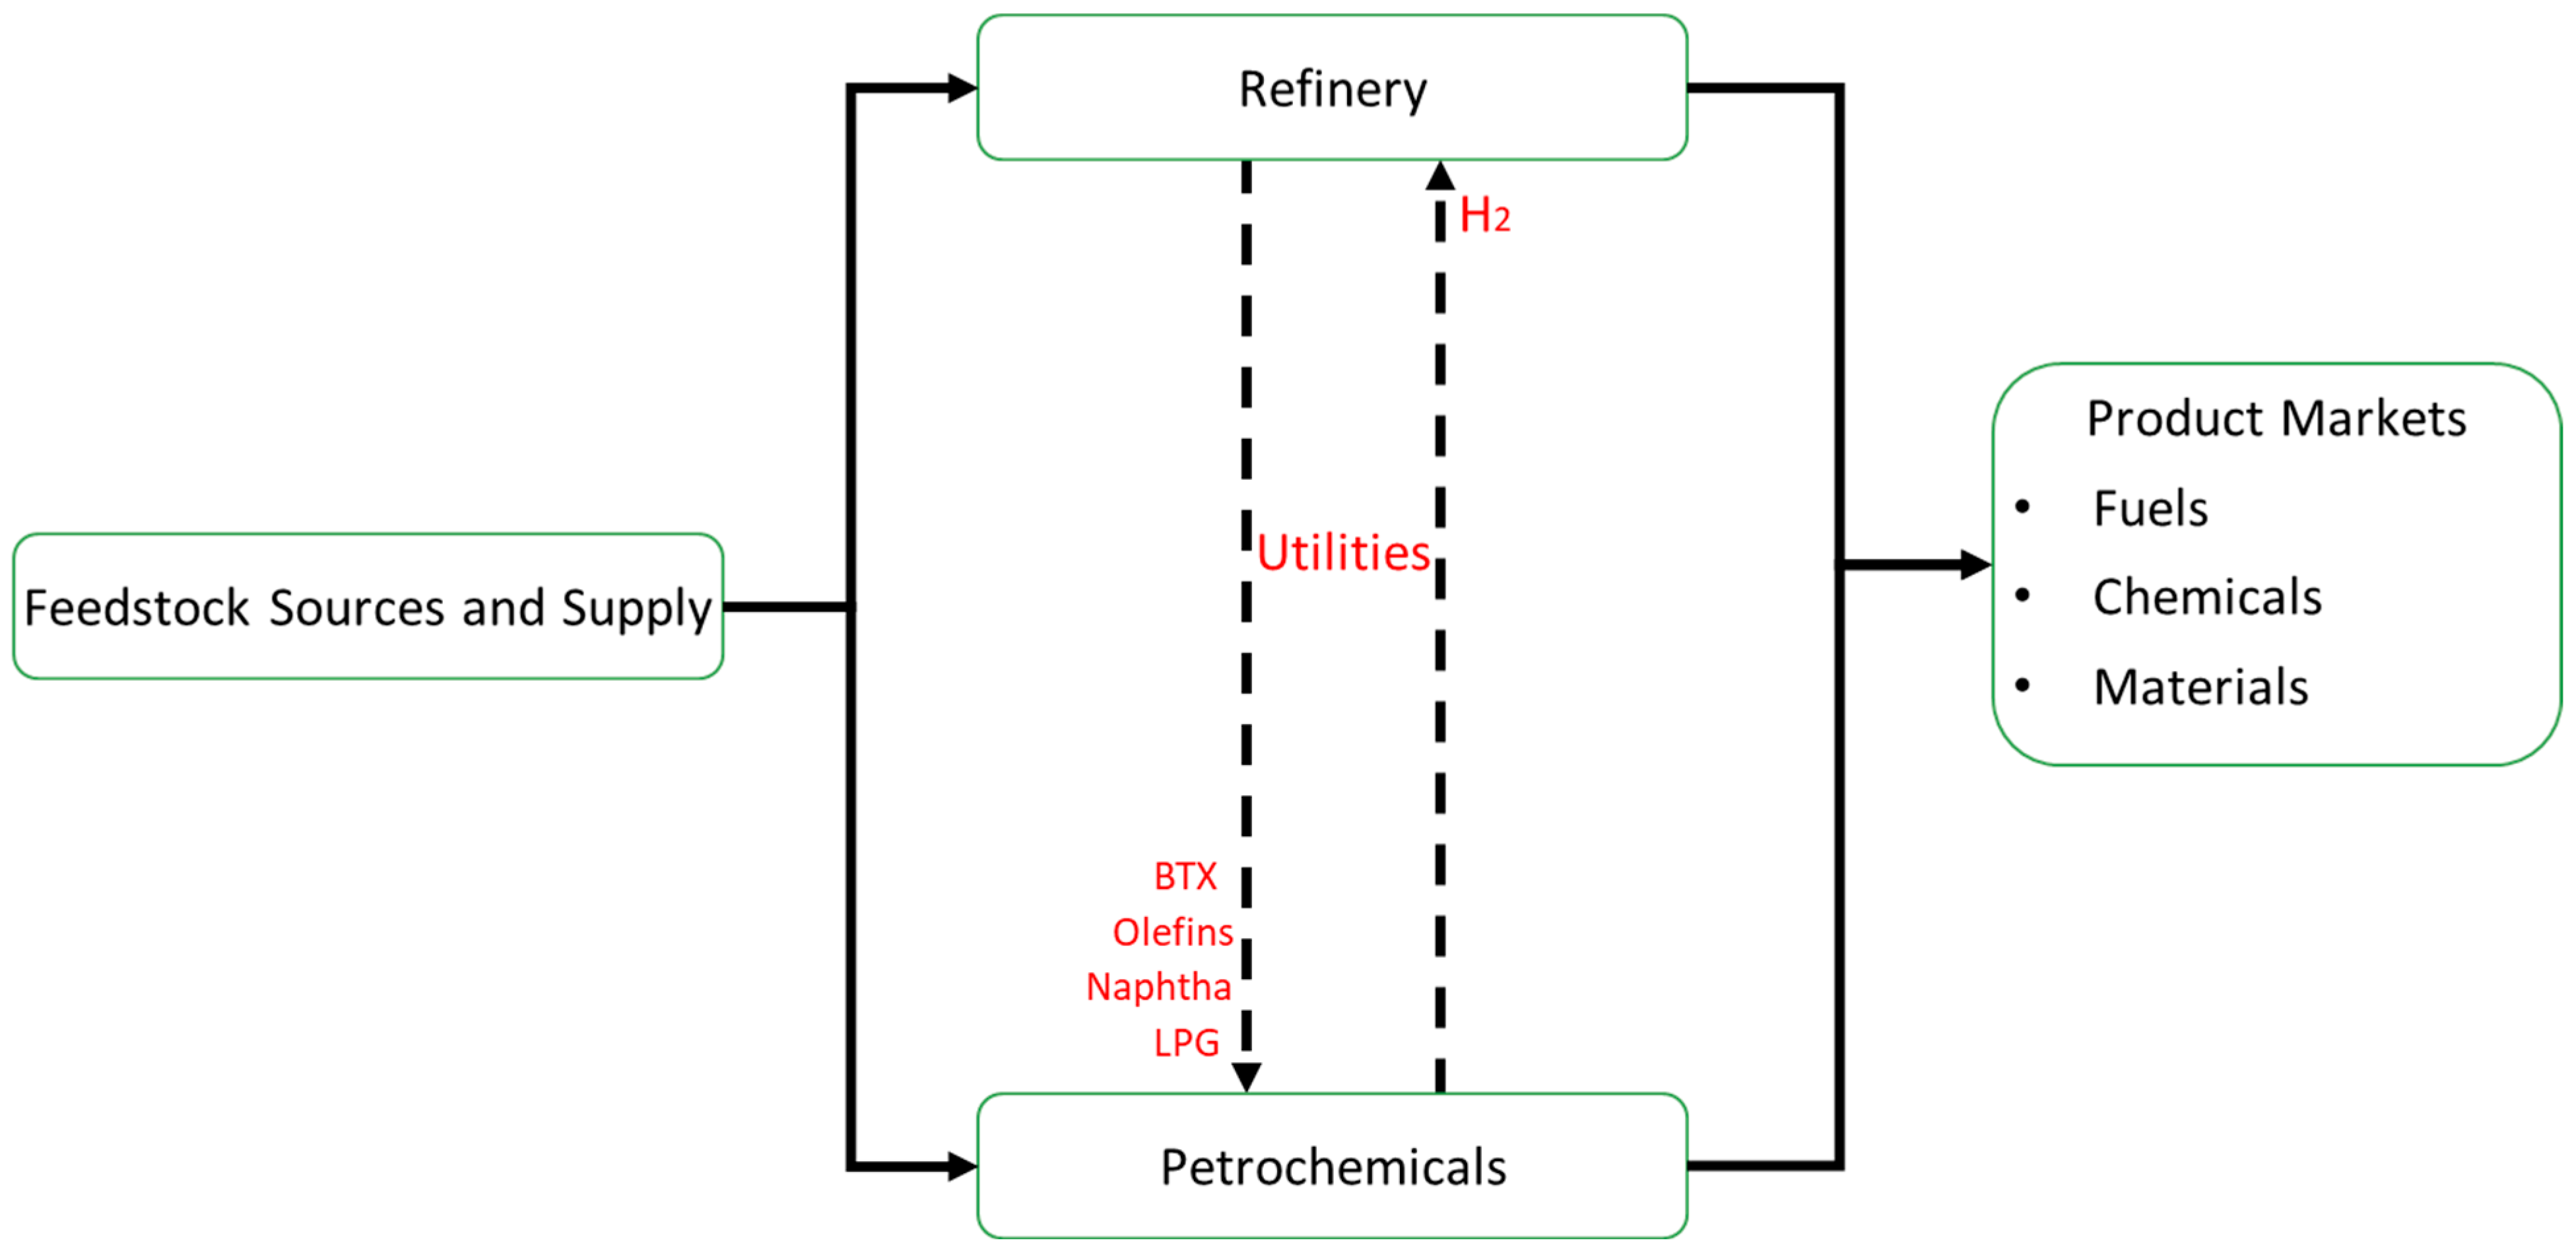
15]. Integrated refinery–petrochemical complexes also present opportunities to capture operational synergies, including improved energy efficiency, enhanced input availability, and greater process flexibility. For example, as illustrated in
Figure 2, hydrogen generated as a by-product in petrochemical operations can be utilized as a critical input for refinery hydrotreating and hydrocracking processes, thereby improving overall system efficiency.
Moreover, integrated facilities can dynamically adjust product slates by shifting between transportation fuels, petrochemical feedstocks, and materials—depending on prevailing market conditions to optimize economic performance. Nevertheless, advancing to higher levels of petrochemical integration requires substantial capital investment in additional process units, retrofits, and technology licensing. Consequently, achieving targeted diversification levels necessitates careful optimization of capital allocation through integrated design strategies and operational flexibility with respect to process technologies, crude feed selection, and product slate configuration.
As petrochemical diversification advances, emerging technologies are being developed and progressively de-risked to enable direct, single-step conversion of crude oil into fundamental petrochemical intermediates, including ethylene, propylene, benzene, toluene, and xylenes. In parallel, industry stakeholders and policymakers have articulated long-term diversification targets, with recent announcements indicating ambitions to achieve petrochemical yield levels in the range of 70% to 85% by 2050 [
13]. Achieving such targets represents a structural transformation of conventional refining systems and necessitates rigorous analytical evaluation.
Model-based analysis provides a systematic framework for assessing the implications of the energy transition on feasible pathways toward these diversification objectives. Beyond evaluating yield potential, integrated refinery models support analyses of efficiency improvements, emissions mitigation strategies, policy design, economic optimization, and investment competitiveness. They also enable the development of more realistic energy outlook scenarios and facilitate examination of future opportunities for co-processing renewable and hydrocarbon feedstocks within existing refinery infrastructures. Realizing these capabilities requires a comprehensive representation of the global refining landscape with sufficient structural and spatiotemporal resolution to inform decision-making at facility, national, and regional levels throughout the anticipated transition horizon.
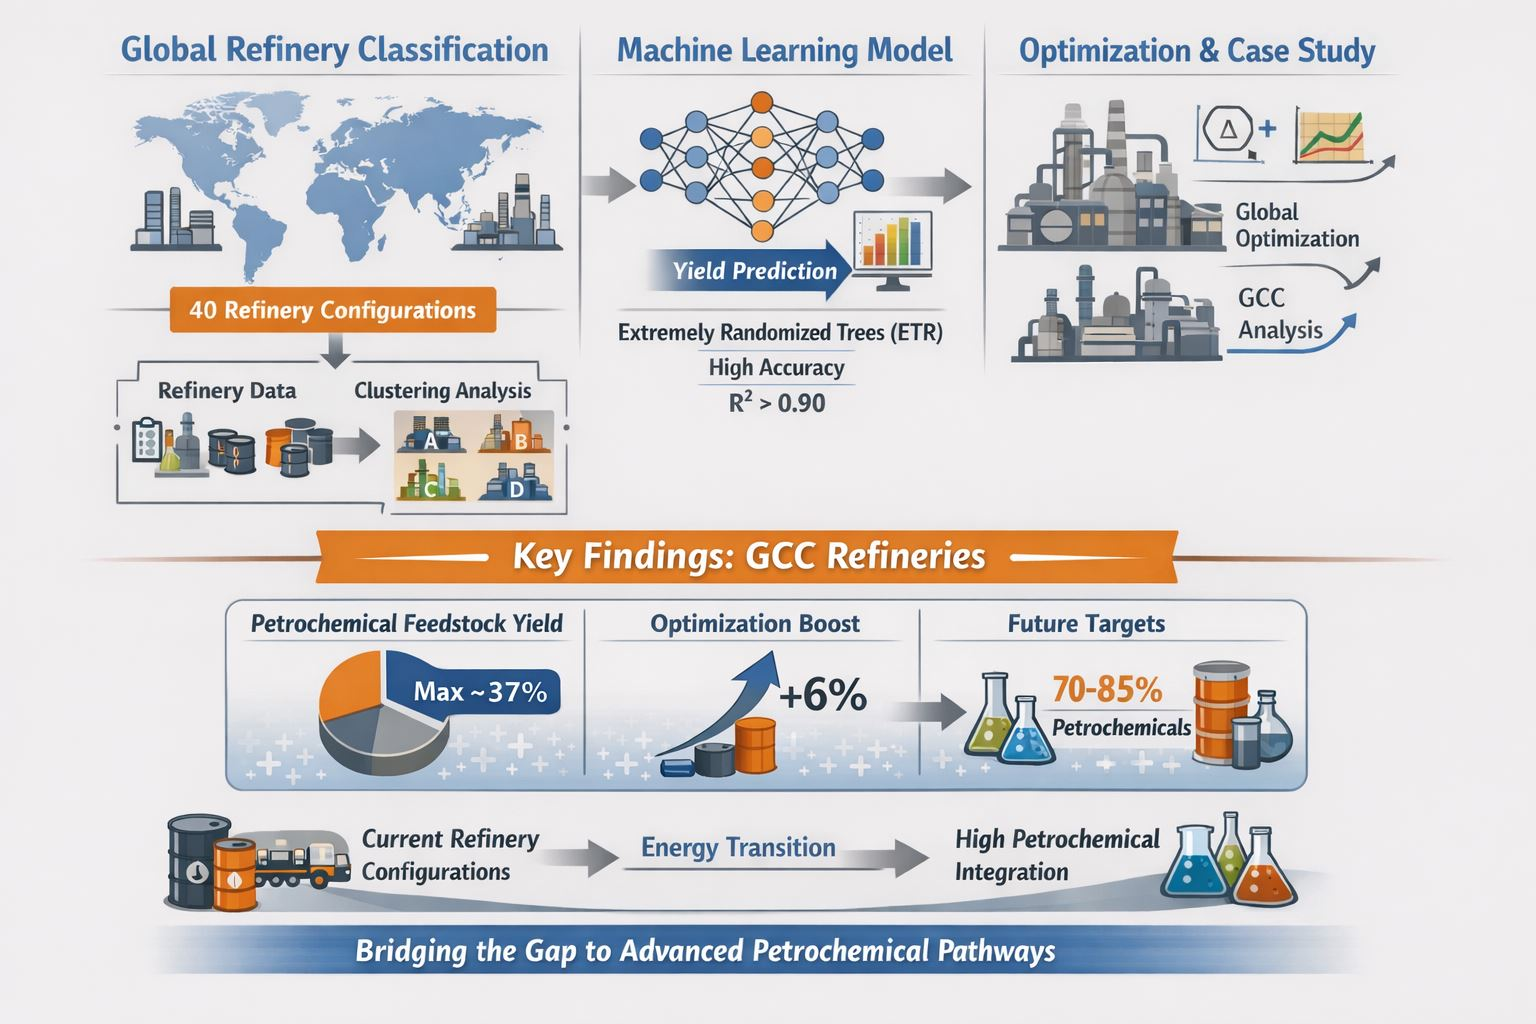
In this study, a machine learning-based framework is developed to construct a configuration-level model of the global crude oil refining system. The predictive model is subsequently integrated with a mathematical optimization module to enable refinery programming under specified operational and feedstock constraints. The coupled modeling framework is applied to evaluate the attainable limits of petrochemical diversification across existing refinery configurations in the Gulf Cooperation Council (GCC) countries.
The remainder of the paper is organized as follows.
Section 2 presents the methodology for classifying global refineries into distinct design configurations.
Section 3 describes the data sources, machine learning formulation, and mathematical programming framework.
Section 4 introduces the GCC case studies, and
Section 5 discusses the results and their implications.
Section 6 concludes with key findings and outlines directions for future research.
3. Refinery Modeling and Mathematical Programming
A machine learning-based (non-parametric) model is developed by implementing the extremely randomized trees regressor (ETR) method in python programming language. Details of the ETR algorithm are available in Geurts et al. [
16]. However, the application of the algorithm in this context is that, for a refinery learning data sample of size
, expressed as:
where
is the vector of explanatory variables (otherwise called features) and
is the vector of corresponding output variables (otherwise called targets). For the case of
features and
targets, both can be denoted as
The sample values of the
feature organized in order of increasing value is
for the features
. Infinite ensemble of extremely random trees estimates the value of the target variable (
) in the following form:
where
is the characteristic function of the hyper-interval as given by
And are real-valued parameters that depend on the examples and , as well as the parameters for minimum sample size for splitting a node () and the number of randomly selected features at each node ().
3.1. Data Preprocessing and Quality Control
The refinery dataset obtained from the S&P Global Platts World Refinery Database contains approximately 15,000 refinery-year observations covering process unit capacities, crude oil runs by grade, and refined product yields between 2005 and 2020. Initial data screening revealed incomplete entries in which either crude feed composition or product yield distributions were missing. Observations lacking essential input–output pairs required for supervised learning were removed, resulting in a final modeling dataset of approximately 11,000 refinery-year observations.
Data consistency checks were performed to ensure material balance plausibility and logical bounds (e.g., non-negative crude runs and product yields). Observations violating physical feasibility constraints were excluded. Outlier detection was conducted using interquartile range (IQR) analysis within each refinery configuration class. Extreme statistical outliers were cross-checked against reported capacity and operational ranges to avoid removal of legitimate but infrequent operating conditions. No artificial truncation or winsorization was applied beyond physical feasibility screening.
Because tree-based ensemble methods are invariant to monotonic transformations and do not require feature normalization, no scaling was applied for the extremely randomized trees (ETR) model. However, for benchmarking with multiple linear regression (MLR), predictors were standardized to zero mean and unit variance to ensure comparability of coefficient magnitudes and numerical stability.
3.2. Feature Engineering and Encoding
The predictive model includes 47 explanatory variables representing refinery scale, feedstock characteristics, and structural configuration.
The feature set consists of:
- 3.
Refinery Configuration—Forty unique refinery configurations identified through clustering. The configurations are treated as categorical variables, which are encoded using one-hot encoding, producing 40 binary indicator variables.
After encoding, all predictors are numeric. The one-hot representation allows the ETR model to learn configuration-specific nonlinear relationships between crude diet, scale, and product yields without imposing parametric assumptions.
3.3. Model Benchmarking Across Algorithms
To evaluate predictive robustness, the extremely randomized trees (ETR) model was benchmarked against multiple alternative algorithms, including:
Multiple Linear Regression (MLR);
Random Forest (RF);
Extreme Gradient Boosting (XGB);
Other ensemble and nonlinear regression models (total of 15 candidate algorithms).
All models were trained using a 70/30 train-test split with identical feature sets. Performance metrics include:
Coefficient of determination ();
Mean Absolute Error (MAE);
Root Mean Square Error (RMSE).
Across all refined products (LPG, naphtha, gasoline, kerosene/jet fuel, diesel/gas oil, and heavy fuel oil), the ETR model achieved the highest average out-of-sample values () and consistently lower MAE and RMSE compared to alternative models. Random Forest (RF) and Extreme Gradient Boosting (XGB) demonstrated competitive performance but exhibited slightly higher variance across product categories. The ETR model was selected for integration with the optimization framework due to its superior predictive stability and computational efficiency.
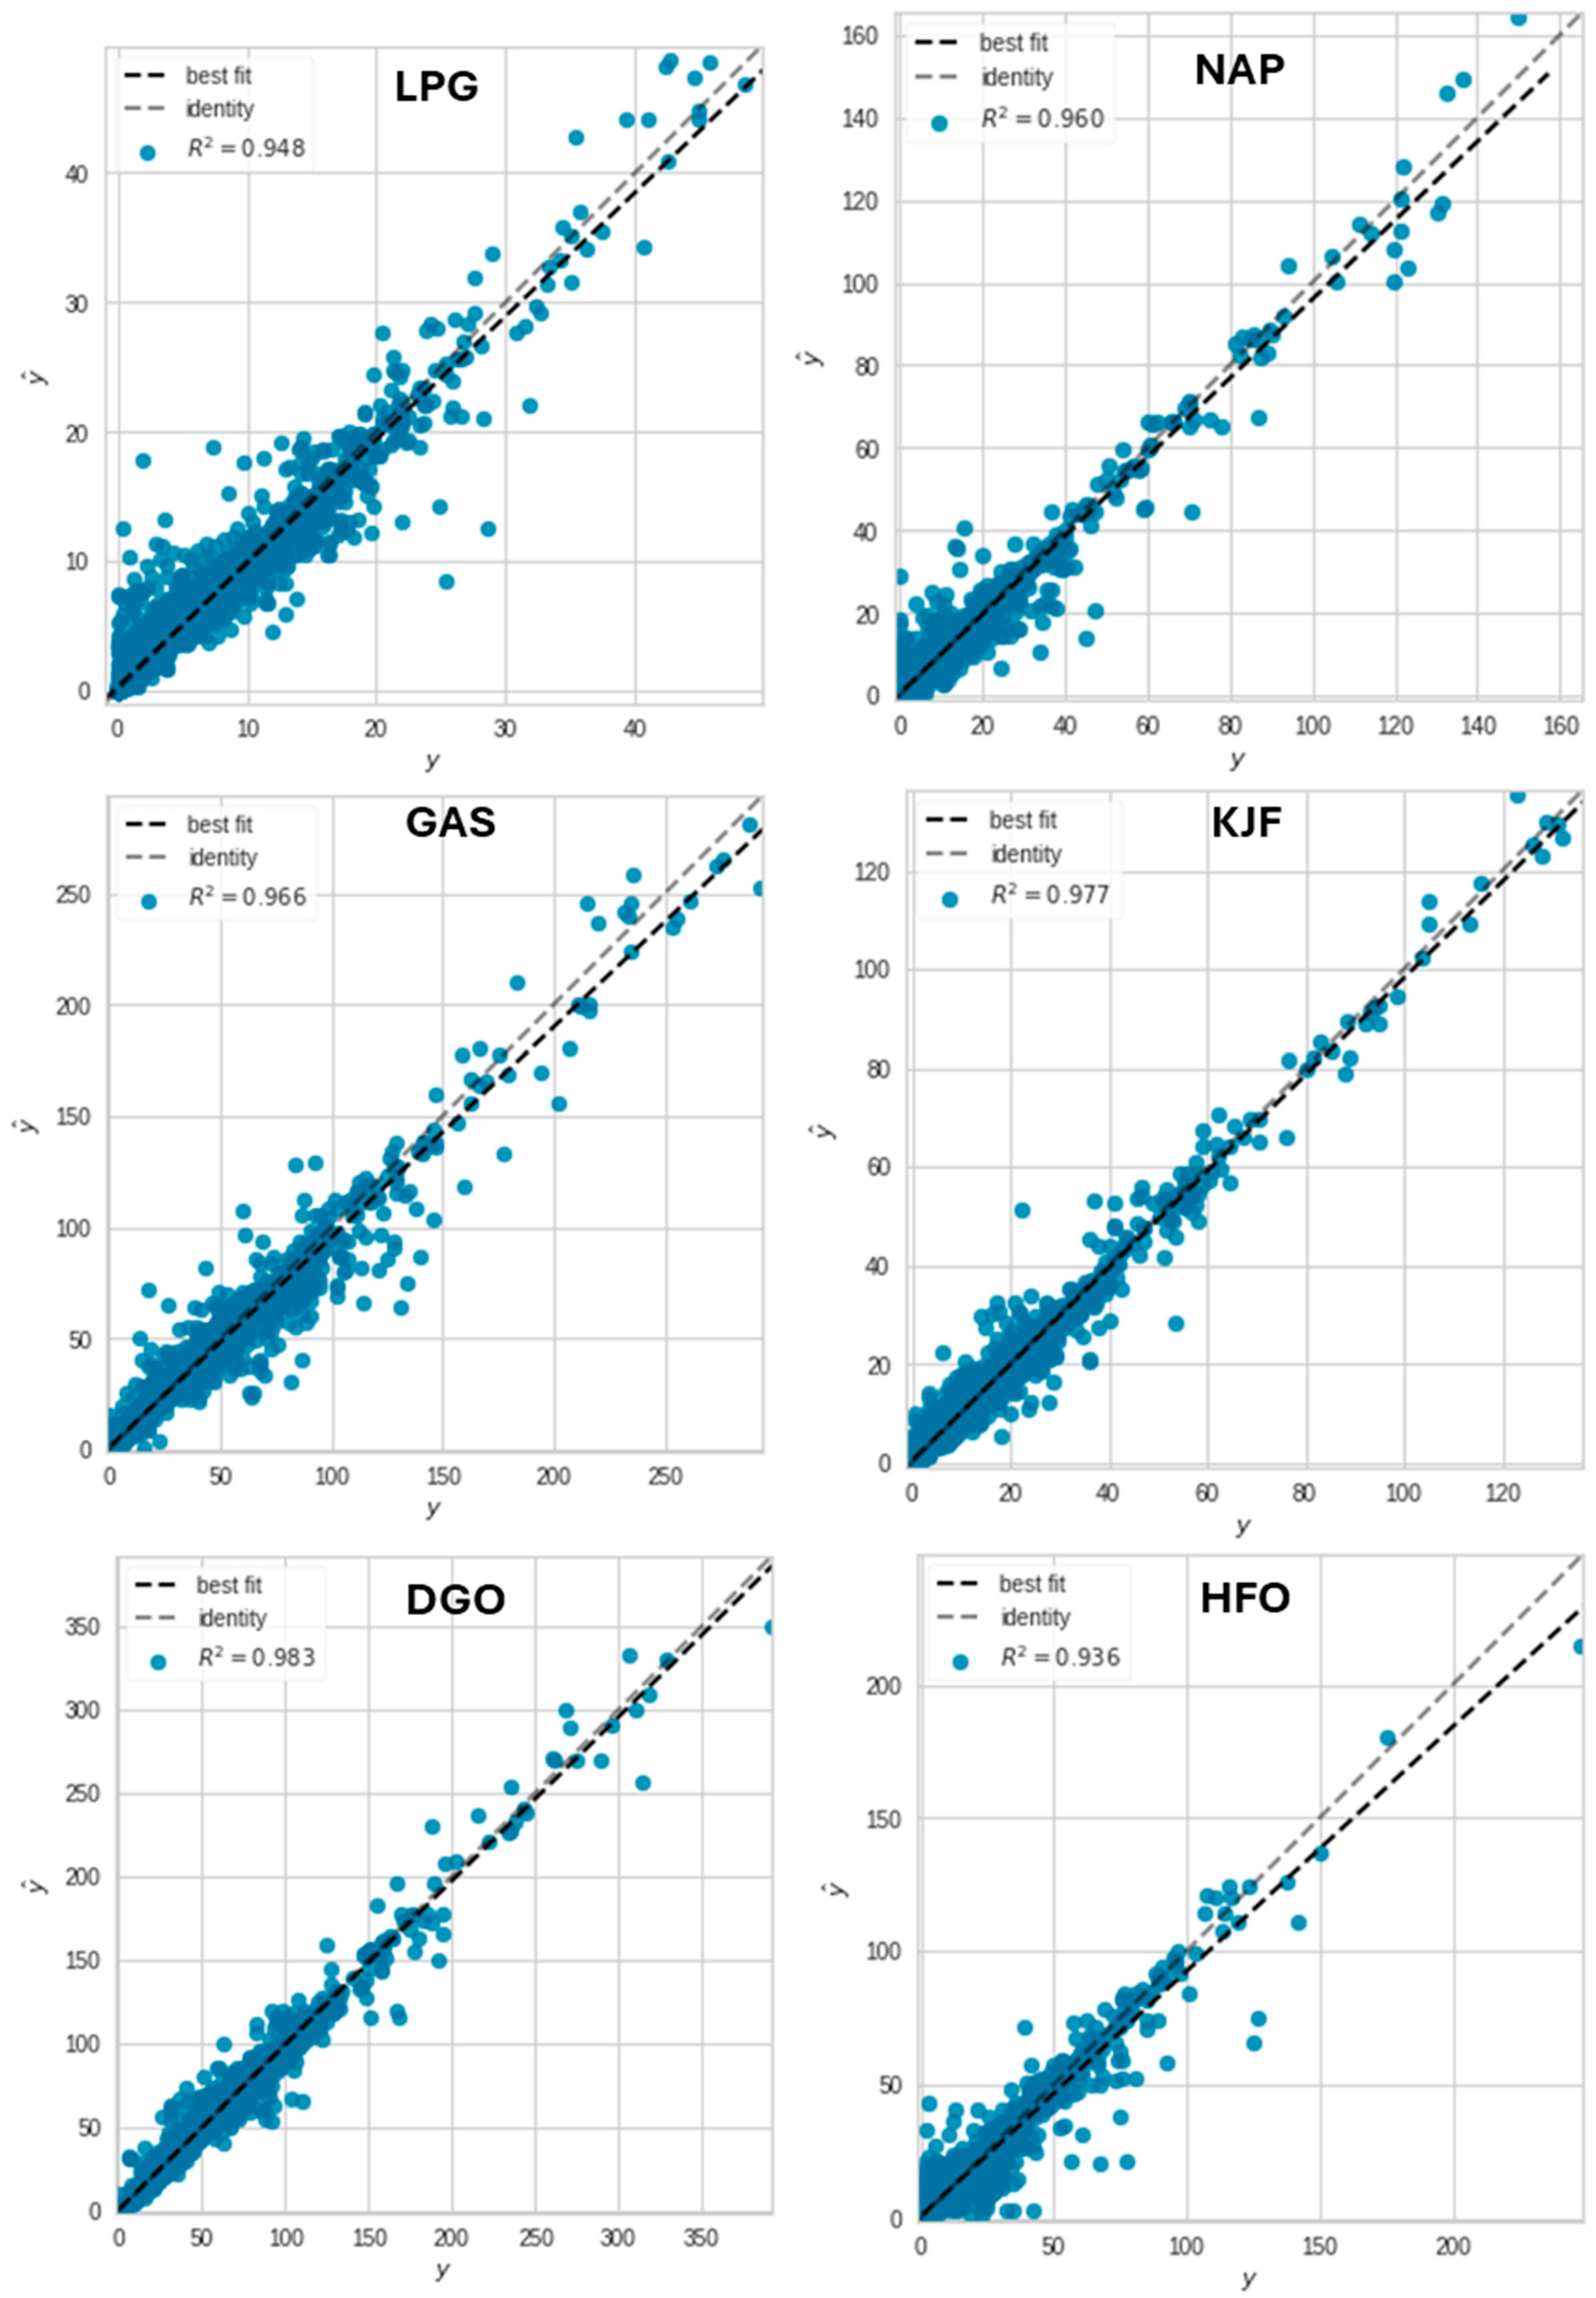
Figure 5 shows parity plots for all the refined products predicted with the developed ETR model. The refined products modeled include liquefied petroleum gas (LPG), naphtha (NAP), gasoline (GAS), kerosene/jet fuel (KJF), diesel/gas oil (DGO), and heavy fuel oil (HFO). The coefficient of determination (
) is above 90% for all refinery products predicted with the ETR model, meaning that over 90% of the variation in the target variables is accounted for by the model.
Table 3 presents all performance metrics used to compare the models. It is observed that the ETR model demonstrates higher predictive performance for the target refined products.
For a given refining configuration, potential sources of deviations between the predicted and observed values of refined products flows could be from differences at the process sub-unit level: design, process technology, operational expertise of plant operators (human factors), and model suitability. Consequently, 15 other training algorithms were applied to the datasets, and none outperformed the ETR model on all target refined products prediction. Based on
results, the MLR model shows its poorest performance on naphtha prediction, whereas the ETR model has the poorest performance on heavy fuel oil prediction. Additional statistical analysis results for the models are available in the
Supplementary Information, Sections S2 and S3.
Given the developed and tested machine learning-based global refinery model, it is possible to simulate operational behaviors of global refineries under various feedstock and product demand dynamics. In fact, the model has been used to assess the market supply impact of the recently commissioned 650 kb/d capacity Dangote Refinery in Nigeria, where it predicted the gasoline supply from the refinery to around 276,000 barrels per day [
17]. Another independent study by Sahdev et al. [
18], using the AVEVA USC Plan software (version 3.3.1.0) to develop an end-to-end flowsheet of the plant, estimated gasoline supply from the refinery to be about 270 kb/d. The gasoline production from the plant is of preference for comparison because the plant was designed for optimal gasoline yield due to its high demand in the Nigerian market.
With established, reliable performance, mathematical optimization models can leverage the predictive power of the developed machine learning model of global refineries to specify optimal performance conditions under given objectives of interest. Mathematical programming has been used extensively in crude oil refineries to represent plant behavior and optimize performance [
19,
20,
21,
22]. A major application area in the industry is production planning where, under dynamic or uncertain market conditions influencing the supply of crude oil feedstocks of various qualities to a refinery plant and/or conditions impacting the demand of refined products by intermediate and final consumers, the goal is to steer the operation of the refinery plant to fulfill all obligations of the business [
21]. Production planning can be done at the individual facility level or coordinated across facilities owned or operated by the same entity. Under such an arrangement, a machine learning model can represent the production operations of the plant. Integrating production and optimization models furnishes the synergized benefits of high-fidelity predictions with an optimum performance seeking technique.
3.4. Differential Evolution Parameterization and Convergence
The optimization problem is formulated as a constrained minimization of the negated objective function, allowing maximization of petrochemical feedstock yields while satisfying:
Crude diet composition bounds
Capacity constraints
Historical operational limits
Non-negativity conditions
The DE algorithm’s population-based search and mutation mechanisms reduce the risk of convergence to local optima, making it suitable for the nonlinear, high-dimensional predictor space induced by the machine learning model.
Workflow of the combined model implementation is presented in
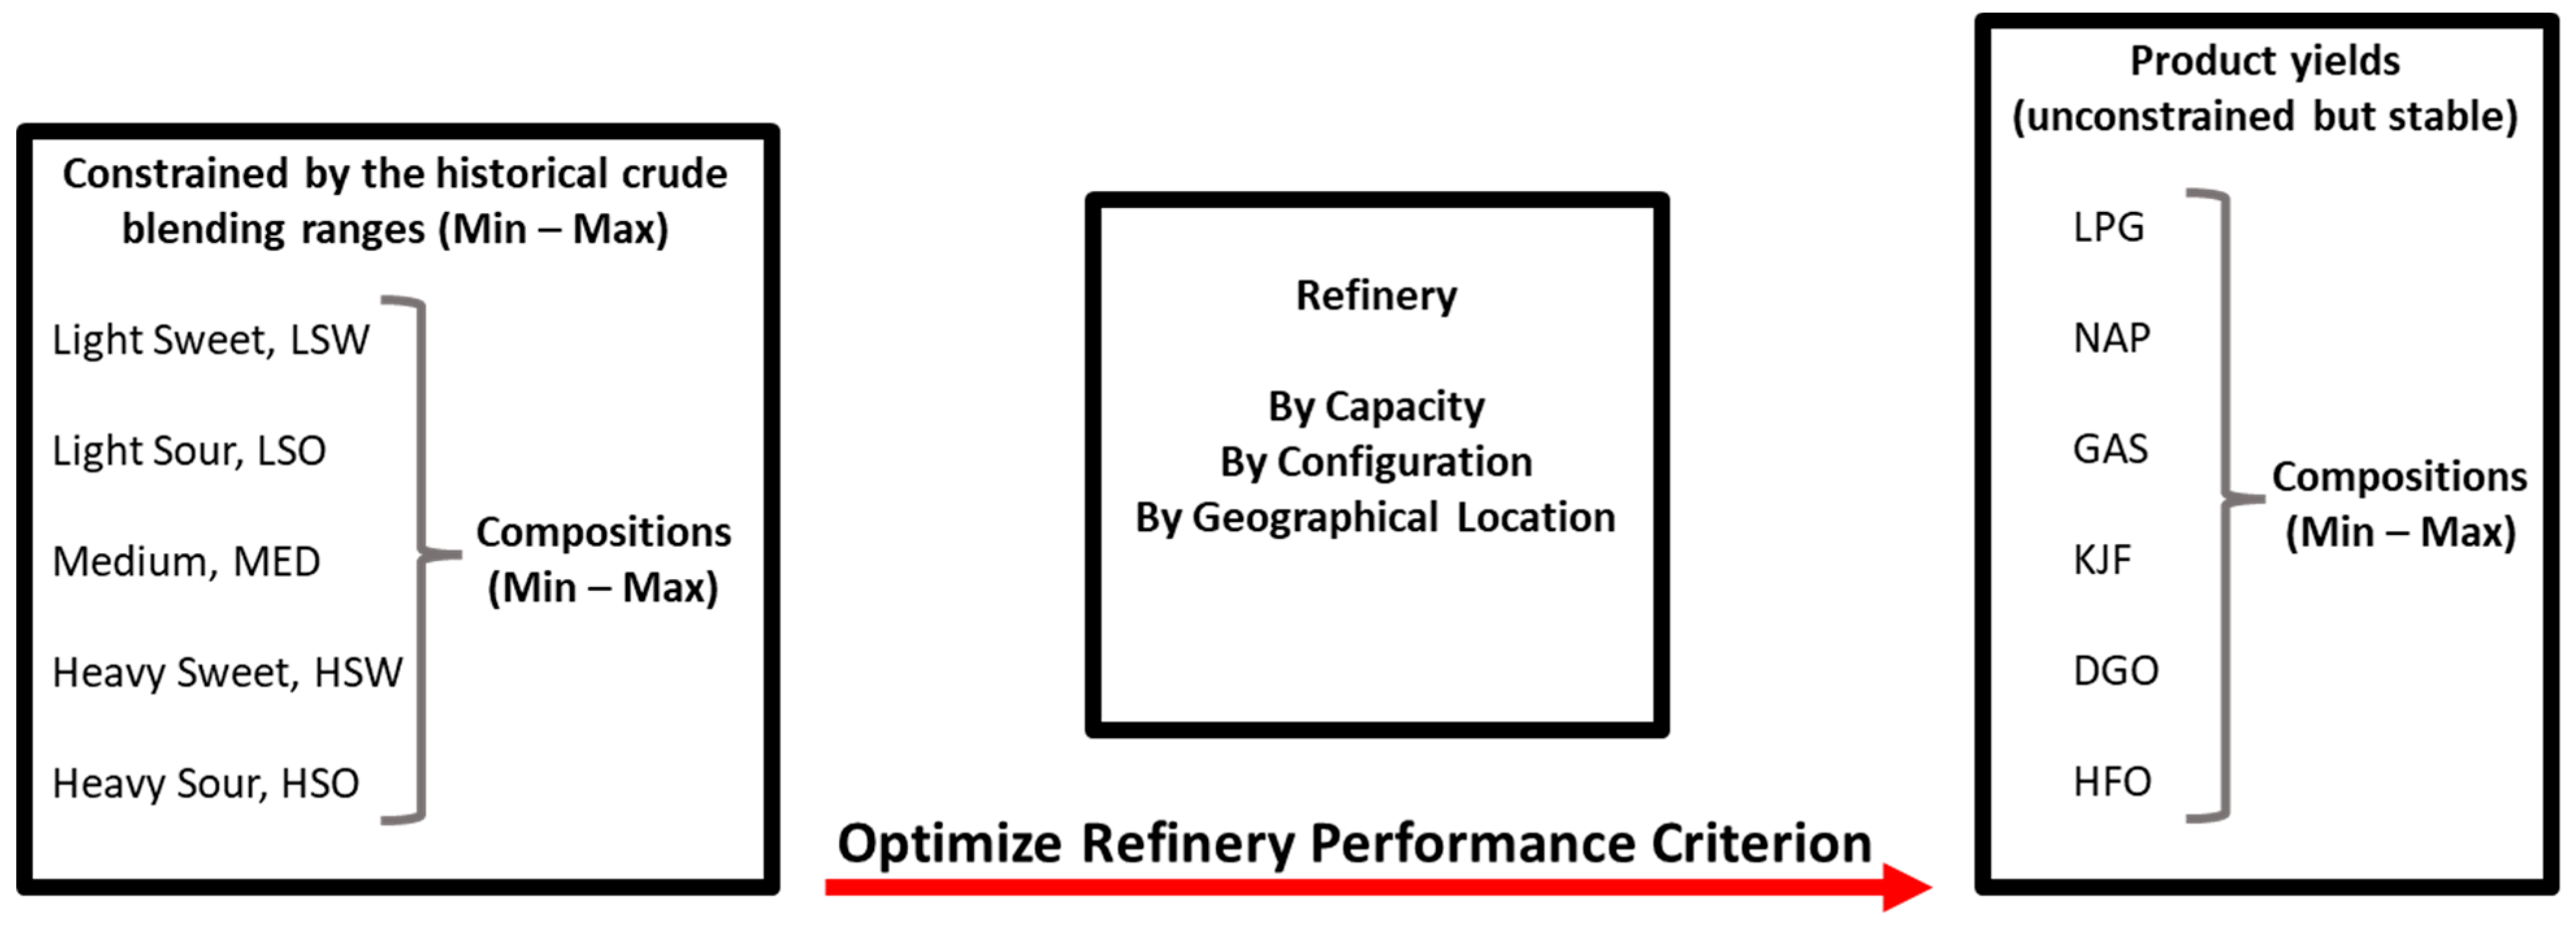
Figure 6, and the following paragraphs provide further description of the differential evolution algorithm, which has been used to analyze the programming problem. All formulations of the problem are also implemented using the Python programming language.
The differential evolution algorithm was presented in a paper by Storn and Price [
19]. In terms of its deployment to programming machine learning-based refinery models, one considers a refinery system whose attributes of interest are represented by real-valued predictors:
For such refinery plants, realizations of normal operational conditions are governed by the design and operating experience, which specifies bounds on the predictors:
where
and
are the lower and upper bounds on the predictors. These bounds are included in the constraints of a mathematical programming problem. Other constraints of the system may comprise material balances, logistical, and/or energy balances, which are all real-valued. The optimization task is to determine the M-dimensional vector of predictors (
), using the differential evolution method, which minimizes an objective function or its negation (in the case of maximization). Differential evolution method generates new parameter vectors by modifying the current generation of predictors using the weighted difference between two population members as follows,
The vectors
are randomly but not repeatedly selected from the population (
) of predictor vectors (
) in the generation
where
where
is a factor that amplifies the differential variation. The new/trial predictor vector (
) must furnish a better value of the objective criterion before it can replace a current predictor in the population of the next generation. Like the crossover process in genetic algorithms and evolutionary strategies, differential evolution also uses a mutation mechanism to introduce diversity in the population of predictor vectors, which can speed up convergence and improve global optimality of results. Further details of the differential evolution algorithm have been presented in the paper by Storn and Price [
19].
To integrate the ETR model of global refineries with the DE model for production optimization purposes, the predictors of the ETR model become the predictor vectors in the DE model. Hence, for the system of models, which takes a vector of predictors comprising crude oil feed by quality and refinery capacity as input, real-valued predictions of refined products from a specified type of refinery design are evaluated as,
The DE algorithm generates the best predictor vector (
) to optimize the properties
, while satisfying all constraints on the system, including the bounds on the predictors. In the case of a refinery model, it is normally desirable to maximize the value of
. Consequently, since the DE algorithm minimizes the objective function (i.e., the negation of
), this results in a min-max formulation of the optimization task. Storn and Price [
19] observed that this case guarantees that all local minima and possible global minimum can be found using the differential evolution algorithm, irrespective of the feasible initialization points. Once the ETR model has been trained over the entire operational landscape of all world refineries in the database, it is possible to benchmark the performance of any refinery plant against the best-in-class of the same configuration globally, over every performance measure of interest.
The differential evolution (DE) optimization was implemented using the scipy.optimize.differential_evolution function in Python (version 3.11.15) with default parameter settings. The algorithm employed the “best1bin” strategy, with a population size equal to 15 times the number of decision variables, a mutation factor uniformly sampled in the interval [0.5, 1], a recombination rate of 0.7, a maximum iteration limit of 1000 generations, and Latin hypercube initialization to enhance diversity of the initial population. Upon termination, the best solution was further refined using the default local polishing step based on the L-BFGS-B algorithm. No manual tuning of DE hyperparameters was performed.
In the present formulation, the decision variables consist exclusively of crude oil diets processed by each refinery, while refinery configuration and capacity are treated as exogenous parameters. The optimization is therefore carried out over a bounded continuous space defined by crude feed shares, subject to inequality constraints enforcing that total feed volumes observe refining capacity limits and inequality constraints representing historical operating limits. The convergence of the DE algorithm follows SciPy’s default termination criterion, whereby optimization stops when the normalized standard deviation of the population objective values satisfies
where
and
denote the standard deviation and mean of population objective values, respectively, and the tolerance parameter is set to its default value of 0.01. For each refinery case, convergence was typically achieved within approximately two minutes on a standard workstation. The observed stability and runtime are consistent with the relatively low dimensionality of the decision space and the smooth response surface induced by the machine learning-based objective function.
4. Application: Optimal Petrochemical Feedstock Yields from GCC Region Refineries
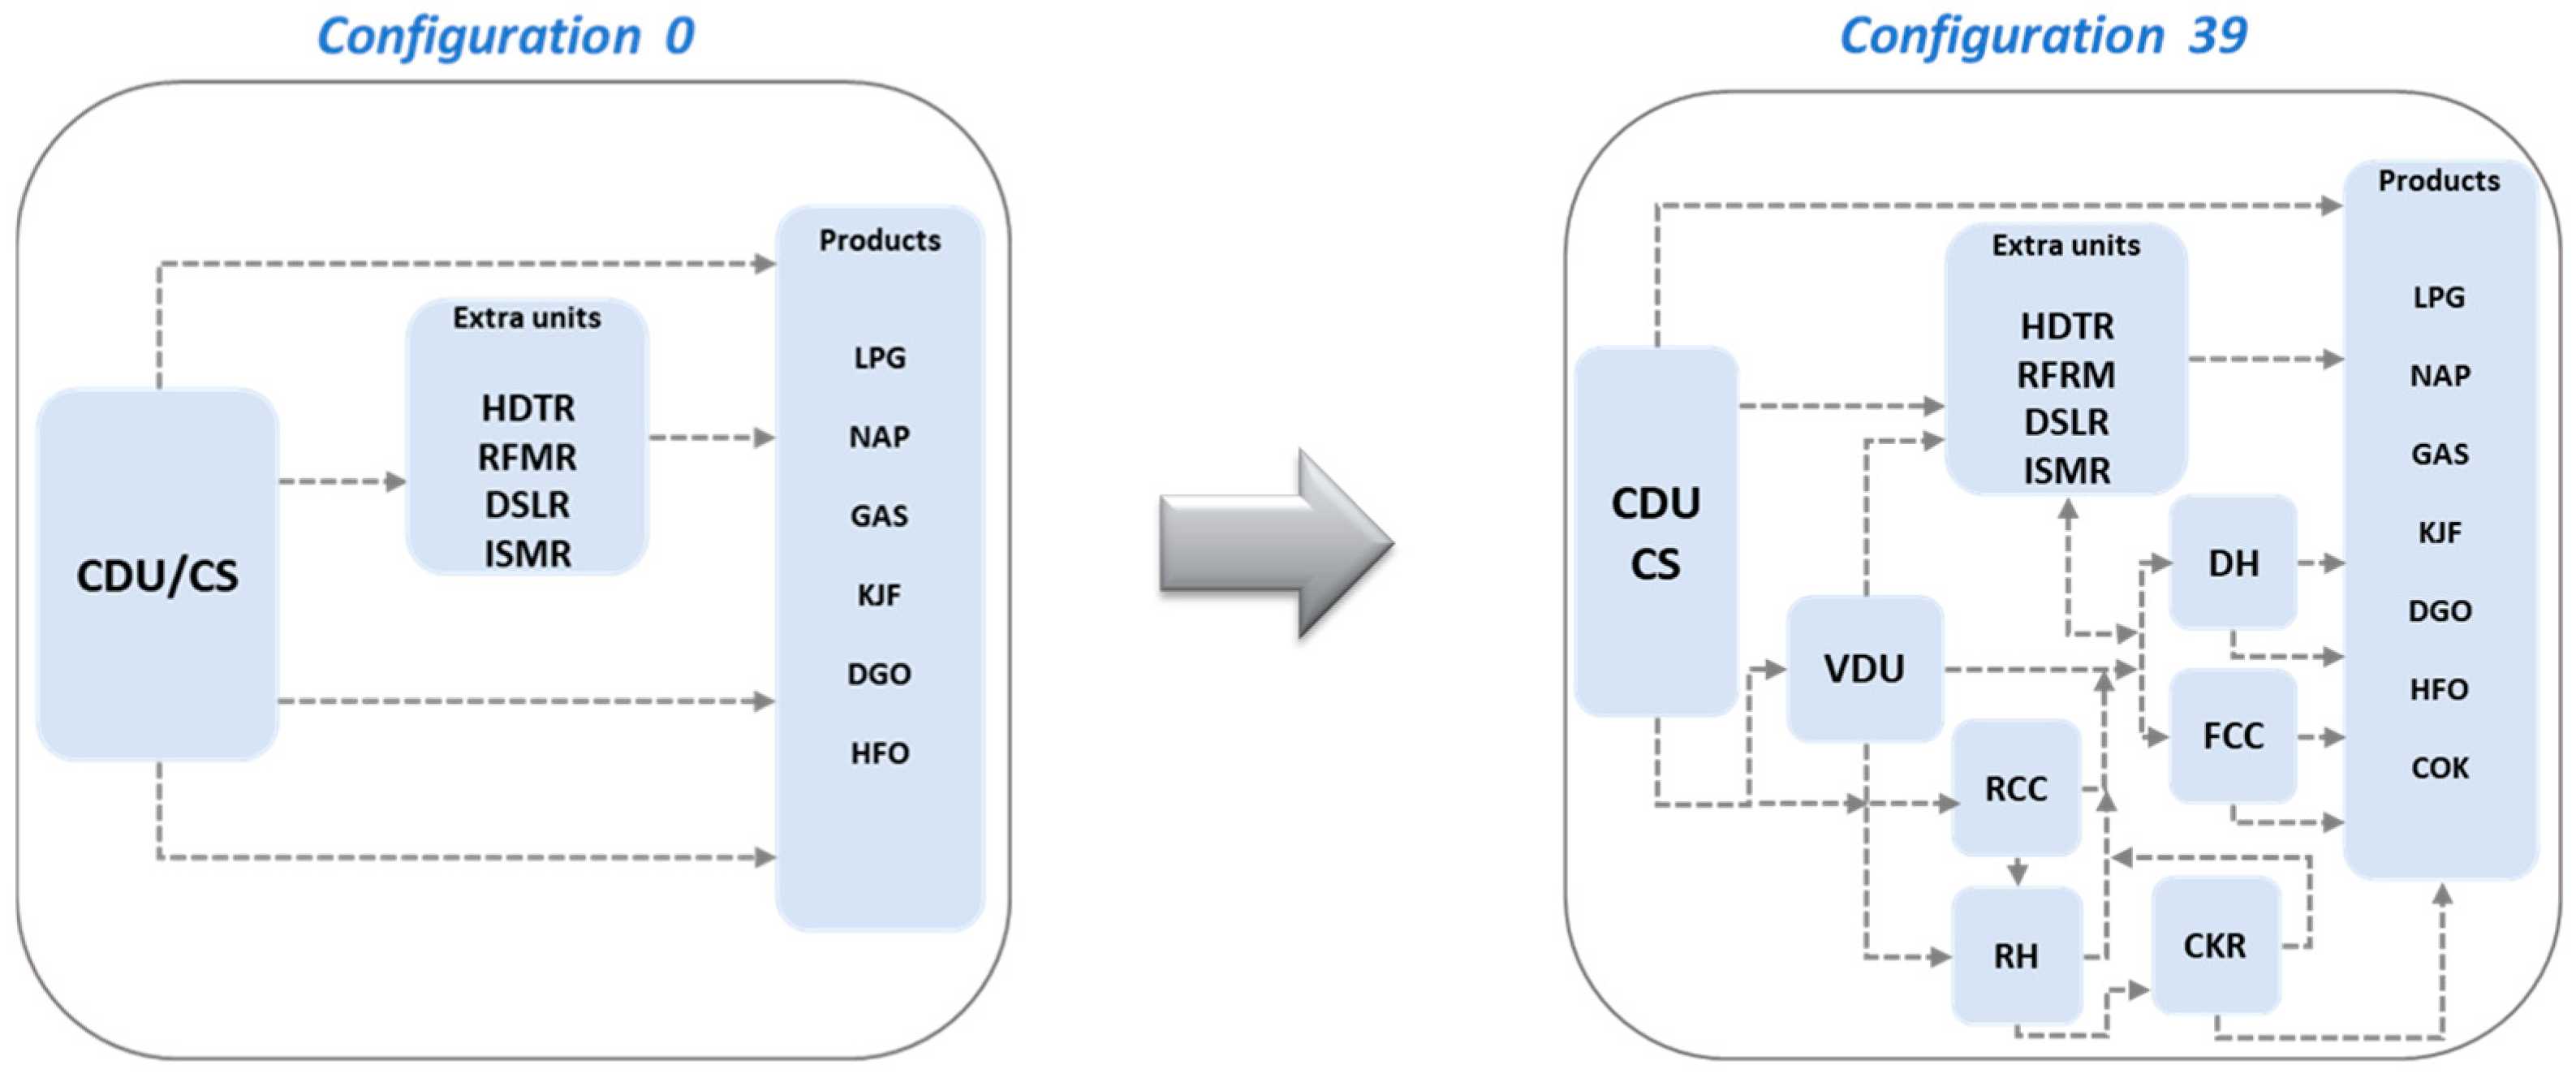
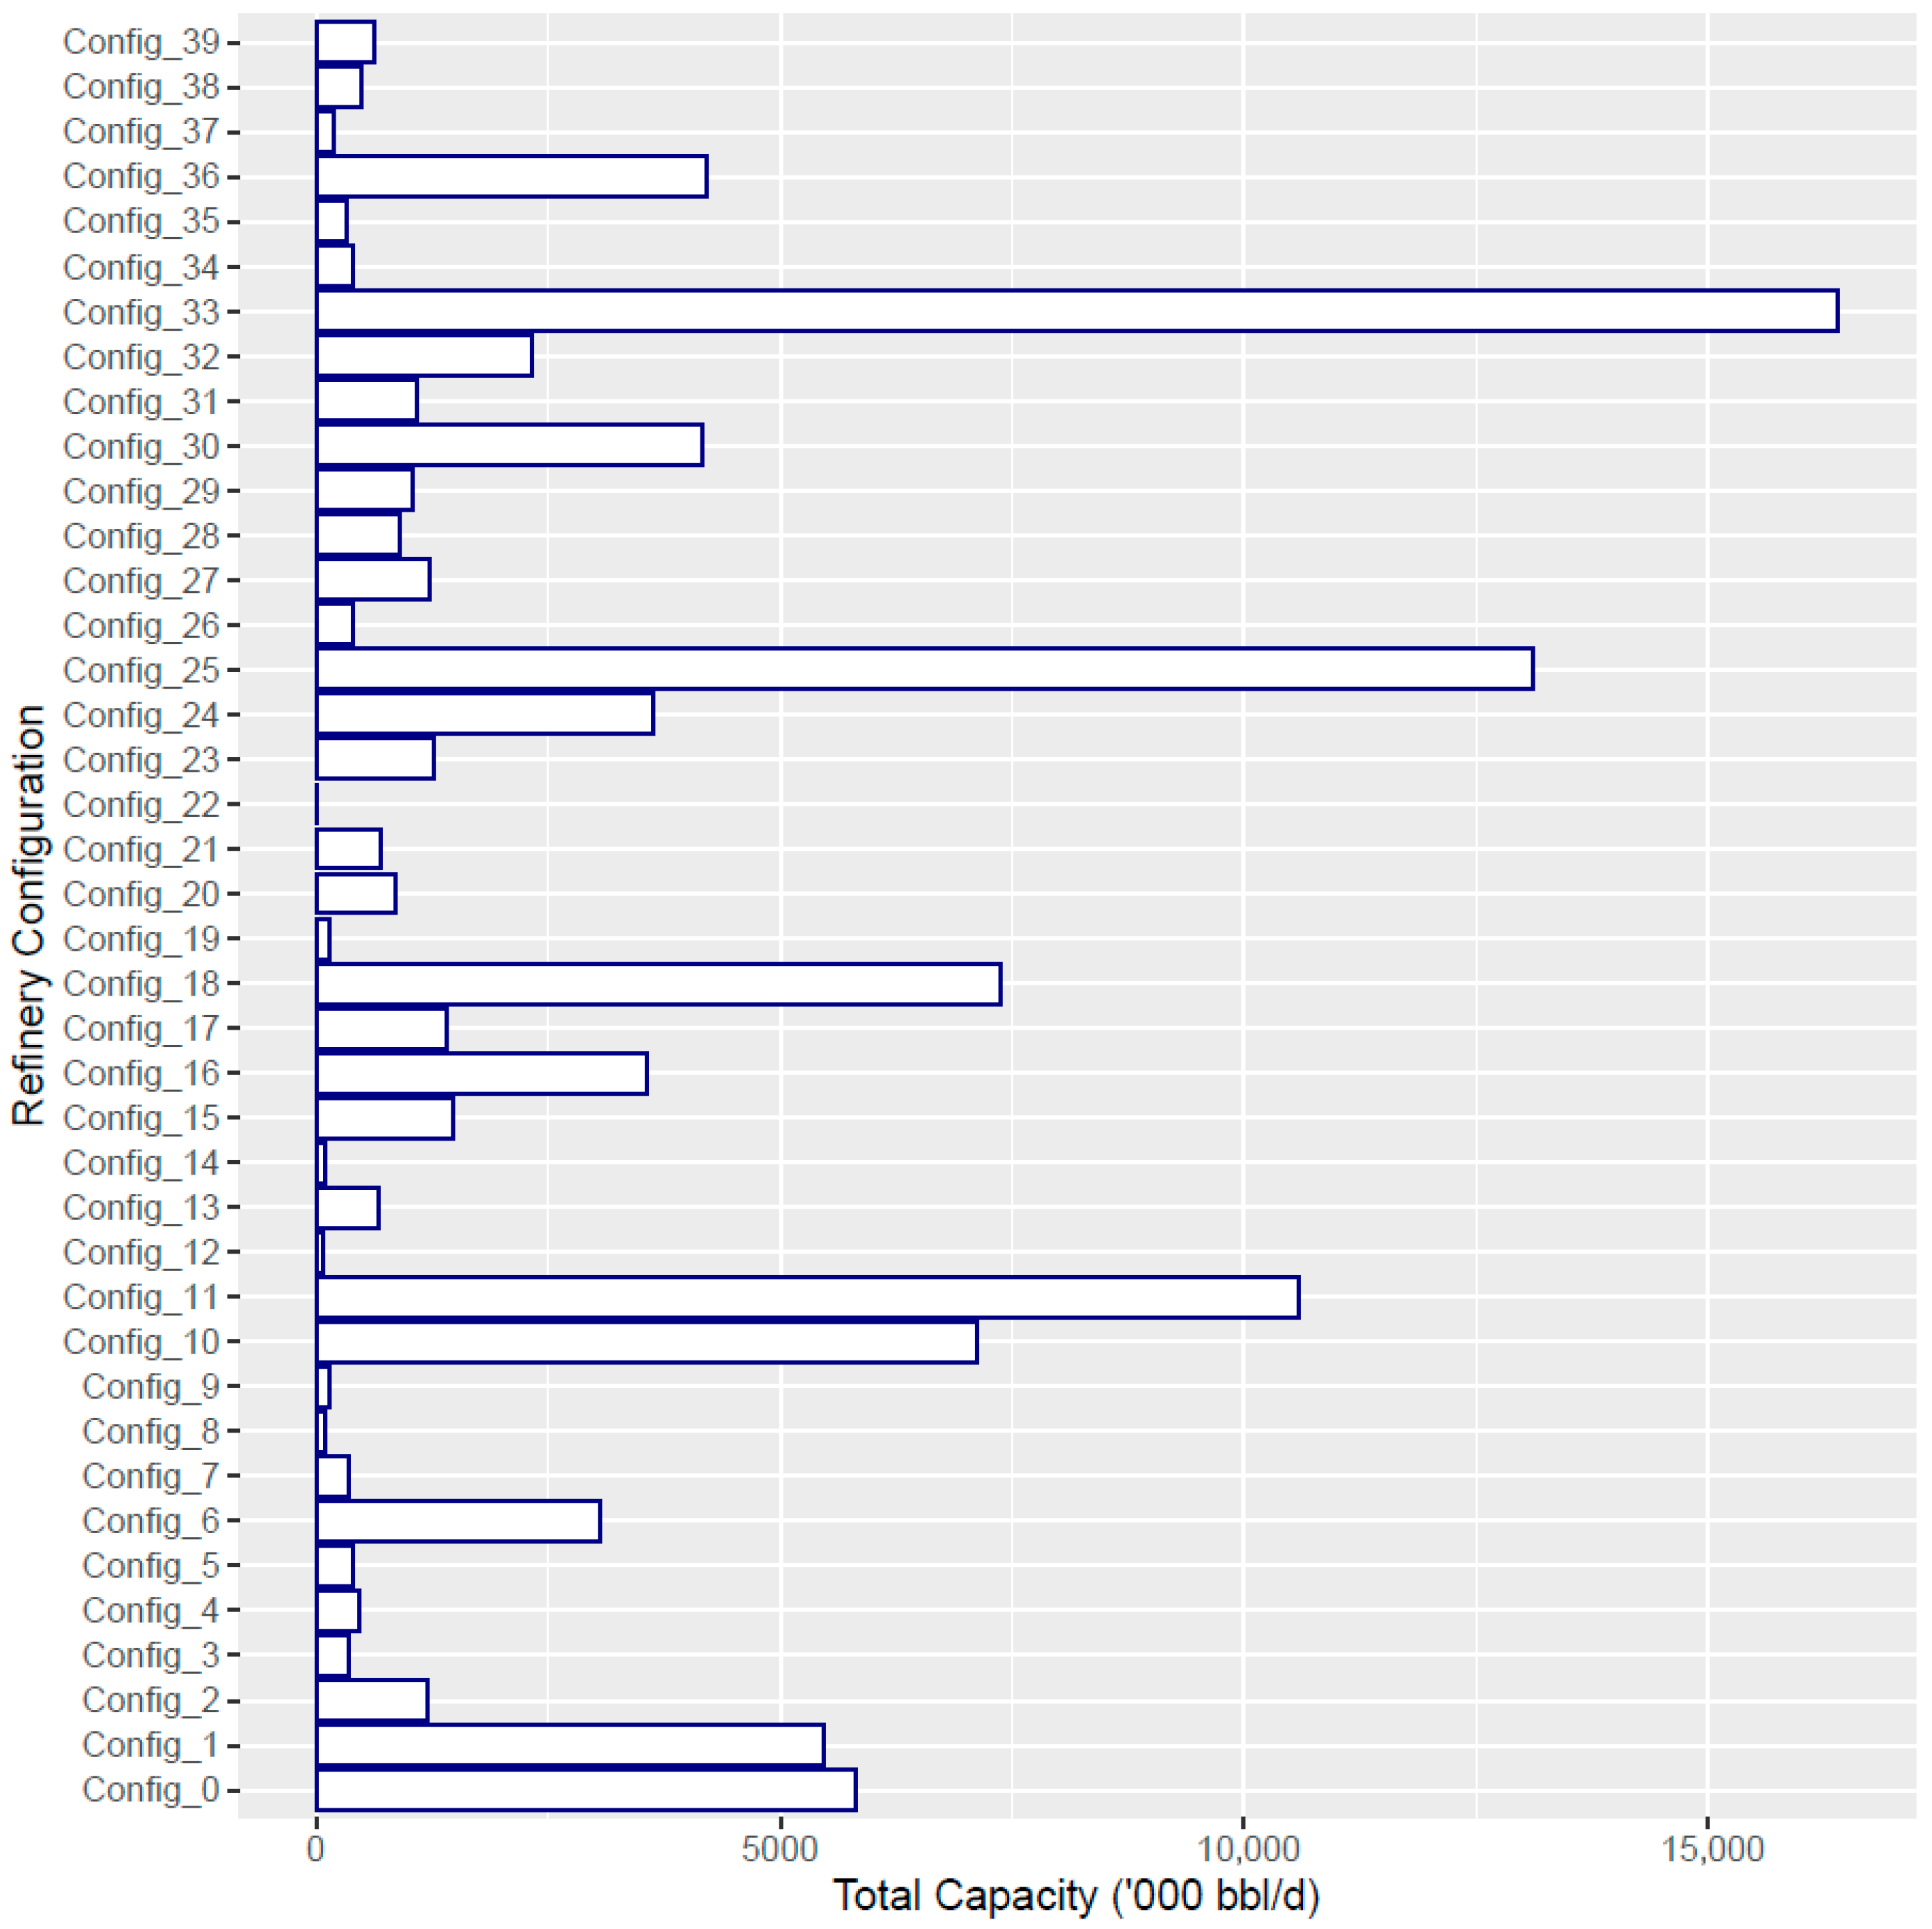
The Gulf Cooperation Council (GCC) countries are among the top producers of crude oil products globally. The GCC comprises Bahrain, Qatar, Oman, Kuwait, the UAE, and Saudi Arabia. There are about 26 refineries in the GCC, of which six are condensate splitters, with a combined capacity of around 6 million barrels per day. As presented in the previous section on identification of refinery configurations, it was demonstrated that global refinery designs range from very simple to complex configurations—categorized on the ascending complexity scale of 0 to 39, where configuration 39 is the most complex deep conversion refinery design. GCC refineries comprise configurations 0, 1, 6, 7, 10, 16, 24, 30, 33, and 36, as illustrated in
Table 4 with their respective total capacities in each country.
Due to the variety of refinery design compositions within each country in the region, the yield of petrochemical feedstocks can vary across countries and even facilities. In light of this, it can be useful to understand the operational and technical limits of petrochemical feedstock supply from all refineries in the region. For this purpose, two case studies are considered to benchmark the performance of each GCC refinery using, on the one hand, the average operating conditions of all global refineries of similar design, and on the other hand, the historical limits of the operational parameters as determined from the world refinery database. Such operational conditions are incorporated into the mathematical optimization problem formulation as discussed below.
The DE algorithm poses the objective function of the optimization task as a minimization problem. In this case, the objective is to maximize the yield of petrochemical feedstocks comprising liquified petroleum gas (LPG) and finished naphtha. Consequently, the objective value (
) is cast and computed as a negation of the objective criterion
which is to be maximized in the DE minimization problem formulation.
The objective criterion can also be expressed in terms of the properties to optimize (
) as,
This function is real-valued and represents the total volume of petrochemical feedstocks produced, as predicted by the machine learning model. The objective function is subjected to two different constraints representing the two benchmarking approaches investigated in this paper. However, a generalized form of the optimization constraints can be expressed as follows:
where
and
are equality and inequality constraints representing historical crude flow conditions for the various types of crude oil qualities, at various geographical coverage levels of national, regional, or global refining landscapes. For each refinery configuration, the design capacity limits are also specified based on real industry data. The geographical coverage determines memberships of the sets
,
,
, and
, according to actual refinery data reported at the resolution (
) of focus (i.e., local, national or regional levels) for analysis. Supersets
and
cover all constraints that enable benchmarking of individual refinery performance by the global best practices of other refineries of the same or similar design. Parameters of the constraint equations are obtained from the historical information in the refinery database. In the following sections, the specific constraints pertaining to each case study are presented, and their corresponding results are briefly discussed.
4.1. Case Study 1: Benchmarking Refinery Performance with Average Historical Operating Data
In this case, optimization constraint variables are bounded by their historical average values aggregated globally for each type of refinery design. Considering the sets of global refinery plants—each denoted by a unique facility name (
) and plant design configuration (
)—the constraints to specify in this case include those on production capacities, crude oil feed diets, and nonnegative feedstock volumes, which are aggregated for each refinery configuration and averaged over a historical operating period. Each constraint is expressed in terms of the predictors as follows:
where
is the capacity of the refinery plant processing crude oil diet consisting of oil types
during the time period
. For each of the crude oil types processed, the feed volume is bounded by the average historical minimum and maximum volumes evaluated across a set of historical time periods (
) for plants of configuration
which are found in locations situated in country
, as expressed in Equations (24) through (26). The cardinality operator (
) computes the memberships of
and
.
4.2. Case Study 2: Benchmarking Refinery Performance with the Limits of Historical Operating Data
In this case, optimization constraint variables are bounded by their historical limit values reported for the marginal refinery among all refineries having the same type of refinery design. For the same groups of global refinery plants, Equation (23) above is retained, but the rest of the constraints to specify in this case include those on the historical limits of crude oil feed diets and nonnegative feedstock volumes for each plant design configuration over the operating period of interest, applied across all global refineries of the same configuration. Therefore, the bounds on predictor variables become:
Unlike in the first case study, the limits of the predictor variables represent the evaluated absolute minimum and maximum historical operating values for the processed crude diets across global refineries that have the same plant design configuration .
5. Results and Discussion
The mathematical formulation of the optimal petrochemical feedstock yields of GCC refineries under the two case studies presented above is implemented in the integrated model. In the first case study, crude oil feedstock blends are specified by the global average historical minimum and maximum feed compositions of each oil type supplied to refineries with the same design configuration as in a GCC country under consideration (as expressed in Equations (24) and (25)). Consequently, in this case, the lower bounds will tend to be always greater than zero and the upper bounds are always less than unity (so far as at least one of the global refineries on record, having the same configuration, has processed the same type of crude oil over the embedded history of analysis), which may not reflect actual operational conditions as can be observed in the baseline operational performance.
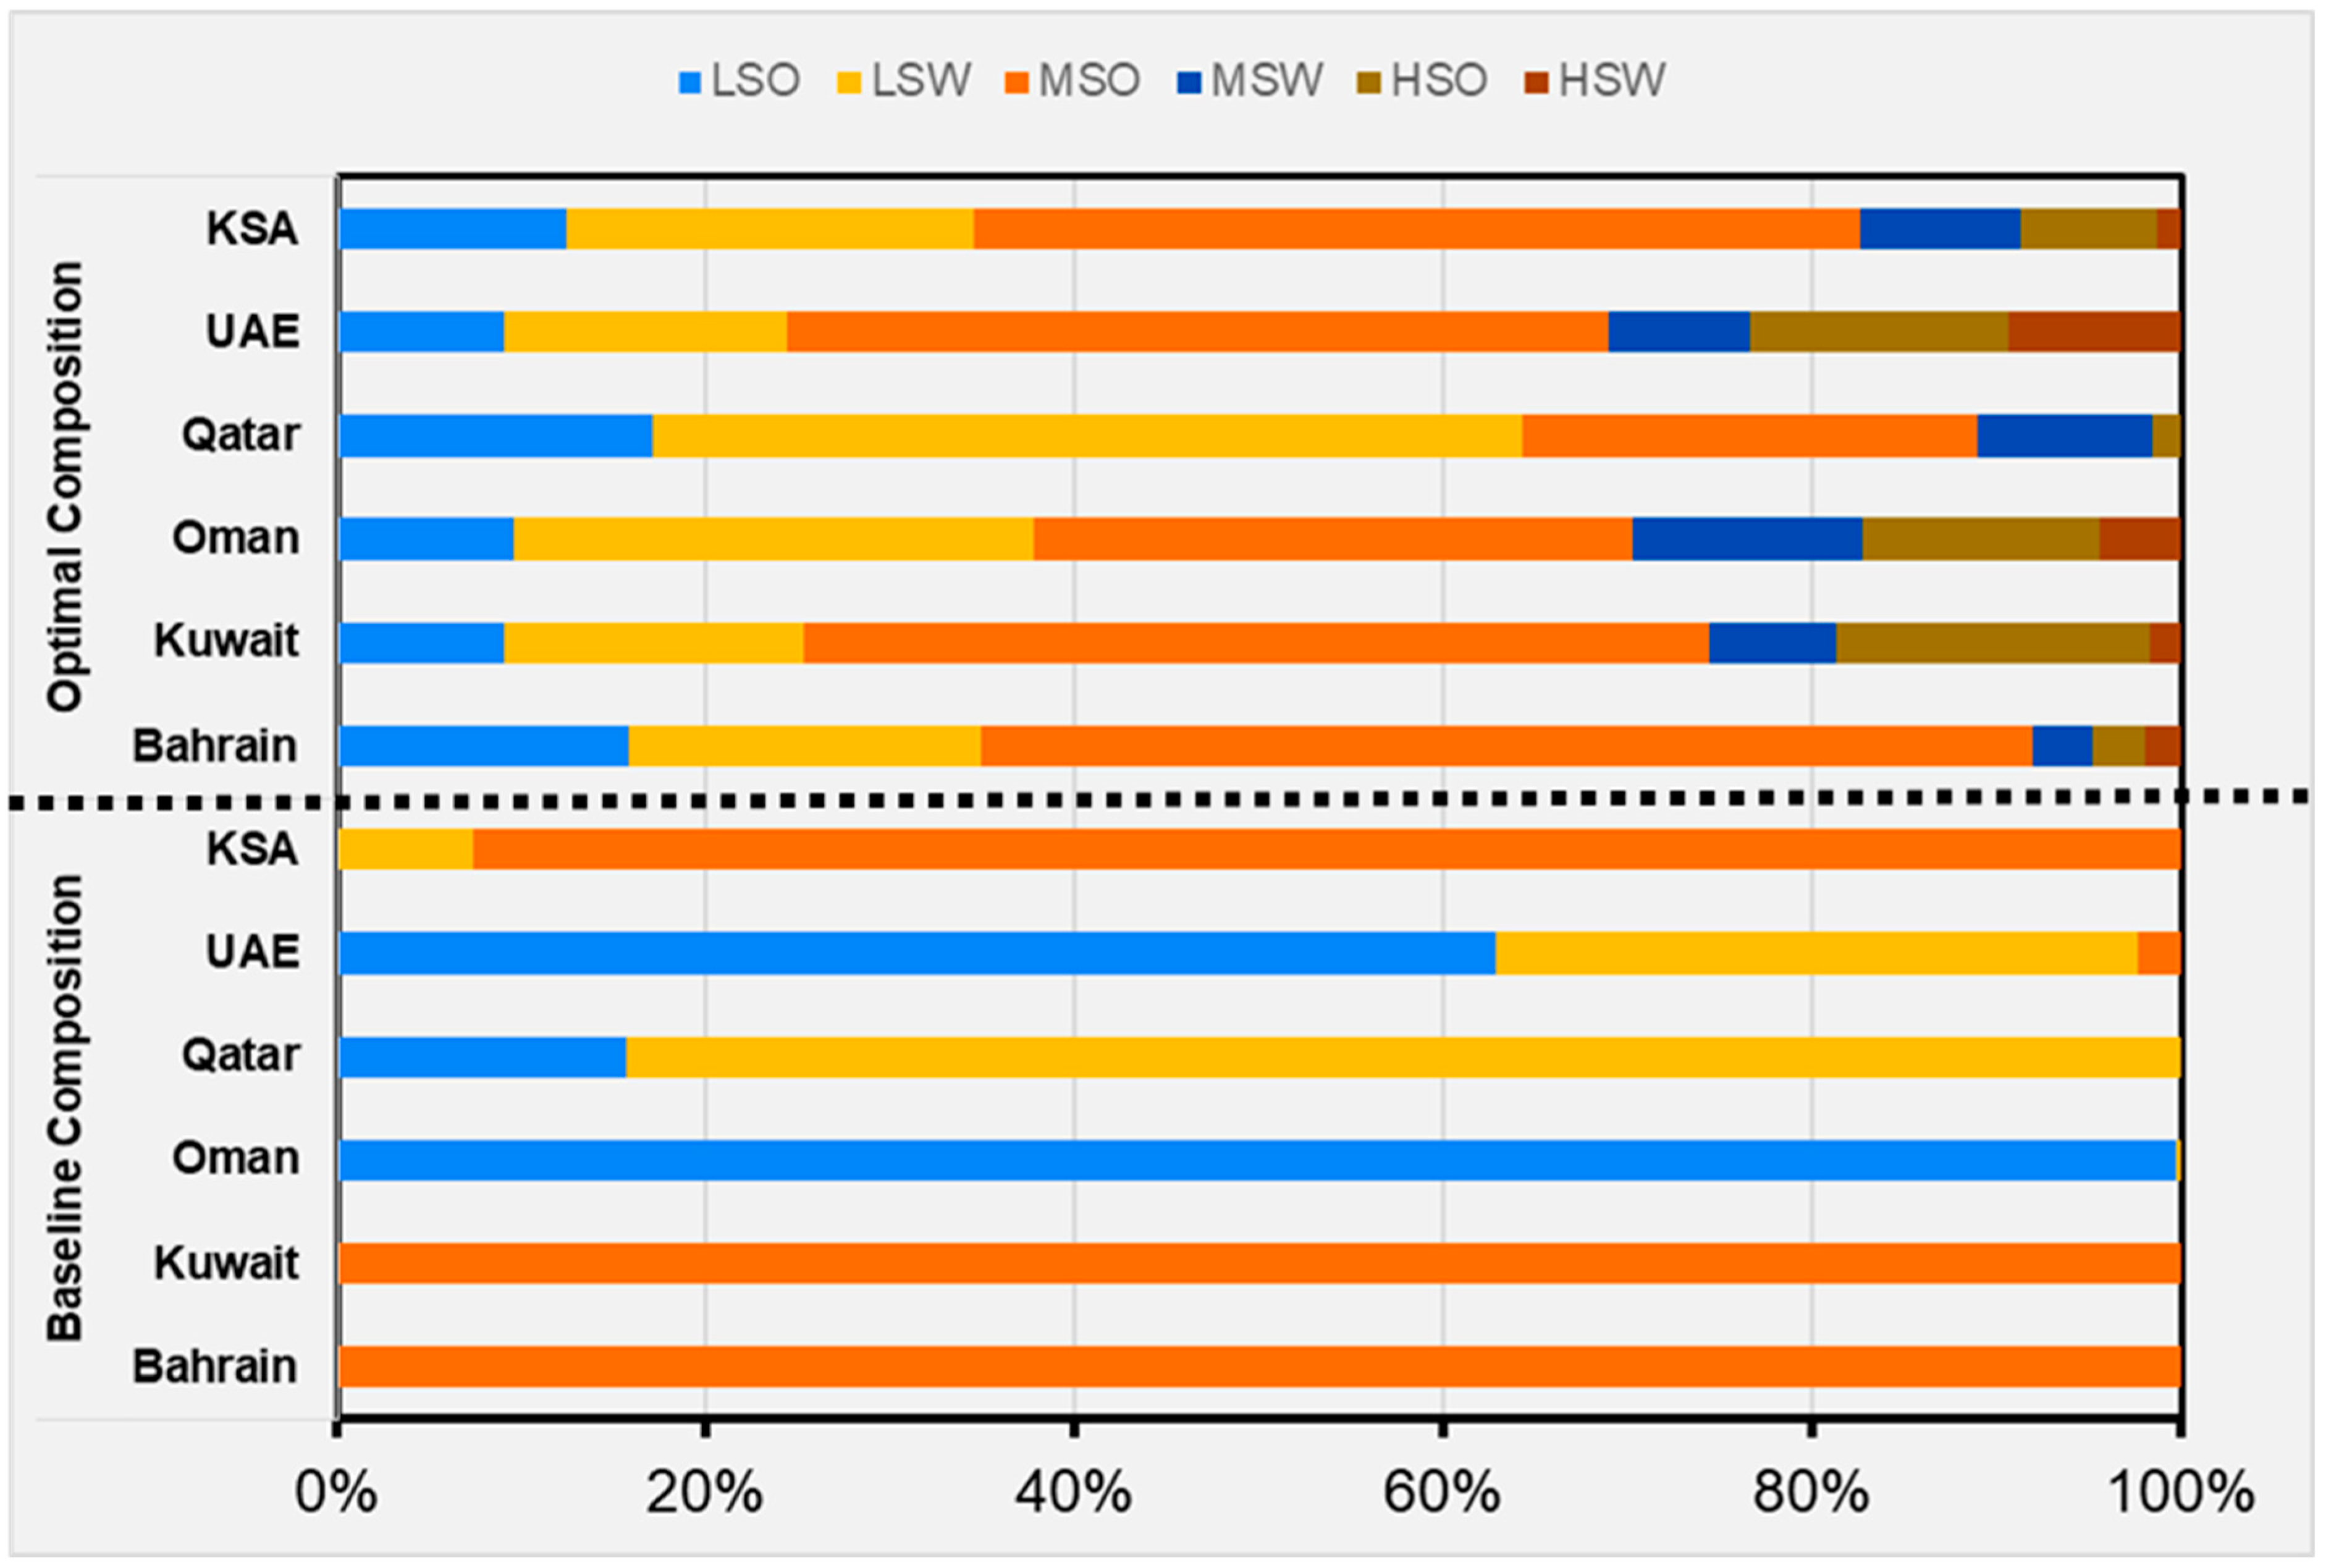
Figure 7 compares the baseline and optimal feedstock blends for each GCC country. The baseline compositions represent historical crude diets of the refineries in each country. For all the countries, baseline crude feed is composed of between 1 and 3 choices of crude oil types (qualities). This is understandable given that oil-producing countries are likely to tailor their refinery selection and operation to ingest locally sourced feedstocks. However, benchmarking local performance with global average feed compositions results in a more diverse crude diet, the components of which may not all be conveniently made available locally.
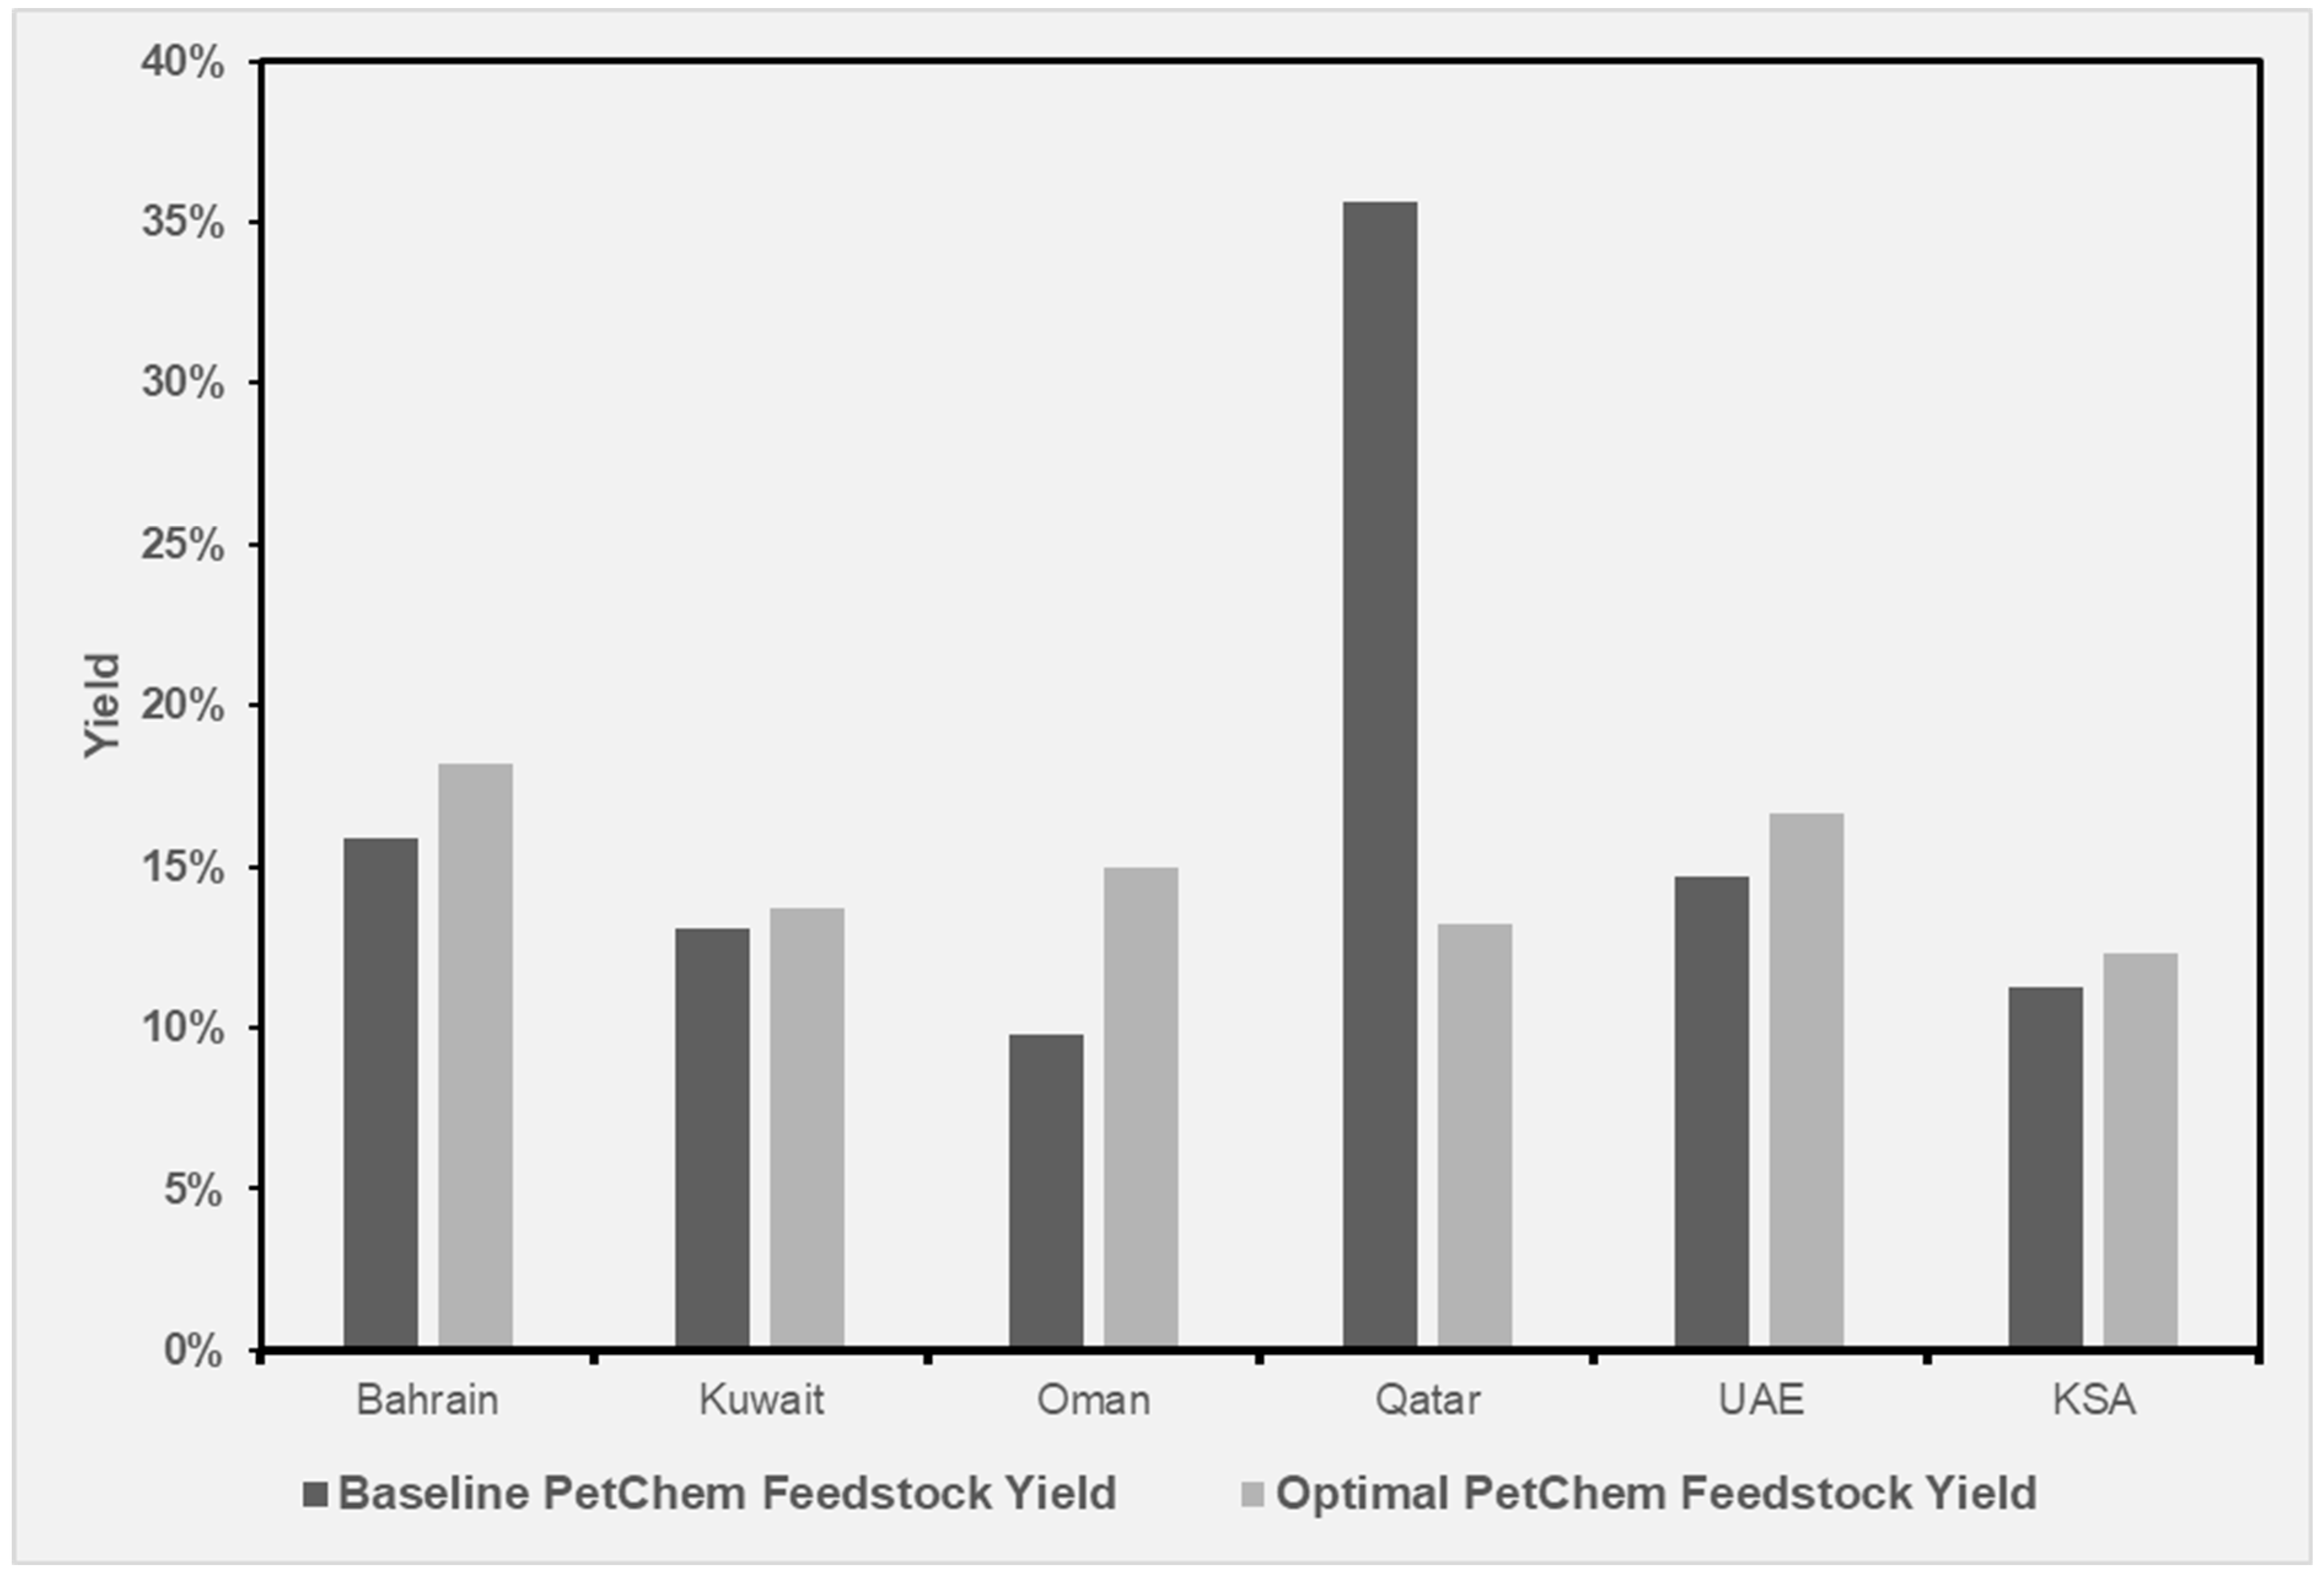
Figure 8 also indicates that this may be counterproductive, particularly for facilities whose baseline performance has been tuned to maximize petrochemical feedstock yields, such as Qatar in this case. Therefore, imposing the constraints in Equations (24) and (25) can alter the solution space in a manner that generates suboptimal crude feed blending guidance for enhancing petrochemical feedstock yields. In other words, Qatar’s refineries seem to have been tuned to locally optimized crude diets; thus, imposing global average crude blend constraints (as in Case Study 1) alters feed flexibility, which can reduce achievable petrochemical yield.
Alternatively, the bounds on crude feed blend compositions can be specified based on the absolute limits of their historical operating values as represented in Equations (20) and (21) for the second case study.
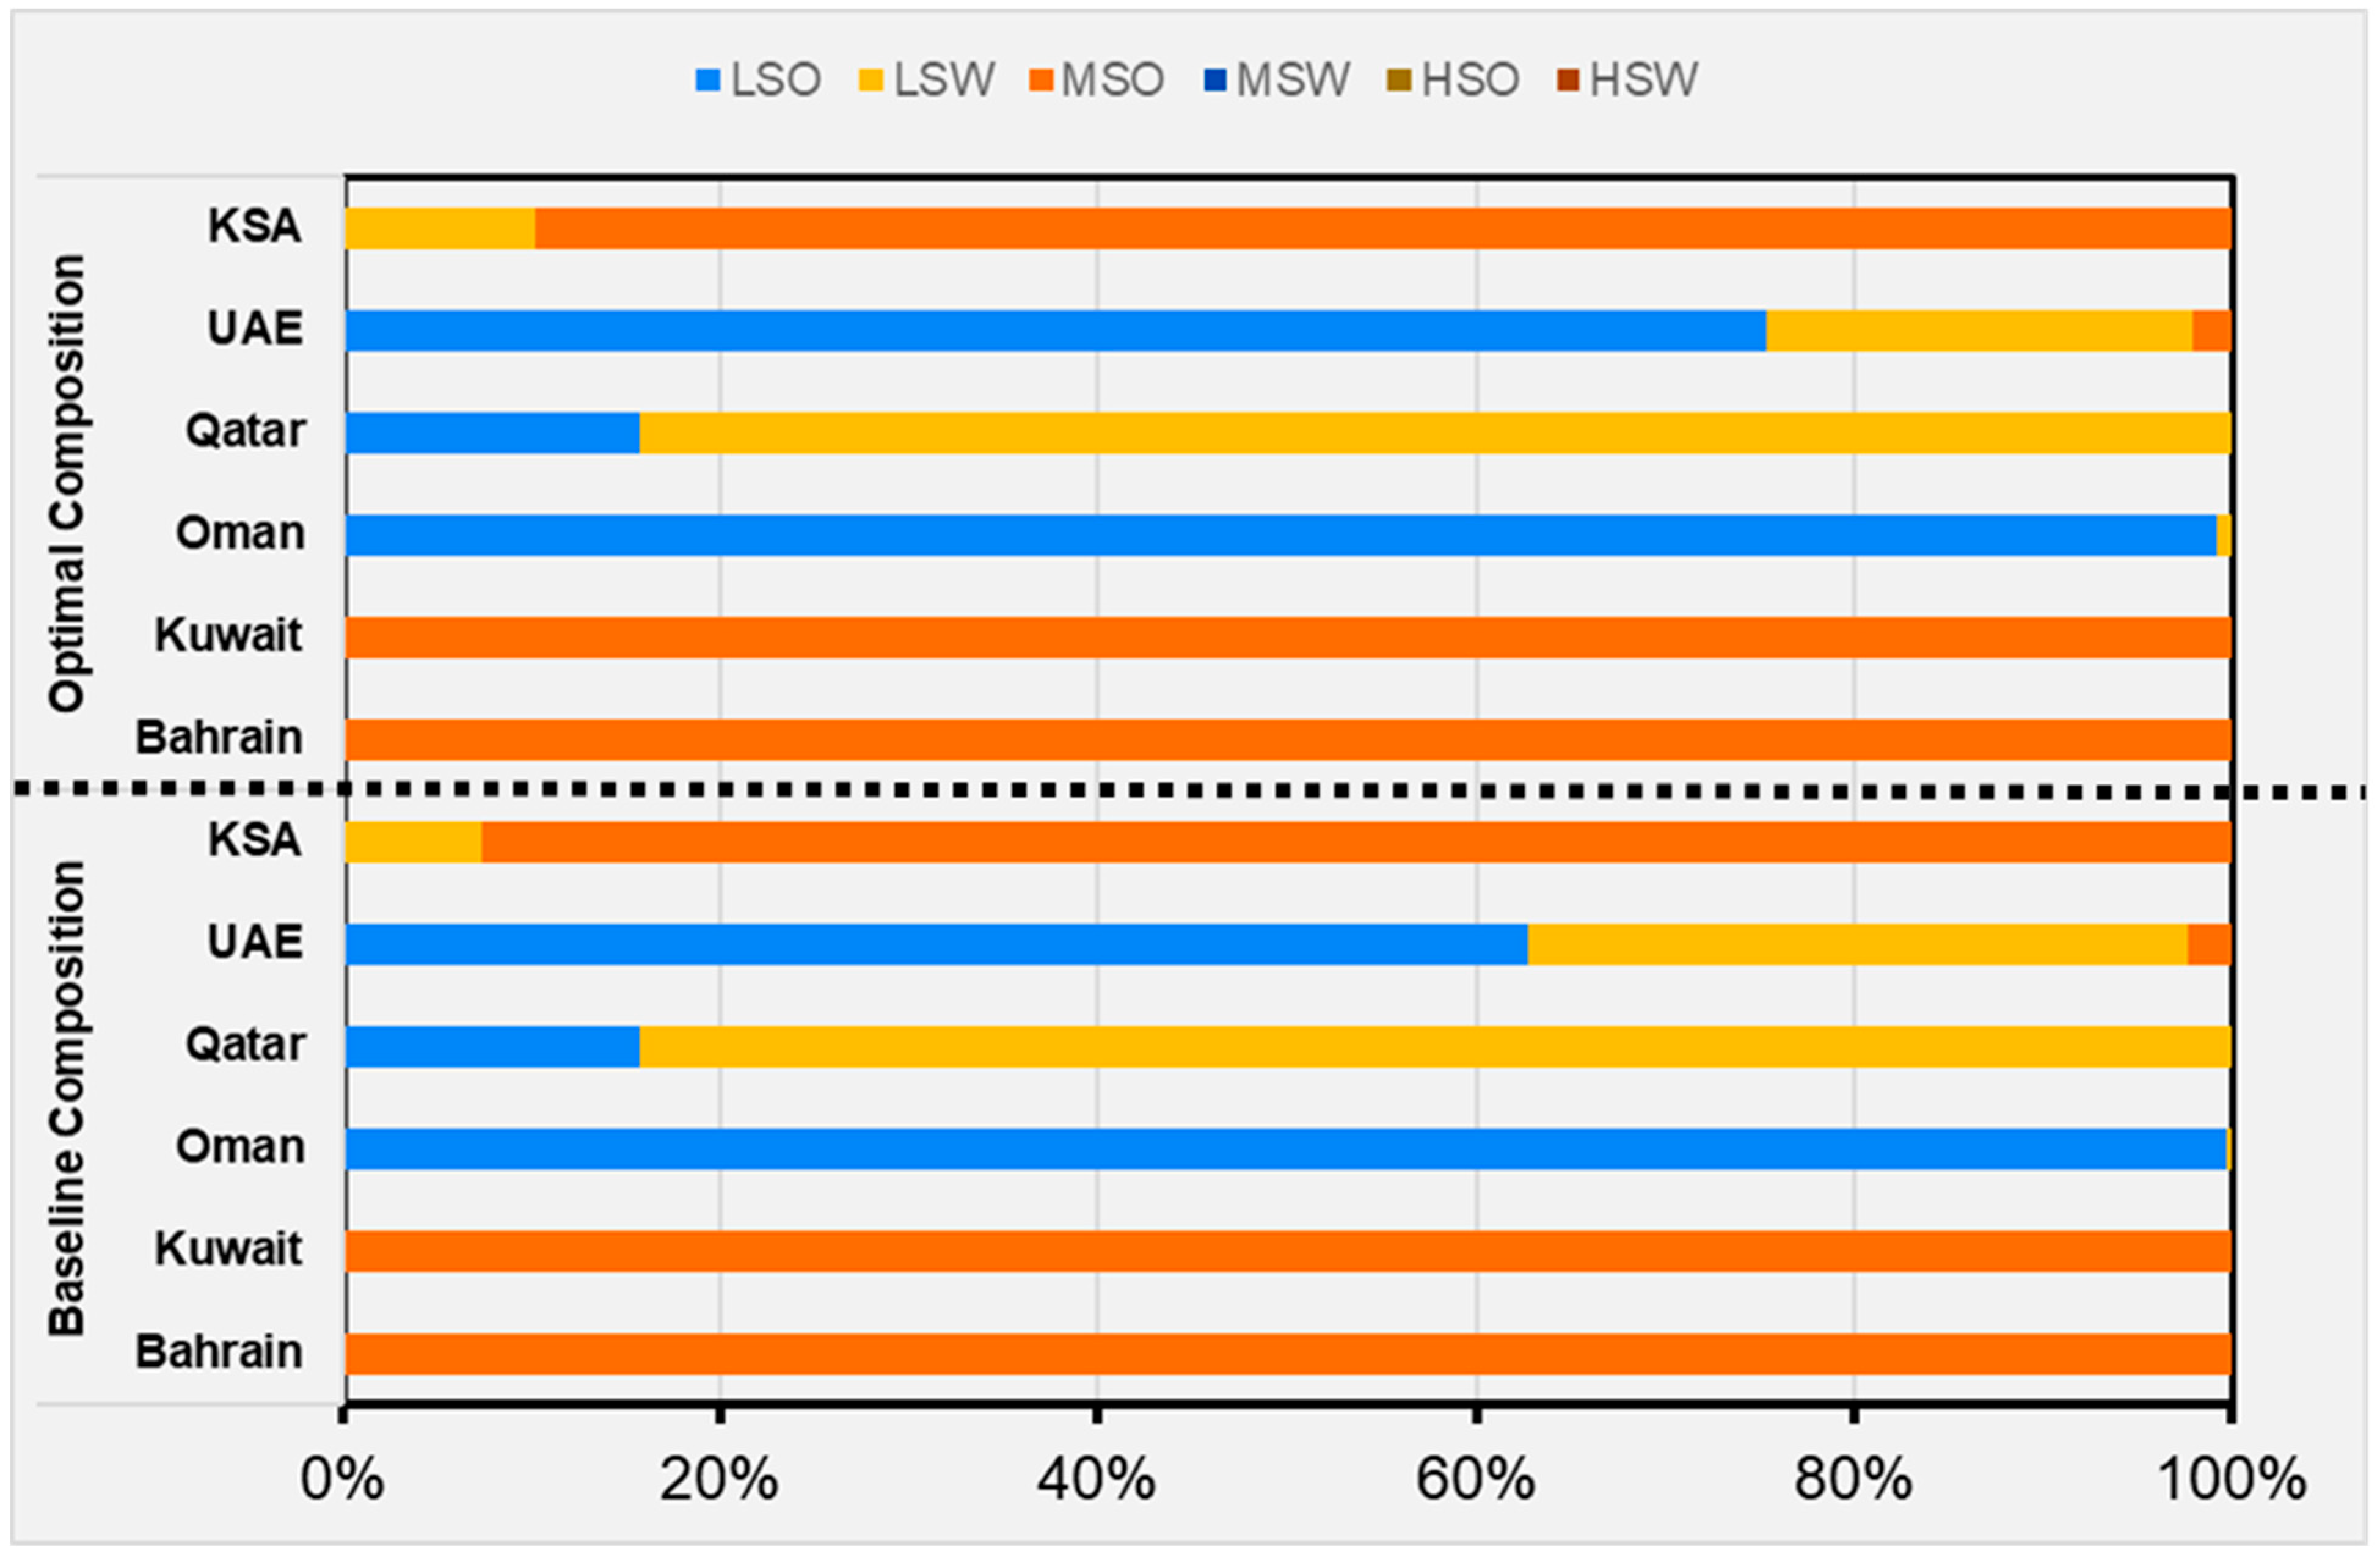
Figure 9 shows the baseline and optimal crude feed compositions for the refineries in each GCC country. Although the baseline and optimal compositions are similar in terms of the variety of crude oil qualities in the diet, the actual compositions of processed volumes are not the same in countries like KSA, UAE, Qatar, and Oman. For Bahrain, Kuwait, and Oman, the baseline and optimal crude diets are the same or very similar, but the call on capacity (utilization rate) is lower in the optimal case, even though the petrochemical feedstock yields and volumes are higher than for the baseline operation.
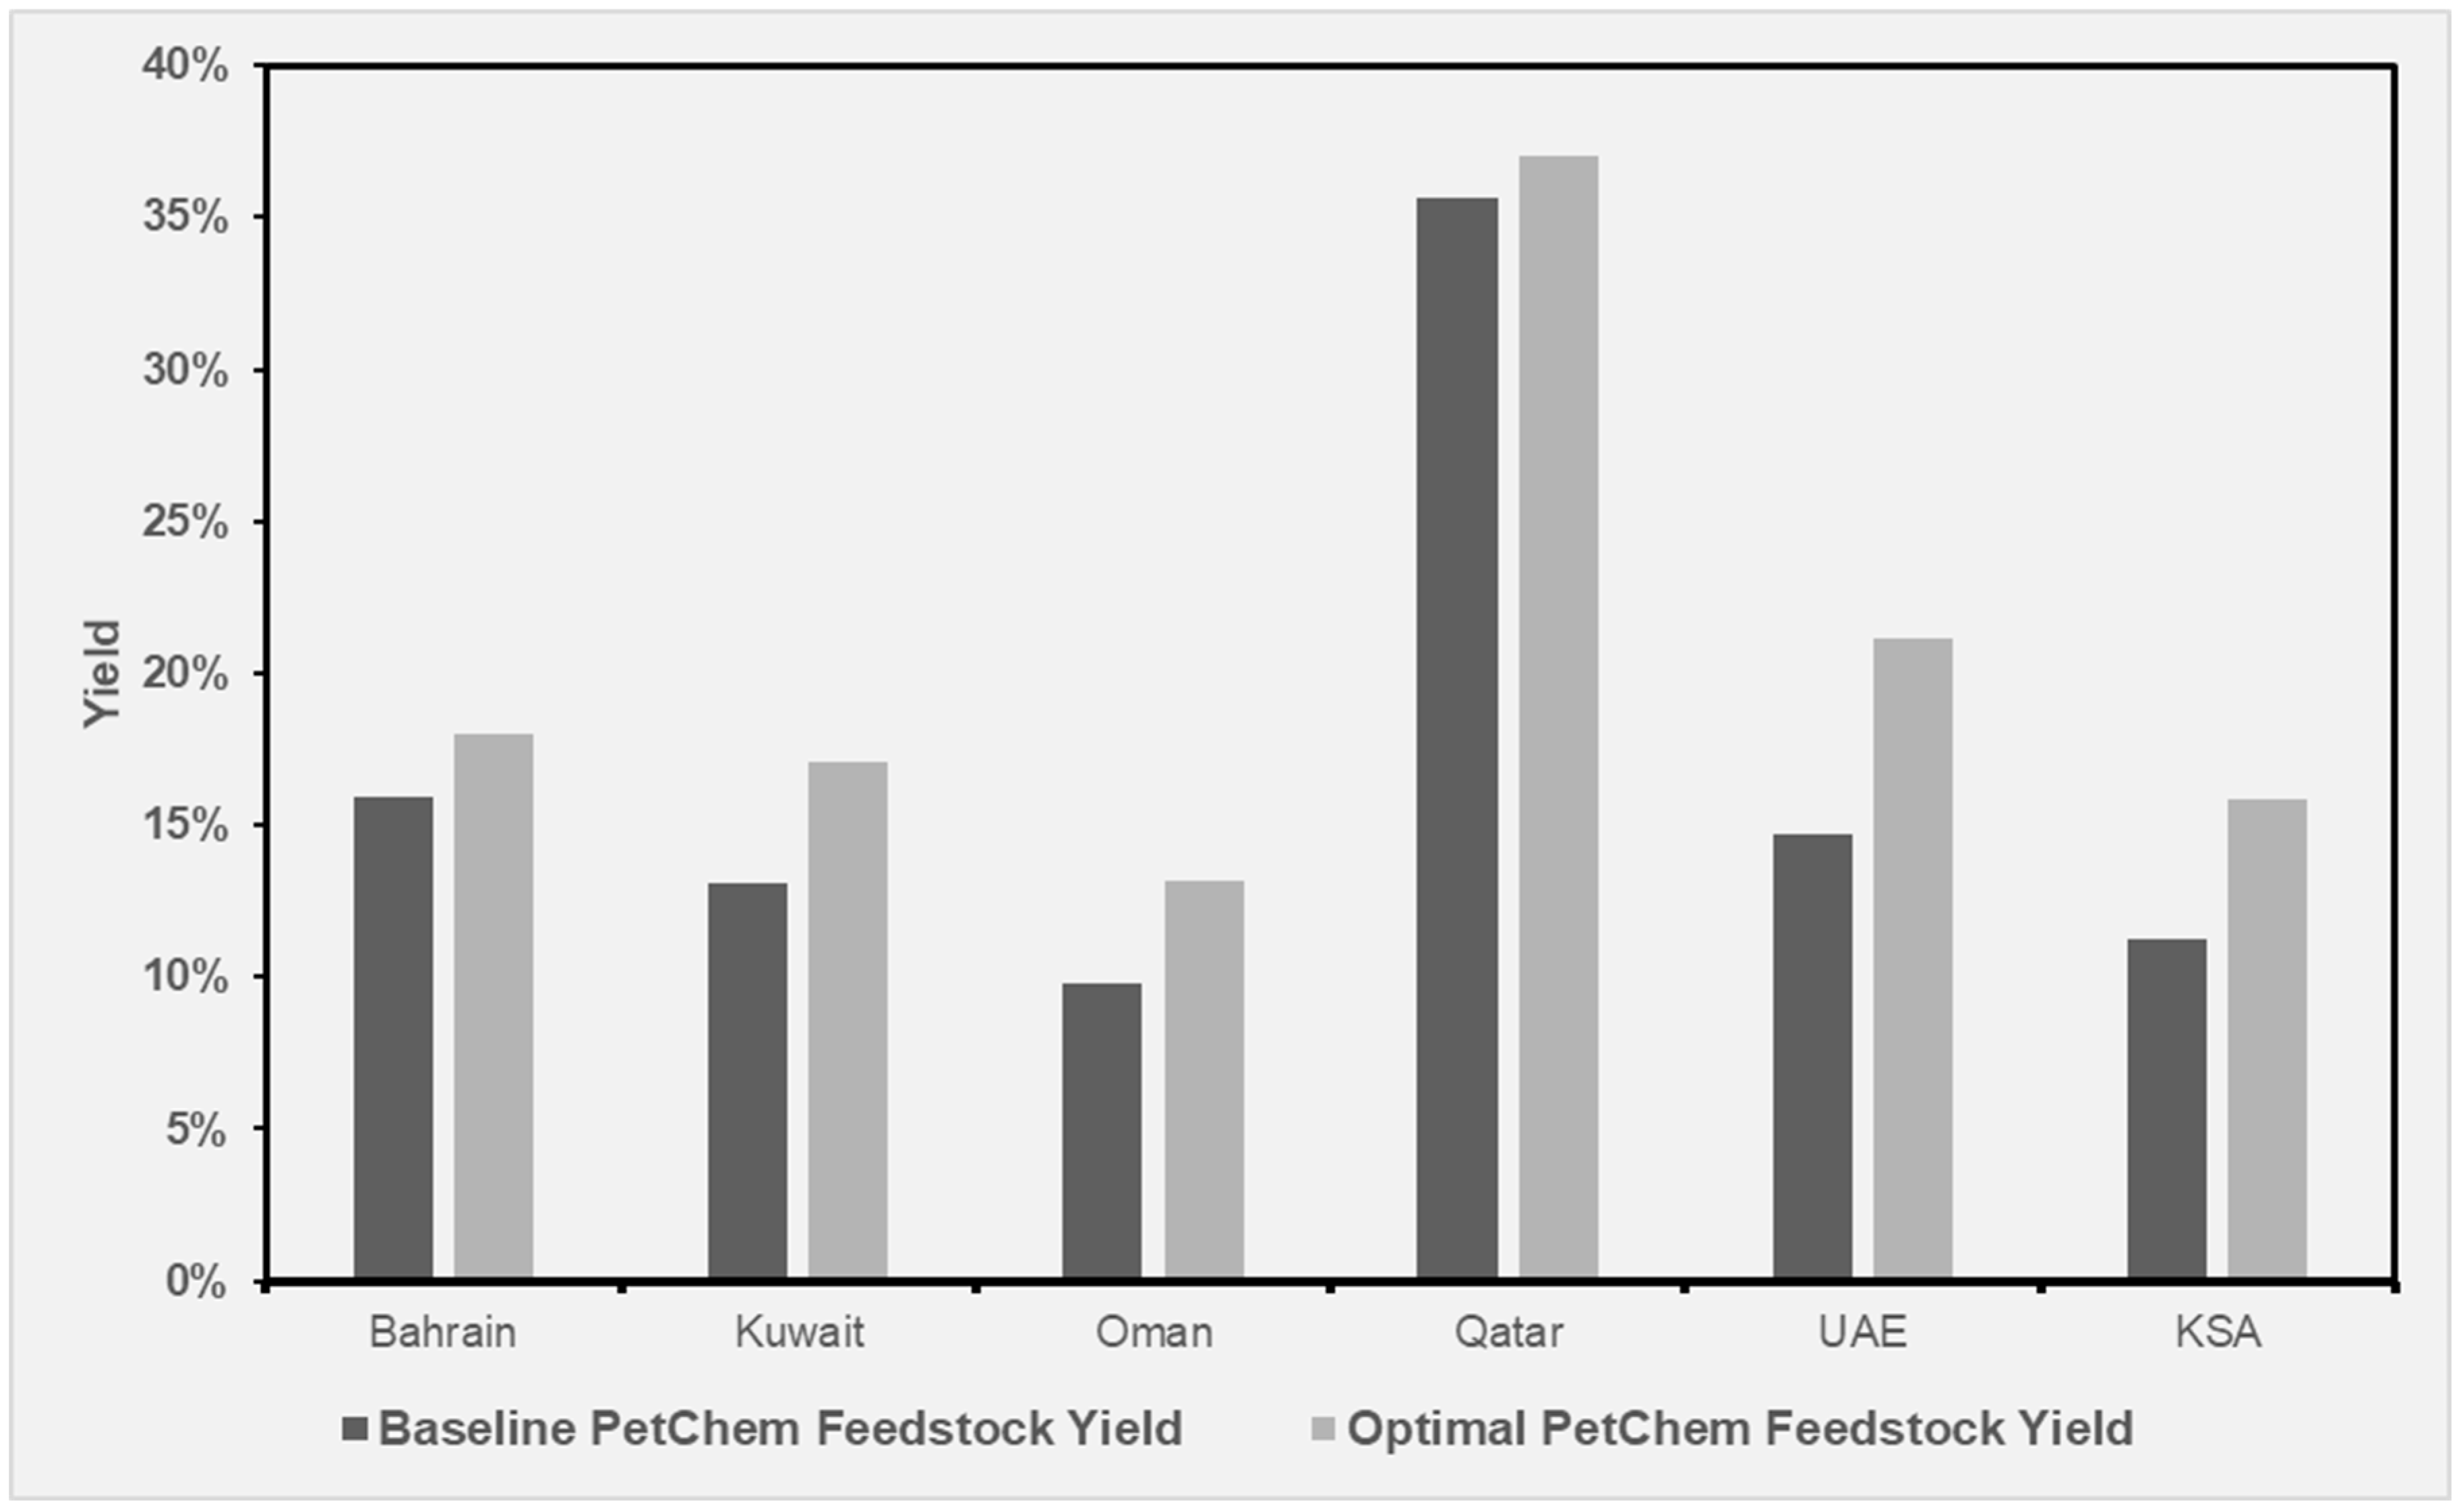
Figure 10 compares the yields for this case study across the GCC countries. In all the countries, optimal petrochemical feedstock yields are higher than the corresponding baseline values, unlike those in the first case study, where the yield for Qatar was lower. It can be observed that the UAE, KSA and Kuwait have the highest potential to improve petrochemical feedstock yields from the corresponding baselines of 15%, 11%, and 13% to optimal limits of 21%, 16%, and 17%, respectively, using the current refining configurations in the countries. Of these three countries, the UAE has the maximum petrochemical feedstock yield improvement opportunity of 6% relative to their baseline, whereas Qatar has the lowest at around 1%, although having the highest yield of about 37%, which is predominantly naphtha (87%). Consequently, under existing conventional refining configurations in the region, the scope for further improvement in petrochemical feedstock yields appears limited. Achieving the approximately 80% petrochemical yield targets articulated by several GCC operators would therefore require structural transformation beyond conventional operational optimization.
Apart from the petrochemical yield limitations of current refining technology, tuning existing refineries to maximize the yields can also result in major product volume shrinkages, particularly for refineries with low baseline petrochemical yields, since such refineries are most likely to have been tuned/optimized by design and operation to maximize yields of other products instead of petrochemicals.
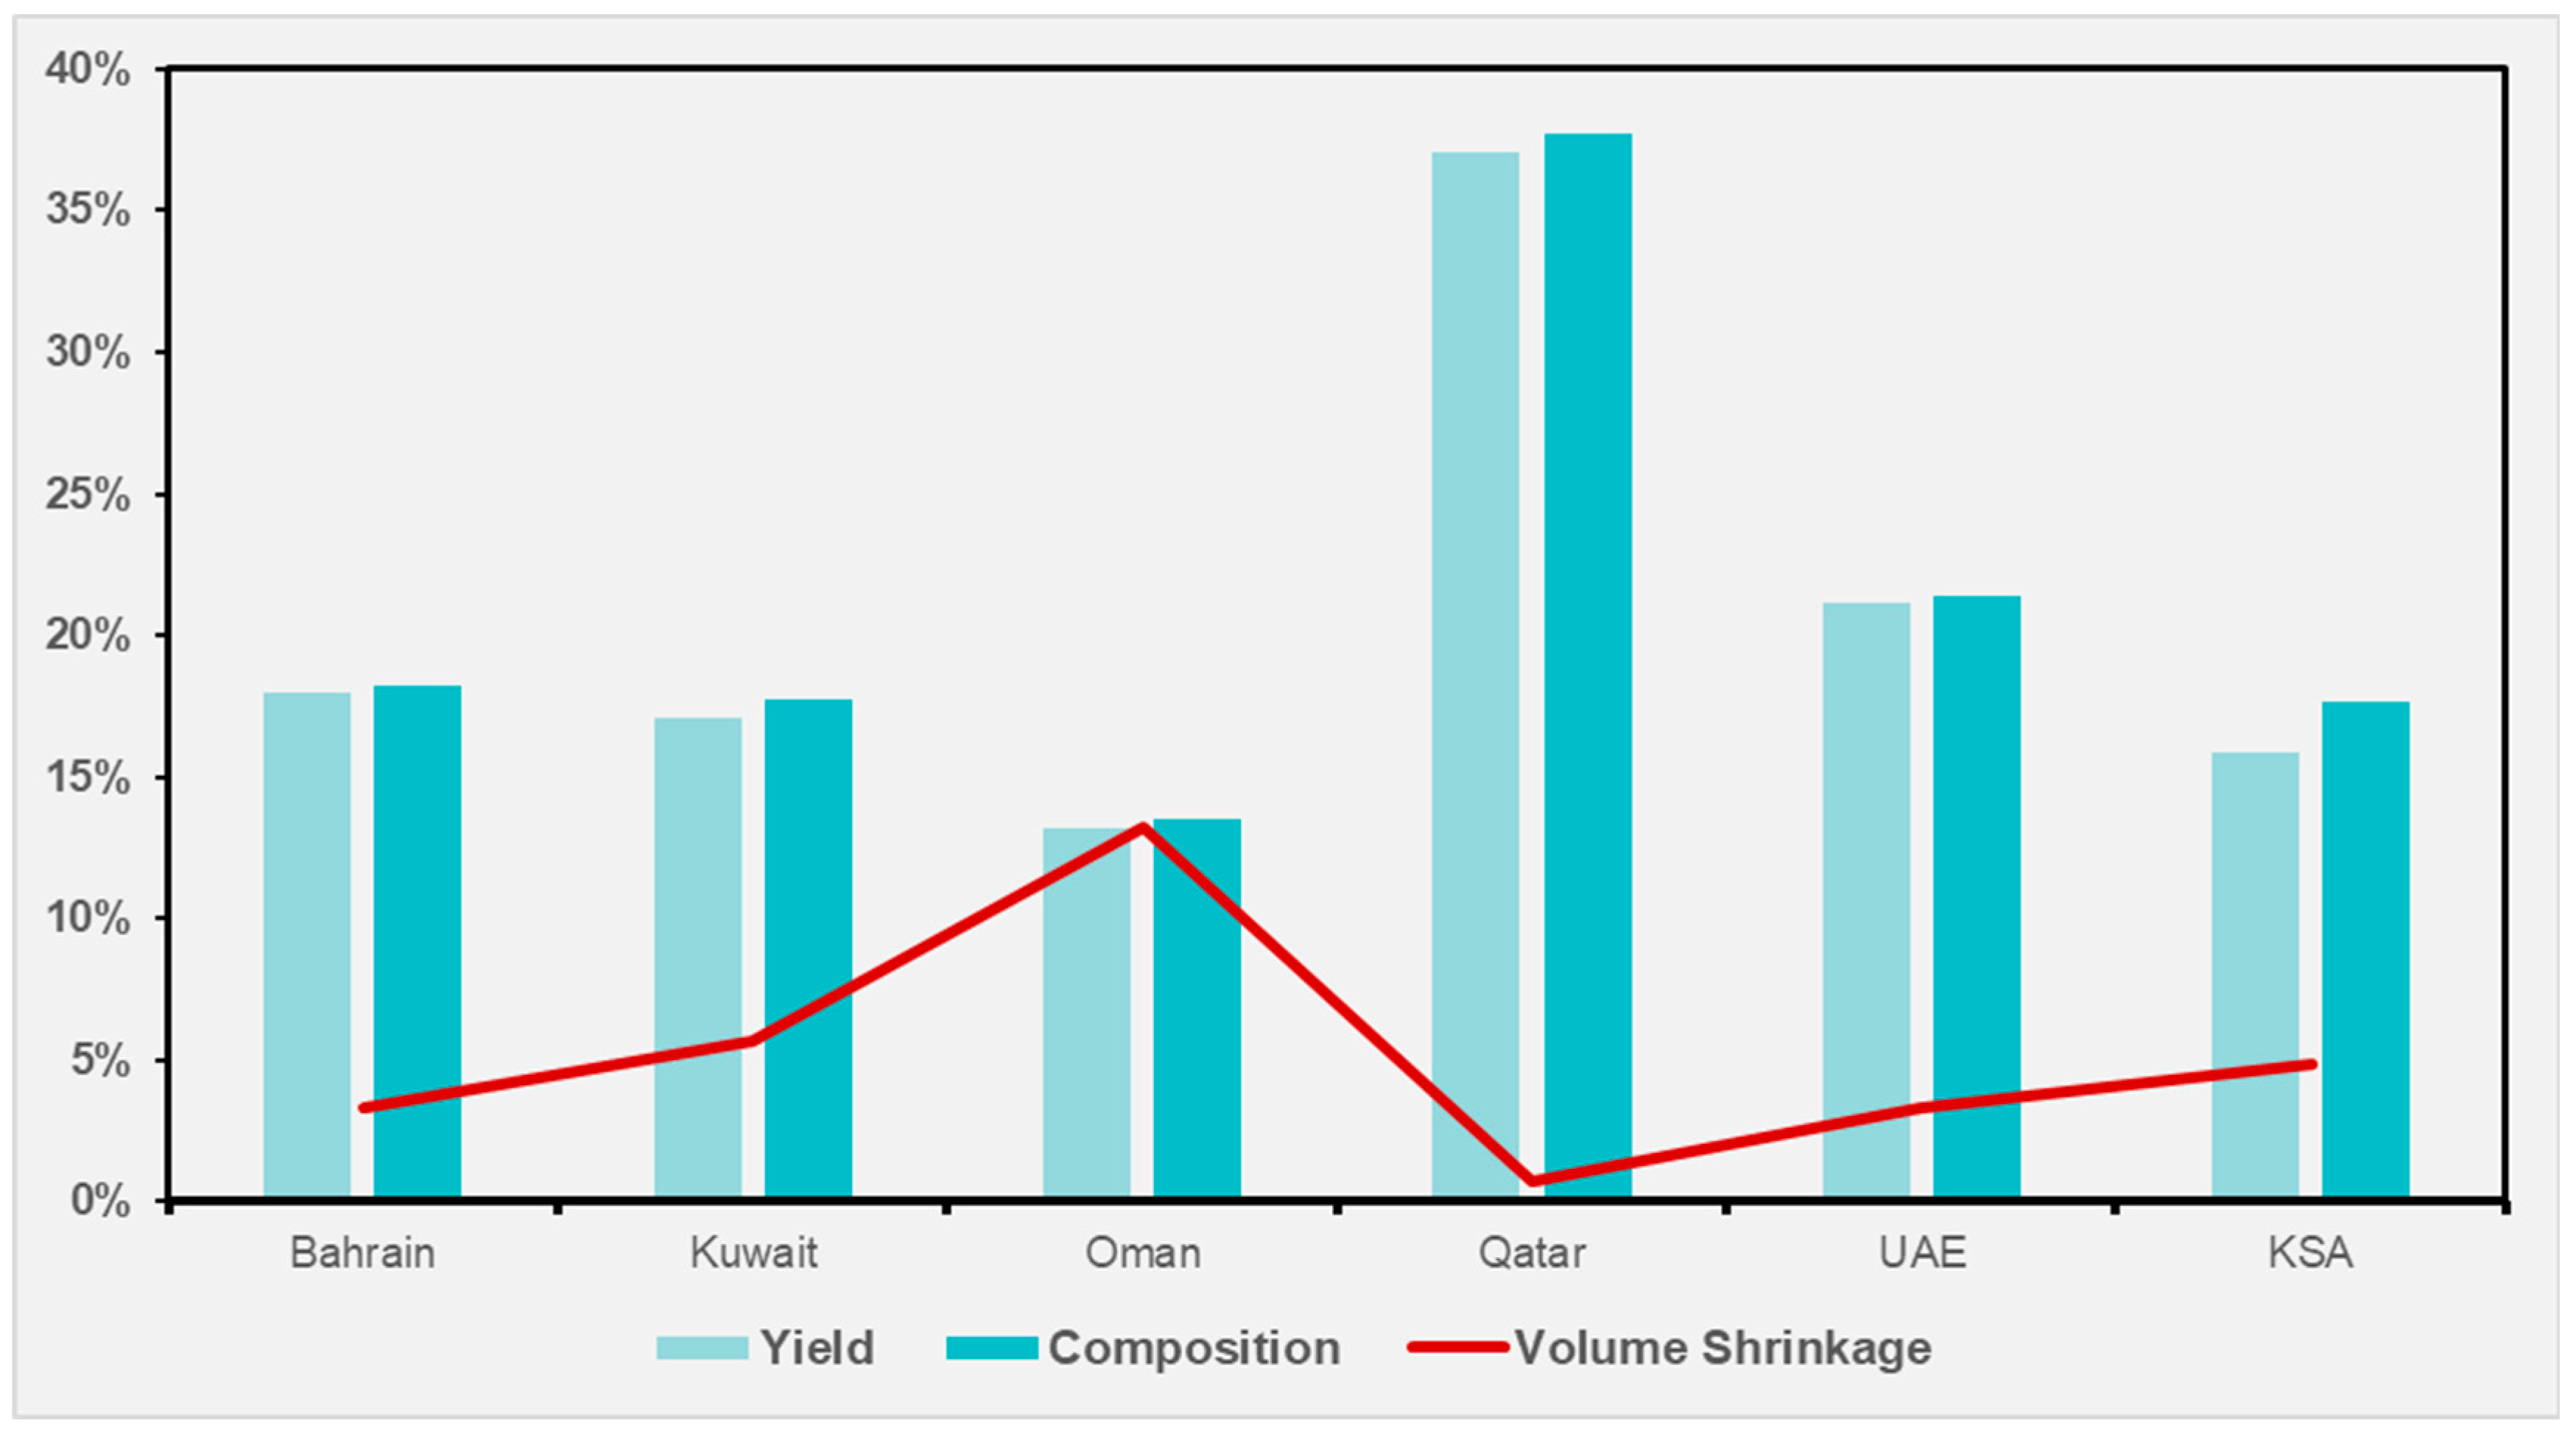
Figure 11 compares the relationships among product volume shrinkage in the refineries to petrochemical feedstock yields and product slate compositions. Qatar, with the biggest baseline petrochemical feedstock yield, posts the smallest product volume shrinkage, 1% below baseline product yields after petrochemical feedstock optimization, whereas Oman, with the smallest baseline yield, experiences the biggest product volume shrinkage of about 13%.
Since volume shrinkage was calculated as the difference in total product volumes between the optimized and baseline operational results, it is useful to understand the plausible reasons for the observed product volume shrinkage. Further analyses of the results are performed by investigating the calls on capacity, total product volumes, and yields of other products, which can be categorized as either lighter or heavier hydrocarbons, such as gasoline and heavy fuel oil, respectively. In comparing the baseline and optimized product yields, only slight differences are observed in the volumes of other products, whether the lighter or heavier ones. However, lower capacity utilization while optimizing for higher volumes of petrochemical feedstocks is obtained in optimized results. For the refineries in Qatar, baseline capacity call is 384 kb/d for a total product volume of 373 kb/d, while the values for optimal petrochemical yields are, respectively, 379 and 370 kb/d. For Oman, the baseline values are 228 and 214 kb/d for total feed and product volumes, respectively. The optimized petrochemical feedstock yields entail a crude oil feedstock of 193 kb/d and a total product volume of 187 kb/d.
In summary, petrochemical feedstock yields depend on refinery design and operational attributes. In other words, the types of refinery configurations in the country, along with the diet of crude oil feedstocks and operating parameters, determine the refined product slates. Some combinations of refinery configuration, type of oil feedstock, capacity, and other operational variables will lead to the highest yields of petrochemical feedstocks, which can be unraveled if all global refineries were to be investigated in a similar manner. Consequently, there is a geographical variability in refinery petrochemicals yields due to differences in the suite of refinery designs and diets of oil feedstock. Therefore, refinery retrofit efforts must consider the impact of design alterations on the potential for the plant to remain viable in the evolving scenarios of a future global energy system. Understanding the maximum yields of petrochemical feedstocks from existing national, regional, or global refineries can improve decision-making regarding the best approaches to closing future gaps when transitioning from the current refining landscape. This would highlight retrofitting opportunities to sustainably transition from maximizing transportation fuel yields to capturing more value from the petrochemical value chain.
5.1. Economic Interpretation of Petrochemical Yield Improvements
To contextualize the operational significance of the observed yield improvements, the economic implications of a representative six percentage-point increase in petrochemical feedstock yield are estimated. Considering the case of the UAE, where the baseline petrochemical feedstock yield of approximately 15% increases to 21% under the optimized scenario. Given an aggregate refining capacity of approximately 1232 kb/d across configurations present in the UAE (
Table 4), a 6% increase corresponds to an incremental petrochemical feedstock volume of approximately 74 kb/d (27.0 million barrels per year). Assuming a conservative net margin differential of 10–20 USD per barrel between resulting petrochemical products and displaced fuel products, the incremental gross margin at 80% yield ranges between 216 and 432 million USD per year.
This estimate is illustrative and does not account for changes in operating costs, hydrogen demand, or capital expenditures required for sustained re-optimization. Nevertheless, it demonstrates that even single-digit percentage improvements in yield can translate into substantial revenue impacts at national refining scales. The economic magnitude reinforces the strategic importance of refinery configuration and operational flexibility in energy transition planning.
5.2. Sensitivity of Petrochemical Yield to Crude Diet Constraints
To evaluate the robustness of the optimization results, a sensitivity analysis was conducted by perturbing crude feed composition bounds within of the historical limits used in Case Study 2. Specifically, lower and upper bounds on crude grade proportions were relaxed and tightened symmetrically while maintaining feasibility constraints.
Results indicate that optimal petrochemical feedstock yields exhibit moderate elasticity with respect to crude diet flexibility. Across GCC configurations, a relaxation in crude composition bounds alters optimal petrochemical yields by approximately 0.5–1.2 percentage points, depending on refinery configuration. Configurations with deep conversion units (e.g., RH and coker) demonstrate lower sensitivity, reflecting structural upgrading capacity, whereas simpler configurations exhibit higher dependence on feedstock composition.
This sensitivity analysis suggests that while feedstock availability influences attainable petrochemical yields, structural configuration remains the dominant determinant of long-run yield potential.