Next Issue
Volume 13, September
Previous Issue
Volume 13, July


Informatics, Volume 13, Issue 8 (August 2026) – 17 articles
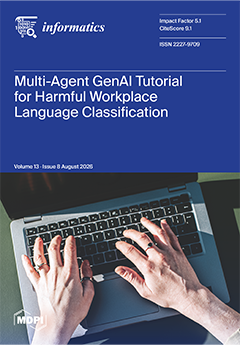
Cover Story (view full-size image): Given recent public and academic concerns on the safety of generative artificial intelligence (GenAI) applications, this work demonstrates how social scientists can use multi-agent GenAI to evaluate language-classification systems within a controlled sandbox environment. Using a workplace example, this work illustrates how synthetic data, automated labeling, model training, and performance evaluation can be integrated into a reproducible research pipeline. The tutorial serves as an educational pre-deployment validation space where appropriate governance considerations can be carefully evaluated. By combining accessible explanations, open-source code, and a fun practical example, the article provides a bridge between behavioral science and machine learning, helping social scientists participate in the evaluation of GenAI systems. View this paper
  • Issues are regarded as officially published after their release is announced to the table of contents alert mailing list.
  • You may sign up for e-mail alerts to receive table of contents of newly released issues.
  • PDF is the official format for papers published in both, html and pdf forms. To view the papers in pdf format, click on the "PDF Full-text" link, and use the free Adobe Reader to open them.
Order results
Result details
Section
Select all
Export citation of selected articles as:
27 pages, 992 KB  
Review
How Data Quality Impacts Decision Outcomes: Scoping Review, Methodological Development, and Empirical Demonstration
by Eric A. Andersson
Informatics 2026, 13(8), 136; https://doi.org/10.3390/informatics13080136 - 21 Aug 2026
Viewed by 505
Abstract
Public sector value generation increasingly relies on data provided by information systems, yet the impact of data quality (DQ) on decision-making remains underexamined. While prior research has identified associations between DQ and decision outcomes, strong causal evidence remains scarce. This study addresses the [...] Read more.
Public sector value generation increasingly relies on data provided by information systems, yet the impact of data quality (DQ) on decision-making remains underexamined. While prior research has identified associations between DQ and decision outcomes, strong causal evidence remains scarce. This study addresses the issue in two phases: first, through a scoping review of experimental research on the impact of value-critical DQ dimensions—accuracy, completeness, consistency, and timeliness—and second, through methodological development. Searches across Scopus, Web of Science, IEEE, and PsycInfo, supplemented by citation searching and Google Scholar to avoid inclusion bias, identified 20 studies after screening and full-text review. Rather than excluding studies based on methodological quality, the review critically examined existing experimental designs and their findings. The literature revealed substantial weaknesses, including unclear distinctions between objective and subjective variables, weak manipulations, ambiguous operationalizations, and small sample sizes. Consequently, existing understanding of DQ impact remains limited and often inconclusive. To address these limitations, the article proposes a formal model for DQ experiments and presents a proof of concept for completeness using open data. The findings suggest that completeness influences value appraisal and subsequent choice behavior, particularly under higher uncertainty and larger value differences between alternatives. Full article
(This article belongs to the Section Social Informatics and Digital Humanities)
Show Figures

Figure 1

48 pages, 12045 KB  
Article
An Ontological Framework for Multidimensional and Multivariate Data Visualization with Applications to Financial and Accounting Data
by Snezana Savoska and Suzana Loshkovska
Informatics 2026, 13(8), 135; https://doi.org/10.3390/informatics13080135 - 20 Aug 2026
Viewed by 387
Abstract
Selecting an appropriate visualization technique for multidimensional and multivariate financial and accounting (F&A) data remains a complex, user-dependent task. The TaxUI&BV4FADA taxonomy previously organized this problem along four dimensions—visualization techniques, user intentions and analytical goals, interaction possibilities, and user groups—but as a human-readable [...] Read more.
Selecting an appropriate visualization technique for multidimensional and multivariate financial and accounting (F&A) data remains a complex, user-dependent task. The TaxUI&BV4FADA taxonomy previously organized this problem along four dimensions—visualization techniques, user intentions and analytical goals, interaction possibilities, and user groups—but as a human-readable structure, it could not be queried, validated, or integrated into semantic decision-support pipelines. This paper presents an ontological framework that extends TaxUI&BV4FADA into a machine-readable OWL DL artifact authored in WebProtégé, with OWL used for semantic structuring and SPARQL used for score-based recommendation retrieval. The framework formalizes the four taxonomy dimensions and adds a decision-support layer and an evaluation layer. An explicit F&A semantic mapping is provided, and two contrasting worked scenarios—a financial analyst testing a gross-margin hypothesis and a CFO seeking a quarterly overview—show that the framework discriminates between F&A roles and analytical tasks. The evaluation demonstrates logical consistency, competency-question satisfaction, and internal consistency of the populated recommendation matrix against taxonomy-derived expectations, rather than independent empirical recommendation accuracy. This constitutes an internal, artifact-centered validation rather than an external empirical study with end users, and a protocol for future empirical validation with financial and accounting professionals is outlined. The framework provides a domain-oriented semantic and matrix-based decision-support foundation on which executable F&A visualization recommenders can be built. Full article
Show Figures

Figure 1

37 pages, 22395 KB  
Article
Estimating Sugarcane Planting Date from Multi-Sensor Satellite Time Series Using Derivative Dynamic Time Warping
by Arket Suksomnuek, Chudech Losiri and Asamaporn Sitthi
Informatics 2026, 13(8), 134; https://doi.org/10.3390/informatics13080134 - 20 Aug 2026
Viewed by 726
Abstract
This study proposes a multi-sensor time-series framework for estimating sugarcane planting Days After Planting (DAP) using Sentinel-1 synthetic aperture radar (SAR) and Sentinel-2 optical imagery in Phu Khiao District, Chaiyaphum Province, Thailand. The framework integrates vegetation indices, SAR backscatter, Dynamic Time Warping Barycenter [...] Read more.
This study proposes a multi-sensor time-series framework for estimating sugarcane planting Days After Planting (DAP) using Sentinel-1 synthetic aperture radar (SAR) and Sentinel-2 optical imagery in Phu Khiao District, Chaiyaphum Province, Thailand. The framework integrates vegetation indices, SAR backscatter, Dynamic Time Warping Barycenter Averaging (DBA), Derivative Dynamic Time Warping (DDTW), and stage-specific Ordinary Least Squares (OLS) calibration to estimate planting DAP and crop age. Sugarcane fields were first identified using a Random Forest classifier trained on combined multispectral and SAR features, achieving an Overall Accuracy of 88.5% and a Kappa coefficient of 0.82 for the optimal feature configuration. Multi-temporal vegetation index and SAR backscatter time series were then smoothed using Locally Weighted Scatterplot Smoothing (LOWESS) and aligned with phenological reference prototypes generated by DBA using DDTW. Stage-specific OLS models were subsequently applied to reduce systematic prediction bias. The calibrated framework achieved a coefficient of determination (R2) of 0.9970 and a root mean square error (RMSE) of 5.21 days, representing a substantial improvement over the uncalibrated DDTW estimates (R2 = 0.9953, RMSE = 7.00 days). DDTW alignment produced the highest accuracy during the grand growth stage (Stage 2), with normalized RMSE (NRMSE) ranging from 0.064 to 0.091 across individual features. Independent validation using 140 sugarcane plots from the 2024/2025 cropping season demonstrated the plausibility of the proposed framework, correctly identifying Stage 3 (sugar accumulation) growth for 98.6% of the plots and estimating a mean planting DAP of 267.06 ± 9.55 days. These findings demonstrate that the proposed framework provides an accurate and operational approach for estimating sugarcane planting dates from satellite time-series data, supporting crop age monitoring and harvest planning in tropical agricultural regions where field-based planting records are unavailable or incomplete. Full article
Show Figures

Figure 1

24 pages, 13867 KB  
Article
Phenology-Informed Crop Type Mapping in Semi-Arid Morocco Using Sentinel-2 NDVI Time Series: A Machine Learning Approach with Temporal Sensitivity Analysis
by Fatima Benzhair, Haytam Elyoussfi, Mouad Alami Machichi, Jada El Kasri, Rahma Azamz, Raouaa Elmousadik and Salwa Belaqziz
Informatics 2026, 13(8), 133; https://doi.org/10.3390/informatics13080133 - 18 Aug 2026
Viewed by 560
Abstract
Accurate crop mapping is essential for food security and water resource management in semi-arid North Africa. This study evaluated four machine learning algorithms for crop classification using Sentinel-2 NDVI time series in the Al Haouz region, Morocco with a time series of 12 [...] Read more.
Accurate crop mapping is essential for food security and water resource management in semi-arid North Africa. This study evaluated four machine learning algorithms for crop classification using Sentinel-2 NDVI time series in the Al Haouz region, Morocco with a time series of 12 dates (December 2023–May 2024) using 105,869 ground reference samples. Support Vector Machine (SVM) achieved the highest performance (macro F1-score = 0.80, Overall Accuracy = 81%), followed by XGBoost (0.79), Random Forest (0.79), and Decision Tree (0.71). Class-wise analysis revealed excellent discrimination for apricots (F1 = 0.99) due to distinctive spring phenology, while citrus showed the lowest accuracy (F1 = 0.61) due to confusion with olives. Dynamic Time Warping (DTW) analysis quantified phenological similarity between crops, revealing that classification confusion correlates with profile similarity. Temporal sensitivity analysis revealed that reducing acquisitions from 12 to 8 dates results in only 2.4% performance loss, offering significant operational advantages for resource-limited contexts. February–March acquisitions proved most discriminative, coinciding with peak vegetative differentiation. These findings provide practical recommendations for operational crop monitoring in semi-arid African regions facing water scarcity and food security challenges. Full article
(This article belongs to the Section Machine Learning)
Show Figures

Figure 1

21 pages, 2036 KB  
Article
Visual Autonomous Docking for Unmanned Surface Vehicles Using Lightweight Supervised Learning Framework
by Junyan He and Wei Liu
Informatics 2026, 13(8), 132; https://doi.org/10.3390/informatics13080132 - 14 Aug 2026
Viewed by 438
Abstract
Autonomous docking is a core capability enabling full autonomy of unmanned surface vehicles (USVs), whose practical deployment demands visual pose estimation with high efficiency, temporal stability, and closed-loop control compatibility. This paper proposes a lightweight monocular visual docking perception framework based on MobileNetV2 [...] Read more.
Autonomous docking is a core capability enabling full autonomy of unmanned surface vehicles (USVs), whose practical deployment demands visual pose estimation with high efficiency, temporal stability, and closed-loop control compatibility. This paper proposes a lightweight monocular visual docking perception framework based on MobileNetV2 and a temporal convolutional network (TCN). In this framework, a MobileNetV2 backbone is adopted to perform end-to-end regression of the USV’s relative pose with respect to the dock from a single monocular image, while a feature-level TCN module fuses sequential visual features across consecutive frames to enhance the short-term stability of pose estimation. To validate the performance and reliability of the proposed method, a high-fidelity simulation environment is established to conduct closed-loop USV docking tests. Comparative results demonstrate that the MobileNetV2 backbone reduces inference latency compared with the VGG19 architecture, and the embedded TCN module effectively suppresses inter-frame pose fluctuations and abnormal estimation jumps. The proposed method provides an efficient and temporally consistent visual perception solution for simulation-validated USV autonomous docking systems. Full article
(This article belongs to the Special Issue Advances in Artificial Intelligence, Robotics, and Control)
Show Figures

Figure 1

30 pages, 4748 KB  
Article
MSC Digital Assetization for Personalized Regenerative Medicine: An AI–Blockchain–Digital Twin Integrated Framework
by Chung Seok Han, Jin Woo Yang, Sun Koo Park and Min Jae Park
Informatics 2026, 13(8), 131; https://doi.org/10.3390/informatics13080131 - 14 Aug 2026
Viewed by 389
Abstract
Mesenchymal stem cells (MSCs) are a critical biological resource for regenerative medicine, immunomodulation, and personalized cell therapy. Three structural problems persist: (1) the absence of standardized, quantitative quality indicators; (2) insufficient tamper-proof traceability throughout the manufacturing and banking lifecycle; and (3) the lack [...] Read more.
Mesenchymal stem cells (MSCs) are a critical biological resource for regenerative medicine, immunomodulation, and personalized cell therapy. Three structural problems persist: (1) the absence of standardized, quantitative quality indicators; (2) insufficient tamper-proof traceability throughout the manufacturing and banking lifecycle; and (3) the lack of a personalized matching system linking MSC batch characteristics to patient-specific clinical requirements. This paper proposes the MSC Digital Assetization Framework (MDAF), an applied engineering framework that addresses all three problems at the architectural and prototype level. Here, digital assetization—the transformation of a biological product into a structured, traceable, and transferable digital quality record within a multi-institutional trust infrastructure—denotes verifiable, traceable, quality-certified digital recordization of MSC batches, not tokenization or financial trading. The quality engine integrates morphological, FLIM-derived metabolic–proliferative, donor blood panel, flow cytometry, and manufacturing metadata inputs through a bidirectional Cross-Attention fusion module, yielding a continuous MSC quality score (MQS, 0–100) and an S/A/B/C/D five-tier grade. Privacy-preserving verification is implemented via two independent Groth16 zero-knowledge proof circuits: a Release Eligibility Proof (REP, MQS ≥ 70) and a Premium Quality Proof (PQP, MQS ≥ 85). A Hyperledger Besu QBFT permissioned blockchain with smart contracts provides immutable lifecycle traceability and DID-based access control. In a synthetic data pilot (n = 2000), the system demonstrated engineering feasibility across all five subsystems. These results are engineering pipeline feasibility benchmarks on synthetic data; biological and clinical validation using real MSC data is mandatory follow-on research. Full article
Show Figures

Figure 1

19 pages, 2115 KB  
Review
Human-Centered AI Adoption in Knowledge Work: A PRISMA-ScR Scoping Review of Technostress, Trust, Autonomy, and Employee Well-Being
by Boštjan Blažič and Jasmina Starc
Informatics 2026, 13(8), 130; https://doi.org/10.3390/informatics13080130 - 13 Aug 2026
Viewed by 709
Abstract
Introduction: Artificial intelligence (AI) is becoming part of everyday knowledge work through generative AI, decision-support systems, algorithmic management, and AI-enabled organizational information systems. This development raises a central question: when does AI support employees, and when does it become a source of technostress, [...] Read more.
Introduction: Artificial intelligence (AI) is becoming part of everyday knowledge work through generative AI, decision-support systems, algorithmic management, and AI-enabled organizational information systems. This development raises a central question: when does AI support employees, and when does it become a source of technostress, surveillance, uncertainty, and reduced autonomy? Objectives: This PRISMA-ScR scoping review mapped evidence on human-centered AI adoption in knowledge-intensive work and examined links with technostress, trust, autonomy, and employee well-being. Methods: Using a population–concept–context approach, we included peer-reviewed journal articles and conference papers addressing AI adoption in knowledge-work settings and at least one human-centered or employee-related outcome. Publicly accessible databases and public metadata records were searched across Scopus, Web of Science Core Collection, IEEE Xplore, ACM Digital Library, ScienceDirect, PubMed/MEDLINE, Business Source Complete, and APA PsycINFO. Searches were conducted in March 2026 and verified between 1 and 15 April 2026. Results: Twenty-six sources were included, comprising 17 journal articles and 9 peer-reviewed conference/proceedings sources. Five evidence clusters were identified: AI as a resource-demand system, information-system properties, generative AI work redesign, organizational implementation conditions, and short- versus long-term employee outcomes. Conclusions: Human-centered AI adoption in knowledge work requires transparent system design, organizational governance, employee participation, and long-term monitoring. The review contributes a business informatics implementation framework for trustworthy, ethically governed, and well-being-oriented AI use. Full article
Show Figures

Figure 1

25 pages, 663 KB  
Systematic Review
Multilingual Conversational AI Chatbots for Efficient Healthcare Delivery During Case History-Taking: A Systematic Review
by Rajashekhara Bhari Sharanesha, Deepti Virupakshappa, Alwaleed Abushanan and Sara Alghamdi
Informatics 2026, 13(8), 129; https://doi.org/10.3390/informatics13080129 - 12 Aug 2026
Viewed by 616
Abstract
Language barriers hinder healthcare, particularly during case history-taking, a key part of diagnosis. While multilingual artificial intelligence (AI) chatbots offer solutions, there is fragmented evidence of their effectiveness and impact. This systematic review followed PRISMA 2020 guidelines, examining studies published between 2015 and [...] Read more.
Language barriers hinder healthcare, particularly during case history-taking, a key part of diagnosis. While multilingual artificial intelligence (AI) chatbots offer solutions, there is fragmented evidence of their effectiveness and impact. This systematic review followed PRISMA 2020 guidelines, examining studies published between 2015 and 2025 on multilingual AI chatbots in healthcare across four databases (Google Scholar, Scopus, Web of Science, and PubMed), using a two-stage screening process. Data extraction focused on applications, supported languages, underlying technologies, target populations, and clinical outcomes. From 503 records, 49 studies, covering primary care, telemedicine, oncology, mental health, and other areas, met the criteria. Supported languages included English, Spanish, Arabic, Chinese, Hindi, and other underrepresented languages. In individual system evaluations using heterogeneous methodologies and evaluation settings, AI chatbots achieved a diagnostic accuracy ranging from 72–92%. Core technologies included large language models (LLMs), bidirectional encoder representations from transformers (BERT), a generative pre-trained transformer (GPT), retrieval-augmented generation (RAG), speech recognition, and distillation. The findings show that these improve clinical workflow (30–70% time savings) and patient engagement, reduce language barriers, and promote health equity. However, the overall evidence certainty was low to moderate, reflecting the predominance of prototype and proof-of-concept studies. Multilingual AI chatbots demonstrate a boost in healthcare efficiency, a reduction in language barriers, and the promotion of health equity, but exhibit challenges regarding validation, workflow integration, and evaluation standards, along with ethical issues such as privacy and bias. Future research should include real-world studies, diverse populations, standardized outcome measures, and long-term equity assessments. Full article
Show Figures

Graphical abstract

11 pages, 213 KB  
Article
Multi-Agent GenAI for Harm Reduction: A Psychologist’s (or Social Scientist’s) Tutorial on Classifying Harmful Workplace Language
by S. Gabe Hatch, Bryar Topham, Cristen Dalessandro, Zachary T. Goodman, Jason T. Martineau and Alexander G. Lovell
Informatics 2026, 13(8), 128; https://doi.org/10.3390/informatics13080128 - 12 Aug 2026
Viewed by 465
Abstract
Background: The American Psychological Association has recently acknowledged that generative artificial intelligence has the potential to cause considerable harm if not properly managed and supervised. The current tutorial situates psychologists, and social scientists, as uniquely positioned to take part in the development of [...] Read more.
Background: The American Psychological Association has recently acknowledged that generative artificial intelligence has the potential to cause considerable harm if not properly managed and supervised. The current tutorial situates psychologists, and social scientists, as uniquely positioned to take part in the development of these models given their ethical background, understanding of human behavior, and ability to conduct meaningful research. Method: In an effort to cause the least amount of harm during the training process, the current work proposes multi-agent generative artificial intelligence simulations as a way to build initial safeguards into deployable models using an accessible and real-life use case: detecting harmful language (e.g., profanity) in employee recognition messages. Results: We provide replicable R code on how to run simulations, which results in models with high levels of classification accuracy on simulated data (i.e., 97.5%). Conclusions: Finally, strengths, limitations, and future directions for research are discussed. Full article
(This article belongs to the Section Machine Learning)
27 pages, 2143 KB  
Article
Adversarial Training and Differential Privacy-Style Noise Injection for Privacy-Preserving Vertical Federated Learning
by Nureni Ayofe Azeez, Oluwatobi Sunday Malomo, Omotolani Mary Okerinde, Abdullateef Akorede Ademoye, Damilola Seun Aaron, Charles Van Der Vyver and Chijioke Erasmus Ogbonna
Informatics 2026, 13(8), 127; https://doi.org/10.3390/informatics13080127 - 9 Aug 2026
Viewed by 671
Abstract
The adoption of federated learning (FL) has been on the rise in recent years due to the decentralized approach to data handling. Vertical federated learning is a type of FL that allows different parties to train shared models on complementary feature spaces without [...] Read more.
The adoption of federated learning (FL) has been on the rise in recent years due to the decentralized approach to data handling. Vertical federated learning is a type of FL that allows different parties to train shared models on complementary feature spaces without the direct exchange of data. However, the gradients these parties exchange can inadvertently carry sensitive information. Adversaries exploit this leakage to mount label inference attacks (LIAs) and adversarial attacks. To curb this, defense mechanisms have been deployed, but most of them either trade robustness for privacy and model utility or vice versa. This study addresses this gap by introducing an improved defense mechanism that combines adversarial training (to harden the model against adversarial perturbations) and differential-privacy-style noise injection (aimed at restoring the label privacy weakened by adversarial training) to collectively enhance the robustness of the existing KDk defense mechanism with marginal model utility trade-off. Instead of relying on heavy encryption or post-processing techniques, it builds privacy directly into the learning dynamics of the model. It was evaluated using five publicly available datasets spanning three data modalities with the proposed mechanism achieving competitive near-baseline accuracy while significantly reducing label-inference success. Under FGSM-based adversarial evaluation, the robustness gap of this mechanism was found to be approximately 1% compared to the 36% robustness gap of the existing KDk mechanism. The Privacy Leakage Index (PLI) reached 81.32%, 96.08%, 82.41%, 86.68% and 73.88% for CIFAR-10, CIFAR-100, CINIC-10, Yahoo! Answers and Criteo datasets, respectively. The results suggest that robustness and privacy security objectives can coexist to secure VFL with minimal effect on model accuracy. Full article
Show Figures

Figure 1

20 pages, 14548 KB  
Article
Distribution of Cognitive Load and Related Debates in Students Interacting with an Augmented Reality Application for History Learning
by Santiago Criollo-C, Oswaldo Moscoso-Zea, Yunifa Miftachul Arif and Sergio Luján-Mora
Informatics 2026, 13(8), 126; https://doi.org/10.3390/informatics13080126 - 7 Aug 2026
Viewed by 750
Abstract
The growing adoption of Augmented Reality (AR) in education raises challenges related to the cognitive load that students experience during learning. Inadequate management of this load can negatively affect information processing during learning activities. Although previous studies have explored AR applications, most have [...] Read more.
The growing adoption of Augmented Reality (AR) in education raises challenges related to the cognitive load that students experience during learning. Inadequate management of this load can negatively affect information processing during learning activities. Although previous studies have explored AR applications, most have focused on usability and learning outcomes, leaving aside the detailed analysis of Cognitive Load Theory (CLT), particularly its dimensions: intrinsic cognitive load (ICL), extraneous cognitive load (ECL) and germane cognitive load (GCL). To address this gap, this study evaluates cognitive load using the HistARium application, designed to support history learning with interactive experiences. A total of 60 students participated and completed a structured questionnaire to measure ICL, ECL, and GCL after using the application. The results show a positive distribution: moderate intrinsic load, low extraneous load, and high germane load. These findings indicate that the HistARium application balances content complexity, reduces unnecessary effort, and promotes cognitive processes associated with information organization and schema education construction. Furthermore, the results suggest that integrating CLT principles into AR applications supports cognitive processing during learning, while also opening new opportunities for the development of immersive and adaptive learning environments. Full article
Show Figures

Figure 1

21 pages, 2378 KB  
Article
Optimizing the Mammography AI Pipeline: From Data Filtering to Vision-Language Models
by Egor Ushakov, Sofya Zimina, Arsenii Litvinov, Sofia Senotrusova, Kirill Lukianov, Tigran G. Gevorkyan and Evgeny Karpulevich
Informatics 2026, 13(8), 125; https://doi.org/10.3390/informatics13080125 - 31 Jul 2026
Viewed by 565
Abstract
The performance of AI solutions in mammography is largely determined by data quality, preprocessing methods, and augmentation strategies. However, systematic evaluation of these factors for models trained on aggregated multicenter datasets remains underexplored. This article presents a comparative assessment of the effects of [...] Read more.
The performance of AI solutions in mammography is largely determined by data quality, preprocessing methods, and augmentation strategies. However, systematic evaluation of these factors for models trained on aggregated multicenter datasets remains underexplored. This article presents a comparative assessment of the effects of different stages of the training pipeline on the final diagnostic accuracy. Using a pooled dataset (VinDr-Mammo, INBreast, CMMD, CBIS-DDSM), we evaluated each pipeline step—from filtering to architecture selection (EfficientNet-B3, CLIP). External testing was conducted on the MosMed database. Among the tested preprocessing steps, filtering the darkest 5% of images proved most effective. For EfficientNet-B3, optimal geometric and photometric augmentations increased test AUROC on the prepared MosMed test set from 0.844 to 0.900. Domain-specific pretraining and high resolution yielded the best performance: Mammo-CLIP achieved an AUROC of 0.949 ± 0.012, and EfficientNet-B3 reached 0.934 ± 0.013. Overall, this study developed a standardized pipeline that includes sequential data filtering and harmonization, augmentation optimization, and architecture selection. This approach ensures reliable and reproducible results for automated mammogram classification. Full article
Show Figures

Figure 1

29 pages, 1532 KB  
Article
Causal-Pathway-Guided DNN–GBDT Distillation for Interpretable Artificial Intelligence in Intensive Care Units
by Hashim Ali
Informatics 2026, 13(8), 124; https://doi.org/10.3390/informatics13080124 - 30 Jul 2026
Viewed by 595
Abstract
Artificial intelligence (AI) systems for intensive care units (ICUs) must support early risk prediction while producing explanations that clinicians can inspect, question, and relate to physiological reasoning. Deep neural networks (DNNs) can learn complex temporal patterns from electronic health records (EHRs), but their [...] Read more.
Artificial intelligence (AI) systems for intensive care units (ICUs) must support early risk prediction while producing explanations that clinicians can inspect, question, and relate to physiological reasoning. Deep neural networks (DNNs) can learn complex temporal patterns from electronic health records (EHRs), but their internal representations are often difficult to translate into clinically actionable explanations. Gradient-boosted decision trees (GBDTs) offer more transparent decision rules, yet they may not capture the full temporal and nonlinear structure of high-dimensional ICU data. This paper presents a causal-pathway-guided DNN–GBDT distillation framework for interpretable ICU decision support. The framework first estimates a directed acyclic graph (DAG), denoted by G, from multivariate ICU time-series data and then uses the graph to guide representation learning in a DNN teacher model through causal gating. The learned teacher is distilled into a GBDT student model using soft predictive targets and a causal attribution-guided split-selection procedure, so that the final model approximates the teacher predictions while prioritizing tree splits aligned with plausible physiological pathways. Experiments using Medical Information Mart for Intensive Care IV (MIMIC-IV) data evaluate sepsis onset and in-hospital mortality prediction through discrimination, precision–recall performance, calibration-oriented reporting, causal consistency, and clinical utility indicators. The proposed causal-aware distilled GBDT achieves stronger predictive performance than conventional interpretable baselines and substantially higher causal consistency than black-box temporal models. The results suggest that causal structure can serve as an inductive bias for converting complex temporal prediction into interpretable rule-based clinical reasoning. The paper also discusses limitations related to observational causal discovery, unmeasured confounding, temporal stationarity, and clinical deployment, following recent reporting expectations for AI-based clinical prediction models. Full article
(This article belongs to the Section Health Informatics)
Show Figures

Figure 1

20 pages, 6592 KB  
Article
SE-POSTER: Channel-Enhanced Landmark Guided Transformer for Facial Emotion Recognition
by Alpamis Kutlimuratov, Kongratbay Sharipov, Piratdin Allayarov, Sayyora Iskandarova, Ruslan Latyfskiy, Gulchehra Tolibaeva and Fazliddin Makhmudov
Informatics 2026, 13(8), 123; https://doi.org/10.3390/informatics13080123 - 30 Jul 2026
Viewed by 531
Abstract
Recognizing facial emotions automatically from images/videos (FER) still represents a difficult problem for emotion computing, mainly due to variations in the face pose, lighting, occlusion, facial features, and expression intensity in the wild. Recent CNN–Transformer-based hybrid models like POSTER have leveraged local feature [...] Read more.
Recognizing facial emotions automatically from images/videos (FER) still represents a difficult problem for emotion computing, mainly due to variations in the face pose, lighting, occlusion, facial features, and expression intensity in the wild. Recent CNN–Transformer-based hybrid models like POSTER have leveraged local feature learning, landmark guidance, and global dependency modeling to achieve strong performance. Yet these methods give the main focus to spatial and contextual representations while not really going deep into adaptive channel-wise feature importance over multi-scale representations. As different feature channels represent emotions in varying degrees, it is likely that by treating all feature channels equally, one would limit the ability of the learned features to discriminate effectively. To overcome this weakness, this article presents a ResNet-18–Transformer landmark-guided module called SE-POSTER that fuses lightweight Squeeze-and-Excitation (SE) attention modules into the multi-scale feature pyramid of the baseline POSTER architecture. The proposed method carries out feature channel recalibration adaptively at the level of features before Transformer-based global attention modeling, thus allowing the network to focus on emotionally informative feature channels and suppress less relevant responses. The inclusion of SE attention in the network enhances fine, mid, and global levels of feature representations at a very low cost in terms of computation. On the basis of the RAF-DB, FERPlus, and AffectNet datasets, enormous experiments prove that the SE-POSTER framework proposed is capable of steadily boosting recognition accuracy relative to the baseline POSTER and several state-of-the-art FER methods. Especially, the proposed model delivers 92.78% accuracy on RAF-DB while it also shows better robustness and generalization capability under difficult real-world conditions. Moreover, additional ablation studies reveal that multi-level channel recalibration is effective in improving discriminative emotional feature learning. Full article
(This article belongs to the Special Issue Practical Applications of Sentiment Analysis)
Show Figures

Figure 1

21 pages, 2459 KB  
Article
A Lightweight 3DMM-CNN Pipeline for Real-Time Single-Image 3D Face Reconstruction: Prototyping Personalised Avatars for Extended Reality Applications
by Qianqian He, Wirapong Chansanam, Lan Thi Nguyen, Kannikar Intawong and Kitti Puritat
Informatics 2026, 13(8), 122; https://doi.org/10.3390/informatics13080122 - 24 Jul 2026
Viewed by 1106
Abstract
Personalised three-dimensional (3D) facial avatars underpin a wide range of immersive virtual, augmented, and mixed reality (XR) experiences, yet conventional 3D capture pipelines remain prohibitively expensive and computationally demanding for prototype-stage XR applications. This study presents and evaluates a lightweight hybrid 3D Morphable [...] Read more.
Personalised three-dimensional (3D) facial avatars underpin a wide range of immersive virtual, augmented, and mixed reality (XR) experiences, yet conventional 3D capture pipelines remain prohibitively expensive and computationally demanding for prototype-stage XR applications. This study presents and evaluates a lightweight hybrid 3D Morphable Model–Convolutional Neural Network (3DMM-CNN) pipeline that reconstructs an animation-ready 3D facial mesh from a single unconstrained RGB photograph and exposes it through an interactive prototype with native export to XR-ready asset formats. A four-channel ResNet-50 backbone fuses RGB pixels with a landmark-mask channel, regresses the 3DMM shape, expression, pose, and illumination parameters, and is refined through a multi-task loss that combines 3D parameter regression, 2D landmark consistency, and image-to-mesh-to-image cycle consistency. The model is trained on a curated 2000-image subset of the LFW-People corpus and evaluated under four yaw-angle strata. The results indicate that on a held-out 400-image test set, the pipeline attains R2 = 0.854, MSE = 0.022, Pearson r = 0.92, and MAPE = 10.6%, with a single-frame inference latency of 35 ms on a commodity RTX-class GPU. Robustness to head rotation improves by 29.9% at extreme poses (60–90° yaw) compared with a single-modality baseline. A Blender-integrated prototype successfully exports the reconstructed mesh as a deformation-ready asset for Unity- and Unreal-based XR engines. The proposed pipeline offers a cost-effective, real-time-capable component for XR avatar prototyping, lowering the entry barrier for small studios, immersive-learning developers, and AR/MR telepresence research. On the standard AFLW2000-3D benchmark, the pipeline additionally attains a Normalised Mean Error of 2.47% and a full-vertex reconstruction error of 1.50%, which is competitive with published lightweight baselines while retaining sub-50 ms inference latency. Full article
Show Figures

Figure 1

18 pages, 282 KB  
Article
Digital Product Passports in Online Fashion Resale: Supporting Circular Fashion, Transparency, and Consumer Trust
by Anna Elizabeth Stookey and Chunmin Lang
Informatics 2026, 13(8), 121; https://doi.org/10.3390/informatics13080121 - 24 Jul 2026
Viewed by 962
Abstract
As online luxury fashion resale platforms continue to emerge and expand, persistent challenges related to trust and product authenticity have become increasingly pronounced. digital product passports (DPPs) offer a potential solution to these trust-related challenges by providing detailed information about a product, thereby [...] Read more.
As online luxury fashion resale platforms continue to emerge and expand, persistent challenges related to trust and product authenticity have become increasingly pronounced. digital product passports (DPPs) offer a potential solution to these trust-related challenges by providing detailed information about a product, thereby enhancing product transparency and traceability throughout the product lifecycle. Drawing on signaling theory, this study investigates how DPP-enabled platforms influence consumers’ purchase intentions toward luxury fashion resale consumption. An online survey generated 307 valid responses. Structural equation modeling (SEM) was employed to test the proposed hypotheses. A multi-group chi-square difference test was also conducted to test the moderating role of DPP usage experience. The results demonstrate that trust and attitude are decisive predictors of consumers’ intention to purchase second-hand luxury fashion products from DPP-enabled platforms. Risk reduction alone does not directly drive intention, highlighting the distinction between eliminating uncertainty and fostering positive motivation. This study focuses on consumer perception and intention regarding DPPs within the luxury fashion resale market, an area that has received limited empirical attention. By integrating signaling theory with fashion resale and digital innovation, this study offers novel insights into the role of technological transparency in driving consumer engagement in circular fashion. Full article
25 pages, 2321 KB  
Article
Activity Classification in E-Commerce Product Reviews Using Deep Learning and Transformer Models
by Tinashe Wamambo, Arooj Fatima, Bethwel Kiplagat, Mahdi Maktab Dar Oghaz and Cristina Luca
Informatics 2026, 13(8), 120; https://doi.org/10.3390/informatics13080120 - 23 Jul 2026
Viewed by 631
Abstract
Existing research on e-commerce product reviews has primarily focused on analysing consumers’ opinions, emotions, sentiments and associated star ratings. Whilst these approaches provide insights into consumers’ perceptions of products, they offer limited understanding of how products are used in real-world contexts. Therefore, they [...] Read more.
Existing research on e-commerce product reviews has primarily focused on analysing consumers’ opinions, emotions, sentiments and associated star ratings. Whilst these approaches provide insights into consumers’ perceptions of products, they offer limited understanding of how products are used in real-world contexts. Therefore, they do little to enhance the e-commerce experience by helping consumers make more informed purchasing decisions based on products’ intended uses without requiring them to read numerous reviews during the decision-making process. To address this problem, this paper investigates the feasibility of automatically identifying and classifying product usage activities from e-commerce reviews. A methodology combining natural language processing, manual activity-level annotation and deep learning-based text classification was developed and evaluated. An initial dataset of 60,000 Amazon product reviews was manually labelled according to six activity classes: run, walk, hike, swim, climb and unknown. Following quality inspection and data cleaning, a final dataset of 50,843 reviews was used for model training and evaluation. Multiple classification approaches were assessed, including CNN, LSTM, hybrid LSTM-CNN architectures and transformer-based models (DistilBERT and DistilBERT-CNN). Experimental evaluation was conducted using multiple random seeds to ensure robustness and reproducibility. The results indicate that activity classification from e-commerce reviews is a challenging task due to ambiguity and overlapping usage descriptions, with all evaluated models achieving comparable performance on the full dataset. Among the evaluated models, the hybrid LSTM-CNN-GloVe architecture achieved the highest performance on the keyword-filtered dataset, whilst the DistilBERT-CNN model also demonstrated strong results. The findings demonstrate the feasibility of extracting activity-oriented information from product reviews and highlight activity classification as a distinct and under-explored natural language processing task that complements traditional sentiment analysis. The proposed methodology provides a foundation for improving product discovery and supporting usage-oriented search and recommendation systems in e-commerce environments. Full article
(This article belongs to the Section Big Data Mining and Analytics)
Show Figures

Figure 1

Previous Issue
Back to TopTop