Article

An Abnormal File Access Detection Model for Containers Based on eBPF Listening

1
Cyberspace Institute of Advanced Technology, Guangzhou University, Guangzhou 510555, China
2
School of Computer Science and Technology, Harbin Institute of Technology (Shenzhen), Shenzhen 518071, China
*
Author to whom correspondence should be addressed.
Mathematics 2026, 14(6), 991; https://doi.org/10.3390/math14060991
Submission received: 4 February 2026 / Revised: 2 March 2026 / Accepted: 9 March 2026 / Published: 14 March 2026

Abstract

With the widespread adoption of container technology, its shared kernel architecture has made abnormal file access behavior a key precursor to container escape and lateral attacks, necessitating precise and efficient runtime detection mechanisms. However, existing monitoring methods typically suffer from issues such as insufficient granularity in data collection, limited path semantic modeling capabilities, and low anomaly detection accuracy. To address these challenges, this paper proposes an eBPF-based method for detecting abnormal file access in containers. A lightweight kernel-level monitoring mechanism is constructed to capture access behavior in real time at the system call level, effectively enhancing both the granularity of data collection and the completeness of context. At the feature modeling layer, a multimodal path semantic representation method is designed, combining risk-layer rules and semantic vectorization strategies to enhance the hierarchical expression of path structures and improve context modeling ability. In the detection layer, an attention-enhanced autoencoder model is introduced, achieving high-precision identification of abnormal access behavior and low false-positive monitoring under unsupervised conditions through a path segment attention mechanism and weighted reconstruction loss function. Experiments in real container environments show that the proposed method achieves a recall rate of 82.0 % , a false-positive rate of 0.79 % , and a Matthews correlation coefficient of 0.852, significantly outperforming mainstream unsupervised detection methods such as Isolation Forest, One-Class SVM, and Local Outlier Factor. These results verify the advantages of the proposed method in terms of detection accuracy, real-time performance, and system friendliness, providing an efficient and feasible solution for enhancing the detection of unknown attacks in container runtimes.

1. Introduction

Since the emergence of container technology in 2013, containerized platforms—most notably Docker [1]—have been widely adopted in the fields of cloud computing and microservices due to their advantages in lightweight design, high performance, scalability, and portability. By packaging applications along with their dependencies into isolated runtime environments, containers enable consistent execution across different operating systems and deployment environments, effectively addressing the “inconsistent environment” issue [2]. Moreover, containers leverage Linux kernel mechanisms such as Namespaces [3] and Cgroups [4] to isolate resources including processes, networks, and file systems. This allows containers to share a single host kernel while maintaining relatively independent execution spaces, thereby significantly improving both system resource utilization and overall security [5,6,7].
However, container security has become an increasingly prominent concern. Because containers share the host kernel, their security heavily depends on the completeness and correctness of kernel configurations. Once an attacker exploits a kernel vulnerability or misconfigured privileges to escalate permissions, it becomes possible to break the isolation boundary between the container and the host, resulting in container escape [8]. This process is often accompanied by complex attack chains involving path resolution attacks, symbolic link hijacking, and unauthorized access to sensitive files. Industry reports likewise confirm that runtime threats to containers have become a major bottleneck in cloud-native deployments. For example, Tencent Cloud’s White Paper on Container Security [9] notes that over 50 % of enterprises have experienced container security incidents, while a 2024 survey by Red Hat revealed that nearly 90 % of organizations encountered at least one runtime security issue involving containers or Kubernetes [10,11] in the past year. These findings underscore the urgent need to establish efficient and real-time monitoring systems for container runtime behavior.
With the increasing programmability of the Linux kernel, extended Berkeley Packet Filter (eBPF) technology [12] has gradually emerged as a key enabler for container security monitoring. eBPF allows custom monitoring logic to be dynamically attached within kernel space in a non-intrusive manner, enabling real-time capture of system calls, process behaviors, and file access activities. Compared with traditional kernel modules or user-space log collection approaches, eBPF introduces significantly lower performance overhead while providing richer contextual awareness, thereby delivering fine-grained runtime behavior data without compromising system stability. As a result, several mainstream security tools, including Falco [13], Tracee [14], and Tetragon [15], have integrated eBPF-based monitoring modules to perform rule-driven event detection. However, these tools largely rely on static rule matching, which limits their ability to model complex behavior sequences and detect previously unseen attack patterns, making them less effective against the rapidly evolving threat landscape in cloud-native environments.
To overcome the limitations of rule-based detection, both academia and industry have increasingly adopted anomaly detection techniques that identify deviations by learning a baseline of normal system behavior. Classical unsupervised methods such as Isolation Forest [16], One-Class Support Vector Machine (One-Class SVM) [17], and Local Outlier Factor (LOF) [18] have demonstrated effectiveness in general system anomaly detection. Nevertheless, they exhibit notable shortcomings in container file access scenarios. Specifically, their feature representation capabilities are limited, making it difficult to capture the hierarchical semantics and contextual relationships inherent in file paths; they tend to be unstable when handling high-dimensional and sparse textual features; and their inference latency is relatively high, which hinders real-time security monitoring under high-concurrency workloads. Autoencoders, owing to their stronger feature reconstruction capability, have attracted growing attention in unsupervised anomaly detection. However, conventional autoencoder models lack flexible modeling mechanisms for structured textual data and struggle to capture long-range dependencies between file path segments. Beyond post-event detection, proactive prediction and early warning of abnormal/fault events have also been emphasized in cyber–physical systems; for example, Cong et al. investigated predictability verification of fault patterns in labeled Petri nets, providing formal criteria for whether fault behaviors can be predicted before their occurrence [19]. Although our work focuses on runtime detection in container environments, this line of research highlights a promising future direction toward proactive defense.
In summary, although kernel-level monitoring and unsupervised detection models respectively provide the technical foundation for container behavior collection and unknown threat identification, building a file access anomaly detection system that is truly applicable to real-world production environments still faces several critical challenges. These challenges can be primarily summarized into three aspects. First, the granularity of data collection remains insufficient, as some existing approaches struggle to reliably capture fine-grained behavioral context that consistently associates containers, processes, and complete file paths under high-concurrency workloads. Second, the capability for path semantic modeling is limited, making it difficult for traditional feature representations to effectively characterize the hierarchical structure and contextual semantics inherent in file paths. Third, detection accuracy and real-time performance are hard to balance: existing unsupervised models are prone to high false-positive rates when dealing with high-dimensional and sparse path features, which significantly constrains their practical applicability in container runtime security monitoring.
To address these challenges and achieve fine-grained monitoring, semantics-enhanced modeling, and effective anomaly detection in container file access scenarios, there is a strong need for a runtime security mechanism that tightly integrates kernel-level data collection with intelligent detection models. To this end, this paper proposes an eBPF-based container file access anomaly detection method. By combining kernel-level behavior capture, multimodal path semantic representation, and an attention-enhanced autoencoder model, the proposed approach enables real-time identification of abnormal file access behaviors while maintaining a low false-positive rate.
The main contributions of this work are summarized as follows:
  • A lightweight eBPF-based container file access monitoring mechanism is proposed. By attaching to the security_file_open hook and reconstructing full file paths through iterative traversal of the dentry structure, the method achieves fine-grained and low-overhead system call collection under high-load scenarios.
  • A multimodal file path semantic representation method is developed, which integrates risk-based hierarchical normalization, a fixed-length six-segment structural encoding scheme with explicit structural markers, and Word2Vec-based semantic vectorization, significantly enhancing the hierarchical expressiveness and semantic consistency of path features.
  • An attention-enhanced autoencoder-based anomaly detection model is designed. By incorporating a path-segment attention layer and a weighted reconstruction loss function, the model improves the accuracy of abnormal access detection while substantially reducing false-positive rates under unsupervised settings.
  • Comprehensive experimental evaluations are conducted from three perspectives—monitoring framework overhead, model parameters and feature embeddings, and multi-model comparisons—demonstrating the proposed method’s advantages in terms of real-time performance, detection accuracy, and false-positive reduction.

2. Related Work

To address the key challenges in container file access anomaly detection, existing studies have explored solutions from three main perspectives: kernel-level behavior collection, file path semantic modeling, and unsupervised anomaly detection. In this section, we review the state of the art and limitations of current research along these three dimensions, with a particular focus on eBPF-based monitoring mechanisms, file path semantic representation methods, and autoencoder-based anomaly detection models.

2.1. eBPF-Based Container Security

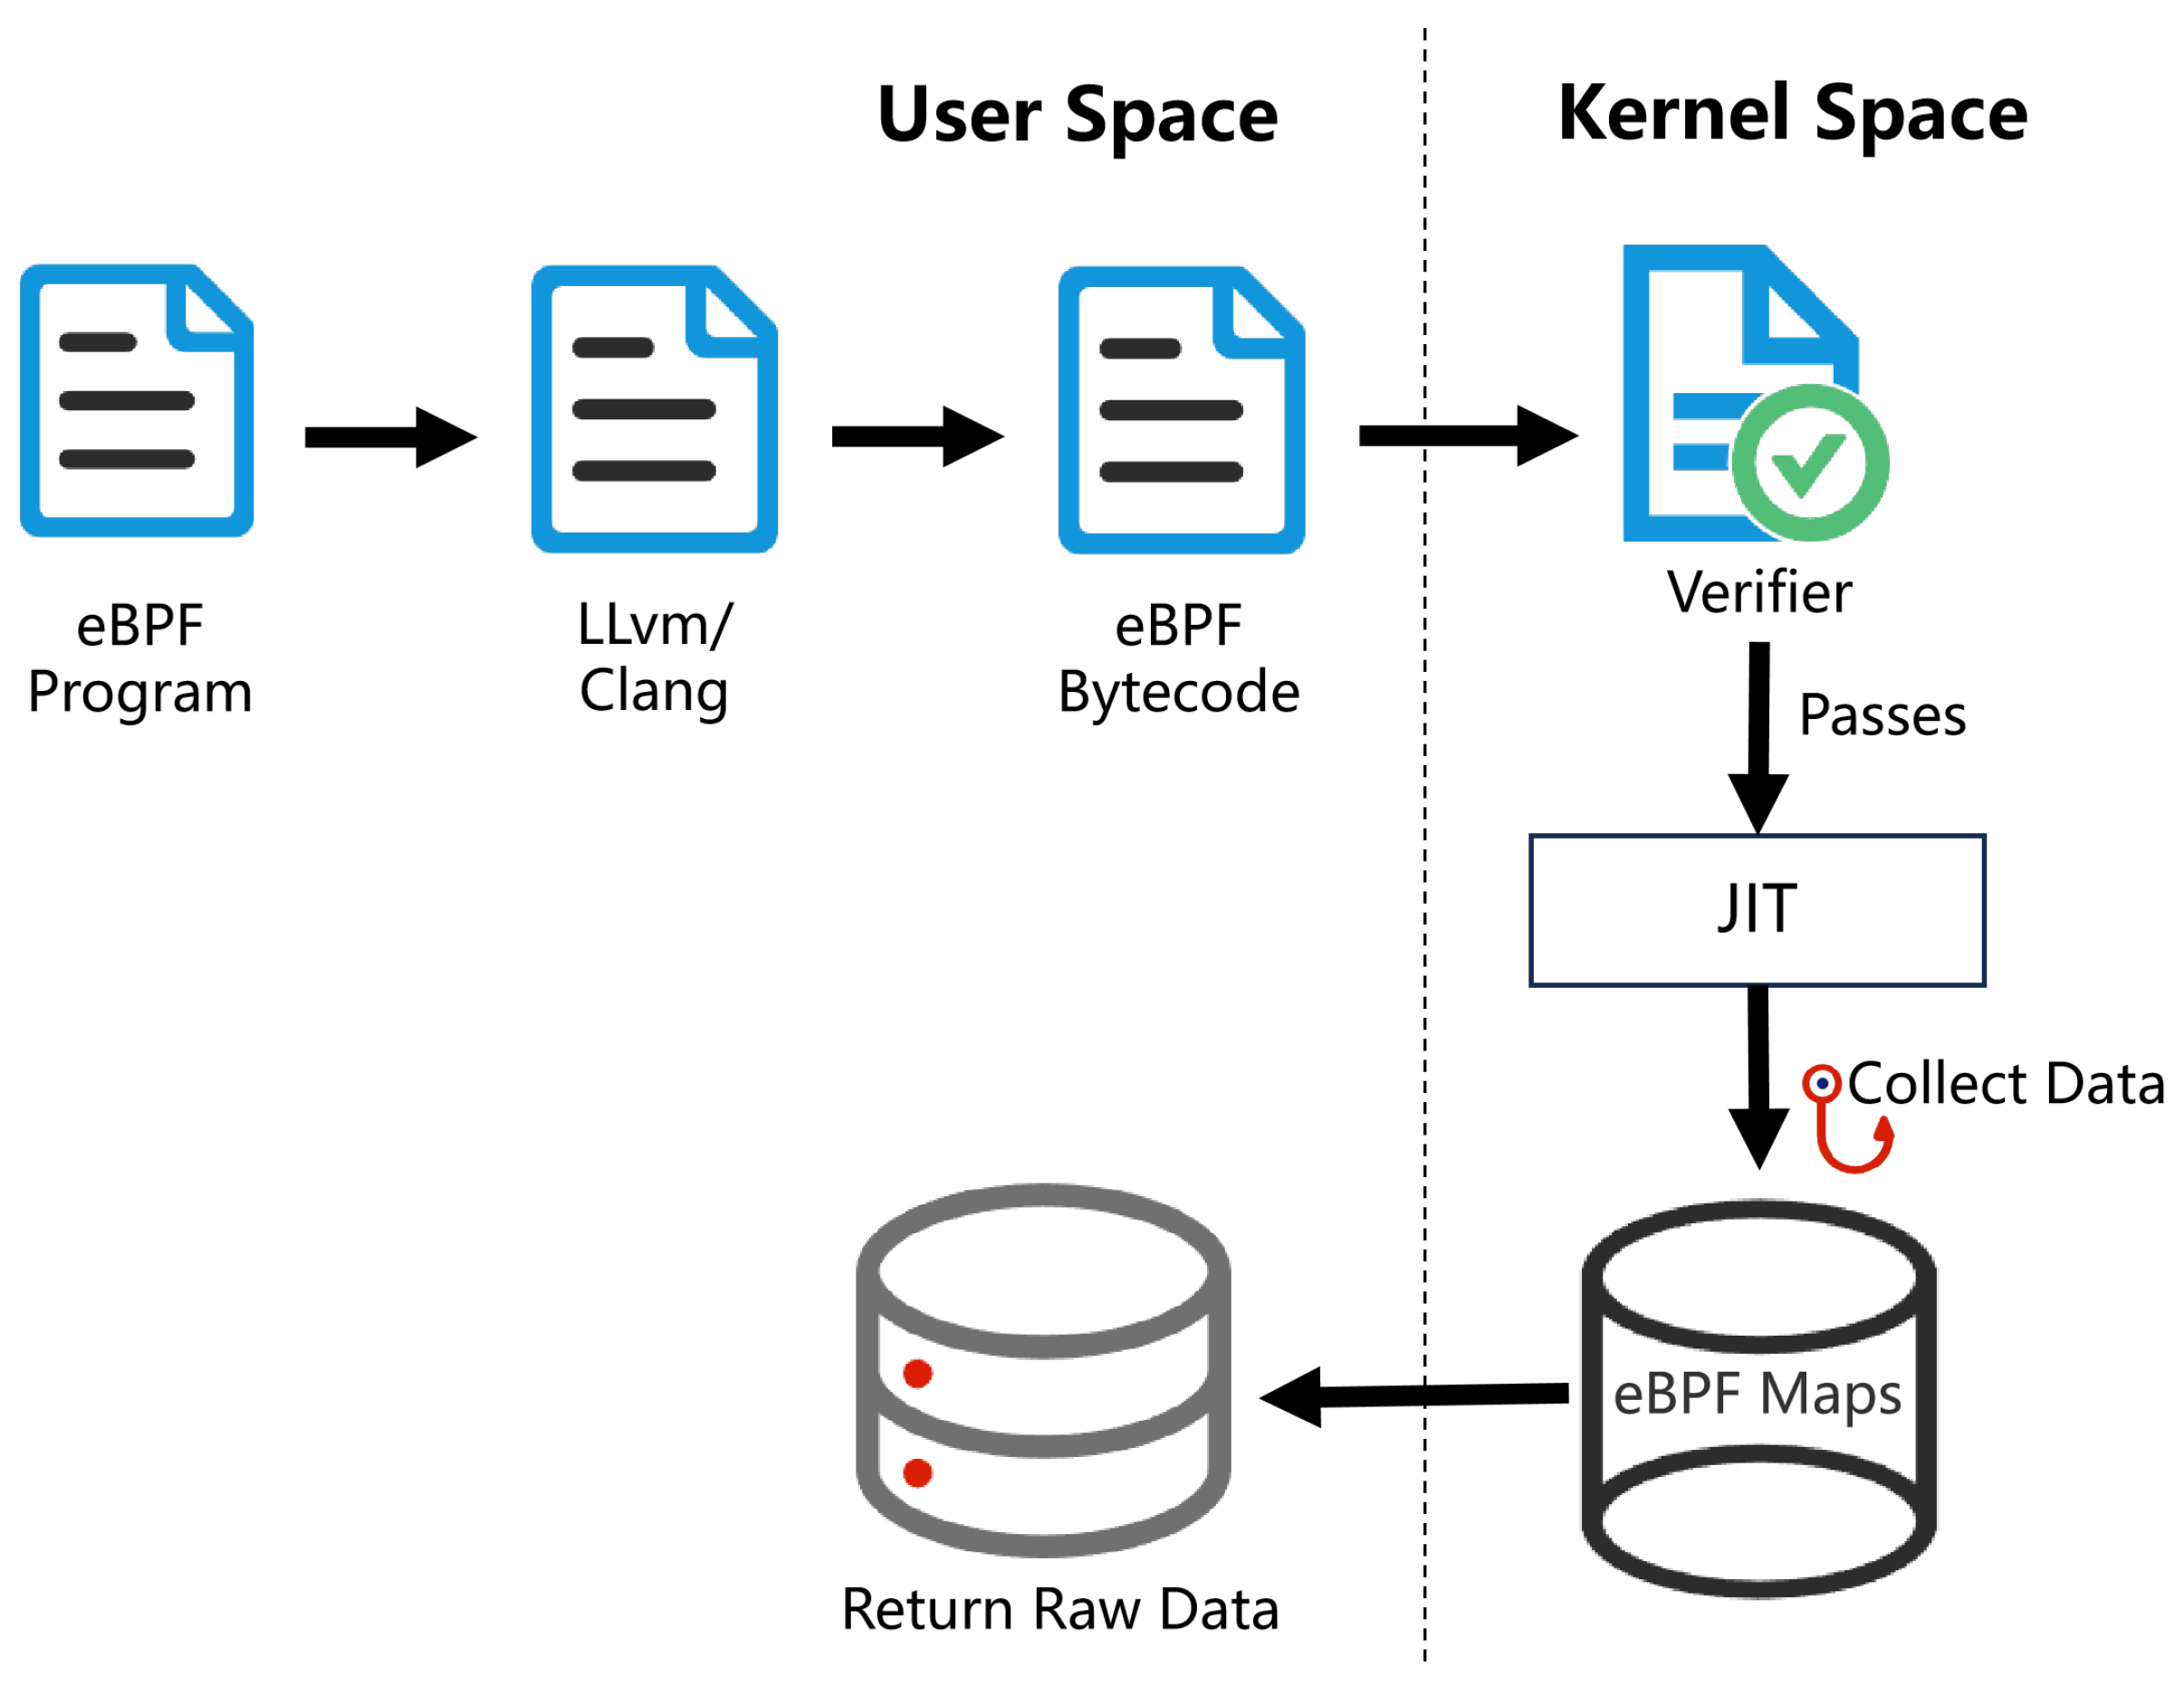
Extended Berkeley Packet Filter (eBPF) is a powerful technology that operates within kernel space and has been widely adopted in recent years for container security monitoring. Its architecture is illustrated in Figure 1. eBPF enables dynamic attachment to kernel events, allowing efficient security enforcement without introducing significant performance overhead. However, eBPF is a double-edged sword: while it can be leveraged to enhance container security and defend against potential attacks, it may also be abused by adversaries to facilitate container escape or kernel-level attacks [20]. This dual nature makes the deployment and management of eBPF-based mechanisms in cloud computing and containerized environments increasingly complex and challenging.
Despite the potential risks of misuse, the defensive role of eBPF in container security remains significant. eBPF enables real-time interception and monitoring of kernel events and has been widely applied in container environments for system call monitoring [21,22], file operation security [23], and network traffic analysis [24]. These capabilities make eBPF an effective foundation for enforcing runtime security policies at the kernel level.
However, most existing approaches rely heavily on rule-based matching or static thresholding mechanisms, which lack semantic understanding of anomalous behaviors and provide limited learning capability for previously unseen threats. As a result, the practical effectiveness of eBPF in fine-grained container runtime file access monitoring remains constrained. How to integrate the low-level data collection capability of eBPF with intelligent detection algorithms at the upper layer has therefore become a key research direction.

2.2. File Path Feature Modeling and Semantic Understanding

File paths inherently contain rich contextual and semantic information and have increasingly been leveraged in recent years to enhance behavior recognition in security-related scenarios. As a structured textual representation, a file path reflects hierarchical directory relationships, access intent, and operational context, making it a valuable source of semantic cues for detecting abnormal behaviors.
Kyadige et al. [25] incorporated file paths as auxiliary features for static malware detection and demonstrated that path context, such as user directories and system directories, can effectively distinguish benign and malicious samples. Lee et al. [26] constructed character-level n-gram embeddings based on FastText and employed Transformer models to capture sequential patterns in file paths. FastText computes path embeddings using the following objective function:
L = ( w , c ) D log σ ( v c v w ) + c N ( w ) log σ ( v c v w )
where v w and v c denote the vector representations of the target word and the context word, respectively, σ ( · ) is the sigmoid function, and N ( w ) represents the set of negative samples associated with w. Unlike traditional Word2Vec, FastText represents each word as a collection of character-level n-grams, which improves the embedding quality of rare words. Consequently, FastText is able to generate meaningful embeddings even for previously unseen path segments.
However, these methods are primarily designed for offline Windows file forensics or static malware analysis scenarios. They neither consider system call streams in container runtime environments nor jointly model multimodal contextual information such as container identifiers and access patterns. Moreover, existing path representations tend to focus on word-level or character-level similarity, providing limited characterization of the relationships among path hierarchy, access risk, and runtime environment. As a result, these approaches are difficult to directly transfer to online container runtime monitoring scenarios, where path-level semantic sensitivity is critical.

2.3. Autoencoder-Based Anomaly Detection Methods

Autoencoders are capable of characterizing the latent distribution of normal behaviors under unsupervised settings and have therefore been widely applied in system monitoring and anomaly detection. Wang et al. [27] proposed a BiLSTM-VAE model that integrates variational autoencoders with bidirectional LSTM networks to jointly model multidimensional monitoring metrics in container cloud environments, such as CPU utilization, I/O latency, and system call sequences, thereby enhancing the modeling of temporal anomaly patterns. The core optimization objective of the model is to minimize the reconstruction error and the Kullback–Leibler (KL) divergence:
L = E q ϕ ( z | x ) log p θ ( x | z ) D KL q ϕ ( z | x ) p ( z )
where q ϕ ( z | x ) denotes the posterior distribution of the encoder, p θ ( x | z ) represents the reconstruction distribution of the decoder, and the Kullback–Leibler (KL) divergence term D KL q ϕ ( z | x ) p ( z ) regularizes the latent space by encouraging q ϕ ( z | x ) to match the prior p ( z ) . With this objective, the model can capture multidimensional temporal dependencies while improving sensitivity to anomalous patterns. Fan et al. [28] approached anomaly detection from an interpretability perspective by clustering reconstruction errors and latent embeddings produced by autoencoders, followed by boundary search to transform the inference process into an allow-list rule library. This approach enhances interpretability in specialized IoT intrusion detection scenarios while maintaining detection performance. The core rule aggregation mechanism can be expressed as follows:
R = r ubc r 1 r 2 r n
More recently, Rao et al. proposed a Bi-Functional Autoencoder framework that generalizes autoencoders to functional representations of time series and performs two-way dimension reduction while preserving temporal structure [29]. However, most existing studies primarily focus on temporal indicators such as resource utilization, network traffic, or system call sequences, while paying limited attention to file paths, which exhibit hierarchical structures and strong semantic dependencies. Moreover, autoencoders are typically trained on pre-concatenated fixed-dimensional feature vectors, lacking explicit mechanisms to focus on critical semantic substructures within multimodal inputs. In highly concurrent container runtime environments, this limitation often leads to insufficient sensitivity to fine-grained anomalous file access behaviors, thereby degrading both detection accuracy and real-time performance.

3. System Architecture

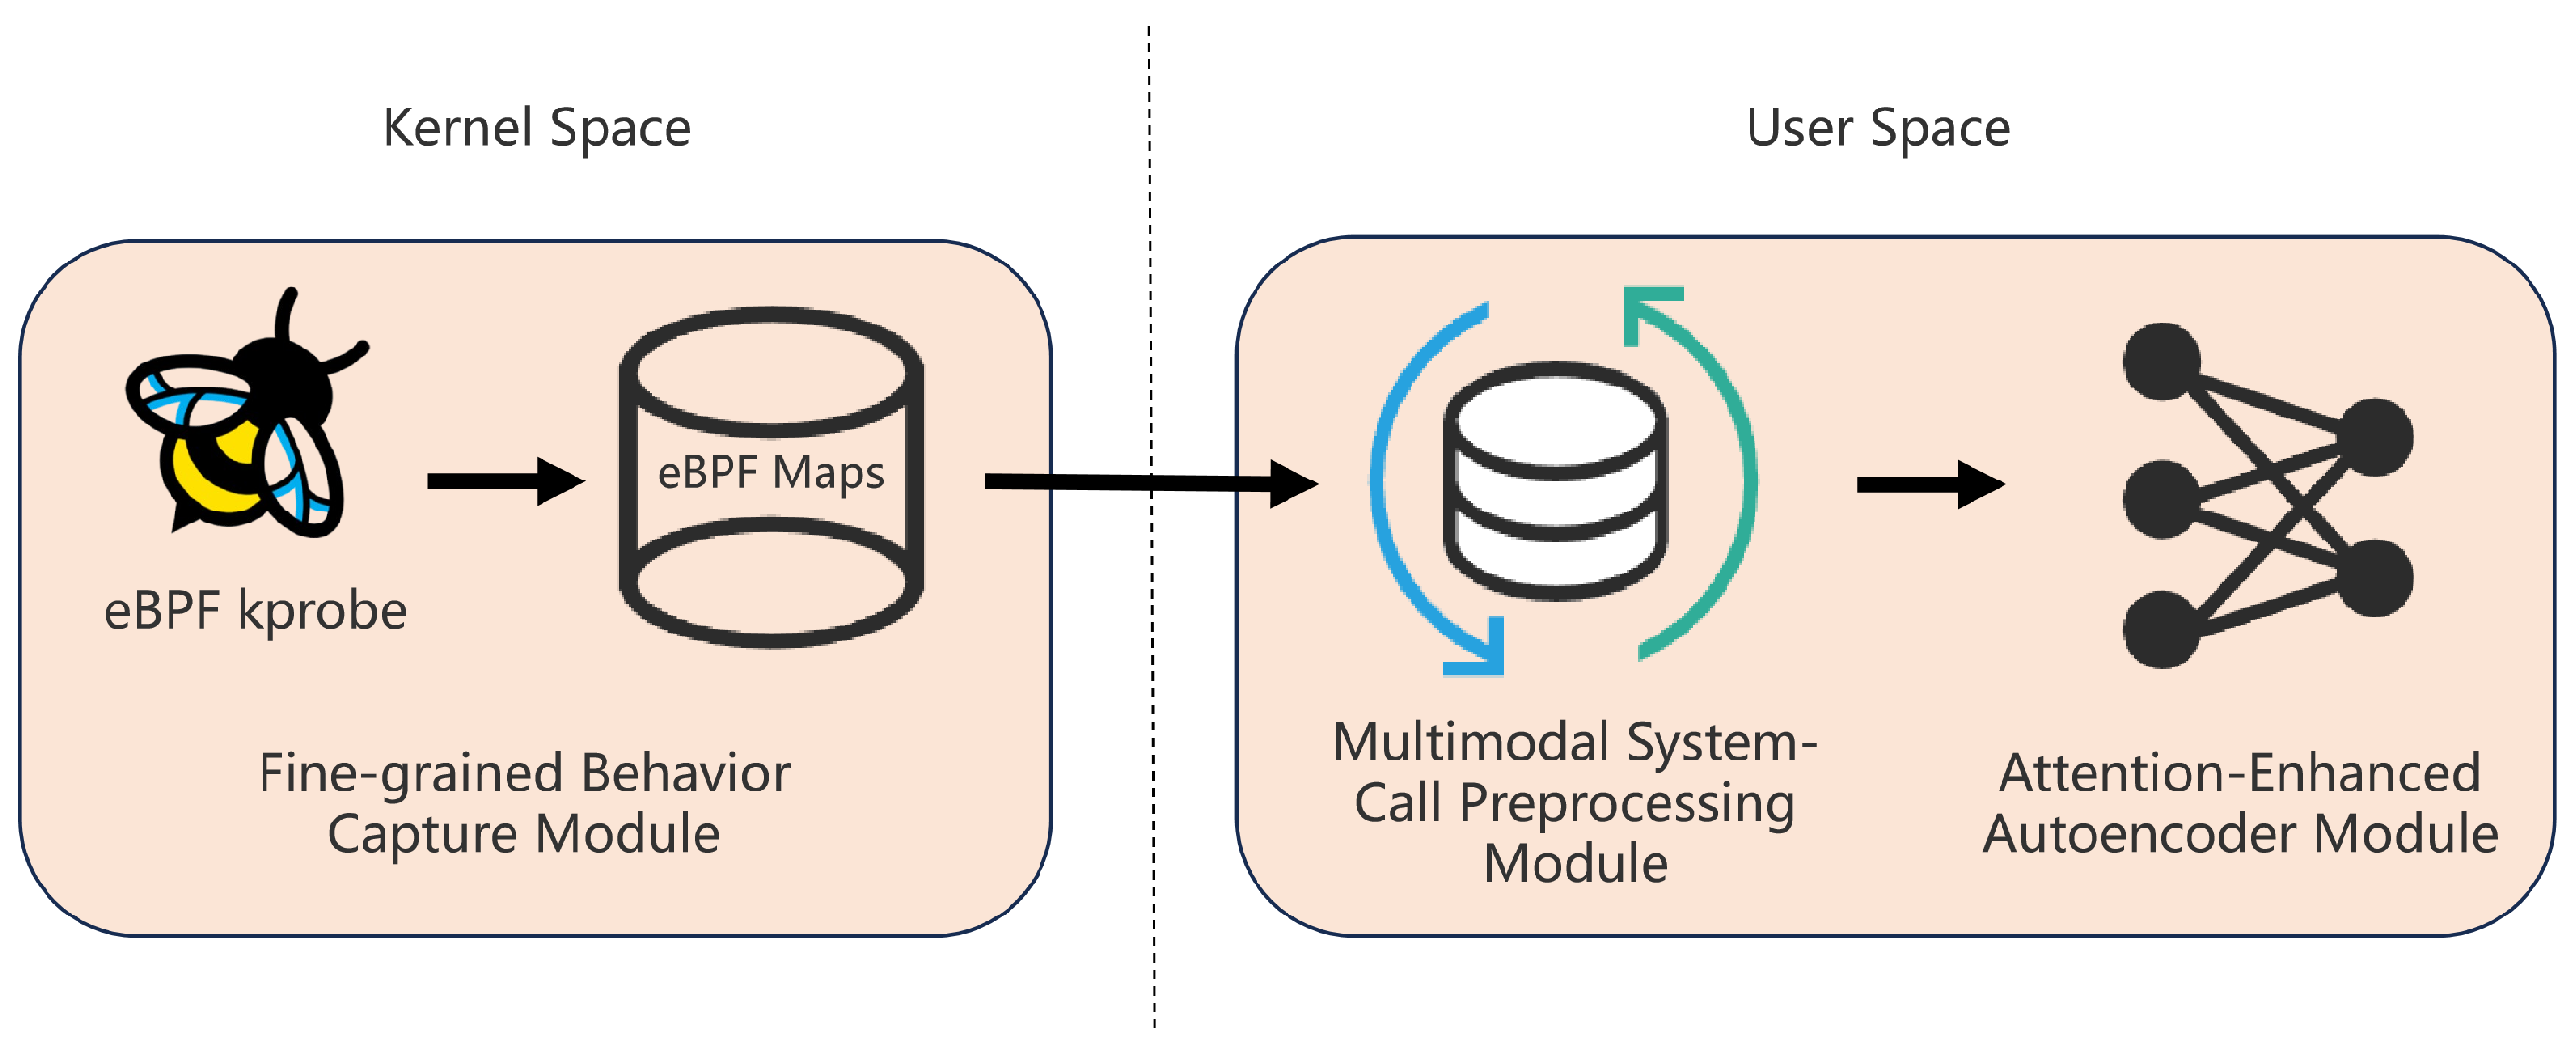
To enable real-time monitoring and high-accuracy anomaly detection of container runtime file access behaviors, we design an eBPF-based container security detection system. The system follows a core logical pipeline of behavior collection–multimodal feature representation–anomaly identification, integrating three key components: kernel-level behavior capture, path semantic modeling, and intelligent detection. Together, these components form an end-to-end monitoring and analysis workflow. As illustrated in Figure 2, the overall system architecture consists of three main modules: (i) an eBPF-based fine-grained container behavior capture module (hereafter referred to as the behavior collection module); (ii) a multimodal system call data preprocessing module with rule-based matching (hereafter referred to as the data preprocessing module); and (iii) an attention-enhanced autoencoder-based anomaly detection module (hereafter referred to as the anomaly detection module).
During system operation, the behavior collection module first leverages eBPF to non-intrusively capture container file access activities in kernel space and parse relevant system call parameters. Next, the data preprocessing module performs normalization and multimodal semantic encoding on the raw data to construct structured feature representations. Finally, the anomaly detection module models behavioral patterns using an attention-enhanced autoencoder network and analyzes reconstruction errors to intelligently identify and respond to anomalous events. The system architecture is designed to jointly balance monitoring granularity and computational efficiency, enabling high-precision anomaly detection under low runtime overhead. This architecture provides an overall framework to support the detailed implementation of each functional module and the subsequent performance evaluation presented in the following sections.

3.1. Fine-Grained Container Behavior Capture Based on eBPF

The objective of this module is to perform fine-grained and real-time monitoring of file access behaviors in container runtimes without introducing significant system overhead, thereby providing high-quality raw data for subsequent semantic modeling and anomaly detection. As the data entry point of the system, its design emphasizes a careful balance among monitoring granularity, contextual completeness, and runtime efficiency.
To this end, eBPF is adopted as the kernel-level event collection mechanism. An eBPF program is loaded into the Linux kernel and dynamically attached to critical system call paths by leveraging kprobe and the Linux Security Module (LSM) interface. Specifically, the eBPF program is attached to the security_file_open hook to intercept file access operations initiated by container processes. Compared with user-space audit log parsing or hooking at other points along the Virtual File System (VFS) path, this hook enables earlier acquisition of access intent and security-relevant parameters, while allowing direct access to kernel data structures. As a result, more complete contextual information can be obtained under relatively low performance overhead. Upon event triggering, the eBPF program synchronously extracts key metadata, including process identifiers (PID and PPID), device identifiers, inode numbers, and access flags. These attributes constitute structured inputs for downstream feature modeling. Representative extracted fields are summarized in Table 1.
File path resolution is a critical component of behavior capture. Traditional log-based analysis techniques often provide truncated or logical paths, which makes it difficult to distinguish differences caused by mount isolation or symbolic links. To improve the accuracy of path reconstruction, we design Algorithm 1, which rebuilds process-visible file paths through a bottom-up traversal of kernel dentry structures. The algorithm operates as follows. First (lines 1–3), it checks whether the input struct path pointer is valid; if not, an anonymous identifier is returned. Next (lines 4–5), the path string is initialized and the dentry node corresponding to the accessed file is obtained. Then (lines 6–19), the algorithm iteratively traverses parent dentry nodes to reconstruct the directory hierarchy by concatenating directory names in reverse order until the root directory or a mount point is reached. Finally (line 20), the reconstructed absolute path is returned. For objects that do not have conventional file paths, such as anonymous memfd files or pipes, the algorithm directly records their unique identifiers to ensure comprehensive coverage and consistency in data collection.
To accurately map kernel events to specific container instances, container identity resolution is implemented in user space. This logic extracts container identifiers by parsing the /proc/[pid]/cgroup file and leveraging naming conventions adopted by different container runtimes. By associating kernel events with container IDs, the system is able to distinguish execution contexts across concurrent containers, avoid confusion between host processes and container processes, and enhance the traceability of subsequent anomaly localization.
For data transmission between kernel space and user space, the eBPF program communicates through a ring buffer mechanism. Compared with polling-based data retrieval approaches, the ring buffer adopts an event-driven push model, in which records are written to the buffer only when file access events occur. This design significantly reduces CPU overhead caused by unnecessary polling and mitigates the cost of frequent context switches, thereby improving the overall runtime efficiency of the monitoring system.
Algorithm 1 Full File Path Reconstruction
  Input: Pointer to file path structure struct path *path
  Output: Full file path as a string
  1: if path == NULL then
  2:       return “Path not available”
  3: end if
  4: Initialize path_string as empty
  5: Set current_dentrypath->dentry
  6: while current_dentryNULL do
  7:       namecurrent_dentry->d_name
  8:       if name is not empty then
  9:              if path_string is empty then
10:                    path_stringname
11:              else
12:                    path_stringname + “/” + path_string
13:              end if
14:       end if
15:       if current_dentry is root or mount point then
16:              break
17:       end if
18:       current_dentrycurrent_dentry->d_parent
19: end while
20: return “/” + path_string

3.2. Rule-Based Preprocessing of Multimodal System Call Data

The objective of this module is to transform raw system call events captured by eBPF into structured and model-ready feature representations while preserving critical semantic information and controlling feature dimensionality. This design provides stable and high-quality inputs for subsequent anomaly detection models. Among various system call attributes, file paths serve as a core indicator of access semantics. However, due to their complex hierarchical structures and highly variable lengths, directly feeding raw paths into learning models often leads to feature sparsity, noise accumulation, or semantic drift. Therefore, specialized structural modeling and semantic representation tailored to path characteristics are required.
To address these challenges, we propose a two-stage path feature representation mechanism consisting of: (1) Structural Hierarchy Normalization and Six-Segment Encoding and (2) semantic vectorization encoding. This mechanism compresses redundant structural information while retaining essential semantic cues, ensuring that paths of different types remain comparable at the model input stage.

3.2.1. Structural Hierarchy Normalization and Six-Segment Encoding

File paths are treated as ordered sequences of semantic units organized in a tree-like hierarchical structure and segmented according to the delimiter “/”. Given that file paths exhibit heterogeneous security sensitivity, we construct a risk-aware classification scheme that categorizes paths into three levels: high risk, medium risk, and low risk. For each risk level, a differentiated truncation strategy is applied, as summarized in Table 2.
To ensure structural consistency and fixed-dimensional representation, all processed paths are normalized into a fixed-length structural encoding
P = [ s 1 , s 2 , s 3 , s 4 , s 5 , s 6 ]
where each s i represents a structural segment after risk-driven truncation and normalization.
  • Fixed-Length Constraint
Regardless of the original path length L, the output representation is restricted to six segments:
-
If L > 6 , risk-aware truncation rules determine which segments are retained;
-
If L < 6 , padding markers are appended until the length equals six.
  • Structural Marker System
To preserve structural information lost during truncation, we introduce explicit structural markers:
-
T R U N C indicates hierarchy truncation;
-
P A D indicates padding for length normalization;
-
A N O M indicates structural irregularity;
-
A M B indicates ambiguous hierarchy.
These markers are treated as learnable tokens in the embedding space, allowing the model to capture both preserved and omitted structural cues.
  • Example
Consider a high-risk path:
/usr/lib/docker/overlay2/abc123/diff/etc/shadow
After tail-priority truncation, the most security-relevant segments are retained. The normalized six-segment encoding becomes:
[ T R U N C , o v e r l a y 2 , d i f f , e t c , s h a d o w , s h a d o w ]
For a medium-risk path such as:
/etc/systemd/system/docker.service
The resulting encoding follows the “ 3 + 2 ” rule and padding strategy:
[ e t c , s y s t e m d , s y s t e m , d o c k e r . s e r v i c e , P A D , P A D ]
This unified representation ensures that all paths are mapped to a consistent six-segment structural space while preserving hierarchical salience.

3.2.2. Path Semantic Vectorization

After structural normalization, paths are further modeled as sequences of segments to capture semantic relationships among path components. Each path segment is vectorized using Word2Vec, which learns semantic associations between segments based on contextual co-occurrence, allowing semantically similar path segments to be embedded closer in the vector space. Let a file path be denoted as p = { w 1 , w 2 , , w | p | } , where w i represents a path segment obtained after hierarchical segmentation and normalization with padding. The overall embedding of the path is computed as the average of the segment embeddings:
Embedding ( p ) = 1 | p | i = 1 | p | Word 2 Vec ( w i )
This representation captures both the hierarchical structure and semantic correlations among path segments. Finally, the path semantic embedding is fused with numerical features and binary container identity features to form a unified high-dimensional input representation, providing semantically rich and structurally stable inputs for the subsequent anomaly detection model.

3.3. Attention-Enhanced Autoencoder for Anomaly Detection

Traditional autoencoders struggle to capture long-range dependencies among path segments in file path sequence modeling and lack explicit mechanisms to focus on multimodal features, which limits detection accuracy in complex access scenarios. To address these limitations, we introduce a path attention mechanism into the autoencoder architecture, enabling dynamic feature weighting to enhance semantic awareness and anomaly identification capability.
The overall model consists of an input layer, a path attention layer, an encoder, a decoder, and an anomaly scoring module. After multimodal feature preprocessing, the input is first fed into the path attention layer to obtain a semantically weighted representation, which is then compressed and reconstructed by the autoencoder to identify and quantify anomalous behaviors.
In the path attention mechanism, a file path is assumed to consist of n segments, where each segment is represented by a vector e i . For each path segment, the attention layer assigns a scalar importance weight α i , which reflects its contribution in the semantic space and is computed as:
α i = exp score ( e i ) j = 1 n exp score ( e j )
where score ( · ) denotes a learnable similarity function. After weighted aggregation, the global path representation is obtained as:
e attn = i = 1 n α i e i
The resulting semantically weighted vector highlights features associated with potentially high-risk path segments and provides a more discriminative input for subsequent feature encoding.
During the encoding and decoding stages, the model adopts a three-layer symmetric architecture, in which nonlinear mappings are employed to achieve feature compression and reconstruction. The encoder maps the attention-weighted input vector into a 32-dimensional latent space to learn normal behavioral patterns of system calls:
h = f W e ( 3 ) f W e ( 2 ) f W e ( 1 ) x + b e ( 1 ) + b e ( 2 ) + b e ( 3 )
where x denotes the input sample, h represents the latent vector, W e ( i ) and b e ( i ) denote the weight matrix and bias of the i-th encoder layer, respectively, and f ( · ) is the Leaky ReLU activation function, which is adopted to mitigate the “dying ReLU” problem commonly observed in standard ReLU.
The decoder reconstructs the input features through a reverse mapping from the latent space:
x ^ = g W d ( 3 ) g W d ( 2 ) g W d ( 1 ) h + b d ( 1 ) + b d ( 2 ) + b d ( 3 )
where x ^ denotes the reconstructed output, W d ( i ) and b d ( i ) are the parameters of the i-th decoder layer, and g ( · ) is also implemented as the Leaky ReLU activation function.
The model adopts the mean squared error (MSE) as the primary anomaly metric to quantify the discrepancy between the input features and their reconstructed outputs. The MSE is defined as follows:
MSE = 1 n i = 1 n x i x ^ i 2
where n denotes the feature dimensionality, and x i and x ^ i represent the i-th elements of the input vector and the reconstructed vector, respectively. By minimizing the MSE loss, the model iteratively optimizes its parameters to ensure that the reconstructed output closely approximates the input representation.
To further enhance sensitivity to critical semantic information, we introduce a weighted reconstruction strategy in the loss computation, in which path-related features are assigned higher weights. This design encourages the model to focus more strongly on semantically important path components, thereby improving the precision of anomaly detection.

4. Experimental Design and Analysis

4.1. Dataset

To evaluate the performance of the proposed eBPF-based container behavior monitoring system and assess the detection accuracy of the attention-enhanced autoencoder model, a dedicated experimental environment was constructed in this study.
  • Software environment: The experimental platform ran Ubuntu 22.04 with Linux Kernel version 6.5.0-45-generic, which provides enhanced support for eBPF functionalities. Docker version 27.3 was used for container management, and cgroups were downgraded to v1 at runtime to reproduce specific vulnerability scenarios.
  • Hardware environment: The experimental host was equipped with a 13th Gen Intel(R) Core(TM) i5-13490F processor and an NVIDIA GeForce RTX 3060 Ti GPU, ensuring stable performance under high-concurrency workloads.
The experimental objective was to detect anomalous system call behaviors related to file access paths. Following the experimental design and data collection methodology proposed by Guo et al. [30] for container zero-day attack analysis, two independent datasets were constructed and utilized in this study.
The first dataset, denoted as Data_normal, records approximately five hours of normal container operation logs, covering common container activities such as container startup and termination, image pulling and updating, configuration file reading and writing, volume mounting, and data interaction. According to the experimental settings, this dataset contains approximately 18,000 system call events. Data_normal was used during the training phase to establish a baseline of normal system behavior.
The second dataset, referred to as Data_abnormal, was employed for model evaluation and contains approximately 90 min of system call records. The first 60 min corresponds to normal operational behavior, while anomalous behaviors were injected during the remaining 30 min to simulate realistic attack scenarios in container runtime environments. During the anomalous phase, a total of 15 complete container escape attack events were reproduced, with each event representing a full attack chain.
Specifically, three representative container escape attacks were injected:
  • Abuse of the release_agent mechanism in cgroups v1 (CVE-2022-0492 [31]);
  • System resource manipulation caused by reference count errors in scheduler debugging paths (CVE-2022-48699 [32]);
  • Privilege escalation and control-flow hijacking in Kubernetes environments via sensitive paths such as /proc/self/exe (CVE-2022-0811 [33]).
Each type of attack was executed five times to maintain a relatively balanced distribution across attack categories and to avoid bias toward any single attack pattern.
In the experimental design, the model was trained in an unsupervised manner using only the Data_normal dataset to learn baseline patterns of normal system behavior. Subsequently, inference and anomaly detection were performed on the Data_abnormal dataset to evaluate the model’s ability to identify unknown threats and its robustness in realistic deployment scenarios.
This experimental setup closely simulates real-world container runtime environments, ensuring that the proposed method can construct behavior baselines solely from normal data and perform real-time detection and decision-making for anomalous events during deployment.
  • Limitations and representativeness: Although the constructed dataset covers three representative container escape attack categories and includes multiple repeated executions, it still has limitations. First, the normal workload mainly reflects typical container management and file-access behaviors on a single host environment; additional workloads (e.g., database-intensive or microservice deployments) may introduce different path distributions. Second, the attack scenarios focus on file-access-related escape chains under a specific kernel and container runtime configuration; evaluating more kernel versions, container runtimes, and attack families is an important direction for future work. Nevertheless, because our method is trained only on normal behavior and relies on semantic-aware path modeling rather than attack signatures, the proposed framework is expected to generalize to unseen attacks that manifest as abnormal file-access patterns.

4.2. System Monitoring Performance Evaluation

To validate the high-performance characteristics of eBPF in system call data collection and to evaluate its real-time capability and resource overhead under high-load conditions, a system performance comparison experiment was designed and conducted in this section. The stress testing was performed using the alexeiled/stress-ng container obtained from Docker Hub, which continuously imposed workload pressure on the target host for 15 min to simulate container runtime scenarios under high concurrency.
During the experiment, system performance metrics were sampled at one-second intervals, resulting in a total of 900 monitoring records. Performance data were collected using the Linux system activity reporting tool sar, including key indicators such as CPU utilization, disk transfers per second (tps), disk I/O throughput, and memory resource usage.
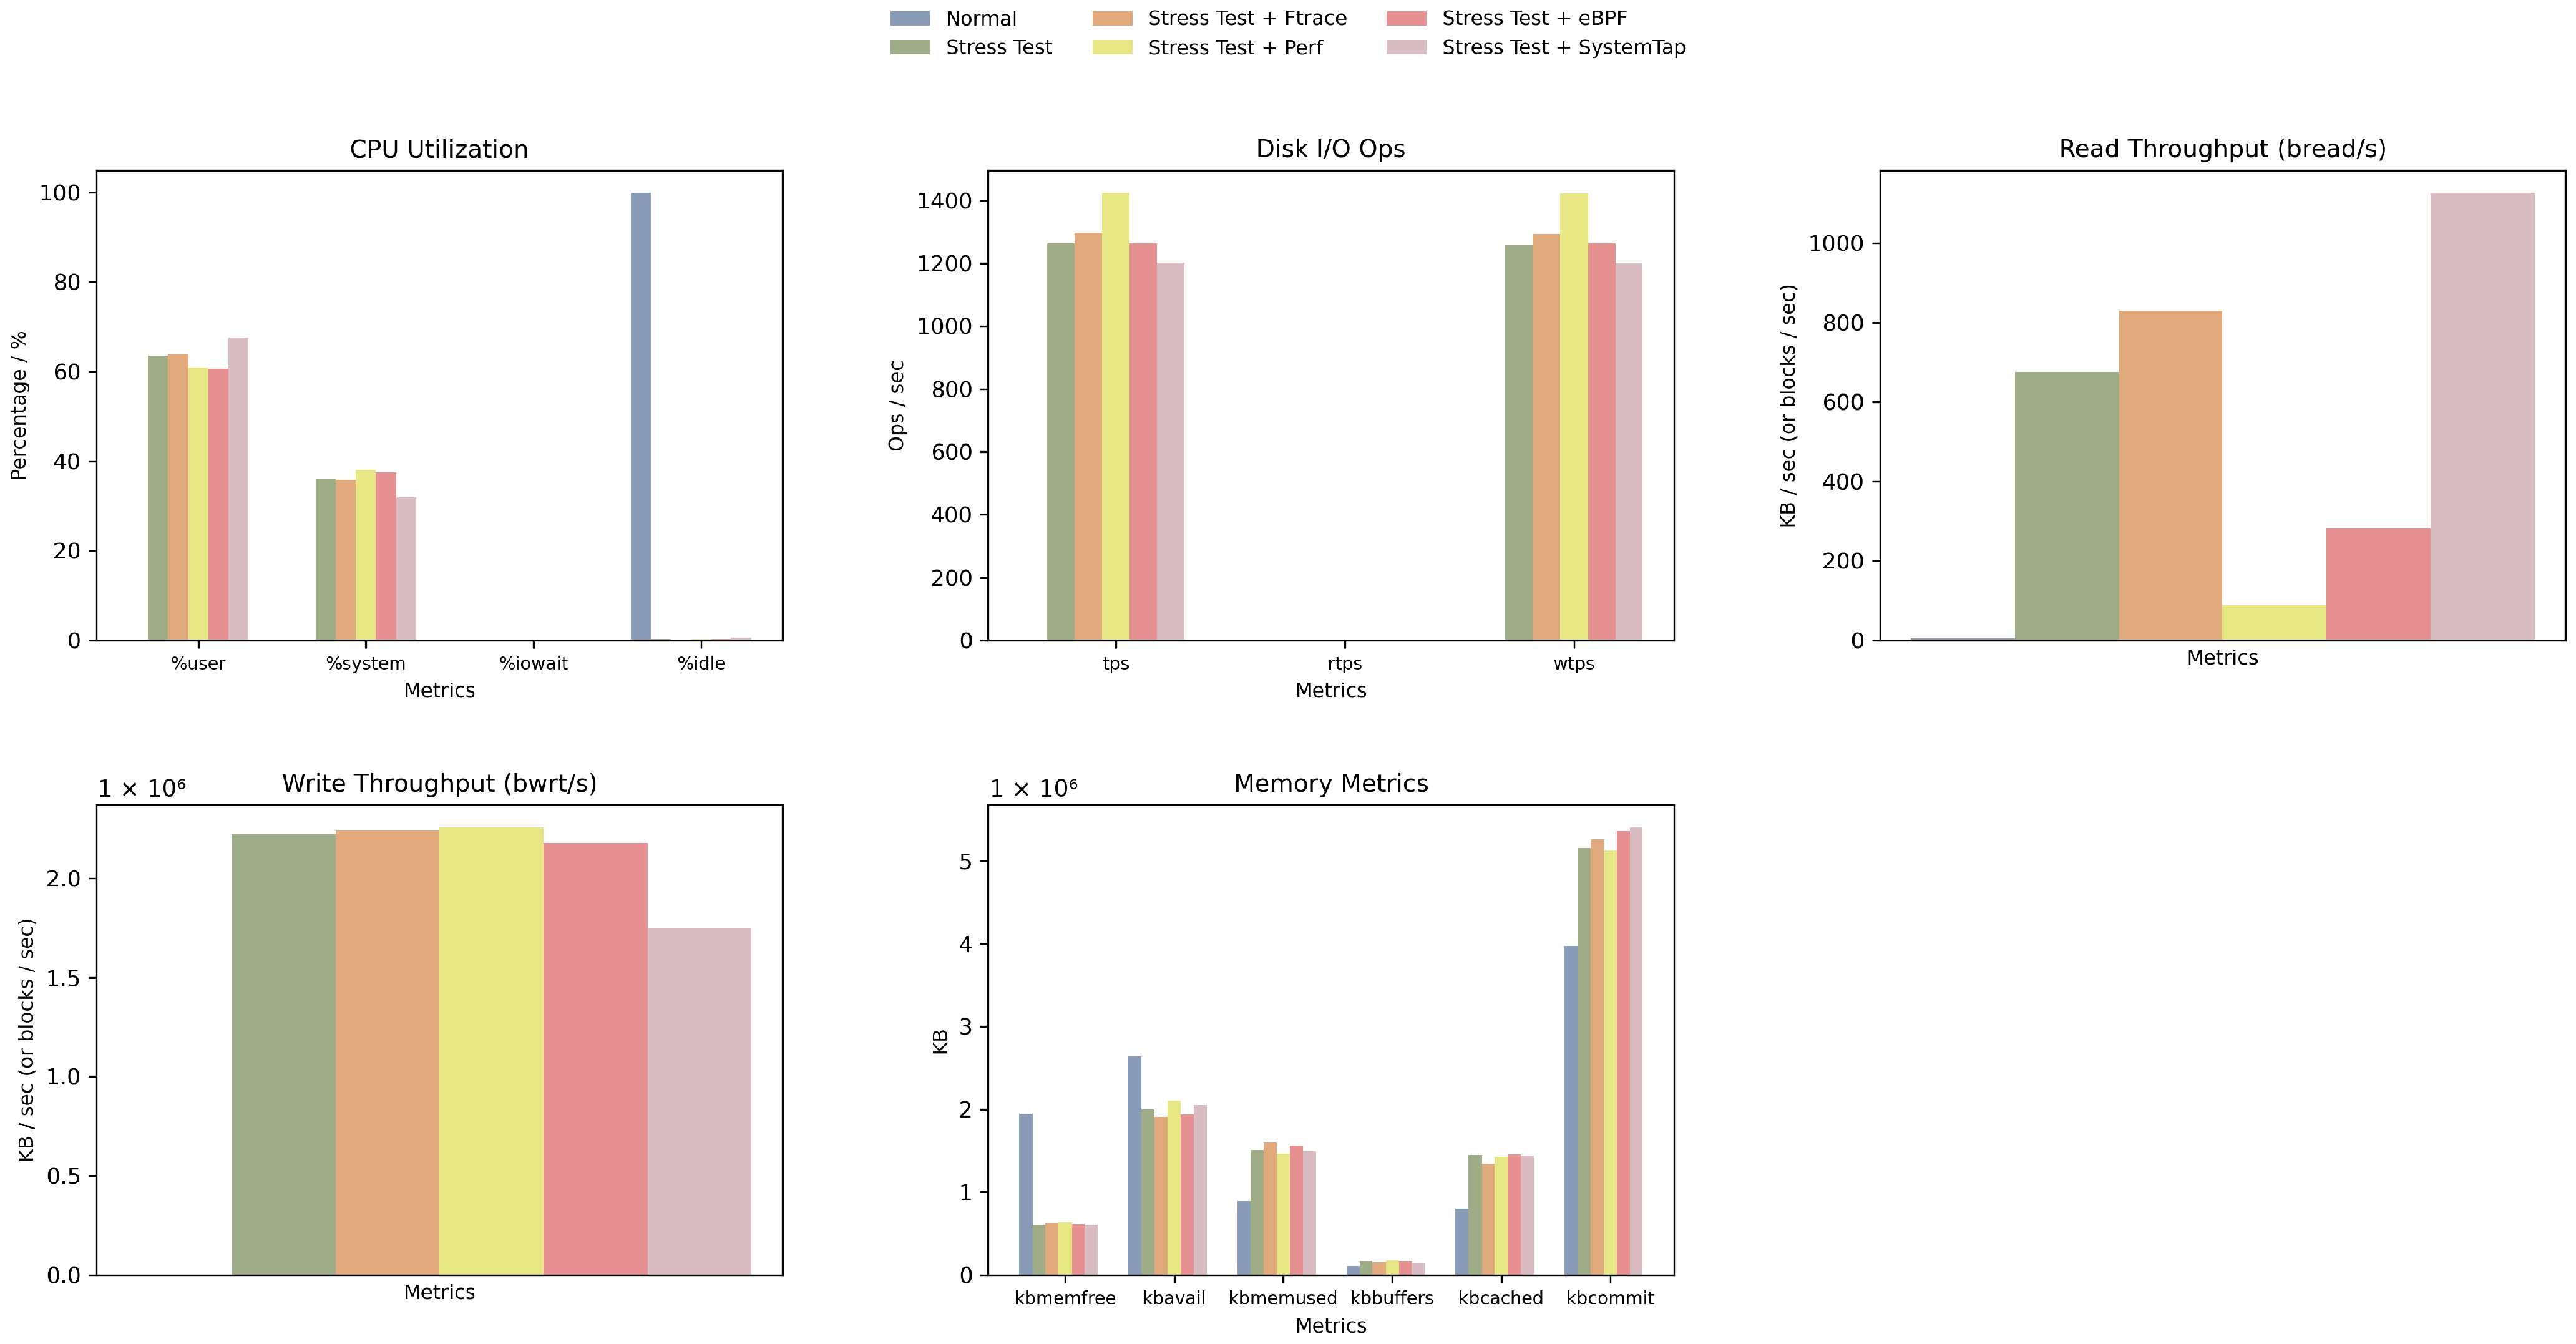
To comprehensively assess the monitoring performance of eBPF, three widely used kernel-level tracing and performance analysis tools [34] were selected for comparison: Ftrace [35], Perf [36], and SystemTap [37]. Figure 3 presents the system performance comparison results under different experimental settings.
Overall, all monitoring tools introduced a certain degree of system overhead under high-load conditions. However, eBPF exhibited the most favorable balance between monitoring effectiveness and resource consumption. From the perspective of CPU utilization, the proportions of user-space and kernel-space CPU usage introduced by eBPF were approximately 60 % and 37 % , respectively, which are lower than those observed for SystemTap and Perf.
This advantage can be attributed primarily to the event-driven execution model of eBPF in the kernel, which avoids frequent user–kernel context switching and thus reduces additional scheduling overhead in high-frequency system call monitoring scenarios. The CPU idle rate remained at approximately 0.3 % , indicating that eBPF can maintain good real-time responsiveness and system stability even under high-concurrency workloads.
In terms of I/O performance, eBPF achieved higher disk transfers per second (tps) and disk write throughput (bwrt/s) than SystemTap, while demonstrating performance comparable to Ftrace and Perf. This result indicates that eBPF provides high throughput and low latency in scenarios involving frequent file access operations.
Regarding memory usage, eBPF maintained relatively high levels of available memory and cache hit rates, suggesting improved efficiency in data transmission and cache management. Taken together, eBPF demonstrates a more balanced system performance across CPU, I/O, and memory dimensions. These results confirm the efficiency and low-overhead characteristics of eBPF as a container runtime monitoring framework, providing stable performance support for the subsequent anomaly detection model.

4.3. Model Parameters and Feature Embedding Experiments

To further improve the overall performance of the anomaly detection system, this section conducts experimental analysis from two perspectives: feature-level representation optimization and model-level structural optimization. Specifically, we investigate the impact of Word2Vec embedding parameters and autoencoder hyperparameters on detection performance.

4.3.1. Path Embedding Model Parameter Optimization

In system call data, file access paths constitute one of the most semantically complex features. To obtain high-quality vector representations of file paths, systematic comparative experiments were conducted on three key Word2Vec parameters: vector size (vector_size), context window size (window_size), and minimum word frequency (min_count).
For each parameter combination, a Word2Vec model was trained using the same set of path samples. The Average Cosine Similarity was adopted as the primary evaluation metric, which measures semantic consistency by computing the average cosine similarity between all path segment vectors. A higher value indicates that semantically similar path segments are mapped closer in the embedding space, reflecting stronger semantic representation capability.
Table 3 summarizes the top ten parameter configurations ranked by Average Cosine Similarity. The results reveal a clear trend: increasing the embedding dimensionality (vector_size) consistently improves semantic representation capability.
A moderate window size (window_size = 3 or 5) provides a favorable balance between local contextual dependency and global semantic coherence. When the window size becomes excessively large, contextual noise may weaken the semantic discrimination ability of the embeddings.
Furthermore, larger min_count values tend to eliminate low-frequency but potentially security-relevant path segments, leading to a measurable decrease in semantic similarity. Among all tested configurations, (vector_size = 100, window_size = 3, min_count = 1) achieves the highest performance with an Average Cosine Similarity of 0.4460. This configuration is therefore selected for subsequent anomaly detection experiments.

4.3.2. Autoencoder Hyperparameters and Threshold Determination

To evaluate the performance of the autoencoder under different hyperparameter configurations, experiments were conducted on the dataset processed with Word2Vec vectorization. During the training phase, the number of epochs was set to 100, and the batch size was fixed at 32. An early stopping mechanism was employed with a patience value of 50 to prevent overfitting and improve training efficiency. Training was automatically terminated when no significant improvement in validation loss was observed over 50 consecutive epochs.
The mean squared error (MSE) was adopted as the loss function, and the Adam optimizer was used for parameter optimization. In addition, L2 regularization and a dynamic learning rate scheduling strategy were incorporated to further enhance model stability.
After training, the model performed inference on the test dataset, and anomalous behaviors were identified based on reconstruction errors. Let the reconstruction error of sample i be defined as:
E i = x i x ^ i 2 2
where x i denotes the original input vector and x ^ i is its reconstructed output produced by the autoencoder.
  • Threshold Determination
To determine the anomaly decision boundary in a systematic manner, the threshold τ is computed using statistics derived from the training (normal) dataset:
τ = μ t r a i n + n σ t r a i n
where μ t r a i n and σ t r a i n denote the mean and standard deviation of reconstruction errors calculated over normal training samples, and n is a tunable threshold coefficient.
A test sample is classified as anomalous if:
E i > τ
This statistical thresholding strategy is widely adopted in unsupervised reconstruction-based anomaly detection, as it adaptively adjusts the decision boundary according to the dispersion of normal behavior patterns. The parameter n directly controls the trade-off between detection sensitivity and false-positive rate.
To quantitatively evaluate anomaly detection performance, Recall, false-positive rate (FPR), and Matthews correlation coefficient (MCC) were adopted as evaluation metrics. These metrics are defined as follows, where TP , TN , FP , and FN denote true positives, true negatives, false positives, and false negatives, respectively:
Recall = TP TP + FN
FPR = FP FP + TN
MCC = TP × TN FP × FN ( TP + FP ) ( TP + FN ) ( TN + FP ) ( TN + FN )
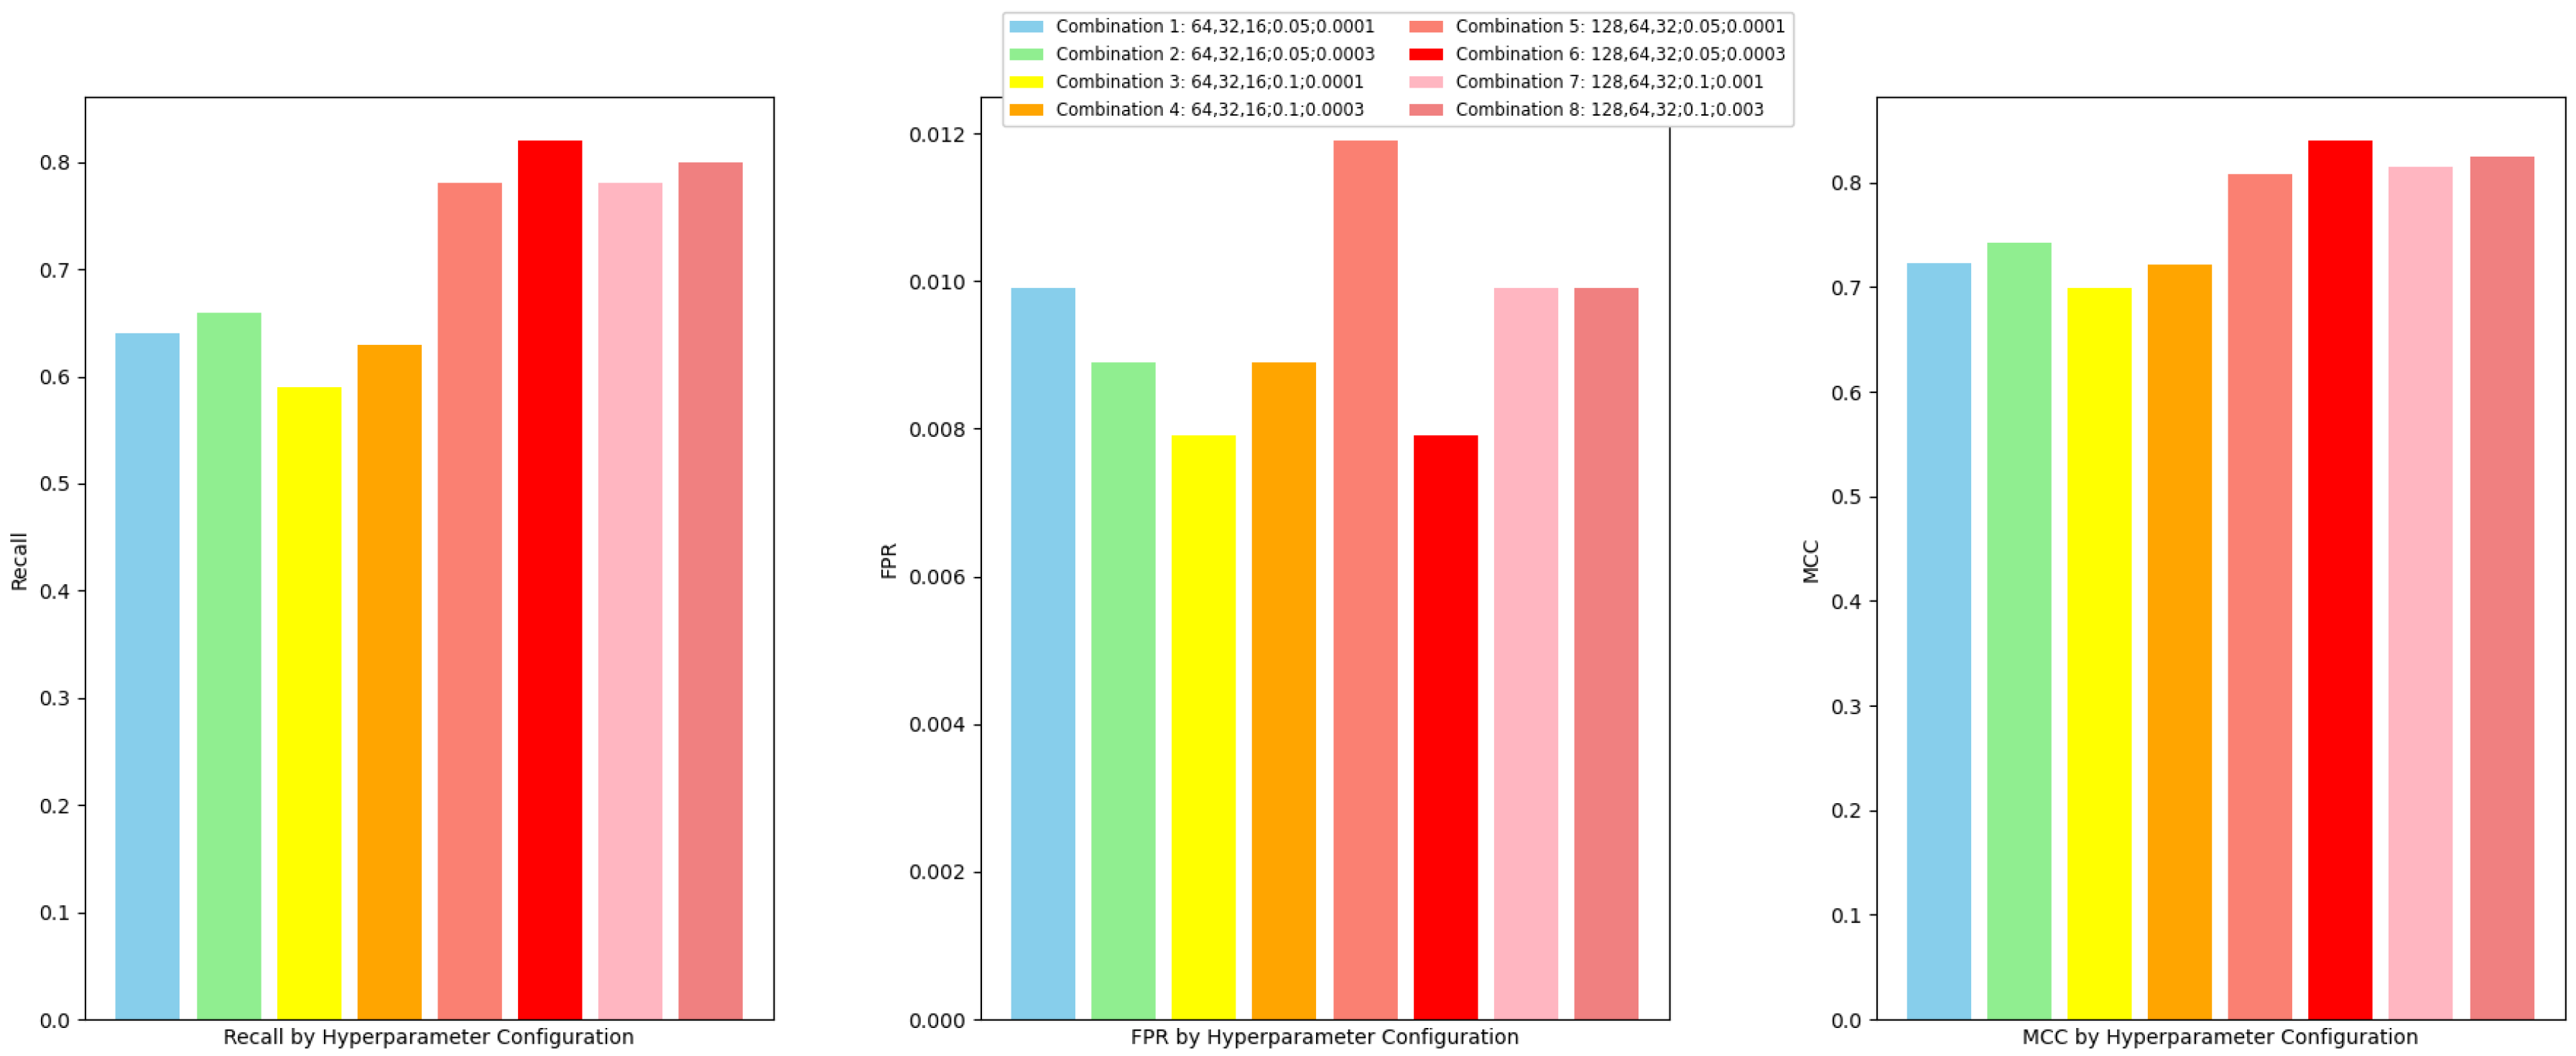
In the hyperparameter configuration experiments, performance comparisons were mainly conducted across different combinations of the number of hidden neurons, dropout rate, and learning rate. Figure 4 illustrates the model performance under eight representative parameter configurations in terms of Recall, FPR, and MCC.
The experimental results indicate that the model achieves optimal performance when the hidden layer structure is configured as [128, 64, 32], the dropout rate is set to 0.05, and the learning rate is 0.0003. Under this configuration, the recall reaches 0.82, the false-positive rate is reduced to 0.0079, and the MCC attains 0.8518. This result demonstrates that a higher neuron capacity combined with a moderate learning rate enables the model to effectively balance detection accuracy and training stability.
In contrast, when the hidden layer configuration is reduced to [64, 32, 16], the overall detection performance degrades significantly. Although the model still retains a certain level of detection capability (Recall = 0.66), its effectiveness is notably lower compared with the optimal configuration.
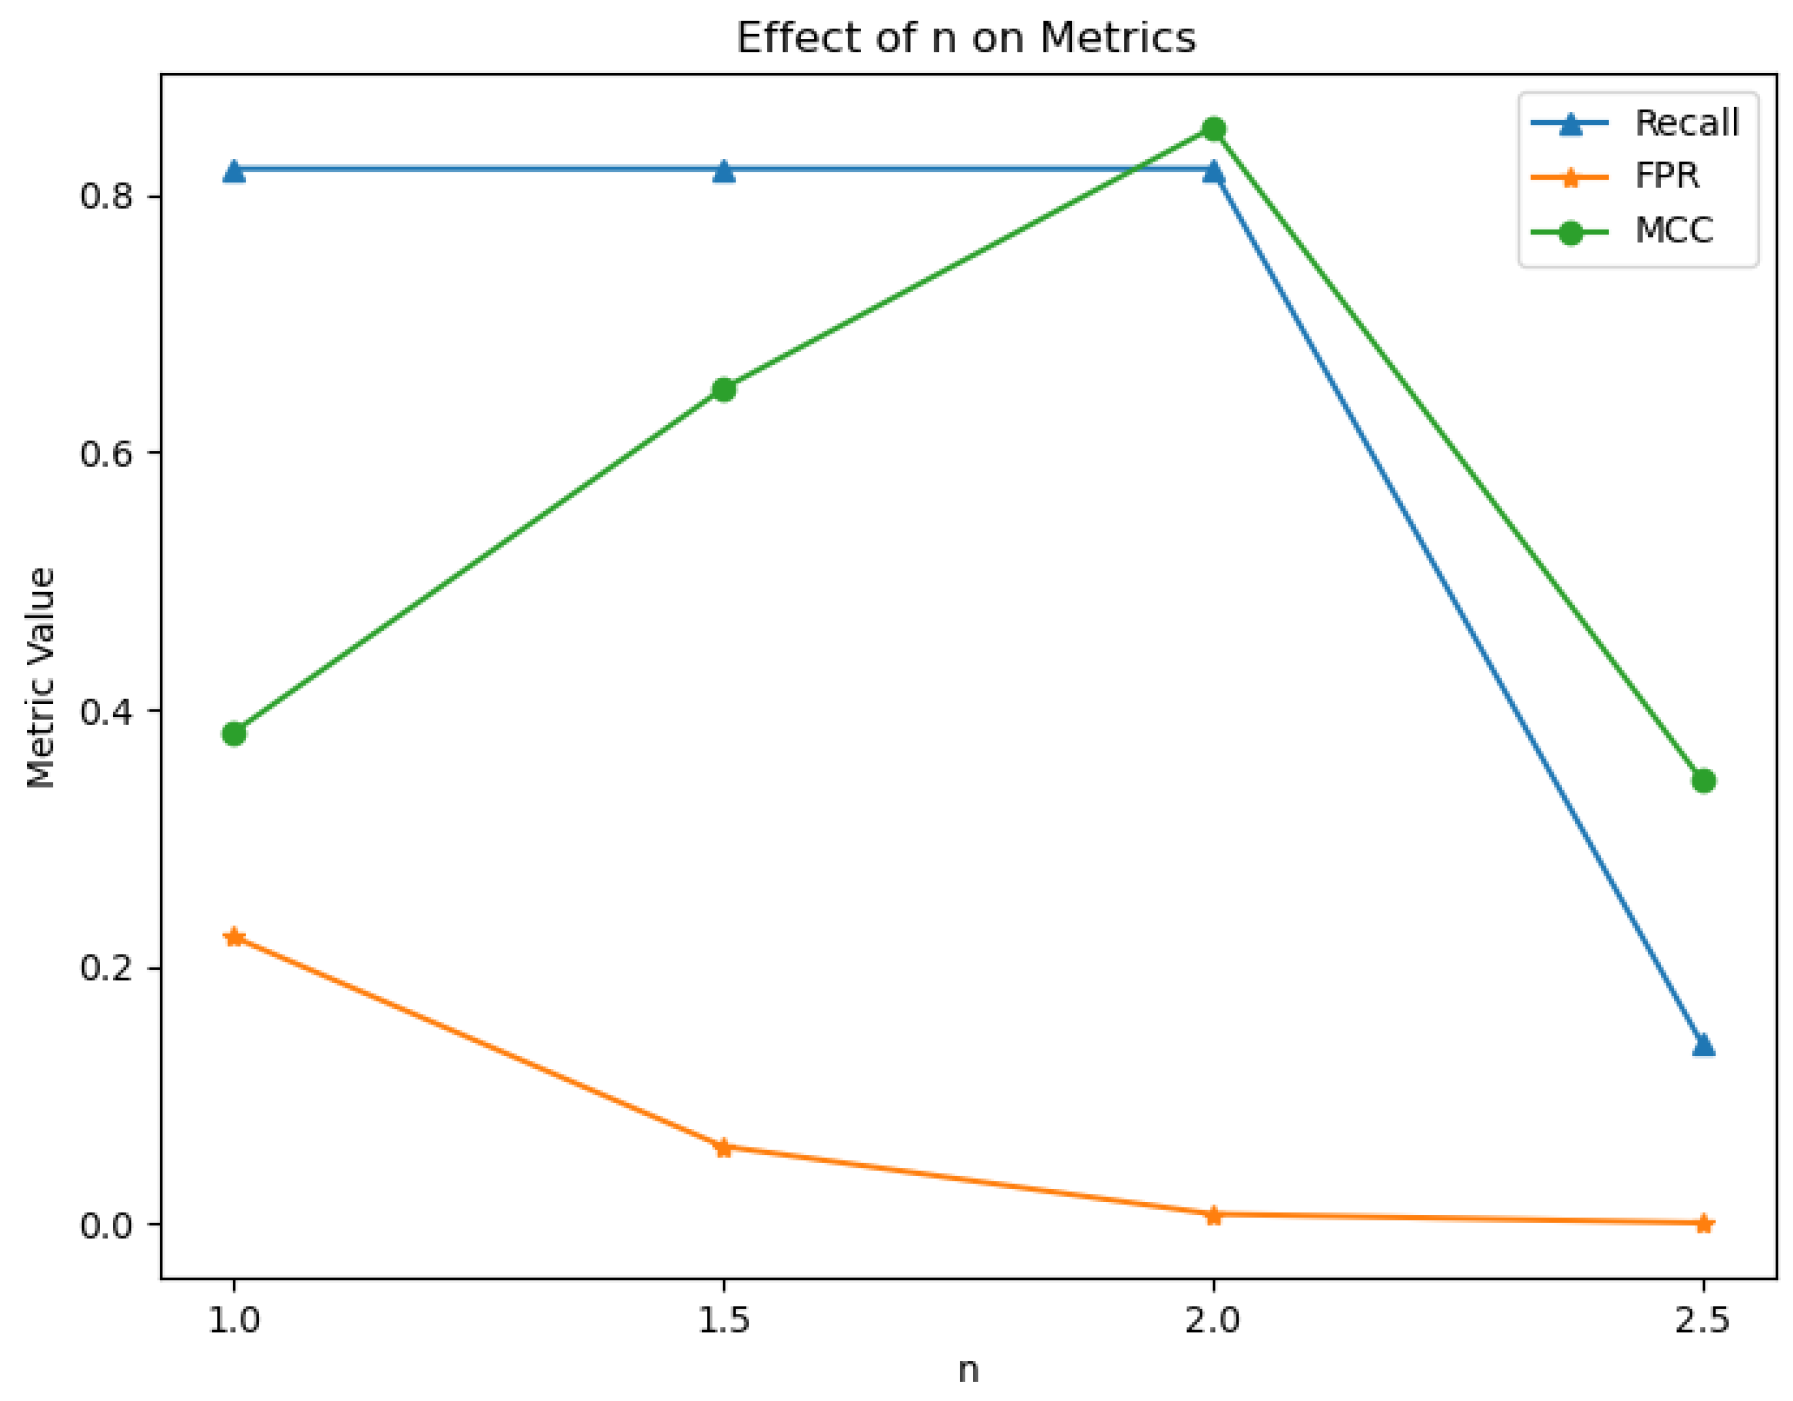
To further investigate the influence of the threshold coefficient n in the above decision rule, we compared detection results under different threshold settings, as shown in Figure 5. It can be observed that when n increases from 1 to 2, the model maintains a high recall, while the false positive rate (FPR) decreases markedly with increasing n. Meanwhile, the Matthews correlation coefficient (MCC) improves and reaches its peak at n = 2 . This indicates that a moderate increase in the threshold can effectively reduce false alarms and enhance the robustness and overall detection performance of the model. This is because the threshold τ explicitly defines the decision boundary in the reconstruction-error space; in an unsupervised setting, it plays a key role in regulating the sensitivity of anomaly identification. However, when n is further increased to 2.5, the recall drops sharply to 0.14, suggesting that the model becomes substantially less sensitive to anomalous samples under this condition. Therefore, n = 2 is selected as the optimal configuration for our experiments.
These results further demonstrate the stability and tunability of the proposed attention-enhanced autoencoder across multiple parameter settings. By appropriately selecting the network architecture and threshold parameter, the model achieves a favorable trade-off between high recall and low false positive rate in the container file-access anomaly detection task, providing reliable guidance for subsequent deployment and real-time monitoring.

4.4. Comparative Analysis of Anomaly Detection Performance

To further validate the effectiveness of the proposed attention-enhanced autoencoder (AEA) in container file-access anomaly detection, we compare it with three widely adopted unsupervised baselines: Isolation Forest (IF), One-Class SVM (OCSVM), and Local Outlier Factor (LOF). These baselines represent three complementary anomaly detection paradigms—partition-based, boundary-based, and density-based—thus providing a representative non-neural benchmark for our reconstruction-based model.
For a fair comparison, all methods use the same input feature vectors (including the Word2Vec-based path embeddings) and follow the same train/test protocol: models are trained solely on Data_normal and evaluated on Data_abnormal, which contains injected container escape attacks. For the proposed AEA, anomalies are detected using the reconstruction-error thresholding rule defined in Section 4.3.2 with n = 2 . For the classical baselines, an anomaly score is first computed for each sample and the decision thresholds are calibrated using normal training data to control false alarms.
Table 4 summarizes the quantitative comparison in terms of Recall, FPR, and MCC.
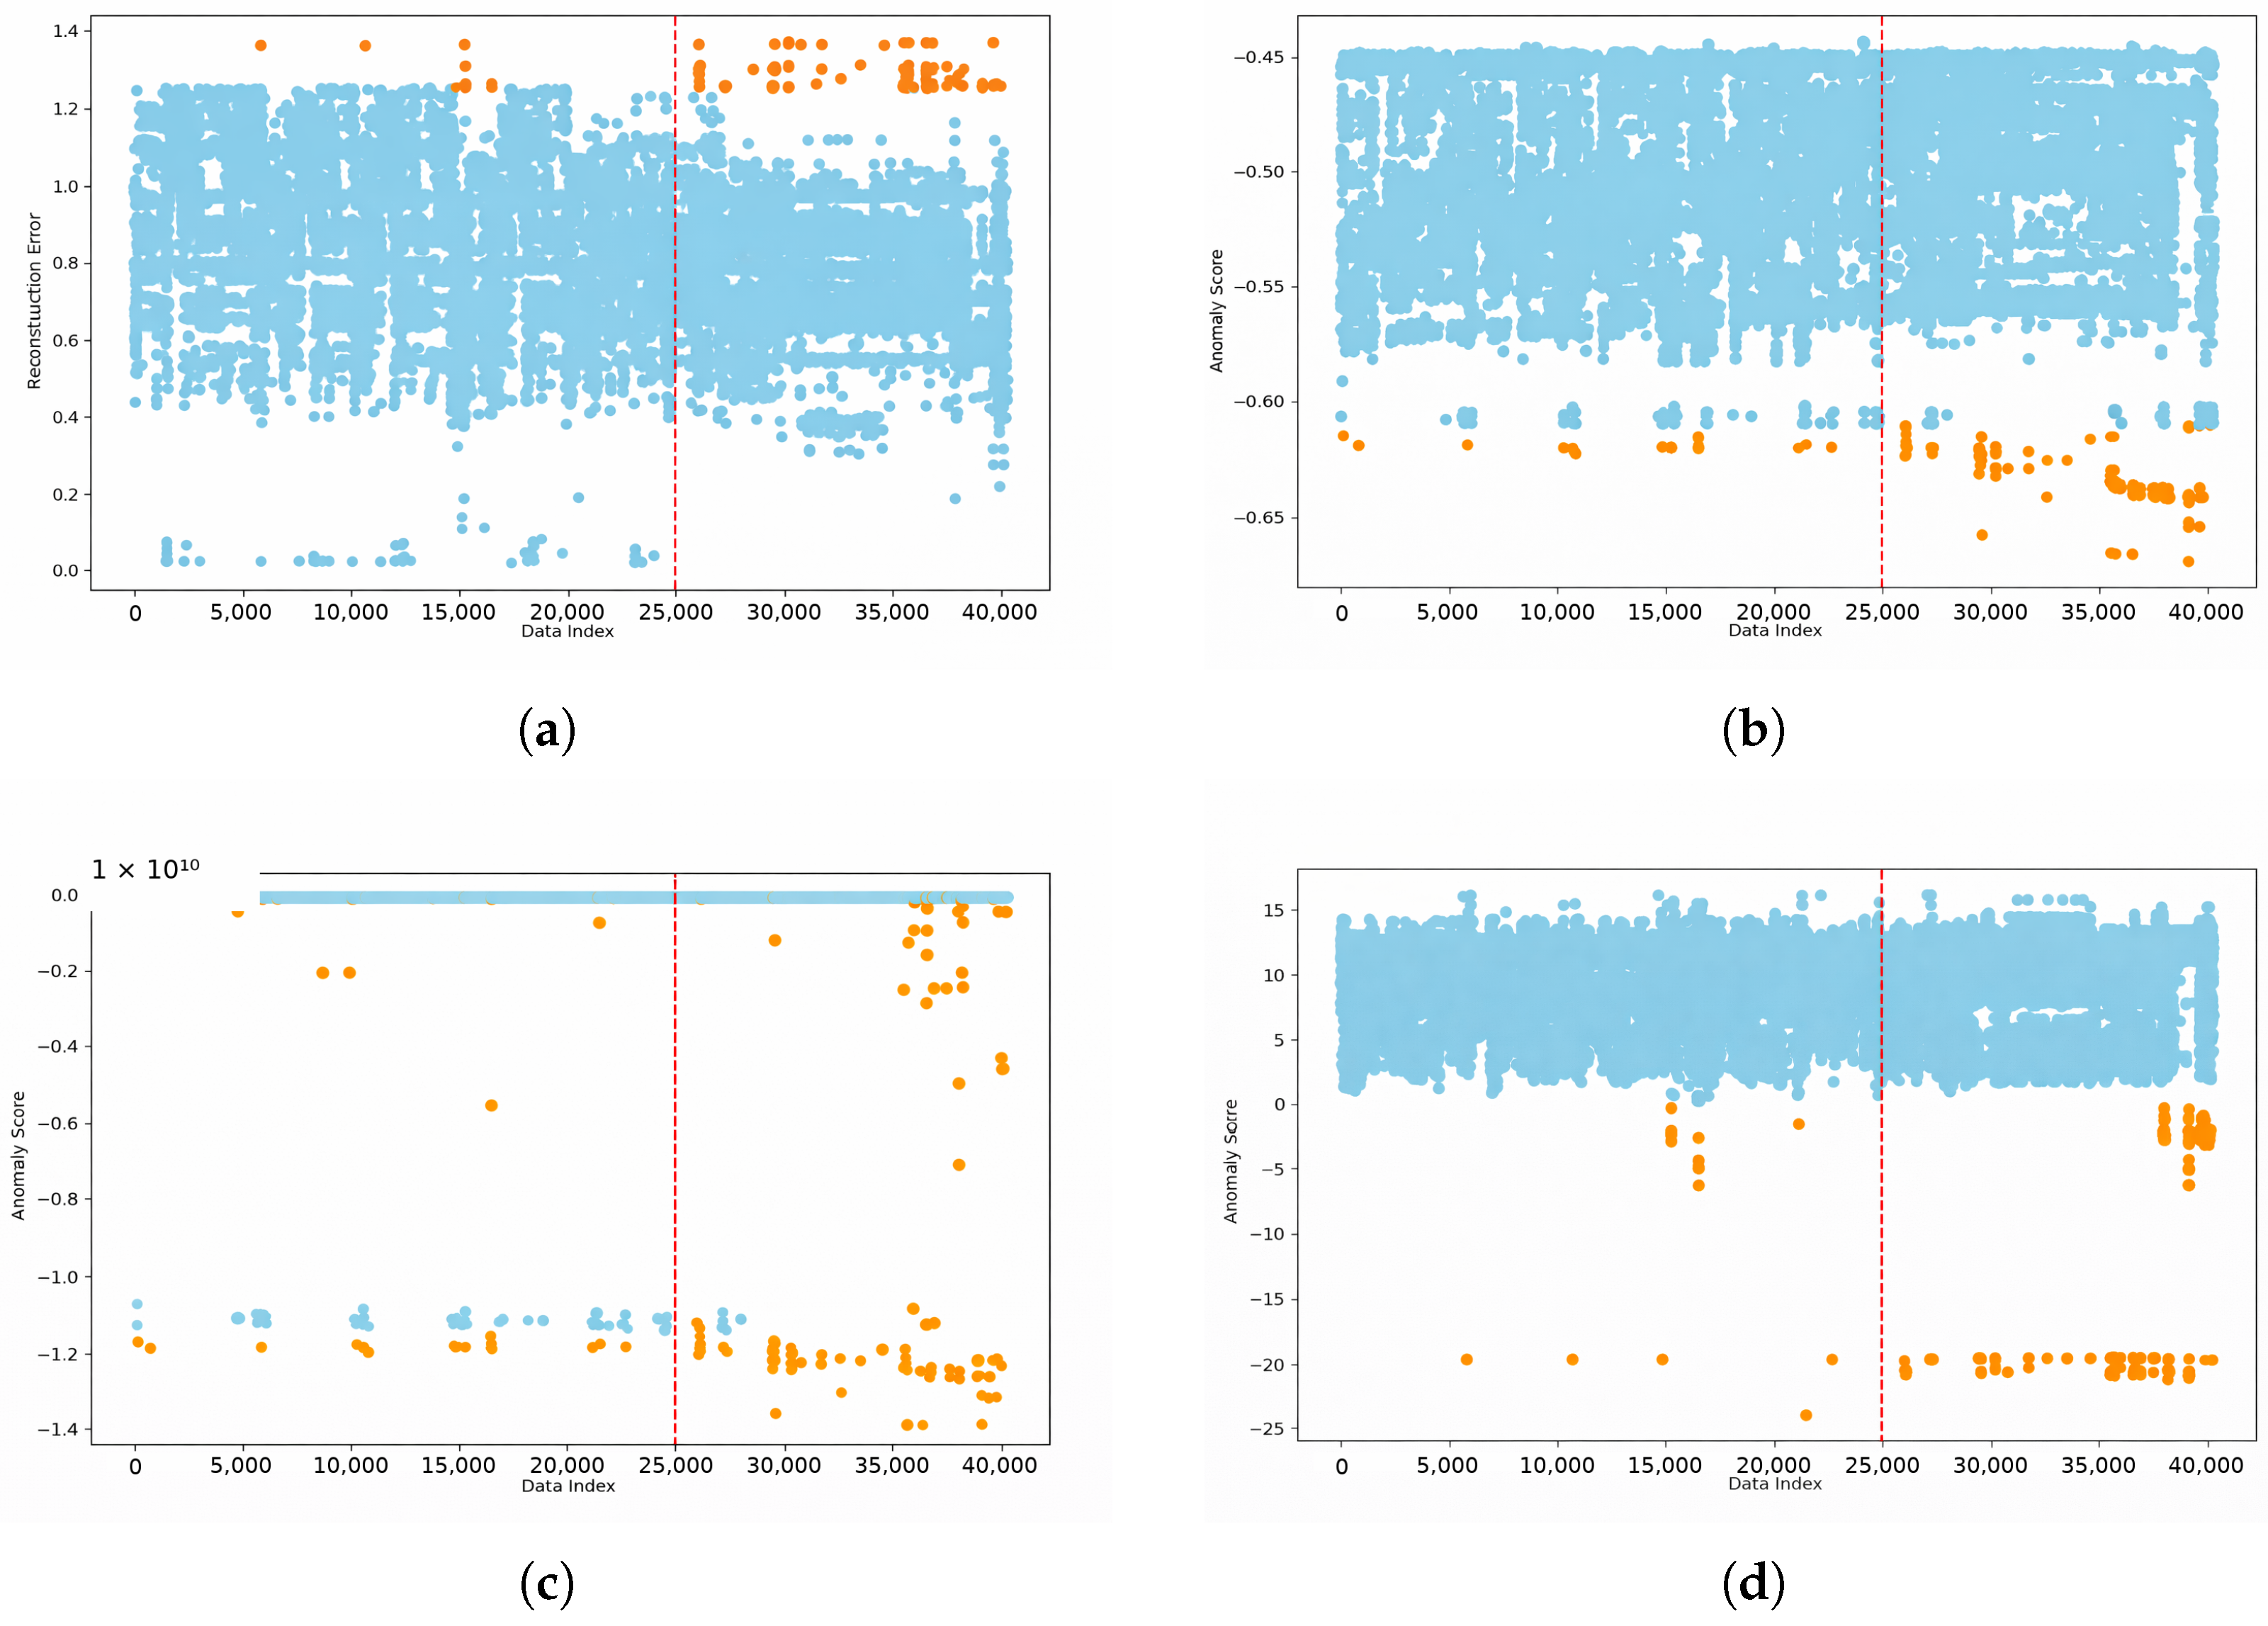
Figure 6 provides a qualitative visualization of the model outputs along the time-ordered test stream. Light-blue points denote samples predicted as normal and dark-orange points denote samples predicted as anomalous. The vertical red dashed line indicates the onset of the injected attack stage (around the 25,000th event). Note that the y-axis reports the model-specific anomaly score (reconstruction error for AEA and decision scores for classical baselines); therefore, the absolute score values are not directly comparable across methods.
As shown in Table 4 and Figure 6, the proposed AEA achieves the best overall performance, maintaining a higher detection rate while controlling false positives. This advantage stems from its reconstruction-based learning of normal behavior manifolds in the latent space, further enhanced by the path-segment attention mechanism and weighted reconstruction loss, which emphasize security-relevant path components.
In contrast, Isolation Forest partitions the feature space using random splits; its performance tends to degrade in the presence of high-dimensional semantic embeddings and sparse path patterns. One-Class SVM relies on a decision boundary in the input feature space and is sensitive to kernel hyperparameters, making it less robust under distribution shifts introduced by diverse attack chains. LOF is effective at suppressing false positives through local density estimation; however, it may miss attacks whose feature representations remain close to dense normal regions, leading to reduced recall in complex container workloads.

Discussion on Additional Deep-Learning Baselines

Deep unsupervised baselines such as VAE- or LSTM-based autoencoders can also be considered for further empirical comparison. Since the proposed detector is itself an autoencoder-family model and the focus of this section is to benchmark against representative non-neural paradigms widely used in system anomaly detection, a comprehensive evaluation against additional deep baselines is left for future work.

5. Conclusions

This paper addresses several critical challenges in container runtime file access monitoring, including insufficient data collection granularity, inadequate path semantic representation, and the difficulty of balancing detection accuracy with real-time performance. To this end, we propose an eBPF-based container file access anomaly detection method that integrates kernel-level monitoring, semantic-enhanced path modeling, and an attention-based autoencoder.
By attaching eBPF programs at the kernel layer, the proposed system enables low-overhead and fine-grained capture of container system calls. At the feature construction level, a multimodal path representation scheme based on risk stratification, structured truncation, and semantic vectorization is introduced, which effectively enhances the structural expressiveness and contextual completeness of path features. In the detection model, a moderately scaled attention mechanism is incorporated to improve the model’s focus on high-risk path segments, while a weighted reconstruction error is employed to achieve more accurate anomaly identification.
Experimental results in realistic container runtime environments demonstrate that the proposed method achieves significant advantages. While maintaining extremely low system overhead, the anomaly detection performance reaches a Recall of 0.82, an FPR of 0.0079, and an MCC of 0.852, along with a low average inference latency. These results indicate that the proposed approach effectively balances detection accuracy, real-time responsiveness, and system friendliness. Furthermore, compared with mainstream unsupervised methods such as Isolation Forest, One-Class SVM, and LOF, the attention-enhanced autoencoder exhibits superior robustness and anomaly detection capability in scenarios involving high-dimensional path semantic representations.
Despite the promising results, several directions remain for future research. First, the current path semantic modeling relies on a fixed Word2Vec embedding space; incorporating context-aware dynamic embeddings based on Transformer architectures [38] may further enhance generalization capability. Second, although the proposed model exhibits low-latency characteristics, its deployment in large-scale, multi-node distributed environments warrants further investigation [39]. In addition, future work may introduce explainability mechanisms to provide more interpretable detection results, thereby assisting security engineers in understanding and analyzing attack paths more intuitively. Another interesting direction is to integrate runtime anomaly detection with proactive prediction/predictability verification mechanisms (e.g., Petri-net-based fault-pattern predictability analysis [19]).

Author Contributions

Conceptualization, N.Z. and H.C.; Methodology, N.Z., H.C. and C.L.; Software, H.C.; Validation, N.Z. and H.C.; Formal analysis, H.C.; Investigation, H.C., Z.C. and F.L.; Resources, N.Z.; Data curation, H.C., Z.C. and F.L.; Writing—original draft, H.C.; Writing—review and editing, H.C. and C.L.; Visualization, H.C., Z.C. and F.L.; Supervision, N.Z.; Project administration, N.Z.; Funding acquisition, N.Z. All authors have read and agreed to the published version of the manuscript.

Funding

This research was funded by the National Natural Science Foundation of China (62002078); Guangzhou Basic Research Program (Grant No. 2025A03J3139).

Data Availability Statement

The data presented in this study are available on request from the corresponding author. The reason for the restriction is that the data involve “security experiment environment configuration and the reproduction of related vulnerabilities,” and therefore cannot be publicly shared.

Conflicts of Interest

The authors declare no conflicts of interest.

References

  1. Docker. Docker Official Website. 2025. Available online: https://www.docker.com/ (accessed on 27 August 2025).
  2. Soltesz, S.; Pötzl, H.; Fiuczynski, M.E.; Bavier, A.; Peterson, L. Container-based Operating System Virtualization: A Scalable, High-performance Alternative to Hypervisors. In Proceedings of the EuroSys 2007, Lisbon, Portugal, 21–23 March 2007; pp. 275–287. [Google Scholar] [CrossRef] [Scilit]
  3. Linux Man-Pages Project. namespaces(7)—Linux Manual Page. 2025. Available online: https://www.man7.org/linux/man-pages/man7/namespaces.7.html (accessed on 27 August 2025).
  4. Linux Man-Pages Project. cgroups(7)—Linux Control Groups. 2025. Available online: https://www.man7.org/linux/man-pages/man7/cgroups.7.html (accessed on 27 August 2025).
  5. Bhaia, N.; Hung, L.H.; Cordingly, R.; Lloyd, W. Understanding Container Isolation: An Investigation of Performance Implications of Container Runtimes. In Proceedings of the 9th International Workshop on Container Technologies and Container Clouds, Bologna, Italy, 11–15 December 2024; pp. 7–12. [Google Scholar] [CrossRef] [Scilit]
  6. Sun, Y.; Safford, D.; Zohar, M.; Pendarakis, D.; Gu, Z.; Jaeger, T. Security Namespace: Making Linux Security Frameworks Available to Containers. In Proceedings of the 27th USENIX Security Symposium (USENIX Security 18), Baltimore, MD, USA, 15–17 August 2018; pp. 1423–1439. [Google Scholar]
  7. Koschel, J.; Borrello, P.; Cono D’Elia, D.; Bos, H.; Giuffrida, C. Uncontained: Uncovering Container Confusion in the Linux Kernel. In Proceedings of the 32nd USENIX Security Symposium (USENIX Security 23), Anaheim, CA, USA, 9–11 August 2023; pp. 5055–5072. [Google Scholar]
  8. Xiao, J.; Yang, N.; Shen, W.; Li, J.; Guo, X.; Dong, Z.; Xie, F.; Ma, J. Attacks are Forwarded: Breaking the Isolation of MicroVM-based Containers Through Operation Forwarding. In Proceedings of the 32nd USENIX Security Symposium (USENIX Security 23), Anaheim, CA, USA, 9–11 August 2023; pp. 7517–7534. [Google Scholar]
  9. Tencent Cloud. White Paper on Container Security; Technical Report; Tencent Cloud: Shenzhen, China, 2021. [Google Scholar]
  10. Kubernetes. Kubernetes Official Website. 2025. Available online: https://kubernetes.io/ (accessed on 27 August 2025).
  11. Red Hat. The State of Kubernetes Security Report: 2024 Edition; Technical Report; Red Hat: Raleigh, NC, USA, 2024; Available online: https://www.redhat.com/en/engage/state-kubernetes-security-report-2024 (accessed on 27 August 2025).
  12. Linux Kernel Documentation. BPF Instruction Set Architecture (ISA). 2025. Available online: https://docs.kernel.org/bpf/standardization/instruction-set.html (accessed on 27 August 2025).
  13. Falco Project. Falco: Cloud Native Runtime Security. 2025. Available online: https://falco.org/ (accessed on 27 August 2025).
  14. Aqua Security. Tracee: Linux Runtime Security and Forensics Using eBPF. 2020. Available online: https://github.com/aquasecurity/tracee (accessed on 27 August 2025).
  15. Cilium Project. Tetragon: eBPF-Based Security Observability and Runtime Enforcement. 2021. Available online: https://tetragon.io/ (accessed on 27 August 2025).
  16. Liu, F.T.; Ting, K.M.; Zhou, Z.H. Isolation Forest. In Proceedings of the 8th IEEE International Conference on Data Mining (ICDM 2008), Pisa, Italy, 15–19 December 2008; pp. 413–422. [Google Scholar] [CrossRef] [Scilit]
  17. Schölkopf, B.; Platt, J.C.; Shawe-Taylor, J.; Smola, A.J.; Williamson, R.C. Estimating the Support of a High-Dimensional Distribution. Neural Comput. 2001, 13, 1443–1471. [Google Scholar] [CrossRef] [Scilit]
  18. Breunig, M.M.; Kriegel, H.P.; Ng, R.T.; Sander, J. LOF: Identifying Density-Based Local Outliers. In Proceedings of the 2000 ACM SIGMOD International Conference on Management of Data, Dallas, TX, USA, 15–18 May 2000; pp. 93–104. [Google Scholar] [CrossRef] [Scilit]
  19. Cong, X.; Yu, Z.; Fanti, M.P.; Mangini, A.M.; Li, Z. Predictability Verification of Fault Patterns in Labeled Petri Nets. IEEE Trans. Autom. Control 2025, 70, 1973–1980. [Google Scholar] [CrossRef] [Scilit]
  20. He, Y.; Guo, R.; Xing, Y.; Che, X.; Sun, K.; Liu, Z.; Xu, K.; Li, Q. Cross Container Attacks: The Bewildered eBPF on Clouds. In Proceedings of the 32nd USENIX Security Symposium (USENIX Security 23), Anaheim, CA, USA, 9–11 August 2023; pp. 5971–5988. [Google Scholar]
  21. Zehra, S.; Syed, H.J.; Samad, F.; Faseeha, U. DeSFAM: An Adaptive eBPF and AI-Driven Framework for Securing Cloud Containers in Real Time. IEEE Access 2025, 13, 139203–139224. [Google Scholar] [CrossRef] [Scilit]
  22. Yu, Y.C.; Hung, C.Y.; Chou, L.D. Kernel-level Hidden Rootkit Detection Based on eBPF. Comput. Secur. 2025, 157, 104582. [Google Scholar] [CrossRef] [Scilit]
  23. Wang, P.; Zhang, A.; Lang, H.; Xun, X.; Zhang, S.; Diao, L. fProcessor: NonIntrusive and On-the-Fly File Data Preprocessing Using eBPF. IEEE Access 2025, 13, 73173–73182. [Google Scholar] [CrossRef] [Scilit]
  24. Remya, S.; Pillai, M.J.; Niranjan, B.; Ajith Kumar, P.M.; Merin Shaju, K.; Dinoy Raj, K.; Ramasubbareddy, S.; Cho, Y. eBPF-Based Runtime Detection of Semantic DDoS Attacks in Linux Containers. IEEE Access 2025, 13, 169178–169219. [Google Scholar] [CrossRef] [Scilit]
  25. Kyadige, A.; Rudd, E.M.; Berlin, K. Learning from Context: Exploiting and Interpreting File Path Information for Better Malware Detection. arXiv 2019, arXiv:1905.06987. [Google Scholar] [CrossRef] [Scilit]
  26. Lee, R.K.; Song, H.M.; Youn, T.Y. Effective Context-Aware File Path Embeddings for Anomaly Detection. Systems 2025, 13, 403. [Google Scholar] [CrossRef] [Scilit]
  27. Wang, Y.; Chen, X.; Wang, Q.; Yang, R.; Xin, B. Unsupervised Anomaly Detection for Container Cloud Via BiLSTM-Based Variational Auto-Encoder. In Proceedings of the ICASSP 2022–2022 IEEE International Conference on Acoustics, Speech and Signal Processing, Singapore, 23–27 May 2022; pp. 3024–3028. [Google Scholar] [CrossRef] [Scilit]
  28. Fan, M.; Zuo, J.; Zhu, J.; Lu, Y. Explainable Anomaly-Based Intrusion Detection for Specialized IoT Environments Enabled by Rule Extraction From Autoencoder. IEEE Internet Things J. 2025, 12, 19504–19521. [Google Scholar] [CrossRef] [Scilit]
  29. Rao, A.R.; Wang, H.; Gupta, C. Functional approach for Two Way Dimension Reduction in Time Series. In Proceedings of the IEEE International Conference on Big Data (Big Data 2022), Osaka, Japan, 17–20 December 2022; pp. 1099–1106. [Google Scholar] [CrossRef] [Scilit]
  30. Guo, S.; Sivanthi, T.; Sommer, P.; Kabir-Querrec, M.; Coppik, N.; Mudgal, E.; Rossotti, A. A zero-day container attack detection based on ensemble machine learning. In Proceedings of the 2023 IEEE 28th International Conference on Emerging Technologies and Factory Automation (ETFA), Sinaia, Romania, 12–15 September 2023; pp. 1–8. [Google Scholar] [CrossRef] [Scilit]
  31. MITRE. CVE-2022-0492: cgroups v1 release_agent Privilege Escalation Vulnerability. 2022. Available online: https://nvd.nist.gov/vuln/detail/CVE-2022-0492 (accessed on 30 January 2026).
  32. MITRE. CVE-2022-48699: Linux Kernel Scheduler Debugging Reference Count Vulnerability. 2022. Available online: https://nvd.nist.gov/vuln/detail/CVE-2022-48699 (accessed on 30 January 2026).
  33. MITRE. CVE-2022-0811: Kubernetes Container Escape via /proc/self/exe. 2022. Available online: https://nvd.nist.gov/vuln/detail/CVE-2022-0811 (accessed on 30 January 2026).
  34. Liao, Y.C.; Langweg, H. Cost-benefit analysis of kernel tracing systems for forensic readiness. In Proceedings of the 2nd International Workshop on Security and Forensics in Communication Systems (SFCS), Kyoto, Japan, 3 June 2014; pp. 25–36. [Google Scholar] [CrossRef] [Scilit]
  35. Linux Kernel Documentation. ftrace—Function Tracer. 2025. Available online: https://www.kernel.org/doc/html/latest/trace/ftrace.html (accessed on 27 August 2025).
  36. Linux Kernel Community. perf(1)—Linux Performance Analysis Tools. 2025. Available online: https://www.man7.org/linux/man-pages/man1/perf.1.html (accessed on 27 August 2025).
  37. SystemTap Project. SystemTap Beginner’s Guide. 2024. Available online: https://docs.redhat.com/en/documentation/red_hat_enterprise_linux/7/html/systemtap_beginners_guide/index (accessed on 27 August 2025).
  38. Wehbe, N.; Alameddine, H.A.; Pourzandi, M.; Assi, C. Empowering 5G SBA security: Time series transformer for HTTP/2 anomaly detection. Comput. Secur. 2025, 148, 104114. [Google Scholar] [CrossRef] [Scilit]
  39. Li, Y.; Li, Q.; Zhang, C.; Wang, L.; Wang, C.; Bai, Z.; Luo, H.; Gao, T.; Ma, K.; Pan, L. DistriAD: Distributed anomaly detection for large-scale microservice systems. In Proceedings of the 2025 IEEE International Conference on Web Services (ICWS), Helsinki, Finland, 7–12 July 2025; pp. 825–834. [Google Scholar] [CrossRef] [Scilit]
Figure 1. Overview of the eBPF execution workflow, including program loading, verification, and map-based communication between kernel space and user space.
Mathematics 14 00991 g001
Figure 2. Overall architecture of the proposed container file-access anomaly detection framework, including kernel-space eBPF monitoring, user-space preprocessing, and the attention-enhanced autoencoder.
Mathematics 14 00991 g002
Figure 3. Runtime overhead comparison of different kernel monitoring tools under stress workload conditions. The figure reports CPU utilization, disk I/O operations, read/write throughput, and memory usage for Normal execution, Stress Test, and Stress Test combined with Ftrace, Perf, eBPF, and SystemTap. The results demonstrate that the proposed eBPF-based monitoring mechanism introduces minimal additional overhead compared to alternative tracing tools.
Mathematics 14 00991 g003
Figure 4. Impact of hyperparameter configurations on anomaly detection performance. The figure illustrates Recall, False Positive Rate (FPR), and Matthews Correlation Coefficient (MCC) under eight different hyperparameter combinations of the proposed attention-enhanced autoencoder. The comparison highlights the trade-off between detection sensitivity and false alarm rate under varying network architectures and regularization settings.
Mathematics 14 00991 g004
Figure 5. Sensitivity analysis of the anomaly threshold coefficient n. The figure shows the variation in Recall, FPR, and MCC as the threshold parameter n in the dynamic decision rule increases from 1.0 to 2.5. A moderate value ( n = 2 ) achieves the best balance between detection accuracy and false positive control.
Mathematics 14 00991 g005
Figure 6. Qualitative comparison of anomaly detection results produced by different models: (a) Proposed AEA. (b) Isolation Forest. (c) Local Outlier Factor (LOF). and (d) One-Class SVM (OCSVM). Light-blue points indicate predicted normal samples, dark-orange points indicate predicted anomalies, and the vertical red dashed line marks the start of the injected attack stage (approximately the 25,000th event). The y-axis corresponds to reconstruction error for the proposed model and anomaly scores for classical baselines.
Mathematics 14 00991 g006
Table 1. Representative container file access data.
Host PIDHost PPIDContainer IDDevice IDInodeFlagsPath
  2851  27954b0e5a55…
9438788f
7146988523
013275691
  4103  33345  /tmp/cgrp/x/notify_on_release
Table 2. Path risk classification and corresponding truncation strategies.
Risk LevelDetermination CriteriaTruncation StrategyRetention Mode
High RiskInvolving kernel interfaces or privileged operationsTail-priority truncation T R U N C + last 5 segments
Medium RiskSystem configuration or service component paths 3 + 2 ” structural truncationFirst 3 segments + last 2 segments + P A D
Low RiskUser-space or temporary file paths 2 + 3 ” dynamic focusingFirst 2 segments + last 3 segments + P A D
Table 3. Top 10 parameter combinations ranked by average cosine similarity.
Parameter CombinationAverage Cosine Similarity
vs:100, ws:3, mc:10.4460
vs:100, ws:5, mc:10.4385
vs:50, ws:3, mc:10.4313
vs:100, ws:3, mc:30.4247
vs:50, ws:5, mc:10.4180
vs:10, ws:3, mc:10.4095
vs:50, ws:3, mc:30.4012
vs:10, ws:5, mc:10.3940
vs:50, ws:7, mc:10.3888
vs:10, ws:3, mc:30.3816
Table 4. Performance comparison between the proposed attention-enhanced autoencoder and representative unsupervised baselines on Data_abnormal.
MethodParadigmRecallFPRMCC
Proposed AEAReconstruction-based0.8200.00790.852
Isolation ForestPartition-based0.7800.00990.820
One-Class SVMBoundary-based0.7800.01710.808
LOFDensity-based0.7900.00850.835
Note: Best results are shown in bold.
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content.