1. Introduction
The Tor anonymity network [
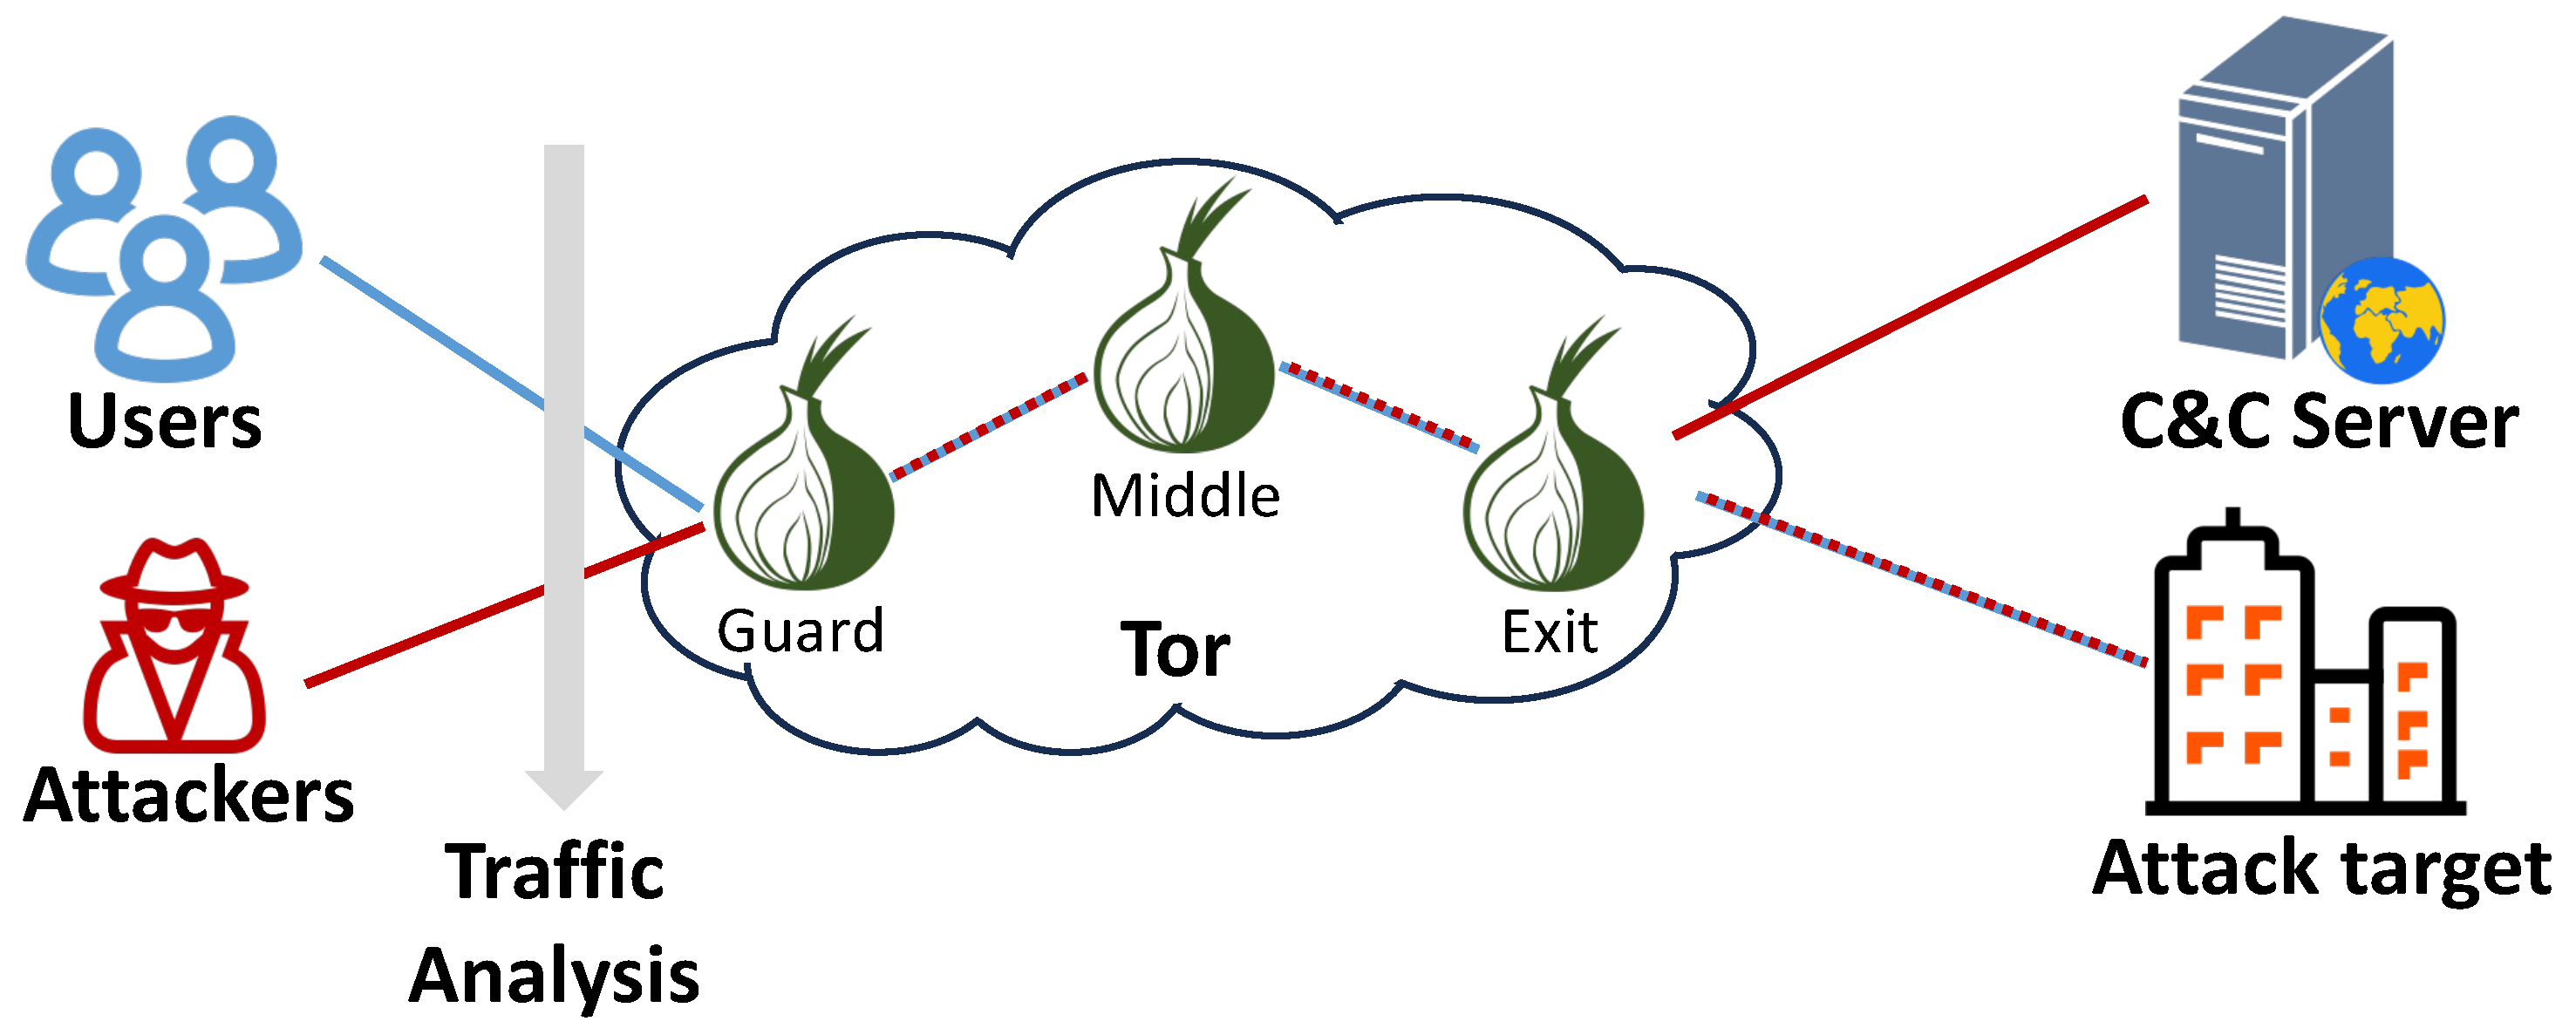
1] provides privacy protection for millions of users worldwide through multi-hop encrypted routing and traffic obfuscation. While this infrastructure enables legitimate applications (e.g., whistleblowing, censorship circumvention, and secure communications in authoritarian regimes), it has also become an attractive vector for malicious actors seeking to evade detection. The NCSC report [
2] indicates that the latest version of the SystemBC malware has switched from using SOCKS5 proxies to the Tor network to encrypt and conceal the destination of its command-and-control (C&C) communications. This dual-use nature creates an urgent need for robust detection mechanisms that can distinguish malicious Tor traffic from legitimate privacy-preserving communications. The analysis and detection of malicious Tor traffic are crucial for security management. For example, identifying ransomware C&C communications enables network administrators to block infection propagation and prevent data exfiltration [
3,
4], while categorizing different attack types allows security providers to implement differentiated response strategies and dedicated containment policies to enhance incident response quality.
Traditional machine learning (ML) methods for malicious Tor traffic detection, such as Artificial Neural Network (ANN) [
5], Random Forest (RF) [
6], and Support Vector Machine (SVM) [
7], rely heavily on expert knowledge to engineer specified features (e.g., packet counts, burst statistics, and inter-packet timing distributions). These statistical features, after feature engineering, are fed into the machine learning models for classification. With advances in deep learning (DL) [
8], recent works have shifted toward feeding raw traffic data directly into DL models to automatically learn discriminative patterns. Representative approaches include DF [
9], based on Convolutional Neural Network (CNN), Var-CNN [
10] and AWF [
11], based on hybrid CNN–Long Short-Term Memory (LSTM) architectures, and TikTok [
12], based on sequential modeling. These DL-based methods can capture complex behavioral patterns from raw packet sequences without manual feature engineering. However, the effectiveness of DL-based encrypted-traffic classifiers depends on large-scale labeled datasets and reasonably balanced class distributions. In the Tor ecosystem, accurately labeling malicious traffic is difficult due to anonymity, encryption, and rapidly evolving attack behaviors. More importantly, real-world Tor deployments exhibit extreme class imbalance, where malicious flows constitute only a tiny minority. Under such skew, standard ERM-trained deep models often optimize majority accuracy, bias toward majority-class predictions, and suffer substantial degradation in malicious-traffic recall and generalizability. This issue is exacerbated by Tor’s fixed 512-byte cell architecture, which removes packet-size diversity and shifts discriminative evidence to multi-scale temporal and directional behaviors. Open-world malware settings further amplify distribution shift and label scarcity. These Tor-specific constraints expose a gap between the existing DL-based approaches and practical malicious Tor traffic detection.
Unfortunately, acquiring large-scale high-quality labeled traffic datasets is substantially harder than labeling conventional domains (e.g., text or images) because traffic labeling requires protocol expertise, scenario knowledge, and costly ground-truth collection. In practice, attack-related flows are sparse, rapidly evolving, and often buried in massive background traffic, making manual labeling prohibitive and high-quality labels scarce.
Unlike standard TCP/IP traffic, where packet sizes reveal application semantics, Tor enforces a fixed 512-byte cell structure that fragments and pads all the data into uniform units [
1,
13]. This architectural design eliminates size-based fingerprinting vectors that conventional encrypted traffic analysis relies upon. The existing traffic analysis methods designed for HTTPS or VPN traffic [
9,
14] fail when applied to Tor’s homogenized cell sequences as discriminative packet-level features are systematically removed by the cell-based protocol. Moreover, real-world network deployments exhibit severe class imbalance where malicious Tor traffic constitutes a small minority of total network flows. Studies on enterprise Tor usage [
15] and recent detection benchmarks [
16] report malicious ratios as low as 1–5%. This scarcity is compounded by high diversity within the minority malicious class as ransomware, spyware, botnet controllers, and data exfiltration tools exhibit distinct behavioral signatures [
17], creating fragmented intra-class distributions that challenge conventional learning paradigms. Additionally, Tor’s multi-layer encryption creates heterogeneous discriminability across training samples. Some flows contain clear behavioral patterns, such as regular C&C beacons [
3,
4], while others exhibit ambiguous features due to short connection durations or defensive padding strategies [
18,
19,
20]. This heterogeneity challenges standard training paradigms that assume uniform sample quality [
21], causing classifiers to either overfit to clear majority-class samples or underfit minority-class patterns due to noisy examples.
Prior approaches have demonstrated the potential of applying representation learning techniques for Tor traffic analysis. For example, DeepCorr [
22] learns correlation patterns between traffic flows at circuit entry and exit points for deanonymization. FlowPrint [
23] generates traffic fingerprints through cross-correlation of burst patterns without requiring labeled data. More recently, specialized methods for malicious Tor detection have emerged. Ling et al. [
3] proposed statistical features capturing temporal characteristics and packet distributions, achieving initial success in distinguishing malware C&C traffic. Dodia et al. [
16] introduced TrafficFormer, applying transformer-based pre-training with masked flow modeling to learn traffic representations. However, these approaches address only subsets of the practical constraints and do not jointly resolve extreme class imbalance and heterogeneous sample quality. Under highly skewed ratios [
15], deep models may collapse toward the majority class and hurt recall, while purely statistical approaches may incur operationally unacceptable false positives.
In this paper, we propose MAESTRO, a modular three-stage framework that reformulates malicious Tor traffic detection as data-centric behavioral modeling under extreme skew, rather than a direct end-to-end classification task. Specifically, MAESTRO combines (i) multi-scale behavioral representation from cell-level metadata, (ii) training-time quality estimation via an ensemble anomaly detection mechanism for adaptive instance weighting, and (iii) controlled multi-generator synthesis with strict ensemble acceptance to mitigate extreme class imbalance while filtering low-fidelity or out-of-distribution artifacts.
As summarized in
Section 4.2, MAESTRO achieves state-of-the-art performance, and its key designs are:
Multi-scale representation. Tor traffic is homogenized by fixed-size cells, but multi-scale temporal patterns remain discriminative. MAESTRO encodes timing, position, and direction metadata at cell, direction, and flow granularities and compresses them into compact latent embeddings via an autoencoder.
Quality estimation and refinement. To handle noisy/low-quality samples, MAESTRO combines five complementary anomaly detection models to produce discriminability scores for adaptive sample weighting, emphasizing representative samples without hard pruning.
Controlled synthesis for imbalance. To address extreme skew, MAESTRO uses three complementary GANs per minority class and performs strict five-model ensemble validation so that only high-fidelity synthetic samples augment training.
We further evaluate MAESTRO on the CCS’22 Tor malware dataset [
16] under systematic class-imbalance variations (100%, 80%, 60%, 40%, 20%, 10%, 5%, and 1% malicious ratios). MAESTRO achieves 92.38% accuracy, 64.79% recall, and 73.70% F1-score under the natural distribution, with up to 15.53% F1 improvement over state-of-the-art baselines. Under the extreme 1% malicious ratio, MAESTRO maintains 21.1% recall and 33.3% F1-score, outperforming the second-best baseline by 14.1 percentage points in recall. Ablations further show complementary gains from multi-scale representation and multi-GAN augmentation.
The rest of this paper is structured as follows.
Section 2 surveys the related work and formulates the problem.
Section 3 presents the MAESTRO framework.
Section 4 evaluates our approach on real-world datasets.
Section 5 discusses implications and limitations.
Section 6 concludes the paper.
3. MAESTRO Framework
This section presents the technical implementation of the MAESTRO framework, systematically addressing the three research gaps outlined in
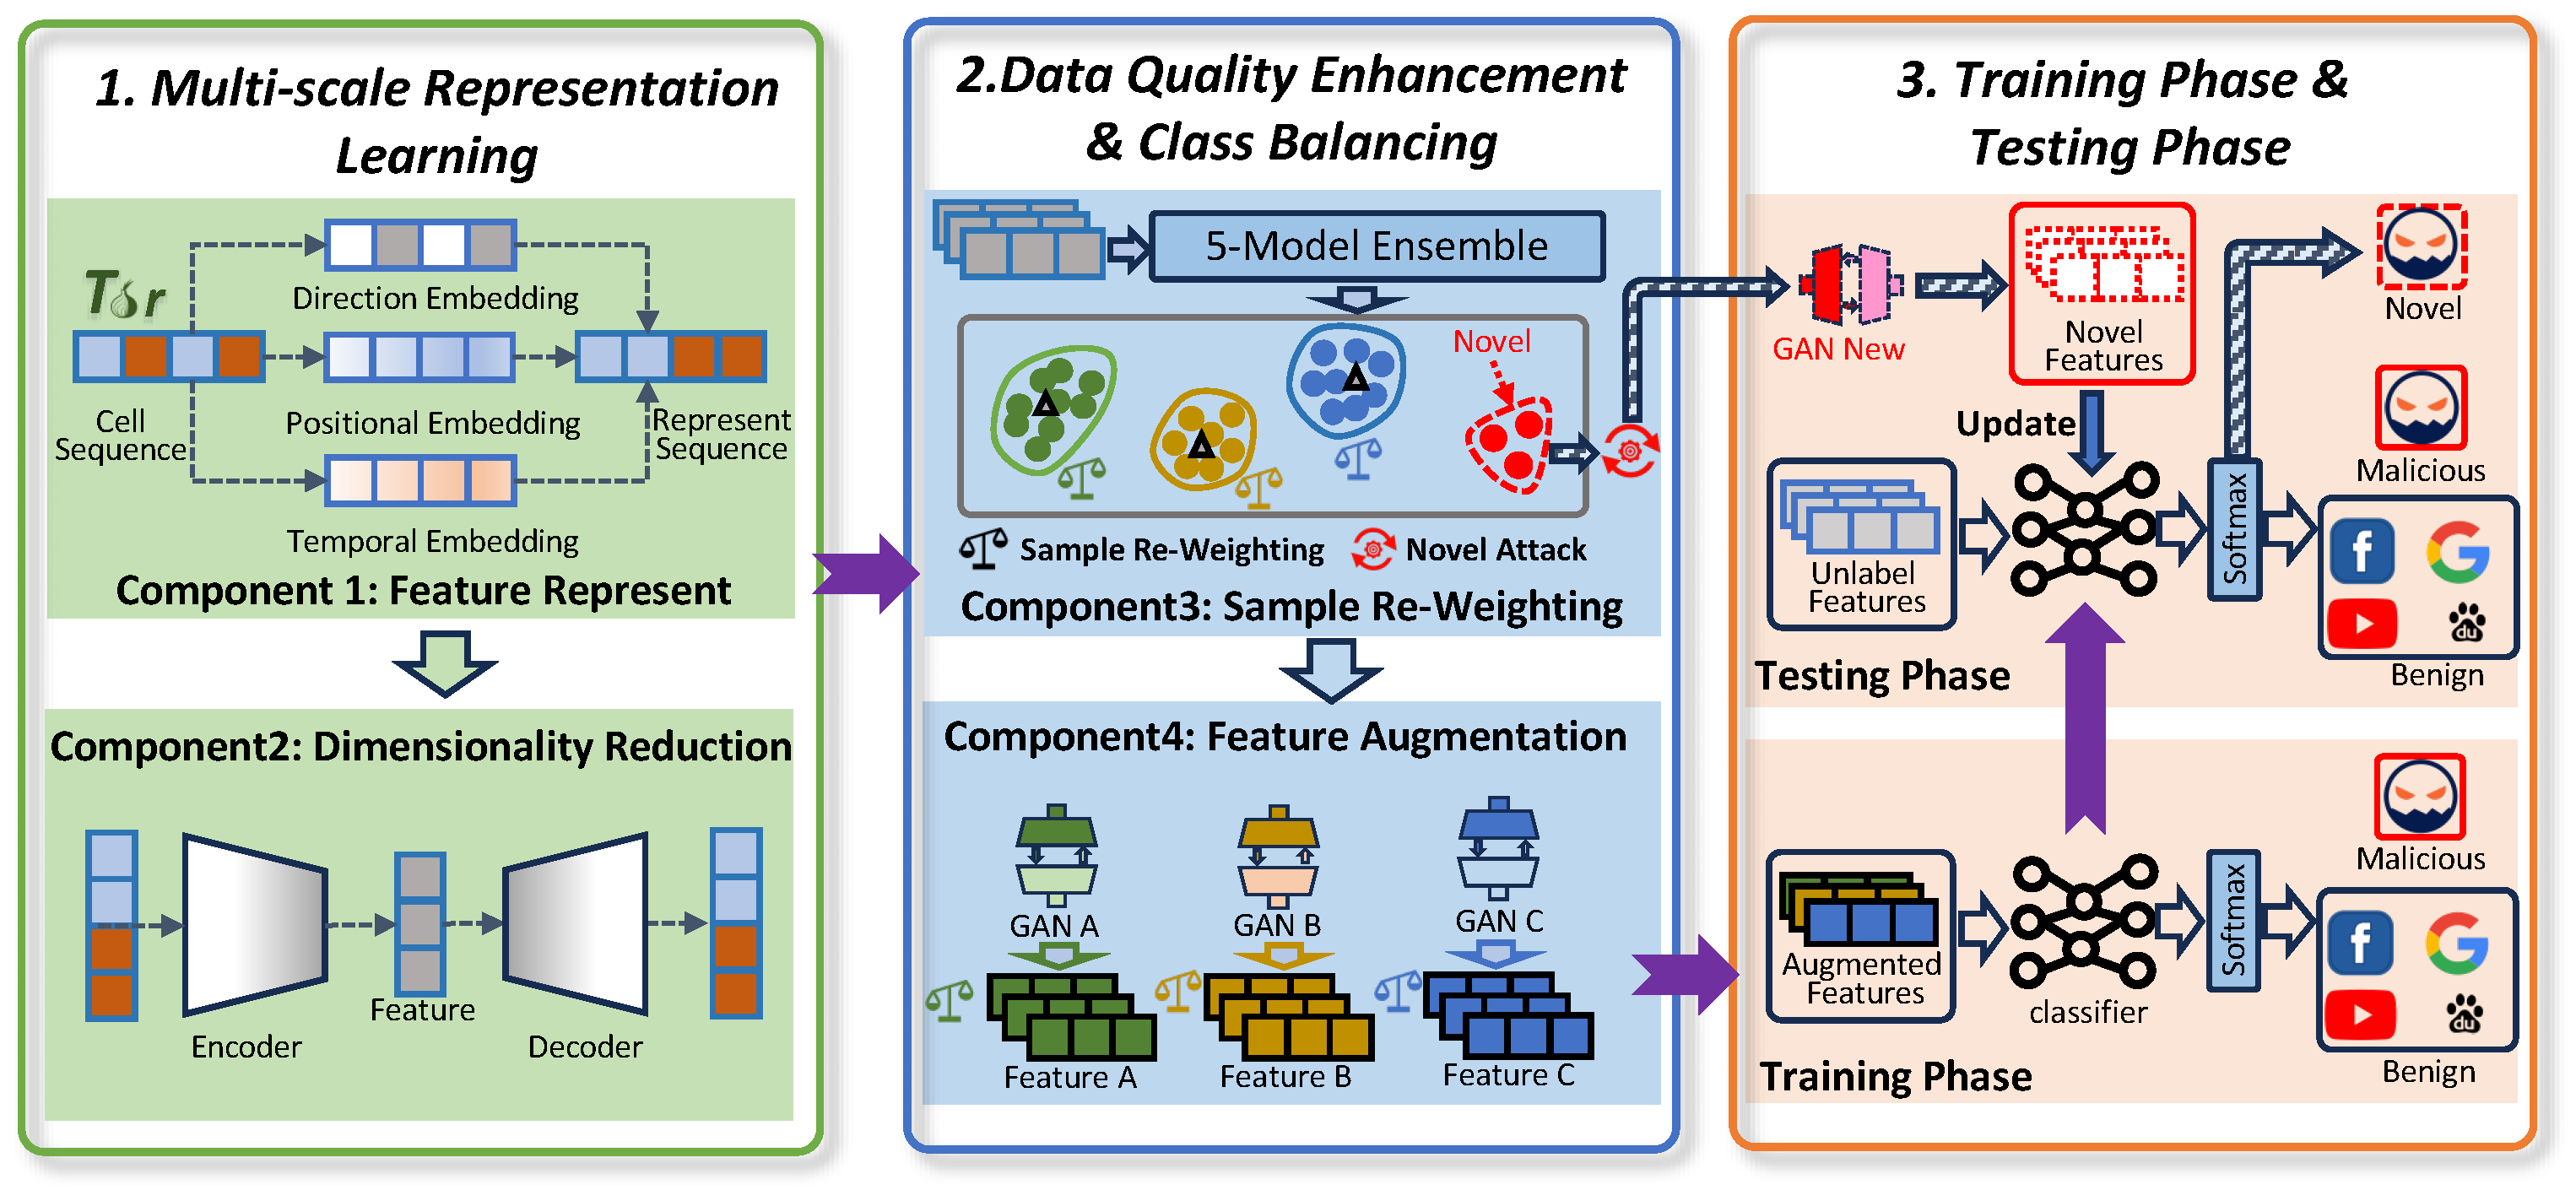
Section 2.5: feature homogeneity under Tor’s cell-based architecture, extreme class imbalance with high intra-malicious diversity, and heterogeneous sample quality. As illustrated in
Figure 2, the framework operates through three sequential stages with four core components, each targeting specific detection challenges.
3.1. Design Philosophy and Technical Roadmap
MAESTRO adopts a modular pipeline where specialized components address distinct aspects of malicious Tor traffic detection.
Stage 1 (multi-scale representation learning) transforms raw Tor cell sequences into compact discriminative representations through two components. Component 1 (
Section 3.2.1) fuses temporal, positional, and directional embeddings to extract behavioral signatures at cell, direction, and flow granularities, capturing multi-scale traffic patterns that remain discriminative despite Tor’s cell-based architecture. Component 2 (
Section 3.2.2) then employs an autoencoder to compress these high-dimensional multi-scale representations into compact latent features through nonlinear dimensionality reduction, amplifying class-discriminative patterns while suppressing noise.
Stage 2 (data quality enhancement and class balancing) improves training data quality and addresses the binary-class imbalance through two subsequent components. Component 3 (
Section 3.3) utilizes an ensemble of five complementary models (Isolation Forest, Local Outlier Factor, One-Class SVM, Variational Autoencoder, and Masked Autoencoder for Density Estimation) to quantify sample-level discriminability from multiple perspectives (density, isolation, boundary distance, reconstruction error, and probabilistic likelihood), producing adaptive weights without discarding any data. All the detector outputs are mapped to a unified class-conditional compatibility (normality) convention, where larger scores indicate that a sample is more typical/compatible with the corresponding class distribution. Component 4 (
Section 3.3.2) trains three specialized Generative Adversarial Networks per class (total of six GANs for binary classification) with complementary architectures (GAN-A, GAN-B, and GAN-C) to synthesize additional latent features from multiple generative perspectives; generated vectors undergo 5-model ensemble-based quality filtering before being added to the training pool, directly targeting the minority-class scarcity while preserving intra-class diversity.
Stage 3 (classifier-agnostic training) (
Section 3.4) feeds the reweighted and augmented latent features into any downstream classifier without further preprocessing, enabling fair comparison across architectures.
Three design principles guide MAESTRO. First is behavioral modeling beyond packet statistics. To counter feature homogeneity, the framework captures temporal patterns, sequential structure, and directional flow, which remain informative despite fixed-size cells. Second is ensemble-based data quality control. Instead of relying on a single quality perspective, MAESTRO combines five complementary models to produce robust sample weights and synthetic-sample filters. Third is modular progressive abstraction. Raw cell sequences are progressively transformed into multi-scale embeddings, compact latent features, ensemble-evaluated weights, and finally balanced representations, allowing each component to focus on a dedicated sub-task.
The three stages synergistically close the gaps identified in
Section 2.5. Stage 1 overcomes feature homogeneity; Stage 2 rectifies extreme imbalance and heterogeneous sample quality through ensemble-based approaches; Stage 3 delivers balanced plug-and-play features to any detection algorithm.
Throughout this section, we focus on binary classification (: malicious vs. benign), although the framework generalizes to multi-class scenarios. We use to denote class labels and to represent latent features with dimensionality .
3.2. Stage 1: Multi-Scale Representation Learning and Dimensionality Reduction
This stage transforms raw Tor cell sequences into compact discriminative latent features through two sequential components. Component 1 extracts multi-scale behavioral signatures by fusing temporal, positional, and directional embeddings at cell, direction, and flow granularities. Component 2 then compresses these high-dimensional representations into a low-dimensional latent space through autoencoder-based nonlinear dimensionality reduction, amplifying class-discriminative patterns while suppressing noise.
3.2.1. Multi-Scale Representation Learning
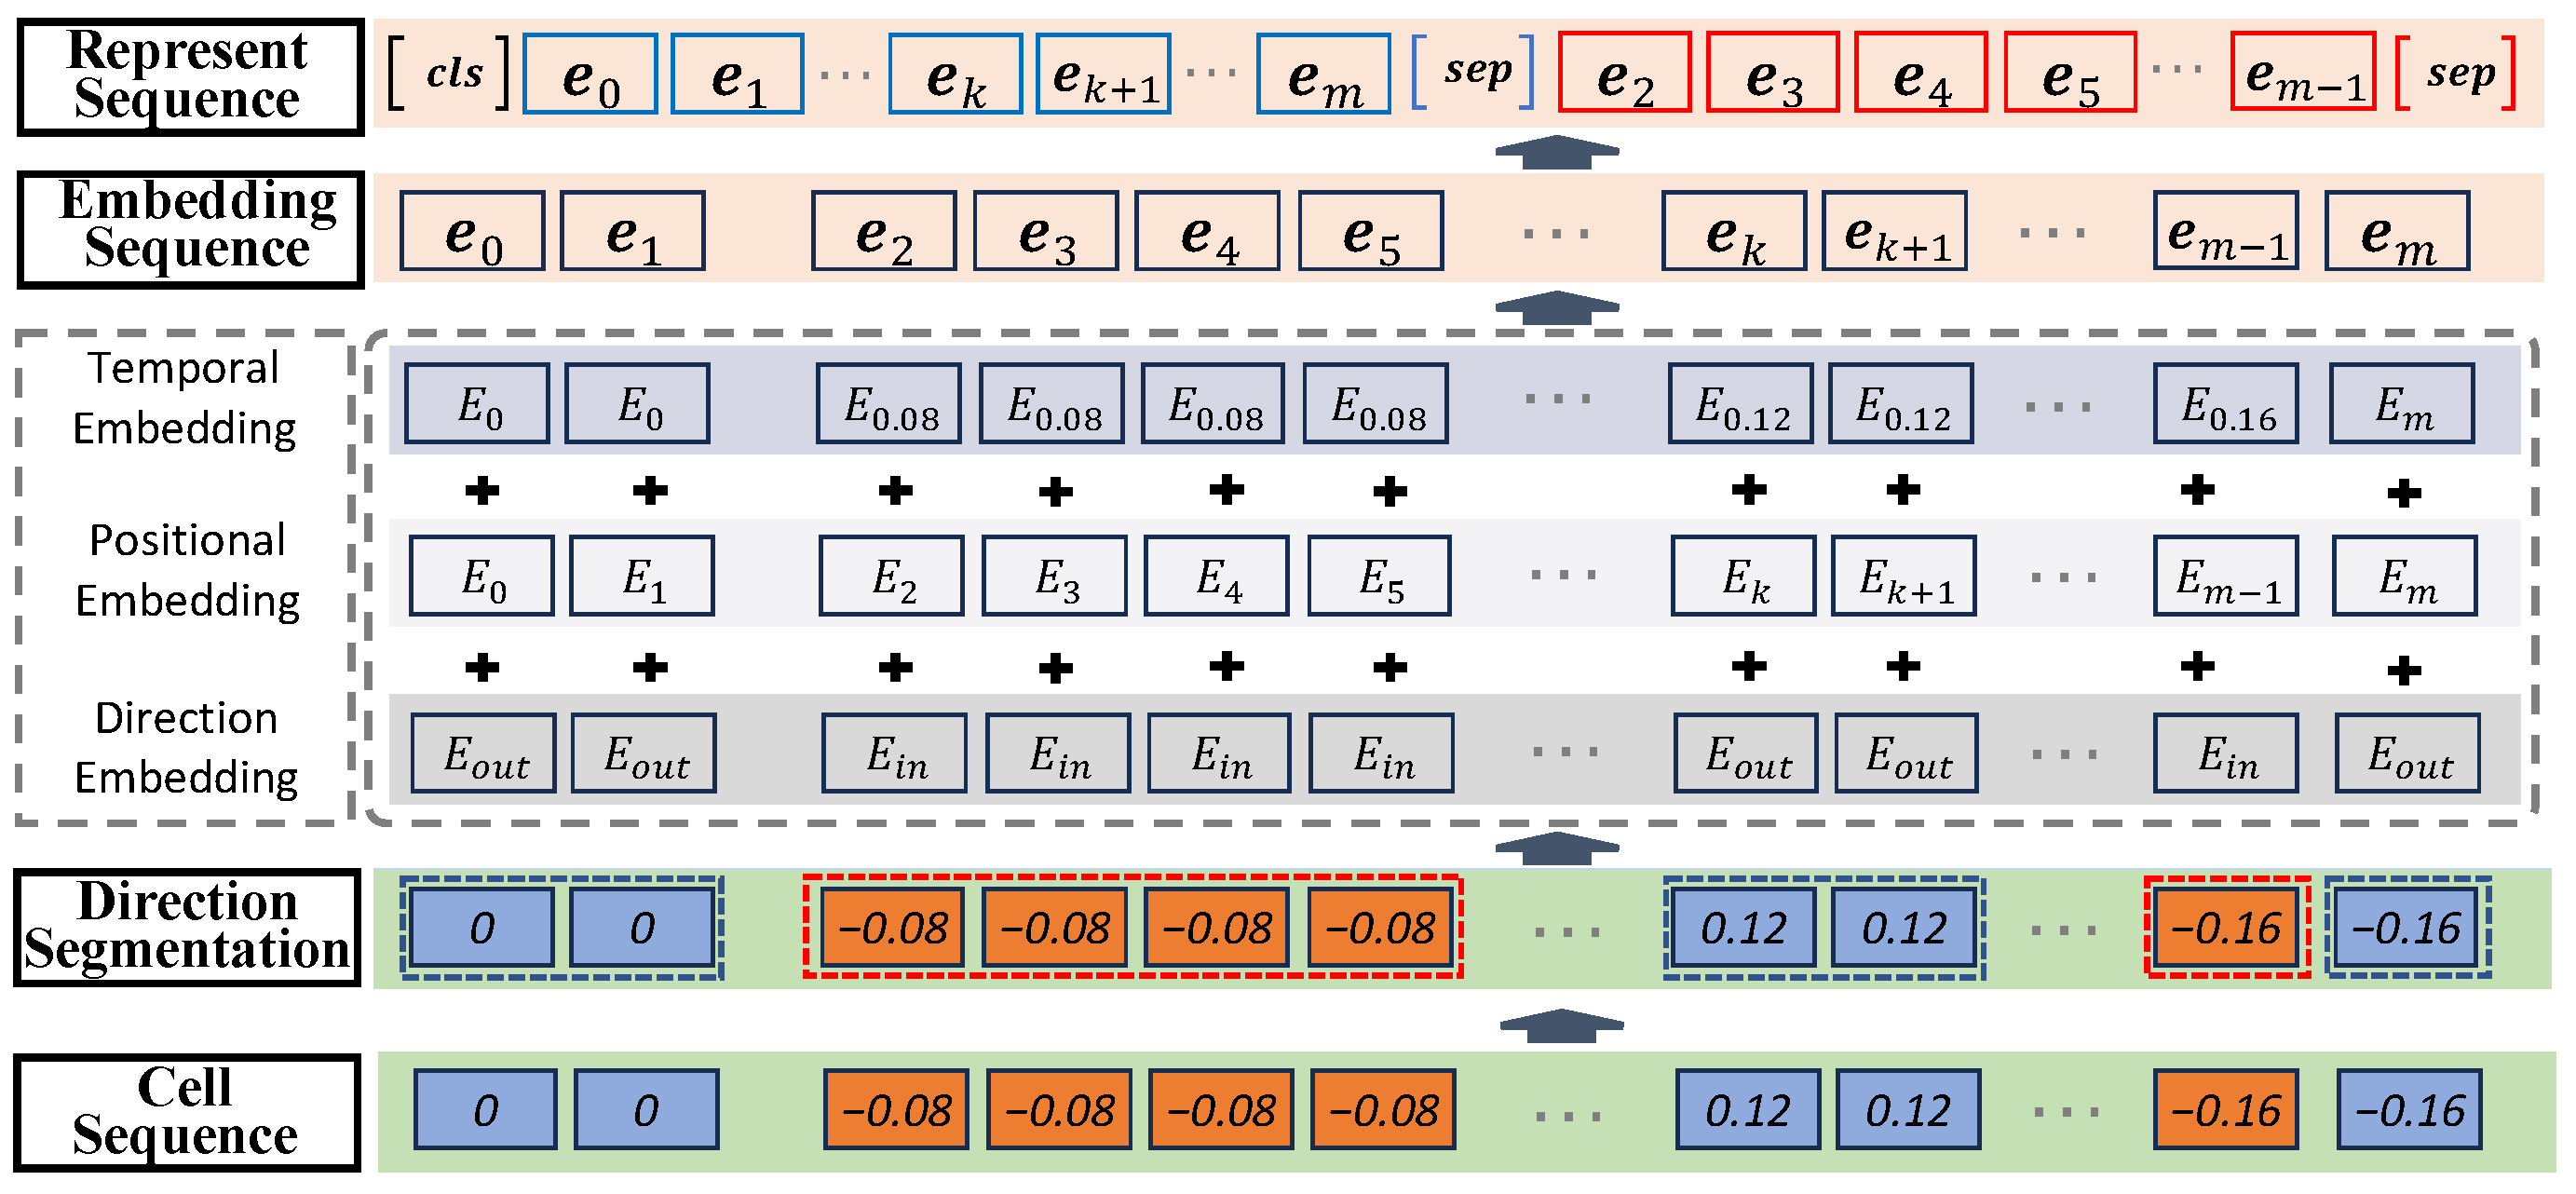
Tor’s cell-based architecture renders conventional packet-size features uninformative, yet cell-level metadata (temporal, position, and direction) remain observable and reflect distinct behavioral signatures. As illustrated in
Figure 3, this component captures such patterns through three-dimensional encoding and direction-aware contextualization, transforming homogenized cell sequences into discriminative representations at multiple granularities.
Given a Tor flow (padded or truncated to fixed length ), each cell exposes three observable metadata attributes: (1) inter-arrival time (milliseconds), (2) position , and (3) direction (0 = outbound; 1 = inbound). We encode these through three complementary transformations.
Temporal encoding captures temporal patterns via logarithmic normalization and z-score standardization. The normalized inter-arrival time is broadcast across all embedding dimensions:
where
and
are the mean and standard deviation of log-transformed inter-arrival times computed from the training set.
Figure 3.
Visualization of multi-scale embeddings. Temporal embedding captures inter-arrival time patterns through logarithmic normalization; positional embedding uses sinusoidal functions to encode sequence structure; directional embedding distinguishes inbound/outbound traffic asymmetry through one-hot encoding. These three complementary representations are fused to form unified cell-level embeddings.
Figure 3.
Visualization of multi-scale embeddings. Temporal embedding captures inter-arrival time patterns through logarithmic normalization; positional embedding uses sinusoidal functions to encode sequence structure; directional embedding distinguishes inbound/outbound traffic asymmetry through one-hot encoding. These three complementary representations are fused to form unified cell-level embeddings.
Positional encoding uses sinusoidal functions to preserve sequence position:
Directional encoding distinguishes traffic direction through binary one-hot vectors padded to dimension
d:
The three encodings are fused via element-wise addition and layer normalization:
producing unified embedding sequence
. To capture directional behavioral patterns characteristic of malicious traffic (e.g., C&C beaconing: periodic small outbound requests triggering large inbound commands), we construct contextual representations:
where
aggregates same-direction neighbors within window
w to capture local sequential patterns, and
captures cross-directional context to model flow-level asymmetry. The final representation sequence
encodes behavioral semantics at three granularities: cell-level (individual embeddings
), direction-level (local context
), and flow-level (global context
), providing multi-scale discriminative features for subsequent compression.
3.2.2. Autoencoder-Based Dimensionality Reduction
The representation sequence from the previous component, while capturing rich behavioral semantics, suffers from high dimensionality that leads to computational inefficiency and overfitting risks. Moreover, the discrete high-dimensional space is unsuitable for probabilistic density estimation required by downstream distribution modeling. We employ an autoencoder to compress into compact latent features that extract abstract behavioral patterns while establishing a smooth low-dimensional manifold conducive to subsequent reweighting and augmentation operations.
Since the autoencoder operates on fixed-size vectors but receives variable-length sequences, we first aggregate
via multi-scale statistical pooling:
This captures central tendency (mean), extreme events (max), and distributional spread (standard deviation), providing a comprehensive flow-level summary.
The encoder
progressively compresses the aggregated representation through a four-layer feedforward bottleneck network:
The decoder
reconstructs the original representation through symmetric four-layer expansion (linear activation in the final layer to allow unrestricted value ranges):
The autoencoder is optimized with a composite loss balancing reconstruction fidelity and class separability:
where
denotes the cross-entropy loss between the one-hot label
and the predicted class probabilities
from an auxiliary classifier attached to the latent bottleneck. The hyperparameter
balances these objectives. Training is carried out using the Adam optimizer with early stopping.
The resulting latent features achieve three critical properties: (1) compactness—dimensionality is dramatically reduced from to , (2) discrimination—different traffic classes form well-separated clusters, and (3) smoothness—continuous manifold structure enables stable probabilistic density estimation (Component 3) and realistic generative synthesis (Component 4).
3.3. Stage 2: Data Quality Enhancement and Class Balancing
Stage 1 produces compact latent features that encode behavioral signatures, but real-world training data exhibits heterogeneous sample quality and extreme class imbalance that affect classifier performance. Due to Tor’s obfuscation mechanisms, training samples demonstrate varying levels of discriminability; some samples contain clear distinctive behavioral patterns that strongly represent their class (e.g., flows with consistent temporal characteristics), while others display ambiguous features due to encryption-induced feature overlap (e.g., flows at class boundaries exhibiting mixed characteristics). Training classifiers by treating all samples equally fails to leverage this quality variance, potentially diluting decision boundaries with less-representative samples. Additionally, extreme class imbalance, where benign traffic may outnumber rare attack types by orders of magnitude, causes classifiers to exhibit severe bias toward majority classes.
This stage addresses both challenges through ensemble-based distribution modeling in latent space. Component 3 employs five complementary models (Isolation Forest, Local Outlier Factor, One-Class SVM, Variational Autoencoder, and Masked Autoencoder for Density Estimation) to quantify sample-level discriminability. All detector outputs are mapped to a unified class-conditional compatibility (normality) convention, where larger scores indicate that a sample is more typical/compatible with the corresponding class distribution. Component 4 then trains three specialized Generative Adversarial Networks per class (total of six GANs for binary classification: malicious-GAN-A/B/C and benign-GAN-A/B/C) with complementary architectures to synthesize diverse realistic features for minority classes, with 5-model ensemble-based quality filtering ensuring generated samples preserve intra-class distributional characteristics. The resulting weighted balanced dataset enables robust classifier training under feature homogeneity and class imbalance.
3.3.1. Ensemble Compatibility Modeling for Sample Weighting
This component quantifies sample-level discriminability using an ensemble of five complementary models, enabling adaptive instance weighting that emphasizes clear representative samples while maintaining complete dataset coverage. By combining multiple algorithms that assess sample quality from different perspectives, this approach provides robust discriminability quantification that is resistant to the biases of individual methods.
For each traffic class , we train five complementary models on the class-specific latent features , where denotes the index set of samples with ground-truth hard label c. Note that is only used to define class-conditional groups for model fitting; the resulting detector outputs are aligned and aggregated into class-conditional compatibility scores, which are then converted into soft instance weights to modulate each sample’s contribution during training.
(1) Isolation Forest (IF) [
56]: Constructs an ensemble of random decision trees that isolate samples through recursive binary partitioning. Samples requiring fewer splits to isolate are considered anomalies. The raw IF score for sample
is computed as
where
is the average path length across all trees and
is the average path length of unsuccessful search in a binary search tree. (In IF, larger values indicate stronger outlierness; we invert its direction when forming compatibility scores).
(2) Local Outlier Factor (LOF) [
57]: Measures the local density deviation of a sample with respect to its neighbors. The LOF score quantifies how isolated a sample is relative to its local neighborhood:
where
denotes the
k-nearest neighbors and LRD is the local reachability density. (In LOF, larger values indicate stronger outlierness; we invert its direction when forming compatibility scores).
(3) One-Class SVM (OC-SVM) [
58]: Learns a decision boundary that encloses the majority of training samples in a high-dimensional feature space using kernel methods. We use the signed decision function value as a compatibility score (larger is more compatible):
where
is the Radial Basis Function (RBF) kernel,
are support vector coefficients, and
is the offset. This boundary-based approach captures global class structure.
(4) Variational Autoencoder (VAE) [
59]: A probabilistic generative model that learns a latent distribution
for the class-specific data. We use a reconstruction-based compatibility score (larger is more compatible):
where
is the mean of the encoded latent distribution.
(5) Masked Autoencoder for Density Estimation (MADE) [
60]: Models the autoregressive probability distribution
using masked connections. We use the log-likelihood as a compatibility score (larger is more compatible):
MADE provides explicit probabilistic density estimation, capturing the likelihood of samples under the learned class distribution.
To obtain robust discriminability estimates, we first calibrate the raw detector outputs from each model to a comparable scale and then aggregate them via weighted averaging. Specifically, for each class
c and detector
m, we apply column-wise min–max normalization over training samples in
:
Since IF/LOF naturally assign larger values to more outlying samples, we align all detectors to a unified larger-is-more-compatible convention via direction correction:
We then compute the ensemble compatibility score as
Intuitively,
summarizes multi-perspective consensus on sample class compatibility/typicality: samples consistently assessed as more compatible with class
c tend to receive higher ensemble scores.
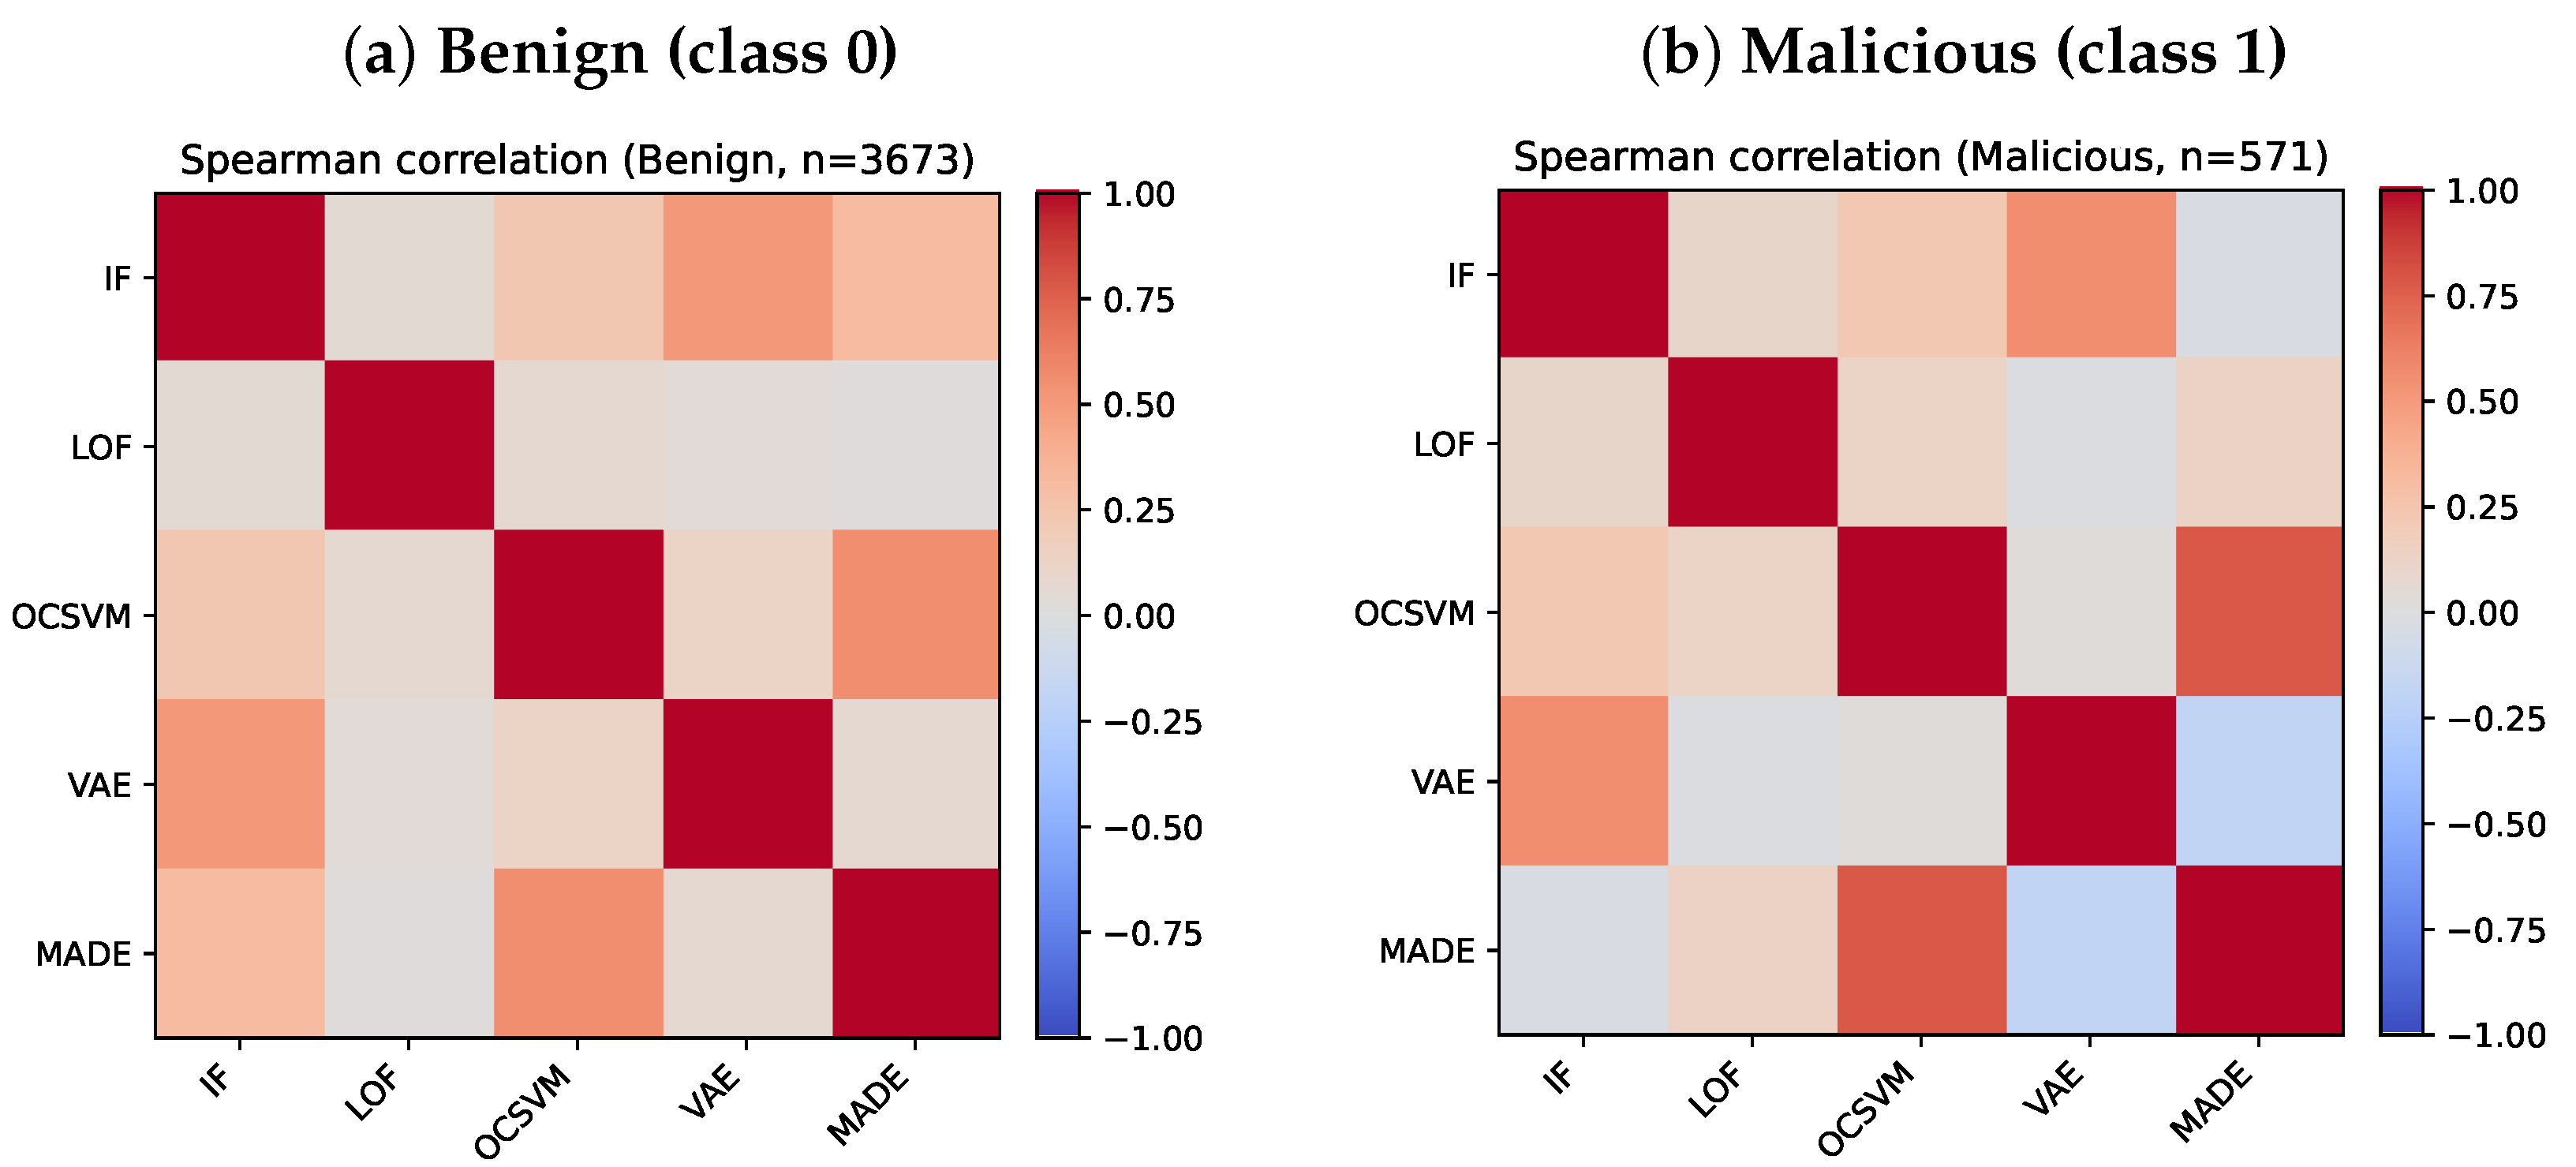
Detector complementarity. To justify using five models in Equation (
17), we assess potential redundancy by computing Spearman rank correlations between model outputs within each class (
Figure 4). We observe generally low off-diagonal correlations (median ≈ 0.093 for benign and ≈0.110 for malicious), indicating limited agreement in sample ranking and thus limited redundancy. LOF exhibits consistently weak correlations with other models, suggesting a relatively independent local-density signal. While OC-SVM and MADE show higher overlap on malicious samples (Spearman
), the overall ensemble remains complementary, supporting robustness through aggregating heterogeneous notions of compatibility. We adopt uniform
to keep the method reproducible and avoid additional tuning under extreme imbalance.
To enable adaptive weighting during classifier training, we convert ensemble scores into class-normalized instance weights via a temperature-controlled softmax:
where
controls how strongly high-compatibility samples are emphasized (larger
larger
). These weights are incorporated into classifier training through a weighted objective:
Robustness to score perturbations. Although exponentiation may amplify score differences, the normalized class-conditional softmax in Equation (
18) admits an explicit stability bound under bounded score perturbations, which addresses concerns about noisy or miscalibrated detector outputs.
Proposition 1 (Stability of class-conditional softmax weighting)
. Fix a class c and consider the score vector withLet perturbed scores be with , and let . Then, for any , Proof. We have
Since
,
for all
k; hence,
. Combining this with
yields
. □
Proposition 1 shows that the relative weight change is controlled by
. Moreover, Equation (
17) averages
heterogeneous models, which mitigates model-specific noise; under approximately independent zero-mean perturbations, the variance of the averaged ensemble score decreases as
. Consequently, the proposed weighting maintains full data coverage while adaptively emphasizing samples whose compatibility is consistently supported by multiple complementary models, yielding robust training-time reweighting under feature homogeneity.
3.3.2. Multi-GAN Augmentation with Ensemble Quality Filtering
This component addresses extreme class imbalance through a multi-GAN architecture that captures complementary distributional aspects of each traffic class. Rather than training a single generator per class, we employ three specialized GANs (denoted GAN-A, GAN-B, and GAN-C) with distinct architectural configurations to synthesize diverse realistic latent features from multiple generative perspectives. By operating in the compact latent space (rather than raw high-dimensional representations), GANs achieve stable training and generate semantically meaningful variations. This ensemble generative approach enhances intra-class diversity, improves robustness against mode collapse, and better captures the distributional complexity of malicious traffic variants. Ensemble-based quality filtering using all five models ensures synthetic samples preserve class-discriminative characteristics.
For each traffic class , we train three GANs with complementary architectures:
GAN-A (Shallow Generator): Uses a compact 3-layer generator [ → 256 → 512 → ] with larger hidden dimensions to capture coarse-grained distributional patterns. Discriminator architecture: [ → 256 → 128 → 1].
GAN-B (Deep Generator): Employs a deeper 4-layer generator [ → 256 → 512 → 256 → ] to model fine-grained behavioral nuances through increased representational capacity. Discriminator architecture: [ → 256 → 128 → 1].
GAN-C (Residual Generator): Incorporates skip connections in a 4-layer architecture [ → 256 → 512 → 256 → ] with residual blocks to preserve input noise structure and facilitate gradient flow. Discriminator architecture: [ → 256 → 128 → 1].
All generators transform random noise
into synthetic latent features
using LeakyReLU activations (negative slope 0.2) and batch normalization to stabilize training. Discriminators omit batch normalization to prevent mini-batch correlation artifacts and employ LeakyReLU followed by sigmoid output. Taking GAN-B as an example, the generator architecture is:
The discriminator for GAN-B follows:
where
is the sigmoid activation.
Each GAN is trained independently using the weighted binary cross-entropy objective. During discriminator training, real samples from class
c are weighted by their instance weights
from Component 3 (
Section 3.3), emphasizing high-quality samples:
where
denotes the GAN variant. The generator training objective is
Training alternates between one discriminator update (minimize
) and one generator update (minimize
). Each of the three GANs is trained independently for 50,000 iterations. Since we train three GANs per class (GAN-A, GAN-B, and GAN-C) and our binary classification problem involves two classes (malicious and benign), the total training involves 6 GANs with 50,000 iterations each.
After all GANs converge, we synthesize additional samples for minority classes to balance the dataset. The target size is set as
, and we use
by default (targeting an approximately 1:1 class ratio), selected via validation. For each class
c with
samples, we compute the augmentation ratio:
If
, we generate
candidate samples from each of the three GANs (GAN-A, GAN-B, and GAN-C), producing a diverse candidate pool covering multiple distributional modes. Each candidate
undergoes ensemble-based quality filtering using all five models from Component 3:
where
is the class-conditional compatibility score defined in Equation (
17) (larger is more compatible/typical). Only candidates exceeding
are retained, ensuring that generated features remain on-manifold and preserve class-discriminative characteristics while avoiding out-of-distribution artifacts. The final augmented dataset
combines weighted real samples with ensemble-validated synthetic samples from all three GANs, providing balanced high-quality training data for the final classifier.
GAN-Based Augmentation Effectiveness. The existing studies on imbalanced learning have shown that simple oversampling (e.g., random oversampling/SMOTE) and loss reweighting can mitigate imbalance but often suffer from limited minority diversity, boundary/noise amplification, or precision degradation, whereas GAN-based generators can better approximate complex minority distributions and thus produce more diverse and realistic synthetic samples, leading to improved minority-sensitive metrics (e.g., F1) under severe imbalance [
53,
61]. Consistent with these findings, our controlled baselines using the same latent features and the same LightGBM classifier show that loss reweighting (
class_weight) or focal-style reweighting yields only limited gains and/or trades precision for recall, while MAESTRO achieves the best overall balance (
Section 4.2). Moreover, replacing Stage 2 with SMOTE noticeably decreases F1 compared to the full GAN-based design (
Section 4.3), indicating that our GAN-driven augmentation (with ensemble quality filtering) provides higher-quality minority samples than simple oversampling.
3.4. Stage 3: Classifier-Agnostic Training
This stage converts the refined latent features from Stage 2 into operational malicious traffic detection through classifier-agnostic training. Since all downstream models operate on compact embeddings produced by the fixed preprocessing pipeline, the training protocol is independent of the specific classifier architecture, enabling fair comparison across diverse models and straightforward replacement with future state-of-the-art classifiers without modifying the data refinement components.
3.4.1. Training Protocol
Given the augmented dataset
produced by Stage 1–2, we train a classifier
on weighted latent samples
by minimizing the weighted empirical risk:
where
is the cross-entropy loss and
are the ensemble-derived instance weights from Component 3. Unless otherwise specified, we assign synthetic samples a uniform weight (
) to avoid propagating detector-induced uncertainty to generated data; real samples keep the class-conditional softmax weights defined in Equation (
18). This design decouples data quality refinement from model selection: we evaluate multiple classifiers using their original optimization settings while keeping
fixed, avoiding confounding factors caused by different feature pipelines.
3.4.2. Inference Pipeline with Class-Conditional Compatibility Screening
For an incoming test flow
, we first compute its multi-scale representation
(Component 1) and obtain the latent embedding
using the frozen encoder (Component 2). We then perform class-conditional compatibility screening using the ensembles trained for each class (Component 3). Let
where a larger value indicates higher compatibility (normality) of
with the corresponding class distribution. A test flow is flagged as a potential novel/unknown attack if it is incompatible with all known classes:
In this case, the flow is routed to analysts for manual verification. Otherwise (
), the system proceeds with standard classification using
and triggers the corresponding security action. This inference protocol is classifier-agnostic: all evaluated architectures consume the same latent features
, and the compatibility screening step is identical across classifiers.
4. Evaluation
This section systematically evaluates MAESTRO to answer three research questions: (RQ1) Does MAESTRO outperform the existing state-of-the-art methods? (RQ2) What is the individual contribution of each stage? (RQ3) How does MAESTRO perform under extreme class imbalance? In addition, for reproducibility, we have publicly released the source code of MAESTRO at
https://github.com/Gpsjinbu/MAESTRO.git (accessed on 30 January 2026).
4.1. Experimental Setup
4.1.1. Dataset
We evaluate MAESTRO on the Tor malware traffic dataset from Dodia et al. [
16] (CCS’22). The dataset contains authenticated malicious and benign Tor traffic collected through controlled sandbox environments. Malicious samples originate from 157 Tor-capable malware binaries (D5 subset) verified on VirusTotal and executed in CrowdStrike Falcon sandbox, yielding 2027 malicious traffic flows. Benign traffic comprises 13,214 flows from automated Tor Browser sessions and ISCXTor2016 dataset [
17]. The dataset exhibits moderate imbalance with a benign-to-malicious ratio of approximately 6.5:1.
Each flow is represented as a sequence of cells with three observable attributes: inter-arrival time
, position
, and direction
. Following standard practices [
9,
11], the first
cells are extracted, with shorter flows padded and longer flows truncated. The dataset is split into training (70%), validation (15%), and test (15%) sets using stratified random sampling.
4.1.2. Evaluation Metrics
We adopt four standard classification metrics to provide comprehensive performance assessment. Accuracy measures the overall fraction of correctly classified flows, calculated as , although this metric can be misleading under class imbalance. Precision quantifies the fraction of flows predicted as malicious that are truly malicious (), where high precision minimizes false alarms in operational deployment. Recall represents the fraction of actual malicious flows correctly identified (), which is critical for security applications where missing threats has severe consequences. F1-score computes the harmonic mean of precision and recall (), and we report macro-averaged F1 emphasizing minority class performance.
For imbalanced scenarios, we prioritize recall and F1-score as primary metrics since accuracy can be trivially achieved by predicting the majority class.
4.1.3. Baseline Methods
We compare MAESTRO against representative methods from two categories:
Category 1: Malicious Tor Traffic Detection
LightGBM [
16]: Gradient boosting classifier trained on statistical flow-level features, including packet counts, inter-arrival time statistics, burst patterns, and directional ratios.
TrafficFormer [
33]: Transformer-based architecture with multi-head self-attention mechanisms for encrypted traffic classification. Pre-trained on large-scale traffic corpora and fine-tuned for binary malicious detection.
Category 2: General Traffic Analysis
DF [
9]: Deep Fingerprinting with CNN architecture employing 1D convolutions over packet direction sequences. Adapted for binary malicious traffic detection.
AWF [
11]: Automated Website Fingerprinting with enhanced CNN incorporating spatial attention mechanisms.
BAPM [
40]: Block Attention Profiling Model combining burst analysis and pattern mining with a Random Forest classifier.
TikTok [
12]: Timing-based fingerprinting method exploiting inter-packet delay distributions.
ContraMTD [
47]: Unsupervised malicious traffic detection using contrastive learning to maximize agreement between augmented traffic views.
AN-Net [
21]: Anti-noise network with attention-based feature selection and noise-robust loss functions for anonymous traffic classification.
Category 1 methods are directly comparable as they target the same problem setting. Category 2 methods, including traditional machine learning approaches (BAPM and TikTok) and deep learning techniques (DF, AWF, ContraMTD, and AN-Net) adapted from encrypted traffic analysis, provide broader context for assessing MAESTRO’s effectiveness across diverse analytical paradigms. All methods are evaluated using hyperparameters tuned on our validation set to ensure a fair comparison. For methods originally designed for multi-class classification (DF and AWF), we replace the output layer with a binary head and retrain the models from scratch on our dataset. In addition, to address concerns about model complexity, we include three simple imbalance-aware baselines that train LightGBM directly on MAESTRO’s latent features: (i) plain objective, (ii) class-weighted loss, and (iii) focal loss, all without MAESTRO’s ensemble-based reweighting or GAN augmentation.
4.1.4. Implementation Details
We implement MAESTRO in PyTorch 1.13.1 on NVIDIA V100 GPUs.
Table 1 details the hyperparameter configuration.
The four components are trained sequentially. Stage 1: Component 1 extracts multi-scale representations, and then Component 2 (autoencoder) is trained for 100 epochs to compress them into latent features. Stage 2a: Five compatibility models are trained per class on class-specific latent features. Stage 2b: Ensemble compatibility scores are computed for all training samples and converted to normalized instance weights (softmax temperature
). Stage 2c: Three GANs per class (6 total) are trained for 50,000 iterations each (300,000 total), generating candidates that undergo 5-model ensemble filtering (Equation (
28)). Stage 3: The final classifier is trained on an augmented balanced dataset with weighted cross-entropy loss. Total training time is approximately 12 h on a V100 GPU. The modular design allows intermediate representations to be cached and reused across experiments.
Unless otherwise stated, we repeat each experiment over
independent runs with different random seeds (data split and model initialization) and report mean ± std for accuracy/precision/recall/F1. The same protocol is applied to all baselines and ablations.
Figure 5,
Figure 6 and
Figure 7 visualize averaged results; standard deviations are not plotted to keep the figures readable.
Why GAN-based augmentation. We prefer GAN-based augmentation (with the compatibility filtering in Equation (
28)) over simpler random oversampling or loss reweighting for two reasons. First, random duplication does not increase minority coverage and can amplify overfitting under extreme imbalance. Second, loss reweighting changes gradient contributions but does not enrich minority support; empirically, simple imbalance-aware training on the same latent features (class_weight/focal) improves recall but significantly reduces precision (
Section 4.2), whereas MAESTRO achieves substantially higher F1 mainly by improving precision. In addition, replacing Stage 2 with a SMOTE-based augmentation baseline yields a notable F1 drop (
Section 4.3), suggesting that controlled generative augmentation better fits the multimodal minority distribution in our latent space.
4.2. RQ1: Overall Performance Comparison
To evaluate MAESTRO’s effectiveness for malicious Tor traffic detection, we compare it against eight state-of-the-art baselines on the CCS’22 Tor Malware dataset test set under natural class distribution (approximately 6.5:1 benign-to-malicious ratio). The baselines include two specialized malicious Tor detection methods (LightGBM and TrafficFormer) and six general traffic analysis methods (DF, AWF, BAPM, TikTok, ContraMTD, and AN-Net). In addition, following the reviewer suggestion on model complexity, we include three simple imbalance-aware baselines that train LightGBM directly on MAESTRO’s latent features: Classifier (plain), Classifier (+class_weight), and Classifier (+focal), all without MAESTRO’s ensemble-based reweighting or GAN augmentation. We report mean ± std over
runs on four key metrics.
Table 2 presents the main comparison with prior work, and
Table 3 further reports the reviewer-requested simple imbalance-aware baselines. Note that the LightGBM baseline in
Table 2 follows the original baseline feature setting, whereas the three simple imbalance-aware baselines in
Table 3 train the same LightGBM directly on MAESTRO’s latent features
to isolate the effect of imbalance handling without MAESTRO’s reweighting/augmentation.
Overall Performance Metrics and Comparative Advantages.
Table 2 shows that MAESTRO achieves the highest mean performance across all four metrics over
runs:
accuracy,
precision,
recall, and
F1-score. We observe the most significant advantage in F1-score, where MAESTRO exceeds the second-best baseline (LightGBM:
) by 15.53% relative improvement (9.91 absolute percentage points) on the mean. In recall, MAESTRO improves over the second-best DF (
) by 6.99% relative on the mean and over LightGBM (
) by 24.4% relative. Using mean recall, the miss rate decreases from 47.89% (LightGBM) to 35.21% (MAESTRO). In precision, MAESTRO reaches
, improving over AWF (
) by 6.76% and over LightGBM (
) by 3.88% on the mean. We hypothesize that this joint improvement is consistent with MAESTRO’s combination of representation learning and data-centric refinement, which can increase minority-class coverage without an excessive increase in false alarms. We also observe that the standard deviations are modest (e.g., F1
), suggesting stable gains across different random seeds.
Comparison with Simple Imbalance-Aware Baselines.
Table 3 reports three simpler imbalance-aware variants that keep the same latent features and the same LightGBM classifier but remove MAESTRO’s ensemble-based reweighting and GAN augmentation. Both class-weighting and focal loss mitigate imbalance to some extent: compared with Classifier (plain), class-weighting increases recall from
to
but reduces precision from
to
, leading to a moderate F1 improvement (
). Focal loss yields a similar trade-off (
F1). MAESTRO still outperforms the strongest simple baseline (Classifier +class_weight) with higher recall (
vs.
) and substantially higher precision (
vs.
), resulting in a higher F1-score (
vs.
, +5.23 absolute points, +7.64% relative). This suggests that MAESTRO’s gains go beyond standard loss-based rebalancing and are consistent with its quality-aware refinement and controlled augmentation design.
Table 2.
Performance comparison under natural class distribution. Best in bold; second-best underlined. Results are reported as mean ± std over runs. Relative improvements are computed on the means.
Table 2.
Performance comparison under natural class distribution. Best in bold; second-best underlined. Results are reported as mean ± std over runs. Relative improvements are computed on the means.
| Category | Method | Accuracy | Precision | Recall | F1-Score |
|---|
| Malicious Tor traffic detection | LightGBM | 0.9200 ± 0.0082 | 0.8222 ± 0.0156 | 0.5211 ± 0.0243 | 0.6379 ± 0.0198 |
| TrafficFormer | 0.8971 ± 0.0112 | 0.7075 ± 0.0214 | 0.4085 ± 0.0187 | 0.5179 ± 0.0225 |
| General traffic analysis | DF | 0.8857 ± 0.0098 | 0.5733 ± 0.0231 | 0.6056 ± 0.0167 | 0.5890 ± 0.0189 |
| AWF | 0.8762 ± 0.0124 | 0.8000 ± 0.0143 | 0.1127 ± 0.0098 | 0.1975 ± 0.0156 |
| BAPM | 0.8990 ± 0.0105 | 0.7812 ± 0.0178 | 0.3521 ± 0.0213 | 0.4854 ± 0.0201 |
| TikTok | 0.8952 ± 0.0131 | 0.6481 ± 0.0256 | 0.4930 ± 0.0194 | 0.5600 ± 0.0173 |
| ContraMTD | 0.8971 ± 0.0118 | 0.6308 ± 0.0224 | 0.5775 ± 0.0156 | 0.6029 ± 0.0168 |
| AN-Net | 0.9048 ± 0.0096 | 0.6780 ± 0.0192 | 0.5634 ± 0.0175 | 0.6154 ± 0.0184 |
| Our method | MAESTRO | 0.9238 ± 0.0075 | 0.8541 ± 0.0132 | 0.6479 ± 0.0146 | 0.7370 ± 0.0123 |
| | | (+0.41%) | (+3.88%) | (+6.99%) | (+15.53%) |
Table 3.
Simple imbalance-aware baselines using the same latent features and the same LightGBM classifier without ensemble-based reweighting or GAN augmentation. Best in bold; second-best underlined. Results are reported as mean ± std over runs.
Table 3.
Simple imbalance-aware baselines using the same latent features and the same LightGBM classifier without ensemble-based reweighting or GAN augmentation. Best in bold; second-best underlined. Results are reported as mean ± std over runs.
| Method | Accuracy | Precision | Recall | F1-Score |
|---|
| Classifier (plain) | 0.9204 ± 0.0042 | 0.7986 ± 0.0602 | 0.5606 ± 0.0392 | 0.6554 ± 0.0088 |
| Classifier (+class_weight) | 0.9200 ± 0.0047 | 0.7382 ± 0.0461 | 0.6423 ± 0.0340 | 0.6847 ± 0.0061 |
| Classifier (+focal) | 0.9196 ± 0.0025 | 0.7475 ± 0.0512 | 0.6310 ± 0.0861 | 0.6772 ± 0.0290 |
| MAESTRO | 0.9238 ± 0.0075 | 0.8541 ± 0.0132 | 0.6479 ± 0.0146 | 0.7370 ± 0.0123 |
Baseline Method Failure Patterns Across Categories. Baseline methods exhibit recurring precision–recall trade-offs under the natural 6.5:1 skew. We observe three representative patterns. (1) Conservative majority bias: some models maintain high accuracy but suppress recall (e.g., LightGBM:
accuracy vs.
recall; AWF:
precision vs.
recall), indicating a tendency to minimize false positives by predicting the majority class more often. (2) High-recall with elevated false alarms: DF achieves relatively high recall (
) but lower precision (
), which would translate into high alert volume in deployment. (3) Loss-based rebalancing trade-off: class_weight/focal improves recall but can noticeably reduce precision (
Table 3), suggesting that loss reweighting alone may increase false alarms even when detection coverage improves.
Architectural Factors Underlying MAESTRO’s Superiority. MAESTRO’s superior performance is consistent with three design choices (interpretations rather than causal proofs). First, multi-scale representation learning captures behavioral signatures at cell-, direction-, and flow-level granularities, which may help to preserve discriminative cues despite Tor’s fixed-size cell homogenization. Second, autoencoder-based compression transforms multi-granularity representations into compact latent embeddings, which may improve separability compared to handcrafted statistical features. Third, the ensemble-based weighting and multi-GAN augmentation explicitly target minority-class learning difficulty: reweighting emphasizes high-confidence samples, while generation plus ensemble filtering aims to expand coverage without introducing low-quality artifacts.
Summary. MAESTRO achieves state-of-the-art performance under natural class distribution, improving F1-score by 15.53% (relative) over the best prior baseline in
Table 2 while maintaining both high recall (
) and high precision (
). Compared with simpler imbalance-aware alternatives on the same latent space (
Table 3), MAESTRO also delivers a higher F1-score (+7.64% relative over class-weighting) with substantially higher precision, indicating benefits beyond standard loss-based rebalancing; we do not claim causal attribution beyond what is supported by controlled ablations.
4.3. RQ2: Ablation Study on Component Contributions
To isolate the contribution of each architectural component, we conduct systematic ablation experiments by removing or replacing key modules. Indeed, “w/o Stage 1” replaces multi-scale embeddings with statistical features and removes the autoencoder. “Stage 2 replaced by SMOTE” removes ensemble-based reweighting and multi-GAN augmentation and instead uses uniform weights and SMOTE-based oversampling in the latent space.
Table 4 presents the performance comparison across configurations.
Impact of Multi-Scale Representation and Autoencoder (Stage 1).
Table 4 shows that removing Stage 1 causes the most severe performance degradation across all metrics. The full MAESTRO achieves
recall and
F1-score, while the w/o Stage 1 variant drops to
recall and
F1-score, representing 15.57% and 15.69% relative degradation on the mean, respectively. Precision decreases from
to
(15.71% relative). We hypothesize that replacing multi-scale behavioral modeling and autoencoder compression with coarse statistical features (e.g., mean/variance) removes temporal ordering and positional dependencies, reducing separability under Tor’s homogenized structure.
Table 4.
Ablation study on component contributions. Results are reported as mean ± std over runs. Relative changes are computed on the means.
Table 4.
Ablation study on component contributions. Results are reported as mean ± std over runs. Relative changes are computed on the means.
| Model Variant | Accuracy | Precision | Recall | F1-Score |
|---|
| MAESTRO (Full) | 0.9238 ± 0.0075 | 0.8541 ± 0.0132 | 0.6479 ± 0.0146 | 0.7370 ± 0.0123 |
| w/o Stage 1 (multi-scale + AE) | 0.8895 ± 0.0078 | 0.7199 ± 0.0156 | 0.5470 ± 0.0189 | 0.6214 ± 0.0145 |
| | (−3.71%) | (−15.71%) | (−15.57%) | (−15.69%) |
| Stage 2 replaced by SMOTE | 0.9010 ± 0.0065 | 0.7338 ± 0.0124 | 0.6338 ± 0.0112 | 0.6798 ± 0.0103 |
| | (−2.47%) | (−14.08%) | (−2.18%) | (−7.76%) |
Impact of Ensemble-Based Weighting and Multi-GAN Augmentation (Stage 2). Replacing Stage 2 with SMOTE yields a 7.76% relative decrease in F1-score on the mean ( to ). We observe a pronounced precision reduction (14.08% relative; to ), while recall changes only slightly (2.18% relative; to ). We hypothesize that ensemble-based reweighting provides a quality-aware training signal and that multi-GAN augmentation with ensemble filtering expands minority coverage while avoiding low-quality synthetic samples; in contrast, SMOTE-style interpolation may be insufficient for multimodal minority distributions in latent space.
Synergistic Component Interaction. We observe that Stage 1 and Stage 2 contribute in complementary ways: removing Stage 1 yields the largest drops across recall/precision/F1, whereas modifying Stage 2 primarily affects precision and F1. We hypothesize an interaction effect where compact latent features from Stage 1 facilitate more stable augmentation and filtering in Stage 2, and Stage 2 refines the effective training distribution for the final classifier. This interpretation does not establish causality; it is consistent with the full model outperforming both ablated variants in
Table 4.
Summary. Both stages contribute substantially to MAESTRO’s performance. Stage 1 has the larger overall impact, while Stage 2 further improves precision/F1 and helps to preserve the precision–recall balance under imbalance.
4.4. RQ3: Robustness Under Varying Class Imbalance
To evaluate robustness under realistic deployment conditions, we systematically vary the malicious traffic sampling ratio from 100% (using all available malicious samples) down to 1% across eight levels (100%, 80%, 60%, 40%, 20%, 10%, 5%, and 1%). This simulates real-world scenarios where malicious Tor traffic constitutes small and varying minorities of total network flows.
Performance Degradation Patterns and Trade-Off Trajectories.
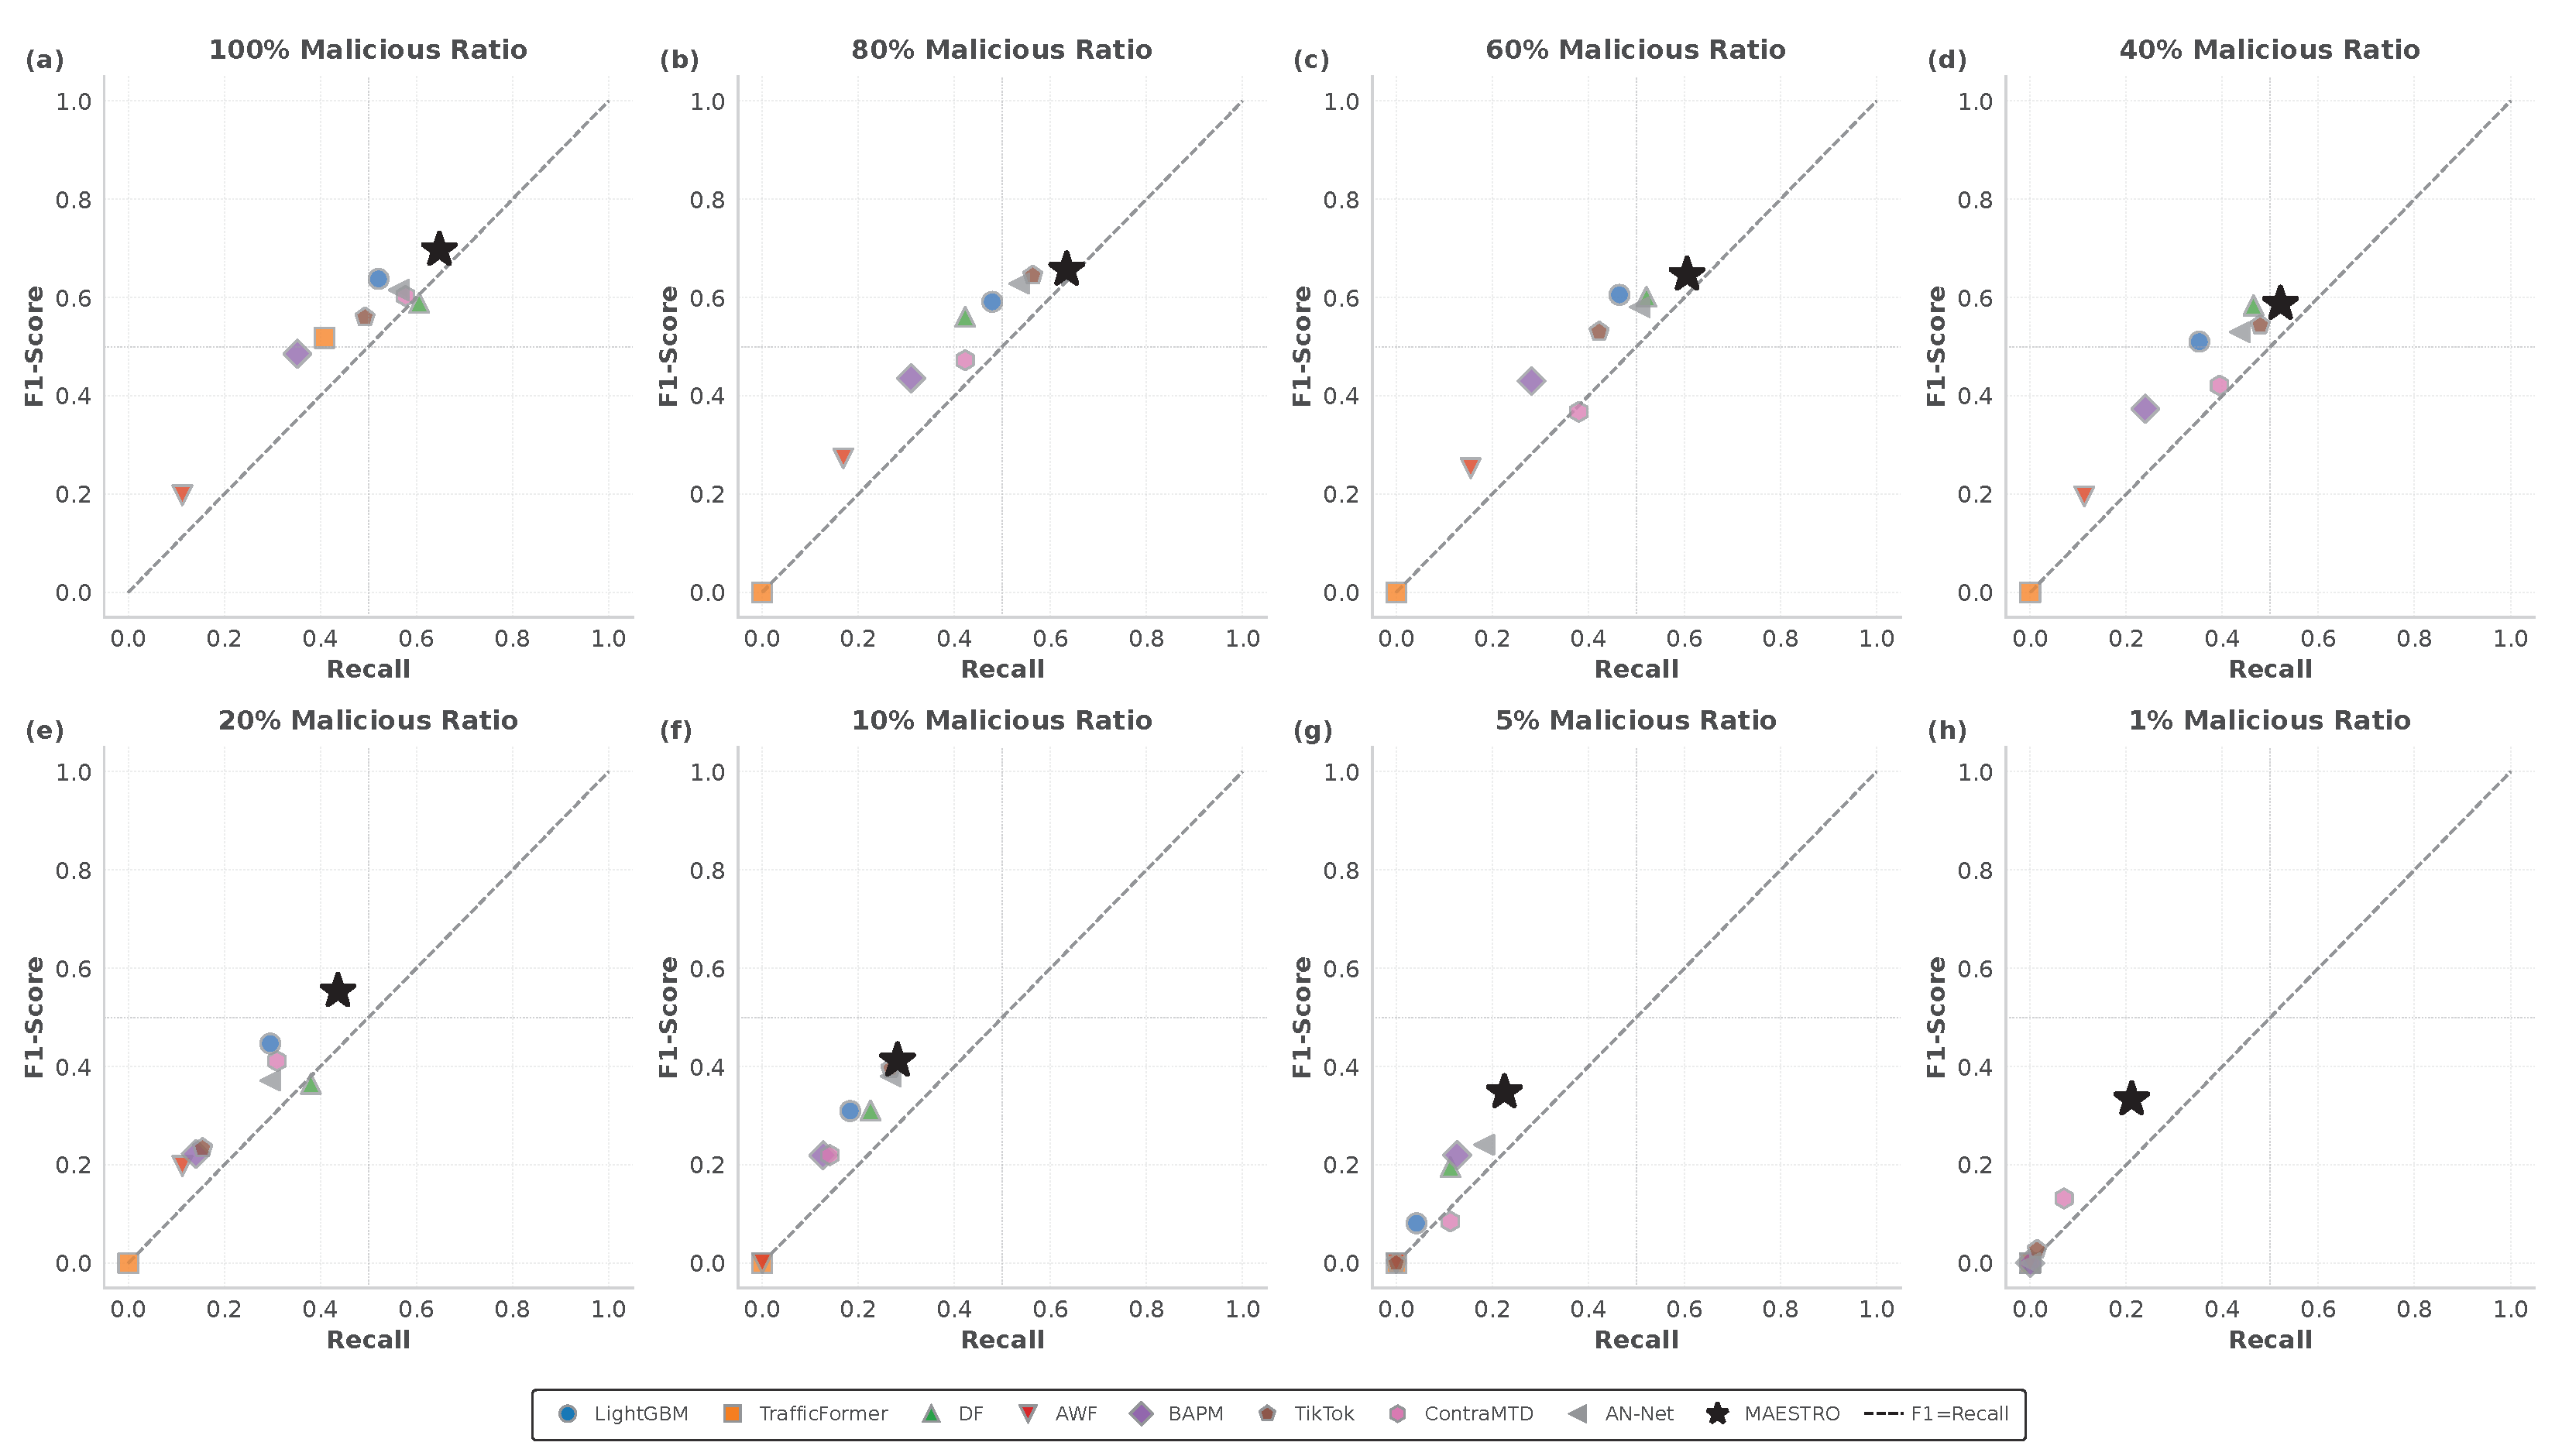
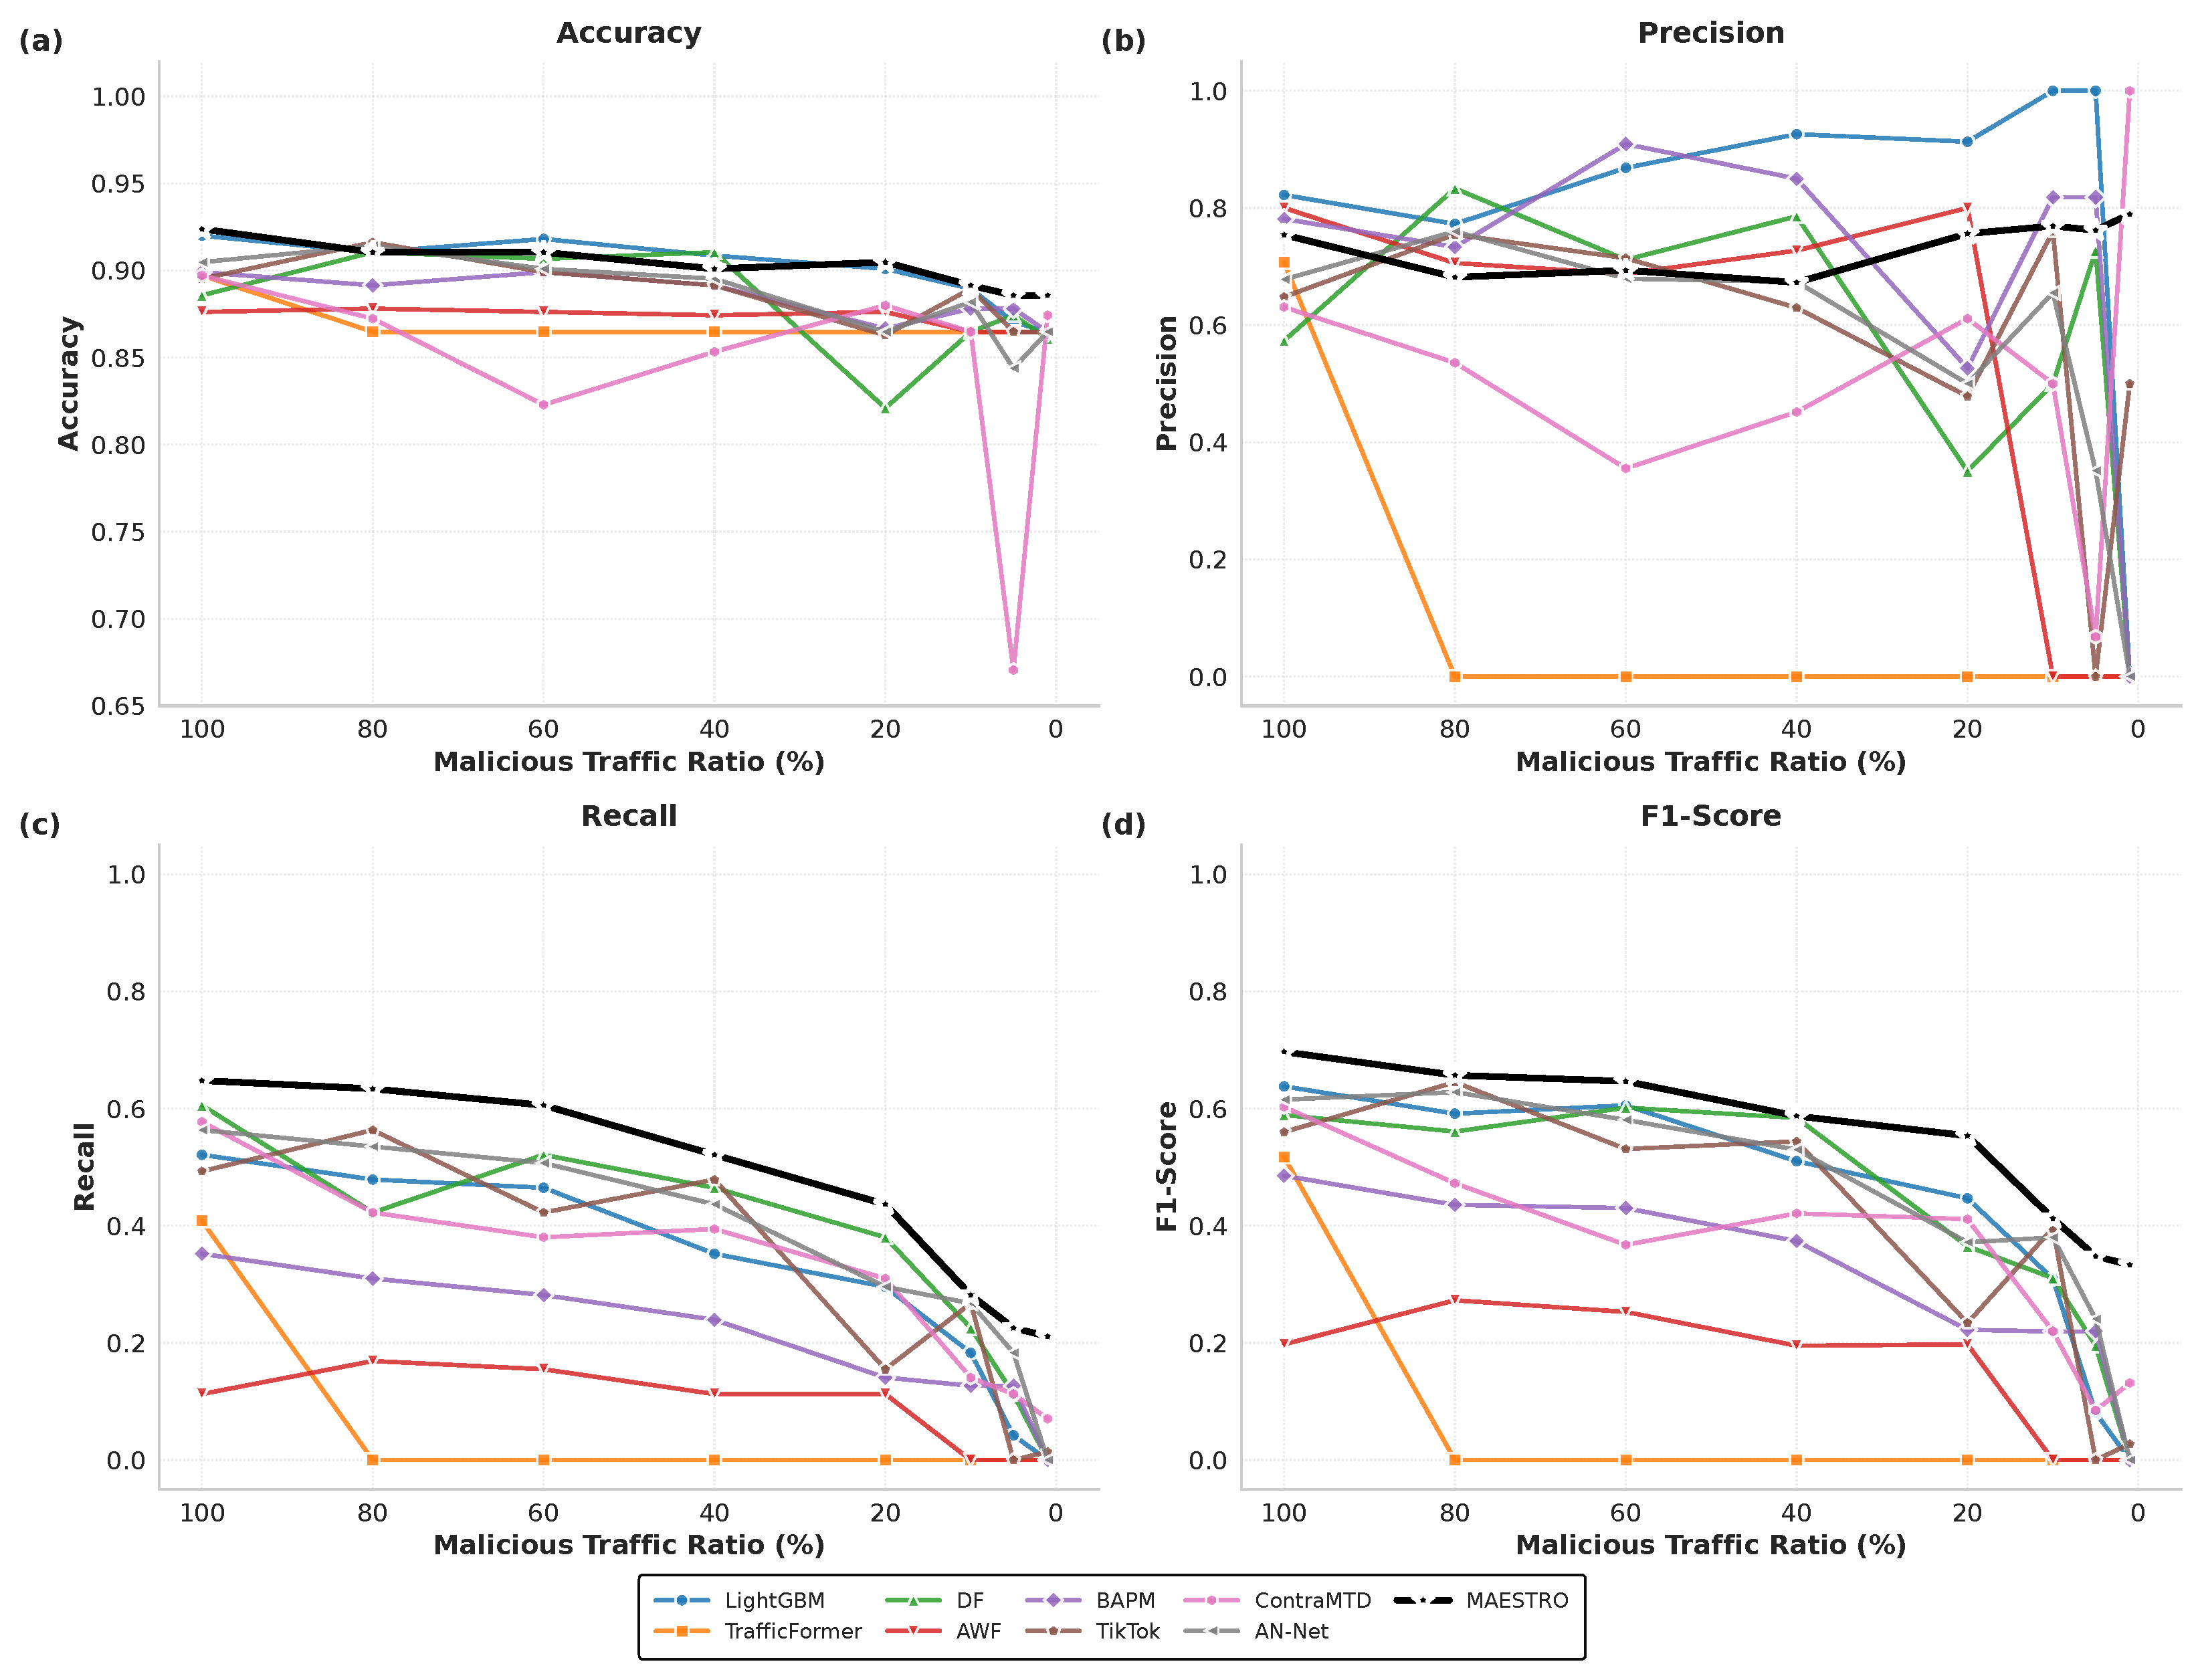
Figure 5 and
Figure 6 report averages over
runs (std omitted in plots for readability). We observe that MAESTRO maintains strong recall and competitive F1-score across all ratios with a smooth monotonic decline as imbalance becomes more extreme. We hypothesize that this behavior is consistent with MAESTRO’s data-centric refinement, where controlled augmentation and quality filtering reduce minority-class collapse while preserving precision.
Figure 5.
Performance curves under varying malicious sampling ratios (100% to 1%): (a) Accuracy; (b) Precision; (c) Recall; (d) F1-score. MAESTRO maintains superior recall and F1-score across all imbalance levels.
Figure 5.
Performance curves under varying malicious sampling ratios (100% to 1%): (a) Accuracy; (b) Precision; (c) Recall; (d) F1-score. MAESTRO maintains superior recall and F1-score across all imbalance levels.
Figure 6.
Recall–F1 scatter plots across eight malicious sampling ratios: (a) ratio 100%; (b) ratio 80%; (c) ratio 60%; (d) ratio 40%; (e) ratio 20%; (f) ratio 10%; (g) ratio 5%; (h) ratio 1%. MAESTRO (black stars) maintains consistent high-performance positioning across all ratios. The diagonal line indicates balanced precision–recall.
Figure 6.
Recall–F1 scatter plots across eight malicious sampling ratios: (a) ratio 100%; (b) ratio 80%; (c) ratio 60%; (d) ratio 40%; (e) ratio 20%; (f) ratio 10%; (g) ratio 5%; (h) ratio 1%. MAESTRO (black stars) maintains consistent high-performance positioning across all ratios. The diagonal line indicates balanced precision–recall.
We observe that accuracy remains misleadingly high for all methods even at 1% ratio, while recall and F1 reveal substantial differences in detection capability. This highlights accuracy’s inadequacy for imbalanced security tasks as high accuracy can mask severe failures in minority-class detection.
Extreme Imbalance Breakdown at 1% Ratio.
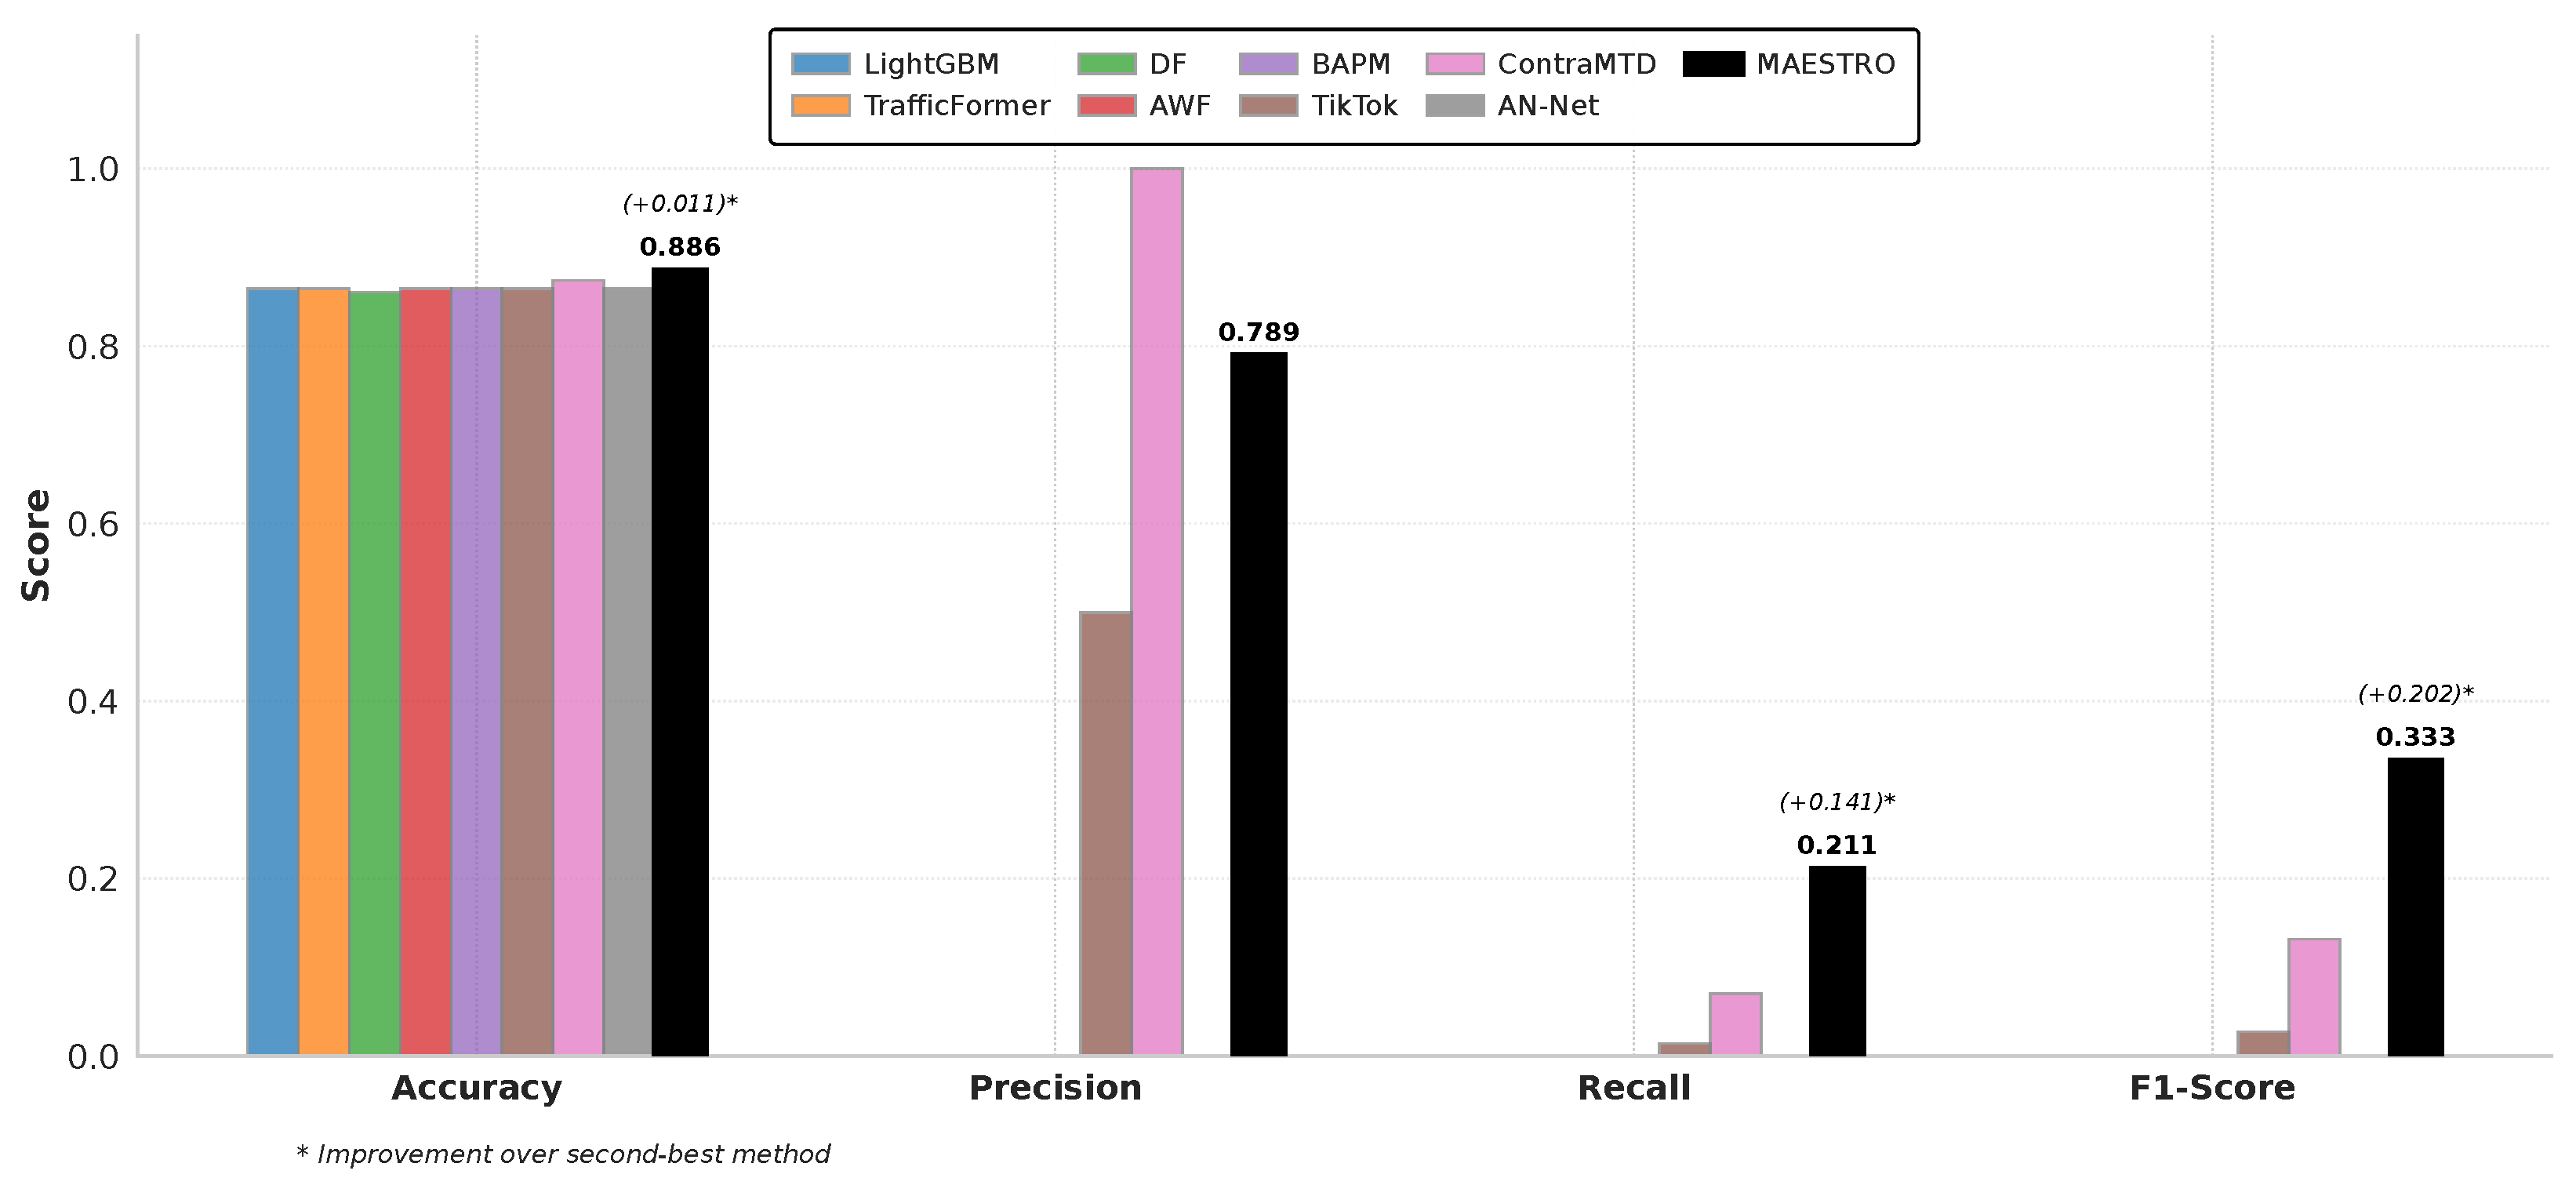
Figure 7 provides a detailed performance breakdown at 1% malicious sampling ratio. We observe that MAESTRO maintains non-trivial detection capability (e.g., recall 21.1% and F1-score 33.3%, as shown in the figure), whereas several baselines collapse toward near-zero recall/F1. A plausible interpretation is that conservative models can maintain high accuracy by predicting the majority class, which is operationally undesirable when false negatives are costly.
Figure 7.
Performance at 1% malicious sampling ratio. MAESTRO achieves 21.1% recall and 33.3% F1-score with 14.1% absolute improvement in recall over second-best ContraMTD, demonstrating robustness against minority-class collapse.
Figure 7.
Performance at 1% malicious sampling ratio. MAESTRO achieves 21.1% recall and 33.3% F1-score with 14.1% absolute improvement in recall over second-best ContraMTD, demonstrating robustness against minority-class collapse.
Despite the recall and F1-score advantages, MAESTRO may exhibit slightly lower accuracy than conservative baselines at extreme skew. We observe that this trade-off corresponds to prioritizing threat detection (higher recall/F1) over majority-class correctness, aligning with typical security monitoring objectives.
Summary. Across the metric curves, recall–F1 trajectories, and the 1% breakdown, MAESTRO shows robust behavior under increasing class imbalance. We hypothesize that this robustness is consistent with combining multi-scale representation learning and controlled quality-filtered augmentation that targets minority collapse.
5. Discussion
MAESTRO demonstrates several key advantages for practical deployment. The modular three-stage design decouples feature extraction, data refinement, and classifier training, enabling flexible integration with existing security infrastructure without requiring specialized hardware or protocol modifications. The classifier-agnostic nature allows security operators to select downstream classifiers (e.g., Random Forest, SVM, and neural networks) based on operational constraints, such as lightweight models for edge deployment or deep architectures for centralized analysis. By operating exclusively on observable cell-level metadata (timing, position, and direction) without deep packet inspection, MAESTRO preserves user privacy and complies with legal constraints prohibiting traffic decryption, making it suitable for ISP-level monitoring and enterprise gateways where privacy regulations apply. Ensemble-based quality control and multi-GAN augmentation provide inherent robustness to class imbalance, maintaining 21.1% recall under an extreme 1% malicious ratio, which is approximately higher than conventional methods that collapse below 10%.
However, the generalizability of these results is subject to certain limitations. Although the effectiveness of the proposed framework is verified on the CCS’22 Tor malware dataset comprising 157 malware families, the evaluation focuses on known threats captured during 2020–2022. As adversaries develop novel evasion techniques, such as adaptive traffic padding or mimicry attacks that replicate benign browsing patterns, the framework’s performance in real-world evolving threat landscapes requires further validation and periodic retraining on updated threat intelligence. Additionally, MAESTRO’s reliance on cell-level metadata (without deep packet inspection) inherently limits its ability to detect sophisticated payload-based threats that manipulate application-layer protocols while maintaining benign-like traffic patterns. The current binary classification framework also lacks support for fine-grained malware family categorization, which would be necessary for implementing differentiated response strategies (e.g., immediate blocking for ransomware versus monitoring for APT reconnaissance). Nonetheless, this study provides a foundational framework, demonstrating the potential of combining multi-scale behavioral modeling, ensemble-based quality control, and multi-generator augmentation in encrypted traffic analysis. Future research can expand on this framework by validating it in more diverse real-world network environments with continuously evolving threats and extending it to multi-class classification scenarios that balance fine-grained threat categorization with computational efficiency.