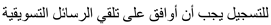Article

A Low-Resource Arabic Dataset and Transformer-Based Benchmark for Dark Pattern Detection in E-Commerce Mobile Applications

by
Reham Alabduljabbar
Information Technology Department, College of Computer and Information Sciences, King Saud University, Riyadh 11362, Saudi Arabia
Electronics 2026, 15(17), 3955; https://doi.org/10.3390/electronics15173955
Submission received: 4 July 2026 / Revised: 23 August 2026 / Accepted: 31 August 2026 / Published: 2 September 2026
(This article belongs to the Special Issue Low-Resource Languages in the Age of Large Language Models)

Abstract

Arabic remains underrepresented in many task-specific natural language processing (NLP) resources and benchmarks, particularly for specialized user interface (UI) understanding tasks. In mobile commerce, Arabic UI text may contain persuasive or deceptive design cues known as dark patterns; however, Arabic-language dark pattern detection remains largely unexplored. To the best of our knowledge, this paper presents the first ML-based benchmark for Arabic dark pattern detection. We construct a novel annotated dataset of 223 Arabic UI text strings from nine e-commerce mobile applications operating in Saudi Arabia, labeled across five dark pattern categories and a non-dark-pattern class (Cohen’s kappa κ = 0.89). Using a stratified, leakage-free 70/10/20 split with parent-aware paraphrase augmentation applied only to the training partition, we fine-tune five pretrained transformer models: AraBERTv2, MARBERT, mBERT, BERT-base-uncased, and RoBERTa-base. Our primary evaluation is 5-fold cross-validation on the 223 original, non-augmented instances, separate from the augmented training corpus used for the held-out test comparison. Under this evaluation, MARBERT achieves the strongest performance (mean macro-F1 = 0.4230), numerically ahead of AraBERTv2 (0.2998) by a margin that does not reach statistical significance at five folds (p ≈ 0.064), and ahead of mBERT (0.3234); MARBERT significantly outperforms both English-only baselines, and mBERT is numerically stronger than both, though mBERT was not directly tested against them for significance. This suggests pre-training on dialectal, code-switched Arabic may matter more here than Arabic pre-training alone. Per-class analysis shows every model struggles with several minority categories, indicating Arabic dark pattern detection remains genuinely difficult at current data volumes. The annotated dataset is publicly released to support future low-resource Arabic NLP research.

1. Introduction

E-commerce has experienced substantial growth across the Arab world, with Saudi Arabia emerging as one of the region’s most dynamic digital markets. The Saudi e-commerce sector is projected to exceed US$19.52 billion by 2030, driven by high smartphone penetration and widespread adoption of mobile shopping platforms [1,2]. As consumers increasingly rely on mobile applications for shopping, food delivery, travel booking, and daily services, interface design plays an important role in shaping user decisions. This rapid expansion has raised growing concerns about the ethical design practices of platforms operating in the region. Among the most pressing concerns in digital consumer protection is the proliferation of dark patterns, which are deceptive user interface (UI) design techniques that manipulate users into actions that may not align with their original intentions or interests [3]. Such patterns are commonly used to encourage unintended purchases, create artificial urgency, obscure additional costs, complicate cancellation processes, or pressure users into disclosing unnecessary personal information. In e-commerce settings, these practices can directly affect consumer autonomy, transparency, and trust. Examples include countdown timers that imply limited availability, hidden delivery or service fees revealed late in the checkout process, misleading subscription prompts, and interface flows that make cancellation or opt-out actions unnecessarily difficult.
Dark patterns are particularly important in mobile commerce because mobile interfaces are often space-constrained, fast-paced, and highly persuasive. Users frequently interact with mobile shopping applications through short UI text, buttons, pop-ups, notifications, promotional banners, and checkout messages. These textual elements are brief but influential, making them suitable targets for automated text-based detection. In our annotated sample from nine e-commerce mobile applications operating in Saudi Arabia, dark pattern cues were identified in 75.8% of UI text instances. Because the dataset was purposively collected from UI strings containing potential dark pattern cues and comparable non-dark-pattern examples, this percentage should not be interpreted as a prevalence estimate for all UI text in the selected applications. Rather, it indicates that potentially deceptive or manipulative interface language appears across multiple Arabic-language mobile commerce contexts and warrants systematic study. Academic and regulatory interest in dark patterns has grown substantially in recent years. Mathur et al. [4] conducted a seminal large-scale analysis of dark patterns in online shopping websites, identifying 1818 dark pattern instances across approximately 11,000 shopping websites. Later studies have examined other forms of deceptive design used in web and mobile interfaces, including scarcity messages, social proof claims, hidden costs, forced continuity, obstruction, and manipulative consent mechanisms. In parallel, machine learning (ML) and natural language processing (NLP) approaches have been explored for automatically detecting dark pattern text. Prior studies have shown that transformer-based language models such as BERT and RoBERTa can achieve high performance on English-language dark pattern datasets [5,6].
Despite this progress, existing ML-based dark pattern detection research has focused predominantly on English-language interfaces. This creates a significant gap because Arabic is spoken by more than 400 million people [7]. Arabic-speaking users interact daily with e-commerce platforms that localize persuasive and promotional interface content into Arabic, yet there is limited computational support for identifying whether such content includes deceptive or manipulative design cues. To the best of our knowledge, no prior ML-based framework has specifically addressed dark pattern detection in Arabic-language e-commerce mobile applications.
Arabic dark pattern detection also introduces linguistic and technical challenges that differ from English-language detection. Arabic NLP remains challenging because of the language’s rich morphology, diverse dialects, complex syntax, orthographic variation, ambiguity, and limited annotated resources [8]. In addition, Arabic digital interfaces may contain Modern Standard Arabic, colloquial or dialectal expressions, transliterated terms, English brand names, numerals, emojis, and mixed-language text, reflecting the diglossic, dialectal, and multilingual nature of Arabic online communication [9,10]. UI text is also typically short and context-dependent, which makes classification difficult because models must infer persuasive intent from limited textual evidence and sparse semantic information [11]. These characteristics may reduce the effectiveness of direct transfer from English-trained models and motivate the use of Arabic-specific language models such as AraBERT, which are pre-trained on Arabic corpora and better suited to Arabic linguistic structure [12].
This problem is especially relevant to low-resource language technology. Although Arabic is widely spoken, task-specific Arabic NLP resources remain limited for many applied domains, including UI understanding, deceptive design detection, and mobile commerce analytics. In the age of large-scale neural and foundation models, such gaps are important because models trained primarily on high-resource languages may not adequately represent Arabic morphology, code-switching, localized persuasive expressions, or short interface microcopy. Therefore, constructing task-specific Arabic datasets and evaluating Arabic-specific models are necessary steps toward more inclusive and reliable language technologies. Another challenge is the limited availability of annotated Arabic datasets for this task. Unlike English dark pattern detection, where prior datasets have supported model development and benchmarking, Arabic e-commerce dark pattern detection lacks publicly available labeled resources. To address this limitation, this study constructs a manually annotated dataset of Arabic UI text strings collected from e-commerce mobile applications operating in Saudi Arabia. Because the initial dataset is relatively small, we also apply Arabic paraphrase-based data augmentation to increase training diversity while preserving the semantic meaning of the original UI text. This is intended as a train-only strategy to mitigate data scarcity rather than an isolated augmentation ablation, which we reserve for future work.
This paper addresses the identified gap through three primary contributions. First, we construct, to the best of our knowledge, the first annotated low-resource Arabic dataset for dark pattern detection in e-commerce mobile applications operating in Saudi Arabia. The dataset contains 223 manually labeled Arabic UI text strings collected from nine applications, with an inter-annotator agreement of κ = 0.89. Second, we develop and evaluate a leakage-free Arabic NLP pipeline in which the original 223 instances are first split using a stratified 70/10/20 split, and Arabic paraphrase-based augmentation is then applied exclusively to the training partition, expanding it from 155 to 452 instances. The validation and test sets contain only original, non-augmented instances, with the held-out test set consisting of 45 original UI text strings. Third, we fine-tune and compare five pretrained transformer models—AraBERTv2, MARBERT, mBERT, BERT-base-uncased, and RoBERTa-base—under a leakage-free training procedure, using 5-fold cross-validation as the primary evaluation given single-split instability (Section 5.1). MARBERT achieves the strongest mean macro-F1 (0.4230), numerically ahead of AraBERTv2 (0.2998) though not to a statistically significant degree at five folds (p ≈ 0.064); MARBERT is significantly ahead of both English-only baselines, and AraBERTv2 is significantly ahead of RoBERTa-base (its margin over BERT-base-uncased does not survive correction for multiple comparisons; Section 5.3). mBERT is numerically stronger than both English-only baselines but was not directly tested against them. These results suggest that the composition of the pre-training corpus, particularly its coverage of dialectal and code-switched Arabic, may be important for this task. Finally, we publicly release the annotated dataset to support future research on low-resource Arabic NLP, Arabic UI text classification, ethical interface design, and dark pattern detection. Consistent with these contributions, this work is best understood as a benchmark and resource paper: it relies on standard transformer fine-tuning rather than introducing new model architectures, learning objectives, or optimization techniques, and its primary research contribution is the annotated dataset and empirical baseline rather than a methodological advance in machine learning.
The rest of the manuscript is organized as follows. Section 2 reviews related work on dark patterns, Arabic NLP, and data augmentation in low-resource settings. Section 3 describes the data collection and annotation methodology. Section 4 presents the ML pipeline, data augmentation process, and experimental setup. Section 5 reports the classification results and analysis. Section 6 discusses the implications, limitations, and future research directions. Section 7 concludes the paper.

2. Related Work

2.1. Dark Pattern Taxonomies

The term “dark patterns” was introduced by Brignull to describe deceptive interface designs that steer users toward actions they did not originally intend to take. Subsequent academic work further examined the normative and design attributes that make such patterns deceptive [13]. Gray et al. [3] later proposed a broader HCI-oriented taxonomy that organized dark patterns into five high-level strategies: nagging, obstruction, sneaking, interface interference, and forced action. This framework shifted the discussion from isolated examples toward a more systematic understanding of deceptive design as an ethical issue in user experience.
Mathur et al. [4] provided one of the most influential empirical studies of dark patterns in e-commerce. Their large-scale analysis of more than 11,000 shopping websites identified 1818 dark pattern instances across 15 dark pattern types. This work demonstrated that dark patterns are not isolated design mistakes, but recurring strategies embedded in online shopping interfaces. More recent work has extended dark pattern research beyond desktop websites to mobile and cross-platform environments. Gunawan et al. [14] compared dark patterns across mobile applications, mobile browsers, and web browsers, showing that deceptive design can manifest differently depending on platform modality, screen size, and interaction style. Accordingly, the present study adopts a focused taxonomy of five categories that are especially relevant to mobile e-commerce contexts, drawing on these prior frameworks [3,4,14].

2.2. Machine Learning Approaches to Dark Pattern Detection

Automated dark pattern detection has emerged as an active research area following earlier manual annotation and taxonomy studies. Initial machine learning work focused primarily on text-based detection using UI strings extracted from e-commerce websites. Yada et al. [6] constructed an e-commerce dark pattern dataset based on previously identified dark pattern instances and evaluated several machine learning and transformer-based models, including BERT, RoBERTa, ALBERT, and XLNet. Their results showed that transformer models can achieve strong performance in distinguishing dark pattern text from non-dark-pattern text, with reported accuracy reaching up to 0.975 [6].
Subsequent studies further demonstrated the effectiveness of transformer-based models for dark pattern classification. Vedhapriyavadhana et al. [5] proposed a BERT-based approach for detecting dark patterns in shopping websites, reporting strong classification performance and demonstrating the potential of transformer-based language models for e-commerce dark pattern detection. Recent work has also focused specifically on dark pattern detection from short interface microcopy. Xu and Chen [15] examined automatic detection and explanation of dark patterns from interface microcopy, comparing rule-based methods, linear classifiers, BERT-style encoders, RoBERTa-style encoders, and LLM-style decoders on short e-commerce UI text. This work is particularly relevant to the present study because Arabic mobile e-commerce dark patterns are often expressed through short UI strings, promotional banners, buttons, alerts, and checkout messages. However, their study remains focused on English-language microcopy, whereas the present work addresses Arabic UI text and evaluates Arabic-specific transformer models.
Later work also explored explainable dark pattern classification. Yada et al. [16] applied post-hoc explainability methods, including LIME and SHAP, to transformer-based classifiers in order to identify the textual features that contribute most strongly to dark pattern predictions. These analyses showed that terms associated with urgency, fear of missing out, popularity consensus, and limited availability often influence model decisions. Explainable detection is important because dark pattern classification is not only a technical task, but also an interpretive and ethical problem requiring transparency in how predictions are made.
Recent work has also incorporated multimodal approaches that combine visual and textual features from UI screenshots. AidUI processes mobile and web screenshots using computer vision and NLP to detect and localize dark patterns across 10 categories [17]. Using the ContextDP dataset, which contains 301 dark pattern instances, AidUI achieved precision of 0.66, recall of 0.67, and F1-score of 0.65, with higher performance for some individual pattern types [17]. Similarly, UIGuard combines computer vision and NLP-based pattern matching to detect dark patterns in mobile UIs. It covers 14 pattern types and reports precision of 0.82, recall of 0.77, and F1-score of 0.79 on 1660 instances across 1023 mobile applications [18]. These studies suggest that multimodal detection can help capture visual layout and contextual cues that may not be fully represented in text alone.
Recent work has further moved toward context-aware and flow-level detection of deceptive patterns in mobile applications. Chen et al. proposed AppRay, an app-level context-aware detection system that combines task-oriented app exploration with automated deceptive-pattern detection [19]. Unlike screenshot-only approaches, AppRay uses large language models to support targeted app exploration and combines static and dynamic dark pattern detection through a contrastive learning-based multi-label classifier and a rule-based refiner. This direction is important because some dark patterns emerge across interaction flows rather than in isolated UI strings or screenshots. However, AppRay focuses on mobile app exploration and multimodal UI states rather than Arabic-language text classification, leaving Arabic UI microcopy detection underexplored.
Although these studies demonstrate the feasibility of automated dark pattern detection, they remain limited in two main ways. First, current detection tools cover only a subset of known dark pattern types, while broader taxonomies and unified frameworks identify a much wider range of deceptive design strategies [20,21]. Second, prior ML-based dark pattern detection systems have been developed primarily using English-language datasets or language-agnostic screenshot features. To the best of our knowledge, none of the existing ML-based studies specifically addresses Arabic-language UI text or Arabic e-commerce mobile applications.

2.3. Non-English and Cross-Cultural Dark Pattern Research

Most dark pattern research has been conducted in Western, English-language, or globally dominant platform contexts. However, recent review and taxonomy-oriented work has emphasized the need for broader theoretical, regulatory, and methodological perspectives on deceptive design practices [20,21]. Other emerging studies have examined dark patterns in non-English or non-Western settings, including work on e-commerce interfaces using clustering-based approaches over linguistically scored features [22]. Despite these developments, Arabic-language dark pattern detection remains underexplored. Arabic-speaking users interact daily with localized e-commerce, travel booking, food delivery, and retail applications, yet no publicly available Arabic dark pattern dataset or Arabic-specific ML detection framework has been identified in the existing literature. This gap is especially important because dark patterns are often expressed through culturally and linguistically localized persuasive language. Therefore, models trained only on English UI text may fail to capture Arabic-specific linguistic cues, local promotional expressions, or context-dependent interface wording.

2.4. Arabic Natural Language Processing

Arabic NLP presents distinctive challenges compared with English NLP. Arabic is a morphologically rich language with complex word formation, clitics, inflectional variation, diacritics, orthographic variation, and ambiguity [8,10,23]. In addition, Arabic digital text may include Modern Standard Arabic, dialectal or colloquial expressions, transliterated Arabic, English brand names, numerals, emojis, and code-switched content [9,24]. These characteristics complicate automatic text processing and make direct transfer from English-trained models less reliable. Pre-trained Arabic language models have substantially advanced Arabic NLP. AraBERT [12], which is pre-trained on large Arabic corpora, has demonstrated strong performance on Arabic text classification tasks compared with multilingual BERT and other baselines [12]. Other Arabic-specific models, including ARBERT and MARBERT [25], further demonstrate the value of monolingual and dialect-aware Arabic pre-training. CAMeLBERT [26] provides additional dialect-aware variants trained on Modern Standard Arabic, dialectal Arabic, classical Arabic, and mixed Arabic corpora. These models highlight the importance of language-specific and dialect-aware pre-training for Arabic NLP tasks. In the present study, AraBERTv2 was initially selected as the focal Arabic-specific model because the collected UI text is predominantly Arabic and because Arabic-specific pre-training was expected to better capture Arabic morphology, lexical variation, and localized e-commerce expressions; Section 4.4.1 describes four additional models subsequently added for comparison, including MARBERT and mBERT.

2.5. Data Augmentation in Low-Resource NLP

Data augmentation is widely used in low-resource natural language processing (NLP) settings to improve model generalization when labeled data are limited. Chen et al. [27] provide an empirical survey of data augmentation for limited-data learning in NLP, showing that augmentation methods can improve data efficiency when annotated training data are scarce. Their study compares augmentation methods across 11 NLP datasets. Back-translation is one of the most commonly used augmentation techniques, in which text is translated into another language and then translated back to generate additional semantically similar training examples. Sennrich et al. [28] demonstrated that automatically back-translated monolingual data can be used as synthetic training data and can substantially improve neural machine translation performance, including in low-resource settings. Similarly, Xie et al. [29] showed that augmentation methods such as back-translation can improve performance across multiple language tasks when labeled data are limited.
Paraphrase-based augmentation follows a similar principle by generating alternative surface forms of existing sentences while preserving their original meaning, thereby increasing linguistic diversity in the training data. Okur et al. [30] found that paraphrase generation can improve natural language understanding models trained on small task-specific datasets, particularly for intent recognition tasks. In addition, Loem et al. [31] proposed ExtraPhrase, an efficient data augmentation approach for abstractive summarization, and showed that paraphrase-based augmentation can be useful when the amount of available training data is limited.
Recent work has also explored large language model (LLM)-based text generation and labeling as a way to reduce the cost and scalability limitations of traditional annotation workflows. One study proposed a Llama 3-based prompt engineering platform for textual data generation and labeling, demonstrating the potential of prompt-based LLM systems to support supervised NLP dataset construction [32]. For low-resource Arabic NLP tasks, such augmentation strategies are particularly important because manually labeled datasets are often small, expensive to construct, and highly domain-specific.
Guided by this prior work, the present study applies Arabic paraphrase-based augmentation to expand the training data while preserving the semantic meaning of the original UI text. To avoid data leakage, augmentation is applied only after the original dataset is split into training, validation, and test partitions, and only the training partition is augmented. Validation and test instances remain original and non-augmented.

2.6. Research Gap

The reviewed literature shows that dark pattern research has progressed from taxonomy development and large-scale manual audits to automated detection using machine learning, transformer-based NLP, and multimodal screenshot analysis. As summarized in Table 1, prior studies have made important contributions to detecting dark patterns in English e-commerce websites, shopping interfaces, short interface microcopy, and mobile or web UI screenshots. For example, Mathur et al. [4] provided a large-scale empirical analysis of dark patterns across shopping websites, while Yada et al. [6] and Vedhapriyavadhana et al. [5] demonstrated the effectiveness of transformer-based models for English dark pattern text classification. Other studies, such as AidUI [17], UIGuard [18], and AppRay [19], extended detection to multimodal screenshots, mobile UI states, and app-level interaction flows.
Despite these advances, three gaps remain. First, existing detection tools cover only a subset of known dark pattern types, while broader taxonomies identify a wider range of deceptive design strategies [20,21]. Second, most ML-based detection studies focus on English-language UI text, short English interface microcopy, or language-agnostic visual features, leaving non-English interfaces underrepresented. Third, to the best of our knowledge, no prior study has specifically applied ML-based dark pattern detection to Arabic-language e-commerce mobile applications. From a low-resource NLP perspective, the absence of Arabic dark pattern datasets also prevents systematic evaluation of how Arabic-specific transformer models perform on specialized UI text classification tasks.
This study addresses these gaps by constructing an annotated Arabic dark pattern dataset from e-commerce mobile applications operating in Saudi Arabia, developing a five-model benchmark comparison spanning Arabic-specific, multilingual, and English-pretrained transformer models (AraBERTv2, MARBERT, mBERT, BERT-base-uncased, and RoBERTa-base). In addition, the study applies Arabic paraphrase-based augmentation as a train-only strategy to mitigate data scarcity in this low-resource Arabic NLP setting. Therefore, unlike prior work summarized in Table 1, the present study focuses specifically on Arabic-language mobile e-commerce interfaces and provides both a dataset and an empirical baseline for future Arabic dark pattern detection research.
As shown in Table 1, prior automated detection studies have primarily focused on English e-commerce text, English interface microcopy, or multimodal UI screenshots, whereas the present study specifically targets Arabic UI text in e-commerce mobile applications operating in Saudi Arabia and incorporates train-only Arabic paraphrase-based augmentation.

3. Dataset Construction

3.1. App Selection and Text Collection Protocol

Nine e-commerce-related mobile applications operating in Saudi Arabia were purposively selected based on three criteria: availability through Google Play and/or the Apple App Store in Saudi Arabia, support for an Arabic-language interface, and high popularity or top-category ranking in Saudi Arabia as accessed in June 2026. Public app-ranking sources were used to support the popularity criterion. Similarweb listed Noon and Temu among the top Shopping Android apps in Saudi Arabia, while 42 matters listed Temu, Shein, Noon, and Amazon Shopping among the most popular Shopping apps in Saudi Arabia [33,34]. Appfigures also listed SHEIN, Temu, Noon, and Amazon Shopping among the top free Google Play Shopping apps in Saudi Arabia [35]. For food delivery, Similarweb’s Saudi Arabia Food & Drink iPhone ranking listed Keeta and HungerStation among the top five apps [36]. For travel and booking, Similarweb’s Travel & Local Android ranking listed Booking.com and Almosafer among the top travel apps in Saudi Arabia [37]. Because app-store rankings fluctuate over time and differ across platforms and categories, ranking was used as an inclusion indicator rather than as a strict ordering variable.
The selected applications span four e-commerce categories: general shopping, fashion, food delivery, and travel and booking. This category diversity was intended to capture different dark pattern contexts, including promotional scarcity, hidden costs, forced continuity, checkout obstruction, and urgency-based messages. Text was collected directly from app interfaces across five predefined user flows per application: account registration, product search, add to cart, checkout, and subscription or cancellation management. During each flow, the annotator manually transcribed Arabic UI text strings that either contained potential dark pattern cues or served as comparable non-deceptive examples from the same interaction context. Data collection took place across multiple sessions spanning several weeks rather than a single sitting; the exact number of sessions or screenshots inspected per application was not systematically logged during collection. Specific promotional or seasonal sales calendars for the selected applications were also not tracked, and we note both points as limitations in Section 6.5. A total of 225 text instances were initially collected and annotated; after excluding two instances whose final consensus label remained “Uncertain” (see Section 3.4), the resulting dataset comprised 223 text instances, of which 169 instances, representing 75.8%, were labeled as dark patterns. Table 2 presents the selected applications, categories, user flows, and the final instance and dark pattern counts.

3.2. Dark Pattern Taxonomy

Following the dark pattern frameworks proposed by Gray et al. [3] and Mathur et al. [4] and considering the mobile-specific characteristics of e-commerce interfaces [14], five dark pattern categories were defined for annotation. These categories were selected because they were the most relevant to short Arabic UI text strings observed in shopping, food delivery, and travel booking applications. Each category was operationalized using text-based cues that could be identified from interface microcopy, promotional messages, checkout text, subscription prompts, and cancellation-related messages. In addition to the five dark pattern categories, text strings that did not contain any of the defined cues were labeled as “None—not a dark pattern.” Table 3 summarizes the main annotation cues and representative Arabic examples for the five dark pattern categories used in this study.
Urgency/Scarcity. This category refers to UI text that creates time pressure or perceived scarcity through limited-time offers, countdown timers, stock warnings, or deadline-based promotional messages. Examples include claims such as “على وشك النفاد” (“almost out of stock”) or messages indicating that only a small number of items remain. Instances were labeled under this category when the text pressured users to act quickly based on scarcity or urgency cues that were not independently verifiable from the interface.
Misdirection. This category includes UI text that directs the user’s attention, interpretation, or emotional response in a way that may lead to an unintended action. Examples include emotionally loaded wording, confirm-shaming, unclear opt-in language, or consent statements bundled with registration in a way that makes refusal less visible. For example, the phrase Electronics 15 03955 i002 (“to register, I must agree to receive marketing messages”) was treated as misdirection when the interface framed marketing consent as part of the primary registration action.
Hidden Costs. This category refers to fees, charges, or payment conditions that are not clearly presented early in the decision process and are revealed or emphasized only at later stages, such as checkout or final payment. Examples include service fees, delivery fees, seat-selection charges, or conditional discount rules. Text such as “رسوم الخدمة” (“service fee”) was labeled as a hidden cost only when the charge appeared late in the transaction flow or was not clearly disclosed before the user progressed toward payment.
Forced Continuity/Roach Motel. This category includes interface text related to automatic renewal, subscription continuation, or cancellation obstruction. Forced continuity occurs when users are enrolled in recurring payments or membership renewal unless they actively cancel, while roach motel patterns occur when opting in is easier than canceling or opting out. For example, “سيتم تجديد عضويتك تلقائيًا” (“your membership will be renewed automatically”) was included when the renewal condition was presented with insufficient salience, unclear cancellation information, or in a context that could lead users to continue a paid service unintentionally.
Social Proof Manipulation. This category refers to UI text that uses social signals to pressure users, such as claims about recent purchases, high demand, popularity, or the number of users viewing or buying an item. Examples include Electronics 15 03955 i001. Instances were labeled under this category when the social proof claim was unverifiable from the interface or appeared to create pressure by suggesting popularity, demand, or collective behavior.
Text strings that did not contain any of the above cues were labeled as “None—not a dark pattern.” When a text string appeared to include more than one cue, annotators assigned the category corresponding to the dominant persuasive or deceptive mechanism in the immediate interface context.

3.3. Annotation Procedure

Two annotators independently labeled each Arabic UI text string. Annotator 1 was the primary researcher, while Annotator 2 was a bilingual Arabic–English colleague familiar with the annotation guidelines. Each annotator assigned one of seven possible labels: the five dark pattern categories, “None—not a dark pattern,” or “Uncertain.” The “Uncertain” label was used only when the annotator could not confidently determine whether the text represented a dark pattern based on the available interface context. Instances assigned or resolved as “Uncertain” were excluded before model training and evaluation.
Annotation was conducted using a structured Microsoft Excel workbook with dropdown menus for each label to ensure consistency and prevent typographical errors. The workbook included columns for the application name, user flow, Arabic UI text, English translation, annotator labels, disagreement status, and final resolved label. Disagreements between annotators were automatically flagged in a dedicated column to support systematic review and resolution.

3.4. Inter-Annotator Agreement and Disagreement Resolution

Inter-annotator agreement was measured using Cohen’s kappa (κ), a standard metric for measuring agreement between two annotators on categorical labels while correcting for chance agreement [38]. Kappa is calculated as follows:
κ = (Po − Pe)/(1 − Pe)
where Po is the observed agreement proportion, representing the fraction of items on which both annotators assigned the same label, and Pe is the expected agreement by chance, calculated from the marginal label frequencies of both annotators. A κ value of 1.0 indicates perfect agreement, while values between 0.81 and 1.00 are commonly interpreted as “almost perfect” agreement and values between 0.61 and 0.80 as “substantial” agreement [39]. Values above 0.75 are also commonly regarded as indicating strong or excellent inter-rater reliability [40].
Agreement was calculated on the full pre-resolution annotation set of 225 instances. The two annotators agreed on 205 instances, corresponding to an observed agreement of Po = 91.1%, and the resulting Cohen’s kappa was κ = 0.89. This indicates almost perfect agreement and demonstrates a high level of consistency between the annotators. A total of 20 disagreements were identified among the 225 pre-resolution instances, corresponding to a disagreement rate of 8.9%. The two annotators reviewed all disagreement cases in a joint adjudication session, considering the Arabic UI text, the application context, and the annotation guidelines. The resolved cases covered all six final categories: Hidden Costs (4 cases), Misdirection (4 cases), Urgency/Scarcity (4 cases), Forced Continuity/Roach Motel (3 cases), None—not a dark pattern (3 cases), and Social Proof Manipulation (2 cases). The disagreements primarily involved distinguishing between persuasive and informational wording and determining the dominant dark-pattern mechanism when more than one interpretation was possible. Late-disclosed fees or conditions were generally resolved as Hidden Costs; popularity- or demand-based claims as Social Proof Manipulation; emotionally persuasive or attention-directing wording as Misdirection; deadline- or action-oriented prompts as Urgency/Scarcity; and subscription, renewal, bundling, or lock-in mechanisms as Forced Continuity/Roach Motel. Cases judged to be purely informational were resolved as None—not a dark pattern. Table 4 presents representative disagreement cases illustrating these different adjudication decisions.
All 20 disagreement cases were resolved through adjudication and retained in the final dataset. Table 4 presents representative examples rather than an exhaustive listing of all disagreement cases. Separately, two instances whose final consensus label remained “Uncertain” were excluded from model training and evaluation, yielding the final dataset of 223 labeled instances.

3.5. Dataset Statistics and Snapshot

Following disagreement resolution and exclusion of uncertain cases, the final dataset comprised 223 annotated Arabic UI text strings collected from nine e-commerce-related mobile applications operating in Saudi Arabia. Table 5 presents the final label distribution. Dark pattern instances accounted for 169 cases, representing 75.8% of the dataset, while the remaining 54 cases, representing 24.2%, were labeled as “None—not a dark pattern.” The inclusion of non-dark-pattern examples was necessary to support supervised model training and enable the classifier to distinguish potentially deceptive UI text from neutral or informational interface content.
Table 6 presents a representative sample of annotated instances from the dataset, illustrating the range of Arabic UI text strings, source applications, user flows, and assigned labels. The full dataset is publicly available on Zenodo [41].

4. Methodology

4.1. Pipeline Overview

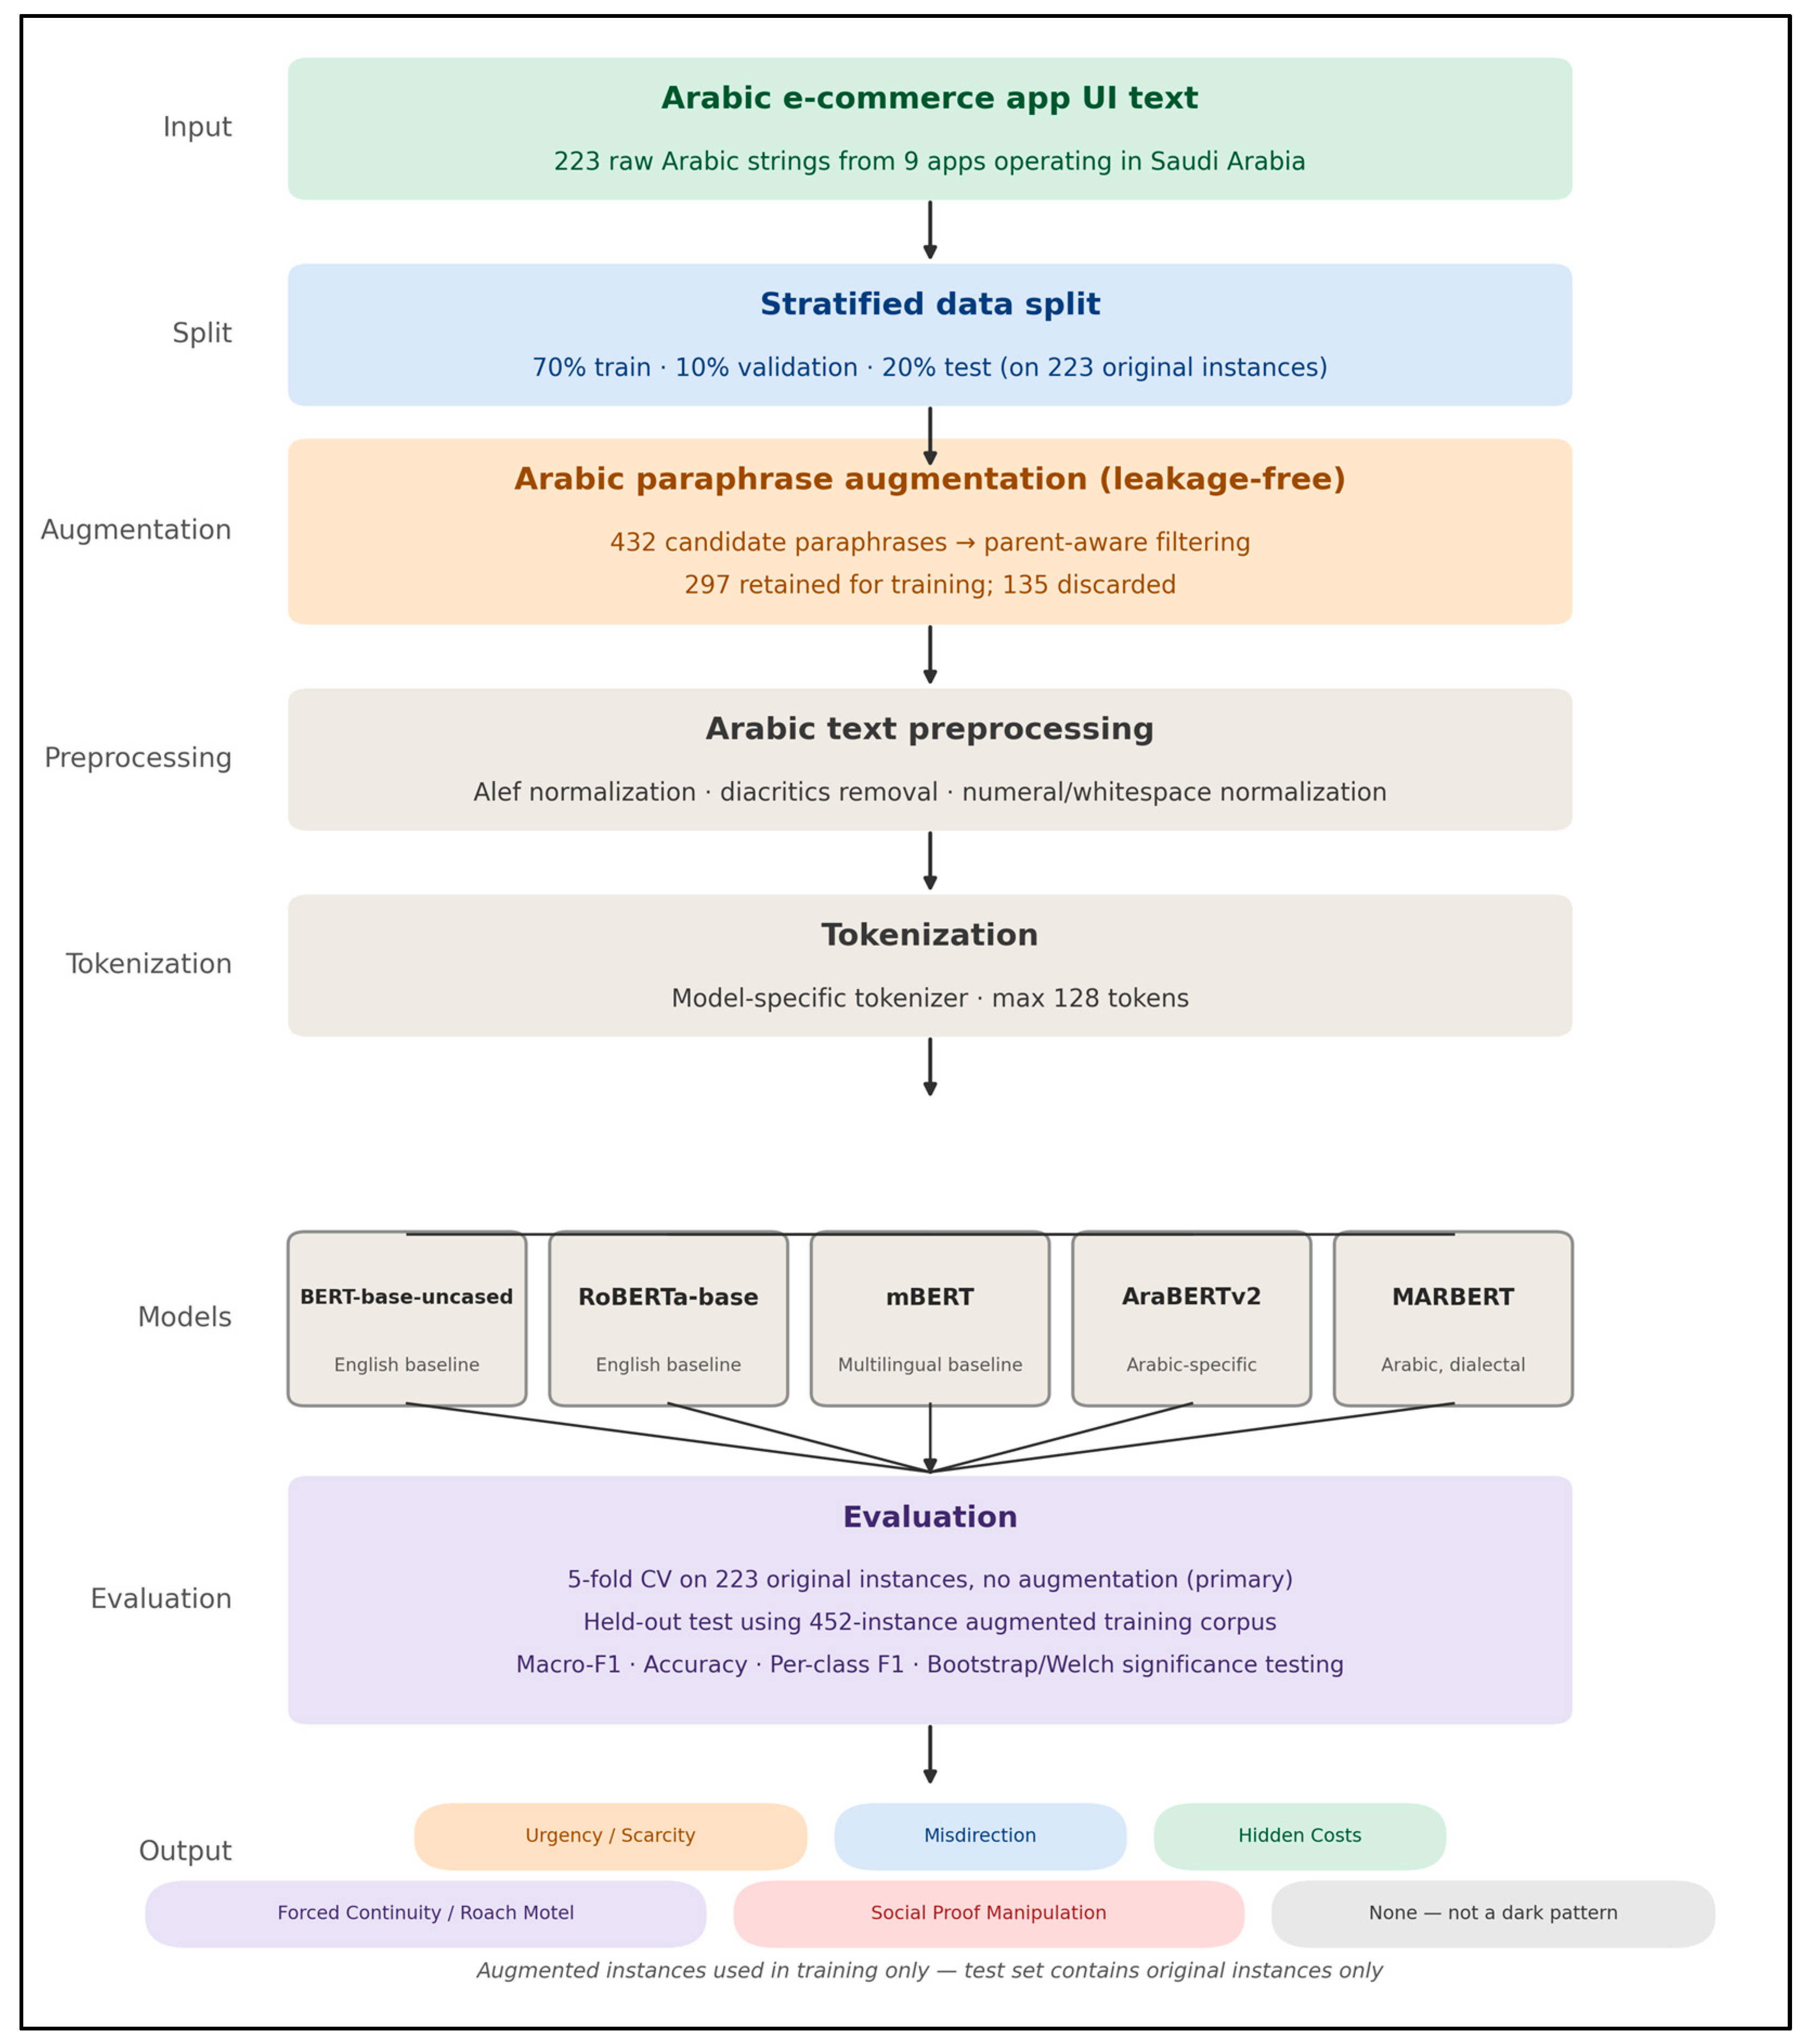
The proposed dark pattern detection pipeline is illustrated in Figure 1. The pipeline accepts raw Arabic UI text strings as input and produces one of six classification labels: the five dark pattern categories or “None—not a dark pattern.”
To avoid data leakage, the original 223 annotated instances were first divided into training, validation, and test partitions using stratified sampling with a 70/10/20 split. This produced 155 original training instances, 23 validation instances, and 45 test instances. Arabic paraphrase-based augmentation was then applied exclusively to the training partition, expanding it from 155 to 452 instances by adding 297 paraphrased variants after excluding paraphrases whose original instance fell in validation or test. The validation and test sets contained only original, non-augmented UI text strings.
Following augmentation, all model-input text strings underwent Arabic text preprocessing, including normalization of alef variants, removal of diacritics, standardization of Arabic–Indic numerals, and whitespace normalization. The preprocessed strings were then tokenized using the tokenizer corresponding to each transformer model. Each model was tokenized using its own pretrained tokenizer (AraBERTv2, MARBERT, mBERT, BERT-base-uncased, and RoBERTa-base each have a dedicated tokenizer). A maximum sequence length of 128 tokens was used across all models.
In the model training stage, five transformer models were fine-tuned and compared: AraBERTv2, MARBERT, and mBERT as Arabic-aware or multilingual models, and two English-pretrained baseline models, BERT-base-uncased and RoBERTa-base. The English-pretrained baselines were included to quantify the performance gap when Arabic-specific pre-training is absent. All models were evaluated on the same 45-instance held-out test set containing only original Arabic UI text instances. Performance was assessed using macro-averaged precision, macro-averaged recall, macro-F1, and accuracy. In addition, stratified 5-fold cross-validation was conducted on the original 223 instances without augmentation, for all five models, to assess model robustness on the clean dataset and serve as the primary evaluation (Section 5.1). Cross-model significance testing was also computed to compare all five models (Section 5.3).

4.2. Data Augmentation

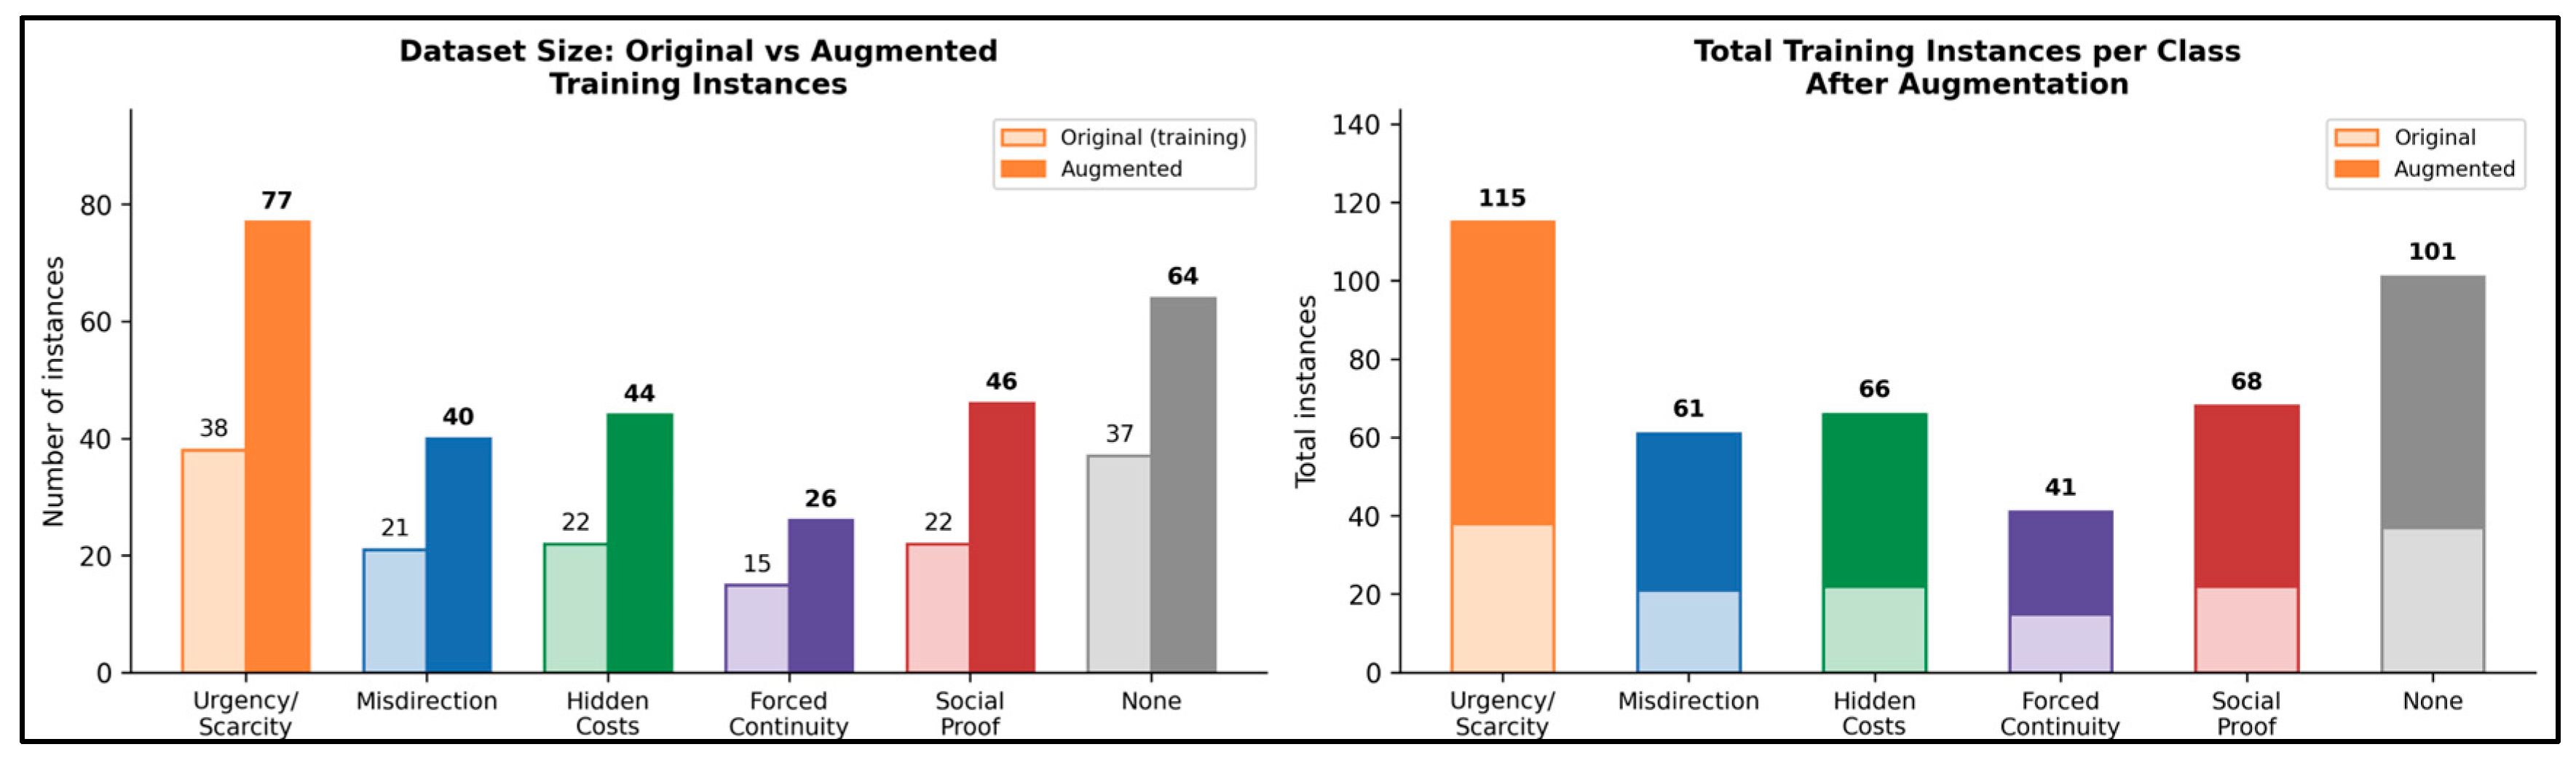
To address the limited size of the training set, a pool of manually generated Arabic paraphrase candidates was subjected to parent-aware filtering after the stratified data split. Only paraphrases whose source instance belonged to the training partition were retained. This resulted in 297 retained paraphrases added to the 155 original training instances, yielding a final training corpus of 452 instances; 135 paraphrase candidates associated with validation or test instances were discarded. Validation and test sets therefore contained only original, non-augmented instances. The paraphrases were generated using three strategies: (1) lexical substitution, replacing words with Arabic synonyms while preserving the dark pattern meaning; (2) syntactic restructuring, reordering sentence constituents while maintaining semantic equivalence; and (3) interface-style paraphrasing, producing natural Arabic variants that reflect phrasing commonly observed in mobile app interfaces. Paraphrases were generated manually by two members of the research team (the same two annotators described in Section 3.3), who reviewed the rewritten instances to confirm semantic equivalence and label consistency with the source instance before inclusion in the training set. On average, approximately two paraphrased variants were generated per original training instance; this varied somewhat by instance rather than following a fixed count. This expanded the training corpus from 155 to 452 instances, representing an overall expansion factor of approximately ×2.92, consisting of 155 original training instances and 297 retained augmented paraphrases. Validation and test sets contained only original, non-augmented instances. Table 7 presents the class-level breakdown of original and augmented training instances, and Figure 2 illustrates the expansion visually. Crucially, augmented instances were added only to the training partition. The held-out test set contained exclusively original, non-augmented instances to ensure unbiased evaluation. The dataset split was 70% training, 10% validation, and 20% testing using stratified sampling to preserve class distribution across partitions.

4.3. Text Preprocessing

Each Arabic UI text string underwent four preprocessing steps: (1) removal of HTML entities and non-informative formatting artifacts; (2) normalization of Arabic characters, including unification of alef variants (أ، إ، آ → ا) and removal of diacritics (tashkeel); (3) standardization of Arabic–Indic numerals (٩–٠) to Western numerals (0–9); and (4) whitespace normalization. Informative symbols commonly used in e-commerce interfaces, such as currency indicators, percentages, plus signs, and numerical values, were retained because they may contribute to dark pattern cues such as discounts, scarcity claims, and hidden costs. Preprocessing was implemented using CAMeL Tools [42] and PyArabic [43], two open-source Python libraries for Arabic natural language processing and Arabic text manipulation.

4.4. Models

4.4.1. Baseline Models

Two English-pretrained transformer models were used as baselines: BERT-base-uncased [44] and RoBERTa-base [45]. BERT introduced deep bidirectional transformer pre-training and can be fine-tuned for downstream NLP tasks using an additional task-specific output layer [44]. RoBERTa is a robustly optimized variant of BERT that improves pre-training through changes such as larger-scale training and optimized hyperparameters [45]. These models were included to quantify the performance gap between English-pretrained models and an Arabic-specific model when applied to Arabic UI text. RoBERTa-base was also included because Yada et al. [6] reported strong performance for RoBERTa-based classification on an English e-commerce dark pattern dataset. Two additional multilingual/Arabic-specific models were included: bert-base-multilingual-cased (mBERT), a multilingual model whose vocabulary includes Arabic, used to isolate whether AraBERTv2′s advantage over the English-only baselines reflects tokenizer/vocabulary coverage rather than Arabic-specific pre-training; and MARBERT [25], an Arabic-specific model pre-trained substantially on dialectal and social-media Arabic rather than Modern Standard Arabic alone. Both were fine-tuned and evaluated using an identical pipeline and hyperparameters to the other three models.

4.4.2. AraBERTv2

AraBERTv2 [12] is an Arabic-specific BERT-based model developed for Arabic language understanding, and was the model that originally motivated this study’s central hypothesis: that Arabic-specific pre-training would outperform English-pretrained baselines on Arabic UI text. AraBERTv2 was pre-trained on large Arabic corpora and was designed to address Arabic NLP challenges arising from the language’s rich morphology and relatively limited resources compared with English [12]. The AraBERT paper reports that AraBERT achieved state-of-the-art performance on most tested Arabic NLP tasks and outperformed multilingual BERT and other baselines [12]. As reported in Section 5.3, this hypothesis is only partly supported: AraBERTv2 significantly outperforms RoBERTa-base and is nominally ahead of BERT-base-uncased (p ≈ 0.031), though this comparison does not survive correction for multiple comparisons; AraBERTv2 is itself numerically outperformed by MARBERT and mBERT under the primary cross-validation evaluation. All five models were fine-tuned for the same six-class dark pattern classification task using a linear classification head on the [CLS] token, following the standard HuggingFace AutoModelForSequenceClassification configuration. The six output classes consisted of the five dark pattern categories and the “None—not a dark pattern” class. The two instances labeled as “Uncertain” were excluded from all model training and evaluation, for every model.

4.5. Training Configuration

All models were fine-tuned using the HuggingFace Transformers library [46] in Python 3.10. Training was conducted on Google Colab Pro using an NVIDIA A100 GPU. The same training configuration was used across all models to provide a controlled comparison. Hyperparameters were set as follows: learning rate = 2 × 10⁻⁵, batch size = 16, maximum sequence length = 128 tokens, number of epochs = 5, and weight decay = 0.01. The AdamW optimizer [47] was used with a linear warmup schedule over 10% of the training steps. Checkpoint selection followed the same rule for every model: the checkpoint with the highest validation-set macro-F1 across the 5 epochs was retained, rather than simply using the final epoch’s weights. No explicit early-stopping criterion was implemented; all models trained for the full 5 epochs regardless of validation trajectory. This identical configuration was used across all five models deliberately, to isolate architecture and pre-training corpus as the only varying factor between them; we note in Section 6.5 that model-specific tuning was not performed and could plausibly shift the comparisons reported here.
The original 223 annotated instances were first split into training, validation, and test sets using stratified sampling with a 70/10/20 ratio. This produced 155 original training instances, 23 validation instances, and 45 test instances. Paraphrase-based augmentation was then applied only to the training partition, expanding the training set to 452 instances. In addition, stratified five-fold cross-validation was conducted for all five models on the 223 original instances, without augmentation, to assess robustness under the clean-data setting; this cross-validation evaluation is treated as primary throughout the paper.

4.6. Evaluation Metrics

Model performance was evaluated on the 45-instance held-out test set using overall accuracy, macro-averaged precision, macro-averaged recall, and macro-F1. Per-class precision, recall, and F1-scores were also reported to analyze category-level performance across the five dark pattern classes and the “None—not a dark pattern” class. Macro-F1 was selected as the primary evaluation metric because the dataset is imbalanced across the six output classes, and macro-averaging gives equal weight to each class regardless of its frequency.
To quantify differences between models, we report pairwise macro-F1 differences and significance tests across all five models (Section 5.3): a paired bootstrap significance test on the single held-out test set and Welch’s t-tests on 5-fold cross-validation fold statistics, with Holm–Bonferroni correction for multiple comparisons across the seven reported pairwise tests. This distinction is important because BERT-base-uncased was the stronger English baseline in our experiments, whereas RoBERTa-base was included due to its strong performance in prior English dark pattern detection studies.

5. Results

5.1. Dataset and Split Statistics

The final annotated dataset comprised 223 Arabic UI text instances collected from nine e-commerce mobile applications operating in Saudi Arabia across five user flows. Of these, 169 instances (75.8%) were labeled as dark patterns, while 54 instances (24.2%) were labeled as “None—not a dark pattern.” Two instances whose final label remained “Uncertain” were excluded before model training and evaluation. Inter-annotator agreement was κ = 0.89.
Following stratified 70/10/20 splitting, 155 original instances were assigned to the training partition, 23 to the validation partition, and 45 to the test partition. Paraphrase candidates were generated before final training-set assembly, yielding 432 candidates. After splitting, a parent-aware filter retained 297 candidates whose parent instance belonged to the 155 training originals, yielding 452 training instances; leakage verification confirmed that the validation and test sets contained zero augmented instances. In addition, because paraphrases were generated prior to finalizing the training-set assembly, we applied a parent-aware filter: for each of the 432 pre-filter paraphrases, we identified its most likely source instance by computing cosine similarity between TF-IDF character n-gram (2–4 character) representations of the paraphrase and every original instance from the same application, then selecting the highest-similarity match as the presumed parent (ties, which did not occur in practice, would default to the first-indexed candidate). An augmented instance was retained in training only if its matched parent belonged to the training partition; this retained 297 of the 432 paraphrases and discarded the remaining 135, whose matched parent fell in validation or test. Final training size = 155 original + 297 retained augmented = 452 instances, and is the procedure used to produce all results reported below. A supplementary check confirmed that the original (non-augmented) instances themselves show only modest similarity across partitions independent of augmentation (mean same-application similarity between test and training originals = 0.304; 3 of 45 test instances exceed a 0.80 similarity threshold, none exceed 0.95), indicating the underlying stratified split is sound and the leakage was specific to the augmentation-assembly step.

5.2. Model Comparison Results

Table 8 presents the classification results for all five models on the 45-instance held-out test set, using the leakage-free training pipeline described in Section 4.1. We report this single-split evaluation for completeness but treat the 5-fold cross-validation results in Section 5.5 as primary, since repeated single-split runs showed meaningful run-to-run variance. MARBERT achieved the highest scores across every evaluation metric on this single split (macro-F1 = 0.3513, accuracy = 0.4000), followed by mBERT (macro-F1 = 0.2656) and AraBERTv2 (macro-F1 = 0.1979). Both English-only baselines trailed substantially: RoBERTa-base reached macro-F1 = 0.1273 and BERT-base-uncased macro-F1 = 0.0901.

5.3. Model Comparison and the Dialectal Pre-Training Advantage

Because cross-validation is the primary evaluation in this study, the primary significance analysis uses Welch’s t-test computed from each model’s cross-validation fold statistics (mean, standard deviation, n = 5 folds); a paired test across folds was not available since per-fold raw predictions were retained only for AraBERTv2, not the four additional models. MARBERT vs. AraBERTv2: t = 2.20, p ≈ 0.064 (not significant, though MARBERT leads by a substantial margin—0.4230 vs. 0.2998). MARBERT vs. mBERT: t = 1.88, p ≈ 0.101 (not significant). MARBERT vs. BERT-base-uncased: t = 7.84, p ≈ 0.0003 (significant). MARBERT vs. RoBERTa-base: t = 10.13, p < 0.0001 (significant). AraBERTv2 vs. BERT-base-uncased: t = 3.02, p ≈ 0.031 (significant). AraBERTv2 vs. RoBERTa-base: t = 4.45, p ≈ 0.0085 (significant). AraBERTv2 vs. mBERT: t = −0.37, p ≈ 0.720 (not significant). Directly on the comparison motivating this analysis, a paired bootstrap significance test on the single held-out test set gives AraBERTv2 vs. BERT-base-uncased ΔF1 = +0.1078, p ≈ 0.017 (significant). Applying Holm–Bonferroni correction across the seven Welch comparisons above, MARBERT remains significant against both English-only baselines; AraBERTv2 remains significant against RoBERTa-base; AraBERTv2′s advantage over BERT-base-uncased (unadjusted p ≈ 0.031) does not survive correction. These Welch tests, computed on five cross-validation folds with overlapping training data, should be read as exploratory secondary evidence. As a secondary check, a paired bootstrap significance test on the single held-out test set (2000 resamples; Table 9) reaches a different conclusion for the MARBERT-AraBERTv2 comparison specifically (p ≈ 0.031, appearing significant)—a further illustration of the single-split instability discussed in Section 5.1, rather than a more reliable result. We report both analyses for transparency but rely on the cross-validation result above for our conclusions. This pattern is informative rather than a simple ranking. MARBERT is pre-trained substantially on dialectal and social-media Arabic, including code-switched and informal register [25], whereas AraBERTv2′s pre-training corpus is more heavily weighted toward Modern Standard Arabic [12]. Our UI text sample includes exactly this kind of informal, code-switched register: mixed Arabic–English brand names, colloquial expressions, and abbreviated promotional phrasing. The results suggest that, for short, informal Arabic UI text of this kind, exposure to dialectal and social-media register during pre-training may matter more than Arabic-language pre-training in general, refining rather than contradicting our original hypothesis that Arabic-aware pre-training helps.

5.4. Per-Class Analysis and Confusion Matrix

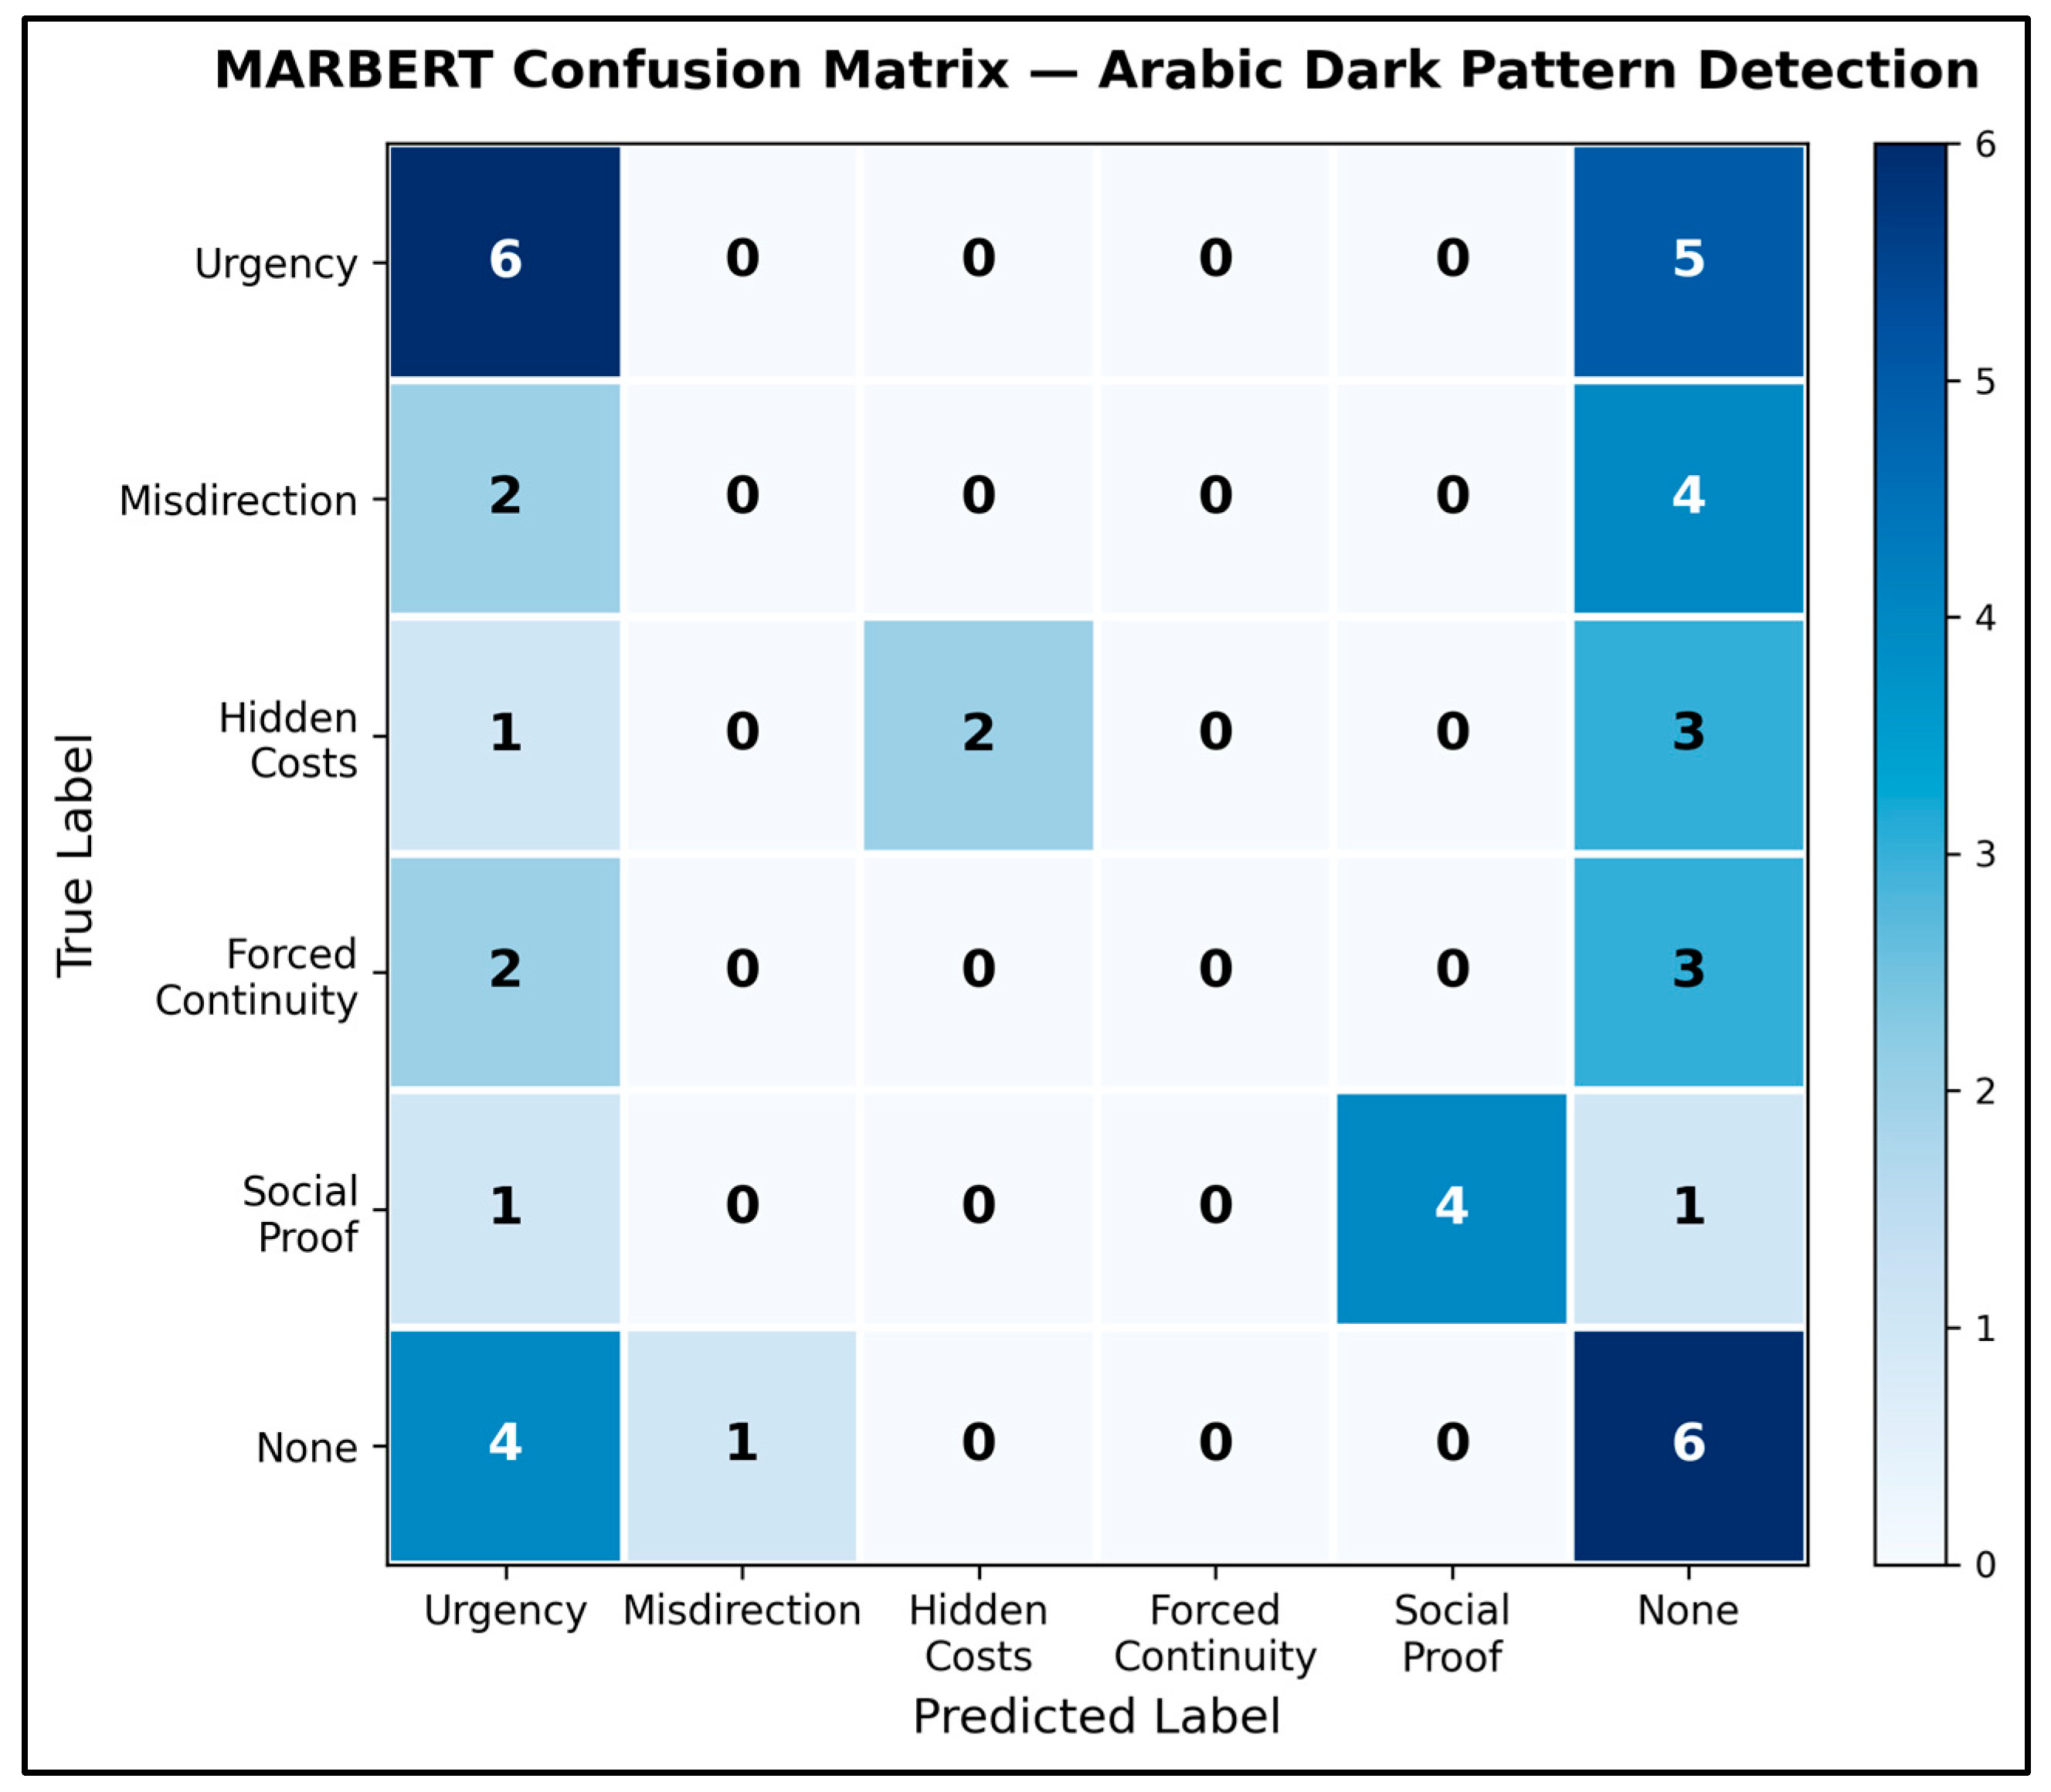
MARBERT’s per-class results (Table 10) show a mixed but informative pattern. Social Proof Manipulation was detected most reliably (F1 = 0.8000, precision = 1.0000, recall = 0.6667), and Hidden Costs was detected with perfect precision but partial recall (F1 = 0.5000). Urgency/Scarcity (F1 = 0.4444) and the non-dark-pattern class (F1 = 0.3636) were detected moderately well. Misdirection and Forced Continuity/Roach Motel were not reliably detected by any model at the current data volume (F1 = 0.0000 for MARBERT and for every other model evaluated), indicating these two categories are the clearest priority for future data collection and augmentation. This pattern held broadly across models: Urgency/Scarcity and the non-dark-pattern class were the most consistently detected categories across all five models, while Misdirection and Forced Continuity were difficult for every model tested.
The confusion matrix (Figure 3) shows that both undetected categories are overwhelmingly misclassified as “None” rather than confused with other dark-pattern types (4 of 6 Misdirection instances and 3 of 5 Forced Continuity instances predicted as “None”), suggesting the model defaults toward the majority-adjacent class under uncertainty rather than conflating distinct dark-pattern categories.

5.5. Cross-Validation Results

To assess robustness independent of any single train/test split, stratified 5-fold cross-validation was conducted for all five models on the 223 original instances, without augmentation. This cross-validation analysis, rather than the single held-out test set, is treated as the primary evaluation throughout this paper, motivated by the run-to-run instability observed when repeating the single-split evaluation under identical code, data, and hyperparameters. Table 11 presents the mean, standard deviation, and variance of macro-F1, together with mean accuracy, across the five folds for each model.
MARBERT achieved the highest mean macro-F1 (0.4230 ± 0.0695), followed by mBERT (0.3234 ± 0.0963) and AraBERTv2 (0.2998 ± 0.1040); both English-only baselines trailed substantially, with BERT-base-uncased reaching 0.1525 ± 0.0334 and RoBERTa-base 0.0863 ± 0.0263. This ranking broadly matches the single held-out test set (Table 8), with one notable exception: BERT-base-uncased outperforms RoBERTa-base under cross-validation, while the reverse holds on the single test split—illustrating that even the relative ranking of the two weaker baselines is sensitive to evaluation protocol at this dataset size. The relatively high standard deviations, particularly for AraBERTv2 (±0.1040) and mBERT (±0.0963), reflect the limited size of each validation fold (approximately 45 instances) and are expected given the small original dataset.

6. Discussion

6.1. The Arabic Dark Pattern Landscape

Our analysis of 223 Arabic UI text instances collected from nine e-commerce mobile applications operating in Saudi Arabia shows that dark pattern cues were common in the annotated sample, appearing in 169 instances (75.8%). Urgency/Scarcity was the most frequent category, representing 24.7% of all instances. This aligns with prior e-commerce dark pattern research showing that scarcity/urgency, social proof, hidden costs, and obstruction-related patterns are common persuasive strategies in online shopping interfaces [3,4]. SHEIN KSA and Temu showed the highest number of dark pattern examples in the dataset, with 32 and 27 instances, respectively. Forced Continuity/Roach Motel patterns appeared mainly in subscription-related services, such as HungerStation’s membership program, Amazon SA’s Prime subscription, and Noon’s “Noon One” loyalty program. These findings are also consistent with prior work showing that dark patterns can vary across platform modality and interaction context, including mobile applications and mobile browsers [14]. Because the dataset was purposively constructed from UI strings containing potential dark pattern cues and comparable non-dark-pattern examples, these results should not be interpreted as prevalence estimates for all UI text in the selected applications. Rather, they indicate that deceptive or manipulative interface language appears across multiple Arabic mobile commerce contexts and warrants systematic study. This supports recent calls for broader methodological and cross-contextual work on deceptive interface design beyond dominant English-language and Western platform settings [20,21].

6.2. Model Comparison Under Low-Resource Conditions

MARBERT, mBERT, and AraBERTv2 all outperformed the English-only baselines, but the gap between the Arabic/multilingual models themselves—with MARBERT numerically well ahead of AraBERTv2, though not to a statistically significant degree at five cross-validation folds—is the more striking finding. This is consistent with prior Arabic NLP research showing that dialectal, code-switched, and informal registers pose distinctive challenges beyond what Modern-Standard-Arabic-focused pre-training addresses [8,9,10,23,24]. Our dataset’s UI text—mixing Modern Standard Arabic, colloquial expressions, and English brand names—is consistent with a possible benefit from MARBERT’s broader dialectal pre-training specifically rather than Arabic pre-training in general. These results are relevant to low-resource language research because the task combines two forms of data scarcity: language-level scarcity in specialized Arabic NLP resources and task-level scarcity in labeled dark pattern examples. Under these conditions, the choice of pre-training corpus—not merely whether a model is “Arabic” or “English”—materially affects performance, and even the best-performing model (MARBERT, mean macro-F1 = 0.4230 under cross-validation) leaves substantial room for improvement, underscoring that pre-training alone is insufficient when task-specific labeled data are this limited.

6.3. Paraphrase Augmentation for Low-Resource Arabic UI Text

Train-only Arabic paraphrase augmentation was applied to expand the small original training set. Because this study centers on comparing five pretrained models under an identical training procedure, we do not report an isolated before/after augmentation ablation here; the augmentation procedure itself, including the parent-aware leakage fix, is described in full in Section 4.2. A dedicated augmentation ablation is a natural direction for future work.

6.4. Practical Implications

The dataset and benchmark models presented in this study have practical implications for consumer protection, platform auditing, and ethical interface design. More specifically, we envision four primary use cases: (1) academic benchmarking, providing a reproducible baseline for future Arabic dark pattern detection research; (2) consumer protection audits, in which regulators or advocacy organizations use the model to triage large volumes of app interface text for manual review; (3) app-store or platform monitoring, where developers or marketplace operators screen submitted interface text for potentially deceptive language before publication; and (4) human-in-the-loop review, in which the model flags candidate instances for a human moderator rather than issuing final determinations. Rather than serving as a fully automated regulatory system, the model can be viewed as an early-stage decision-support tool that helps flag potentially deceptive Arabic UI text for further human review. Regulatory bodies, consumer protection organizations, and app developers could use such tools to support manual audits, identify high-risk interface text, and improve transparency in mobile commerce applications. However, given the modest dataset size and the remaining classification errors, especially for Forced Continuity/Roach Motel, human expert validation remains essential before any real-world deployment. This is consistent with recent work comparing UX experts and AI-based evaluators for dark pattern detection, which highlights the importance of expert oversight when interpreting deceptive design practices [48]. The need for human review is also supported by multimodal dark pattern detection research showing that text alone may be insufficient when deception depends on layout, visual salience, or interaction flow [17,18,19].

6.5. Limitations

The findings should be interpreted in light of several limitations. First, the dataset is small and was constructed through purposive, non-random sampling of UI strings likely to contain dark-pattern cues; consequently, both the absolute dataset size (223 instances, remaining small compared with English dark pattern datasets [4,6], despite augmentation) and the 75.8% dark-pattern rate reported in Section 5.1 reflect the composition of this deliberately constructed sample and should not be interpreted as an estimate of how frequently dark patterns occur across all UI text in the selected applications. Second, the held-out test set contains only 45 instances, which limits the stability of per-class performance estimates. Third, Forced Continuity/Roach Motel was not detected by any model at the current data volume (recall = 0.0000 for MARBERT; Table 10), reflecting limited examples and high linguistic variation within this category. Fourth, the augmented paraphrases were generated by the research team rather than through automated back-translation or generative augmentation pipelines, which may introduce paraphrase similarity bias. Future studies could compare manual paraphrasing with augmentation strategies such as back-translation and automated paraphrase generation [28,30]. Fifth, the study is text-based and relies on static app-session UI strings; therefore, it may miss visual, interactional, or dynamic dark patterns that emerge only across full user flows. Prior multimodal and app-level detection systems, such as AidUI, UIGuard, and AppRay, show that screenshots, visual hierarchy, and interaction flow can provide important context for detecting deceptive patterns [17,18,19]. Finally, the study covers nine e-commerce mobile applications operating in Saudi Arabia, and generalization to other Arab countries or dialectal Arabic contexts may require additional data collection and fine-tuning, given the linguistic diversity of Arabic digital communication [9,24]. In addition, session- and screenshot-level counts were not systematically logged during data collection, and specific promotional or seasonal sales calendars for the selected applications were not tracked; it is therefore possible that the observed frequency of urgency- and scarcity-based UI text was influenced by promotional activity at the time of collection rather than reflecting a stable baseline.

6.6. Future Work

Future work should expand the dataset to include more applications, additional Arab countries, and dialectal Arabic variants. Increasing the number and diversity of Forced Continuity/Roach Motel examples should be prioritized because this category remained the most difficult to detect. Future studies could also compare human-generated paraphrases with automated back-translation and LLM-based augmentation to evaluate which strategy produces more diverse and useful training examples [28,30]. In particular, LLMs could be explored for controlled paraphrase generation, active learning, and annotation assistance, provided that generated examples are carefully validated to avoid semantic drift and label noise.
Having compared five pretrained transformer models in this study, an important remaining direction is to evaluate large language models as zero-shot, few-shot, and instruction-tuned classifiers for Arabic dark pattern detection, to test whether prompting-based approaches can match or exceed fine-tuned encoder models under the same low-resource conditions. Closely related Arabic-specific models such as CAMeLBERT and ARBERT were not evaluated here and represent a natural extension, particularly because MARBERT’s strong performance suggests dialect-aware pre-training is a promising direction to explore further. Such experiments would allow direct comparison between Arabic-specific transformer fine-tuning and LLM-based prompting under low-resource conditions. This direction is especially relevant because the present study uses fine-tuned transformer models rather than LLM prompting, and future comparisons could clarify when supervised fine-tuning, data augmentation, or prompting-based approaches are more effective for specialized Arabic UI text classification. Another important direction is multimodal dark pattern detection. Incorporating UI screenshots, layout structure, button salience, visual hierarchy, and interaction-flow data may help detect cases where text alone is insufficient. This direction is supported by recent systems such as AidUI, UIGuard, and AppRay, which show that visual and interaction-level context can improve dark pattern detection beyond isolated text strings [17,18,19]. In addition, future work could explore human-in-the-loop auditing systems in which ML models flag potentially deceptive Arabic UI text for expert review rather than making fully automated decisions. Recent research comparing UX experts and AI-based evaluators suggests that expert oversight remains important for reliable dark pattern auditing [48]. Longitudinal studies could also track how dark patterns change across app versions and promotional seasons, providing evidence to support consumer protection and regulatory monitoring.

7. Conclusions

This paper presented, to the best of our knowledge, the first ML-based dark pattern detection benchmark for Arabic-language e-commerce mobile interfaces. We constructed a 223-instance annotated dataset from nine e-commerce mobile applications operating in Saudi Arabia, achieving strong inter-annotator agreement (κ = 0.89). The dataset addresses an important gap in low-resource Arabic NLP by providing task-specific labeled data for a specialized UI text classification problem.
We then developed a leakage-free augmentation pipeline in which the original instances were split first, followed by paraphrase-based augmentation applied only to the training partition, with a parent-aware filter ensuring no paraphrase of a validation or test instance entered training. We fine-tuned five pretrained transformer models—AraBERTv2, MARBERT, mBERT, BERT-base-uncased, and RoBERTa-base—on the resulting 452-instance training corpus for the held-out test comparison. Separately, our primary evaluation used 5-fold cross-validation on the 223 original, non-augmented instances. Under this cross-validation, MARBERT achieved the strongest performance (mean macro-F1 = 0.4230), numerically ahead of AraBERTv2 (0.2998) by a margin that did not reach statistical significance at five folds (p ≈ 0.064), and ahead of mBERT (0.3234); MARBERT significantly outperformed both English-only baselines; AraBERTv2 significantly outperformed RoBERTa-base, with its advantage over BERT-base-uncased not surviving correction for multiple comparisons; and mBERT was numerically stronger than both English-only baselines but was not directly tested against them. This suggests that, for short and informal Arabic UI text, pre-training on dialectal and code-switched Arabic may matter more than Arabic pre-training in general. Per-class analysis showed that even the best-performing model reliably detected only a subset of categories—Social Proof Manipulation and Hidden Costs were detected with reasonable precision, while Misdirection and Forced Continuity/Roach Motel remained undetected by every model evaluated. These findings highlight both the promise of dialect-aware Arabic pre-training and the continuing difficulty of Arabic dark pattern detection at current data volumes. The annotated dataset is publicly released on Zenodo to support future research on low-resource Arabic NLP, Arabic UI text classification, dark pattern detection, ethical interface design, and consumer protection technologies.
Overall, this work provides a rigorously validated initial benchmark for studying deceptive interface language in Arabic mobile commerce, and its central finding—that dialectal pre-training coverage may matter as much as language-matching alone—offers a concrete direction for future low-resource Arabic NLP research.


Funding

This research project was supported by Ongoing Research Funding Program, (ORF-2026-905), King Saud University, Riyadh, Saudi Arabia.

Institutional Review Board Statement

This study did not involve human participants, personal data collection, or clinical procedures. All data were collected from publicly available mobile application interfaces for non-commercial academic research purposes. No ethical review or approval was required.

Informed Consent Statement

Not applicable.

Data Availability Statement

The annotated dataset constructed in this study is publicly available on Zenodo at https://doi.org/10.5281/zenodo.21047182.

Acknowledgments

During the preparation of this work, the author used ChatGPT (OpenAI, GPT-4) to support the proofreading and linguistic refinement of written sections, to enhance clarity and academic tone.

Conflicts of Interest

The author declares no conflicts of interest.

References

  1. Statista. eCommerce—Saudi Arabia|Statista Market Forecast. Available online: https://www.statista.com/outlook/emo/ecommerce/saudi-arabia/ (accessed on 30 June 2026).
  2. Alotaibi, S.; Aljaafari, M.A.H. Social Commerce in Saudi Arabia: Opportunities and Challenges in a Digital Society. Sustainability 2024, 16, 10951. [Google Scholar] [CrossRef] [Scilit]
  3. Gray, C.M.; Kou, Y.; Battles, B.; Hoggatt, J.; Toombs, A.L. The Dark (Patterns) Side of UX Design. In Proceedings of the 2018 CHI Conference on Human Factors in Computing Systems, in CHI ’18; Association for Computing Machinery: New York, NY, USA, 2018; pp. 1–14. [Google Scholar] [CrossRef] [Scilit]
  4. Mathur, A.; Acar, G.; Friedman, M.J.; Lucherini, E.; Mayer, J.; Chetty, M.; Narayanan, A. Dark Patterns at Scale: Findings from a Crawl of 11K Shopping Websites. Proc. ACM Hum.-Comput. Interact. 2019, 3, 81:1–81:32. [Google Scholar] [CrossRef] [Scilit]
  5. Vedhapriyavadhana, R.; Bharti, P.; Chidambaranathan, S. Detecting dark patterns in shopping websites—A multi-faceted approach using Bidirectional Encoder Representations From Transformers (BERT). Enterp. Inf. Syst. 2025, 19, 2457961. [Google Scholar] [CrossRef] [Scilit]
  6. Yada, Y.; Feng, J.; Matsumoto, T.; Fukushima, N.; Kido, F.; Yamana, H. Dark patterns in e-commerce: A dataset and its baseline evaluations. In Proceedings of the 2022 IEEE International Conference on Big Data (Big Data), Osaka, Japan, 17–20 December 2022; pp. 3015–3022. [Google Scholar] [CrossRef] [Scilit]
  7. World Arabic Language Day|UNESCO. Available online: https://www.unesco.org/en/world-arabic-language-day (accessed on 1 July 2026).
  8. Alayba, A.M. Arabic Natural Language Processing (NLP): A Comprehensive Review of Challenges, Techniques, and Emerging Trends. Computers 2025, 14, 497. [Google Scholar] [CrossRef] [Scilit]
  9. Hamed, I.; Sabty, C.; Abdennadher, S.; Vu, N.T.; Solorio, T.; Habash, N. A Survey of Code-switched Arabic NLP: Progress, Challenges, and Future Directions. In Proceedings of the 31st International Conference on Computational Linguistics, Abu Dhabi, UAE, 19–24 January 2025; Association for Computational Linguistics: Stroudsburg, PA, USA, 2025; pp. 4561–4585. Available online: https://aclanthology.org/2025.coling-main.307/ (accessed on 30 June 2026).
  10. Habash, N.Y. Introduction to Arabic Natural Language Processing; Synthesis Lectures on Human Language Technologies; Springer International Publishing: Cham, Switzerland, 2010. [Google Scholar] [CrossRef] [Scilit]
  11. Uddin, F.; Chen, Y.; Zhang, Z.; Huang, X. Short text classification using semantically enriched topic model. J. Inf. Sci. 2025, 51, 481–498. [Google Scholar] [CrossRef] [Scilit]
  12. Antoun, W.; Baly, F.; Hajj, H. AraBERT: Transformer-based Model for Arabic Language Understanding. In Proceedings of the 4th Workshop on Open-Source Arabic Corpora and Processing Tools, with a Shared Task on Offensive Language Detection, Marseille, France, May 2020; Al-Khalifa, H., Magdy, W., Darwish, K., Elsayed, T., Mubarak, H., Eds.; European Language Resources Association: Paris, France, 2020; pp. 9–15. Available online: https://aclanthology.org/2020.osact-1.2/ (accessed on 30 June 2026).
  13. Mathur, A.; Kshirsagar, M.; Mayer, J. What Makes a Dark Pattern... Dark? Design Attributes, Normative Considerations, and Measurement Methods. In Proceedings of the 2021 CHI Conference on Human Factors in Computing Systems, in CHI ’21; Association for Computing Machinery: New York, NY, USA, 2021; pp. 1–18. [Google Scholar] [CrossRef] [Scilit]
  14. Gunawan, J.; Pradeep, A.; Choffnes, D.; Hartzog, W.; Wilson, C. A Comparative Study of Dark Patterns Across Web and Mobile Modalities. Proc. ACM Hum.-Comput. Interact. 2021, 5, 377:1–377:29. [Google Scholar] [CrossRef] [Scilit]
  15. Xu, H.; Chen, Y.; Med, A. Automatic Detection and Explanation of Dark Patterns from Interface Microcopy: Empirical Comparison of BERT-Style Encoders, RoBERTa-Style Encoders, and LLM-Style Decoders on the ec-darkpattern Dataset. J. Technol. Inform. Eng. 2025, 4, 590–612. [Google Scholar] [CrossRef] [Scilit]
  16. Yada, Y.; Matsumoto, T.; Kido, F.; Yamana, H. Why is the User Interface a Dark Pattern?: Explainable Auto-Detection and its Analysis. In Proceedings of the 2023 IEEE International Conference on Big Data (BigData), Sorrento, Italy, 15–18 December 2023; pp. 6308–6310. [Google Scholar] [CrossRef] [Scilit]
  17. Mansur, S.M.H.; Salma, S.; Awofisayo, D.; Moran, K. AidUI: Toward Automated Recognition of Dark Patterns in User Interfaces. In Proceedings of the 45th International Conference on Software Engineering, in ICSE ’23, Melbourne, VIC, Australia, 14–20 May 2023; IEEE Press: New York, NY, USA, 2023; pp. 1958–1970. [Google Scholar] [CrossRef] [Scilit]
  18. Chen, J.; Sun, J.; Feng, S.; Xing, Z.; Lu, Q.; Xu, X.; Chen, C. Unveiling the Tricks: Automated Detection of Dark Patterns in Mobile Applications. In Proceedings of the 36th Annual ACM Symposium on User Interface Software and Technology, in UIST ’23; Association for Computing Machinery: New York, NY, USA; pp. 1–20. [CrossRef] [Scilit]
  19. Chen, J.; Wang, Z.; Sun, J.; Xing, Z.; Lu, Q.; Huang, Q.; Xu, X.; Zhu, L. From Exploration to Revelation: App-Level Context-Aware Deceptive Pattern Detection for Mobile Applications. ACM Trans. Softw. Eng. Methodol. 2026. [Google Scholar] [CrossRef] [Scilit]
  20. Chang, W.J.; Seaborn, K.; Adams, A.A. Theorizing Deception: A Scoping Review of Theory in Research on Dark Patterns and Deceptive Design. In Extended Abstracts of the CHI Conference on Human Factors in Computing Systems, in CHI EA ’24; Association for Computing Machinery: New York, NY, USA, 2024; pp. 1–7. [Google Scholar] [CrossRef] [Scilit]
  21. Li, M.; Wang, X.; Nie, L.; Li, C.; Liu, Y.; Zhao, Y.; Xue, L.; Said, K.S. A Comprehensive Study on Dark Patterns. arXiv 2024, arXiv:2412.09147. [Google Scholar] [CrossRef] [Scilit]
  22. Nazarov, D.; Baimukhambetov, Y. Clustering of Dark Patterns in the User Interfaces of Websites and Online Trading Portals (E-Commerce). Mathematics 2022, 10, 3219. [Google Scholar] [CrossRef] [Scilit]
  23. Darwish, K.; Habash, N.; Abbas, M.; Al-Khalifa, H.; Al-Natsheh, H.T.; Bouamor, H.; Bouzoubaa, K.; Cavalli-Sforza, V.; El-Beltagy, S.R.; El-Hajj, W.; et al. A panoramic survey of natural language processing in the Arab world. Commun. ACM 2021, 64, 72–81. [Google Scholar] [CrossRef] [Scilit]
  24. Guellil, I.; Saâdane, H.; Azouaou, F.; Gueni, B.; Nouvel, D. Arabic natural language processing: An overview. J. King Saud Univ.-Comput. Inf. Sci. 2021, 33, 497–507. [Google Scholar] [CrossRef] [Scilit]
  25. Abdul-Mageed, M.; Elmadany, A.; Nagoudi, E.M.B. ARBERT & MARBERT: Deep Bidirectional Transformers for Arabic. In Proceedings of the 59th Annual Meeting of the Association for Computational Linguistics and the 11th International Joint Conference on Natural Language Processing (Volume 1: Long Papers); Zong, C., Xia, F., Li, W., Navigli, R., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2021; pp. 7088–7105. [Google Scholar] [CrossRef] [Scilit]
  26. Inoue, G.; Alhafni, B.; Baimukan, N.; Bouamor, H.; Habash, N. The Interplay of Variant, Size, and Task Type in Arabic Pre-trained Language Models. In Proceedings of the Sixth Arabic Natural Language Processing Workshop, Kyiv, Ukraine (Virtual), 19 April 2021; Habash, N., Bouamor, H., Hajj, H., Magdy, W., Zaghouani, W., Bougares, F., Tomeh, N., Abu Farha, I., Touileb, S., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2021; pp. 92–104. Available online: https://aclanthology.org/2021.wanlp-1.10/ (accessed on 1 July 2026).
  27. Chen, J.; Tam, D.; Raffel, C.; Bansal, M.; Yang, D. An Empirical Survey of Data Augmentation for Limited Data Learning in NLP. Trans. Assoc. Comput. Linguist. 2023, 11, 191–211. [Google Scholar] [CrossRef] [Scilit]
  28. Sennrich, R.; Haddow, B.; Birch, A. Improving Neural Machine Translation Models with Monolingual Data. In Proceedings of the 54th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), Berlin, Germany, 7–12 August 2016; Erk, K., Smith, N.A., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2016; pp. 86–96. [Google Scholar] [CrossRef] [Scilit]
  29. Xie, Q.; Dai, Z.; Hovy, E.; Luong, T.; Le, Q. Unsupervised Data Augmentation for Consistency Training. Adv. Neural Inf. Process. Syst. 2020, 33, 6256–6268. [Google Scholar]
  30. Okur, E.; Sahay, S.; Nachman, L. Data Augmentation with Paraphrase Generation and Entity Extraction for Multimodal Dialogue System. In Proceedings of the Thirteenth Language Resources and Evaluation Conference, Marseille, France, 20–25 June 2022; Calzolari, N., Béchet, F., Blache, P., Choukri, K., Cieri, C., Declerck, T., Goggi, S., Isahara, H., Maegaard, B., Mariani, J., et al., Eds.; European Language Resources Association: Paris, France, 2022; pp. 4114–4125. Available online: https://aclanthology.org/2022.lrec-1.437/ (accessed on 30 June 2026).
  31. Loem, M.; Takase, S.; Kaneko, M.; Okazaki, N. ExtraPhrase: Efficient Data Augmentation for Abstractive Summarization. arXiv 2022, arXiv:2201.05313. [Google Scholar] [CrossRef] [Scilit]
  32. Alsakran, W.S.; Alabduljabbar, R. A Novel Llama 3-Based Prompt Engineering Platform for Textual Data Generation and Labeling. Electronics 2025, 14, 2800. [Google Scholar] [CrossRef] [Scilit]
  33. Similarweb. Top Shopping Apps Ranking—Most Popular Shopping Apps in Saudi Arabia [June 28]. Available online: https://www.similarweb.com/top-apps/google/saudi-arabia/shopping/top-free/ (accessed on 1 July 2026).
  34. Matters, A.G. Most Popular Shopping Apps: Saudi Arabia|42matters. Available online: https://42matters.com/most-popular-shopping-apps-saudi-arabia (accessed on 1 July 2026).
  35. Appfigures. Top Shopping Apps for Android on Google Play in Saudi Arabia. Available online: https://app.appfigures.com/top-apps/google-play/saudi-arabia/shopping (accessed on 1 July 2026).
  36. Similarweb. Top iPhone Food & Drink Apps Ranking in Saudi Arabia [June 28]. Available online: https://www.similarweb.com/top-apps/apple/saudi-arabia/food-drink/top-free/ (accessed on 1 July 2026).
  37. Similarweb. Top Travel & Local Apps Ranking—Most Popular Travel & Local Apps in Saudi Arabia [June 28]. Available online: https://www.similarweb.com/top-apps/google/saudi-arabia/travel-local/top-free/ (accessed on 1 July 2026).
  38. Cohen, J. A Coefficient of Agreement for Nominal Scales. Educ. Psychol. Meas. 1960, 20, 37–46. [Google Scholar] [CrossRef] [Scilit]
  39. Landis, J.R.; Koch, G.G. The Measurement of Observer Agreement for Categorical Data. Biometrics 1977, 33, 159–174. [Google Scholar] [CrossRef] [Scilit]
  40. Fleiss, J.L. Statistical Methods for Rates and Proportions, 2nd ed.; Wiley: New York, NY, USA, 1981. [Google Scholar]
  41. Alabduljabbar, R. Arabic Dark Pattern Dataset for E-Commerce Mobile Applications Operating in Saudi Arabia. Zenodo 2026. [Google Scholar] [CrossRef]
  42. Obeid, O.; Zalmout, N.; Khalifa, S.; Taji, D.; Oudah, M.; Alhafni, B.; Inoue, G.; Eryani, F.; Erdmann, A.; Habash, N. CAMeL Tools: An Open Source Python Toolkit for Arabic Natural Language Processing. In Proceedings of the Twelfth Language Resources and Evaluation Conference, Marseille, France, 13–15 May 2020; Calzolari, N., Béchet, F., Blache, P., Choukri, K., Cieri, C., Declerck, T., Goggi, S., Isahara, H., Maegaard, B., Mariani, J., et al., Eds.; European Language Resources Association: Paris, France, 2020; pp. 7022–7032. Available online: https://aclanthology.org/2020.lrec-1.868/ (accessed on 2 July 2026).
  43. Zerrouki, T. PyArabic: A Python package for Arabic text. J. Open Source Softw. 2023, 8, 4886. Available online: https://pypi.org/project/PyArabic/ (accessed on 2 July 2026).
  44. Devlin, J.; Chang, M.-W.; Lee, K.; Toutanova, K. BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding. In Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers); Burstein, J., Doran, C., Solorio, T., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2019; pp. 4171–4186. [Google Scholar] [CrossRef] [Scilit]
  45. Liu, Y.; Ott, M.; Goyal, N.; Du, J.; Joshi, M.; Chen, D.; Levy, O.; Lewis, M.; Zettlemoyer, L.; Stoyanov, V. RoBERTa: A Robustly Optimized BERT Pretraining Approach. arXiv 2019, arXiv:1907.11692. [Google Scholar] [CrossRef] [Scilit]
  46. Wolf, T.; Debut, L.; Sanh, V.; Chaumond, J.; Delangue, C.; Moi, A.; Cistac, P.; Rault, T.; Louf, R.; Funtowicz, M. Transformers: State-of-the-Art Natural Language Processing. In Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing: System Demonstrations, Online, 16–20 November 2020; Liu, Q., Schlangen, D., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2020; pp. 38–45. [Google Scholar] [CrossRef] [Scilit]
  47. Loshchilov, I.; Hutter, F. Decoupled Weight Decay Regularization. In Proceedings of the International Conference on Learning Representations; Available online: https://openreview.net/forum?id=Bkg6RiCqY7 (accessed on 2 July 2026).
  48. Nwokeji, J.; Nkwo, M.; Ikwunne, T.; Yeerbo, M. UX Experts vs. AI: Exploring the Performance of Large Language Models and Humans on Detecting Dark Patterns. AI Ethics 2026, 6, 2026. [Google Scholar] [CrossRef] [Scilit]
Figure 1. Full dark pattern detection pipeline, from raw Arabic UI text collection through stratified data splitting, train-only paraphrase augmentation, preprocessing, model-specific tokenization, transformer fine-tuning, and six-class evaluation. Augmented instances are used only during training, while validation and test sets contain original non-augmented instances.
Electronics 15 03955 g001
Figure 2. Training partition expansion by class after paraphrase-based augmentation. Light bars represent original training instances, while dark bars represent augmented paraphrases.
Electronics 15 03955 g002
Figure 3. Confusion matrix for MARBERT, the best-performing model, on the 45-instance held-out test set.
Electronics 15 03955 g003
Table 1. Comparison of representative dark pattern analysis and detection studies with the present study on Arabic UI text in e-commerce mobile applications operating in Saudi Arabia.
StudyLanguagePlatformInput TypeMain MethodReported PerformanceAugmentation
Mathur et al. [4]EnglishE-commerce websitesUI textLarge-scale crawl and manual analysis1818 instances across 11,000+ websitesNo
Yada et al. [6]EnglishE-commerce websitesUI textBERT, RoBERTa, ALBERT, XLNetAccuracy up to 0.975No
Vedhapriyavadhana et al. [5]EnglishShopping websitesWeb textFine-tuned BERTStrong dark pattern classification performanceNo
Xu and Chen [15]EnglishE-commerce interfacesInterface microcopyLinear classifiers, BERT-style encoders, RoBERTa-style encoders, and LLM-style decodersStrong microcopy-based dark pattern detection performanceNo
Yada et al. [16]EnglishE-commerce websitesUI textTransformer model + LIME/SHAPExplainable auto-detection of influential dark-pattern termsNo
Mansur et al./AidUI [17]English/visual UIWeb and mobile UIsScreenshot + textCV + NLPPrecision = 0.66, recall = 0.67, F1 = 0.65No
Chen et al./UIGuard [18]English/visual UIMobile appsMobile UI screenshotsComputer vision + NLP-based pattern matchingPrecision = 0.82, recall = 0.77, F1 = 0.79No
Chen et al./AppRay [19]English/visual UIMobile appsApp-level UI states and interaction flowsLLM-assisted exploration + contrastive learning + rule refinementDetects static and dynamic deceptive patterns across mobile app flowsNo
Present studyArabic E-commerce mobile applications operating in Saudi ArabiaArabic UI textAraBERTv2, MARBERT, mBERT, BERT-base-uncased, RoBERTa-baseMacro-F1 = 0.4230 (MARBERT, best-performing model; 5-fold CV)Yes, train-only Arabic paraphrase augmentation
Table 2. Applications included in the final dataset, user-flow coverage, final labeled text instances, and dark pattern counts. Note. Reg. = account registration; Search = product search; Cart = add to cart; Checkout = checkout flow; Cancel = subscription or cancellation management.
AppCategoryUser FlowsInstancesDark Patterns
Shein KSAFashionReg, Search, Cart, Checkout, Cancel3932
NoonGeneral ShoppingReg, Search, Cart, Checkout, Cancel3222
TemuGeneral ShoppingReg, Search, Cart, Checkout, Cancel3127
Amazon SAGeneral ShoppingReg, Search, Cart, Checkout, Cancel2620
KeetaFood DeliveryReg, Search, Cart, Checkout, Cancel2114
HungerStationFood DeliveryReg, Search, Cart, Checkout, Cancel2117
AlmosaferTravel & BookingReg, Search, Cart, Checkout, Cancel2017
NamshiFashionReg, Search, Cart, Checkout, Cancel177
Booking SATravel & BookingReg, Search, Cart, Checkout, Cancel1613
TOTAL9 apps, 4 categories5 flows per app223169
Table 3. Main annotation cues and representative Arabic examples for the five dark pattern categories.
CategoryMain CueRepresentative Example
Urgency/ScarcityTime pressure or limited availabilityعلى وشك النفاد
MisdirectionEmotional framing, unclear consent, attention manipulationElectronics 15 03955 i003
Hidden CostsLate-disclosed fees or conditional chargesرسوم الخدمة
Forced Continuity/Roach MotelAuto-renewal or difficult cancellationسيتم تجديد عضويتك تلقائيًا
Social Proof ManipulationPopularity or demand claimsتم بيع +٢٥٠ مؤخرًا
Table 4. Representative disagreement cases illustrating annotator disagreement and adjudication decisions.
RowAnnotator 1Annotator 2Final LabelJustification
12Hidden CostsNone—not a dark patternHidden CostsCredit offers included conditions that were not clearly presented upfront
40MisdirectionSocial Proof ManipulationSocial Proof ManipulationBest-seller claim functioned primarily as a popularity-based social proof cue
58MisdirectionNone—not a dark patternMisdirectionReferral reward framing was interpreted as persuasive framing that could influence user behavior
128Urgency/ScarcityUncertainUrgency/ScarcityDeadline-based prompt created urgency within the interface context
130None—not a dark patternForced Continuity/Roach MotelForced Continuity/Roach MotelCard-linked benefit structure could make subscription continuation more difficult to avoid
137Social Proof ManipulationNone—not a dark patternNone—not a dark patternPersonal savings history was informational rather than manipulative
177None—not a dark patternUncertainNone—not a dark patternPrice-floor statement was clear and informational
188Forced Continuity/Roach MotelMisdirectionMisdirectionAbandoned-cart nudge used emotional framing and was therefore classified as misdirection
Table 5. Final dataset label distribution.
LabelCount% of Total
Urgency/Scarcity5524.7%
None—not a dark pattern5424.2%
Social Proof Manipulation3113.9%
Hidden Costs3113.9%
Misdirection3013.5%
Forced Continuity/Roach Motel229.9%
TOTAL223100.0% *
* Percentages may not sum to 100% due to rounding.
Table 6. Representative annotated examples from the Arabic dark pattern dataset.
AppUser Flow/Interface ContextArabic UI TextLabel
NoonPop-up/Bannerخصم إضافي ١٥٪ للمشتركين في نون None—not a dark pattern
NoonAccount Registrationللتسجيل يجب أوافق على تلقي الرسائل التسويقيةMisdirection
NoonProduct Searchتم بيع + ٢٥٠ مؤخراSocial Proof Manipulation
TemuProduct Searchعلى وشك النفاذUrgency/Scarcity
TemuCheckoutأقل من الحد الأدنى لعمل طلبMisdirection
TemuPop-up/Bannerاحصل على رصيد بقيمة٢٠٠ ر.س.Hidden Costs
KeetaCheckoutرسوم الخدمةHidden Costs
KeetaAdd to Cartتنتهي صلاحيتها في ٢٢س ١٢د ٣٩ثUrgency/Scarcity
Shein KSAProduct Searchستنفد الكمية قريبًا! لا تتردد!Urgency/Scarcity
Shein KSAAdd to Cart155.55 بعد الكوبونHidden Costs
NamshiAccount Registrationوش رايك بتجرب تسوق معمولة على ذوقك؟Misdirection
HungerStationSubscription & Cancellationوفرت 184 ريال يتجدد في 102 يوماًForced Continuity/Roach Motel
Amazon SAPop-up/Bannerينتهي غدًا لا تفوت الفرصة!Urgency/Scarcity
Amazon SASubscription & Cancellationسيتم تجديد الاشتراك تلقائيًا بعد انتهاء الفترة التجريبية.Forced Continuity/Roach Motel
Booking SACheckoutقد يتم تطبيق تكاليف إضافيةHidden Costs
AlmosaferAdd to Cartاختر المقاعد بدءًا من ٢٢٧.٨٢ ر.سHidden Costs
Table 7. Training corpus expansion by class after train-only paraphrase augmentation. Validation and test sets contained original non-augmented instances only.
ClassOriginalAugmentedTotal
Urgency/Scarcity3877115
None—not a dark pattern3764101
Social Proof Manipulation224668
Hidden Costs224466
Misdirection214061
Forced Continuity/Roach Motel152641
TOTAL155297452
Table 8. Model comparison on the 45-instance original held-out test set, leakage-free training pipeline. Precision, recall, and F1-score are macro-averaged. All models were trained on 452-instance training corpus.
ModelPrecisionRecallF1-ScoreAccuracy
MARBERT0.44130.34850.35130.4000
mBERT0.38890.29550.26560.3778
AraBERTv20.20270.25510.19790.3556
RoBERTa-base0.10470.19700.12730.2889
BERT-base-uncased0.06730.13640.09010.2000
Table 9. 95% bootstrap confidence intervals for macro-F1 (2000 stratified resamples of the 45-instance test set).
ModelMacro-F195% Bootstrap CI
MARBERT0.3513[0.2092, 0.4449]
mBERT0.2656[0.1356, 0.3737]
AraBERTv20.1979[0.1105, 0.2800]
RoBERTa-base0.1273[0.0708, 0.1794]
BERT-base-uncased0.0901[0.0439, 0.1368]
Table 10. Per-class results for MARBERT, the best-performing model, on the held-out test set.
ClassPrecisionRecallF1-ScoreSupport
Urgency/Scarcity0.37500.54550.444411
Misdirection0.00000.00000.00006
Hidden Costs1.00000.33330.50006
Forced Continuity/Roach Motel0.00000.00000.00005
Social Proof Manipulation1.00000.66670.80006
None—not a dark pattern0.27270.54550.363611
Macro avg0.44130.34850.351345
Table 11. Stratified 5-fold cross-validation results for all five models on the 223 original instances, without augmentation.
ModelMean Macro-F1 (±SD; Variance)Mean Accuracy
MARBERT0.4230 ± 0.0695 (variance = 0.00483)0.5023 ± 0.0469
mBERT0.3234 ± 0.0963 (variance = 0.00927)0.4124 ± 0.0757
AraBERTv20.2998 ± 0.1040 (variance = 0.01082)0.4123 ± 0.0780
BERT-base-uncased0.1525 ± 0.0334 (variance = 0.00112)0.2872 ± 0.0596
RoBERTa-base0.0863 ± 0.0263 (variance = 0.00069)0.2373 ± 0.0443
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content.