1. Introduction
The development of convenience devices, such as infotainment systems, has transformed vehicles from simple means of transportation into living spaces. These days, highly advanced embedded devices equipped with various autonomous driving and connected features are widely installed in vehicles. As these features generate large volumes of in-vehicle data, Automotive Ethernet has been introduced to expand bandwidth and improve in-vehicle network performance.
The existing in-vehicle network protocols, such as CAN (Controller Area Network), FlexRay, and LIN (Local Interconnect Network), have revealed limitations in meeting the demands of large-scale data transmission. For example, CANFD (CAN Flexible Data Rate), an improved version of CAN, only supports message sizes up to 64 bytes. To address these limitations, Automotive Ethernet has been adopted, and SOME/IP (Scalable service-Oriented Middleware over IP) has emerged as a key middleware of AUTOSAR (AUTomotive Open System ARchitecture) for service-oriented in-vehicle communication. The SOME/IP protocol, which supports service-oriented communication in vehicles. However, the SOME/IP protocol lacks built-in security mechanisms, making it vulnerable to various security threats. Without authentication and encryption, SOME/IP deployments can be exposed to threats such as DoS (Denial-of-Service) and MitM (Man-in-the-Middle) attacks. For instance, the SOME/IP-SD function transmits identifying information, such as IP addresses and MAC (Media Access Control) addresses, using UDP (User Datagram Protocol) multicast, enabling malicious users to impersonate legitimate users, call services, or steal data. Although IPSec (Internet Protocol Security) and TLS (Internet Protocol Security) can provide transport-layer security for SOME/IP, they may not fully match all automotive communication patterns (e.g., multicast and application-level identity), which can limit coverage in practice [
1]. For example, IPSec could secure tunnels between different ECUs, but its lack of application awareness prevents it from authenticating the communicating parties. Similarly, TLS does not support multicast communication, which SOME/IP uses to minimize transmissions when possible. In addition, by surveying recent work [
2] on automotive public key infrastructures, we observe that deployment in production fleets remains uneven and faces persistent challenges in certificate provisioning, distribution, and revocation, as well as in the secure storage of keys within control units.
Moreover, most existing anomaly detection system approaches focus on protecting traditional in-vehicle network communications such as CAN. Among previous approaches to anomaly detection in in-vehicle networks, only a few address SOME/IP security. Most ECUs using SOME/IP communication are likely to offer more functionality than those relying on CAN, with these features often being safety-critical and directly impacting vehicle operations, such as autonomous driving. Consequently, a security mechanism specialized for SOME/IP communication is essential. To address this need, we developed a SOME/IP anomaly detection system.
In this paper, attack scenarios that may occur in the vehicle SOME/IP network, including fuzzy, denial-of-service, and man-in-the-middle attacks, are first introduced. These attacks can have adverse impacts on vehicles, including manipulation of ECU behavior and abnormal vehicle operation. In addition, we propose an anomaly detection framework that mitigates attacks exploiting the service provisioning and RPC (Remote Procedure Call) mechanisms of the SOME/IP and SOME/IP-SD protocols. To identify network anomalies, the framework relies on behavior-oriented features derived from raw traffic, including packet time-interval patterns, payload entropy and likelihood, and packet length variations. Rather than using message header field values in their original form, which often contain implementation-specific identifiers and may cause overfitting, our framework preprocesses traffic records to generate transformed and aggregated features that more clearly represent network state and communication behavior. Among the many features available in raw network traces, we extract behavior-related discriminative features and analyze them using XGBoost (eXtreme Gradient Boosting), which is well suited to large-scale tabular classification. Its built-in regularization helps control overfitting, and it can be trained efficiently on large datasets via parallelization.
To clarify the scope of this study, we address three research questions. RQ1: Can behavior-centric features derived from SOME/IP and SOME/IP-SD traffic achieve clear normal–attack separation without relying on header-derived features? This is evaluated using visualization, clustering, and performance metrics using behavioral information only, excluding headers. RQ2: Can an XGBoost-based detector achieve robust detection across diverse SOME/IP attack scenarios while maintaining a controlled false alarm rate under both realistic and controlled evaluation protocols? We investigate this through comprehensive detection experiments that evaluate both classification quality. RQ3: Is the proposed IDS (Intrusion Detection System) computationally feasible for near-real-time monitoring under resource constraints representative of gateway or domain ECUs? We assess this by measuring processing efficiency of the framework, including feature extraction and model inference.
To enable a reproducible evaluation of these questions, we construct a large-scale labeled SOME/IP dataset using a multi-ECU vSomeIP simulation, in which normal traffic and representative attack families such as DoS, fuzzing, MitM, and message drop are executed in a controlled manner. Because real in-vehicle SOME/IP attack traces are rarely available and difficult to capture from production vehicles, the simulation provides protocol-compliant communication flows and attack behaviors in a repeatable and inspectable environment. We then perform a stratified split into training and test sets while preserving the natural class imbalance, and we select the operating threshold based on training-side evaluation. Because real deployments are typically imbalanced with benign traffic dominating, we explore CTGAN (Conditional Tabular Generative Adversarial Network)-based augmentation to generate additional attack samples and mitigate training-time imbalance. However, since balanced training does not necessarily reflect operational conditions, we evaluate performance on both an imbalanced test set that preserves the natural imbalance and a balanced test set constructed for controlled comparison, in order to accurately assess detection behavior under both realistic and controlled settings. Finally, we explicitly state the bounds of generality of our study: while the evaluation is conducted in a controlled vSomeIP-based environment for reproducibility, the proposed features and detection workflow are intended to generalize at the SOME/IP and SOME/IP-SD behavior level, whereas absolute performance may vary under real-vehicle implementations due to differences in ECU hardware, background workloads, network conditions.
The contributions of this paper can be summarized as follows:
- -
We design and implement realistic SOME/IP attack scenarios (DoS, fuzzing, MitM, and message-drop) in a multi-ECU vSomeIP simulation and construct a large-scale labeled SOME/IP dataset that enables reproducible evaluation [
3].
- -
We propose an end-to-end SOME/IP anomaly detection framework that derives layered, stream-wise features from raw Ethernet traffic to capture dynamic service and RPC behaviors.
- -
The diverse characteristics of network behavior under SOME/IP are explored, and methods for extracting network behavior-oriented features using the XGBoost ensemble algorithm are proposed.
- -
We compared detection performance with prior approaches and analyzed real-time feasibility from multiple perspectives.
The structure of the paper is as follows.
Section 2 reviews related work on in-vehicle network security and intrusion detection, with an emphasis on prior CAN- and SOME/IP-oriented approaches.
Section 3 introduces SOME/IP communication models and discusses key vulnerabilities and representative attack scenarios.
Section 4 describes a simulation-based experimental setup and the construction of a dataset, including the normal SOME/IP communication flow and the implemented attack procedures.
Section 5 presents the proposed XGBoost-based anomaly detection framework, detailing the layered packet extraction, feature engineering, and detection workflow.
Section 6 reports experimental evaluation results, including dataset partitioning and performance analyses such as t-SNE (t-distributed Stochastic Neighbor Embedding)-based feature assessment, detection metrics, comparative baselines, and real-time feasibility under resource constraints. Finally,
Section 7 concludes the paper and outlines limitations and directions for future work.
2. Related Works
Most of the previous research has focused on intrusion detection for classical in-vehicle networks, especially the CAN bus. Aloqaily et al. [
4] proposed a hybrid intrusion detection system for connected vehicles in smart cities, combining a deep belief network for dimensionality reduction with a decision-tree classifier to detect attacks in cloud-connected vehicular services. Refat et al. [
5] presented a lightweight IDS for CAN that abstracts CAN traffic into temporal graphs and uses neighborhood similarity to detect spoofing, fuzzy, and DoS attacks with small frame chunks. Deng et al. [
6] exploited voltage fingerprints to build ID-level profiles that can identify malicious frames and infer the identities of attacker ECUs without requiring proprietary ID–ECU mapping. Other CAN-centric approaches include n-gram analysis of ID sequences in DAGA [
7], time-interval–based detection for resource-constrained ECUs [
8], signature-based patterns derived from real attacks [
9], statistically optimized thresholds over sliding windows [
10], CNN (Convolution Neural Network)-based IDS for large-scale network traffic [
11], and conditional-entropy–based time-interval analysis in TCE-IDS [
12]. These works demonstrate the effectiveness of various statistical techniques for CAN, but they are designed to operate at the data-link layer, so they cannot exploit the multi-layer service semantics, RPC patterns, or service discovery behavior that characterize SOME/IP-based Automotive Ethernet. In contrast, our framework is explicitly designed to span the IP, transport (TCP/UDP), and SOME/IP (including SOME/IP-SD) layers, deriving features from service discovery, request–response, and publish–subscribe interactions rather than from CAN IDs or raw link-layer frames.
More recent studies have introduced deep learning, explainability, adversarial robustness, and federated learning into automotive IDS design. Ding et al. [
13] proposed DeepSecDrive, an explainable deep-learning framework that combines deformable convolutions and lightweight non-local networks for real-time detection in in-vehicle networks, with SHAP (Shapley Additive exPlanations)-based explanations of model decisions. Seo et al. [
14] showed that GAN (Generative Adversarial Network)-generated adversarial examples can drastically reduce the detection performance of ML-based in-vehicle IDS, highlighting the need for adversarial robustness. Jeong et al. [
15] developed AERO, an unsupervised Automotive Ethernet observer that extracts multimodal features and uses neural networks to compute outlier scores for real-time anomaly detection. Peng et al. [
16] designed CNN-based IDS models suitable for resource-constrained IoV (Internet of Vehicles) terminals, while Shahriar et al. [
17] proposed CANShield, a signal-level deep-learning framework that decodes CAN payloads into time-series signals and uses ensembles of autoencoders to detect stealthy attacks. He et al. [
18] combined CGAN (Conditional GAN)-based data augmentation with federated learning and blockchain for UAV networks, and Anand et al. [
19] introduced a two-stage deep-learning IDS with rule extraction for IoT-based smart vehicle networks. Meng et al. [
20], Seo et al. [
21], Taslimasa et al. [
22], Amutha et al. [
23], and Yang et al. [
24] further explored graph-based, GAN-based, federated, and multi-tier hybrid IDS frameworks for CAN and IoV. While these methods provide valuable insights into model architectures, explainability, and distributed training, they are either evaluated on controller area network data or on generic internet-of-vehicles datasets, or they treat network traffic as generic tabular or time-series data. In contrast, our work focuses on a compact set of SOME/IP-specific behavior features and uses a shallow learning approach based on XGBoost, enabling detection with short inference time even on resource-constrained automotive platforms.
Compared with the above CAN- and IoV-oriented studies, research directly targeting SOME/IP-based Automotive Ethernet remains relatively limited [
25,
26]. Luo et al. [
27] proposed an intrusion detection system for SOME/IP based in vehicle networks that combines rule-based modules for headers, SOME/IP Service Discovery messages, message intervals, and communication procedures with a GRU (Gated Recurrent Unit) based module for payload analysis, and they constructed a simulation environment using Prescan, Simulink, and CANoe. Herold et al. [
28] used the Esper complex event processing engine to encode SOME/IP protocol rules and to detect protocol violations and attacks based on complex event processing queries spanning multiple packets. Casparsen et al. [
29] developed a host-based intrusion detection system that detects SOME/IP attacks, such as denial-of-service and impersonation, using arrival times, payload values, and packet contradictions. Gehrmann and Duplys [
30] discussed conceptual challenges and opportunities for SOME/IP intrusion detection and pointed out that service-oriented semantics and metadata can provide rich context for monitoring. Koyama et al. [
31] presented a whitelist based SOME/IP intrusion detection system that combines real-time and retroactive anomaly detection at the session level to meet United Nations Regulation R155 requirements, while Alkhatib et al. [
32] modeled SOME/IP sessions as sequences and applied recurrent neural network-based sequential models using a custom SOME/IP dataset. Other implementations include machine learning based intrusion detection using SOME/IP headers and reception times, the self-attention based SAID method for modeling long range dependencies in SOME/IP packet sequences [
33], a Suricata based rule driven SOME/IP intrusion detection system with a dedicated protocol parser and rule set [
34], and SISSA, which uses SOME/IP traffic for integrated monitoring of hardware functional safety and cybersecurity [
35]. These SOME/IP-focused intrusion detection systems either rely predominantly on header-level rules and whitelists or treat traffic as raw sequences for deep sequential models. By contrast, our approach extracts behavior-centric features from layered and stream-level packet representations, explicitly modeling time-interval variation, payload log-likelihood and cross-entropy, payload change via Hamming distance, and length change on a per-flow basis. This design allows us to capture dynamic service and remote procedure call behavior across the entire SOME/IP communication stack, and we empirically show, using distributed stochastic neighbor embedding and clustering indices, that these features provide stronger class separation than header-only feature sets. Furthermore, we evaluated our framework in comparative experiments with methods [
33,
34,
35] and observed that it achieves better performance.
Another line of previous work focuses on securing SOME/IP communication through cryptographic protocols and secure gateways rather than anomaly detection. Ma et al. [
36] introduced an authentication and secure communication scheme with a central key management controller, and payload-level authenticated encryption for SOME/IP-based in-vehicle networks. Zuo et al. [
37] designed a CANFD-to-SOME/IP gateway that provides multiple security levels with acceptable overhead, while Li et al. [
38] proposed Ori, a gray-box fuzzer that efficiently finds vulnerabilities in SOME/IP applications. Iorio et al. [
39] defined a secure SOME/IP framework with service-level security policies and a formally verified session protocol, and Du et al. [
40] used formal models to reveal weaknesses in existing SOME/IP security schemes and suggested improvements. Lee et al. [
41] finally presented a Kerberos-style ticket mechanism for SOME/IP to mitigate replay and man-in-the-middle attacks with fewer asymmetric key operations. These studies provide preventive security mechanisms at the protocol and gateway level, which are complementary to our detection-oriented framework: even in the presence of secure SOME/IP variants, misconfigurations, software bugs, or implementation-specific vulnerabilities can still lead to abnormal behavior on the network, making behavior-based anomaly detection an essential second line of defense.
Most existing automotive intrusion detection work is still centered on CAN and CANFD, and even the intrusion detection systems that explicitly target SOME/IP usually highlight header rules, whitelist policies, or direct sequence modeling, instead of systematically exploiting layered and per-stream behavioral features over Ethernet, IP, transport, SOME/IP, and SOME/IP Service Discovery. Our framework, by contrast, performs layered packet extraction and stream-level grouping so that features such as inter-arrival timing, payload likelihood, and entropy, and changes in payload and length are evaluated within each flow and service context, allowing us to capture attack-related anomalies in service discovery procedures, publish–subscribe communication, and request–response interactions. We also move beyond relatively small proprietary datasets by constructing a large-scale labeled SOME/IP dataset with roughly 14.23 million samples from a realistic vSomeIP-based multi-ECU environment that includes nine control units and four representative attack families: denial-of-service, fuzzy traffic, message drop, and man-in-the-middle. Instead of deep sequential architectures such as GRU- or attention-based networks, we employ XGBoost, which is well-suited to tabular features and achieves sub-millisecond inference time per message, making it practical for in-vehicle deployment.
3. SOME/IP and Its Vulnerabilities
This section provides an overview of the basic SOME/IP communication flow, followed by a description of attack scenarios that exploit vulnerabilities arising from the lack of authentication and encryption.
3.1. Preliminaries on SOME/IP Communications
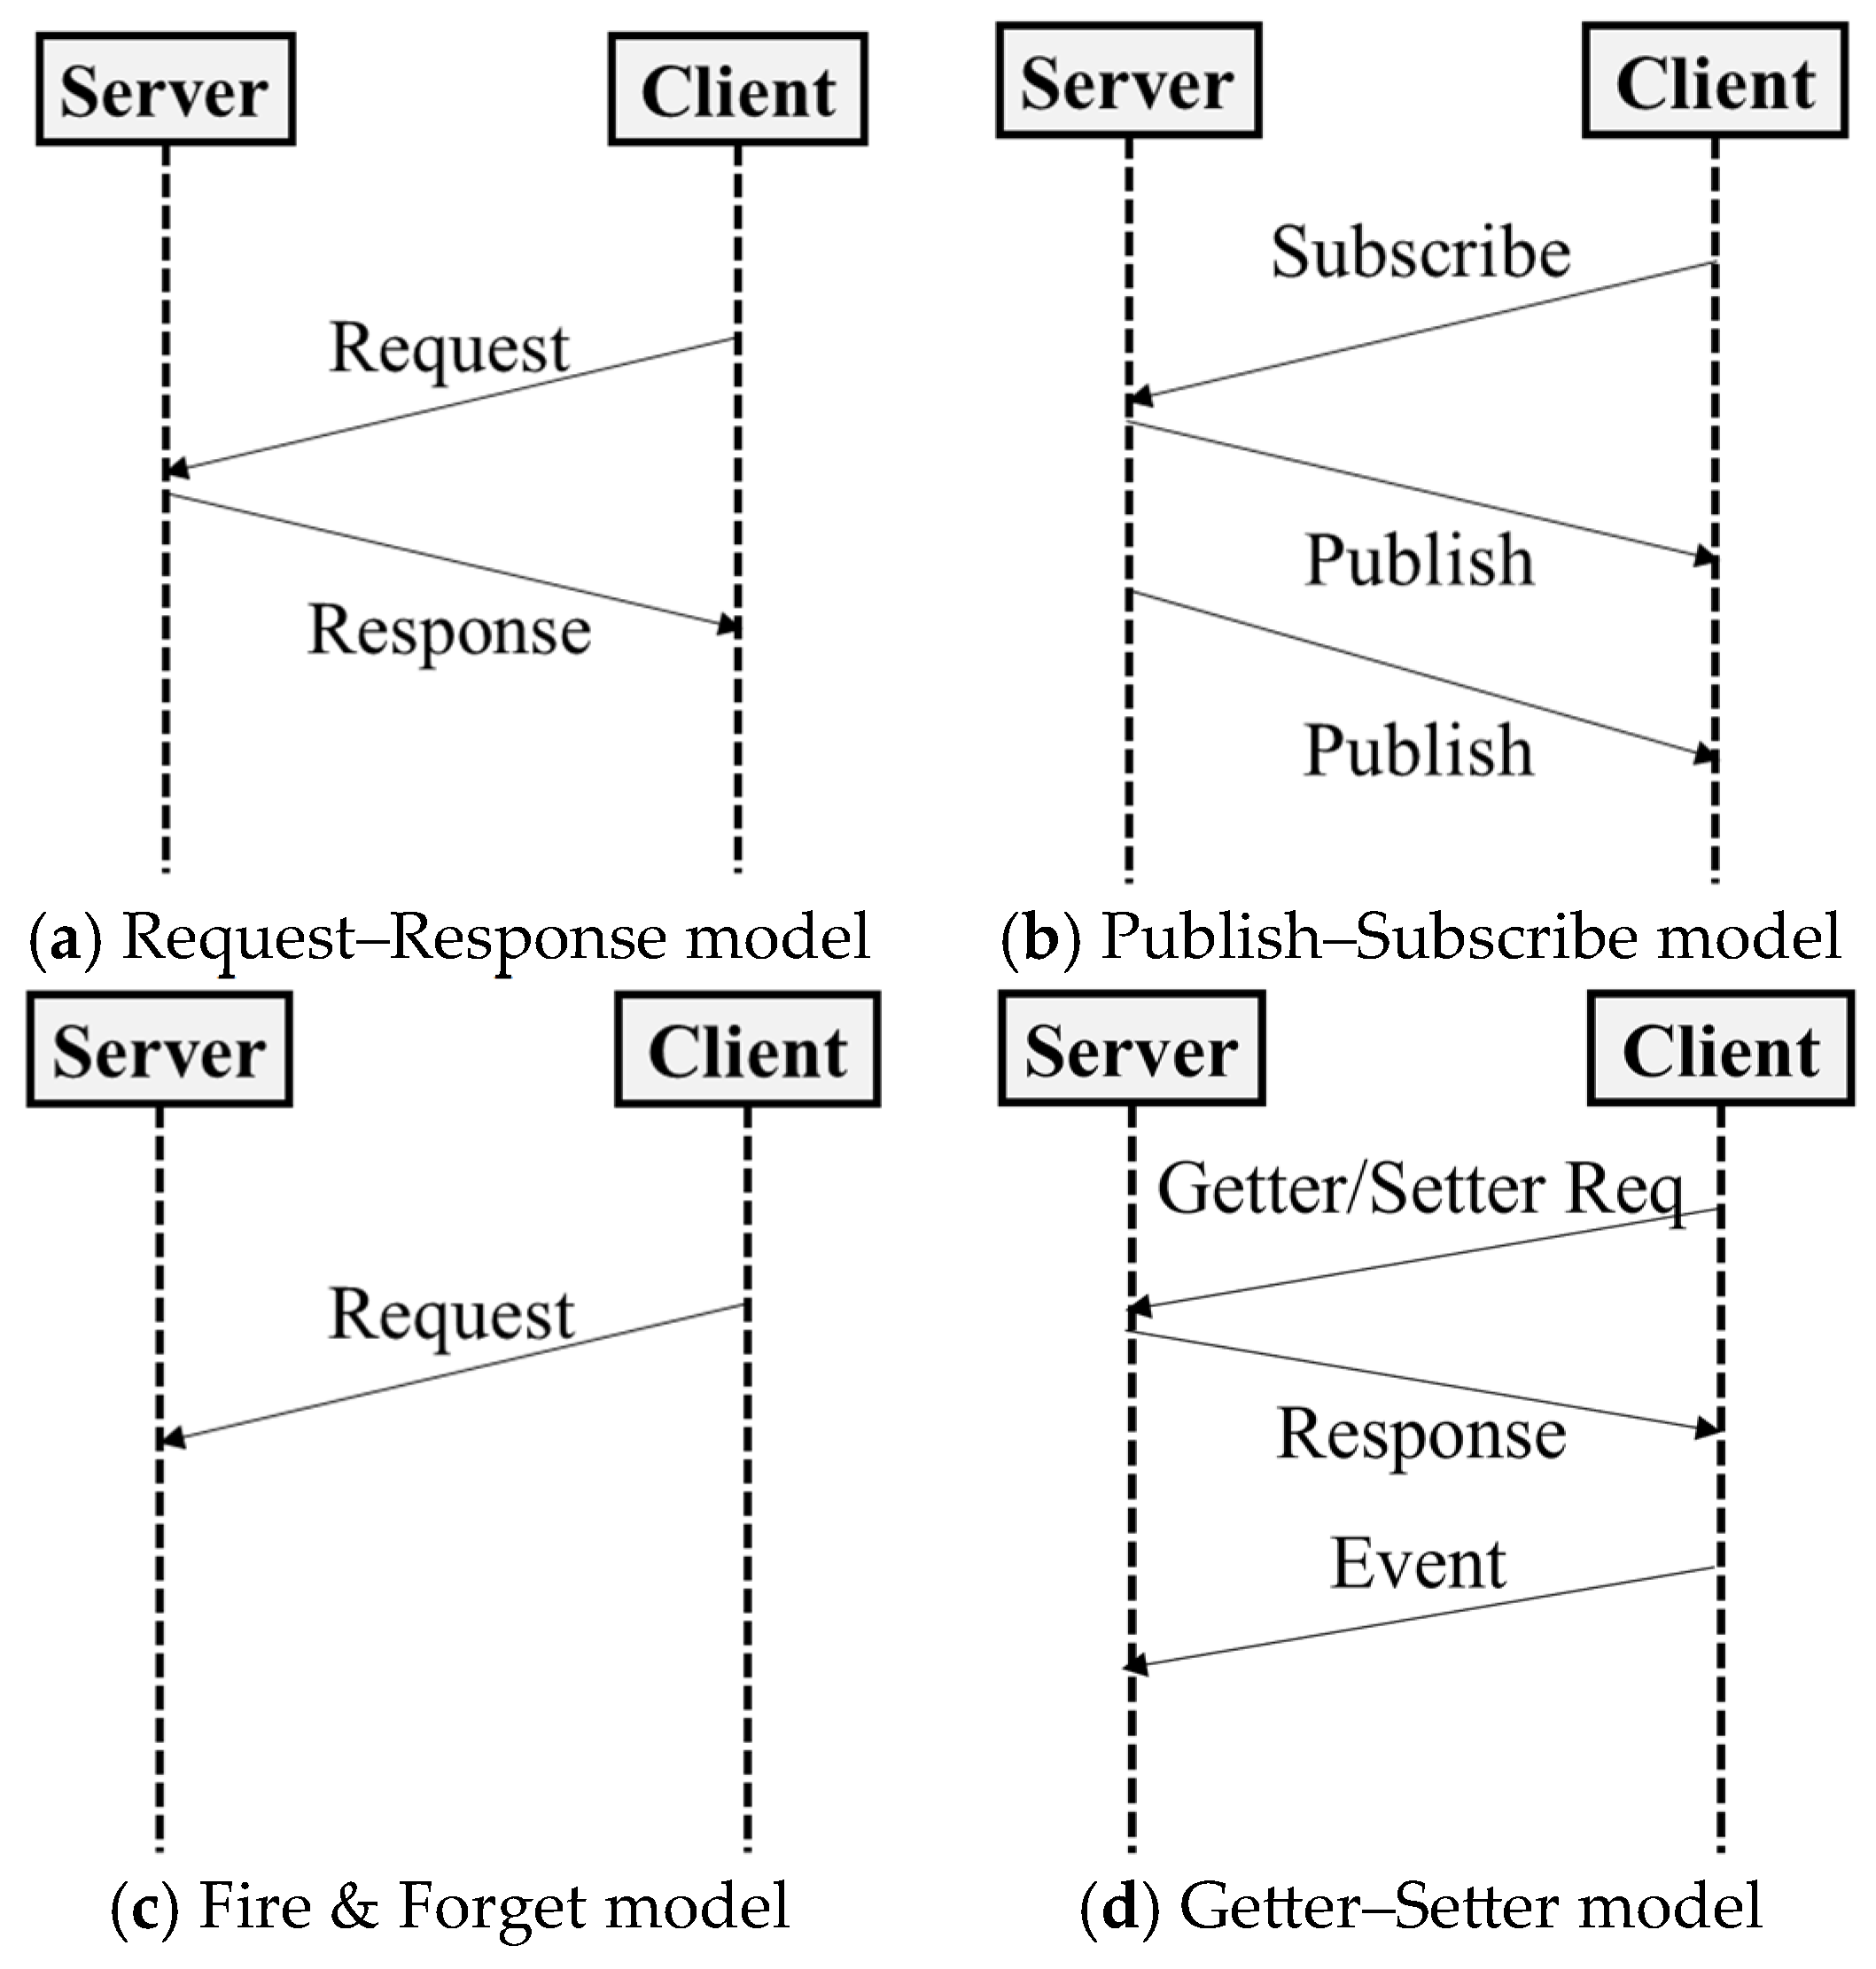
SOME/IP supports four primary in-vehicle communication patterns: publish–subscribe, request–response, fire-and-forget, and getter/setter interactions. In the request–response communication illustrated in
Figure 1a, the client sends a request message to the server, which responds with a unicast response message. A request message is a client’s request to either retrieve data or instruct a task, while a response message is the server’s reply that provides the result of processing the client’s request. For instance, a client, such as the Central Control Unit (CCU), requests the current temperature from a specific part of the vehicle, like the rear-seat air conditioning unit. The client sends a request message asking for the temperature, and the server processes this request and responds with the current temperature.
The publish–subscribe communication illustrated in
Figure 1b is based on events that occur dynamically. The publisher generates event data and ensures that the information is delivered to the subscribers whenever an event occurs.
In in-vehicle SOME/IP networks, the most commonly used communication pattern is typically publish–subscribe, meaning event-based publishing and subscribing. This is because most in-vehicle data naturally appear as periodic or asynchronous signals, such as sensor readings, state changes, and notification events, so it is efficient for a server to continuously publish events while multiple ECUs subscribe and receive them.
In the fire and forget communication illustrated in
Figure 1c, the client sends a request message to the server, but unlike in request–response communication, the server does not send a response back to the client.
The getter/setter communication in
Figure 1d manages state values, such as driving mode, temperature, and headlight status, allowing clients to either retrieve the current state or update it. In this model, the getter message enables the client to request the current state value from the server, while the setter message allows the client to modify the state by sending new values to the server.
In addition to SOME/IP message exchange, vehicles often use SOME/IP Service Discovery (SOME/IP-SD). SOME/IP-SD discovers available services and manages subscriptions for event-based communication by announcing and finding services and setting up event-group subscriptions when needed.
3.2. SOME/IP Attack Scenarios
SOME/IP lacks essential security features, including authentication, encryption, and data integrity verification. These weaknesses make it vulnerable to various cyberattacks. To highlight the practical risks arising from these vulnerabilities, representative attack scenarios are introduced: DoS, Message Drop, Fuzzy, MitM. These attacks demonstrate how protocol-level weaknesses in SOME/IP can be exploited to disrupt communication or compromise system behavior. The attack simulation environment used in this study is described in detail in
Section 4, and each attack scenario is briefly explained in the following paragraphs.
DoS Attack Scenario: The attacker overwhelms the service provider by injecting a large volume of event messages at extremely short intervals. These messages are formatted to appear legitimate but are used to exhaust processing resources, delay normal operations, and degrade the performance of other communication in the network. Many electronic control units that have registered to receive event messages may be affected by a denial-of-service attack.
Fuzzy Attack Scenario: In this scenario, the attacker initiates a valid session and then transmits protocol-conformant messages with intentionally malformed payloads, such as overly long strings or unexpected data types. These packets are structurally valid but contain anomalous content that might trigger exceptions, crashes, or unstable behavior in the receiving system.
Message Drop Attack Scenario: The attacker drops SOME/IP messages in transit so they never reach the receiver, causing missing updates or failed requests and leading to stale or inconsistent ECU behavior.
Man-in-the-Middle Attack Scenario: The attacker impersonates a valid service by manipulating service discovery messages, leading a client to establish a session with the wrong endpoint. Once positioned between the client and the legitimate service, the attacker intercepts and alters messages in transit. This enables various sub-attacks such as injecting fake error messages, dropping requests, delaying responses, or responding with forged data.
4. SOME/IP Benign and Attack Traffic Simulation
This section describes the SOME/IP normal and attack simulation environment and the dataset construction used in this study. It provides the context needed to interpret the evaluation results presented.
4.1. Simulation Data Collection
Real-world SOME/IP traces from production vehicles are rarely publicly available and collecting them in the field is costly and difficult to reproduce. Therefore, we construct a simulation-based testbed and generate traffic under controlled and repeatable conditions. The simulation was conducted on Ubuntu Linux, and we used the open-source vSomeIP library [
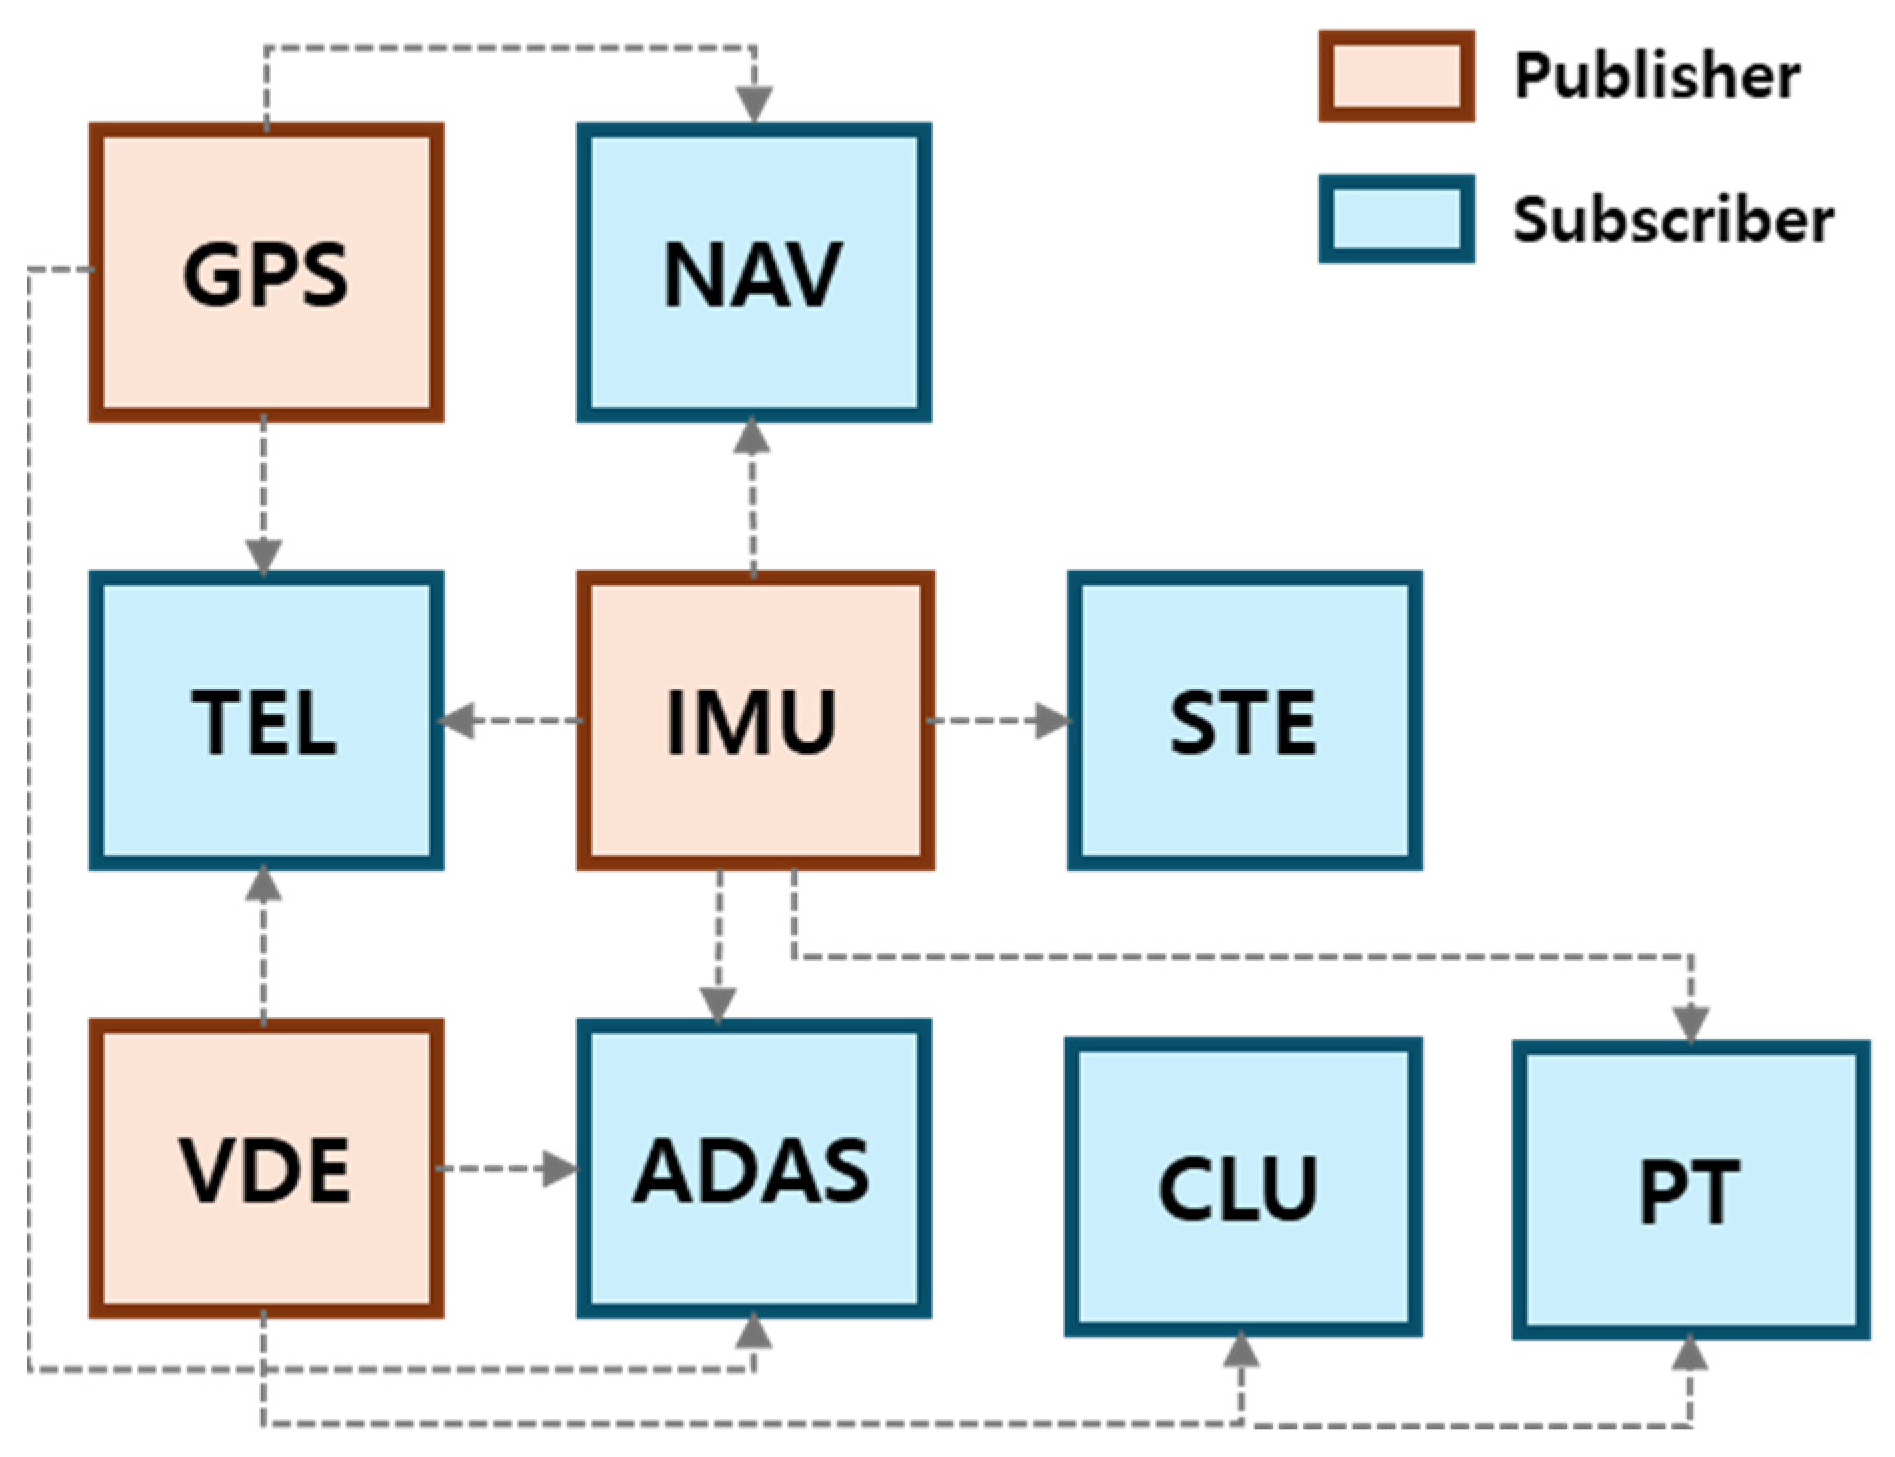
42] to implement ECUs and to realize SOME/IP and SOME/IP-SD communication. As shown in
Figure 2, the simulated in-vehicle SOME/IP network consists of nine ECUs: ADAS (Advanced Driver Assistance System), CLU (Cluster), GPS Sensor, IMU (Inertial Measurement Unit) Sensor, NAV (Navigation), PT (Powertrain), STE (Steering), TEL (Telematics), and VDE (Vehicle Dynamics). The ECUs are categorized into data providers and consumers. In our setup, the GPS Sensor ECU, IMU Sensor ECU, and VDE act as data providers, while the remaining ECUs are configured as consumers.
To emulate realistic driving-related signals, the providers read sensor measurements from a public driving dataset [
43]. These signals are supplied to each provider ECU according to its role, and selected values are transmitted to consumer ECUs via SOME/IP communication patterns supported by the service interfaces (e.g., publish–subscribe notifications and request–response methods). The following subsections,
Section 4.1.1,
Section 4.1.2,
Section 4.1.3,
Section 4.1.4 and
Section 4.1.5, describe the normal SOME/IP communication flow and the four representative attack scenarios used to generate labeled traffic.
4.1.1. Normal SOME/IP Simulation
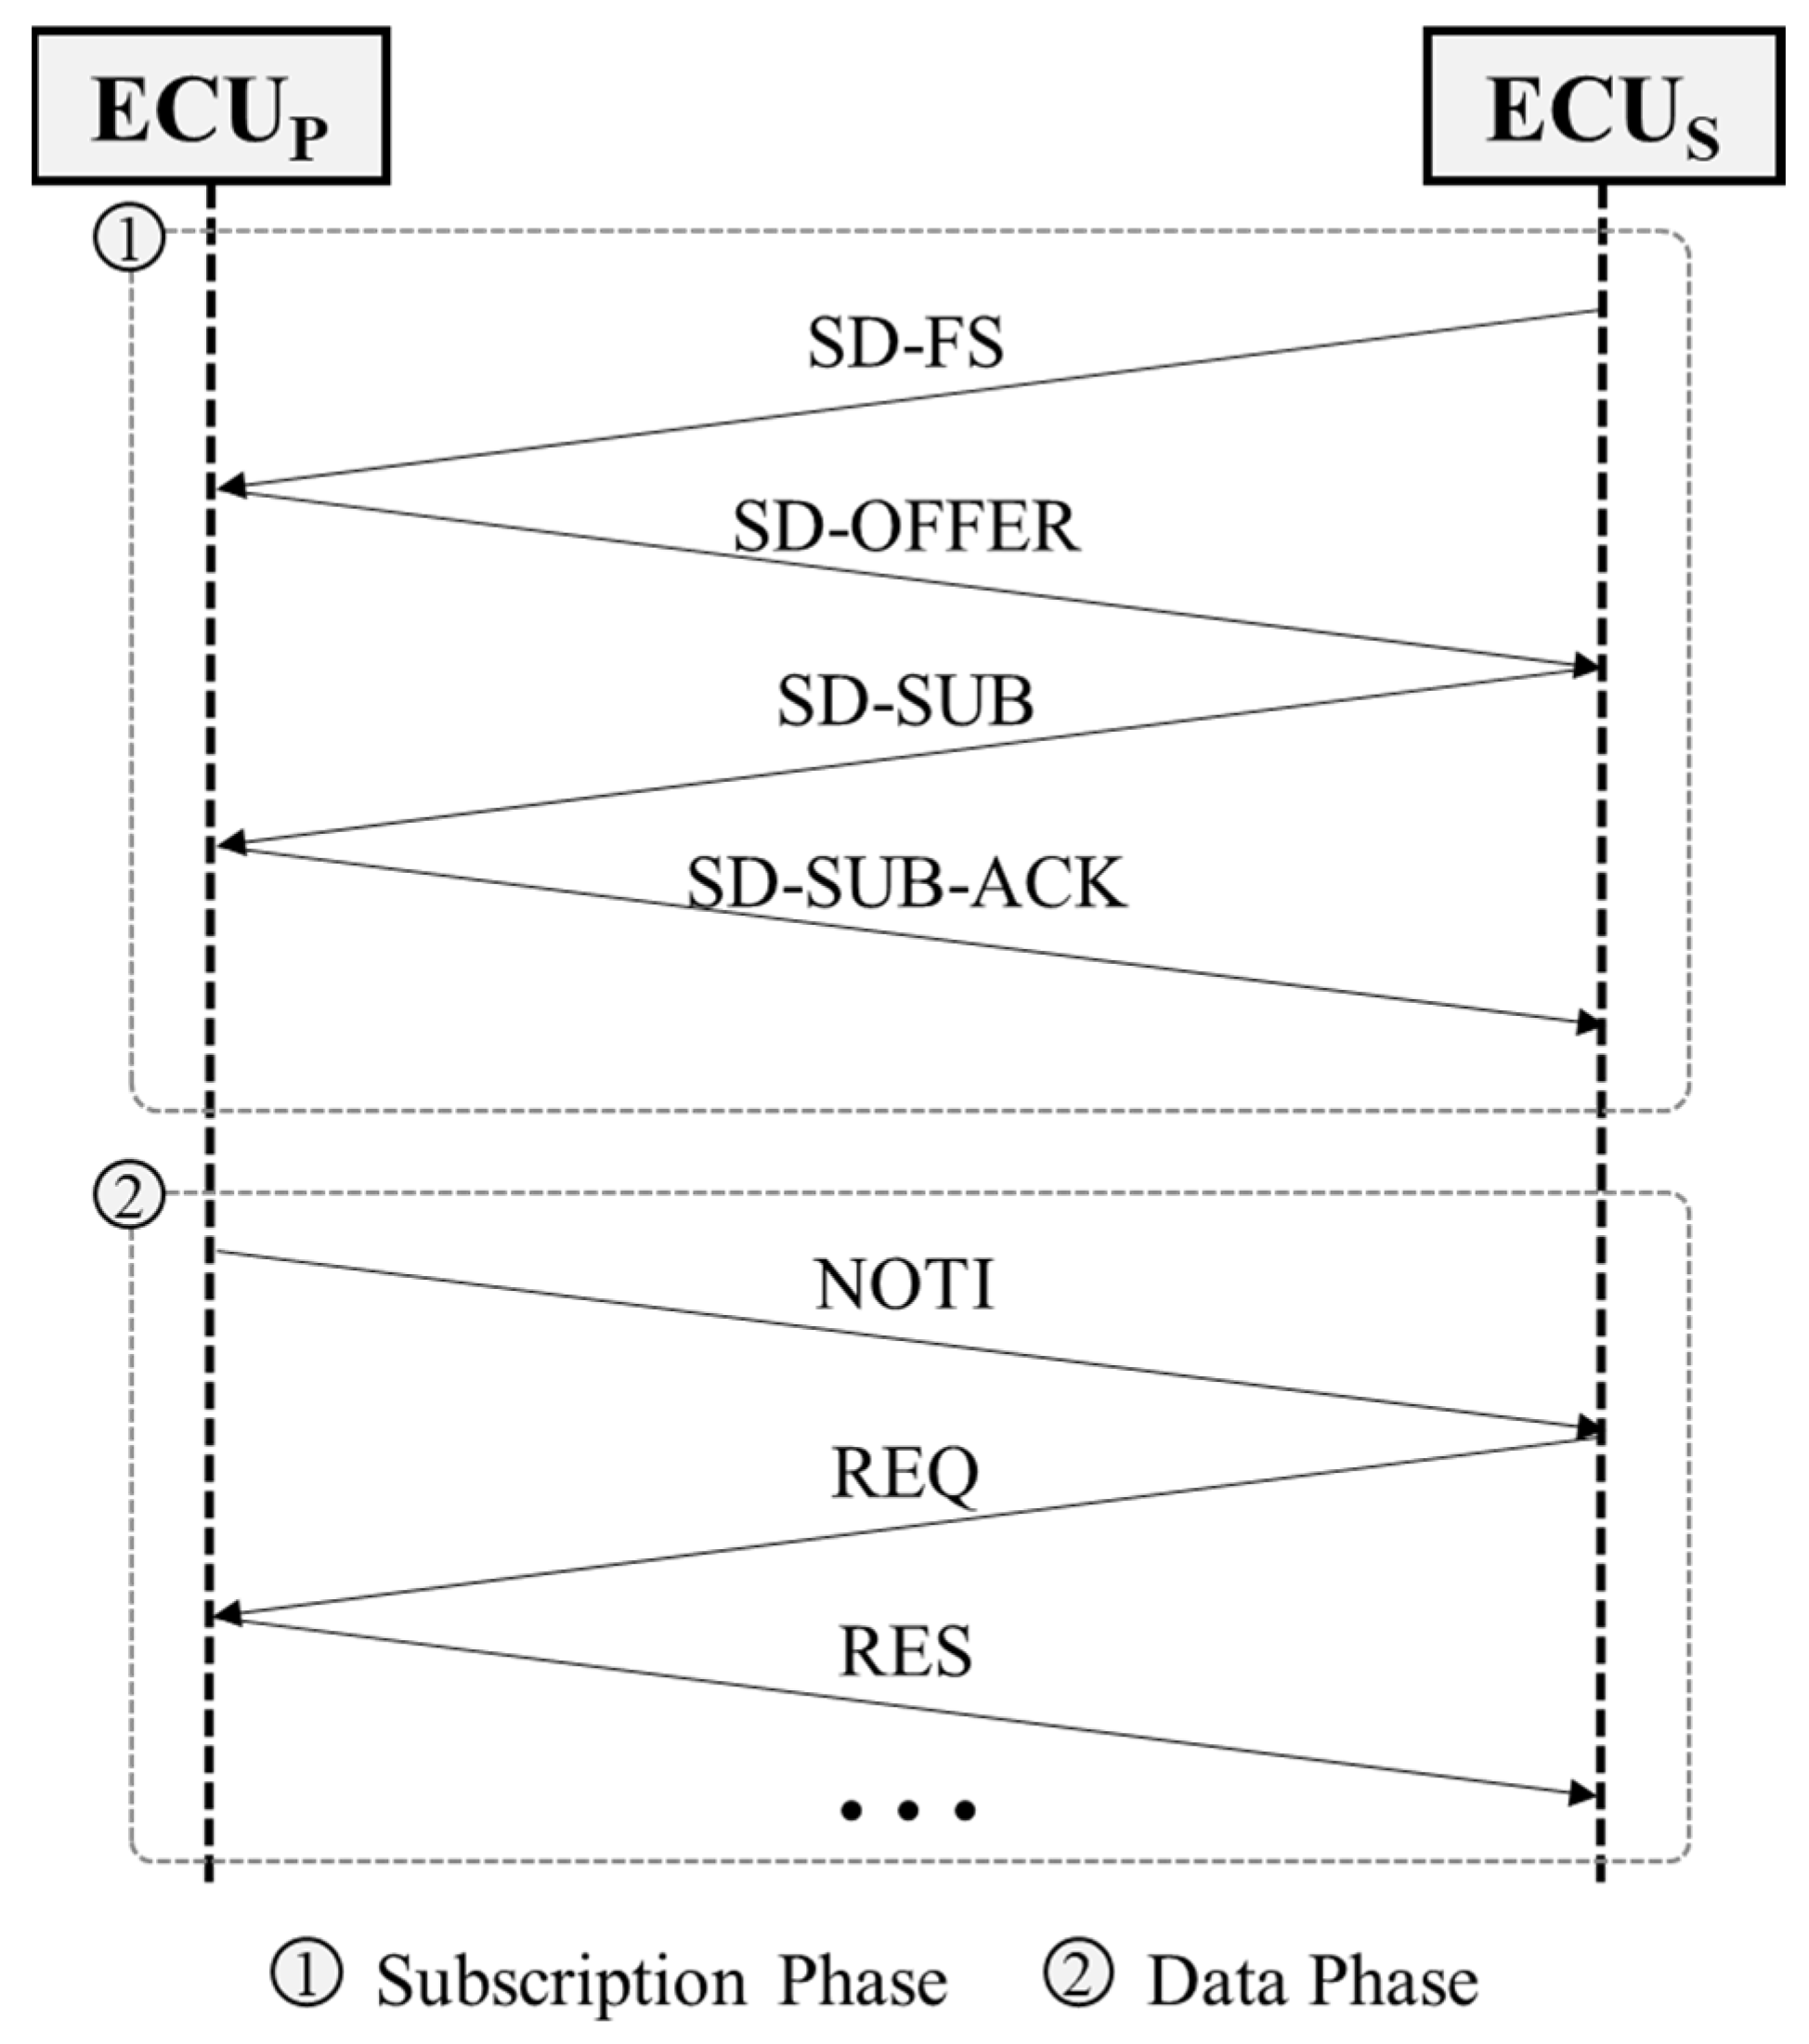
Figure 3 illustrates the normal communication flow in our SOME/IP-based in-vehicle network simulation. The diagram shows the interaction between a service provider ECU and one or more service consumer ECUs. In our testbed, the traffic is generated primarily under the publish–subscribe model because many in-vehicle data are naturally delivered as periodic or event-driven notifications, and multiple ECUs may subscribe to the same stream. During the service discovery and subscription phase, the provider announces availability by sending OfferService entries that describe its service, instance, and event group information. Consumers search by sending FindService entries and learn provider details from service discovery replies that carry matching entries and options. Each consumer then expresses interest by sending a SubscribeEventgroup entry, and the provider confirms with a SubscribeEventgroupAck entry. After subscriptions are established, the data phase begins. The provider produces application data and transmits it as SOME/IP Notification messages to the subscribed event groups; consumers receive these notifications and pass them to their application logic.
Although our simulation setup focuses on publish–subscribe notifications, the same simulated environment can also realize the other communication models in
Figure 1. Request–response can be enabled by exposing method calls and responses over unicast, fire and forget can be realized by one-way method invocations without responses, and getter/setter can be modeled as state access and update operations implemented as methods with structured payloads. In all cases, the service discovery phase remains the prerequisite that binds endpoints and enables the subsequent message exchange.
4.1.2. DoS Attack Simulation
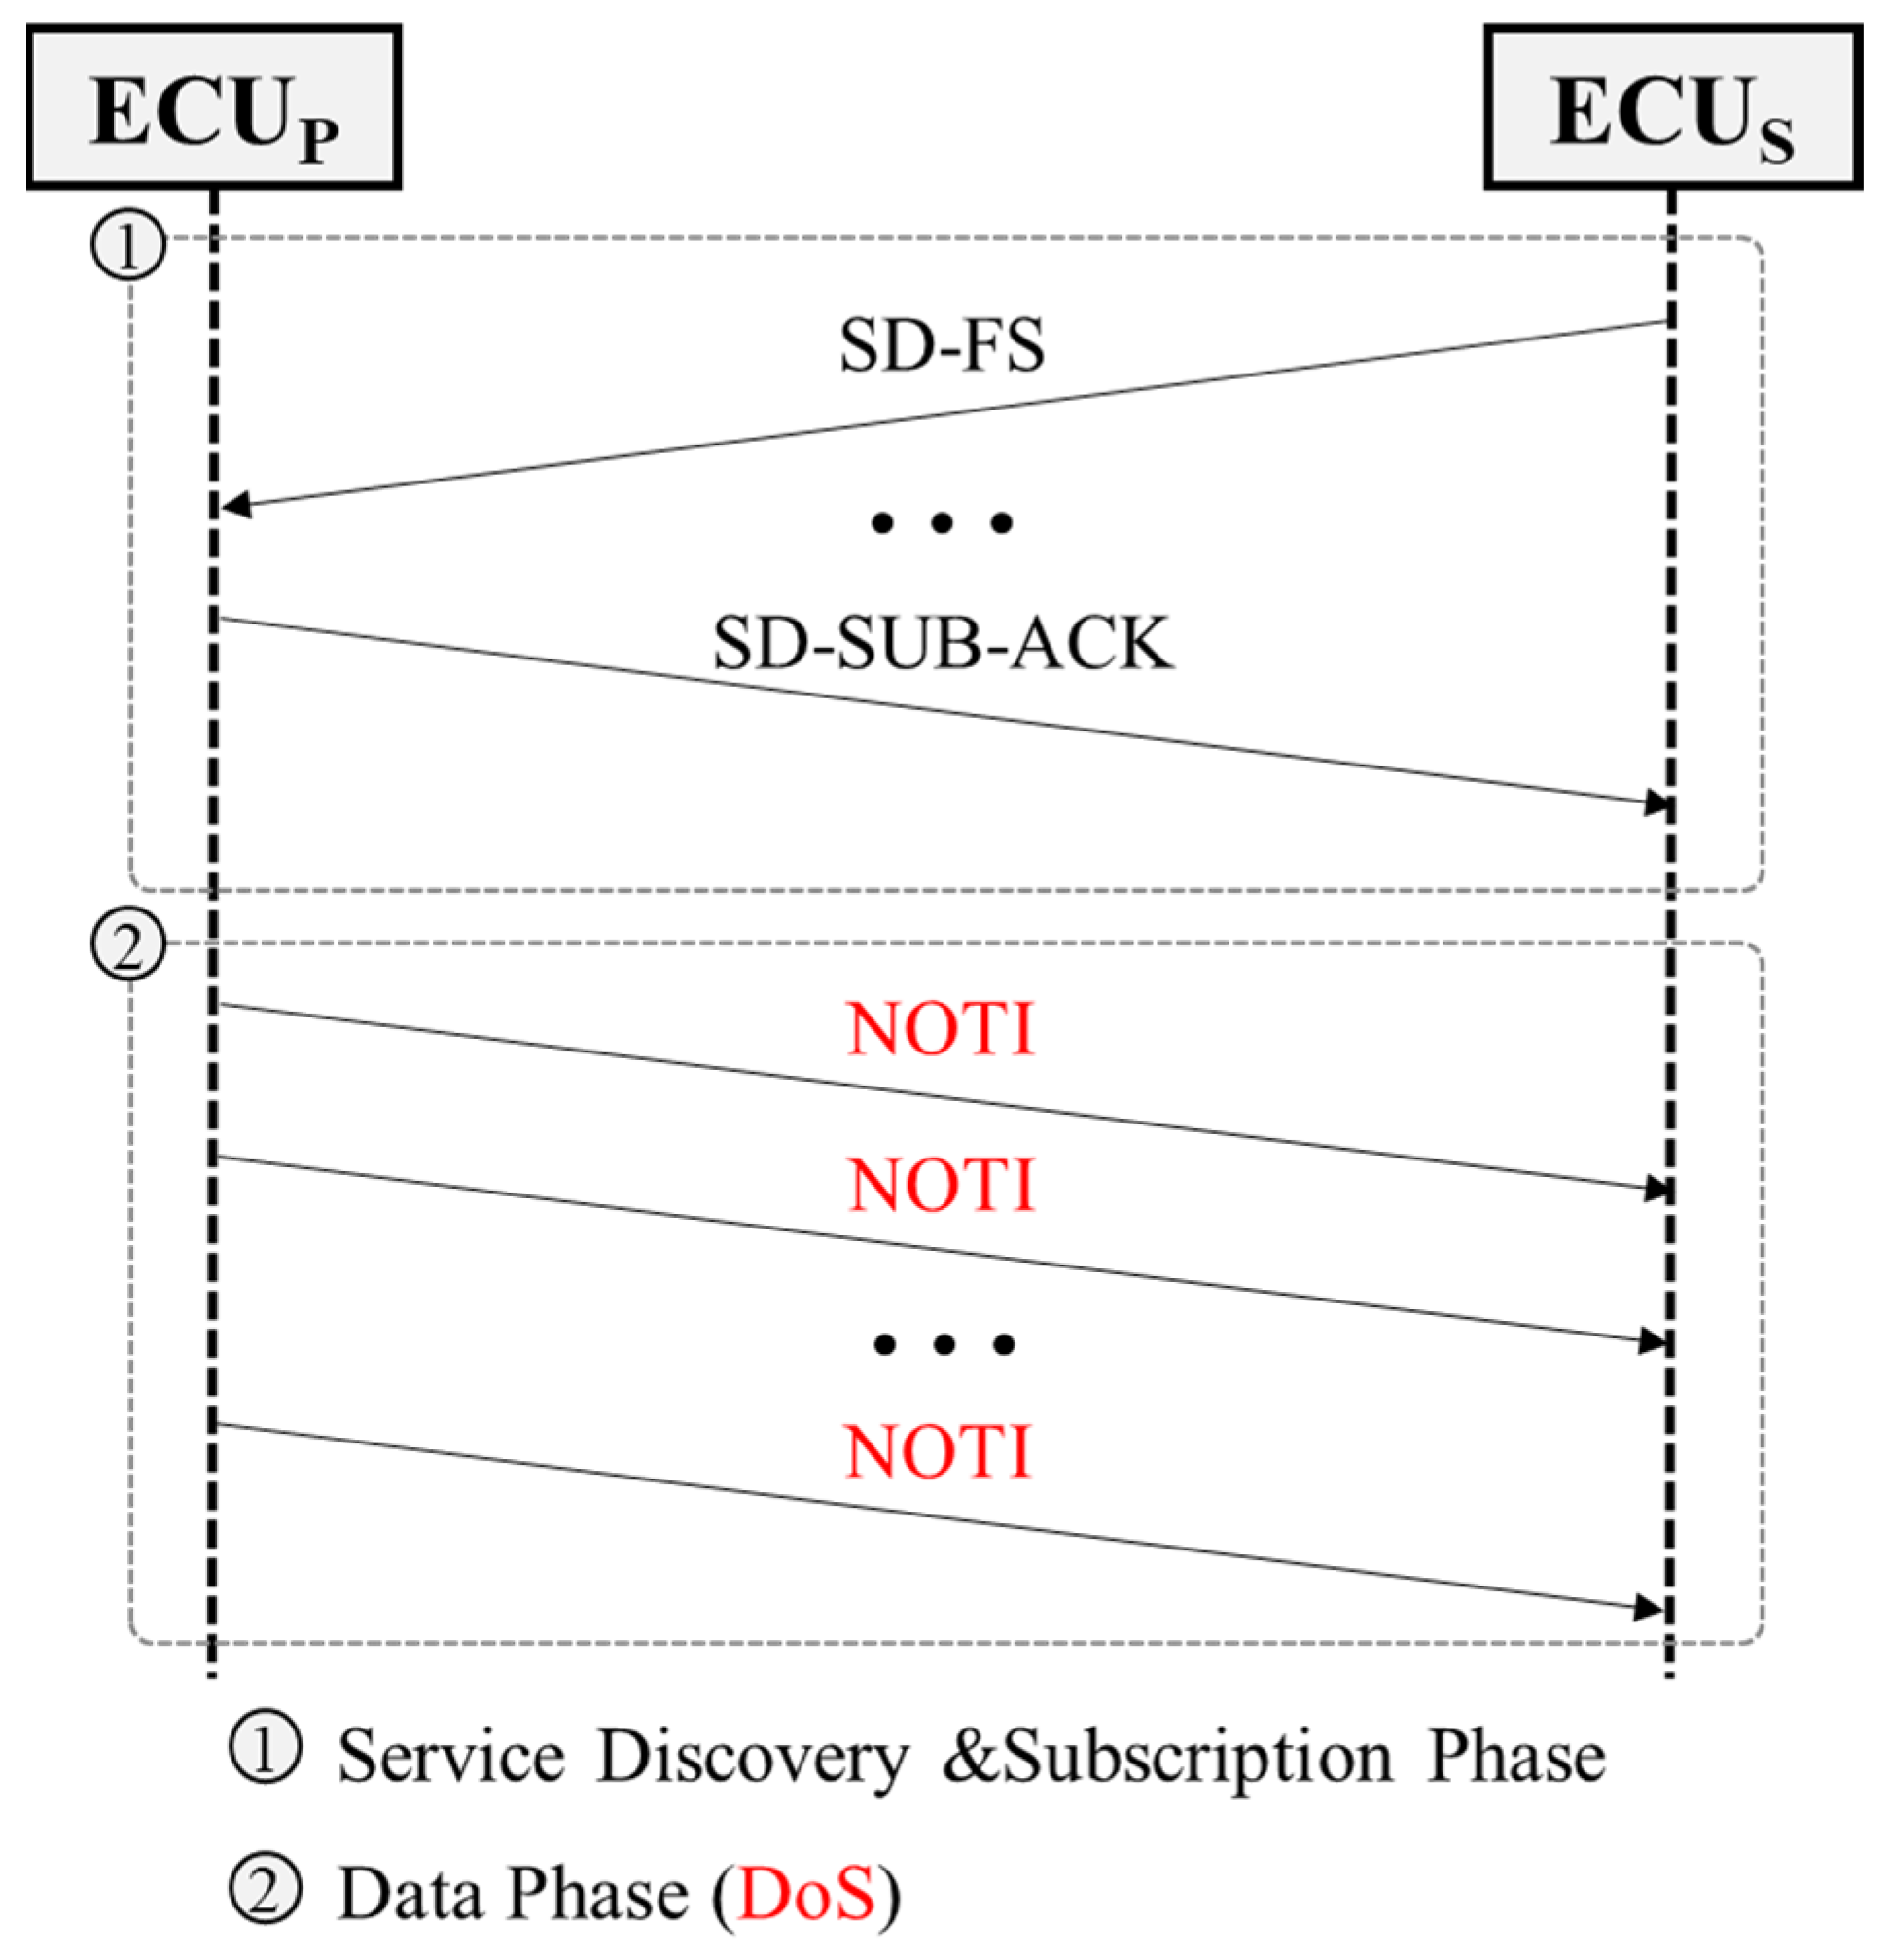
Figure 4 illustrates the communication flow of a denial-of-service attack in our SOME/IP-based simulation. In the publish–subscribe communication model, we implement DoS by violating the nominal timing of event notifications and generating bursty notification streams at an abnormally high rate, and we assume that there is a compromised ECU in the network. After the network starts triggering, the compromised ECU uses service discovery to announce service and event groups, allowing consumers to establish subscriptions as usual. Once the subscription state is established, the compromised ECU transmits a rapid burst of randomized event notifications outside the intended event period, thereby creating an overload condition. This setting causes congestion and latency accumulation in the transport and receiver pipeline.
The same DoS attack can also be simulated under request–response by issuing bursts of method requests, under fire and forget by sending one-way invocations at an excessive rate, and under getter/setter by repeatedly querying or updating state at a frequency far above normal. This is feasible because all four SOME/IP communication models ultimately generate SOME/IP messages that consume shared network bandwidth and ECU processing resources, so the increased traffic in any model can trigger the same resource-exhaustion and queuing effects. In other words, while publish–subscribe is the primary target in our baseline, the core mechanisms are traffic amplification and resource exhaustion, and they are not limited to a single communication model.
4.1.3. Fuzzy Attack Simulation
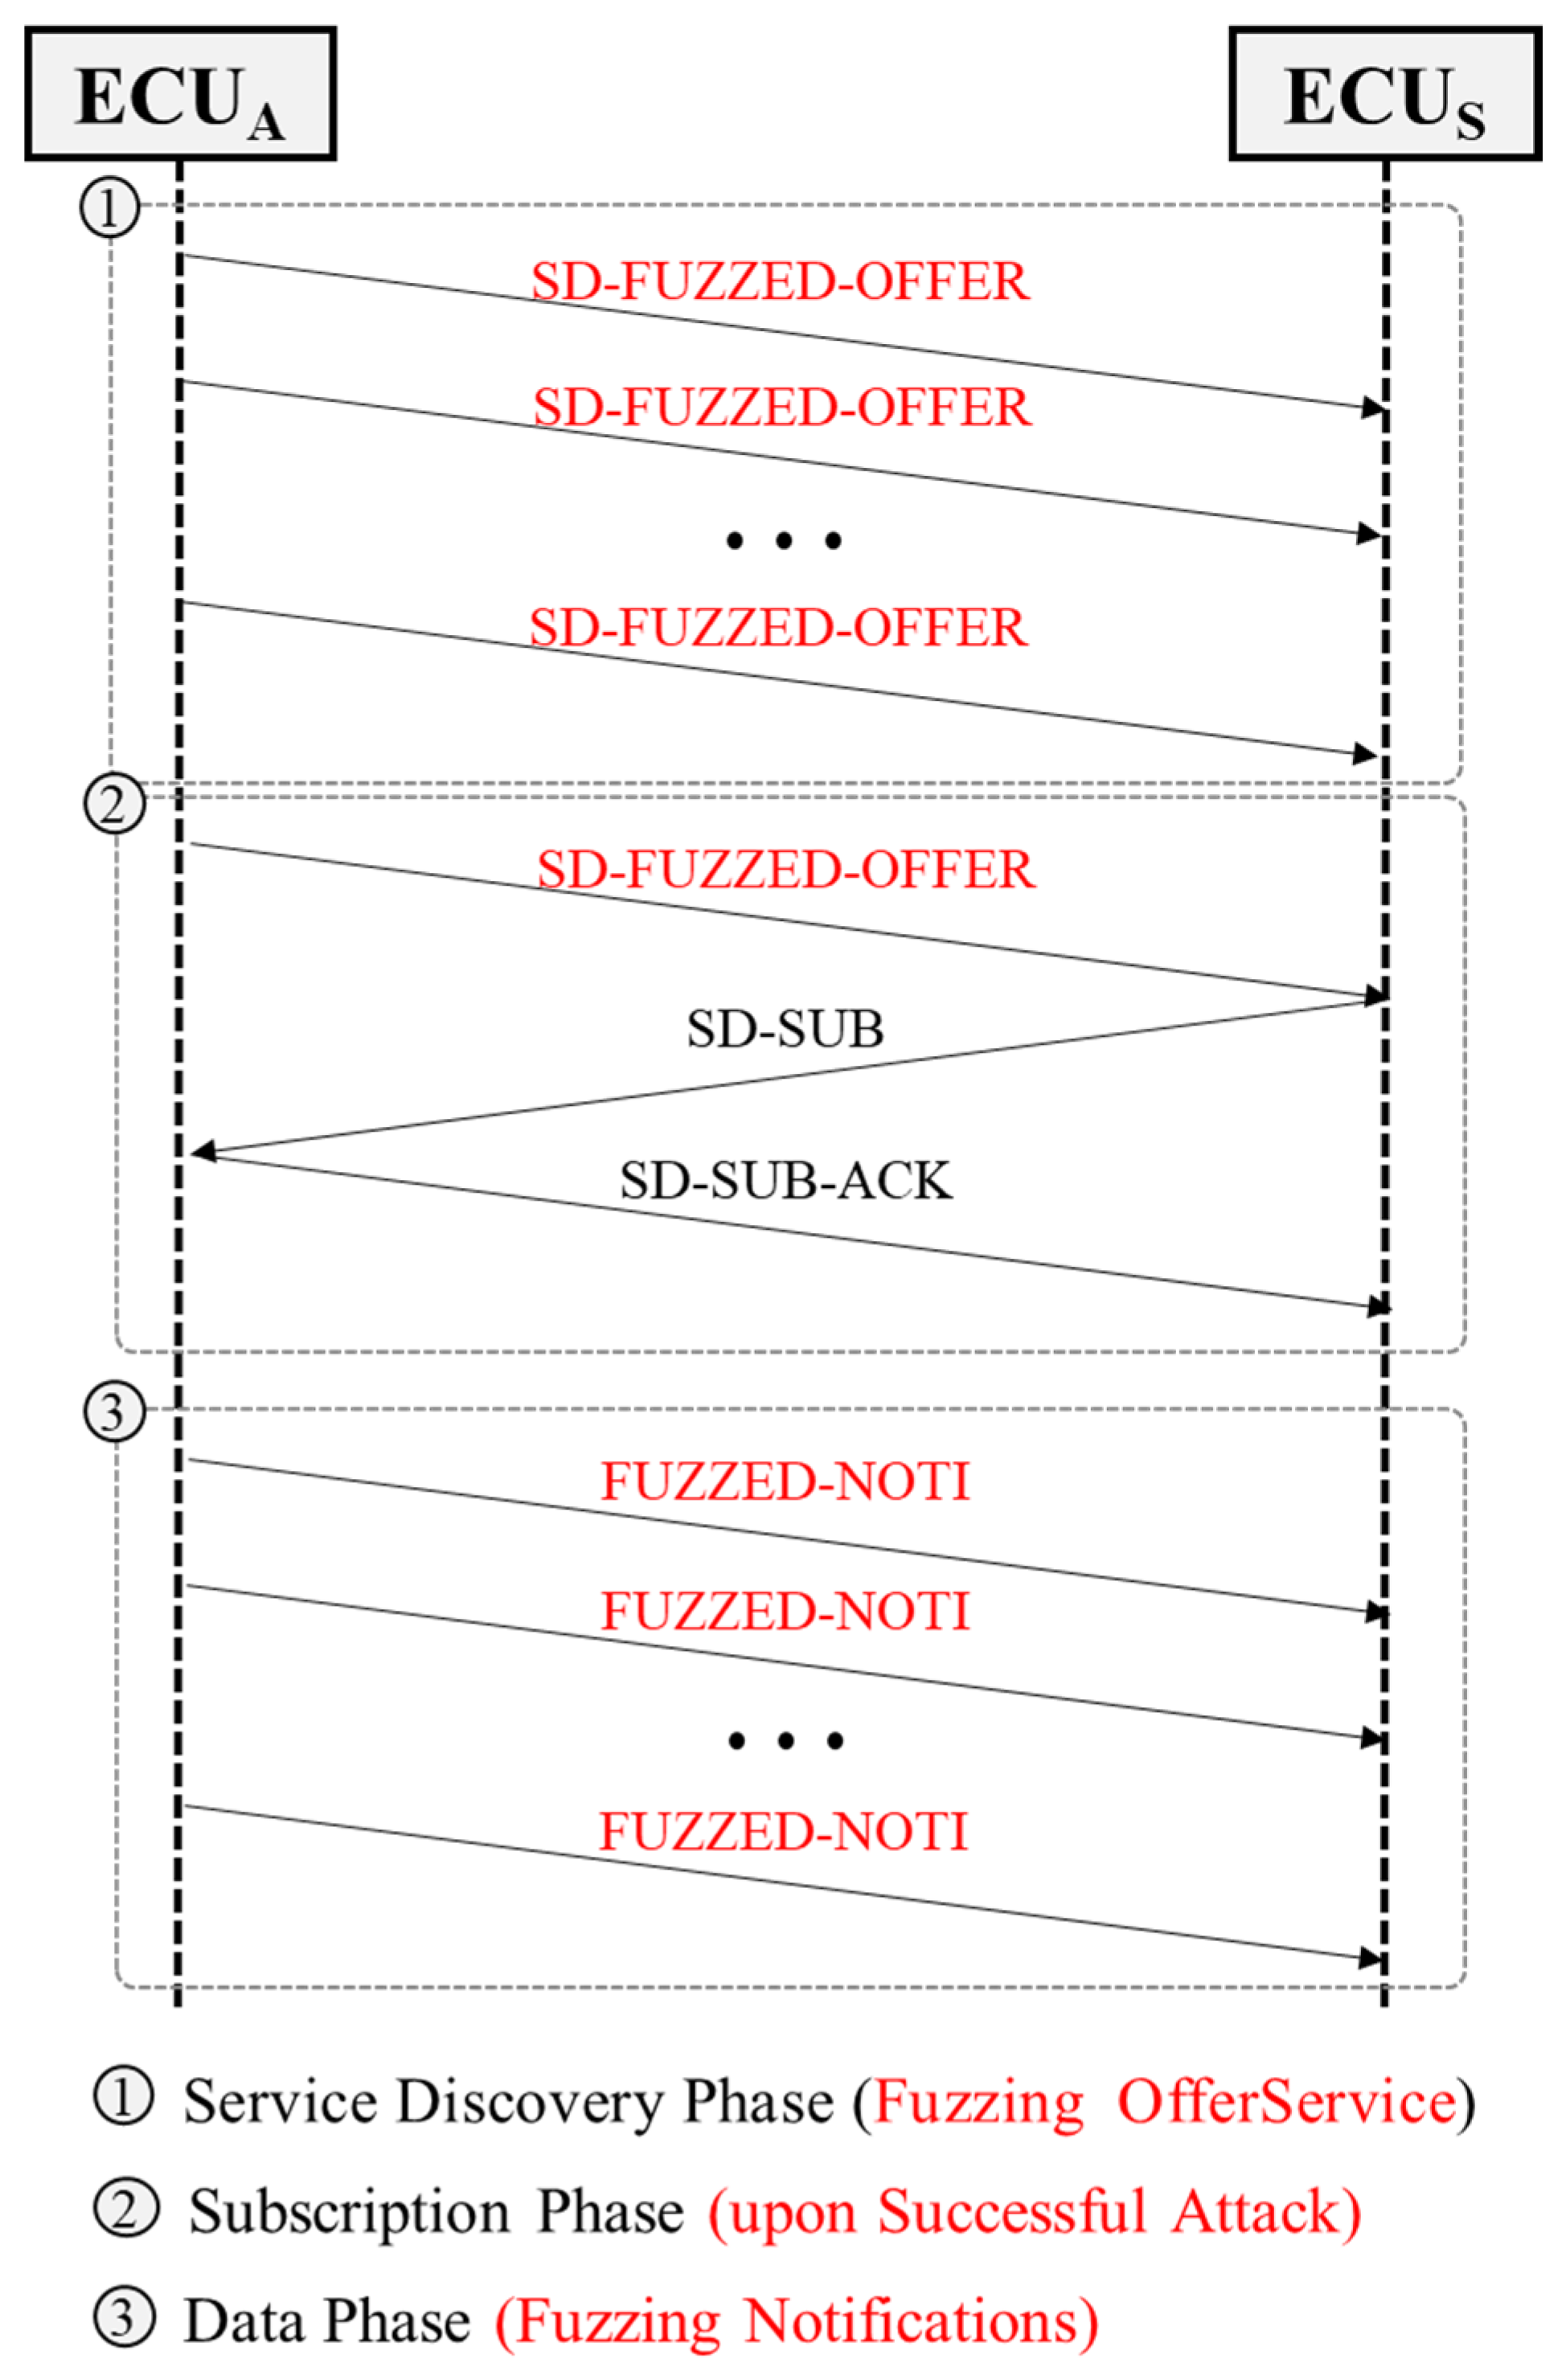
Figure 5 illustrates the communication flow of a fuzzing attack in our SOME/IP-based simulation. First, during service discovery, the attacker continuously sends OfferService entries while varying identifiers, such as service, instance, and event group values, over a wide range. This probes how discovery caches and matching logic behave under unusual but syntactically valid combinations and can reveal edge cases in how endpoints and subscriptions are formed. Next, during message exchange, the attacker maintains a plausible interface and transmits protocol-conformant but anomalous payloads in SOME/IP messages. In the publish–subscribe baseline, these are delivered as notifications, allowing us to trace how receiver parsing, validation, and exception handling respond to unexpected content and payload structure.
Beyond publish–subscribe, the same payload-focused fuzzing is directly applicable to request–response methods, fire and forget invocations, and getter/setter operations because they all rely on structured payload semantics and identifier consistency. Concretely, each of these models carries typed parameters in the SOME/IP payload and is dispatched using the same service/instance/method identifiers, so malformed field values, boundary cases, and inconsistent IDs can provoke the same parsing and validation failures regardless of the interaction pattern.
4.1.4. Message Drop Attack Simulation
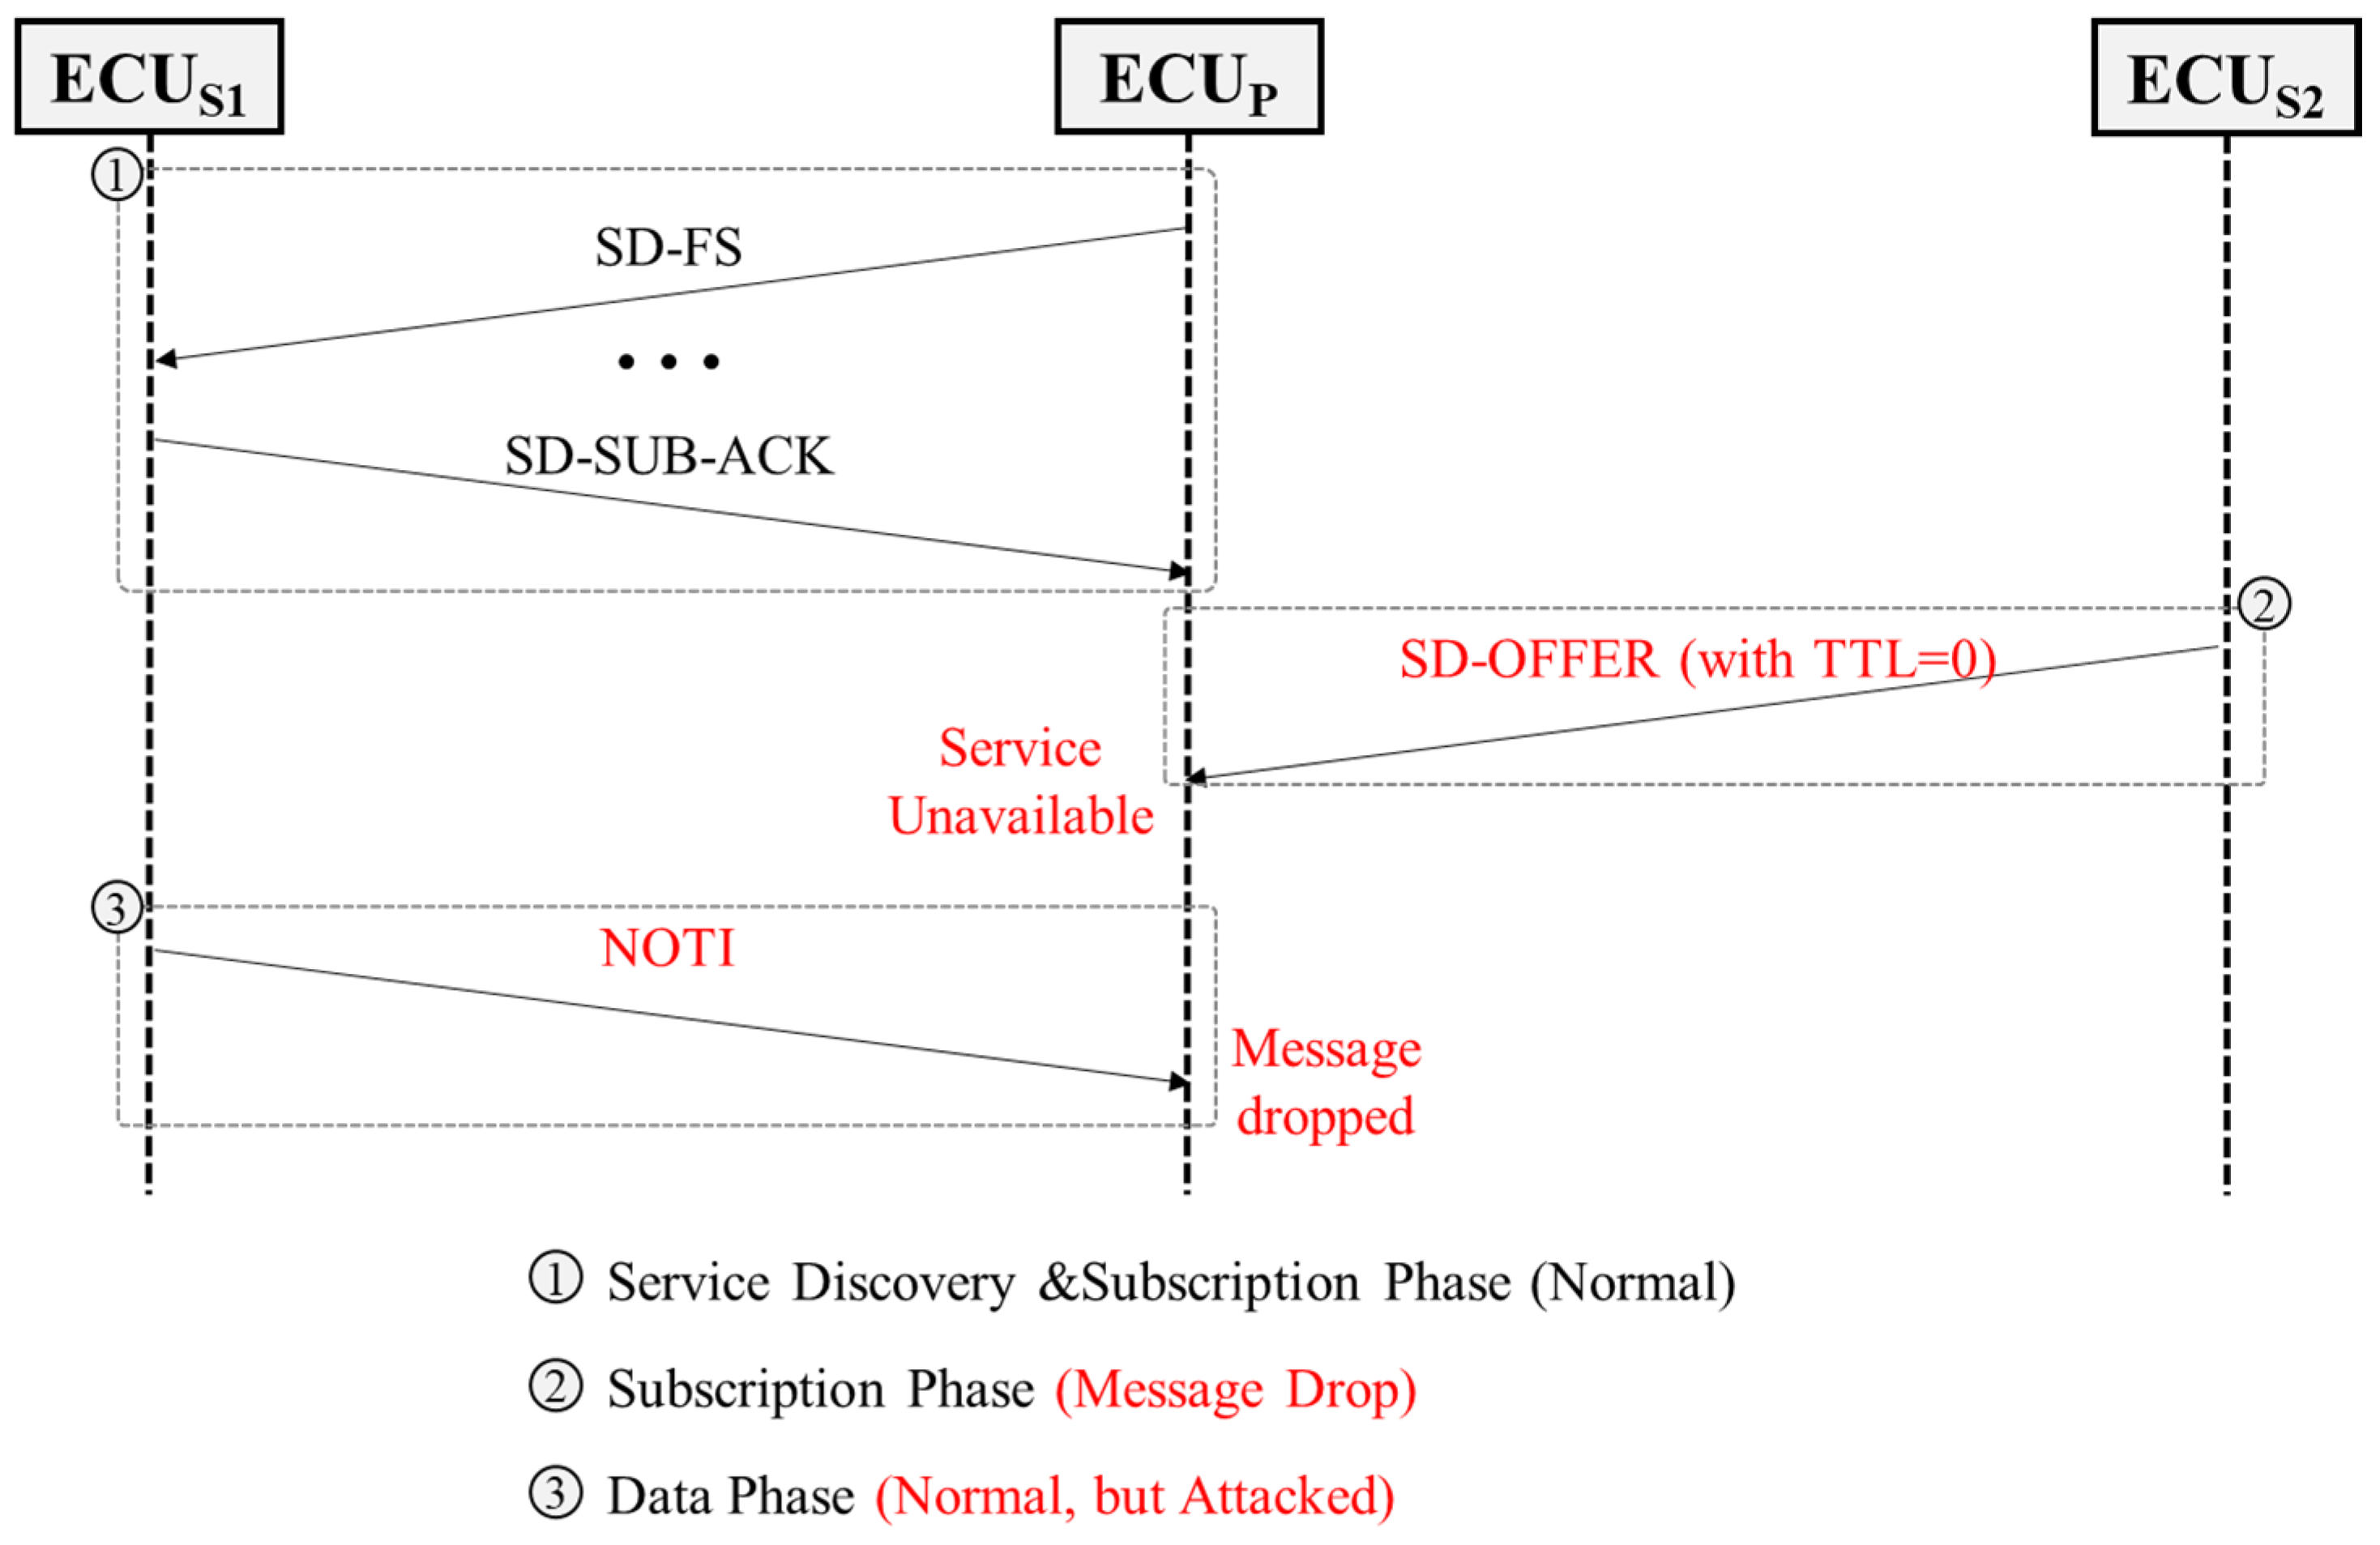
Figure 6 illustrates the communication flow of the message-drop effect in our SOME/IP-based simulation. In our experiments, the message-drop effect is not executed as an independent scenario with separately collected traces; instead, it is introduced as part of the MitM procedure described in
Section 4.1.5. The drop effect is triggered by manipulating SOME/IP Service Discovery traffic so that receivers revoke the availability of the legitimate service instance and tear down the associated subscription state, thereby preventing subsequent notifications from being delivered. Concretely, the attacker forges an SD OfferService entry with a TTL (Time To Live) value of 0, which effectively acts as a StopOffer for the victim service and instance, and unicasts it to the target host. Upon receiving this TTL = 0 OfferService update, consumers invalidate the previously learned service availability and remove the subscription context, including the state established via SubscribeEventgroup. As a result, notifications that would normally be delivered under publish–subscribe no longer reach consumers, causing pauses and interruptions in the notification stream. In our MitM procedure, the drop phase corresponds to the forced StopOffer-induced invalidation and the transition interval before redirection is established.
This message-drop effect can impact any SOME/IP interaction that depends on SOME/IP-SD. Once the service instance is withdrawn from discovery, endpoints may fail to resolve or may time out, leading to failed calls, delivery failures, and repeated retries across request–response, fire and forget, and getter/setter operations.
4.1.5. MitM Attack Simulation
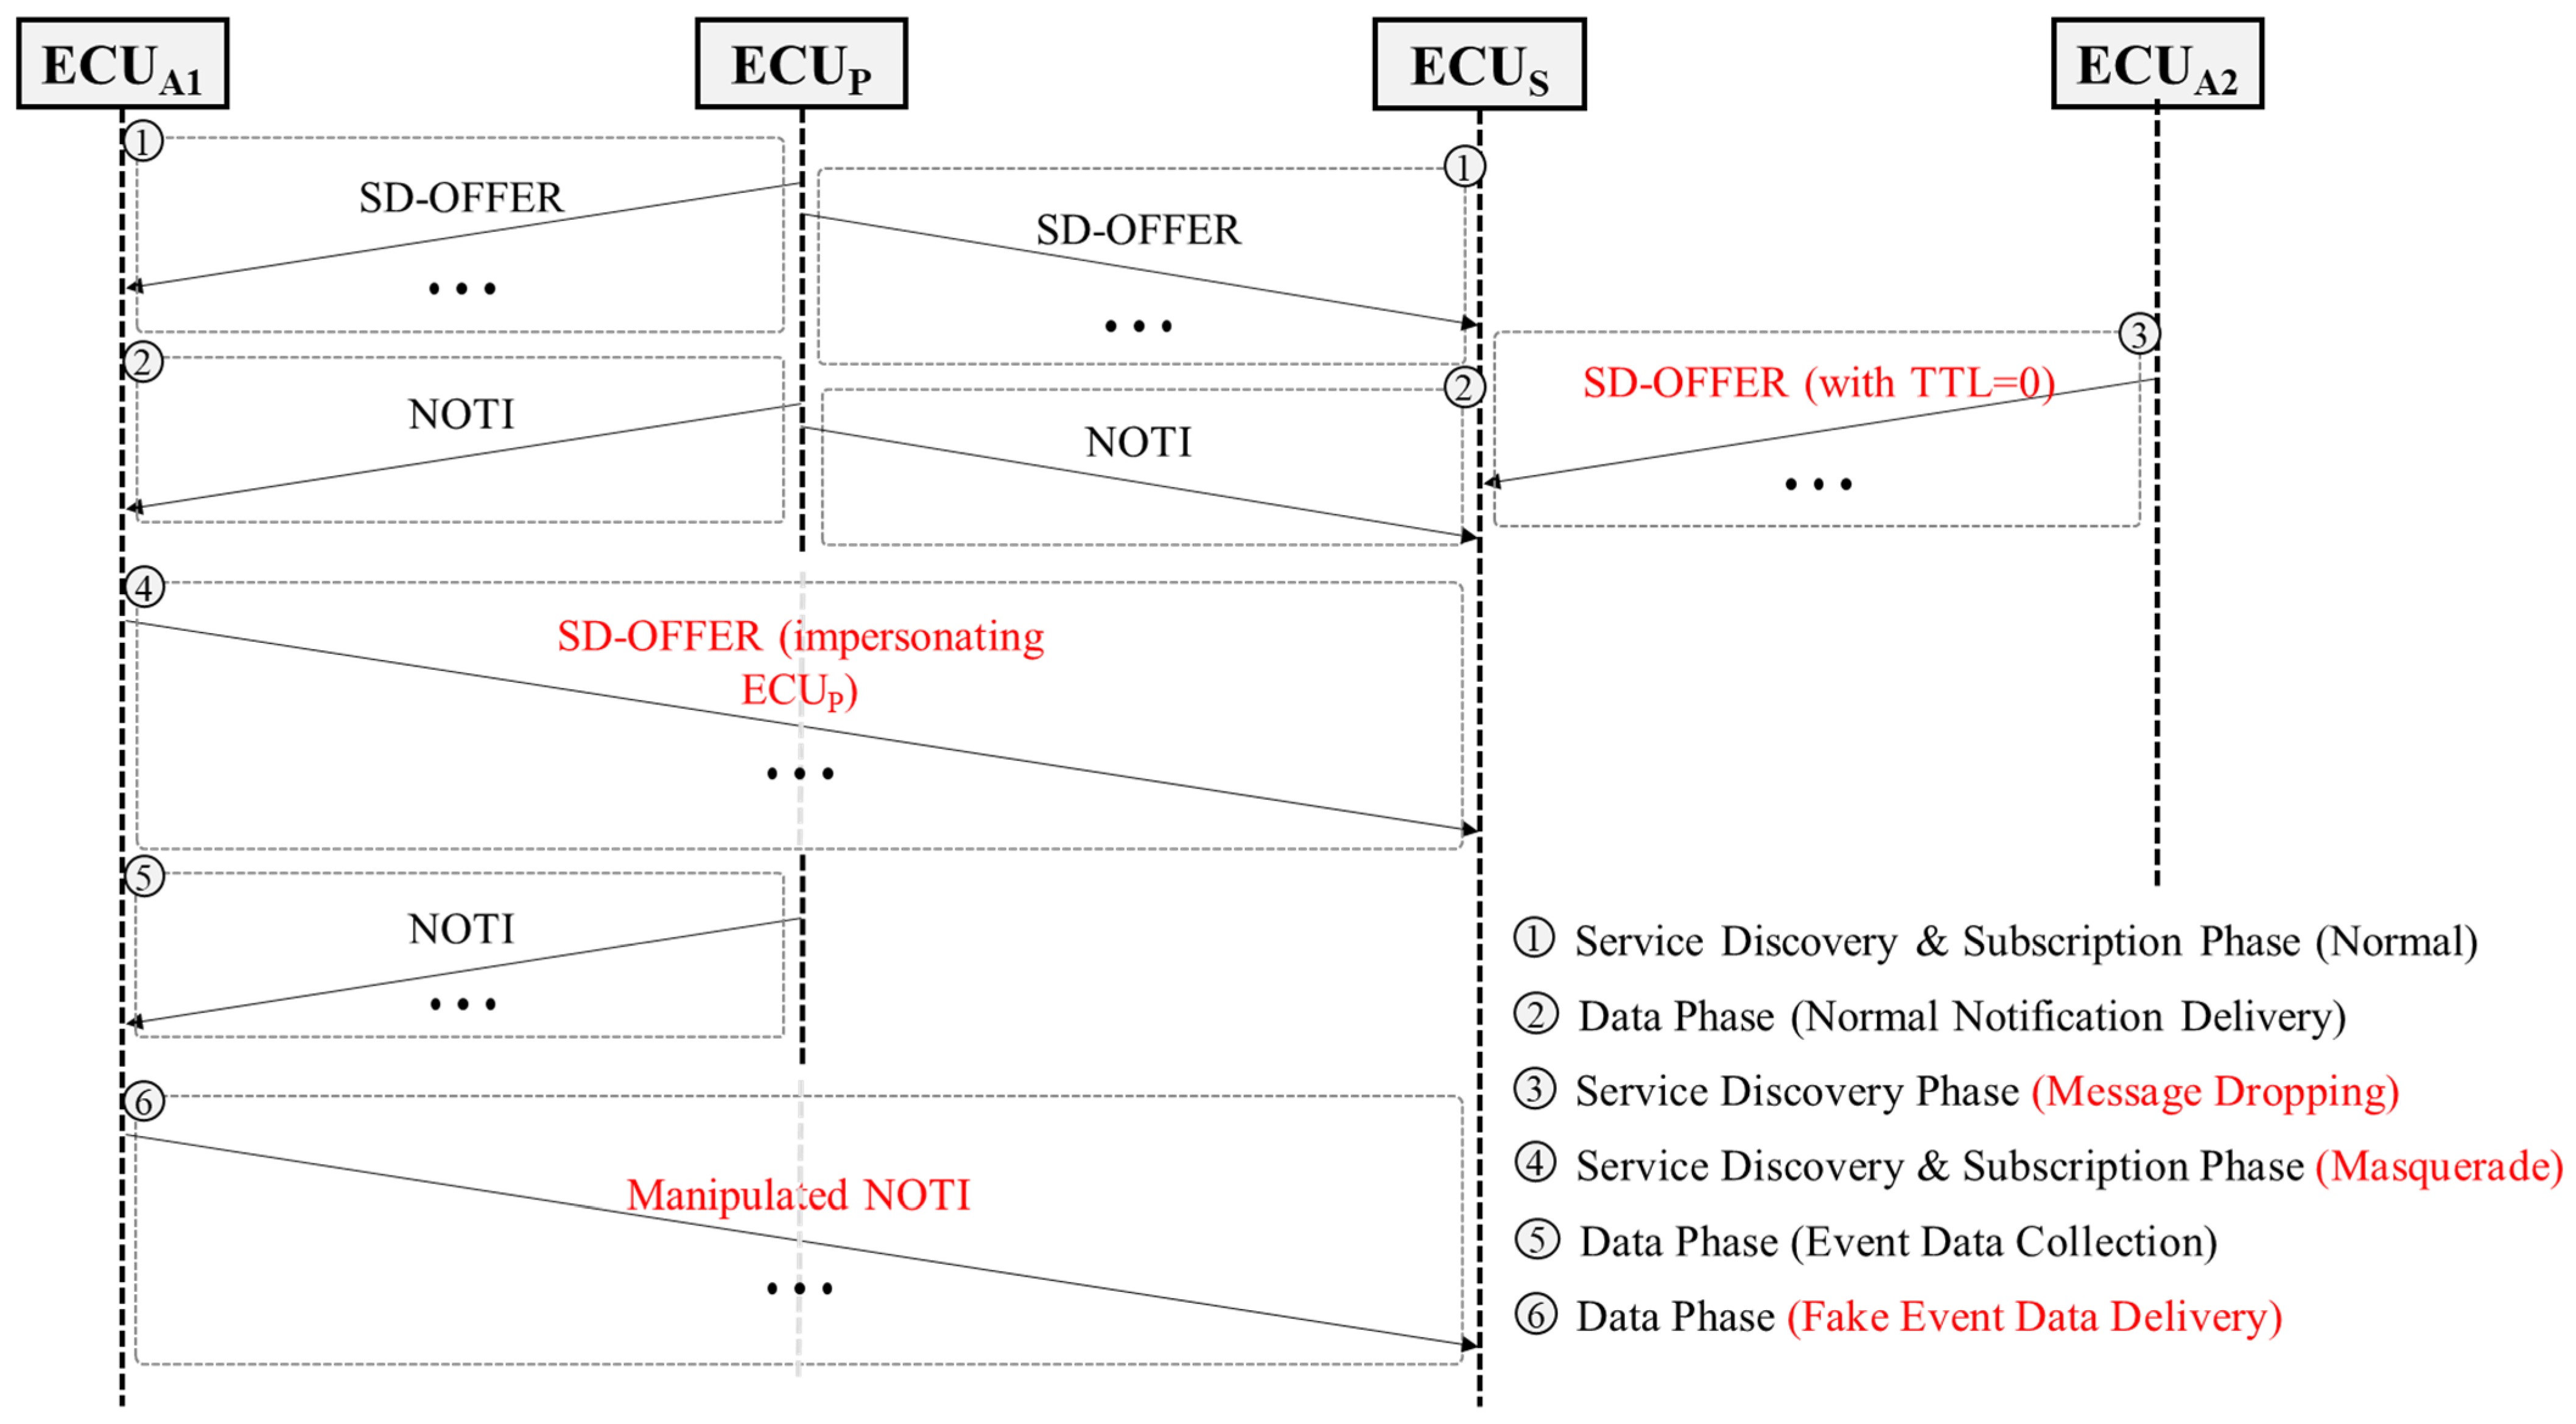
Figure 7 illustrates the communication flow of a man-in-the-middle attack in our SOME/IP simulation. The diagram shows interactions among two attacker ECUs, a legitimate provider ECU, and a consumer ECU; in practice, a single attacker can also perform both roles, and our collected traces cover both cases. Our MitM scenario incorporates the message-drop step described in
Section 4.1.4 to break the existing discovery and subscription state and to redirect peers toward attacker-controlled endpoints; therefore, MitM and the drop effect are executed together, and the resulting traffic is collected in a single run.
After the trigger, the relay attacker joins the victim service and event group as a consumer through normal discovery and receives the legitimate notification stream. It then republishes the received events as its own notifications so that other ECUs can subscribe to the relayed stream. Meanwhile, the SD attacker forges service discovery traffic that withdraws the legitimate service advertisement by injecting a zero-TTL OfferService announcement to the target host. Once the receiver invalidates the legitimate endpoint and subscription state, the peer shifts away from the authentic provider and may reconnect to attacker-controlled endpoints. Immediately after this forced withdrawal, the relay attacker re-advertises the same service and instance as if it were the provider by sending OfferService entries that point to attacker-controlled endpoints, prompting the consumer to re-discover and re-subscribe to the attacker’s relayed stream. The relay attacker can then forward only selected notifications, delay delivery, or transmit manipulated values, thereby introducing selective alteration and timing irregularities while maintaining an apparently valid service presence.
Our demonstration focuses on publish–subscribe traffic, but the same MitM concept can also be extended to request–response, fire and forget, and getter/setter interactions when method calls or state operations are exposed as service interfaces. This extension is feasible because service discovery decouples a service identity from its transport endpoint; by advertising attacker-controlled endpoints and then proxying traffic, an adversary can interpose on any SOME/IP message type, including method requests/responses and field read/write operations, not only event notifications.
5. Our Proposed Framework
We propose an XGBoost-based intrusion detection framework to detect abnormal traffic in SOME/IP communication. Many SOME/IP attacks preserve message format validity while altering runtime communication behavior, including timing patterns, subscription dynamics, and payload statistics. We therefore emphasize behavioral evidence extracted per stream and per layer, which remains informative even when field values look normal. Based on this rationale, we design the framework to reconstruct layer-specific message records and stream contexts instead of relying on static header identifiers, enabling the detection of subtle disruptions in service discovery, bursty notification dynamics, and payload irregularities even under protocol-compliant adversarial behavior.
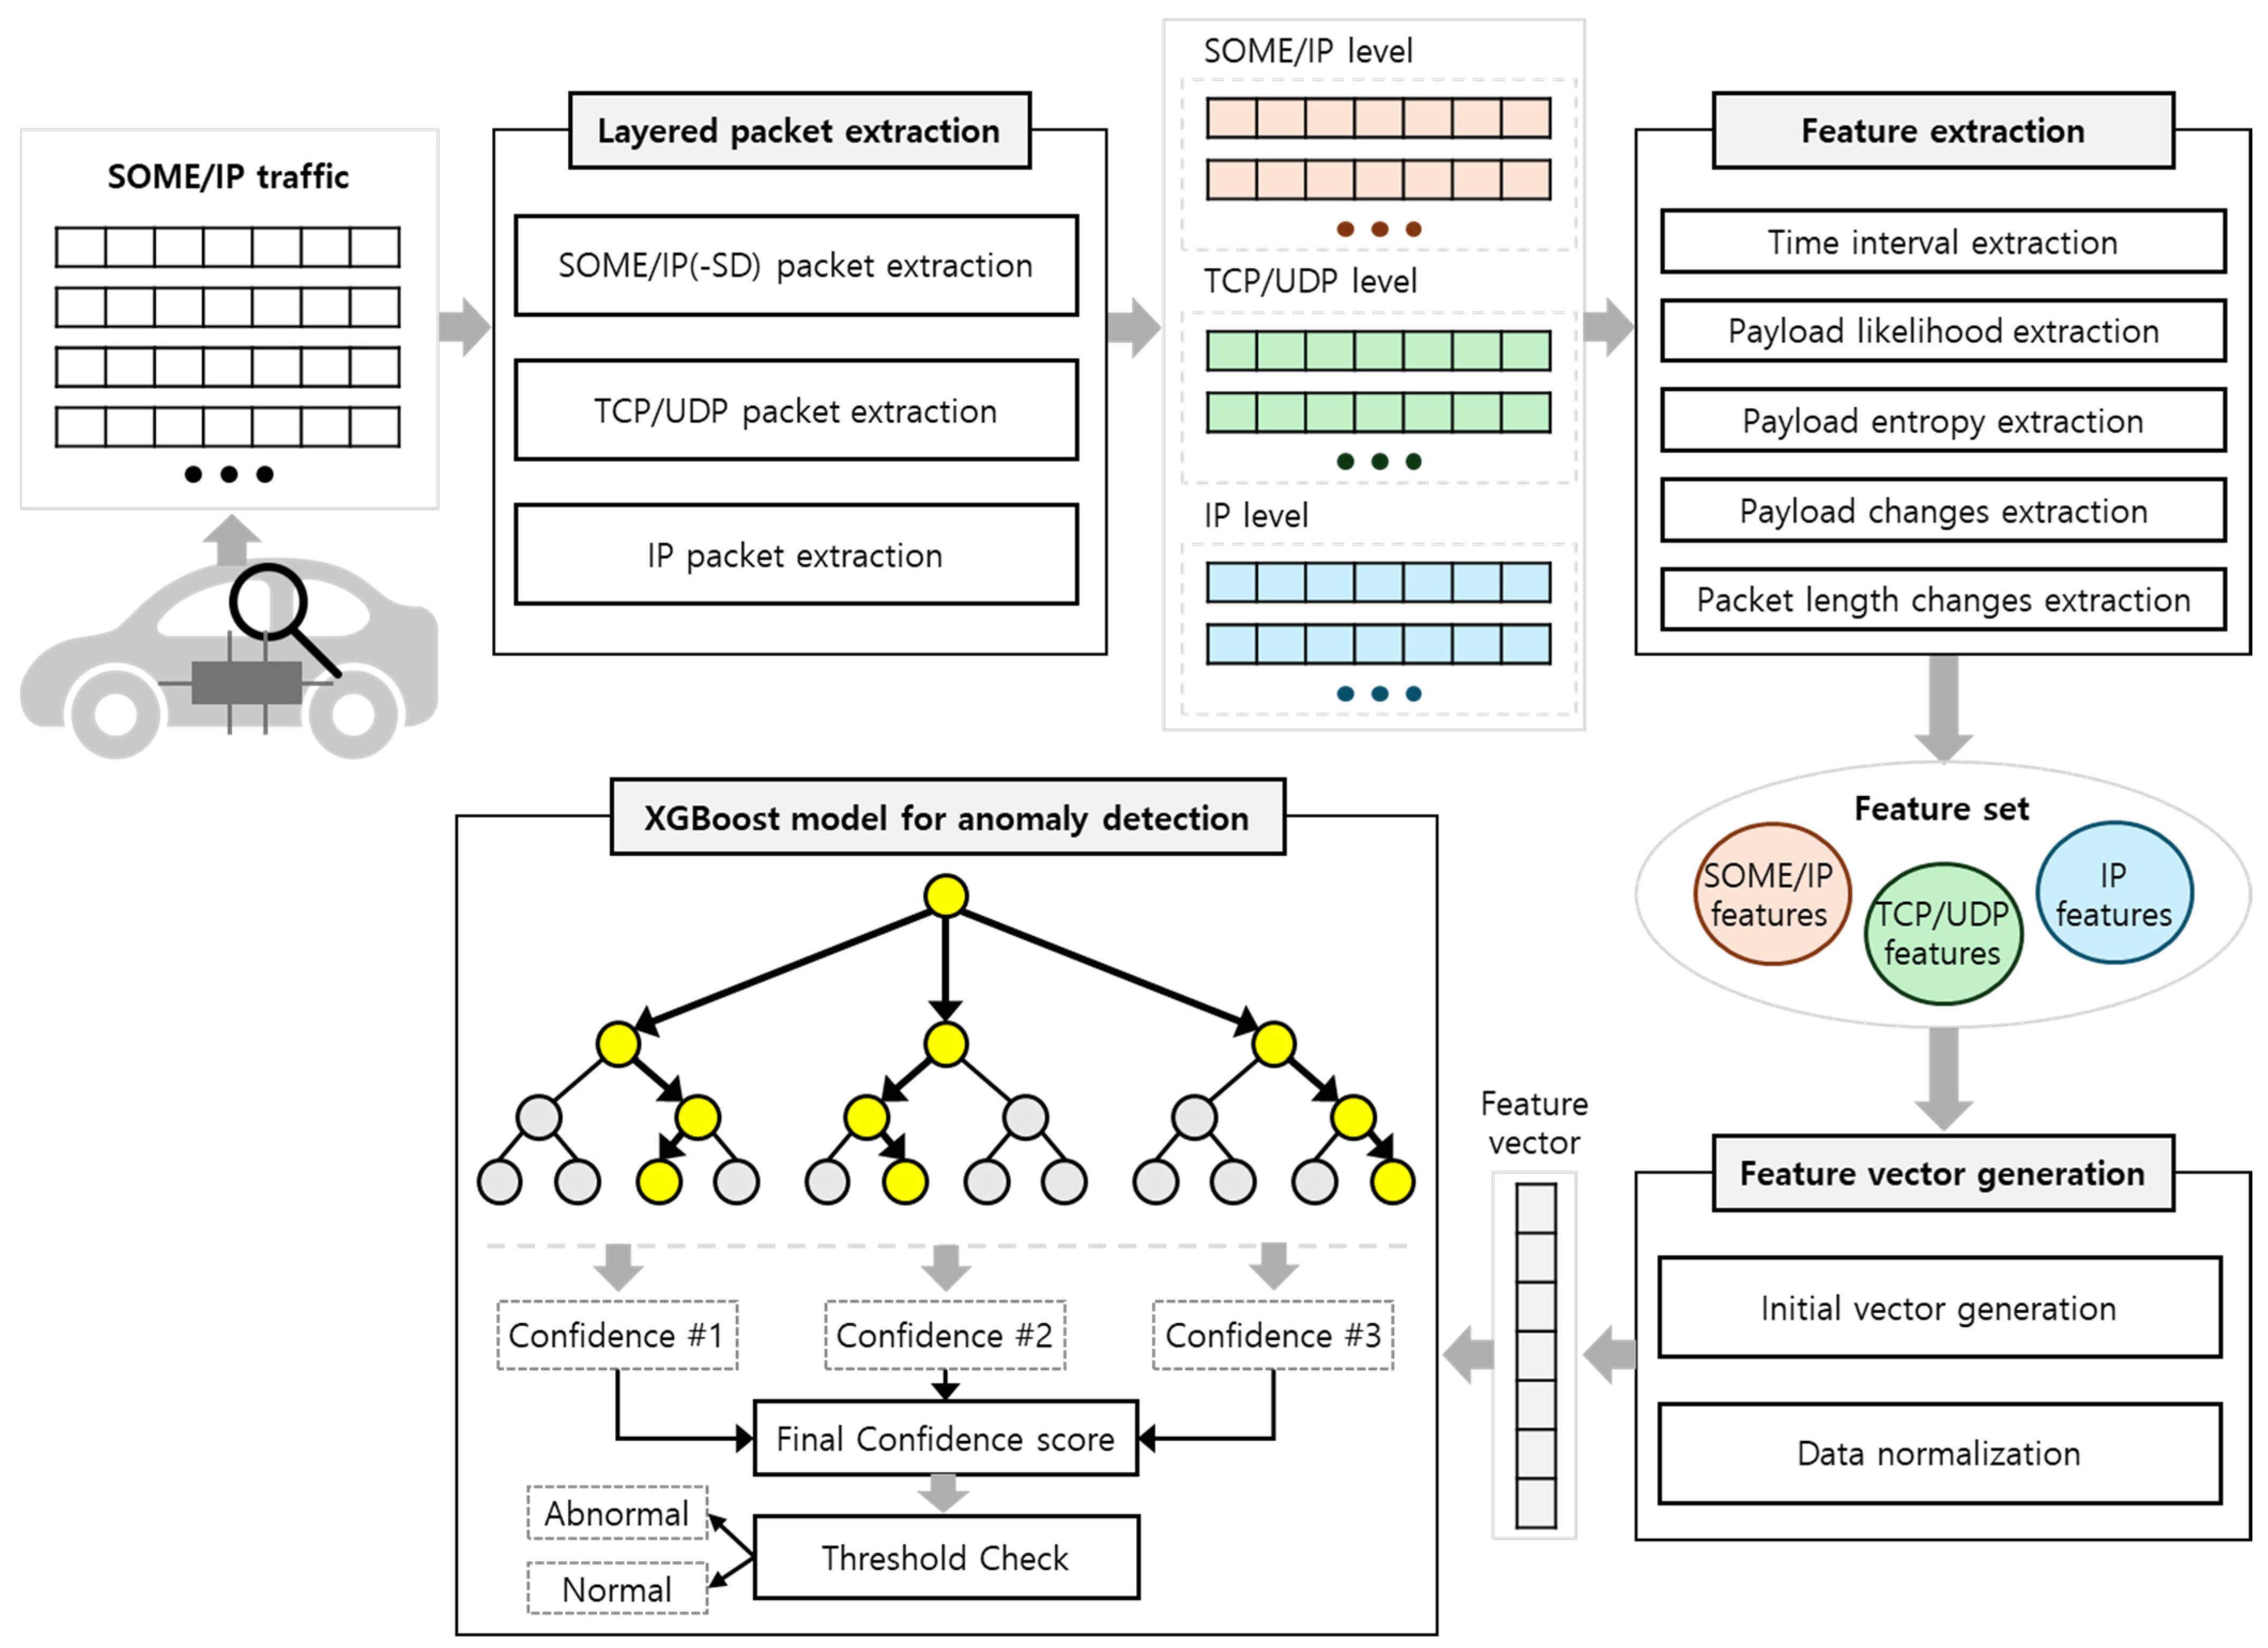
The architecture of the framework is illustrated in
Figure 8. The proposed framework starts with in-vehicle traffic collection, where raw SOME/IP-based Ethernet frames are continuously captured from the Automotive Ethernet network. This stream of packets is first delivered to the layered packet extraction module, which parses each frame along the protocol stack and separates it into logically distinct components corresponding to the IP, TCP, or UDP, and SOME/IP layers. During this process, the original ordering and positional relationships of header fields and payload segments are strictly preserved so that higher-level behavioral patterns, such as request and response sequences or timing dependencies among traffic, can be accurately reconstructed in later stages. By converting packets into a clean, layer-aware form, the layered packet extraction module creates a clear basis for systematically analyzing heterogeneous in-vehicle Ethernet traffic.
The layer-parsed packets (i.e., per-layer records extracted from each Ethernet frame) are then processed by the feature extraction module, which derives a comprehensive set of attributes that reflect both low-level protocol properties and higher-level communication behavior. These features include transmission timestamps and interarrival times, source and destination addresses and ports, flag and option values, packet length, and SOME/IP message types. Importantly, the extracted features are organized per stream, with packets sharing the same source and destination endpoints (e.g., IP/port pairs) grouped and processed separately. This stream-wise separation enables the framework to capture consistent flow-level behaviors and distinguish anomalies within each communication pair. The extracted attributes are then passed to the feature vector generation module, where they are organized into three interpretable groups, namely SOME/IP features, TCP/UDP features, and IP features. Within this module, all selected features are concatenated and normalized to construct a unified fixed-length feature vector that compactly represents each observed packet or flow instance while preserving its multi-layer characteristics. This structured feature vector serves as the direct input to the learning-based detection engine.
Finally, each feature vector is supplied to the detection module, which contains an XGBoost model trained offline. In the XGBoost model, each input vector is evaluated across an ensemble of gradient-boosted decision trees; individual tree outputs are aggregated to produce a prediction score reflecting the likelihood that the instance is malicious or benign. Based on a predefined or adaptively tuned threshold, the model outputs an anomaly score, enabling fine-grained control over detection sensitivity, and a binary decision is made by comparing the score to the threshold. Instances classified as normal are treated as legitimate in-vehicle traffic, while packets or flows identified as anomalous are highlighted, separated from the normal stream, and forwarded to the alerting and logging components for further inspection, correlation with attack scenarios, and potential response by security operators. A detailed explanation of each component of the framework is provided in the following subsections.
5.1. Layered Packet Extraction
The layered packet extraction module transforms raw captured frames into a structured, analysis-ready representation by sequentially parsing protocol headers across the communication stack, including Ethernet, IP, TCP, UDP, and SOME/IP. During this process, it validates header formats and length fields, extracts relevant header values, and separates payload segments into logically distinct components. As a result, the framework produces separate packet sets for each network layer, such as SOME/IP and SOME/IP-SD messages, TCP/UDP segments, and IP frames. These layer-specific datasets can then be independently analyzed, enabling more fine-grained inspection of anomalous behavior at each layer and facilitating the detection of abnormal patterns that may not be clearly observable when all layers are treated as a single, unified stream.
In practice, the layered packet extraction module can be implemented as a deterministic parser using standard protocol parsing steps. The layered packet extraction module is implemented as a deterministic parser that processes each captured Ethernet frame and emits a set of layer-specific records. For each packet, the module first parses the Ethernet header and then checks the EtherType to determine whether the payload contains IPv4 or IPv6. It then extracts the IP header fields and uses the protocol identifier to parse either UDP or TCP. For UDP, the module validates the UDP length field and treats the UDP payload as a candidate SOME/IP or SOME/IP-SD message. For TCP, the module performs stream reconstruction using a five-tuple key and sequence numbers, reassembles in-order payload bytes, and then applies SOME/IP parsing to each complete message unit. The SOME/IP parser validates the message header, including service ID, method ID, client ID, session ID, interface version, message type, return code, and payload length, and it classifies Service Discovery messages based on the SOME/IP-SD header and entries.
Layer-wise analysis is useful because some attacks become visible only at the SOME/IP-specific layers while appearing normal at lower layers. For instance, in a MitM scenario, spoofed SOME/IP-SD messages may advertise a sudden change in endpoint IP or port, or abnormal TTL values, even though the UDP multicast traffic and IP/UDP headers remain perfectly valid. Similarly, during a fuzzy attack, TCP/IP transmission can look error-free, yet the SOME/IP payload length, type, or entropy may deviate sharply from the expected distribution for a given service or method. When all layers are merged into a single stream, these semantic anomalies at the SOME/IP level can be masked by benign patterns from other layers, making them harder to notice and detect.
5.2. Feature Extraction
The feature extraction module converts the structured packet representation into a set of numerical features that capture the behavioral characteristics of communication at each network stack, accounting for both packet-level and flow-level aspects. In the proposed framework, a total of nine feature types listed in
Table 1 are employed for anomaly detection. Although many other features can be derived from protocol header fields, many of these values do not directly reflect meaningful changes in network behavior and may introduce unnecessary noise. For example, consider a DoS attack targeting a SOME/IP service. An adversary may generate a large volume of requests while keeping the service ID, method ID, port number, and protocol type identical to those used in legitimate communication. In this case, the combination of IP, TCP/UDP, and SOME/IP header field values remains almost indistinguishable from normal traffic, making it difficult to separate benign and malicious flows using header values alone. In contrast, behavior-based features such as the number of requests per session or per time unit, inter-arrival time between consecutive packets, and sudden surges in requests to a specific service provide clear evidence of abnormal traffic patterns caused by a DoS attack. When computing such relational features between consecutive packets (e.g., time intervals or payload variations), the comparison is restricted to packets that share the same source and destination IP addresses and transport-layer ports, ensuring that the resulting feature values accurately characterize behavioral changes within the same communication flow.
Therefore, our approach focuses on essential features closely related to behavioral deviations induced by attacks such as DoS, MitM, and fuzzing. In particular, the selected features are designed to detect whether traffic is transmitted at an unusually high rate and whether specific payload patterns are frequently observed under normal conditions. They also capture sudden variations in payload content or packet length. While incorporating additional header-level information could potentially increase detection accuracy in controlled experimental environments, it also heightens the risk of overfitting. This issue is especially critical given the current lack of realistic, large-scale attack datasets for SOME/IP-based in-vehicle networks.
The stream-wise feature used in our framework can be categorized into five classes: time-interval features, payload log-likelihood features, payload cross-entropy features, payload-change features, and length-change features. Each feature class captures a distinct behavioral symptom of SOME/IP attacks and provides complementary signals beyond static header fields. Time-interval features measure how quickly messages arrive within a stream; unusually small or highly variable intervals are typical of bursty DoS traffic or timing disruption. Length-change features track abrupt shifts in packet sizes between consecutive messages; large or frequent jumps often indicate malformed inputs, unexpected service behavior, or injected messages. Payload log-likelihood features quantify how typical an observed payload is under a normal byte-distribution model learned from benign traffic; low log-likelihood indicates rare or unexpected byte patterns that can arise from fuzzing or payload manipulation, even when headers remain valid. Payload cross-entropy features summarize the average surprisal of payload bytes under the same normal model, providing a normalized measure that is less sensitive to payload length and highlights statistically irregular content. Finally, payload-change features (Hamming distance between consecutive payloads) capture sudden content shifts within a flow; large distances can indicate message tampering, injected notifications, or abnormal state transitions during MitM or fuzzing scenarios.
As depicted in Equation (1), the time interval feature and the length change feature can be obtained by computing the difference between consecutive packet values.
The payload likelihood feature can be computed by summing up the log likelihood values of each byte in SOME/IP(-SD) or TCP/UDP payload. The equation for calculating the log likelihood is described in the below equations (Equations (2)–(5)).
Let
be a set of
normal packet payloads, each of fixed length
. Each payload sequence
is represented as:
where
, corresponding to the possible values of an unsigned 8-bit byte, and for each byte position
and each byte value
denotes the position-wise byte frequency, that is, the number of normal payload sequences in
whose
-th byte equals
:
A probability distribution over byte values at each position
is then estimated using Laplace smoothing. Let
be the smoothing parameter, the probability,
for each position
and byte value
, is defined as:
After computing
for all positions
and byte values
, the likelihood of a given packet payload
, where
denotes the payload length in bytes is defined as the product of the position-wise probabilities of its byte values:
where
represents the likelihood that the payload
is generated from the normal byte-distribution model learned from benign traffic. For subsequent analysis, this likelihood is converted into the log-likelihood, to ensure numerical stability as shown below.
Like the likelihood feature, payload entropy feature utilizes the position-wise byte distribution
for the calculation. If payload
is given, the cross-entropy of
is computed as:
The payload change feature is the hamming distance between the payloads of the consecutive packets. Hamming distance is used because payloads are processed as fixed-length byte sequences and the goal is to measure the magnitude of discrete content changes between adjacent messages. Unlike Euclidean-type distances that assume continuous-valued features, Hamming distance directly counts bit-level mismatches via XOR, making it a simple and interpretable indicator of abrupt payload modifications caused by fuzzing or MitM manipulation. The equation for payload change feature is depicted in Equation (7). Let
be two given payloads and each
, then the hamming distance
between the two payloads is defined as:
where
denotes the bitwise XOR operation and
is the hamming weight.
5.3. Feature Vector Generation
The feature vector generation module organizes and refines the extracted features into a format suitable for the XGBoost model. The previously extracted features are first aligned and ordered for each Ethernet frame, and all feature types derived from that frame are concatenated into a single feature vector. In this process, SOME/IP and SOME/IP-SD features are separate vector elements because their roles and traffic distributions differ and merging them would mix signals. The continuous variables in this vector are then normalized to mitigate bias caused by differing value ranges using min-max normalization. Min-max normalization rescales a feature value to a fixed range, typically, based on the minimum and maximum values observed in the data. It is defined as:
where
and
are the minimum and maximum values of that feature, and
is the normalized value.
5.4. XGBoost Model-Based Detection
The final component of the framework is the XGBoost-based anomaly detection module, which performs real-time classification of network behavior using the generated feature vectors. The model is trained offline on labeled datasets that include both normal SOME/IP traffic and attack traffic from multiple scenarios, including fuzzy, Denial-of-Service, and Man-in-the-Middle attacks. By leveraging gradient-boosted decision trees, XGBoost effectively captures nonlinear relationships between features and is well-suited for handling heterogeneous, imbalanced data typical of in-vehicle networks.
During operation, each incoming feature vector is evaluated by the ensemble of trees, and the model outputs a prediction score reflecting the likelihood that the instance belongs to the attack class. A decision threshold, which can be tuned, is applied to convert this score into a binary decision. Instances classified as benign are considered legitimate SOME/IP communication, while those classified as malicious are flagged as anomalies. Through this integrated process, the XGBoost-based module enables accurate, low-latency detection suitable for deployment as a real-time protection component in Automotive Ethernet environments.
5.4.1. Parameter Setting & Training Strategy
The XGBoost model is configured using the hyperparameters summarized in
Table 2. The learning rate is set to 0.05 and the number of trees to 1000, allowing the model to capture complex behavioral patterns in SOME/IP traffic while ensuring stable convergence of the boosting process. These values were not selected via exhaustive tuning; instead, they were chosen as a conservative and commonly used configuration for large-scale gradient-boosted trees, where a smaller learning rate supports stable updates and a larger number of trees provides sufficient capacity. The row subsampling ratio (=0.8) and feature subsampling ratio (=0.8) are used as additional regularization mechanisms to reduce overfitting to environment-specific characteristics. In addition, L2 regularization [
44] is applied with lambda (=1.0) for mitigating overfitting.
In our proposed framework, the CTGAN-based data generation process is employed to alleviate the severe class imbalance in SOME/IP anomaly detection. We adopt the CTGAN architecture for tabular data synthesis, specifically designed to handle mixed-type features and highly skewed distributions. CTGAN internally applies a data transformation pipeline in which continuous variables are modeled with mode-specific normalization and discrete variables are represented via one-hot encoding. The generator is implemented as a multilayer perceptron that takes as input a Gaussian noise vector concatenated with a conditional vector corresponding to discrete attributes. The critic discriminator is also implemented as a multilayer perceptron and trained using the WGAN-GP (Wasserstein GAN with Gradient Penalty) objective with a gradient penalty to stabilize training. In addition, CTGAN employs log-frequency-based conditional sampling to better model rare categories and PacGAN (Packed GAN)-style packing to mitigate mode collapse. Through this architecture, CTGAN captures higher-order dependencies between timing, payload statistics, and structural variations in SOME/IP attack traffic, rather than perturbing individual features independently.
In our framework, CTGAN is configured with an embedding dimension of 128; a generator and critic implemented as two hidden layers with 256 units each; a batch size of 500; learning rates with weight decay for both networks; a 1:1 update ratio between the critic and generator; and PacGAN with a packing degree of 10. CTGAN is trained for 100 epochs, which we found sufficient to achieve stable convergence while keeping the computational overhead manageable for our SOME/IP dataset.
After generating feature vectors from both the normal dataset and the attack dataset. The feature vectors from the attack dataset, which is the minority class, are used as training data for CTGAN, enabling the generator to explicitly learn the joint distribution of attack-specific feature patterns. After training on the attack-only subset, the CTGAN generator is used to generate synthetic attack records until the number of generated attack samples matches the number of normal samples in the training set, resulting in a balanced training dataset in which the attack class comprises both real and CTGAN-generated records. Finally, this augmented and balanced dataset is used to train the downstream XGBoost-based anomaly detection model.
5.4.2. Threshold-Based Decision
The XGBoost-based detection model produces a confidence score as the final output for a given input. Specifically, the feature vector of a SOME/IP traffic instance is passed through an ensemble of decision trees; their leaf scores are summed to form an intermediate prediction. During boosting, each tree is trained to correct the residuals of the previous trees, and the aggregate output is then passed through a sigmoid function to yield a continuous confidence score in the range [0, 1], representing the likelihood that the instance belongs to the attack (positive) class. The final decision is obtained by comparing this score with a predefined optimal threshold.
To make that decision reliably, an appropriate confidence-score threshold must be established in advance. By evaluating multiple candidate thresholds on validation data and selecting the one that maximizes the target metric (e.g., F1), it is possible to systematically balance detection performance against false alarms, rather than relying on a naive fixed threshold (e.g., 0.5). Once the threshold is defined, each input’s confidence score is compared against it to classify the instance as normal or attack, thereby linking probabilistic predictions to clear, policy-level binary decisions.
6. Evaluation
This section presents the results of experiments conducted to demonstrate the performance of the proposed framework.
Section 4 describes the simulation environment and traffic-generation procedures used to construct the raw SOME/IP traces. The dataset and train–test partitioning used in the experiments are summarized below, followed by the experimental results in the subsequent subsections.
The dataset used in our experiments consists of approximately 14.23 million labeled samples, where each instance is labeled as either normal or attack traffic. We performed a stratified 50/50 train–test split, obtaining 7,116,674 training samples and 7,116,674 test samples while preserving the original class proportions in each split. Under this original distribution, normal traffic accounts for 6,285,515 instances, corresponding to 88.32%, and attack traffic comprises 831,159 instances, corresponding to 11.68%. We evaluate the detector under two complementary test settings: the original imbalanced test set, which reflects realistic traffic conditions, and a downsampled class-balanced test set derived from the same held-out split to enable controlled analysis. The imbalanced test set contains 7,116,674 samples with 6,285,515 normal and 831,159 attack instances, whereas the balanced test set contains 1,662,318 samples with 831,159 normal and 831,159 attack instances. During training, we mitigate minority-class scarcity by applying CTGAN-based augmentation only to the training portion. Using cached synthetic attack samples, we generate additional attacks to approximately match the number of normal samples, resulting in an augmented training set of 13,402,188 samples composed of 6,285,515 normal and 7,116,673 attack samples.
Table 3 summarizes the resulting class distributions in the training and test sets before and after CTGAN augmentation and downsampling.
6.1. t-SNE Analysis on Feature Dataset
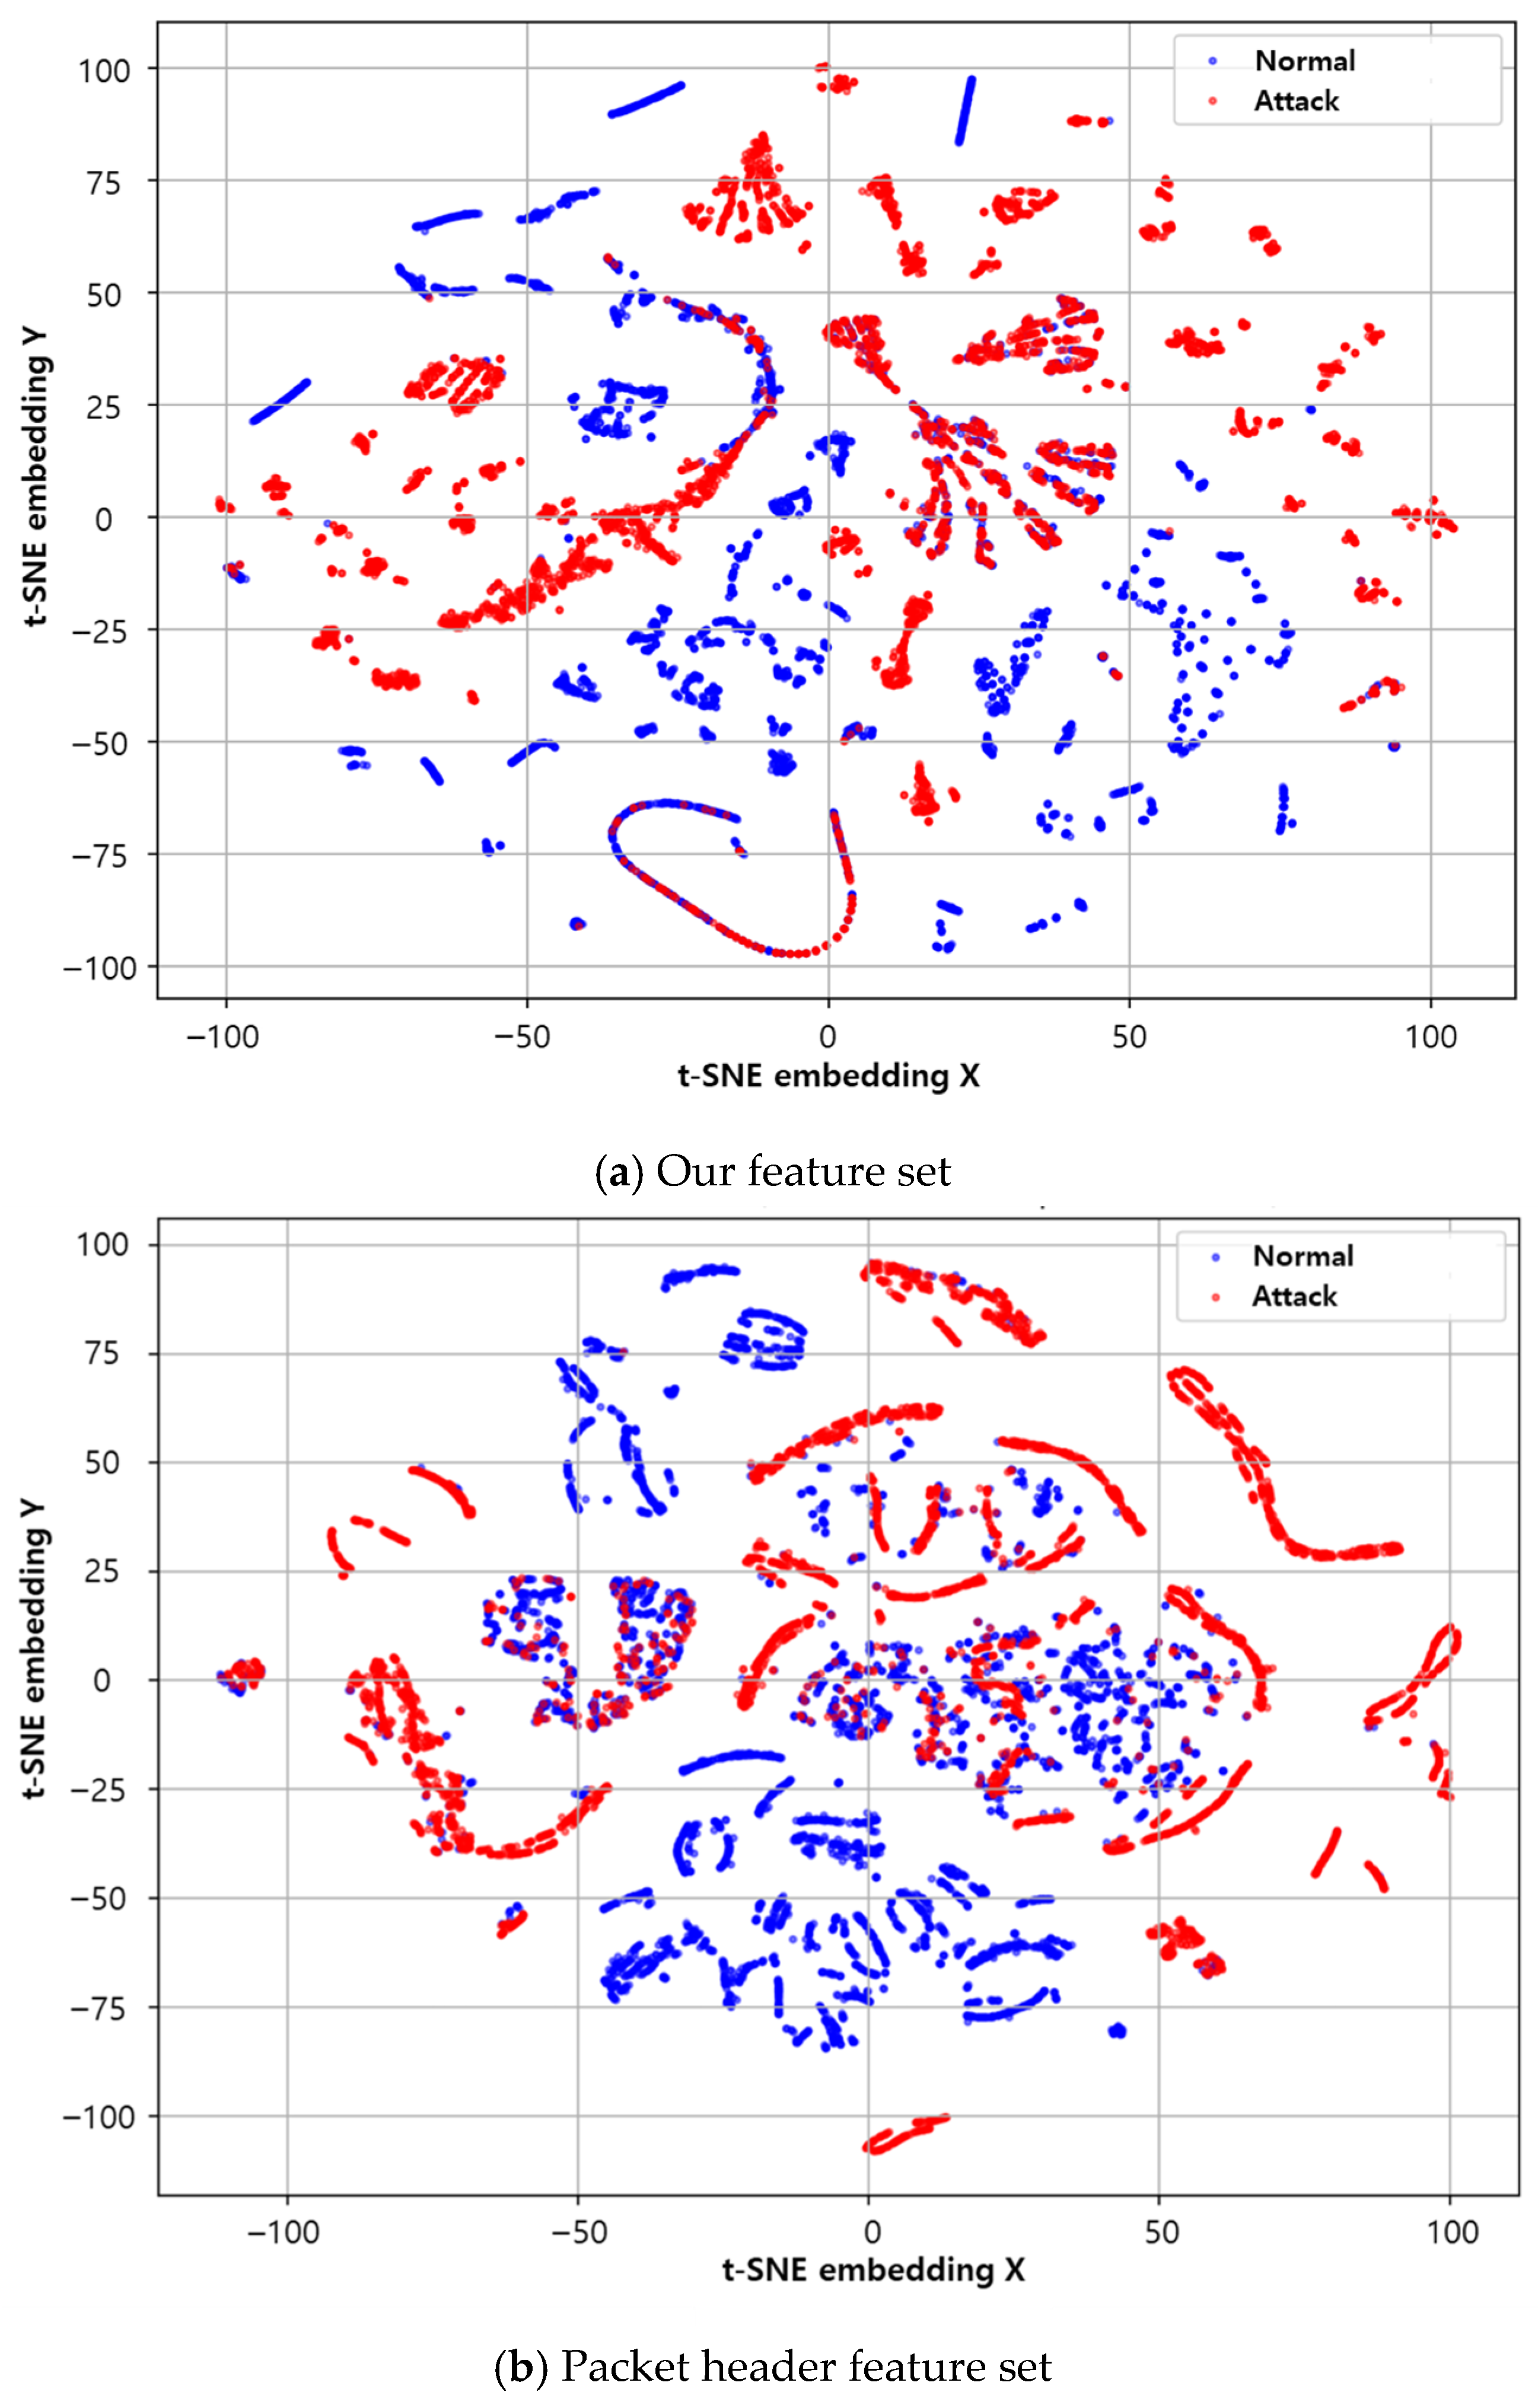
t-SNE analysis was conducted to examine how data instances defined by multiple features separate normal and attack classes, and to compare the proposed feature set with a header-based feature set. For this analysis, we randomly sampled 10,000 instances, consisting of 5000 normal and 5000 attack samples. The header-based feature set comprises values derived from protocol header fields, including IP, TCP, UDP, SOME/IP, and SOME/IP-SD, in addition to the behavior-oriented features proposed in this work; the detailed list and definitions of these header-based features are provided in
Table A1 in the
Appendix A.
To quantitatively assess the quality of the t-SNE projections, we employ widely used cluster evaluation metrics, including the silhouette score [
45], the Calinski–Harabasz index [
46], the Davies–Bouldin index [
47], and the Fisher Ratio [
48]. The silhouette score measures how similar a sample is to its own cluster compared to other clusters and provides an intuitive indication of cluster compactness and separation. Higher values indicate better-defined cluster structures. The Calinski–Harabasz index indicates how clearly different clusters are separated while each cluster remains tightly grouped; higher values indicate better separation with more compact clusters. In contrast, the Davies–Bouldin index reflects how much each cluster overlaps with its most similar neighboring cluster by considering both within-cluster spread and the distance between clusters, and lower values correspond to better-separated clusters. Finally, the Fisher Ratio measures how distinct the normal and attack classes are in the projected space by comparing the variability between classes to the variability within each class. These metrics were selected because they capture complementary aspects of low-dimensional representations, including within-cluster cohesion, cluster separation, and class discriminability. This enables an objective assessment of whether the reduced feature space preserves meaningful distinctions between normal and attack traffic beyond visual inspection.
As illustrated in
Figure 9b, header-based embedding samples form several locally compact arcs and blocks, often dominated by a single label, consistent with the slightly higher silhouette score of 0.0721. This makes local grouping in the two-dimensional view lo ok marginally cleaner.
In contrast, the embedding obtained with the proposed feature set, as shown in
Figure 9a, exhibits a richer class structure: attack and normal samples form many fine-grained islands that are separated at the cluster level, and the boundary regions where the two classes meet are visibly interleaved. These visual patterns align with the quantitative results. Compared to the header-based embedding, as depicted in
Table 4, the proposed embedding achieves a higher Calinski–Harabasz index, with a value of 486.91 for the proposed features and 443.48 for the header-based features, and a lower Davies–Bouldin index, with values of 4.1696 for the proposed features and 4.3374 for the header-based features, indicating clearer global structure and reduced overlap overall. The centroid distance is also larger for the proposed features, namely 28.41, compared with 26.77 for the header-based features, suggesting stronger separation between the class centers. Moreover, the Fisher Ratio increases from 0.1054 for the header-based features to 0.1150 for the proposed features, which further indicates improved class discriminability (i.e., increased between-class variance relative to within-class variance) rather than merely tighter local neighborhoods. The higher boundary rate, equal to 0.0845 for the proposed features compared with 0.0529 for the header-based features, is visible as more mixed border regions and implies a non-trivial, locally varying decision surface that better reflects real in-vehicle attack behavior.
Importantly, for intrusion detection, it is more valuable to obtain global class separation with less overlap than to achieve slightly cleaner local clusters in a projection. Stronger global separation and reduced overlap directly lower false positives and false negatives, and support stable generalization across different vehicles and network conditions. Therefore, the proposed feature set, which captures key behavioral signals such as service-discovery disruptions, payload statistical anomalies, and timing or length variations, yields a more meaningful class structure and supports the suitability of XGBoost for learning these nonlinear and locally varying patterns.
6.2. Comprehensive Analysis of Model Detection Performance
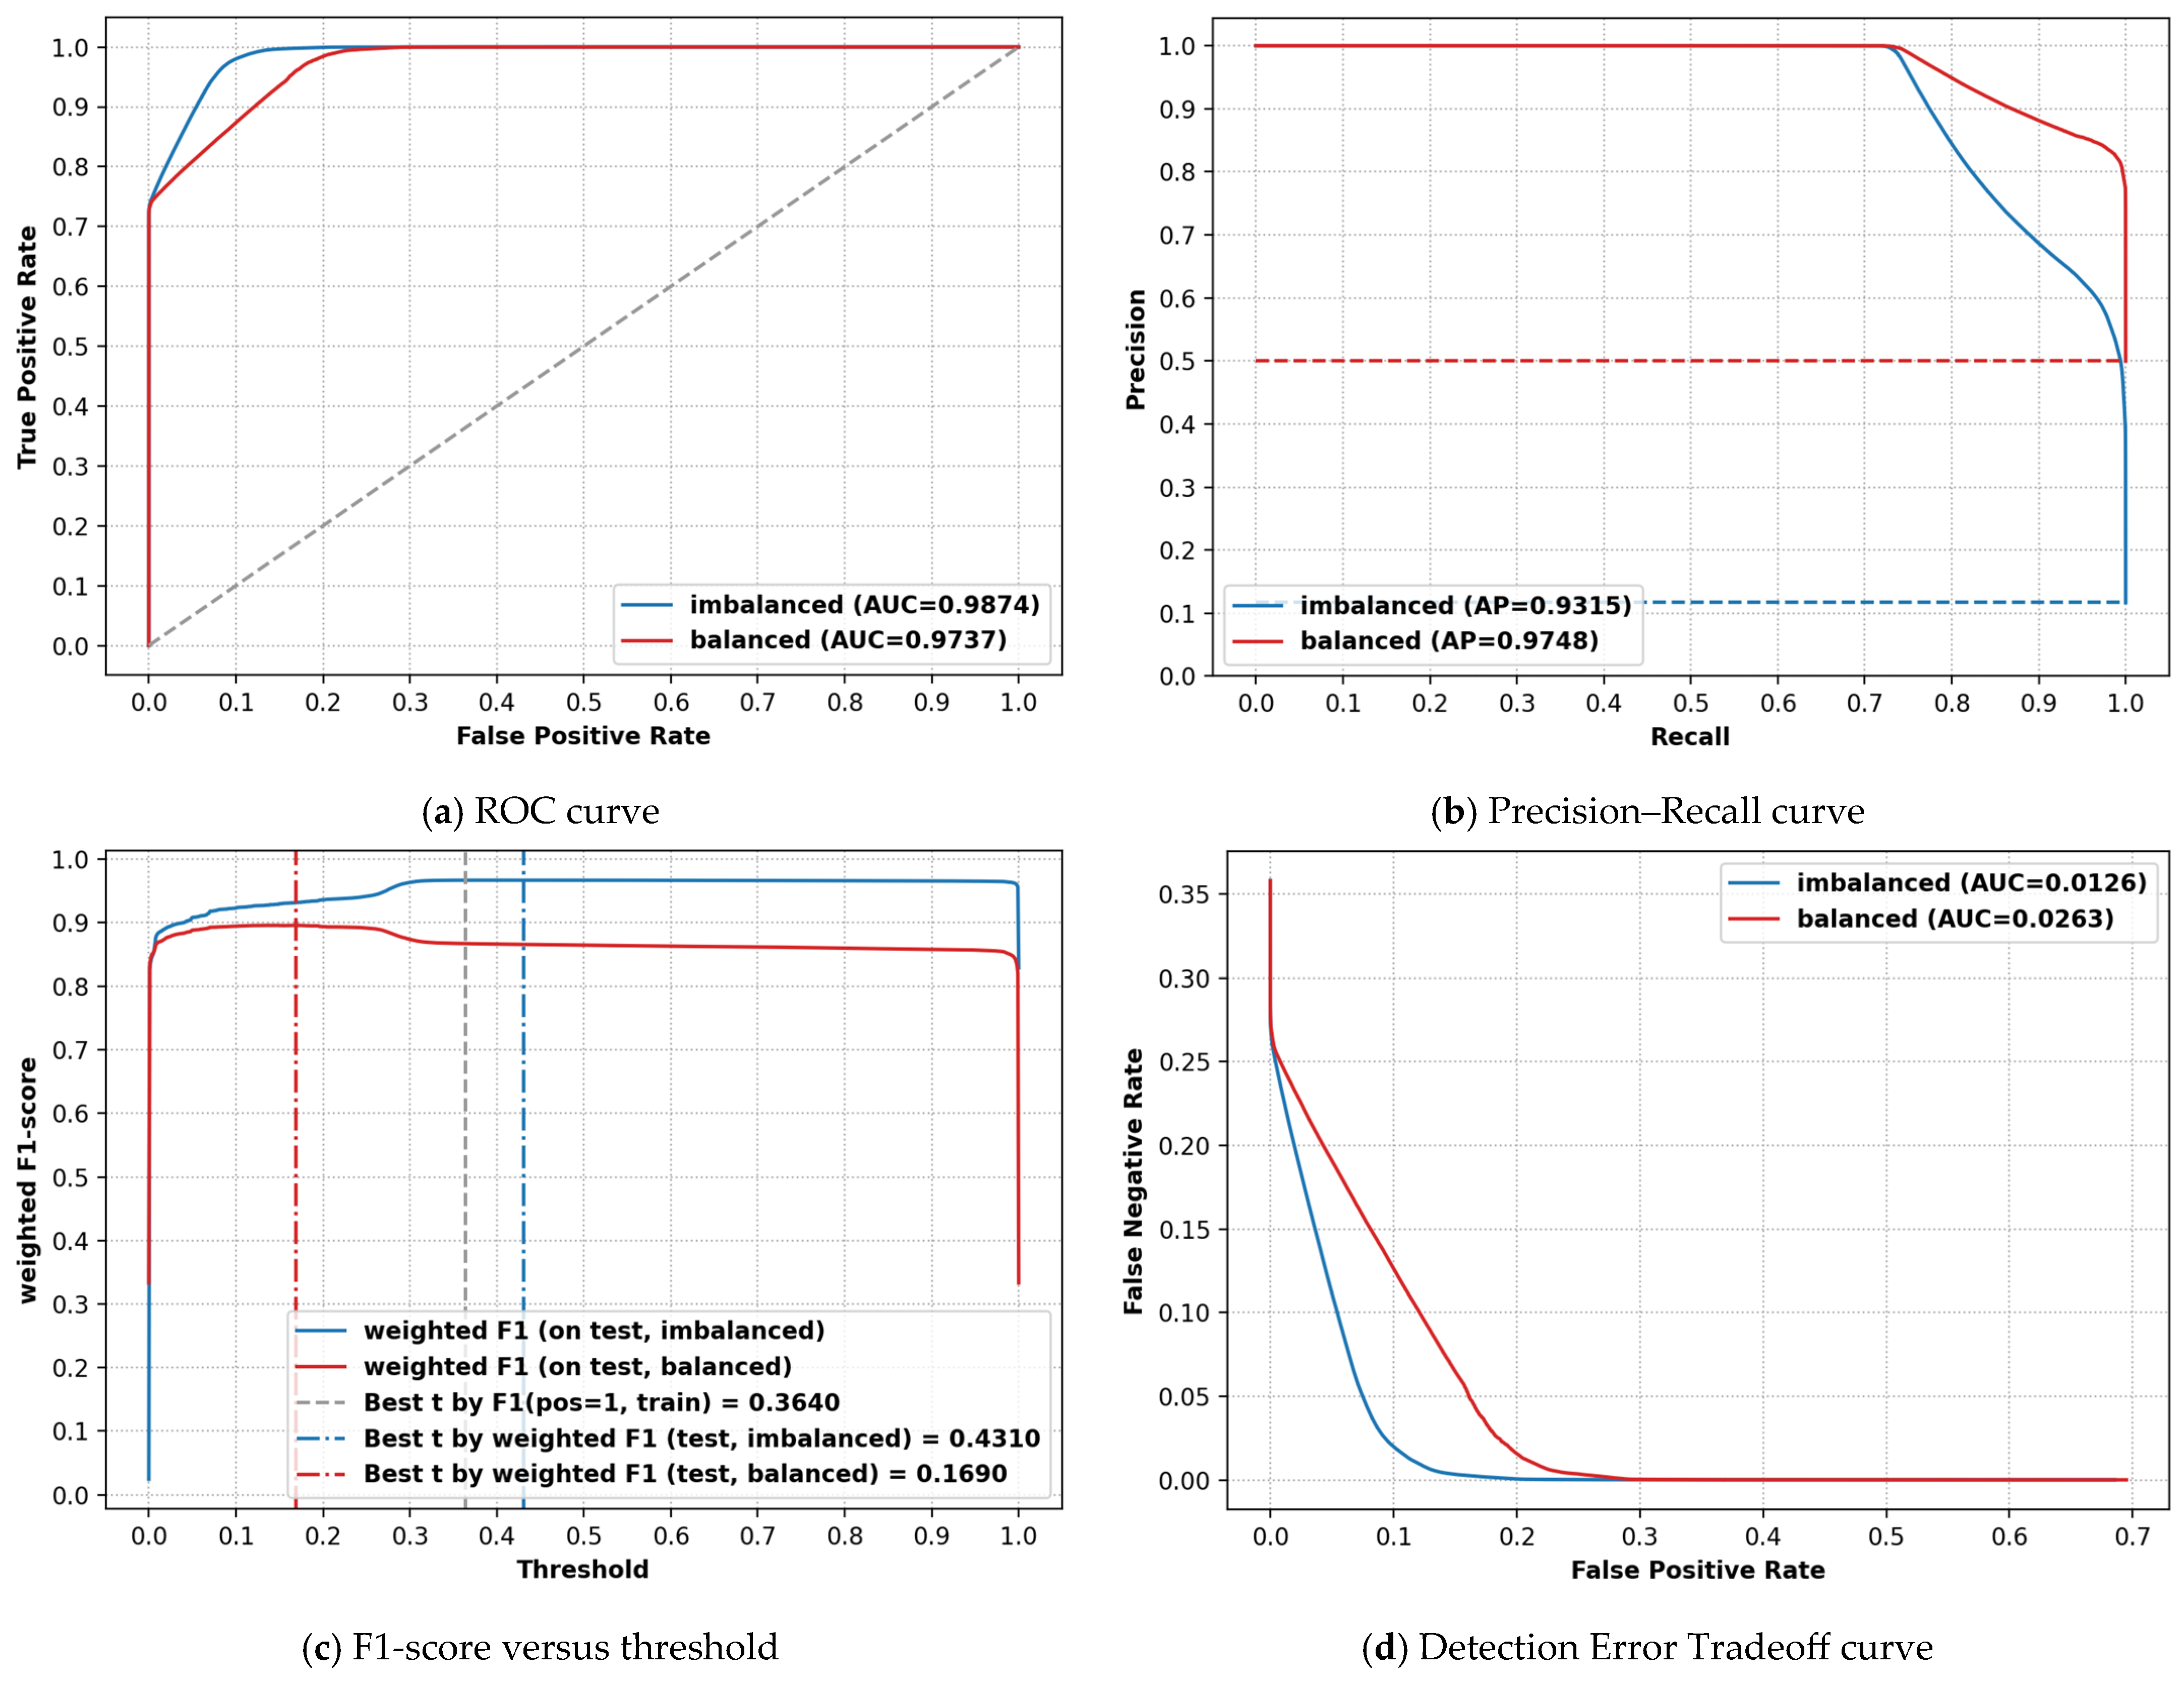
We evaluate an imbalanced test set because real SOME/IP traffic is mostly benign, and attacks are rare, so false-alarm-related metrics should reflect this class imbalance. A balanced test set is additionally used to avoid majority dominance in summary metrics and to support controlled comparisons. The balanced set is formed by downsampling normal traffic to 831,159 instances to match 831,159 attack instances, whereas the imbalanced set contains 6,285,515 normal and 831,159 attack instances. The ROC (Receiver Operating Characteristic) curve in
Figure 10a summarizes how well the model separates normal and attack traffic across all thresholds, with the x-axis reporting the false-positive rate and the y-axis reporting the true-positive rate. The ROC AUC (Area Under the Curve) is 0.99 on the imbalanced test set and 0.97 on the balanced test set, so both curves remain close to the top left region. Both values indicate reasonably good separability in each evaluation protocol. This implies that across a broad range of thresholds, high true positive rates can be achieved while keeping false positives relatively low, meaning attack scores typically exceed normal scores.
The precision–recall curve in
Figure 10b focuses on the quality of positive predictions as recall increases. This is especially relevant when attacks are rare, and alerts must remain meaningful. The PR AUC (Precision–Recall Area Under the Curve) is 0.93 on the imbalanced test set and 0.97 on the balanced test set. These values indicate consistent ranking behavior under both evaluation settings. Precision–recall performance improves when class priors are balanced. Unlike the ROC-based metric, the PR curve shows comparatively lower performance on the imbalanced test set. This is likely because false positives have a larger impact when benign traffic dominates.
The F1 versus threshold curve in
Figure 10c shows how the F1 score changes as the decision threshold ranges from 0 to 1, helping identify an operating point rather than adopting a fixed default. In our setting, the selected threshold, obtained by maximizing F1 for the positive class, is 0.36, yielding an F1 score of 0.97. On the test sets, the threshold that maximizes F1 is 0.43 under the imbalanced setting, yielding an F1 score of 0.97, and 0.17 under the balanced setting, yielding an F1 score of 0.90. Notably, applying the training-selected threshold of 0.36 yields the same F1 score of 0.97 on both test sets, even though their optimal thresholds differ. This observation is consistent with the fact that the class prior influences the precision–recall tradeoff and shifts the threshold at which F1 is maximized.
The DET (Detection Error Tradeoff) curve in
Figure 10d plots the false positive rate on the x-axis against the false negative rate on the y-axis across thresholds, explicitly showing the trade-off between error rates. The DET AUC is 0.01 on the imbalanced test set and 0.03 on the balanced test set, and both values are small, indicating that the curve stays near the origin for a meaningful range of thresholds. Compared with the imbalanced setting, the balanced setting yields a larger DET AUC, suggesting a higher aggregate error level when false positives and false negatives contribute more symmetrically to the evaluation. Overall, the curves in
Figure 10a–d indicate that the detector achieves solid separability and stable ranking behavior under both imbalanced and balanced evaluation settings. However, the DET curve suggests that false alarms remain non-negligible in both test sets. Specifically, in the imbalanced set, the FPR is 0.10 at an FNR of 0.01 and 0.09 at an FNR of 0.02; in the balanced set, the FPR is 0.19 at an FNR of 0.01 and 0.18 at an FNR of 0.02. In practical terms, an operating point with FNR = 0.01 and FPR = 0.10 implies that when the detector is tuned aggressively to minimize missed attacks, it may still trigger false alarms for about 1 out of every 100 messages. Such frequent alarms can undermine operational usability and reduce trust in the security mechanism; therefore, further improvement is required.
6.3. Comparative Evaluation with the Other Machine Learning Models
To comprehensively validate the proposed XGBoost-based SOME/IP anomaly detection framework, we conducted a comparative study against ten representative supervised and unsupervised baselines using the imbalanced set. The goal is to evaluate detection quality and computational efficiency on a large-scale dataset. Accordingly, this section reports precision, recall, F1 score, and PR AUC for each model, and then compares training and test time to assess scalability for in-vehicle deployment. As a result, XGB is considered the most suitable option because it achieves top-tier detection performance while requiring much lower training and test time than most competing models. A detailed explanation is provided in the following subsections.
6.3.1. Comparison of Classification Metrics
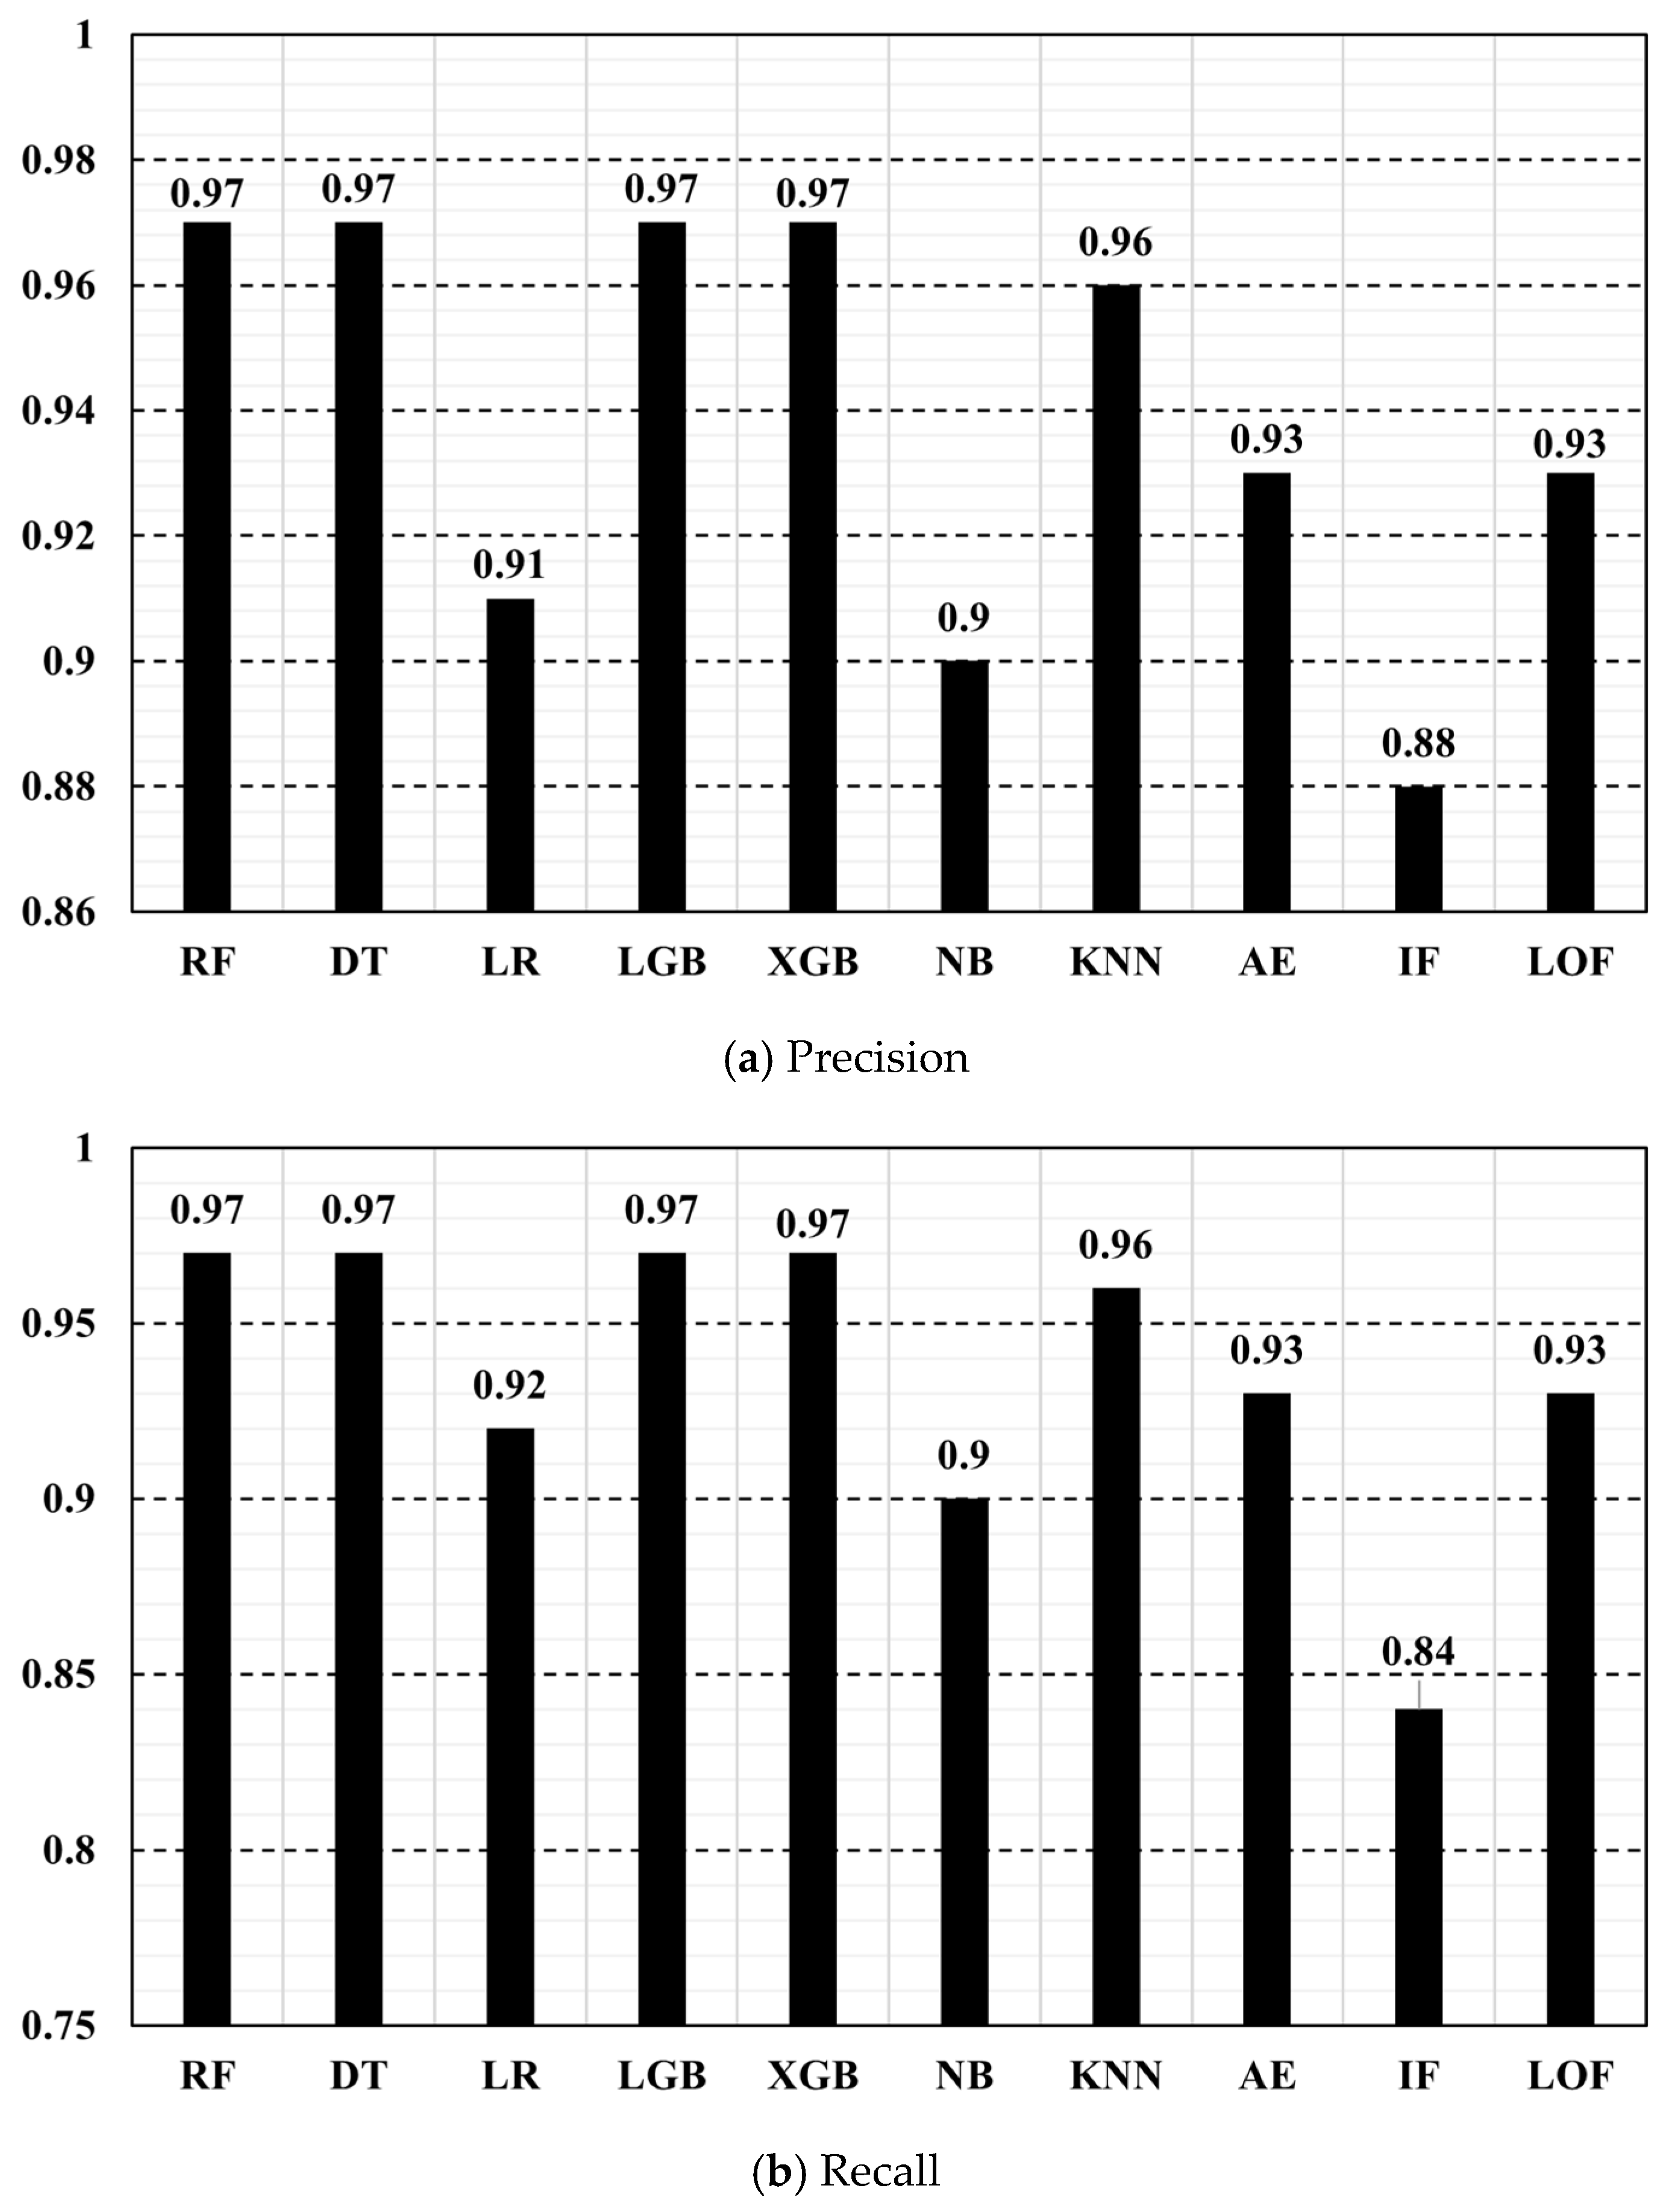
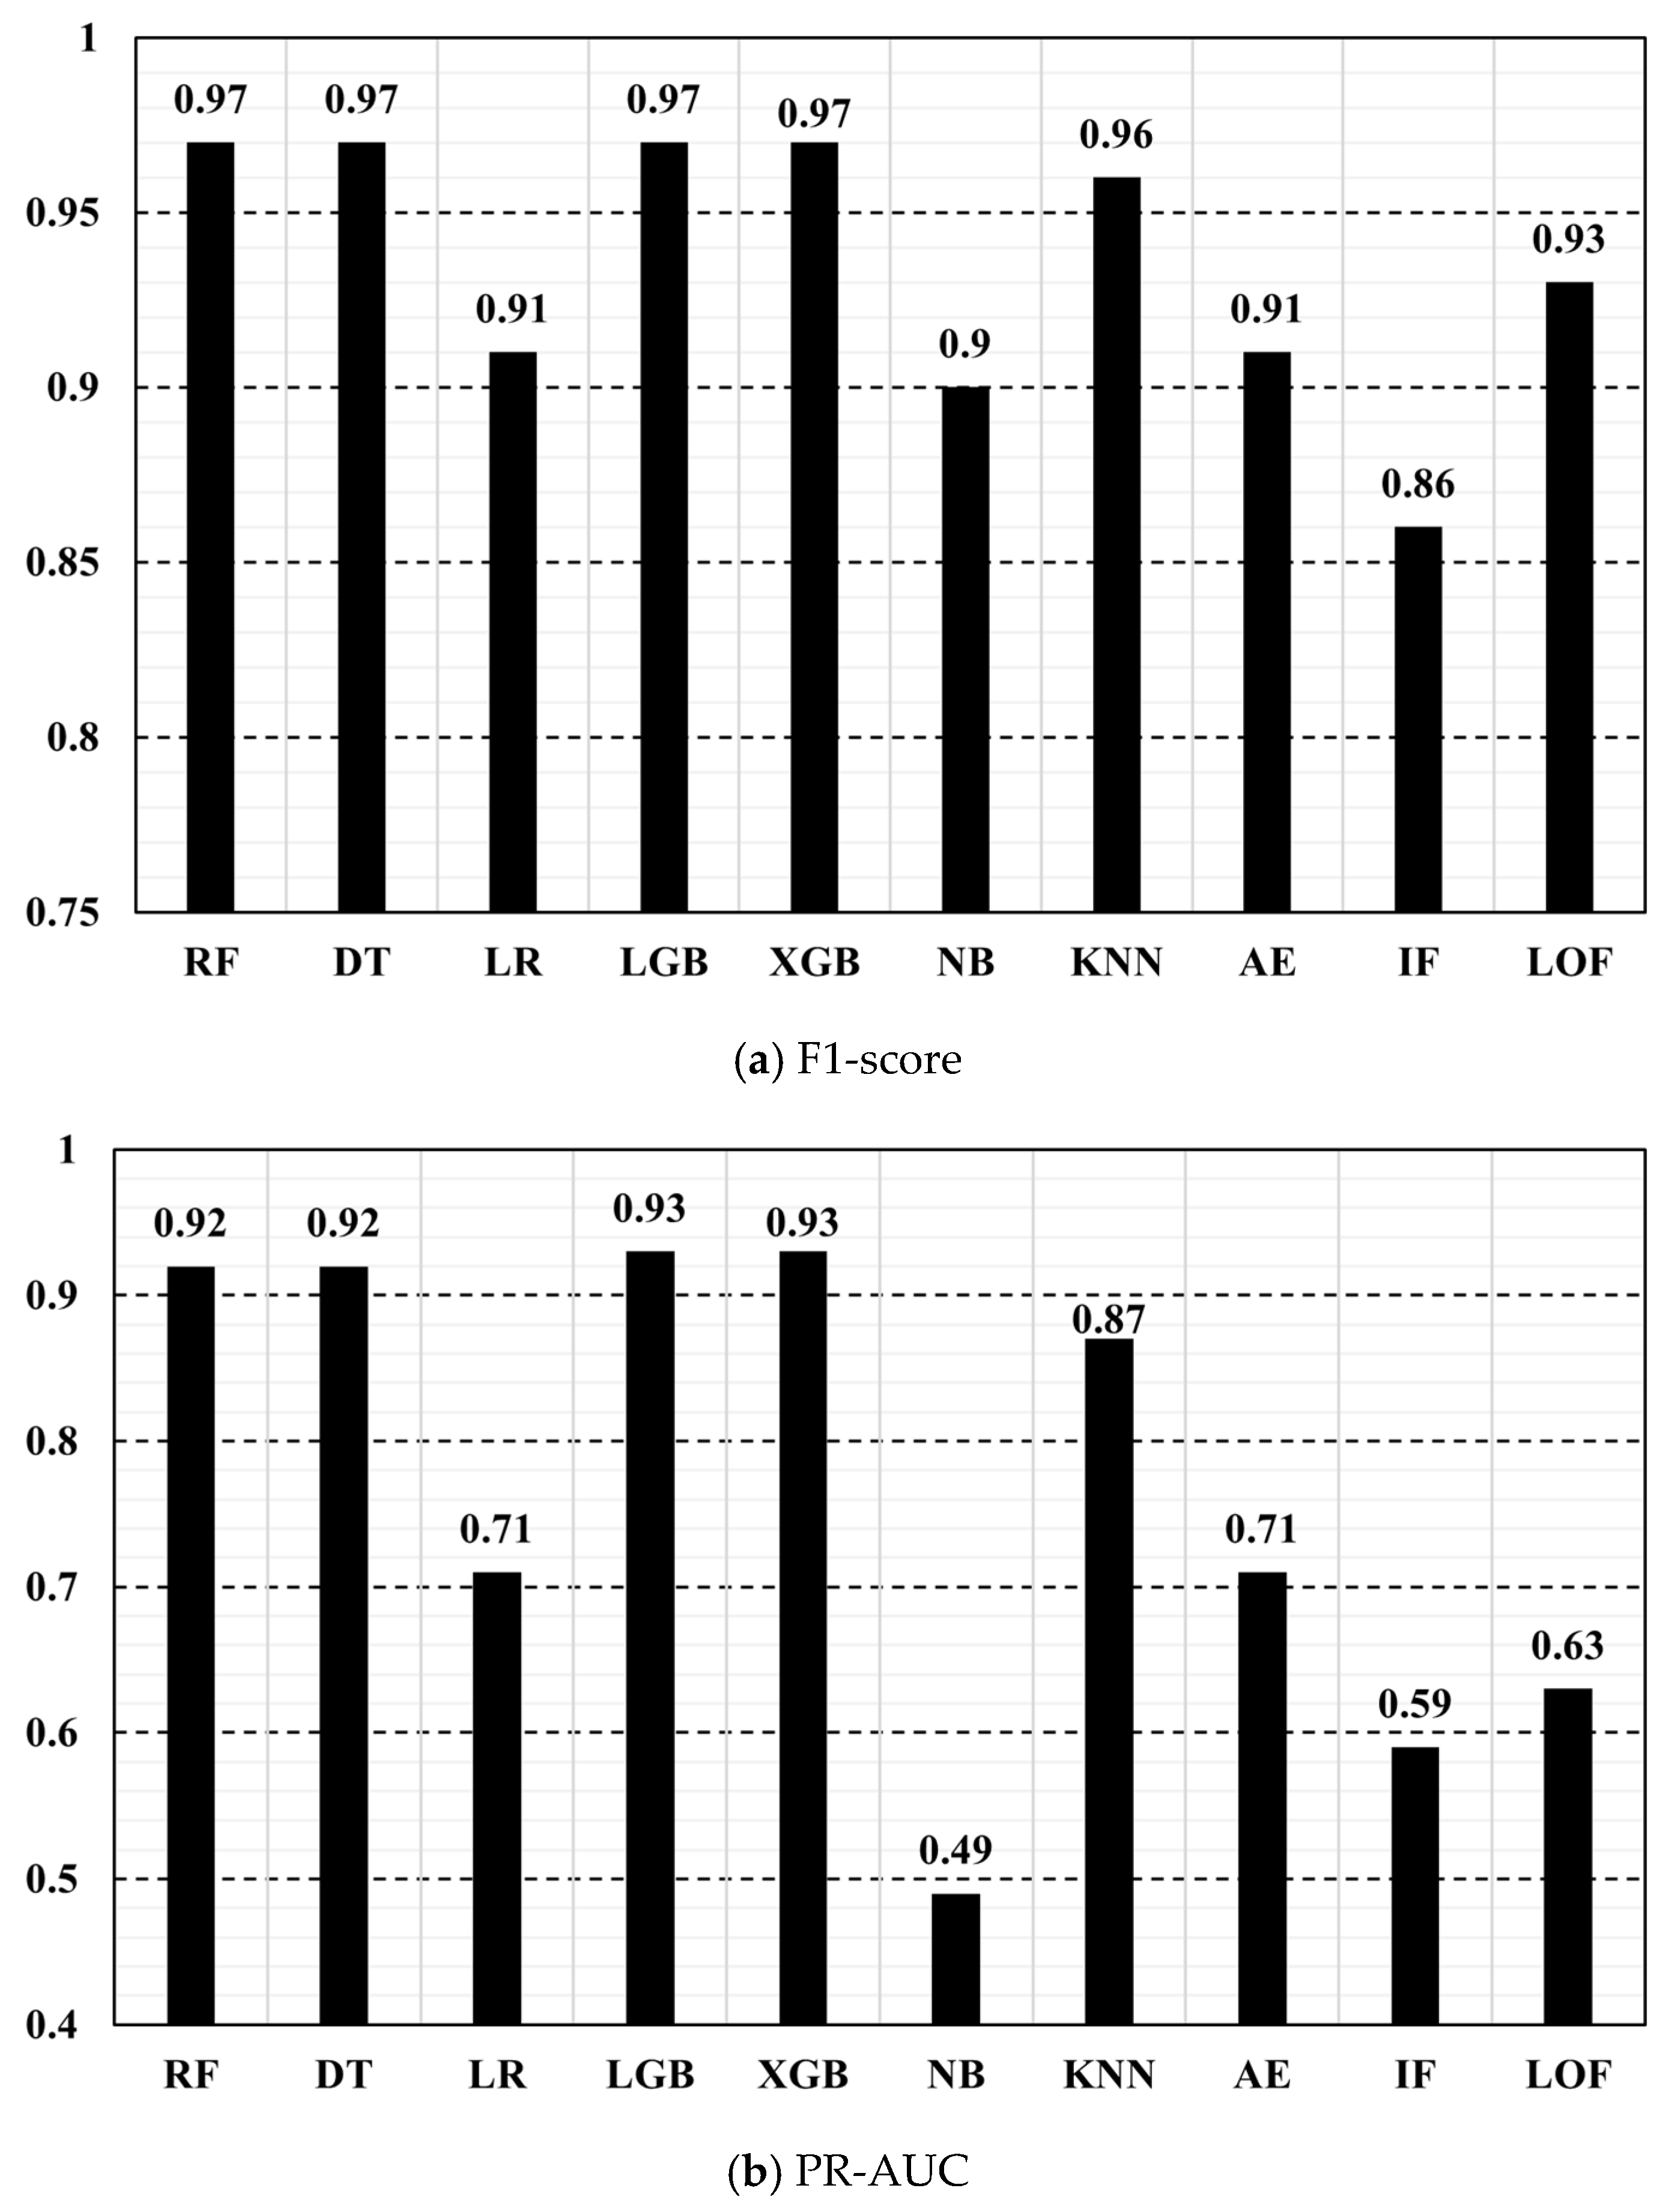
Figure 11 and
Figure 12 summarize the detection performance of ten models. The XGB model achieves precision, recall, and F1 scores of 0.97, and a PR AUC of 0.93. Overall, XGB ranks first across the reported metrics in this comparison, providing the most balanced performance among the evaluated models. Tree-based supervised baselines show comparable performance, with RF and DT reaching precision 0.97, recall 0.97, and F1 score 0.97, and PR AUC 0.92, while LGB attains precision 0.97, recall 0.97, F1 score 0.97, and PR AUC 0.93.
KNN remains competitive with precision 0.96, recall 0.96, F1 score 0.96, and PR AUC 0.87, whereas LR is lower with precision 0.91, recall 0.92, F1 score 0.91, and PR AUC 0.71. Among unsupervised methods, AE reaches a precision of 0.93, a recall of 0.93, an F1 score of 0.92, and a PR AUC of 0.71, while IF and LOF show lower PR AUC values of 0.59 and 0.63, respectively, indicating poorer ranking quality even when their point metrics can appear acceptable under a chosen threshold. NB yields the lowest PR AUC at 0.49, suggesting limited robustness under the diverse SOME/IP traffic dynamics.
6.3.2. Comparison of Computational Efficiency
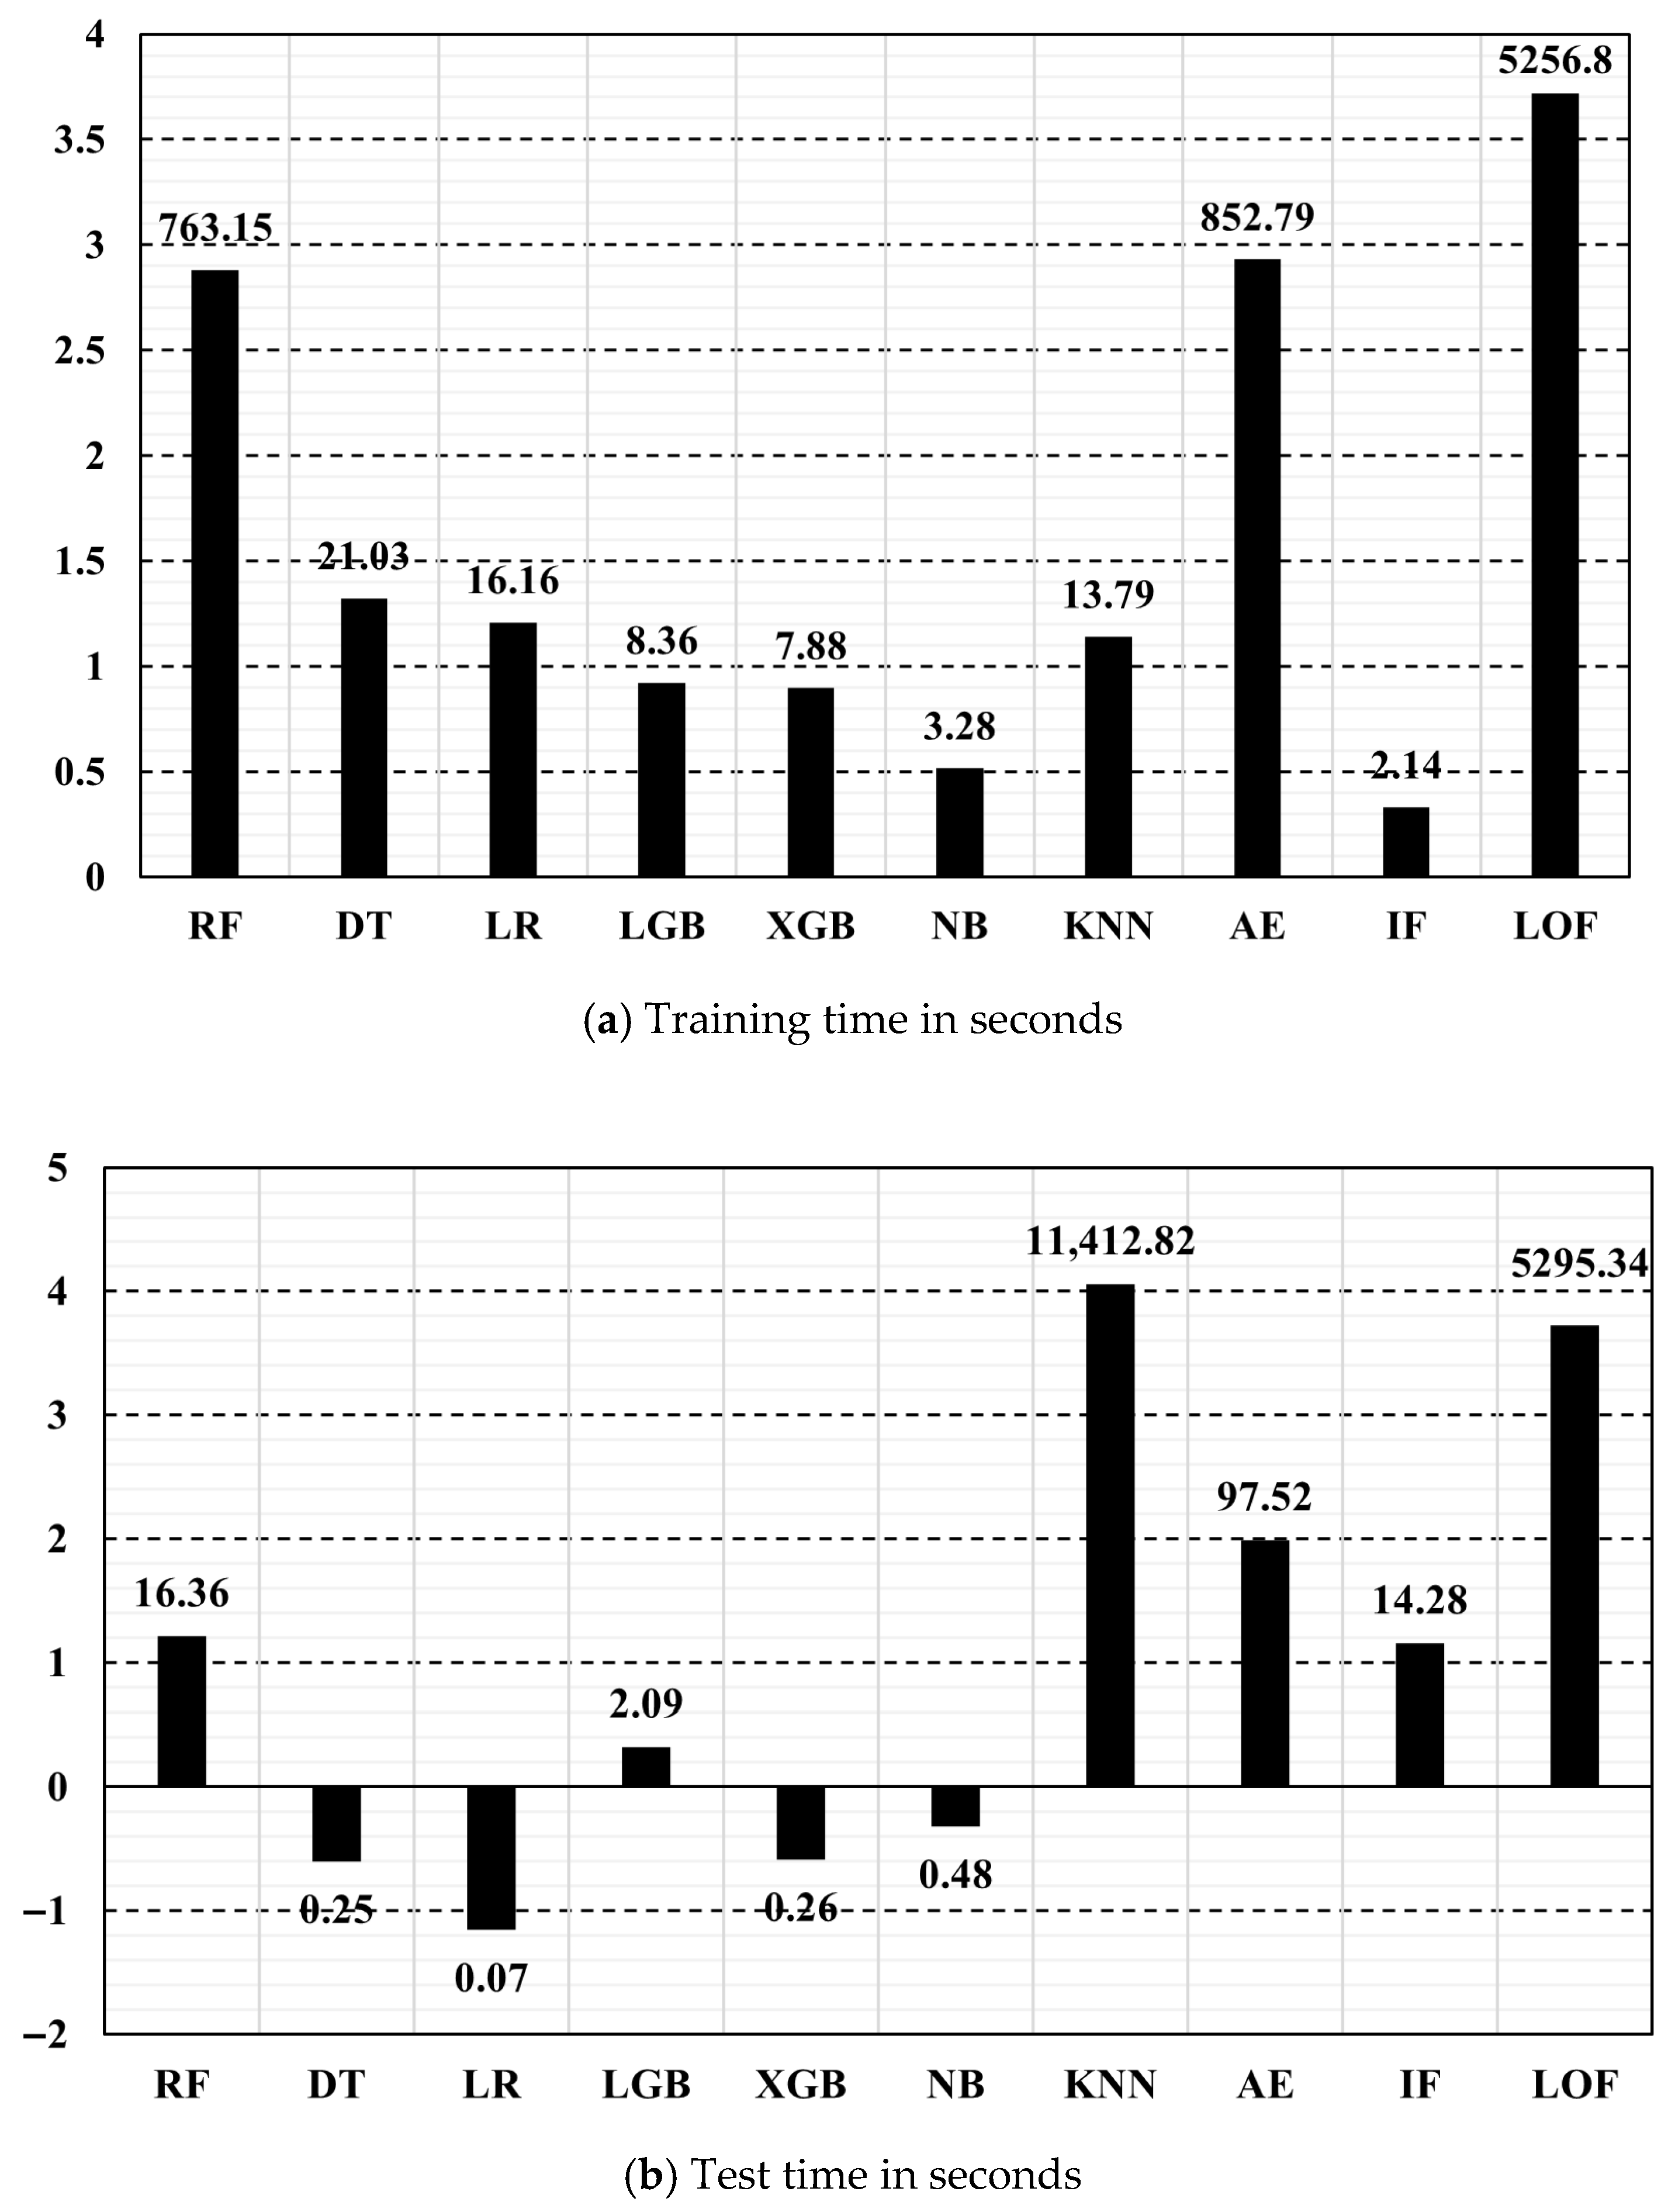
The computation time results in
Figure 13 demonstrate that our XGBoost-based detector is highly efficient even with a large-scale dataset. The benchmark experiments were conducted on an x86_64 system equipped with an AMD Ryzen Threadripper 7970X CPU (Advanced Micro Devices, Inc., Santa Clara, CA, USA) and an NVIDIA GeForce RTX 4090 GPU (NVIDIA Corporation, Santa Clara, CA, USA). Training was performed on 13,402,188 samples, and XGB completed training in 7.88 s, which is much faster than RF at 763.15 s and AE at 852.79 s, and far faster than LOF at 5256.80 s. For inference, testing on 1,662,318 samples took 0.24 s with XGB, which is comparable to DT at 0.25 s and slower than LR at 0.07 s, while several baselines are substantially slower, such as AE at 97.52 s, KNN at 11,412.82 s, and LOF at 5295.34 s. Normalized by the test set size, XGB requires about 0.14 microseconds per sample, which corresponds to roughly 6.9 million samples per second. Overall, XGB offers a favorable balance between high detection accuracy and low training and inference time, supporting its practicality for real-time SOME/IP monitoring.
6.4. Real-Time IDS Performance Scaling Under CPU Quota Constraints
In-vehicle IDS and IPS functions are increasingly consolidated on gateway or domain controller ECUs, which aggregate in-vehicle Ethernet traffic and multiple CAN and LIN networks. Compared to traditional single-MCU ECUs, these nodes require higher compute capability, diverse interfaces, and high bandwidth. Renesas states that a communication gateway ECU, described as a vehicle computer-type platform, requires application-level performance enabled by multiple Arm CPU clusters [
49]. Renesas also presents a vehicle gateway development kit example that combines aggregation and routing for TSN Ethernet and legacy buses such as CAN, CANFD, LIN, and FlexRay, while providing sufficient compute capacity to host security and networking applications [
50].
As a concrete example of commercial SoCs targeting gateway and domain controller ECUs, the NXP S32G family is a multicore Arm Cortex-A53 platform explicitly designed for service-oriented gateways and domain controllers [
51]. The S32G3 product brief further explains that the automotive network processor is designed to handle a combination of CAN, LIN, and FlexRay with high-speed Ethernet [
52]. In addition, the S32G3 family supports up to 8 Cortex-A53 cores, up to 1.3 GHz operating frequency, and up to 4 GB of external DRAM, such as DDR3L or LPDDR4, which aligns with the broader trend of gateway and domain ECUs evolving toward an Arm CPU cluster plus external memory architecture. Therefore, the experimental scope of this study, for example, a 4 to 8 core class environment with gigahertz class clocks and gigabyte class memory, is intended to cover the performance range of practical commercial gateway and domain controller ECUs and can be considered an empirically grounded and deployment-oriented evaluation setting [
49,
50,
51,
52].
All performance measurements were conducted on a workstation equipped with an AMD Ryzen Threadripper 7970X CPU, using CPU quota control and core pinning to emulate constrained compute budgets. For each environment, we performed the experiment on 100 randomly selected packets and calculated the average to ensure representative results. The experimental results are reported in
Table 5. The overall cost of the proposed SOME/IP-based IDS, including feature generation and XGBoost inference, is approximately 0.556 ms per packet, yielding a throughput of around 1800 packets per second (1/0.000556 ≈ 1799 pps), as shown in
Table 5. This result suggests that the framework can achieve sub-millisecond per-packet latency under the evaluated gateway- or domain-ECU-like resource constraints, supporting near-real-time IDS operation. Since feature generation dominates the total cost and inference is only a few tens of microseconds, optimization should primarily target the feature extraction path rather than the model.
6.5. Effectiveness of CTGAN in Real-World
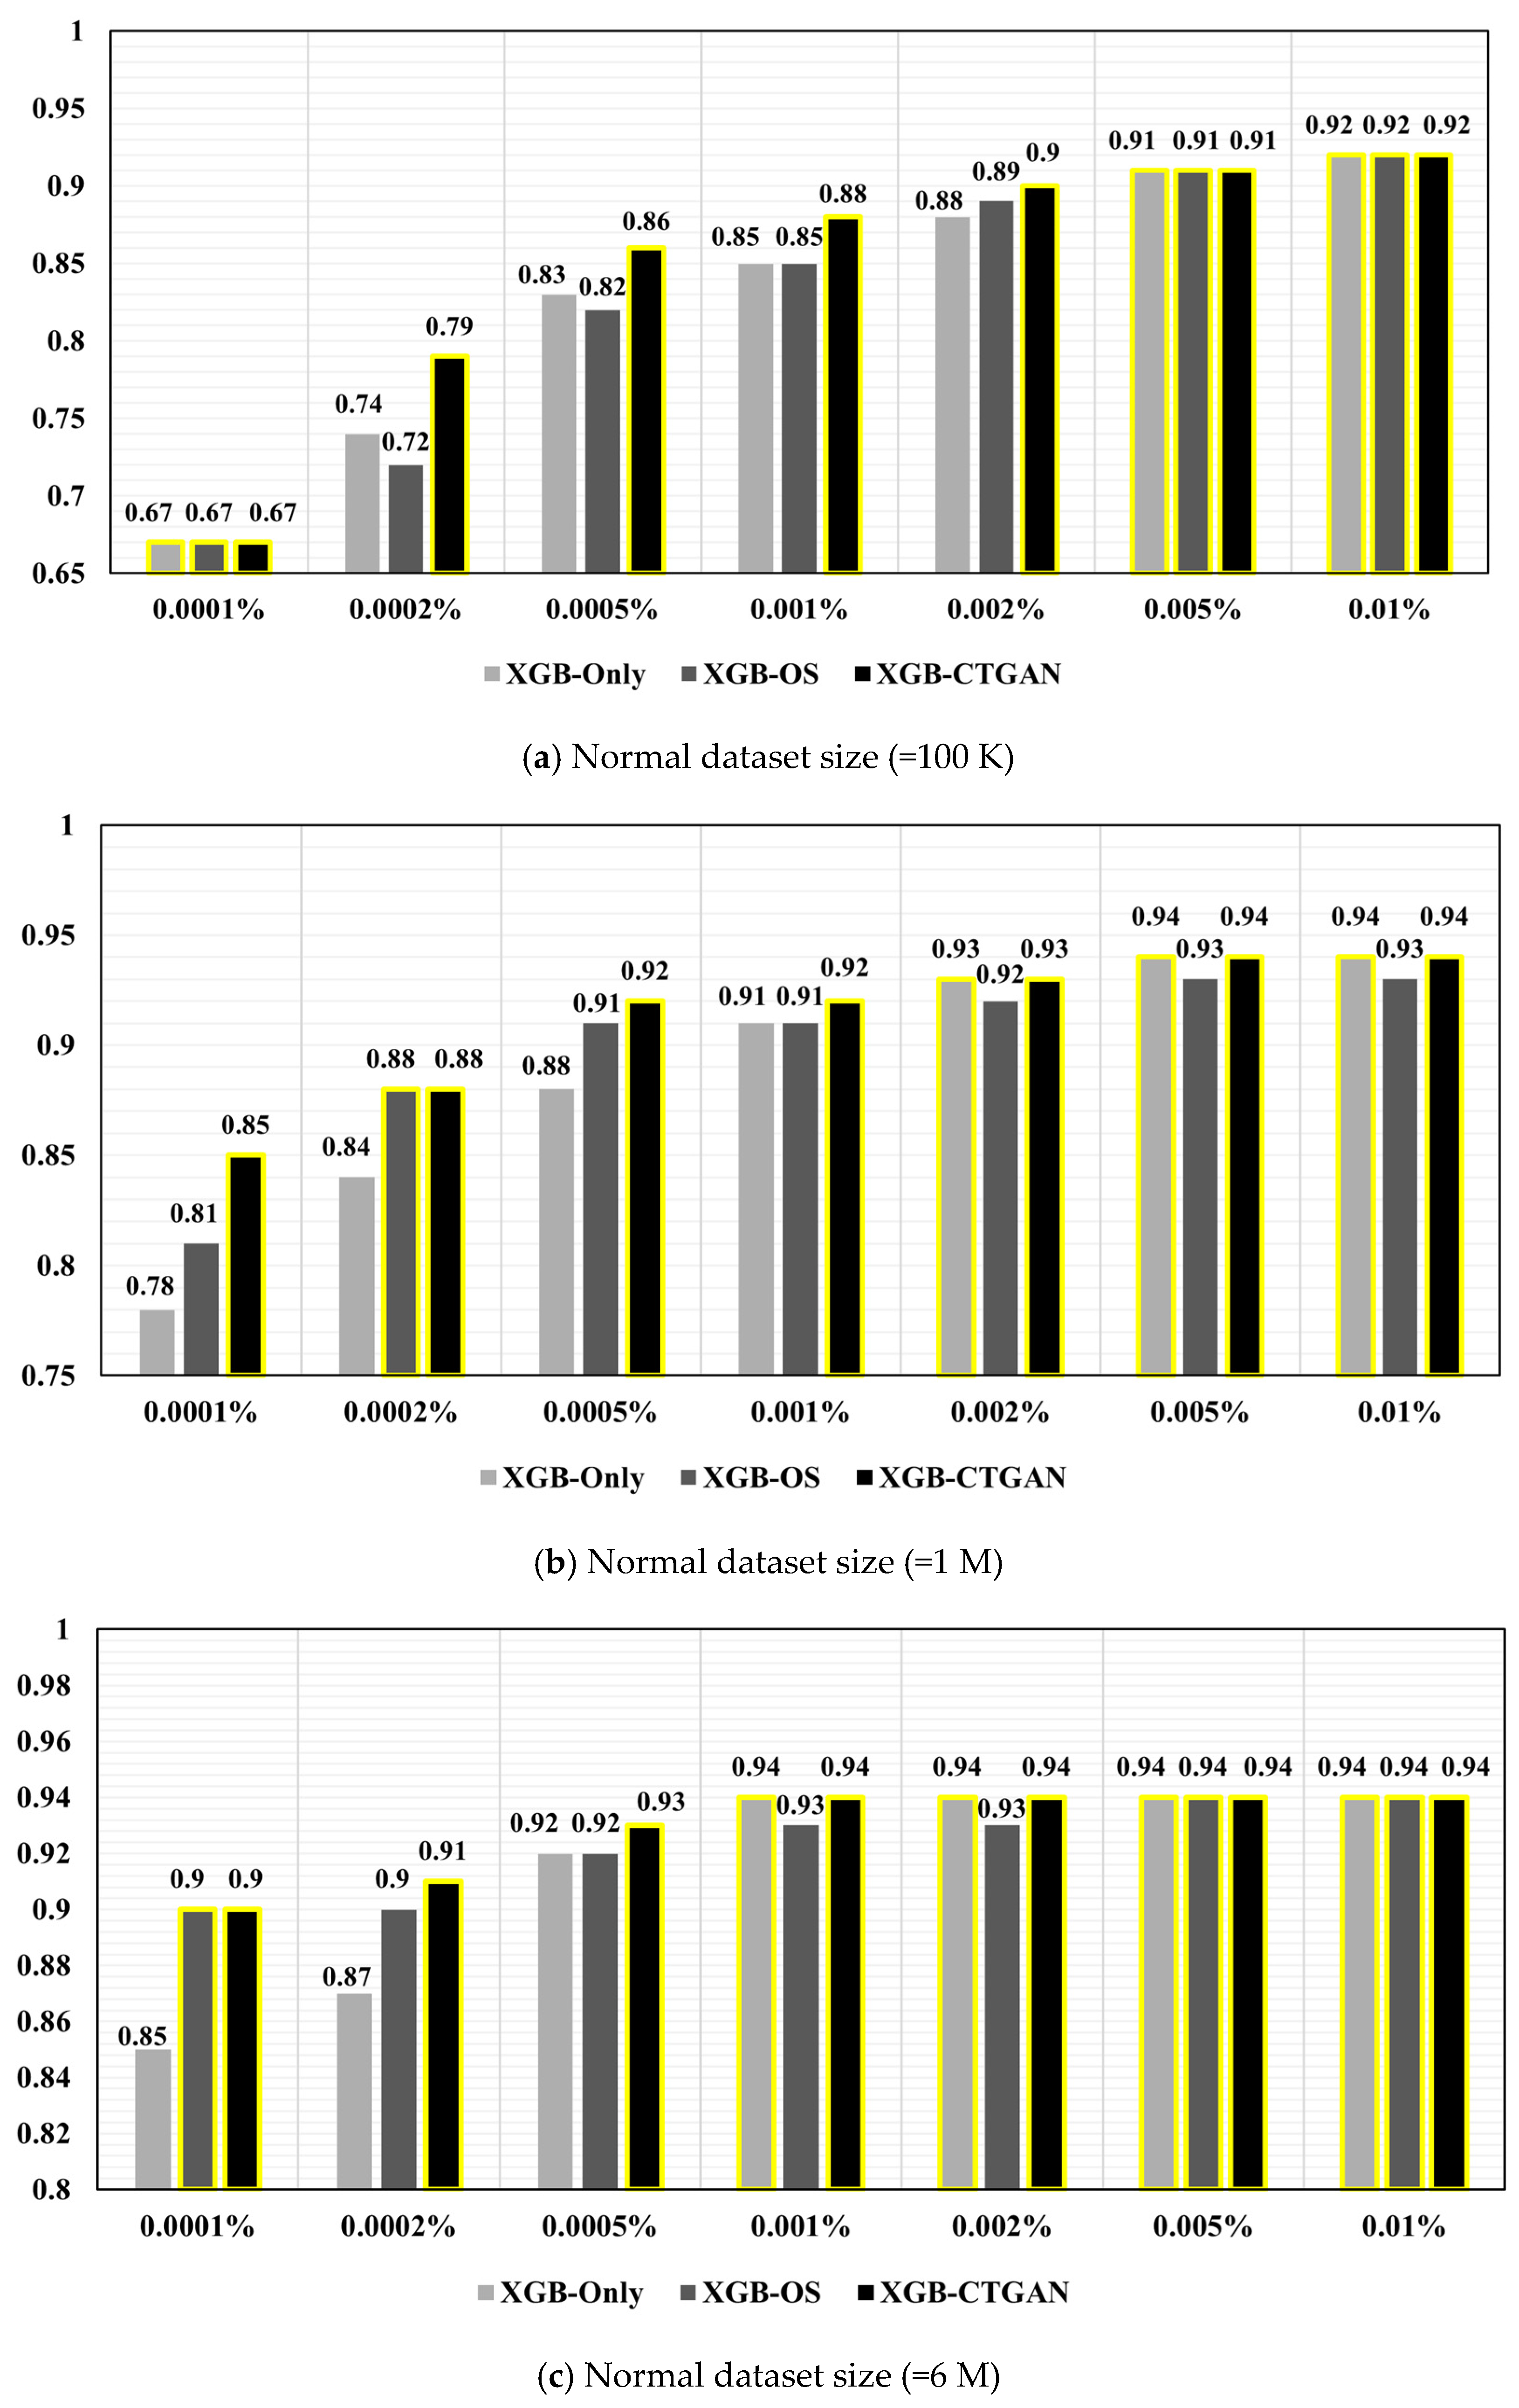
As shown in
Figure 14, we assessed CTGAN by comparing three training settings: XGBoost without CTGAN, XGBoost with random oversampling, and XGBoost with CTGAN. To evaluate these methods under different imbalance regimes, we varied both the normal data size and the attack ratio and measured the resulting F1 scores. As the attack ratio increases, all methods improve and eventually saturate, especially when the normal set is large. For instance, with 6 M normal samples, all three settings converge around an F1 of 0.94, and a similar convergence of 0.93–0.94 appears for 1 M normal samples at higher attack ratios, suggesting limited room for augmentation when conditions are favorable. In contrast, CTGAN shows its clearest benefit when attack samples are extremely scarce. With 1 M normal samples at the smallest attack ratio, F1 rises from 0.78 for XGB Only and 0.81 for XGB OS to 0.85 for XGB CTGAN. With 100 K normal samples at very low attack ratios, CTGAN also improves performance, for example, 0.79 versus 0.74 and 0.72, and at a slightly higher ratio, it reaches 0.88 while the others remain at 0.85. Overall, CTGAN does not dominate across all regimes, but it meaningfully improves robustness to extreme class imbalance by enriching minority-class representation and stabilizing performance in the most challenging settings.
6.6. Comparison with the Previous Approaches
We compared our framework with existing SOME/IP IDS approaches using the pre-down-sampled imbalanced set The SAID [
33] based experiment parses each PCAP into SOME/IP packets, assigns attack labels according to a fixed IP and port rule, represents each packet with a 58-byte payload vector, and trains a transformer-style attention model on sequences of 128 packets with class-balanced sampling. The Suricata [
34] style experiment 40 does not learn a model but applies a fixed rule engine on simple header-level cues, raising alerts based on conditions such as non-zero return codes, unexpected ports, and inconsistent session identifiers. The SISSA [
35] based experiment instead uses an 11-dimensional header and timing feature vector per packet, forms time-ordered sequences, and trains a residual self-attention network following the SISSA architecture.
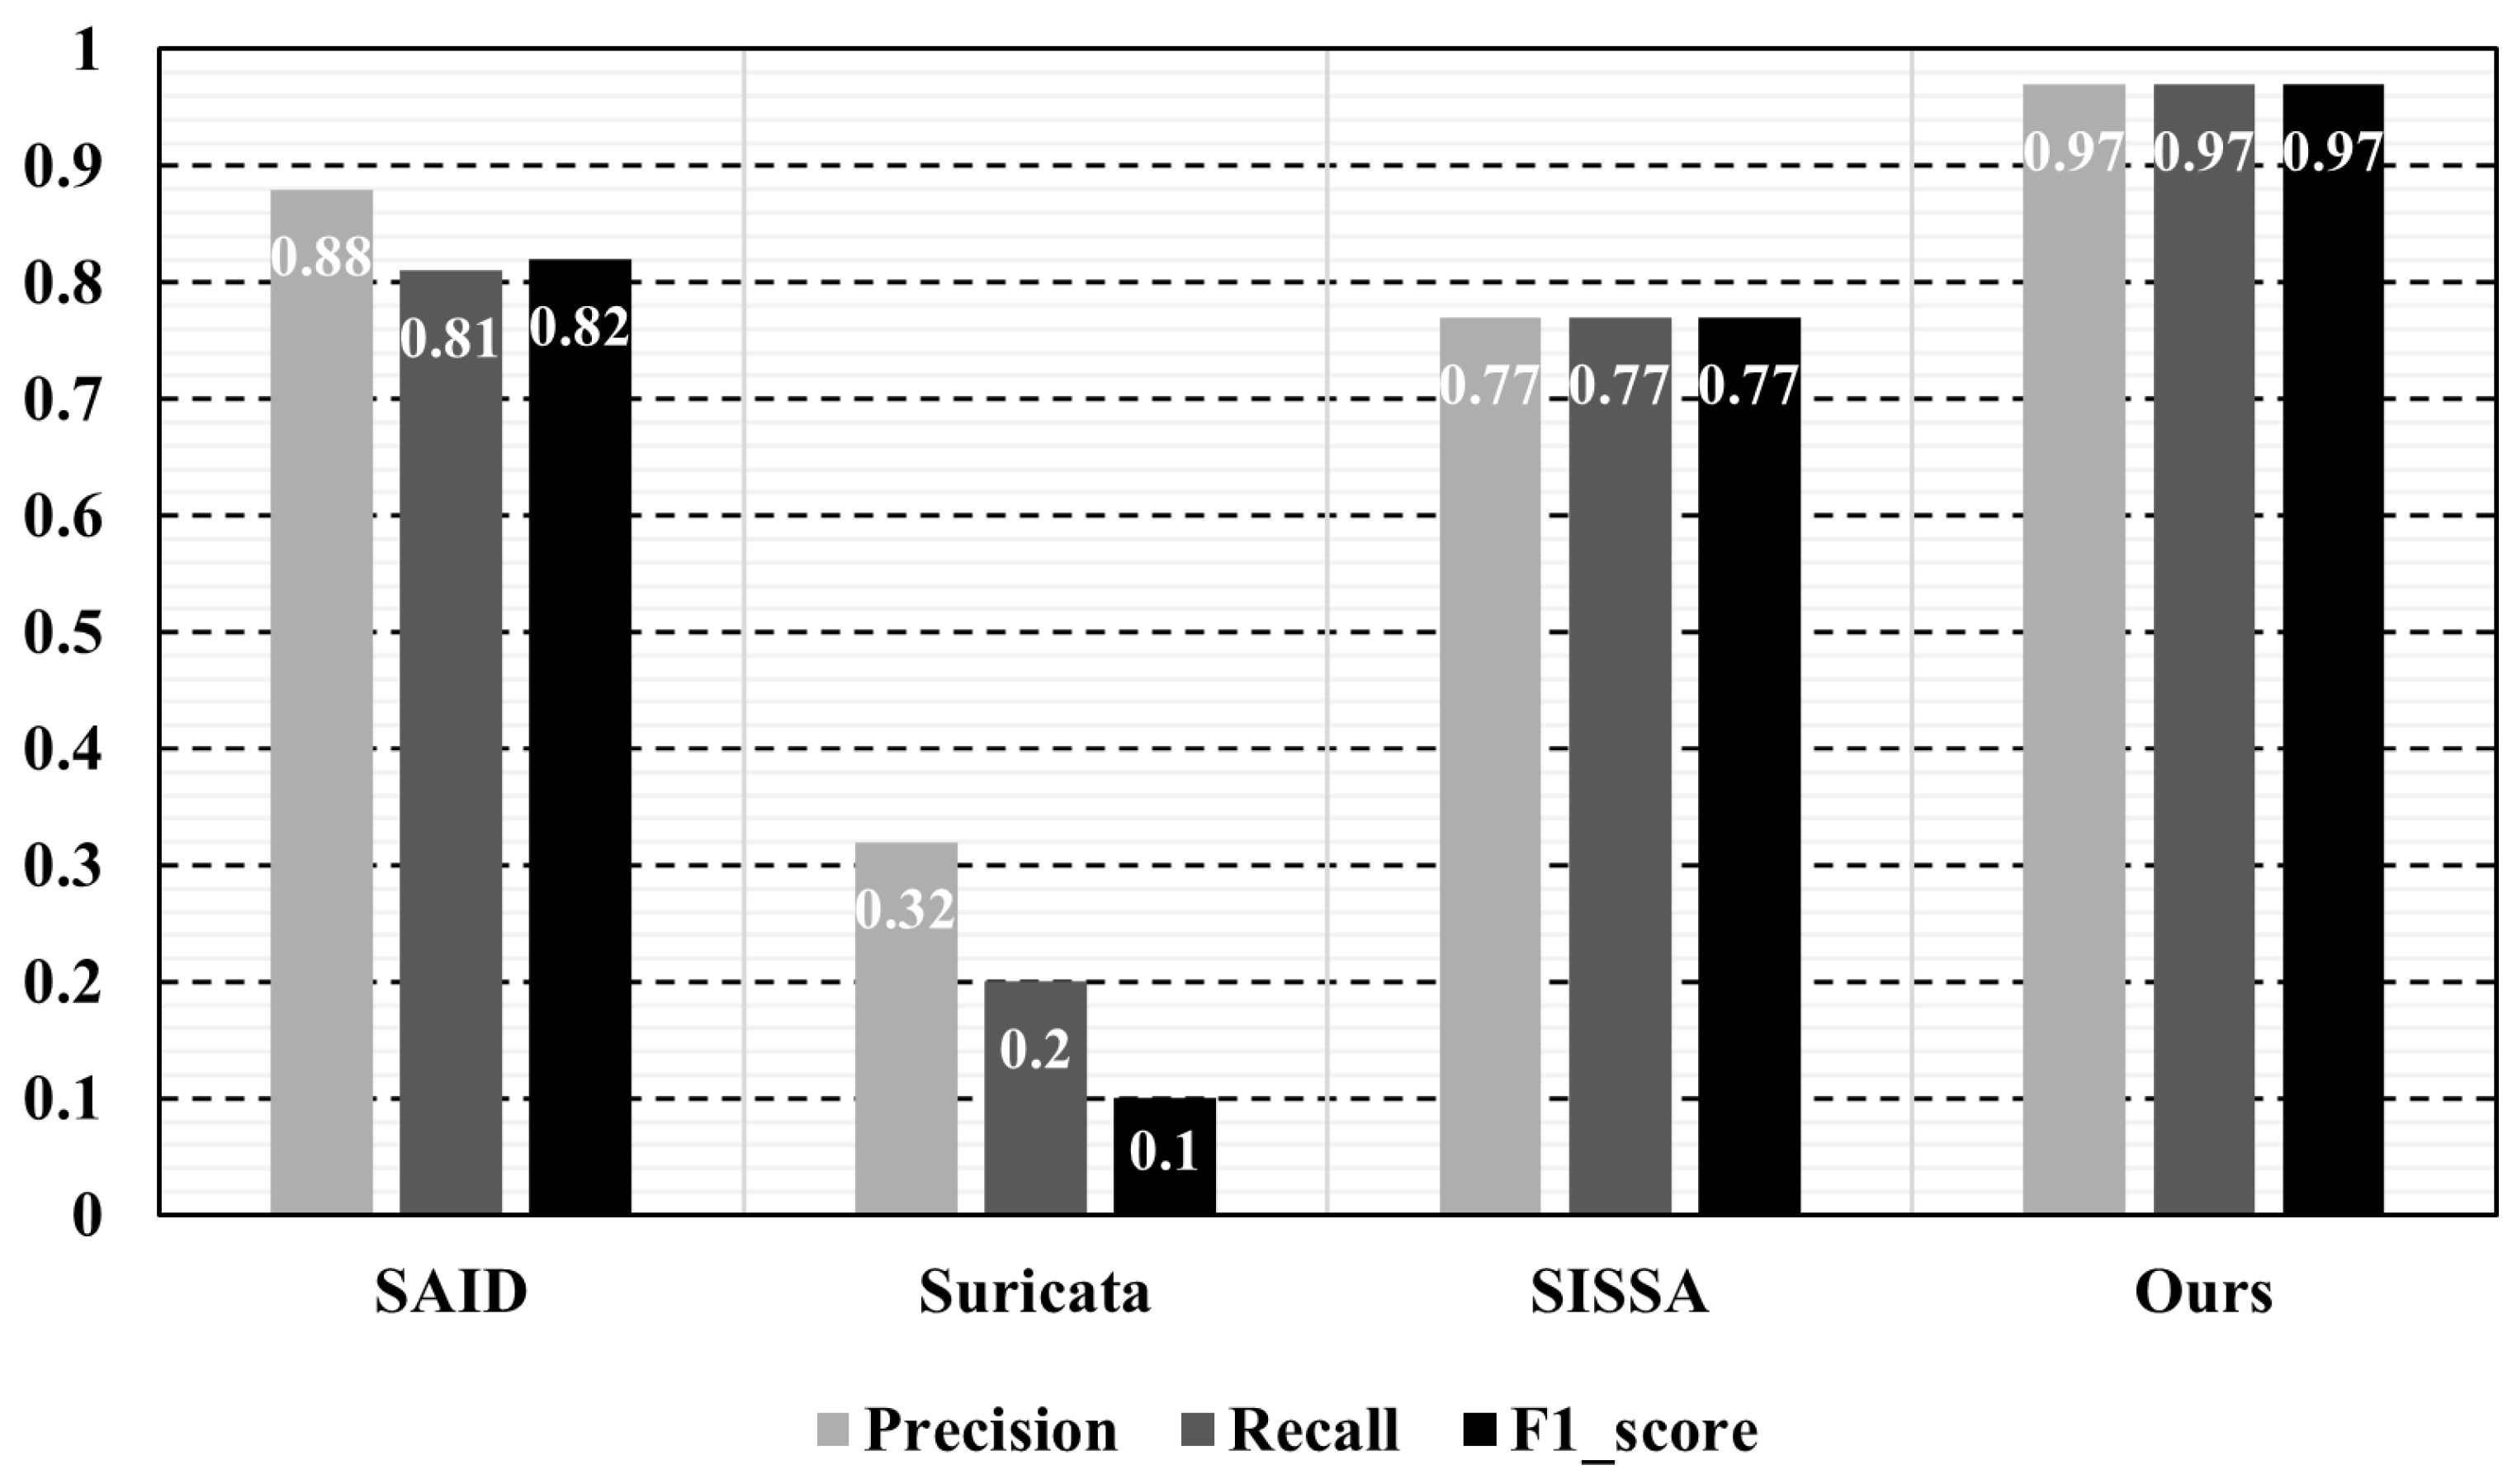
As shown in
Figure 15, SAID achieves a precision of 0.88, a recall of 0.81, and an F1 score of 0.82, while SISSA reports a precision of 0.77, a recall of 0.77, and an F1 score of 0.77. In contrast, Suricata exhibits substantially lower performance, with a precision of 0.32, a recall of 0.20, and an F1 score of 0.10, indicating limited detection capability under our mixed attack conditions. Our method achieves precision, recall, and F1 scores of 0.97, outperforming all three baselines and reducing both false positives and missed attacks. A plausible reason is that our detector leverages richer behavior-centric features and a supervised classifier tuned to diverse DoS, fuzzing, and MitM behaviors, whereas SAID relies primarily on fixed payload slices, SISSA uses compact header and timing cues, and Suricata’s static rules cannot adapt to traffic variations. To strengthen this interpretation, further analyses, such as feature ablation, evaluations across different attack mixtures, and retraining all methods under identical class-balancing and hyperparameter settings, would be valuable.
7. Conclusions
SOME/IP has become core middleware for automotive Ethernet and AUTOSAR-based in-vehicle networks, enabling scalable, service-oriented communication among distributed ECUs. However, its lack of built-in authentication, encryption, and integrity protection exposes modern vehicles to practical threats such as DoS, fuzzing, and MitM attacks, while existing intrusion-detection studies have largely focused on CAN/CANFD and therefore fail to capture the dynamic service structure and multi-layer behaviors unique to SOME/IP. To address these gaps, we proposed an end-to-end XGBoost-based anomaly detection framework tailored for SOME/IP traffic. The framework parses raw Ethernet frames into layered representations, extracts behavior-centric features, and constructs normalized feature vectors for real-time classification. To overcome the severe class imbalance inherent to attack data collection, we further integrated CTGAN-based augmentation that learns attack-specific feature distributions and generates synthetic attack records to balance the training set. Extensive experiments on a large-scale SOME/IP dataset collected from a realistic multi-ECU vSomeIP simulation validate these benefits. Our model achieved the best overall detection performance among ten baselines, reaching 0.97 precision, 0.97 recall, and 0.97 F1-score on the imbalanced test set, outperforming both conventional supervised models and unsupervised detectors. In addition, the proposed framework achieves 0.556 ms per packet, with feature generation dominating latency while XGBoost inference takes only a few tens of microseconds. These results confirm that the proposed XGBoost-based framework effectively mitigates SOME/IP-specific vulnerabilities and provides a practical, accurate, and low-latency intrusion-detection solution for next-generation in-vehicle Ethernet environments.
8. Limitations and Future Work
The proposed detector is most effective when attacks induce measurable deviations in timing patterns, subscription dynamics, or payload statistics relative to benign behavior. It may be less sensitive to low and slow adversaries that deliberately mimic normal timing and payload distributions, to replay-style behaviors that reuse previously observed benign payloads, or to attacks whose impact is primarily semantic at the application layer while remaining statistically similar at the byte level. In addition, concept drift caused by software updates, service-interface changes, or shifting background workloads can alter normal traffic characteristics and increase false alarms unless the model and thresholds are periodically recalibrated. Finally, because our evaluation relies on a vSomeIP-based simulation environment and primarily models a publish–subscribe baseline, absolute performance may vary across real vehicles due to differences in ECU implementations, scheduling, and network conditions. Nevertheless, the behavioral feature design is intended to generalize at the SOME/IP and SOME/IP Service Discovery interaction level.
Future work will extend the simulation and evaluation to cover a broader range of SOME/IP communication models and service interfaces beyond the publish–subscribe baseline, including request–response, fire and forget, and getter/setter interactions, as well as more diverse service mixes and traffic regimes. We will also explore adaptive and online learning strategies to cope with evolving in-vehicle communication patterns and emerging attack strategies. In addition, we did not prioritize systematic hyperparameter optimization in this study because preliminary tests on smaller subsets showed no material performance changes; however, we agree that it remains beneficial and will apply more systematic searches (e.g., grid search) to further refine XGBoost settings across different deployment constraints and datasets. We also plan to investigate calibration and drift-monitoring mechanisms to maintain stable false-alarm rates over time.