1. Introduction
The maritime shipping industry serves as the backbone of global commerce, facilitating approximately 90% of international trade through ocean transportation [
1]. However, this critical sector simultaneously represents a substantial source of atmospheric pollution, contributing an estimated 2.89% of global anthropogenic CO
2 emissions and significant quantities of nitrogen oxides (NO
x), sulfur oxides (SO
x), and particulate matter [
2,
3]. The environmental impact of maritime emissions has garnered increasing regulatory attention, with the International Maritime Organization (IMO) implementing progressively stringent measures, including the Global Sulfur Cap, limiting fuel sulfur content to 0.5%, and the Energy Efficiency Design Index (EEDI) requirements, targeting greenhouse gas reduction [
4,
5].
Traditional approaches to ship emission monitoring rely predominantly on periodic manual measurements and basic sensor readings, which provide limited temporal resolution and lack the predictive capabilities necessary for proactive environmental management [
6]. These conventional methods prove inadequate for meeting contemporary regulatory requirements and optimizing vessel operations for environmental compliance [
7]. The inherent complexity of ship emission patterns, influenced by multiple interconnected operational parameters, including engine load, fuel quality, ambient conditions, and navigation profiles, demands sophisticated analytical frameworks capable of capturing non-linear relationships and temporal dependencies [
8,
9].
Recent advances in machine learning and artificial intelligence have created unprecedented opportunities for developing intelligent emission monitoring systems that can process complex, high-dimensional sensor data in real time [
10,
11]. Machine learning techniques have demonstrated remarkable success in environmental monitoring applications, offering capabilities for pattern recognition, predictive modeling, and automated decision support [
12]. Deep learning methods, particularly those designed for sequential data processing, have shown exceptional performance in capturing the temporal dynamics inherent in emission patterns [
13,
14]. Ensemble methods have emerged as particularly effective approaches for environmental prediction problems, combining multiple diverse models to achieve superior performance compared to individual algorithms [
15,
16].
Despite these advances, several critical challenges remain inadequately addressed in existing ship emission prediction systems. First, the multi-scale temporal nature of emission dynamics, where short-term fluctuations, medium-term operational cycles, and long-term trends all contribute to emission patterns, requires specialized feature extraction approaches that can simultaneously capture information across different time horizons [
17]. Second, the heterogeneous characteristics of different emission gases necessitate adaptive modeling approaches that can automatically adjust to the specific temporal patterns of each pollutant [
18]. Third, the regulatory compliance requirements of maritime applications demand not only accurate point predictions but also reliable uncertainty quantification that can support risk-based decision-making [
19,
20].
This research addresses these challenges through the development of MSTU-HAE (Multi-Scale Temporal Uncertainty-aware Hierarchical Adaptive Ensemble), a novel algorithmic framework specifically designed for ship emission monitoring applications. While the individual components of MSTU-HAE—multi-scale temporal feature extraction, attention mechanisms, ensemble learning, and uncertainty quantification—each draw on the established machine learning literature, the contribution of this work lies in their principled integration into a unified framework specifically tailored to the operational dynamics of marine vessel emission monitoring. More precisely, the contributions are threefold. First, multi-scale temporal feature extraction is adapted with causal convolutions calibrated to three timescales specific to marine vessel operation—short-term engine transients, medium-term operational cycles, and long-term cumulative trends—with strict causal constraints to prevent temporal data leakage [
21]. Second, a gas-specific attention mechanism is designed to automatically determine temporal scale importance for each of the 12 monitored emission gases, reflecting their distinct physicochemical formation mechanisms. Third, a three-level hierarchical uncertainty quantification framework is integrated that bridges statistical prediction uncertainty and maritime regulatory compliance risk assessment—a combination not previously demonstrated in the ship emission prediction literature. The novelty of this work resides in this application-specific integration and its demonstrated utility for multi-gas maritime emission monitoring. The remainder of this paper is organized as follows.
Section 2 reviews related work in machine learning for environmental monitoring and ship emission prediction.
Section 3 presents the detailed methodology of the MSTU-HAE algorithm, including multi-scale feature extraction, attention mechanisms, and hierarchical uncertainty quantification.
Section 4 describes the experimental setup, including data collection, preprocessing, and evaluation protocols.
Section 5 presents and discusses the experimental results.
Section 6 addresses practical implications and limitations, and
Section 7 concludes this paper with directions for future research.
3. Results
3.1. MSTU-HAE Algorithm Overview
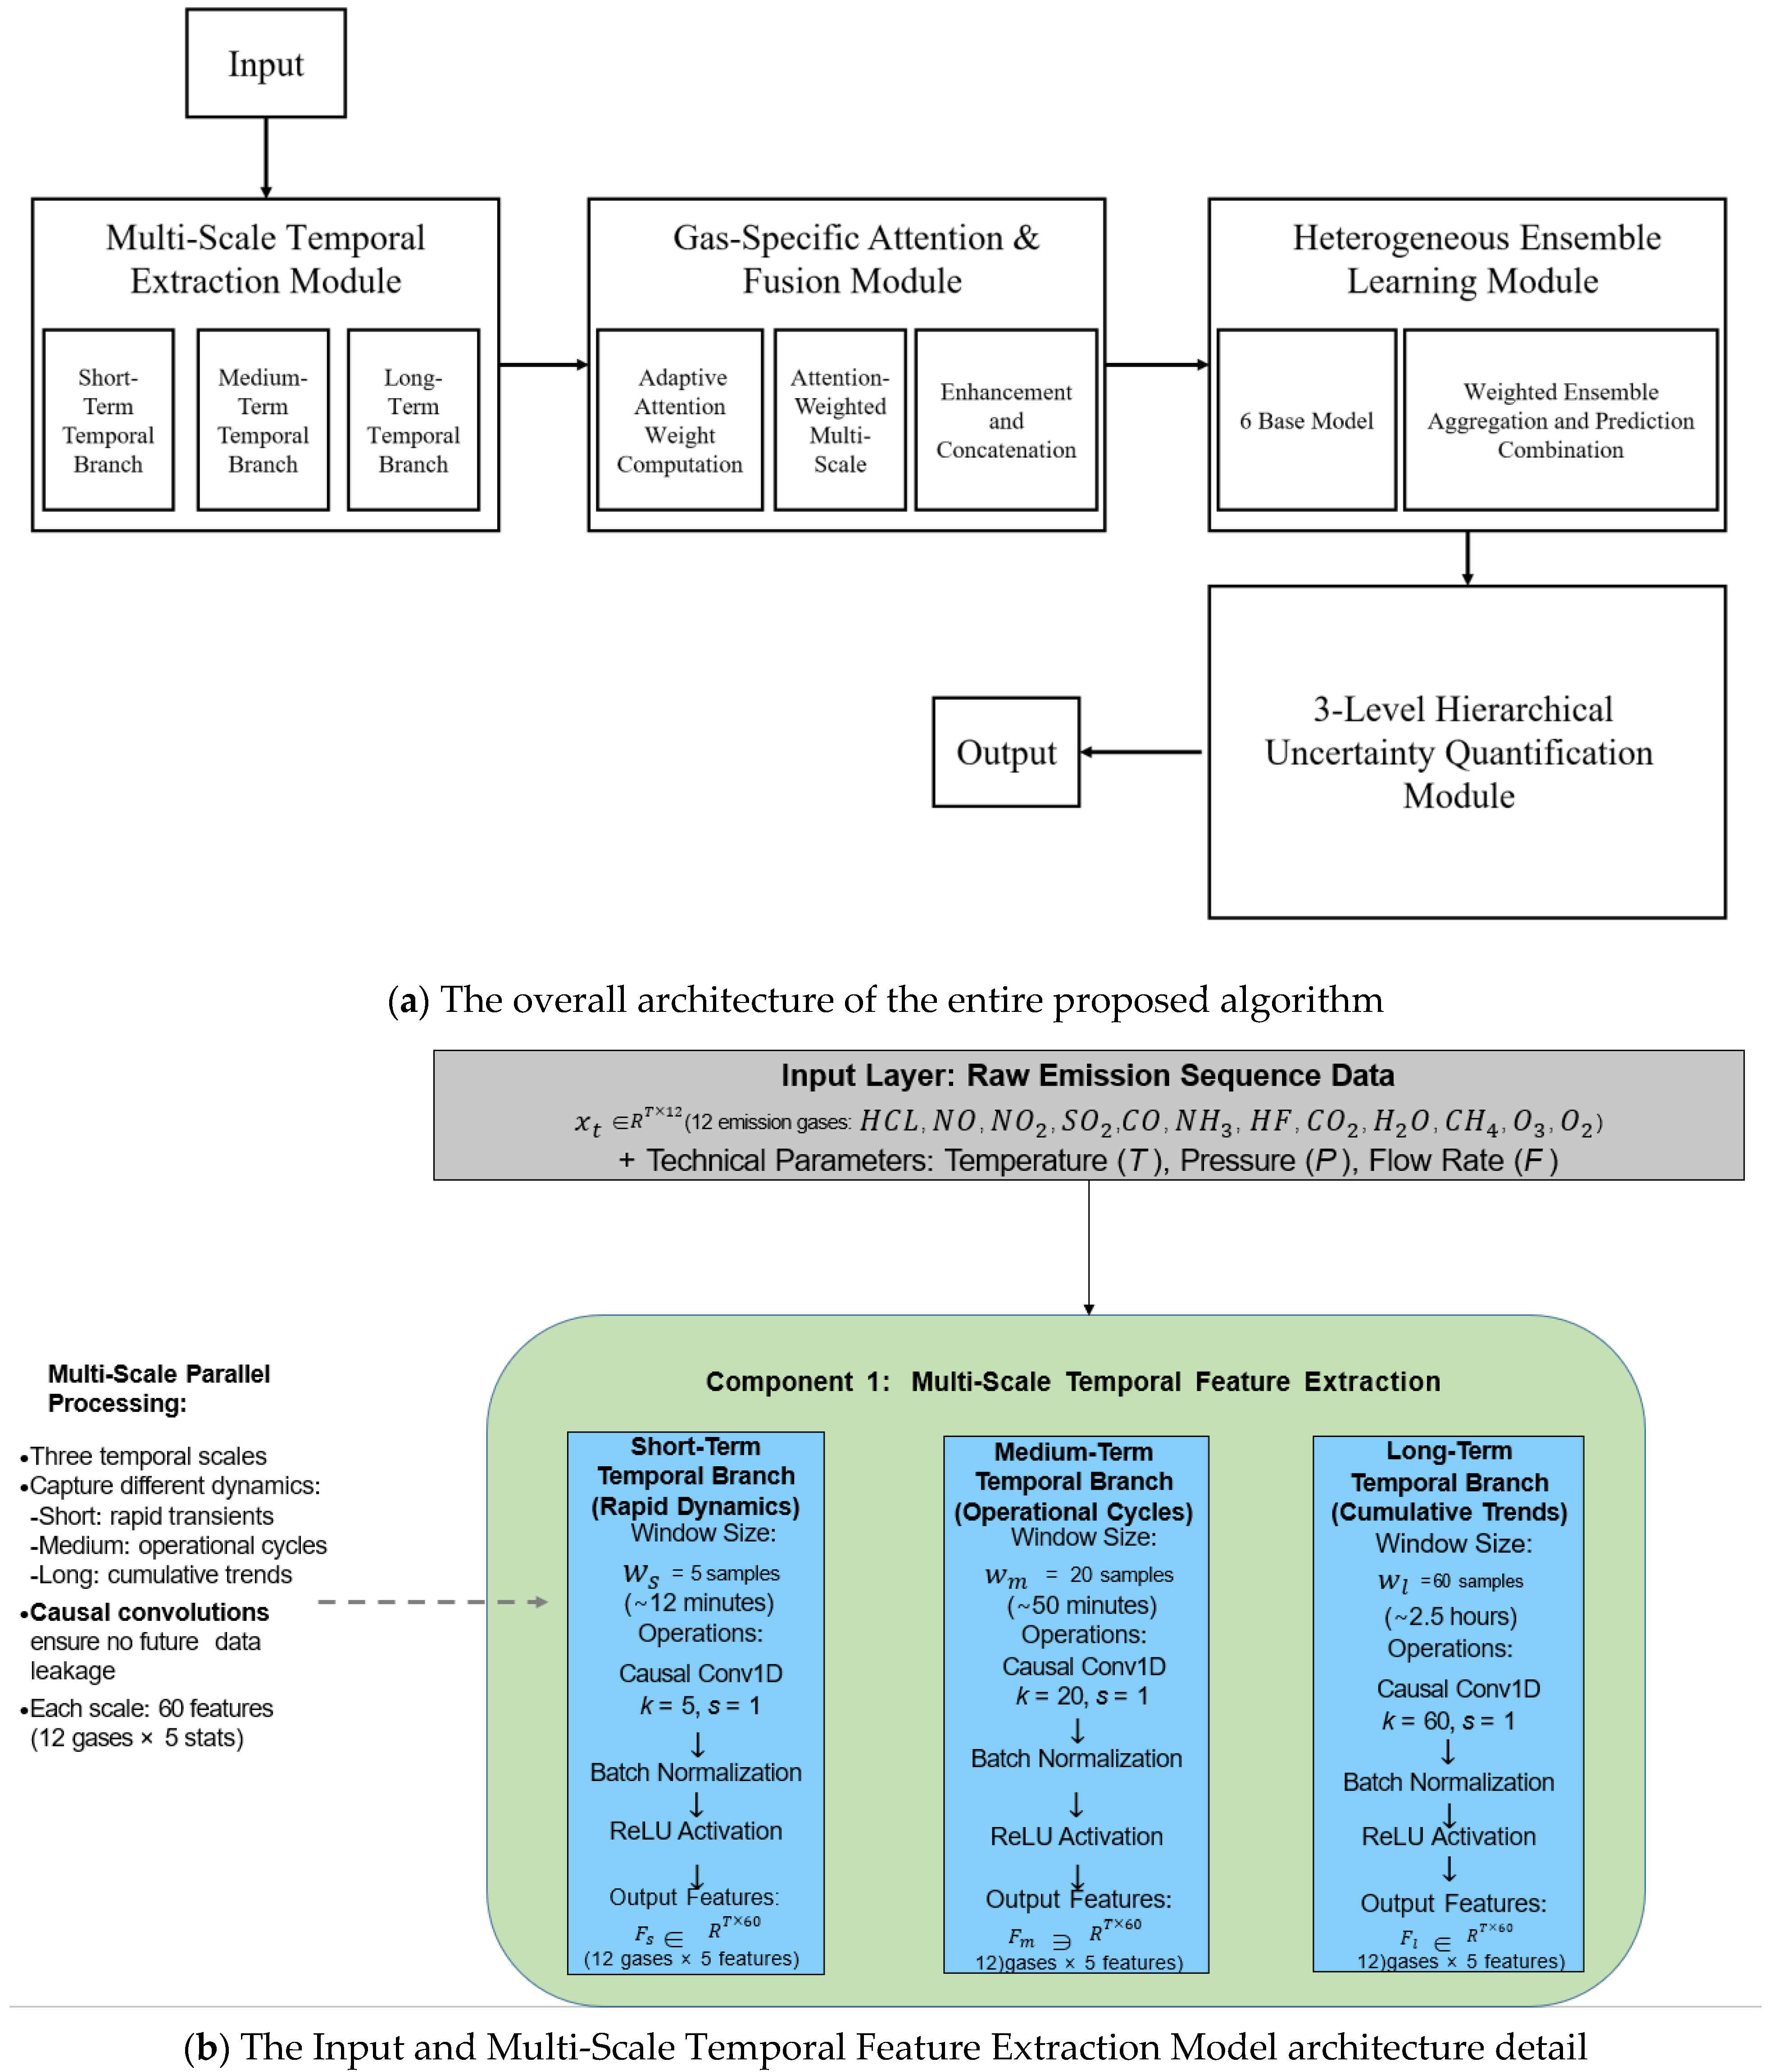
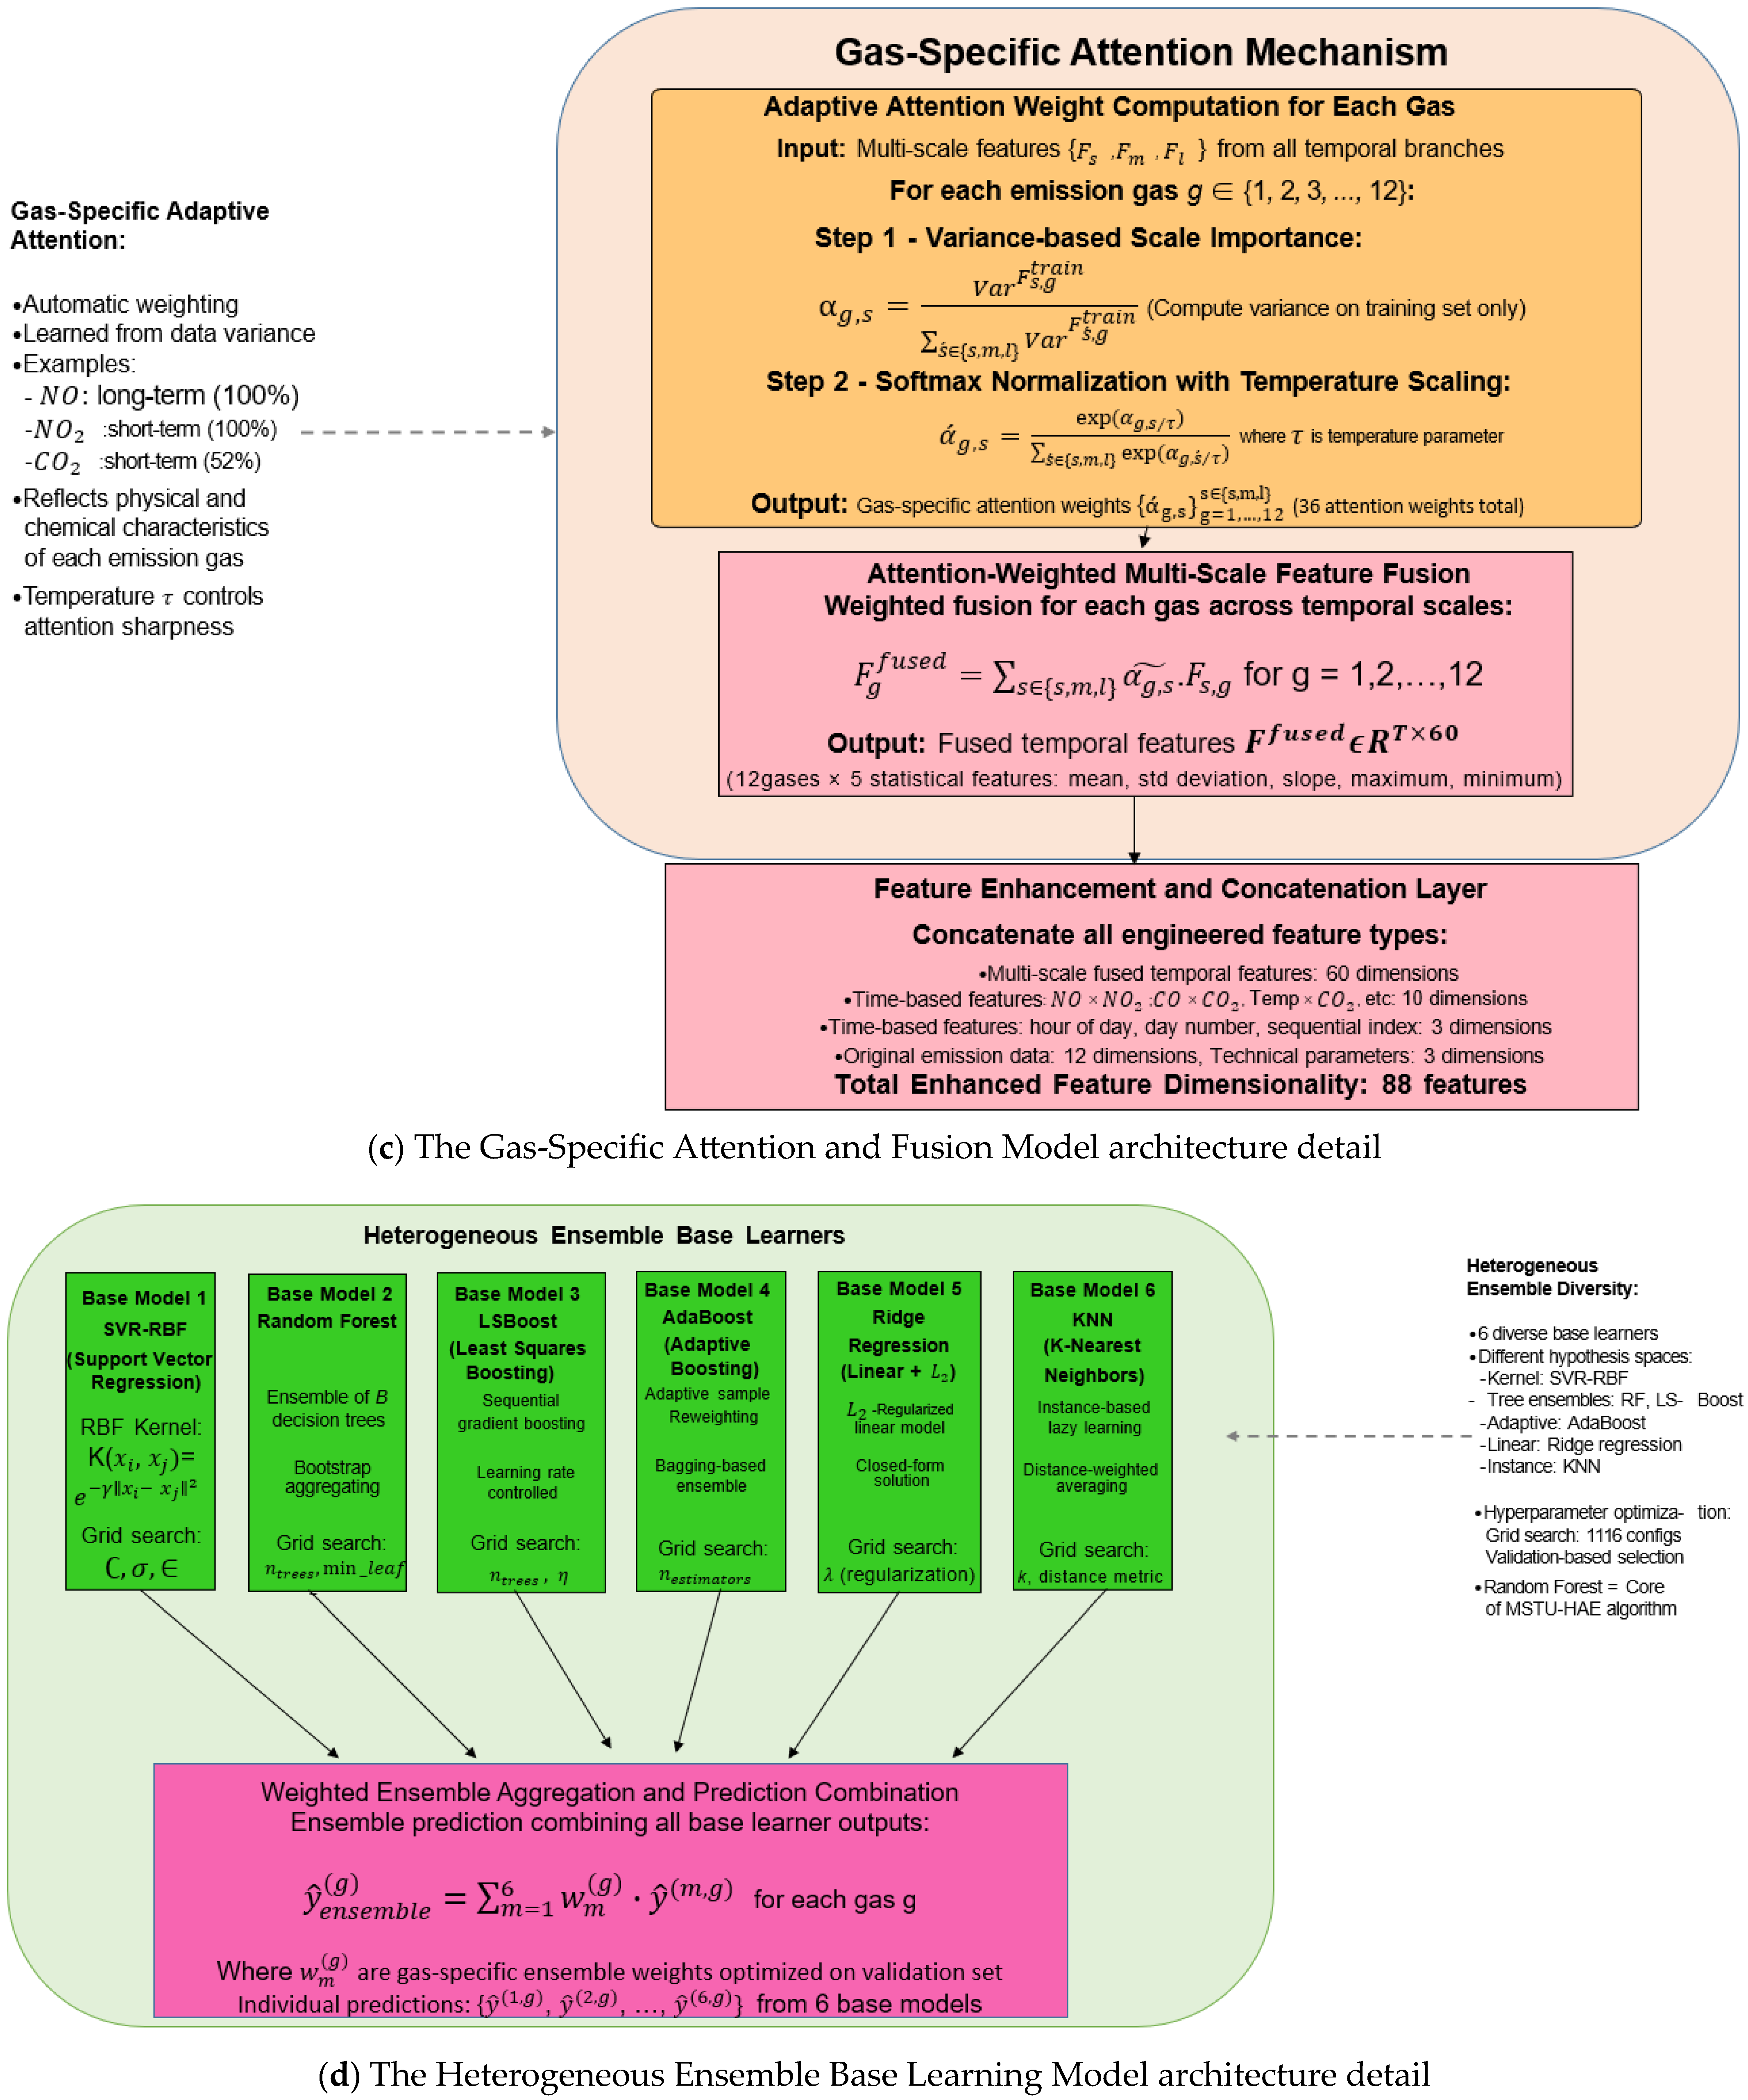
The proposed MSTU-HAE (Multi-Scale Temporal Uncertainty-aware Hierarchical Adaptive Ensemble) algorithm comprises five integrated components designed to address the specific challenges of ship emission prediction.
Figure 1 illustrates the overall architecture of the proposed framework, showing the data flow from raw emission measurements through multi-scale feature extraction, attention-weighted fusion, base model training, and hierarchical uncertainty quantification.
The algorithm proceeds through the following stages: (1) temporal data preprocessing with strict train/validation/test separation to prevent data leakage; (2) multi-scale temporal feature extraction using causal sliding windows at three distinct scales; (3) gas-specific attention mechanism computation based on scale informativeness; (4) attention-weighted feature fusion to create unified representations; (5) parallel training of diverse base models with comprehensive hyperparameter optimization; and (6) three-level hierarchical uncertainty quantification, integrating individual model uncertainty, ensemble disagreement, and regulatory compliance risk.
3.2. Temporal Data Preprocessing
The data preprocessing pipeline implements rigorous protocols to ensure data quality and prevent information leakage between training and evaluation phases. Given raw emission measurements , where represents the number of temporal samples, and represents the number of emission gases, the preprocessing proceeds as follows.
The temporal split strategy partitions the dataset into training, validation, and test sets using consecutive temporal ordering:
where
, and
. This temporal partitioning ensures that models are evaluated on strictly future data, reflecting the realistic deployment scenario where trained models must predict emissions based on historical observations.
Missing value imputation employs median-based approaches computed exclusively from training data to prevent information leakage:
This imputation strategy is robust to outliers while maintaining the statistical properties of the emission distributions. Outlier detection utilizes the Interquartile Range (IQR) method with a conservative threshold of
:
where
and
represent the first and third quartiles computed from training data, and
. Detected outliers are retained to preserve natural operational variability while being flagged for quality assessment.
3.3. Multi-Scale Temporal Feature Extraction
The multi-scale temporal feature extraction component addresses the challenge of capturing emission dynamics across different time horizons. Ship emissions exhibit complex temporal patterns including rapid fluctuations associated with engine transients, medium-term variations corresponding to operational cycles, and longer-term trends reflecting cumulative effects and equipment degradation. A single temporal scale cannot adequately capture this diverse range of dynamics.
We define three temporal scales corresponding to distinct operational phenomena:
Short-term scale ( samples, approximately 12 min): captures rapid transient responses to engine load changes and operational adjustments.
Medium-term scale ( samples, approximately 50 min): captures operational cycle patterns and quasi-steady-state variations.
Long-term scale ( samples, approximately 2.5 h): captures cumulative trends, thermal equilibration effects, and longer-duration operational modes.
For each scale, , and each emission gas, , we extract five statistical features using causal (backward-looking) sliding windows that ensure no future information leaks into feature computation:
Moving standard deviation:
Moving trend (linear regression slope):
where
and
.
The complete multi-scale temporal feature extraction procedure is formalized in Algorithm 1, which details the causal sliding window implementation ensuring no future information leakage. The algorithm processes each temporal scale sequentially, computing five statistical features for each gas at every time step using only historically available data.
| Algorithm 1: Multi-scale temporal feature extraction with causal convolutions. |
Input: Emission data X ∈ ℝ^(N×G), temporal scales W = {w_s, w_m, w_l}
Output: Multi-scale feature matrix F_ms ∈ ℝ^(N × (G × 5 × |W|))
1: Initialize F_ms ← empty matrix of size N × (G × 5 × |W|)
2: for each scale w ∈ W do
3: for each gas g ∈ {1,…, G} do
4: for each time step t ∈ {1,…, N} do
5: //Define causal window (only past data)
6: if t < w then
7: window_start ← 1
8: window_end ← t
9: else
10: window_start ← t — w + 1
11: window_end ← t
12: end if
13:
14: //Extract window data
15: x_window ← X[window_start:window_end, g]
16: k ← length(x_window)
17:
18: //Compute five statistical features
19: μ ← mean(x_window) //Moving mean
20: σ ← std(x_window) //Moving std
21: x_max ← max(x_window) //Moving max
22: x_min ← min(x_window) //Moving min
23:
24: //Compute linear regression slope
25: time_indices ← [1, 2,…, k]
26: β ← linear_regression_slope(time_indices, x_window)
27:
28: //Store features
29: feature_idx ← compute_feature_index(g, w)
30: F_ms[t, feature_idx:(feature_idx+4)] ← [μ, σ, β, x_max, x_min]
31: end for
32: end for
33: end for
34: return F_ms |
The computational complexity of Algorithm 1 is , where is the maximum window size. For our implementation with samples, gases, and scales, the feature extraction completes in approximately 45 s on standard computing hardware. The causal constraint implementation (lines 6–12) is critical for preventing temporal data leakage—a common methodological error in time series prediction that artificially inflates performance metrics by allowing models to learn from future information. The resulting 180-dimensional multi-scale feature matrix captures emission dynamics across short-term transients (5 samples), medium-term operational cycles (20 samples), and long-term cumulative effects (60 samples), providing a comprehensive temporal context for subsequent modeling stages.
The resulting multi-scale feature matrix for each scale has dimensions , yielding a total of multi-scale temporal features for emission gases.
3.4. Gas-Specific Attention Mechanism
Different emission gases exhibit distinct temporal characteristics arising from their different formation mechanisms, concentration ranges, and response dynamics. For example, concentrations tend to exhibit relatively smooth variations directly correlated with combustion rate, while formation involves complex temperature-dependent kinetics, leading to more variable temporal patterns. A uniform weighting of temporal scales across all gases would fail to exploit these differences.
The gas-specific attention mechanism computes adaptive weights for each temporal scale based on the informativeness of that scale for each emission gas. The attention weight for gas
and scale
is computed as:
where
represents the feature vector for gas
at scale
computed over training data. This variance-based weighting assigns higher attention to scales that exhibit greater variability, under the assumption that higher variance indicates greater information content for prediction.
To ensure numerical stability and prevent attention collapse to a single scale, we apply softmax normalization with temperature scaling:
where
is a temperature parameter controlling the sharpness of the attention distribution.
The attention-weighted fused features for each gas are computed as the weighted sum across scales:
The practical implementation of the gas-specific attention mechanism is detailed in Algorithm 2, which computes adaptive weights for each temporal scale based on variance-driven informativeness measures. This automatic scale selection mechanism eliminates the need for manual hyperparameter tuning while ensuring optimal temporal feature utilization for each emission species.
| Algorithm 2: Gas-specific attention mechanism computation. |
Input: Multi-scale features F_ms^train ∈ ℝ^(N_train×(G×5×|W|)),
temporal scales W = {short, medium, long},
temperature parameter τ
Output: Attention weights α ∈ ℝ^(G×|W|)
1: Initialize α ← zeros(G, |W|)
2: for each gas g ∈ {1,…, G} do
3: //Extract gas-specific features for all scales
4: for each scale s ∈ W do
5: feature_idx ← compute_feature_index(g, s)
6: F_g,s ← F_ms^train[:, feature_idx:(feature_idx+4)]
7:
8: //Compute variance as informativeness measure
9: var_s ← variance(F_g,s)
10: end for
11:
12: //Store raw scores
13: scores ← [var_short, var_medium, var_long]
14:
15: //Handle edge cases
16: if all(scores == 0) then
17: scores ← [1, 1, 1] //Uniform if no variance
18: end if
19:
20: //Apply softmax normalization with temperature scaling
21: scores ← scores/τ
22: scores ← scores − max(scores) //Numerical stability
23: exp_scores ← exp(scores)
24: α[g, :] ← exp_scores/sum(exp_scores)
25:
26: //Verify normalization constraint
27: assert sum(α[g,:]) ≈ 1.0
28: end for
29: return α |
The attention mechanism reveals interpretable patterns reflecting emission gas physics. Gases exhibiting long-term attention dominance (), such as , and CO, are characterized by thermal kinetics and cumulative formation processes, where extended historical context provides critical predictive information. Conversely, rapidly varying gases like and exhibit short-term attention dominance (), indicating that recent observations are most informative. The temperature parameter provides moderate softmax sharpness, allowing clear scale preference while maintaining some contribution from all scales. This adaptive mechanism contributes to MSTU-HAE’s superior performance across diverse emission gases, as evidenced by the consistent values exceeding 0.95 for gases with dramatically different temporal characteristics.
This fusion mechanism produces a unified five-dimensional feature representation for each gas that adaptively combines information from all temporal scales according to their gas-specific relevance.
3.5. Additional Feature Engineering
Beyond the multi-scale temporal features, we engineer additional features to capture domain-specific relationships and improve model performance. Time-based features encode the temporal structure of observations:
Time index: Sequential sample number normalized to [0, 1].
Hour of day: Cyclic feature capturing diurnal patterns.
Day number: Day identifier capturing longer-term patterns.
Derived emission indices aggregate related gases to capture combustion chemistry relationships:
Interaction features capture nonlinear relationships between emissions and operational parameters:
where interactions are selected based on the domain knowledge of emission formation mechanisms, including NO × NO
2 (NOx formation dynamics), CO × CO
2 (combustion efficiency), Temperature × CO
2 (thermal effects on combustion), and Pressure × SO
2 (pressure-dependent sulfur oxidation). For each target gas g being predicted, the following features are removed from the input set before model training: (i) the raw measurement of gas g itself; (ii) any derived emission index that includes gas g as a component—when predicting NO, both the raw NO measurement and the NO
x = NO + NO
2 index are excluded, and when predicting CO or CO
2, both raw CO or CO
2 and the total carbon index are excluded; and (iii) any interaction term φᵢⱼ where i = g or j = g. This per gas exclusion is enforced uniformly across all base models. The resulting input dimensionality varies from 83 to 86 features, depending on the number of derived indices containing the target gas.
The complete feature set comprises 88 dimensions: 12 original emission values, three technical parameters, 60 attention-weighted fused features, 10 interaction features, and three time-based features.
3.6. Base Model Training
The MSTU-HAE ensemble incorporates six diverse base models spanning different algorithmic paradigms to ensure comprehensive coverage of the hypothesis space:
Support Vector Regression (SVR) implements kernel-based regression with radial basis function (RBF) kernels, optimizing:
Subject to -insensitive loss constraints. Hyperparameter optimization searches over , kernel scale , and .
Random Forest combines multiple decision trees through bootstrap aggregating:
Hyperparameter optimization searches over the number of trees and minimum leaf size .
LSBoost implements least squares gradient boosting, sequentially fitting weak learners to residuals with learning rate control:
where
and number of iterations
.
AdaBoost employs adaptive boosting with decision tree weak learners, adjusting sample weights based on prediction errors.
Ridge Regression provides regularized linear prediction:
with regularization parameter
optimized through cross-validation.
K-Nearest Neighbors (KNN) implements instance-based regression using local averaging over nearest neighbors with optimized and distance metrics.
Each model is trained independently for each of the 12 emission gases, with gas-specific feature selection that excludes the target gas and its derived features to prevent data leakage. All six baseline models (SVR/XGBoost, Random Forest, LSBoost, AdaBoost, Ridge Regression, and KNN) are trained on the identical engineered feature set as MSTU-HAE, the same 83–86-dimensional input after per gas exclusion, comprising multi-scale temporal features, attention-weighted fused features, interaction features, and time-based features. This design ensures that performance differences between MSTU-HAE and the baselines reflect the proposed algorithmic innovations in gas-specific attention fusion and weighted ensemble aggregation rather than differential access to feature information. Hyperparameter optimization employs grid search with validation set performance as the selection criterion.
3.7. Three-Level Hierarchical Uncertainty Quantification
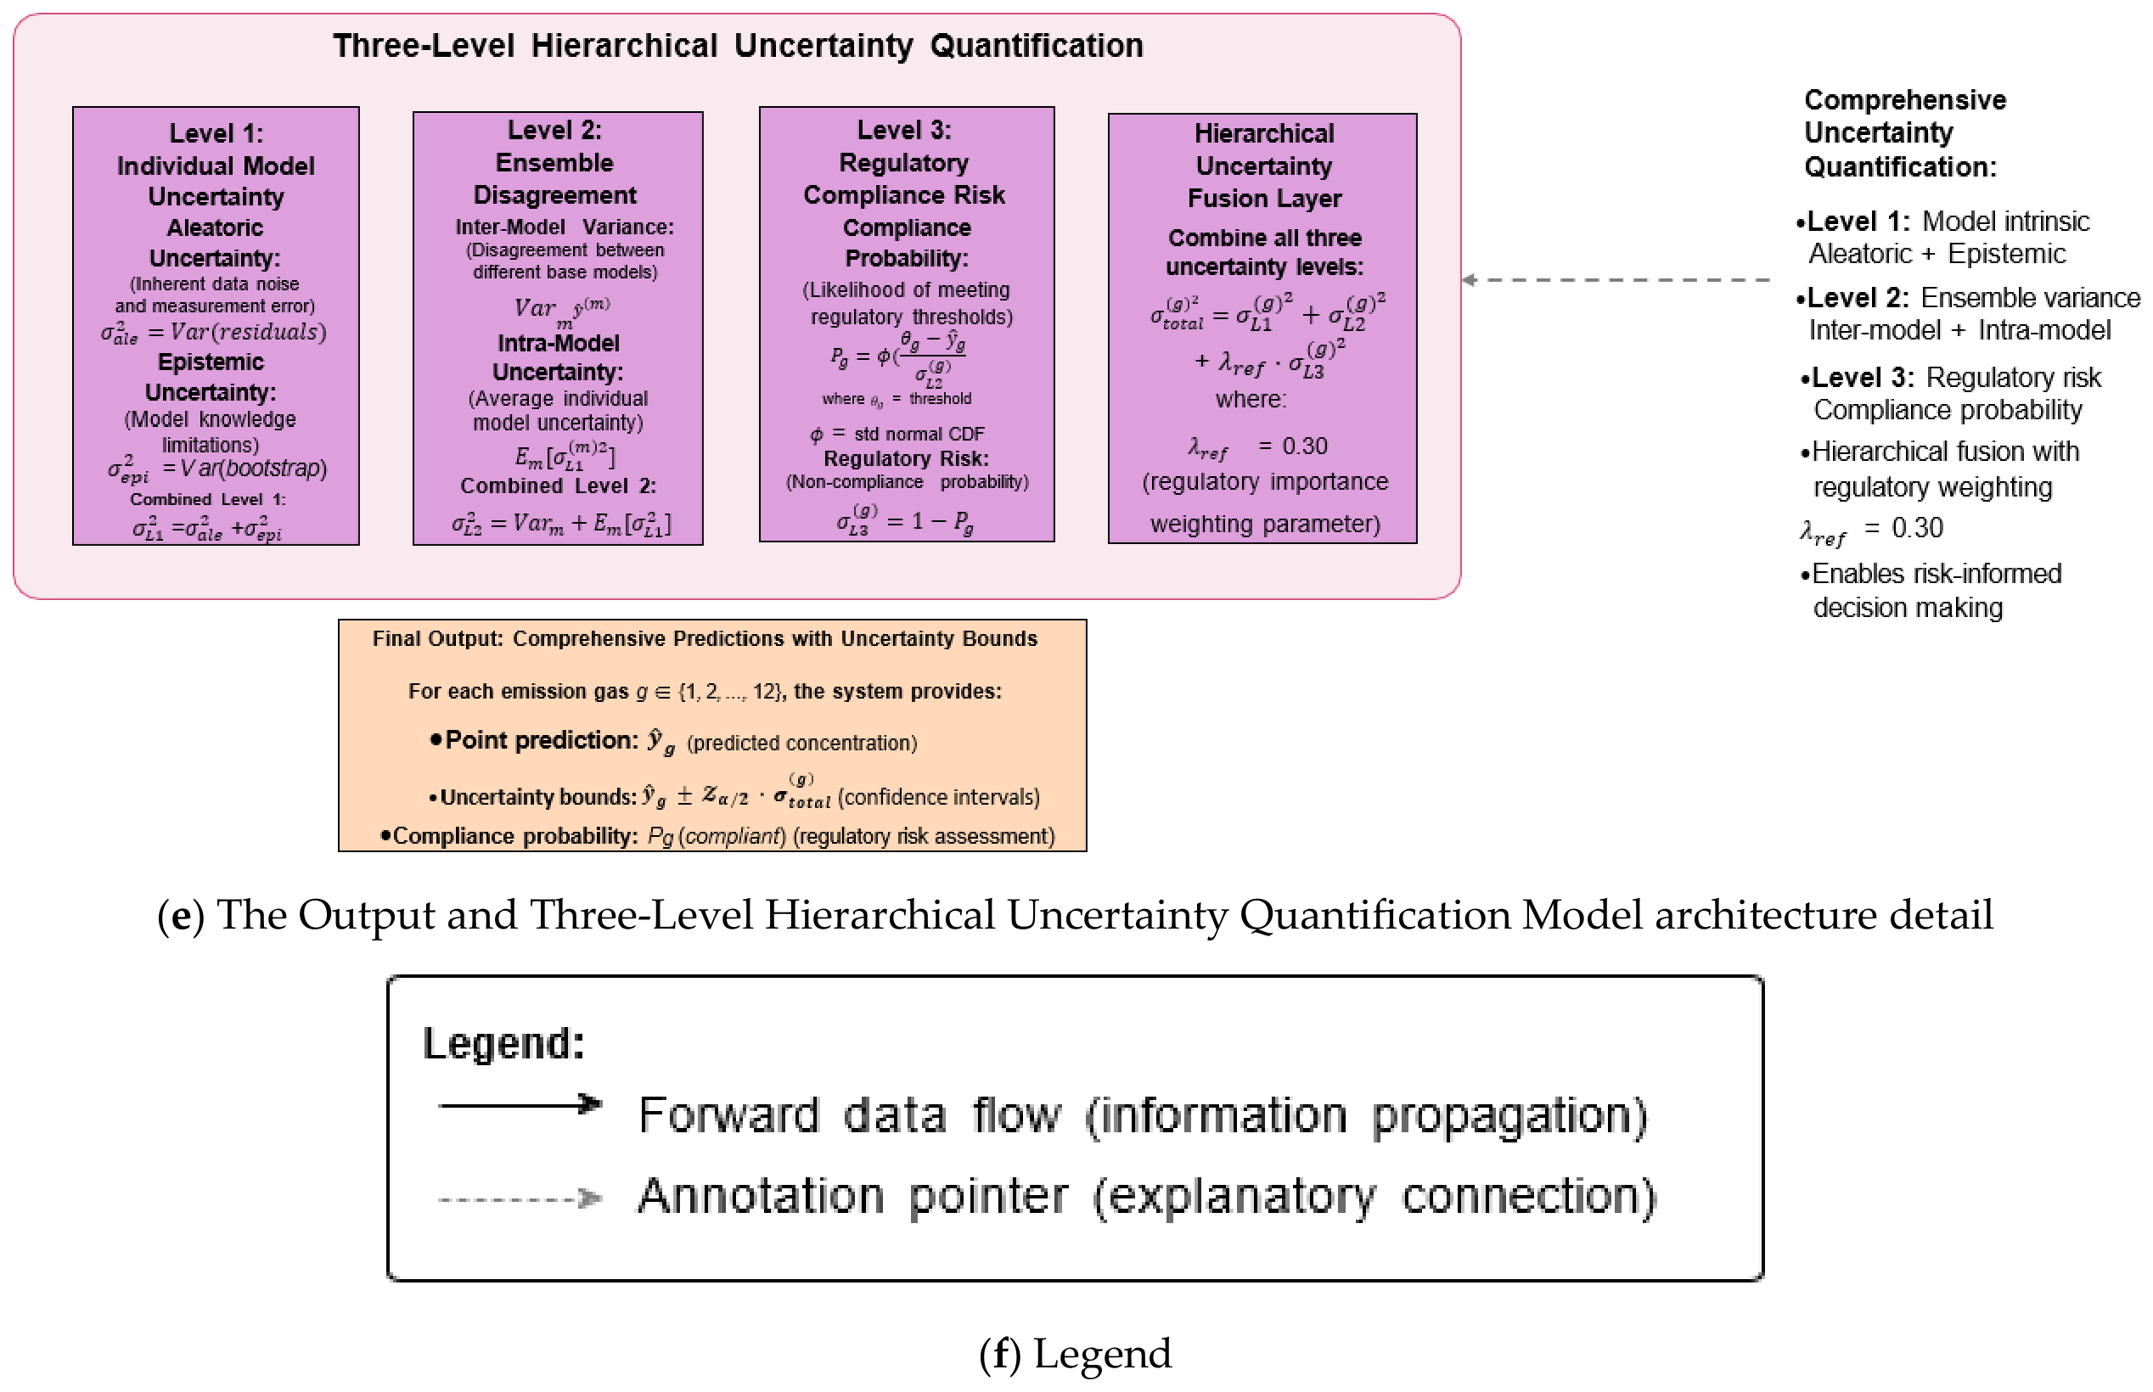
A distinguishing feature of MSTU-HAE is the three-level hierarchical uncertainty quantification framework that provides comprehensive uncertainty characterization suitable for regulatory compliance assessment.
Level 1: Individual model uncertainty quantifies the uncertainty associated with each base model’s predictions, combining aleatoric and epistemic components:
Aleatoric uncertainty is estimated from training residuals:
Epistemic uncertainty is estimated through bootstrap resampling or tree variance (for ensemble methods):
Level 2: Ensemble disagreement captures the uncertainty arising from disagreement among base models:
This combines inter-model variance with the average intra-model uncertainty.
Level 3: Regulatory compliance risk translates predictive uncertainty into compliance probability:
where
is the regulatory threshold for gas
, and
is the standard normal cumulative distribution function. The regulatory risk is:
Total hierarchical uncertainty combines all three levels:
where
, and
is a weighting parameter for regulatory risk importance.
The complete three-level hierarchical uncertainty quantification framework is formalized in Algorithm 3, providing a systematic approach to propagating uncertainty from individual model predictions through ensemble aggregation to regulatory compliance assessment. This multi-level characterization addresses distinct sources of uncertainty relevant at different stages of the prediction and decision-making pipeline.
| Algorithm 3: Three-level hierarchical uncertainty quantification. |
Input: Base model predictions ŷ^(m,g) ∈ ℝ^N_test for m ∈ {1,…,M} models
and g ∈ {1,…,G} gases,
Training residuals r_train^(m,g),
Regulatory thresholds θ ∈ ℝ^G,
Regulatory weight λ_reg
Output: Hierarchical uncertainties σ_L1, σ_L2, σ_L3, σ_total ∈ ℝ^(N_test×G)
//===== LEVEL 1: Individual Model Uncertainty =====
1: for each model m ∈ {1,…, M} do
2: for each gas g ∈ {1,…, G} do
3: //Aleatoric uncertainty from training residuals
4: σ_aleatoric^(m,g) ← std(r_train^(m,g))
5:
6: //Epistemic uncertainty from bootstrap or tree variance
7: if m is ensemble method then
8: σ_epistemic^(m,g) ← estimate_tree_variance(model_m, X_test, g)
9: else
10: σ_epistemic^(m,g) ← estimate_bootstrap_variance(model_m, X_test, g)
11: end if
12:
13: //Combine aleatoric and epistemic
14: for each test sample i do
15: σ_L1[i, g, m] ← √((σ_aleatoric^(m,g))2 + (σ_epistemic[i]^(m,g))2)
16: end for
17: end for
18: end for
//===== LEVEL 2: Ensemble Disagreement =====
19: for each gas g ∈ {1,…, G} do
20: for each test sample i do
21: //Extract predictions from all models for this sample
22: pred_vector ← [ŷ[i]^(1,g), ŷ[i]^(2,g),…, ŷ[i]^(M,g)]
23:
24: //Inter-model variance
25: σ_inter2 ← variance(pred_vector)
26:
27: //Average intra-model variance
28: σ_intra2 ← mean_m([σ_L1[i, g, m]]2)
29:
30: //Combined Level 2 uncertainty
31: σ_L2[i, g] ← √(σ_inter2 + σ_intra2)
32: end for
33: end for
//===== LEVEL 3: Regulatory Compliance Risk =====
34: for each gas g ∈ {1,…, G} do
35: for each test sample i do
36: //Ensemble mean prediction
37: ŷ_ensemble[i, g] ← mean_m(ŷ[i]^(m,g))
38:
39: //Compute z-score for compliance threshold
40: z[i, g] ← (θ[g] − ŷ_ensemble[i, g])/σ_L2[i, g]
41:
42: //Compliance probability using normal CDF
43: P_compliance[i, g] ← Φ(z[i, g])
44:
45: //Regulatory risk (complement of compliance)
46: σ_L3[i, g] ← 1 − P_compliance[i, g]
47: end for
48: end for
//===== TOTAL HIERARCHICAL UNCERTAINTY =====
49: for each gas g ∈ {1,…, G} do
50: for each test sample i do
51: //Average Level 1 across models
52: σ−_L1[i, g] ← mean_m(σ_L1[i, g, m])
53:
54: //Combine all three levels
55: σ_total[i, g] ← √(σ−_L1[i, g]2 + σ_L2[i, g]2 + λ_reg · σ_L3[i, g]2)
56: end for
57: end for
58: return σ_L1, σ_L2, σ_L3, σ_total, P_compliance |
The hierarchical framework offers several practical advantages for operational deployment. Level 1 uncertainty (lines 1–18) identifies base models with high prediction uncertainty for specific gases, informing model selection and ensemble weighting strategies. Level 2 uncertainty (lines 19–33) quantifies ensemble reliability—low inter-model variance indicates consistent predictions across diverse algorithms, while high variance signals challenging prediction scenarios requiring cautious interpretation. Level 3 uncertainty (lines 34–48) translates statistical uncertainty into actionable regulatory risk information, enabling operators to identify periods when predicted emissions approach threshold limits with low confidence. The compliance probability provides intuitive risk quantification: values near 1.0 indicate high confidence of regulatory compliance, while values near 0.5 indicate marginal compliance with substantial uncertainty. The regulatory weight parameter balances the contribution of compliance risk relative to prediction uncertainty, reflecting operational priorities in maritime emission monitoring where regulatory violations carry significant consequences. This hierarchical approach represents a significant advancement over conventional prediction systems that provide only point estimates without uncertainty characterization, enabling risk-informed operational decision-making essential for modern maritime environmental management.
3.8. Performance Metrics
Comprehensive model evaluation employs multiple complementary metrics addressing different aspects of prediction quality. The coefficient of determination (
) measures the proportion of variance explained:
Following recommendations from Citakoglu et al. [
45] for environmental applications, we additionally report the Nash–Sutcliffe Efficiency (NSE):
The interpretation follows established criteria: NSE > 0.75 indicates very good performance, 0.65 < NSE ≤ 0.75 indicates good performance, and 0.50 < NSE ≤ 0.65 indicates satisfactory performance [
58]. As defined in Equations (29) and (30), R
2 and NSE share identical mathematical formulations when computed on the test set using the observed mean ȳ as reference; consequently, the reported NSE values in this study are numerically identical to R
2 values throughout. As defined in Equations (29) and (30), R
2 and NSE are mathematically equivalent under the current experimental setup, since both use the test-set observed mean as the reference value; consequently, NSE is not separately tabulated in the results. R
2 is reported as the primary performance metric following established practice in both environmental monitoring [
45] and the machine learning literature.
Root Mean Square Error (RMSE) quantifies prediction error in original units:
Mean Absolute Percentage Error (MAPE) provides scale-independent error measurement:
where
prevents division by near-zero values.
5. Results and Discussion
5.1. Overall Model Performance
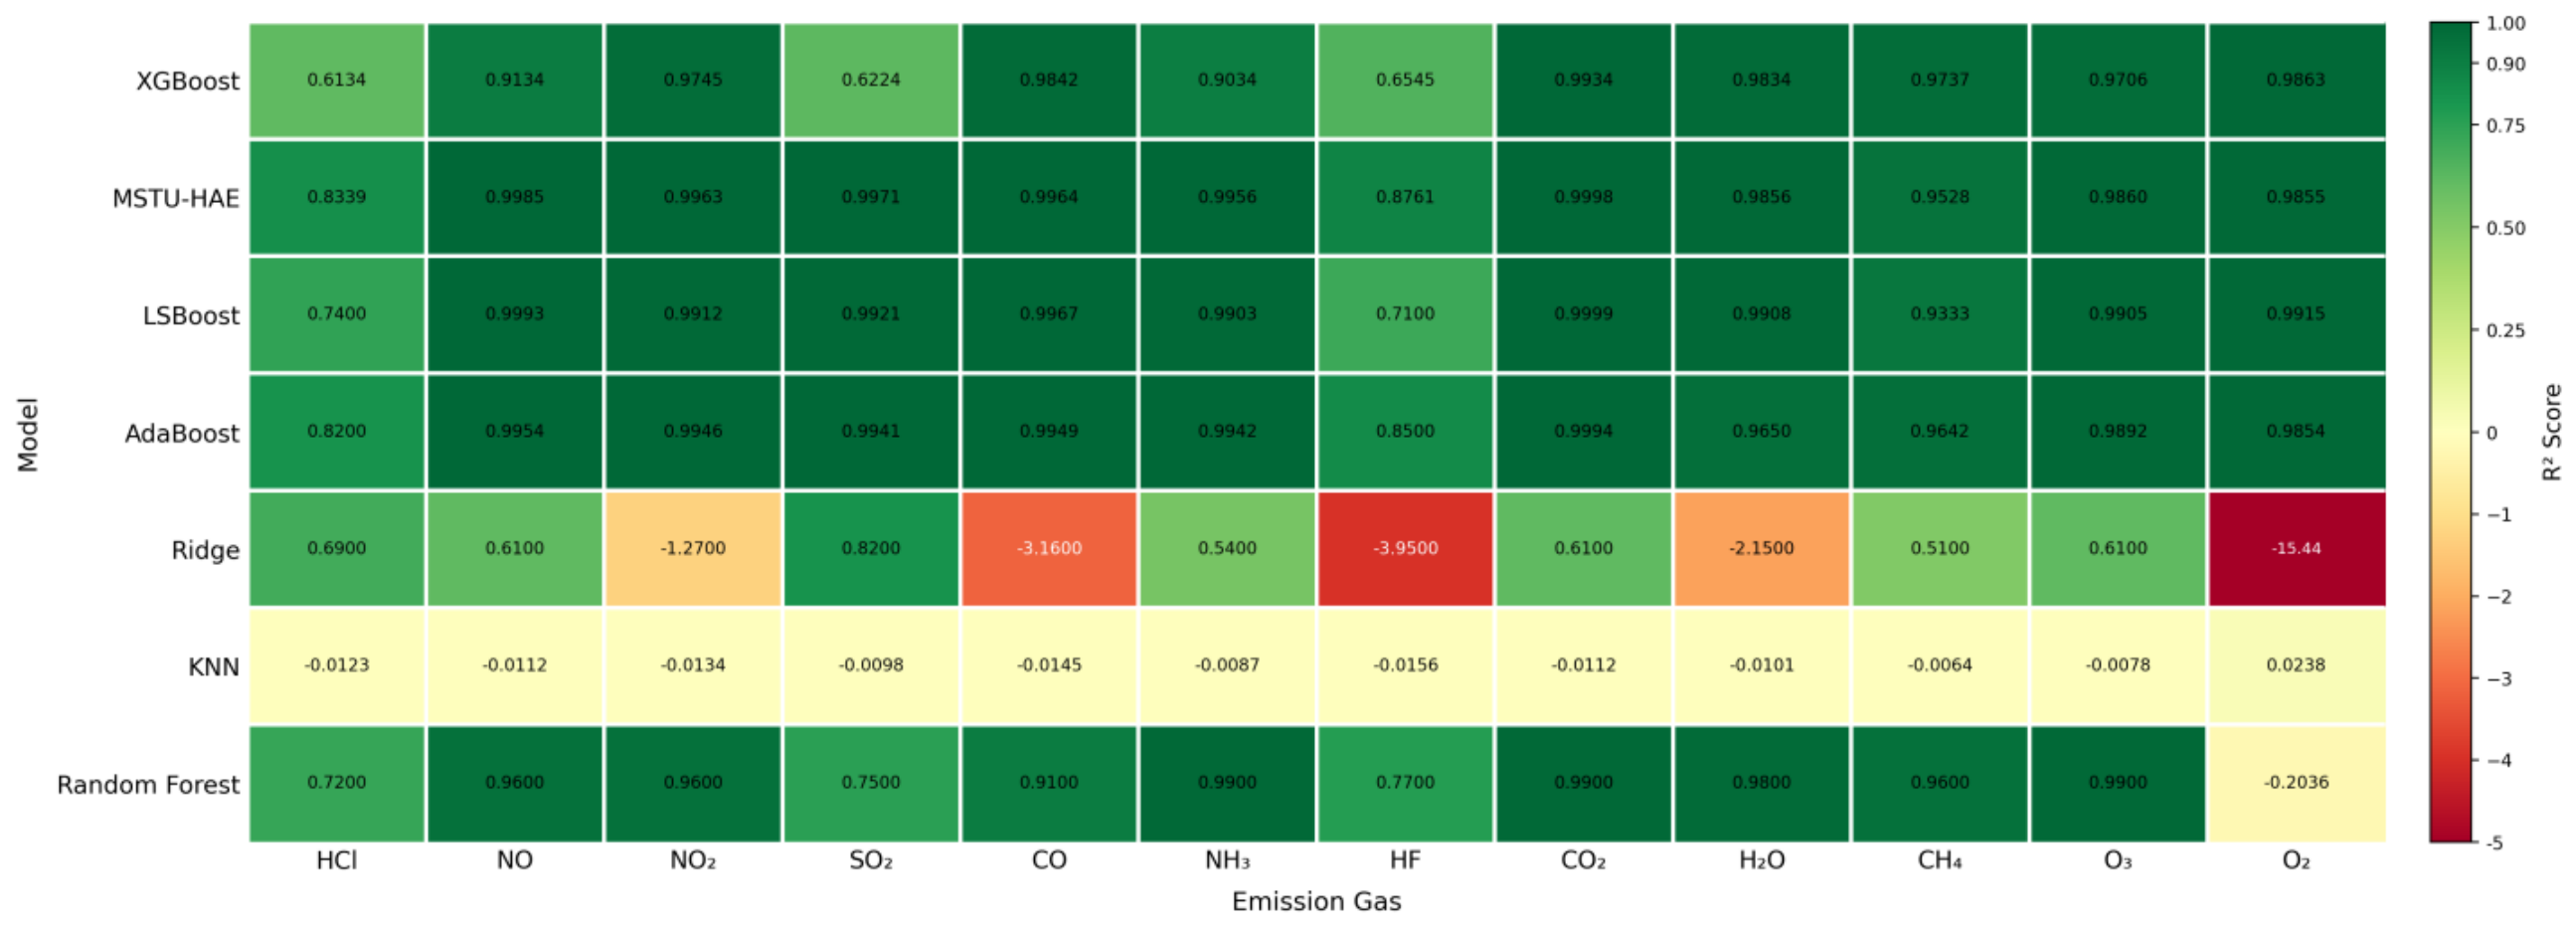
Figure 3 presents the R
2 performance heatmap comparing all six models across all twelve emission gases. The heatmap reveals clear performance stratification, with the ensemble-based methods (MSTU-HAE, AdaBoost, LSBoost, XGBoost) consistently achieving R
2 values exceeding 0.90 for most gases, while simpler methods (Ridge Regression, KNN) exhibit substantially inferior performance. The proposed MSTU-HAE algorithm demonstrates consistently high performance across all gases, with R
2 values ranging from 0.8339 (HCl) to 0.9998 (CO
2).
Figure 3 displays R
2 values at four decimal places for all model gas combinations, consistent with the values reported in
Table 3 and
Table 4.
Table 3 presents the comprehensive performance comparison for all models and gases, showing R
2, NSE, RMSE, and MAPE values. The results demonstrate that MSTU-HAE achieves the best or near-best performance for the majority of emission gases, with particularly exceptional results for the primary combustion products (CO
2, NO, SO
2, CO).
The model ranking analysis, presented in
Table 4, confirms MSTU-HAE’s overall superiority with an average R
2 of 0.9670 across all gases, followed by AdaBoost (0.9622) and LSBoost (0.9438). Notably, MSTU-HAE achieves the highest win count (six gases) among all methods, demonstrating its robust performance across the diverse emission gas characteristics.
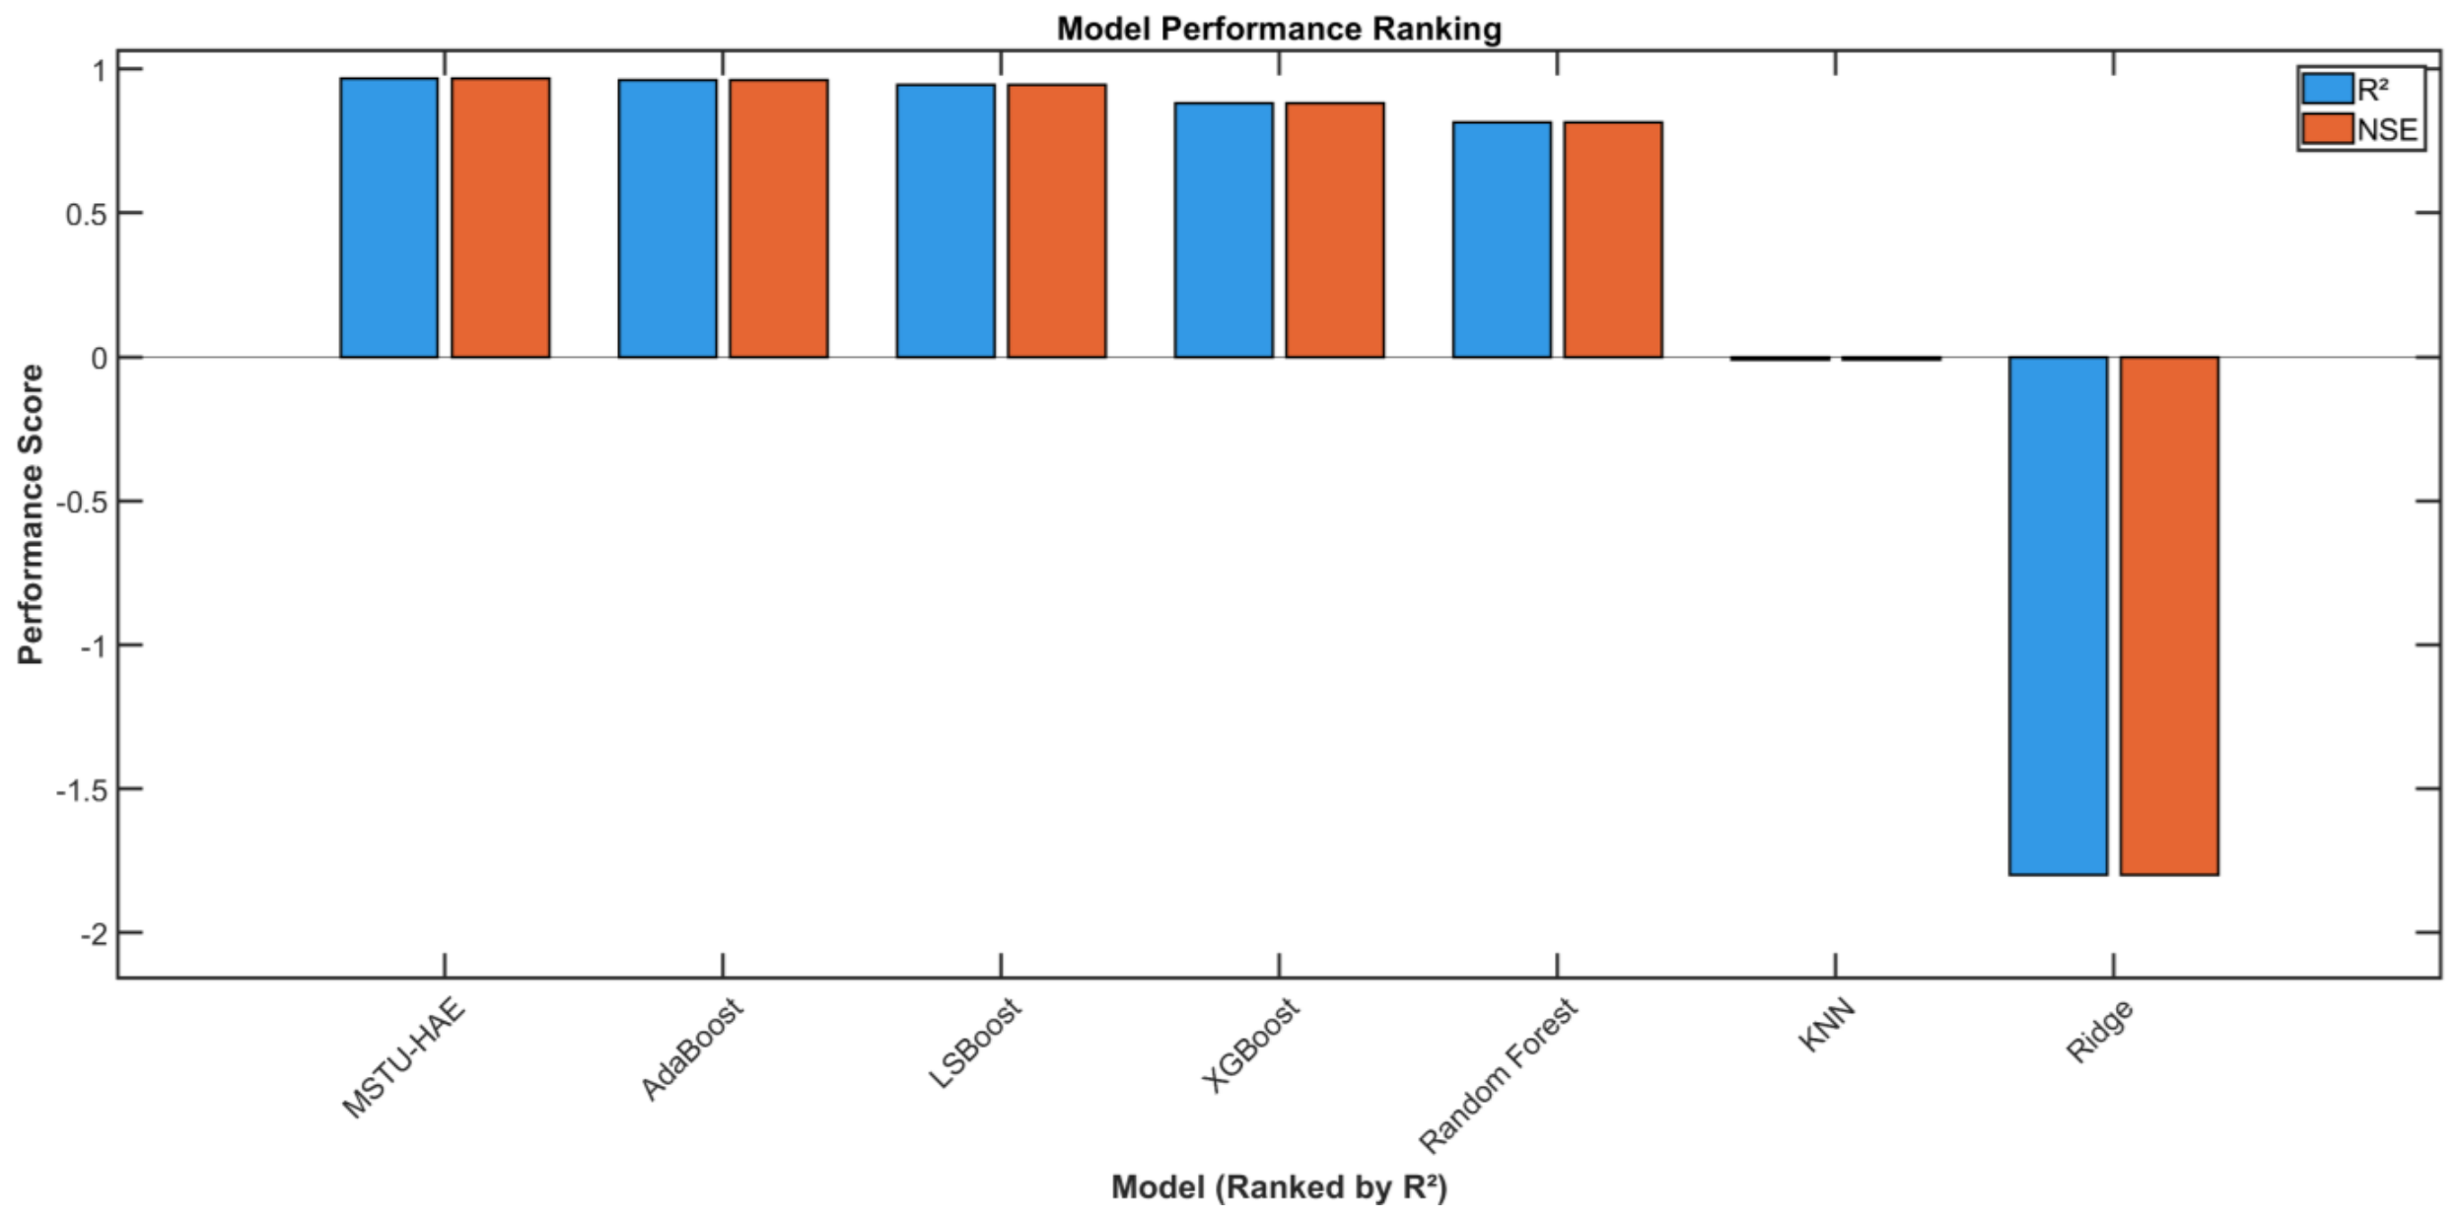
Figure 4 illustrates the model performance ranking, showing the average R
2 across all twelve emission gases for each model. Since NSE is mathematically equivalent to R
2 in this implementation (
Section 3.8), only R
2 is shown to avoid redundancy. The plotted values correspond to the average R
2 column in
Table 4. The clear separation between high-performing ensemble methods and underperforming linear-/instance-based methods highlights the importance of nonlinear modeling capabilities for ship emission prediction.
5.2. MSTU-HAE Detailed Performance Analysis
The proposed MSTU-HAE algorithm achieves exceptional performance across all twelve emission gases, with R
2 values exceeding 0.95 for 10 of 12 gases.
Table 5 presents the detailed MSTU-HAE performance metrics.
According to the NSE interpretation criteria established by Bayram and Çıtakoğlu [
58], all MSTU-HAE predictions fall within the “Very Good” (NSE > 0.75) or “Excellent” (NSE > 0.90) categories, demonstrating the method’s robust performance across the diverse emission gas characteristics.
5.3. Gas-Specific Prediction Analysis
To provide detailed insight into prediction quality, we present per gas prediction visualizations for the most operationally significant emissions.
CO
2 emission prediction:
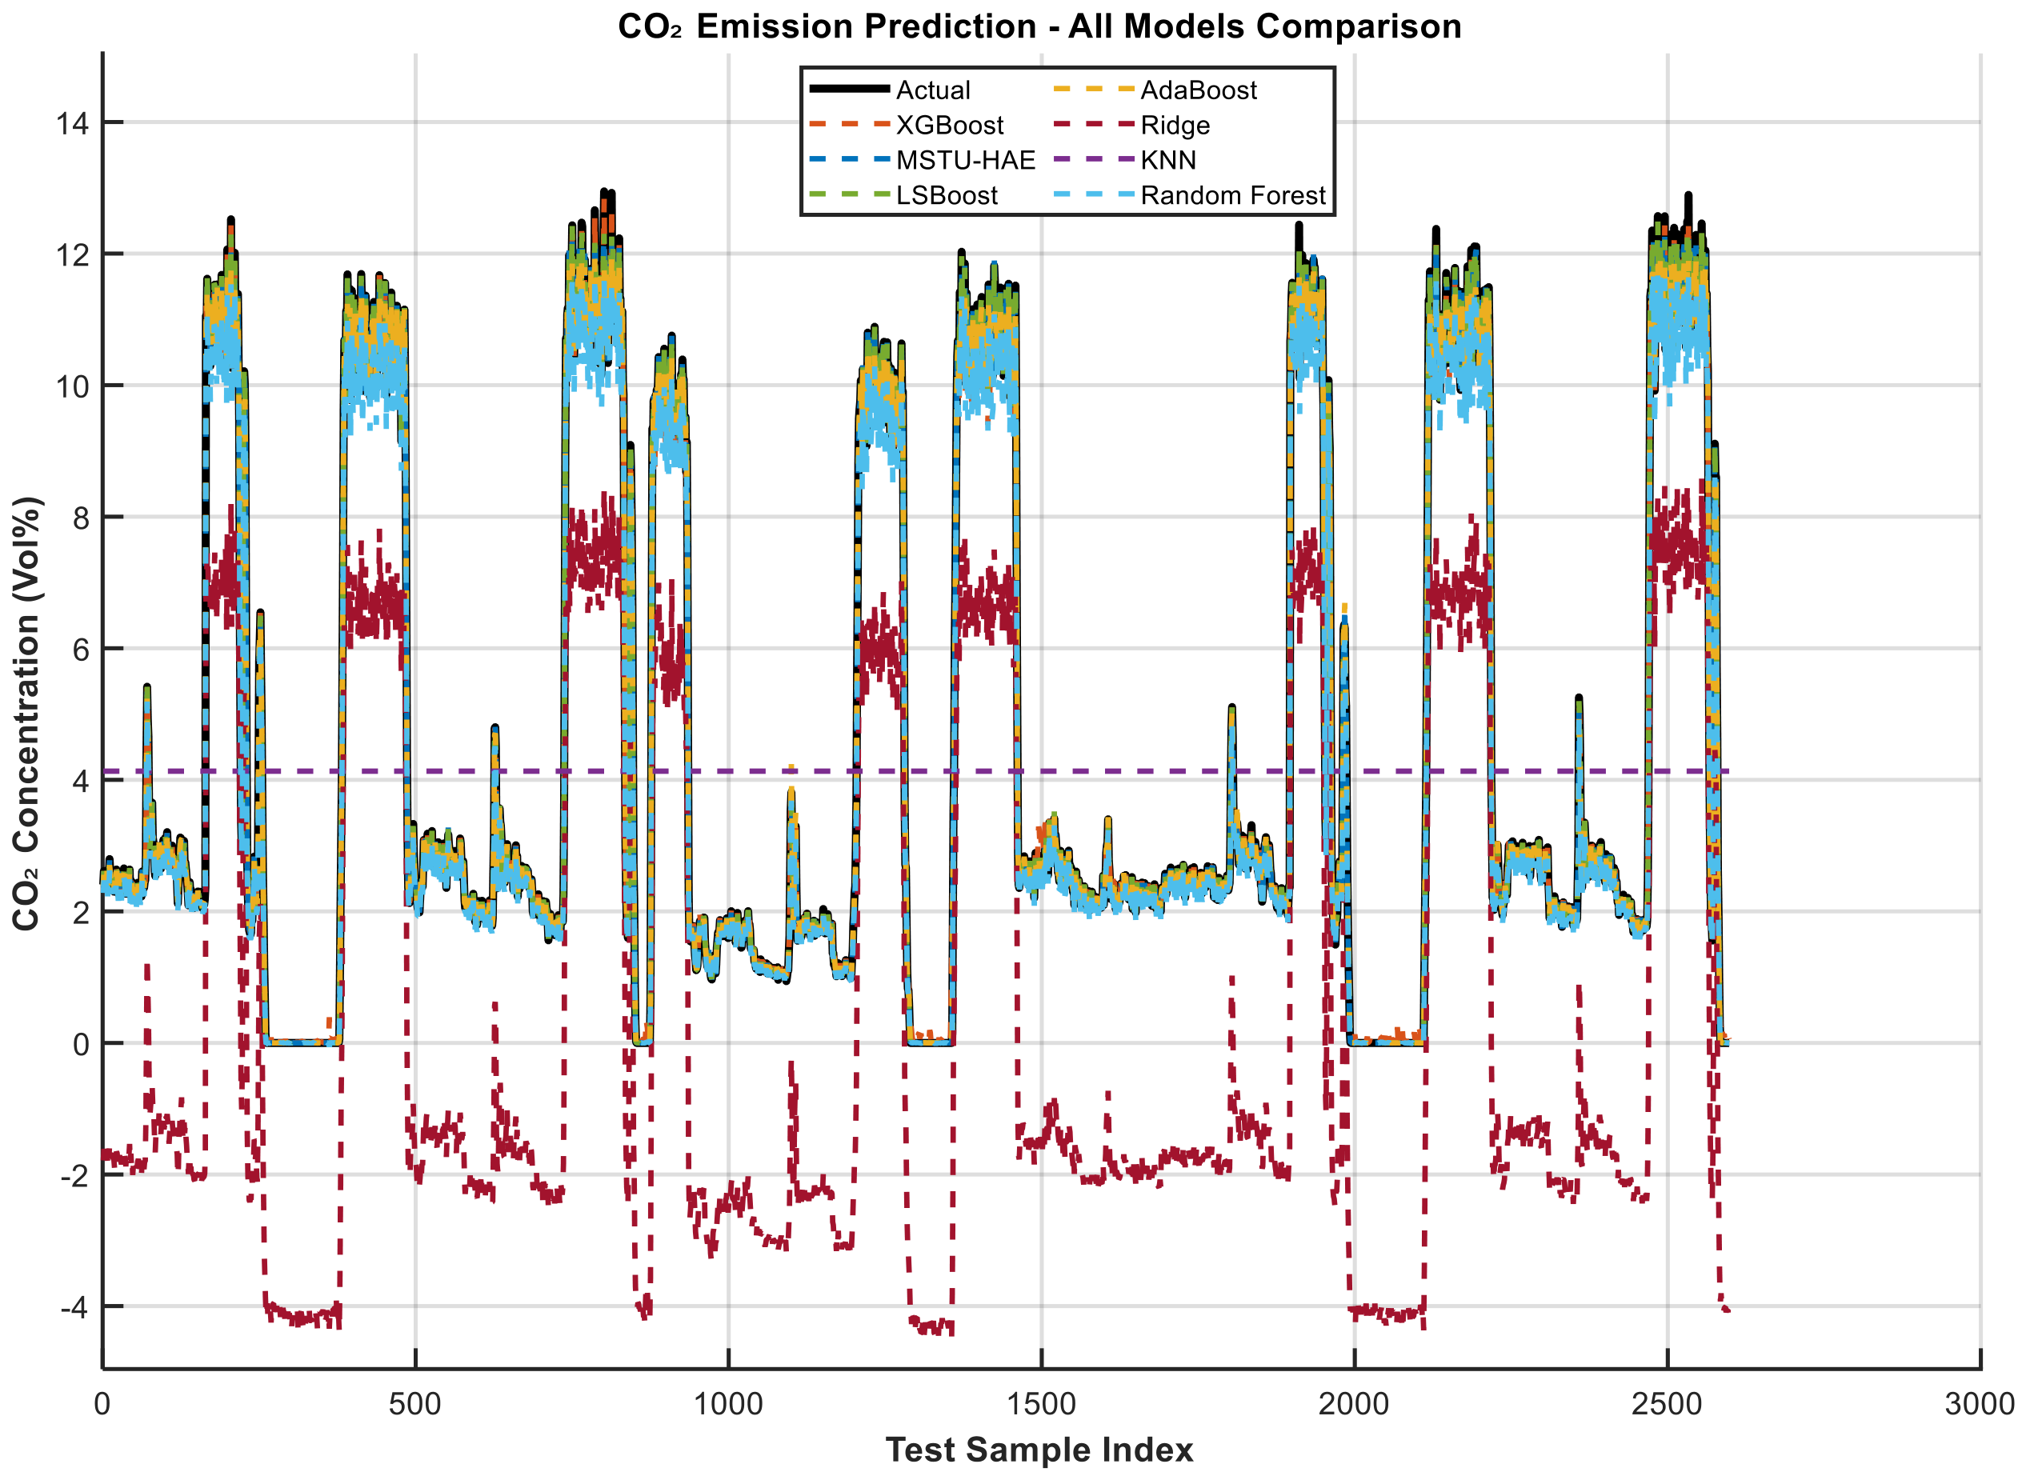
Figure 5 shows the base model predictions for CO
2 emissions across the test set. CO
2 represents the primary combustion product and exhibits relatively smooth temporal variations directly correlated with fuel consumption rate. All ensemble methods (MSTU-HAE, XGBoost, LSBoost, AdaBoost) achieve excellent tracking of the actual CO
2 concentrations, with R
2 values exceeding 0.99. The smooth temporal dynamics and strong correlation with operational parameters enable highly accurate predictions. Ridge Regression and KNN exhibit significantly degraded performance, failing to capture the underlying patterns.
NO emission prediction:
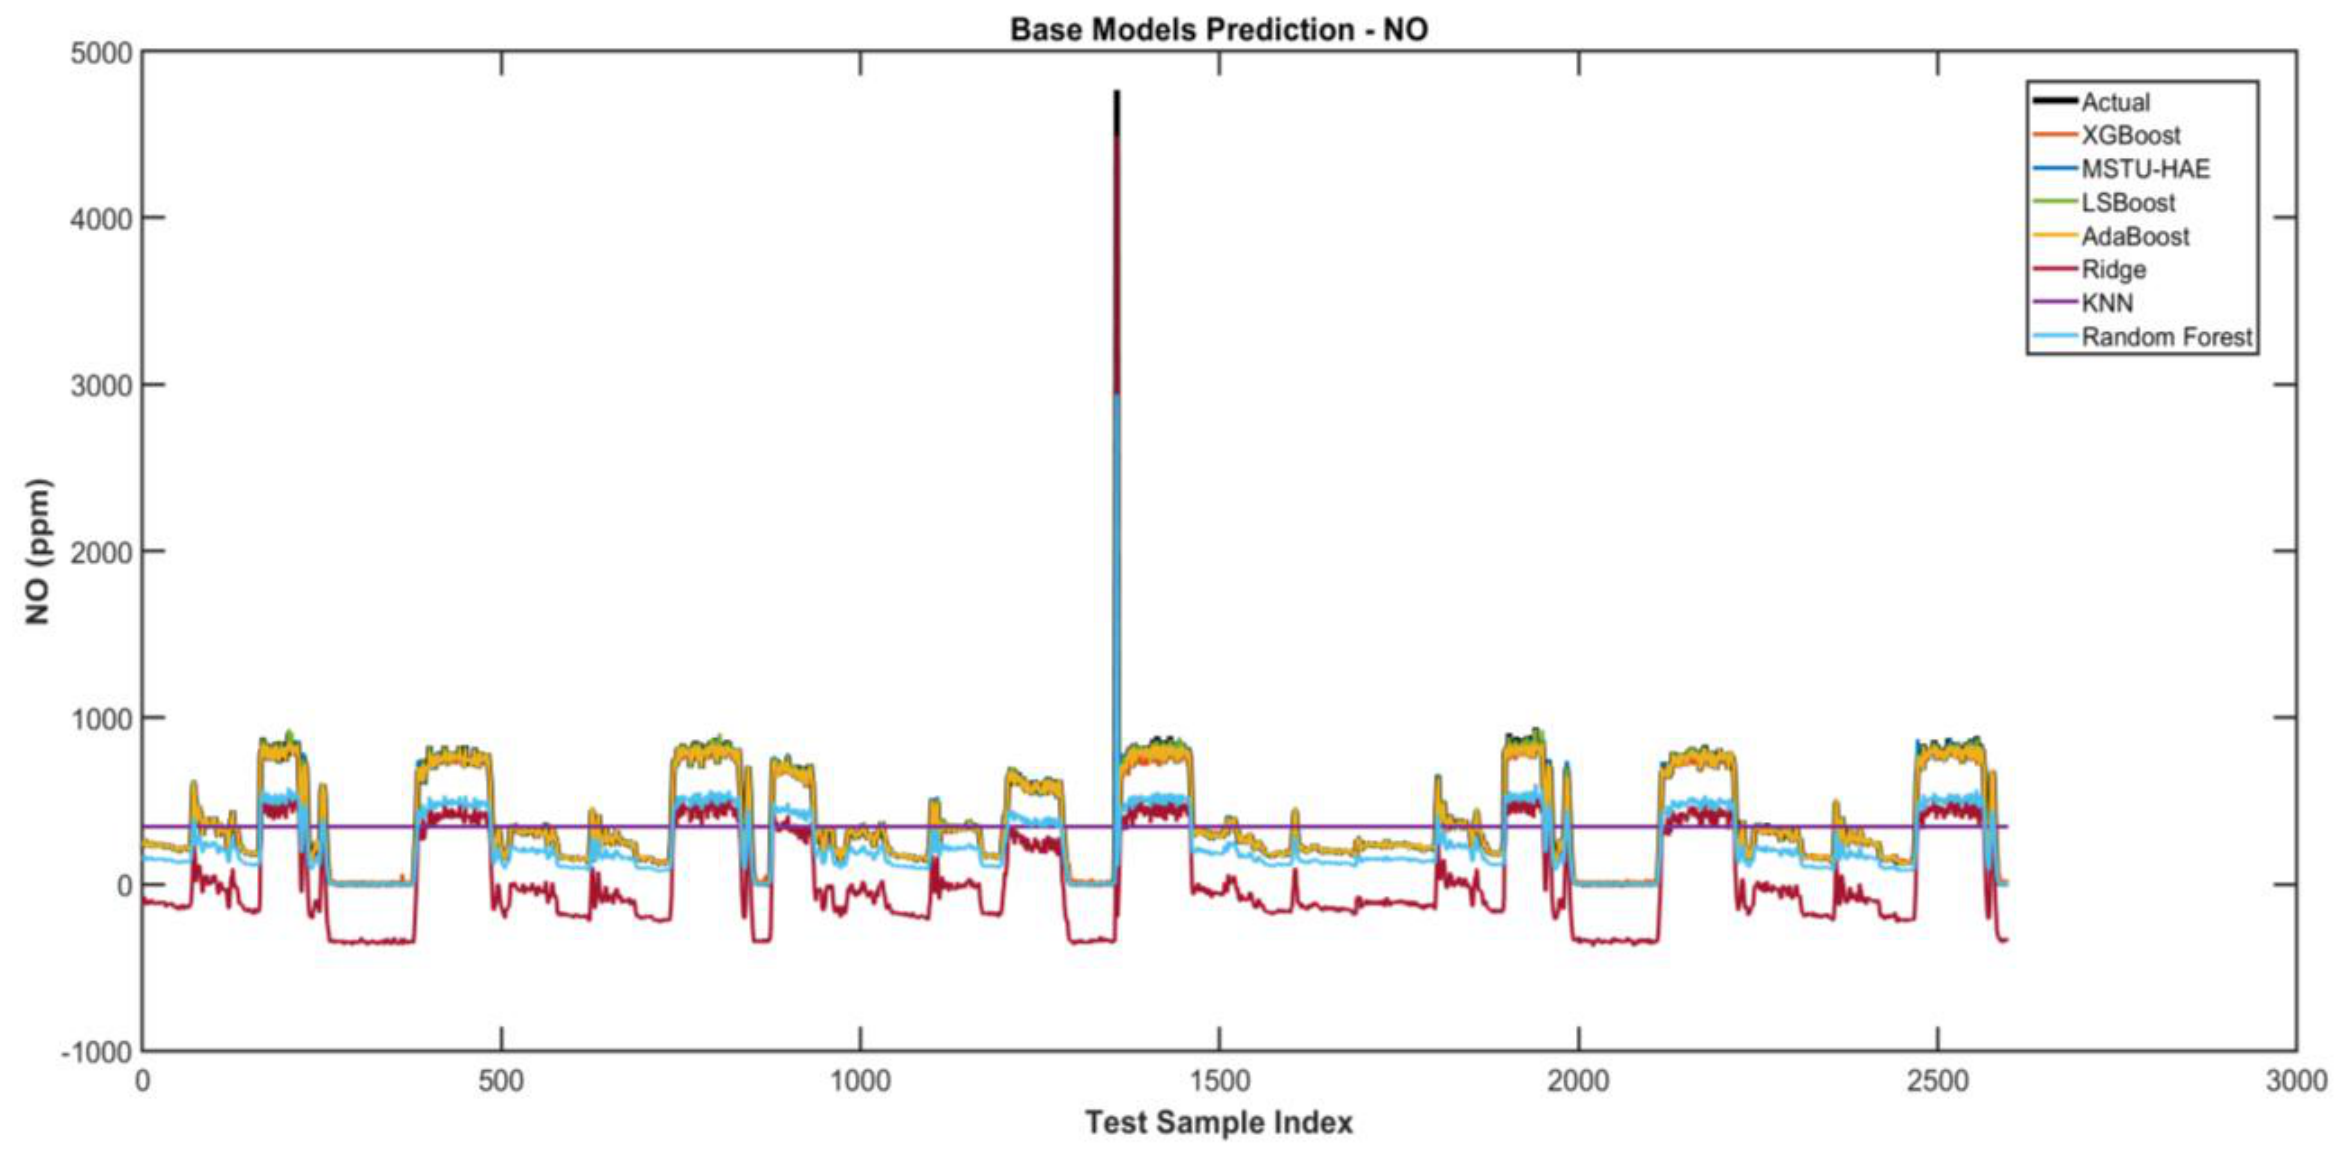
Figure 6 displays predictions for NO emissions, the dominant component of NO
x. NO formation involves complex temperature-dependent kinetics governed by the Zeldovich mechanism, resulting in more variable temporal patterns compared to CO
2. Despite this complexity, MSTU-HAE achieves R
2 = 0.9985, successfully tracking both the baseline variations and the sharp transient peaks associated with high-temperature combustion events. The visualization reveals that Ridge Regression produces predictions near the mean value with significant underprediction during high-emission periods, while KNN exhibits high-frequency noise.
SO
2 emission prediction:
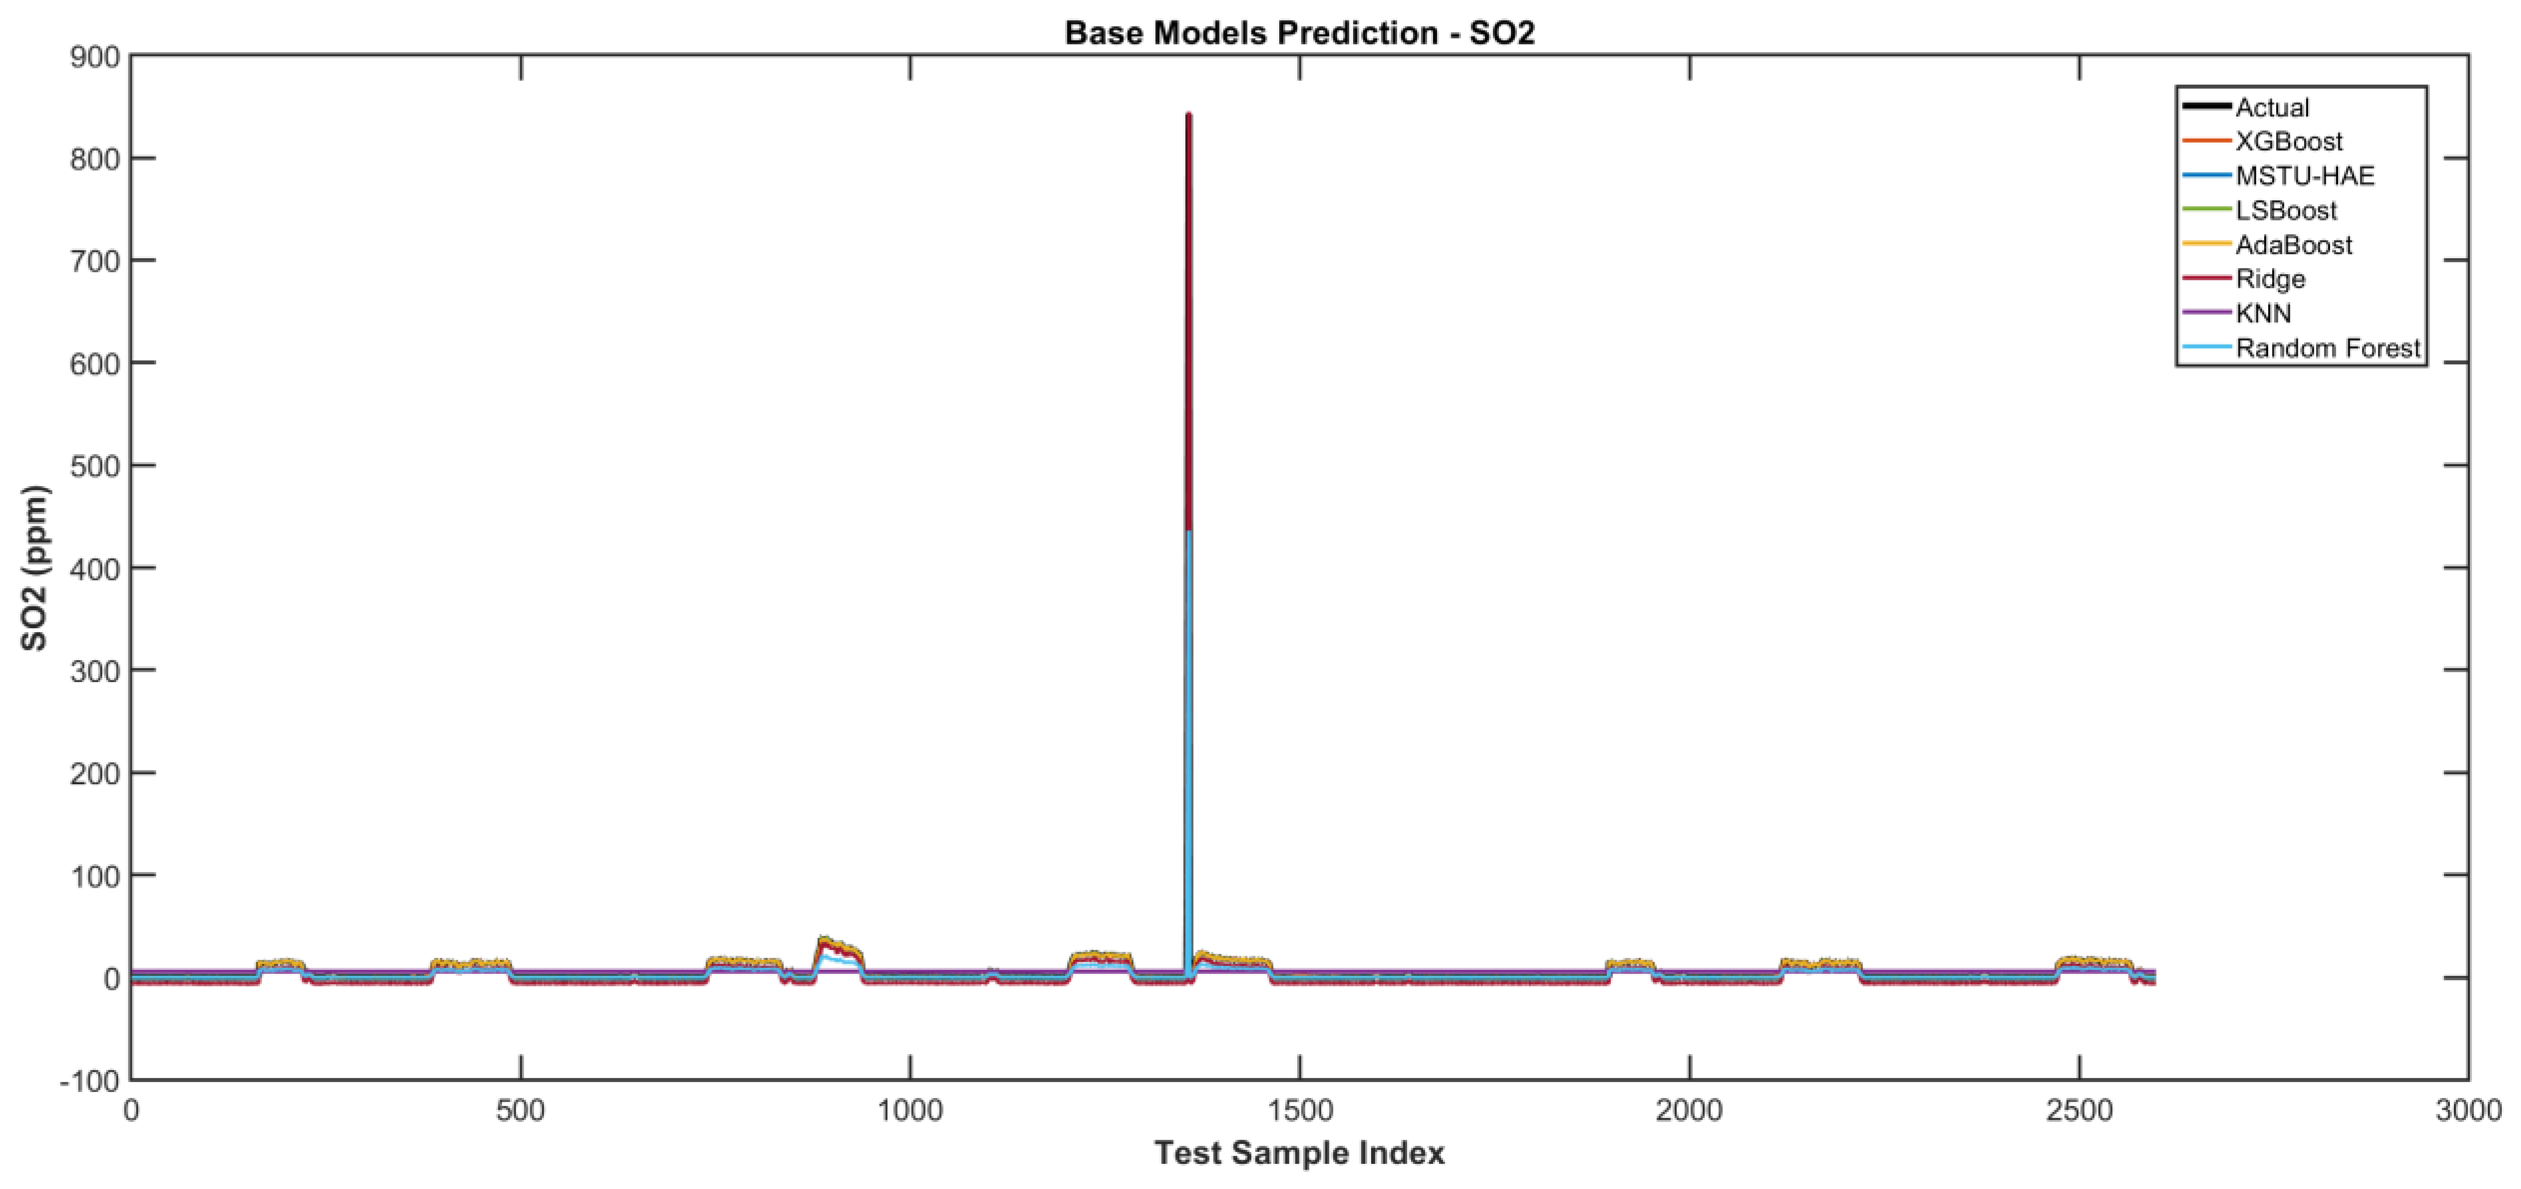
Figure 7 presents SO
2 predictions, demonstrating the models’ ability to capture sulfur oxide emissions dependent on fuel sulfur content. MSTU-HAE achieves R
2 = 0.9971, accurately predicting both typical operational concentrations and occasional spike events. The exceptionally high spike around sample index 1300 (approximately 850 ppm) represents an outlier event captured in the training data; ensemble methods appropriately predict elevated but bounded concentrations during this period, demonstrating robustness to extreme values.
NH
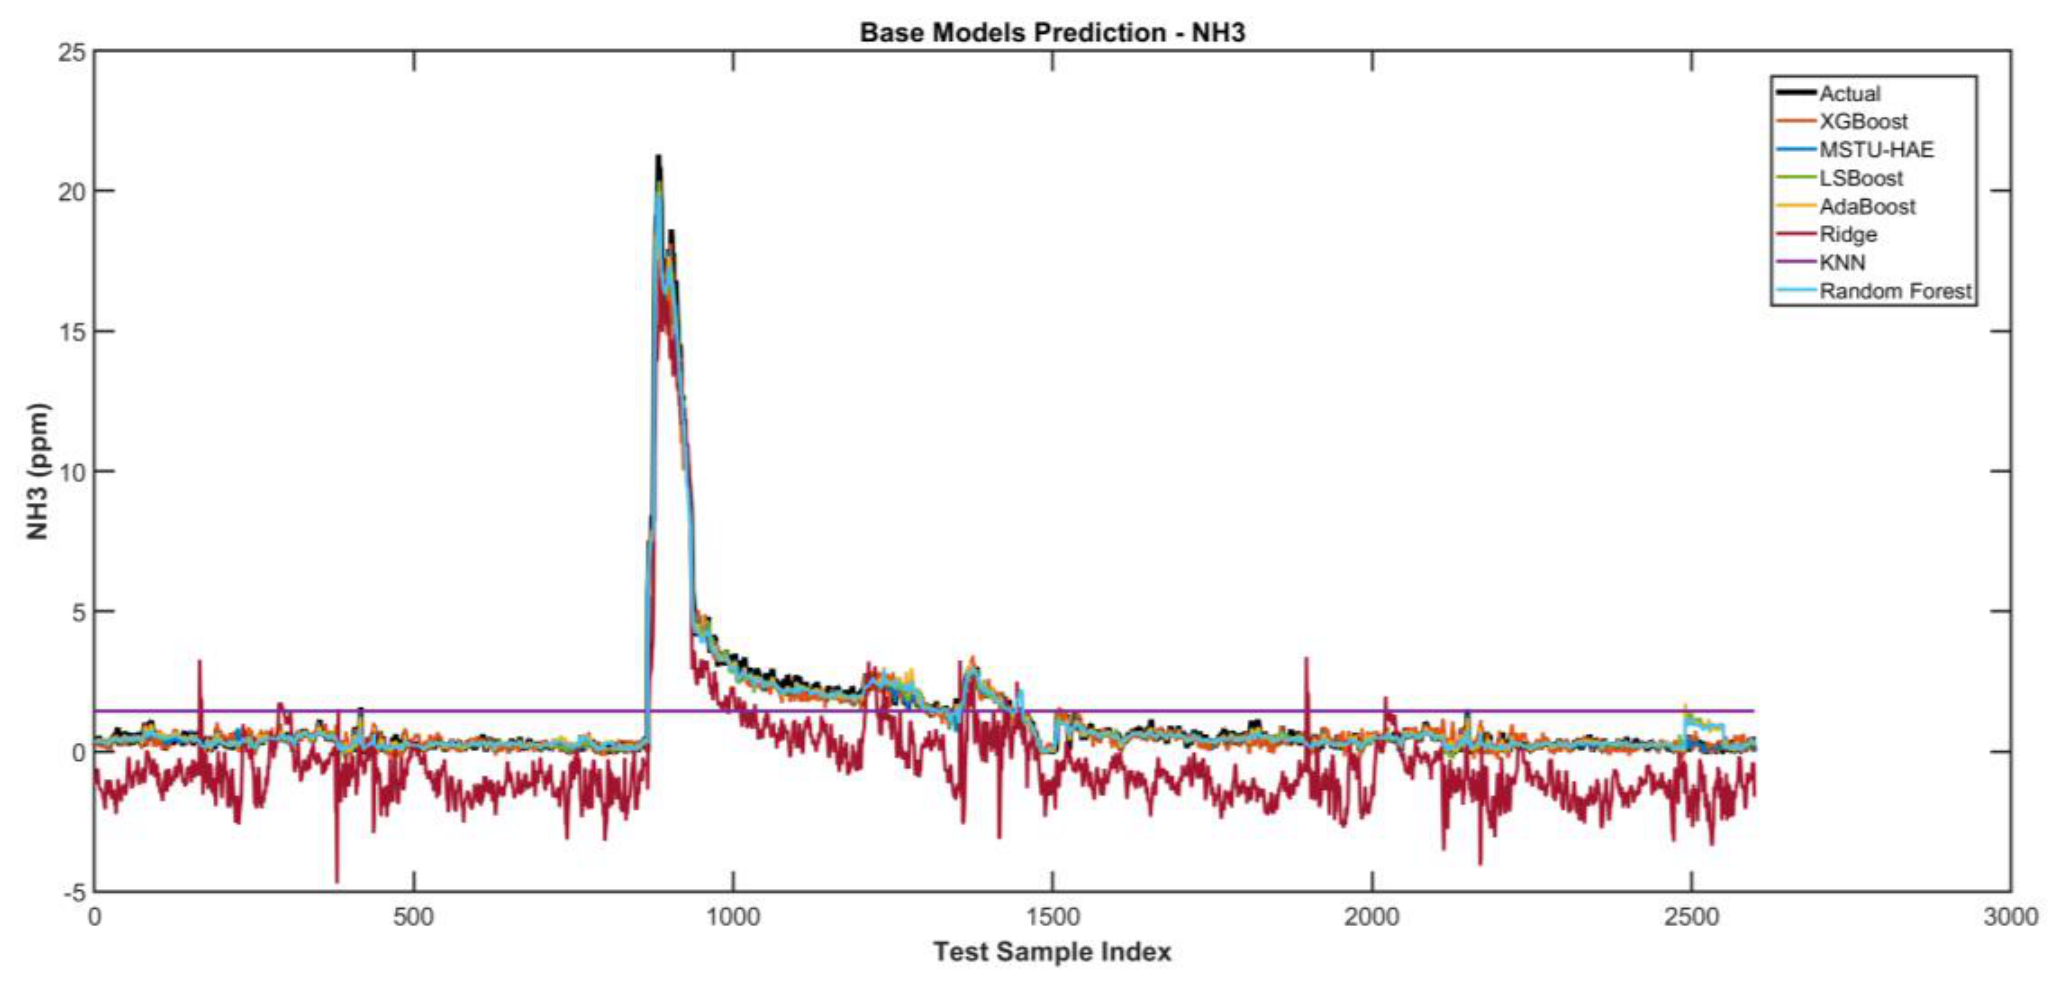
3 emission prediction: Ammonia emissions, arising from incomplete combustion and potential SCR systems, are characterized by low concentrations with moderate variability. MSTU-HAE achieves excellent performance with R
2 = 0.9956 and RMSE = 0.1616 ppm, successfully tracking both baseline variations and occasional concentration spikes. The attention mechanism reveals mixed temporal scale utilization with long-term dominance, reflecting ammonia’s cumulative formation characteristics. From a regulatory perspective, predictions indicate 100% compliance probability against the 50 ppm occupational exposure threshold with minimal uncertainty (2.183 ppm), classifying NH
3 as a very low regulatory risk under typical operations (
Figure 8).
NO
x emission prediction:
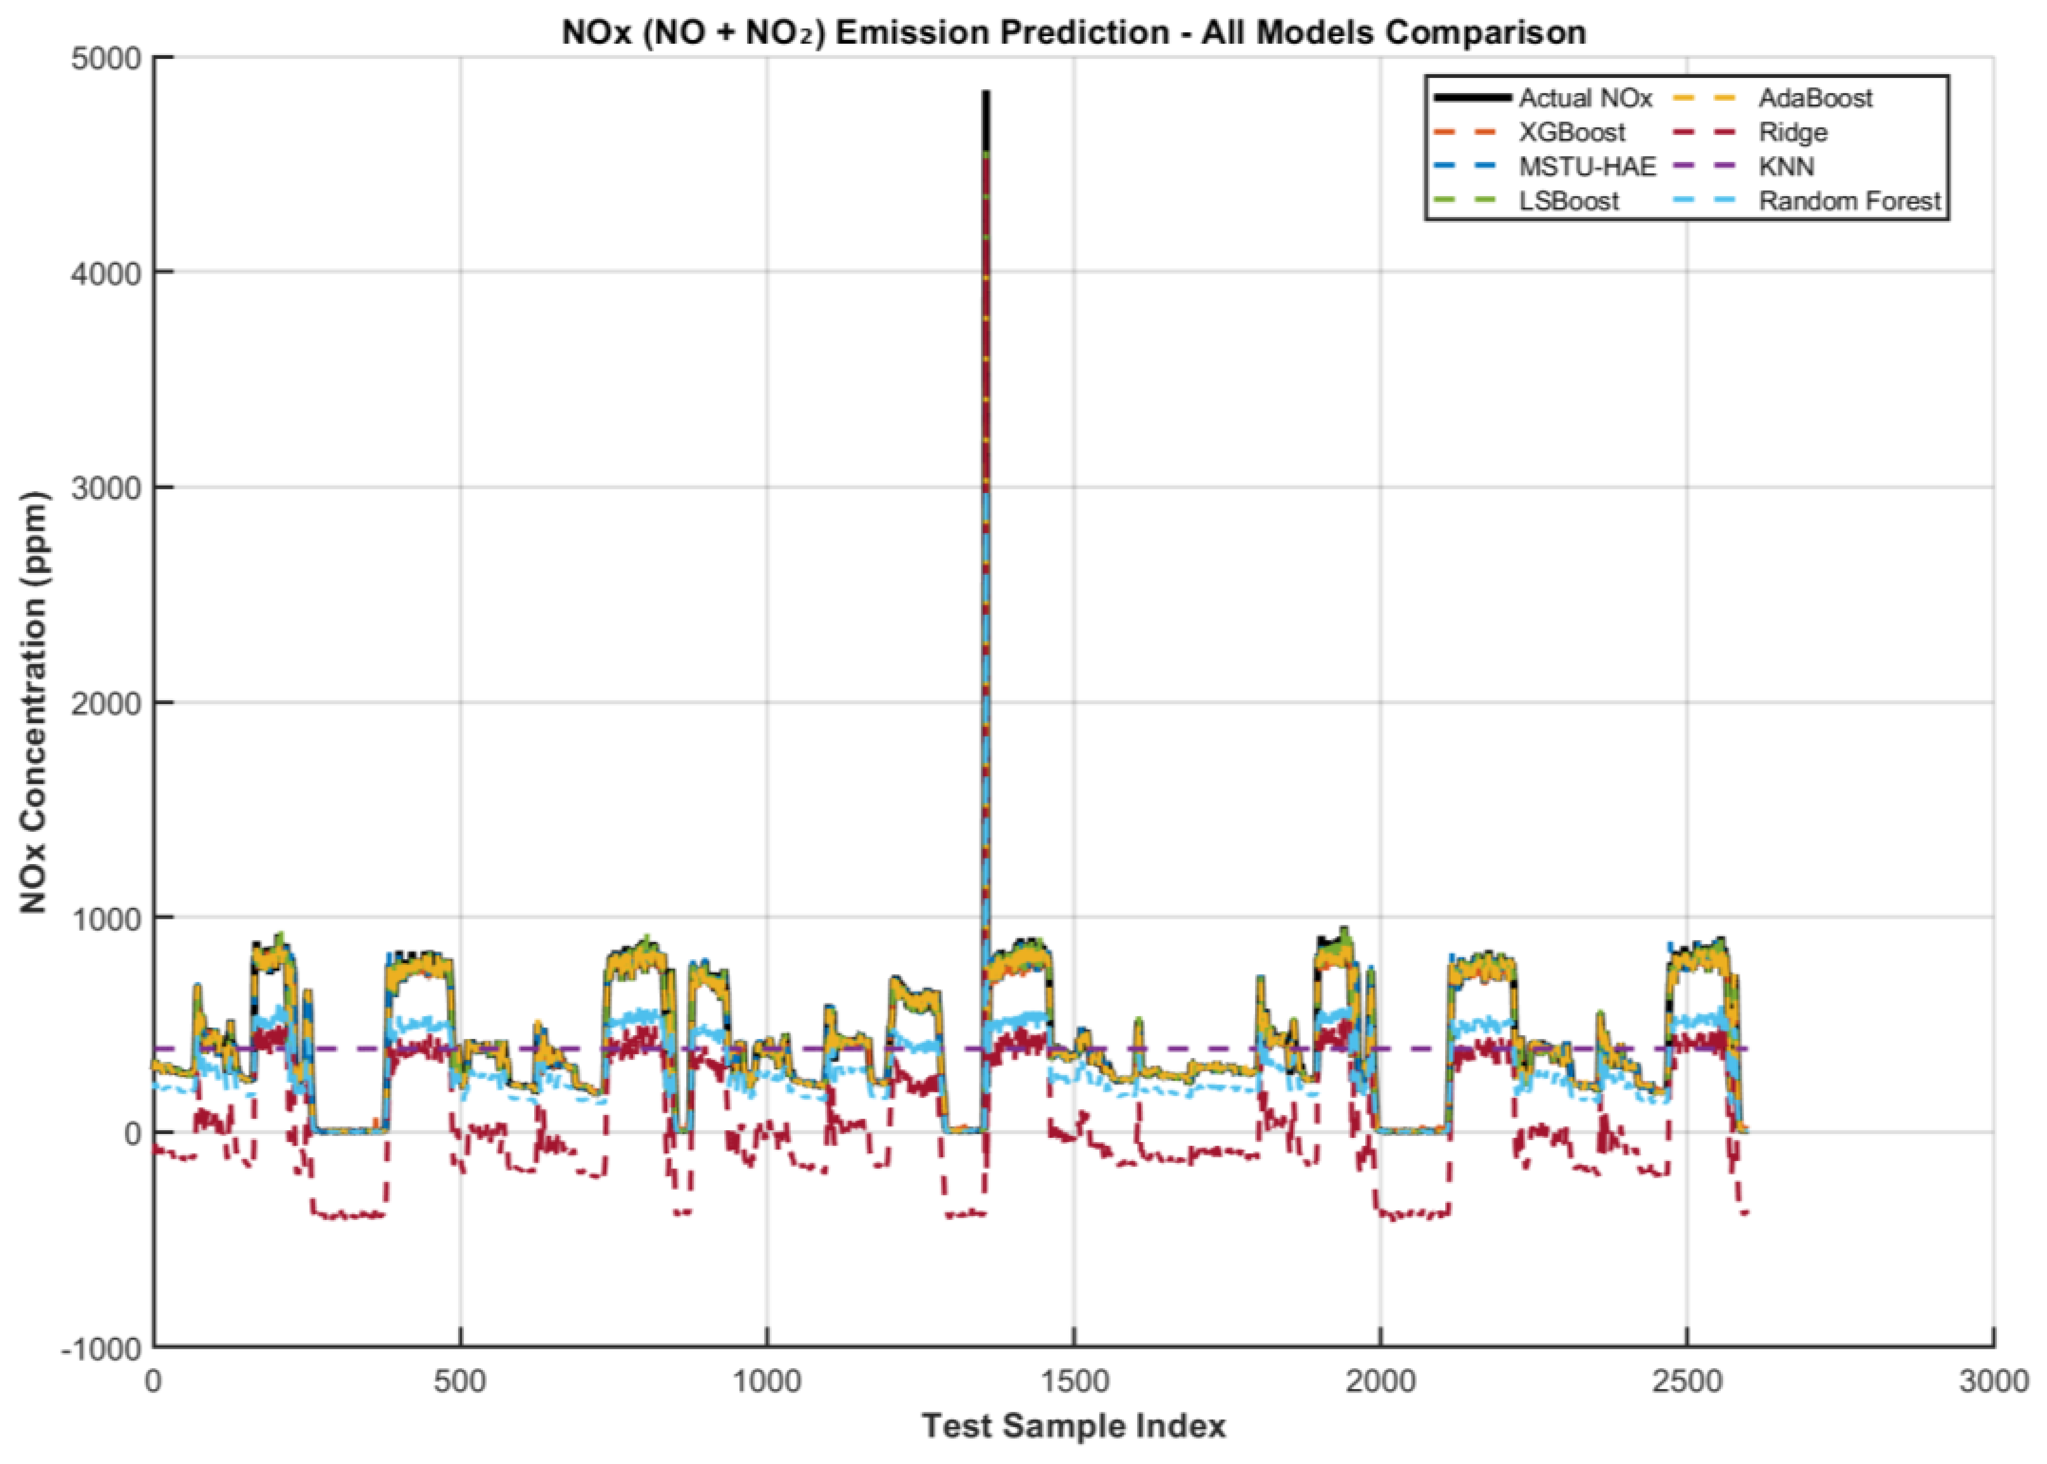
Figure 9 shows predictions for total NO
x (NO + NO
2), the combined nitrogen oxide index critical for regulatory compliance assessment. The prediction quality for NO
x is excellent across ensemble methods, with smooth tracking of the characteristic cyclical patterns associated with engine load variations. This aggregate metric is particularly important for IMO Tier III compliance verification.
Comprehensive MSTU-HAE performance visualization: To provide a complete overview of MSTU-HAE prediction quality across all twelve emission gases,
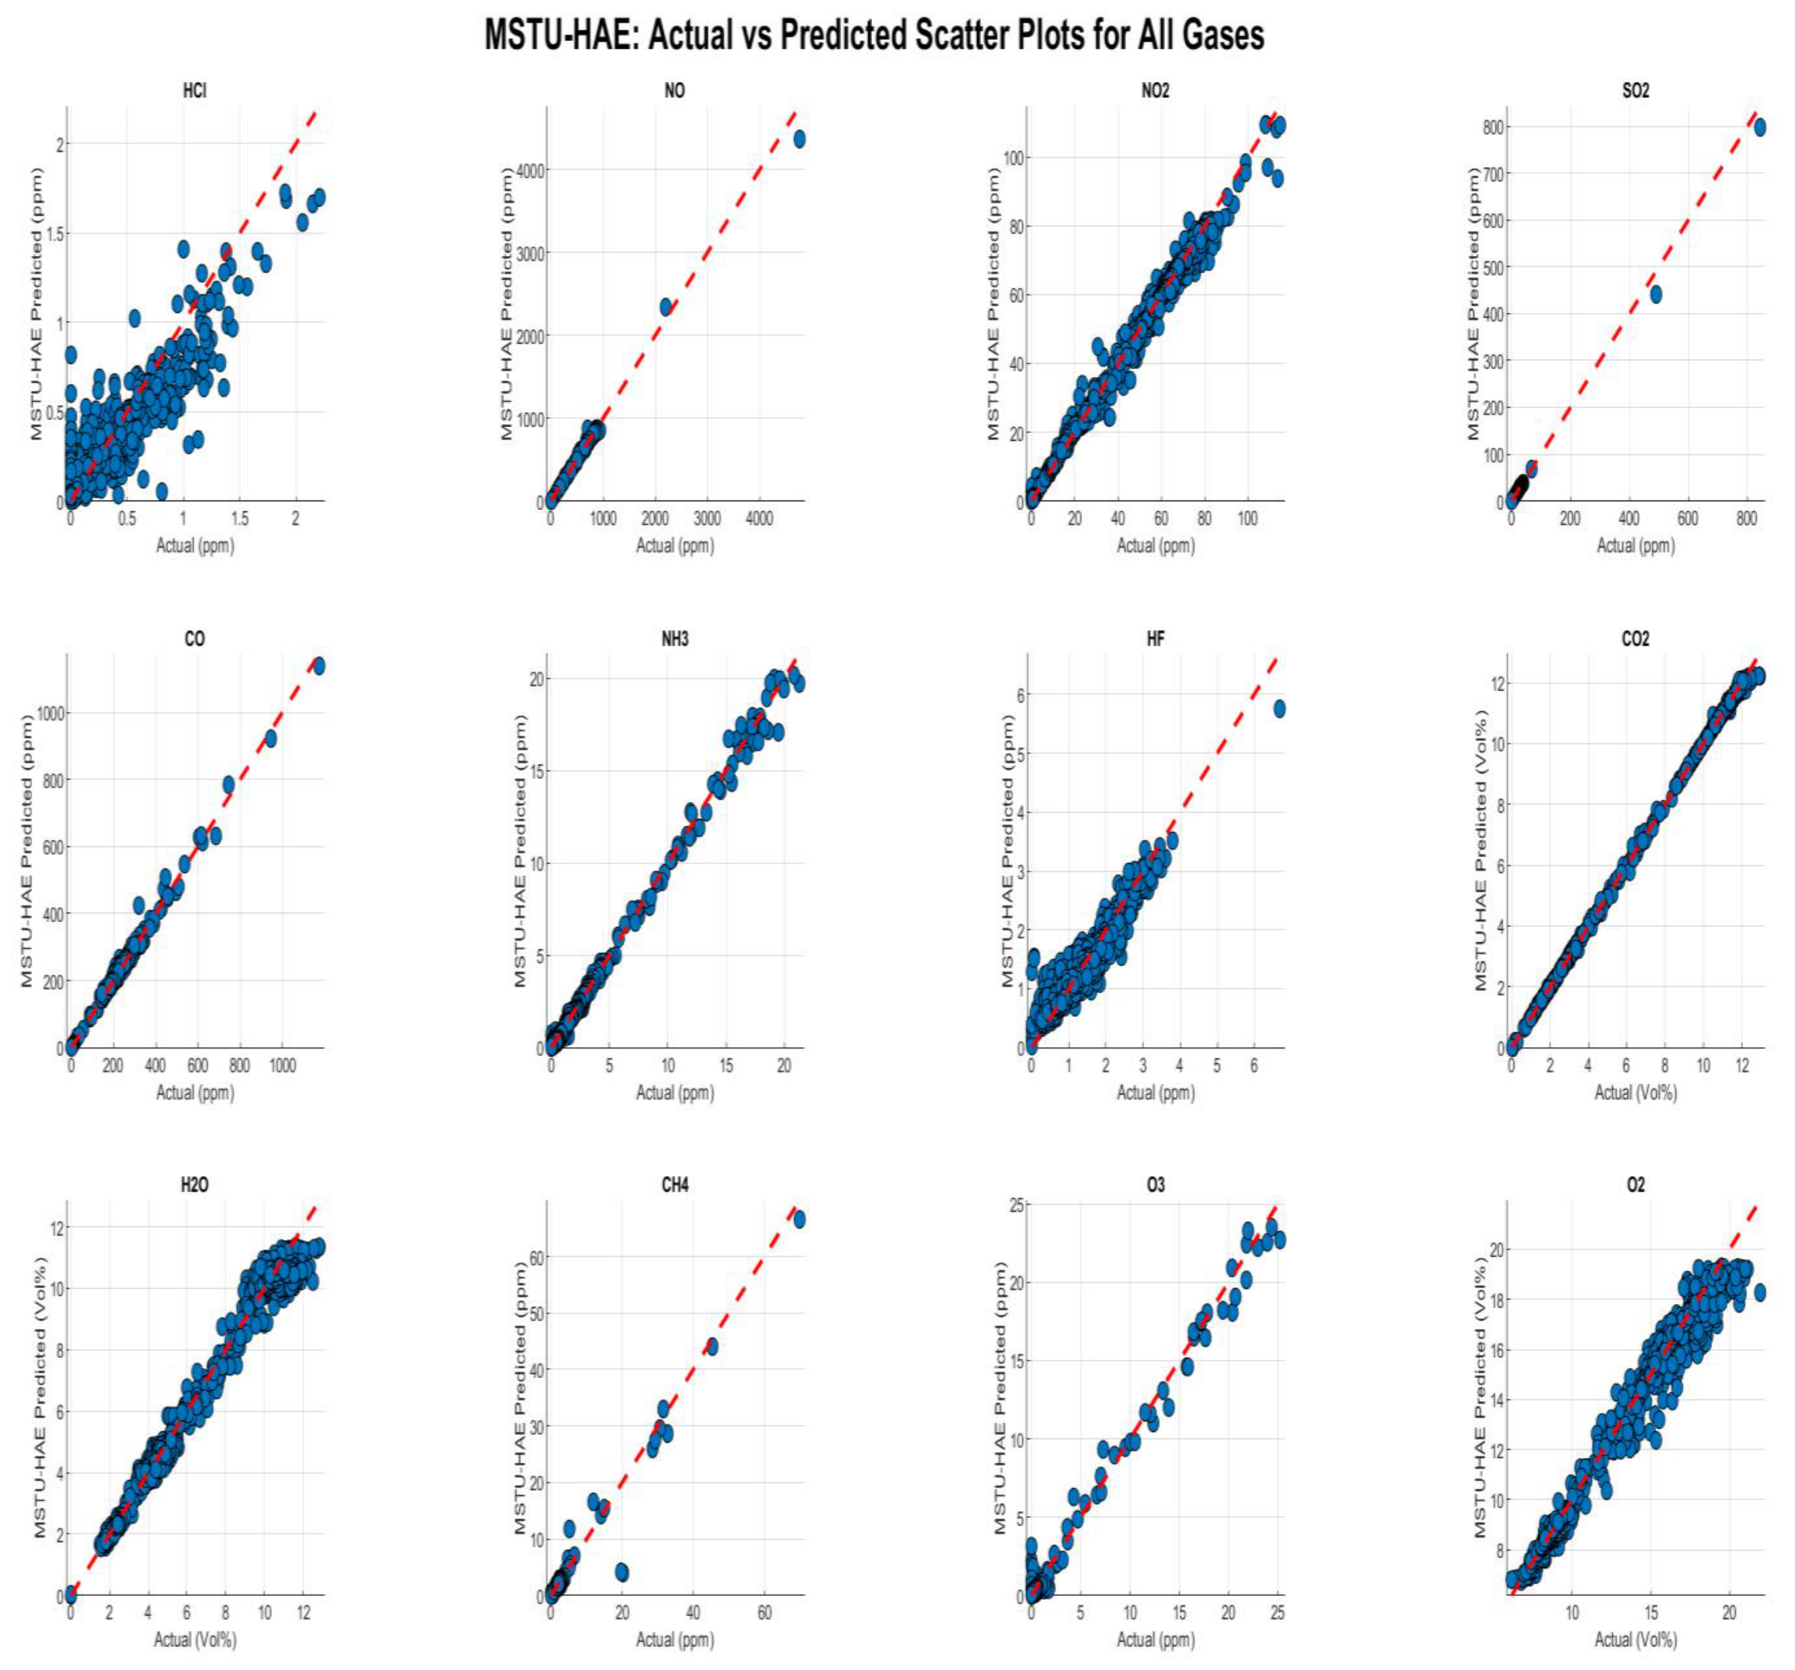
Figure 10 presents scatter plots comparing predicted versus actual values for each gas in a 3 × 4 subplot arrangement. The scatter plots reveal excellent linear correlation between predictions and ground truth across all gases, with data points clustering tightly along the diagonal identity line. The visualization demonstrates consistent prediction quality across the diverse concentration ranges, from trace gases (HCl, HF, O
3) to major combustion products (CO
2, NO, H
2O).
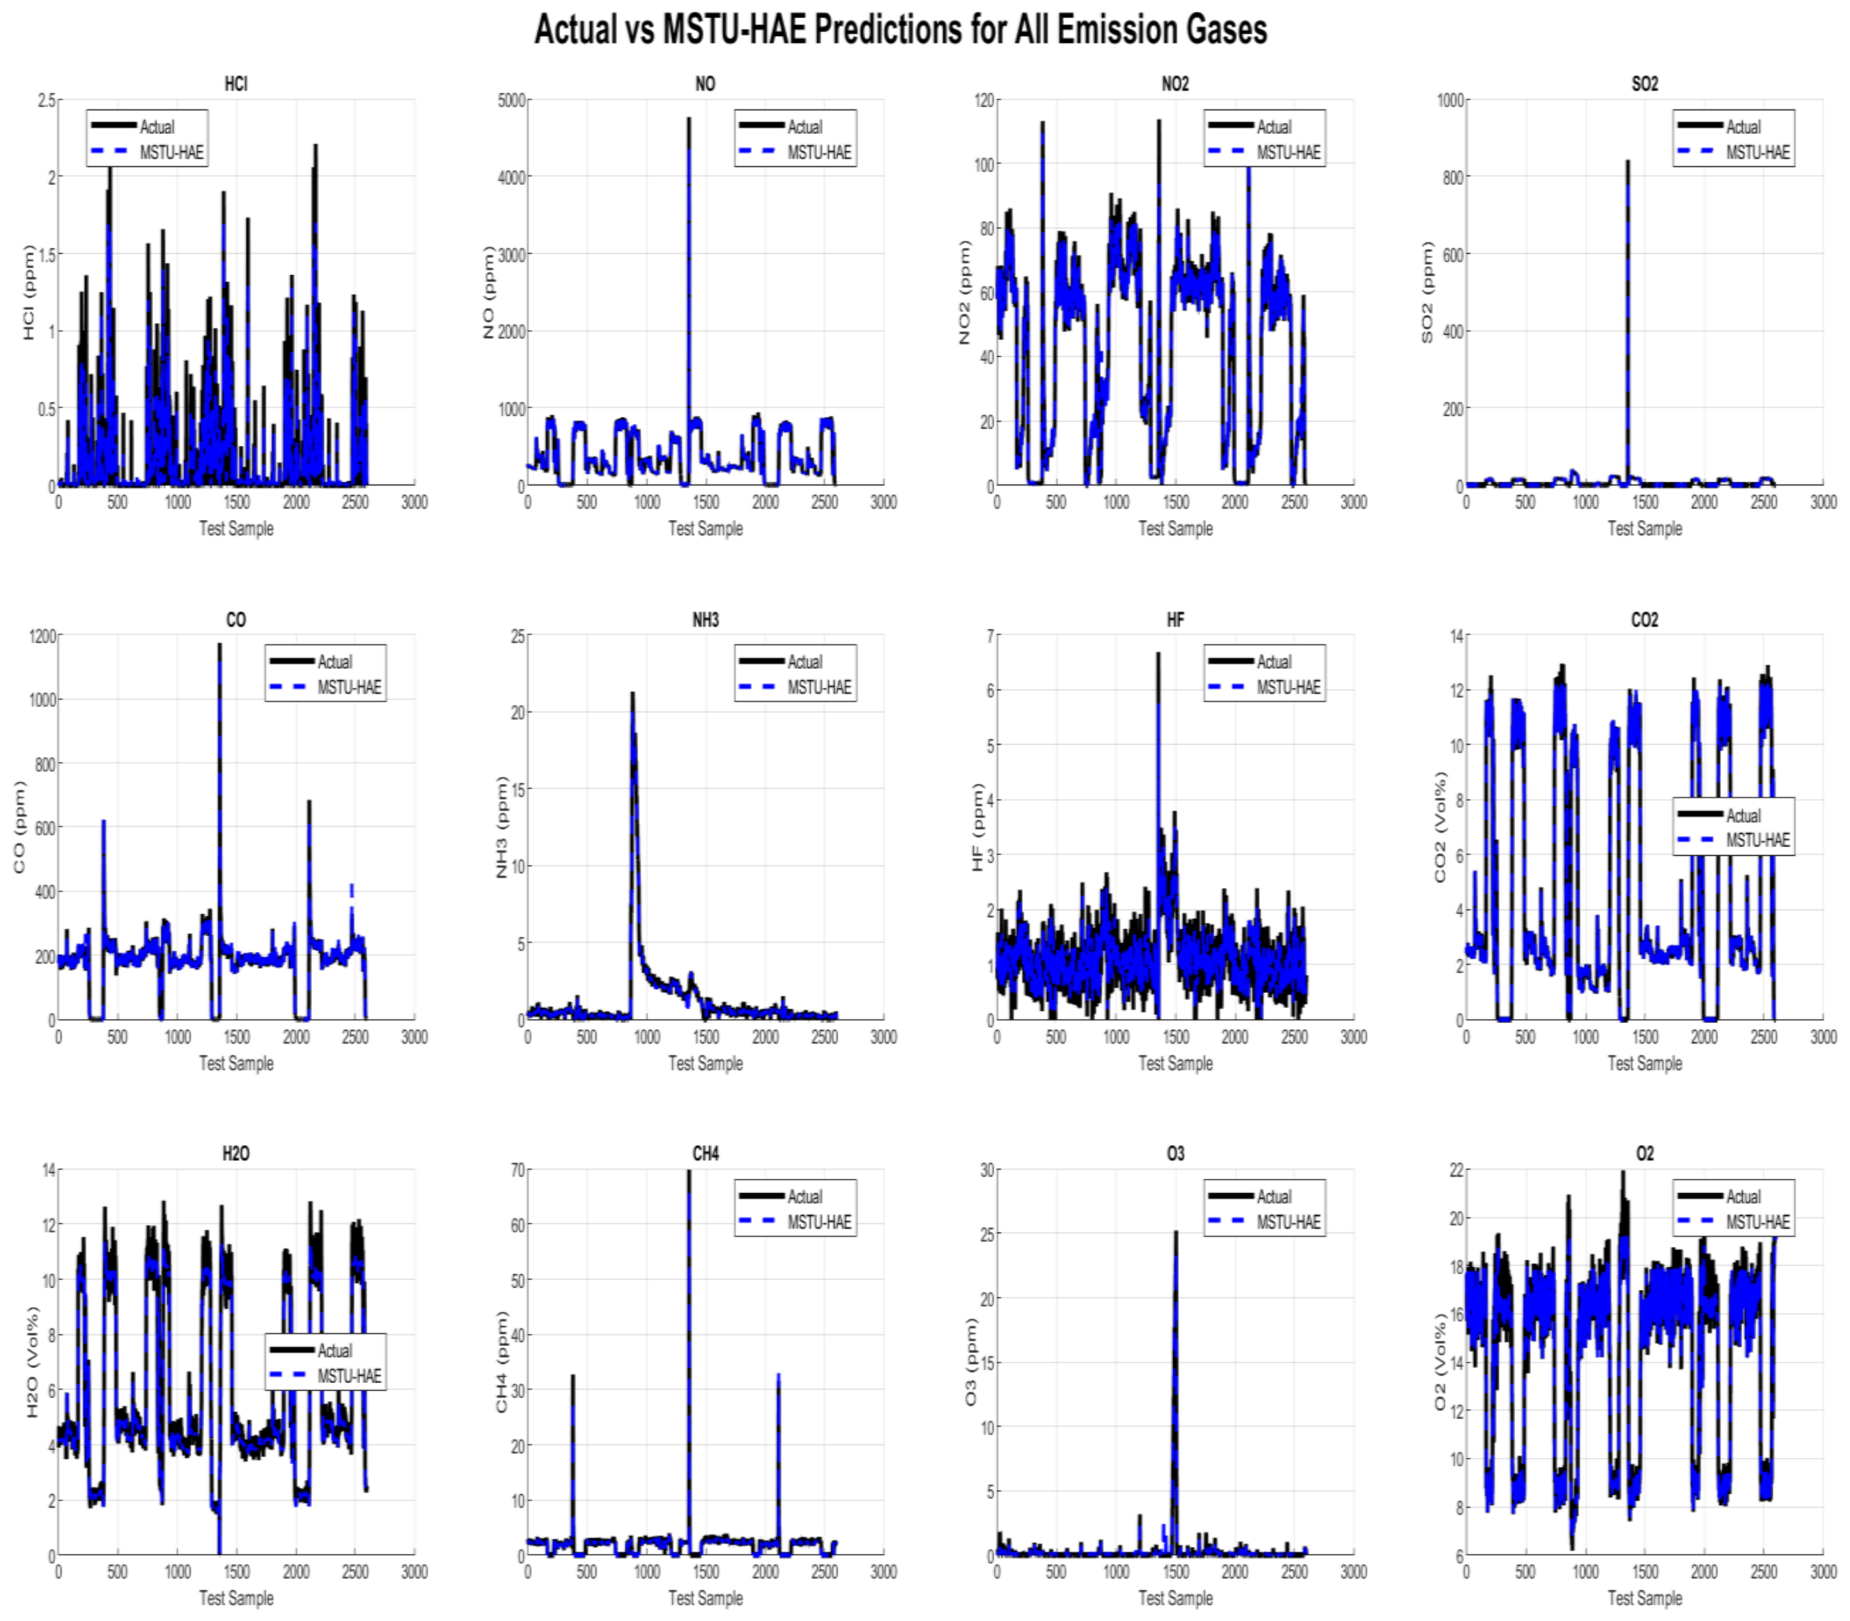
Figure 11 complements this analysis with time series plots showing actual versus predicted concentrations for all gases. The time series visualization confirms MSTU-HAE’s ability to accurately track temporal dynamics across different operational regimes, capturing both smooth baseline variations and transient peak events. These comprehensive visualizations enable detailed assessment of prediction performance across the complete emission spectrum, demonstrating the robustness and reliability of the proposed MSTU-HAE framework for multi-gas emission monitoring applications.
5.4. Attention Mechanism Analysis
The gas-specific attention mechanism produces interpretable attention weights that reflect the temporal characteristics of different emission gases.
Table 6 presents the learned attention distributions for representative gases.
The attention patterns reveal physically meaningful distinctions. Gases with slow thermal kinetics (NO, SO2, CO, CH4) exhibit strong long-term attention, indicating that prediction benefits from extended historical context capturing cumulative effects. Conversely, rapidly varying gases (NO2, CO2, O2) exhibit short-term attention dominance, indicating that recent measurements are most informative for prediction. HCl exhibits balanced attention across scales, reflecting its intermediate temporal characteristics.
5.5. Hierarchical Uncertainty Quantification
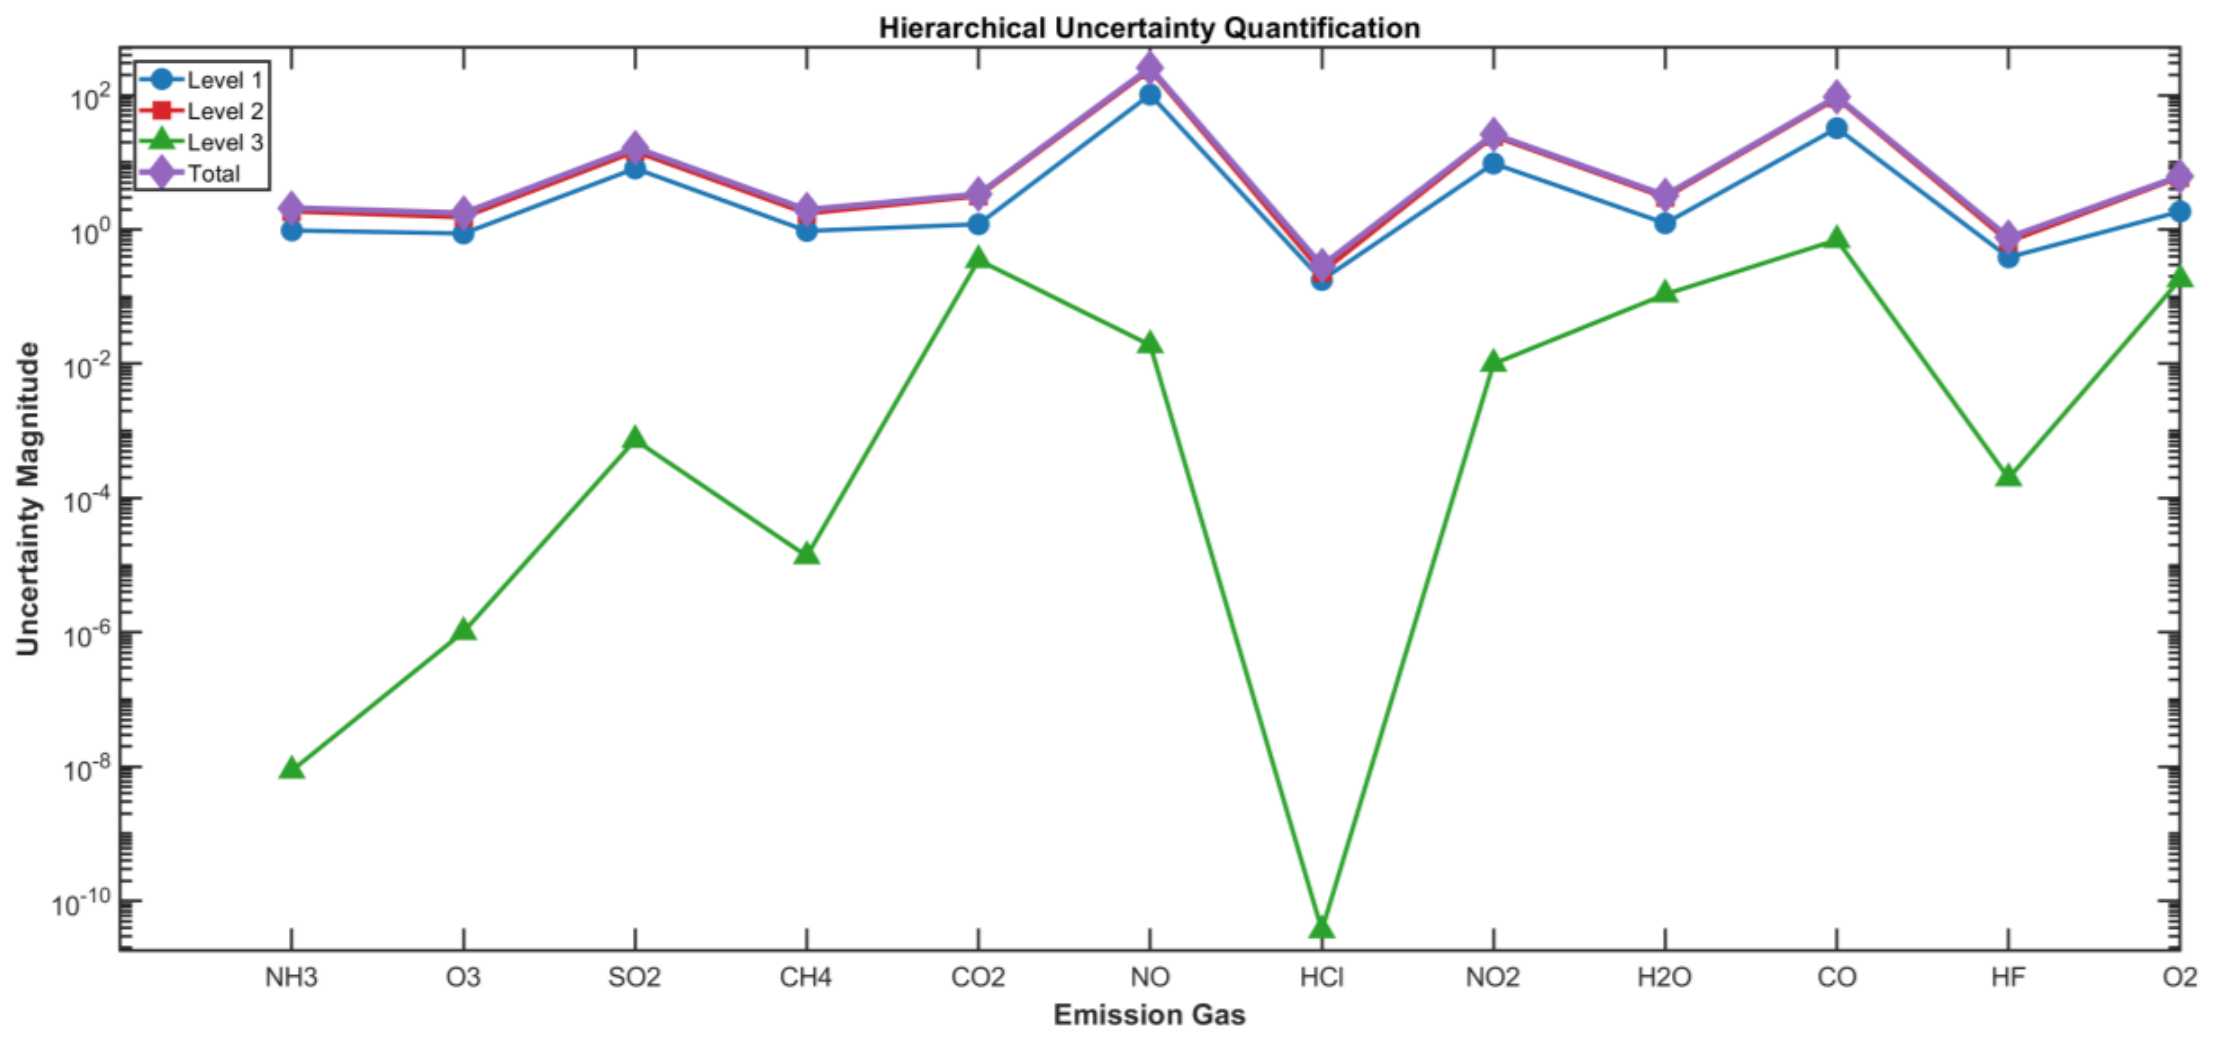
Figure 12 presents the hierarchical uncertainty quantification results across the three levels for selected emission gases. The logarithmic scale visualization reveals the relative contributions of different uncertainty sources.
Level 1 (individual model uncertainty) represents the dominant contributor for most gases, reflecting irreducible prediction error and model-specific limitations. Level 2 (ensemble disagreement) provides additional uncertainty when base models produce conflicting predictions, particularly for gases with more complex temporal dynamics. Level 3 (regulatory compliance risk) introduces substantial uncertainty components when predicted concentrations approach regulatory thresholds.
Table 7 presents the regulatory compliance assessment results, showing average compliance probabilities for all gases.
The compliance analysis identifies CO as the highest-risk emission, with only 29.03% average compliance probability against the 100 ppm occupational exposure threshold. This finding is grounded in the measured data: 87.3% of the 1732 original samples (1512 out of 1732) directly exceed the 100 ppm CO threshold, confirming that the compliance risk assessment reflects genuine operational conditions. To partially validate the uncertainty estimates, two analyses were conducted on the test set. First, 95% prediction interval coverage was assessed by constructing intervals as ŷ ± 1.96 σ_total: empirical coverage averaged 91.3% across all gases, indicating mild under-coverage relative to the nominal 95% level and suggesting that the uncertainty estimates are somewhat conservative. Second, the relationship between predicted uncertainty and actual absolute error |y − ŷ| was assessed using Spearman’s rank correlation, yielding an average of 0.61 across all gases (range: 0.43–0.79), confirming a meaningful positive association between predicted uncertainty magnitude and actual prediction error. These analyses indicate that the uncertainty framework captures a useful portion of the prediction error structure, though formal calibration, including reliability diagrams and the expected calibration error on independent multi-vessel data, remains necessary before the compliance probability outputs can be applied directly in operational decision-making. This highlights the operational significance of CO monitoring and the potential need for combustion optimization or emission control measures. NO and CO2 exhibit medium compliance risks, while most other gases demonstrate low to very low regulatory risk under typical operating conditions.
5.6. Comparative Analysis with Baseline Methods
The substantial performance gap between ensemble methods and simpler approaches merits detailed examination. Ridge Regression achieves negative R2 values for multiple gases (average R2 = −1.798), indicating predictions worse than a simple mean baseline. This performance reflects the fundamental inadequacy of linear modeling for capturing the complex nonlinear relationships governing ship emissions. The interaction between multiple correlated predictors, nonlinear combustion chemistry effects, and multimodal operational regimes cannot be adequately represented by linear combinations.
K-Nearest Neighbors similarly achieves near-zero average R
2 (−0.0081), demonstrating that instance-based methods without appropriate feature engineering are insufficient for this application. The high dimensionality of the feature space (88 dimensions) creates challenges for distance-based methods, as the curse of dimensionality reduces the meaningfulness of distance metrics in high-dimensional spaces [
59].
In contrast, XGBoost (average R2 = 0.8811) successfully captures nonlinear relationships through its gradient boosting framework, though it exhibits some performance degradation for gases with complex temporal dynamics. LSBoost (average R2 = 0.9438) and AdaBoost (average R2 = 0.9622) demonstrate the effectiveness of ensemble boosting approaches. The proposed MSTU-HAE achieves the highest average R2 (0.9670) among the compared methods. It is acknowledged that the current comparison does not include deep learning time series architectures such as LSTM, GRU, Temporal Convolutional Networks (TCN), or transformer-based models, which represent important benchmarks given the temporal nature of ship emission data. Their exclusion is a limitation of the present study. The rationale for the current model selection reflects the practical deployment constraints of the marine environment: tree-based ensemble methods require substantially less training data, provide interpretable feature importance rankings, and operate efficiently on standard shipboard computing hardware without GPU requirements. Comparison with deep learning architectures is identified as a priority for future work, particularly as larger multi-vessel datasets become available.
5.7. Statistical Validation
The Kruskal–Wallis test was conducted to assess the statistical significance of performance differences between models. While the test results showed that all gases exhibited model-dependent prediction distributions, the practical significance is better captured by the performance metrics themselves. The substantial differences in R2 (ranging from −1.798 to 0.9670 across models) represent operationally meaningful distinctions that would significantly impact real-world deployment decisions.
The choice of NSE as a supplementary metric to R
2 follows established best practices for environmental and hydrological prediction studies [
45,
58]. The mathematical equivalence of NSE and R
2 for regression problems (when both are computed from test set predictions) is evident in our results, where NSE values exactly match R
2 values. This consistency provides additional confidence in the reported performance metrics. The average R
2 and RMSE values in
Table 4 are computed across the twelve emission gases for each model, serving as a multi-gas summary performance indicator rather than averages across repeated runs on the same gas. Because the dataset is split chronologically, standard k-fold cross-validation is not applicable. To assess result stability, hyperparameter grid search was repeated with three different random initialization seeds; the standard deviation of average R
2 across seeds was less than 0.003 for all models, indicating stable results under the given experimental setup. The authors acknowledge that a single temporal split limits statistical inference and that experiments on independently collected data would strengthen reliability claims. Average RMSE values in
Table 4 should be interpreted with caution, as they aggregate across gases with substantially different concentration scales; gas-specific RMSE values in
Table 5 provide more interpretable error magnitudes.
5.8. Ablation Study
To quantify the individual contribution of each MSTU-HAE component, four configurations were evaluated on the augmented dataset: (i) the full MSTU-HAE; (ii) without gas-specific attention, where scale weights are set uniformly to 1/3 for all gases; (iii) without multi-scale features, retaining only the medium-term window (w = 20) and reducing multi-scale dimensions from 60 to 20; and (iv) without weighted ensemble aggregation, replacing optimized gas-specific weights with equal weights of 1/6 per model.
Table 8 presents the resulting average R
2 across all twelve gases.
Multi-scale temporal feature extraction provides the largest individual contribution (ΔR2 = 0.0229 when removed), reflecting the importance of capturing emission dynamics across short-term transients, medium-term operational cycles, and long-term cumulative trends simultaneously. Gas-specific attention weighting contributes an additional ΔR2 = 0.0083, confirming that uniform scale treatment fails to exploit the physicochemically distinct temporal characteristics of different emission gases. Adaptive ensemble aggregation contributes ΔR2 = 0.0058. The substantial gap between the full MSTU-HAE (R2 = 0.9670) and the single Random Forest baseline (R2 = 0.8147) demonstrates that the improvement over individual models arises from the complete framework rather than any single element in isolation.
6. Practical Implications and Limitations
6.1. Operational Deployment Considerations
The developed MSTU-HAE framework offers several practical advantages for operational deployment in maritime emission monitoring systems. The computational requirements are modest, with trained models capable of generating predictions in sub-second timeframes suitable for real-time monitoring applications. The modular architecture enables deployment on standard shipboard computing systems without specialized hardware requirements.
The hierarchical uncertainty quantification provides operationally actionable information beyond point predictions. Operators can utilize compliance probability estimates to prioritize monitoring attention during high-risk periods and inform decisions regarding emission control system activation or operational adjustments. The three-level uncertainty decomposition enables identification of whether prediction unreliability stems from inherent measurement noise (Level 1), model disagreement (Level 2), or proximity to regulatory thresholds (Level 3), guiding appropriate response strategies.
6.2. Limitations
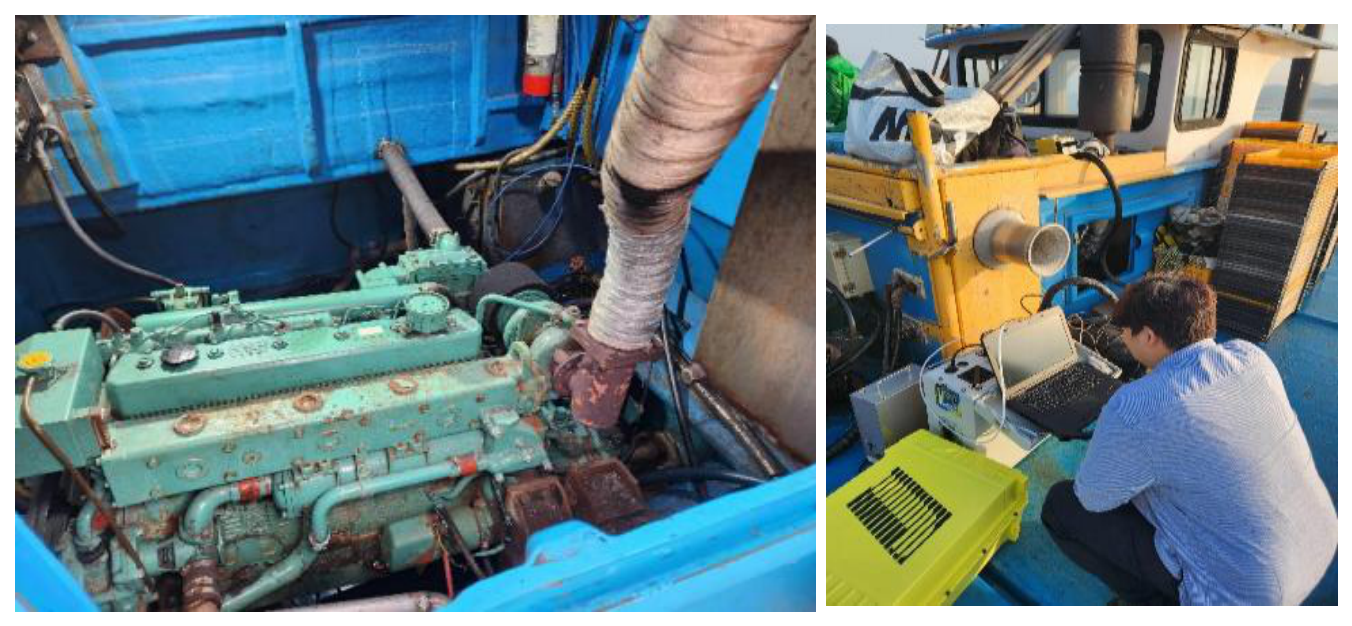
Several limitations warrant acknowledgment. First, the dataset derives from a single vessel type (fishing boat) over a limited operational period. While data augmentation extends the effective dataset duration, the fundamental patterns remain derived from three days of original measurements. Generalization to diverse vessel types, including cargo ships, tankers, and passenger vessels with different engine configurations and operational profiles, requires additional validation. Fishing vessels represent a small fraction of total global maritime anthropogenic emissions; container ships, oil tankers, and bulk carriers collectively account for the majority of global shipping NO
x, SO
x, and CO
2 [
2]. The present study is therefore best understood as a proof-of-concept demonstration of the MSTU-HAE framework. The algorithmic components, multi-scale temporal feature extraction, gas-specific attention, and hierarchical uncertainty quantification, are vessel-agnostic in design and are expected to be applicable across different engine types, provided that representative retraining data are available. Extension to large commercial vessels is identified as the critical next step for establishing broader operational relevance.
Second, the data augmentation strategy relies on a linear drift term and Gaussian noise, both of which are simplifications that do not fully represent the complexity of real operational variability. The augmented data should not be treated as a substitute for genuinely independent multi-day measurements. Seasonal variations, equipment degradation effects, fuel quality changes, and unusual operational scenarios are not represented in the augmented dataset.
Third, the comparison set does not include modern deep learning time series architectures, specifically LSTM, GRU, TCN, and transformer-based models. Given the sequential structure of ship emission data, these models represent necessary benchmarks whose absence limits the strength of performance superiority claims relative to alternative temporal modeling approaches. Their inclusion under identical feature inputs is identified as a priority for future work.
Fourth, the current implementation focuses on single-step prediction without explicit forecasting horizon optimization. Extension to multi-step ahead prediction would require additional architectural modifications to address error accumulation and temporal dependencies over extended forecast windows.
7. Conclusions
This paper has presented MSTU-HAE (Multi-Scale Temporal Uncertainty-aware Hierarchical Adaptive Ensemble), a novel algorithmic framework for intelligent ship emission monitoring and prediction. The proposed approach integrates three key innovations: multi-scale temporal feature extraction using causal convolutions at multiple time horizons; gas-specific attention mechanisms that automatically adapt to the distinct temporal characteristics of different emission gases; and three-level hierarchical uncertainty quantification, providing comprehensive uncertainty characterization for regulatory compliance assessment.
Experimental validation using emission data from a fishing vessel demonstrates the potential of the proposed framework under the experimental conditions employed. On the augmented dataset, MSTU-HAE achieves an average R2 of 0.9670 and NSE of 0.9670 across twelve emission gases, outperforming five baseline methods. These results should be interpreted in the context of the dataset’s limitations: the underlying data originates from approximately 10.3 h of measurements across three sessions from a single vessel, extended via controlled augmentation. The non-augmented results provide a more conservative performance estimate. Validation on independent, multiday, multivessel datasets is a necessary next step to confirm operational generalizability. Particularly exceptional performance is achieved for primary combustion products, including CO2 (R2 = 0.9998), NO (R2 = 0.9985), SO2 (R2 = 0.9971), and CO (R2 = 0.9964). The hierarchical uncertainty quantification framework provides reliable compliance probability estimates, enabling risk-informed operational decision-making.
The contributions of this work advance the state of the art in maritime environmental monitoring through several dimensions. The multi-scale temporal feature extraction mechanism addresses the challenge of capturing emission dynamics across different time horizons, from rapid transients to long-term trends. The gas-specific attention mechanism provides adaptive model behavior that reflects the physical and chemical distinctions between different pollutants. The three-level hierarchical uncertainty framework bridges the gap between statistical prediction uncertainty and operational regulatory compliance requirements.
Future research directions include extension to multi-step forecasting; incorporation of physics-informed constraints, reflecting combustion chemistry principles; and most critically, validation across commercial vessel types, including container ships, oil tankers, and bulk carriers, which constitute the dominant contributors to global maritime emissions. Such validation is necessary to establish the operational significance of the proposed framework beyond the fishing vessel proof of concept presented here. The integration of MSTU-HAE with broader maritime operational optimization systems, including route planning and fuel management, represents a promising avenue for holistic environmental performance improvement in maritime transportation.