Review

A Focused Survey of Generative AI-Based Music Therapy Systems: Recent Progress and Open Challenges

by
Jin S. Seo
Department of Electronic and Semiconductor Engineering, Kangwon National University, Gangneung 25457, Republic of Korea
Appl. Sci. 2026, 16(9), 4120; https://doi.org/10.3390/app16094120
Submission received: 5 March 2026 / Revised: 10 April 2026 / Accepted: 20 April 2026 / Published: 23 April 2026
(This article belongs to the Special Issue Advances in Digital Health Technologies)

Abstract

Generative artificial intelligence (AI)-based music generation has the potential to create new opportunities for music therapy; however, integrated examinations of generative AI and music therapy remain limited. This paper provides a focused survey of recent studies that apply generative AI within music therapy-related contexts, examining how such approaches have been explored in relation to therapeutic considerations, including emotional and physiological regulation. Rather than offering an exhaustive historical review, we analyze generative AI-augmented music therapy systems from a system-level perspective, focusing on their overall design and implementation. Based on this survey, we discuss open research challenges at the intersection of generative music, adaptive systems, and digital health, and outline future research directions toward scalable and personalized generative AI-based music therapy.

1. Introduction

Mental and developmental disorders affect individuals across the lifespan and remain among the leading contributors to the global burden of disease, imposing substantial social, economic, and healthcare costs worldwide. Alongside pharmacological and psychotherapeutic interventions, music therapy has emerged as an effective complementary intervention for supporting emotional regulation, cognitive functioning, and psychosocial well-being. Often described as a universal language, music plays a fundamental role in human emotional expression and social communication, making it particularly well suited for therapeutic contexts that require nonverbal or affect-centered interventions [1,2,3].
A large body of clinical and experimental research has demonstrated the therapeutic benefits of music-based interventions across diverse populations and conditions [4]. Structured music therapy has been shown to reduce symptoms of anxiety [5] and depression [6], alleviate behavioral disturbances in dementia [7], promote cognitive and language development in children [8], and enhance emotional resilience in individuals experiencing chronic illness or psychological stress [9]. Across the lifespan, music therapy engages multiple therapeutic mechanisms, including emotional expression, social interaction, memory recall, and physiological regulation. Despite these advantages, traditional music therapy practices often rely on fixed musical repertoires or therapist-led improvisation, which limits scalability [10,11]. Especially where trained music therapists are scarce [12], fine-grained and continuous personalization is difficult to achieve in real time. Recent advances in generative artificial intelligence (AI) have significantly expanded data-driven music generation and modeling, enabling increasingly adaptive and personalized music-based intervention systems. Contemporary generative music AI (GMAI) systems can produce high-quality, structurally coherent, and stylistically diverse music in both symbolic and audio domains [13,14,15]. In parallel, progress in affective computing, multimodal sensing, and digital health technologies has enabled continuous or near-continuous measurement of users’ emotional, physiological, and behavioral states [16]. The convergence of these developments has given rise to GMAI-augmented music therapy, in which generative models are informed by contextual or user-state information to support personalized musical experiences in therapeutic settings.
In this paper, GMAI refers to AI models based on deep generative architectures that can produce symbolic music representations, audio waveforms, or hybrid forms thereof. Through multimodal sensing and affective modeling, changes in a user’s emotional or physiological state can be estimated, and such information may be used to guide generative models toward music that is appropriate for individual preferences, cultural context, or therapeutic intent. GMAI systems may be deployed either as stand-alone tools or as assistive technologies that support music therapists. By enabling adaptive and interactive musical experiences, GMAI-based music therapy has the potential not only to enhance therapeutic effectiveness but also to improve accessibility and scalability, particularly in resource-limited or remote healthcare environments [10,17].
Despite growing interest, research at the intersection of generative AI and music therapy remains fragmented. Existing review studies tend to focus either on the therapeutic effects of music for specific clinical populations [1,2,4] or on advances in music generation technologies themselves [13,14,15]. In contrast, system-level integration, including architectural design, user interaction and UI/UX considerations, and differentiated generative strategies tailored to therapeutic goals and target populations, has received comparatively limited attention. Furthermore, recent technical developments, such as controllable music generation [18], multimodal representation learning [16], and reinforcement learning-based personalization [19], have not yet been coherently synthesized within the context of music therapy. As generative models continue to mature and interest in AI-driven digital therapeutics grows, there is an increasing need for an architecture-oriented and focused survey of generative AI-based music therapy systems.
Accordingly, this paper aims to analyze recent representative research trends in which generative AI has been integrated into music therapy-related systems and to identify key open challenges and future research directions. To this end, we address the following research questions:
  • RQ1 (Conceptual perspective): How have generative AI-based music generation techniques been conceptualized and utilized in music therapy contexts, and how have therapeutic considerations, such as emotional or physiological regulation, been discussed in relation to generative mechanisms?
  • RQ2 (System-level perspective): How do AI-augmented music therapy systems incorporate common components-including sensing, affective state modeling, generative music modules, and adaptive feedback loops-and how are these components implemented across experimental and real-world settings?
  • RQ3 (Future outlook): What major open challenges remain at the intersection of generative music, affect-aware adaptation, and digital health, and what research directions are required to enable scalable and personalized generative AI-based music therapy?
The remainder of this paper is organized as follows. Section 2 reviews the background of music therapy and GMAI. Section 3 outlines the literature search methodology and presents the integrated system architecture derived from the surveyed studies. Section 4 discusses representative case studies mapped onto the derived system architecture, and highlights open challenges and future research directions for adaptive, generative AI-based music therapy systems.

2. Music Therapy and Digital Technology-Based Interventions

Music therapy is a clinically established intervention that utilizes structured musical experiences to support emotional regulation, cognitive engagement, and social interaction across diverse populations. While traditional active and receptive methods rely on human-mediated adaptation, the field is increasingly shifting toward digital frameworks to enhance the precision and scalability of these interventions.

2.1. Digital Transformation of Music Therapy Interventions

The transition from traditional practices to digital technology-based interventions has fundamentally altered the therapeutic landscape. Early systems primarily functioned through rule-based playback, but modern approaches integrate affective computing and multimodal sensing to enable responsive and adaptive therapeutic environments.
While traditional music therapy has established efficacy across clinical conditions-ranging from stress reduction in mental health to cognitive stimulation in dementia care-recent advances in digital sensing and interactive media have driven a shift toward computationally grounded intervention paradigms [20]. In this context, generative AI has emerged as a key enabling technology, moving beyond static playback control toward systems that adapt musical content based on real-time physiological and behavioral data.
Building on these advances, recent digital interventions increasingly incorporate GMAI with affective computing frameworks, enabling closed-loop interaction through the integration of physiological signals, behavioral cues, and user feedback. The potential benefits of such digital technology-based music interventions can be summarized as follows:
  • Large-scale personalization: GMAI enables the creation of music that reflects individual preferences, cultural background, and therapeutic needs. This capability supports more fine-grained personalization even in contexts where direct therapist involvement is limited.
  • Dynamic adaptability: By leveraging real-time physiological and behavioral data-such as heart rate, affective state estimates, or sleep-related indicators-generative systems can produce context-sensitive music that responds to a user’s current condition. This dynamic adaptation has the potential to enhance intervention effectiveness in applications such as stress management, mood regulation, and neurorehabilitation.
  • Accessibility and scalability: By reducing reliance on continuous access to trained therapists or pre-curated musical content, AI-based music intervention systems can improve accessibility to music therapy in resource-constrained or remote environments.
These capabilities position GMAI-based systems as a key enabler of next-generation music therapy, bridging personalized intervention with scalable and adaptive digital health solutions.

2.2. Generative AI for Music

Automated or AI-based music generation is a research area at the intersection of computational creativity, machine learning, and audio signal processing, and has evolved steadily over the past several decades. Such systems are commonly referred to as music generation systems [21] and, as illustrated in Figure 1, support various stages of the music production pipeline, including composition, arrangement, sound design, mixing, and mastering.
In practical music generation settings, the input representation plays a critical role in determining both model behavior and output characteristics. Inputs may take diverse forms, such as symbolic sequences (e.g., MIDI), raw audio waveforms, spectral representations, text prompts, style descriptors, structural templates, or excerpts of reference music. These representation choices directly influence model dimensionality, training stability, and the perceptual quality of the generated output. GMAI systems leverage such inputs to support interactive creative processes, including ideation and exploration, and to determine melodic, harmonic, rhythmic, timbral, and expressive attributes of generated music. Prior to the widespread adoption of deep learning, music generation had been extensively studied using a range of computational approaches [22]. Early systems were primarily based on rule-based methods grounded in explicit music theory and compositional constraints, and were later extended using probabilistic models such as Markov models and optimization techniques including evolutionary algorithms. While these approaches allowed for transparent incorporation of musical rules, they faced inherent limitations in expressive flexibility, musical diversity, and emotional depth. With the introduction of deep learning, music generation transitioned decisively toward data-driven, sequence-based modeling paradigms [23]. Recurrent neural networks (RNNs) and long short-term memory (LSTM) architectures enabled effective modeling of music as temporal sequences, capturing local temporal dependencies and forming the foundation of symbolic music generation. The subsequent adoption of transformer architectures further advanced the field by employing attention mechanisms to model long-range structure and complex inter-instrument relationships, substantially improving performance in symbolic composition and performance modeling tasks [24].
Despite their strengths in learning high-level musical structures such as melody, harmony, and rhythm, symbolic approaches remain limited in representing key perceptual aspects of real-world music, including timbre, performance nuance, and fine-grained expressive gestures. To address these limitations, recent research has increasingly shifted toward audio-domain music generation, in which models synthesize high-fidelity audio directly in the waveform domain, typically conditioned on raw waveforms or high-resolution acoustic representations. Sample-level audio generation became feasible with autoregressive models such as WaveNet [25], while generative adversarial network (GAN)-based approaches later improved synthesis efficiency while maintaining direct waveform-level generation [26,27]. More recently, diffusion-based models have emerged as a dominant paradigm, demonstrating strong performance in terms of audio quality, stability, and temporal coherence [28].
In parallel, self-supervised learning on large-scale audio corpora has led to significant advances in music representation learning [29,30]. The resulting embeddings capture rich musical attributes, including semantic content, style, instrument identity, and expressive characteristics, and have become a core foundation for multimodal music generation systems that integrate audio, symbolic, and textual modalities. Enabled by these technological developments, AI-generated music has been increasingly adopted in applications such as game audio, adaptive soundtracks, virtual production, interactive composition, and large-scale content generation.
Nevertheless, music remains a highly complex generative target that simultaneously demands hierarchical structure, polyphonic coherence, and expressive communication. In particular, the precise control [31] of emotional conveyance, tension-release dynamics, and subtle expressive variation continues to pose fundamental challenges for generative models. These limitations are especially salient in therapeutic contexts, where musical expressivity and contextual appropriateness play a critical role, underscoring the need for system-level integration and adaptive control strategies in generative AI-based music therapy systems.

3. System Design Framework for AI-Based Music Therapy

To examine recent developments in AI-based music therapy, a structured literature search was conducted using Web of Science (WoS) and Google Scholar. The primary Boolean query applied to titles, abstracts, and metadata included the terms “music therapy” OR “intervention.” WoS was selected for its curated indexing and standardized metadata quality, whereas Google Scholar was used to ensure broader coverage of interdisciplinary and emerging research spanning computer science, digital health, and music technology.
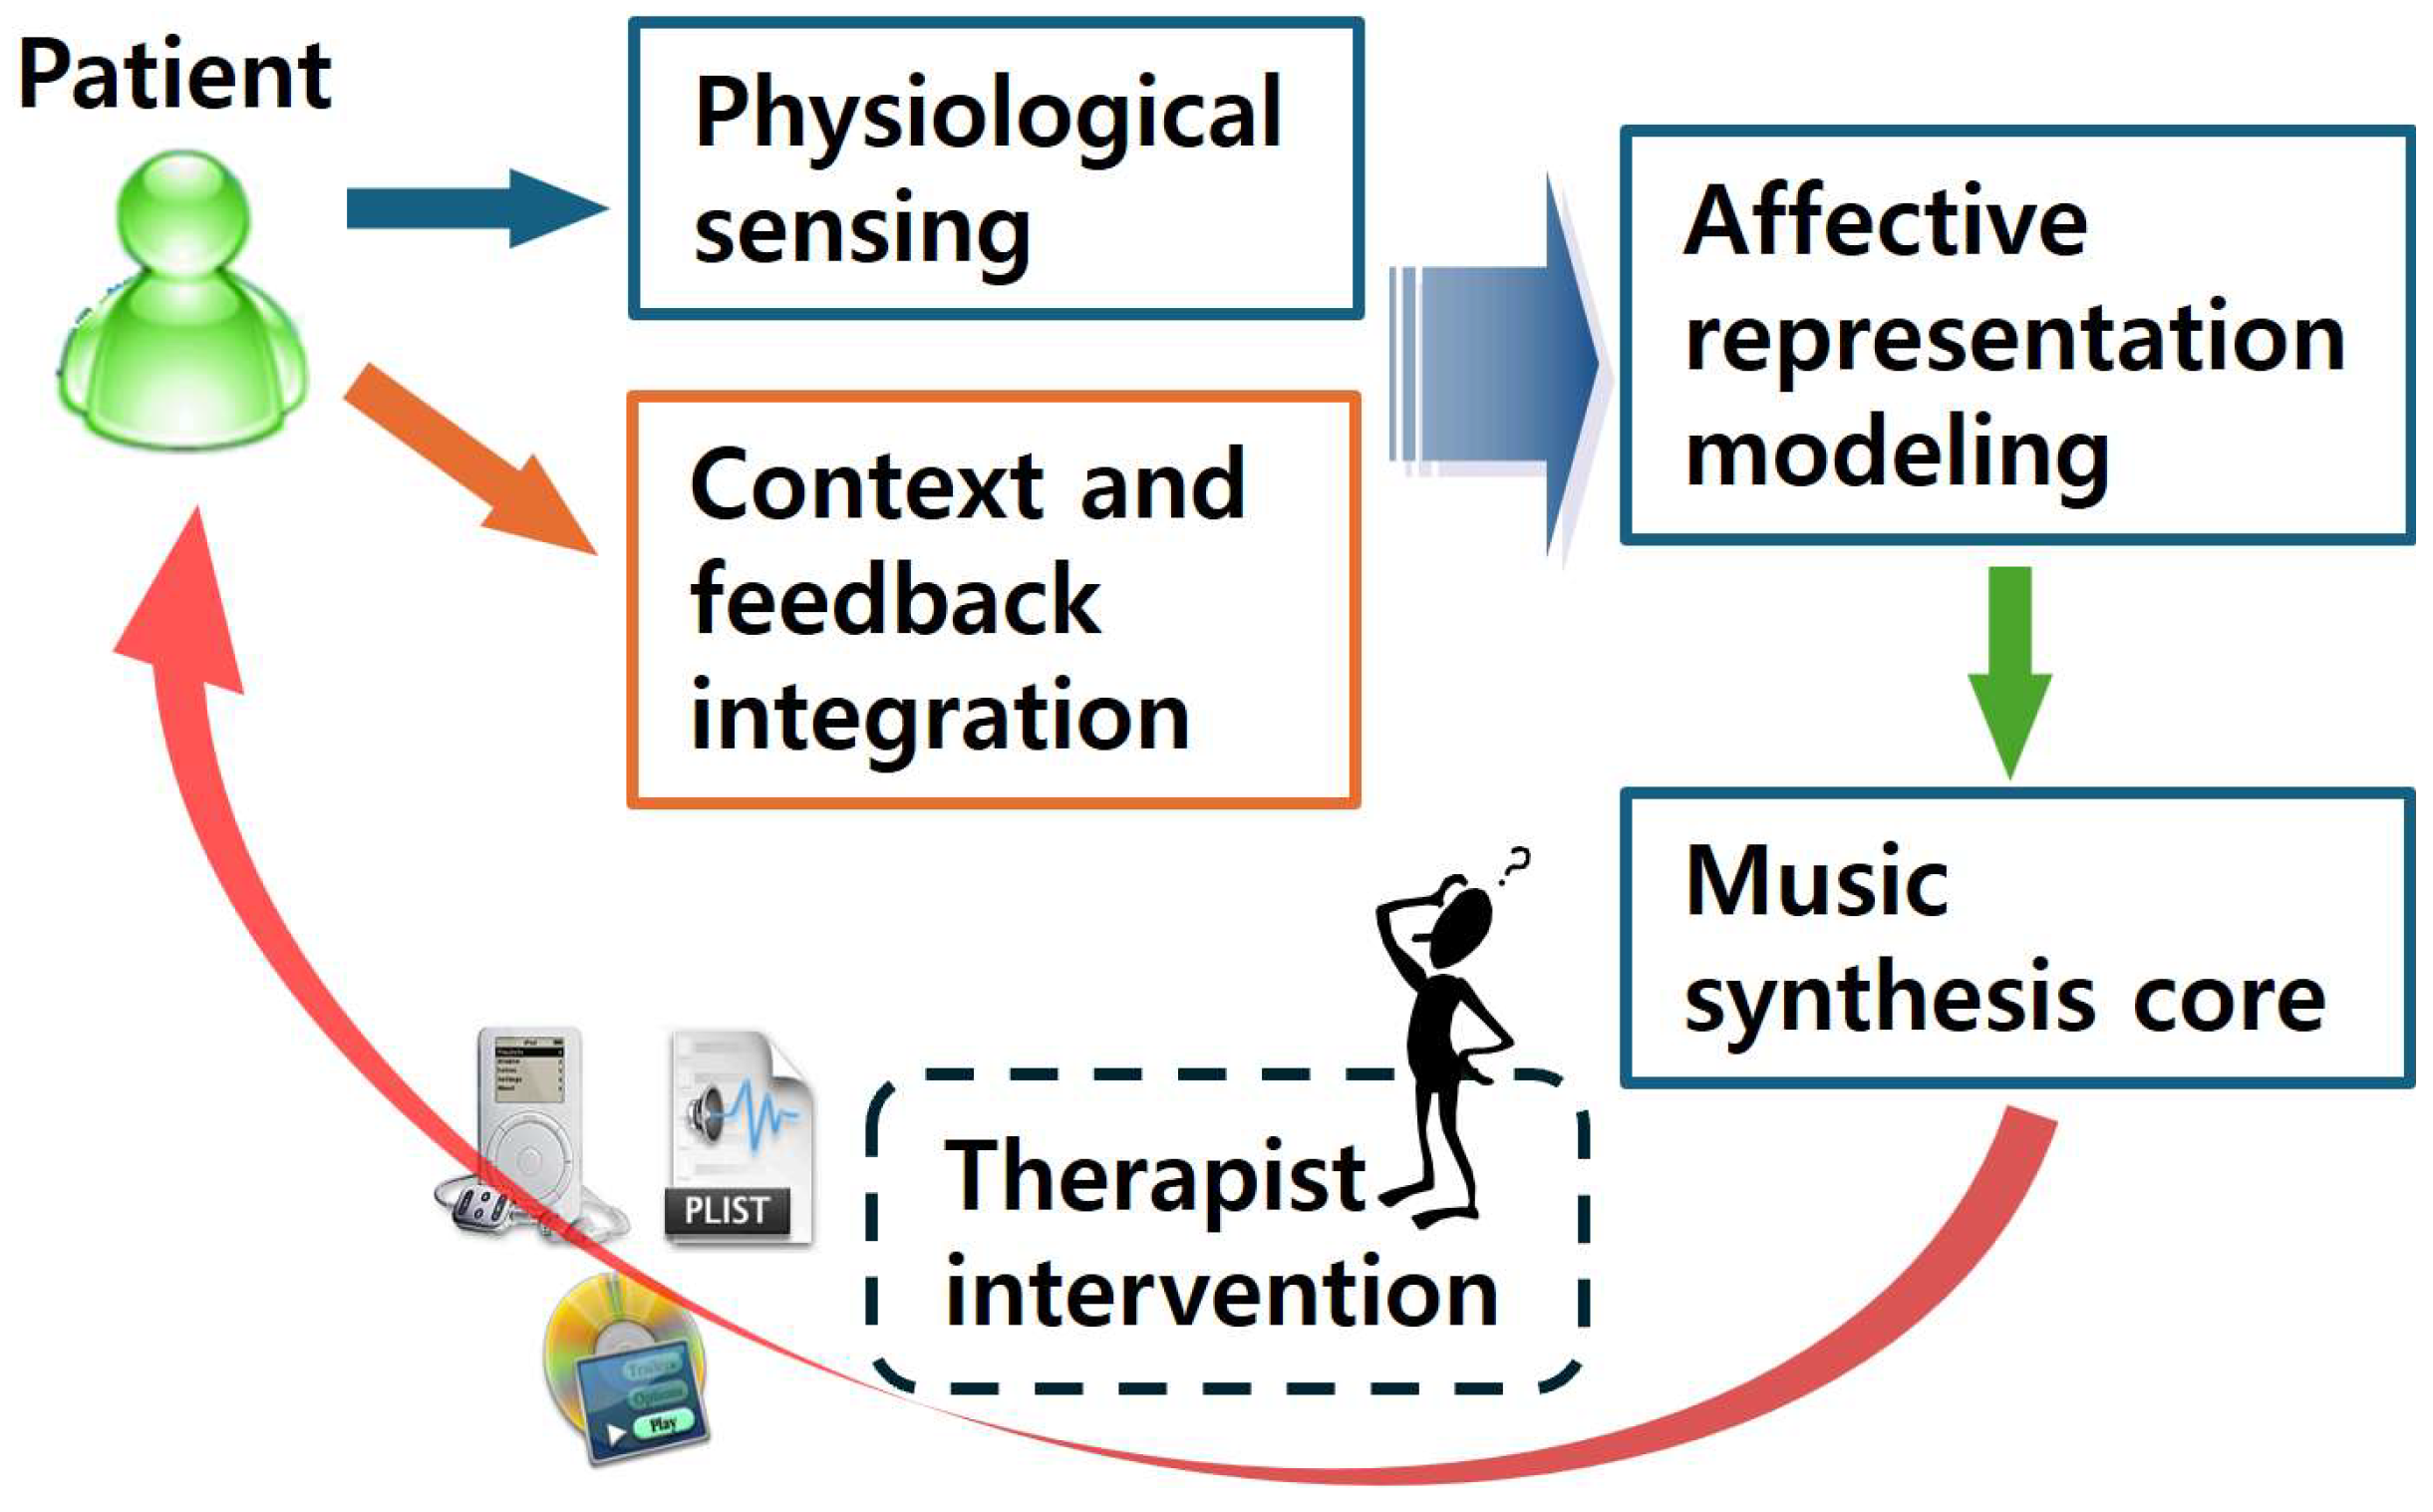
This survey adopts a system-oriented perspective, emphasizing architectural design aspects, including computational models, modular configurations, interaction pipelines, and multimodal integration strategies, rather than quantitative validation of therapeutic efficacy or comparative clinical performance. Analysis of the retrieved studies revealed recurring architectural patterns that can be abstracted into four functional layers, as illustrated in Figure 2. Although individual systems differ in sensing modalities, music generation techniques, and therapeutic application contexts, many share a modular and closed-loop structure grounded in principles of affective computing.
From this perspective, AI-based music therapy systems may be conceptualized as comprising four interconnected functional layers: (1) sensing, (2) affective modeling, (3) music generation, (4) adaptive feedback. These layers provide an organizational lens for examining how multimodal inputs, AI-driven generative models, and control mechanisms are coordinated to enable adaptive and personalized music-based interventions.
The four-layer architecture shown in Figure 2 is proposed as an interpretive framework for organizing heterogeneous systems reported in the literature. It does not prescribe a specific implementation strategy nor claim methodological novelty; rather, it offers a descriptive abstraction of structural elements that recur across existing approaches. Table 1 summarizes the primary roles and typical design characteristics associated with each functional layer. Detailed discussions of representative methods, design considerations, and technical variations are provided in Section 3.1, Section 3.2, Section 3.3 and Section 3.4.

3.1. Multimodal Acquisition Layer

The multimodal acquisition layer is responsible for collecting observable signals that reflect the user’s emotional, cognitive, and physiological states. Because complex affective responses and therapeutic dynamics cannot be sufficiently captured by a single signal modality, recent systems increasingly emphasize the integration of complementary multimodal information.

3.1.1. Physiological Signals

Physiological signals capture autonomic and neurophysiological responses closely associated with emotional arousal and stress [32]. Representative measures include electroencephalography (EEG) [33], heart rate and heart rate variability [34], respiration rate, electrodermal activity [35], and galvanic skin response [36]. These signals offer objectivity and high temporal resolution, but typically require careful preprocessing to mitigate noise and motion artifacts.

3.1.2. Behavioral and Kinematic Signals

Behavioral and kinematic signals capture externally observable expressions of affect, such as body movement, posture, gestures, and interaction patterns [37]. In music therapy contexts, such signals can reflect engagement, relaxation, and social responsiveness.

3.1.3. Visual and Facial Cues

Visual and facial cues, including facial expressions, gaze patterns, and head movements, enable non-invasive estimation of emotional state and attentional focus [38].

3.1.4. Acoustic and Speech-Related Features

Acoustic and speech-related features, such as pitch, energy, speaking rate, and spectral characteristics, provide paralinguistic indicators for inferring affective valence and arousal levels [39]. In practical therapeutic environments, however, acoustic observations are often contaminated by background noise, reverberation, and concurrent sound sources. This necessitates the use of multi-source separation and signal reconstruction techniques to extract clean acoustic feedback [51,52]. By improving the signal-to-noise ratio of captured audio, such methods can enhance the reliability of downstream affective feature extraction and contribute to more robust multimodal inference.

3.1.5. Self-Report and Interaction-Based Inputs

Self-report and interaction-based inputs, including mood ratings, preference selections, and therapist annotations, offer contextual and reference information for affective modeling, albeit with lower temporal resolution [40].
While multimodal integration can compensate for the limitations of single-modality approaches and yield more robust user state estimation, practical system deployment remains constrained by increased computational complexity, latency, sensor synchronization requirements, and processing costs. Consequently, many existing systems still rely on a single modality or a limited subset of modalities.

3.2. Affective Representation and Modeling Layer

The affective representation and modeling layer translates heterogeneous sensory inputs into structured representations of the user’s emotional state. Conceptually, this layer functions as the semantic bridge between raw observations and adaptive music generation, transforming multimodal physiological, behavioral, and contextual signals into interpretable affective descriptors that can guide therapeutic intervention.
At a high level, existing approaches to affect modeling can be grouped into three complementary paradigms. First, dimensional models represent emotion within continuous low-dimensional spaces, most commonly arousal–valence (AV) or pleasure–arousal–dominance (PAD) frameworks [42,53]. These representations are particularly well-suited for music-based applications because musical attributes such as tempo, intensity, and harmonic tension naturally align with continuous affective dimensions. Second, categorical models map inputs to discrete emotional states (e.g., happiness, sadness, anxiety), offering intuitive interpretability for clinical settings and user interaction [43]. Third, representation-learning approaches embed multimodal signals into shared latent spaces through cross-modal alignment or joint embedding techniques [41]. These learned representations often capture subtle affective nuances that predefined taxonomies may fail to explicitly encode.
Beyond representational format, temporal modeling constitutes a defining characteristic of this layer. Emotional states evolve dynamically rather than instantaneously; accordingly, many systems incorporate smoothing, state-tracking, or sequential modeling mechanisms to ensure temporal coherence and robustness under noisy sensing conditions [44,45]. Such mechanisms help prevent abrupt or unstable transitions in downstream music generation, thereby preserving therapeutic continuity.
Moreover, depending on the disorder and the patient’s physical condition, this layer may incorporate cohort-specific psychoacoustic constraints to enhance therapeutic effectiveness. For example, conditions such as chronic tinnitus necessitate frequency-aware regulation, informed by objective psychoacoustic principles such as critical bands and auditory masking, to avoid symptom exacerbation [54]. More broadly, the cognitive nature of auditory perception underscores the importance of integrating measurable perceptual factors-such as loudness, spectral balance, and individualized hearing profiles-into affect modeling. Embedding such psychoacoustic parameters as intermediate control targets allows clinically relevant constraints to be systematically conveyed to the music synthesis core, thereby supporting more precise, controllable, and effective therapeutic interventions.
From a systems perspective, the primary contribution of the affective modeling layer lies not merely in classification accuracy, but in its capacity to produce stable, interpretable, and controllable affect embeddings. These embeddings serve as intermediate control signals that link sensed user states with generative music parameters, enabling structured alignment between inferred emotion and musical expression. By abstracting high-dimensional observations into semantically meaningful representations, this layer establishes the foundation for adaptive, personalized, and closed-loop music-based interventions.

3.3. AI-Assisted Music Synthesis Core

Building upon the structured affective embeddings produced by the preceding layer, the AI-assisted music synthesis core translates inferred emotional states into adaptive musical expression. Whereas the affective modeling layer abstracts multimodal signals into semantically meaningful representations, this layer operationalizes those representations as generative control inputs for music creation. In doing so, it enables a closed-loop linkage between sensed user state and therapeutic sound output.
In contrast to earlier systems that relied primarily on music recommendation from predefined libraries, contemporary approaches increasingly frame music production as a controllable generative process. Affective embeddings, whether dimensional, categorical, or learned latent vectors, are mapped onto musically salient parameters such as tempo, rhythmic density, harmonic tension, melodic contour, timbral characteristics, and dynamic intensity. These control variables condition generative models, allowing emotional intent to be systematically aligned with musical structure.
Current implementations span multiple generative paradigms, including transformer-based symbolic music models, autoregressive audio generators, diffusion-based synthesis frameworks, and hybrid architectures that integrate symbolic planning with waveform-level rendering [24,46]. Across these approaches, the central design objective is not merely expressive diversity, but controllability: the capacity to produce musically coherent outputs that remain consistent with the inferred affective state over time.
Moreover, when the type of disorder and the therapeutic environment permit, the integration of spatial audio and sound field reproduction can further enhance the effectiveness of AI-assisted music synthesis. Compared to conventional mono sound, spatial audio provides a heightened sense of immersion and spatial presence, which can facilitate attentional engagement. Such increased engagement has been associated with reductions in perceived pain and boredom in clinical settings [55,56]. Despite these potential benefits, spatial audio and sound field reproduction remain relatively underexplored in both music therapy [57] and generative music AI [58], even though they are actively studied in broader audio engineering domains [59]. Incorporating spatial rendering as an additional control dimension-alongside tempo, harmony, and timbre-opens new possibilities for shaping therapeutic soundscapes that dynamically adapt not only in musical content but also in spatial perception.
From a therapeutic systems perspective, stability, interpretability, and safety are critical considerations. Generated music must avoid abrupt structural shifts or unintended affective cues that could disrupt therapeutic continuity. Consequently, many systems incorporate constraints on tempo ranges, harmonic progression patterns, stylistic boundaries, or structural repetition to maintain predictable and clinically appropriate behavior [1].
Viewed within the broader four-layer architecture, the music synthesis core functions as an adaptive translation mechanism that converts abstract affect embeddings into structured musical narratives. Its effectiveness depends on how reliably affective representations can be transformed into coherent, emotionally aligned musical trajectories that support personalized intervention goals.

3.4. Feedback and Adaptive Optimization Layer

Extending the generative translation performed by the music synthesis core, the feedback and adaptive optimization layer completes the closed-loop architecture by monitoring user responses and updating system behavior over time. Whereas the affective modeling layer abstracts user state and the synthesis core operationalizes it into musical output, this layer evaluates the consequences of that output and adjusts subsequent generation accordingly. In this sense, it provides the temporal continuity necessary for sustained therapeutic interaction.
User responses, captured through the multimodal acquisition layer, serve as evidence for assessing the evolving impact of the generated music. Changes in physiological signals, behavioral indicators, or inferred affective states inform whether therapeutic objectives are being approached, maintained, or deviated from. These observations may be interpreted as implicit feedback signals that guide adaptive control.
Adaptation strategies span a continuum of complexity. At a basic level, systems may implement rule-based parameter adjustments that modulate tempo, intensity, or structural features in response to detected affective shifts. More advanced approaches employ learning-based optimization mechanisms, including reward modeling grounded in affective state transitions [47], reinforcement learning or online adaptation strategies [48,49], and other data-driven policy updates.
From a therapeutic systems perspective, however, adaptation extends beyond algorithmic optimization. Human-in-the-loop configurations, particularly therapist oversight, remain central to maintaining clinical validity, ethical responsibility, and contextual appropriateness [50]. Rather than fully automating intervention decisions, many practical deployments position adaptive algorithms as assistive components that augment professional judgment.
Within the overall four-layer framework, the feedback and optimization layer functions as the regulatory mechanism that stabilizes and personalizes the intervention trajectory. Its effectiveness depends on the reliable interpretation of user responses, the controllability of the generative process, and the balanced integration of automated adaptation with human expertise.

3.5. System Integration and Implementation

The practical implementation of an AI-based music therapy system requires careful design choices regarding which components, discussed in Section 3.1, should be incorporated into therapeutic workflows, as well as whether a single-modal or multimodal approach is more appropriate. In multimodal settings, differences in temporal resolution across modalities must be reconciled, typically through temporal smoothing and joint latent embedding techniques, to map heterogeneous signals into a unified affective representation space [60,61]. Common representation spaces include the AV model and the PAD framework, as noted in Section 3.2.
However, widely used large-scale generative models such as MusicGen [18] and Suno [62] are not inherently trained within these affective representation spaces. As a result, affective embeddings must be transformed into compatible input formats, such as structured text prompts or descriptive metadata. In practice, this is often achieved by decoding emotion-based embeddings into natural language descriptors that guide the generation process [38]. Additionally, personal information-including user-preferred genres, individual physiological baselines, and historical therapeutic responses-can be incorporated into the generation process through style descriptors or meta-tags appended to the prompt [63]. This enables the generated music to be not only emotionally aligned but also personalized to the user’s cultural and aesthetic context, thereby enhancing therapeutic engagement.
Nevertheless, the embedding-to-text transformation introduces a potential loss or distortion of affective information [64]. Addressing this issue requires tighter coupling between representation learning and generative control, motivating a transition toward unified architectures in which the latent space of affective modeling is directly aligned with the conditioning space of the generative model [65,66]. One possible approach is to adopt joint embedding frameworks, similar to those used in contrastive language–image pre-training (CLIP) [67] or contrastive language–audio pre-training (CLAP) [68], where physiological states and musical features are projected into a shared space to minimize representational discrepancy. Alternatively, the development of specialized generative models tailored for music therapy—capable of directly conditioning on affective embeddings without intermediate text conversion—could further mitigate information loss. However, such end-to-end approaches remain limited in practice due to the scarcity of labeled data and the inherent difficulty of defining stable training objectives for subjective therapeutic outcomes.
A critical engineering hurdle in this integrative pipeline is maintaining real-time responsiveness. While a system is technically considered as real-time operation if it generates audio faster than playback, effective music therapy requires that subsequent stimuli be generated within a few seconds to preserve the continuity of the feedback loop. System-imposed delays have been shown to negatively affect user perception and task performance [69,70]. In practice, end-to-end latency encompasses sensing, preprocessing, inference, and audio rendering, and must typically be constrained within a range of a few hundred milliseconds to a few seconds, depending on the interaction paradigm. To address this, recent efforts focus on reducing generation latency through efficient neural architectures and incremental or streaming generation strategies [71]. Furthermore, cloud-edge integration is increasingly adopted to minimize transmission delays, although it introduces additional challenges related to system reliability, bandwidth variability, and deployment cost [72,73]. These considerations highlight that achieving clinically viable real-time performance requires not only algorithmic efficiency but also careful system-level optimization across the entire pipeline.

4. Current Status and Future Research Directions for Generative-AI Based Music Therapy

4.1. Literature Search and Case Study Selection

Building on the four-layer architectural framework derived in Section 3, we further explore recent case studies in GMAI-based music therapy. The objective of this section is not to quantitatively compare performance or to assess clinical superiority across methods. Instead, the focus is on analyzing how the GMAI-based music therapy architectural framework is instantiated in existing systems, and on characterizing the associated design space, including sensing modalities, generative modeling strategies, and interaction mechanisms.
We select only case studies that explicitly employ GMAI as a core system component, to reflect a shift from treating generative models as auxiliary tools toward embedding them as central elements of therapeutic system design. The literature search was restricted to studies published between January 2019 and December 2025. This period corresponds to the emergence and active integration of contemporary generative AI paradigms-such as transformer-based sequence models, diffusion-based generative models, and neural music generation systems-into digital health and music-based interventions.
The primary Boolean query applied to titles, abstracts, and metadata was:
(“music”) AND (therapy OR intervention OR clinical) AND
(“AI” OR “AI-augmented” OR “AI-assisted” OR “generative model”)
Retrieved records were screened to retain studies where generative AI constituted a core methodological component rather than a peripheral tool. After screening, five case studies were identified that met the selection criteria. This subsection examines five representative case studies (S1–S5 [74,75,76,77,78]; see Table 2). As GMAI has only recently reached a level of maturity that enables its application across diverse domains, relatively few music therapy studies currently position generative AI as a core system component. Notably, the five selected case studies were all published between 2024 and 2025, reflecting this emerging trend.
In Table 2, selected representative case studies are analyzed and mapped onto the four-layer framework, illustrating how different sensing modalities, affective modeling, generative paradigms, and interaction strategies instantiate shared design principles. Consistent with prior system-oriented reviews, this survey emphasizes architectural diversity and conceptual abstraction, aiming to synthesize a coherent system-level perspective across diverse implementations.
These studies reflect a shift from treating generative models as auxiliary tools toward embedding them as core elements of therapeutic system design. The objective is not to compare clinical outcomes or benchmark performance, but to analyze how the proposed architectural abstraction is instantiated in practice, including sensing modalities, generative strategies, and interaction mechanisms.
Case S1 Ref. [74] utilizes environmental video captured around the patient as the primary input modality. A vision–language model extracts semantic descriptors from the video stream, which are curated by the patient or therapist and provided as textual prompts to a commercial GMAI system (Suno API [62]). This approach exemplifies prompt-mediated control, where environmental context influences music generation through user-guided textual conditioning rather than explicit affective state modeling.
Case S2 Ref. [75] proposes a closed-loop framework in which EEG signals are encoded into latent representations using a pretrained encoder. These embeddings condition a music generation model to enable affect-informed synthesis. An adaptive control mechanism based on reinforcement learning permits selective user intervention, supporting dynamic adjustment of the generative process in response to inferred neural states.
Case S3 Ref. [76] similarly adopts an EEG-driven closed-loop paradigm, combining EEG-based emotion recognition with pretrained audio generative models. The system integrates an EEG emotion classifier, a HiFiGAN-based audio generator, and a variational autoencoder (VAE) derived from DCASE Challenge Task 7.1. While the study demonstrates the feasibility of coupling neural signals with high-fidelity audio synthesis, the feedback pathway is only partially specified, and explicit mechanisms for adaptive control remain limited.
Case S4 Ref. [77] introduces a hybrid generative architecture that combines a cross-modal transformer (CMT) with a VAE. The CMT models associations between textual prompts and music representations through attention mechanisms, while the VAE introduces stochastic latent variables to enhance generative diversity. Although user feedback is conceptually acknowledged as a potential adaptation mechanism, detailed learning procedures and quantitative evaluations of adaptive behavior are limited.
Case S5 Ref. [78] builds on a pretrained MusicGen [18] model and proposes a continuous prompt-engineering strategy. Initial music generation is driven by a base textual prompt, after which subsequent iterations incorporate partial audio outputs from previous steps together with additional textual inputs describing the patient’s emotional state, preferred instruments, and musical genres. Experimental results indicate improved alignment between generated music and target affective conditions, highlighting the potential of iterative, context-aware prompting for affect-aligned generation.
In summary, the representative studies summarized in Table 2 demonstrate increasing interest in integrating generative AI into music therapy systems, while also indicating that practical therapeutic deployment remains at an early stage. Most current approaches rely predominantly on text-based conditioning to encode emotional or therapeutic intent, with comparatively limited integration of multimodal affective representations and fully realized adaptive closed-loop control. These observations motivate the open challenges and the future research opportunities discussed in Section 4.2 and Section 4.3.

4.2. Open Challenges in AI-Based Music Therapy Systems

Existing review articles and prior studies have identified several open challenges and future directions for AI applications in music therapy. Collectively, this body of work suggests that the field is transitioning from static music recommendations toward adaptive, closed-loop systems that incorporate biofeedback, multimodal sensing, and interactive control. The representative systems reviewed in Section 4.1 (S1–S5) reflect this transition at varying levels of architectural maturity.

4.2.1. Advanced Personalization via Biofeedback Loops

A central challenge is enabling fine-grained personalization through real-time biofeedback. Future AI-based music therapy systems are increasingly envisioned as prescription digital therapeutics (DTx) rather than static media delivery tools, in which music is dynamically adapted in response to physiological and affective signals. Prior work has proposed affect-aware music generation interfaces explicitly designed for biofeedback, such as AffectMachine-Classical [79], as representative examples of this paradigm.
Among the surveyed systems, S2 and S3 most clearly instantiate biofeedback-driven personalization by incorporating EEG signals into closed-loop music generation pipelines. In S2, EEG-derived latent embeddings condition the generative process within a reinforcement learning-based control framework, enabling adaptive modulation of music in response to inferred neural states. S3 similarly integrates EEG-based emotion recognition with pretrained audio generative models, although the feedback pathway remains implicit and lacks explicit adaptive optimization.
In contrast, S1, S4, and S5 primarily rely on static or semi-static textual prompts to encode affective intent. While such prompt-mediated personalization offers accessibility and ease of interaction, it limits the system’s ability to respond dynamically to evolving user states, underscoring a key challenge for next-generation AI-based music therapy systems.

4.2.2. Neurorehabilitation and Motor Function Recovery

Beyond affect regulation, AI-driven music therapy is increasingly explored in neurorehabilitation contexts, including stroke and Parkinson’s disease [80]. In intelligent rhythmic auditory stimulation (RAS), AI systems dynamically adjust musical tempo and rhythmic structure to align with a patient’s gait, effectively acting as a responsive rhythmic partner during rehabilitation.
Although none of the representative systems (S1–S5) explicitly target motor rehabilitation, the closed-loop architectures demonstrated in S2 and S3 provide a technical foundation that could be extended to such applications. Their continuous biosignal acquisition and generative control mechanisms align with the requirements of adaptive RAS systems.
Relatedly, studies on neural plasticity suggest that AI-generated music combined with brainwave entrainment-for example, 40 Hz gamma stimulation-may support memory recall and neural integrity in patients with Alzheimer’s disease [10]. These applications further emphasize the importance of sample-level, audio-domain generative models, as employed in S3, where waveform-level synthesis enables precise temporal and spectral control relevant to neural entrainment.

4.2.3. Human-in-the-Loop and Co-Creative Paradigms

A recurring theme in the literature is that AI systems should augment rather than replace therapists [81]. Human-in-the-loop paradigms remain essential for maintaining clinical validity, ethical responsibility, and contextual appropriateness. Therapist-facing interfaces that provide interpretable indicators-such as synchronization between physiological responses and musical structure-can support informed intervention during therapy sessions.
Among the reviewed systems, S1 and S5 most explicitly incorporate human mediation. In S1, semantic descriptors extracted from environmental video are curated by the patient or therapist before being passed as prompts to a commercial GMAI system, positioning humans as critical intermediaries in the control loop. S5 similarly adopts a sequential prompt refinement strategy, where affective state and musical preferences are incrementally injected into the generation process.
While none of the surveyed systems fully realize real-time musical co-performance, S4’s cross-modal transformer architecture suggests a potential pathway toward interactive co-creation by aligning textual intent and musical structure through attention-based mechanisms.

4.2.4. Expansion of Therapeutic Domains and Clinical Validation

Finally, although anxiety and depression remain dominant application domains, AI-based music therapy is gradually expanding into broader clinical contexts. Across S1–S5, however, therapeutic objectives are typically framed in broad affective terms, with limited differentiation across clinical cohorts.
Large-scale randomized controlled trials (RCTs) specifically targeting AI-driven music therapy remain scarce. While standardized outcome measures and multimodal physiological evaluation frameworks are gradually maturing [10], the lack of explicit clinical endpoints in S1–S5 highlights a persistent gap between proof-of-concept system design and clinically grounded evaluation.

4.3. Generative AI-Specific Research Gaps and Opportunities

While many of the challenges discussed in Section 4.2 are shared with broader AI-driven music therapy and digital health systems, the adoption of modern GMAI introduces additional research gaps that are not adequately addressed in existing literature. This section highlights opportunities that arise specifically from the use of GMAI as a core generative component, many of which are directly reflected in the limitations observed across S1–S5.

4.3.1. Goal-Oriented and Therapy-Aware GMAI Models

A fundamental research direction is the development of GMAI models explicitly aligned with therapeutic objectives. From a technical standpoint, this requires training generative models on clinically annotated datasets, ensuring robustness across diverse populations, and supporting interoperability across heterogeneous sensing devices and care environments.
Across the reviewed systems, S1, S4, and S5 rely primarily on large-scale, general-purpose pretrained music generation models. While these models exhibit strong expressive capacity, their training corpora lack therapeutic annotation, cohort specificity, and clinical context. Consequently, therapeutic intent is injected post hoc via textual prompts rather than being embedded within the model’s generative priors.
In contrast, S2 and S3 take preliminary steps toward therapy-aware modeling by incorporating biosignal-derived representations into the generation pipeline. Nevertheless, even these systems stop short of training GMAI models on clinically grounded, cohort-specific datasets. Given that music therapy principles vary substantially across populations-for example, ISO-based emotional transitions in adult mental health [82,83], reminiscence therapy [84] in dementia care, and action-oriented musical forms in pediatric neurodevelopmental interventions [85,86]-developing cohort-adaptive GMAI models remains a largely unexplored opportunity.
Moreover, recent analyses of music intervention studies report substantial issues in reporting quality, including inconsistencies and ambiguities in methodological descriptions, which limit reproducibility and data reuse [87]. These limitations pose a critical challenge for GMAI-based music therapy, where high-quality, well-annotated datasets are essential for model training. In particular, existing clinical data sources such as electronic health records (EHRs) often lack fine-grained musical information, including detailed repertoire characteristics, session structure, and therapist intervention strategies. As a result, constructing datasets suitable for training therapy-aware GMAI models remains highly challenging.
Addressing this gap requires the establishment of standardized data collection guidelines tailored to music therapy contexts. Prior work on clinical music therapy practice highlights the importance of structured outcome documentation and EHR-integrated data collection processes [88,89,90]. Extending these principles to GMAI-oriented datasets would enable the systematic capture of both clinical outcomes and music-specific features. Furthermore, recent studies emphasize the importance of human-AI co-design and collaboration with music therapists in developing usable systems and interfaces [81,91]. Incorporating such collaborative approaches into dataset construction is essential to ensure that collected data accurately reflect therapeutic intent and real-world clinical practices.

4.3.2. User Interface, Interaction Design, and Translational Barriers

The effectiveness of GMAI-based music therapy systems depends not only on algorithmic performance but also on user interface (UI) and user experience (UX) design, particularly in clinical settings. This challenge is evident across the reviewed systems. S1 and S5 offer relatively accessible interaction paradigms based on text prompts and preference selection but rely heavily on user interpretation and manual control. Conversely, S2 and S3 incorporate sophisticated sensing and modeling components, yet provide limited discussion of therapist-facing interfaces or interpretability mechanisms.
Addressing this gap requires UI/UX mechanisms that mediate between architectural layers, enabling clinicians to interact through intuitive and clinically interpretable controls. However, current GMAI-based systems lack unified evaluation protocols that simultaneously capture generative performance and therapeutic relevance. While music generation studies primarily assess perceptual quality and diversity using objective or distribution-based metrics [92], music therapy research relies on standardized clinical outcome measures such as behavioral, cognitive, and affective assessments [93,94]. This methodological divergence highlights a critical research gap and underscores the need for integrated evaluation frameworks that align computational generative metrics with clinical therapeutic objectives for context-sensitive and patient-specific assessment.
Beyond interface design, the physical configuration of the therapy environment and the adoption of specialized equipment represent an additional, yet often overlooked, dimension of system effectiveness. Thoughtful music therapy room design, combined with the use of noise reduction technologies, can help minimize ambient distractions and enhance patient engagement [95,96]. For instance, active noise control or environmental noise suppression may improve attentional focus and cognitive stability, as excessive noise in clinical settings has been associated with impaired attention, stress, and reduced care quality [97,98]. Such considerations highlight the importance of integrating environmental and hardware-level design into the broader GMAI system framework.

4.3.3. Digital Twin-Driven Simulation for Generative Music AI Design

Beyond real-time closed-loop control, digital twin frameworks offer a complementary approach by enabling offline, patient-specific simulation of therapeutic processes [99,100]. Such frameworks allow systematic evaluation of generative strategies without direct exposure to patients.
While none of the representative systems explicitly implement digital twins, S2 and S5 implicitly point toward this direction. S2’s reinforcement learning-based adaptive control and S5’s sequential conditioning strategy both suggest the need for simulation-based evaluation of generative policies prior to deployment.
When integrated with GMAI, digital twins enable controlled simulation of affective and behavioral responses to synthesized music under diverse therapeutic assumptions. High-level patient state representations encoded within the digital twin can serve as conditioning variables for generative models, extending the conditioning mechanisms explored in S2 and S3 into a principled, simulation-driven design framework. By shifting optimization and validation into virtual environments, digital twin-based approaches offer a promising pathway toward safer, more interpretable, and clinically grounded deployment of GMAI-based music therapy systems [101,102].

5. Conclusions

This survey examined recent generative AI-based music therapy systems from a system-level perspective, organizing prior work within a four-layer architectural framework encompassing multimodal acquisition, affective representation, music synthesis, and feedback-driven adaptive optimization. By mapping representative studies onto this framework, we clarified how generative music AI is integrated into therapeutic settings and identified both recurring design patterns and persistent research gaps.
Our analysis indicates that existing systems predominantly emphasize isolated components—most notably music generation—while comprehensive end-to-end integration remains uncommon. In particular, cohort-specific therapeutic modeling, principled and interpretable affective representations, and sustained feedback-driven adaptation are insufficiently addressed. No single system currently spans all architectural layers in a clinically grounded and scalable manner. This suggests that present limitations stem less from generative model capacity and more from challenges in system integration, validation, and translational deployment.
Future research should therefore prioritize system-oriented and cohort-aware design, with greater emphasis on interpretable affective modeling, human-in-the-loop interaction, and precautionary digital twin-driven simulation for safe evaluation. Advancing generative AI from a standalone content generation tool to an adaptive therapeutic component is essential for achieving personalized, reliable, and clinically meaningful systems. Ultimately, progress in this area will require close collaboration among generative AI researchers, clinicians, and music therapists to ensure that technical advances translate into safe and effective therapeutic practice.

Funding

This research was supported by the Regional Innovation System & Education (RISE) program through the Gangwon RISE Center, funded by the Ministry of Education (MOE) and the Gangwon State (G.S.), Republic of Korea (2026-RISE-10-002).

Institutional Review Board Statement

Not applicable.

Informed Consent Statement

Not applicable.

Data Availability Statement

No new data were created or analyzed in this study.

Acknowledgments

We sincerely thank the anonymous reviewers for their insightful comments, which have significantly enhanced the technical depth and practical considerations related to the deployment of AI-based music therapy. During the preparation of this manuscript, generative AI was utilized for language translation and grammatical correction to improve the readability of the text. The authors have reviewed and edited the output and take full responsibility for the content of this publication.

Conflicts of Interest

The author declares no conflicts of interest.

References

  1. Agres, K.R.; Schaefer, R.S.; Volk, A.; Van Hooren, S.; Holzapfel, A.; Dalla Bella, S.; Müller, M.; De Witte, M.; Herremans, D.; Ramirez Melendez, R.; et al. Music, computing, and health: A roadmap for the current and future roles of music technology for health care and well-being. Music Sci. 2021, 4, 2059204321997709. [Google Scholar] [CrossRef] [Scilit]
  2. Zaatar, M.T.; Alhakim, K.; Enayeh, M.; Tamer, R. The transformative power of music: Insights into neuroplasticity, health, and disease. Brain Behav. Immun.-Health 2024, 35, 100716. [Google Scholar] [CrossRef] [Scilit]
  3. Williams, D.; Hodge, V.J.; Wu, C.Y. On the use of ai for generation of functional music to improve mental health. Front. Artif. Intell. 2020, 3, 497864. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  4. Hillecke, T.; Nickel, A.; Bolay, H.V. Scientific perspectives on music therapy. Ann. N. Y. Acad. Sci. 2005, 1060, 271–282. [Google Scholar] [CrossRef] [Scilit]
  5. Hong, Y.J.; Han, J.; Ryu, H. The effects of synthesizing music using AI for preoperative management of Patients’ anxiety. Appl. Sci. 2022, 12, 8089. [Google Scholar] [CrossRef] [Scilit]
  6. Rodwin, A.H.; Shimizu, R.; Travis, R., Jr.; James, K.J.; Banya, M.; Munson, M.R. A systematic review of music-based interventions to improve treatment engagement and mental health outcomes for adolescents and young adults. Child Adolesc. Soc. Work J. 2023, 40, 537–566. [Google Scholar] [CrossRef] [Scilit]
  7. Ridder, H.M.O.; Stige, B.; Qvale, L.G.; Gold, C. Individual music therapy for agitation in dementia: An exploratory randomized controlled trial. Aging Ment. Health 2013, 17, 667–678. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  8. Zhou, Z.; Zhao, X.; Yang, Q.; Zhou, T.; Feng, Y.; Chen, Y.; Chen, Z.; Deng, C. A randomized controlled trial of the efficacy of music therapy on the social skills of children with autism spectrum disorder. Res. Dev. Disabil. 2025, 158, 104942. [Google Scholar] [CrossRef] [Scilit]
  9. Feng, Y.; Wang, M. Effect of music therapy on emotional resilience, well-being, and employability: A quantitative investigation of mediation and moderation. BMC Psychol. 2025, 13, 47. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  10. Jiao, D. Advancing personalized digital therapeutics: Integrating music therapy, brainwave entrainment methods, and AI-driven biofeedback. Front. Digit. Health 2025, 7, 1552396. [Google Scholar] [CrossRef] [Scilit]
  11. Mondanaro, J. Challenges to music therapy programming: A case study of innovation, burden, and resilience in United States hospitals. Music Med. 2019, 11, 115–126. [Google Scholar] [CrossRef] [Scilit]
  12. Baglione, A.N.; Clemens, M.P.; Maestre, J.F.; Min, A.; Dahl, L.; Shih, P.C. Understanding the technological practices and needs of music therapists. Proc. ACM Hum.-Comput. Interact. 2021, 5, 33. [Google Scholar] [CrossRef] [Scilit]
  13. Civit, M.; Civit-Masot, J.; Cuadrado, F.; Escalona, M.J. A systematic review of artificial intelligence-based music generation: Scope, applications, and future trends. Expert Syst. Appl. 2022, 209, 118190. [Google Scholar] [CrossRef] [Scilit]
  14. Dash, A.; Agres, K. AI-based affective music generation systems: A review of methods and challenges. ACM Comput. Surv. 2024, 56, 287. [Google Scholar] [CrossRef] [Scilit]
  15. Wei, L.; Yu, Y.; Qin, Y.; Zhang, S. From Tools to Creators: A Review on the Development and Application of Artificial Intelligence Music Generation. Information 2025, 16, 656. [Google Scholar] [CrossRef] [Scilit]
  16. Das, R.; Singh, T.D. Multimodal sentiment analysis: A survey of methods, trends, and challenges. ACM Comput. Surv. 2023, 55, 270. [Google Scholar] [CrossRef] [Scilit]
  17. Clements-Cortés, A.; Pranjić, M.; Knott, D.; Mercadal-Brotons, M.; Fuller, A.; Kelly, L.; Selvarajah, I.; Vaudreuil, R. International music therapists’ perceptions and experiences in telehealth music therapy provision. Int. J. Environ. Res. Public Health 2023, 20, 5580. [Google Scholar] [CrossRef] [Scilit]
  18. Copet, J.; Kreuk, F.; Gat, I.; Remez, T.; Kant, D.; Synnaeve, G.; Adi, Y.; Défossez, A. Simple and controllable music generation. Adv. Neural Inf. Process. Syst. 2023, 36, 47704–47720. [Google Scholar]
  19. Poddar, S.; Wan, Y.; Ivison, H.; Gupta, A.; Jaques, N. Personalizing reinforcement learning from human feedback with variational preference learning. Adv. Neural Inf. Process. Syst. 2024, 37, 52516–52544. [Google Scholar]
  20. Raglio, A. Applications of technology innovations in music therapy practice. Nord. J. Music Ther. 2025, 34, 31–41. [Google Scholar] [CrossRef] [Scilit]
  21. Herremans, D.; Chuan, C.H.; Chew, E. A functional taxonomy of music generation systems. ACM Comput. Surv. (CSUR) 2017, 50, 69. [Google Scholar] [CrossRef] [Scilit]
  22. Liu, C.H.; Ting, C.K. Computational intelligence in music composition: A survey. IEEE Trans. Emerg. Top. Comput. Intell. 2016, 1, 2–15. [Google Scholar] [CrossRef] [Scilit]
  23. Hernandez-Olivan, C.; Beltran, J.R. Music composition with deep learning: A review. In Advances in Speech and Music Technology: Computational Aspects and Applications; Springer: New York, NY, USA, 2022; pp. 25–50. [Google Scholar]
  24. Huang, C.Z.A.; Vaswani, A.; Uszkoreit, J.; Shazeer, N.; Simon, I.; Hawthorne, C.; Dai, A.M.; Hoffman, M.D.; Dinculescu, M.; Eck, D. Music transformer. In Proceedings of the International Conference on Learning Representations, New Orleans, LA, USA, 6–9 May 2019. [Google Scholar]
  25. Van Den Oord, A.; Dieleman, S.; Zen, H.; Simonyan, K.; Vinyals, O.; Graves, A.; Kalchbrenner, N.; Senior, A.; Kavukcuoglu, K. Wavenet: A generative model for raw audio. arXiv 2016, arXiv:1609.03499. [Google Scholar] [CrossRef] [Scilit]
  26. Donahue, C.; McAuley, J.; Puckette, M. Adversarial audio synthesis. arXiv 2018, arXiv:1802.04208. [Google Scholar]
  27. Dhariwal, P.; Jun, H.; Payne, C.; Kim, J.W.; Radford, A.; Sutskever, I. Jukebox: A generative model for music. arXiv 2020, arXiv:2005.00341. [Google Scholar] [CrossRef] [Scilit]
  28. Kong, Z.; Ping, W.; Huang, J.; Zhao, K.; Catanzaro, B. Diffwave: A versatile diffusion model for audio synthesis. arXiv 2020, arXiv:2009.09761. [Google Scholar]
  29. Saeed, A.; Grangier, D.; Zeghidour, N. Contrastive learning of general-purpose audio representations. In Proceedings of the ICASSP 2021—2021 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP); IEEE: New York, NY, USA, 2021; pp. 3875–3879. [Google Scholar]
  30. Niizumi, D.; Takeuchi, D.; Ohishi, Y.; Harada, N.; Kashino, K. BYOL for audio: Exploring pre-trained general-purpose audio representations. IEEE/ACM Trans. Audio Speech Lang. Process. 2022, 31, 137–151. [Google Scholar] [CrossRef] [Scilit]
  31. Zhang, Y.; Xia, G.; Levy, M.; Dixon, S. COSMIC: A conversational interface for human-AI music co-creation. In Proceedings of the International Conference on New Interfaces for Musical Expression, Shanghai, China, 15–18 June 2021. [Google Scholar]
  32. Lin, W.; Li, C. Review of studies on emotion recognition and judgment based on physiological signals. Appl. Sci. 2023, 13, 2573. [Google Scholar] [CrossRef] [Scilit]
  33. Mohammed, M.H.; Kadhim, M.N.; Al-Shammary, D.; Ibaida, A. EEG-Based Emotion Detection Using Roberts Similarity and PSO Feature Selection. IEEE Access 2025, 13, 79353–79366. [Google Scholar] [CrossRef] [Scilit]
  34. Wang, Z.; Zou, Y.; Liu, J.; Peng, W.; Li, M.; Zou, Z. Heart rate variability in mental disorders: An umbrella review of meta-analyses. Transl. Psychiatry 2025, 15, 104. [Google Scholar] [CrossRef] [Scilit]
  35. Kim, S.R.; Zhan, Y.; Davis, N.; Bellamkonda, S.; Gillan, L.; Hakola, E.; Hiltunen, J.; Javey, A. Electrodermal activity as a proxy for sweat rate monitoring during physical and mental activities. Nat. Electron. 2025, 8, 353–361. [Google Scholar] [CrossRef] [Scilit]
  36. Al-Nafjan, A.; Aldayel, M. Anxiety detection system based on galvanic skin response signals. Appl. Sci. 2024, 14, 10788. [Google Scholar] [CrossRef] [Scilit]
  37. Karg, M.; Samadani, A.A.; Gorbet, R.; Kühnlenz, K.; Hoey, J.; Kulić, D. Body movements for affective expression: A survey of automatic recognition and generation. IEEE Trans. Affect. Comput. 2013, 4, 341–359. [Google Scholar] [CrossRef] [Scilit]
  38. Wang, Y.; Song, W.; Tao, W.; Liotta, A.; Yang, D.; Li, X.; Gao, S.; Sun, Y.; Ge, W.; Zhang, W.; et al. A systematic review on affective computing: Emotion models, databases, and recent advances. Inf. Fusion 2022, 83, 19–52. [Google Scholar] [CrossRef] [Scilit]
  39. Wani, T.M.; Gunawan, T.S.; Qadri, S.A.A.; Kartiwi, M.; Ambikairajah, E. A comprehensive review of speech emotion recognition systems. IEEE Access 2021, 9, 47795–47814. [Google Scholar] [CrossRef] [Scilit]
  40. Bradley, M.M.; Lang, P.J. Measuring emotion: The self-assessment manikin and the semantic differential. J. Behav. Ther. Exp. Psychiatry 1994, 25, 49–59. [Google Scholar] [CrossRef] [Scilit]
  41. Geetha, A.; Mala, T.; Priyanka, D.; Uma, E. Multimodal emotion recognition with deep learning: Advancements, challenges, and future directions. Inf. Fusion 2024, 105, 102218. [Google Scholar]
  42. Eerola, T.; Vuoskoski, J.K. A comparison of the discrete and dimensional models of emotion in music. Psychol. Music 2011, 39, 18–49. [Google Scholar] [CrossRef] [Scilit]
  43. Poria, S.; Cambria, E.; Bajpai, R.; Hussain, A. A review of affective computing: From unimodal analysis to multimodal fusion. Inf. Fusion 2017, 37, 98–125. [Google Scholar] [CrossRef] [Scilit]
  44. Kim, J.; André, E. Emotion recognition based on physiological changes in music listening. IEEE Trans. Pattern Anal. Mach. Intell. 2008, 30, 2067–2083. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  45. Wöllmer, M.; Kaiser, M.; Eyben, F.; Schuller, B.; Rigoll, G. LSTM-modeling of continuous emotions in an audiovisual affect recognition framework. Image Vis. Comput. 2013, 31, 153–163. [Google Scholar] [CrossRef] [Scilit]
  46. Yu, B.; Lu, P.; Wang, R.; Hu, W.; Tan, X.; Ye, W.; Zhang, S.; Qin, T.; Liu, T.Y. Museformer: Transformer with fine-and coarse-grained attention for music generation. Adv. Neural Inf. Process. Syst. 2022, 35, 1376–1388. [Google Scholar]
  47. Livingstone, S.R.; Muhlberger, R.; Brown, A.R.; Thompson, W.F. Changing musical emotion: A computational rule system for modifying score and performance. Comput. Music J. 2010, 34, 41–64. [Google Scholar] [CrossRef] [Scilit]
  48. Katahira, K.; Matsuda, Y.T.; Fujimura, T.; Ueno, K.; Asamizuya, T.; Suzuki, C.; Cheng, K.; Okanoya, K.; Okada, M. Neural basis of decision making guided by emotional outcomes. J. Neurophysiol. 2015, 113, 3056–3068. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  49. Shakya, A.K.; Pillai, G.; Chakrabarty, S. Reinforcement learning algorithms: A brief survey. Expert Syst. Appl. 2023, 231, 120495. [Google Scholar] [CrossRef] [Scilit]
  50. Gil, M.; Pelechano, V.; Fons, J.; Albert, M. Designing the human in the loop of self-adaptive systems. In Proceedings of the International Conference on Ubiquitous Computing and Ambient Intelligence; Springer: New York, NY, USA, 2016; pp. 437–449. [Google Scholar]
  51. Vincent, E.; Virtanen, T.; Gannot, S. Audio Source Separation and Speech Enhancement; John Wiley & Sons: New York, NY, USA, 2018. [Google Scholar]
  52. Wang, D.; Chen, J. Supervised speech separation based on deep learning: An overview. IEEE/ACM Trans. Audio Speech Lang. Process. 2018, 26, 1702–1726. [Google Scholar] [CrossRef] [Scilit]
  53. Mehrabian, A. Pleasure-arousal-dominance: A general framework for describing and measuring individual differences in temperament. Curr. Psychol. 1996, 14, 261–292. [Google Scholar] [CrossRef] [Scilit]
  54. Ni, T.; Jiang, Y.; Lin, Z.; Ruan, J.; Wang, Y.; Liu, Y.; Han, Z. The results of short-course acoustic test could act as an effective predictor of the efficacy of customized music therapy for chronic tinnitus. Front. Neurosci. 2025, 19, 1544723. [Google Scholar] [CrossRef] [Scilit]
  55. Greenberg, D.M.; Bodner, E.; Shrira, A.; Fricke, K.R. Decreasing stress through a spatial audio and immersive 3D environment: A pilot study with implications for clinical and medical settings. Music Sci. 2021, 4, 2059204321993992. [Google Scholar] [CrossRef] [Scilit]
  56. Panteliodi, E.; Hudson, D. A sense of space in the core of the bore: Enhancing the MRI experience through use of spatial audio. Radiography 2024, 30, 1451–1454. [Google Scholar] [CrossRef] [Scilit]
  57. Bruschi, V.; Generosi, A.; Terenzi, A.; Mengoni, M.; Cecchi, S. A Preliminary Study on the Effect of Spatial Sound Reproduction based on Physiological Responses and Facial Expressions of the Listener. In Proceedings of the 2025 Immersive and 3D Audio: From Architecture to Automotive (I3DA); IEEE: New York, NY, USA, 2025; pp. 1–7. [Google Scholar]
  58. Chi, T.; Gao, L.; Zhang, Y. STASE: A spatialized text-to-audio synthesis engine for music generation. arXiv 2025, arXiv:2509.11124. [Google Scholar]
  59. Yang, J.; Barde, A.; Billinghurst, M. Audio augmented reality: A systematic review of technologies, applications, and future research directions. J. Audio Eng. Soc. 2022, 70, 788–809. [Google Scholar] [CrossRef] [Scilit]
  60. Hssayeni, M.D.; Ghoraani, B. Multi-modal physiological data fusion for affect estimation using deep learning. IEEE Access 2021, 9, 21642–21652. [Google Scholar] [CrossRef] [Scilit]
  61. Qu, W.; Wang, M.J.S. Structured and Factorized Multi-Modal Representation Learning for Physiological Affective State and Music Preference Inference. Symmetry 2026, 18, 488. [Google Scholar] [CrossRef] [Scilit]
  62. Suno, Inc. SUNO Music Generation API. 2024. Available online: https://suno.com (accessed on 18 January 2026).
  63. Le, D.V.T.; Bigo, L.; Herremans, D.; Keller, M. Natural language processing methods for symbolic music generation and information retrieval: A survey. ACM Comput. Surv. 2025, 57, 175. [Google Scholar] [CrossRef] [Scilit]
  64. Pandey, A.; Singh, J.; Kaur, M. Bridging Text and Speech for Emotion Understanding: An Explainable Multimodal Transformer Fusion Framework with Unified Audio–Text Attribution. J. Intell. 2025, 13, 159. [Google Scholar] [CrossRef] [Scilit]
  65. Naik, P.S.; Ranjan, H.; Uma, D. Cross-Modal Emotion-Aware Music Generation for Therapeutic Healing Using LoRA-Tuned Transformers. In Proceedings of the 2025 20th International Joint Symposium on Artificial Intelligence and Natural Language Processing (iSAI-NLP); IEEE: New York, NY, USA, 2025; pp. 1–6. [Google Scholar]
  66. Li, S.; Ji, S.; Wang, Z.; Wu, S.; Yu, J.; Zhang, K. A survey on music generation from single-modal, cross-modal, and multi-modal perspectives. ACM Comput. Surv. 2025, 58, 279. [Google Scholar] [CrossRef] [Scilit]
  67. Radford, A.; Kim, J.W.; Hallacy, C.; Ramesh, A.; Goh, G.; Agarwal, S.; Sastry, G.; Askell, A.; Mishkin, P.; Clark, J.; et al. Learning transferable visual models from natural language supervision. Proc. Int. Conf. Mach. Learn. 2021, 139, 8748–8763. [Google Scholar]
  68. Elizalde, B.; Deshmukh, S.; Al Ismail, M.; Wang, H. Clap learning audio concepts from natural language supervision. In Proceedings of the ICASSP 2023—2023 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP); IEEE: New York, NY, USA, 2023; pp. 1–5. [Google Scholar]
  69. Liu, X.; Zhang, Y.; Yan, Z.; Ge, Y. Defining ‘seamlessly connected’: User perceptions of operation latency in cross-device interaction. Int. J. Hum.-Comput. Stud. 2023, 177, 103068. [Google Scholar] [CrossRef] [Scilit]
  70. Fang-Yi Tan, F.; Nov, O. Counting the Wait: Effects of Temporal Feedback on Downstream Task Performance and Perceived Wait-Time Experience during System-Imposed Delays. arXiv 2026, arXiv:2602.04138. [Google Scholar]
  71. Lam, M.W.; Tian, Q.; Li, T.; Yin, Z.; Feng, S.; Tu, M.; Ji, Y.; Xia, R.; Ma, M.; Song, X.; et al. Efficient neural music generation. Adv. Neural Inf. Process. Syst. 2023, 36, 17450–17463. [Google Scholar]
  72. Caspe, F.; Shier, J.; Sandler, M.; Saitis, C.; McPherson, A. Designing neural synthesizers for low-latency interaction. arXiv 2025, arXiv:2503.11562. [Google Scholar] [CrossRef] [Scilit]
  73. Fan, X.; Zou, W.; Moghimi, M.; Yi, W. Integrating AI and cloud-edge technologies for music creation in educational and performance domains. J. Cloud Comput. 2026, 15, 32. [Google Scholar] [CrossRef] [Scilit]
  74. Wei, X.; Zhang, Z.; Yue, Z.; Chen, H.T. Context-AI Tunes: Context-Aware AI-Generated Music for Stress Reduction. In Proceedings of the International Conference on Human-Computer Interaction; Springer: New York, NY, USA, 2025; pp. 330–345. [Google Scholar]
  75. Shen, L.; Zhang, H.; Zhu, C.; Li, R.; Qian, K.; Meng, W.; Tian, F.; Hu, B.; Schuller, B.W.; Yamamoto, Y. A first look at generative artificial intelligence based music therapy for mental disorders. IEEE Trans. Consum. Electron. 2025, 71, 7439–7453. [Google Scholar] [CrossRef] [Scilit]
  76. Shen, L.; Zhang, H.; Zhu, C.; Li, R.; Qian, K.; Tian, F.; Hu, B.; Schuller, B.W.; Yamamoto, Y. Enhancing emotion regulation in mental disorder treatment: An aigc-based closed-loop music intervention system. IEEE Trans. Affect. Comput. 2025, 16, 2245–2260. [Google Scholar] [CrossRef] [Scilit]
  77. Venkatachalam, N. MusiciAI: A Hybrid Generative Model for Music Therapy using Cross-Modal Transformer and Variational Autoencoder. In Proceedings of the 2024 2nd International Conference on Intelligent Data Communication Technologies and Internet of Things (IDCIoT); IEEE: New York, NY, USA, 2024; pp. 1176–1180. [Google Scholar]
  78. Nikolakakis, E.; Ching, J.; Karystinaios, E.; Sipin, G.; Widmer, G.; Marinescu, R. Language Models for Music Medicine Generation. In Proceedings of the 2024 International Society for Music Information Retrieval Conference, San Francisco, CA, USA, 10–14 November 2024. [Google Scholar]
  79. Agres, K.R.; Dash, A.; Chua, P. AffectMachine-Classical: A novel system for generating affective classical music. Front. Psychol. 2023, 14, 1158172. [Google Scholar] [CrossRef] [Scilit]
  80. Braun Janzen, T.; Koshimori, Y.; Richard, N.M.; Thaut, M.H. Rhythm and music-based interventions in motor rehabilitation: Current evidence and future perspectives. Front. Hum. Neurosci. 2022, 15, 789467. [Google Scholar] [CrossRef] [Scilit]
  81. Sun, J.; Yang, J.; Zhou, G.; Jin, Y.; Gong, J. Understanding human-AI collaboration in music therapy through co-design with therapists. In Proceedings of the 2024 CHI Conference on Human Factors in Computing Systems, Honolulu, HI, USA, 11–16 May 2024; pp. 1–21. [Google Scholar]
  82. Qiu, Z.; Yuan, R.; Xue, W.; Jin, Y. Generated Therapeutic Music Based on the ISO Principle. In Summit on Music Intelligence; Springer: New York, NY, USA, 2023; pp. 32–45. [Google Scholar]
  83. Bao, J.; Lyu, Y.; Yang, J.; Jin, Y.; Gong, J. How Generative Music Affects the ISO Principle-Based Emotion-Focused Therapy: An EEG Study. In Proceedings of the Annual Meeting of the Cognitive Science Society, San Francisco, CA, USA, 30 July–2 August 2025; Volume 47. [Google Scholar]
  84. Jin, Y.; Cai, W.; Chen, L.; Zhang, Y.; Doherty, G.; Jiang, T. Exploring the design of generative AI in supporting music-based reminiscence for older adults. In Proceedings of the 2024 CHI Conference on Human Factors in Computing Systems, Honolulu, HI, USA, 11–16 May 2024; pp. 1–17. [Google Scholar]
  85. Low, B.; Liu, X.; Li, R.Z.; Ren, E.; Zhang, J.X. Music therapy for autism Spectrum disorder: A comprehensive literature review on therapeutic efficacy, limitations, and AI integration. In Proceedings of the 2024 IEEE 15th Annual Ubiquitous Computing, Electronics & Mobile Communication Conference (UEMCON); IEEE: New York, NY, USA, 2024; pp. 90–99. [Google Scholar]
  86. Yang, W.; Huang, C.F.; Huang, H.Y.; Zhang, Z.; Li, W.; Wang, C. Research on the improvement of children’s attention through binaural beats music therapy in the context of ai music generation. In Summit on Music Intelligence; Springer: New York, NY, USA, 2023; pp. 19–31. [Google Scholar]
  87. Robb, S.L.; Hanson-Abromeit, D.; May, L.; Hernandez-Ruiz, E.; Allison, M.; Beloat, A.; Daugherty, S.; Kurtz, R.; Ott, A.; Oyedele, O.O.; et al. Reporting quality of music intervention research in healthcare: A systematic review. Complement. Ther. Med. 2018, 38, 24–41. [Google Scholar] [CrossRef] [Scilit]
  88. Lacson, C.; Myers-Coffman, K.; Kesslick, A.; Krater, C.; Bradt, J. Conducting Clinical Studies in Community Health Settings: Challenges and Opportunities for Music Therapists. Music Ther. Perspect. 2021, 39, 105–112. [Google Scholar] [CrossRef] [Scilit]
  89. Rodgers-Melnick, S.N.; Block, S.; Rivard, R.L.; Dusek, J.A. Optimizing patient-reported outcome collection and documentation in medical music therapy: Process-improvement study. JMIR Hum. Factors 2023, 10, e46528. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  90. Rodgers-Melnick, S.N.; Rivard, R.L.; Block, S.; Dusek, J.A. Effectiveness of medical music therapy practice: Integrative research using the electronic health record: Rationale, design, and population characteristics. J. Integr. Complement. Med. 2024, 30, 57–65. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  91. Baltaxe-Admony, L.B.; Hope, T.; Watanabe, K.; Teodorescu, M.; Kurniawan, S.; Nishimura, T. Exploring the creation of useful interfaces for music therapists. In Proceedings of the Audio Mostly 2018 on Sound in Immersion and Emotion; ACM: New York, NY, USA, 2018; pp. 1–7. [Google Scholar]
  92. Kader, F.B.; Karmaker, S. A survey on evaluation metrics for music generation. arXiv 2025, arXiv:2509.00051. [Google Scholar]
  93. Spiro, N.; Tsiris, G.; Cripps, C. A systematic review of outcome measures in music therapy. Music Ther. Perspect. 2018, 36, 67–78. [Google Scholar] [CrossRef] [Scilit]
  94. Sabbatella, P.E. Assessment and clinical evaluation in music therapy: An overview from literature and clinical practice. Music Ther. Today 2004, 5, 1–32. [Google Scholar]
  95. Zhao, F.; Sun, Z.; Niu, W. Effect of ward noise reduction technology combined with music therapy on negative emotions in inpatients undergoing gastric cancer radiotherapy: A retrospective study. Noise Health 2023, 25, 257–263. [Google Scholar] [CrossRef] [Scilit]
  96. Zhang, X.; Zheng, B.; Lu, D.; Qi, W.; Lin, L.; He, S. Retrospective Analysis of the Influence of Music Therapy Combined with Noise Reduction Technology in Dental Implant Patients. Noise Health 2025, 27, 785–793. [Google Scholar] [CrossRef] [Scilit]
  97. Dallı, Ö.E.; Yıldırım, Y.; Aykar, F.Ş.; Kahveci, F. The effect of music on delirium, pain, sedation and anxiety in patients receiving mechanical ventilation in the intensive care unit. Intensive Crit. Care Nurs. 2023, 75, 103348. [Google Scholar] [CrossRef] [Scilit]
  98. Witek, S.; Schmoor, C.; Montigel, F.; Grotejohann, B.; Ziegler, S. Sustainable reduction in sound levels on intensive care units through noise management-an implementation study. BMC Health Serv. Res. 2025, 25, 9. [Google Scholar] [CrossRef] [Scilit]
  99. Elgammal, Z.; Albrijawi, M.T.; Alhajj, R. Digital twins in healthcare: A review of AI-powered practical applications across health domains. J. Big Data 2025, 12, 234. [Google Scholar] [CrossRef] [Scilit]
  100. Khoshfekr Rudsari, H.; Tseng, B.; Zhu, H.; Song, L.; Gu, C.; Roy, A.; Irajizad, E.; Butner, J.; Long, J.; Do, K.A. Digital twins in healthcare: A comprehensive review and future directions. Front. Digit. Health 2025, 7, 1633539. [Google Scholar] [CrossRef] [Scilit]
  101. Yan, R.; Shen, X.; Wachi, A.; Gros, S.; Zhao, A.; Hu, X. Offline Guarded Safe Reinforcement Learning for Medical Treatment Optimization Strategies. arXiv 2025, arXiv:2505.16242. [Google Scholar] [CrossRef] [Scilit]
  102. Lauer-Schmaltz, M.W.; Cash, P.; Hansen, J.P.; Das, N. Human digital twins in rehabilitation: A case study on exoskeleton and serious-game-based stroke rehabilitation using the ETHICA methodology. IEEE Access 2024, 12, 180968–180991. [Google Scholar] [CrossRef] [Scilit]
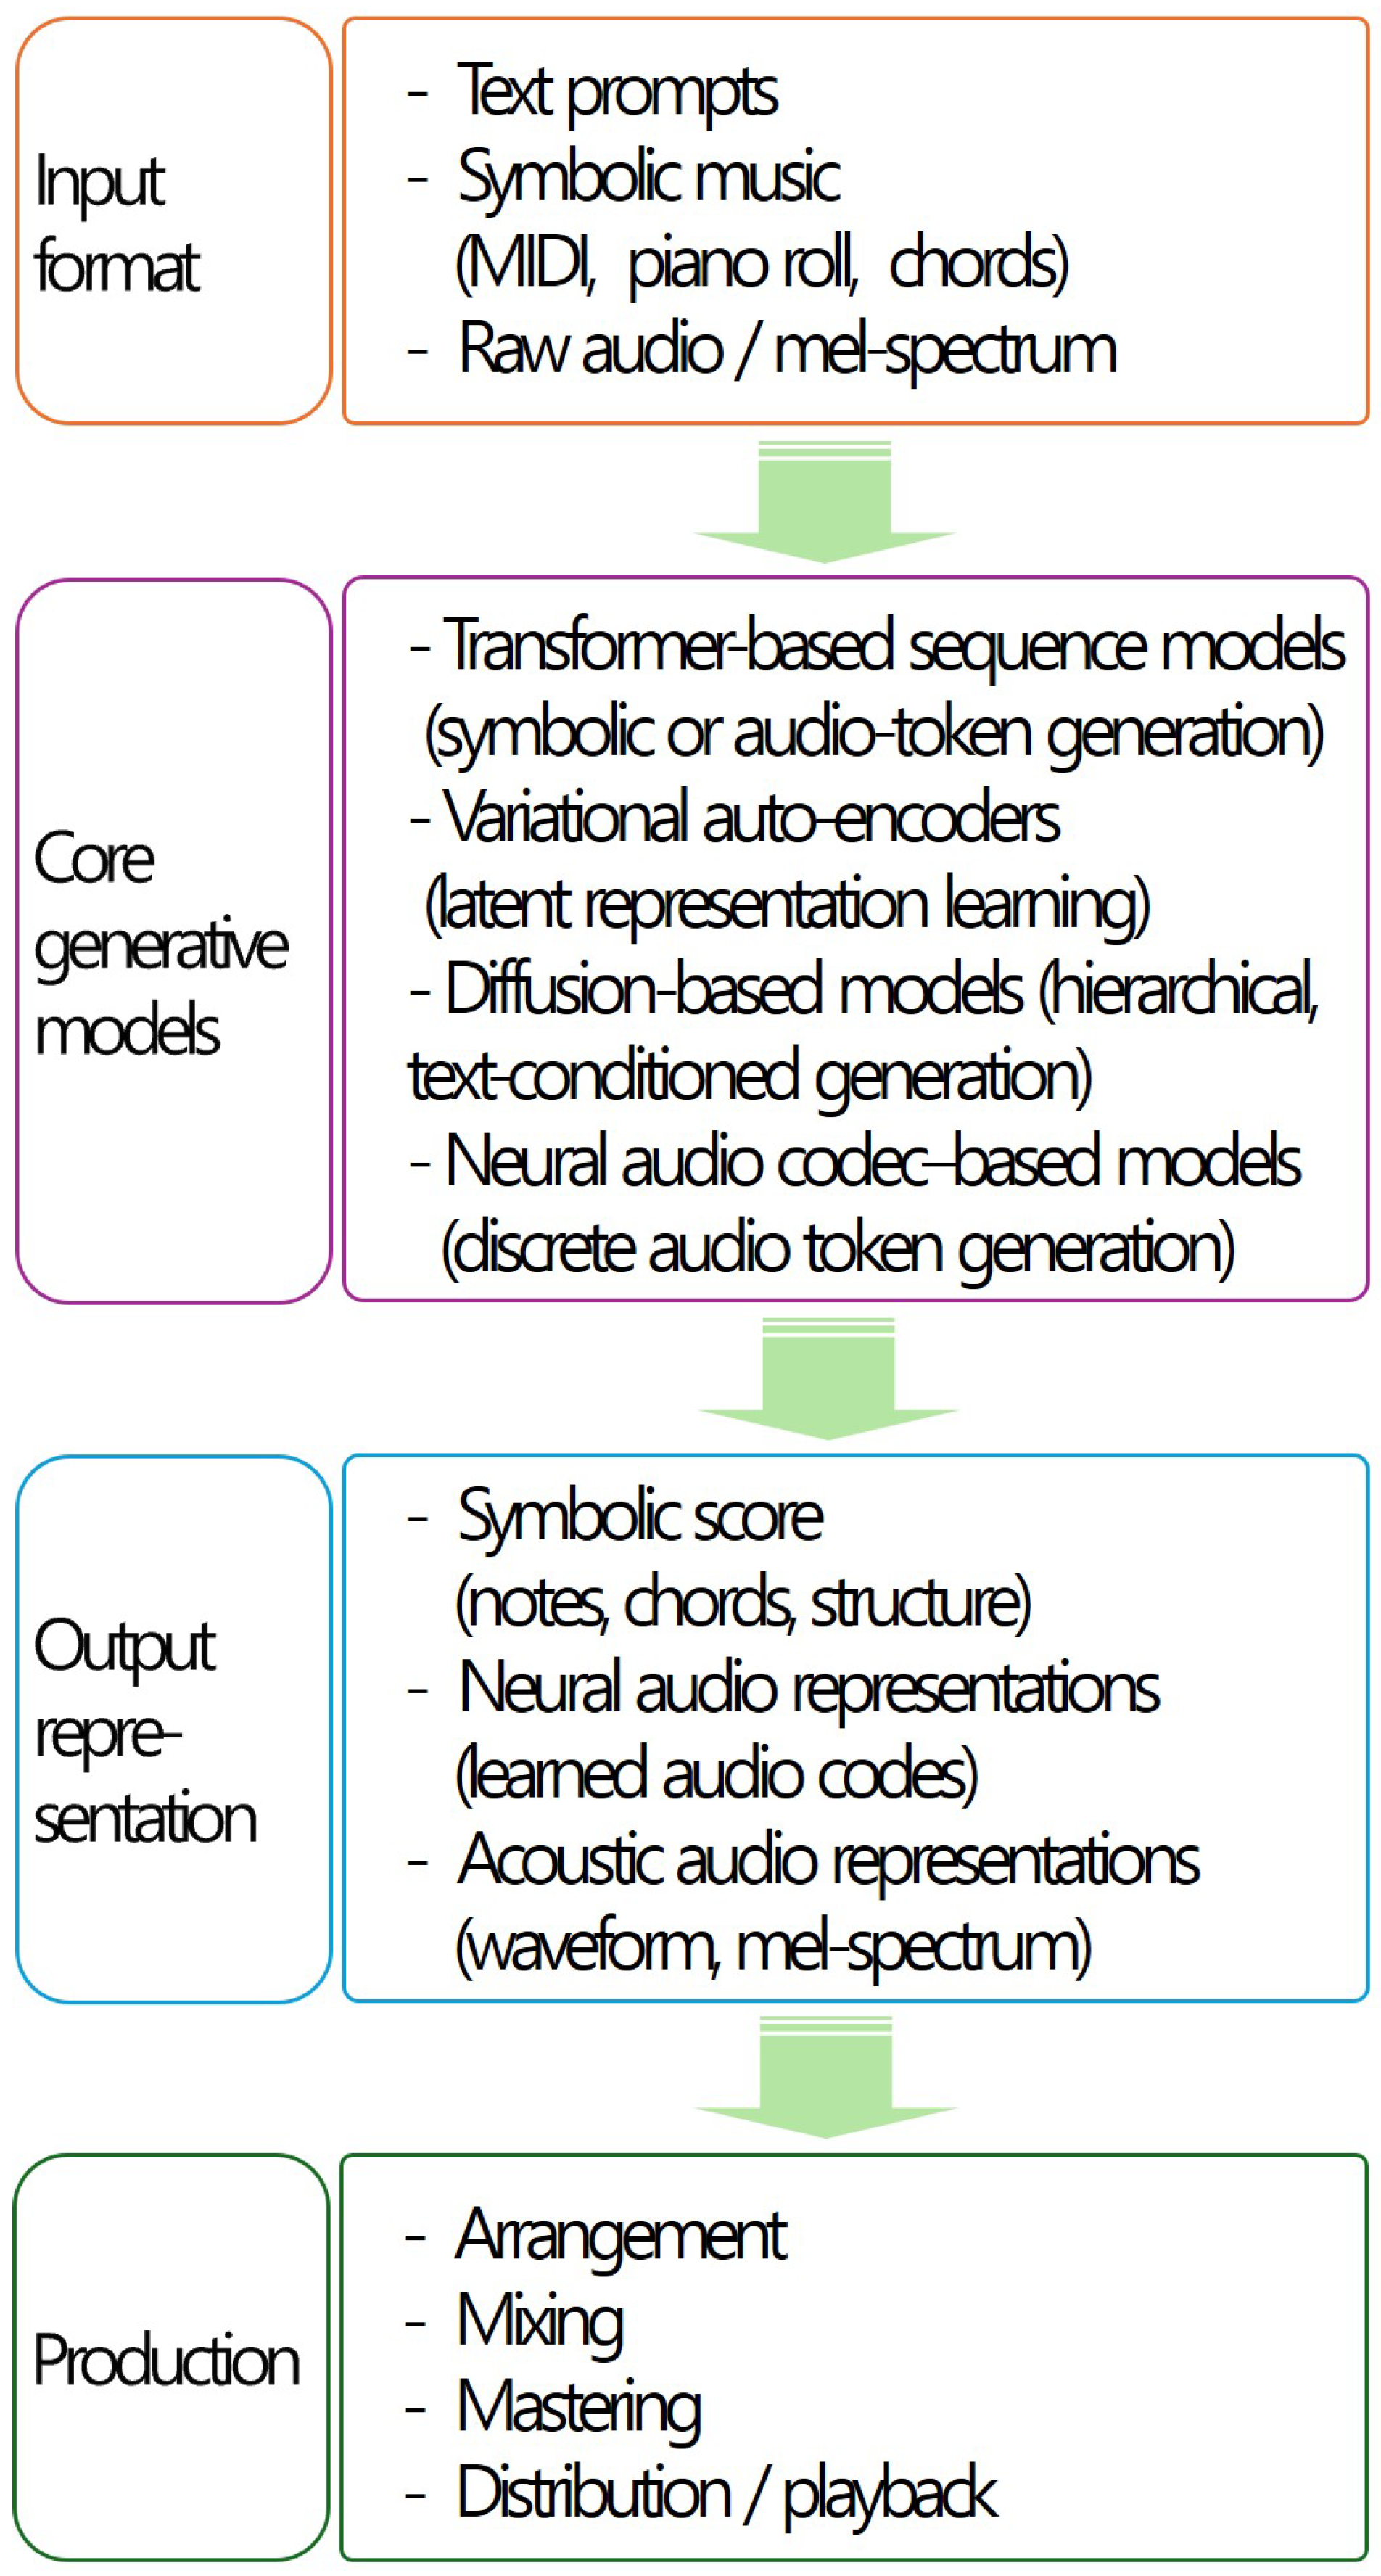
Figure 1. General architecture of an AI-based music generation. Overview of an end-to-end generative music AI pipeline, illustrating input modalities, core generative modeling, output representations, and integration with conventional music production processes.
Applsci 16 04120 g001
Figure 2. System architecture for adaptive affective music therapy. The framework integrates multimodal physiological sensing, ambient context, and patient feedback with a music synthesis core, which might be optimized through a closed-loop affective reward-based reinforcement learning process with optional clinical mediation.
Applsci 16 04120 g002
Table 1. System-level functional layers in AI-based music therapy systems.
Functional LayerPrimary RoleTypical Inputs/MethodsStudies
Multimodal acquisition layerCapture observable signals reflecting user emotional, physiological, and behavioral statesEEG, HR/HRV, EDA, respiration; motion and posture; facial expression and gaze; speech and acoustic features; self-report measures[32,33,34,35,36,37,38,39,40]
Affective representation and modeling layerFuse heterogeneous inputs into unified, machine-interpretable affective state representationsCross-modal feature alignment; joint latent embeddings; arousal–valence or PAD models; temporal smoothing and state estimation[41,42,43,44,45]
AI-assisted music synthesis coreGenerate or control music content conditioned on affective state and therapeutic intentSymbolic generation (transformer-based); audio-domain generation (diffusion models); affect-to-music parameter mapping; safety-constrained generation[13,14,18,23,24,27,31,46]
Feedback and adaptive optimization layerClose the loop between generated music and user response to enable dynamic adaptationRule-based control; reward modeling from affective change; reinforcement learning; online optimization; human-in-the-loop intervention[47,48,49,50]
Table 2. Representative case studies of generative AI-based music therapy systems.
CaseInput ModalityAffective ModelingGeneration & AdaptationArchitectural Emphasis
S1 [74]Environmental videoImplicit affect and contextual cues extracted via a visual-language model; mediated through user or therapist promptsCommercial text-to-music system (Suno API) with manual prompt refinement; no automated closed-loop adaptationPrompt-mediated contextual control without explicit physiological affect modeling
S2 [75]Real-time EEGLatent affect embeddings from a pretrained EEG encoder used as continuous conditioning variablesAffect-conditioned music generation integrated with reinforcement learning-based adaptive control and selective user interventionEEG-conditioned closed-loop generation emphasizing neural affect modeling and adaptation
S3 [76]EEGDiscrete or continuous affect labels inferred from EEG-based emotion recognitionPretrained audio generative models (HiFiGAN + VAE); no explicit adaptive feedbackFeasibility-driven EEG-audio integration without closed-loop optimization
S4 [77]Text prompts and symbolic or latent musicImplicit affective descriptors embedded via cross-modal attentionHybrid cross-modal transformer and VAE; feedback conceptually acknowledged but weakly specifiedCross-modal latent alignment prioritizing expressive diversity over adaptive therapy
S5 [78]Iterative text prompts with partial audioAffective intent encoded through iterative textual descriptors updated across generationsMusicGen guided by prompt engineering and generation history; adaptation across iterationsIterative affect-aware prompting with temporal refinement of affect alignment
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content.