1. Introduction
Phishing remains one of the most prevalent and financially damaging cyber threats, accounting for a substantial proportion of credential theft, data breaches, and online financial fraud [
1,
2]. Despite continuous advances in defensive technologies, phishing campaigns continue to grow in both volume and sophistication. According to the Anti-Phishing Working Group (APWG), more than one million phishing attacks were recorded during the first quarter of 2025 alone, highlighting the persistent scale of this threat [
3]. Because malicious URLs are inexpensive to generate, easy to modify, and often short-lived, traditional blacklist-based approaches struggle to keep pace with newly emerging attacks. Consequently, machine learning (ML) classifiers that distinguish phishing URLs from legitimate ones have become a central component of modern anti-phishing systems [
1,
2]. Detectors built on lexical URL features and host-based attributes routinely achieve accuracy and F1 scores exceeding 0.95 on widely used benchmark datasets [
4,
5].
Although these models report impressive performance on benchmark datasets, such results are typically obtained under standard evaluation settings in which the training and test data follow the same underlying distribution. In real-world deployment, however, attackers deliberately manipulate URLs to evade detection while preserving their malicious functionality. Adversarial machine learning research has repeatedly shown that models achieving near-perfect performance under standard evaluation can experience substantial performance degradation when exposed to carefully crafted perturbations [
5,
6,
7]. Similar weaknesses have subsequently been demonstrated for phishing URL detectors, raising increasing concerns about their robustness in operational environments [
8,
9,
10].
A key methodological distinction in adversarial robustness evaluation concerns the difference between the feature space and the problem space. Apruzzese et al. [
9] define the feature space as the domain in which an attacker directly manipulates feature values, whereas in the problem space the attacker must generate a real, functional URL whose feature representation changes only as a consequence of valid modifications. This distinction is particularly important because perturbations introduced in the feature space may not correspond to any feasible URL transformation, potentially leading to an overly optimistic estimate of an attacker’s capabilities. Consequently, a considerable proportion of the reported vulnerabilities in phishing URL detection has been demonstrated under feature-space assumptions rather than realistic problem-space constraints. Recent work has continued to investigate realistic adversarial attacks by generating functionally valid phishing webpages, further emphasizing the importance of evaluating detection systems under realizable attack scenarios rather than relying exclusively on feature-space perturbations [
11].
This paper makes two closely related contributions. First, we provide an empirical assessment of the discrepancy between feature-space and problem-space robustness. Using two benchmark datasets, we show that feature-space evaluations tend to overestimate model fragility, whereas realistic problem-space attacks are considerably less effective because much of the discriminative information resides in host-related attributes that are substantially more difficult to manipulate. Critically, and in direct response to the concern that cross-dataset comparisons are confounded, we additionally evaluate both attack types on the same real-URL dataset using an identical classifier and manipulable-feature budget, so that any observed difference is attributable to the attack space rather than to differences in dataset, feature extraction, or class composition. Second, motivated by this finding, we introduce a set of manipulation-resistant features, including domain word realness for detecting typosquatting and homoglyph attacks [
12,
13], brand impersonation cues [
14], subdomain depth, character entropy [
15], and transport- and host-level attributes. These features not only improve robustness against adversarial manipulation but also enhance performance under standard evaluation. We validate both contributions through a comprehensive empirical study comprising a model-by-defense comparison, hyperparameter sensitivity analysis, per-feature robustness evaluation, SHAP-based interpretation, a multi-seed statistical evaluation with confidence intervals, an adaptive-attacker analysis, a domain-disjoint split, and a host-only ablation study. Our contribution is not the individual features, several of which appear in prior typosquatting, homoglyph, and domain-impersonation research; rather, it is their assembly as a robustness-oriented, manipulation-resistant representation whose contribution to adversarial robustness we quantify. We note that the study by Apruzzese et al. [
9] and its journal extension, Multi-SpacePhish [
16], previously contrasted feature-space and problem-space evasion; our focus on robustness-oriented feature engineering is complementary to those works and was not addressed by them.
The remainder of this paper is organized as follows.
Section 2 reviews the related work.
Section 3 describes the datasets, threat model, and proposed manipulation-resistant features.
Section 4 presents the experimental results.
Section 5 discusses the implications of the findings,
Section 6 outlines the study limitations, and
Section 7 concludes the paper.
3. Data and Methodology
This study employs two complementary datasets to investigate adversarial robustness under both feature-space and problem-space evaluation settings. Unless otherwise stated, all experiments were conducted using a fixed random seed of 42 and an 80/20 stratified train–test split to ensure reproducibility and fair model comparison. To quantify variability, all headline results are additionally repeated over three independent stratified splits (seeds 42, 7, 123), and we report means with 95% confidence intervals in
Section 4.3. For reproducibility, the software environment is specified as Python 3.12.3, scikit-learn 1.8.0, SHAP 0.52.0, wordfreq 3.1.1, NumPy 2.4.4, pandas 3.0.2, and Matplotlib 3.10.8.
3.1. Dataset A: Feature-Space Benchmark
Dataset A is the publicly available phishing dataset introduced by Vrbančič et al. [
25]. It contains 88,647 instances, comprising 58,000 legitimate and 30,647 phishing samples, represented by 111 numerical features. Following the taxonomy adopted throughout this study, we distinguish between lexical URL features, which are derived directly from the URL string and are generally easier for an attacker to manipulate, and host-based features, which describe domain properties (e.g., domain age, DNS/TTL, certificate information, and ASN) and are substantially more resistant to manipulation. Twelve lexical features were designated as manipulable during adversarial evaluation, whereas the remaining 99 features were treated as robust.
3.2. Dataset B: Real URLs for Problem-Space Evaluation
Dataset B consists of real-world URLs, including confirmed phishing URLs obtained from PhishTank and benign URLs collected from a publicly available source [
26], with 14,000 samples per class. For each URL, both lexical and host-based features are extracted using our custom feature extraction framework. Unlike Dataset A, this dataset enables evaluation in the problem space by applying modifications directly to the original URL and subsequently re-extracting the feature representation. Importantly, because Dataset B contains the raw URL strings, it also supports a feature-space attack on the same samples; this is what enables the controlled, same-dataset comparison of the two attack spaces reported in
Section 4.6. Consequently, every adversarial example corresponds to a syntactically valid URL whose feature values arise naturally from the modified URL rather than being altered directly in the feature space.
3.3. Threat Model and Attacks
We consider an adversary who has full control over the phishing URL and aims to evade the detector while preserving the functionality of the phishing website, consistent with the problem-space threat model described by Apruzzese et al. [
9]. By “full control over the URL” we specifically mean control over the path and query components; changing host-level attributes such as domain age or DNS history would require re-registering or compromising a domain, a stronger and costlier capability that we treat separately in
Section 6. Two attack models are considered in this study. For Dataset A, we employ a feature-space attack in which each manipulable lexical feature of a phishing sample is progressively shifted toward the median value of the legitimate class. The attack strength is controlled by a parameter
, where larger values correspond to stronger perturbations. Because these perturbations are applied directly to feature values, the resulting feature vectors do not necessarily correspond to realizable URLs. For Dataset B, we perform problem-space attacks by modifying the original URL itself (e.g., shortening the path or removing unnecessary special characters) and subsequently re-extracting all lexical and host-based features from the modified URL. We formally define the manipulation level
as follows: at level
L, a fraction
L of the URL path segments (ordered from the tail) is removed and special characters (hyphens, underscores, percent-encodings) are stripped, so that
leaves the URL unchanged and
reduces it to the bare host. This provides an explicit, monotone parameter analogous in role to the feature-space strength
s; we do not claim the two are numerically equivalent, and the decisive comparison in
Section 4.6 instead holds the dataset, model, and manipulable features fixed. Consequently, every adversarial example corresponds to a syntactically valid URL whose feature representation is derived from the modified URL rather than manipulated directly in feature space, enabling a realistic comparison between feature-space and problem-space robustness. In all problem-space transformations the URL scheme and host are preserved, so the transformed URL resolves to the same host; we verify syntactic validity but do not claim to have verified the live page-level functionality of historical phishing URLs, most of which are already offline (see
Section 6). To assess whether the proposed features are unfairly favoured by an attacker that ignores them, we additionally define an adaptive attacker (
Section 4.8) permitted to perturb the manipulable components of the proposed feature set—lowering token entropy and subdomain depth and avoiding the homoglyph and brand-substring flags—in addition to the ordinary lexical features, while host-derived features remain fixed.
3.4. Proposed Features Designed to Improve Robustness
Building on findings from the typosquatting, homoglyph, and domain impersonation literature [
12,
13,
14], we design a set of features intended to improve robustness by capturing domain characteristics that are substantially more resistant to direct lexical manipulation than conventional URL-based features. Rather than relying solely on easily modifiable lexical descriptors, the proposed features incorporate semantic, structural, and host-related properties that are more difficult for an attacker to alter while maintaining a convincing phishing domain. The proposed features are summarized below.
Lexical word validity: Indicates whether the primary domain token corresponds to a valid dictionary word using corpus-based word-frequency statistics. Concretely, we use the wordfreq library (English corpus); a token of length
is valid if its word frequency exceeds zero. Legitimate domains are more likely to contain meaningful words, whereas phishing domains often consist of meaningless character sequences or deliberately modified words. Previous studies have shown that lexical and semantic characteristics of domain names provide useful information for phishing detection [
27].
Homoglyph disguise: Identifies whether a non-dictionary domain token becomes a valid word after homoglyph normalization (e.g., paypa1 → paypal), thereby capturing visually deceptive domain names [
13]. Normalization applies the map 0→o, 1→l, 3→e, 4→a, 5→s, 7→t,
$→s, @→a, followed by the digraph substitutions rn→m and vv→w, after which the token is re-checked against the dictionary.
Brand impersonation: Detects whether a protected brand name appears within a domain while the registered domain itself does not belong to the legitimate brand, capturing combosquatting behaviour [
14]. We use a fixed list of protected brand names with substring and normalized edit-distance checks.
Character entropy: Measures the Shannon entropy of the primary domain token. Previous studies have shown that phishing domains tend to exhibit higher entropy than legitimate domains [
15].
Subdomain depth: Counts the number of subdomain levels. Phishing URLs frequently conceal brand-related keywords within deeply nested subdomains.
Transport signal: Indicates whether HTTPS is present. Although HTTPS is no longer a reliable indicator of legitimacy on its own, it still provides useful contextual information when combined with other features.
Unlike conventional lexical features, the proposed features are primarily derived from domain- and host-level characteristics or require external information for their computation. Consequently, simple lexical modifications of a phishing URL have only limited influence on these features, making them suitable candidates for improving robustness against feature-space manipulation.
The objective of these features is not merely to improve classification performance on clean data, but to identify characteristics whose values cannot be substantially altered through simple lexical modifications of a phishing URL. This design principle distinguishes the proposed feature set from conventional lexical descriptors that can be manipulated directly in the feature space and forms the basis for the experimental evaluation presented in the following sections.
3.5. Models and Defenses
To evaluate the proposed features under both conventional and adversarial conditions, we consider four widely used machine learning classifiers representing different model families: Logistic Regression (LR), Decision Tree (DT), Random Forest (RF; 200 trees), and Histogram-based Gradient Boosting (HGB; 200 boosting iterations). These models provide a representative comparison across linear, tree-based, ensemble, and boosting approaches while avoiding dependence on a single learning algorithm.
For Dataset A, we evaluate two defense strategies against feature-space attacks. The first is adversarial training, in which the training set is augmented with adversarially manipulated phishing samples generated using the proposed attack procedure, following the principle introduced by Goodfellow et al. [
6]. The second is robust feature selection, where the 12 manipulable lexical features are excluded during training, forcing the models to rely exclusively on the remaining non-manipulated features.
Model performance is evaluated using the phishing detection rate (recall for the phishing class) on both clean and adversarially manipulated test data. Because the primary objective of phishing detection is to minimize missed phishing attacks, phishing recall is adopted as the primary evaluation metric throughout this study. To ensure that robustness gains are not obtained by inflating false positives, we additionally report precision, F1, and the false-positive rate on clean and attacked data; the baseline per-model metrics (accuracy, precision, recall, F1, ROC-AUC) are given in
Table 1.
4. Results
4.1. Baseline Performance (Dataset A)
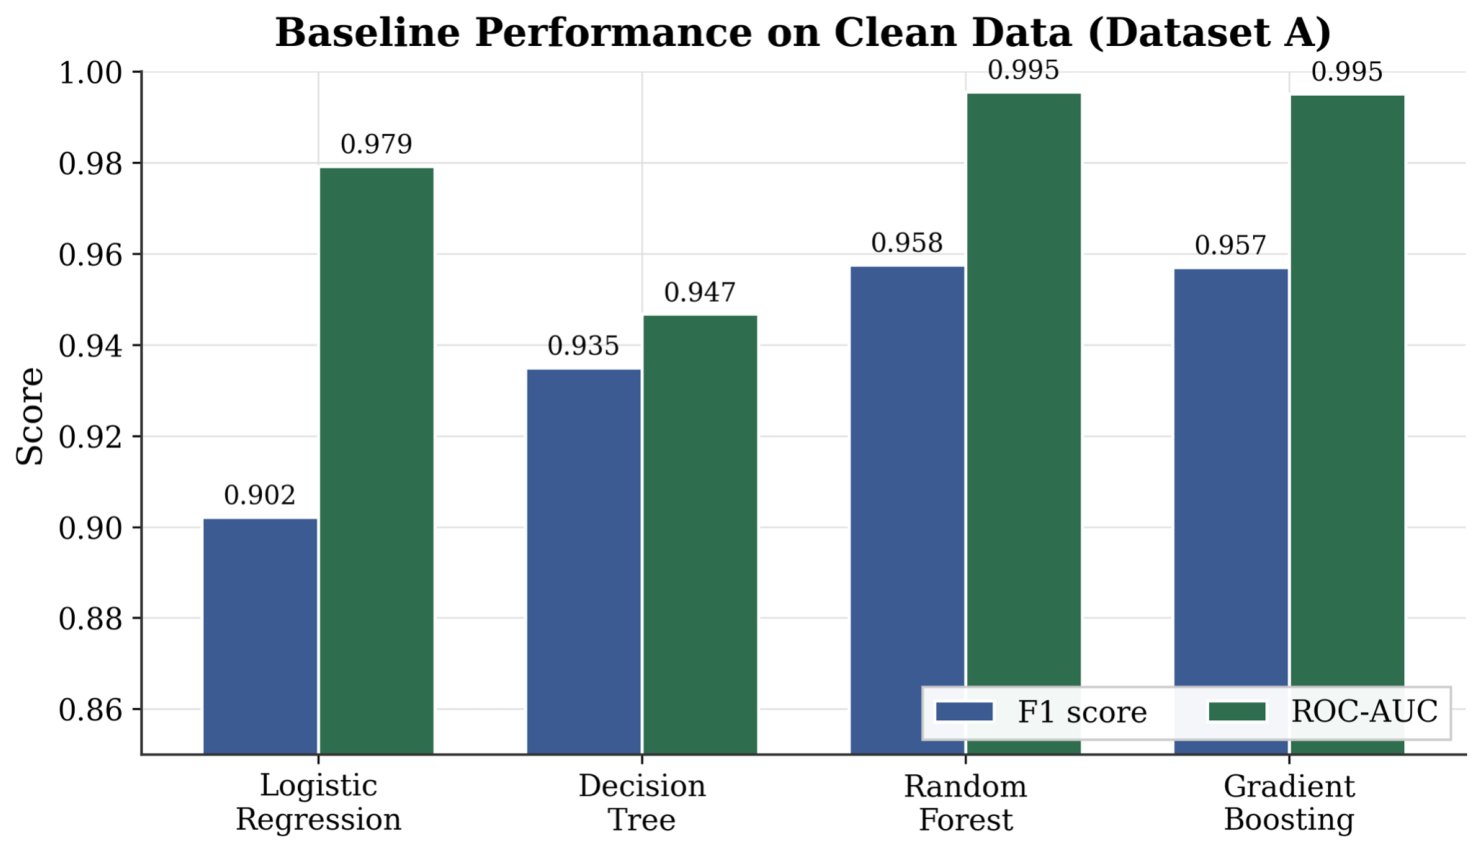
Table 1 summarizes the baseline performance of the four evaluated classifiers on the clean test set of Dataset A, while
Figure 1 and
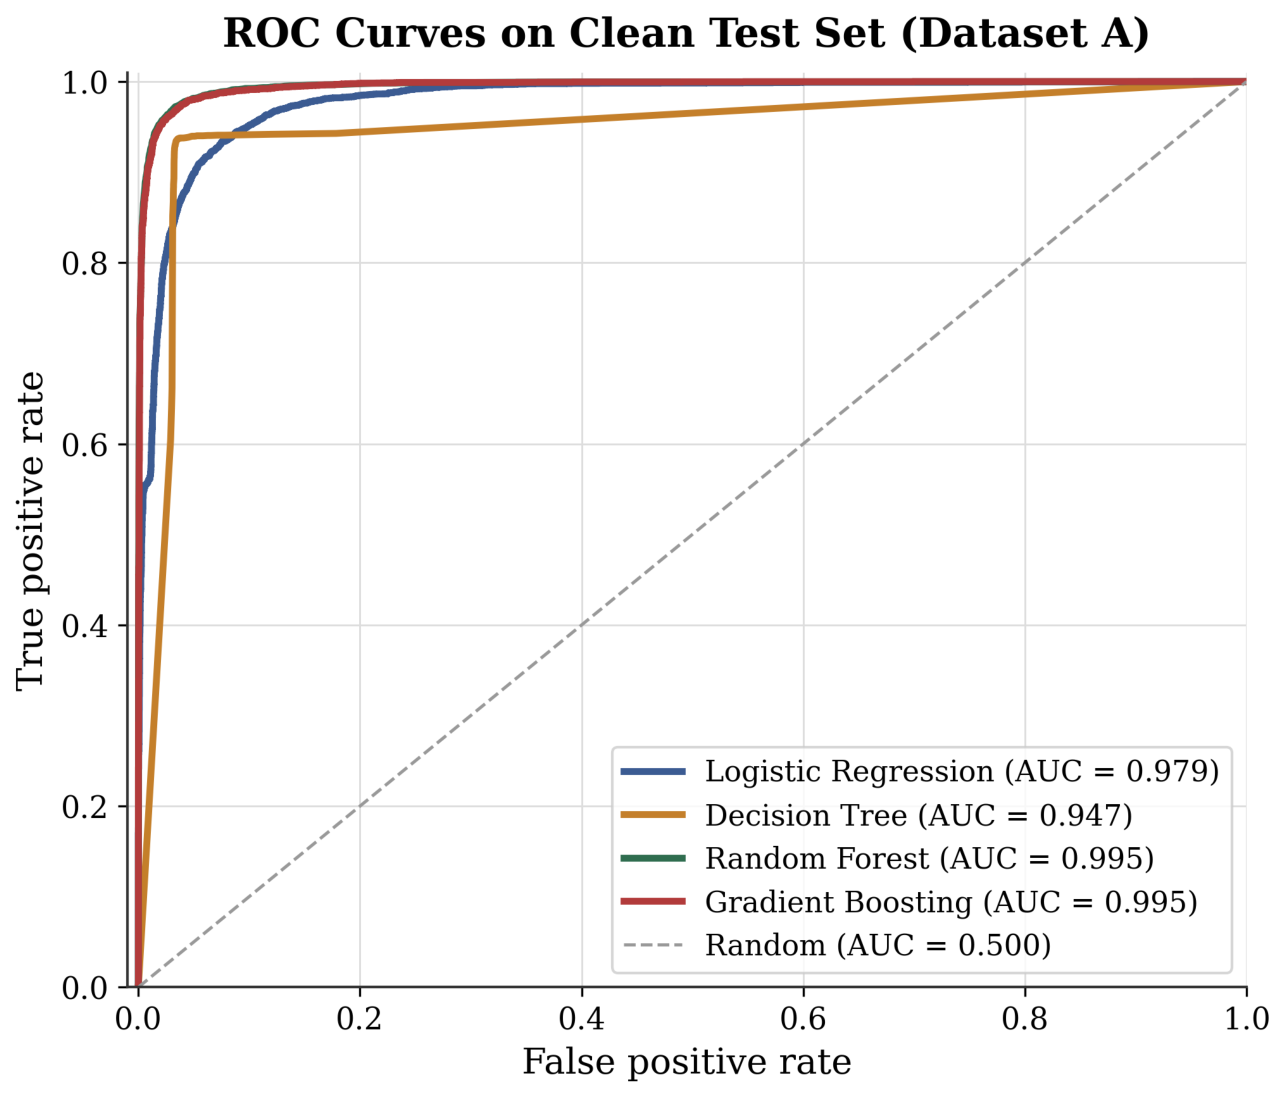
Figure 2 present the corresponding F1 scores and ROC curves. Although phishing recall is the primary evaluation metric adopted throughout this study, F1 score and ROC-AUC are also reported to provide a more comprehensive assessment of overall classification performance under clean conditions.
Overall, the ensemble-based models achieved the strongest baseline performance. Random Forest obtained the highest F1 score (0.958) and ROC-AUC (0.995), while Histogram-based Gradient Boosting achieved nearly identical performance with an F1 score of 0.957 and the same ROC-AUC. In comparison, Logistic Regression and Decision Tree produced lower F1 scores of 0.902 and 0.935, respectively, although all four models achieved ROC-AUC values above 0.94.
The ROC curves shown in
Figure 2 further confirm these observations. Random Forest and Histogram-based Gradient Boosting remain consistently closest to the upper-left corner of the ROC space, indicating superior discriminative capability under clean conditions. Logistic Regression also achieved a relatively high ROC-AUC (0.979) despite its lower F1 score, whereas Decision Tree exhibited the lowest ROC-AUC (0.947) among the evaluated models.
These baseline results provide a reliable reference for the subsequent adversarial evaluation. By establishing that all models perform well under clean conditions, the following experiments can more clearly attribute any performance degradation to feature-space and problem-space attacks rather than to differences in baseline classification capability.
4.2. Feature-Space Fragility and the Accuracy–Robustness Gap
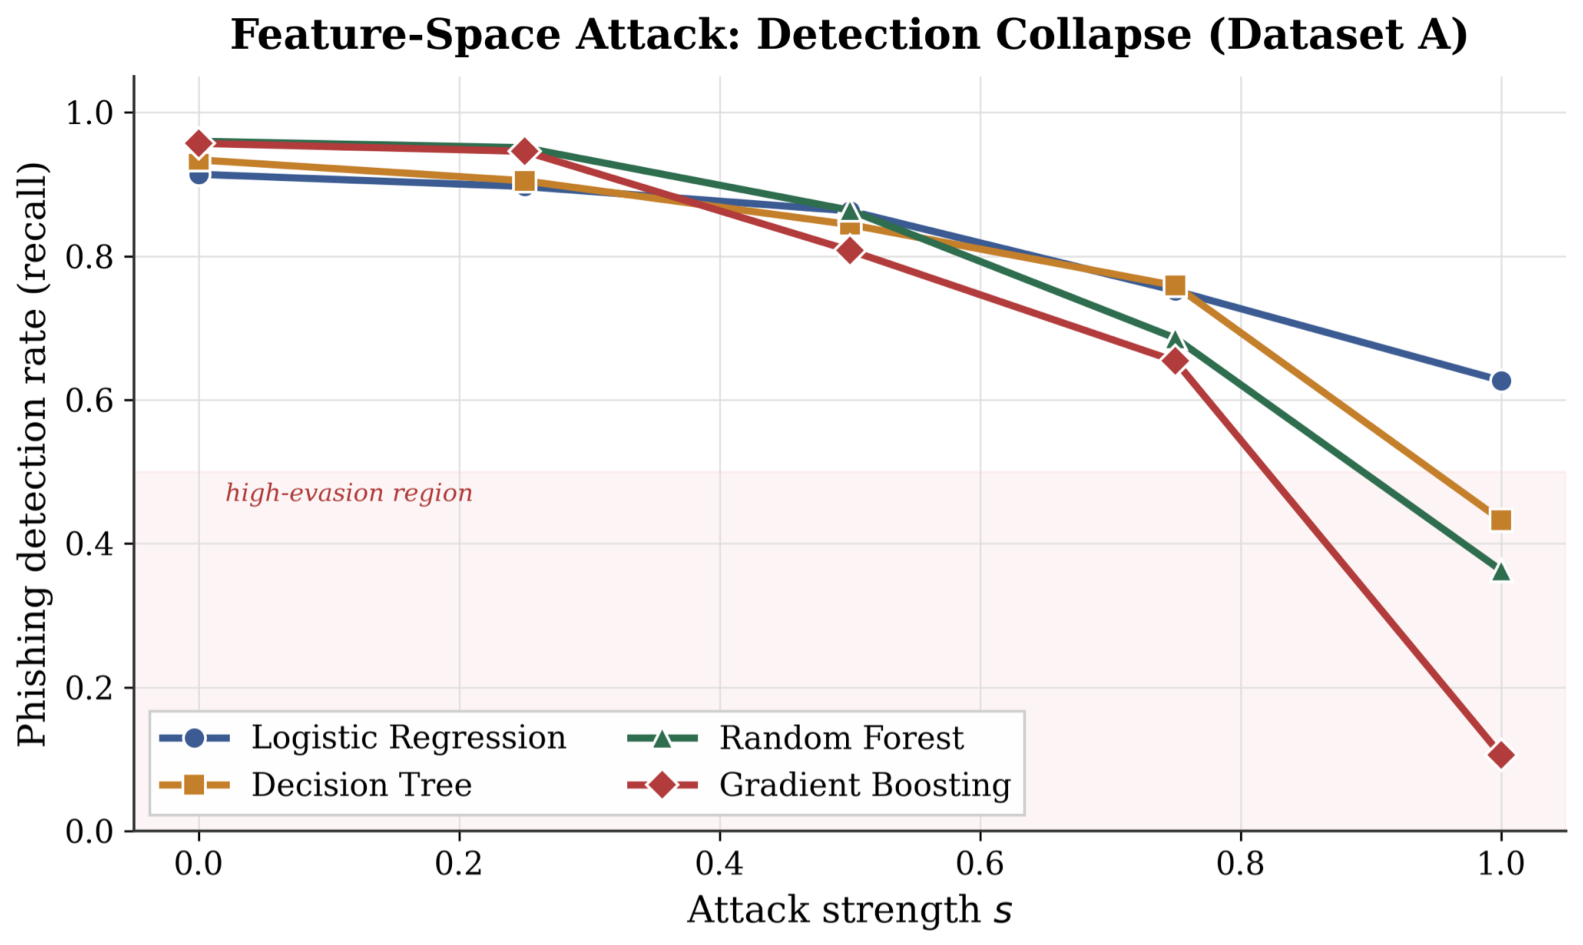
Table 2 and
Figure 3 summarize the phishing detection rate (recall) under progressively stronger feature-space attacks. As the attack strength increases, all classifiers experience a substantial decline in phishing detection performance, confirming that models achieving strong performance on clean data remain vulnerable to direct feature-space manipulation.
At the maximum attack strength (), the detection rate decreases markedly for every model. Random Forest declines from 0.960 to 0.363, while Histogram-based Gradient Boosting exhibits the largest performance degradation, falling from 0.957 to 0.106. In contrast, Logistic Regression, despite achieving the lowest baseline performance under clean conditions, retains the highest phishing detection rate (0.627) at the strongest attack level.
These results reveal a clear accuracy–robustness gap. Models that achieve the highest baseline performance are not necessarily the most resilient to feature-space attacks. In particular, the two ensemble-based models that performed best under clean conditions experience the largest degradation as attack strength increases, whereas Logistic Regression exhibits the greatest robustness throughout the evaluation.
Figure 3 further illustrates this trend. Detection performance remains relatively stable under weak perturbations (
) but declines rapidly as the manipulation strength increases, particularly for the ensemble-based models. This behaviour highlights the limitations of evaluating phishing detectors solely on clean datasets and motivates the subsequent investigation of defense strategies and problem-space attacks.
4.3. Defenses Across Models
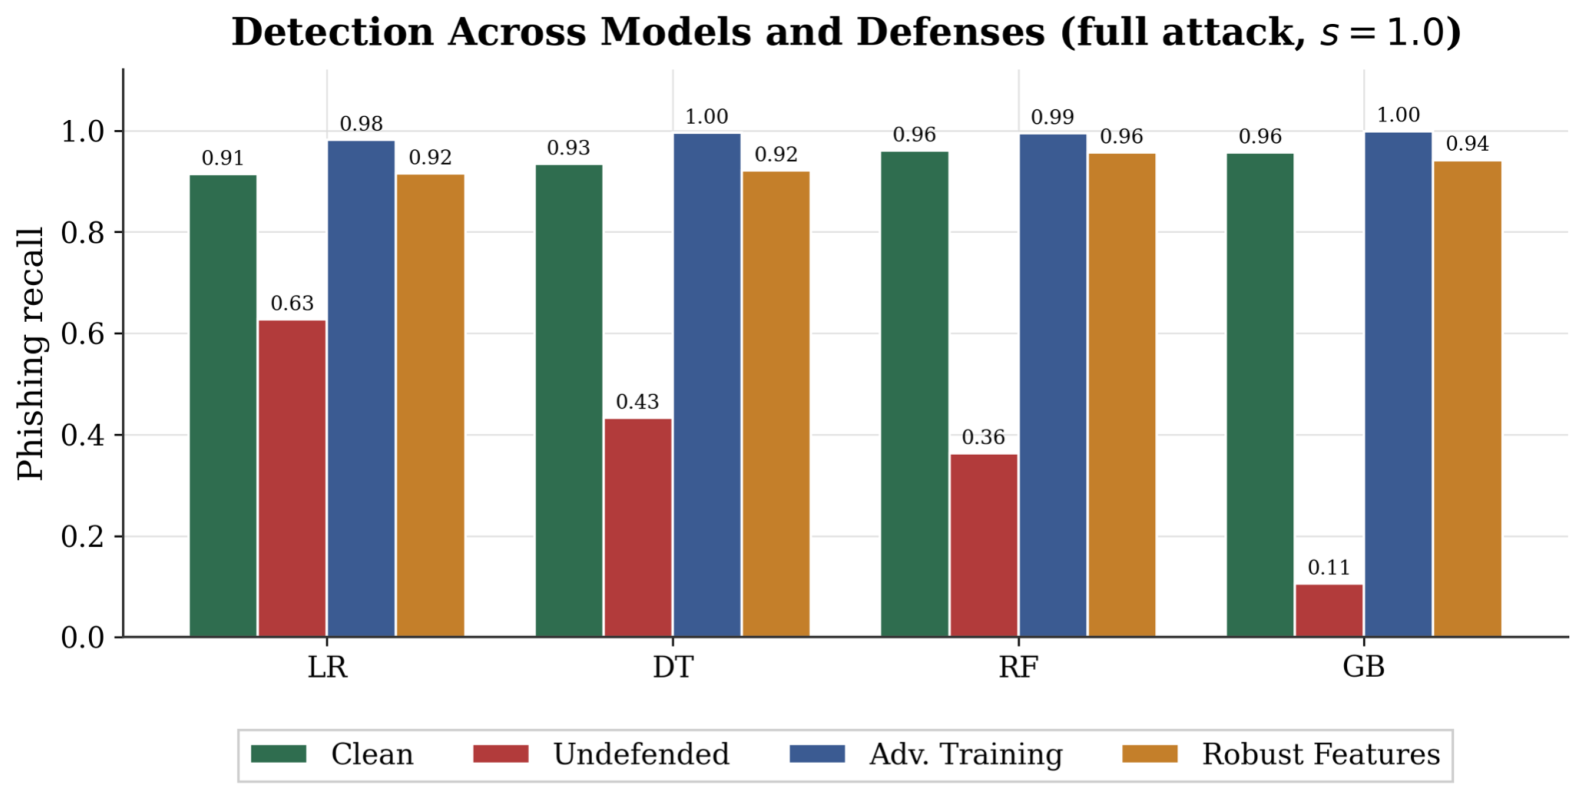
Table 3 and
Figure 4 compare phishing detection performance under the strongest feature-space attack (
) before and after applying the two defense strategies. Both adversarial training and robust feature selection substantially improve phishing detection across all evaluated classifiers, although their effectiveness differs.
Adversarial training consistently provides the largest performance gains. Across all four classifiers, phishing recall increases to approximately 0.99 under the strongest attack, effectively restoring the detection performance observed under clean conditions. Notably, this improvement is achieved without any measurable degradation in clean-data performance.
Robust feature selection also produces a substantial improvement compared with the undefended models. By excluding the 12 manipulable lexical features during training, all classifiers maintain phishing recall between 0.915 and 0.957 under the strongest attack. Although this defense does not fully recover the clean-data performance achieved through adversarial training, its performance remains remarkably stable across different model architectures, indicating that the proposed non-manipulated features retain considerable discriminative power even under adversarial manipulation. For Random Forest, phishing recall decreases by only 0.003 compared with the clean baseline (0.960 vs. 0.957), illustrating that excluding manipulable lexical features can preserve nearly all clean-data performance while substantially improving robustness.
Figure 4 further highlights the consistent behaviour of both defense strategies across all classifiers. These results demonstrate that reducing reliance on manipulable lexical features substantially improves resilience to feature-space attacks and provides an effective defense against adversarial feature manipulation.
To quantify variability, we repeated the key Dataset A experiments over three stratified splits (seeds 42, 7, 123) and computed 95% confidence intervals. The Random Forest baseline F1 is 0.959 (95% CI [0.958, 0.960]); its recall under the strongest feature-space attack is 0.400 (95% CI [0.351, 0.448]); Histogram-based Gradient Boosting under the same attack is 0.090 (95% CI [0.049, 0.132]); adversarial training restores recall to 0.995 (95% CI [0.995, 0.996]); and robust feature selection yields 0.957 (95% CI [0.955, 0.958]). The narrow intervals indicate that the findings are stable across resampling, and replace the earlier informal reference to repeated experiments.
4.4. Is the Fragility Structural? Hyperparameter and Per-Feature Analysis
To better understand the origin of the observed feature-space vulnerability, we further investigate whether the performance degradation is primarily influenced by model hyperparameters or by the manipulation of individual lexical features.
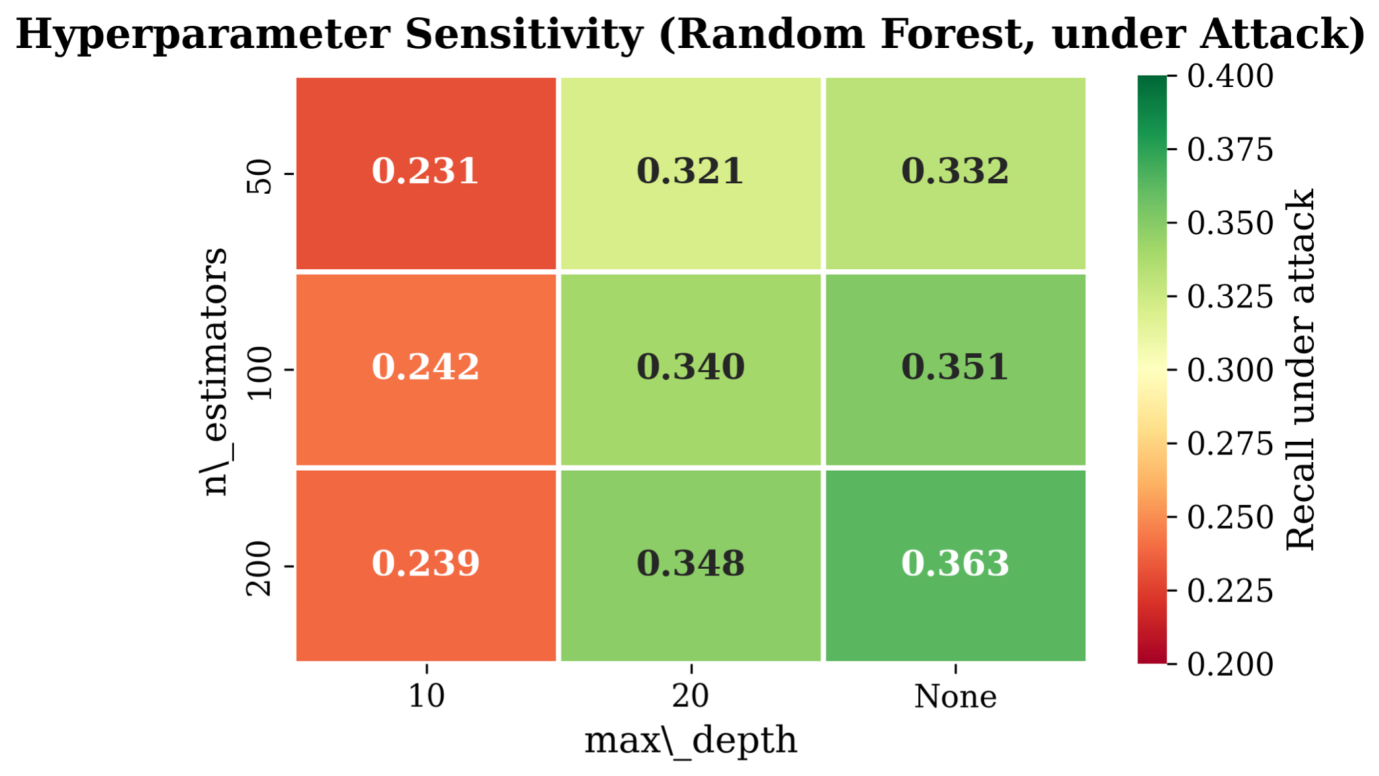
Figure 5 presents a hyperparameter sensitivity analysis for Random Forest, while
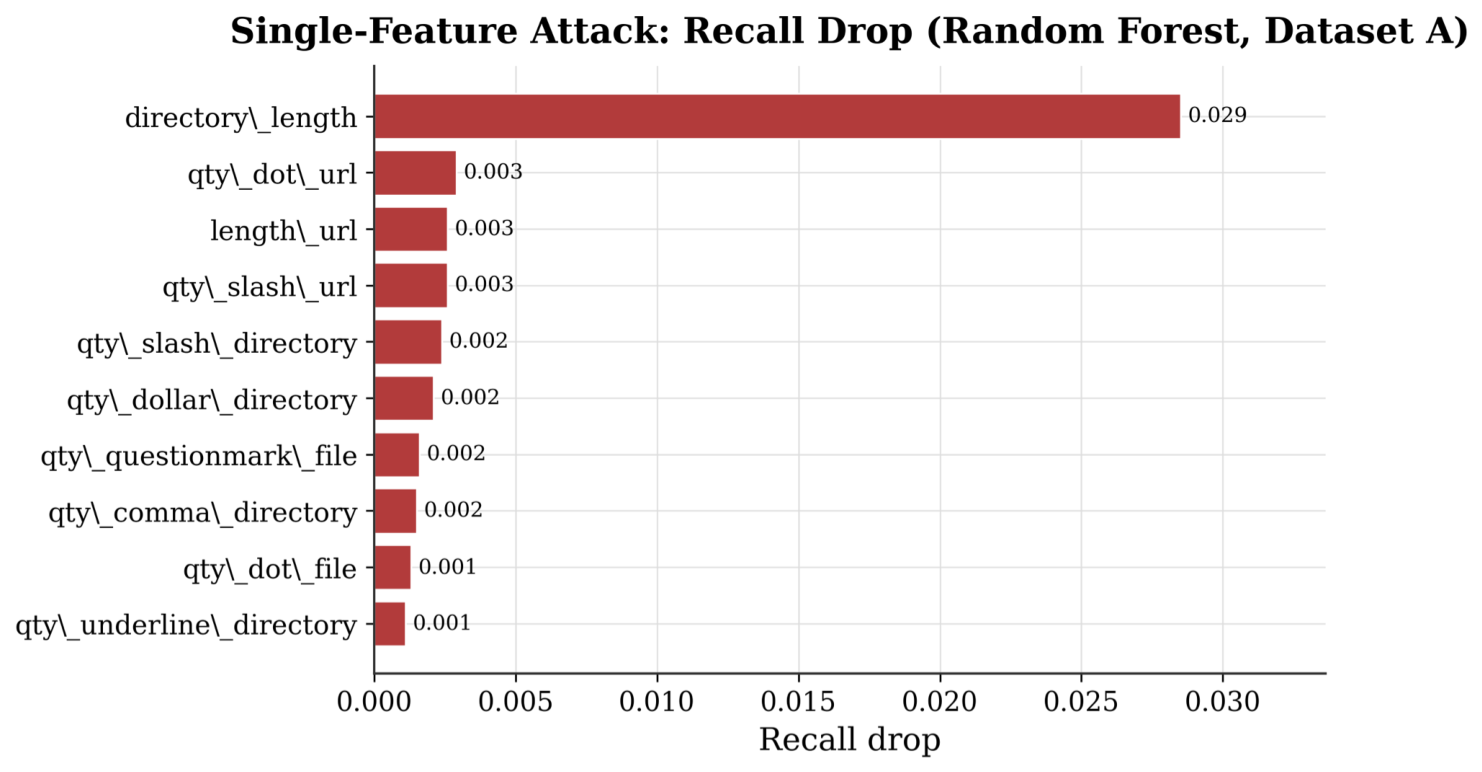
Figure 6 evaluates the impact of manipulating each lexical feature individually.
Figure 5 shows that varying the number of trees and the maximum tree depth produces only modest changes in phishing recall under feature-space attack. Across all evaluated configurations, recall remains consistently low, ranging from 0.231 to 0.363. These results indicate that the observed vulnerability is not specific to a particular Random Forest configuration but persists across a broad range of hyperparameter settings.
Figure 6 provides further insight into the source of this vulnerability. Manipulating any single lexical feature in isolation results in only a small reduction in phishing recall, with the largest decrease limited to 0.029. This suggests that no individual feature dominates the attack outcome. Instead, the substantial degradation observed in
Section 4.2 arises from the combined manipulation of multiple lexical features, indicating that the effectiveness of the feature-space attack is driven by cumulative rather than individual feature perturbations. This observation is consistent with the attack formulation introduced in
Section 3.3, where multiple manipulable lexical features are perturbed simultaneously during adversarial example generation.
4.5. Why the Attack Works: SHAP Attribution Analysis
To better understand the mechanism underlying the feature-space attack,
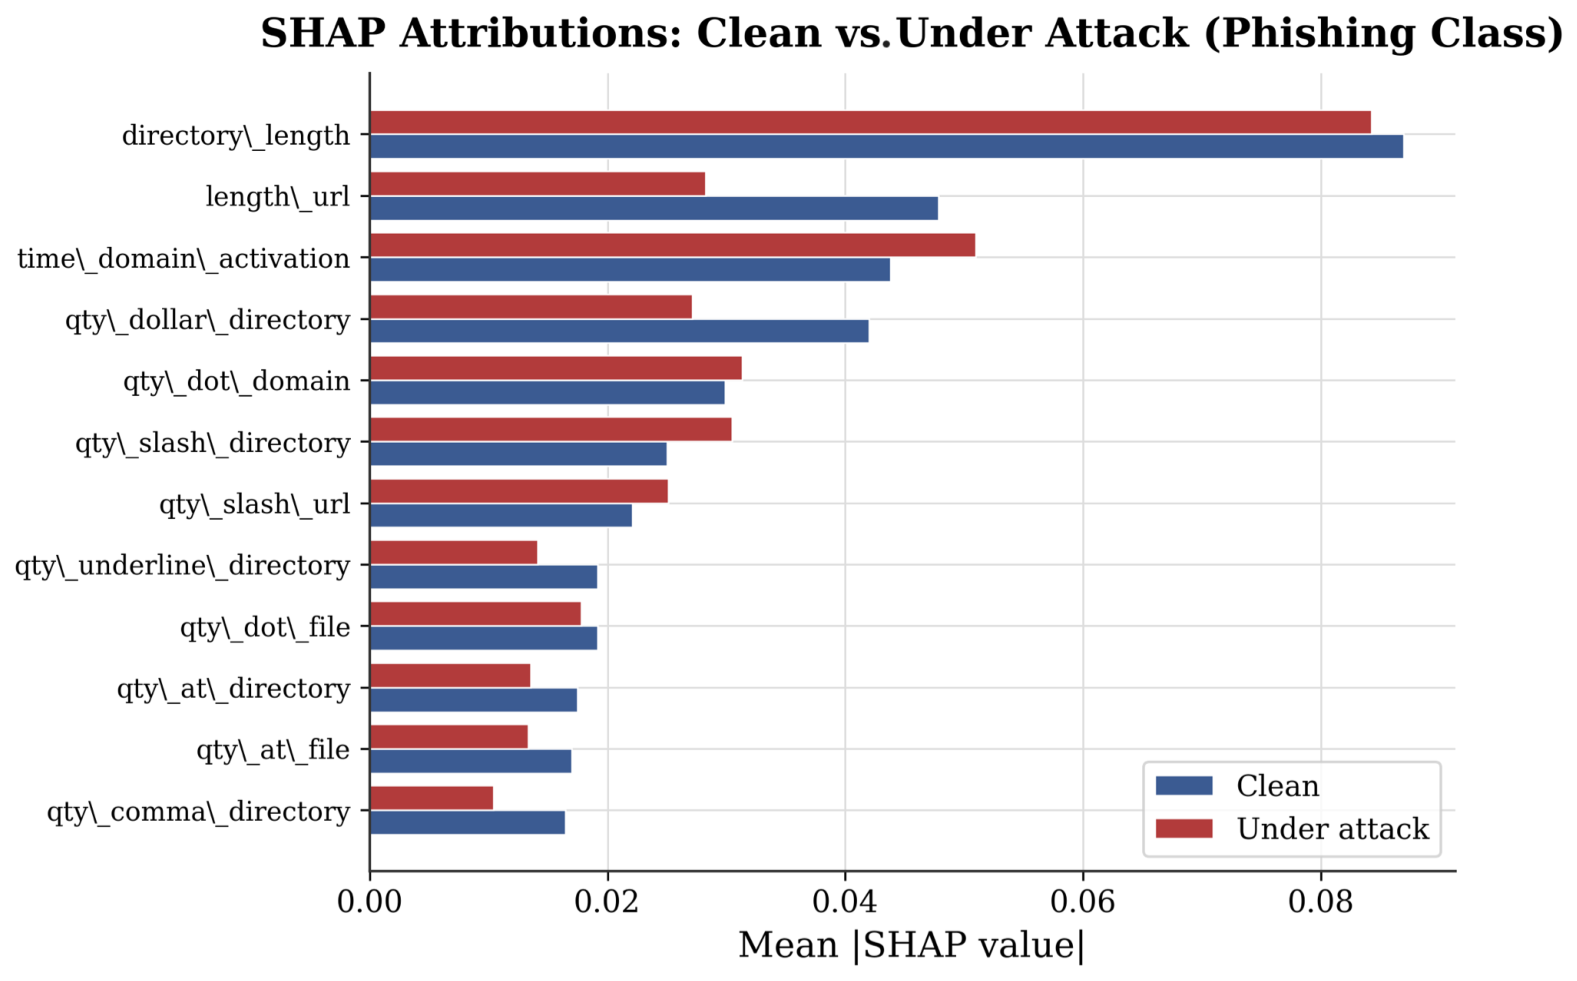
Figure 7 compares SHAP feature attributions for phishing samples under clean conditions and after adversarial manipulation. The analysis reveals a clear shift in feature importance following the attack, providing insight into how the manipulation alters the model’s decision process.
The importance of several manipulable lexical features decreases after the attack. For example, the SHAP contribution of directory_length decreases from 0.092 to 0.077, while length_url decreases from 0.050 to 0.028. In contrast, the contribution of the host-based feature time_domain_activation increases from 0.037 to 0.048, indicating that the classifier places greater emphasis on host-related information when lexical cues become less reliable.
These findings provide an explanation for the effectiveness of the defense strategies presented in
Section 4.3. As the influence of manipulable lexical features diminishes under attack, features derived from host characteristics become increasingly important. This observation supports both the robust feature selection strategy and the proposed features designed to improve robustness, which intentionally rely on information that is substantially more resistant to direct lexical manipulation. Together, these results provide an interpretable explanation for the observed accuracy–robustness gap and reinforce the rationale behind the proposed feature design.
4.6. The Reality Check: Problem-Space Attack on Real URLs
The experiments on Dataset B provide a realistic assessment of adversarial robustness by evaluating attacks performed directly on real URLs rather than on manipulated feature vectors. Under clean conditions, the detector achieves an F1 score of 0.994. Across all evaluated manipulation levels, modifying the original URL results in only negligible changes in phishing detection performance, with recall remaining close to its clean baseline.
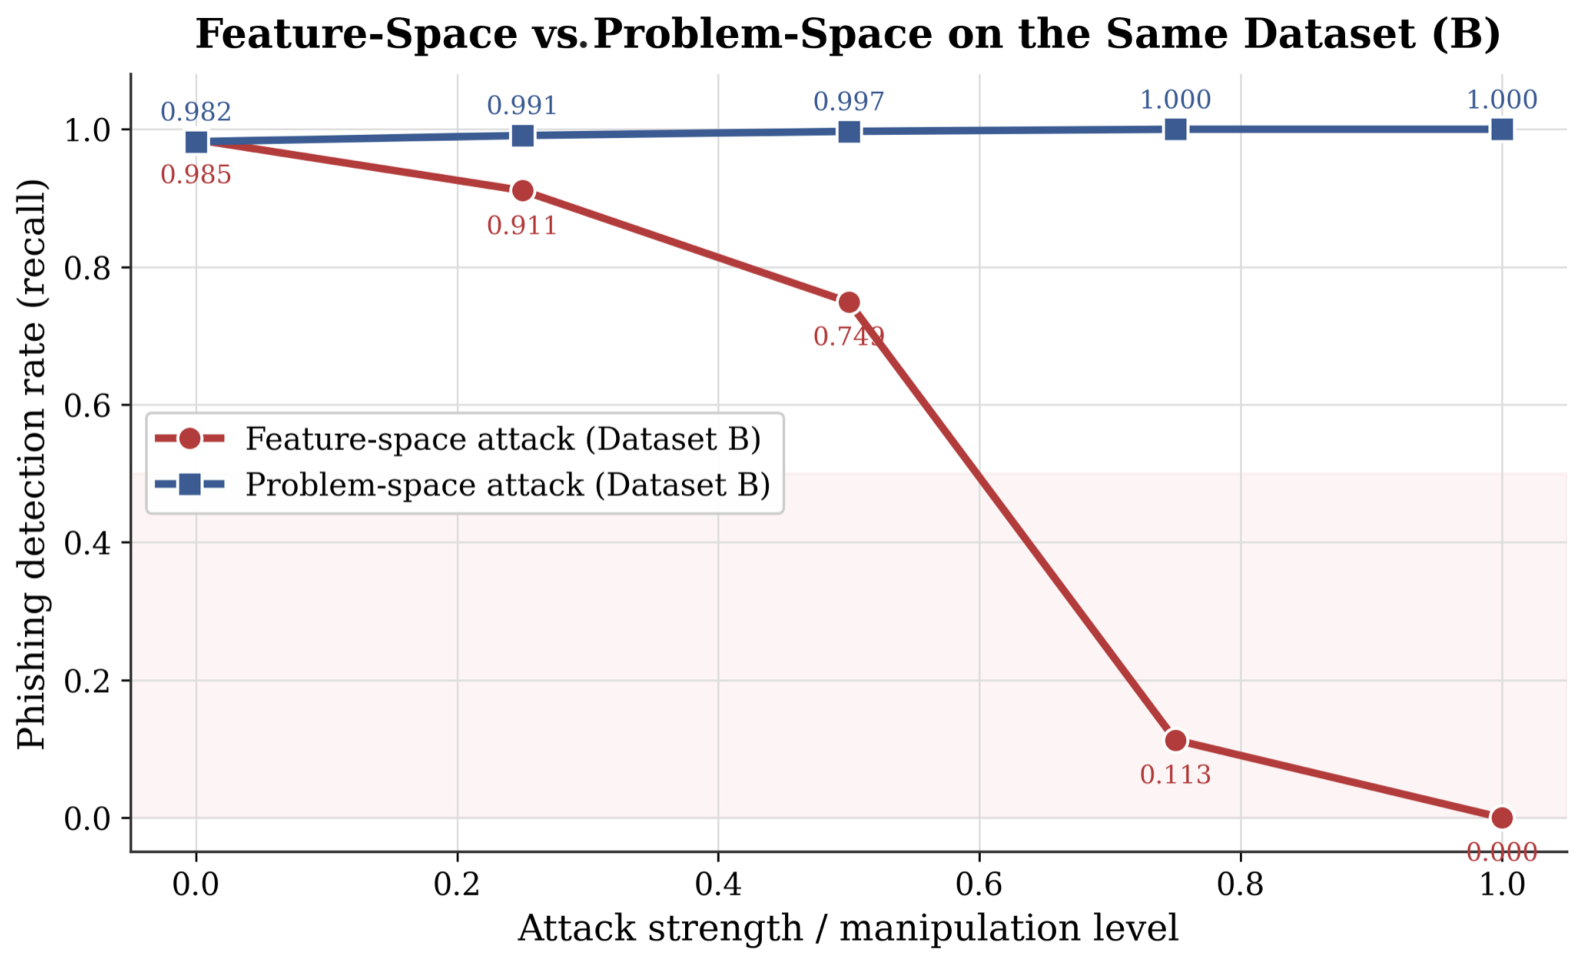
To remove any confound arising from comparing a feature dataset (A) with a real-URL dataset (B), we further apply both attack types to the same Dataset B, using the same Random Forest classifier and the same set of manipulable lexical features. The result is unambiguous (
Table 4): under the feature-space attack, detection on Dataset B collapses from 0.985 at strength 0 to 0.000 at full strength, whereas under the problem-space attack on the identical data it is essentially unchanged, moving from 0.982 to 1.000 across the same range. The two zero-attack baselines (0.985 and 0.982) correspond to the same model evaluated in two independent attack runs and differ only by sampling variation. Because dataset, model, and manipulable features are held constant, the divergence is attributable to the attack space itself rather than to dataset differences.
Figure 8 directly compares the feature-space and problem-space attack scenarios on Dataset B. While phishing detection deteriorates substantially under feature-space manipulation, falling to 0.000 at the strongest attack level, the corresponding problem-space curve remains almost unchanged throughout the evaluation. We note that the two feature-space collapse values reported in this paper refer to different settings and are therefore not directly comparable: the Random Forest model on the 111-feature Dataset A declines to 0.363 (
Table 2), whereas the lexical-only model on the 9-feature Dataset B, which retains far fewer non-manipulable signals, declines to 0.000 (
Table 4). This contrast demonstrates that the severe degradation observed under feature-space attacks does not readily translate to realistic attacks on valid URLs.
The SHAP analysis presented in
Section 4.5 provides a plausible explanation for this behaviour. Although lexical modifications reduce the influence of several URL-based features, discriminative information increasingly shifts toward host-based characteristics, which remain largely unaffected by simple URL editing. Consequently, modifying a valid phishing URL has only a limited impact on the overall feature representation and, therefore, on the classifier’s prediction.
To address the risk of domain-level information leakage under a random split, we repeated the Dataset B evaluation with a domain-disjoint split in which no registered domain (5538 unique domains) appears in both partitions. As expected, clean performance is lower because the model can no longer memorize domain identities (lexical-only clean F1 0.884 versus 0.988 under the random split; proposed 0.896 versus 0.994), but the qualitative conclusions are unchanged: under the strongest feature-space attack the lexical-only model falls to 0.000 while the proposed features retain 0.202 (versus 0.280 under the random split), and the problem-space attack remains ineffective.
These findings reinforce the central argument of this study: robustness evaluations based solely on feature-space perturbations may substantially overestimate the practical vulnerability of phishing detectors. Incorporating realistic problem-space attacks is therefore essential for obtaining a more reliable assessment of adversarial robustness. This finding supports the use of problem-space evaluation as a more realistic benchmark for assessing the adversarial robustness of phishing detection systems.
4.7. Host-Based Features as the Robust Core
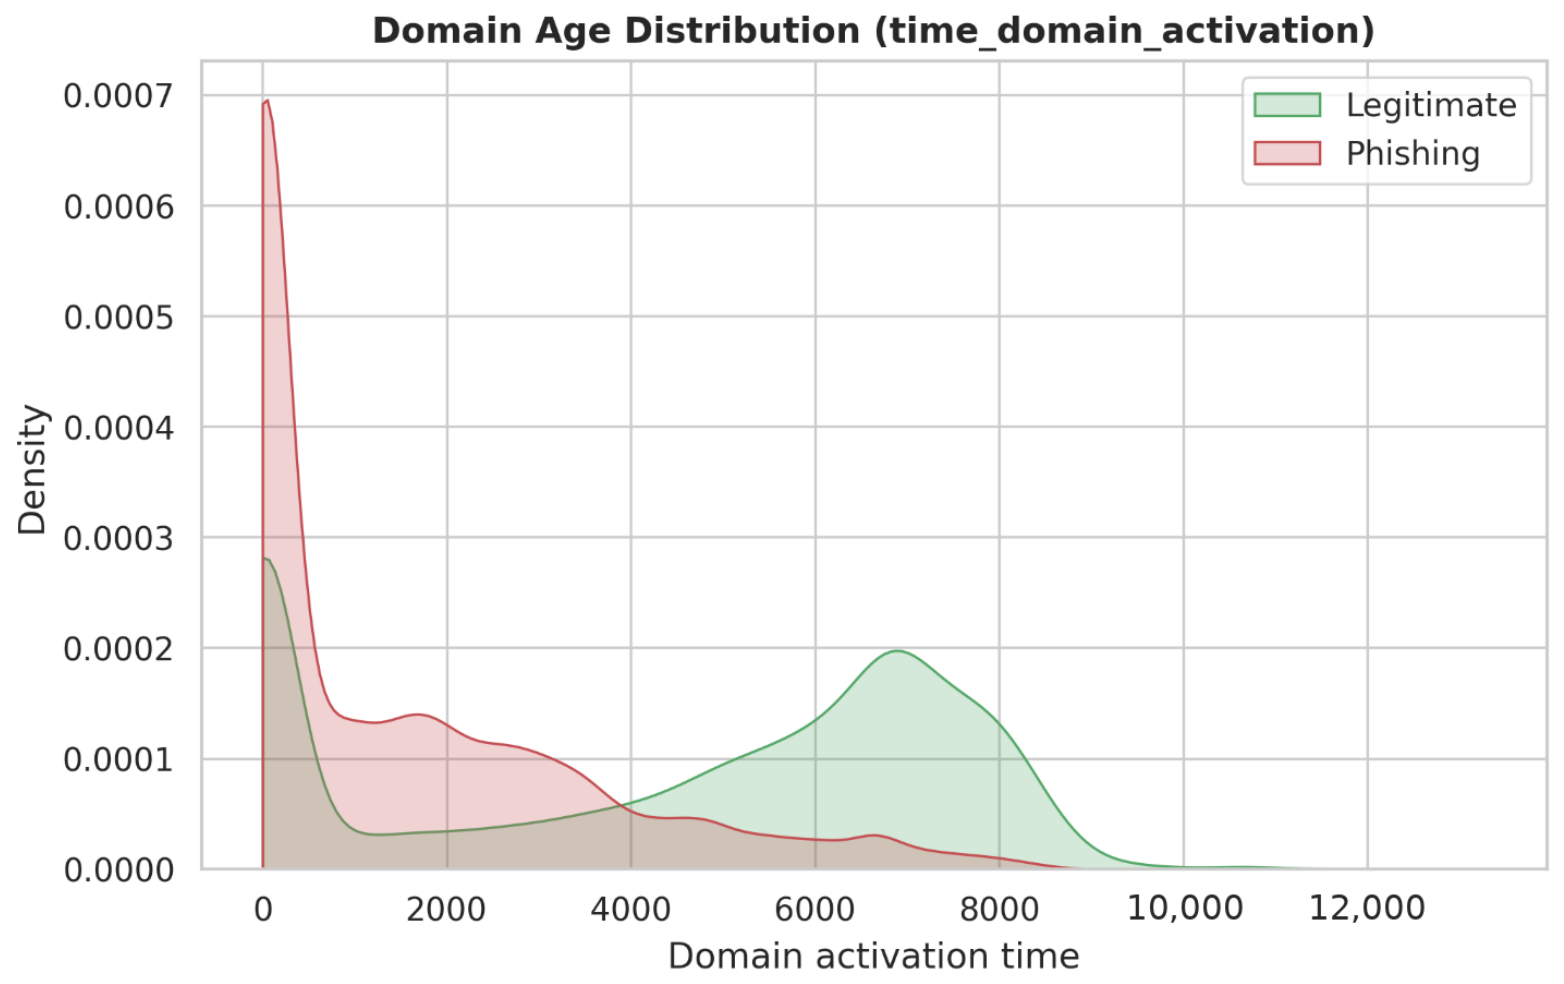
To identify the source of the observed robustness, we further examine the contribution of host-based features in Dataset A. Collectively, host- and SEO-related features account for approximately 21% of the overall feature importance, with domain age representing the most influential host-based characteristic.
Figure 9 compares the distribution of domain activation time for legitimate and phishing domains. Legitimate domains are generally substantially older than phishing domains, providing a discriminative signal that cannot be easily modified through simple lexical manipulation of the URL. This observation is consistent with the SHAP analysis presented in
Section 4.5, which showed that the relative importance of host-based information increases under feature-space attack.
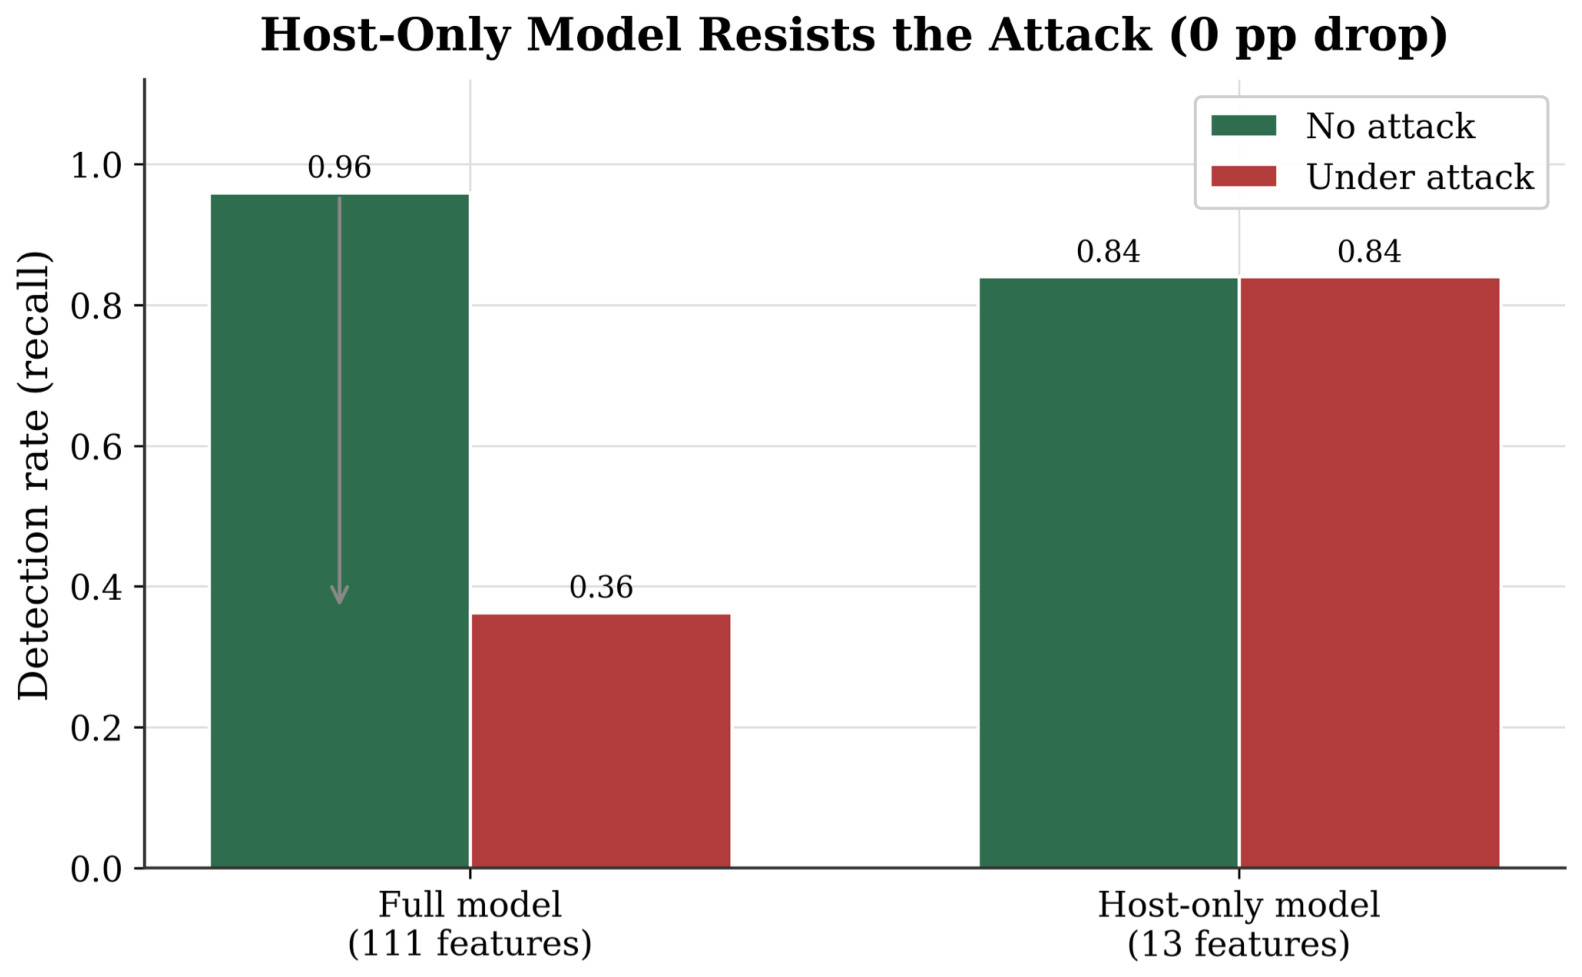
To further evaluate the contribution of these features, we trained a classifier using only host-based attributes. As shown in
Figure 10, the host-only model maintains identical phishing recall under clean and adversarial conditions (0.84 vs. 0.84), whereas the full model experiences a substantial decline from 0.96 to 0.36 under the same attack. Although the host-only model achieves a lower baseline recall than the full model, its performance remains stable because the attack targets only lexical features.
These findings indicate that host-based features constitute a stable source of discriminative information that is largely unaffected by feature-space manipulation. This provides further evidence supporting the proposed features designed to improve robustness, which intentionally emphasize characteristics that are substantially more resistant to direct lexical manipulation.
4.8. Robustness Evaluation of the Proposed Features
To evaluate the effectiveness of the proposed features introduced in
Section 3.4, we augment the baseline lexical feature set with the proposed host- and semantic-based features and evaluate performance on Dataset B under progressively stronger feature-space attacks.
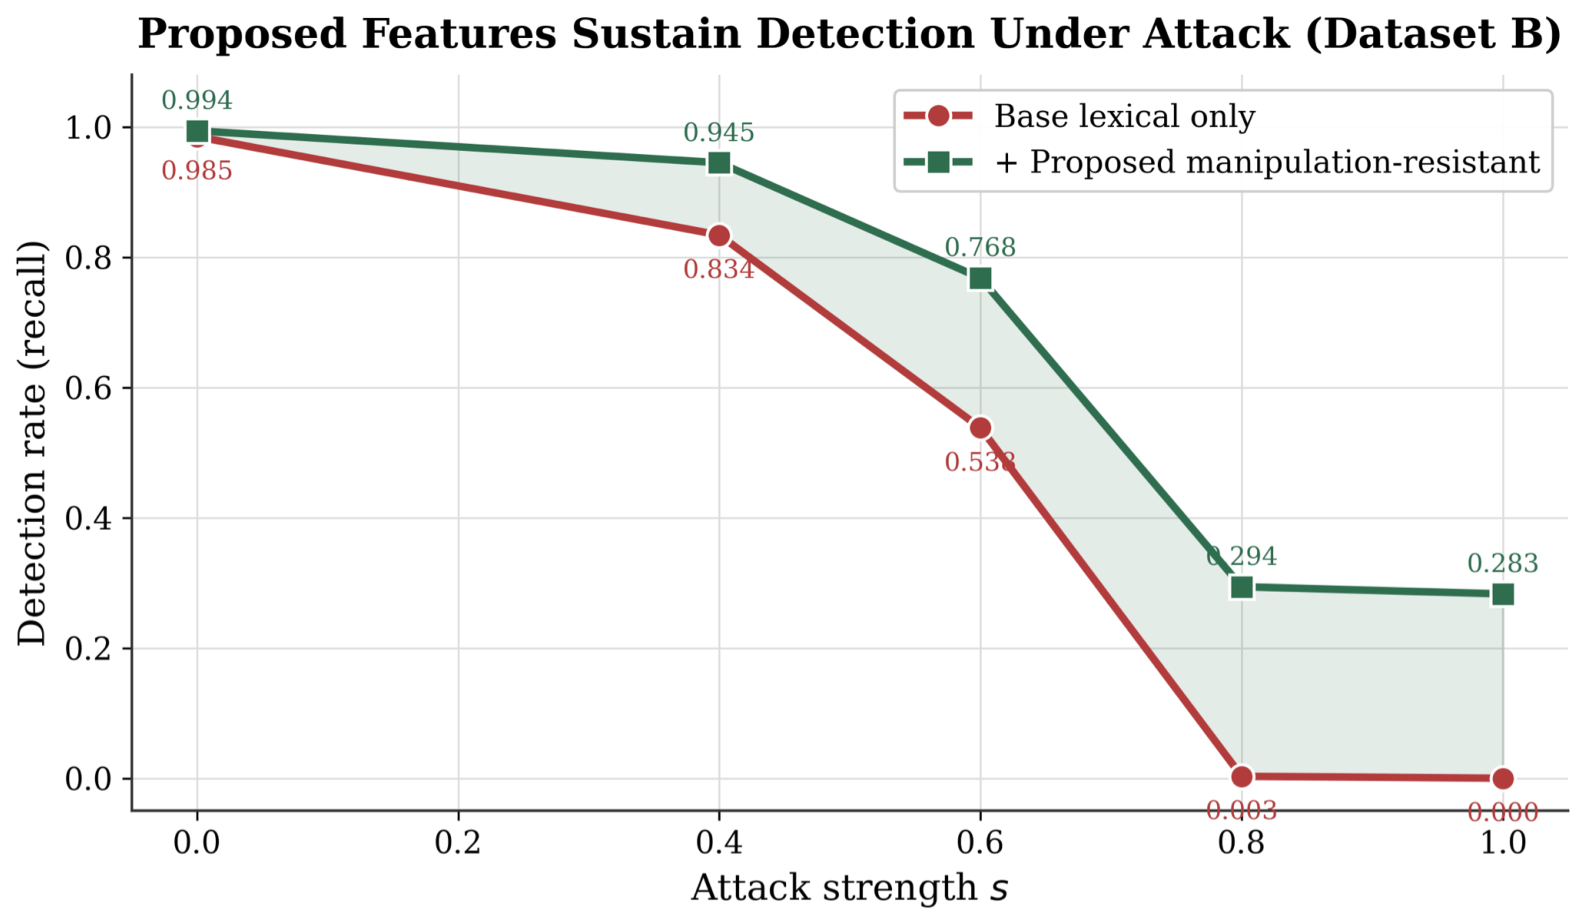
Table 5 and
Figure 11 summarize the resulting phishing detection performance.
Under clean conditions, incorporating the proposed features produces a modest improvement in F1 score, increasing performance from 0.985 to 0.994. As attack strength increases, however, the benefit becomes substantially more pronounced. While the lexical-only model experiences a rapid degradation in phishing detection performance, the augmented model consistently maintains substantially higher recall across all attack levels.
The largest improvement is observed under the strongest attacks. At an attack strength of 0.8, phishing recall increases from 0.003 to 0.294 (+29.1 percentage points), while under the strongest attack (), the augmented model maintains a phishing recall of 0.283 compared with complete detection failure for the lexical-only model. These results demonstrate that the proposed features substantially improve robustness against feature-space manipulation while preserving strong performance under clean conditions.
Among the proposed features, subdomain depth, character entropy, and lexical word validity contribute most strongly to the observed performance gains. By contrast, free and suspicious top-level domain (TLD) indicators provided only limited discriminative value for this dataset and were therefore excluded from the final feature set. This observation highlights that not all intuitively meaningful host-related indicators contribute equally, reinforcing the importance of empirical feature evaluation during feature design.
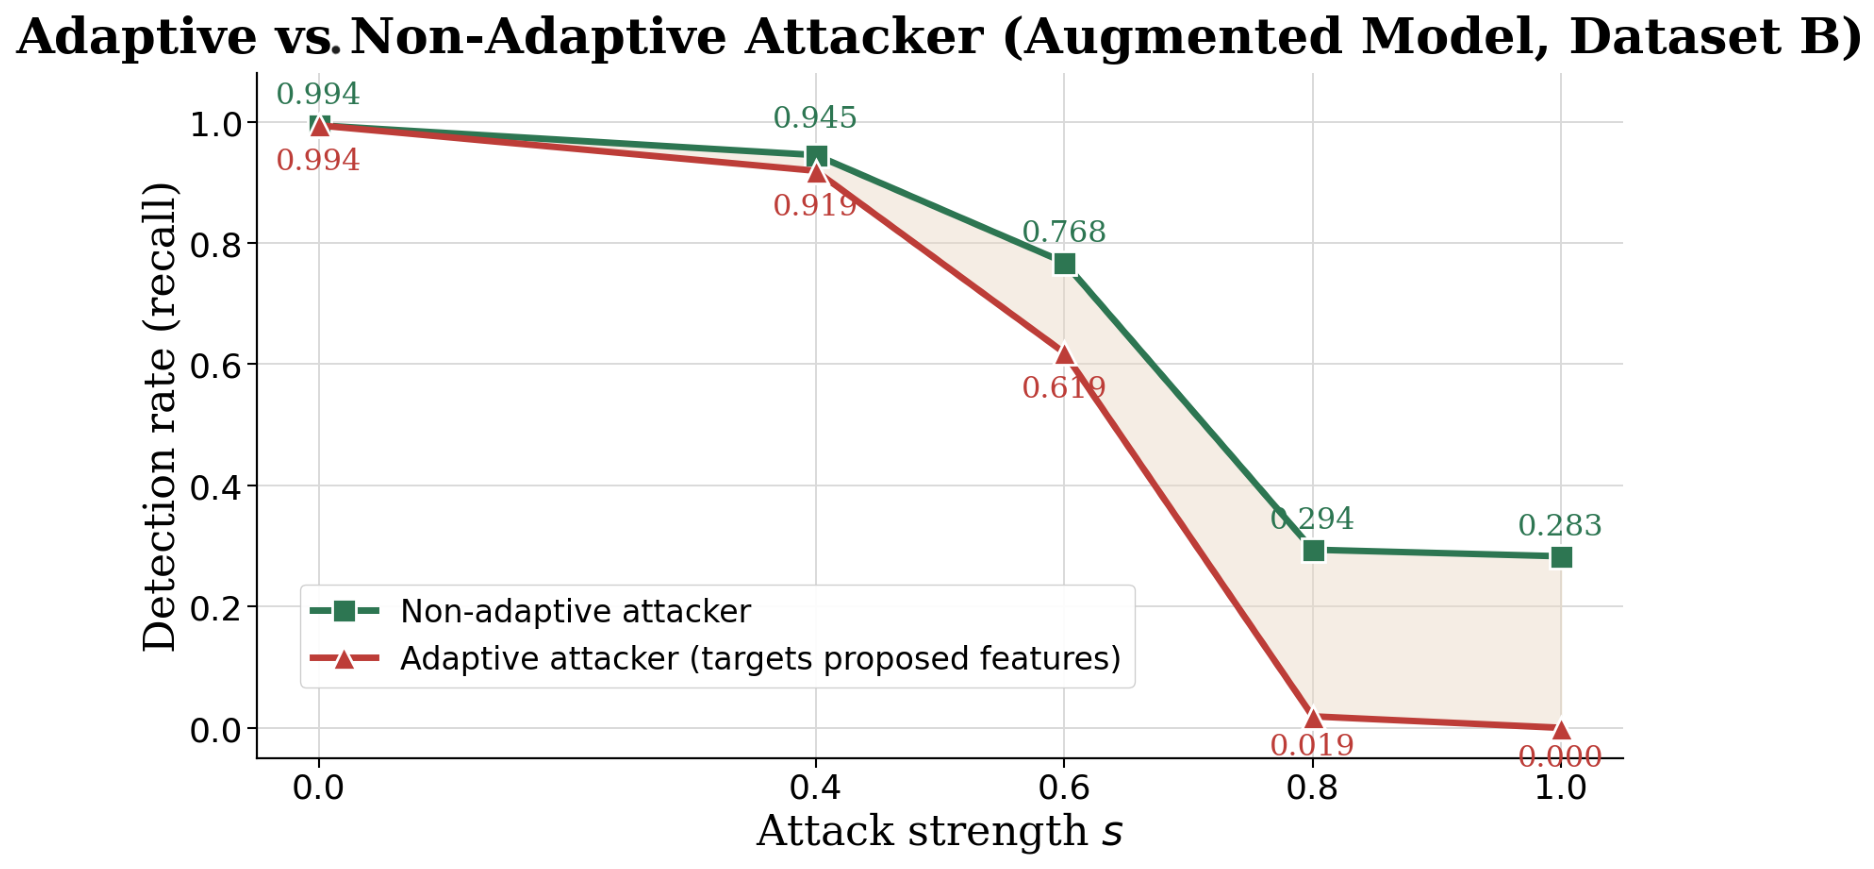
The preceding test assumes a non-adaptive attacker that ignores the proposed features. To evaluate fairly, we consider an adaptive attacker permitted to also target the manipulable components of the proposed set (lowering entropy and subdomain depth, and avoiding the homoglyph and brand-substring flags).
Table 6 and
Figure 12 report the outcome. Under moderate attacks the proposed features still help (recall 0.919 versus 0.945 at
; 0.619 versus 0.768 at
, adaptive versus non-adaptive), but under the strongest adaptive attack the advantage disappears, with recall falling to 0.000—matching the lexical-only baseline. The genuinely attack-invariant component is therefore the host-derived feature set, which URL editing cannot alter at all. We consequently position the proposed semantic and structural features as raising the attacker’s cost and helping against non-adaptive and moderate attacks, and as a complement to—not a replacement for—host-based signals.
Overall, these results show that incorporating features substantially more resistant to direct lexical manipulation provides an effective means of improving adversarial robustness while preserving strong performance under clean conditions.
5. Discussion
The results presented in this study have several important implications for the evaluation and design of phishing detection systems. First, they demonstrate that feature-space robustness alone can substantially overestimate the practical vulnerability of a detector. Although feature-space attacks reduce Random Forest phishing recall on Dataset A from 0.96 to 0.36 (and drive the lexical-only model on Dataset B to zero), the corresponding problem-space evaluation on the same real URLs shows almost no degradation in detection performance. Consequently, reporting robustness solely under feature-space perturbations may provide an overly pessimistic assessment of a model’s operational security.
Second, the experiments reveal that robustness is not directly correlated with clean-data performance. The models achieving the highest baseline performance under clean conditions are not necessarily the most resilient to adversarial manipulation. This finding suggests that model selection for phishing detection should consider adversarial robustness alongside conventional performance metrics rather than relying exclusively on clean-data evaluation.
Third, the experimental analysis consistently identifies host-based information as the primary source of robustness. The SHAP analysis, host-only experiments, and evaluation of the proposed feature set all indicate that characteristics which are substantially more resistant to direct lexical manipulation provide stable discriminative information even under adversarial conditions. The adaptive-attacker analysis qualifies this: the semantic and structural features raise the attacker’s cost and help under moderate attacks, but only host-derived features are strictly attack-invariant, so we frame the proposed representation as complementary to host-based signals rather than a standalone defense. This observation is consistent with recent studies showing that incorporating metadata and host-related information substantially improves the resilience of phishing URL detectors under adversarial evasion scenarios [
28].
These findings extend the evasion-space perspective introduced by Apruzzese et al. [
9] and its journal extension [
16] by demonstrating, in the specific context of phishing detection, that feature-space evaluations alone may not accurately reflect realistic adversarial risk. At the same time, they establish a direct connection with the typosquatting, homoglyph, and domain impersonation literature [
12,
13,
14], showing that domain characteristics originally studied for phishing detection also provide valuable robustness properties under adversarial manipulation. More broadly, treating robustness as a property of the feature representation complements architecture- and training-level approaches to AI-system resilience such as that of Moskalenko et al. [
22].
6. Limitations and Threats to Validity
This study has several limitations that should be considered when interpreting the results. First, the feature set extracted for Dataset B is intentionally more limited than that of Dataset A. Our custom feature extraction framework computes lexical features together with selected host-based attributes but does not include the full range of network-derived information (e.g., live WHOIS records or DNS-based features) available in Dataset A. Incorporating these additional sources of information may further improve robustness under realistic attack scenarios.
Second, the adversarial evaluation considers a median-shift feature-space attack together with a problem-space attack based on realistic URL modifications. Although other attack strategies, such as gradient-based or query-based methods [
7], may produce different perturbation patterns in the feature space, they remain subject to the same realizability constraints when attacks are required to generate valid URLs. We further note that we verify the syntactic validity and host-preservation of problem-space transformations but do not verify the live page-level functionality of historical phishing URLs, most of which are offline; our claims therefore concern host-preserving URL edits.
Third, some host-based characteristics may also be circumvented in practice. For example, attackers can exploit aged or compromised domains to reduce the discriminative value of features such as domain age. Consistent with this, our adaptive-attacker analysis (
Section 4.8) shows that the semantic and structural components of the proposed set do not withstand a determined adversary who targets them directly. Consequently, the proposed feature set should be viewed as complementary to existing phishing detection features rather than as a complete replacement for them.
Finally, although both datasets used in this study are relatively large and representative, phishing attacks continue to evolve over time. Future work should therefore investigate temporal robustness, cross-dataset generalization, and the effectiveness of the proposed features against emerging phishing strategies and newly observed attack patterns. Evaluating the proposed feature set against additional real-world phishing datasets and continuously evolving attack techniques represents an important direction for future research.
7. Conclusions
This study presented a comprehensive investigation of adversarial robustness in URL-based phishing detection by combining feature-space and problem-space evaluations across two complementary datasets. While feature-space attacks have become the dominant benchmark for evaluating adversarial robustness, our results demonstrate that they do not necessarily reflect the behaviour of phishing detectors under realistic attack conditions. By explicitly comparing feature-space perturbations with attacks performed on valid URLs, we provide a more complete assessment of adversarial robustness in practical phishing detection scenarios.
The experimental results show that feature-space attacks substantially overestimate the practical vulnerability of phishing detectors. Although feature-space perturbations reduce Random Forest phishing recall on Dataset A from 0.96 to 0.36, the corresponding problem-space attacks performed on real URLs have only a limited effect on detection performance. Further analysis demonstrates that this difference arises because host-based characteristics continue to provide stable discriminative information even when manipulable lexical features are altered.
Building on these observations, we proposed a set of features designed to improve robustness by emphasizing characteristics that are substantially more resistant to direct lexical manipulation. Experimental evaluation demonstrated that incorporating these features consistently improved robustness under feature-space attacks while preserving excellent clean-data performance. The proposed feature set increased clean-data performance to an F1 score of 0.994 and maintained substantially higher phishing detection rates than conventional lexical features under the strongest evaluated attacks, although, as our adaptive-attacker analysis shows, host-based features remain the strictly attack-invariant core. Unlike previous studies that primarily evaluate robustness through feature-space perturbations, this work demonstrates the importance of jointly considering realistic attack feasibility and feature representation when assessing adversarial robustness in phishing detection.
More broadly, our findings suggest that adversarial robustness should not be viewed solely as a property of the learning algorithm but also as a consequence of the underlying feature representation. Designing features that remain informative under realistic attack constraints is therefore as important as developing more sophisticated classifiers. We hope that this work encourages future research to complement conventional feature-space evaluation with realistic problem-space assessment and to place greater emphasis on feature engineering as a fundamental component of adversarially robust phishing detection systems.