Article

Error-Profile-Conditioned Augmentation for Chinese L2 Writing Assessment: Evaluating Synthetic Tail Data Under Data Scarcity

1
Aerospace Information Research Institute, Chinese Academy of Sciences, Beijing 100094, China
2
School of Foreign Studies, University of Science and Technology Beijing, Beijing 100083, China
*
Author to whom correspondence should be addressed.
Appl. Sci. 2026, 16(17), 8736; https://doi.org/10.3390/app16178736
Submission received: 16 August 2026 / Revised: 30 August 2026 / Accepted: 31 August 2026 / Published: 2 September 2026
(This article belongs to the Section Computing and Artificial Intelligence)

Abstract

Automated essay scoring models trained on imbalanced examination data often compress predictions toward the score mean, disproportionately harming low-proficiency responses. We investigate whether synthetic tail data can mitigate this failure in Chinese second-language writing assessment. Using 10,067 HSK writing samples, we introduce Error-Profile-Conditioned Synthesis (EPCS), which transfers a complete error profile and examiner score from a real low-band donor to an expert-corrected mid-band substrate, uses authentic error exemplars, and verifies the generated manifest. We evaluate three method versions using surface-feature tests, real-versus-synthetic discrimination, and downstream MacBERT scoring under full, 25%, and 10% low-band retention. Surface similarity did not predict downstream utility: the least detectable version transferred poorly, whereas content-degraded versions were more useful. With only 49 real low-band training samples, EPCS with reweighting reduced low-band mean absolute error from 14.91 to 12.66 and increased below-60 recall from 0.10 to 0.33; recall improved in all five paired seeds and low-band error in four. However, overall QWK changed from 0.506 to 0.497, precision decreased from 0.78 to 0.56, and the false-positive rate increased from 0.015 to 0.106. The pattern replicated across two further pretrained encoders and a feature-based scorer and survived a ± 5 -point stress test of the inherited labels. EPCS therefore acts as a scarcity-conditioned operating-point intervention, improving tail detection at the cost of more false alarms and high-band under-scoring.

1. Introduction

Automated essay scoring (AES) is not only a prediction problem but also a measurement-and-use problem. Evidence for an automated score must support the intended interpretation and decision, including the response groups and score regions for which errors have the greatest consequences [1,2,3]. This requirement is especially important in second-language (L2) writing, where low-proficiency responses can be both relatively rare and linguistically heterogeneous [4]. A model optimized on a middle-heavy score distribution may achieve acceptable aggregate agreement by shrinking predictions toward the mean while providing weak evidence at the lower tail. Aggregate performance can therefore conceal score-conditional error and materially different classification behavior around a chosen decision threshold.
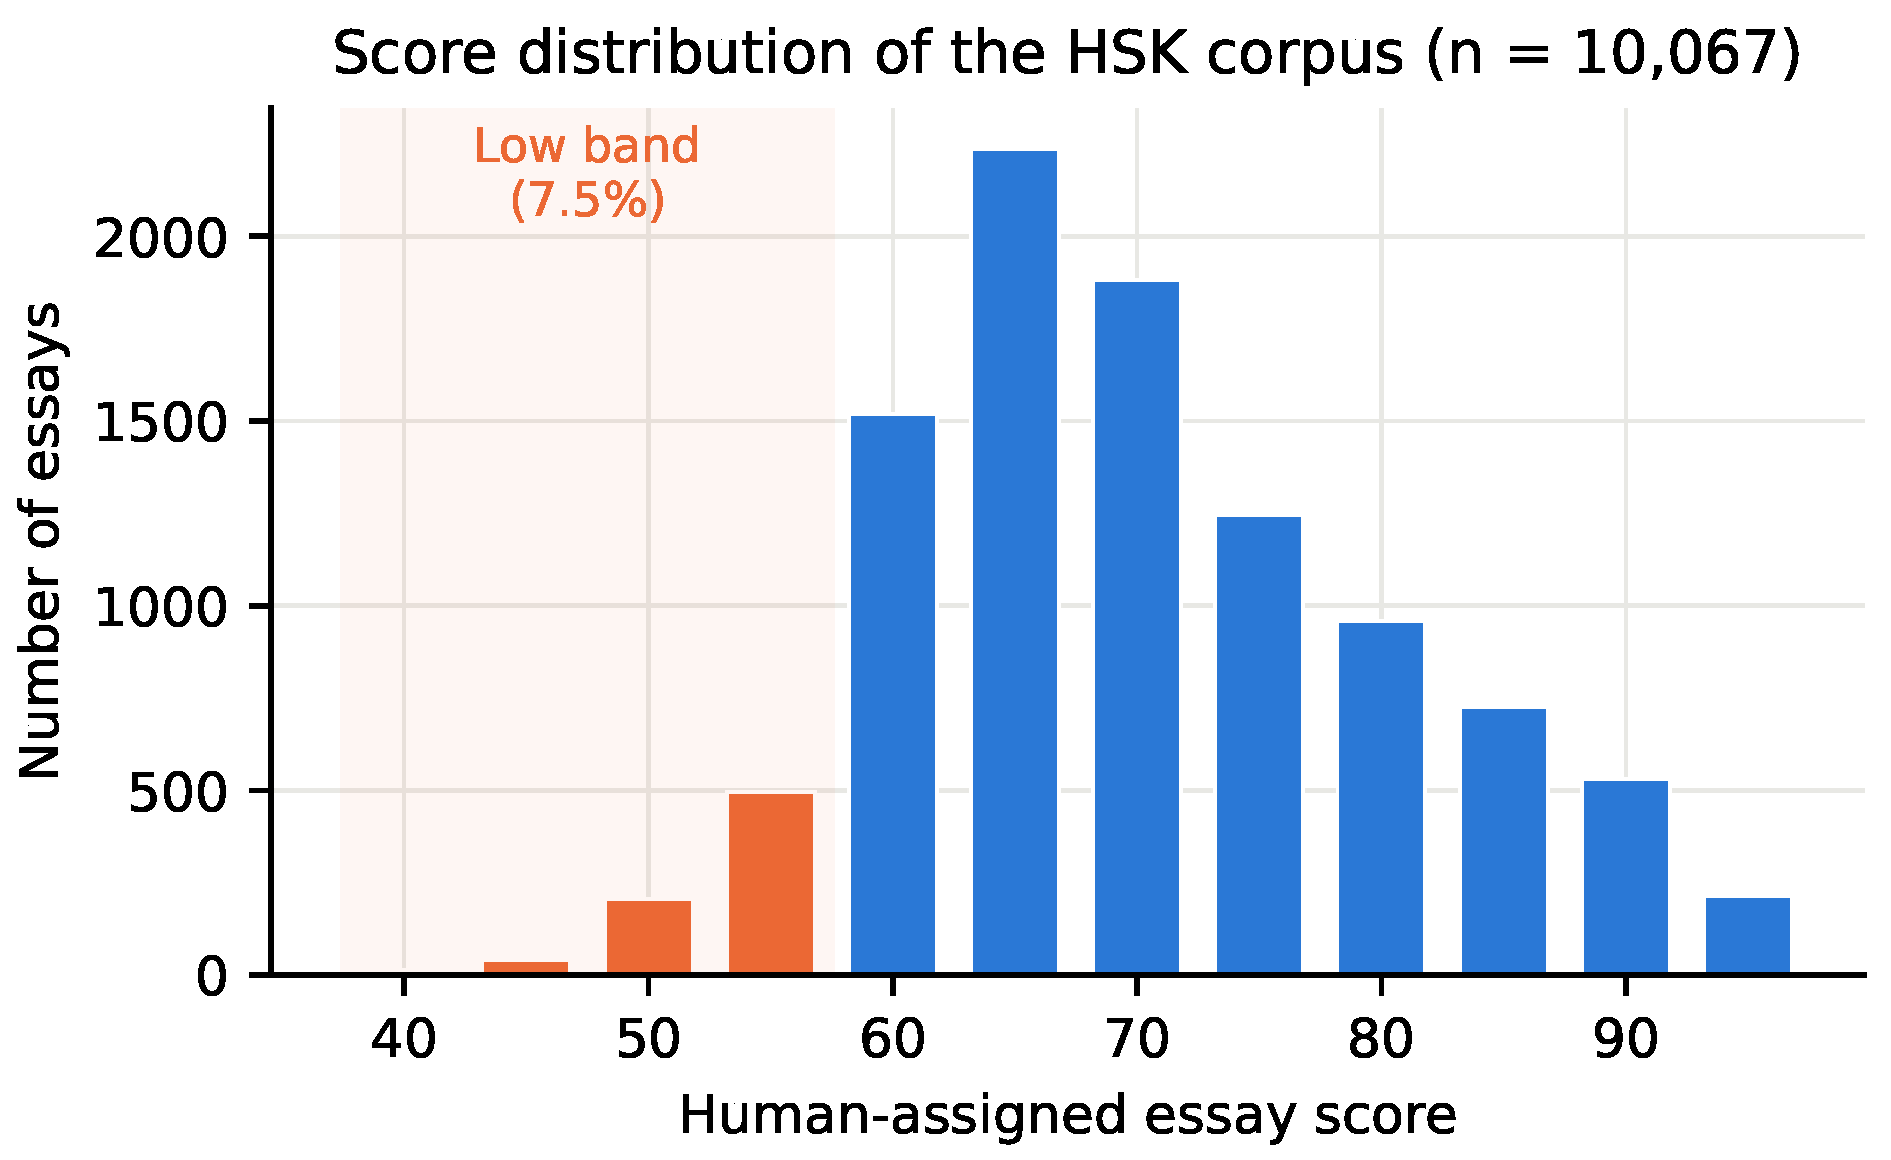
Chinese-as-a-second-language (CSL) writing provides a consequential test case. The HSK Dynamic Composition Corpus is one of the principal publicly accessible resources used in Chinese AES research [5,6]. In the analytic sample used here, only 7.5% of responses occupy the 40–59 band. A MacBERT regression scorer trained on the natural distribution over-scores this band by + 14.0 points on average and compresses the score scale to a slope of 0.44 . When the available real low-band training set is reduced from 496 to 49 samples, below-60 recall falls to 1.4 % for the unweighted model and remains 10.1 % under inverse-frequency loss weighting. We use 60 as a prespecified analytic boundary between the study’s low and middle bands; we do not interpret it as an official historical HSK writing pass mark. These observations expose the central scientific contradiction that motivates this study: optimizing a scorer on a middle-heavy score distribution produces deceptively high aggregate agreement statistics while concealing severe, systematic evaluation errors exactly at the score boundary where automated decisions carry the greatest consequences for learners. Aggregate optimization and lower-tail reliability are thus in direct conflict, and resolving this conflict requires interventions—and evaluation designs—that treat the lower tail as a first-class target rather than a residual.
Large language models (LLMs) offer a tempting remedy: synthesize the missing tail. Yet low-proficiency learner writing is a difficult generation target. Prompts such as “write like a beginner” encode stereotypes rather than an empirical interlanguage distribution. In our audit, naive role-play text is trivially distinguishable from authentic low-band writing (GBDT AUC 0.97 ) and offers little downstream benefit. Recent AES work has likewise found that LLM-generated augmentation is sensitive to prompt design, proficiency control, and the amount of synthetic data [7,8,9]; broader reviews similarly stress that synthetic-data quality must be evaluated against task-specific utility and risk [10]. The relevant question is therefore not simply whether synthetic essays can be produced, but which signals must be preserved, under what data regime, and at what decision cost.
We propose EPCS (Error-Profile-Conditioned Synthesis). It exploits the fact that error statistics can be better documented than rare scored texts. From 105,462 expert-annotated learner sentences, we reconstruct empirical error profiles and authentic single-error exemplars. Each synthetic sample borrows a complete per-category error budget from a real low-band donor. An LLM injects the budget into an expert-corrected mid-band substrate, returns a machine-readable manifest, and repairs outputs that fail local checks. The sample inherits the donor’s examiner score, avoiding LLM self-labeling while retaining a transparent approximation: the donor profile, rather than the new content, anchors the label.
Existing work establishes the feasibility of LLM augmentation and controlled error generation but leaves three linked questions open: whether measured fidelity predicts downstream usefulness, whether augmentation adds value beyond a strong cost-sensitive baseline when real tail support changes, and what score-conditional costs accompany any gain. The present study addresses these questions through three versioned generators, layered fidelity tests, paired training seeds, a simulated scarcity gradient, and an operating-point analysis.
The scope of the study can be stated formally. The object of research is the process of automated evaluation and scoring of CSL/L2 writing samples under severe class imbalance, in which low-proficiency responses are rare in training data yet carry the highest decision stakes. The subject of research is the set of mechanisms implemented in the proposed EPCS framework—empirical error-budget donation from real low-band donors, exemplar-guided error injection into expert-corrected substrates, verify–repair control of the generated manifest, and examiner-score inheritance—together with the effect of these mechanisms on lower-tail scoring behavior. The overall research goal is to determine under which data-scarcity conditions and at which decision costs error-profile-conditioned synthetic tail data improves low-band scoring reliability without degrading aggregate agreement. This goal is decomposed into five research tasks: (i) to develop a donor-conditioned synthesis procedure that replaces unconstrained LLM role-play with empirical error-budget injection and avoids LLM self-labeling; (ii) to audit the fidelity of the synthetic samples at three measurement levels—univariate surface features, classifier-based discrimination, and downstream transfer; (iii) to quantify the incremental utility of the joint augmentation–reweighting configuration against a cost-sensitive reweighting baseline across a controlled scarcity gradient; (iv) to evaluate the below-threshold operating-point and score-range costs that accompany tail recovery; and (v) to examine the boundary conditions imposed by donor support, synthetic dose, and generator choice.
These tasks are operationalized as four research questions: RQ1, how do EPCS versions differ in surface fidelity, detectability, and downstream transfer, and do these rankings agree? RQ2, how does EPCS combined with reweighting compare with reweighting alone as real low-band support decreases? RQ3, what below-threshold and score-range costs accompany tail recovery? RQ4, how sensitive are the findings to donor support, synthetic dose, and one generator change?
Our main contributions are:
  • A donor-conditioned synthesis procedure with per-sample error budgets, authentic exemplars, a verify–repair loop, and examiner-score inheritance that avoids LLM self-labeling (Section 3.4).
  • A layered audit and three-version ablation showing that surface-feature indistinguishability and downstream utility can have opposite rankings (Section 4.1).
  • Evidence that the behavior of the joint augmentation–reweighting configuration is scarcity conditioned: v3 improves low-band MAE and recall relative to reweighting in 3/5 seeds at full data and 4/5 at both 25% and 10% retention; at 10%, recall improves in all five seeds (Section 4.2).
  • An operating-boundary analysis showing that tail recovery trades precision and high-band accuracy for recall, and that donor-conditioned augmentation expands observed score support rather than extrapolating to absent score levels (Section 4.3, Section 4.4, Section 4.5 and Section 5).

2. Related Work

2.1. Automated Essay Scoring and Validity

Operational AES predates neural models. Feature-engineered systems such as e-rater combined a compact inventory of interpretable linguistic features with transparent scoring models [11], while supervised work on ESOL examination scripts established widely used learner-writing benchmarks and feature-based grading methods [12]. Neural AES then moved toward end-to-end sequence representations: recurrent models learn score-sensitive word representations, and hierarchical attention models aggregate evidence across words and sentences [13,14,15]. Surveys document the subsequent progression to pretrained encoders and more complex cross-prompt settings [16,17,18]. For Chinese, whole-word-masking variants such as MacBERT are common backbones [19,20], and recent work also uses LLMs directly as zero-shot or rubric-conditioned scorers [21].
This architectural progression does not remove the measurement problem. AES features are strongest at representing text production, linguistic form, and organization but may provide more limited evidence about rhetorical and conceptual quality [22]. Across model families, QWK, therefore, remains a useful but incomplete headline metric. Automated-scoring frameworks accordingly call for evidence about score meaning, subgroup performance, and consequences of use rather than a single agreement coefficient [1,3]. Aggregate agreement weights performance by the evaluation score distribution and can remain stable while errors change substantially at a decision threshold. We treat low-band MAE, below-60 precision, recall, F1, and false-positive rate as first-class outcomes rather than diagnostics subordinate to QWK.

2.2. Imbalanced Regression and Low-Score Performance

Class imbalance is traditionally addressed by resampling and synthetic minority oversampling [23]. Deep imbalanced regression extends the problem to continuous targets, where few-shot regions of the label space suffer both representation and optimization disadvantages [24]. Regression-specific data-level methods such as SMOGN combine undersampling with interpolation or noise around rare targets [25]; algorithm-level alternatives instead estimate target density and increase the loss contribution of low-density observations [26]. Inverse-frequency loss weighting is an inexpensive and strong baseline of the latter kind: it redistributes gradient mass toward rare score bands. Its limitation is support. When only a few tail observations remain, weighting can amplify those observations but cannot add linguistic variation. Our analysis distinguishes the empirical behavior of a joint augmentation-plus-weighting configuration from a stronger causal claim of synergy; the weighting objective used here is stated explicitly because it changes as the retained real tail shrinks.

2.3. Synthetic Learner Writing and Error Generation

NLP augmentation spans token edits, paraphrasing, back-translation, latent perturbations, and model-based generation; reviews emphasize that diversity is useful only when task-relevant labels remain valid [27,28]. Large language models extend this toolkit by producing prompt-controlled mixtures or variations of observed examples [29], but fluent output does not by itself establish that a proficiency label or score has been preserved.
Artificial error generation has a long history in grammatical error correction, where machine translation, pattern-based, pseudo-data, and tagged corruption models create parallel pretraining data [30,31,32,33]. Controlled error generation is now also used in low-resource settings and AES. Most directly, Qwaider et al. [7] generate Arabic essays across proficiency levels and compare LLM and model-based error injection guided by empirical CEFR profiles. Zhang et al. [8] study GPT-generated responses as training augmentation for automated scoring, including subgroup discrepancies and prompt/sample-size sensitivity. These studies establish that synthetic AES data and controlled errors are not new in themselves.
These studies leave open whether per-instance learner profiles offer different conditioning information from average proficiency-band profiles and whether a score attached to a real donor remains informative after its error profile is transferred to new content. Human-rated realism and score preservation provide one form of evidence for synthetic AES data [9]; a complementary approach is to state label transfer as a modeling approximation and test its empirical support boundary.
This qualification is especially relevant for low-proficiency writing. Prior work shows that AES systems can face distinctive construct-coverage and error- distribution challenges for low-proficient L2 writers [4]. Consequently, the present study treats synthetic labels as a modeling assumption to be stress-tested, not as newly established human scores.

2.4. Evaluating Synthetic Data Fidelity

Data augmentation studies commonly report only downstream task performance, although synthetic text can match selected statistics while retaining systematic artifacts [28]. Distributional auditing can be framed as a two-sample problem: kernel tests compare samples in a rich function space, whereas classifier two-sample tests ask how accurately a learned discriminator separates them [34,35]. We combine three practical views: univariate distribution tests over surface features, classification-based two-sample tests, and downstream transfer. These views are not assumed to agree. Their disagreement is itself evidence about which properties the AES encoder uses.
Taken together, the literature leaves four gaps relevant to low-score CSL assessment. First, aggregate AES agreement can obscure error concentrated at the lower tail. Second, controlled learner-text generation has seldom linked each synthetic sample to a complete real donor profile and an authentic examiner score. Third, distributional fidelity and downstream utility are often reported separately, leaving their relationship unclear. Fourth, augmentation is rarely evaluated across a controlled scarcity gradient while also reporting threshold-specific benefits, false alarms, and score-range costs. The present study addresses these gaps with per-donor EPCS, a versioned fidelity audit, comparison against reweighting, three levels of retained real low-band support, and explicit analysis of operating-point and donor-support boundaries.

3. Materials and Methods

3.1. Corpus, Writing Samples, and Analytic Score Bands

We use Version 2.0 of the HSK Dynamic Composition Corpus [36], which contains error-annotated examination writing produced between 1992 and 2005. The official resource page reports 11,569 compositions (4.24 million Chinese characters), while prior Chinese AES work describes examiner scores on a 40–95, five-point scale and reports that two professional assessors’ scores were averaged [5,6]. From the records available through the corpus interface, we aggregate 105,462 annotated sentences into 11,319 essay-level units and reconstruct for each unit (i) the student version, with annotated errors restored, and (ii) the expert-corrected version. Because the source stores retrieved annotated sentences rather than complete manuscripts, our unit of analysis is a writing sample (a median of 263 and a mean of 271 characters), not a full essay. The same unit is used for training, synthesis, and evaluation. Three considerations justify this unit. First, it is a constraint of the data source rather than a modeling choice: complete manuscripts are not distributed through the corpus interface, and no publicly accessible CSL resource pairs complete low-band essays with examiner scores at a comparable scale. Second, because training, synthesis, and the frozen test set all use the identical unit, every between-configuration comparison in this study is internally consistent; no configuration gains an advantage from a longer or more complete input. Third, the unit choice narrows the measured construct in a documented direction: a 270-character sample carries dense evidence about orthographic, lexical, and syntactic control but limited evidence about essay-level organization and argumentation. All claims in this paper, therefore, concern scoring of local linguistic quality, and the reported examiner scores remain meaningful for this construct because the corpus errors were annotated at the sentence level by trained experts. Extension to full-length essays, where macrostructure and discourse contribute additional score variance, is an external validity question that the present design cannot answer and is listed among the study’s limitations (Section 5.6).
After excluding units without a valid score in [ 40 , 95 ] or shorter than 150 characters, 10,067 samples remain. Scores lie on a five-point lattice with 12 observed levels. We define three analysis bands before model comparison: low (L, 40–59), middle (M, 60–79), and high (H, 80–95). The boundary at 60 is used to summarize lower-tail detection and corresponds to the transition between the prespecified L and M bands; it is not asserted to be an official pass/fail standard for the historical HSK writing component. L contains 756 samples (7.5%), compared with 6880 in M and 2431 in H (Figure 1). We freeze a tail-enriched, stratified test set of 800 samples (L200/M400/H200) and a development set of 400; the remaining 8867 form the training pool (L496/M6240/H2131). The enriched test set provides 200 below-60 cases for tail analysis, but its 25% low-band prevalence is not the operational corpus prevalence; overall test metrics in this paper refer to this frozen evaluation design.
The corpus is publicly searchable, but it is not an openly licensed dataset. Its official copyright notice requires source attribution, restricts commercial use without permission, and limits automated downloads. We therefore report aggregate analyses without redistributing the source texts or corpus-derived text fields. This distinction also governs the availability conditions reported in the Data Availability Statement.

3.2. Empirical Error Profiles

The parser maps the corpus annotations into 18 reporting fields. Fourteen categories have sufficient single-error exemplars to form the injection whitelist: six common character categories (wrong, illegible, missing, redundant, traditional, and variant forms); pinyin substitution; three word categories (misuse, omission, redundancy); syntactic error; and three punctuation categories. Thirteen prevalent categories are used in the error-profile distribution audit; the rare variant-form category is retained for generation but excluded from that descriptive comparison.
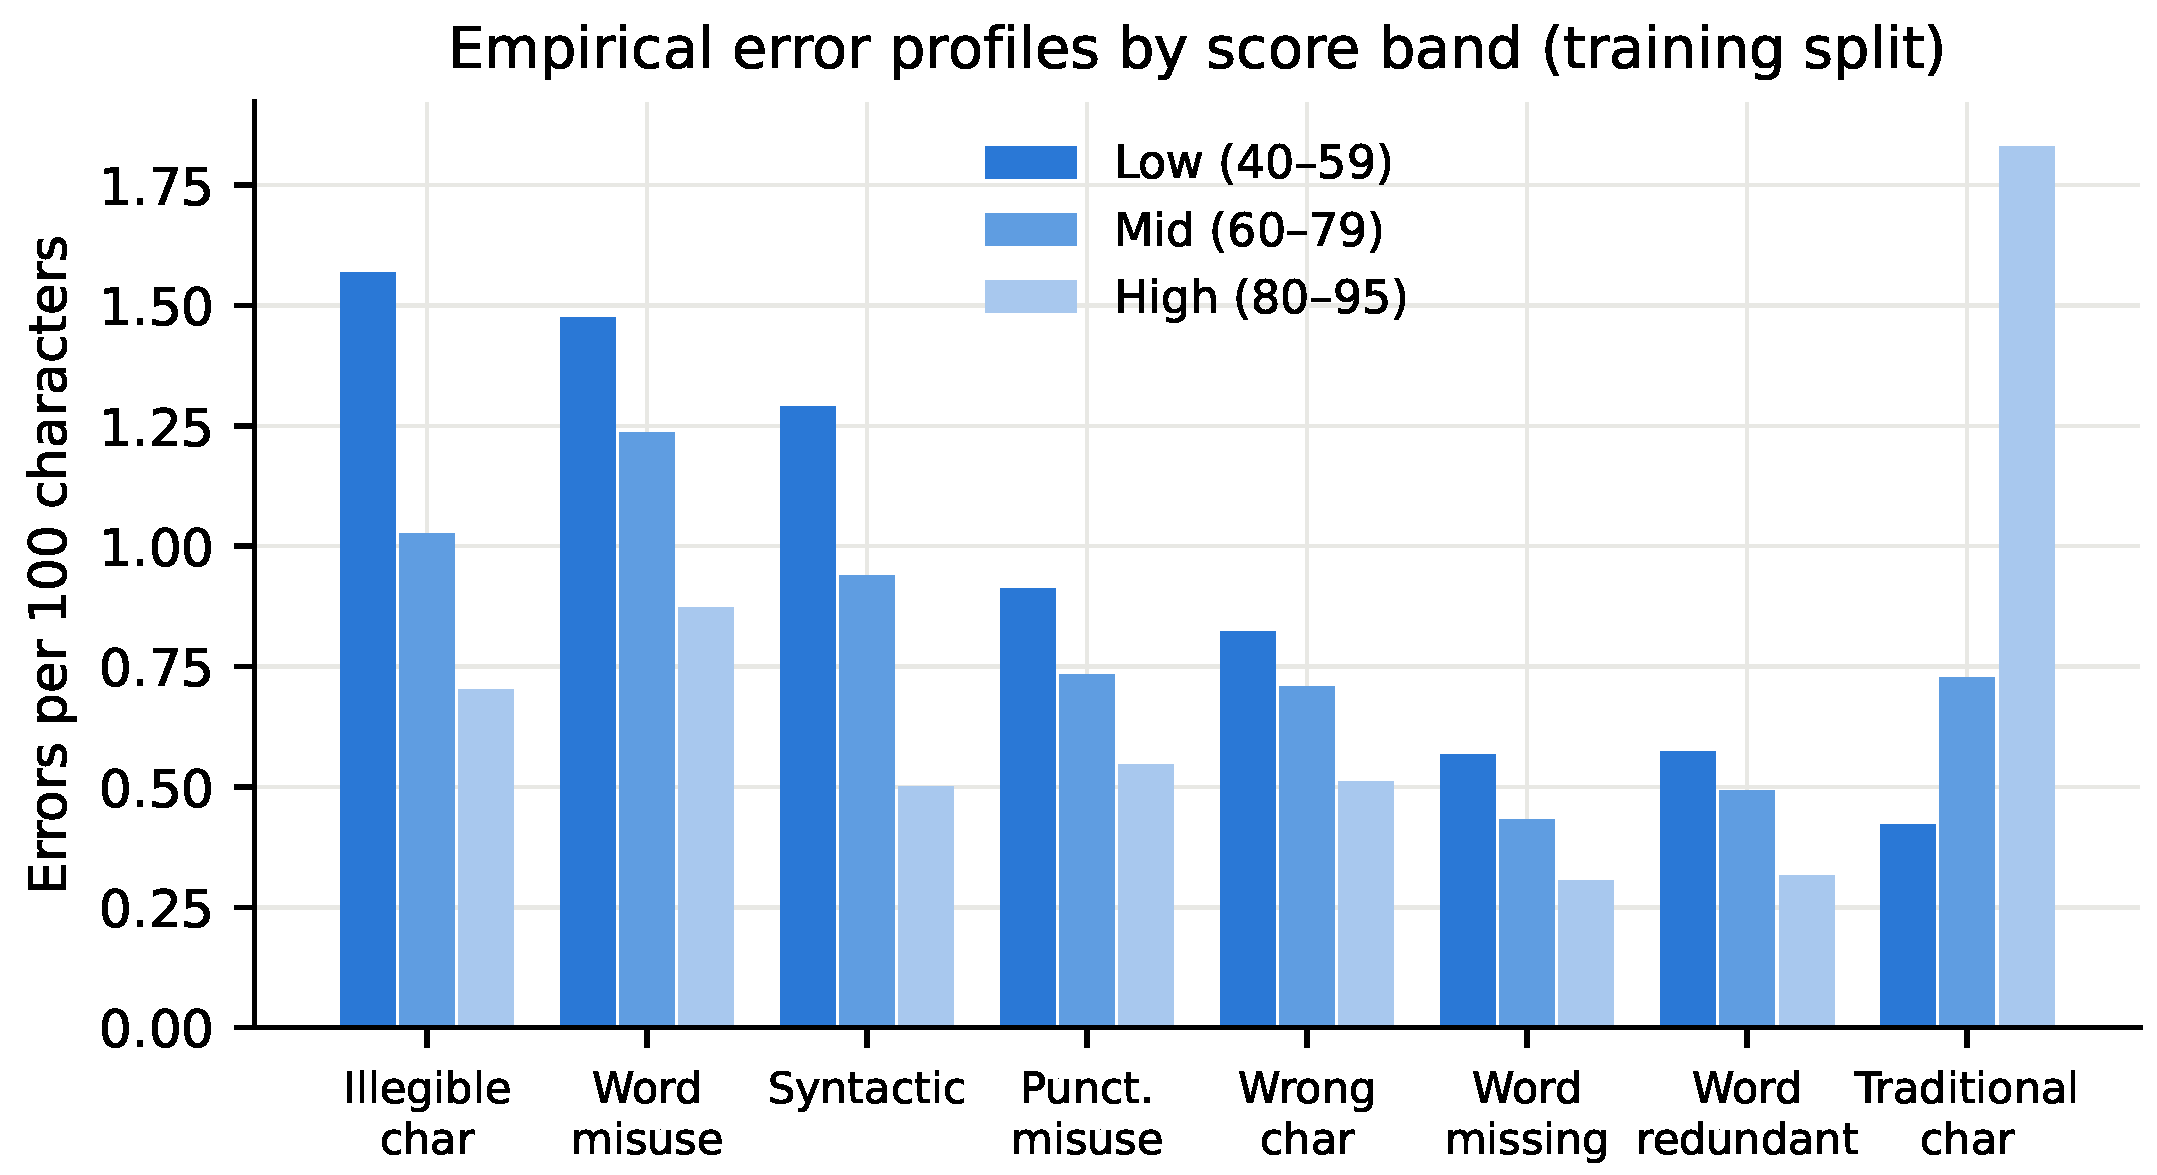
Profiles are computed from the training split only. Figure 2 shows selected densities. Low-band writing has 2.2× the illegible-character density, 2.6× the syntactic-error density, and 6–9× the pinyin-substitution and foreign-word densities of high-band writing. Equally important are counterintuitive patterns. Traditional-character annotations are more common in the high band, reflecting candidates from traditional-script regions rather than lower proficiency. Low-band sentences are also not shorter than mid-band sentences (32.6 versus 31.4 characters per sentence; per-sample means averaged across samples). These observations motivated the calibrated content rules in v3.
We additionally extract 5462 training-split sentences containing exactly one annotated error. Each is stored as a category, erroneous form, and corrected form and supplies authentic few-shot demonstrations during synthesis. Categories without adequate single-error exemplars are not injected even if they remain in the descriptive corpus profile.

3.3. Research Design and Central-Tendency Bias

The real-only MacBERT baseline achieves QWK 0.543 on the enriched test set but over-scores the low band by + 14.02 points, recalls only 0.112 of below-60 responses and has a prediction-on-score slope of 0.443 . Under 10% retention, the unweighted model recalls only 0.014 . These numbers motivate a tail-targeted evaluation: QWK alone does not reveal whether a model can make the below-60 distinction at the prespecified analytic boundary.

3.4. Error-Profile-Conditioned Synthesis (EPCS)

EPCS synthesizes low-band writing samples in four stages.
Step 1: Profile donation. A donor is sampled from the available real low-band training set. Its full injectable error-count vector { n c } becomes the synthetic budget, its length becomes the target length, and its examiner score becomes the candidate label. Under simulated scarcity, the donor pool is restricted to the retained low-band subset. Donation preserves per-sample co-occurrence patterns that would be lost if categories were independently sampled from band averages.
Step 2: Substrate selection. The substrate is the expert-corrected version of a mid-band training sample whose length lies within ± 30 % of the donor length. Corrected text avoids double-injecting annotated errors; a corpus substrate retains authentic topic and discourse material that free generation may not reproduce. The design also creates the central label approximation: the content originates from a mid-band response, whereas the error profile and label originate from a low-band donor.
Step 3: Budgeted injection with authentic exemplars. The generator receives the substrate, the per-category budget, and up to two single-error exemplars for every requested category. It returns rewritten text and a manifest of ( category , before , after ) records restricted to the whitelist. In v3 the prompt additionally requests lexical impoverishment, reuse of basic vocabulary, preservation of the substrate’s sentence-boundary rhythm, and compression toward the donor length. These rules follow the measured TTR, sentence length, and length distribution rather than an assumed “beginner” style.
Step 4: Verify–repair and label transfer. The online verifier checks manifest counts against the budget with tolerance ± 1 per requested category, checks output length, and attempts to locate declared after-spans. Violations trigger up to two repair rounds. A local re-verifier normalizes whitespace, accepts an exact match or a matching five-character window, requires at least 80% of manifest entries to be locatable, and records whether before-spans occur in the substrate. These checks verify manifest consistency, not independently annotated linguistic correctness; this distinction is preserved in our claims. Accepted samples inherit the donor’s real examiner score. The procedure avoids LLM self-labeling but assumes that the transferred profile is sufficiently diagnostic of low proficiency.
Method versions.
Version 1 injects surface errors only. Version 2 adds intuition-driven vocabulary downgrading, sentence simplification, and compression. Version 3 replaces the sentence-simplification heuristic with empirical calibration: preserve the observed sentence rhythm, reduce lexical variety without naming target function words, and match donor length. The versions form an audit trail, not an assumed monotone improvement sequence.
Executable sampling logic. The implementation fixes the synthesis RNG to 42 and executes the following record for sample i: sample donor d i uniformly from the retained Train-L pool; retain every whitelisted category with donor count n c > 0 and an available exemplar; form the candidate set of corrected Train-M substrates whose original length lies in [ 0.7 , 1.3 ] times the donor length; sample one substrate s i uniformly; draw at most two single-error demonstrations per requested category; call the generator; verify the returned text and manifest; repair at most twice; and, if accepted, emit ( x i , M i , y i ) = ( rewritten text , manifest , donor score ) . The 14 injectable codes map to wrong, illegible, missing, redundant, traditional, and variant characters; pinyin substitution; word misuse, omission, and redundancy; syntactic error; and punctuation misuse, omission, and redundancy. This mapping, the donor and substrate identifiers, target counts, output text, manifest, verifier status, and repair count are stored for every attempted sample.
Prompt and generation record. The operative Chinese prompt template, translated here, was: “Rewrite the corrected substrate as plausible low-proficiency Chinese; for each listed category inject exactly n c errors using the supplied correct-to-error demonstrations; distribute the changes; apply the version-specific content rules; and return JSON with a text field and an injections list of cat/before/after records.” v3 further required at least five advanced expressions to be replaced by common vocabulary, preservation of the substrate’s sentence-final boundaries, compression toward donor length, and no deliberate increase in named function words. Generation runs were made in August 2026 through the OpenAI chat-completions endpoint with model identifier gpt-5.6-luna; the generator-change batch used qwen/qwen3-max through OpenRouter. Requests allowed 8000 completion tokens and specified temperature 0.7. When supported by the endpoint (otherwise the unsupported field was omitted and the request retried). Generation and repair used the same model settings; no separate LLM judge was used. Each initial call and repair was logged, yielding approximately 15,000 LLM calls over all version, scarcity, and dose batches.
Representative accepted record. Sample epcs_v3_0001 inherited a score of 50 from its donor and rewrote a score-75 corrected substrate. Its target profile contained two wrong-character, two illegible-character, two word-misuse, and two syntactic errors. One repair produced a 207-character output for a 196-character donor target; all eight manifest after-spans were locatable, and seven of eight before-spans matched the substrate. This case illustrates what the verifier certifies—budget and span consistency—without treating the record as an independent linguistic rating.

3.5. Synthetic Data Fidelity Audit

We compare each synthetic batch with real low-band training text at three levels. First, the 23 surface features are text length; mean and SD of sentence length; character and character-bigram TTR; rates per 100 characters of the illegible-character placeholder, all punctuation, commas, and Latin letters; and 14 character-level high-frequency markers (de, le, zai, shi, bu, wo, ta, men, zhe, jiu, dou, ye, hen, you). For each feature we report a two-sample K–S test. The number with raw p > 0.05 is a descriptive no-difference count, not evidence of equivalence and not corrected for multiple testing. Second, logistic regression and gradient boosting discriminators classify real versus synthetic feature vectors under stratified five-fold cross-validation. Third, the batches are used in the fixed downstream scoring pipeline.

3.6. Experimental Conditions and Statistical Analysis

Scorer and training. All configurations fine-tune MacBERT-base [20] with a regression head. Scores are z-normalized within each training configuration; the objective is MSE, maximum length is 256, and batch size is 32. All reported fine-tuning runs use an NVIDIA RTX 5090 with CUDA bfloat16 autocasting. The optimizer is AdamW with learning rate 2 × 10 5 and ( β 1 , β 2 ) = ( 0.9 , 0.999 ) , epsilon 10 8 , and weight decay 0.01. A linear scheduler uses 10% warm-up; gradients are clipped at norm 1.0, and training runs for at most eight epochs with early stopping after two epochs without improvement in development QWK. We report seeds { 1 , 2 , 3 , 4 , 42 } except for the v1 full-data joint row, for which three runs are available. The retained scarcity subset is fixed with RNG 1234 across training seeds.
Configurations. The evaluated configurations are real only: random oversampling of retained low-band samples; inverse-frequency reweighting; naive role-play synthesis; EPCS without reweighting; and EPCS v1/v2/v3 combined with reweighting. To hold augmentation volume constant across versions and scarcity conditions, the main comparisons add N = 490 samples; larger amounts are examined only in the dose analysis.
Weighting objective. For a retained real training set with N r samples and band count n b , the loss weight is
w b = N r 3 n b .
Weights are computed before augmentation, and a synthetic sample receives the weight of its inherited label band. The implementation averages w b ( y ^ y ) 2 over the batch rather than normalizing by the sum of weights. Consequently, the joint configuration changes both textual support and effective loss mass. With 490 synthetic low-band samples, the low band accounts for 49.8%, 71.2%, and 84.6% of total nominal weighted loss mass at 100%, 25%, and 10% retention, respectively. We therefore describe comparisons with reweighting as the behavior of a joint intervention, not a factorial proof that synthesis and weighting are independently complementary.
Scarcity gradient. We retain { 100 % , 25 % , 10 % } of the 496 real low-band training samples with a fixed subset across seeds. Integer truncation yields 496, 124, and 49 samples. The donor pool is restricted to the same subset. The exemplar bank and the empirically derived v3 prompt rules remain fixed training-split resources; the scarcity experiment, therefore, simulates loss of scored low-band writing support, not loss of all previously estimated error statistics.
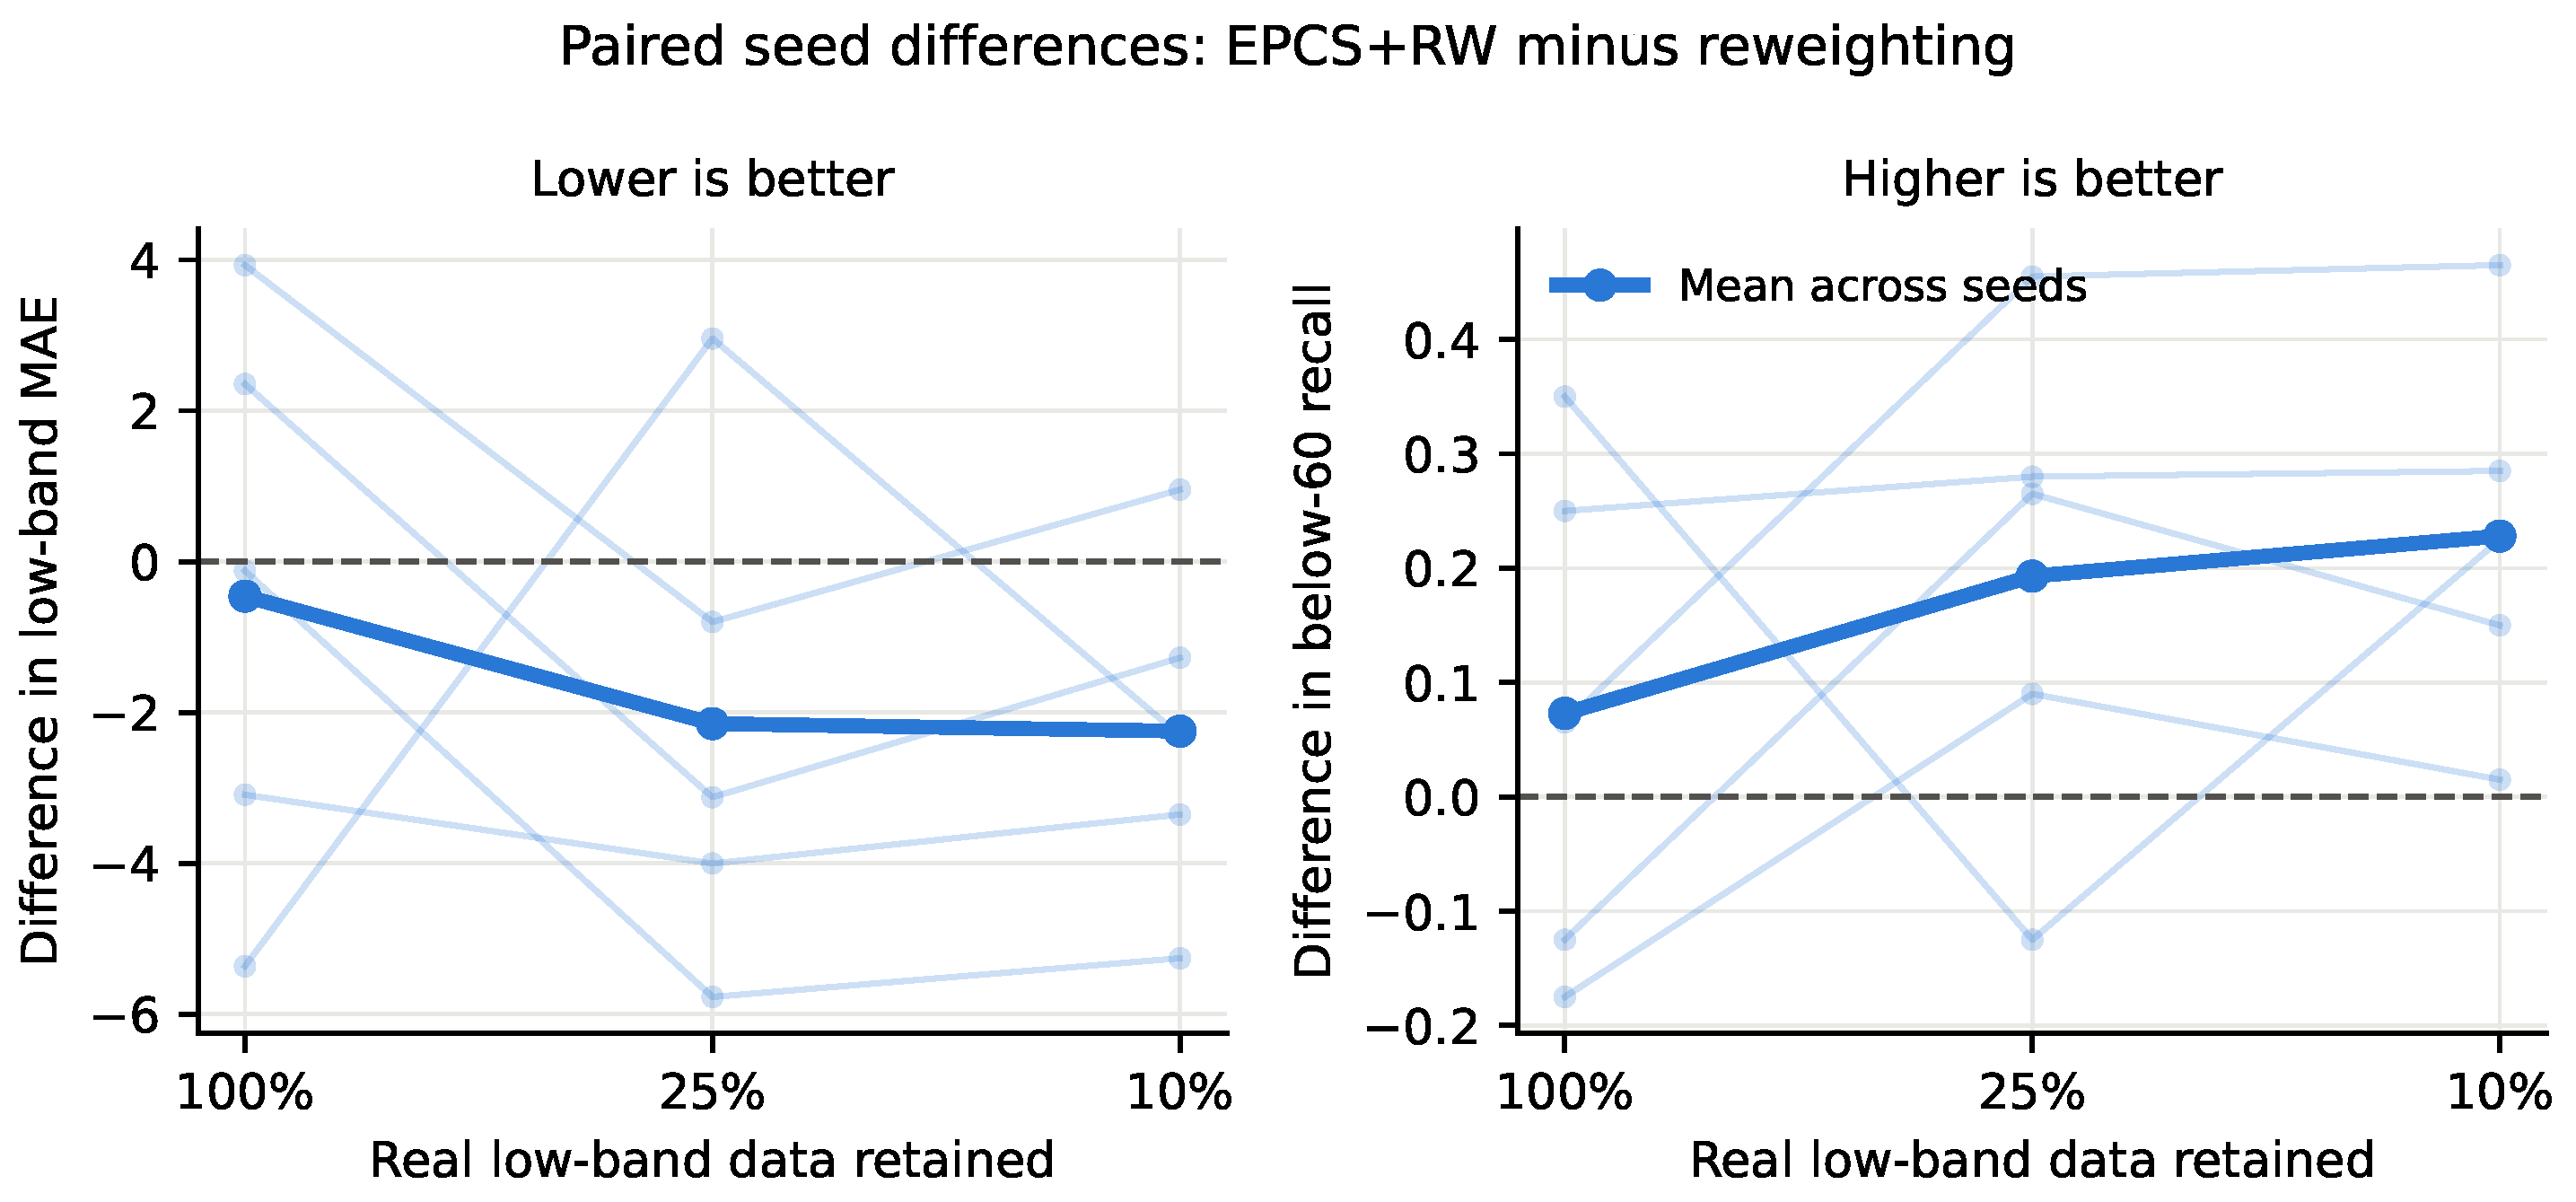
Metrics and result provenance. Overall metrics are QWK on the 12-level lattice, following the weighted-kappa framework of Cohen [37], Spearman correlation, and MAE. Tail metrics are low-band MAE and signed bias, below-60 precision, recall, F1, false-positive rate, and the prediction-on-score slope β . Paired bootstrap intervals [38] resample test items 2000 times and average the metric over the observed training runs. Resampling is paired by test-item index, uses RNG 42, and reports the 2.5th and 97.5th percentiles and computes a two-sided sign-based p value as twice the smaller bootstrap tail proportion. The intervals are conditional on the observed runs and do not model training-seed uncertainty. Per-run predictions retain essay identifier, band, true score, and predicted score; Figure 3 displays all five paired seed trajectories rather than only their mean. The analysis matrix contains 138 unique final configuration–seed results, each aligned with its retained per-item prediction file.


4. Results

4.1. Fidelity and Downstream Utility

This subsection addresses RQ1 by comparing measured fidelity with downstream transfer. Table 1 shows that the rankings do not coincide.
The naive generation is exposed by missing illegible-character placeholders, overuse of the intensifier “hen”, and inflated comma density. Version 1 best matches the measured feature space. Content degradation moves v2 and v3 away from that space, even as it makes the samples more useful downstream. Thus, the audit does not identify a single fidelity winner; it identifies a disagreement between what the hand-engineered features measure and what the scoring encoder learns from text.

4.2. Incremental Effects Under Tail Scarcity

This subsection addresses RQ2 by comparing the joint EPCS+RW configurations with reweighting alone as real low-band support decreases.
  • Full-data pattern.
Table 2 reports the full-data comparison with all 496 real low-band training samples retained.
Three observations qualify the full-data claim. First, adding v3 EPCS data without reweighting changes little (recall 0.122 versus 0.112), as does naive synthesis. Second, reweighting is the strongest inexpensive intervention. Third, the joint v2 and v3 configurations improve tail metrics, but Version 3’s advantage over reweighting is small and seed-sensitive: it improves low-band MAE and recall in only three of five paired seeds. The paired item bootstrap for v3 versus reweighting gives low-band MAE 0.47 (95% CI [ 0.77 , 0.17 ] , p = 0.003) and recall +0.074 (CI [+0.043, +0.105], p < 0.001), but these intervals are conditional on the five observed training runs. Version 2 has the best full-data point estimates. The method versions should therefore be read as a fidelity–utility trade-off, not a monotone progression. Table 3 reports rank correlation and band-wise error for the same runs: Spearman ρ varies little across configurations (0.612–0.653) and overall MAE improves only slightly (8.38 to 7.81 points), whereas the low-band gain is accompanied by a rise in high-band MAE from 6.75 to 8.43–8.48 points.
  • Scarcity gradient.
Table 4 compares reweighting with the two content-degraded versions at the three levels of retained real low-band support.
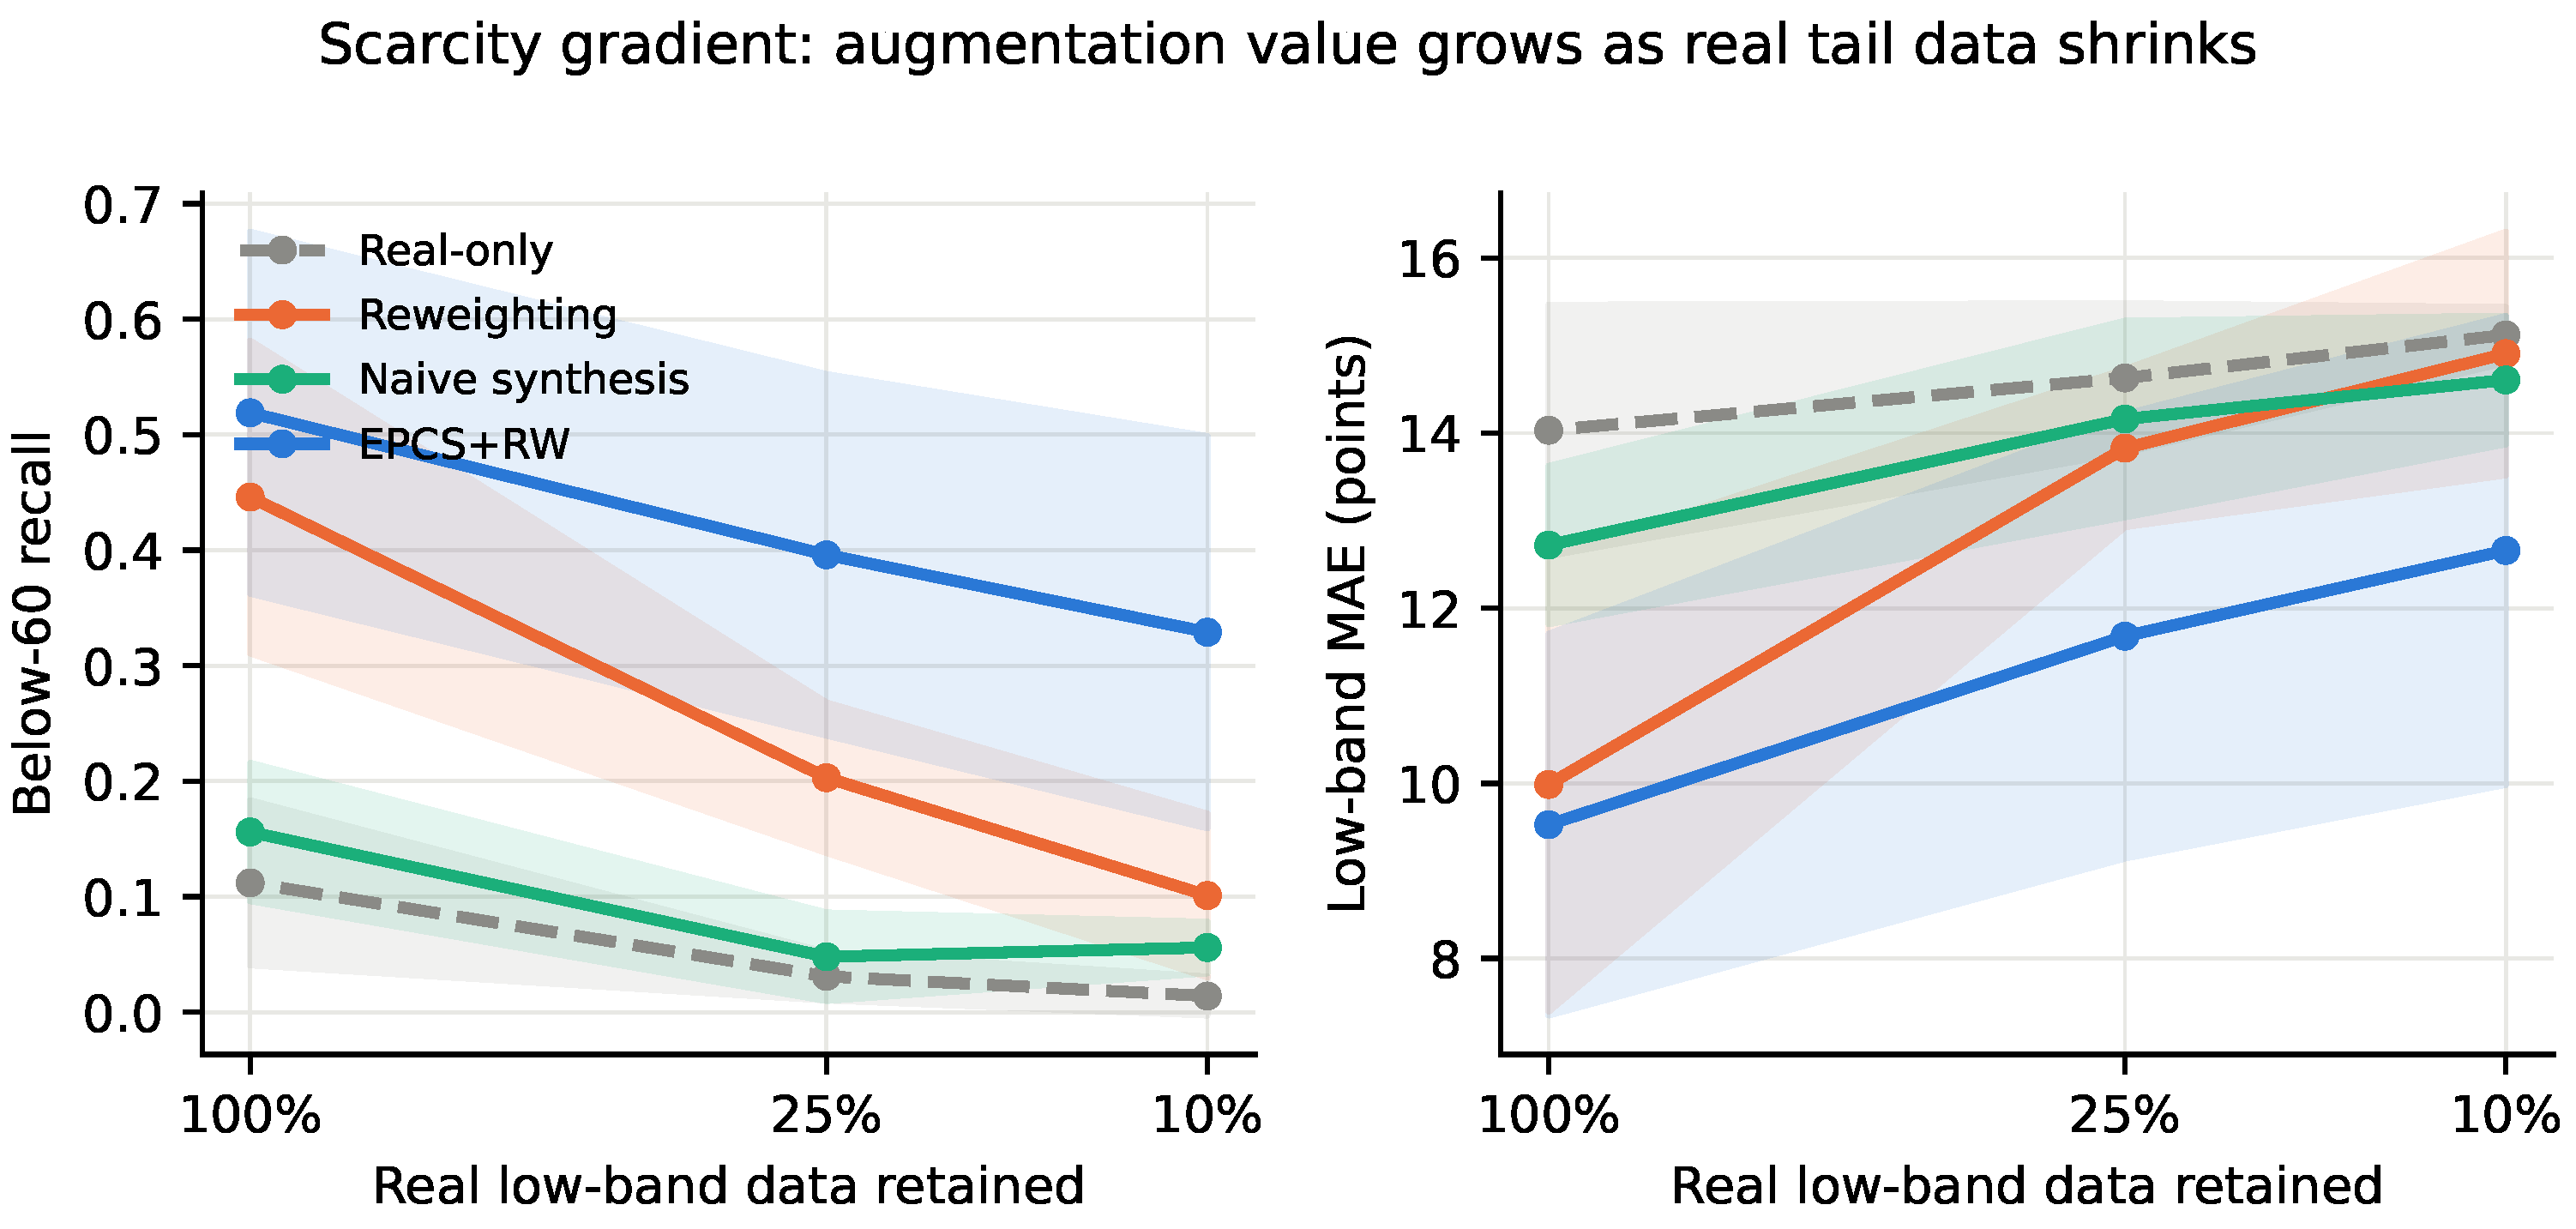
The central pattern is not a universal gain but a larger mean tail benefit under scarcity. Relative to reweighting, v3 improves both low-band MAE and recall in 3/5 seeds at full data and 4/5 seeds at both 25% and 10% retention (Figure 3); at 10%, recall improves in all five seeds while one seed worsens on low-band MAE. The mean low-band MAE difference changes from 0.46 to 2.15 to 2.25 points, and the recall difference from +0.073 to +0 . 193 to +0.228 (Figure 4). Item-bootstrap tests for the latter two scarcity levels yield p < 0.001. Thus, the mean effects are larger than at full data but do not increase monotonically from 25% to 10%, and seed dependence remains. QWK point estimates remain close, but no formal equivalence margin was preregistered, so we describe aggregate agreement as similar rather than statistically equivalent.
The v2/v3 ordering also depends on scarcity. Version 2 is more aggressive at full and 25% data and achieves higher recall there. At 10%, v3 has a modest mean advantage over v2 in low-band MAE (0.31 points) and recall (0.055), but improves both metrics in only two of five paired seeds. Empirical calibration therefore does not make v3 uniformly superior even in the smallest-support regime.

4.3. Below-Threshold and Score-Range Trade-Offs

To address RQ3, tail recall is interpreted together with false alarms and score-conditional error. Table 5 reports the 10% regime, where the tail gain is most stable. Reweighting is extremely conservative: it predicts below 60 for only 3.6% of the tail-enriched test set, yielding high precision but missing nine of ten true below-60 responses. Version 3 predicts below 60 for 16.2%, raising recall and F1 but also the false-positive rate. Thus the result is not a free accuracy gain; it is a move to a less conservative and more balanced decision point.
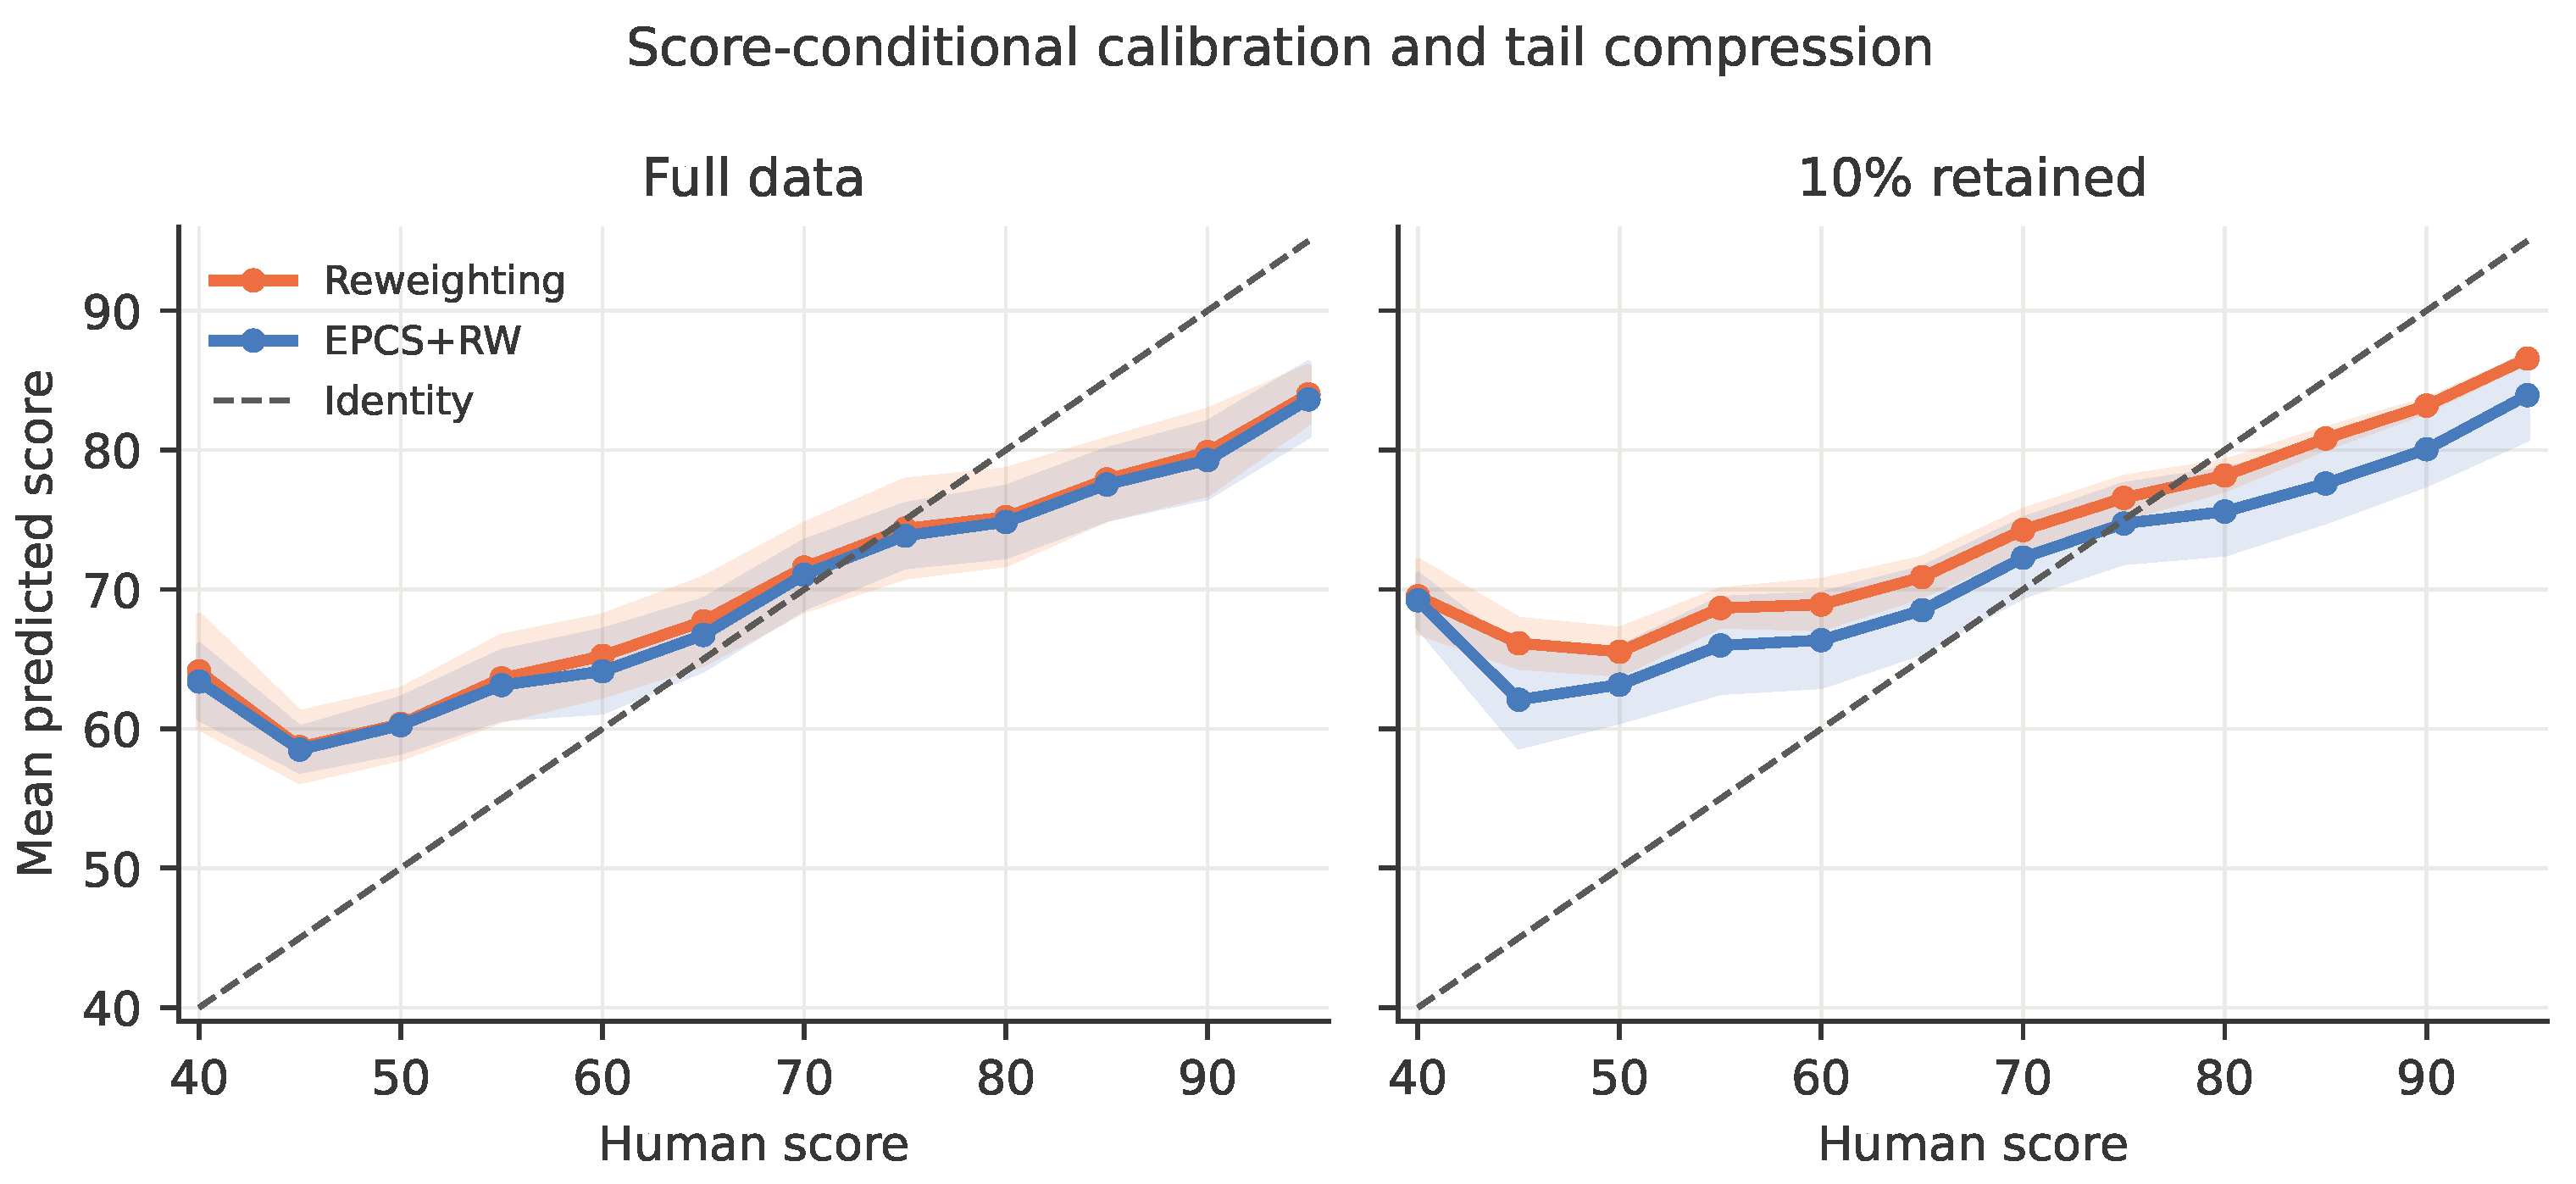
Score-conditional predictions clarify the trade-off (Figure 5). At 10% retention, v3 lowers the mean prediction relative to reweighting from 66.13 to 62.09 for true score 45, from 65.53 to 63.17 for score 50, and from 68.67 to 65.98 for score 55. It nevertheless continues to over-score the low tail substantially. The same downward shift also affects the upper range: at true scores 90 and 95, means fall from 83.18/86.56 to 80.05/83.93. Low-band recovery therefore coexists with greater high-band under-scoring and a slope that remains far below one.

4.4. Donor Support, Dose, and Generator Sensitivity

To address RQ4, we examine donor reuse, synthetic dose, and one generator change. The 490-sample v3 training prefix uses 310 unique donors at full data, 123 at 25%, and all 49 retained donors at 10%. Median reuse rises from one to four to ten synthetic samples per donor (maximum 15 in the 10% batch), while the number of unique substrates remains 456–470. More importantly, the 10% synthetic labels contain 39 samples at score 45, 152 at 50, and 299 at 55, but none at 40 because the retained donor subset contains no 40-point response. EPCS therefore densifies observed low-score support; it cannot create a score level absent from the donor pool. This helps explain why the extreme 40-point test cases remain strongly over-scored, although that test cell is small ( n = 4 ).
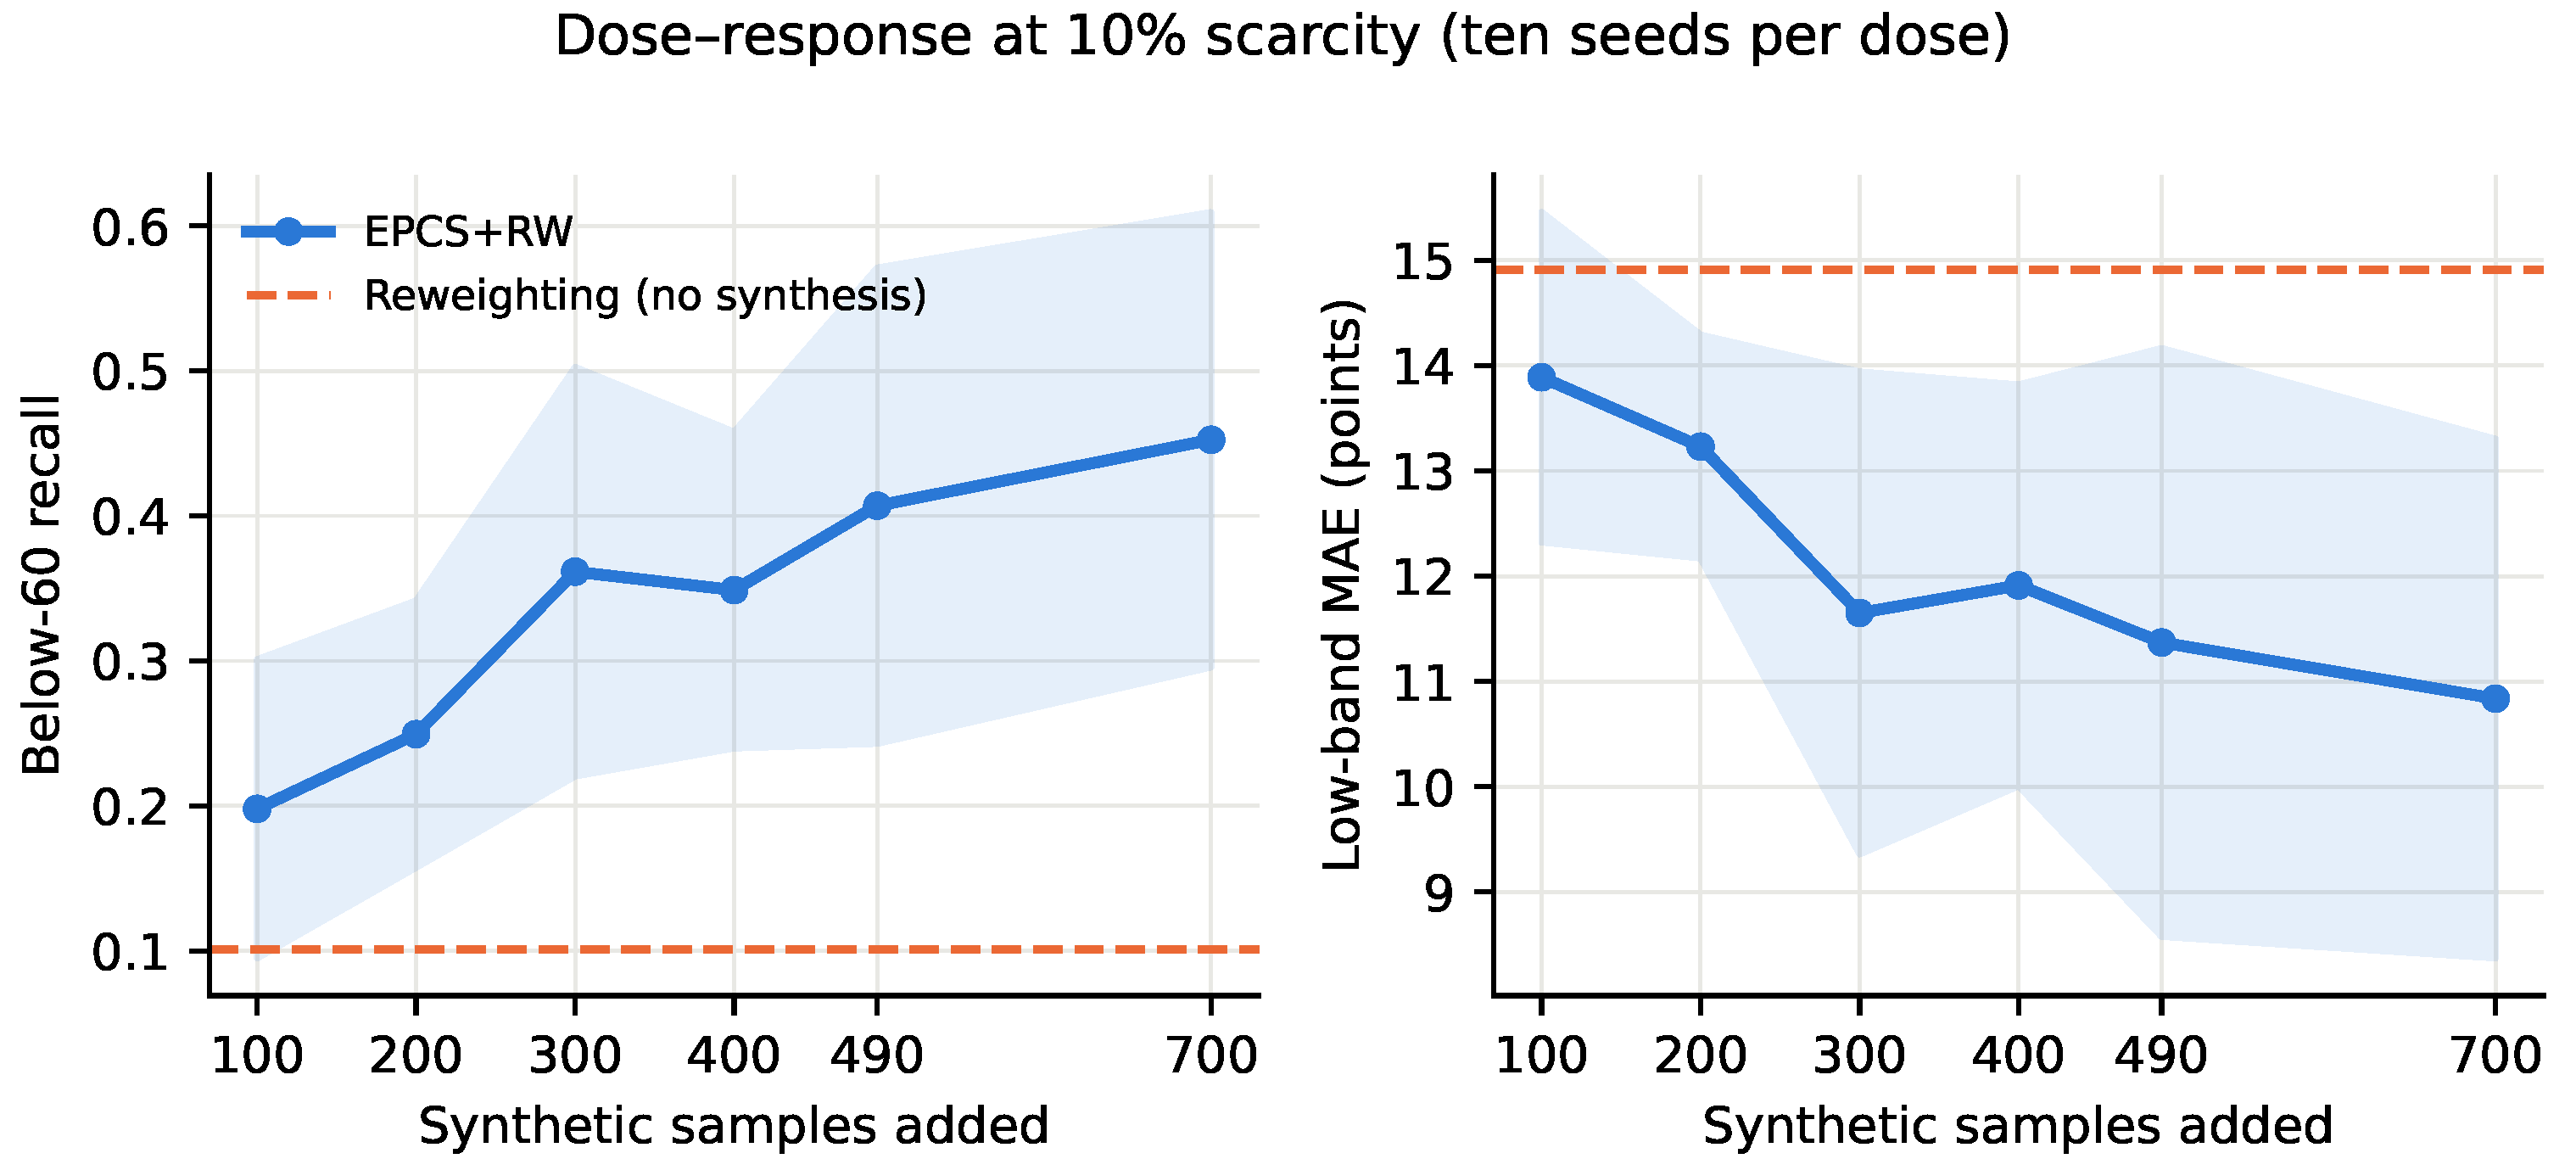
An apparently non-monotone dose–response in an initial five-seed analysis motivated a stability check with five additional training seeds, giving ten seeds per dose. Over ten seeds, the response is broadly increasing with diminishing returns: mean recall rises from 0.198 ± 0.103 (100 samples) through 0.249 ± 0.092 (200), 0.361 ± 0.141 (300), 0.349 ± 0.109 (400), and 0.407 ± 0.164 (490) to 0.453 ± 0.157 (700), while low-band MAE falls from 13.89 to 10.84 (Figure 6). The 490-sample point is the ten-seed mean of the configuration reported at five seeds in Table 4, which is why the two values differ. Adjacent-dose differences above 300 samples are small relative to cross-seed variability, and dose orderings reverse between disjoint seed groups (for example, 400 versus 490 samples). The dips seen with five seeds are therefore attributable to optimization variance rather than a reproducible dose effect. Practically, roughly 300 synthetic samples—about six times the retained real tail in this regime—reach the plateau region, and no degradation is observed up to 700 samples.
Regenerating the 10% batch with qwen/qwen3-max instead of gpt-5.6-luna, while holding donors and protocol fixed, yields recall 0.481 ± 0.125, low-band MAE 10.43 ± 2.01, and QWK 0.509 ± 0.005. The second generator thus reproduces the direction of tail recovery despite stylistic differences. With only two generators, the evidence supports replication across one generator change, not generator independence in general.

4.5. Cross-Architecture and Label-Perturbation Checks

Two further checks probe whether the central findings are artifacts of the MacBERT encoder or of the score-inheritance approximation.
Scorer architectures. We replicated the core comparison—real only, reweighting, and v3 EPCS+RW—on two additional pretrained encoders under the identical protocol (five seeds each), and on a non-neural scorer: a gradient-boosted regression tree (GBDT) over the same 23 surface features used in the fidelity audit (a deterministic fit, reported without seed variation). Table 6 summarizes the low-band results.
The scarcity-conditioned pattern reproduces on every architecture. At full data, the gain over reweighting is negligible for BERT (recall 0.464 versus 0.462) and modest for MacBERT (0.446 to 0.519), whereas RoBERTa-wwm gains more (0.329 to 0.444); for every architecture, however, the gain is larger at 10% retention. At 10% retention, the joint configuration improves both low-band MAE and recall in five of five paired seeds for BERT and four of five for RoBERTa, and the false-positive rate rises in the same way as for MacBERT (BERT: 0.018 to 0.138; RoBERTa: 0.023 to 0.110). The feature-based GBDT scorer is weaker overall, as expected, yet shows the same direction, indicating that the effect is not produced by the pretrained encoder itself. The full version ablation and fidelity audit were not repeated across architectures; the replication covers the core comparison only.
Label-perturbation stress test. Score inheritance assumes the donor’s examiner score remains informative for the rewritten content. To bound the consequences of label misspecification, we retrained the 10%-retention joint configuration with all inherited synthetic labels shifted by 5 points, by + 5 points (the direction implied by the concern that mid-band substrate content may deserve a higher score), and randomly by ± 5 points per sample (one lattice step; five seeds each). Table 7 reports the resulting tail metrics.
The qualitative conclusion survives all three perturbations: every perturbed configuration retains higher below-60 recall and lower low-band MAE than reweighting alone. A downward shift changes little. The upward shift is the most consequential, and its mechanism is structural: 299 of the 490 inherited labels sit at score 55, so a + 5 shift moves them across the 60-point boundary, shrinking the synthetic low-band support and its loss weight. Even under this worst-case assumption about label validity, recall remains roughly twice that of reweighting (0.195 versus 0.101) with a milder operating-point shift (FPR 0.030). The stress test thus bounds, rather than eliminates, the score-inheritance approximation: tail recovery degrades gracefully with label misspecification instead of depending on exact label correctness.

5. Discussion

The results answer the research questions with a conditional, rather than uniform, account of synthetic tail augmentation.

5.1. Fidelity Does Not Guarantee Downstream Utility

Addressing RQ1, the fidelity and utility rankings diverged: v1 was the least detectable EPCS batch in the measured surface space but transferred least effectively, whereas the content- degraded versions were easier to detect and more useful for lower-tail prediction. This finding is consistent with synthetic-data reviews that separate distributional resemblance from task utility [10,28]. It also extends classifier two-sample auditing [35]: low detectability under a chosen feature representation is not evidence that all score-relevant properties have been preserved. Realism remains important, but the evidence supports a layered audit rather than selection by a single fidelity statistic.

5.2. Synthetic Augmentation Helps Mainly Under Tail Scarcity

Addressing RQ2, the incremental benefit of the v3 joint configuration was smallest and seed-sensitive when all 496 real low-band samples were retained, but its mean low-band advantage over reweighting increased as real support decreased. At 10% retention, below-60 recall improved in all five paired seeds and low- band MAE in four. This pattern accords with the central distinction in imbalanced regression: loss weighting can increase the influence of rare observations, whereas augmentation can add variation around observed support [24,26]. It also qualifies recent AES augmentation findings that are sensitive to sample size and generation design [7,8]. The present evidence does not show that synthesis is generally superior to reweighting; it identifies a scarcity regime in which the tested joint configuration changes lower-tail behavior more consistently. The scarcity-conditioned pattern is moreover not an artifact of one network: it reproduces on classical BERT, on RoBERTa-wwm, and on a feature-based GBDT scorer under the identical protocol (Section 4.5).

5.3. Tail Recovery Changes the Decision Operating Point

RQ3 makes the practical meaning of that change explicit. At 10% retention, v3+RW moved the model away from a highly conservative below-60 operating point: recall rose, but precision and specificity fell and high-band under-scoring increased. From a validity perspective, this is not a free accuracy gain. Automated-scoring evaluations require the intended decision and the relative costs of false-negative and false-positive classifications to be specified [1,2,3]. Because 60 is an analytic boundary rather than a verified official pass mark, the reported classification metrics are best interpreted as a diagnostic of score-range sensitivity. They do not establish that EPCS improves an actual HSK certification decision.
Whether the observed cost—a false-positive rate rising from 0.015 to 0.106—is acceptable depends on the intended use, and the two principal use cases point in opposite directions. In a screening configuration, where a below-60 prediction routes the response to human re-scoring rather than issuing a final grade, the cost of a false positive is one additional human rating, while the cost of a false negative is an undetected low-proficiency response; under 10% retention, reweighting alone misses nine of ten true below-60 responses, so the trade is plausibly worthwhile. In a fully automated certification configuration, a false positive directly assigns an undeservedly failing decision to a competent examinee; we consider the observed false-positive rate too high for unsupervised use of the below-60 signal in that setting, and we would not recommend deploying the augmented model there without human verification of below-threshold decisions. Two further qualifications apply. First, the reported rates are computed on the tail-enriched test set (25% low-band prevalence); at the corpus prevalence of 7.5%, the same recall and false-positive rate imply that roughly one in five below-60 flags would be a true positive, which reinforces the screening interpretation. Second, the operating point is tunable: the decision threshold need not equal the analytic boundary, and assessment designers can trade recall against false alarms along the score-conditional curves in Figure 5 to match their own error costs.

5.4. Donor Conditioning Provides Support but Not Extrapolation

Addressing RQ4, dose effects showed no reproducible non-monotonicity once seed variance was accounted for over ten seeds; a second generator reproduced the direction of tail recovery; and donor conditioning imposed a clear support boundary. Reusing 49 donors with many substrates introduced lexical and topical variation, but could not create evidence for a 40-point score when the retained donor set contained no such response. Score inheritance, therefore, avoids LLM self-labeling while remaining an approximation because the generated text is anchored by the donor profile rather than an independent rating. This distinction is particularly consequential for low-proficiency L2 writing, where construct coverage and atypical error patterns already challenge automated scoring [4]. Accordingly, the results support score-conditioned augmentation within observed donor support, not equivalence between transferred and independently assigned scores.
The support boundary should be read as a designed scope condition rather than an incidental failure. EPCS anchors every synthetic sample to an empirical donor profile and a real examiner score precisely so that no synthetic label is asserted without observed evidence; generating a 40-point sample from a donor pool that contains no 40-point response would require the generator to invent an error profile and a score with no empirical anchor, which is the unconstrained role-play failure mode the method was built to avoid. Densification within observed support is also where the practical value lies: the scarcity experiments show that the dominant failure at 10% retention is not the absence of a score level but the collapse of detection across the entire observed low band, and that failure is what donor-conditioned augmentation mitigates. Where a score level is genuinely absent, the appropriate remedy is data-side, not generation-side: collecting even a small number of authentic responses at the missing level would immediately extend the donor pool, and the per-donor design means each new donor contributes its full profile, length, and score to subsequent synthesis.

5.5. Implications for Automated Writing Assessment

Taken together, the findings position synthetic tail augmentation as a choice about measurement design and error costs rather than a generic route to higher accuracy. Researchers should report score-conditional behavior, compare augmentation with cost-sensitive baselines, and state the intended use of any below-threshold classification. For operational use, the preferred model would depend on whether missed low-score responses or false alarms carry the greater consequence; the present study does not determine that policy choice.
Finally, the joint configuration simultaneously expands low-score text support and assigns synthetic samples weights computed before augmentation; its nominal low-band loss share reaches 84.6% in the smallest-support regime. The current design therefore cannot attribute the observed change to synthetic content alone or estimate an augmentation-by-weighting interaction. The defensible claim consequently concerns the documented EPCS+RW training objective, not EPCS as an isolated treatment.

5.6. Limitations

The study has five principal limitations. First, the unit is a roughly 270-character writing sample reconstructed from annotated corpus sentences, not a complete manuscript, and donor-score inheritance is an approximation rather than an independent rating of the generated response. Second, the corpus contains paper-based examinations from 1992 to 2005; the stratified test set enriches the low band, and all 27 test topics occur in training. The design, therefore, addresses within-distribution tail scarcity, not a new topic, new population, or current operational shift. Third, the main experiments use one encoder; the core comparison is replicated on BERT, RoBERTa-wwm, and a feature-based GBDT scorer (Section 4.5), but the version ablation and the fidelity–utility ordering were not repeated across architectures and may depend on MacBERT. Fourth, the surface audit uses uncorrected K–S tests and a 23-feature discriminator, while v3 remains readily distinguishable from real low-band text (AUC approximately 0.9). Fifth, five training seeds per configuration (ten for the dose analysis) limit inference about optimization variability, and the pre-augmentation weighting scheme prevents isolation of synthesis from objective rebalancing. These constraints narrow the claim to the documented corpus, scorer, joint weighting objective, donor support, and within-distribution scarcity simulation.

6. Conclusions

This study investigated whether, and under which conditions, synthetic low-band data can restore lower-tail reliability in Chinese L2 automated essay scoring. We introduced EPCS, a donor-conditioned procedure for synthesizing low-proficiency writing samples from corpus error profiles, authentic single-error exemplars, verified injection manifests, and transferred examiner scores, and we evaluated it with a layered fidelity audit, a controlled scarcity gradient, paired training seeds, and an explicit operating point analysis.
Scientific novelty. To our knowledge, this is the first synthesis framework for learner-writing augmentation that conditions each synthetic sample on the complete per-category error budget of an individual real donor and lets the sample inherit that donor’s examiner score, replacing unconstrained LLM role-play—which our audit showed to be trivially detectable (GBDT AUC 0.970) and of little downstream value—with empirical error-budget injection into expert-corrected substrates (best EPCS version: AUC 0.743). The study further develops the evaluation methodology for synthetic assessment data in two ways: it demonstrates empirically that surface-feature fidelity and downstream utility can rank generator versions in opposite orders, and it shows that the utility of augmentation must be indexed to the amount of real tail support rather than reported as a single number.
Principal quantitative outcomes. Under severe scarcity (49 real low-band training samples, 10% retention), the joint EPCS v3 plus reweighting configuration reduced low-band MAE from 14.91 to 12.66 points and raised below-60 recall from 0.101 to 0.329 relative to inverse-frequency reweighting alone; the recall improvement held in all five paired seeds and the MAE improvement in four, with item-bootstrap p < 0.001. At 25% retention the mean advantages were 2.15 points of low-band MAE and + 0.193 recall (p < 0.001), whereas at full data the advantage shrank to 0.46 points and + 0.073 recall and held in only three of five seeds. Aggregate agreement remained similar throughout (QWK 0.506 versus 0.497 at 10% retention), and the full-data v2 configuration raised the prediction-on-score slope from 0.443 (real-only baseline) to 0.519. The gains were not free: below-60 precision fell from 0.784 to 0.563, and the false-positive rate rose from 0.015 to 0.106 at 10% retention, and a second generator (qwen/qwen3-max) reproduced the direction of tail recovery (recall 0.481 ± 0.125 ) under the same protocol. The scarcity-conditioned pattern further replicated across scorer architectures at 10% retention—classical BERT (recall 0.116 to 0.390), RoBERTa-wwm (0.132 to 0.339), and a feature-based GBDT scorer (0.025 to 0.200)—and survived ± 5 -point perturbation of the inherited labels, with every perturbed configuration retaining better tail detection than reweighting alone.
Practical significance. For AES developers and assessment designers, the results translate into three concrete recommendations. First, treat synthetic tail augmentation as a scarcity-conditioned intervention: when several hundred real low-band samples are available, inverse-frequency reweighting captures most of the achievable tail improvement at no generation cost; augmentation earns its cost as real tail support falls toward tens of samples, and a synthetic dose of roughly six times the retained real tail reached the benefit plateau in this setting. Second, choose the operating point deliberately: the augmented model is suited to screening configurations in which a below-threshold flag routes a response to human re-scoring and is not recommended for unsupervised certification decisions at the observed false-positive rate, particularly after correcting reported rates to operational tail prevalence. Third, audit synthetic data at more than one level: selecting a generator by surface indistinguishability alone would have chosen the version with the weakest downstream transfer in this study.
Limitations and future research. The study’s boundaries are stated in Section 5.6: a 270-character writing-sample unit rather than complete essays, a 1992–2005 examination corpus, donor-score inheritance as a modeling approximation, a single downstream encoder family for the main experiments, and a joint augmentation–weighting objective that precludes factorial attribution. These boundaries map directly onto future work: validating the framework on other non-native target languages and on full-length essays; resolving the score-extrapolation constraint by targeted collection of authentic responses at missing score levels rather than by unanchored generation; extending the architecture replication to LLM-as-a-judge scoring; obtaining independent human ratings of synthetic samples to complement the label-perturbation bound on the score-inheritance approximation; and developing prompt-free error injection mechanisms—for example, tagged-corruption or edit-based generators trained on the exemplar bank—to remove residual prompt-induced artifacts such as the function-word overuse observed in v3.

Author Contributions

Conceptualization, D.L. and X.T.; methodology, D.L.; software, D.L.; validation, X.T.; resources, X.T.; data curation, D.L. and X.T.; writing—original draft preparation, D.L.; writing—review and editing, X.T.; supervision, D.L.; funding acquisition, X.T. All authors have read and agreed to the published version of the manuscript.

Funding

This research was supported by the University of Science and Technology Beijing General Project for Undergraduate Education and Teaching Reform (No. JG2024M49).

Institutional Review Board Statement

Not applicable. This study is a secondary analysis of a publicly accessible research corpus and involved no new participant recruitment, intervention, or attempt to re-identify examinees.

Informed Consent Statement

Not applicable. No participants were recruited for the present secondary analysis.

Data Availability Statement

The HSK Dynamic Composition Corpus is publicly searchable through Beijing Language and Culture University at https://yuyanziyuan.blcu.edu.cn/en/info/1043/1501.htm (accessed on 11 August 2026). The source is copyrighted and is not released under an open-data license; access, attribution, download, and commercial-use conditions are governed by the provider. Restrictions therefore apply to redistribution of raw corpus texts, corpus-derived exemplars and substrates, and synthetic rewrites of those texts. These materials are available from the corpus provider under its stated conditions. Aggregate results supporting the findings are reported in the article; further inquiries may be directed to the corresponding author.

Acknowledgments

Figure color palettes were adapted from SciDraw AI (https://sci-draw.com/).

Conflicts of Interest

The authors declare no competing interests.

Abbreviations

The following abbreviations are used in this manuscript:
AESAutomated essay scoring
AUCArea under the receiver operating characteristic curve
CEFRCommon European Framework of Reference for Languages
CIConfidence interval
CSLChinese as a second language
EPCSError-Profile-Conditioned Synthesis
ESOLEnglish for speakers of other languages
FPRFalse-positive rate
GBDTGradient-boosted decision trees
HSKHanyu Shuiping Kaoshi (Chinese Proficiency Test)
K–SKolmogorov–Smirnov
L2Second language
LLMLarge language model
LRLogistic regression
MAEMean absolute error
MSEMean squared error
NLPNatural language processing
QWKQuadratic weighted kappa
RNGRandom number generator
RWReweighting
SDStandard deviation
TTRType–token ratio

References

  1. Williamson, D.M.; Xi, X.; Breyer, F.J. A Framework for Evaluation and Use of Automated Scoring. Educ. Meas. Issues Pract. 2012, 31, 2–13. [Google Scholar] [CrossRef] [Scilit]
  2. Kane, M.T. Validating the Interpretations and Uses of Test Scores. J. Educ. Meas. 2013, 50, 1–73. [Google Scholar] [CrossRef] [Scilit]
  3. Shermis, M.D. Anchoring Validity Evidence for Automated Essay Scoring. J. Educ. Meas. 2022, 59, 314–337. [Google Scholar] [CrossRef] [Scilit]
  4. De Wilde, V.; De Clercq, O. Challenges and Opportunities of Automated Essay Scoring for Low-Proficient L2 English Writers. Assess. Writ. 2025, 66, 100982. [Google Scholar] [CrossRef] [Scilit]
  5. Yang, H.; He, Y.; Bu, X.; Xu, H.; Guo, W. Automatic Essay Evaluation Technologies in Chinese Writing—A Systematic Literature Review. Appl. Sci. 2023, 13, 10737. [Google Scholar] [CrossRef] [Scilit]
  6. Wang, Y.; Hu, R. A Prompt-Independent and Interpretable Automated Essay Scoring Method for Chinese Second Language Writing. In Proceedings of the 20th Chinese National Conference on Computational Linguistics; Chinese Information Processing Society of China: Beijing, China, 2021; pp. 1202–1217. [Google Scholar]
  7. Qwaider, C.; Alhafni, B.; Chirkunov, K.; Habash, N.; Briscoe, T. Enhancing Arabic Automated Essay Scoring with Synthetic Data and Error Injection. In Proceedings of the 20th Workshop on Innovative Use of NLP for Building Educational Applications; Association for Computational Linguistics: Stroudsburg, PA, USA, 2025; pp. 549–563. [Google Scholar] [CrossRef] [Scilit]
  8. Zhang, M.; Badola, A.; Johnson, M.; Li, C. Augmenting AI Scoring of Essays with GPT-Generated Responses. J. Writ. Res. 2026, 17. [Google Scholar] [CrossRef] [Scilit]
  9. Wolfe, E.W.; Barber, J.O. Calibrating Generative AI to Produce Realistic Essays for Data Augmentation. arXiv 2026, arXiv:2602.06772. [Google Scholar] [CrossRef] [Scilit]
  10. Long, L.; Wang, R.; Xiao, R.; Zhao, J.; Ding, X.; Chen, G.; Wang, H. On LLMs-Driven Synthetic Data Generation, Curation, and Evaluation: A Survey. In Proceedings of the Findings of the Association for Computational Linguistics: ACL 2024; Association for Computational Linguistics: Stroudsburg, PA, USA, 2024; pp. 11065–11082. [Google Scholar] [CrossRef] [Scilit]
  11. Attali, Y.; Burstein, J. Automated Essay Scoring with e-rater V.2. J. Technol. Learn. Assess. 2006, 4, 1–30. [Google Scholar]
  12. Yannakoudakis, H.; Briscoe, T.; Medlock, B. A New Dataset and Method for Automatically Grading ESOL Texts. In Proceedings of the 49th Annual Meeting of the Association for Computational Linguistics: Human Language Technologies; Association for Computational Linguistics: Stroudsburg, PA, USA, 2011; pp. 180–189. [Google Scholar]
  13. Alikaniotis, D.; Yannakoudakis, H.; Rei, M. Automatic Text Scoring Using Neural Networks. In Proceedings of the 54th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers); Association for Computational Linguistics: Stroudsburg, PA, USA, 2016; pp. 715–725. [Google Scholar] [CrossRef] [Scilit]
  14. Taghipour, K.; Ng, H.T. A neural approach to automated essay scoring. In Proceedings of the 2016 Conference on Empirical Methods in Natural Language Processing; Association for Computational Linguistics: Stroudsburg, PA, USA, 2016; pp. 1882–1891. [Google Scholar] [CrossRef] [Scilit]
  15. Dong, F.; Zhang, Y.; Yang, J. Attention-based Recurrent Convolutional Neural Network for Automatic Essay Scoring. In Proceedings of the 21st Conference on Computational Natural Language Learning; Association for Computational Linguistics: Stroudsburg, PA, USA, 2017; pp. 153–162. [Google Scholar] [CrossRef] [Scilit]
  16. Ke, Z.; Ng, V. Automated essay scoring: A survey of the state of the art. In Proceedings of the 28th International Joint Conference on Artificial Intelligence; International Joint Conferences on Artificial Intelligence Organization: Darmstadt, Germany, 2019; pp. 6300–6308. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  17. Uto, M. A Review of Deep-Neural Automated Essay Scoring Models. Behaviormetrika 2021, 48, 459–484. [Google Scholar] [CrossRef] [Scilit]
  18. Ramesh, D.; Sanampudi, S.K. An Automated Essay Scoring Systems: A Systematic Literature Review. Artif. Intell. Rev. 2022, 55, 2495–2527. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  19. Devlin, J.; Chang, M.W.; Lee, K.; Toutanova, K. BERT: Pre-training of deep bidirectional transformers for language understanding. In Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers); Association for Computational Linguistics: Stroudsburg, PA, USA, 2019; pp. 4171–4186. [Google Scholar] [CrossRef] [Scilit]
  20. Cui, Y.; Che, W.; Liu, T.; Qin, B.; Wang, S.; Hu, G. Revisiting pre-trained models for Chinese natural language processing. In Proceedings of the Findings of the Association for Computational Linguistics: EMNLP 2020; Association for Computational Linguistics: Stroudsburg, PA, USA, 2020; pp. 657–668. [Google Scholar] [CrossRef] [Scilit]
  21. Lee, S.; Cai, Y.; Meng, D.; Wang, Z.; Wu, Y. Unleashing Large Language Models’ Proficiency in Zero-shot Essay Scoring. In Proceedings of the Findings of the Association for Computational Linguistics: EMNLP 2024; Association for Computational Linguistics: Stroudsburg, PA, USA, 2024; pp. 181–198. [Google Scholar] [CrossRef] [Scilit]
  22. Deane, P. On the Relation between Automated Essay Scoring and Modern Views of the Writing Construct. Assess. Writ. 2013, 18, 7–24. [Google Scholar] [CrossRef] [Scilit]
  23. Chawla, N.V.; Bowyer, K.W.; Hall, L.O.; Kegelmeyer, W.P. SMOTE: Synthetic minority over-sampling technique. J. Artif. Intell. Res. 2002, 16, 321–357. [Google Scholar] [CrossRef] [Scilit]
  24. Yang, Y.; Zha, K.; Chen, Y.; Wang, H.; Katabi, D. Delving into deep imbalanced regression. In Proceedings of the 38th International Conference on Machine Learning, Virtual, 18–24 July 2021; Volume 139, pp. 11842–11851. [Google Scholar]
  25. Branco, P.; Torgo, L.; Ribeiro, R.P. SMOGN: A Pre-processing Approach for Imbalanced Regression. In Proceedings of the First International Workshop on Learning with Imbalanced Domains: Theory and Applications, Skopje, Macedonia, 18–22 September 2017; Volume 74, pp. 36–50. [Google Scholar]
  26. Steininger, M.; Kobs, K.; Davidson, P.; Krause, A.; Hotho, A. Density-based Weighting for Imbalanced Regression. Mach. Learn. 2021, 110, 2187–2211. [Google Scholar] [CrossRef] [Scilit]
  27. Feng, S.Y.; Gangal, V.; Wei, J.; Chandar, S.; Vosoughi, S.; Mitamura, T.; Hovy, E. A Survey of Data Augmentation Approaches for NLP. In Proceedings of the Findings of the Association for Computational Linguistics: ACL-IJCNLP 2021; Association for Computational Linguistics: Stroudsburg, PA, USA, 2021; pp. 968–988. [Google Scholar] [CrossRef] [Scilit]
  28. Chen, J.; Tam, D.; Raffel, C.; Bansal, M.; Yang, D. An Empirical Survey of Data Augmentation for Limited Data Learning in NLP. Trans. Assoc. Comput. Linguist. 2023, 11, 191–211. [Google Scholar] [CrossRef] [Scilit]
  29. Yoo, K.M.; Park, D.; Kang, J.; Lee, S.W.; Park, W. GPT3Mix: Leveraging Large-scale Language Models for Text Augmentation. In Proceedings of the Findings of the Association for Computational Linguistics: EMNLP 2021; Association for Computational Linguistics: Stroudsburg, PA, USA, 2021; pp. 2225–2239. [Google Scholar] [CrossRef] [Scilit]
  30. Rei, M.; Felice, M.; Yuan, Z.; Briscoe, T. Artificial Error Generation with Machine Translation and Syntactic Patterns. In Proceedings of the 12th Workshop on Innovative Use of NLP for Building Educational Applications; Association for Computational Linguistics: Stroudsburg, PA, USA, 2017; pp. 287–292. [Google Scholar] [CrossRef] [Scilit]
  31. Grundkiewicz, R.; Junczys-Dowmunt, M.; Heafield, K. Neural grammatical error correction systems with unsupervised pre-training on synthetic data. In Proceedings of the 14th Workshop on Innovative Use of NLP for Building Educational Applications (BEA); Association for Computational Linguistics: Stroudsburg, PA, USA, 2019; pp. 252–263. [Google Scholar] [CrossRef] [Scilit]
  32. Kiyono, S.; Suzuki, J.; Mita, M.; Mizumoto, T.; Inui, K. An empirical study of incorporating pseudo data into grammatical error correction. In Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP); Association for Computational Linguistics: Stroudsburg, PA, USA, 2019; pp. 1236–1242. [Google Scholar] [CrossRef] [Scilit]
  33. Stahlberg, F.; Kumar, S. Synthetic Data Generation for Grammatical Error Correction with Tagged Corruption Models. In Proceedings of the 16th Workshop on Innovative Use of NLP for Building Educational Applications; Association for Computational Linguistics: Stroudsburg, PA, USA, 2021; pp. 37–47. [Google Scholar]
  34. Gretton, A.; Borgwardt, K.M.; Rasch, M.J.; Schölkopf, B.; Smola, A. A Kernel Two-Sample Test. J. Mach. Learn. Res. 2012, 13, 723–773. [Google Scholar]
  35. Lopez-Paz, D.; Oquab, M. Revisiting Classifier Two-Sample Tests. In Proceedings of the 5th International Conference on Learning Representations, Toulon, France, 24–26 April 2017. [Google Scholar]
  36. Beijing Advanced Innovation Center for Language Resources; Beijing Language and Culture University. HSK Dynamic Composition Corpus (Version 2.0). 2019. Available online: https://yuyanziyuan.blcu.edu.cn/en/info/1043/1501.htm (accessed on 11 August 2026).
  37. Cohen, J. Weighted Kappa: Nominal Scale Agreement Provision for Scaled Disagreement or Partial Credit. Psychol. Bull. 1968, 70, 213–220. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  38. Efron, B.; Tibshirani, R.J. An Introduction to the Bootstrap; Monographs on Statistics and Applied Probability; Chapman & Hall: New York, NY, USA, 1993; Volume 57. [Google Scholar] [CrossRef] [Scilit] [PubMed]
Figure 1. Examiner-score distribution of the full corpus. Orange bars and the shaded panel mark the low band (40–59), which contains 7.5% of samples; blue bars mark the middle (60–79) and high (80–95) bands. The frozen test set deliberately enriches the low band for tail evaluation.
Applsci 16 08736 g001
Figure 2. Selected empirical error densities by score band, computed from the training split.
Applsci 16 08736 g002
Figure 3. Paired seed differences, v3+RW minus reweighting. Thin pale lines are the five individual training seeds and the heavy line with round markers is their mean; the dashed line at zero marks no difference from reweighting. Left: difference in low-band MAE, where lower is better. Right: difference in below-60 recall, where higher is better. Negative low-band MAE differences and positive recall differences favor v3. The recall direction is consistent across all five seeds at 10% retention; low-band MAE improves in four.
Applsci 16 08736 g003
Figure 4. Mean ± SD tail metrics as real low-band data shrinks. Lines are means over five seeds and the shaded bands span ± 1 SD across those seeds; the four series are real-only (grey dashed), reweighting, naive synthesis, and EPCS+RW (v3), as labeled in the legend. Left: below-60 recall. Right: low-band MAE in points. The widening gap between v3+RW and reweighting is descriptive of the joint configurations under the stated weighting objective.
Applsci 16 08736 g004
Figure 5. Mean predicted score at each examiner score for reweighting (orange) and v3+RW (blue), with shaded bands spanning ± 1 SD across seeds; the grey dashed diagonal is the identity line, on which the predicted score equals the examiner score. Left: full data. Right: 10% retention. Version 3 restores some lower-tail separation under scarcity but shifts the upper range downward.
Applsci 16 08736 g005
Figure 6. Dose sensitivity at 10% retention, ten seeds per dose. The solid line is the mean over the ten seeds and the shaded band spans ± 1 SD across them; the orange dashed line is the reweighting-only baseline, which adds no synthetic data. Left: below-60 recall. Right: low-band MAE in points. The response is broadly increasing with diminishing returns; adjacent-dose differences above 300 samples lie within cross-seed variability.
Applsci 16 08736 g006
Table 1. Fidelity audit. “No-diff.” counts surface features (of 23) for which a raw K–S test did not reject at p > 0.05 ; the count is descriptive and does not establish equivalence. AUC is five-fold cross-validated real-versus- synthetic classification; 0.5 is chance.
BatchNo-Diff. FeaturesAUC (LR)AUC (GBDT)
Naive role-play1/230.9510.970
EPCS v1 (surface only)10/230.6940.743
EPCS v2 (+content, intuition)6/230.9350.927
EPCS v3 (+content, calibrated)5/230.9050.917
v2 shortens sentences to 24.1 characters on average versus 32.6 for real low-band text. Version 3 restores 33.7 characters and matches character TTR (0.537 versus 0.534; raw p = 0.057 ), but retains function-word artifacts.
Table 2. Full-data results with N = 490 added samples. Values are mean ± SD over five seeds unless noted. Best values are bold.
ConfigurationQWKLow-Band MAELow-Band BiasRecallSlope
Real only0.543 ± 0.03414.03 ± 1.43+14.020.112 ± 0.0710.443
Oversampling0.538 ± 0.03713.21 ± 1.12+13.160.125 ± 0.0590.404
Reweighting0.590 ± 0.0379.99 ± 2.59+9.670.446 ± 0.1350.485
Naive synth.0.555 ± 0.03112.72 ± 0.90+12.690.156 ± 0.0600.419
EPCS alone (v3)0.542 ± 0.04113.64 ± 1.04+13.610.122 ± 0.0880.418
EPCS+RW (v1)0.569 ± 0.04410.76 ± 1.30+10.620.418 ± 0.0870.452
EPCS+RW (v2)0.607 ± 0.0119.10 ± 2.01+8.670.550 ± 0.1250.519
EPCS+RW (v3)0.591 ± 0.0339.53 ± 2.18+9.290.519 ± 0.1570.489
v1 has three runs; all other rows have five.
Table 3. Full-data rank correlation and error coverage for the same runs as Table 2. MAE is reported overall and by L/M/H band.
ConfigurationSpearman ρ Overall MAEMAE-LMAE-MMAE-H
Real only0.646 ± 0.0168.38 ± 0.6014.03 ± 1.436.36 ± 1.046.75 ± 1.00
Oversampling0.653 ± 0.0208.06 ± 0.5313.21 ± 1.125.68 ± 1.097.66 ± 1.21
Reweighting0.641 ± 0.0187.87 ± 0.639.99 ± 2.596.53 ± 1.028.43 ± 2.26
Naive synth.0.612 ± 0.0207.92 ± 0.2412.72 ± 0.905.44 ± 0.448.10 ± 0.55
EPCS alone (v3)0.643 ± 0.0148.13 ± 0.3513.64 ± 1.045.89 ± 0.707.10 ± 1.01
EPCS+RW (v1)0.624 ± 0.0298.00 ± 0.2410.76 ± 1.306.62 ± 0.428.02 ± 0.83
EPCS+RW (v2)0.642 ± 0.0217.82 ± 0.319.10 ± 2.016.85 ± 0.638.45 ± 1.90
EPCS+RW (v3)0.635 ± 0.0207.81 ± 0.379.53 ± 2.186.61 ± 0.498.48 ± 1.80
Table 4. Scarcity gradient for reweighting and the two content-degraded versions (five seeds). F1 treats scores below 60 as the positive class. Best values within each retention level are bold.
Real L DataConfigurationQWKLow-Band MAERecallF1
100% (496)Reweighting0.590 ± 0.0379.99 ± 2.590.446 ± 0.1350.503 ± 0.086
EPCS+RW v20.607 ± 0.0119.10 ± 2.010.550 ± 0.1250.547 ± 0.040
EPCS+RW v30.591 ± 0.0339.53 ± 2.180.519 ± 0.1570.528 ± 0.066
25% (124)Reweighting0.538 ± 0.02513.83 ± 0.900.203 ± 0.0650.313 ± 0.073
EPCS+RW v20.515 ± 0.03910.36 ± 3.010.505 ± 0.1540.487 ± 0.038
EPCS+RW v30.534 ± 0.03011.68 ± 2.540.396 ± 0.1560.435 ± 0.096
10% (49)Reweighting0.506 ± 0.04914.91 ± 1.390.101 ± 0.0710.168 ± 0.104
EPCS+RW v20.495 ± 0.02812.97 ± 2.690.274 ± 0.1720.359 ± 0.172
EPCS+RW v30.497 ± 0.02712.66 ± 2.670.329 ± 0.1700.379 ± 0.097
Table 5. Below-60 operating point and high-band cost at 10% retention (five seeds). FPR is the false-positive rate among responses scored 60 or above.
ConfigurationPrecisionRecallF1FPRPred. <60 RateHigh-Band MAE
Reweighting0.784 ± 0.1570.101 ± 0.0710.168 ± 0.1040.015 ± 0.0150.036 ± 0.0296.09 ± 0.53
EPCS+RW v20.699 ± 0.0800.274 ± 0.1720.359 ± 0.1720.075 ± 0.0710.143 ± 0.1048.11 ± 2.13
EPCS+RW v30.563 ± 0.1020.329 ± 0.1700.379 ± 0.0970.106 ± 0.0920.162 ± 0.1118.10 ± 2.04
Table 6. Cross-architecture replication of the core comparison. Five seeds per cell for the pretrained encoders; the GBDT feature model is a deterministic single fit. Recall is below-60 recall on the enriched test set.
Scorer Configuration 100% Retention10% Retention
MAE-L Recall MAE-L Recall
MacBERTReweighting9.99 ± 2.590.446 ± 0.13514.91 ± 1.390.101 ± 0.071
MacBERTEPCS+RW9.53 ± 2.180.519 ± 0.15712.66 ± 2.670.329 ± 0.170
BERT-base-ChineseReweighting9.99 ± 2.570.464 ± 0.16914.32 ± 1.440.116 ± 0.082
BERT-base-ChineseEPCS+RW10.36 ± 2.350.462 ± 0.13110.98 ± 1.190.390 ± 0.081
RoBERTa-wwm-extReweighting11.95 ± 1.300.329 ± 0.07714.69 ± 2.230.132 ± 0.131
RoBERTa-wwm-extEPCS+RW10.48 ± 2.730.444 ± 0.15912.37 ± 2.730.339 ± 0.137
GBDT (23 features)Reweighting13.020.19016.890.025
GBDT (23 features)EPCS+RW11.460.29514.000.200
Table 7. Label-perturbation stress test at 10% retention (v3, N = 490, five seeds). The unperturbed row repeats the main-experiment values; reweighting without synthesis is shown for reference.
Synthetic LabelsMAE-LRecallPrecisionFPR
Inherited (unperturbed)12.66 ± 2.670.329 ± 0.1700.563 ± 0.1020.106 ± 0.092
All 5 12.71 ± 2.500.357 ± 0.1290.542 ± 0.1010.112 ± 0.070
All + 5 14.39 ± 1.180.195 ± 0.0600.707 ± 0.1200.030 ± 0.018
Random ± 5 13.24 ± 1.890.254 ± 0.0890.551 ± 0.1080.073 ± 0.049
Reweighting (no synthesis)14.91 ± 1.390.101 ± 0.0710.784 ± 0.1570.015 ± 0.015
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content.