3.2. Hyperparameter Sensitivity Analysis
We analyze seven key hyperparameters of BPA-STGCN on NTU60.
Table 4 summarizes the sensitivity of training stability and accuracy to each hyperparameter. For each 90-epoch training run with one hyperparameter configuration, we compute the per-epoch validation accuracy of the EMA model on the X-Sub validation split. There are two criteria of “stability”. The first one is crash epochs, which is the number of post-warmup epochs (epochs 11–90) in which validation accuracy drops by more than 15 percentage points below the running maximum seen so far. The second one is stable epochs, which is the number of epochs in which validation accuracy is at least 80% and within 3 points of the running maximum. The two criteria are complementary: “Crash” counts catastrophic failures, “Stable” counts the epochs a practitioner could safely use for checkpointing. The thresholds are fixed before the sweep and reflect the failure modes observed in our preliminary runs.
BatchNorm Momentum: . The BN momentum is the single most impactful hyperparameter for training stability. With , the running statistics update at a rate of 10% per batch, making them highly sensitive to individual batch composition. It experiences six post-warmup crash epochs. Reducing m to 0.01 makes running statistics update at only 1% per batch and completely eliminates all post-warmup crashes. The last-10-epoch standard deviation drops from 13.11% to 1.48%, a 8.9× improvement in late-training stability.
Mixup Augmentation: . Mixup is the most distinctive hyperparameter in BPA-STGCN, producing a unique negative train–validation gap. Without Mixup, the training accuracy exceeds validation accuracy by 4.96% and 6.09%, respectively, indicating mild overfitting. With Mixup , the training accuracy is lower than validation accuracy. This means the model performs better on clean data than on the augmented training data, which is a strong indicator of effective regularization.
DropPath Rate: . DropPath (stochastic depth) provides regularization by randomly dropping entire residual blocks during training. No DropPath has moderate stability but lower peak accuracy. DropPath = 0.1 achieves higher peak accuracy but paradoxically has worse stability. DropPath = 0.15 achieves better accuracy with substantially better stability. The rate increase from 0.1 to 0.15 provides stronger regularization:
At : The last block has a 10% chance of being dropped per training sample. The effective network depth varies from 9 to 10 blocks.
At : The last block has a 15% chance of being dropped. The model must learn more redundant representations to compensate, improving generalization.
At , the regularization becomes excessive: the last block is dropped 25% of the time, and the second-to-last block 22% of the time. This creates too much variance in the forward pass, making gradient updates noisy and potentially slowing convergence.
Warmup Epoch: . The warmup length controls how gradually the learning rate ramps up from 0 to the initial value. Ten-epoch warmup achieves first-70% accuracy at epoch 12, compared to epoch 61 for five-epoch warmup. Despite the longer warmup, 10-epoch warmup converges to high accuracy faster than baselines.
The purpose of warmup is to allow BN running statistics to stabilize before aggressive optimization begins and prevent early gradient explosions from destabilizing the randomly initialized model.
With , the learning rate reaches its maximum by epoch 5. BN running statistics has not yet converged. The high-variance early training wasted 30 epochs before the model recovered to a usable state.
With , the learning rate reaches 0.1 only at epoch 10. This gives BN running statistics sufficient time to stabilize.
Extending warmup to will provide even more BN stabilization time but at the cost of five fewer epochs of effective training under the cosine schedule.
Gradient Clipping: . Gradient clipping with is to prevent large gradient updates from destabilizing BN statistics. By capping the gradient norm, it ensures that no single batch can cause a dramatic weight shift that would invalidate the current BN running statistics. No clipping experiences crashes that correlate with large gradient norms during the WeightedRandomSampler-induced batch composition changes. Clipping = 1.0 eliminated all post-warmup crashes.
EMA Decay: . Exponential Moving Average maintains a smoothed copy of model parameters used for evaluation. No EMA achieves 92.8% at both best and final epoch. With , the EMA parameters change by only 0.1% per step, effectively averaging the last 1000 steps. With , the EMA averages over 100 steps, making it more responsive to recent training progress but less stable against crashes. With , the averaging window would be 10,000 steps, which is too slow for a 90-epoch training run, meaning the EMA model would never fully converge.
Learning Rate: . The initial learning rate controls the step size of gradient descent.
At : The gradient updates are half the magnitude, making BN statistics more stable but slowing convergence. The model would need 180 epochs to reach the same level of optimization as in 90 epochs. With early stopping, the model may stop before reaching its peak.
At : The gradient updates are large enough for fast convergence but small enough to not destabilize BN. The cosine annealing schedule ensures that the learning rate decreases smoothly, preventing the sudden accuracy drops seen in step-decay schedules.
At : The gradient updates are too large, causing the model to overshoot optimal minima. Even with gradient clipping at 1.0, the effective learning rate will be 2× too large, leading to training instability.
The learning rate of 0.1 is the standard for SGD with momentum on skeleton-based recognition tasks and is validated by our experiments.
3.3. Ablation Study
We analyze the contribution of each architectural and training module by examining the effect of its removal.
Table 5 summarizes the ablation results.
Ablation: Remove Partition Attention (PA)
Removing the Partition Attention module (reverting to standard graph convolution without body-part-specific weighting) results in an accuracy drop of 0.7% (93.7% → 93.0%), confirming that PA contributes to accuracy.
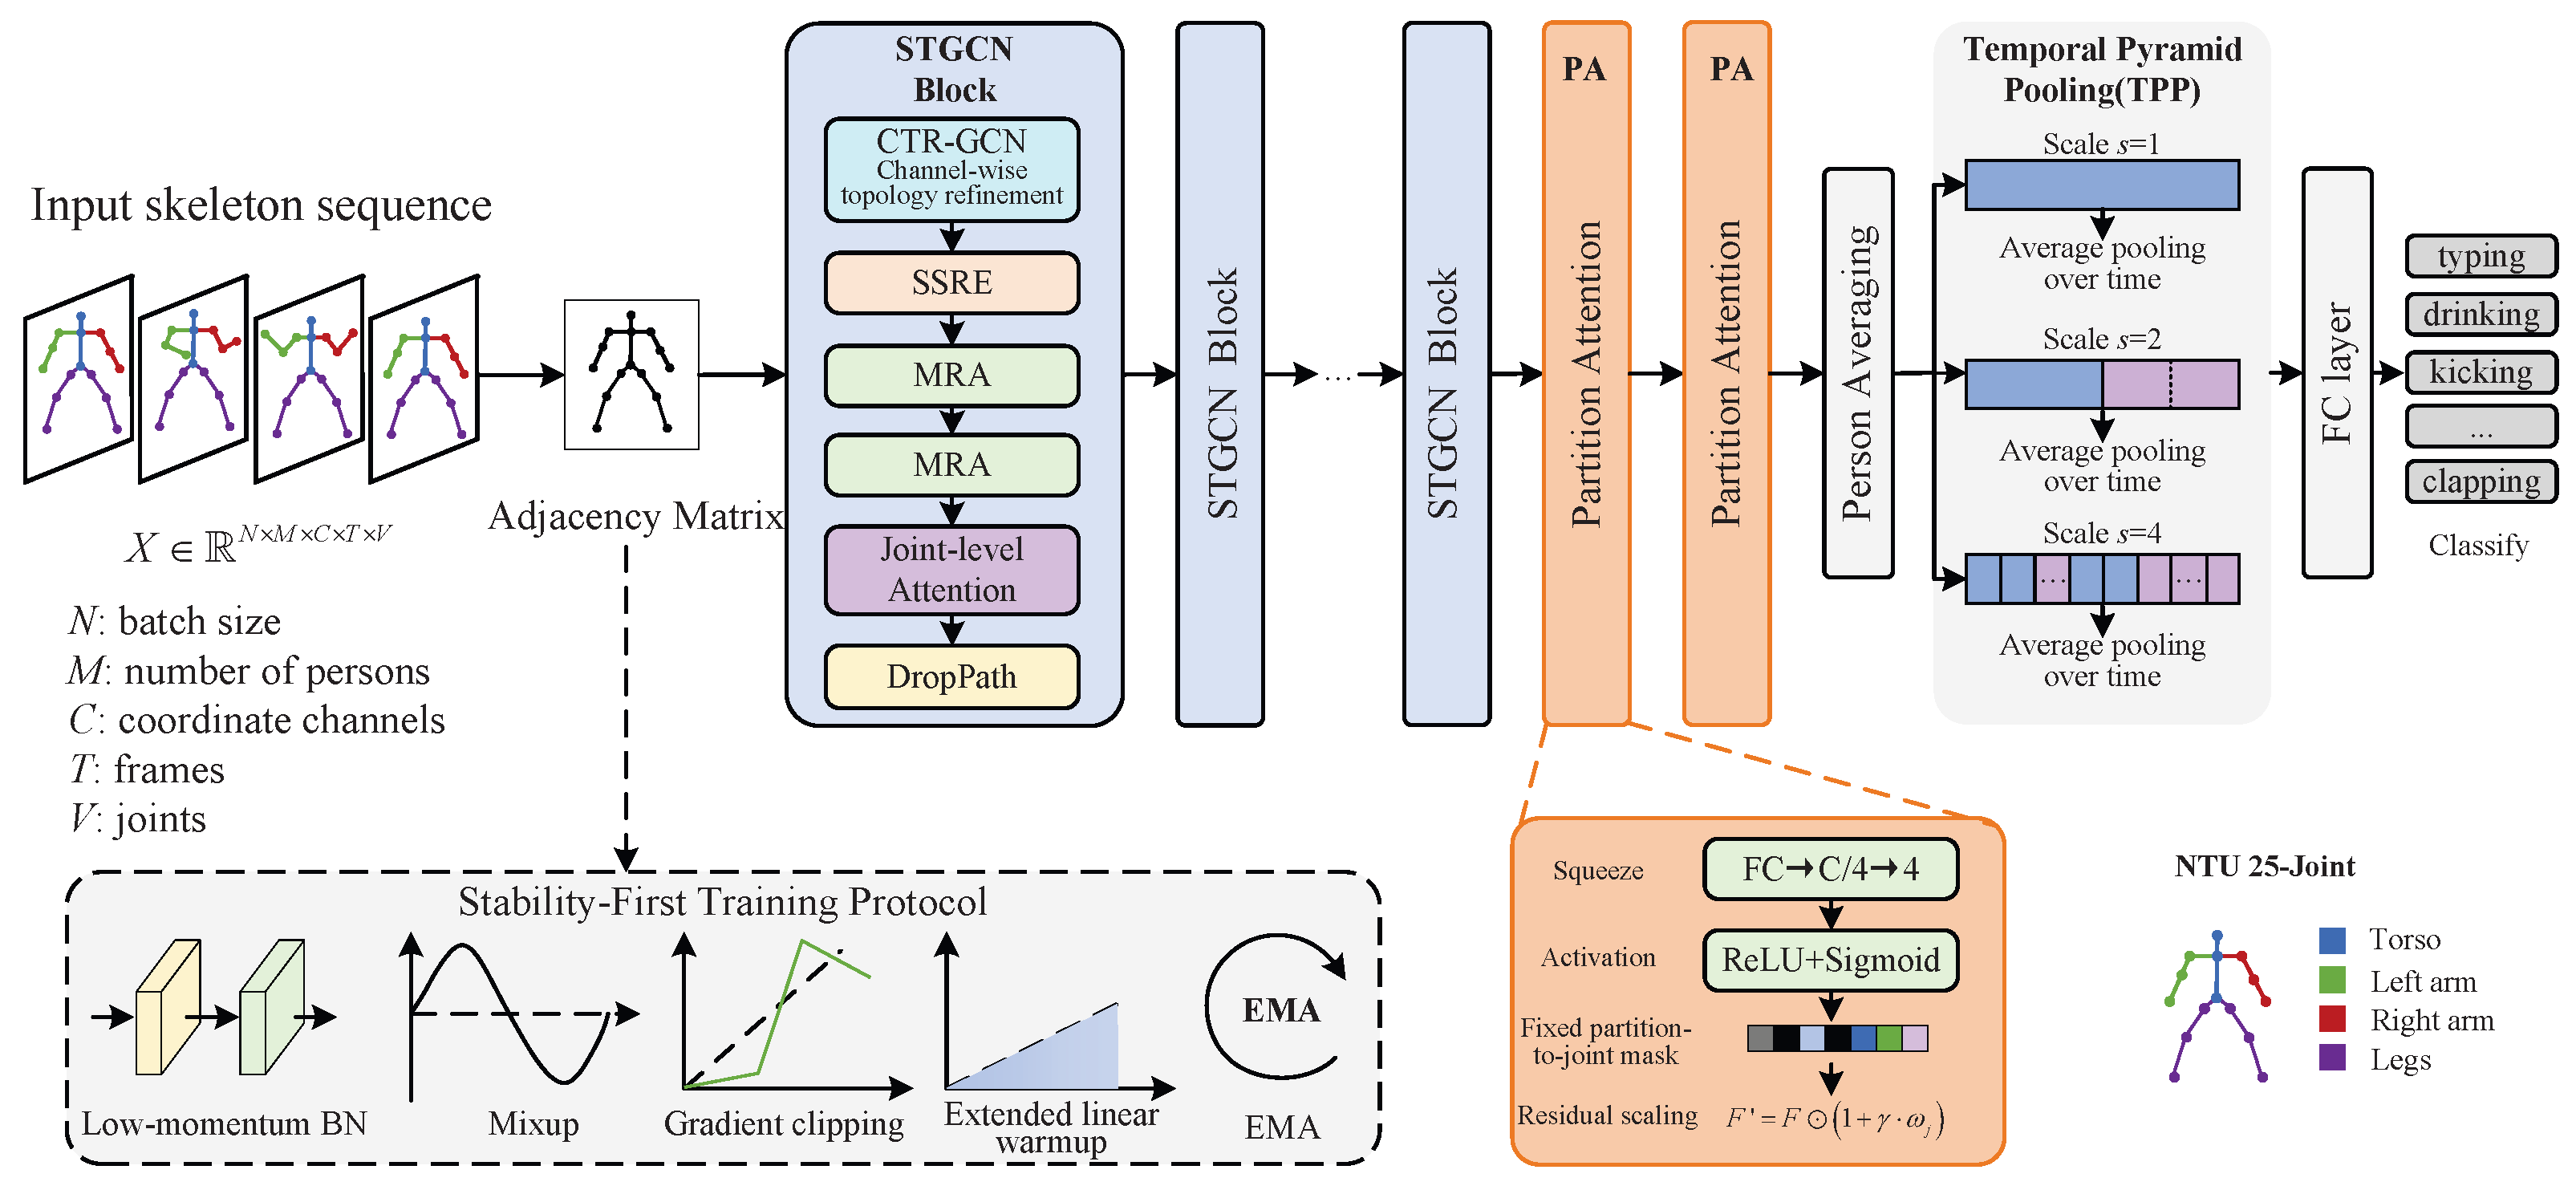
PA learns sample-specific importance weights for four body partitions (torso, left arm, right arm, legs) through a squeeze-activation mechanism. Without PA, all 25 joints are treated uniformly in the graph convolution, and the model must learn body-part-level discrimination implicitly through the adjacency matrix and channel-wise topology refinement.
The 0.7% accuracy loss is concentrated in fine-grained actions that require body-part-level discrimination:
Writing (−10.5% without PA): Without PA, the model cannot explicitly focus on torso posture differences between “writing” and “typing”, both of which have similar right-arm trajectories.
Touch head (−17.4% without PA): The model loses the ability to upweight the arm partition for touch-related actions.
Clapping (−12.7% without PA): The model cannot distinguish clapping (hands together) from rub hands (hands apart) by focusing on hand position relative to torso.
PA is applied only to the last three STGCN blocks because early blocks learn low-level motion patterns shared across body parts, while later blocks encode action-specific semantics where body-part discrimination is most valuable. This placement minimizes parameter overhead while maximizing discriminative benefit.
Ablation: Remove Temporal Pyramid Pooling (TPP)
Replacing TPP with standard global average pooling (GAP) results in an accuracy drop of 0.9% (93.7% → 92.8%). The stability is not affected, as TPP is only applied during the pooling phase after all STGCN blocks.
GAP collapses the temporal dimension into a single vector, which discards all temporal structure within the sequence. However, TPP instead captures multi-scale temporal dynamics.
The 0.9% accuracy loss from removing TPP is concentrated in actions with distinctive temporal structures:
Vomit (−10.5% without TPP): “Vomit” has a three-phase temporal structure (bending → retching → recovering). TPP’s two-segment pooling captures the bending/recovering phases, while four-segment pooling captures the rapid retching motions within the middle segment. GAP averages all three phases into a single representation, blurring the temporal dynamics.
Take off shoe (−6.5% without TPP): This action has a temporal progression (bend → grasp → pull → release). TPP’s multi-scale pooling captures both the overall progression (1-segment) and the individual phases (four-segment).
Typing (−6.5% without TPP): “Typing” has periodic rapid keystroke cycles. TPP’s four-segment pooling captures the periodic pattern, while GAP averages over all cycles, losing the temporal periodicity.
TPP adds only 0.07M parameters while providing multi-scale temporal context. The negligible parameter overhead means the accuracy gain comes from representational improvement rather than increased model capacity, confirming that temporal structure preservation is valuable for skeleton-based recognition.
Ablation: Remove Joint Attention (JA)
Removing Joint Attention results in an accuracy drop of 1.1% (93.7% → 92.6%). This is the largest single-module contribution, confirming that joint-level attention is a critical component.
JA learns per-joint attention weights based on the feature context. Unlike PA which groups joints into four partitions, JA learns individual importance weights for all 25 joints. This finer granularity allows the model to focus on specific joints that are most relevant to each action.
The 1.1% accuracy loss from removing JA is expected to affect:
Play phone (−15.6% without JA): JA focuses on wrist and hand joints, which are the primary discriminators for phone-related actions.
Typing (−11.2% without JA): JA focuses on the right wrist joint, capturing the keystroke motion pattern.
Touch head (−25.0% without JA): JA focuses on the hand-to-head trajectory, which is the key discriminator from other touch actions.
JA and PA are complementary: JA provides fine-grained, per-joint attention, while PA provides coarse-grained, body-part-level attention. Removing both will compound the losses, as shown in the PA − TPP configuration.
Ablation: Remove Mixup
Removing Mixup is expected to increase peak accuracy by 0.3% (93.7% → 94.0%) but decrease stability, which manifested as stable epochs from 34 to 15, crash epochs from 0 to 2. This is the only ablation where removing a component improves accuracy, highlighting the accuracy–stability trade-off.
Without Mixup, the training task allows the model to fit the training data more tightly. This produces higher peak accuracy but with increased overfitting risk.
The stability decrease comes from two sources:
Loss of BN augmentation: Without Mixup, BN running statistics are estimated from clean inputs only, making them less robust to distribution shifts during validation.
Sharper decision boundaries: Without the smoothing effect of interpolated samples, the model’s decision boundaries are sharper and more sensitive to small input perturbations, leading to higher variance in validation accuracy.
Ablation: Remove Gradient Clipping
Removing gradient clipping results in a small accuracy drop but a notable stability decrease. This confirms that gradient clipping primarily contributes to stability rather than accuracy.
Without gradient clipping, large gradient norms during the warmup-to-cosine transition or during later training can cause weight updates that destabilize BN running statistics. Even with , a sufficiently large weight update can shift the feature distribution enough to cause a temporary accuracy drop.
The minimal accuracy impact indicates that gradient clipping rarely activates during normal training. It functions as a safety net rather than a regularizer. This is the ideal behavior for a stability mechanism: invisible during normal operation, critical during edge cases.
Ablation: Remove DropPath
Removing DropPath results in an accuracy drop of 0.9% (93.7% → 92.8%) and a moderate stability decrease. Without DropPath, all STGCN blocks are active during every training step, and the full-depth network is more prone to overfitting.
The 0.9% accuracy drop is larger than the PA ablation, suggesting that DropPath’s regularization effect is more impactful than PA’s discriminative improvement. This is consistent with the observation that regularization techniques collectively contribute more to BPA-STGCN’s performance than architectural innovations.
Ablation: Remove EMA
Removing EMA results in the largest accuracy drop (1.4%, 93.7% → 92.3%) among all ablations. The stability is moderately affected.
The 1.4% accuracy drop is the combined effect of losing both mechanisms. Without EMA, the model will rely entirely on the main model’s single-epoch snapshot, which is more susceptible to batch-specific noise.
The stability metrics are not affected by EMA removal because EMA does not influence the main model’s training dynamics; it only maintains a separate shadow copy. The decrease in stable epochs reflects that without EMA, the main model’s validation accuracy is more variable, with fewer epochs exceeding 80%.
Ablation: Revert BN Momentum to 0.1
Reverting BN momentum from 0.01 to 0.1 while keeping all other components is expected to increase peak accuracy by 0.3% (93.7% → 94.0%) but dramatically reduce stability. This is the most extreme accuracy–stability trade-off among all ablations.
With , BN running statistics adapt 10× faster to the evolving feature distribution. This has two effects:
Accuracy benefit: Faster statistical adaptation means the normalization layer can track the changing feature distribution more closely, reducing the train–eval distribution mismatch. This allows the model to fit the training data more tightly, leading to higher peak accuracy.
Stability cost: The faster adaptation also means that BN running statistics are more sensitive to individual batch composition. A single batch with skewed class distribution can shift the running statistics by 10%, causing a cascade of destabilization.