1. Introduction
Techniques based on artificial intelligence (AI) affect all areas of our lives in an attempt to solve important problems. Smart homes, or home automation, as one of the AI areas, integrates internet-connected devices for remote monitoring and device and appliance management. They provide security and home comfort, e.g., ensuring proper lighting and air temperature, switching appliances on/off, and offering remote control with self-learning of schedules and adapting accordingly. The increasing consumption of household energy in smart homes (about 40% of all energy consumed) puts forward the task of modelling for the purpose of prediction and optimisation of both home energy consumption and solar- and photovoltaic-based energy production. The models also serve energy management, the design of the best schedule and control of the power-driven home devices in smart homes for saving energy and related costs, balancing between comfort and security on one side and costs and energy efficiency on the other. They provide meaningful insights for energy planning and management, as well as intelligent decision-making on appliance scheduling and load balancing.
The prediction of smart homes’ energy consumption and solar or photovoltaic generation is based on weather and time variables and reveals the human interactions with the energy system. The dataset used is often transformed into time series data, i.e., a sequence of data points measured at successive, evenly spaced points in time. The time series characteristics are autoregression, seasonality and stationarity, i.e., the statistical properties (mean, variance, and covariance) do not change over time. The univariate time series forecast future values by leveraging past observations and learning from historical patterns in the data. For multivariate time series forecasting, it is related to time and also to various other variables, e.g., the most influential weather variables. Many time series machine learning (ML) approaches are developed to predict energy consumption and generation in smart homes by capturing the non-linearities and the complex patterns in the data. ML, as a subset of AI, trains systems to learn from data and improve autonomously without being explicitly programmed. Artificial neural networks (ANNs), as a subset of ML, inspired by the human brain, are successful in modelling, control, and prediction [
1]. The most popular ANN models are based on multilayer perceptron (MLP) for regression models, probabilistic Bayesian Neural Networks for robustness by incorporating uncertainty into predictions, and Generalised Regression Neural Networks (GRNNs)— radial basis networks for modelling complex relationships in the data. Deep learning (DL) is considered the most suitable for time series forecasting and also the most computationally intensive. Some of the popular DL models are multilayered ANN, Recurrent Neural Networks and Long Short-Term Memory (LSTM) networks, which capture temporal patterns and long-term dependencies in data, respectively.
The prediction can be short- or long-term, over various time horizons, across different time frames, searching for intraday patterns and a daily cycle, for seasonal, monthly, or yearly patterns. In addition, the models may concern energy consumption and generation of different groups of electrical appliances across time or different time spans, of various residents and house locations, etc. The prediction of energy consumption can support cost-effectiveness, reduced environmental impact, efficient resource utilisation, and learning the electricity consumption patterns to plan the national power system and electricity production policy. ML approaches are applied to national residential building energy forecasting, as well as to individual homes. Prediction models can serve as a basis for energy consumption optimisation and an energy optimisation strategy that adjusts based on real-time data for changes in occupancy, weather conditions, or energy prices.
The effectiveness of prediction is dependent on the quality of available data. Prior to modelling, the collection of data is carefully planned, which includes selection of variables to be measured, the technical equipment and its location, unification of measured information, sample size, and sampling, e.g., the weather variables are measured daily as they tend to keep relatively constant over short timeframes, etc. Then the data are pre-processed and analysed, which comprises data cleaning via tackling missing and distorted measurements and outliers; feature engineering-transformations; smoothing, normalisation, and data testing for normal distribution, correlation, and linearity; and splitting the data for network training, model validation, and model testing.
The model training and validation are followed by performance assessment of the designed model. The evaluation metrics commonly used include mean squared error (MSE), root MSE (RMSE), mean absolute error (MAE), mean absolute percentage error (MAPE), correlation gain R, coefficient of determination R2 and residual diagnostics.
The increased ANN applications in smart homes and the great amount of various energy-related data from the smart appliances and on local weather conditions published in online repositories motivate the design and assessment of MLP models for predicting smart home energy consumption and generation. MLP is selected as a computationally simple ANN that is widely spread and easily designed, understood and applied by various engineers with different levels of programming skills.
The problem considered in the present research is to fill in the gap of an easy-to-use methodology for derivation of simple and accurate MLP models for the prediction of energy consumption and solar generation in smart homes using Matlab
TM 2013 [
2] and to illustrate its application for designing a single and a two-layered MLP models from available published datasets of time and weather variables and also consumed and generated energy. The models are simplified as a result of various correlation analyses for the assessment of the significant MLP input variables.
Classical ML methods have been applied for modelling and predicting power energy consumption such as linear regression (LR) [
3], Support Vector Machines (SVM) [
4], etc. In [
5], five advanced ML models for the prediction of energy consumption are compared—decision trees (DT) regression, stochastic gradient descent regression (SGDR), Bayesian ridge regression (BRR), LR, gradient boosting (GBoost) regression and the Facebook modular regression forecasting model, Prophet, based on time series with separately treated components: trend, seasonality and holidays. The dataset used includes smart meter measurements taken each minute over the course of 350 days of household energy consumption, solar generation, energy use of 32 groups of electrical appliances (dishwasher, furnace, etc.) and local meteorological information (temperature, pressure, wind speed, etc.). The BRR model outperforms the rest in accuracy. Ensemble methods have emerged to tackle the ML approaches limitations in processing big data, overfitting and mapping nonlinear relationships. An example is the prediction model with enhanced performance that integrates DT, random forest (RF), eXtreme Gradient Boosting (XGBoost), and k-nearest neighbour (KNN) ML algorithms [
6]. The use of two datasets enables observation of energy consumption patterns over time. In [
7], big data and ML are integrated to learn the users’ energy consumption patterns enabling the classification of houses.
In [
8], different classical ML and DL approaches are compared for the prediction of energy consumption. The capability of LSTM models to effectively capture temporal energy usage patterns and generate accurate short-term forecasts is studied based on six years of daily electricity consumption for a univariate time series dataset from Finland. A stacked LSTM model with four hidden layers, each containing 50 units, is developed with a dropout layer for the prevention of overfitting. The synergism of time series analysis with DL proves effective in forecasting energy consumption trends. A dataset for Sustainable Household Energy and Environment Resources Management (SHEERM) is built from literature reviews and existing databases in [
9]. It is collected by certified smart meters from 13 houses, selected from various climate regions in Portugal, over the course of three years, relating weather variables, electrical load, energy cost, and solar energy production. The data are unified and pre-processed to be ready for use in the planning of household energy needs, weather forecasting, assessing solar or photovoltaic energy production, and projecting trends in energy prices. The suitability of the data is demonstrated for: linearity or piecewise linearity analysis aimed at the reduction in model complexity; correlation analysis for feature selection, based on principal component analysis (PCA) and Pearson’s correlation, which applies to data with normal distribution, checked by histograms, and linear relationships, inspected by scatter plots; various Python 3.3-based ML models (RF Regression and XGBoost) and DL models (LSTM and MLP), trained and validated for capturing trends and accurately forecasting household consumption, solar generation, types of clouds, sun irradiance, etc., and compared based on the metrics MSE, RMSE, and
R2. A DL neural network with two dense layers of 64 neurons each, two activation functions, Rectified Linear Unit (ReLU), and one dense neuron as the output layer is developed to predict and validate the next data point received from online measurement. An overview, analysis, and comparison of various ML and DL models for smart home energy forecasting are presented in [
10]. Different stages in the model design are discussed: data collection from publicly available datasets, data pre-processing—cleaning, normalisation, and sliding window transformation, model design, training, and validation across two datasets with different sampling times and household patterns, and performance evaluation, based on MAE, MAPE, RMSE,
R2, computational complexity, and deployment viability. The recurrent LSTM model, which was cross-validated, outperforms the baseline models by capturing long-range temporal dependencies, which are characteristic of energy consumption data. The trade-off is the longer training time. A developed convolutional neural network (CNN) CNN-LSTM model has the best performance, reducing bias and overfitting at the expense of a sophisticated hybrid architecture and the great computational resources and training time needed, which may reduce its computational feasibility in smart home IoT implementations for real-time energy forecasting. Eight of the most commonly used probabilistic, ML, and DL forecasting models for smart home energy consumption at the household appliance level across various temporal resolutions, such as hourly, daily, weekly, monthly, and quarterly, are evaluated in [
11]. The aim is to identify the most suitable model for each time frame to enhance energy optimisation and scheduling. Besides the common evaluation metrics MSE, RMSE, MAE,
R2, and residual diagnostics, the Augmented Dickey–Fuller stationarity test and time series decomposition to examine model robustness to changing deployment conditions are also carried out. The architecture is developed in Python and runs on Google Colab, showing cloud-based scalability and the possibility of real-time deployment via Home Energy Management Systems (HEMS) and integrated IoT platforms. The LSTM models are outlined as the best for short-term forecasting, as they capture temporal dependencies, and probabilistic are more suitable for long-term horizons, where uncertainty and seasonality dominate. A system for predicting power consumption and estimating energy utilisation by household appliances, supporting their scheduling in smart homes, is presented in [
12]. It combines Grey Wolf optimisation (GWO) with DL models of several layers with CNN for extracting spatial features from time series data and LSTM for capturing temporal dependencies. The activation functions are ReLU and the hyperbolic tangent (tansig). The CNN-LSTM model learns from historical energy data, weather patterns, and user preferences. Then, GWO optimises the CNN-LSTM network to improve the accuracy of the prediction. The optimisation strategy adjusts the model based on real-time data and changes in occupancy, weather, or energy prices. The model outperforms the baseline models in terms of prediction accuracy, including the existing approaches LR, LSTM, XGBoost, RF, DT, SVM, and other methods for CNN-LSTM network optimisation.
In [
13], a review of different types of ANN prediction models for energy consumption in various buildings and their applications across the building phases—design, operation and renovation—is suggested. In [
14], an MLP network of seven layers, three dense layers of 2056, 512 and 256 neurons and ReLU activation functions, and 3 output neurons for low-, medium-, and high-power consumption with SoftMax activation functions that assign probability values to the three outputs, is designed and validated to dynamically optimise energy use for controlling lighting, heating, and cooling, cutting down energy wastage without compromising the comfort of occupants. An open-source dataset for energy consumption from 3 years for one flat with one resident in Korea, sampled every second, is structured and used for a multi-classification task. The model outperforms the existing models in the literature in terms of MSE. In [
15], an MLP with sigmoidal and linear activation functions is developed for the prediction of energy consumption in a residential building. The number of the hidden layers
h in an ML with
i input layers and
o output layers is determined between 5 and 14 from the Kolmogorov theorem
, where the constant
c∈[1, 10]. By trials, varying the number of layers, the optimal number of hidden layers, 12, is computed to ensure minimal MSE and
R closest to 1. The dataset used contains 352 observations for 13 variables such as total built-up area, number of residents, billing days, average occupancy, outdoor temperature, and energy consumption by various groups of appliances, including lighting, heating, cooling, ventilation, refrigeration, etc. The dataset is collected over the course of 12 months from 44 households in India. The total monthly energy consumption is the MLP output. The validation data are from the last month of each season. The prediction accuracy is compared with the trend extrapolation method for a polynomial of sixth degree determined by trials. In [
16], two identical in structure MLP models are developed for a residential house and a heat pump energy consumption based on three input variables—the day number, outdoor temperature, and solar radiation. The dataset is collected over the course of 3 months, June, July, and August, for an unoccupied test house where all energy systems are electric. The MLP with a single hidden layer of seven neurons that represent the different consumers in the house and logarithmic sigmoidal (logsig) and linear (purelin) activation functions is trained by the Matlab
TM Levenberg–Marquardt and OWO-Newton algorithms. The optimal number of neurons in the hidden layer
nh = 7 is computed from
nh = 2
ni + 1, where
ni is the number of input variables. The minimum number of observations needed for training
nd = 50 is computed from
nd = [
nh + (
ni +
no)/2]
2, where
no is the number of neurons in the output layer. The other 30% of all data are used for validation and testing. The simple ANN models show good accuracy with
R2 of about 0.9.
Most of the existing methods, as seen in the papers overview, suffer from the building of sophisticated ML models often with an unjustified complicated architecture, design, and training, which makes them computationally intensive both for development and use. They are also difficult to understand, with many parameters assigned by trial and error, and require high programming skills and computing resources. In addition, the approaches focus mainly on the comparison of various models rather than on developing simple and accurate ANN prediction models which are viable for online, real-time deployment in smart homes. Cross-household validation and enhancing uncertainty and variability awareness in energy demand are outlined for future research. The optimisation of neural network structures, online learning, improving data quality by more effective methods for data cleaning, feature engineering, and data integration remain future concerns and challenges.
The aim of the present research is to develop an engineering methodology and to design on its basis computationally simple MLP models for accurate and reliable prediction of the generated and consumed energy as a function of weather variables in an average smart home handling sequential and time series recorded data and to assess the MLP models’ viability and potential for real-time deployment in smart homes. The methodology is intended for use by practitioners with basic programming skills in engineering applications. It requires limited computational resources.
The freely available data for the energy consumption and solar panel generation, as well as local weather variables, are collected every hour over the course of a year and averaged from 13 selected family houses equipped with smart appliances and solar generators, located in different climate regions between 41° and 44° North latitude, where Bulgaria is also located. The dataset is extracted from the freely accessible online repository [
17,
18].
The investigation is carried out with the help of the well-mastered and widely spread in engineering applications Matlab
TM and its Statistics and Neural networks Toolboxes [
2,
19].
The novelty and the main contributions of this paper are the following.
1. A user-friendly engineering methodology for the development of computationally simple and easily understood MLP-based models for the prediction of the energy consumed and also generated in smart homes as a function of weather variables is proposed. Based on low computational resource requirements and the well-mastered MatlabTM software, the methodology can serve as a detailed guide for various practicing engineers with small programming skills. The integrated and ordered standard steps—initial data collection and cleaning, analysis, feature engineering, pre-processing, network training, validation and testing, analysis of the results, and assessment of the models’ performance—are complemented by model design based on correlation analyses and identification of optimal models. Most steps are supplied with exemplary MatlabTM functions. Since the approach focuses on model simplicity to facilitate their widespread practical viability, it is proposed to evaluate it based on the number of inputs from smart sensors, alongside the number of hidden layers and neurons within them.
2. Simple MLP prediction models of the average smart home energy consumption and solar energy generation based on significant weather features determined from different correlation tests are derived and validated following the developed methodology. Deploying the models enables energy-efficient strategies in controlling smart home devices, as well as reducing the costs.
3. Assessment of the derived MLP models with respect to simplicity, estimated by the number of the tuned parameters, a measure of the potential for real-time deployment, closeness to LR, determined by R, and accuracy, assessed by MSE.
The further organisation of this paper is as follows.
Section 2 presents a suggested methodology for designing simple MLP-based prediction models for smart home energy consumption and solar generation using Matlab
TM.
Section 3 describes the implementation of the methodology for the design, training, and validation of MLP models using open-source data and different correlation evaluation approaches for selection of significant features. The performance of various MLP models and their viability for real-time deployment in smart homes are assessed and compared in
Section 4.
Section 5 outlines the conclusion and highlights the directions for future research.
2. Methodology for Design of MLP Prediction Models for Smart Homes Energy Consumption and Generation
The design of the MLP models is based on the following methodology:
1. Planning of experiments for the collection of model input-target data.
1.1. Definition of the temporal variables that anchor measurements to specific timeframes (e.g., hours, days, and months) and the independent variables among them for possible MLP inputs.
The key measured meteorological variables that define the state of the atmosphere and the weather conditions on the surface and are crucial for the forecasting of the energy consumption and generation include air temperature, humidity, wind speed/direction, cloud cover, precipitation, atmospheric pressure, air quality index, and radiation. The solar-panel-generated energy and the total consumed energy are also measured. The variables are recorded as time series data. They are characterised as seasonal, non-smooth, and with peaks.
1.2. Definition of the sampling period.
In the present research one hour is assumed as an optimal sampling period to reflect the changes in the variables. The size of the data sample is N = 8399 measurements (observations).
2. Selection of key independent variables.
Here, the easily measured, each hour in every home, air temperature “temp”, humidity “hum”, wind speed “wind” and cloud cover “cloud” are selected as the meteorological variables with the most significant impact on energy consumption “use” and solar energy generation “gen”, accepted for targets for the training of two types of MLP models [
9]. The ranges for the variables considered from the dataset extracted from [
17,
18] are [0, 12.8] kWh for “use”, [0, 0.59] kWh for “gen”, [−24.8, 34.3] °C for “temp”, [0.13, 0.98] % for “hum”, [0, 23] km/h for “wind” and [0, 1] % for “cloud”.
3. Analysis, cleaning, and pre-processing of data.
3.1. Filling missing values, most commonly applying averaging techniques.
3.2. Handling random outliers, applying averaging techniques.
3.3 Smoothing the independent variable candidates for MLP model inputs, if necessary, using most commonly a moving average. It shrinks the difference between the high and the low values. Each value is substituted by the mean of its adjacent values or the mean of the values in an accepted window around it. There are also other noise filters, e.g., the Savitzky–Golay filter fits a polynomial in a window to keep the peaks from being smoothed; a Smoothing Spline turns the data into smooth analytical function, used to easily compute derivatives; and Seasonal Trend Decomposition uses losses, which divides data into a seasonal cycle, a long-term trend, and noise.
4. Conversion of the input data into time series.
The relation of each measurement to the exact time, known as “timestamping”, turns measurements into time series. In the present research, the information added is the month (1 ÷ 12), the date of the month (1 ÷ 30, 1 ÷ 31 or 1 ÷ 28 for February), and the hour of the day (0 ÷ 23) of each measurement. The specifying of the time of each measurement brings “context” to the MLP model to tackle the problem of identical inputs–different outcomes (the time information turns the input variables from identical into different) and adds unique information about the season, the time of the day, the angle of the sun rays that fall on the solar panel, the holidays, the weekends, etc.
5. Data transformations.
5.1. Amplification of inputs, e.g., by raising the non-smooth input to the power of 2 the filtering of the big peaks in the input, mistaken for noise, and the filtering of the outliers are avoided.
5.2. The square root Tsqrt = or logarithm Tlog = log(T + 1) of the target helps linearise the usually quadratic relationship between solar generation and some meteorological factors.
After the training, the simulated result Y is raised to the power of 2 to compensate for the square root of T.
5.3. Lifting of target weight by multiplying T by 1.5 and dividing the result after the training and the simulation Y by 1.5. Thus, the peaks can be modelled without smoothing.
6. Standardisation and normalisation of the above-processed time series data of positive values.
The string variables are converted into integers. Then the distance between the minimum and maximum values of each feature is computed, and the min–max normalisation in the range [0, 1] is used, Pn = (P − minP)/(maxP − minP) for the inputs and Tn = (T − minT)/(maxT − minT) for the targets. The normalisation enhances the learning efficiency and makes all variables dimensionless and hence comparable. In addition, the variables change in the same range. Via min–max scaling, the data are compressed or expanded to fit. For standardisation, the data are centred around 0 with a standard deviation of 1. There also exist maximum absolute scaling and robust scaling, where the data are scaled based on the interquartile range, reducing sensitivity to outliers and improving robustness to extreme values.
After training, first the output Y is denormalised and then compensated for the transformation to obtain the MLP output in real physical units.
7. Correlation analyses.
7.1. The high and statistically significant correlation between the target and the independent key variables from p.2 determines the best MLP models inputs.
Both the “use” and the “gen” MLP models have potential inputs from the meteorological variables. The “gen” variable is an extra candidate for input of the “use” MLP model.
The Pearson correlation test detects a linear, no cause–result relationship between a dependent and an independent variable, here between each of the target vectors and each of the vectors with the values of the input variables, all with normal distribution, standardised, without outliers. So, first, the data are tested for normal distribution and, after passing the test, the strength of the correlation between the target and each input (the correlation coefficient R∈[−1,1]) and its statistical significance index p (p < 0.05 for a significant correlation) are assessed. The correlation coefficient shows how close the data are to a straight line; for |R|∈[0.7,1] the correlation is strong and linear, whereas for |R|∈[0,0.3] it is weak. The main tests for normal distribution are the statistical (quantitative), Jarque–Bera, Kolmogorov–Smirnov, Lilliefors, etc., and the visual (qualitative), which are used here as more reliable in the case of a great amount of data. A visual test can find the best Gaussian curve with an assessed mean value µ and standard deviation σ that matches the dataset. Under a normal distribution, 95% of the data must fall symmetrically within the range [µ − 2σ, µ + 2σ]. A positive dataset with σ > µ violates the assumption of normal distribution since the lower bound of the range drops below zero, which contradicts the positive dataset.
The Spearman rank correlation is appropriate for assessing a monotonic relationship in the case of nonlinear relationships, e.g., nonlinear regression models, and data with outliers and data that are different from a normal distribution:
where
Rs is the Spearman rank correlation gain,
di is the difference between the ranks of the two variables for each measurement, and
N is the number of measurements (observations).
The Spearman rank correlation gain Rs assesses the strength of the specific relationship, here a monotonic relationship, and also the statistical index of significance p of the correlation. Usually, the correlation is considered statistically significant for p < 0.05, i.e., the null hypothesis is rejected with confidence level of 95%. If some input has |Rs| < 0.1, it should be neglected as introducing only noise. For |Rs| > 0.7, the monotonic correlation is high and, for |Rs| < 0.3, correlation is missing.
The nonlinear stepwise regression is a systematic method for adding and removing terms from a multilinear model based on their statistical significance in a regression model. It is an iterative procedure for fitting regression models by selecting the most significant predictive variables, applied to normalised input–output data. The model is built by adding (forward selection) or removing (backward elimination) variables based on statistical significance (e.g., F-tests or t-tests) to achieve a balance between complexity and predictive power. It is used to identify relevant predictors and simplify models, preventing over-parameterisation. The MatlabTM function used is [B,SE,p, Inmodel] = stepwisefit(In,T′), where In is the input vector, T is the target, p the index of statistical significance (p < 0.05 for significant correlation) and Inmodel = 1 indicates a significant variable that should be considered in the model.
7.2. The high and statistically significant correlation between the input features can detect correlated or collinear pairs of input vectors, one of which has to be eliminated.
8. Design of the MLP architecture by the number of layers, the number of hidden neurons in each layer, and the connection of neurons.
8.1. A standard feedforward MLP with two or more hidden layers, the first layer smooths to catch the tendency, while the second layer models the local nonlinearities (the peaks).
8.2. A cascade MLP that adds direct links from the inputs to the output layer to model target variables with peak values, suitable also for exact models, nonlinear relationships, and a small amount of data.
8.3. A radial basis network (RBN) with as many neurons as the data size N.
8.4. A generalised regression network GRNN, etc.
The data of N = 8399 records and 2 ÷ 4 or 2 ÷ 5 independent variables for inputs allow the design of a deeper MLP of several hidden layers. Here, two and three hidden layers are accepted—one to smooth the seasonal and daily cycles and another to tackle the non-smooth meteorological changes.
9. Splitting of data for training, validation and testing (cross-validation), usually 70%-15%-15%.
10. Determination of activation functions in each layer.
The most commonly used activation functions are the linear function, applied in the output layer to broaden the range of the output variable, and different nonlinear functions for the hidden layers, such as the saturating smooth hyperbolic tangent tansig and logistic sigmoid logsig functions, which tend to smooth the data, and also the piecewise linear (poslin or ReLU), which is suitable to model without saturation from the second layer the peak values of the target by combining the smooth curves from the first layer.
11. Selection of the training algorithm that balances between speed and accuracy and does not smooth the peaks of the target.
The most commonly used algorithms for the training of an MLP are:
11.1. The standard backpropagation algorithm, which easily gets trapped in local minima often due to noisy data.
11.2. The powerful Levenberg–Marquardt algorithm, which is fast and aggressive in the minimisation of the error; how aggressive it is depends on the parameter µ. The default value is µ = 0.001; for greater values, the aggressiveness can be reduced in order to preserve the peaks.
11.3. Bayesian regularisation, a slower modification of Levenberg–Marquardt algorithm, which tackles non-smooth and noisy data by restricting the network weights, also automatically excludes the redundant neurons, performing complex computations to balance between model accuracy and complexity via regularisation.
11.4. The RBN self-adapting training algorithm, which adds neurons where the error is great, i.e., on the spots of the target peaks, and controls the neurons’ width by the parameter “spread” [0.1 ÷ 1.0]—for small values, the neurons shrink, thus catching the peaks.
11.5. The exact radial basis network (ERBN) and GRNN, which are equivalent to interpolation and compute the output directly without iterations, passing via all points and controlling the accuracy by the parameter “spread”—the accuracy is greater for a smaller value of “spread”, e.g., 0.05.
12. Selection of a cost function and a function for model assessment.
The most often used are:
12.1. The Mean Squared Error (MSE) for model accuracy
where
N is the number of measurements (observations),
T—the observed value (target, measured dependent variable),
Y—the predicted value (the model output), and
—the prediction/modelling error (residual).
12.2. The Root Mean Square Error (RMSE)
12.3. Related to MSE, the Sum of Squared Errors (SSE):MSE = SSE/N
12.4. The Mean Absolute Error (MAE)
12.5. The Mean Absolute Percentage Error (MAPE)
12.6. The Integral Squared Error (ISE)
12.7. The Integral Absolute Error (IAE)
12.8. The Sum Squared Weights (SSW) for smooth models.
13. Training, testing for generalisation, validation, and cross-validation.
To enhance the MLP model’s generalisation ability, it is recommended to validate the model across diverse datasets.
14. Analysis of the results.
14.1. The correlation coefficient R = [0, 1] is used to test the correlation between the target and the MLP output reached after training. For a correlation coefficient R > 0.7, the model is good; for R < 0.3, there is no correlation. However, the correlation is considered valid depending on the computed statistical significance index p—for p < 0.05, the corresponding R is statistically significant. This analysis applies to variables with normal or close to normal distribution.
14.2. The coefficient of determination
R2 is a statistical measure of how well a regression model explains the observed data or how close the data are to the regression-fitted line, i.e.,
R2 quantifies the degree of any linear correlation between
T and
Y:
where
is the residual sum of squares (also the sum of the squares error),
is the total sum of squares (proportional to the data variance), with
/
N being the observed data mean value.
R2 measures the percentage of the variance in the dependent variable that is explained by the independent variable(s) in a linear regression model. The value of
R2 varies between 0 and 1; a value of
R2 = 0.9 indicates that 90% of the total variability in the response variable
Y is accounted for by the predictor variables, which is a reasonable indicator of a good fit, but further analysis may be required to ensure a robust fit.
14.3. The residual analysis shows the error in every point, which helps to improve the model by adding an extra variable or changing the activation function.
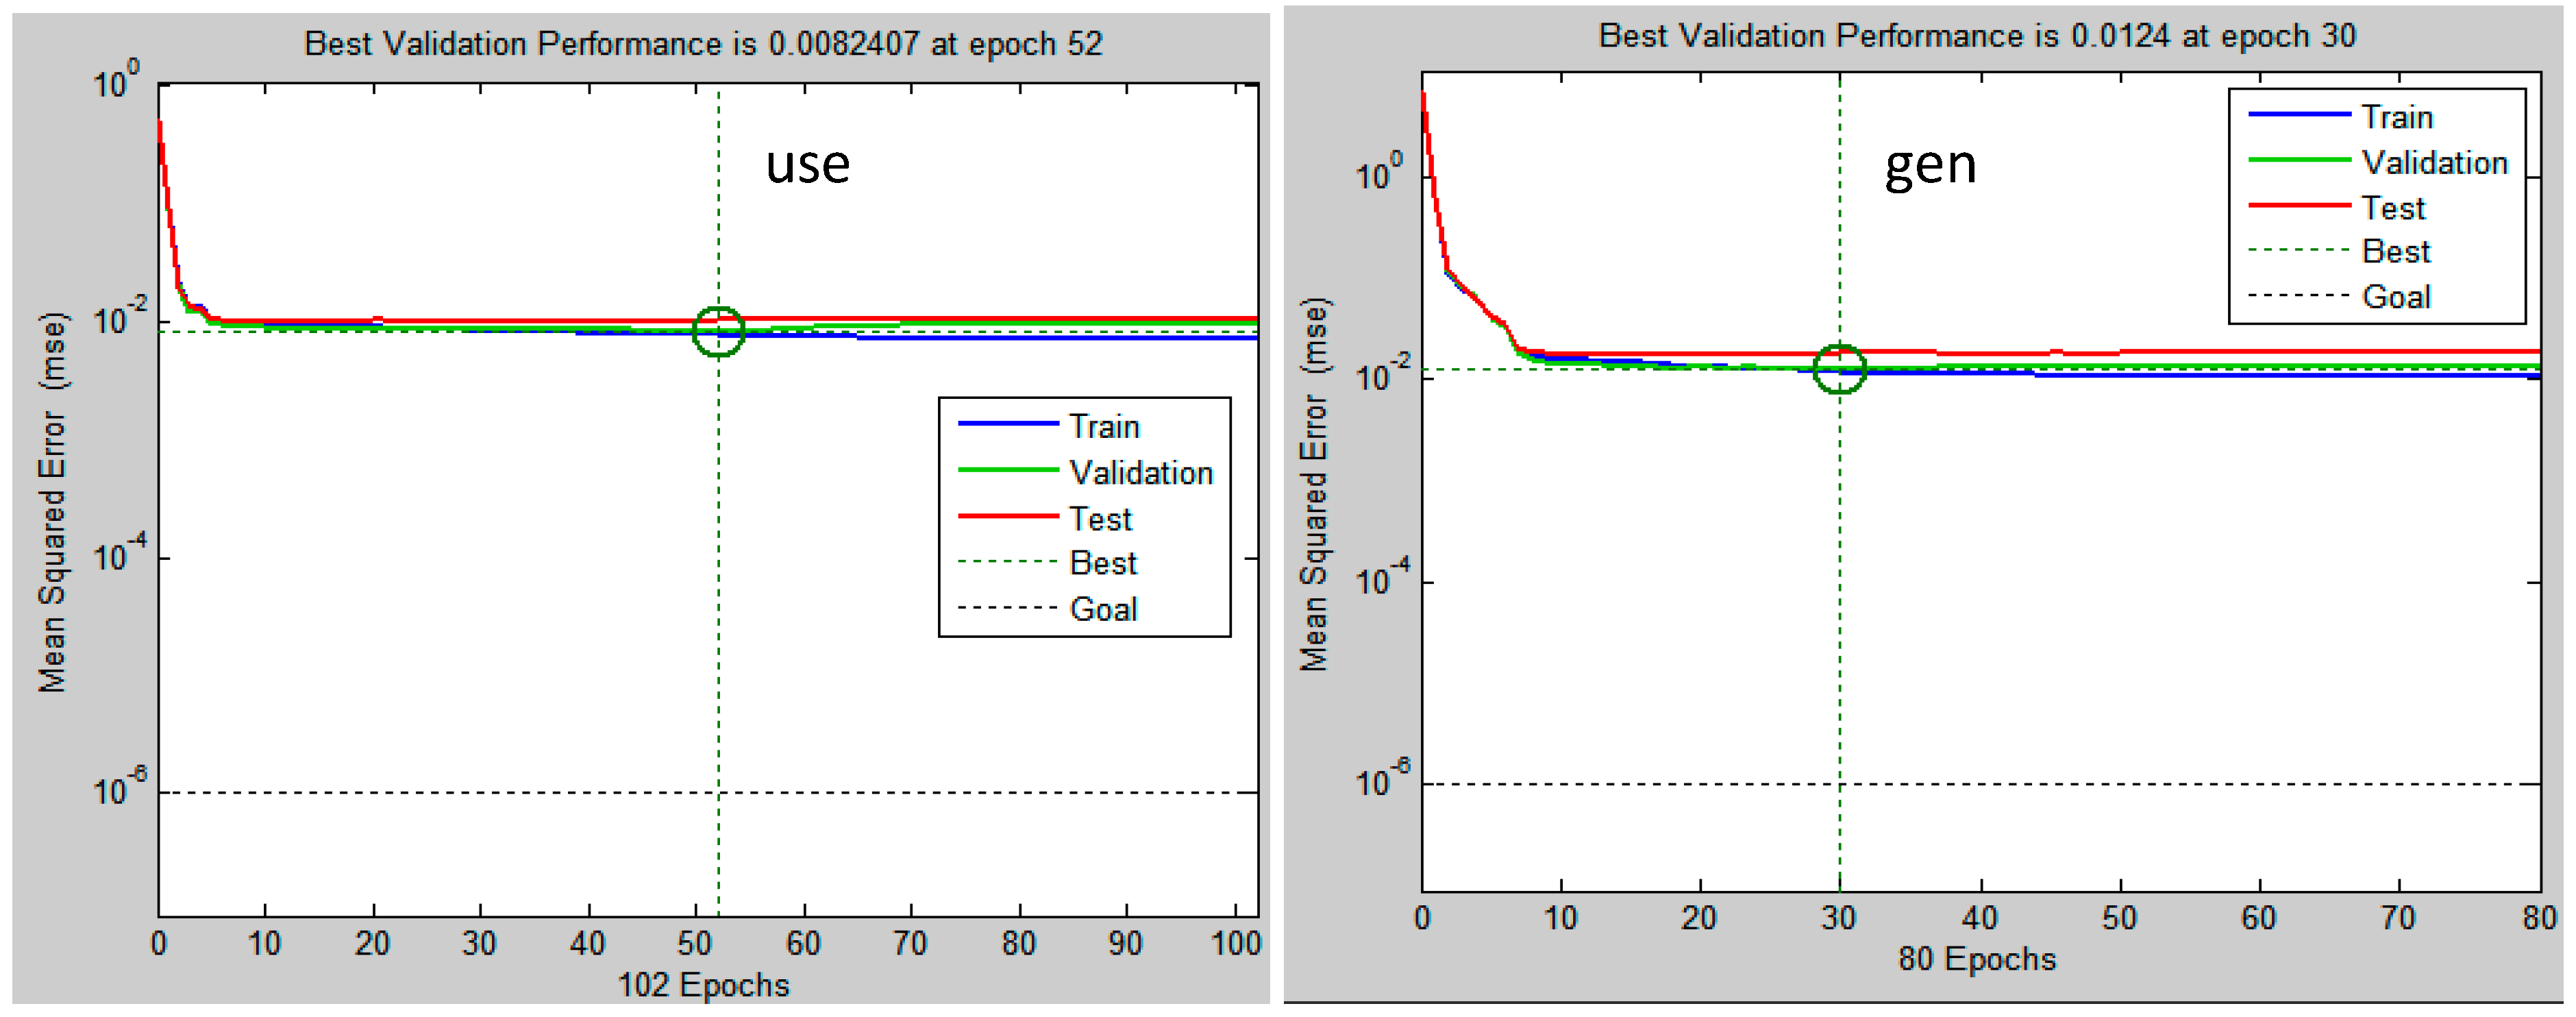
14.4. Close training and validation curves throughout the learning process indicate that the model generalises well. The small fluctuations are attributed to variations in the training data.
3. Design, Training and Validation of MLP Models for Household Energy Consumption and Generation
The methodology developed in
Section 2 is applied to guide the design of two types of computationally simple and accurate MLP models for the prediction of smart home energy consumption (“use” MLP models) and solar energy generation (“gen” MLP models) accounting for the local weather features. An MLP model is accepted to be computationally simple and accurate if a small MSE is achieved for a minimal number of tuning parameters, namely weights and biases, from a maximal number of the hidden layers of 3 and a maximal number of hidden neurons in a hidden layer of 32.
Potential inputs of the MLP models are computed using various correlation analyses among the measured weather variables temp, hum, wind, and cloud. The “use” MLP models include as an extra potential input the solar generated energy “gen”. The dataset of models’ targets and potential inputs is transformed into time series by adding time variables for the month, day of the month, and hour of the day. The first measurement is at 5 o’clock on the 1st of January.
The peaks of the targets T of the two types of MLP models in the vectors “use” and “gen” have to be preserved in the data pre-processing and transformations and in the model training in order to obtain accurate predictions. Here, the target of model “use” Tuse is transformed to TsqrtUse = (0.5√Tuse) to make peaks closer to each other and facilitate the training. The target of model “gen” is transformed by using only the square root Tsqrtgen = √Tuse. Then all the time-series dataset is subjected to min–max normalisation in the range [0, 1].
After the training, the model output Yuse ≈ Tuse is simulated, and the result Yuse is first denormalised by the MatlabTM function Yduse = mapminmax(“reverse”, Yuse, ts), then raised to the power of 2 to compensate for the square root of Tuse, and, for the “use” model, additionally divided by 0.5 to compensate for the multiplication with 0.5-Y = (Yduse)2/0.5. The simulated output Ygen in the gen model is denormalised, then raised to the power of 2.
The time-series dataset is described by the 8399 x9 matrix
PP = [
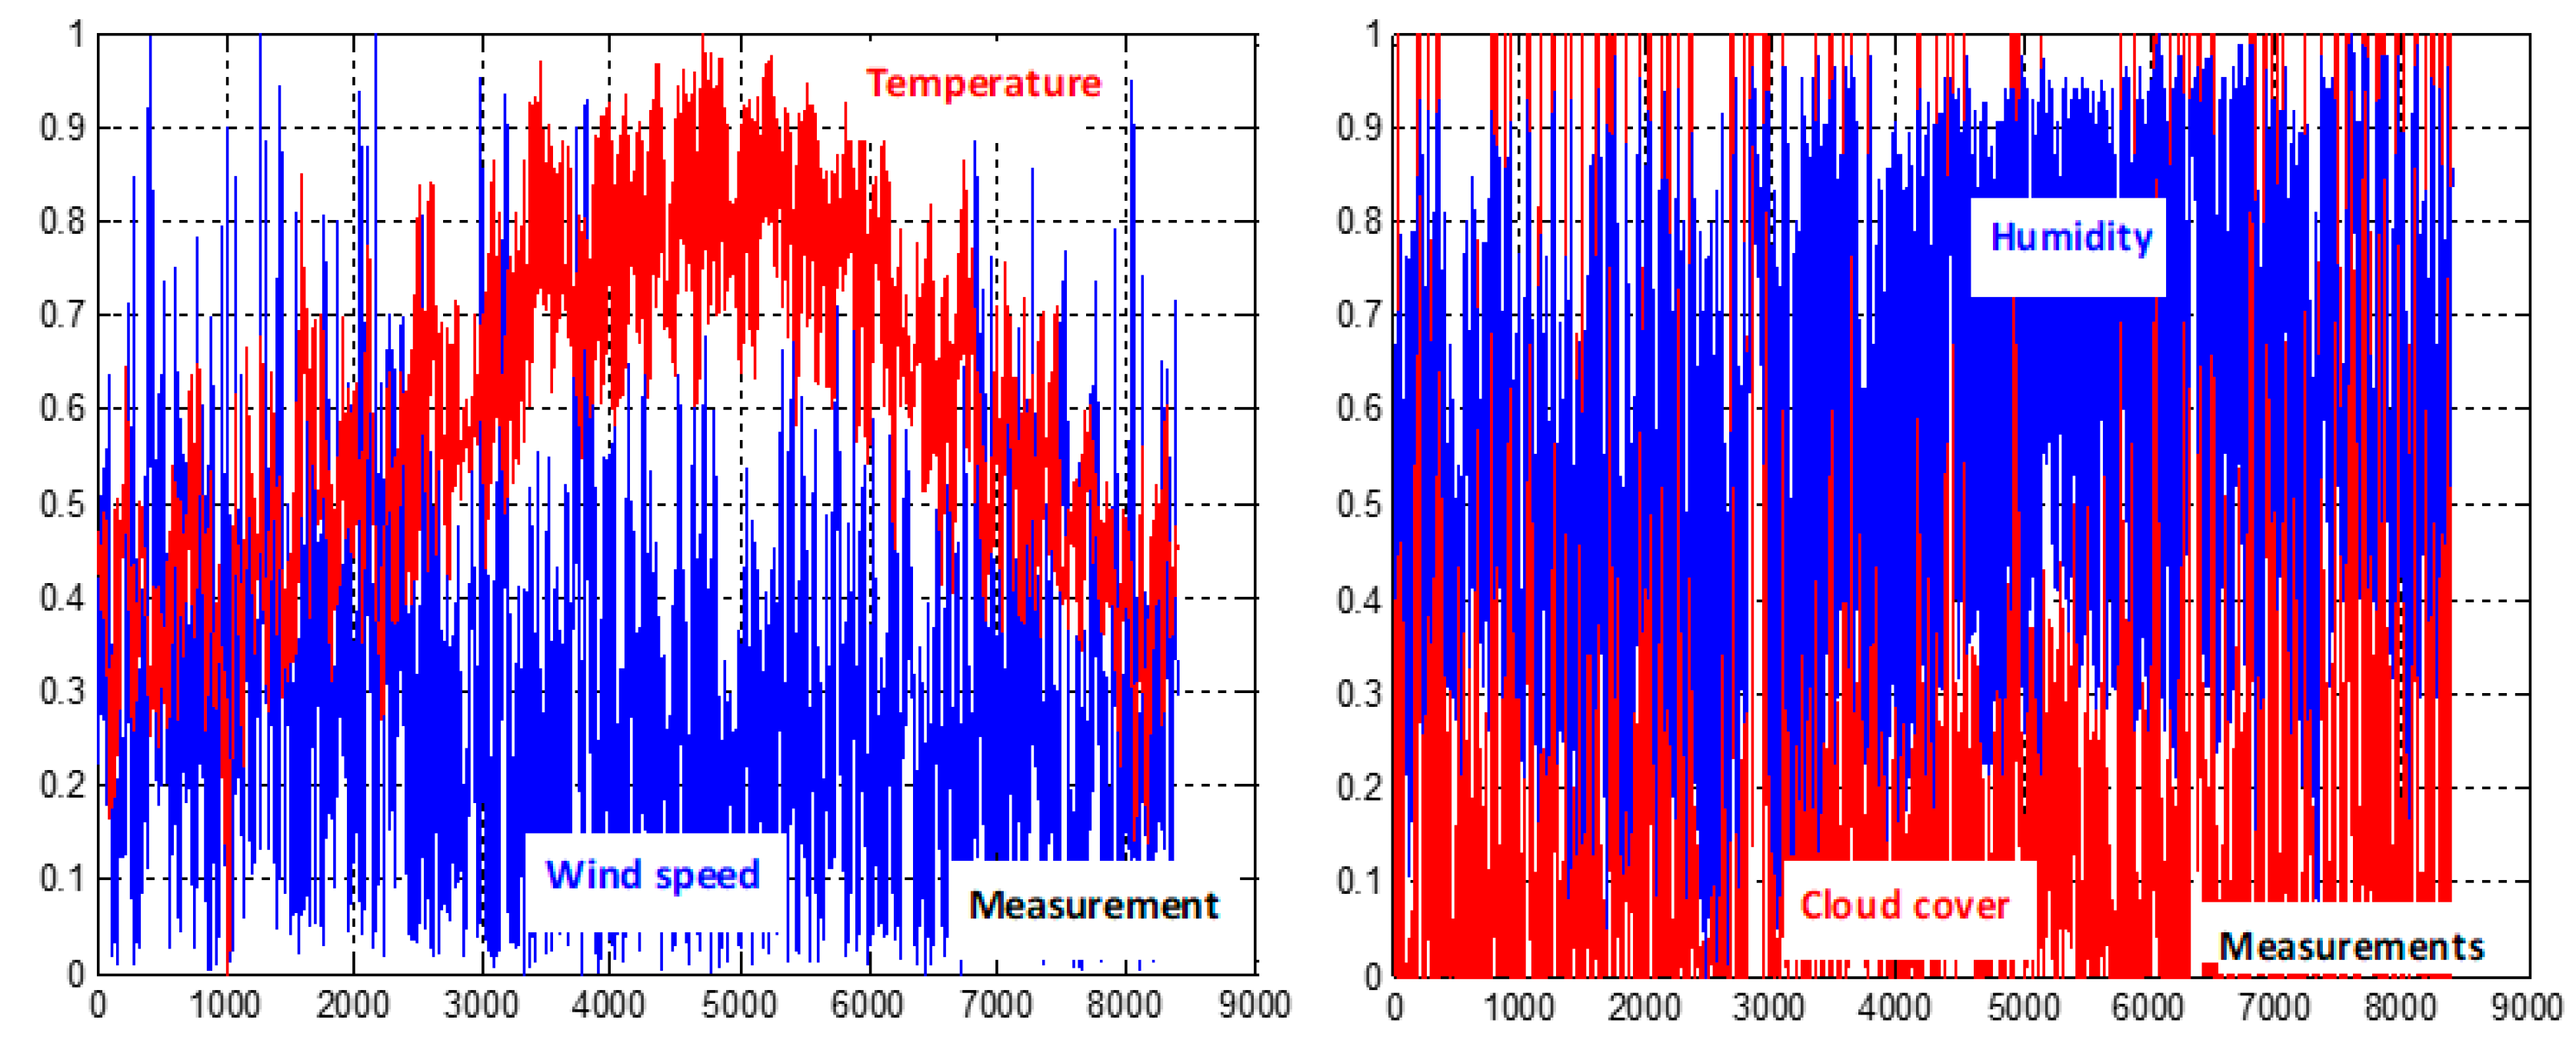
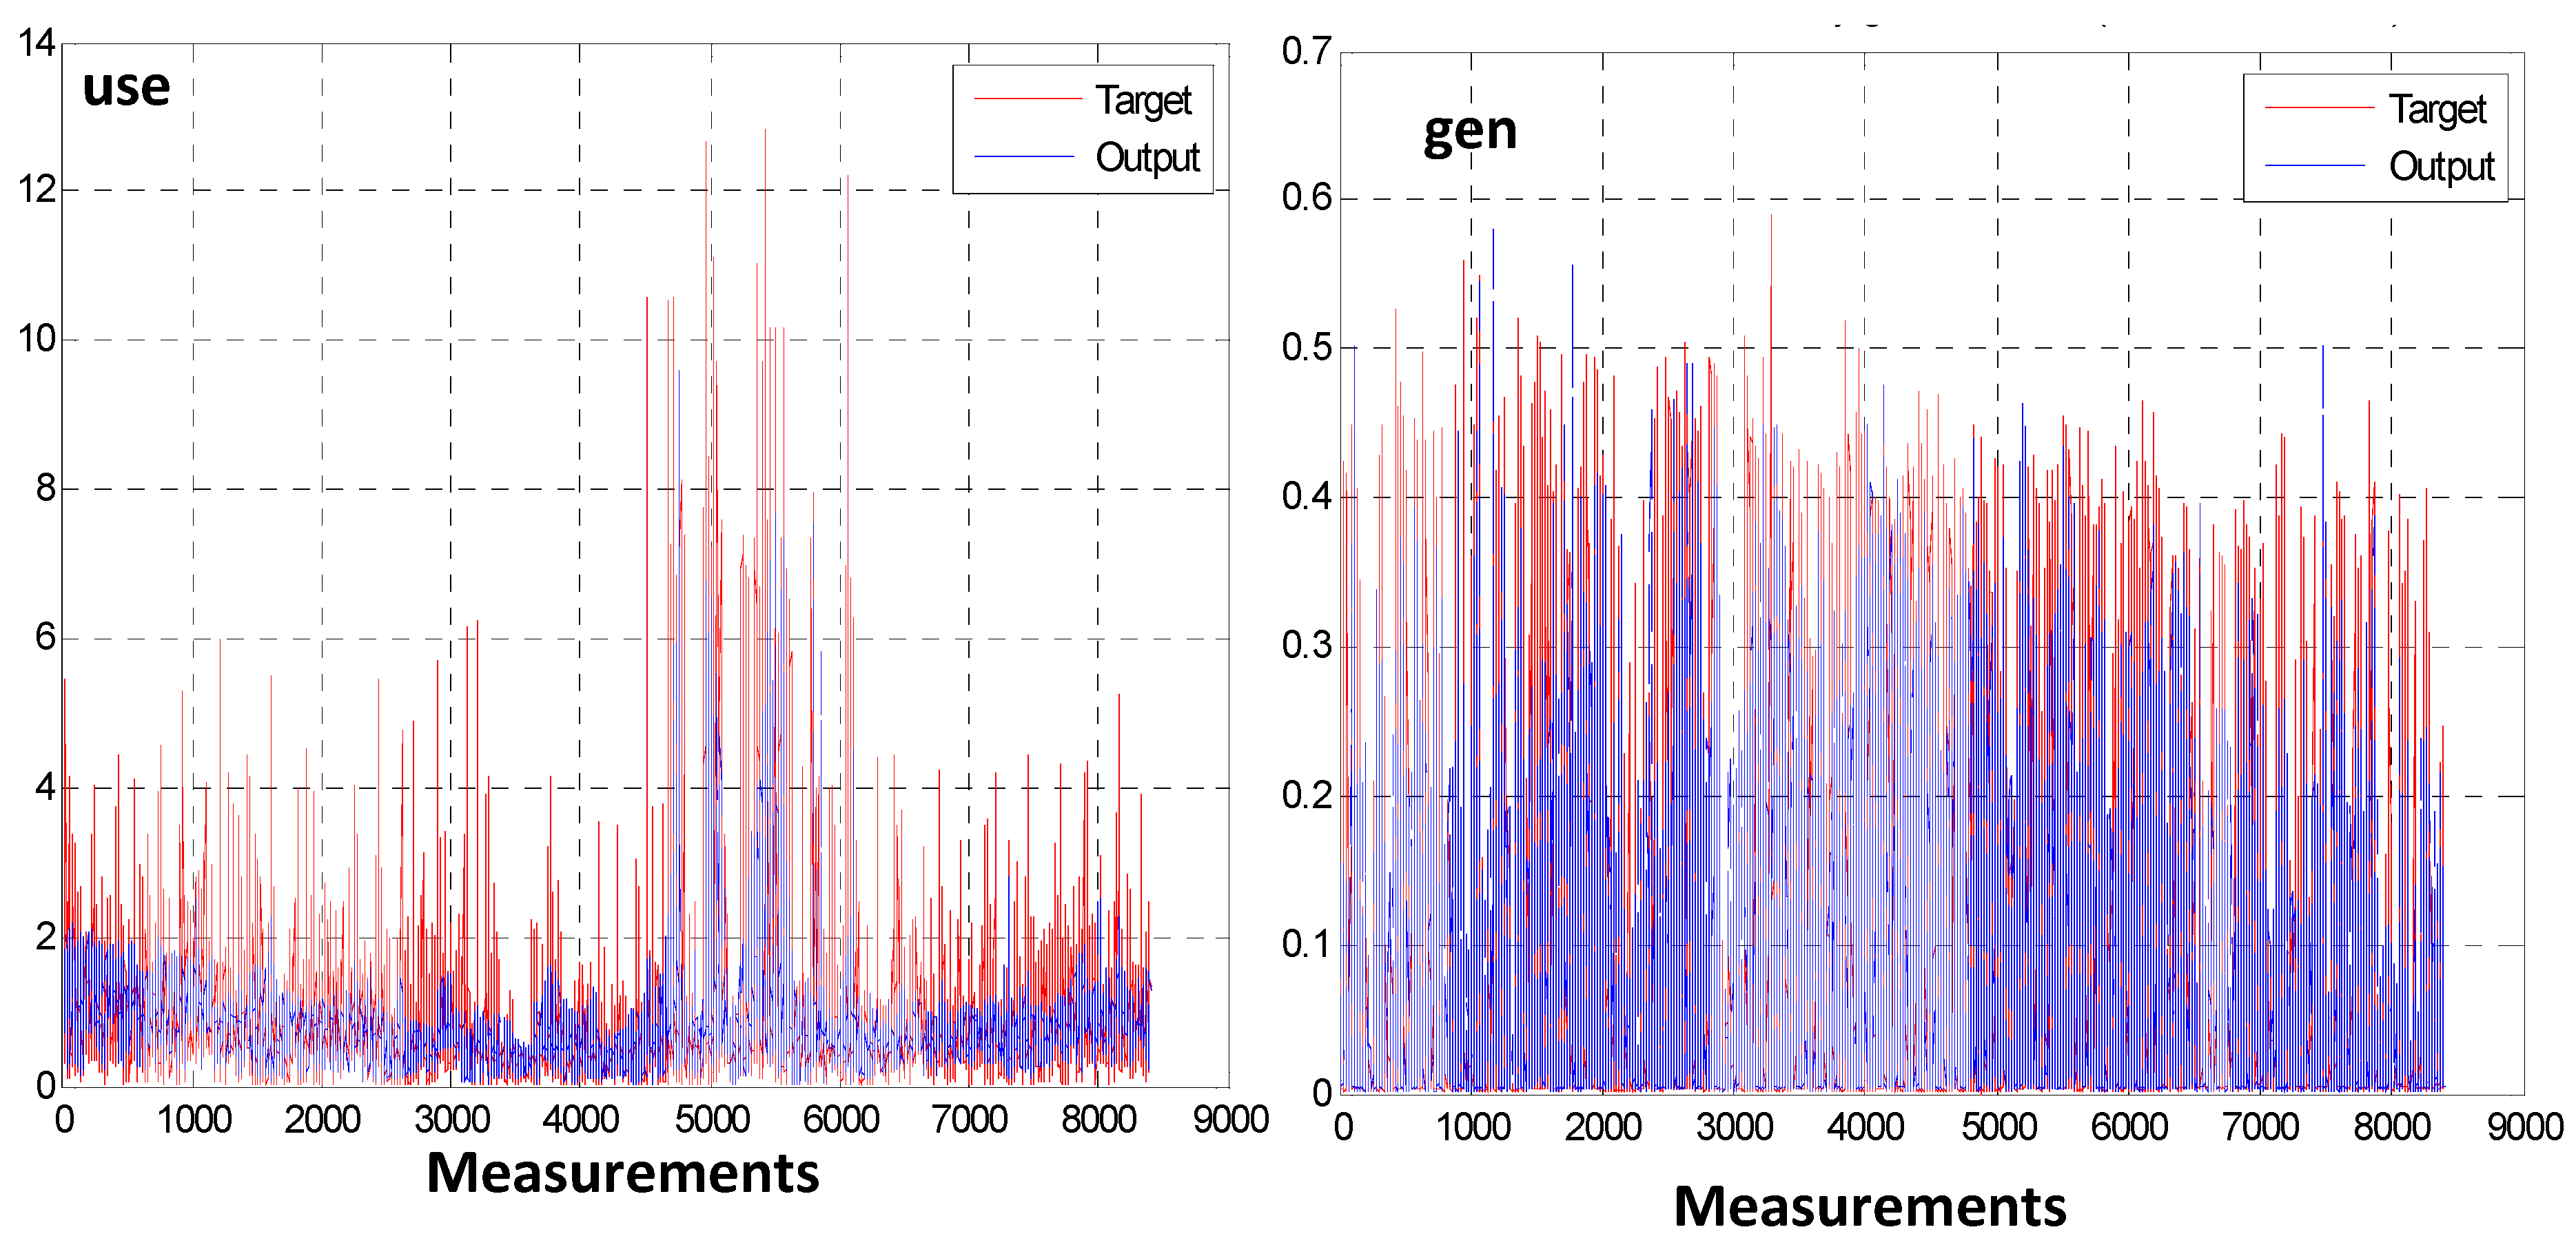
PPi] = [use gen temp hum wind cloud month day hour], where 8399 represents the hourly observations and 9 represents all normalised variables—targets and potential inputs. The specific non-smooth character with peaks of the measured variables is seen for the normalised weather variables in
Figure 1.
The determination of the input variables of the MLP model from the potential inputs is based on a correlation analysis between the target and each of the inputs. Here, different correlation tests are applied. The Pearson correlation test requires a normal distribution and finds linear relationships between the target and the input. Therefore, firstly, each of the target and weather variables in PP is tested for normal distribution. Because of the great amount of measurements, a visual test for normal distribution is accepted. In Matlab
TM, the function
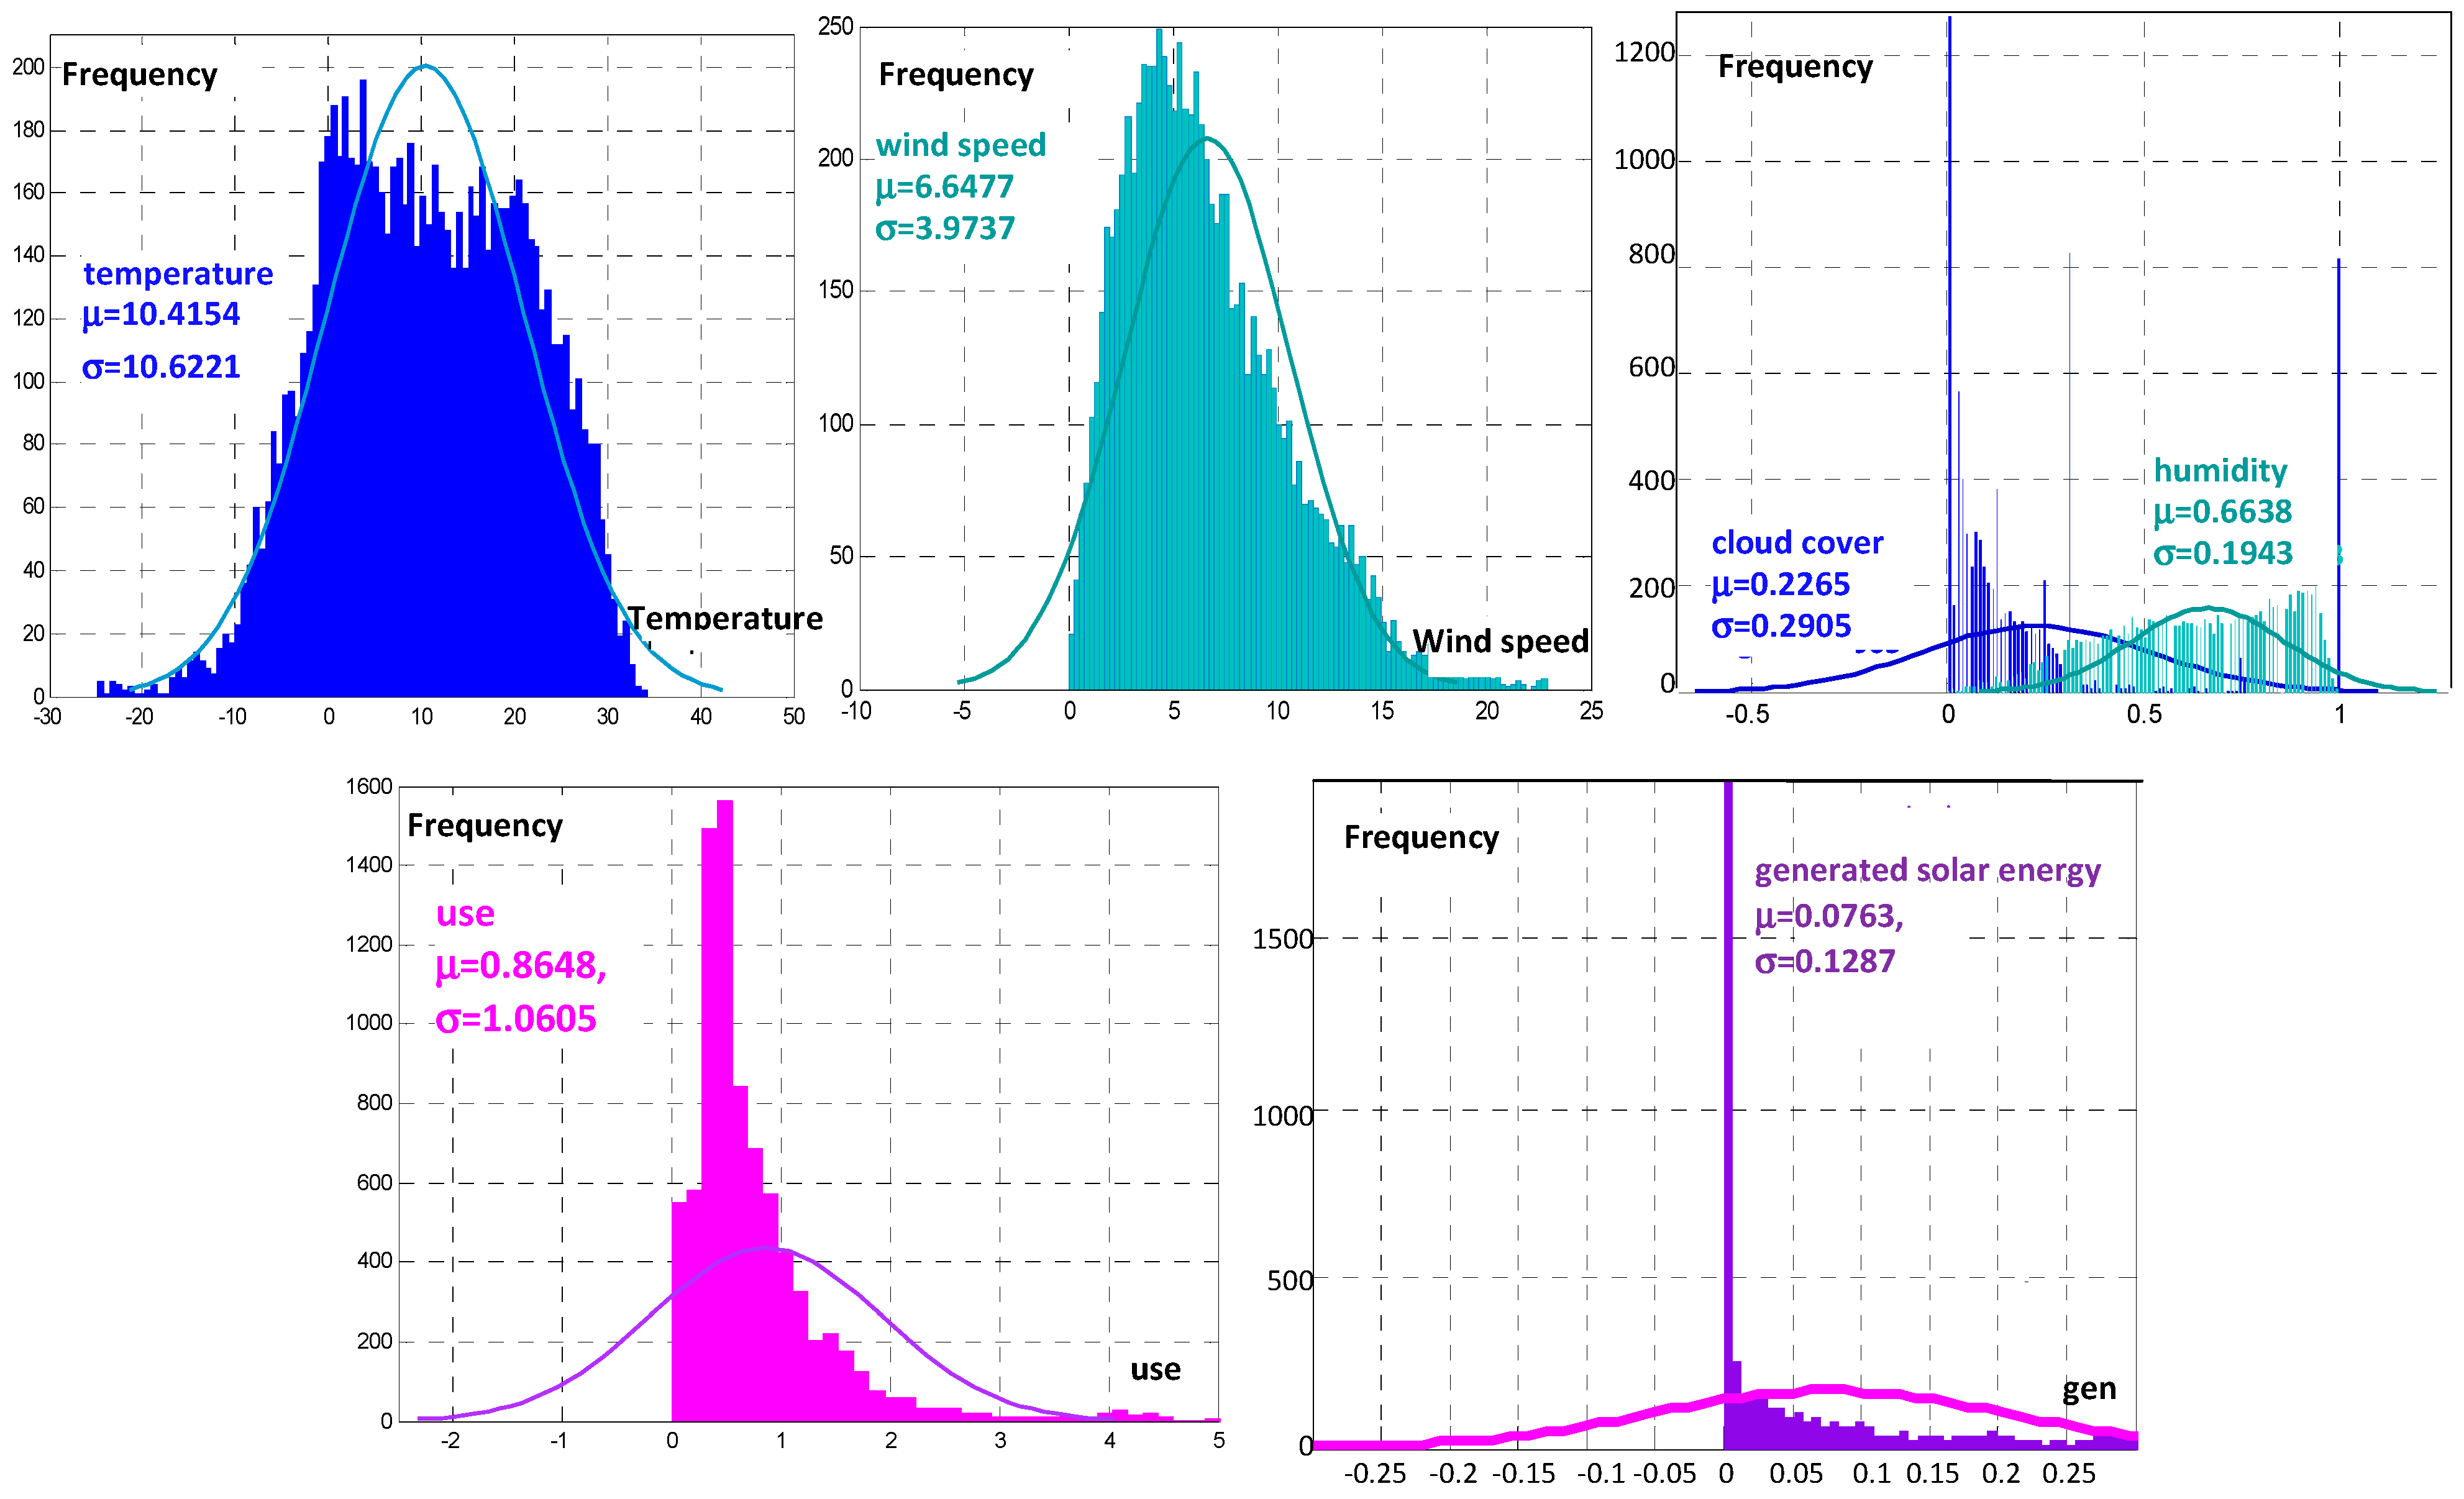
histfit(variable) computes the histograms in
Figure 2.
The mean values µ and the standard deviation σ are computed by another function [µ,σ] =
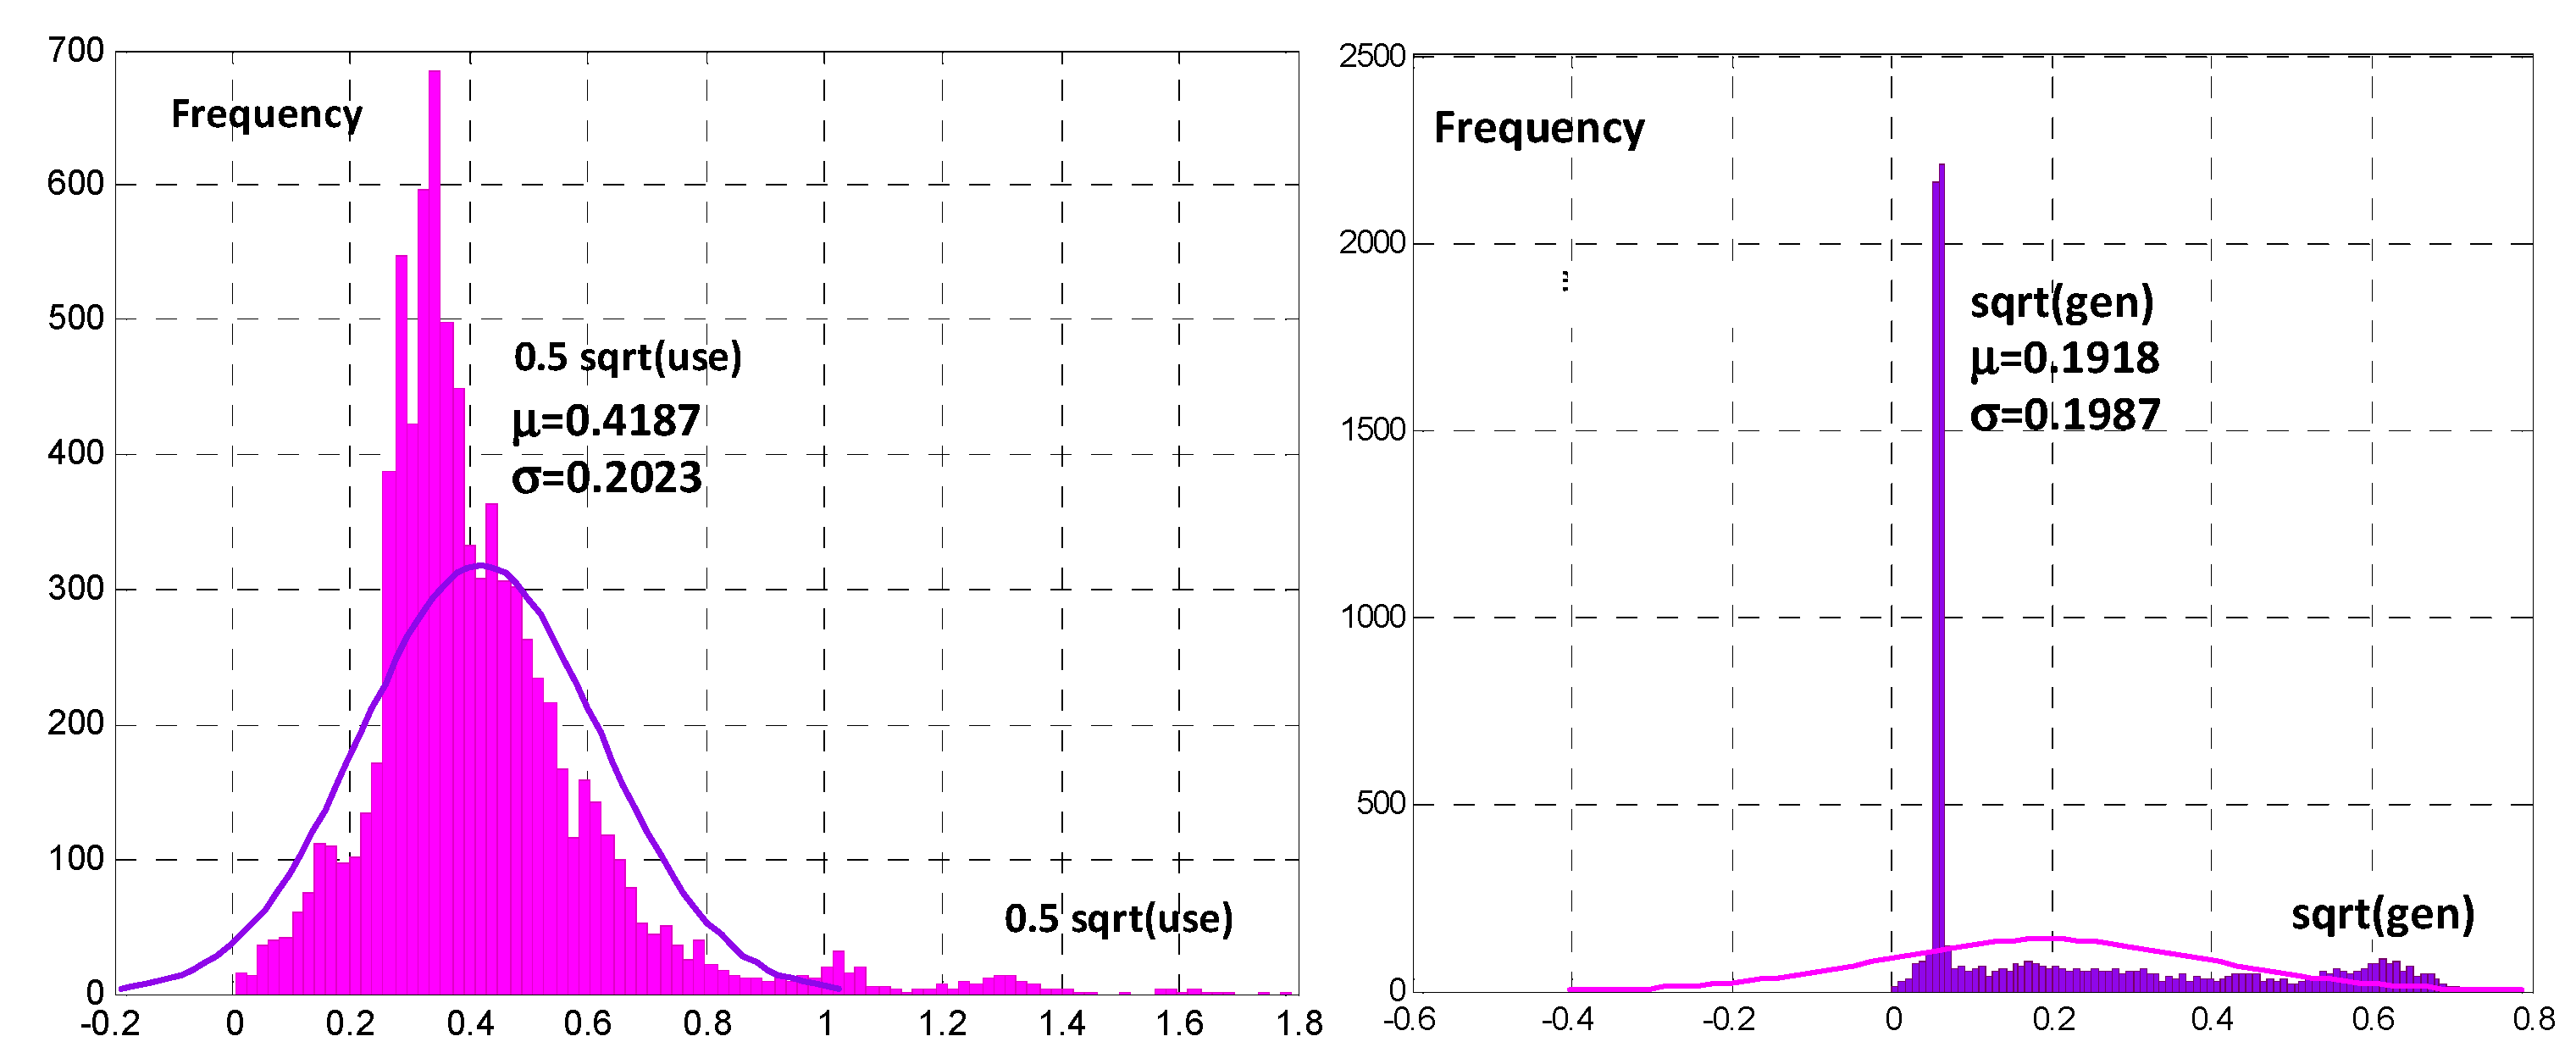
normfit(variable). The normal distribution test fails for some of the variables, as they have only positive values, except for temp, and the standard deviation σ is greater than the mean value µ, σ > µ, except for hum and wind. So, the negative interval (µ − 2σ) should contain a half of the 95% of the variable values due to the symmetry, as the range [µ − 2σ]–[µ + 2σ] covers 95% of the normally distributed data, typically leaving 2.5% in the lower tail and 2.5% in the upper tail. The normal distribution is perfectly symmetric about its mean. This means that the bell-shaped curve is a mirror image on either side of the centre, with 50% of the data falling below the mean and 50% above it. The visual test via the histograms in
Figure 2, however, allows us to assume a near-normal distribution, presented by the best fitted Gaussian curve shown. The transformations of the “use” and the “gen” datasets reduce the peaks and approach the normal distribution, as seen from the last two histograms, the changed µ and σ.
The Pearson test for correlation among the potential inputs In = [temp hum wind cloud] shows a weak correlation between hum and wind (R = −0.45, p = 0) and between hum and cloud (R = 0.36, p = 0), so the impact of hum can be represented by the wind and cloud variables.
The correlation between the target “use” and each of the potential inputs In
use = [gen temp hum wind cloud] of the use MLP model and the correlation between the target “gen” and each of the potential inputs In
gen = [temp hum wind cloud] of the gen MLP model are studied using the Pearson and Spearman test in Matlab
TM, [R, p] =
corr(T, In, ‘Type’, <‘Spearman’>) and the stepwise regression ([B,SE,p, Inmodel] =
stepwisefit(T, In). The results are shown in
Table 1, where the significant input variables are shown in bold. The statistically significant (
p < 0.05) small values for
R show a nonlinear correlation. The grey-backgrounded variables are possible inputs with small impact on the target.
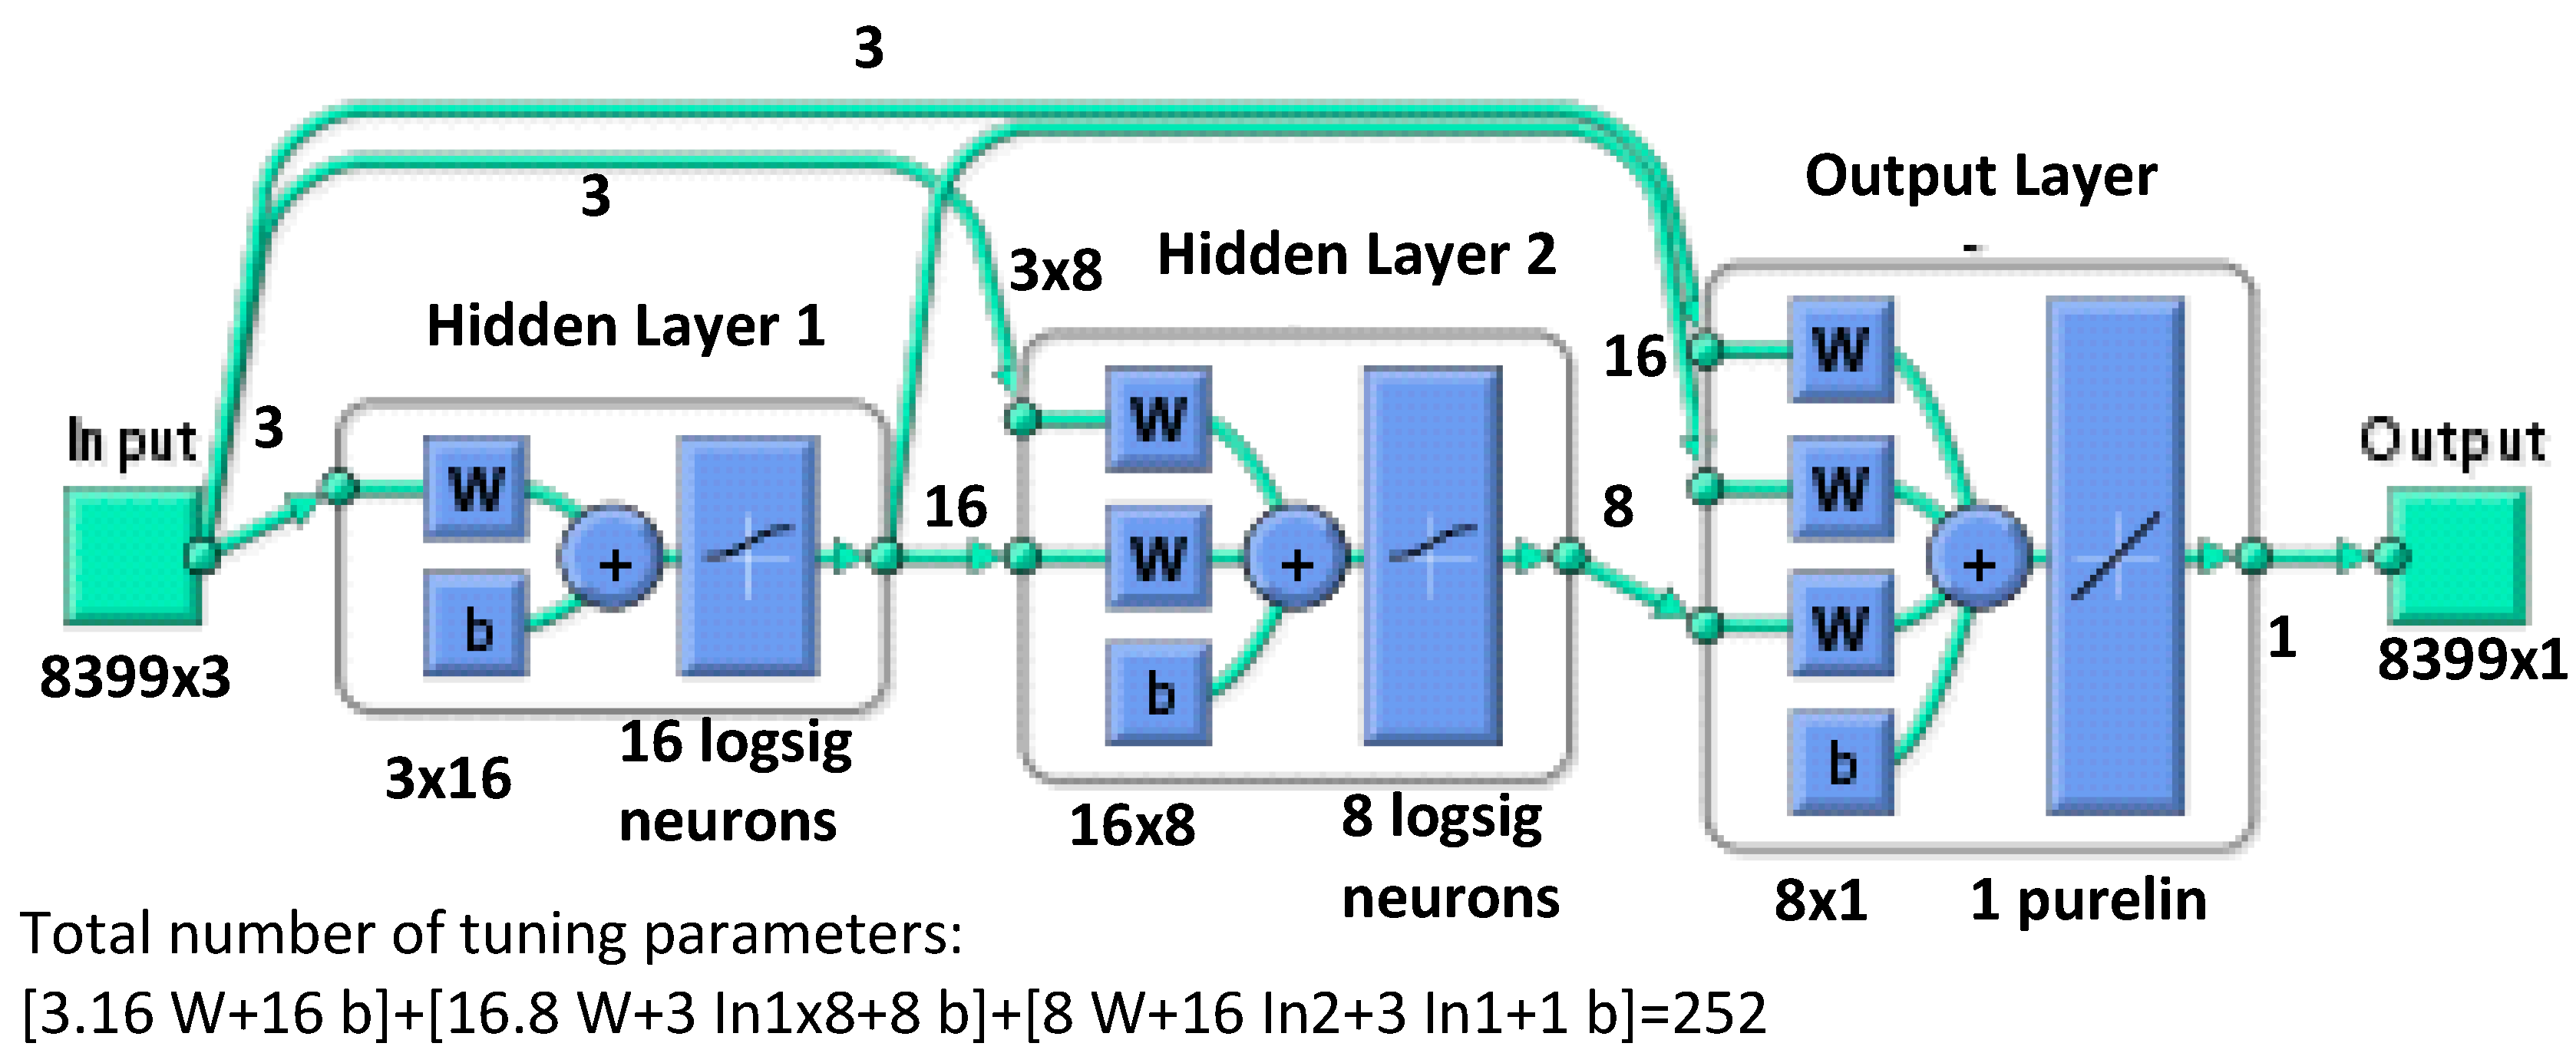
Cascade-Forward Network (CFN) architecture is selected to better model a function with peaks. Every layer of neurons in the CFN is associated with all preceding layers of neurons, directly linking their inputs to all neurons, as seen in
Figure 3. This architecture helps the ANN better catch both linear and nonlinear relations, handling “difficult” data by sending the inputs directly to the output to capture peaks. The CFN relies on the standard supervised backpropagation algorithm (chain rule and gradient descent) to compute the error and update weights and biases iteratively during training. Because the direct connections allow error signals to propagate more quickly from the output back to earlier layers, these networks converge (learn) faster than a standard MLP. For a small dataset, the large number of interconnected weights (especially as the network grows deeper with cascade connections) may cause overfitting.
The activation functions of the neurons in the hidden layers are also simple and the most commonly used, the saturating and smoothing logsig and tansig, and the shaping of the output peaks poslin (piecewise linear, similar to ReLU). The activation function of the output neuron is pureline. The cost function is MSE.
The MLP is trained using the Levenberg–Marquardt fast algorithm with a parameter for normal and high aggressiveness, mu = 0.01 or 0.001. The small value of mu may cause smoothing of the peaks in the output. The other training parameters are random selection of 70% of the data for training, 15% for validation, and 15% for testing. The end condition is MSE > 10−6 or the reaching of a maximal number of epochs 1000.
The CFN-MLP models trained, validated, and tested are defined by the inputs and outputs in
Table 1 and simple architectures that comprise all combinations of (number of hidden layers ∈[2, 3],
nh = [8,16,32,64], and activation function ∈[logsig, tansig, poslin]). The training starts from random values for the weights and biases. The Matlab
TM default Nguyen–Widrow method is used to generate initial weight and bias values for each layer so that the active regions of the layer’s neurons will be distributed roughly evenly over the input space. The cost function is, by default, the minimal MSE. To eliminate the impact of the random initial parameters, each model is retrained 20 times by training, validation, and testing on the corresponding dataset, keeping the same in each run, starting from different random initial values for the parameters from initialisation. After each run, the model MSE is evaluated from the real target and the renormalised final model output computed from simulation for all data for the model. The model with a minimal MSE for the 20 runs and successful validation and testing with MSE from validation and from testing close to the model’s MSE is selected as the best for the architecture used. The best CFN-MLP models with good validation and testing, the smallest number of tuned parameters and MSE, and also with the highest
R are systematised in
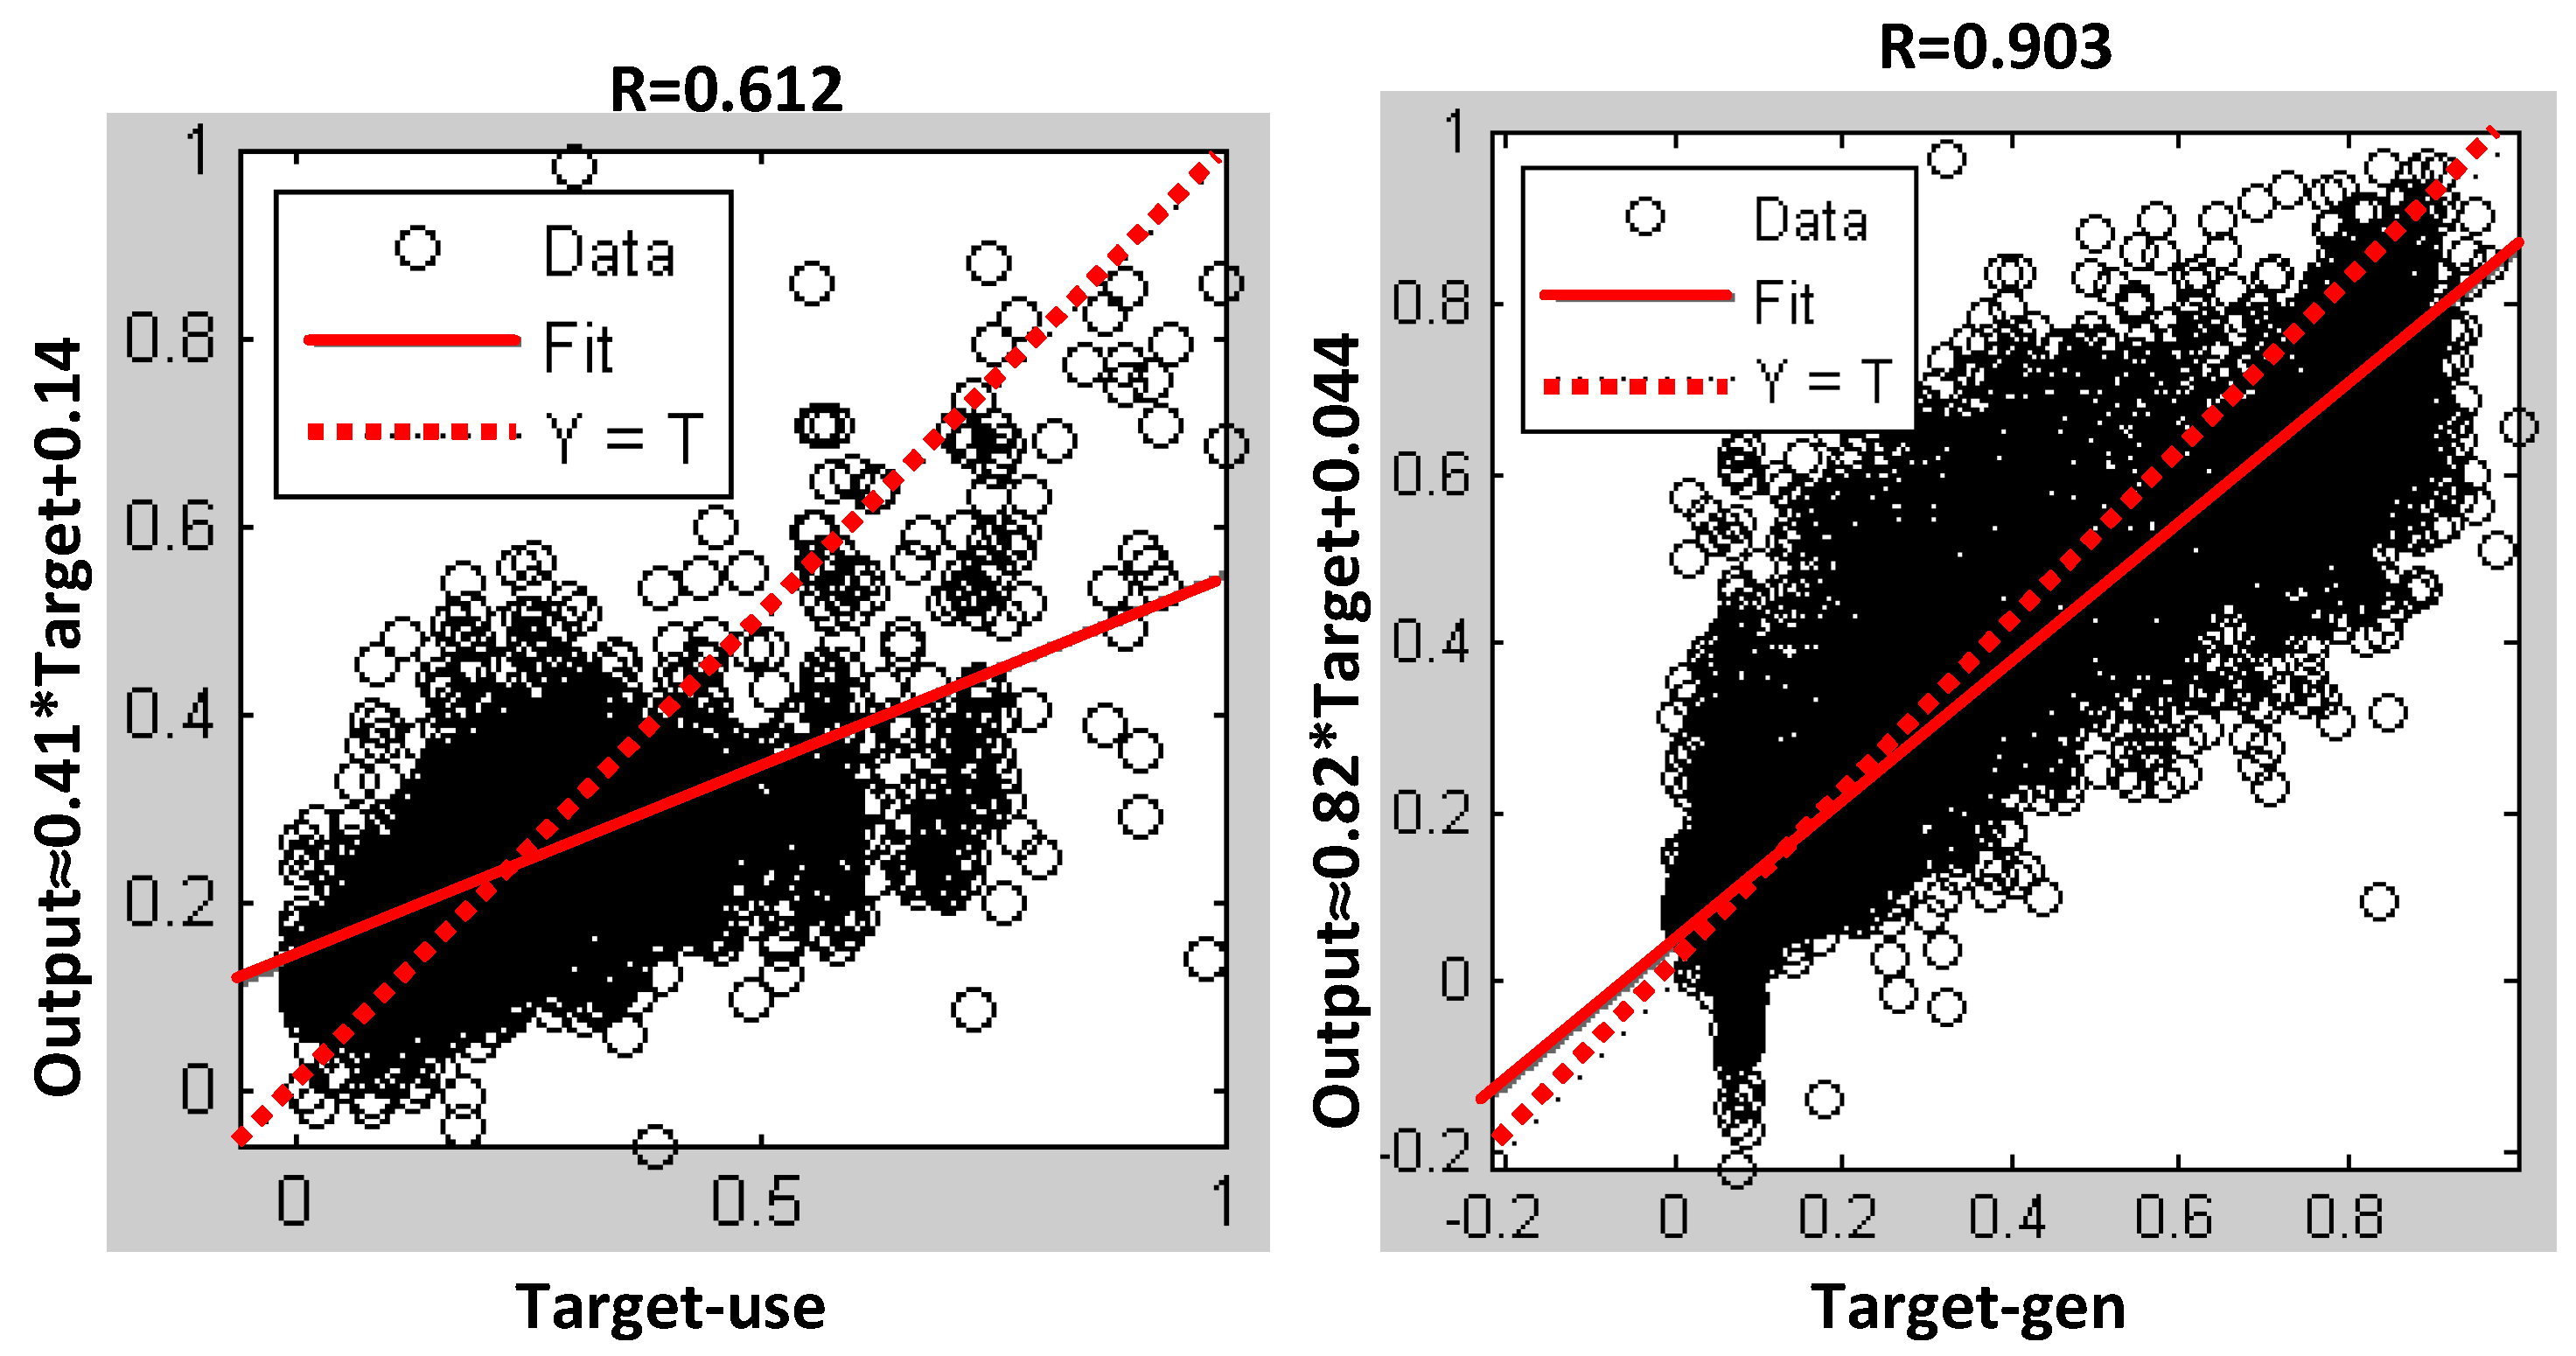
Table 2. The MSE, there, is computed from the real target and the simulated output for all the data for this model, i.e., the prediction. The correlation coefficient
R is obtained from the normalised model target
T and the normalised simulated output
Y:
where ‘•’ denotes Hadamard product (element by element),
and
are the mean values for the vectors
Y and
T, e.g.,
, and
N = 8399 is the number of measurements. The values for
R∈(0.6,0.7) for
p = 0 indicate that the ANN target data
T is satisfactorily covered by the ANN model output
Y. These values justify the use of nonlinear ANN models.