Article

A Staged PEFT Framework for Industrial Pointer-Gauge Reading with Multimodal Large Language Models

1
Zhejiang Electronic Information Products Inspection and Research Institute, Hangzhou 310007, China
2
School of Computer Science and Technology, Zhejiang Sci-Tech University, Hangzhou 310018, China
*
Author to whom correspondence should be addressed.
Appl. Sci. 2026, 16(16), 7924; https://doi.org/10.3390/app16167924
Submission received: 2 June 2026 / Revised: 23 July 2026 / Accepted: 4 August 2026 / Published: 8 August 2026

Abstract

Pointer gauges remain widely deployed in industrial environments because they are inexpensive, resistant to electromagnetic interference, and readable from a distance. However, automatic reading remains difficult in practice because reliable prediction requires jointly interpreting pointer geometry, scale layout, and unit-type consistency under challenging conditions such as glare, scratches, blur, and oblique viewpoints. Although multimodal large language models (MLLMs) offer a promising unified interface for visual understanding and structured output, their direct application to gauge reading is limited by weak geometric grounding, unit confusion, and unstable numeric generation. Rather than claiming a new model architecture or a new reading algorithm, this work frames the contribution as a practical adaptation and evaluation framework for applying existing MLLM and PEFT components to structured industrial gauge reading. Our framework combines three components: (i) a dedicated dataset and VQA-style annotation protocol covering multiple noise types and intensity levels; (ii) a unified screening pipeline for selecting a suitable MLLM backbone under zero-shot settings; and (iii) parameter-efficient adaptation of the selected model with Projector-LoRA, together with training and decoding mechanisms designed to improve reading robustness and output consistency. On our test set, the fine-tuned Granite-Vision 3.2 model achieves 99.9% type accuracy, 43.77% reading accuracy, and 43.60% joint accuracy. It obtains an MAE of 3.98 over valid numerical predictions, a parsing coverage of 98.65%, and an all-sample penalized normalized MAE of 0.052. These results substantially outperform the evaluated zero-shot MLLM baselines in structured prediction accuracy, although the lightweight CNN baseline remains slightly better in all-sample normalized numerical error.These results should be interpreted as evidence of promise and measurable improvement over untuned MLLMs, not as evidence that the system is already sufficient for safety-critical or fully autonomous industrial deployment. More broadly, the proposed framework offers a practical, traceable path for adapting large multimodal models to visual measurement tasks that require structured numerical outputs.

1. Introduction

Analog gauges and dial instruments remain common in critical industrial settings, including energy, power, chemical processing, and safety monitoring systems, because they are inexpensive, robust to electromagnetic interference, and readable from relatively long distances [1]. Yet, automatic gauge reading is still far from solved in realistic deployments. Accurate reading requires jointly resolving the geometric relationship between the pointer and scale marks and the semantic association between scale values and physical units (where the unit and the numerical range are determined by the gauge category), all under adverse imaging conditions such as glare, scratches, blur, oblique viewpoints, and cluttered backgrounds [2,3]. These factors make industrial pointer-gauge reading a structured visual measurement problem rather than a simple object-detection or regression task.
Traditional gauge-reading methods, including edge-based pipelines, Hough-transform variants, and detection–regression architectures, have shown promising performance in constrained settings, but they often generalize poorly across diverse gauge layouts, different gauge categories, and severe real-world noise [4,5]. Moreover, many existing pipelines focus mainly on recovering a numerical value, while offering limited support for closely related deployment requirements such as type identification, unit binding, abnormality rejection, and auditable output formatting. As a result, there remains a practical gap between benchmark-level reading performance and the level of robustness required in industrial environments.
Recent multimodal large language models (MLLMs) provide a compelling alternative because they can unify image understanding, instruction following, and structured output generation within a single framework [6,7]. This makes them attractive for gauge reading, where the desired output is not only a number but also an interpretable structured response conditioned on task instructions. However, directly applying general-purpose MLLMs to analog gauge reading remains problematic. Unlike broad visual question answering tasks, gauge reading depends on precise geometric grounding and numerically consistent reasoning. In practice, off-the-shelf MLLMs may rely too heavily on linguistic priors from pretraining rather than image-grounded measurement cues, which can lead to unit confusion, range misinterpretation, and unstable numeric outputs [8,9]. The central challenge, therefore, is not merely to transfer a general multimodal model to a new domain, but to adapt it so that it behaves more like a controlled and verifiable visual measurement assistant.
This paper addresses this challenge through a practical adaptation framework rather than a newly designed model architecture. Instead of treating model choice, task adaptation, and evaluation as loosely connected steps, we organize them into a closed-loop pipeline: systematic backbone screening, parameter-efficient adaptation, and robustness-oriented evaluation. This design aims to reduce trial-and-error model selection and provide a more transparent path from exploratory experimentation to deployment-oriented assessment.
Beyond the industrial application itself, the main novelty of this work lies in converting pointer-gauge reading into a structured multimodal visual measurement task and integrating backbone screening, Projector-LoRA adaptation, robustness-oriented data design, constrained numerical post-processing, and auditable evaluation into a reproducible practical framework. This framing differs from both conventional gauge-reading pipelines, which usually optimize a task-specific detector or regressor, and generic MLLM prompting, which lacks explicit mechanisms for task selection, output validation, and traceable evaluation.
Our work is motivated by three specific gaps in the current literature. First, well-documented gauge-reading benchmarks remain limited, especially those that jointly emphasize realistic industrial disturbances, structured VQA-style supervision, and split protocols designed to reduce leakage across related samples. Second, although MLLMs are increasingly used for structured visual reasoning, their adaptation to industrial gauge reading has not been studied systematically under a unified selection-and-fine-tuning pipeline. Third, prior work rarely treats auditability as a central design objective, even though industrial adoption requires explicit control over model versions, evaluation subsets, and prediction traces.
To close these gaps, we make the following contributions:
  • We construct a dedicated pointer-gauge dataset with explicit source distinctions, noise categories, and VQA-style dual-question annotations, together with a split protocol intended to support rigorous and reproducible evaluation.
  • We propose a practical staged adaptation framework, rather than a new MLLM architecture, for industrial pointer-gauge reading, in which representative MLLMs are first screened under a unified protocol, and the selected backbone is then adapted using Projector-LoRA and robustness-oriented training and decoding strategies.
  • We clarify the methodological novelty at three levels: task-level reformulation from reading regression to structured multimodal measurement, framework-level integration of PEFT adaptation and constrained decoding, and evaluation-level traceability through unified metrics and auditable prediction records.
  • We show empirically that the resulting fine-tuned system substantially improves over the evaluated zero-shot baselines on type accuracy, reading accuracy, joint accuracy, and MAE, while also supporting a more auditable evaluation workflow for deployment-oriented comparison. We explicitly treat the fact that 56.4% of samples are not jointly correct as a limitation that motivates stronger baselines, variability analysis, and human-in-the-loop deployment safeguards.
The remainder of this paper is organized as follows. Section 2 reviews related work. Section 3 formalizes the task and evaluation protocol. Section 4 describes the proposed method. Section 5 presents the experimental setup and results. Section 6 concludes this paper and discusses limitations and future directions.

2. Related Work

2.1. Pointer-Gauge Reading with Classical Vision Pipelines

Automatic gauge reading has traditionally been studied through modular pipelines that separate localization, geometric interpretation, and value computation. Early approaches rely on hand-crafted image processing, typically combining edge detection, circle/line extraction, perspective correction, and explicit pointer-angle estimation to recover the reading from the dial geometry [10,11]. Later work integrates object detectors to localize the gauge region and then applies geometric fitting, keypoint estimation, or OCR-assisted parsing to infer the final value and unit [3,4,12]. This line of research remains attractive because it is interpretable and can often be debugged stage by stage.
More broadly, the literature on Automatic Meter Reading (AMR) and Automatic Dial Meter Reading (ADMR) has established useful datasets and two-stage baselines for industrial and utility scenarios [5,13,14]. However, despite steady progress, existing pipelines still face important limitations. Their performance often depends on carefully tuned assumptions about dial appearance, viewing angle, and lighting conditions, and robustness may degrade substantially under glare, blur, occlusion, or cross-device domain shift [2,3]. In addition, many such systems are optimized primarily for numerical regression, rather than for jointly producing type, unit, and auditable structured outputs. These limitations motivate interest in more unified models that can couple visual understanding with structured reasoning.

2.2. Multimodal Large Models for Structured Visual Reasoning

Recent multimodal large language models (MLLMs) and vision–language models (VLMs) have shown strong performance on general image understanding, instruction following, OCR-related tasks, and multimodal reasoning [6,7,15,16]. Closely related benchmarks include TextVQA and ST-VQA, which require reading text in natural scenes and combining it with contextual reasoning [17,18]; DocVQA, which emphasizes document-image understanding across layouts [19]; and PlotQA, ChartQA, and InfographicVQA, which focus on extracting structured information from charts and performing numerical comparison or cross-element reasoning [20,21,22]. Together, these tasks suggest that large multimodal models can serve as flexible interfaces for converting visual observations into structured textual outputs.
At the same time, evidence from chart and measurement-oriented benchmarks indicates that current MLLMs remain fragile when precise numerical consistency is required. Their outputs can be sensitive to prompt wording, chart type, and latent linguistic priors, even when the underlying visual evidence is relatively clear [8]. This issue is especially relevant for pointer-gauge reading, where correct prediction depends on a tightly coupled geometry–scale–value relationship rather than on semantic plausibility alone. Therefore, although general-purpose MLLMs provide an appealing unified backbone, they do not directly solve the industrial gauge-reading problem without task-specific adaptation and evaluation control.

2.3. Positioning of This Work

Our work is most closely related to two streams of prior research: specialized gauge-reading systems and multimodal models for structured visual reasoning. Relative to classical gauge-reading pipelines, we do not seek to discard geometric priors; rather, we shift the emphasis from handcrafted stage-wise design toward a unified multimodal framework that can jointly predict gauge type, reading value, and unit under a consistent prompting and evaluation protocol. Relative to generic MLLM reasoning benchmarks, we focus on a narrower but more deployment-oriented setting in which numerical validity, type–unit consistency, and auditability are central requirements.
The main distinction of this paper lies in its methodology and evaluation procedure. We propose a staged, engineering-oriented closed loop that combines the following: (i) a dedicated dataset and VQA-style supervision protocol for industrial pointer gauges; (ii) unified backbone screening under controlled prompting and evaluation settings; and (iii) parameter-efficient adaptation together with robustness-oriented training and constrained decoding. In addition, we treat evaluation transparency and traceability as central concerns by tracking model variants, evaluation subsets, and prediction outputs within a standardized workflow, even though raw data and model weights cannot be publicly released. In this sense, this paper contributes not only a model adaptation strategy but also a practical framework for studying MLLM-based gauge reading in a more rigorous and deployment-relevant manner.

3. Problem Definition

This paper studies automated reading of pointer-type gauges in industrial scenarios. Given an image I containing a gauge, the objective is to recover a structured output that identifies the instrument category, estimates its current reading, and assigns the correct physical unit. We formalize the task as predicting a triplet ( t , v , u ) , where t denotes the gauge type, v denotes the numerical reading, and u denotes the unit.

3.1. Task Formulation

Let I denote an input image of a pointer gauge acquired from an arbitrary source, such as on-site photography, inspection video frames, or curated public datasets. The image may contain substantial real-world disturbances, including glare, scratches, blur, occlusion, and perspective distortion. The desired output is a structured triplet
( t , v , u ) ,
in which the type t is selected from a predefined label set
T = { temperature , current , pressure , voltage } ,
v is a real-valued measurement, and u is a unit consistent with the predicted type. In the current setting, the valid type–unit mappings are fixed: temperature ↔ °C, current A , pressure MPa , and voltage V .
From a geometric perspective, pointer-gauge reading depends on the relationship between pointer angle and scale value. If a gauge has measurement range [ s min , s max ] and corresponding angular span [ θ min , θ max ] , then under the common linear-scale assumption the reading can be expressed as
v ( θ ) = s min + θ θ min θ max θ min · ( s max s min ) , v [ s min , s max ] .
In other words, the model must infer the pointer orientation and interpret it correctly with respect to the category-specific scale extent and zero position. This work primarily targets common linear-scale gauges and a limited set of simple non-linear cases; highly specialized non-linear dials are left to future work.

3.2. Core Challenges

The task is challenging for at least three reasons. First, it exhibits strong geometry–semantics coupling: correct prediction depends on jointly understanding pointer direction, tick-mark layout, scale values, and unit semantics rather than on any single visual cue alone. Second, industrial images are often affected by severe disturbances such as illumination variation, reflections, stains, scratches, and partial occlusions, all of which can degrade both geometric estimation and semantic interpretation. Third, the target output must be structured, machine-parsable, and physically consistent. Unlike free-form captioning or open-ended VQA, gauge reading requires explicit control over output format, type–unit binding, and numerical validity.
These characteristics make pointer-gauge reading a structured visual measurement problem that is closely related to, but more constrained than, general multimodal question answering. Accordingly, we model it as an image-conditioned structured prediction task implemented through a VQA-style interface: the model receives an image together with task prompts and is expected to return normalized answers for type identification and reading extraction. This formulation enables the use of MLLMs while preserving evaluation compatibility with conventional accuracy and error metrics. In the present dataset, the numerical range (e.g., 0–1.6 MPa for pressure) is fully determined by the gauge type, so range awareness is implicitly learned through type recognition.

3.3. Evaluation Targets

The experimental protocol focuses on five task-level metrics: Type-Acc, Unit-Acc, Value-Acc, Joint-Acc, and mean absolute error (MAE). Type-Acc measures whether the gauge category is correctly predicted; Unit-Acc measures whether the unit is valid and correctly bound to the prediction; Value-Acc evaluates whether the numeric prediction falls within the accepted tolerance of the ground truth; Joint-Acc requires the type, value, and unit to be simultaneously correct; and MAE captures the average absolute numerical deviation. Together, these metrics reflect both semantic correctness and quantitative reading quality. To avoid overestimating numeric quality, the revised evaluation protocol additionally reports the invalid-output rate, parsing coverage, MAE over valid predictions, and penalized normalized MAE over all samples. The Value-Acc tolerance is further examined through a sensitivity analysis under multiple tolerance thresholds, so that numerical accuracy is not tied to a single tolerance choice.
Because MLLM outputs are naturally generated as text, evaluation requires a normalization and parsing stage. In our setting, the generated answer is converted into a canonical structured representation before scoring. This allows free-form model outputs to be assessed under fixed type–unit binding rules and numeric tolerance criteria, thereby improving comparability across backbones, prompts, and fine-tuning strategies. The role of the proposed framework is therefore not to make the task open-ended but to use multimodal instruction following as a controlled interface for structured industrial measurement. For stochastic fine-tuning runs, we report mean ± standard deviation across independent seeds and conduct paired comparisons on the same test samples. This supports a more conservative interpretation of the Mixed strategy and avoids relying on single-run differences alone.
In the revised evaluation protocol, invalid or empty textual outputs are treated as first-class evaluation outcomes rather than silently removed before error computation. We therefore distinguish the parsing coverage, invalid-output rate, MAE on valid predictions, and penalized normalized MAE over all samples. For penalized normalized MAE, an invalid prediction is assigned a type-determined penalty equal to the full-scale range of the corresponding gauge and is then normalized by that range. Similarly, Value-Acc is reported under strict, default, and loose tolerance settings derived from half-tick resolution, one-tick resolution, and fixed percentages of the full-scale range. This makes the numerical accuracy claims less dependent on a single tolerance choice.

4. Method

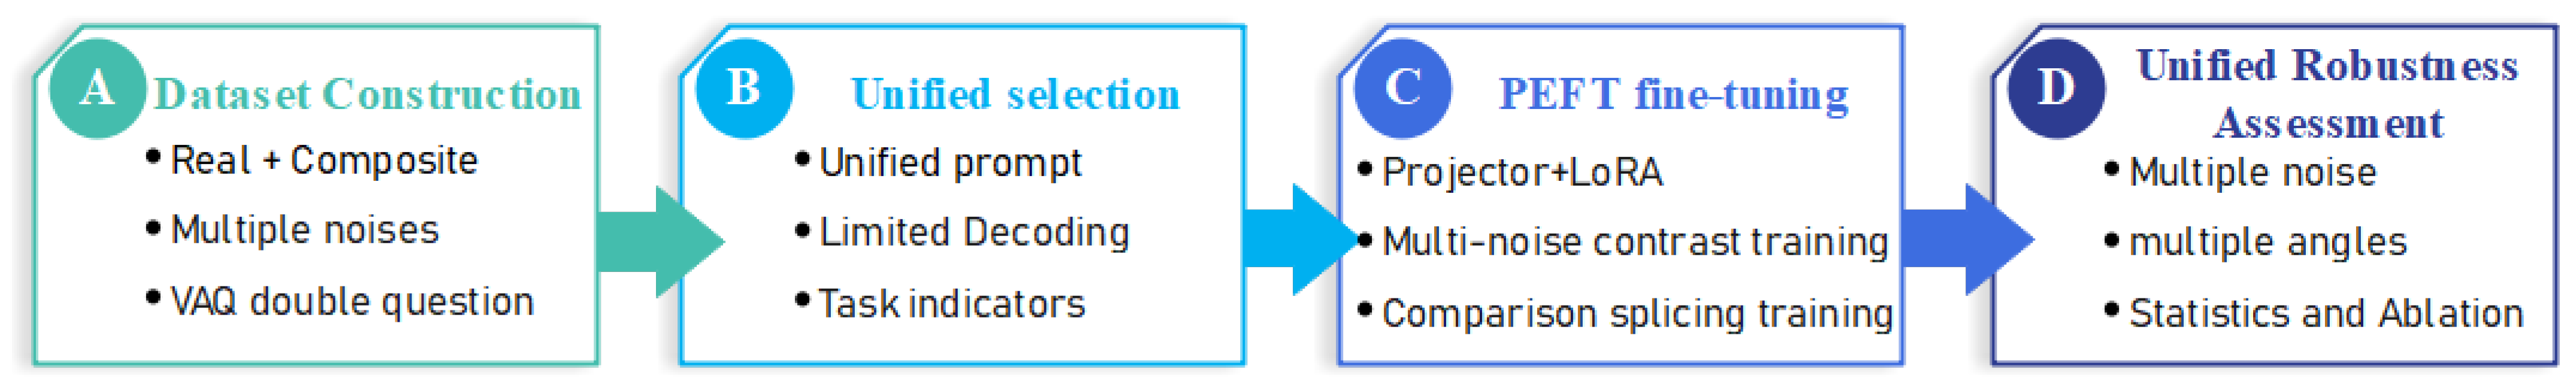
Our method aims at “traceable and evaluation-transparent model adaptation” and establishes a controlled, recoverable, and metric-auditable engineering loop across data–model–training–decoding–evaluation. First, we prepare training/validation samples and protocol-level metadata under a unified data and annotation specification. We then adopt an instruction-following multimodal architecture—“vision encoder ϕ –visual projector π –language model L ”—that projects image-patch representations into the language embedding space and, together with textual prompts, drives autoregressive generation of a structured answer ( t , v , u ) . For adaptation, we inject low-rank LoRA branches into the linear mappings of the projector, enabling cross-modal alignment and task specialization with minimal trainable degrees of freedom. During training, we introduce anti-center-cropping/resolution overriding, deterministic batching + mid-run checkpoint resumption, and per-second loss logging to ensure stability and traceability in long-running training. During inference/evaluation, we use normalized parsing and threshold-based decisions (absolute/relative tolerances), a unified metric protocol (Type/Unit/Value/Joint/MAE), and Eval-Guard (LoRA parameter fingerprints and prediction fingerprints) to build an auditable chain from the configuration to the results. The horizontal overview is shown in Figure 1, and the main dataset construction pipeline is shown in Figure 2.

4.1. Dataset and Annotation Protocol

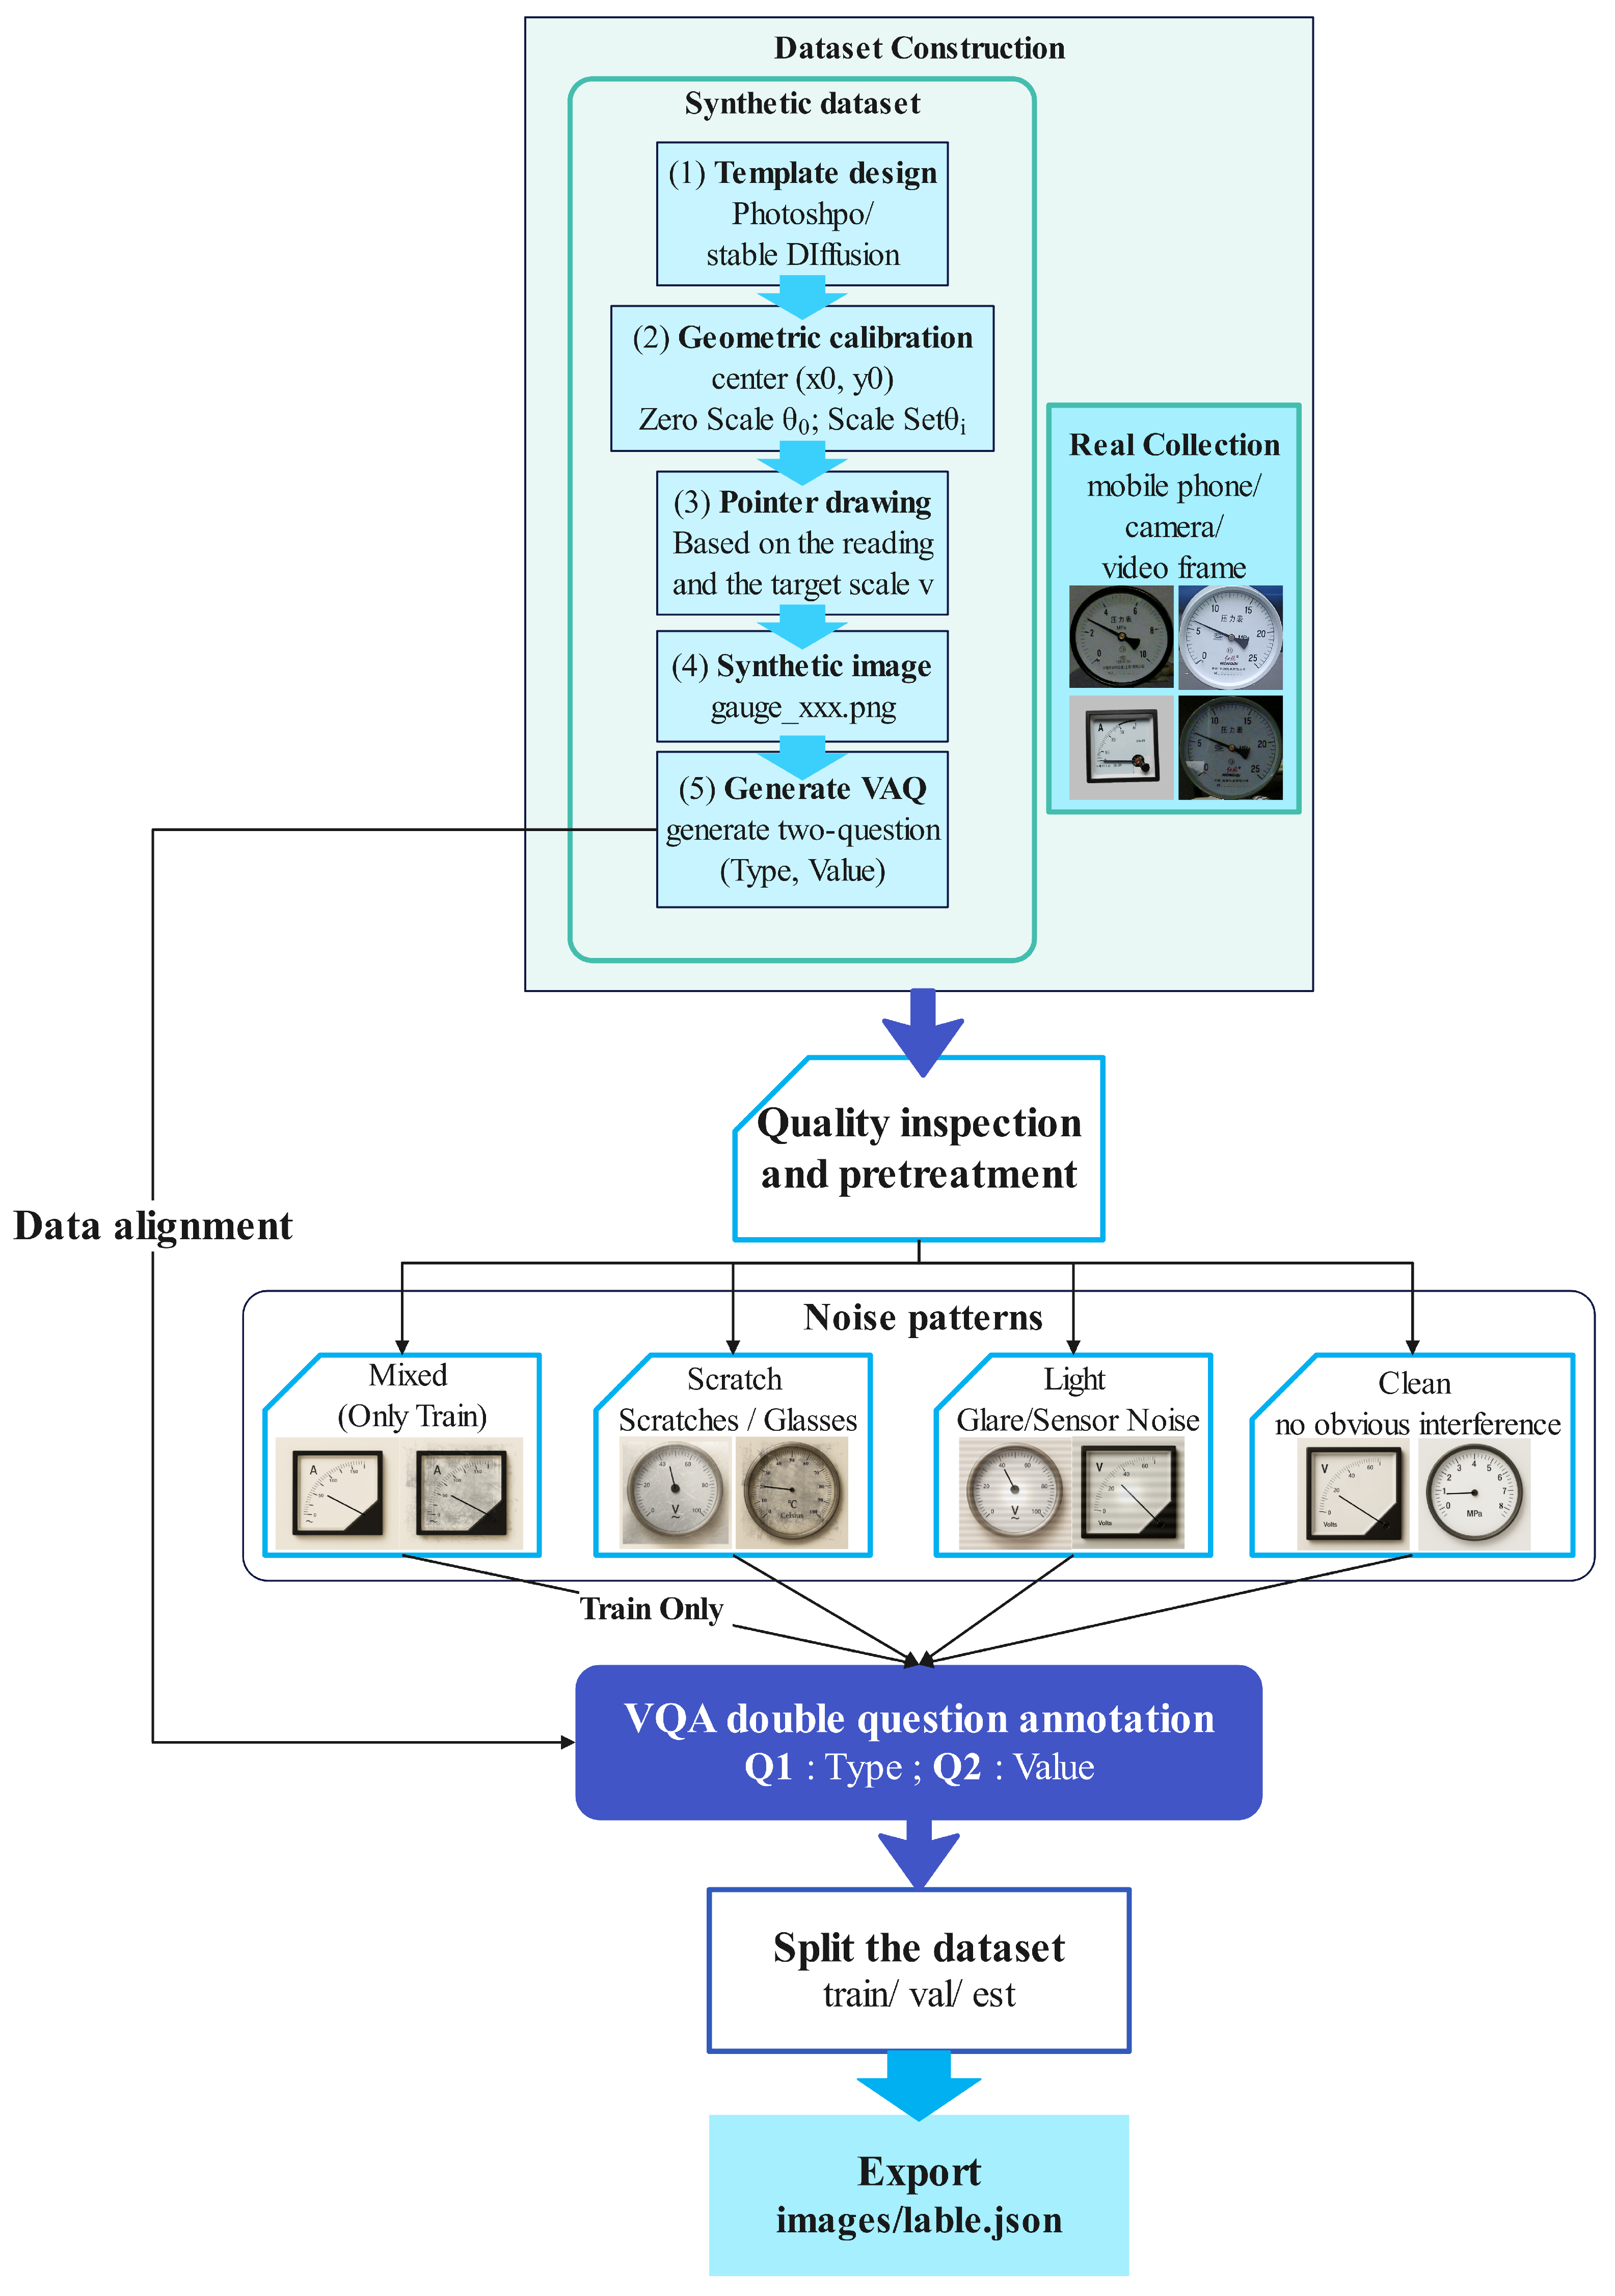
This work relies on a dedicated dataset and annotation protocol designed specifically for structured pointer-gauge reading. The goal is not only to provide enough training data for model adaptation but also to establish a reproducible benchmark that supports robustness analysis across different disturbance regimes. The overall construction pipeline is illustrated in Figure 2.
We cast gauge reading as a two-task multimodal instruction-learning problem. The first task is type identification, which predicts one label from temperature, current, pressure, and voltage. The second task is reading extraction, which produces a structured answer containing only the numeric reading and its unit, such as 15 °C, 120 V, 3.5 MPa, or 8 A. This task design matches the practical requirement of returning both semantic and numerical information, while remaining compatible with the question–answer interface of multimodal large language models.

4.1.1. Data Sources and Organization

The dataset contains two complementary sources. Self-made data (5446 images) are constructed from clean gauge images and then augmented with two controlled disturbance families: light, which captures optical effects such as glare, reflection, exposure variation, and mild blur; and scratch, which captures structural corruption such as scratches and partial occlusion. These samples provide controllable supervision for training, validation, and synthetic robustness testing. Real data (8424 images) are collected from on-site imagery and compliant public sources. To preserve a meaningful real-world evaluation subset, 20% of the real data are reserved as clean-test, while the remaining 80% are routed into the training pipeline and augmented to form additional light and scratch samples.
This organization serves two purposes. First, it reduces the gap between controlled synthetic perturbations and real deployment conditions. Second, it enables robustness analysis under aligned disturbance categories rather than mixing all noise sources into a single undifferentiated split. We therefore organize the dataset along the joint dimensions of morphology and disturbance type, as summarized in Table 1.
The mixed morphology is particularly important methodologically: it is not an additional evaluation domain but a training-time mechanism intended to expose the model to paired clean–noisy evidence and encourage disturbance-invariant representations. By separating mixed from the official dataset count, we keep the benchmark definition clear while still supporting robustness-oriented augmentation.
Each image is associated with two annotated questions under minimal decidability constraints. For type identification, the answer space is limited to the four predefined categories. For reading extraction, the answer must follow a normalized number + unit format. In addition, type and unit are bound by fixed physical correspondences: temperature ↔ °C, pressure ↔ MPa, voltage ↔ V, and current ↔ A. These constraints help convert open-ended multimodal generation into a controlled structured prediction task.
To clarify the overall composition of the benchmark, Table 2 reports the contribution of self-made and real data.
To prevent leakage, all splitting was performed on the original base images before any augmentation. Images derived from the same base (e.g., the clean version and its light and scratch variants) are always assigned to the same split. The real-clean images reserved for the clean-test set were never used in training or validation, even indirectly through augmentation.

4.1.2. Scale and Distribution (Total Images = 13,870)

The scale of the dataset is organized to support both standard training and disturbance-specific evaluation. For the self-made subset, the clean, light, and scratch morphologies are explicitly tracked across train, validation, and synthetic test splits, as shown in Table 3. This design makes it possible to examine whether robustness gains arise uniformly or only under selected corruption types.
For the real subset, we adopt a split policy that balances benchmark realism and training coverage. A held-out clean-test portion is kept untouched for deployment-oriented evaluation, while the remaining real-clean images are routed into augmentation-based train/validation construction. The routing statistics are shown in Table 4.
After entering the training pipeline, the real-clean subset is redistributed into aligned clean, light, and scratch morphologies. The approximate train/validation breakdown is reported in Table 5. Although these values are approximate because of proportional routing, they make the training composition transparent and reproducible.
Combining the self-made and real subsets yields the final Train/Val/Test distribution summarized in Table 6. The resulting benchmark preserves a clean evaluation domain, disturbance-specific robustness subsets, and a training distribution that benefits from both controlled augmentation and real-image coverage.

4.1.3. Dataset Showcase

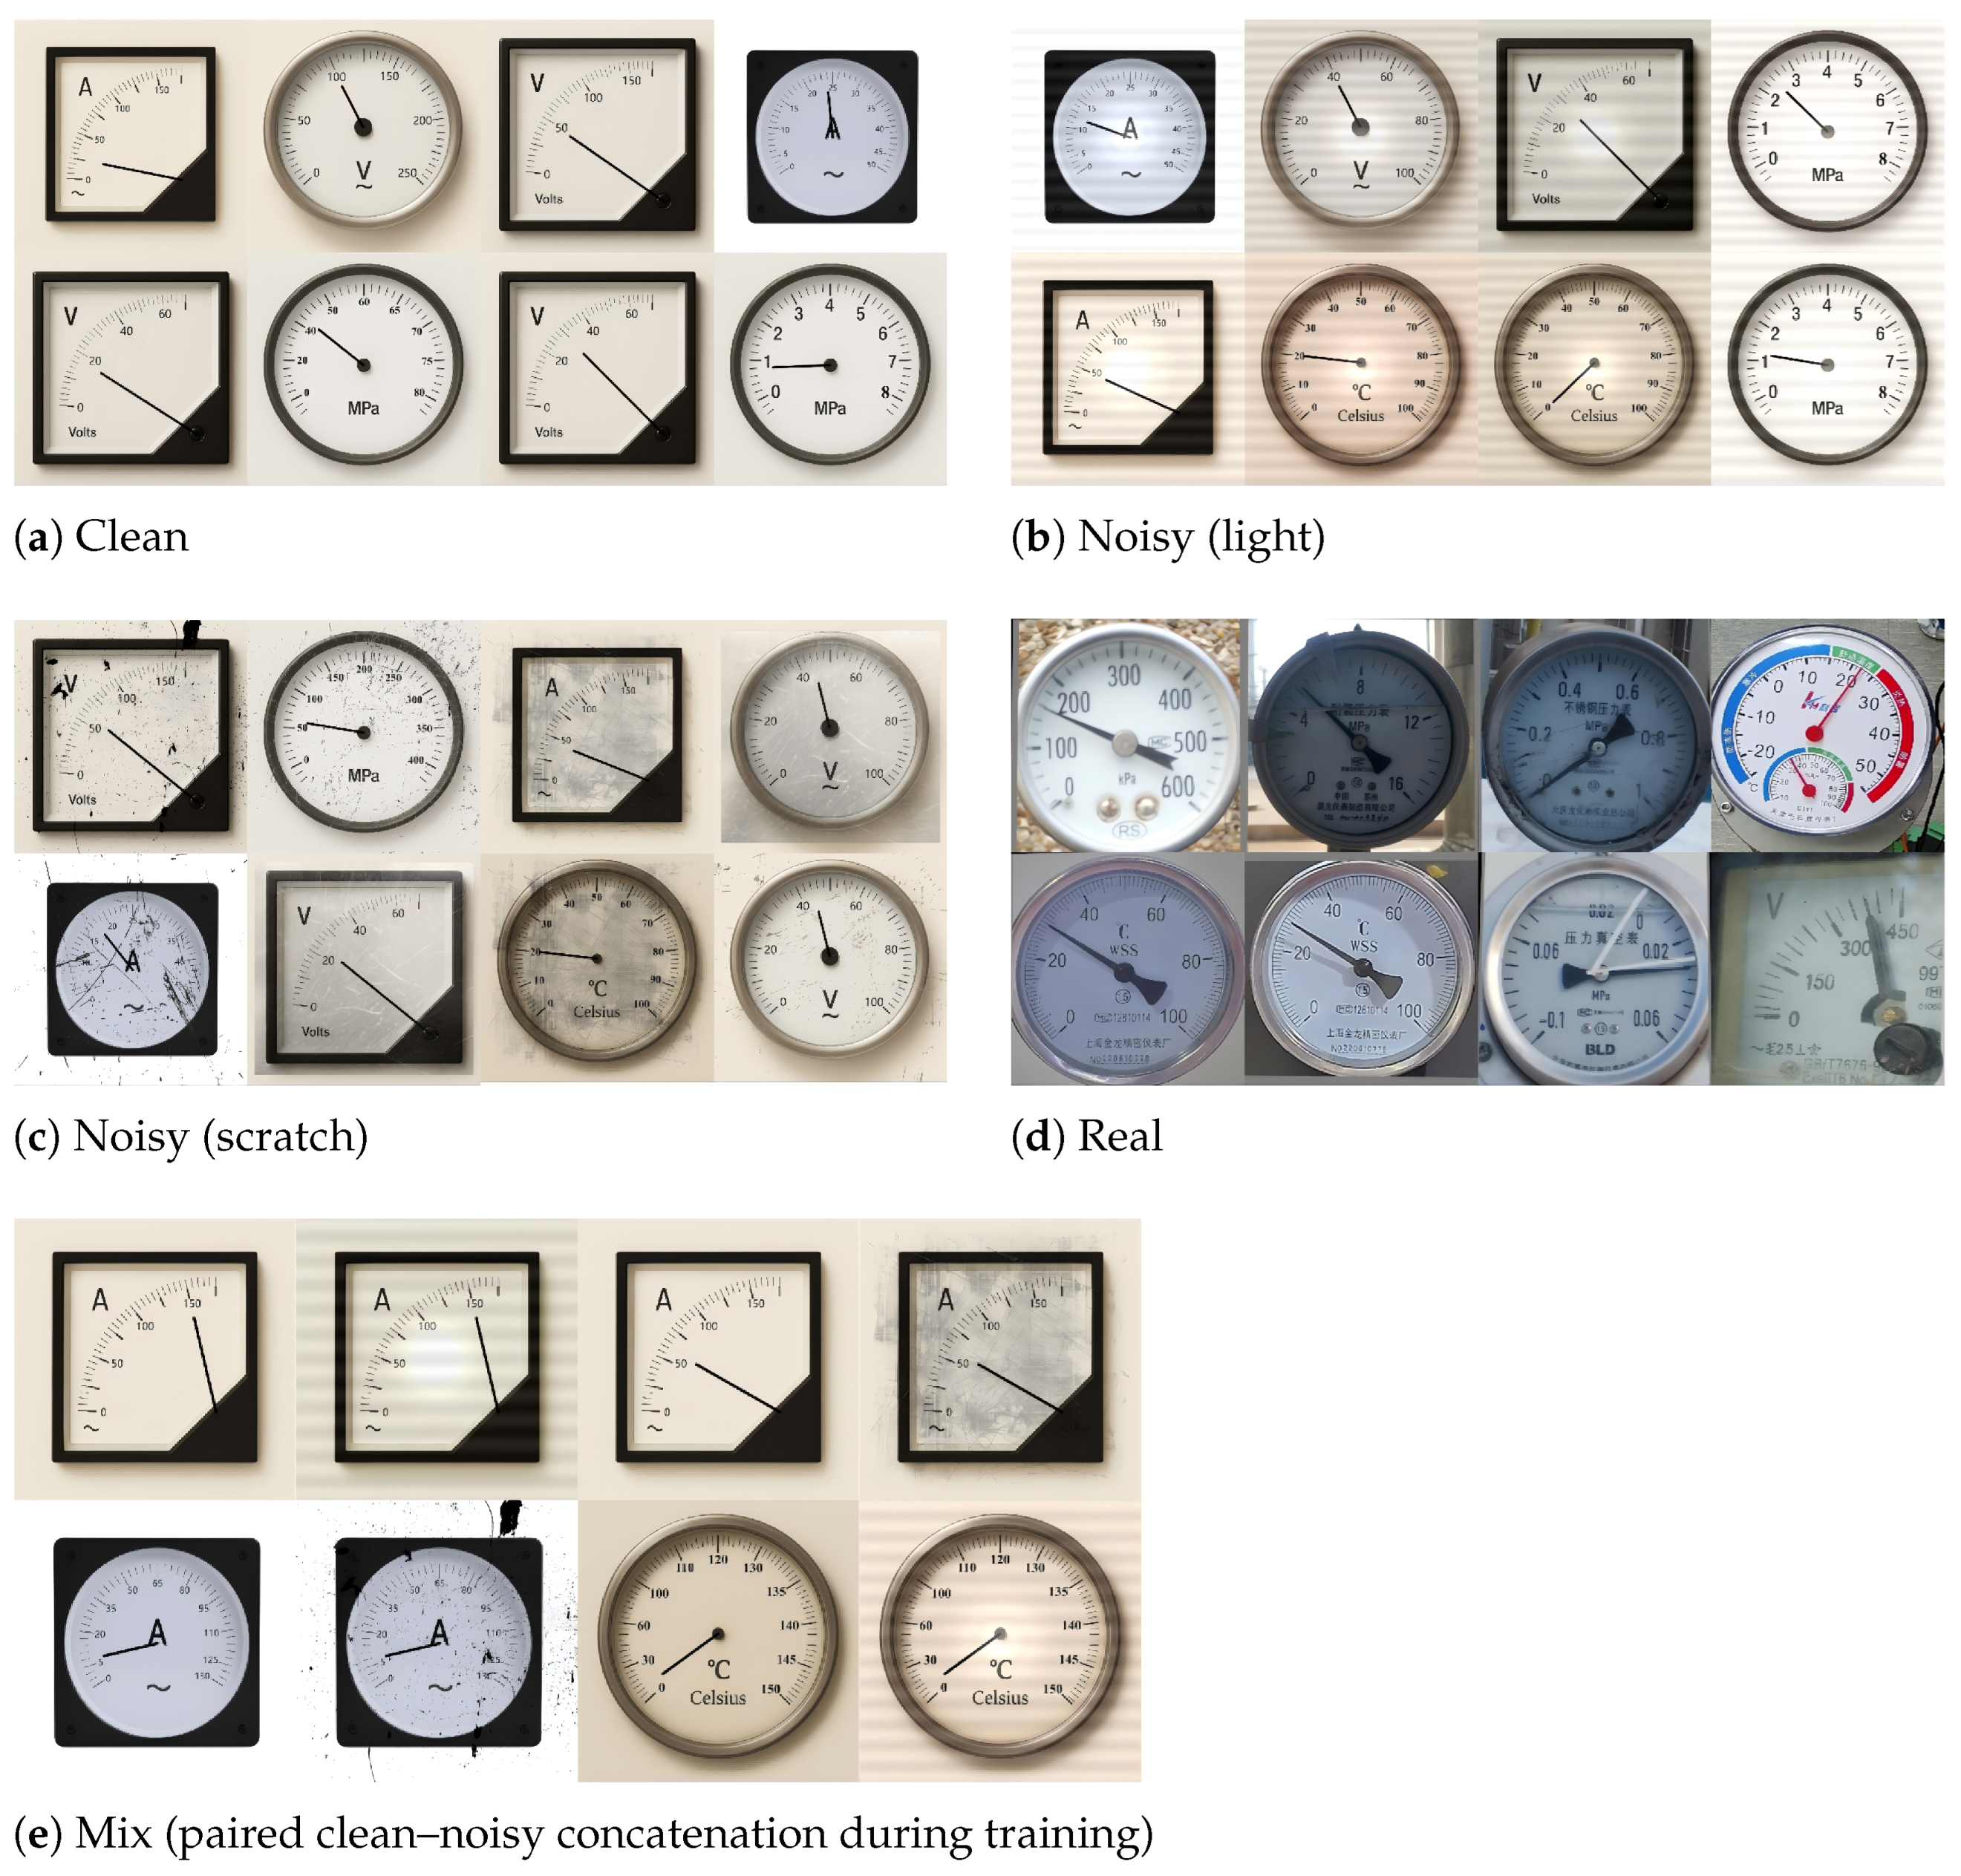
Figure 3 provides representative examples from the main dataset morphologies. The figure is intended to give an intuitive sense of the visual diversity of the benchmark rather than to serve as a statistical summary. Clean samples illustrate standard acquisition conditions, light samples emphasize illumination-related corruption, scratch samples highlight structural degradation, real samples reflect deployment-oriented capture conditions, and mix samples visualize the paired clean–noisy concatenation strategy used during training.

4.2. Multimodal Architecture and Projector Fine-Tuning for Pointer-Gauge Reading

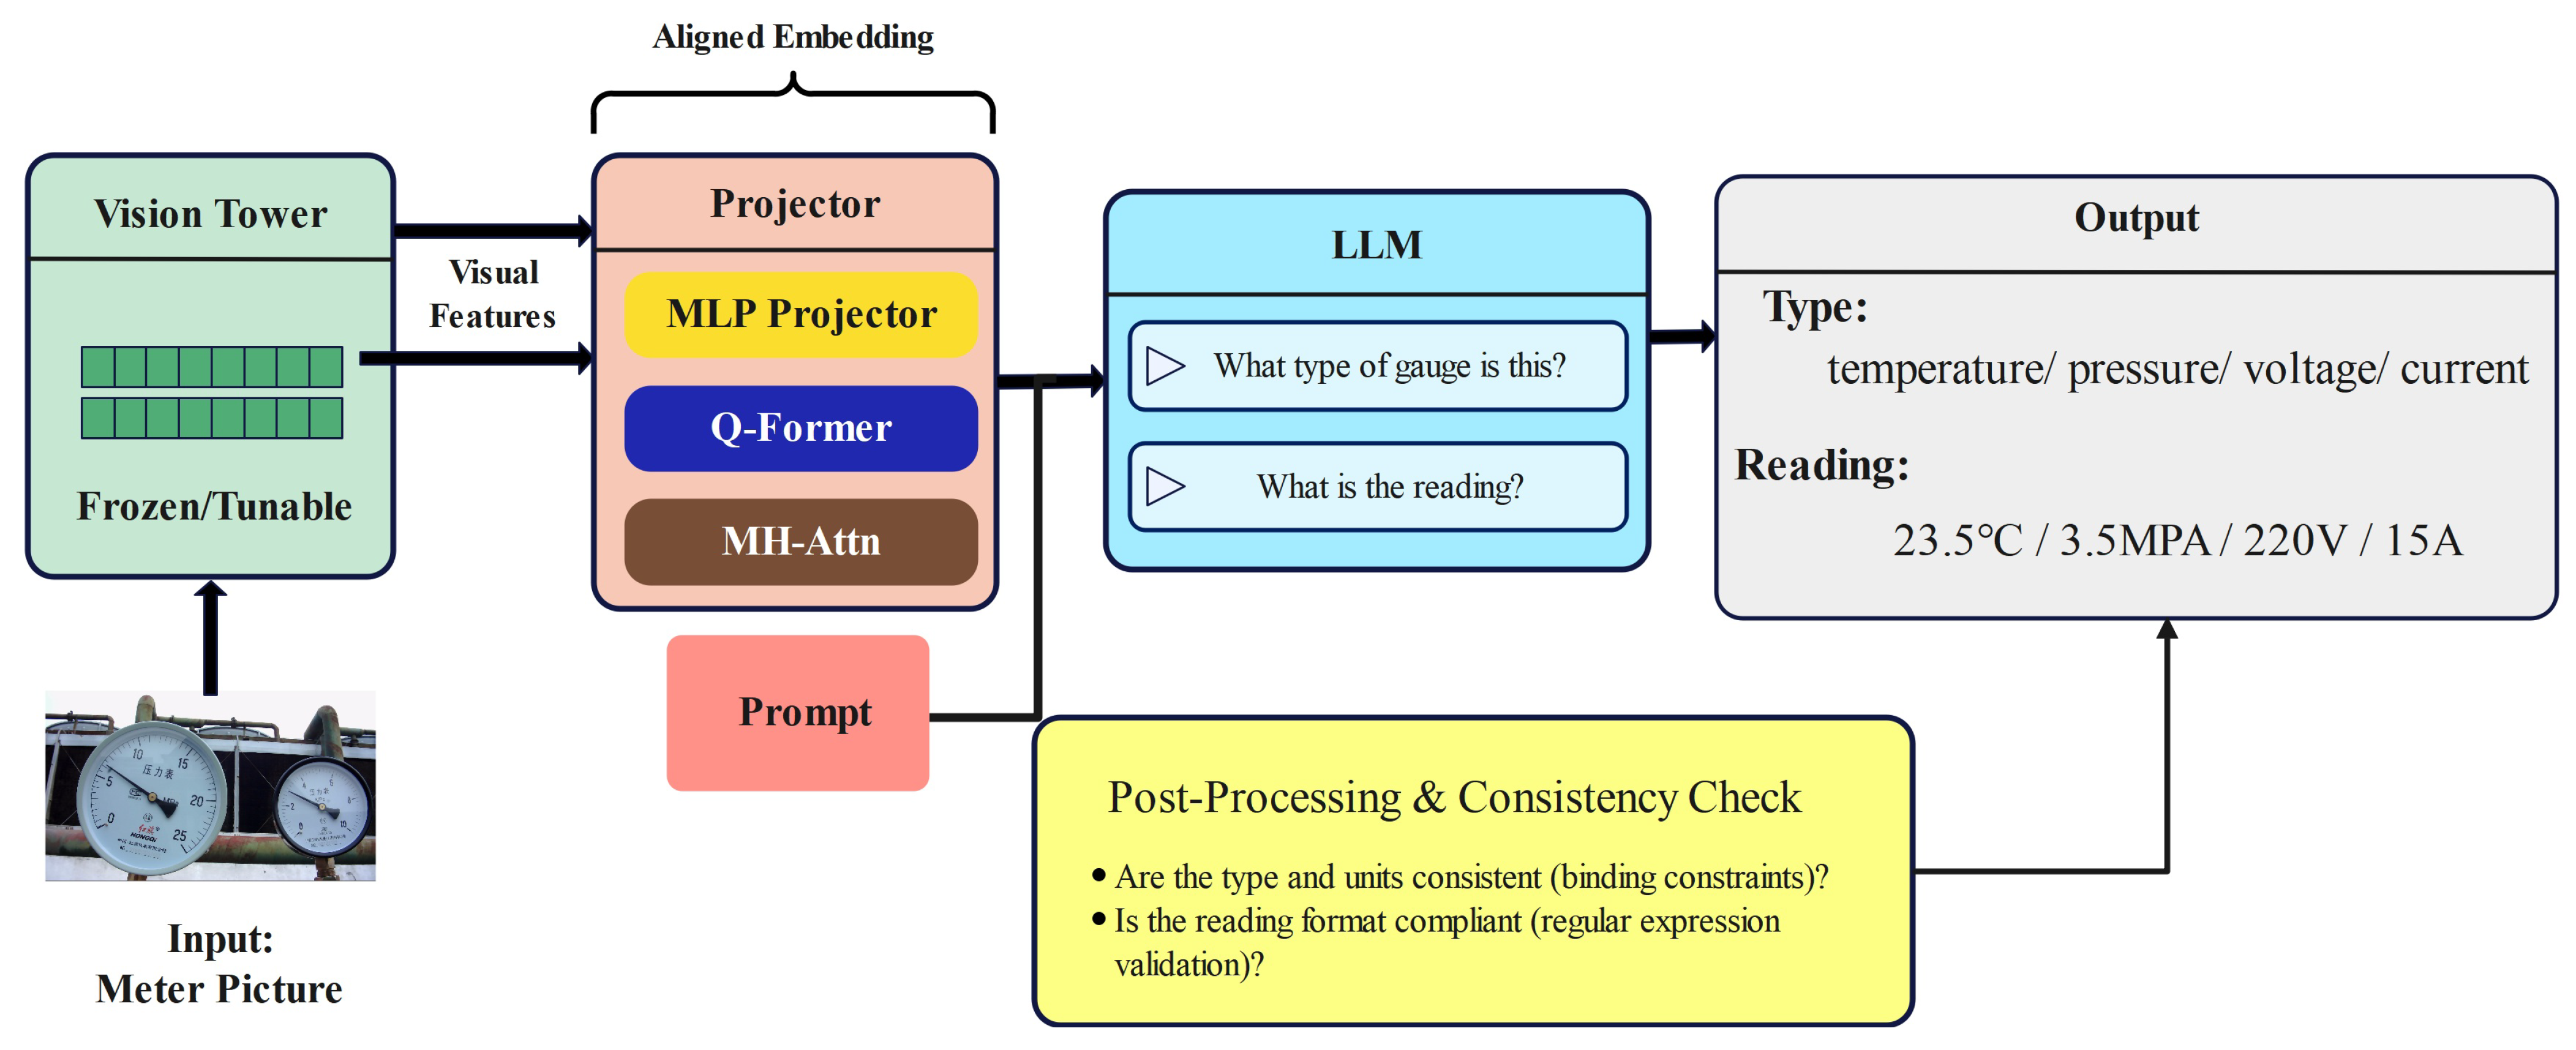
The proposed model is built on Granite-Vision and is designed to convert a gauge image into a structured prediction rather than an open-ended description. Figure 4 summarizes the workflow. The key design principle is alignment: the problem definition, prompt format, trainable parameters, and post-processing rules are deliberately chosen so that the model is optimized for structured gauge reading rather than for generic multimodal conversation.
Figure 4 is intended as a conceptual overview of the visual–language alignment stage. The Q-Former and multi-head-attention blocks illustrate alternative connector designs, whereas the Granite-Vision configuration used in all reported experiments employs only the two-layer MLP projector.

4.2.1. Inputs, Outputs, and Minimal Decidability Constraints

Given a gauge image x, the model is required to produce a structured prediction
f ( x ) = ( t ^ , v ^ , u ^ ) ,
where t ^ T denotes the predicted gauge type, v ^ R denotes the predicted numerical reading, and  u ^ denotes the predicted physical unit. Operationally, this triplet is generated through two coordinated VQA-style queries: the first query predicts t ^ , while the second query generates the reading string from which ( v ^ , u ^ ) are parsed.
To make the task decidable and auditable, we impose fixed output constraints. The type answer must belong to the predefined category set, and the reading answer must follow a normalized number + unit pattern. We additionally enforce fixed type–unit bindings,
temperature ° C , pressure MPa , voltage V , current A .
These constraints are important because they reduce ambiguity in both training and evaluation, and they ensure that the multimodal model is judged as a structured measurement system rather than as a free-form text generator.

4.2.2. Core Design

The underlying multimodal pipeline follows the standard Granite-Vision factorization,
x E vis v P ϕ z LLM y ^ ,
where E vis is the vision tower, P ϕ is the visual projector, and the LLM is the language-generation backbone. In the Granite-Vision configuration used here, the visual encoder is SigLIP, the connector is a two-layer MLP with GELU activations, and the language side is based on granite-3-2b-instruct. This architecture is naturally compatible with the “image + instruction → structured answer” setting adopted in our dataset protocol.
Our method focuses on the projector as the primary adaptation interface. Intuitively, when both the vision tower and the language backbone are frozen, the projector becomes the narrowest and most influential component for aligning visual gauge evidence with the token space required for structured output. Rather than fine-tuning the entire multimodal stack, we adapt this bottleneck so that generic visual representations can be better translated into the task-specific output space of gauge type and numerical reading.
Training is organized around the two-task supervision described above. For each image x i , we create one supervised instance for type prediction and one for reading prediction and optimize the autoregressive language-modeling objective
L = L type + λ L read ,
where L type supervises generation of a valid category label, and L read supervises generation of a short normalized reading string. The balancing factor λ can be fixed to 1 or tuned on the validation set.
The parameter-update strategy is intentionally conservative. The vision encoder, language model, and original projector weights are frozen. LoRA adapters are inserted only into the linear layers of the visual projector, and only the LoRA parameters are updated during training. This Projector-LoRA configuration localizes adaptation at the visual–language interface, substantially reduces the number of trainable parameters, and avoids modifying the pretrained backbone and original projector weights. It also aligns directly with the broader goal of this paper, namely to study whether a staged PEFT workflow can specialize a general multimodal model for industrial gauge reading without resorting to full-model retraining.
Prompt design is treated as part of the model specification rather than as an ad hoc implementation detail. For type prediction, the prompt asks for exactly one label from the allowed category set. For reading extraction, the prompt asks for a response in the normalized number + unit format, with the unit restricted to {°C, MPa, V, A}. This consistency between task definition, prompt wording, and training targets reduces output drift and makes the generated predictions easier to normalize and score.
Finally, we include a lightweight consistency-check stage during inference. This stage verifies whether the generated reading matches the required format and whether the predicted type and unit satisfy the predefined binding rules. If an output violates these constraints, it can be flagged as invalid or corrected under a controlled policy. In our experiments, we use the check result as part of the final evaluation protocol so that reported performance remains consistent with the structured task definition.

4.2.3. Summary

In summary, the first two components of the method work together as follows: the dataset defines a structured and disturbance-aware supervision space, and the Granite-Vision projector serves as the main adaptation bottleneck for mapping gauge imagery into that space. This combination allows us to preserve most general multimodal capabilities while specializing the model toward auditable, structured, and deployment-oriented gauge reading.

4.3. Parameter-Efficient Fine-Tuning (LoRA/QLoRA) and Injection Location

This subsection describes how the proposed framework is implemented under a parameter-efficient fine-tuning regime. Building on the architecture introduced above, the multimodal model can be written as
I ϕ Z R N × d v π X R N × d l L y ^ ,
where the vision tower ϕ encodes the input image, the projector π aligns visual features with the language-token space, and the language model L generates the final structured response. In the present task, this response must support both type identification and reading extraction, so the adaptation strategy must improve cross-modal alignment without unnecessarily disturbing the general capabilities of the backbone.
From this perspective, the projector is the most natural PEFT target. It acts as the narrow interface between visual evidence and language-space reasoning and therefore largely determines whether pointer geometry, scale layout, and textual unit cues are translated into a representation that the language model can use reliably. Adapting this interface is substantially cheaper than updating the entire multimodal stack, while remaining closely tied to the structure of the target task.

4.3.1. Projector Mechanism: From Dimension Alignment to Semantic Bridging

From a modeling perspective, the projector does more than match feature dimensions. Its practical role is twofold:
1.
Dimension alignment: map d v -dimensional visual representations into the d l -dimensional language representation space, ensuring that visual tokens can interact with text tokens within the same Transformer;
2.
Semantic bridging: re-encode task-relevant visual evidence (pointer direction, scale distribution, digit characters, unit symbols, etc.) into an intermediate representation that is more “readable” to the LLM, thereby improving the determinism and format stability of the generated answers.
Because the projector is much smaller than the vision tower and the LLM, direct projector adaptation offers an attractive trade-off between effectiveness and cost. In this work, we therefore use projector-centered PEFT as the main adaptation path, with the explicit goal of improving how “geometry–value coupled” evidence is transferred from the visual encoder to the language model.

4.3.2. LoRA/QLoRA: Further Minimizing the Fine-Tuning Cost

Although projector-only fine-tuning is already lightweight, even tighter PEFT variants are desirable when memory is limited or when adaptation must be extended to selected additional modules. For this reason, we also consider LoRA/QLoRA as optional implementations of the same adaptation principle.
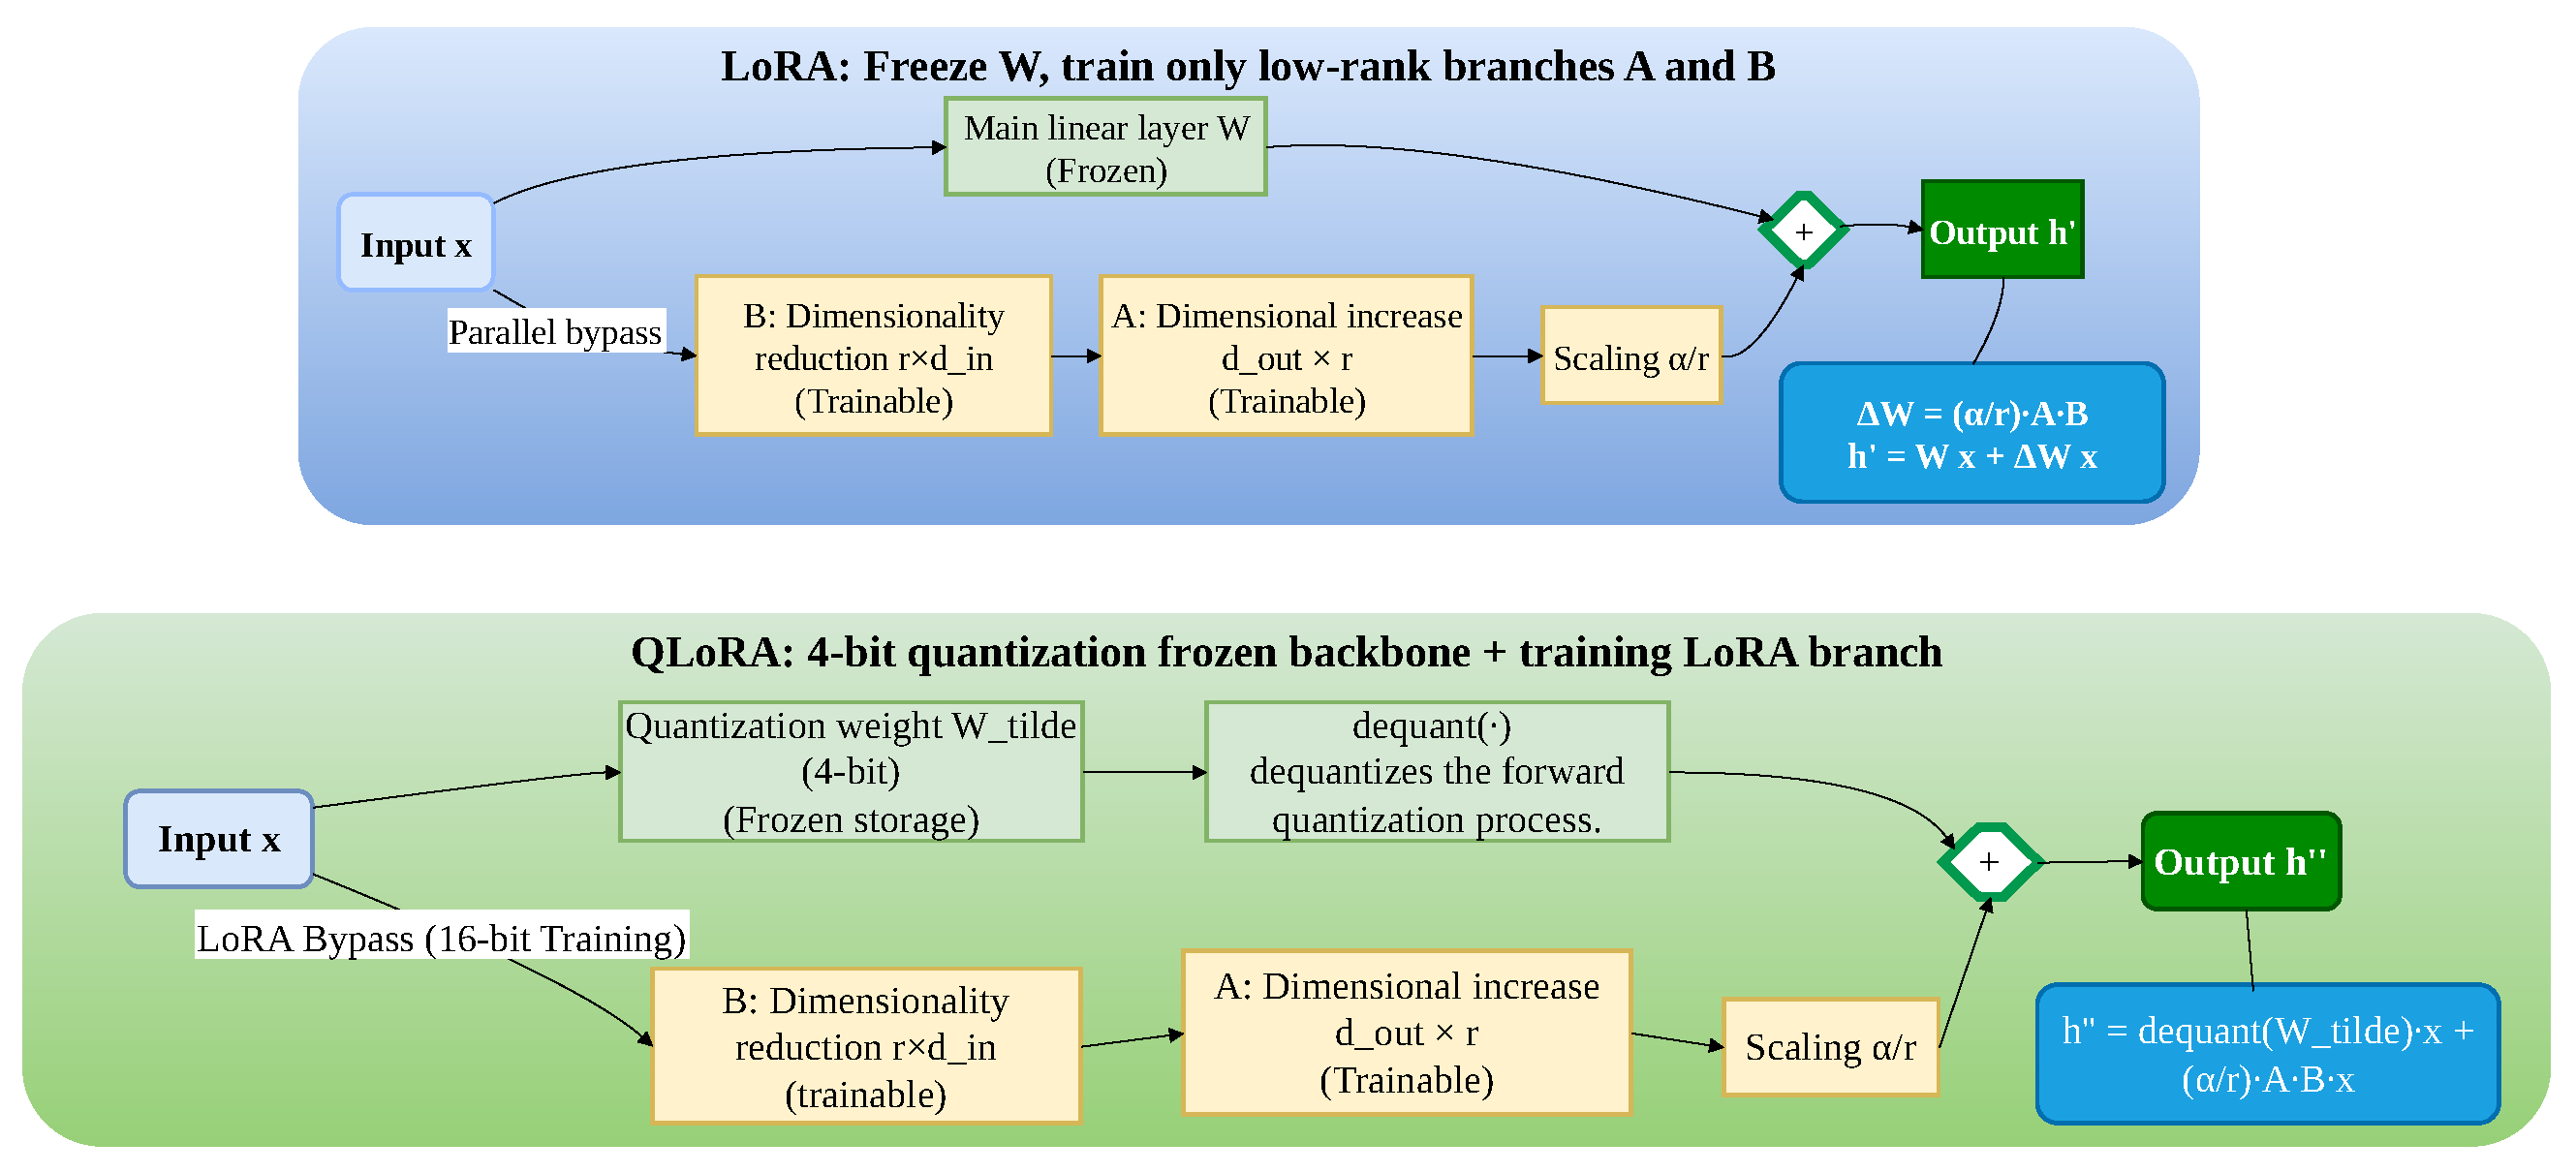
LoRA learns an incremental update Δ W via a low-rank decomposition while keeping the original weight W frozen, enabling effective adaptation with few trainable parameters [23]. For a linear layer h = W x with W R d out × d in , LoRA rewrites it as
h = W x + Δ W x , Δ W = α r A B ,
where A R d out × r and B R r × d in , r is the rank, and  α is a scaling factor. Training freezes W and updates only A , B . Since r min ( d in , d out ) , the number of trainable parameters is approximately r ( d in + d out ) , which is far smaller than full fine-tuning’s d in d out , while still providing a structured correction of the mapping and often more stable convergence.
QLoRA extends LoRA by storing the frozen backbone weights in low-bit quantized form and dequantizing them for computation during the forward pass, significantly reducing GPU memory usage while still adapting via the LoRA branches [24]. A typical form is the following:
h = dequant ( W ˜ ) x + α r A B x ,
where W ˜ denotes the quantized weight representation, and dequant ( · ) is the dequantization operator. In practice, QLoRA is commonly combined with 4-bit quantization and corresponding strategies to balance performance and resources [24].

4.3.3. Injection Location: “Projector First” as the Main Thread

As illustrated in Figure 5, we inject adapters into the projector (Projector/Connector), which is the main fine-tuning target in this work. Specifically, we inject LoRA into the linear layers of the projector (denoted { W k } ) or enable QLoRA (quantized frozen backbone) under more resource-constrained settings, so that it learns a task-specialized alignment from the visual features Z to the language-space tokens X. This location directly determines whether evidence such as “pointer/scale/digits/unit” can be expressed in an LLM-usable manner; therefore, the gains are the most stable.

4.4. Data Packaging and Anti-Center-Cropping (Visibility-Related)

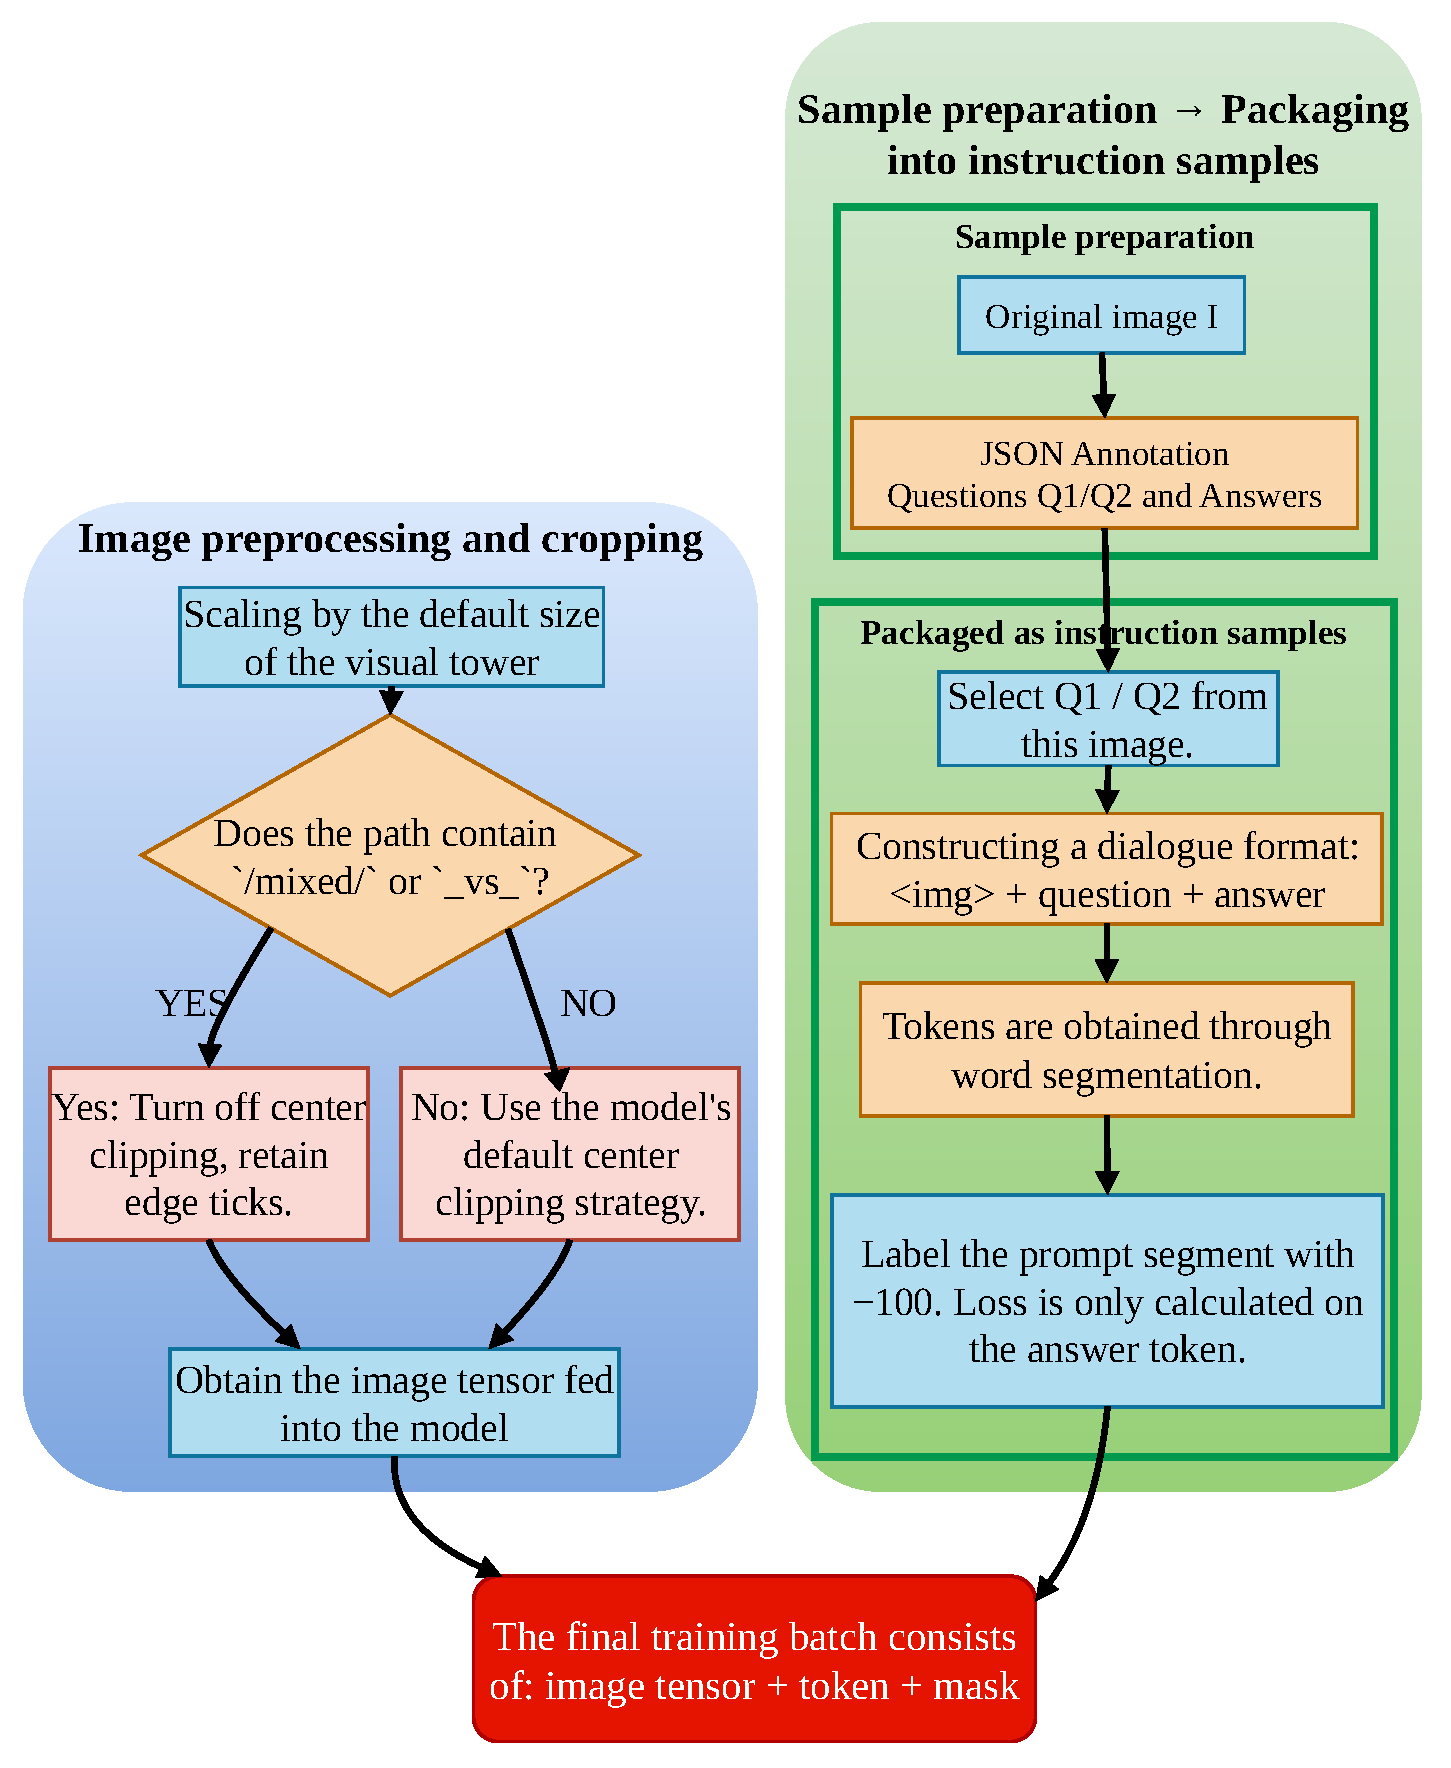
In multimodal instruction fine-tuning, we treat each gauge image as a minimal sample unit and construct up to two QA rounds around it: the first asks for the gauge type (Type), and the second asks for the reading and unit (Value+Unit). Specifically, for an image I, we construct two dialogue-style instruction samples:
  • Q1: What type of gauge is this? → A1: pressure/temperature/voltage/current;
  • Q2: What is the reading? → A2: 3.5 MPa/15 °C/120 V/8 A.
In implementation, the above QAs are expanded into a unified text sequence using the chat template provided by the model processor, e.g., <image> + user: question + assistant: answer. To prevent the model from “copying the question” during training, we compute the loss only on the answer tokens: when constructing supervision labels, we mark all prompt and question positions as −100 and assign ground-truth labels only to the answer tokens. This ensures that optimization focuses on extracting correct structured information from the image and question, rather than memorizing a particular question template.
For image preprocessing, all samples are first resized with the aspect ratio preserved to the default input size of the vision encoder. When needed, we explicitly set a higher resolution via image_size_override to improve the visibility of tick marks and pointer details. By default, many open-source multimodal backbones apply center cropping to match the pretraining distribution; however, for pointer-type gauges where critical information is concentrated near the dial boundary, center cropping can truncate tick marks or unit text, leading to insufficient visible information. Therefore, we use a conditional anti-center-cropping strategy aligned with the data-packaging pipeline in Figure 6. For paired mixed samples whose paths contain /mixed/ or _vs_, center cropping is disabled and aspect-ratio-preserving resizing is used so that both the image regions and boundary tick marks remain visible. For ordinary single-image samples, the default center-cropping behavior of the model processor is retained. This conditional design prevents truncation of the paired mixed input while avoiding unnecessary deviation from the backbone’s default preprocessing distribution for ordinary samples.

4.5. Deterministic Training and Recoverable Execution

Given the large scale of multimodal foundation models, a single training run often takes tens of hours. Since this work involves extensive comparison experiments across hyperparameters and backbone combinations, determinism and recoverability become essential parts of the engineering system. Therefore, beyond standard mixed-precision training and gradient accumulation, we introduce explicit constraints such as “deterministic shuffling by epoch + seed” and “exact mid-run checkpoint resumption”.
Specifically, we use AdamW to combine the benefits of adaptive learning rates and weight decay and employ mixed precision (e.g., FP16 or bfloat16) in forward and backward computation to reduce GPU memory usage. Because multimodal backbones incur large per-step memory costs, we use a small physical batch size together with a large gradient accumulation factor (e.g., accum_steps = 64) to emulate a larger effective batch while keeping peak memory within the capacity of a single GPU.
To ensure that each run traverses samples in exactly the same order under a fixed random seed, we construct a deterministic batch sampler for each epoch: we set a unified seed for the RNGs of Python (3.11), NumPy (2.4.0), and PyTorch (2.7.0), generate a full permutation of dataset indices based on that seed, and slice it into batches. If training must be resumed due to external interruption (e.g., power, job scheduling, or manual termination), we not only save model parameters, LoRA branches, optimizer states, and mixed-precision scaler states but also explicitly record the current epoch ID and the completed batch offset. During resumption, we reconstruct the same epoch-wise index permutation and continue from the recorded batch position, ensuring that the sample order before and after resumption is identical.
For checkpoint management, the main training loop supports periodically writing a lightweight resume file (e.g., ckpt_resume.pth) by either “step count” or “time interval”, containing all necessary model and optimizer states. When receiving SIGINT or SIGTERM, the process does not terminate immediately; it finishes the current mini-batch iteration and then gracefully saves the final checkpoint. Meanwhile, the training process appends statistics such as current loss, learning rate, and gradient norm to a CSV log at approximately 1 Hz, enabling trend visualization and anomaly detection for long-running training. At the end of each epoch, the system exports two artifacts: a compact weight file containing only LoRA/QLoRA parameters for fast loading and deployment and a full resume checkpoint for quick continuation or reproduction of experiments.

4.6. Unified Evaluation Protocol and Normalized Parsing

To fairly compare different backbones, training strategies, and test domains (clean/light/scratch/real), we adopt a unified metric protocol and a normalized parsing procedure during evaluation. We report five core metrics: type accuracy (Type-Acc), unit accuracy (Unit-Acc), reading accuracy (Value-Acc), joint accuracy (Joint-Acc), and mean absolute error (MAE). Type-Acc and Unit-Acc reflect discrete classification capability for gauge category and reading unit; Value-Acc and Joint-Acc, on the basis of correct numeric regression, further require the type or type+unit to be correct; MAE quantifies the overall numerical deviation on the reading task.
Since MLLM outputs are typically natural-language text, we first perform normalized parsing on the model outputs: we use a restricted regular expression to extract the “numeric part” and the “unit suffix” from the text. We then normalize the extracted unit symbol by case normalization and synonym mapping (e.g., treating mpa and MPa as the same unit). Next, we apply the “type–unit binding” rules in Table 7 to check whether the predicted ( t ^ , u ^ ) is a valid combination; if invalid, the corresponding Unit-Acc and Joint-Acc are counted as incorrect.
For the numeric value, we use a tolerance criterion that combines absolute and relative errors, defining “correct reading” as follows:
ok ( v ^ , v ) v ^ v max τ abs , τ rel · | v | ,
where v is the ground-truth value, v ^ is the parsed predicted reading, τ abs is the absolute tolerance (e.g., 0.5 unit), and  τ rel is the relative tolerance (e.g., 1%). If Equation (9) holds, the sample is counted as correct for Value-Acc; otherwise, it is incorrect. Joint-Acc requires the type, unit, and reading to all satisfy their respective conditions. MAE is computed by averaging | v ^ v | over all valid predictions.
To make the treatment of unparsable outputs explicit, let N denote the total number of test samples and V denote the subset of samples whose outputs can be parsed into a valid structured triplet ( t ^ , v ^ , u ^ ) . We define parsing coverage and invalid-output rate as
Coverage = | V | N , Invalid = 1 Coverage .
The MAE over valid predictions is computed as
MAE valid = 1 | V | i V | v ^ i v i | .
For the all-sample evaluation, we additionally report a range-normalized penalized error:
nMAE all = 1 N i = 1 N e i r i , e i = | v ^ i v i | , i V , r i , i V ,
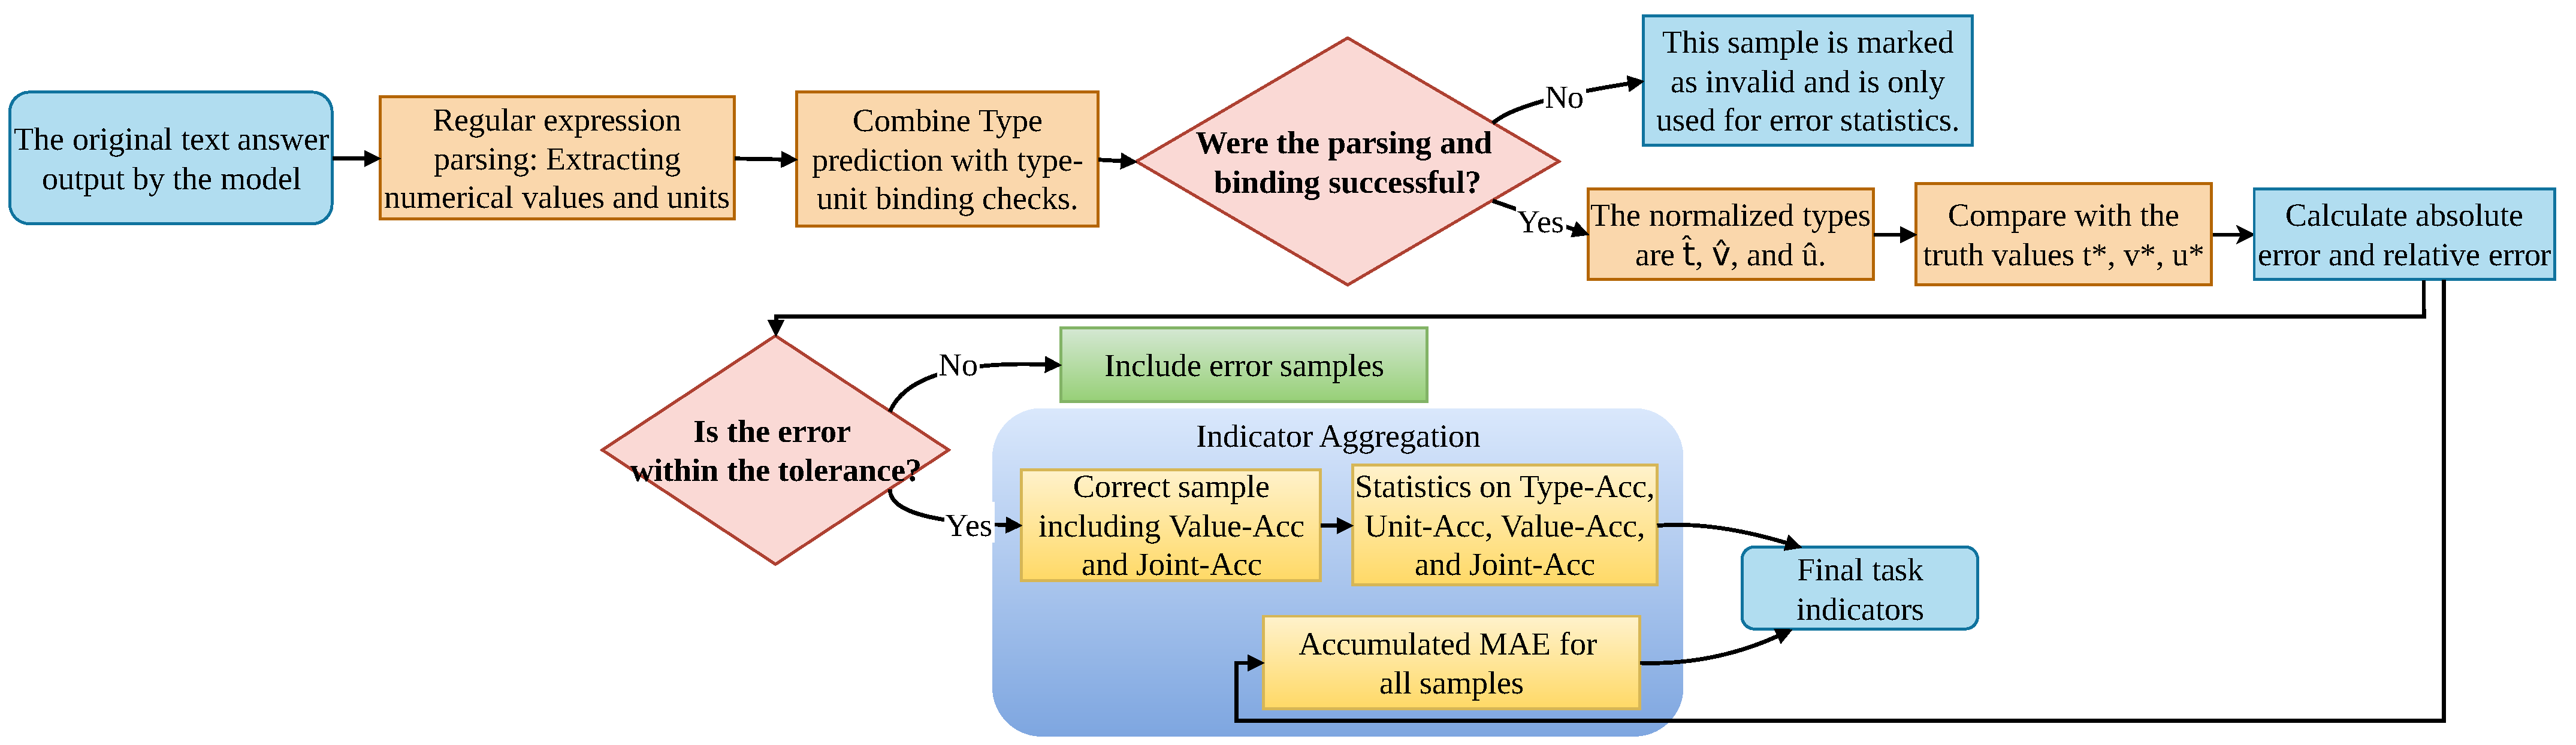
where r i = s max , i s min , i denotes the numerical span of the corresponding gauge. For an invalid or unparsable output, the absolute error is assigned as r i , yielding a normalized penalty of 1 for that sample. This metric prevents a model from obtaining an artificially low numerical error by producing invalid or empty outputs. It should be emphasized that the evaluation pipeline constrains free-form natural-language answers into a restricted format at the parsing–decision level. On the one hand, type–unit binding and validity/range checks remove physically implausible outputs; on the other hand, unified regex parsing and tolerance criteria improve comparability across different models and output styles and reduce sensitivity to specific prompts and output templates.The overall evaluation workflow is illustrated in Figure 7.

4.7. Implementation Notes and Key Hyperparameters (Script-Aligned)

Our implementation builds the multimodal gauge-reading model on Granite-Vision (a vision–language backbone in the LLaVA-Next family) and enables remote-code trust to load the official vision forward pass and projector implementation. Except for the LoRA/QLoRA branches, all other backbone parameters remain frozen. On the vision side, we use the default input resolution of the model; in experiments that require improved tick visibility, we raise the short-side resolution via –image_size_override. On the language side, we keep the original vocabulary and tokenizer unchanged, without additional tokenizer modifications.
For training hyperparameters, we adopt conservative yet stable settings: total epochs epochs = 20; physical batch size batch_size = 1 together with accum_steps = 64 to achieve a larger effective batch; learning rate lr = 10 6 ; LoRA rank r { 8 , 16 } ; scaling factor alpha = 2r; and a typical LoRA dropout of 0.05. Attention computation uses the efficient sdpa implementation. During generation, we set max_new_tokens = 16 and temperature = 0 to obtain deterministic outputs. At the environment-variable level, we disable TOKENIZERS_PARALLELISM to avoid tokenizer parallelism warnings and enable expandable CUDA segments via PYTORCH_CUDA_ALLOC_CONF=expandable_segments:True to mitigate GPU memory fragmentation.
For logging and script organization, each training configuration (clean/noisy/mixed) corresponds to an independent run script, with unified settings for random seeds, data paths, LoRA scope, and Eval-Guard flags. Training logs aggregate statistics per second, including training loss, learning rate, and GPU memory usage. After each epoch, a validation evaluation is automatically triggered, and Eval-Guard is run on a fixed-size validation subset to generate the corresponding fingerprint logs. This organization helps quickly locate training anomalies during experimentation and facilitates comparison of training curves and resource overheads across configurations during paper writing.

5. Results and Discussion

5.1. Methodological Novelty and Practical Scope

The proposed approach should be understood as a practical adaptation framework for industrial visual measurement rather than as a newly designed neural architecture. Its novelty is methodological and system-oriented: it links a structured VQA formulation, unified MLLM screening, Projector-LoRA-based parameter-efficient adaptation, robustness-oriented training mechanisms, constrained numerical post-processing, and auditable evaluation into a single workflow. This combination is particularly relevant for industrial pointer gauges because the task requires not only image recognition but also unit binding, structured numeric output under fixed per-category ranges, and traceable evaluation. At the same time, the scope of the method is intentionally bounded. The present results demonstrate the potential of staged MLLM adaptation, but they do not establish a fully autonomous or safety-certified reading system.

5.2. Zero-Shot Evaluation and Backbone Model Selection

We begin with a zero-shot study to determine how far contemporary MLLMs can go on pointer-gauge reading before any task-specific adaptation. All experiments use the dataset introduced in Section 4.1, including clean, light-noise, and scratch-noise test conditions, and all candidate models are evaluated under the same local deployment setting. The compared backbones include Granite-Vision, Qwen-VL/Qwen2-VL, Gemma-3, and MiniCPM-V, which together represent a diverse set of contemporary multimodal systems with strong performance on generic VQA, document understanding, and OCR-oriented tasks [6,7,15,16,25].
To keep the comparison controlled, we use the same image preprocessing, prompting pattern, and lightweight decoding restrictions across all models. Images are resized while preserving the aspect ratio and are not center-cropped, since center cropping may remove the pointer or boundary tick marks. Each image is evaluated with two prompts, one for type identification and one for reading extraction. Every model is run five times on each test set, and mean performance is reported. Although the generation temperature is set to 0, we run each model five times to account for potential nondeterminism in GPU floating-point operations and the autoregressive sampling loop under batch processing. The variation across runs was negligible (Type-Acc standard deviation < 0.1%).

5.2.1. Evaluation Metrics

We report four main metrics in the zero-shot comparison. Type-Acc measures exact gauge-type classification. Value-Acc measures whether the predicted reading falls within the predefined tolerance window. Joint-Acc requires both type and reading to be correct simultaneously, and therefore captures end-to-end task success. MAE reports the Mean Absolute Error (MAE), i.e., the mean absolute difference between predicted and ground-truth values over all test samples, to characterize the typical magnitude of reading deviation in physical units. Notably, in our annotation and scoring protocol, units are deterministically bound to gauge types and thus can be inferred from the type. However, in free-form zero-shot natural responses, models may still exhibit instability such as unit omission or confusion; this unit dimension is not separately counted in the structured scoring of this experiment.

5.2.2. Zero-Shot Results and Analysis

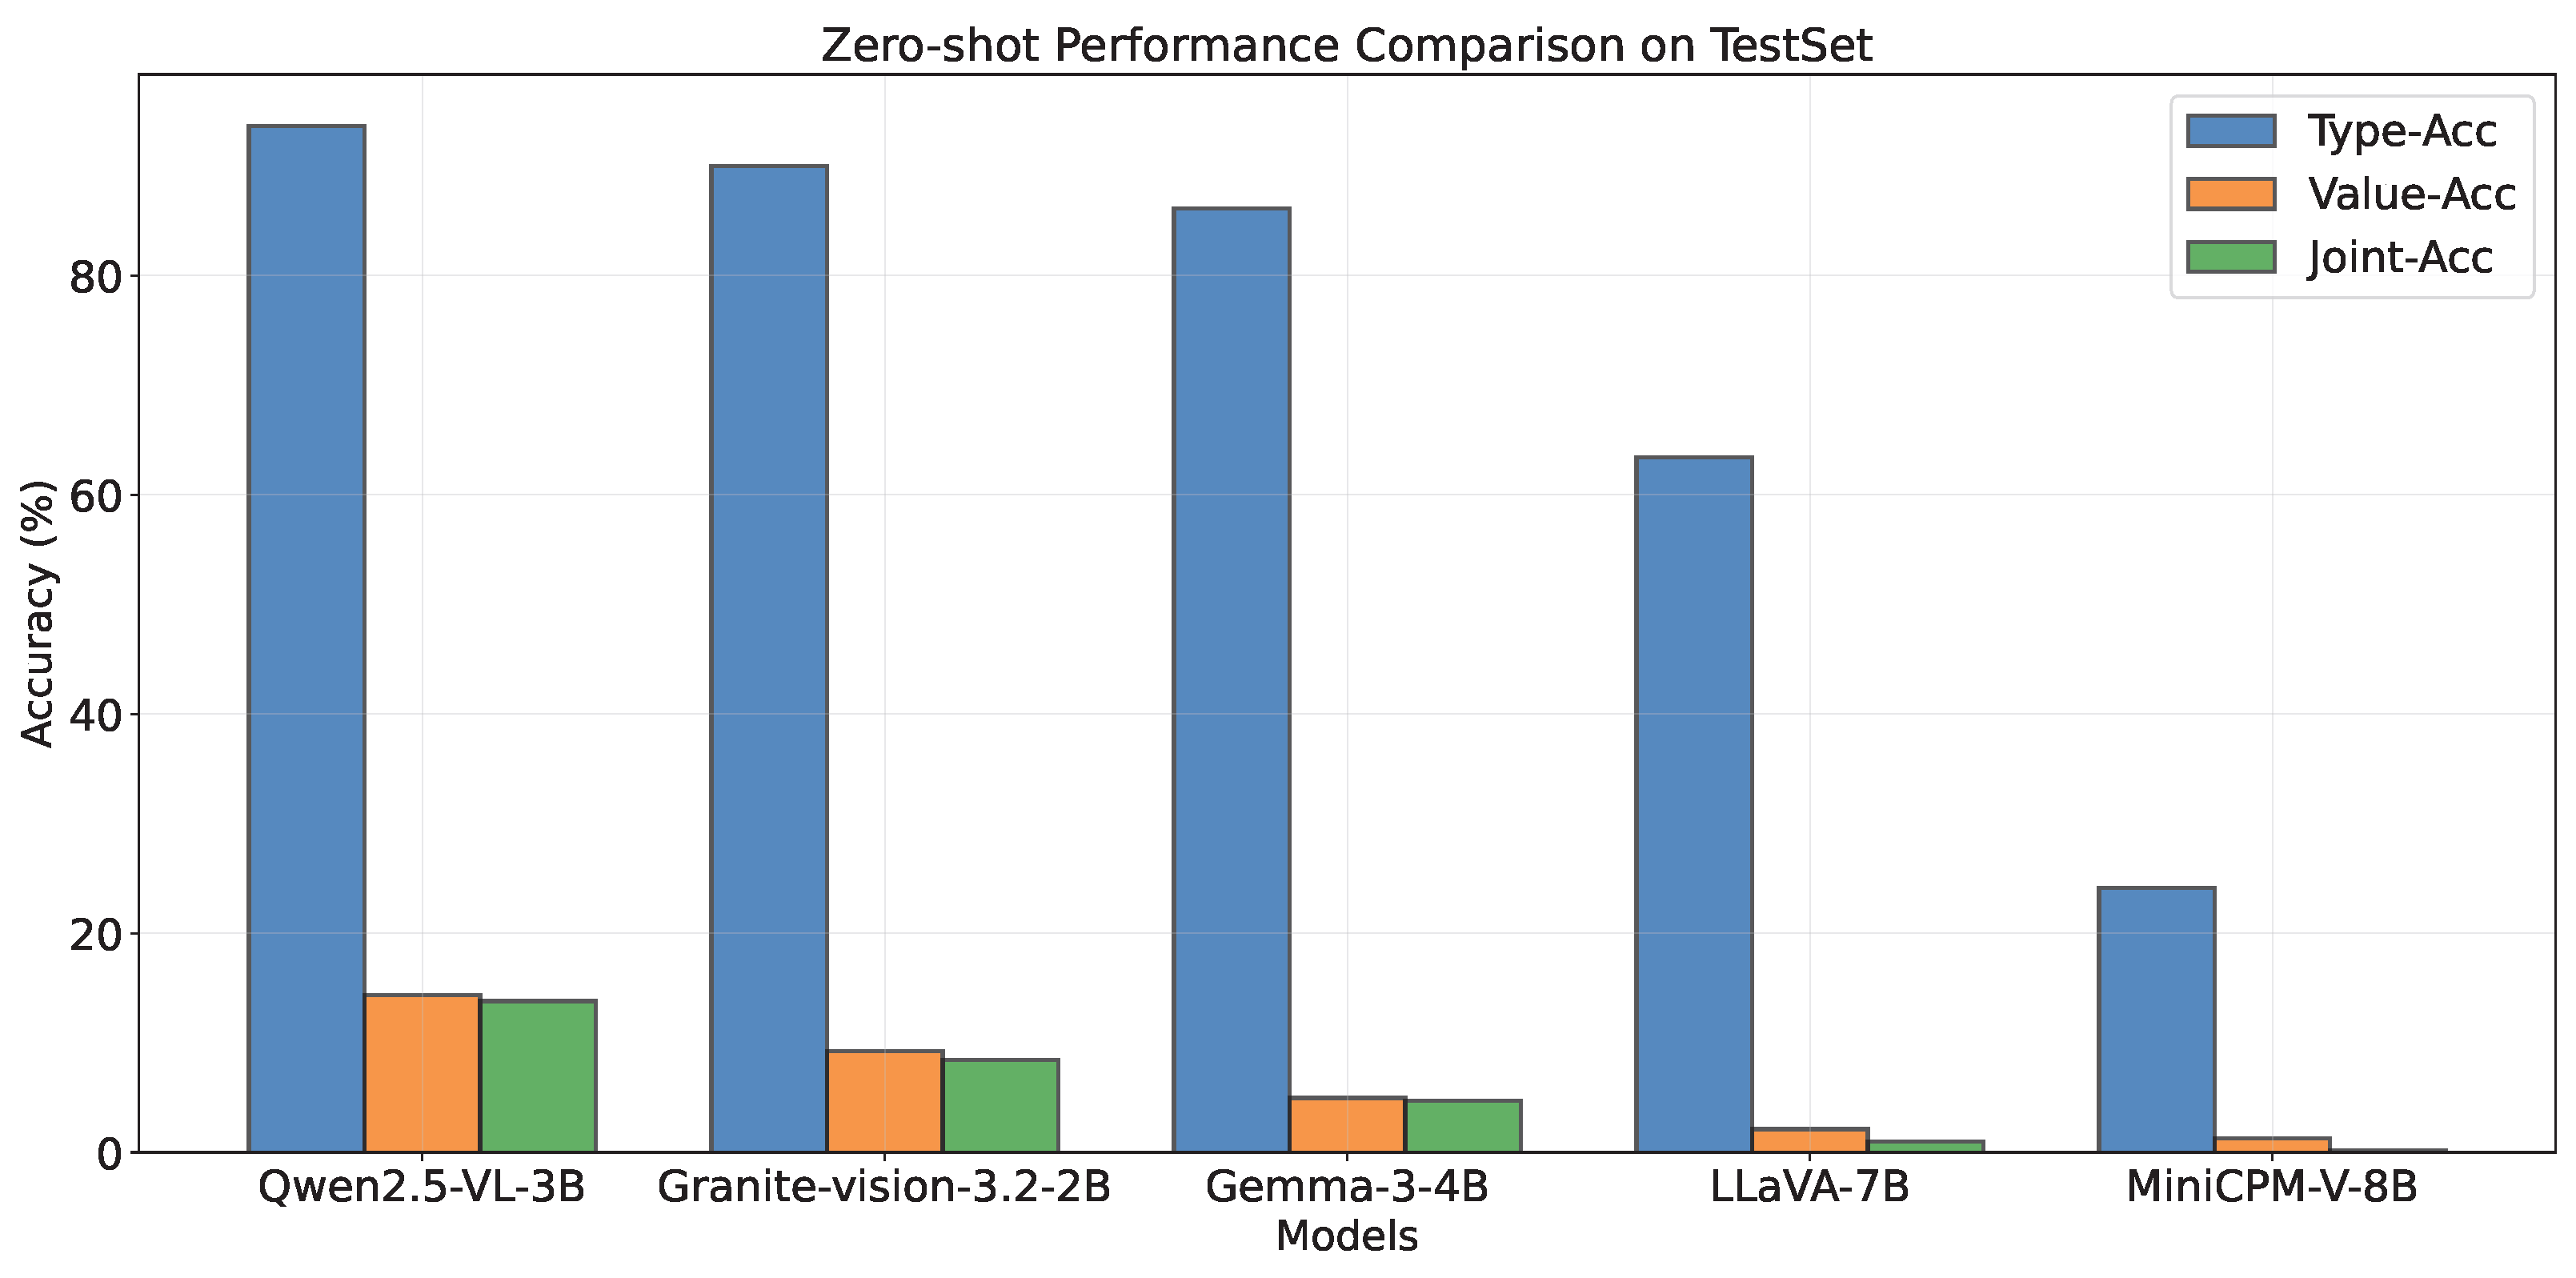
Table 8 summarizes the structured reading performance of different models on the test sets. As can be seen, these baseline models without task-specific fine-tuning achieve relatively high accuracy on type identification, with some models exceeding 80% (e.g., Qwen2-VL reaches about 90%), indicating a certain level of semantic understanding. However, when the task shifts to precise numerical reading, Value-Acc for all models drops sharply to below 15%, and some models are close to zero; Joint-Acc also generally remains at a single-digit level. This suggests that, without task-specific training, it is difficult for models to “internalize” the linear mapping between pointer geometry, scale layout, and physical quantities into a stable reasoning pattern.
In terms of error scale, zero-shot baselines typically exhibit MAE values on the order of tens or higher. Moreover, LLaVA-7B and MiniCPM-V-8B produce extreme outliers on certain samples, which inflate the overall MAE. This not only reflects near-random behavior on the reading task but also exposes the risk of free-form text generation without numerical constraints—the model may not only read incorrectly but also output physically implausible values beyond the gauge range. The comparison curves in Figure 8 further show that while zero-shot MLLMs already perform well on “image understanding”, they still have an inherent weakness on the structured reading dimension of “geometry–value mapping”.
It is worth noting that LLaVA-7B and MiniCPM-V produce extremely erroneous numeric predictions on some test samples (e.g., predicting extreme values or invalid formats), leading to abnormally large MAE values. This indicates severe issues with numerical stability for these models.

5.2.3. Backbone Model Selection

Considering both accuracy and engineering cost, Granite-Vision and Qwen2.5-VL-3B are the strongest zero-shot candidates in the present comparison. Qwen2.5-VL-3B achieves the highest zero-shot Type-Acc, Value-Acc, and Joint-Acc, whereas Granite-Vision provides a compact language backbone and a visual projector that is convenient for localized parameter-efficient adaptation. Under the unified measurements reported in Table 9, Qwen2.5-VL-3B and Granite-Vision exhibit similar measured latency and peak GPU memory on the test hardware. Therefore, the selection of Granite-Vision is not based on a claimed two- or three-fold inference advantage but on the combined considerations of model scale, adaptation interface, local implementation stability, and compatibility with the proposed Projector-LoRA workflow.
In terms of inference efficiency, the larger LLaVA-7B and MiniCPM-V-8B models require higher peak memory and exhibit longer measured latency under the same environment, while their zero-shot numerical-reading performance is substantially weaker. Gemma-3-4B provides moderate resource usage but also trails the leading candidates in Value-Acc and Joint-Acc. Based on this combined accuracy–resource–adaptation trade-off, Granite-Vision 3.2 is selected as the backbone for subsequent parameter-efficient fine-tuning.

5.3. Parameter-Efficient Fine-Tuning for Structured Reading and Robustness

After selecting Granite-Vision as the backbone, we focus on adapting it to the combined task of “gauge type identification + numerical reading” via lightweight fine-tuning. To balance performance and deployment cost, we adopt parameter-efficient fine-tuning (PEFT), specifically Low-Rank Adaptation (LoRA) [23]. The core idea of LoRA is to freeze the pretrained backbone weights while inserting trainable low-rank matrices A R r × d and B R d × r into certain linear layers, using B A as an update to the original weights:
h = W 0 x + B A x ,
where W 0 is the frozen pretrained weight, and B A is the low-rank update. Since r d , the number of trainable parameters and GPU memory overhead are small; during inference, B A can be merged back into W 0 without introducing additional inference latency [23]. Related QLoRA work further demonstrates that combining LoRA updates with 4-bit quantized weights can achieve performance close to full fine-tuning on large models [24].
In this work, we adopt a Projector-LoRA configuration, inserting trainable LoRA adapters into the multimodal projection layer (vision projector) between the vision encoder and the language model, i.e., primarily adjusting the mapping from image features to language-token representations. We test three injection strategies: applying LoRA only to the vision side (projection/vision modules), applying LoRA only to the language-side Transformer layers, or applying LoRA to both the vision and language sides simultaneously. Experiments show that for this task, the primary bottleneck lies in “how to encode a gauge image into visual tokens containing geometric information”, while the language model’s capability for understanding and generating text is already sufficient. Therefore, concentrating LoRA on the vision/projection subnetwork works best, whereas adding LoRA on the language side yields limited gains but increases training and deployment complexity. The final results are based on the “Projector-LoRA-only” configuration.
In addition to LoRA, we introduce three key mechanisms for reading stability during training and inference:
1.
Anti-center-cropping and resolution overriding: During fine-tuning, for paired mixed samples we disable the automatic center cropping to keep the full gauge region visible, while retaining the default center-cropping for ordinary single-image samples (see Section 4.4). We also randomly vary the upper bound of the input resolution so that the model can learn scale details under different zoom levels. This effectively mitigates truncation of tick marks or pointers caused by center cropping and improves spatial robustness to off-center, distant-view, or oblique-view scenarios.
2.
Paired mixed-noise training: For each selected gauge instance, we construct a paired input by concatenating a clean image and a heavily degraded version containing reflections, scratches, or related disturbances. Both views share the same ground-truth type and reading. The paired input is optimized using the same autoregressive task loss as the other training samples; no explicit contrastive representation loss is introduced. By presenting two visual realizations of the same underlying measurement within one input, the training procedure encourages the model to focus on pointer geometry, scale structure, and other reading-relevant evidence that remains consistent across the two views.
3.
Numerically constrained post-processing: During inference, the model generates a short text sequence. We apply a post-generation regex-based validation: the output must match a normalized number + unit pattern with the unit drawn from { C , MPa , V , A } . If the output does not conform or the numeric value lies outside a plausibility range (e.g., negative reading for an absolute pressure gauge), the prediction is treated as invalid and excluded from valid-sample metrics. This format-and-range gate is not a token-level constrained decoder; it operates on the completed output string. It prevents extreme outliers from inflating MAE but may reduce valid coverage. The effect on coverage is reported alongside the main metrics.
Training configurations.
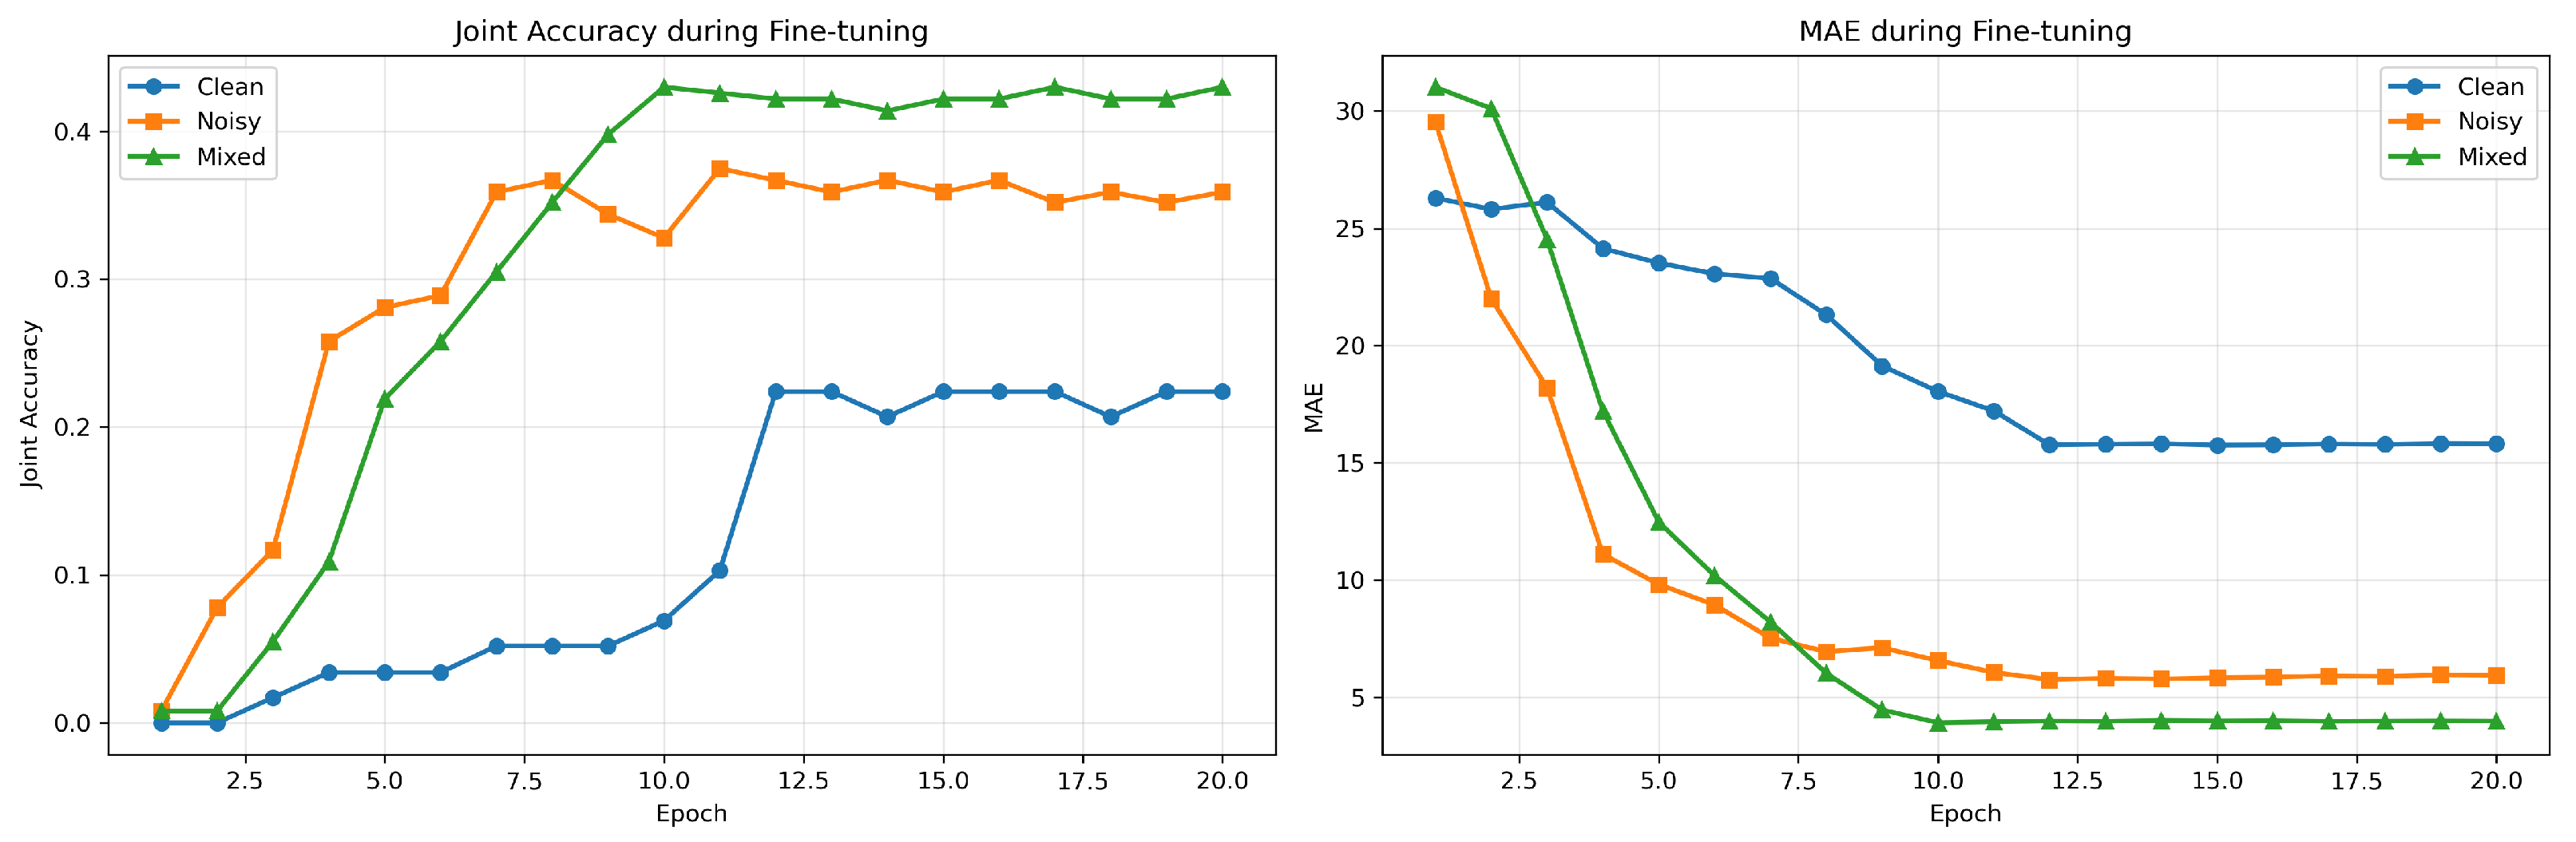
Based on the above strategies, we train three Granite-Vision fine-tuning variants: the Clean model trained only on the clean training set, the Noisy model trained only on augmented samples including light/scratch, and the Mixed model trained using the “clean + noisy paired clean–noisy concatenation” strategy. All models are trained for 20 epochs with an effective batch size of 64, using a learning rate of 1 × 10 6 , and training is monitored on an independent validation set containing clean/light/scratch subsets.
As shown in Figure 9, the training curves show that training loss decreases smoothly under all three settings, and validation performance improves across epochs without obvious overfitting, indicating that with the current dataset scale and LoRA capacity configuration, the model has sufficiently learned task-specific knowledge. The Mixed strategy achieves the best joint accuracy, reaching a peak performance of about 43% during training, while MAE converges to around 3.98. In comparison, the Clean strategy shows slower growth in joint accuracy and eventually stabilizes at 22.4%, while the Noisy strategy yields intermediate joint accuracy but achieves a better-converged MAE.

5.4. Results: Accuracy and Robustness Improvements from Fine-Tuning

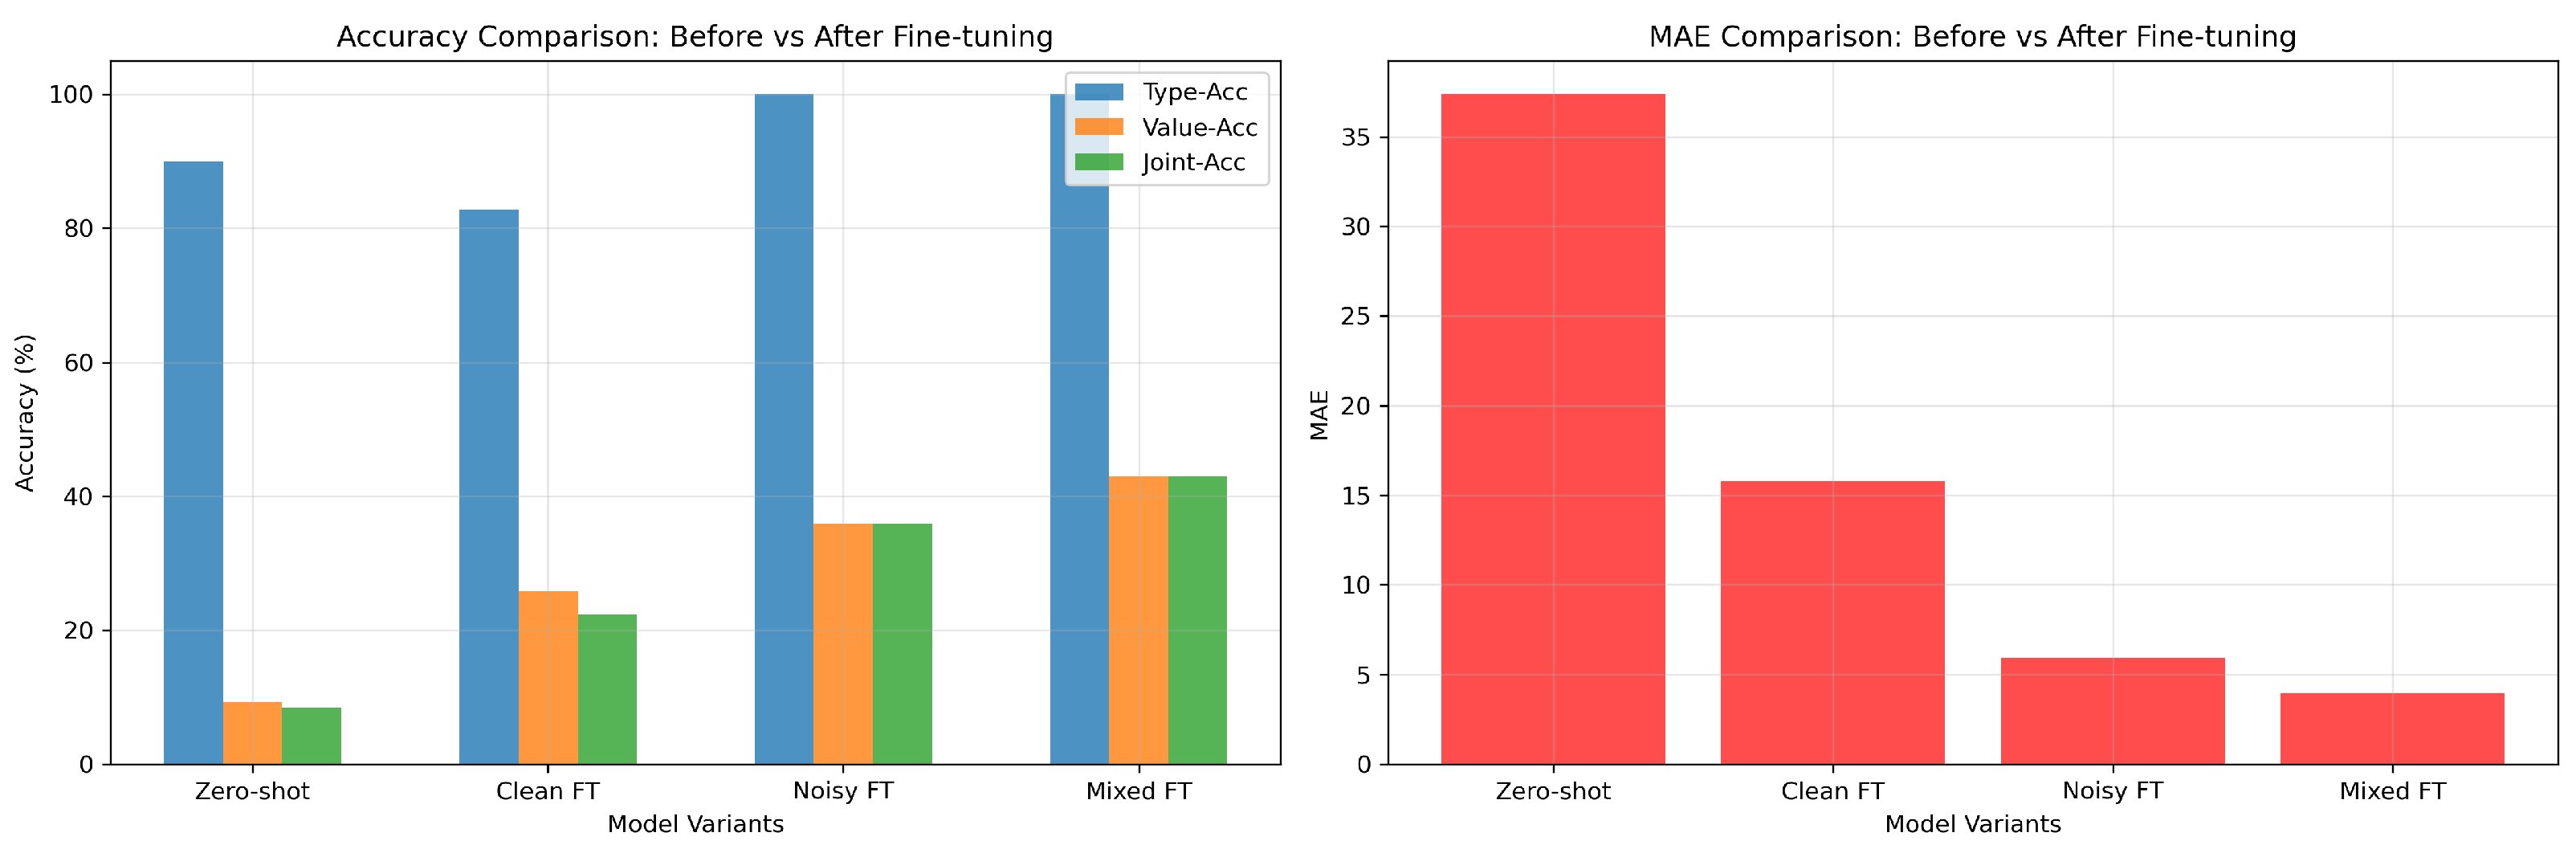
After fine-tuning, Granite-Vision exhibits a substantial change in performance on the dual tasks of “gauge type identification + numerical reading”. Table 10 compares the overall performance of the backbone model and the three fine-tuned variants on the full test set.
Overall, Projector-LoRA fine-tuning yields substantial performance gains across the key metrics: the fine-tuned model under the Mixed data strategy reaches a Value-Acc of 43.77% and a Joint-Acc of 43.60%. This should be described as a clear improvement over the Granite zero-shot Joint-Acc of 8.46% reported in Table 8, rather than as an “almost 0%” baseline. This means that on about 43% of the test samples, the model can simultaneously output the correct gauge type and numerical reading. In particular, for numerical reading, Value-Acc increases from below 10% to above 40%, indicating that the model has learned part of the previously missing geometric mapping rule from “pointer angle to reading”. For type recognition, the main Granite zero-shot Type-Acc is already 90.00%, so the strongest improvement is the combination of near-perfect type recognition with improved value and joint correctness after fine-tuning.
Notably, the fine-tuned models achieve near-ceiling performance on type recognition: Type-Acc is close to 100% under all three strategies. This implies that the main source of reading error has shifted from “misidentifying the gauge” to “fine-grained tick interpretation on the same gauge”. In other words, LoRA fine-tuning first consolidates the semantic understanding strengths of MLLMs and then enhances their ability to capture subtle pointer-angle changes and tick-spacing differences. Nevertheless, because more than half of the samples are still not jointly correct, the system should be viewed as a promising measurement assistant rather than a reliable autonomous reader.
In terms of error scale, the backbone model’s MAE before fine-tuning is on the order of tens, while the Mixed model reduces MAE to 3.98. Because MAE can be overly optimistic if computed only over valid parsed predictions, this value should be reported together with invalid-output rate, coverage, and a penalized MAE over all test samples. More importantly, the overall error distribution contracts toward zero: even when not perfectly correct, the fine-tuned model tends to output values closer to the ground truth rather than making random guesses. To clarify where the remaining failures occur, Section 5.7.2 further reports condition-wise statistics and error-distribution analysis based on manually assigned dominant visual-condition labels for the test set.
These results should therefore be interpreted as evidence of adaptation effectiveness rather than as proof that an MLLM universally outperforms specialized gauge-reading systems. To provide a stronger empirical reference, Section 5.8 introduces a Geometry/Hough baseline and a CNN multi-task baseline trained and evaluated under the same dataset split and metric protocol.
In terms of type recognition, the fine-tuned models achieve near-perfect accuracy (98.5–99.9%), representing a substantial improvement over the 90.00% zero-shot baseline.
Comparing the three fine-tuned variants on the full test set indicates that training-data composition has a substantial influence on overall generalization. The Clean-only model improves over the zero-shot backbone, but it remains the weakest of the three fine-tuned variants in numerical reading, reaching a Value-Acc of 22.66 ± 0.80 %, a Joint-Acc of 22.41 ± 0.80 %, and an MAE-valid of 5.18 ± 0.18 . The Noisy-only model obtains stronger overall numerical performance, with a Value-Acc of 37.58 ± 0.74 %, a Joint-Acc of 37.36 ± 0.71 %, and an MAE-valid of 4.31 ± 0.16 . The Mixed strategy achieves the best overall result, reaching a Value-Acc of 43.77 ± 0.43 %, a Joint-Acc of 43.60 ± 0.47 %, and an MAE-valid of 3.98 ± 0.10 . These full-test results suggest that exposure to both clean and degraded paired samples provides a more balanced training signal than either Clean-only or Noisy-only supervision. Condition-specific differences are analyzed separately later.
Table 10. Performance comparison of Granite-Vision 3.2 before and after fine-tuning on the full test set. Fine-tuned results are reported as mean ± sample standard deviation over five runs using matched random seeds { 1 , 2 , 3 , 4 , 5 } across the three training strategies. (Figure 10 summarizes the comparison.)
VariantType-AccValue-AccJoint-AccMAE-Valid
Granite (zero-shot)90.00%9.23%8.46%37.37
Fine-tuned (Clean) 98.47 ± 0.29 % 22.66 ± 0.80 % 22.41 ± 0.80 % 5.18 ± 0.18
Fine-tuned (Noisy) 99.05 ± 0.22 % 37.58 ± 0.74 % 37.36 ± 0.71 % 4.31 ± 0.16
Fine-tuned (Mixed) 99.86 ± 0.05 % 43.77 ± 0.43 % 43.60 ± 0.47 % 3.98 ± 0.10
With the paired clean–noisy training strategy, the Mixed model maintains strong performance across both clean and degraded test conditions. Among the three fine-tuned variants, it obtains the highest full-test Joint-Acc and the lowest MAE-valid. These results suggest that presenting paired views with the same reading under different visual disturbances provides a more balanced supervision signal than using Clean-only or Noisy-only training. Because no explicit contrastive loss is used, the observed effect should be interpreted as the benefit of paired disturbance-aware augmentation rather than as evidence of conventional contrastive representation learning.
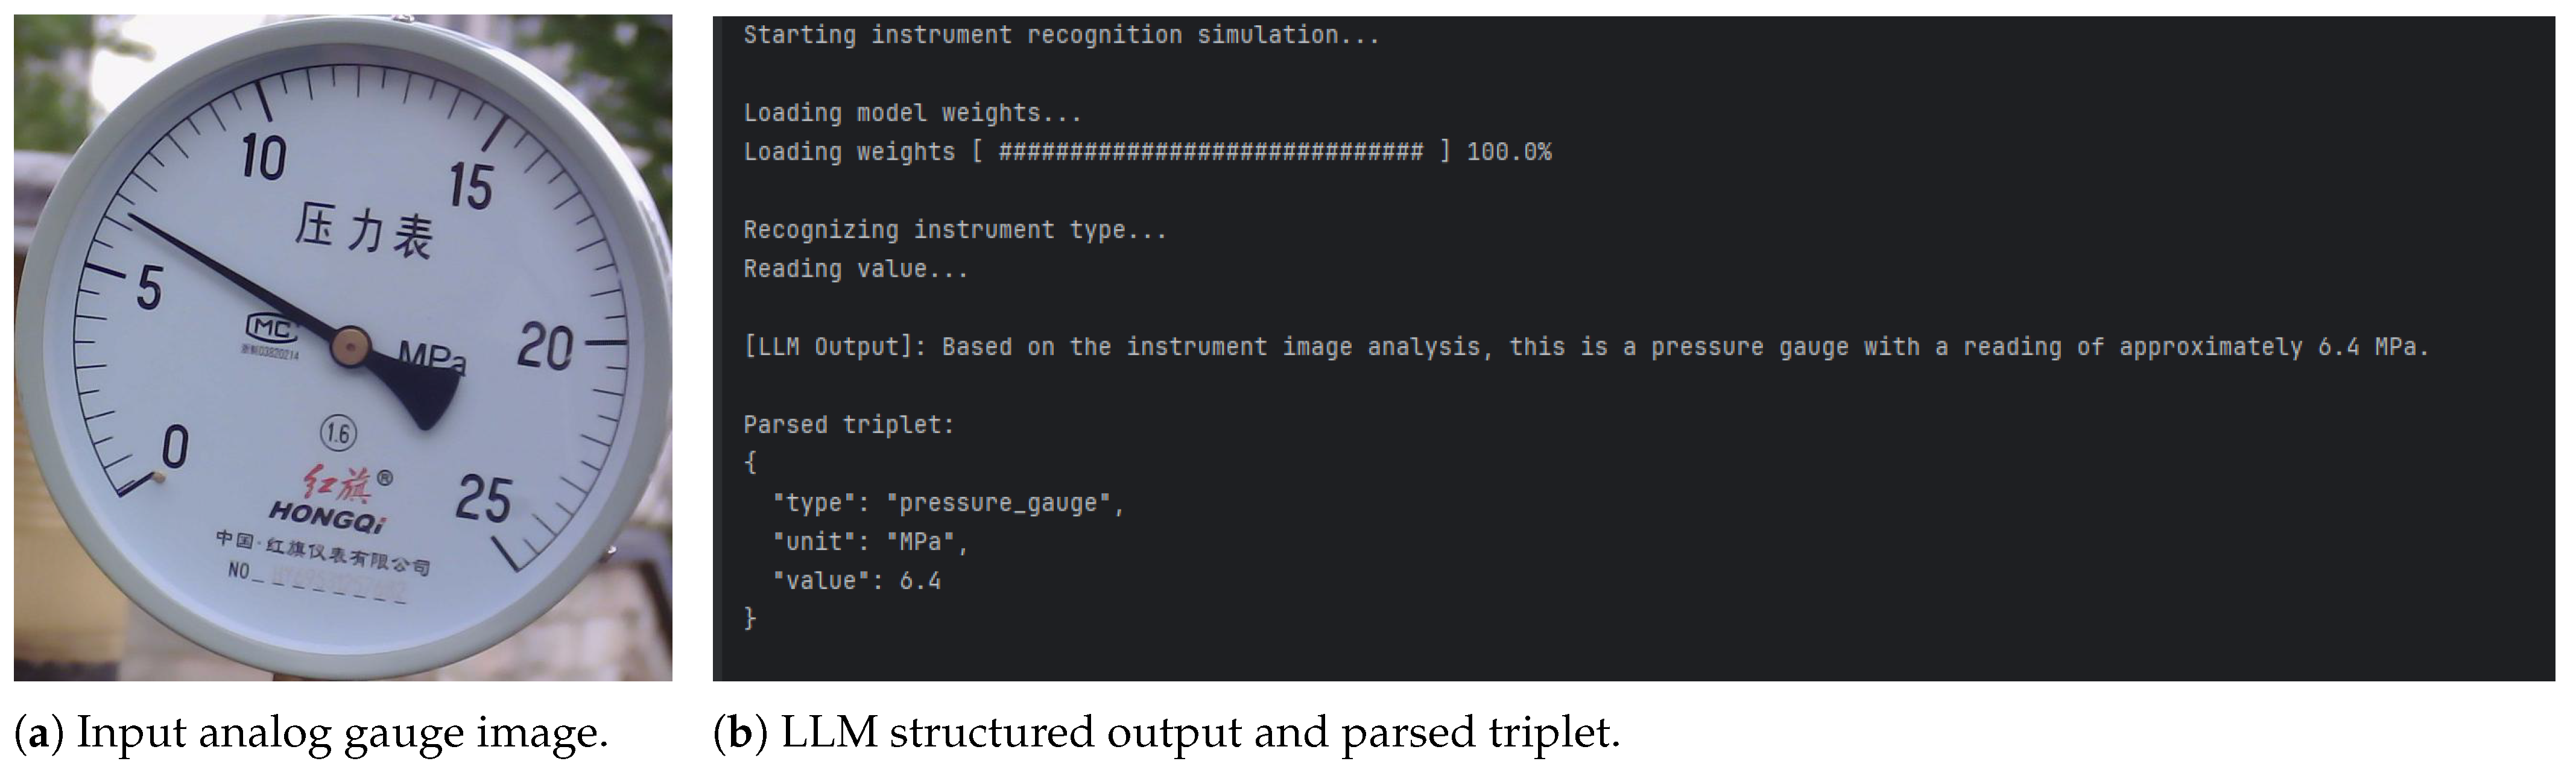
Identification is performed using the fine-tuned model weights:
As shown in Figure 11, the model produces a structured triplet (type, unit, value) for downstream use, with an error of 2%.

5.5. Coverage-Aware Evaluation and Penalized Numerical Error

Because MLLM predictions are generated as free-form text before normalized parsing, reporting only the valid-sample MAE may overestimate numerical reliability. We therefore evaluate all fine-tuned variants with the parsing coverage, invalid-output rate, MAE over valid predictions, and penalized normalized MAE over all test samples. Table 11 summarizes the results.
The Mixed setting achieves the highest parsing coverage and the lowest invalid-output rate among the three fine-tuned variants. It also obtains the lowest MAE-valid and nMAE-all, indicating that its numerical improvement is not achieved by selectively excluding a larger proportion of difficult or unparsable outputs. In this evaluation, every unparsable output is treated as a failed prediction and receives a full-range penalty in the computation of nMAE-all.

5.6. Tolerance Sensitivity of Value Accuracy

Value-Acc depends on the numerical tolerance used to determine whether a predicted reading is sufficiently close to the ground truth. A prediction is considered value-correct when
| v ^ i v i | max τ abs , τ rel | v i | ,
which is equivalent to accepting the prediction when either the absolute-error criterion or the relative-error criterion is satisfied. The use of the maximum prevents the evaluation from becoming excessively strict for readings near zero while retaining scale-aware tolerance for larger readings. The most common minimum tick interval in the present dataset is approximately 0.5 measurement units, although some gauges use intervals of approximately 0.2 or 1.0 units. Accordingly, the strict, default, and loose absolute tolerances are set to 0.25, 0.50, and 1.00, corresponding approximately to half, one, and two of the most common minimum tick intervals. Their paired relative tolerances are 0.5%, 1.0%, and 2.0%, respectively. The default setting is used in the main experiments, while the strict and loose settings are reported as a sensitivity analysis rather than as universal industrial acceptance thresholds.
Both Value-Acc and Joint-Acc increase monotonically as the tolerance is relaxed. Nevertheless, the main observation remains unchanged across all three settings: numerical reading accuracy, rather than type recognition, is the principal bottleneck of the current system. The default tolerance is retained as the primary reporting setting because it provides an intermediate operating point between overly strict and overly permissive numerical matching.The sensitivity results are reported in Table 12.

5.7. Ablation Study and Error Analysis

To quantify the contribution of each component, we design several ablation experiments: under the Mixed data setting, we remove one component at a time (anti-center-cropping, paired mixed-noise training, or numerically constrained post-processing) and observe performance changes. The results indicate that all three mechanisms contribute to performance and robustness from complementary perspectives: input visibility, training distribution, and output validity.
First, removing the conditional anti-center-cropping (i.e., applying standard center-cropping to all images, including the paired mixed samples) decreases type recognition accuracy by about 3–4 percentage points on some “off-center” test images. Specifically, when the gauge lies near the image boundary, is viewed from an oblique angle, or is only partially visible, a model that has not seen such compositions during training is more likely to misclassify or fail to recognize the type. With anti-center-cropping and variable-resolution training retained, these samples are typically still recognized correctly. This indicates that exposing the model to richer field-of-view layouts during training has practical value for improving spatial coverage.
Second, removing paired mixed-noise training (i.e., still mixing clean and noisy samples but no longer constructing paired concatenated inputs and instead feeding them separately) noticeably degrades reading performance in noisy scenarios: overall Value-Acc drops by about 5 percentage points, and on the scratch-noise subset, the drop can reach 8–10 percentage points; joint accuracy also decreases by a similar magnitude. Qualitative analysis shows that without the paired clean–noisy input, the model is more likely to be misled by spurious cues such as reflections and scratches, sometimes treating noise structures as tick marks or the pointer. Such errors are rarely observed in the Mixed model with paired constraints. This demonstrates that paired mixed-noise training plays an important role in guiding the model to learn noise-invariant features.
Third, removing numerically constrained post-processing leads to “catastrophic errors” on a small number of difficult samples. For instance, when the dial is nearly illegible or the reading is near the range boundary, the model may output absurd values far beyond the gauge range or add natural-language descriptions around the structured reading, such as “approximately 50 MPa” or “the reading is 50 MPa”, which violates the required normalized output format and complicates deterministic parsing. These abnormal outputs noticeably increase the overall MAE. With constrained decoding, the model is required to remain in the normalized number + unit format and tends to return an empty response rather than guessing blindly on extreme samples, thereby reducing the influence of a small number of outliers on overall error. In our experiments, numeric constraints further reduce MAE by about 1.5 absolute units and slightly improve reading accuracy (because some outputs previously judged as format errors are corrected into valid numeric values).
Because the fine-tuning procedure is stochastic, the Clean-only, Noisy-only, and Mixed configurations were each trained using the same five random seeds, { 1 , 2 , 3 , 4 , 5 } . Table 10 reports the mean ± sample standard deviation over these five runs.
For the statistical significance analysis, we first constructed one ensemble prediction for each test sample within each training strategy. The predicted numerical value was obtained by averaging the valid numerical predictions across the five seeds, whereas categorical outputs (gauge type and unit) were determined by majority voting. This produced one ensemble prediction for each of the 2230 test samples.
Paired nonparametric bootstrap resampling was then performed over these sample-level ensemble predictions. In each of the 10,000 bootstrap iterations, 2230 sample indices were drawn with replacement, and the identical resampled indices were applied to both compared strategies to preserve sample-level pairing. Two-sided 95% confidence intervals were obtained from the 2.5th and 97.5th percentiles of the bootstrap difference distribution. Two-sided bootstrap p-values were computed as twice the smaller empirical tail probability on either side of zero. All reported differences are defined as the Mixed strategy minus the compared strategy.
The single-run ablation results are summarized in Table 13.
Table 14 summarizes paired bootstrap comparisons between the five-seed ensemble predictions of the Mixed strategy and those of the Clean-only and Noisy-only strategies. The bootstrap analysis is performed over the 2230 test samples rather than over random seeds.
The bootstrap analysis reflects sample-level variability of the ensemble predictions under paired resampling. The observed differences are consistent with the per-strategy mean differences reported in Table 10. These results indicate that the Mixed ensemble outperforms the other two strategies on the present test set with high sample-level stability. However, because the ensemble construction already averages across training seeds, the bootstrap p-values should not be over-interpreted as definitive evidence that the Mixed strategy is universally superior. Full transparency would require per-sample prediction files and bootstrap scripts, which are not publicly released due to data restrictions. We therefore present the bootstrap results as a descriptive assessment of prediction-level consistency, not as a formal hypothesis test.
The Mixed strategy also shows a consistent reduction in valid-sample numerical error. Compared with Noisy-only training, the observed MAE-valid difference is 0.33 , with a 95% bootstrap confidence interval of [ 0.48 , 0.19 ]. Compared with Clean-only training, the MAE-valid difference is 1.20 , with a 95% confidence interval of [ 1.52 , 0.88 ]. Both intervals exclude zero, and the corresponding two-sided bootstrap p-values are below 0.001. These findings indicate that the numerical-error reduction is consistently supported across the paired test samples rather than being driven by only a small subset of favorable cases.

5.7.1. Type-Level Confusion Analysis

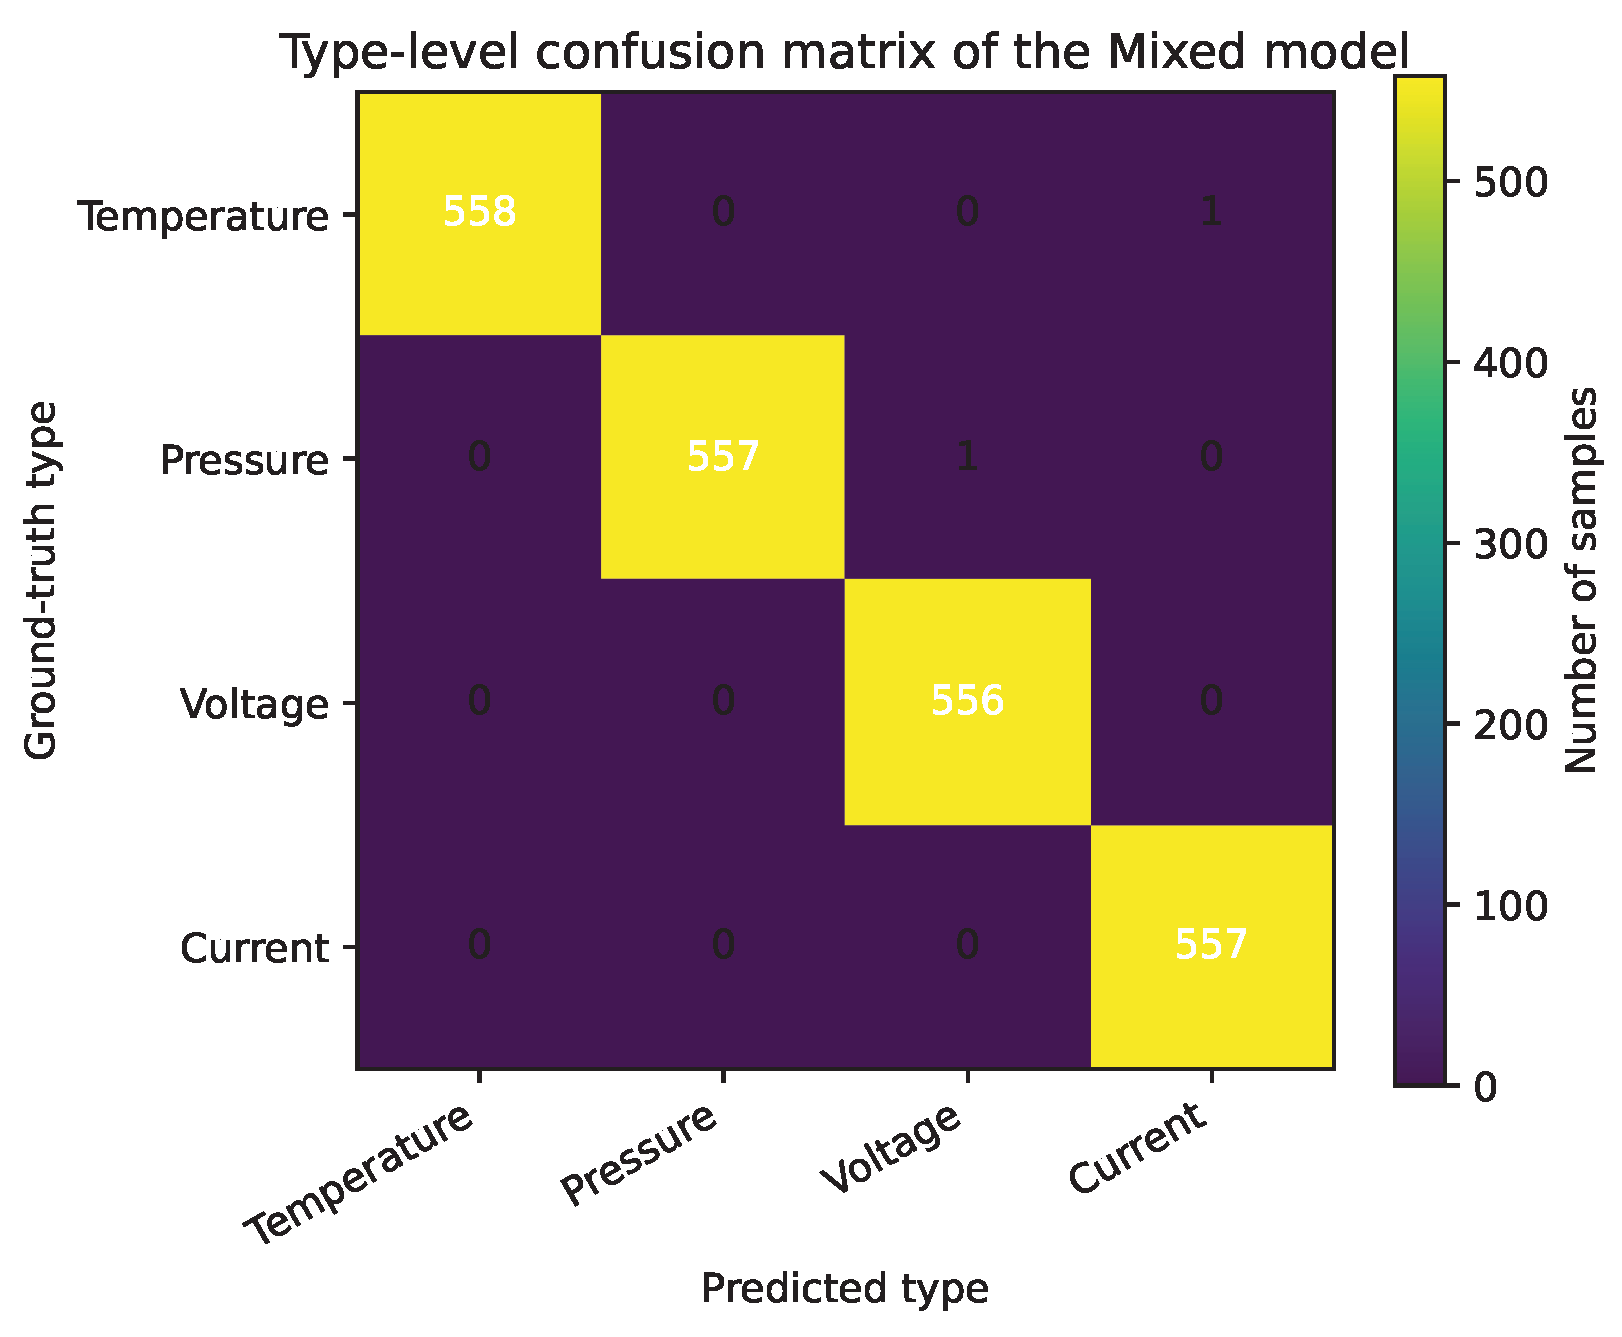
Since Joint-Acc requires type, unit, and numeric value to be simultaneously correct, we separately inspect the type-level confusion matrix to determine whether the remaining joint failures are mainly caused by semantic type errors or by numeric reading errors.
As shown in Figure 12, type recognition errors are rare after fine-tuning. The confusion matrix is derived from the five-seed ensemble (majority vote for type). Among 2230 test samples, only two type-level errors are observed, corresponding to an ensemble Type-Acc of approximately 99.91%, close to the five-run mean of 99.86%. Therefore, the main bottleneck of Joint-Acc is not semantic type recognition but the numeric reading component, especially under visual disturbances that degrade pointer and scale visibility.

5.7.2. Condition-Wise Error Analysis

We further analyze the Mixed model under different visual conditions. This condition-wise analysis helps identify whether the remaining failures are mainly caused by semantic confusion or by visually degraded pointer–scale evidence. For a valid prediction, the normalized absolute error is defined as
e i norm = | v ^ i v i | s max , i s min , i ,
where a prediction is counted as an extreme error when e i norm > 0.20 , i.e., when its absolute reading error exceeds 20% of the full-scale numerical span of the corresponding gauge. The extreme-error rate is calculated only over valid parsed predictions. This deliberately loose threshold is used as a diagnostic indicator of severe reading failures rather than as an industrial acceptance criterion.
For this diagnostic analysis, the test samples are regrouped according to their dominant observed visual condition rather than the original dataset morphology labels used in Table 6. The four diagnostic groups are mutually exclusive and together cover all 2230 test samples.
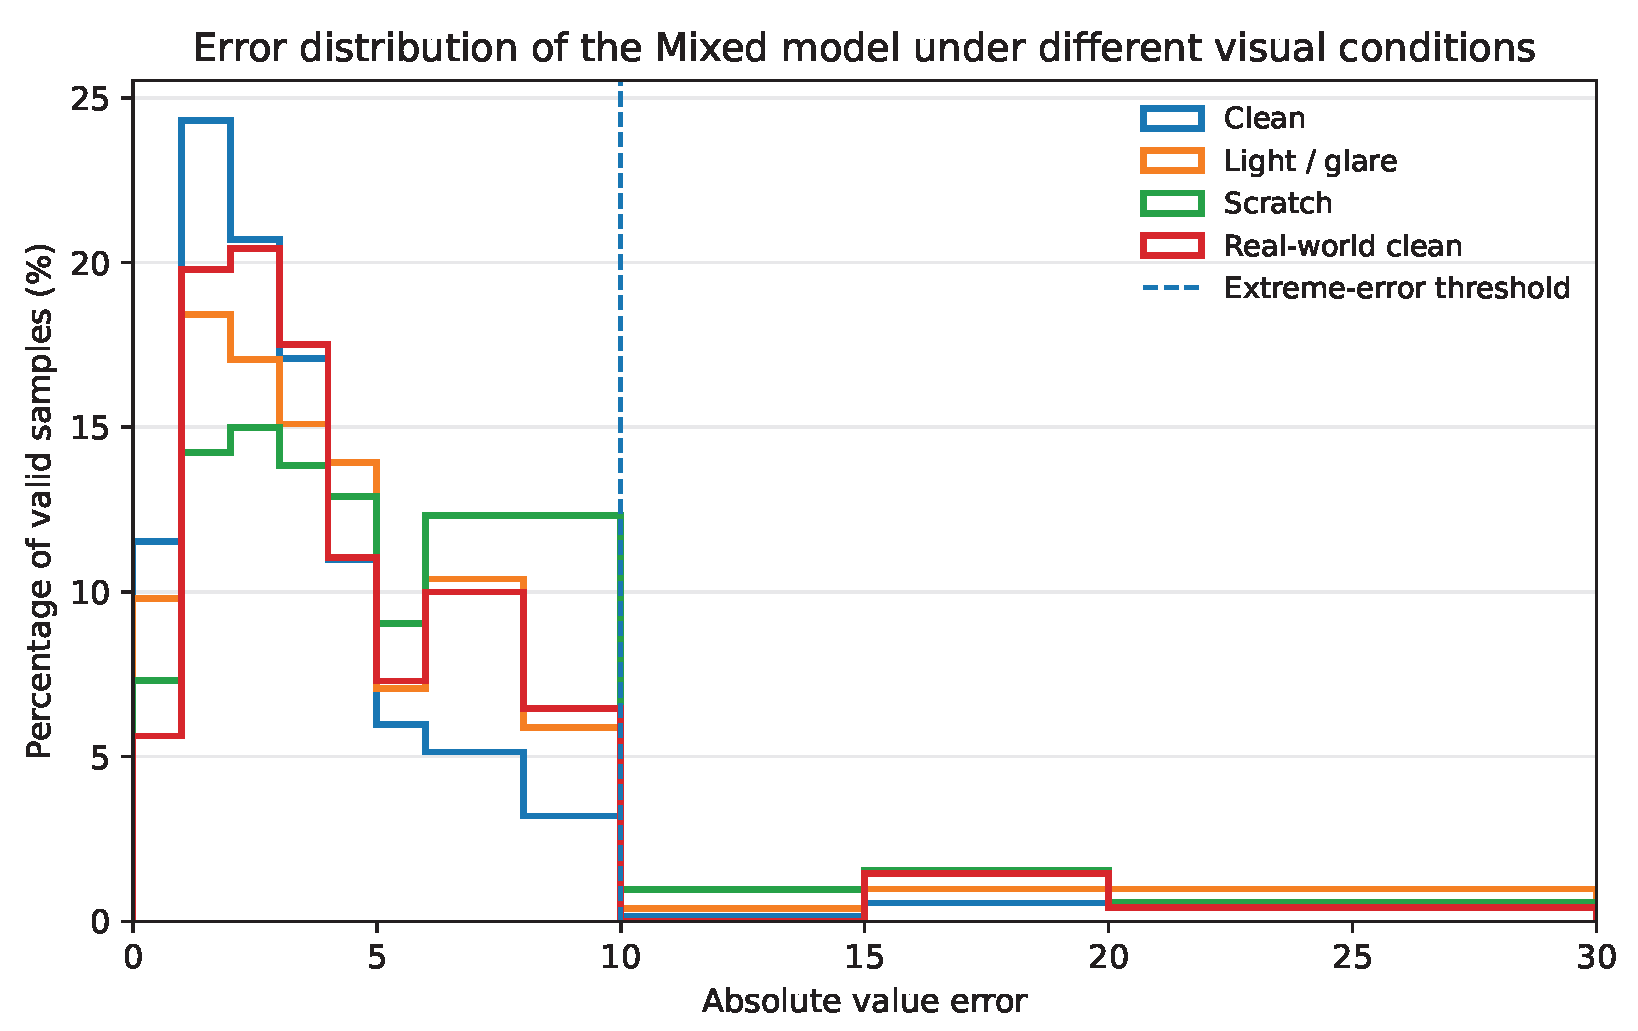
The remaining errors are more frequent under scratch and glare conditions, where pointer boundaries and tick marks are partially corrupted. This supports the interpretation that the major limitation is still precise visual measurement under degraded local evidence, rather than type or unit recognition.
Figure 13 further illustrates the distribution of absolute value errors under different visual conditions. Most valid predictions are concentrated in the low-error region, whereas scratch and glare conditions show heavier right tails and a higher proportion of samples beyond the extreme-error threshold. This trend is consistent with Table 15, indicating that the remaining failures are mainly associated with degraded local pointer–scale evidence rather than incorrect type or unit prediction.
In addition to the quantitative condition-wise analysis, we also inspect representative residual-error cases of the Mixed model. Although overall performance improves substantially, about 57% of samples still fail to achieve fully correct joint predictions. Current errors are mainly concentrated under extreme visual conditions: severe occlusion, very poor illumination, or tick marks/pointer segments being covered by reflections; and type confusion caused by a small number of “unusual-looking” gauges, such as a thermometer that visually resembles a common pressure gauge. We also observe that the model sometimes confuses 1 and 7 near the zero tick, which is related to local pointer-shape distortion caused by reflective occlusion. These observations suggest potential directions for improvement, such as introducing OCR to read tick texts for unit verification or leveraging multi-view images for joint reasoning.

5.8. Comparison with Specialized Gauge-Reading Methods

From the perspectives of reading accuracy and engineering applicability, Granite-Vision differs in positioning from traditional vision-based gauge-reading solutions. Many early works employed rule-based digital image processing pipelines. For example, Chi et al. estimated the angle between the pointer and scale by edge detection and circle/line fitting and then computed the gauge reading by combining the scale range and zero position [26]. Li et al. targeted safety inspection scenarios and integrated dial detection, tick-mark segmentation, and pointer localization into a geometric fitting pipeline for automatic detection and reading of multiple industrial gauges [27]. Such methods share clear geometric models and strong interpretability and do not rely on large-scale labeled data. Under fixed installation positions and controllable lighting, reliable readings can be obtained after careful manual calibration. However, they often require designing thresholds and geometric constraints separately for each specific gauge type; are sensitive to viewpoint changes, reflections, stains, and partial occlusions; and incur high maintenance costs when transferring across devices and scenarios.
With the development of deep learning, an increasing number of works have adopted end-to-end or two-stage neural gauge-reading frameworks. For instance, Zuo et al. proposed an improved Mask R-CNN-based method for pointer-gauge reading, jointly learning instance segmentation of the dial region, tick marks, and pointer to achieve more robust pointer localization and reading across multiple dial types [28]. Lin et al. designed an intelligent gauge-reading system that combines convolutional neural networks with traditional geometric post-processing to automatically recognize and read different categories of pointer gauges [29]. Peixoto et al. focused on IoT applications and deployed lightweight convolutional networks on edge devices and local servers to enable remote meter reading and alarms [30]. These methods often achieve high numerical accuracy and some degree of viewpoint robustness on task-specific datasets, but they still require re-collecting data and fully training or fine-tuning networks for different industries and gauge appearances. Moreover, their task space is mainly limited to “reading regression”, making it difficult to simultaneously handle complex textual semantics and multi-turn interaction requirements.
Compared with these specialized pipelines, the proposed framework is not intended to replace all conventional gauge-reading methods in every deployment scenario. Instead, its main purpose is to adapt an existing multimodal large language model to structured industrial gauge reading, where the model is required to jointly output gauge type, numeric value, unit information, and auditable textual responses. Therefore, a fair comparison should consider not only numerical reading accuracy but also structured-output consistency, parsing coverage, invalid-output rate, and the ability to bind visual readings with semantic information.
To provide a stronger reference than zero-shot MLLM prompting, we additionally implement two specialized baselines under the identical train/validation/test split and evaluation protocol. All methods receive a cropped image containing a single gauge. The crop is produced by the same fixed upstream gauge detector used during dataset preparation; the detector is not updated during the baseline experiments. This ensures that the comparison focuses on gauge interpretation rather than on differences in gauge localization.
Geometry/Hough baseline. The geometry-based baseline first applies conventional image preprocessing and uses OpenCV Hough-circle detection to estimate the outer dial boundary. Probabilistic Hough line detection is then applied to obtain candidate line segments. Candidate pointer segments are filtered according to their length and their spatial proximity to the detected dial center, and the longest plausible center-crossing segment is retained as the pointer. The numerical reading is calculated from the pointer angle using the per-category predefined start angle, end angle, and measurement range (e.g., all pressure gauges share a fixed range of 0–1.6 MPa; all temperature gauges share 0–100 °C). These per-category ranges are known from the gauge specification and are not derived from the individual sample ground truth; thus, no per-sample information leakage occurs. If the dial circle cannot be detected or no valid pointer candidate satisfies the geometric constraints, the output is marked as invalid and contributes to the invalid-output rate.
CNN multi-task baseline. The learning-based specialized baseline uses an ImageNet-pretrained ResNet-50 backbone with a shared feature extractor and two output heads. The classification head is a fully connected layer that predicts one of the four gauge types. The regression head outputs a single normalized reading value in [ 0 , 1 ] , defined relative to the per-category numerical range of the corresponding gauge (e.g., 0–1.6 for pressure; 0–100 for temperature). The actual value is recovered as v ^ = s min + v ^ norm · ( s max s min ) , where s min , s max are fixed per category. The training objective is
L CNN = L CE + L MSE ,
where L CE is the cross-entropy loss for gauge-type classification, and L MSE is the mean-squared error for normalized-value regression. Input images are resized and randomly crop-rescaled to 224 × 224 . The model is trained for 50 epochs with a batch size of 32 using Adam, an initial learning rate of 10 3 , and step-wise learning-rate decay. The CNN baseline is reported from one deterministic training run because of computational constraints; it is therefore used as a same-split reference rather than as the basis for a statistical superiority claim.
For both non-generative baselines, the unit is assigned deterministically from the predicted gauge type using the same fixed type–unit mapping adopted in the dataset annotations. Consequently, Unit-Acc equals Type-Acc for these two baselines and should not be interpreted as an independently learned unit-recognition capability. All methods are evaluated using Type-Acc, Unit-Acc, Value-Acc, Joint-Acc, parsing coverage, invalid-output rate, MAE over valid predictions, and penalized normalized MAE over all samples.
Keypoint-supervised and segmentation-supervised baselines were not included in the same-split quantitative comparison because the current dataset provides image-level type, value, and unit annotations but does not provide the fine-grained geometric annotations required by such methods, including dial centers, pointer tips, reference-scale keypoints, or pointer masks. Constructing these annotations only for a small subset would not support a fair comparison on the complete test set. We therefore compare methods that can be trained under the same annotation protocol, while leaving keypoint- and segmentation-based evaluation to a future extension of the dataset.
For both non-generative baselines, range and angle metadata are fixed per gauge category, not per image. The MLLM-based method does not receive such explicit numerical range parameters; it must infer the range from visual context.
As shown in Table 16, the specialized baselines provide a stronger comparison than zero-shot MLLM prompting alone. The fine-tuned Granite-Vision model achieves the highest Type-Acc, Unit-Acc, Value-Acc, and Joint-Acc among the compared methods, indicating that structured multimodal adaptation improves the consistency of type–value–unit prediction. The CNN multi-task baseline remains competitive in penalized normalized error because it always produces a numeric output, whereas the geometry-based pipeline may fail when pointer localization, dial fitting, or reference-scale estimation is unreliable. These results suggest that the proposed framework is most useful when structured output, unit binding, and auditable textual responses are required, while lightweight specialized models remain attractive for resource-constrained deployment.‘ 1
Nevertheless, the large-model solution does not dominate traditional methods across all criteria. Under extreme imaging conditions such as very small targets, severe blur, or strong reflections, specialized segmentation/detection networks that are carefully optimized for pointer and tick textures may still have advantages in local detail modeling. In addition, current multimodal large models incur substantially higher inference latency and computational cost than lightweight convolutional networks or traditional digital image-processing algorithms, which limits their direct deployment on ultra-low-latency or resource-constrained edge nodes. Overall, Granite-Vision is better suited to settings that require a unified model for multiple gauge types, structured reading tasks, unit-aware outputs, and textual interaction, whereas traditional rule-based methods and specialized deep networks remain reasonable choices when the priority is maximum task-specific accuracy, low cost, or fixed-scenario online monitoring.


6. Conclusions and Future Work

This paper presents a staged PEFT framework for industrial pointer-gauge reading with multimodal large language models. Across data construction, backbone screening, parameter-efficient adaptation, and evaluation, the goal is to make MLLM-based gauge reading more robust, reproducible, and relevant to practical industrial settings. In particular, we reformulate gauge reading as a structured multimodal prediction task through VQA-style supervision and combine this task formulation with a deployment-oriented evaluation protocol. Rather than introducing a new foundation model, the central contribution of this work is a reusable adaptation and evaluation recipe for applying existing multimodal models to industrial measurement tasks that require structured numerical outputs, unit-aware prediction, and auditable evaluation.
Empirically, the fine-tuned Granite-Vision 3.2 model demonstrates substantial improvement over the evaluated zero-shot baselines, achieving 99.9% type accuracy, 43.77% reading accuracy, 43.60% joint accuracy, and an MAE of 3.98 on the constructed test set. The 43.60% Joint-Acc demonstrates a clear improvement over untuned MLLM prompting, but it also shows that a considerable fraction of samples still contain at least one incorrect component among type, value, and unit. Therefore, the current system should be interpreted as a promising structured-reading framework rather than as a finished safety-critical industrial reading solution. At the same time, the proposed workflow provides practical components beyond the final model itself, including a dataset protocol, a unified screening procedure, Projector-LoRA adaptation, constrained numerical post-processing, and a transparent evaluation pipeline whose metrics and splits are fully documented.
The experimental protocol also includes same-split comparisons with a Geometry/Hough baseline and a CNN multi-task baseline. All methods are evaluated under the same train/validation/test split and scored using Type-Acc, Value-Acc, Joint-Acc, parsing coverage, invalid-output rate, MAE-valid, and nMAE-all. Since type and unit are deterministically linked in this benchmark, Unit-Acc for the specialized baselines is identical to Type-Acc and serves as a consistency check rather than an independent unit recognition capability. The results show that the fine-tuned Granite-Vision model achieves stronger type–value–unit consistency, while lightweight specialized models remain competitive in penalized numerical error and computational practicality. This suggests that the MLLM-based framework is beneficial when structured output and auditable textual responses are needed, whereas specialized models remain attractive for resource-constrained deployment.
The evaluation protocol further covers coverage-aware metrics, tolerance-threshold sensitivity, run-to-run variability across independent seeds, type-level confusion analysis, condition-wise error statistics, and error-distribution visualization. These analyses provide a more conservative assessment of the proposed framework. The type-level confusion results indicate that semantic type recognition errors are rare after fine-tuning, whereas the condition-wise and distributional analyses show that the remaining failures are mainly associated with degraded local pointer–scale evidence under glare, scratches, occlusion, blurred tick marks, and ambiguous pointer boundaries.
Several limitations remain. First, the current dataset focuses mainly on four common gauge categories and single-pointer dials, leaving more complex settings such as multi-pointer instruments, multi-scale layouts, and non-linear scales insufficiently explored. Second, the present framework operates primarily on single static images and does not explicitly exploit multi-view or temporal information, which may limit robustness under severe reflections, partial occlusions, or long-term drift. Third, although the framework improves structured reading performance, higher-level tasks such as alarm interpretation, causal diagnosis, and maintenance recommendation are still beyond the scope of the current study. These limitations define the practical boundary of the current methodology: it is best viewed as an adaptation and evaluation framework for controlled industrial reading studies rather than as a finished deployment product.
Fourth, MLLM-based numeric generation can still produce plausible but incorrect readings, especially when the local visual evidence of pointer and scale marks is degraded. Therefore, practical deployment should involve human verification, uncertainty checks, or independent rule-based safeguards. Fifth, the computational cost and latency of large-model inference remain important barriers for edge deployment on inspection robots or resource-constrained industrial devices. Most importantly, incorrect gauge readings can have serious consequences in safety-sensitive industrial settings, so the current method should not be used as a fully autonomous decision module without additional verification mechanisms.
This study focuses on baselines that can be trained or evaluated using the same annotation level as the proposed framework. Keypoint-supervised and segmentation-supervised gauge-reading pipelines are not included in the same-split comparison because they require additional point- or mask-level annotations, such as dial centers, pointer tips, reference scale marks, and pointer masks, which are beyond the current dataset annotation protocol. Future dataset extensions may include such fine-grained geometric annotations to support more detailed comparisons with segmentation- and keypoint-based methods.
Future work can extend this line of research in three directions. First, broader datasets and task definitions can be developed by incorporating more diverse gauge families and multi-task supervision, such as joint reading, OCR-based scale verification, limit-exceedance diagnosis, and abnormal-state interpretation. Second, hybrid systems that combine explicit geometric priors with multimodal large models could be explored to improve interpretability and numerical reliability under difficult visual conditions. Third, model compression, distillation, and lightweight adapter deployment should be investigated for edge-side inspection robots and resource-constrained industrial devices. Overall, we view this work not as a complete solution to industrial gauge reading but as a practical step toward more reliable, evaluation-transparent, and traceable multimodal visual measurement systems.

Supplementary Materials

The following supporting information can be downloaded at https://www.mdpi.com/article/10.3390/app16167924/s1: Table S1: Detailed full-test performance of the Clean-only, Noisy-only, and Mixed strategies across five matched random seeds, { 1 , 2 , 3 , 4 , 5 } .

Author Contributions

Conceptualization, J.W., X.L. and W.S.; Methodology, J.W., X.L. and W.S.; Investigation, J.W., X.L. and W.S.; Writing—original draft, X.L.; Writing—review & editing, J.W. and W.S.; Visualization, X.L.; Supervision, J.W. and W.S.; Project administration, W.S. All authors have read and agreed to the published version of the manuscript.

Funding

This research received no external funding.

Institutional Review Board Statement

Not applicable.

Informed Consent Statement

Not applicable.

Data Availability Statement

The dataset used in this study contains self-constructed images and images obtained from public or third-party sources. Due to license and redistribution restrictions, the raw images and trained model weights cannot be publicly released. To support transparency and future reproducibility, the following materials will be made publicly available on GitHub 3.12 upon acceptance of this manuscript: (1) A de-identified split manifest (CSV file) listing for each image its dataset split (train/val/test), assigned condition label (clean/light/scratch/real-clean), and source category (self-made or public reference). The manifest contains no raw image data. (2) Image preprocessing and evaluation scripts (Python 3.11), including the regex-based parser, tolerance-based metric computation, and constrained decoding wrapper. (3) A document describing the exact train/validation/test split procedure, performed at the original image level before augmentation to prevent any original image from appearing in more than one split. Aggregate experimental results and five-seed statistics are fully reported in this manuscript and Table S1.

Conflicts of Interest

The authors declare no conflicts of interest. The funders had no role in the design of the study; in the collection, analyses, or interpretation of data; in the writing of the manuscript; or in the decision to publish the results.

References

  1. Ninama, H.; Raikwal, J.; Ravuri, A.; Sukheja, D.; Bhoi, S.K.; Jhanjhi, N.Z.; Elnour, A.A.H.; Abdelmaboud, A. Computer vision and deep transfer learning for automatic gauge reading detection. Sci. Rep. 2024, 14, 23019. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  2. Leon-Alcazar, J.; Alnumay, Y.; Zheng, C.; Trigui, H.; Patel, S.; Ghanem, B. Learning to Read Analog Gauges from Synthetic Data. In Proceedings of the IEEE/CVF Winter Conference on Applications of Computer Vision (WACV), Waikoloa, HI, USA, 4–8 January 2024. [Google Scholar]
  3. Reitsma, M.; Keller, J.; Blomqvist, K.; Siegwart, R. Under pressure: Learning-based analog gauge reading in the wild. arXiv 2024, arXiv:2404.08785. [Google Scholar]
  4. Zhang, C.; Shi, L.; Zhang, D.; Ke, T.; Li, J. Pointer Meter Recognition Method Based on YOLOv7 and Hough Transform. Appl. Sci. 2023, 13, 8722. [Google Scholar] [CrossRef] [Scilit]
  5. Laroca, R.; Barroso, V.; Diniz, M.A.; Gonçalves, G.R.; Schwartz, W.R.; Menotti, D. Convolutional Neural Networks for Automatic Meter Reading. J. Electron. Imaging 2019, 28, 013023. [Google Scholar] [CrossRef] [Scilit]
  6. Liu, H.; Li, C.; Wu, Q.; Lee, Y.J. Visual Instruction Tuning. In Proceedings of the Neural Information Processing Systems (NeurIPS), New Orleans, LA, USA, 10–16 December 2023. [Google Scholar]
  7. Wang, P.; Bai, S.; Tan, S.; Wang, S.; Fan, Z.; Bai, J.; Chen, K.; Liu, X.; Wang, J.; Ge, W.; et al. Qwen2-VL: Enhancing Vision-Language Model’s Perception of the World at Any Resolution. arXiv 2024, arXiv:2409.12191. [Google Scholar]
  8. Mukhopadhyay, S.; Qidwai, A.; Garimella, A.; Ramu, P.; Gupta, V.; Roth, D. Unraveling the Truth: Do VLMs really Understand Charts? A Deep Dive into Consistency and Robustness. In Proceedings of the Findings of Empirical Methods in Natural Language Processing (EMNLP), Miami, FL, USA, 12–16 November 2024. [Google Scholar]
  9. Huang, K.H.; Qin, C.; Qiu, H.; Laban, P.; Joty, S.; Xiong, C.; Wu, C.S. Why Vision Language Models Struggle with Visual Arithmetic? Towards Enhanced Chart and Geometry Understanding. In Proceedings of the Findings of Association for Computational Linguistics (ACL), Vienna, Austria, 27 July–1 August 2025. [Google Scholar]
  10. Canny, J. A Computational Approach to Edge Detection. IEEE Trans. Pattern Anal. Mach. Intell. 1986, PAMI-8, 679–698. [Google Scholar] [CrossRef] [Scilit]
  11. Duda, R.O.; Hart, P.E. Use of the Hough Transformation to Detect Lines and Curves in Pictures. Commun. ACM 1972, 15, 11–15. [Google Scholar] [CrossRef] [Scilit]
  12. Howells, B.; Charles, J.; Cipolla, R. Real-Time Analogue Gauge Transcription on Mobile Phone. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops, Virtual, 19–25 June 2021. [Google Scholar]
  13. Salomon, G.; Laroca, R.; Menotti, D. Deep Learning for Image-based Automatic Dial Meter Reading: Dataset and Baselines. arXiv 2020, arXiv:2005.03106. [Google Scholar]
  14. Salomon, G.; Laroca, R.; Menotti, D. Image-based Automatic Dial Meter Reading in Unconstrained Scenarios (UFPR-ADMR-v2). arXiv 2022, arXiv:2201.02850. [Google Scholar]
  15. Bai, J.; Bai, S.; Yang, S.; Wang, S.; Tan, S.; Wang, P.; Lin, J.; Zhou, C.; Zhou, J. Qwen-VL: A Versatile Vision-Language Model for Understanding, Localization, Text Reading, and Beyond. arXiv 2023, arXiv:2308.12966. [Google Scholar]
  16. Yao, Y.; Yu, T.; Zhang, A.; Wang, C.; Cui, J.; Zhu, H.; Cai, T.; Li, H.; Zhao, W.; He, Z.; et al. MiniCPM-V: A GPT-4V Level MLLM on Your Phone. arXiv 2024, arXiv:2408.01800. [Google Scholar]
  17. Singh, A.; Natarajan, V.; Shah, M.; Jiang, Y.; Chen, X.; Parikh, D.; Rohrbach, M. Towards VQA Models that can Read. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Long Beach, CA, USA, 15–20 June 2019. [Google Scholar]
  18. Biten, A.F.; Tito, R.; Mafla, A.; Gómez, L.; Karatzas, D. Scene Text Visual Question Answering. In Proceedings of the International Conference on Computer Vision (ICCV), Seoul, Republic of Korea, 27 October–2 November 2019. [Google Scholar]
  19. Mathew, M.; Karatzas, D.; Jawahar, C.V. DocVQA: A Dataset for VQA on Document Images. In Proceedings of the IEEE/CVF Winter Conference on Applications of Computer Vision, Virtual, 5–9 January 2021. [Google Scholar]
  20. Mathew, M.; Bagal, V.; Tito, R.P.; Karatzas, D.; Valveny, E.; Jawahar, C.V. InfographicVQA. arXiv 2021, arXiv:2104.12756. [Google Scholar]
  21. Methani, N.; Ganguly, P.; Khapra, M.; Kumar, P. PlotQA: Reasoning over Scientific Plots. In Proceedings of the IEEE/CVF Winter Conference on Applications of Computer Vision, Snowmass Village, CO, USA, 1–5 March 2020. [Google Scholar]
  22. Masry, A.; Long, D.; Tan, J.Q.; Joty, S.; Hoque, E. ChartQA: A Benchmark for Question Answering about Charts. In Proceedings of the Findings of Association for Computational Linguistics (ACL), Dublin, Ireland, 22–27 May 2022. [Google Scholar]
  23. Hu, E.J.; Shen, Y.; Wallis, P.; Allen-Zhu, Z.; Li, Y.; Wang, S.; Wang, L.; Chen, W. LoRA: Low-Rank Adaptation of Large Language Models. arXiv 2021, arXiv:2106.09685. [Google Scholar]
  24. Dettmers, T.; Pagnoni, A.; Holtzman, A.; Zettlemoyer, L. QLoRA: Efficient Finetuning of Quantized LLMs. In Proceedings of the Advances in Neural Information Processing Systems (NeurIPS), New Orleans, LA, USA, 10–16 December 2023. [Google Scholar]
  25. Banks, J.; Warkentin, T. Gemma: Introducing New State-of-the-Art Open Models. Google Deepmind Technical Report. 2024. Available online: https://ai.google.dev/gemma (accessed on 5 August 2025).
  26. Chi, J.; Liu, L.; Liu, J.; Jiang, Z.; Zhang, G. Machine Vision-Based Automatic Detection Method of Indicating Values of a Pointer Gauge. Math. Probl. Eng. 2015, 2015, 283629. [Google Scholar] [CrossRef] [Scilit]
  27. Li, B.; Yang, J.; Zeng, X.; Yue, H.; Xiang, W. Automatic Gauge Detection via Geometric Fitting for Safety Inspection. IEEE Access 2019, 7, 87042–87048. [Google Scholar] [CrossRef] [Scilit]
  28. Zuo, L.; He, P.; Zhang, C.; Zhang, Z. A Robust Approach to Reading Recognition of Pointer Meters Based on Improved Mask-RCNN. Neurocomputing 2020, 388, 90–101. [Google Scholar] [CrossRef] [Scilit]
  29. Lin, Y.; Zhong, Q.; Sun, H. A Pointer-Type Instrument Intelligent Reading System Design Based on Convolutional Neural Networks. Front. Phys. 2020, 8, 618917. [Google Scholar] [CrossRef] [Scilit]
  30. Peixoto, J.; Sousa, J.; Carvalho, R.; Santos, G.; Mendes, J.; Cardoso, R.; Reis, A. Development of an Analog Gauge Reading Solution Based on Computer Vision and Deep Learning for an IoT Application. Telecom 2022, 3, 564–580. [Google Scholar] [CrossRef] [Scilit]
Figure 1. Staged closed loop (horizontal): “(A) data and annotation protocol → (B) unified multi-model selection → (C) PEFT fine-tuning and mechanisms → (D) unified robustness evaluation”, with error analysis feeding back into data supplementation.
Applsci 16 07924 g001
Figure 2. Dataset construction pipeline.
Applsci 16 07924 g002
Figure 3. Examples from each dataset subset.
Applsci 16 07924 g003
Figure 4. Conceptual workflow for structured gauge reading.
Applsci 16 07924 g004
Figure 5. PEFT illustration.
Applsci 16 07924 g005
Figure 6. Data packaging and conditional anti-center-cropping: from images and JSON annotations to instruction samples and image tensors, with center cropping disabled based on paths to preserve boundary tick marks.
Applsci 16 07924 g006
Figure 7. Unified evaluation protocol: from raw textual answers to regex parsing, type–unit binding checks, and tolerance-based decisions and finally aggregating task and resource metrics.
Applsci 16 07924 g007
Figure 8. Zero-shot performance comparison of different MLLMs on the test sets. The x-axis lists models (Qwen2.5-VL-3B, Granite-Vision 3.2, Gemma-3, LLaVA-7B, and MiniCPM-V), and the y-axis shows Type-Acc, Value-Acc, and Joint-Acc. Type identification consistently outperforms numerical reading, confirming that “geometry–value mapping” is the primary bottleneck for structured gauge reading.
Applsci 16 07924 g008
Figure 9. Trends of Joint-Acc and MAE during fine-tuning under three training configurations (Clean, Noisy, and Mixed). The left panel shows joint accuracy across epochs, and the right panel shows the corresponding mean absolute error. All three configurations exhibit steadily increasing Joint-Acc and decreasing MAE values, and the Mixed configuration achieves the highest joint accuracy and the lowest MAE after convergence.
Applsci 16 07924 g009
Figure 10. Overall performance comparison of Granite-Vision before and after fine-tuning (zero-shot versus Clean-only, Noisy-only, and Mixed fine-tuning). The left panel shows Type-Acc, Value-Acc, and Joint-Acc, and the right panel shows MAE-valid. All three fine-tuning strategies substantially improve structured reading performance over the zero-shot backbone, with the Mixed strategy providing the strongest overall accuracy–error trade-off among the evaluated fine-tuned variants.
Applsci 16 07924 g010
Figure 11. Qualitative case study of analog gauge reading. The model identifies the instrument type as pressure_gauge, identifies the unit as MPa, and outputs the reading value (e.g., 6.4). (The “#” symbols in the image represent a visual simulation of the model weight loading progress.)
Applsci 16 07924 g011
Figure 12. Type-level confusion matrix for the Mixed setting on the test set. Rows denote ground-truth types, and columns denote predicted types.
Applsci 16 07924 g012
Figure 13. Error distribution of the Mixed model under different visual conditions. The histogram is computed over valid predictions, and the dashed vertical line indicates the extreme-error threshold used in Table 15.
Applsci 16 07924 g013
Table 1. Morphology and disturbance taxonomy.
MorphologyDisturbance TypeDescription
cleannoneIncludes self-made clean images and real clean images.
lightopticalOptical disturbances synthesized for self-made data (highlights, reflections, exposure shifts, mild blur, etc.) and optical augmentations derived from real-clean images.
scratchstructuralStructural disturbances synthesized for self-made data (scratches, occlusions, etc.) and structural augmentations derived from real-clean images.
mixedpaired clean–noisy concatenationUsed only during training by concatenating clean and degraded versions of the same base image under the same target annotation. No explicit contrastive loss is used.
Table 2. Source distribution (total: 13,870).
SourceCountShare
Self-made544639.3%
Public/Real (compliant use)842460.7%
Total13,870100%
Table 3. Counts of self-made data by morphology and split.
MorphologyTrainValTest-SynthTotal
clean (base)8721091081089
light (synthetic optical)17422182182178
scratch (synthetic structural)17432172192179
Subtotal43575445455446
Table 4. Real (8424) split and augmentation routing.
DestinationCountDescription
Test (clean-test)168520% of real, preserving “real clean” evaluation semantics
Train/Val entry (real-clean)673980% of real is merged into clean, then augmented into light/scratch
Table 5. Approximate Train/Val distribution over three morphologies for real-clean data (6739).
MorphologyTotal(Train/Val)
clean2696≈2426/270
light2022≈1820/202
scratch2021≈1819/202
Table 6. Overall Train/Val/Test distribution across three morphologies.
SplitCleanLightScratchTotal
Train32983562356210,422
Val3794204191218
Test17932182192230
Total54704200420013,870
Table 7. Fixed type–unit bindings.
Gauge TypeUnit
temperature°C
pressureMPa
voltageV
currentA
Table 8. Zero-shot baseline results on the test sets (mean of five independent runs). Although type identification is acceptable, numerical-reading performance remains low for all evaluated models, with Value-Acc below 15%, and MAE is high. Granite-Vision provides a better trade-off between accuracy and resource overhead (resource overhead is reported in Table 9) and is therefore selected as the backbone for subsequent fine-tuning.
ModelType-AccValue-AccJoint-AccMAE
Qwen2.5-VL-3B93.67%14.33%13.81%28.27
Granite-Vision90.00%9.23%8.46%37.37
Gemma-386.13%4.97%4.72%43.25
LLaVA-7B63.43%2.13%0.98%188,629,696,945.43
MiniCPM-V-8B24.13%1.27%0.21%7,589,949.62
Table 9. Inference resource overhead of candidate backbone models. All measurements are obtained on the same NVIDIA RTX 4090 GPU with batch size 1 under a unified inference protocol. Latency denotes average end-to-end time per image after warm-up, and peak memory denotes maximum allocated GPU memory during inference.
ModelParameter ScaleLatency/ImagePeak VRAM
Qwen2.5-VL-3B3B50 ms16 GB
Granite-Vision 3.23B including vision50 ms16 GB
Gemma-3-4B4B60 ms18 GB
LLaVA-7B7B70 ms24 GB
MiniCPM-V-8B8B80 ms32 GB
Table 11. Coverage-aware numerical evaluation of the fine-tuned variants on the full test set. Results are averaged over five independent runs where applicable.
Training SettingCoverageInvalid-Output RateMAE-ValidnMAE-All
Clean-only97.62%2.38% 5.18 ± 0.18 0.071
Noisy-only98.07%1.93% 4.31 ± 0.16 0.059
Mixed98.65%1.35% 3.98 ± 0.10 0.052
Table 12. Tolerance sensitivity of Value-Acc and Joint-Acc under the Mixed setting.
Tolerance Setting τ abs τ rel Value-AccJoint-Acc
Strict0.250.5%34.82%34.76%
Default0.501.0%43.77%43.60%
Loose1.002.0%55.14%55.03%
Table 13. Summary of ablation experiments under the Mixed configuration. All results, including the “Mixed (full)” baseline, are from a single run with seed 1.
SettingType-AccValue-AccJoint-AccCoverageInvalidMAE-ValidnMAE-All
Mixed (full)99.9043.4543.2598.651.353.850.052
w/o conditional anti-center-cropping96.4542.6539.7097.802.204.050.060
w/o paired mixed-noise training99.1237.1836.9698.101.904.420.063
w/o numerically constrained post-processing99.7241.8341.7199.500.505.470.078
Notes on changes: w/o conditional anti-center-cropping—reverting to default center-crop for all images degrades type recognition on off-center gauges and slightly increases invalid rate. w/o paired mixed-noise training—using separate clean–noisy samples instead of paired concatenation reduces Value-Acc and Joint-Acc, especially under scratch. w/o numerically constrained post-processing—removing the format-and-range gate improves coverage (fewer rejects) but allows extreme outlier values, which inflate both MAE-valid and nMAE-all. All ablation experiments were conducted with seed 1, and the baseline “Mixed (full)” reflects the performance of seed 1 (see Table S1 for seed-wise results).
Table 14. Bootstrap uncertainty analysis of pairwise differences between the Mixed ensemble and the Clean-only/Noisy-only ensembles. The 95% confidence intervals and two-sided tail probabilities are based on 10,000 paired sample resamples.
ComparisonMetricObserved DifferenceBootstrap 95% CIBootstrap p-Value
Mixed vs. Clean-onlyJoint-Acc+21.19 pp[+19.45, +22.88] pp<0.001
Mixed vs. Noisy-onlyJoint-Acc+6.24 pp[+4.98, +7.50] pp<0.001
Mixed vs. Clean-onlyMAE-valid 1.20 [ 1.52 , 0.88 ]<0.001
Mixed vs. Noisy-onlyMAE-valid 0.33 [ 0.48 , 0.19 ]<0.001
Note: Differences are Mixed minus the compared strategy. The reported intervals and tail probabilities are descriptive measures of sample-level variability, not formal hypothesis tests. These values quantify the stability of the observed differences under sample resampling but do not account for additional variability from model training or data collection.
Table 15. Condition-wise error analysis of the Mixed strategy, averaged over the five independent runs. The weighted averages across conditions are consistent with the full-test results in Table 10 (Value-Acc: 43.77%; Joint-Acc: 43.60%).
ConditionSamplesValue-AccJoint-AccMAE-ValidExtreme Error
Clean72049.38%49.20%3.251.12%
Light/glare51042.16%42.00%4.152.35%
Scratch52037.85%37.69%4.853.08%
Real-world clean48043.47%43.30%3.951.87%
Table 16. Same-split comparison with specialized gauge-reading baselines.
MethodType-AccUnit-AccValue-AccJoint-AccCoverageInvalidMAE-ValidnMAE-All
Geometry/Hough baseline84.36%84.36%31.42%28.12%91.20%8.80%6.720.094
CNN multi-task baseline96.28%96.28%38.61%36.77%100.00%0.00%4.910.049
Granite-Vision + Projector-LoRA (Mixed)99.90%99.90%43.77%43.60%98.65%1.35%3.980.052
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content.