1. Introduction
In recent years, the context window size of Large Language Models (LLMs) has continued to expand, making long-context processing a central research direction in intelligent agents, code generation, and complex task reasoning [
1,
2,
3]. However, a larger context window does not necessarily lead to more stable long-horizon generation. Existing benchmarks and empirical studies have shown that LLMs may still fail to use long contexts effectively, especially when key information is located in less salient positions or when long-range dependencies must be maintained across multiple reasoning stages [
4,
5,
6]. In prolonged interactions, multi-file code analysis, and complex task planning, LLMs may still suffer from context drift, dependency fragmentation, and global consistency degradation [
7,
8,
9].
Existing studies have addressed long-context modeling from several complementary directions. Transformer-based architectures provide the foundation for modern sequence modeling [
10], while subsequent long-context methods extend the effective context range through segment-level recurrence, sparse or global attention, memory compression, and recurrent memory mechanisms [
11,
12,
13,
14,
15]. Retrieval-based methods further enhance long-range information access by retrieving relevant external or historical information when the required information exceeds the active context window [
16,
17]. Memory-augmented approaches also introduce explicit memory mechanisms to extend the usable history of language models [
18]. These methods have substantially improved long-range information access, context utilization, and memory efficiency.
At the workflow level, long-context management has also evolved beyond simple summarization or sliding-window truncation into multi-stage processes of context organization and reconstruction [
19,
20,
21]. Modern agent systems commonly integrate mechanisms such as historical summarization, context compression, retrieval augmentation [
17,
22], local cleanup, and session memory compaction [
23,
24] to progressively control context growth and mitigate organizational distortion during long-horizon tasks. In deployed coding-agent workflows, context compaction and history summarization are also commonly used to release active context space for subsequent reasoning when the interaction history approaches the context limit [
25,
26]. These workflow-level strategies show that long-context management is not only an architectural problem, but also a process-level problem of how historical information is reorganized and reused.
Although these approaches are effective in extending, retrieving, compressing, or reusing historical information, long-horizon generation is not only a problem of preserving more tokens or retrieving more fragments. In many structured generation tasks, the key challenge is to maintain the organizational relationships that remain relevant across stages, such as topic direction, section-level planning, argument progression, local transition constraints, task-specific semantic anchors, and dependencies among intermediate states. A model may retain partial awareness of what has happened, while gradually losing the structural relationships among information units, the propagation paths of long-term constraints, and the hierarchical organization of multi-stage tasks [
27,
28].
From this perspective, context compression can be reinterpreted as a high-level process of abstraction and organization. Its objective is not limited to reducing token consumption, but also includes preserving the structures that remain useful for subsequent reasoning and generation. Inspired by logic-related abstraction and higher-order reasoning perspectives [
29,
30,
31], we introduce the concept of Order to characterize changes in organizational hierarchy during the abstraction process of contextual information. In this paper, Order does not refer only to logical order in the formal sense; rather, it is extended into a context-oriented representation concept for describing how raw information is lifted into higher-level organizational structures.
Most existing context compression methods already perform a form of Order Elevation, where large amounts of raw contextual information are transformed into higher-level abstract representations to reduce subsequent reasoning complexity. However, the core limitation of many current approaches does not lie in whether abstraction is performed, but in whether the abstraction process follows stable organizational directions. If heterogeneous information is repeatedly compressed into a single undifferentiated summary or accumulated as a long token sequence, task-relevant organizational structures may become entangled with irrelevant details, making later generation less controllable.
In practical tasks, the same context can be abstracted along different organizational trajectories. In structured reasoning and planning scenarios, contextual information may be organized according to entities, relations, reasoning paths, intermediate states, or task-specific dependency structures [
32,
33,
34]. In product-oriented writing, the same input may be organized according to target users, usage scenarios, selling points, emotional anchors, or article structure. Different organizational trajectories lead to different abstraction outcomes, and the stability of long-horizon generation often depends on whether critical trajectories can be preserved throughout the generation process. Recent studies have also explored context compression, sparse computation, memory management, and training strategies to improve long-context utilization and inference efficiency [
35,
36,
37,
38,
39]. These studies further indicate that long-context processing involves not only longer context windows, but also more effective organization and use of contextual information.
We refer to such organizational trajectories as Dimensions. The term Dimension does not denote a mathematical dimension in vector space. Instead, it describes a task-oriented organizational direction formed during contextual abstraction. A Dimension is therefore not treated as an independent static label, but as a structural direction that determines which relationships should be preserved, strengthened, or ignored under a given task objective. Without Order Elevation, no higher-level organizational trajectory can be formed; with different elevation trajectories, different Dimensions naturally emerge.
Based on this view, existing compression, retrieval, and memory-based methods can preserve useful information and delay context degradation, but they may still lack an explicit dimension-level constraint mechanism for maintaining stable organizational direction across stages. As a result, heterogeneous dependency structures may be merged into unified compressed representations during iterative abstraction, leading to blurred organizational boundaries, interference among propagation paths, and gradual degradation of long-term structural stability. In other words, existing approaches often focus on what information should be preserved, while paying less attention to along which Dimension the abstraction and propagation process should proceed.
To address this issue, we propose a Recursive Dimension-Constrained Organizational Relay (DCOR) framework. Unlike conventional one-shot global compression methods, DCOR does not uniformly abstract the entire historical context into a single compressed representation. Instead, it selects task-relevant Dimensions, performs local generation under dimensional constraints, propagates finite organizational states across stages, and converges these states into final textual outputs. Through recursive organizational relay, DCOR aims to maintain task-relevant structural continuity under restricted local-context conditions. DCOR is intended as a workflow-level complement to architecture-level long-context models, retrieval-augmented generation, and memory-based methods, rather than as a replacement for these approaches.
The main contributions of this paper are as follows.
First, we propose a dimension-oriented theoretical perspective for long-context management. This perspective treats context not merely as a linear token container, but as an evolving organizational structure. It introduces Order and Dimension to describe how task-relevant organizational structures are extracted, elevated, and propagated during long-horizon generation.
Second, we introduce the DCOR framework as a workflow-level method for long-horizon generation. The framework consists of Organizational Set Extraction, Dimension-Constrained Generation, Organizational Relay, and Organizational Convergence. Instead of repeatedly replaying the complete historical context, DCOR propagates finite organizational states that preserve task-relevant structure across generation stages.
Third, we instantiate DCOR in two generation tasks: cumulative multi-instance advertisement generation and long-form article generation. The advertisement task evaluates large-scale structured generation under repeated localized generation, while the long-form article task evaluates sustained section-level organization and repetition control in a single long-form output.
Fourth, we conduct an expanded empirical evaluation using ten independent runs for each principal experimental condition. In addition to direct generation, rolling-summary generation, and hierarchical-outline generation, we introduce a Neural RAG-Memory baseline to provide a stronger retrieval-based comparison. We further conduct component ablations for Dimension, Organizational Relay, and Order; a pilot human assessment of selected DCOR outputs; a cross-backbone replication using Qwen3.7-Plus; and an observational analysis of workflow-level model calls, token usage, and execution time.
The results demonstrate complementary and task-dependent findings rather than uniformly superior performance on all evaluation metrics. In advertisement generation, both DCOR and Neural RAG-Memory successfully completed the cumulative multi-instance generation workflow, while the format-matched evaluation revealed different repetition and diversity profiles across methods. In long-form article generation, DCOR achieves the lowest mean character-level 4-gram and 6-gram repetition among all evaluated methods, including Neural RAG-Memory, although it does not achieve the best performance on every lexical diversity metric. The ablation results further show that removing Dimension, Organizational Relay, or Order consistently increases character-level repetition, providing component-level evidence for the contribution of all three mechanisms. The successful execution of the same DCOR workflow using Qwen3.7-Plus further demonstrates implementation-level cross-backbone transferability.
Overall, the empirical findings support a bounded interpretation of DCOR. The framework provides a workflow-level mechanism for maintaining and propagating task-relevant organizational states under restricted local-context conditions.
The remainder of this paper is organized as follows.
Section 2 introduces the theoretical foundation of Order and Dimension.
Section 3 presents the Recursive Dimension-Constrained Organizational Relay framework.
Section 4 reports the experimental design, baseline comparisons, human evaluation, ablation study, cross-backbone analysis, and computational-cost analysis.
Section 5 discusses the empirical findings, boundary conditions, limitations, and future work.
2. Theoretical Foundation
2.1. Order and Dimension as Organizational Abstraction
The concept of
Order in this study is inspired by changes in the abstraction level of reasoning objects in formal logic [
40,
41,
42].
In First-Order Logic, quantification is typically performed over individual objects. For example,
where
denotes an individual object,
and
denote predicates.
Second-order logic additionally permits quantification over predicates, properties, or relations. A generic second-order expression can be written as
where
denotes a predicate or property, while
and
denote individual objects. The purpose of Equation (2) is not to state a universally valid logical law, but to illustrate that the quantified object can be elevated from an individual entity to a predicate or relational structure.
This distinction motivates the organizational use of Order in the present study. However, DCOR is not formally derived from first- or second-order logic. Rather, the logical distinction provides an analogy for changes in the type of information processed by a generation workflow. At a lower organizational level, the system may process raw textual elements or concrete facts. At a higher organizational level, it may process relations, task constraints, section roles, dependency structures, or intermediate plans.
Accordingly, we define Order as the organizational abstraction level and relational complexity of the information being processed. Order elevation transforms lower-order information units into higher-order representations composed of properties, relations, constraints, and dependency structures. As Order increases, the processed objects become more abstract and the organizational relationships among them become more complex. This concept is inspired by changes in logical order, but is used operationally in DCOR rather than as a formal equivalence to higher-order logic.
We further define Dimension as the task-oriented direction along which this elevation is performed. Dimension does not refer to a mathematical dimension in a vector space. Instead, it specifies which organizational relationships should remain active under a particular task objective. A Dimension may determine which relations should be preserved, emphasized, weakened, or temporarily excluded during abstraction and generation.
Order and Dimension therefore describe two related but distinct aspects of organizational abstraction. Order specifies the abstraction level of the representation, whereas Dimension specifies the task-oriented direction according to which that representation is constructed.
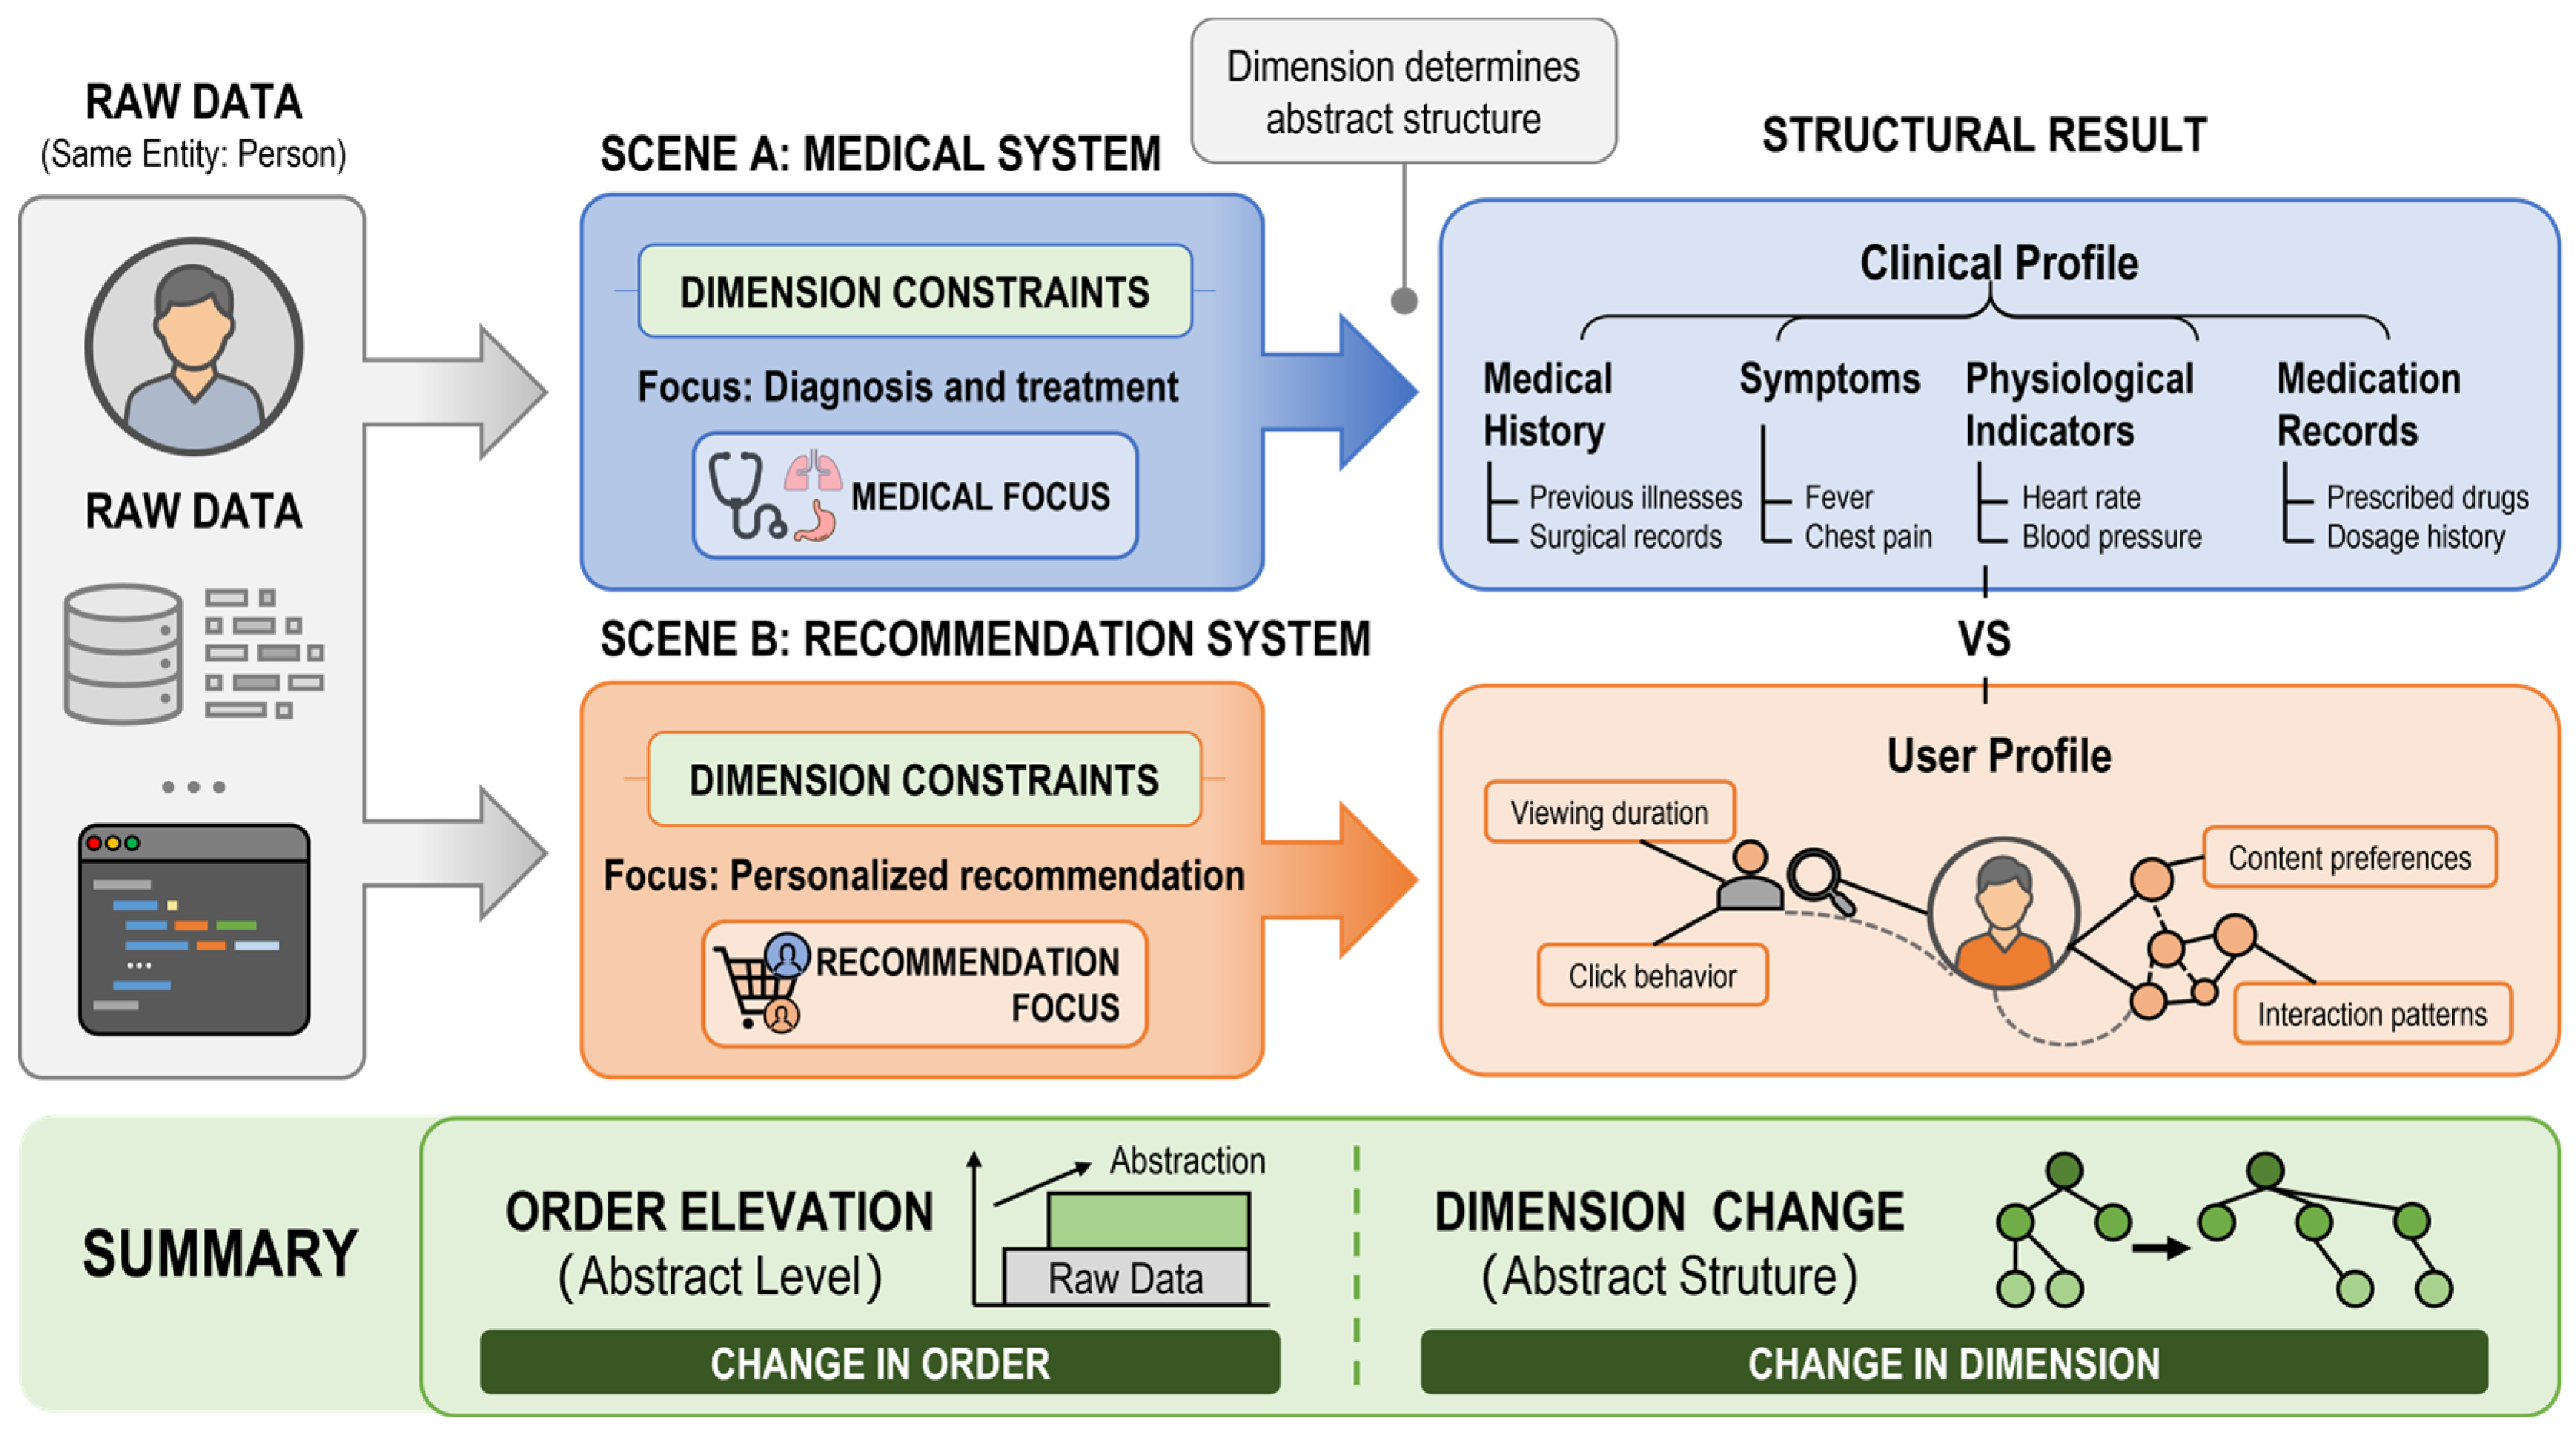
Figure 1 illustrates the dimension-oriented elevation process of Order.
2.2. Dimension as Task-Oriented Structure Selection
A Dimension determines how information is organized and which structures should remain active during long-horizon generation. Existing context compression and summarization methods often adopt a uniform elevation strategy: the historical context is compressed into a single abstract representation in order to preserve as much information as possible within a limited context window. However, in complex tasks, information is not equally important. Different task stages require different organizational structures to remain salient.
From this perspective, the essence of a Dimension is task-driven organizational structure selection. A Dimension determines not only what information should be retained, or ignored, but also how the retained information should be organized for use in the current and subsequent stages. This selective preservation reduces interference from task-irrelevant information and helps the generation process remain focused on the current organizational objective.
For example, in a medical task, the relevant Dimension may preserve symptom correlations, indicator changes, medication–disease dependencies, and clinical temporal progression. In a recommendation task, the relevant Dimension may instead preserve interest transitions, behavioral patterns, interaction frequency, and long-term preference evolution. These two tasks may involve overlapping raw information, but they require different organizational structures to be maintained.
Therefore, a Dimension can be regarded as a task-oriented preservation mechanism for organizational structures. In the context of long-horizon generation, dimensional constraints guide the model to expand within task-relevant semantic and structural directions, rather than treating the entire historical context as an undifferentiated information container.
2.3. Dimension Collapse in Uniform Context Compression
The context management problem in large language models is often described as a limitation of context length. However, from the organizational perspective, an equally important issue is the loss of stable dimensional structure during compression and propagation.
In this paper, we use dimension collapse as a descriptive term for a potential failure mode in which heterogeneous organizational relationships are mixed into a unified representation, causing task-relevant structures to lose decomposability, traceability, and local controllability. When historical context is compressed globally and non-hierarchically, information from different task dimensions may become entangled. As a result, critical dependency relationships may be weakened, while task-irrelevant relationships may continue to consume part of the active context budget.
At the output level, dimension collapse may produce an organizational analogue of hallucination: the generated text may remain locally fluent and plausible while gradually deviating from the intended task structure or mixing organizational directions that should remain distinct. This interpretation is related to prior discussions of hallucination as a consequence of probabilistic language generation [
43]. However, the failure mode considered here is not limited to factual fabrication. It concerns the loss, mixing, or uncontrolled propagation of task-relevant organizational constraints across generation stages.
For example, in a medical task, preserving entertainment preferences, video-click behavior, or social interaction records may be unnecessary even if such information belongs to the same user history. If such relationships are repeatedly mixed into the compressed context, they may interfere with symptom–indicator dependencies and clinical temporal structures. In generation tasks, a similar problem can occur when topic, style, argument, example, and conclusion structures are compressed into a single undifferentiated summary.
Thus, long-context degradation does not arise only from increasing token length. It can also arise from the uncontrolled mixing of organizational structures during repeated compression, summarization, or context propagation. This perspective motivates the need for explicit dimensional constraints in long-horizon generation workflows.
2.4. Dimension-Oriented Context Management
Based on the preceding analysis, we treat context not merely as a linear token container, but as an evolving organizational structure. In long-horizon tasks, the goal of context management is not necessarily to preserve more historical tokens. Instead, the goal is to preserve the organizational relationships that remain relevant to the current task, including dependency structures, intermediate constraints, section-level plans, topic anchors, and transition states.
Dimension-oriented context management therefore shifts the focus from token preservation to organizational-state preservation. Instead of repeatedly replaying the complete historical context, the system extracts and propagates finite organizational states under task-relevant Dimensions. These states provide a compact but structured representation of what should remain active in subsequent generation stages.
This theoretical perspective leads to the proposed Dimension-Constrained Organizational Relay framework. The framework uses dimensional constraints to guide local generation directions, organizational relay to propagate finite structured states across stages, and organizational convergence to integrate the propagated states into final textual outputs. In this way, the framework aims to support long-horizon generation under restricted local-context conditions while reducing interference from task-irrelevant historical information.
2.5. Relationship Among Order, Dimension, and Organizational State
The concepts of Order, Dimension, and organizational state describe different aspects of the same abstraction and propagation process.
Order: Order describes the organizational abstraction level and relational complexity of the information being processed. Order elevation transforms lower-order information units into higher-order representations composed of properties, relations, constraints, and dependency structures. Order reduction transforms higher-order organizational structures into more concrete, locally executable, or textual representations.
Dimension: Dimension describes the task-oriented direction along which Order elevation is performed. It determines not only which information should be retained or ignored, but also how the retained information should be organized for use in the current and subsequent stages.
Organizational state: An organizational state is a finite structured representation constructed under one or more active Dimensions. It records the task-relevant goals, relationships, constraints, anchors, plans, and intermediate results that should remain available to later generation stages.
Organizational Relay: Organizational Relay transfers and updates organizational states across workflow stages. Rather than repeatedly replaying the complete accumulated text, each stage receives the finite state required for its local objective.
Organizational Convergence: Organizational Convergence performs Order reduction by integrating the propagated higher-order organizational states and rendering them into the required final textual output.
Taken together, Order describes the level and relational complexity of representation, Dimension specifies the direction of task-oriented organization, organizational state serves as the finite carrier of the selected relationships, and Organizational Relay transfers this state across stages.
Section 3 explains how these concepts are instantiated in the DCOR workflow.
3. Recursive Dimension-Constrained Organizational Relay Framework
3.1. Framework Overview
Building upon the concepts of Order and Dimension introduced in
Section 2, we further propose a Recursive Dimension-Constrained Organizational Relay (DCOR) framework for long-horizon generation under restricted local-context conditions. The central idea of DCOR is to replace full historical token replay with the propagation of finite organizational states. Instead of repeatedly appending or reconstructing the complete generation history, the framework extracts, updates, and relays structured representations that preserve the task-relevant organization of the generation process.
In conventional long-context workflows, continuity is often maintained by preserving more historical text, compressing previous content into summaries, or retrieving relevant fragments from external memory. These strategies are useful, but they still treat the historical context primarily as a token sequence or a set of text fragments. As the task becomes longer, heterogeneous information such as topic goals, local examples, stylistic constraints, argument structure, and transition states may become mixed in the active context. This can increase organizational complexity and weaken the controllability of subsequent generation stages.
DCOR addresses this problem from an organizational perspective. It assumes that long-horizon generation does not always require the repeated propagation of complete historical text. What must be maintained is the task-relevant organizational structure, including dimensional states, dependency relationships, intermediate constraints, topic anchors, and local transition states. These elements are represented as organizational states and are recursively updated between generation stages.
The overall framework is defined as:
where:
: Organizational Set Extraction
: Dimension-Constrained Generation
: Organizational Relay
: Organizational Convergence
The four operators correspond to the principal stages of the DCOR workflow. Organizational Set Extraction transforms the raw task context into structured task-relevant elements. Dimension-Constrained Generation performs localized generation under an active task-oriented Dimension. Organizational Relay extracts, updates, and transfers finite organizational states between stages. Organizational Convergence integrates the propagated states and renders them into the required final textual output.
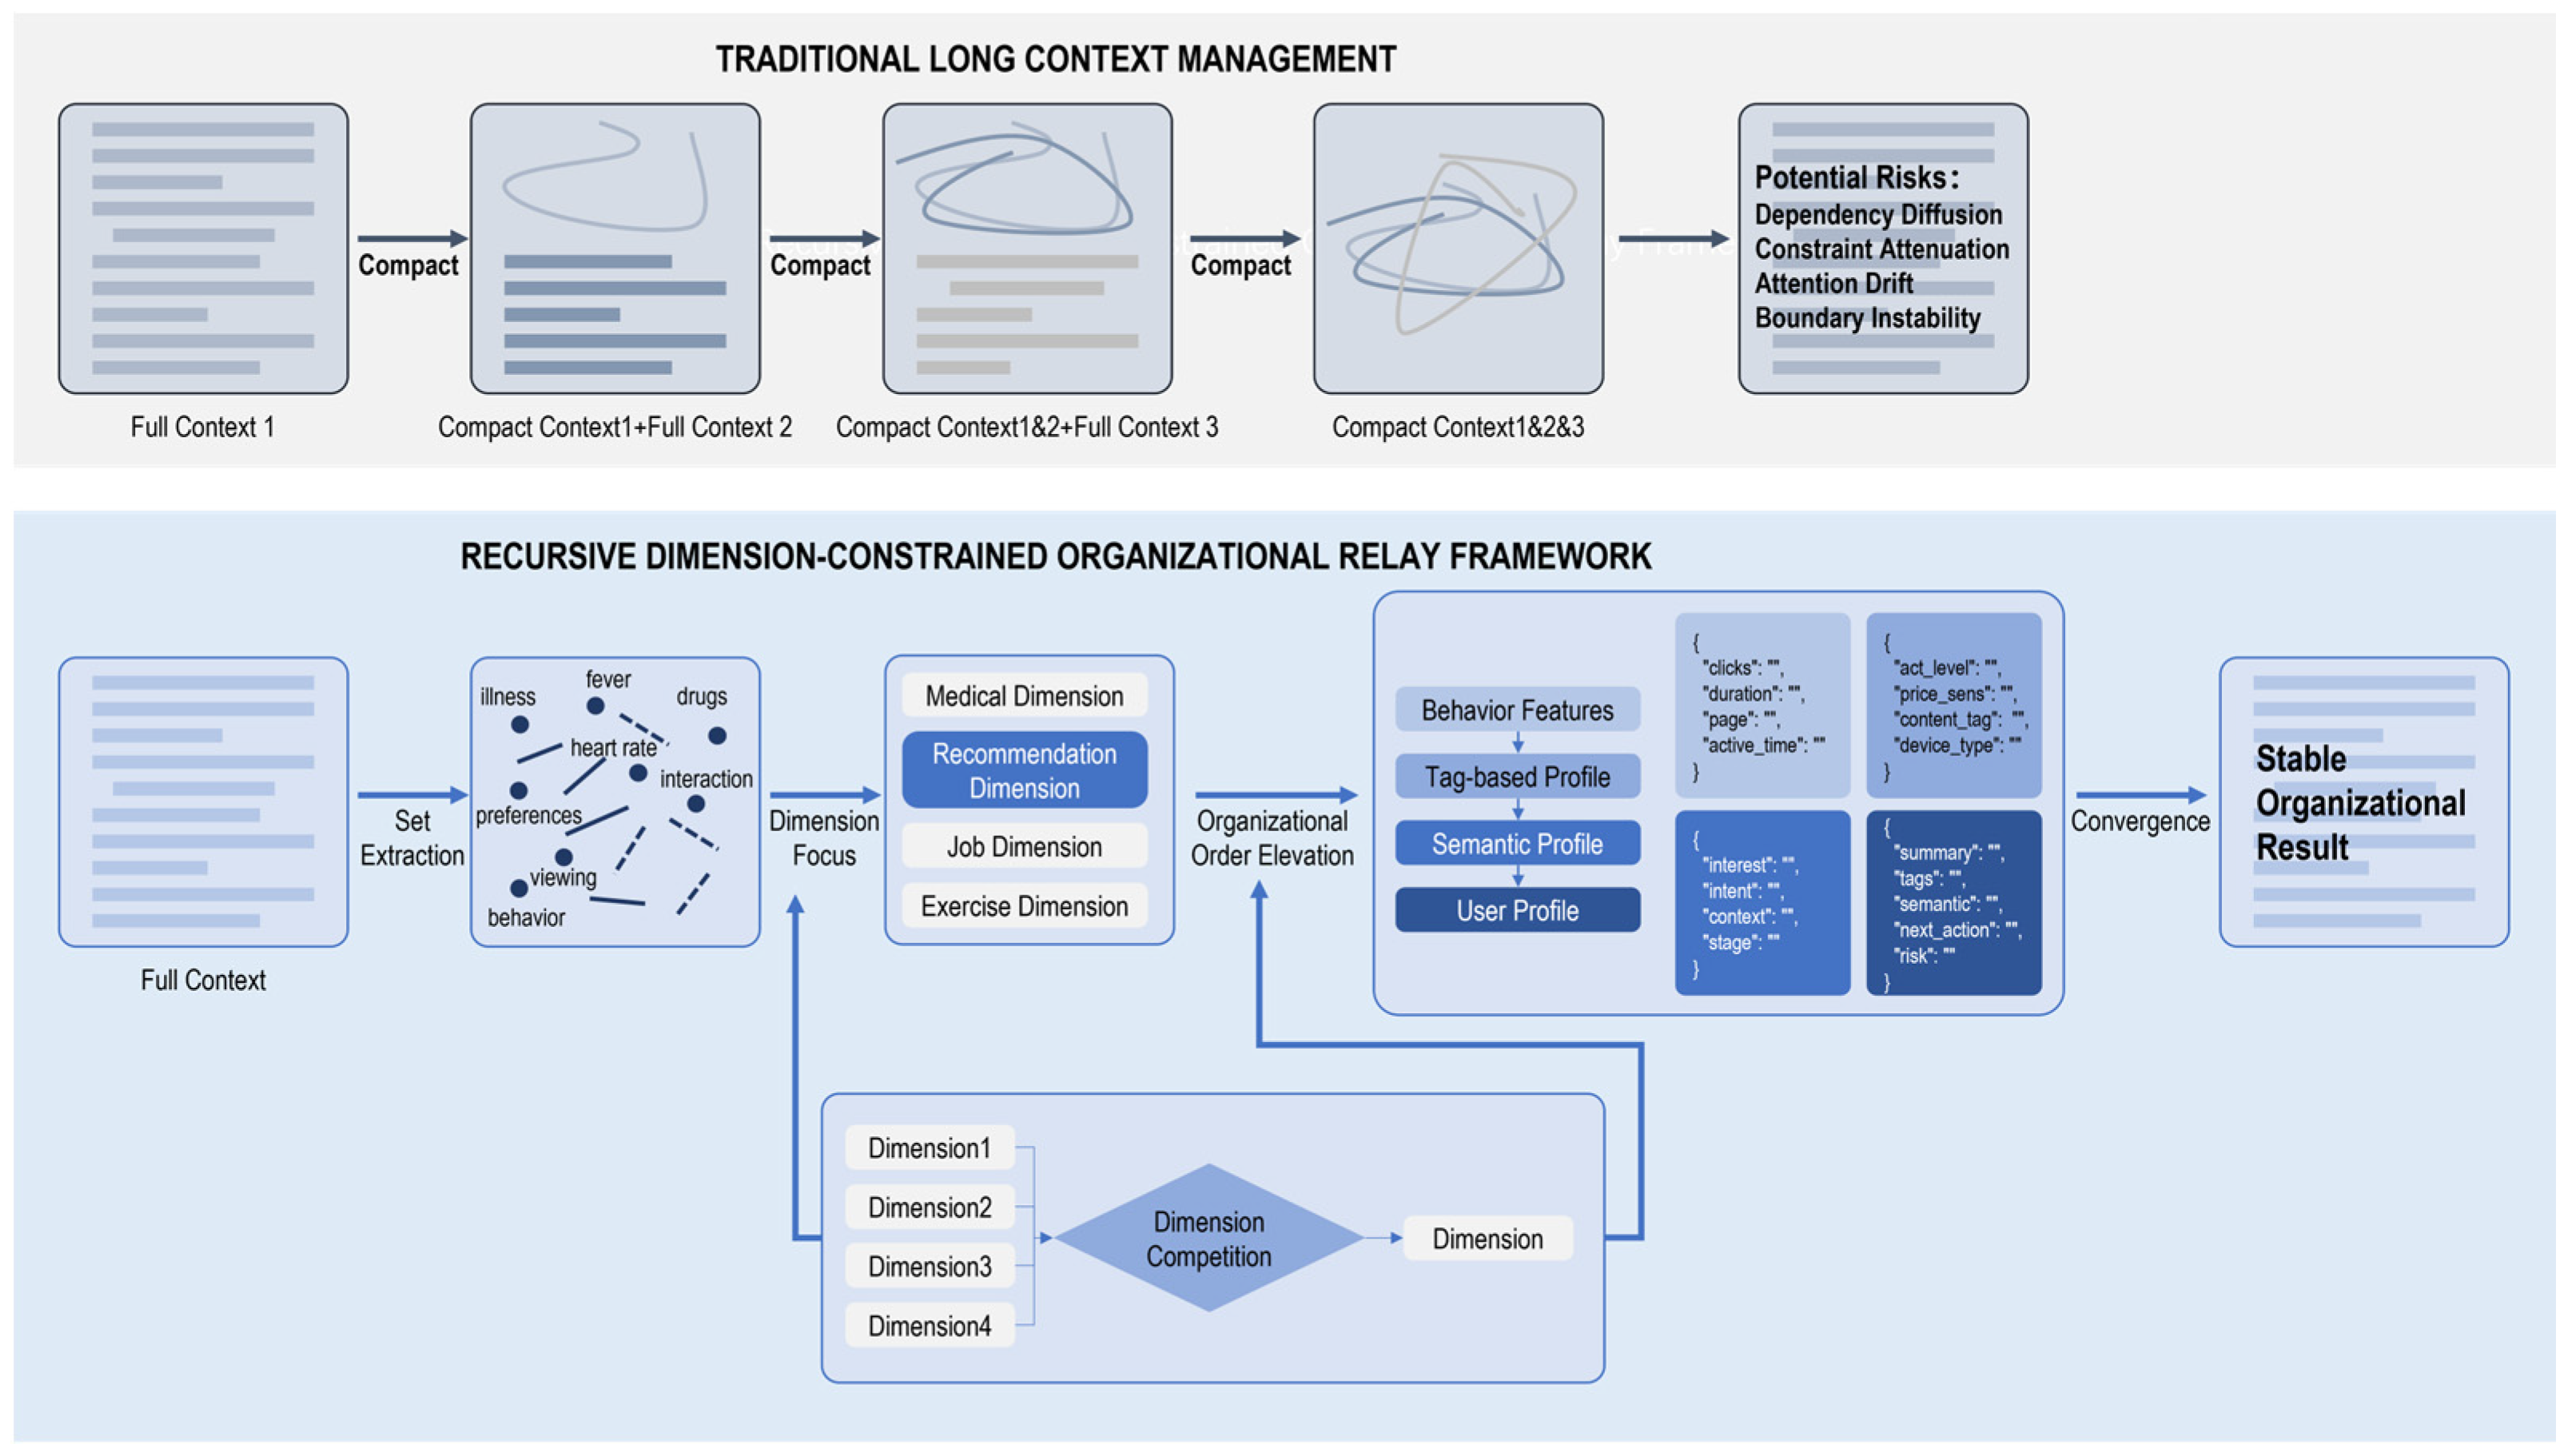
Figure 2 illustrates the conceptual comparison between repeated context compaction and the DCOR workflow.
The complete stage-wise execution procedure of DCOR is summarized in Algorithm 1.
| Algorithm 1. Execution procedure of the Recursive Dimension-Constrained Organizational Relay framework |
| | Input: Raw task context X; task objective G; ordered workflow stages and Dimension configurations D. |
| | Output: Final textual output Y. |
| 1 | ← ExtractOrganizationalSet |
| 2 | ← InitializeOrganizationalState |
| 3 | H ← InitializeOrganizationalTopology |
| 4 | for t = 1 to T do |
| 5 | ← SelectActiveDimension |
| 6 | ← |
| 7 | ← GenerateWithLLM |
| 8 | ← ExtractAndUpdateState |
| 9 | if hierarchical dependencies are required then |
| 10 | ← UpdateOrganizationalTopology |
| 11 |
end if |
| 12 | end for |
| 13 | ← ConvergeOrganizationalStates |
| 14 | ← RenderFinalOutput |
| 15 | return |
Algorithm 1 provides a general description of the DCOR execution procedure. In the current implementation, the ordered stages and their candidate Dimensions are specified by the workflow configuration. An active Dimension may be directly associated with a predefined stage objective or selected from multiple candidate directions when Dimension competition is enabled. GenerateWithLLM represents a local invocation of the underlying language model, whereas ExtractAndUpdateState converts the local generation result into a finite structured state for use by subsequent stages.
ConstructLocalContext combines only the task information, active Dimension, organizational set, and relay state required by the current stage. It does not repeatedly append the complete accumulated generation history. Organizational-topology initialization and updating are optional operations and are primarily used when the task contains explicit hierarchical dependencies, as in long-form article generation.
3.2. Organizational Set Extraction
The first stage of DCOR is Organizational Set Extraction. Its purpose is to transform raw context into structured units that can be used as stable propagation carriers in subsequent stages. Unlike direct summarization, which often compresses the input into a single textual summary, Organizational Set Extraction identifies task-relevant structural elements and organizes them into dimension-related sets.
Let the raw context be defined as:
where:
The system then performs a mapping:
where:
denotes the organizational set extracted from the raw task context.
Equation (5) indicates that the raw input is transformed into a structured organizational representation rather than being propagated directly as a complete token sequence. Because the extraction is conditioned on the task objective, the same raw context may produce different organizational sets for different tasks.
The organizational set may include task goals, constraints, role relations, topic anchors, intermediate reasoning states, structural dependencies, and local transition conditions. These elements are not treated as ordinary attributes. Instead, they function as organizational nodes that guide later generation stages.
For example, in a product-oriented generation task, the extracted organizational set may include product identity, usage scenarios, target users, selling points, emotional anchors, content structure, and expected delivery format. In a long-form article generation task, the extracted set may additionally include topic direction, central viewpoint, supporting dimensions, section relations, and conclusion structure.
Through this stage, the primary workflow input changes from an undifferentiated textual sequence to a structured organizational set. This represents the first operational step of Order elevation: lower-order information units are reorganized into higher-order goals, relations, constraints, and dependencies that can be reused and updated across stages.
3.3. Dimension-Constrained Generation
After obtaining the organizational set, DCOR performs Dimension-Constrained Generation.
The purpose of this stage is to control the direction of local generation by restricting expansion to task-relevant dimensions. Instead of allowing the model to expand over all possible associations in the input context, the framework guides generation along selected semantic or structural directions.
Let the organizational set be defined as:
where
denotes the
organizational element extracted from the task context.
At workflow stage
, the system constructs a localized context
using the organizational set
S, the stage definition
, the active Dimension
, and the preceding organizational state
. The local generation result is then produced by the underlying LLM:
where:
denotes the local-context construction operation;
denotes the objective and configuration of stage ;
denotes the active Dimension;
denotes the organizational state propagated from the previous stage;
denotes the underlying LLM;
denotes the local generation result.
Different dimensions correspond to different organizational expansion trajectories.
Depending on the task scenario, dimensions may include emotional dimensions, scenario dimensions, argumentative dimensions, identity-related dimensions, structural dimensions, or constraint-oriented dimensions. For example, in advertisement generation, dimensions may include product advantage, usage scenario, emotional resonance, and story construction. In long-form article generation, dimensions may include topic selection, supporting argument, section structure, product integration, and conclusion convergence.
Dimension-Constrained Generation therefore decomposes a complex generation task into multiple localized sub-processes. Each sub-process expands within a relatively stable organizational direction. This helps reduce interference from task-irrelevant relationships and makes the generation trajectory easier to control.
In multi-dimensional settings, the framework may further apply dimension competition. Multiple candidate directions can be generated and compared according to organizational consistency, relevance to task goals, and structural compatibility with later stages. The selected dimension then becomes the active organizational direction for subsequent relay.
In the current implementation, Dimensions are primarily associated with predefined stage objectives in the workflow configuration. Dimension competition is activated only when a stage produces multiple candidate directions that require selection. It is therefore an optional operation rather than a mandatory component of every DCOR stage.
3.4. Organizational Relay
After Dimension-Constrained Generation, DCOR performs Organizational Relay. This stage is the principal mechanism for transferring task-relevant information between workflow stages without repeatedly propagating the complete accumulated textual history.
Formally, the organizational state at stage
is defined as:
where:
: denotes the local objective of stage ,
: denotes the active Dimension,
: denotes the organizational relations and dependencies that remain relevant;
: denotes task anchors, constraints, section plans, or transition conditions;
: denotes the structured intermediate result produced at stage .
The state-update operation is represented as:
where
denotes the operation that extracts task-relevant information from the local generation result
, combines it with the previous state
, and constructs the state required by subsequent stages.
This differs from a full-context propagation process, which can be represented as:
where
denotes the complete accumulated textual context available at stage
. Equation (9) represents finite organizational-state updating, while Equation (10) represents the propagation of the accumulated textual history. DCOR principally adopts the former operation. The next stage receives the organizational information required for its local objective rather than the complete text produced by all preceding stages.
The propagated state may include the current task objective, selected Dimension, topic anchors, relevant product attributes, section relationships, transition constraints, candidate decisions, and structured intermediate outputs. Which fields remain active depends on the role of the next stage.
This mechanism does not imply that historical information is discarded arbitrarily. Rather, historical information is reorganized into finite states that preserve task-relevant structure. In this sense, continuity is maintained at the organizational level instead of the token-sequence level.
The relay state is implemented as a structured or semi-structured textual record, such as a JSON object or a schema-constrained model output. It is not assumed to be a separate latent neural representation. This design allows the state to be inspected, updated, and passed between workflow nodes.
3.5. Advanced Organizational Topology
For complex long-horizon tasks, shallow organizational relay may be insufficient to maintain structural stability. Long-form generation often requires hierarchical dependencies among central viewpoints, supporting arguments, examples, transitions, and conclusions. To represent these dependencies, DCOR introduces Advanced Organizational Topology as an optional enhancement mechanism.
Traditional generation can be approximated as a linear progression:
where each textual unit or generation stage follows the preceding unit in a linear sequence. However, complex long-form tasks are rarely organized only as linear continuations. Different sections may provide support, contrast, elaboration, examples, transitions, or convergence toward a final conclusion. DCOR represents these organizational dependencies as a graph:
where:
denotes the set of organizational nodes,
denotes the set of directed organizational relationships among the nodes.
The nodes may include core viewpoints, primary supporting dimensions, secondary reasoning relations, examples, evidence structures, transition anchors, and conclusion nodes. The edges represent dependency relationships, such as support, contrast, elaboration, transition, or convergence.
This topology allows the system to maintain long-chain organizational dependencies under finite organizational states. Instead of remembering all generated text, the system maintains a structured map of how the current section relates to the overall task. In long-form article generation, this topology helps guide section planning, content expansion, and final integration. It is especially useful when the output requires sustained section-level organization rather than isolated local paragraphs.
Advanced Organizational Topology is optional. In the present implementation, it is primarily used in long-form article generation, where dependencies among multiple sections must remain explicit. The cumulative advertisement workflow mainly relies on stage-wise organizational relay and does not require the same depth of hierarchical topology.
3.6. Organizational Convergence
The final stage of DCOR is Organizational Convergence. After Organizational Set Extraction and multiple rounds of Dimension-Constrained Generation and Organizational Relay, the system integrates the propagated organizational states into a converged organizational representation.
The convergence process can be represented as:
where
denotes the converged organizational representation and
denotes the optional organizational topology.
The final textual output is then generated through:
where
denotes the final textual output and
denotes the original task objective.
Equation (13) combines task-relevant states and dependencies accumulated across the workflow. Equation (14) performs Order reduction by converting the resulting higher-order organizational representation into the concrete textual form required by the task.
DCOR does not claim that the final output is non-textual. Rather, the distinction concerns the primary unit propagated between intermediate stages. During the workflow, the system passes finite organizational states rather than repeatedly transmitting the complete generated history. At convergence, these states are integrated and rendered into the required textual output.
In advertisement generation, Organizational Convergence produces structured creative blocks according to the required output fields. In long-form article generation, it integrates the topic, section plan, supporting content, transitions, product information, and conclusion into a multi-section article.
3.7. Implementation and Computational Characteristics
DCOR is implemented as a configurable multi-stage LLM workflow. In the current system, workflow orchestration is implemented in TypeScript. Each stage is represented by a workflow node containing a local objective, an active or candidate Dimension configuration, an input schema, a prompt template, and an expected structured output.
The orchestration layer determines stage order, constructs local inputs, invokes the underlying LLM, validates or parses the generated output, and transfers the resulting organizational state to downstream nodes. Intermediate states are stored as finite structured or semi-structured textual records, including JSON objects and schema-constrained outputs. The framework does not require additional model training or modification of the underlying LLM parameters.
At the field level, the components of are mapped directly to workflow-node configurations, prompt blocks, and structured schemas. The local goal is represented by the node-local objective and is inserted into the task-objective block of the prompt. The active Dimension is represented by the node’s active or candidate Dimension configuration and is inserted into the dimensional-constraint block. The organizational relations are serialized through the dependency and relation fields, while the task anchors are represented through constraint, section-plan, product-anchor, and transition-state fields. The local result is the schema-validated structured output returned by the current node. ConstructLocalContext reads only the fields required by the current node’s input schema. After generation, ExtractAndUpdateState validates the returned result against the output schema, retains the fields required by downstream input schemas, and writes them into . The ordered stage list and, where applicable, the dependency edges in encode Order. ConvergeOrganizationalStates subsequently consumes the retained states and topology to construct the final rendering input. Thus, Dimension and Order are encoded explicitly in workflow configuration and structured prompt fields rather than inferred from the complete prior transcript.
For each stage, the active context contains the task information required by that operation, the relevant organizational elements, the active dimensional constraint, and the relay state from preceding stages. The complete accumulated output is not repeatedly appended to every subsequent prompt. Consequently, the input length of an individual model call depends primarily on its local prompt and relay state rather than on the total amount of text generated by the entire workflow.
This restriction limits the growth of the active context per call, but it does not necessarily reduce the total number of calls or the total token usage of the full workflow. DCOR exchanges repeated full-context replay for a larger number of localized generation and state-processing operations.
Let
denote the number of workflow stages and
denote the number of LLM calls executed at stage
. The total number of model calls is:
Let
and
denote the input-token and output-token counts of the
-th model call. The total workflow-level token usage is:
The computational burden therefore depends on the number of workflow stages, the number of candidate generations produced within each stage, the length of local prompts, the size of the propagated states, and the latency of the underlying LLM.
At the orchestration layer, excluding the internal cost of LLM inference, one sequential traversal requires control operations, where is the number of dependency edges in the optional organizational topology. If intermediate states are archived, workflow-level storage is , where denotes the size of . The active context of an individual call is , where is the local prompt size and is the serialized state supplied to that call. These bounds characterize workflow bookkeeping rather than the internal computational complexity of the underlying LLM. Inference latency and total resource consumption remain dominated by the selected backbone, the number of model calls, and the corresponding input and output token counts.
When candidate-generation operations within a stage are independent, they can be executed concurrently. Concurrency may reduce wall-clock execution time, but it does not reduce the total number of model calls or the total token usage. The degree of achievable concurrency also depends on dependencies among workflow nodes and the rate limits of the model provider.
The current implementation records model calls, input and output tokens, total execution time, and stage-level execution behavior. The empirical computational characteristics of the advertisement and long-form workflows are reported in
Section 4. These measurements describe the observed workflow-level burden of the implementation rather than a theoretical claim of lower computational cost than alternative approaches.
4. Experiments
4.1. Experimental Design and Evaluation Protocol
The experiments evaluate whether DCOR can support structured long-horizon generation under restricted local-context conditions by propagating finite organizational states rather than repeatedly replaying the complete generation history. The evaluation is organized around the following research questions:
RQ1: Can DCOR support large-scale structured generation under restricted local-context conditions?
RQ2: How does DCOR compare with practical generation-level baselines under the same model and task settings?
RQ3: How do DCOR and the comparison methods differ in character-level repetition and lexical diversity in cumulative advertisement and long-form article generation?
RQ4: How do human raters evaluate the coherence, structural consistency, semantic continuity, non-repetition, diversity, and overall quality of DCOR outputs?
RQ5: How do Dimension, Organizational Relay, and Order contribute to repetition control and sustained long-form generation?
RQ6: What do the separate Neural RAG-Memory comparison, cross-backbone replication, and workflow-level resource analysis reveal about DCOR?
DCOR was instantiated in two tasks: cumulative multi-instance advertisement generation and long-form article generation. The task-specific comparisons used Direct Generation, Rolling-Summary Generation, and Hierarchical-Outline Generation as practical generation-level baselines. These methods respectively generate directly from the task prompt, propagate a compact summary of prior content, or expand a previously constructed hierarchical outline. A separate comparison evaluated Neural RAG-Memory as a retrieval-based alternative using locally deployed BAAI/bge-small-zh-v1.5 embeddings, cosine similarity, and k = 3. Its results are reported separately from the original three-baseline comparisons.
All principal methods used deepseek-v4-flash with thinking mode disabled, temperature = 0.7, top-p = 0.9, and maximum output tokens = 8192. The same task inputs and decoding settings were used across methods, and all principal automatic experiments were independently repeated ten times. A separate DCOR-only replication used Qwen3.7-Plus under the same task settings. Because the baselines were not rerun with Qwen3.7-Plus, this experiment evaluates workflow-level transferability and backbone sensitivity rather than cross-backbone superiority.
For cumulative advertisement generation, the full workflow was evaluated descriptively using creative-block count, Chinese-character count, format compliance, and exact or near-duplicate outputs. A format-matched comparison using 30 creative blocks per run evaluated character-level 4-gram and 6-gram repetition and TF-IDF cosine diversity. For long-form article generation, the primary metrics were character-level 4-gram and 6-gram repetition, Distinct-2, and Distinct-3; output length and section count were treated only as descriptive indicators of sustained generation. BLEU and ROUGE were not used as primary metrics because the open-ended tasks have no single reference output.
Following a metric-validity audit, Section Coverage was excluded from the cross-method comparison because it depended on method-specific planning structures and denominators. Self-plan adherence was retained only as an internal DCOR diagnostic, entity/term consistency was excluded because the implemented proxy did not reliably represent semantic consistency across the Chinese outputs, and section-length regularity was treated only as a supplementary descriptive statistic. Automatic results are reported as means and standard deviations across ten runs; reported pairwise comparisons include effect sizes and multiplicity-adjusted p-values. The findings are interpreted as evidence for the evaluated settings rather than universal superiority across tasks, models, or prompting configurations.
Under the restricted local-context protocol, each DCOR stage received a localized prompt and a finite organizational state containing only the active Dimension, structural anchors, intermediate states, selected dependencies, and local transition conditions required for its objective. Most stage-level prompts were approximately 1.5K tokens, and the active context of an individual call remained below 10K tokens. The experiments therefore evaluate cumulative structured generation and long-form organizational generation under context decoupling rather than full-window continuation.
The automatic evaluation was complemented by a non-comparative pilot in which five raters assessed selected DCOR outputs for global coherence, structural consistency, semantic continuity, non-repetition, diversity where applicable, and overall quality. Because no baseline outputs were included, the pilot characterizes perceived DCOR quality but does not establish human-preference superiority. The long-form task also included three ten-run ablations that removed or weakened Dimension, Organizational Relay, and Order, respectively. Finally, workflow-level model calls, token usage, and wall-clock time were recorded for resource analysis; because the workflows generated different output quantities and structures, these measurements are not interpreted as output-normalized monetary or per-instance efficiency comparisons.
4.2. Cumulative Multi-Instance Advertisement Generation
4.2.1. Task Setup
The first experiment evaluates whether DCOR can generate a large number of structured advertisement creatives under restricted local-context conditions while maintaining a stable output format and avoiding trivial duplication. From a product name or description, the workflow extracts a profile containing the product identity, manufacturer, purpose, usage scenario, target audience, category, advantages, competitive information, and marketing keywords.
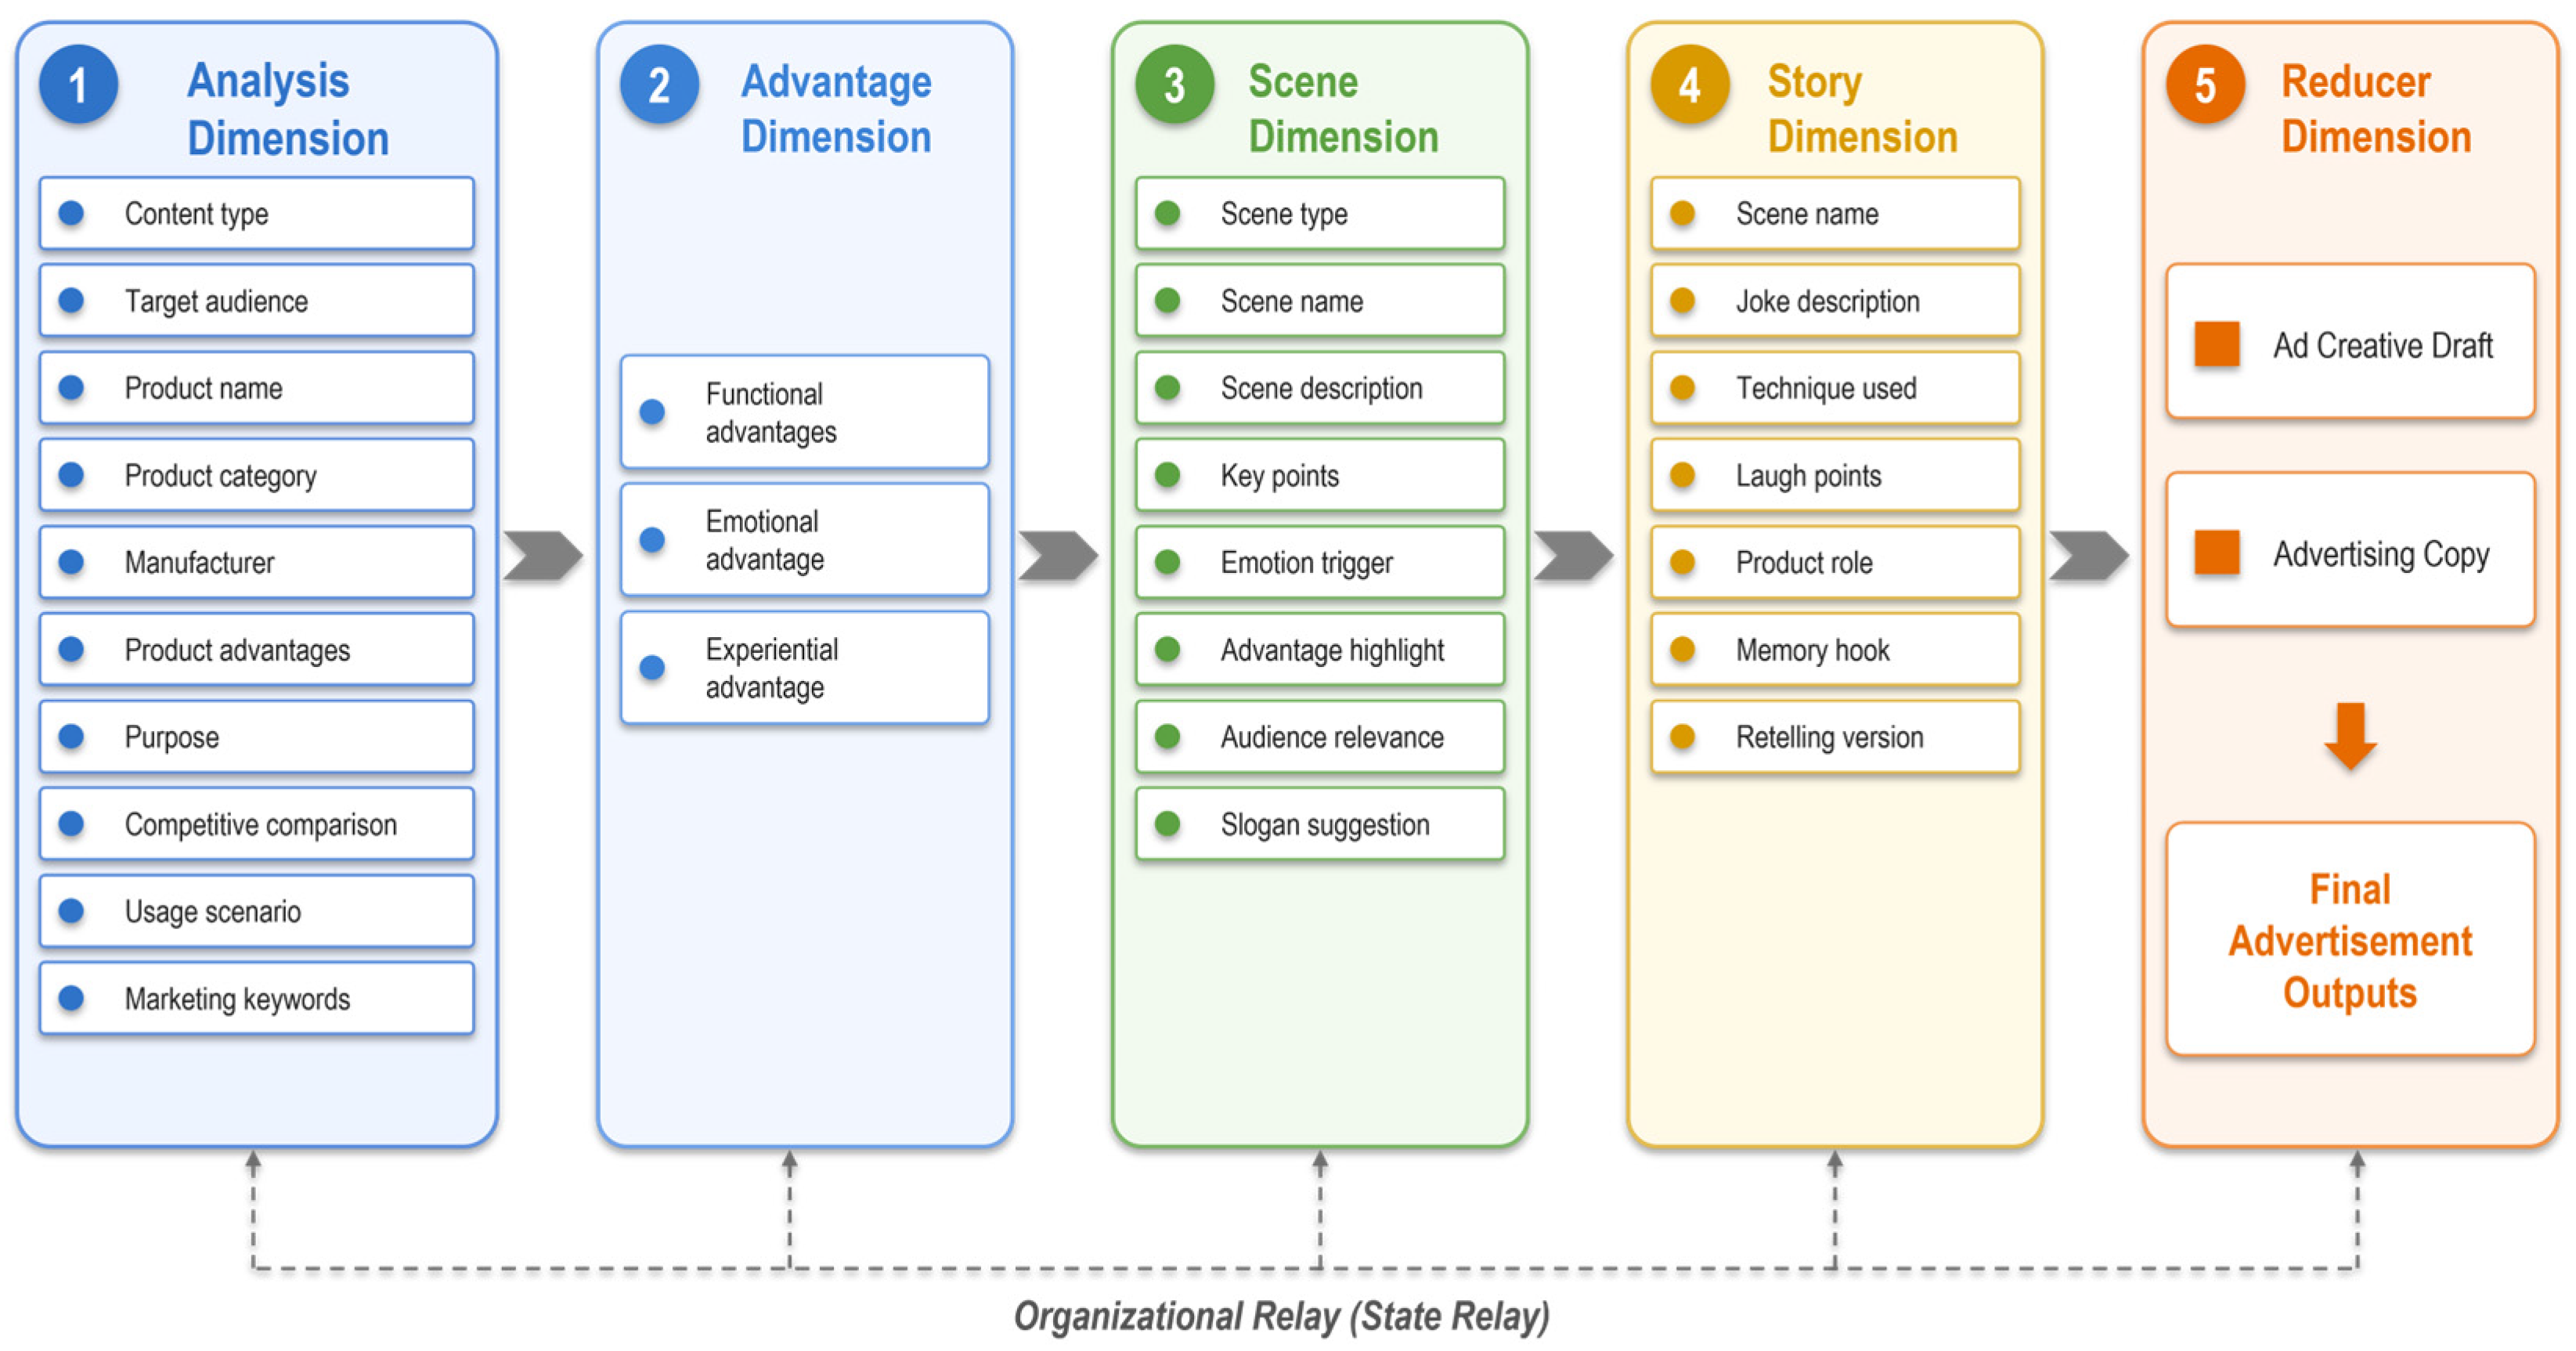
As shown in
Figure 3, the workflow comprises product analysis, advantage extraction, scenario construction, story-oriented expansion, and final reduction. The advantage, scenario, and story stages support one-to-many candidate generation through localized, schema-constrained prompts. Each operation receives only the product profile and structured records needed for its local objective, and the reducer merges the resulting candidates into final creative blocks.
DCOR and the three generation-level baselines used the same target format and were each evaluated across ten runs. The full-scale setting assessed cumulative multi-instance generation, whereas the format-matched setting compared 30 creative blocks per method. For each full-scale DCOR run, the 30 blocks were selected using a fixed deterministic rule rather than manual quality-based selection.
The task-specific execution procedure of the cumulative advertisement generation workflow is summarized in Algorithm 2.
| Algorithm 2. Task-Specific Instantiation of DCOR for Cumulative Advertisement Generation |
| | Input: Product name or description X; Advantage Dimensions D = {functional, emotional, experiential}; workflow configuration Cfg. |
| | Output: Structured advertisement creative blocks Y. |
| 1 | P ← ProductAnalysis(X) |
| 2 | O0 ← InitializeOrganizationalState(P) |
| 3 | A ← |
| 4 | for each d in D do |
| 5 | ← GenerateAdvantages(P, d, Cfg) |
| 6 | A ← A ValidateAndParse() |
| 7 |
end for |
| 8 | O1 ← UpdateOrganizationalState(O0, A) |
| 9 | S ← |
| 10 | for each advantage a in A do |
| 11 | ← GenerateScenarios(P, a, O1, Cfg) |
| 12 | S ← S ValidateAndParse() |
| 13 | end for |
| 14 | O2 ← UpdateOrganizationalState(O1, S) |
| 15 | T ← |
| 16 | for each scenario s in S do |
| 17 | T_s ← GenerateStoryVariants(P, s, O2, Cfg) |
| 18 | T ← T ValidateAndParse() |
| 19 | end for |
| 20 | O3 ← UpdateOrganizationalState(O2, T) |
| 21 | Y ← ReduceAndRender(P, A, S, T, O3) |
| 22 | Y ← ValidateOutputSchema(Y) |
| 23 | return Y |
Algorithm 2 formalizes this procedure. ProductAnalysis constructs the initial profile; GenerateAdvantages, GenerateScenarios, and GenerateStoryVariants perform one-to-many expansion; and UpdateOrganizationalState retains only the structured fields required downstream. ReduceAndRender then integrates the product, advantage, scenario, and story records into the final creative blocks. The associated prompts, schemas, and workflow configurations are available in the public source-code repository.
4.2.2. Cumulative Generation Scale
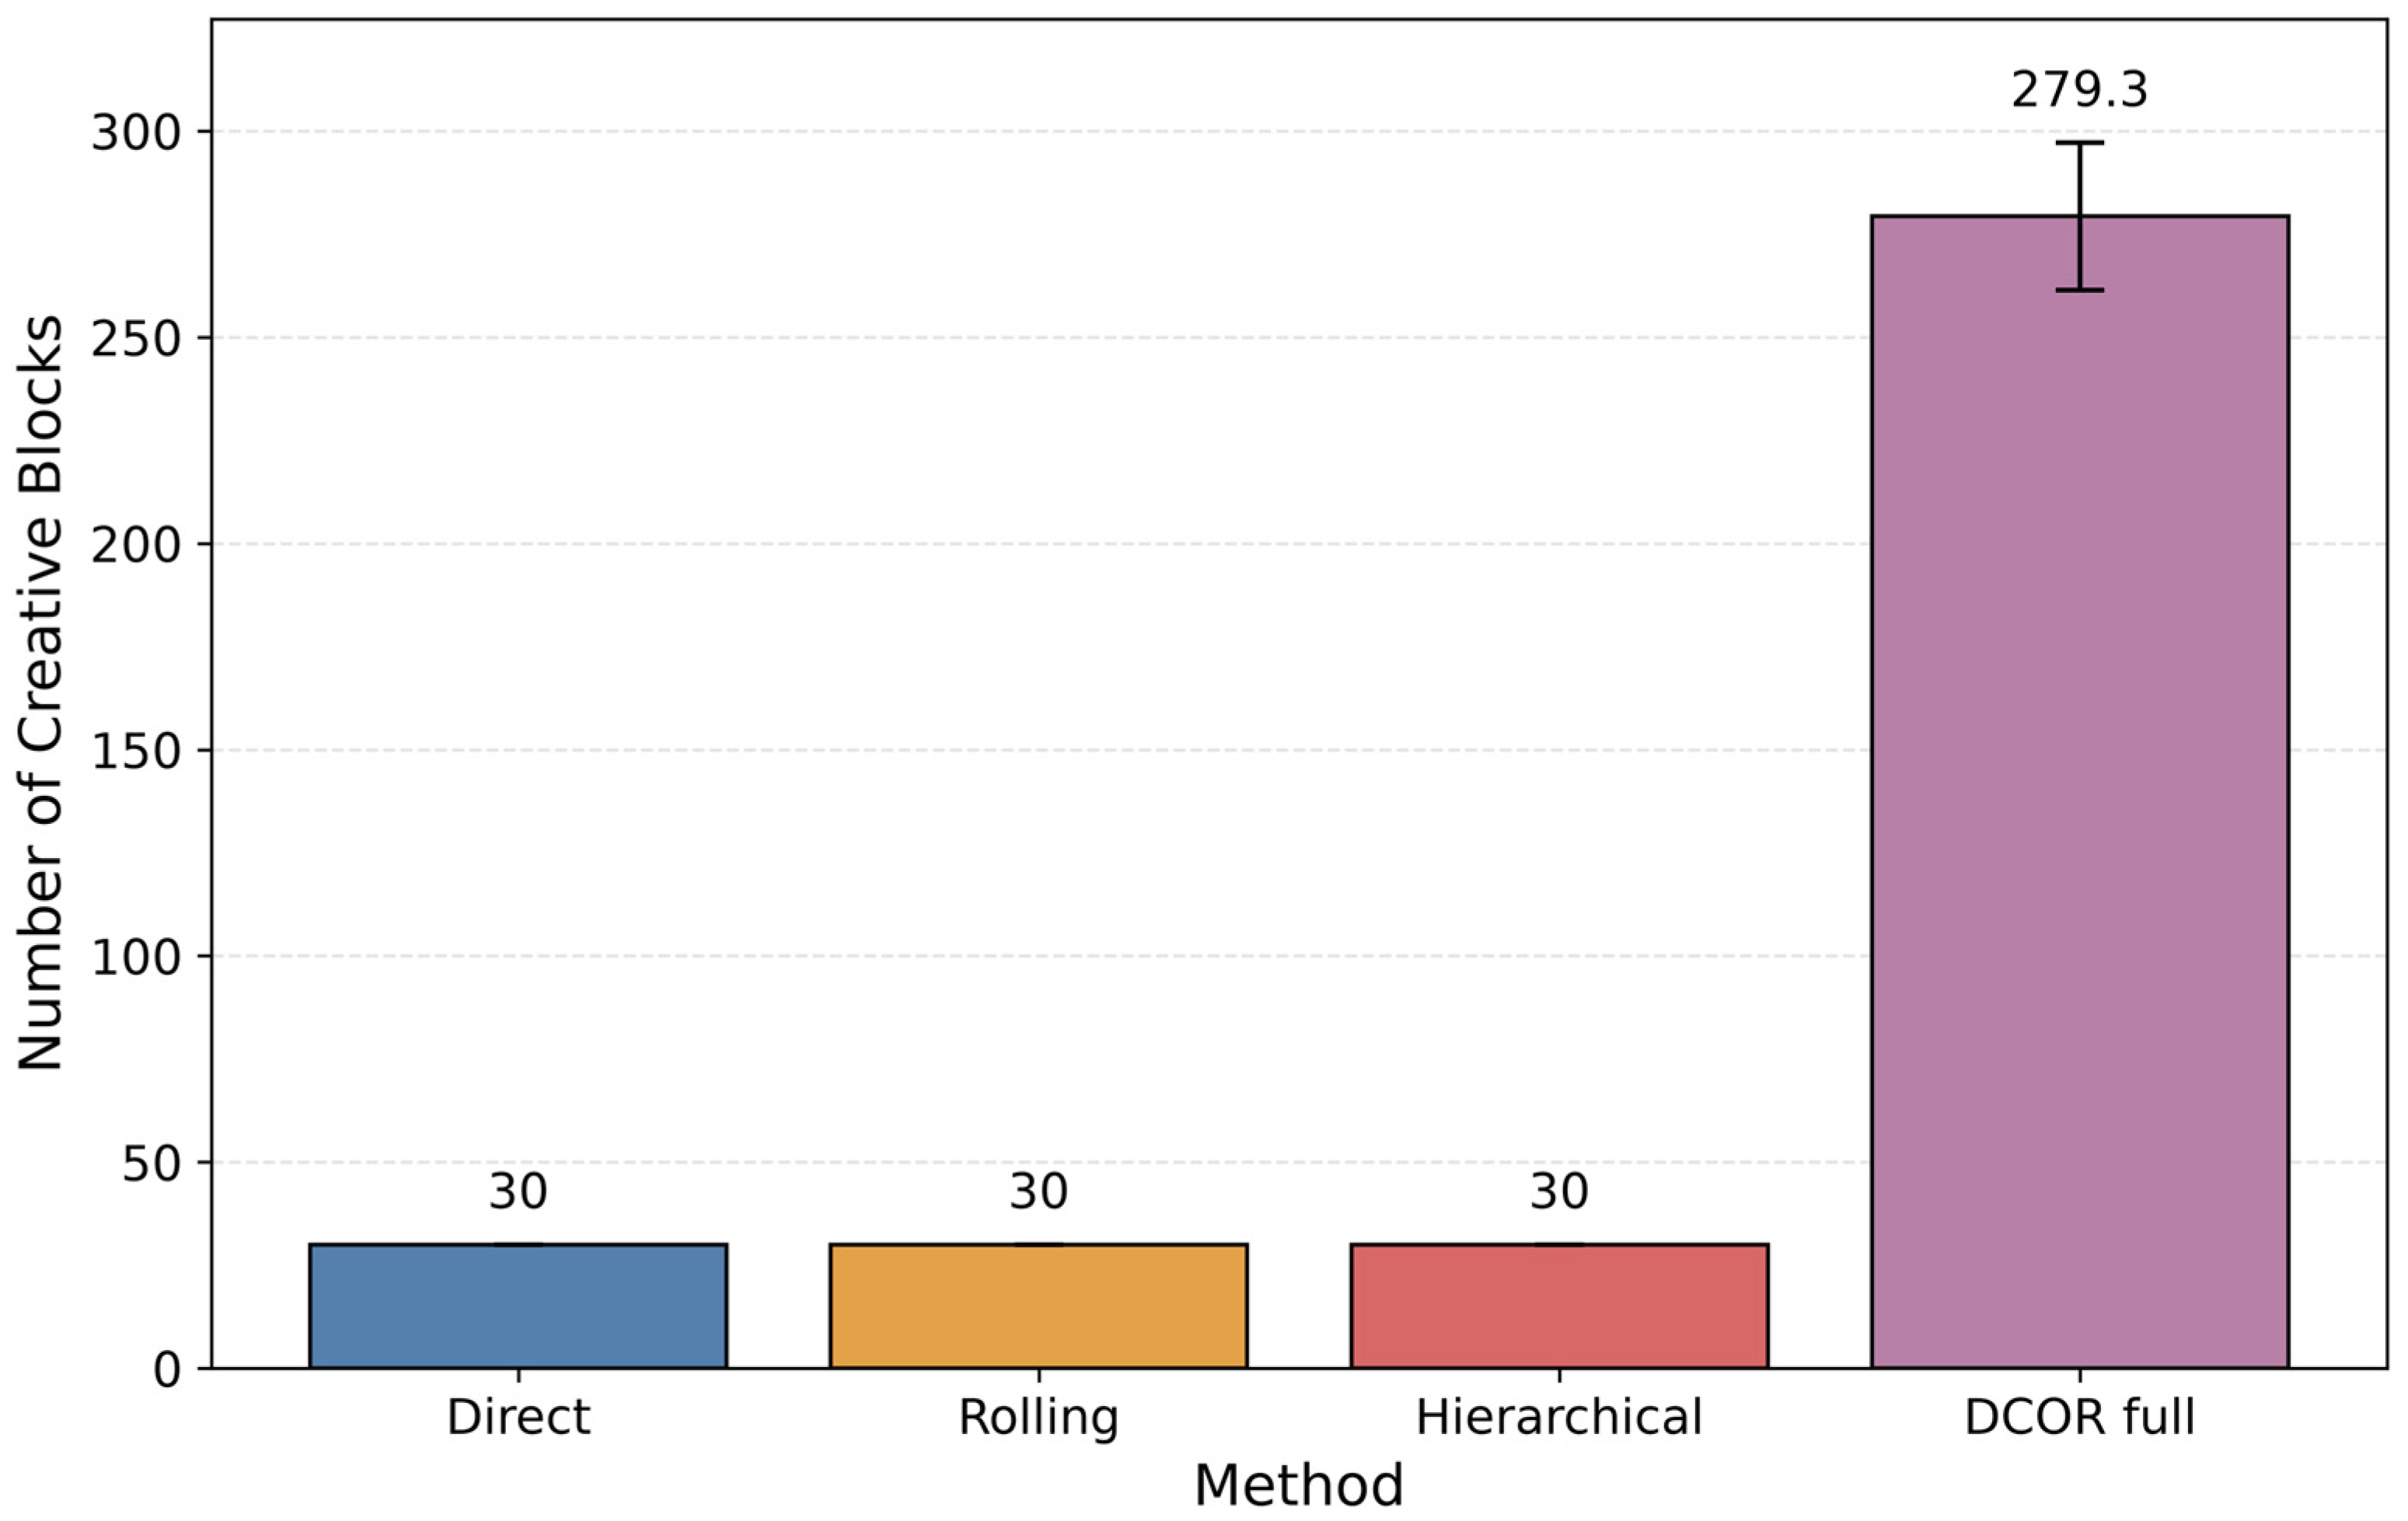
The original DCOR setting generated a large number of structured advertisement creatives in each run. Across ten runs, DCOR produced 259–315 structured creative blocks, with a mean of 279.3 ± 17.9 creative blocks per run. The cumulative output length ranged from 317,546 to 382,891 Chinese characters, with a mean of 341,441 ± 20,779 Chinese characters.
This result should be interpreted as cumulative multi-instance generation rather than single-pass 300K-character long-context generation. The system does not generate a single continuous 300K-character document. Instead, it repeatedly produces separate structured advertisement creatives under the same organizational workflow while propagating finite organizational states across stages.
Figure 4 shows the cumulative generation scale of DCOR compared with the baseline generation settings. The baseline methods were configured to generate 30 structured creative blocks per run in the format-matched setting, whereas the full DCOR setting produced substantially more creative blocks in each run. This comparison highlights the cumulative scale of the DCOR workflow in repeated structured generation. It is used only to illustrate the cumulative generation capacity of the implemented workflow, while the quality-oriented comparison is conducted under the matched 30-block setting in
Section 4.2.3.
In addition to generation scale, the DCOR outputs maintained stable structured formatting across runs. No exact duplicate or near-duplicate creative blocks were observed in the full DCOR outputs. This provides evidence that the implemented workflow maintained basic instance-level distinctiveness during cumulative generation. However, duplicate-level distinctiveness does not necessarily imply superior lexical diversity or lower local repetition. These aspects are evaluated separately in the format-matched comparison in
Section 4.2.3.
4.2.3. Comparison with Format-Matched Baselines
For each DCOR run, 30 creative blocks were sampled using a fixed deterministic sampling rule rather than manual selection, so that the sampled subset was not chosen based on output quality. To avoid comparing long structured DCOR outputs with much shorter baseline slogans or brief advertisement copies, we conducted a format-matched comparison. In this setting, all baseline methods were required to generate structured creative blocks using the same output fields as DCOR. Each method was repeated ten times, and the baseline methods generated 30 structured creative blocks per run.
Table 1 reports the main comparison results. At the matched small-batch scale, DCOR did not achieve the lowest lexical repetition or the highest TF-IDF cosine diversity. The rolling-summary generation baseline achieved the lowest 4-gram repetition, lowest 6-gram repetition, highest semantic diversity proxy, and lowest inter-creative similarity. Hierarchical-outline generation and direct generation also outperformed DCOR sampled-30 on these lexical diversity metrics.
For example, DCOR sampled-30 obtained a 4-gram repetition score of 0.1744 ± 0.0047 and a 6-gram repetition score of 0.1350 ± 0.0040. In contrast, Rolling-Summary Generation obtained 0.0681 ± 0.0045 and 0.0216 ± 0.0034, respectively. The TF-IDF cosine diversity scores were 0.9001 ± 0.0056 for DCOR sampled-30, 0.9338 ± 0.0082 for Rolling-Summary Generation, 0.9216 ± 0.0067 for Hierarchical-Outline Generation, and 0.9081 ± 0.0126 for Direct Generation.
These results indicate that DCOR should not be interpreted as the best method for maximizing lexical diversity in small-batch advertisement generation. Instead, the main value of DCOR in this task lies in its cumulative generation scale. The full-scale DCOR setting generated 279.3 ± 17.9 structured creative blocks per run, substantially exceeding the format-matched baseline setting, while maintaining complete format compliance and avoiding exact or near-duplicate creative blocks.
4.2.4. Discussion
The advertisement-generation experiment provides a mixed but informative result. The main advantage of DCOR in this task is not lexical-diversity superiority at the matched small-batch scale, but cumulative generation scale and format-stable structured production. In the full-scale setting, DCOR generated 259–315 structured creative blocks per run, with a mean of 279.3 ± 17.9 creative blocks and 341,441 ± 20,779 cumulative Chinese characters. This is substantially larger than the format-matched baseline setting, which generated 30 structured creative blocks per run.
Another important observation is that DCOR maintained stable output structure during large-scale cumulative generation. The full-scale DCOR outputs achieved complete format compliance and showed no exact or near-duplicate creative blocks. Moreover, the metric values of DCOR full-scale generation were close to those of the DCOR sampled-30 setting. The 4-gram repetition scores were 0.1743 ± 0.0023 for DCOR full-scale and 0.1744 ± 0.0047 for DCOR sampled-30, while the TF-IDF cosine diversity scores were 0.9004 ± 0.0031 and 0.9001 ± 0.0056, respectively. This suggests that the cumulative generation process did not show an obvious additional degradation in the evaluated metrics when moving from the sampled 30-block setting to the full-scale output.
However, the format-matched baseline comparison also reveals a clear limitation. At the matched small-batch scale, DCOR did not achieve the lowest repetition or the highest semantic diversity. Rolling-summary generation, hierarchical-outline generation, and direct generation all produced lower character-level 4-gram and 6-gram repetition than DCOR sampled-30. The rolling-summary baseline also achieved the highest semantic diversity proxy and the lowest inter-creative similarity. These results indicate that the current DCOR implementation may preserve repeated organizational patterns when repeatedly generating structured advertisement creatives for the same product.
Therefore, the conclusion of this experiment is task-specific. In the advertisement task, DCOR showed strength in large-scale cumulative structured generation, stable format compliance, and avoidance of trivial duplication. However, it should not be claimed to outperform all baselines on advertisement diversity or local repetition metrics.
4.3. Long-Form Article Generation
4.3.1. Task Setup
The second experiment evaluates DCOR in a single long-form article generation task requiring sustained organization across multiple sections. From a product-oriented writing request, the system generates a public-media article with a coherent topic, hierarchical structure, product integration, and complete argumentative progression. The task examines local repetition, multi-section generation, and organizational continuity under restricted local-context conditions.
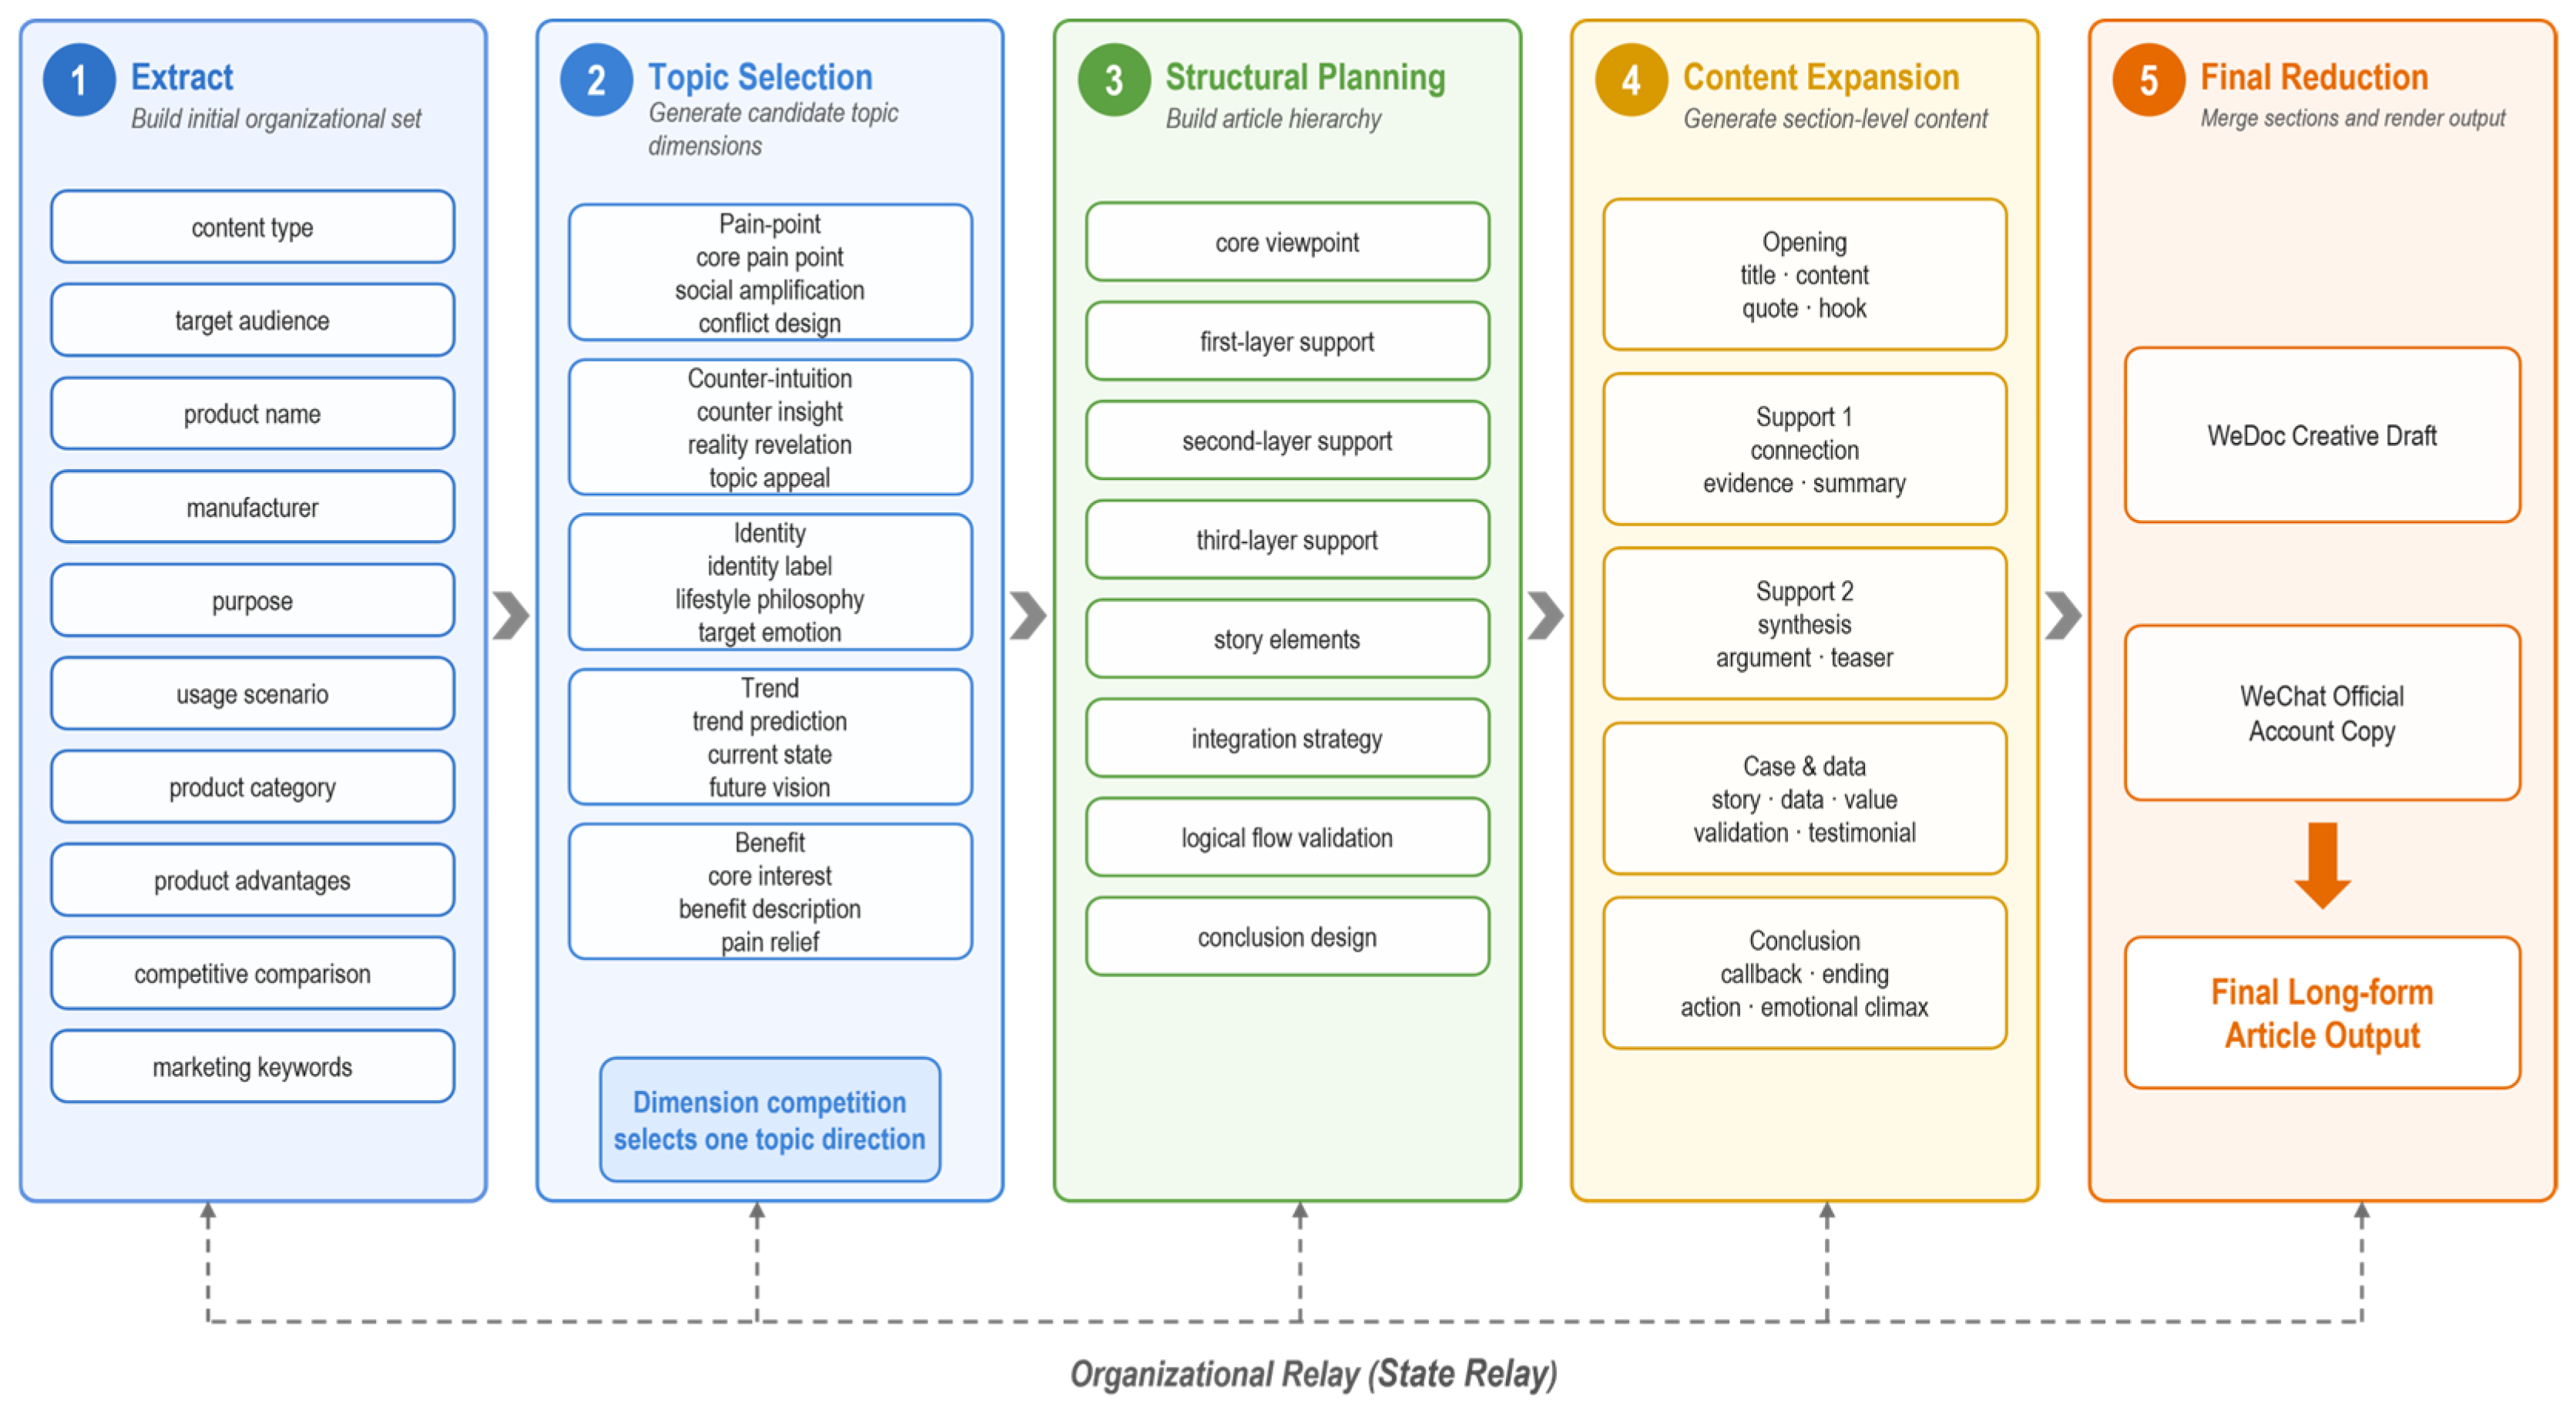
As shown in
Figure 5, the workflow comprises information extraction, topic selection, structural planning, content expansion, and final reduction. These stages transform the request into structured states, select a topical direction, construct hierarchical relationships and product-integration points, generate section-level content, and integrate the sections into the final article. Each stage receives localized prompts and finite states, such as topic anchors, section plans, transition cues, and structural dependencies, rather than the complete accumulated history.
DCOR was compared with Direct Generation, Rolling-Summary Generation, and Hierarchical-Outline Generation under the same model setting, with ten runs per method. The primary metrics were character-level 4-gram and 6-gram repetition, Distinct-2, and Distinct-3. Output length and section count were retained only as descriptive indicators of sustained generation.
The task-specific execution procedure of the long-form article generation workflow is summarized in Algorithm 3.
| Algorithm 3. Task-specific instantiation of DCOR for long-form article generation |
| | Input: Product name or description X; Topic Dimensions = {pain-point amplification, counter-intuition, identity recognition, trend prediction, benefit relevance}; workflow configuration Cfg. |
| | Output: Structured long-form article Y. |
| 1 | P ← ExtractProductProfile(X) |
| 2 | O0 ← InitializeOrganizationalState(P) |
| 3 | Q ← |
| 4 | for each topic dimension d in do |
| 5 | ← GenerateTopicCandidates(P, d, Cfg) |
| 6 | Q ← Q ValidateAndParse() |
| 7 | end for |
| 8 | q* ← SelectTopicByDimensionCompetition(Q, P, Cfg) |
| 9 | O1 ← UpdateOrganizationalState(O0, q*) |
| 10 | H ← PlanHierarchicalStructure(P, q*, O1, Cfg) |
| 11 | H ← ValidateAndParse(H) |
| 12 | O2 ← UpdateOrganizationalState(O1, H) |
| 13 | C ← |
| 14 | for each section plan h in DependencyOrder(H) do |
| 15 | ← SelectLocalizedState(O2, h) |
| 16 | ← GenerateSection(P, q*, h, Cfg) |
| 17 | C ← C ValidateAndParse() |
| 18 | O2 ← UpdateTransitionState(O2, h, ) |
| 19 | end for |
| 20 | O3 ← UpdateOrganizationalState(O2, C) |
| 21 | Y ← ReduceAndRender(P, q*, H, C, O3) |
| 22 | Y ← ValidateOutputSchema(Y) |
| 23 | return Y |
Algorithm 3 formalizes this procedure. ExtractProductProfile constructs the initial profile; GenerateTopicCandidates and SelectTopicByDimensionCompetition determine the topical direction; and PlanHierarchicalStructure defines the article dependencies. During section generation, SelectLocalizedState exposes only the required anchors and transition cues, while UpdateTransitionState retains compact relay information. ReduceAndRender then integrates the section-level outputs. The associated prompts, schemas, and workflow configurations are available in the public source-code repository.
4.3.2. Baseline Comparison
Table 2 reports the automatic evaluation results for the long-form article generation task. In contrast to the advertisement generation task, where the format-matched baselines achieved stronger lexical diversity at the matched small-batch scale, DCOR showed clearer advantages in character-level repetition reduction in the long-form article generation setting.
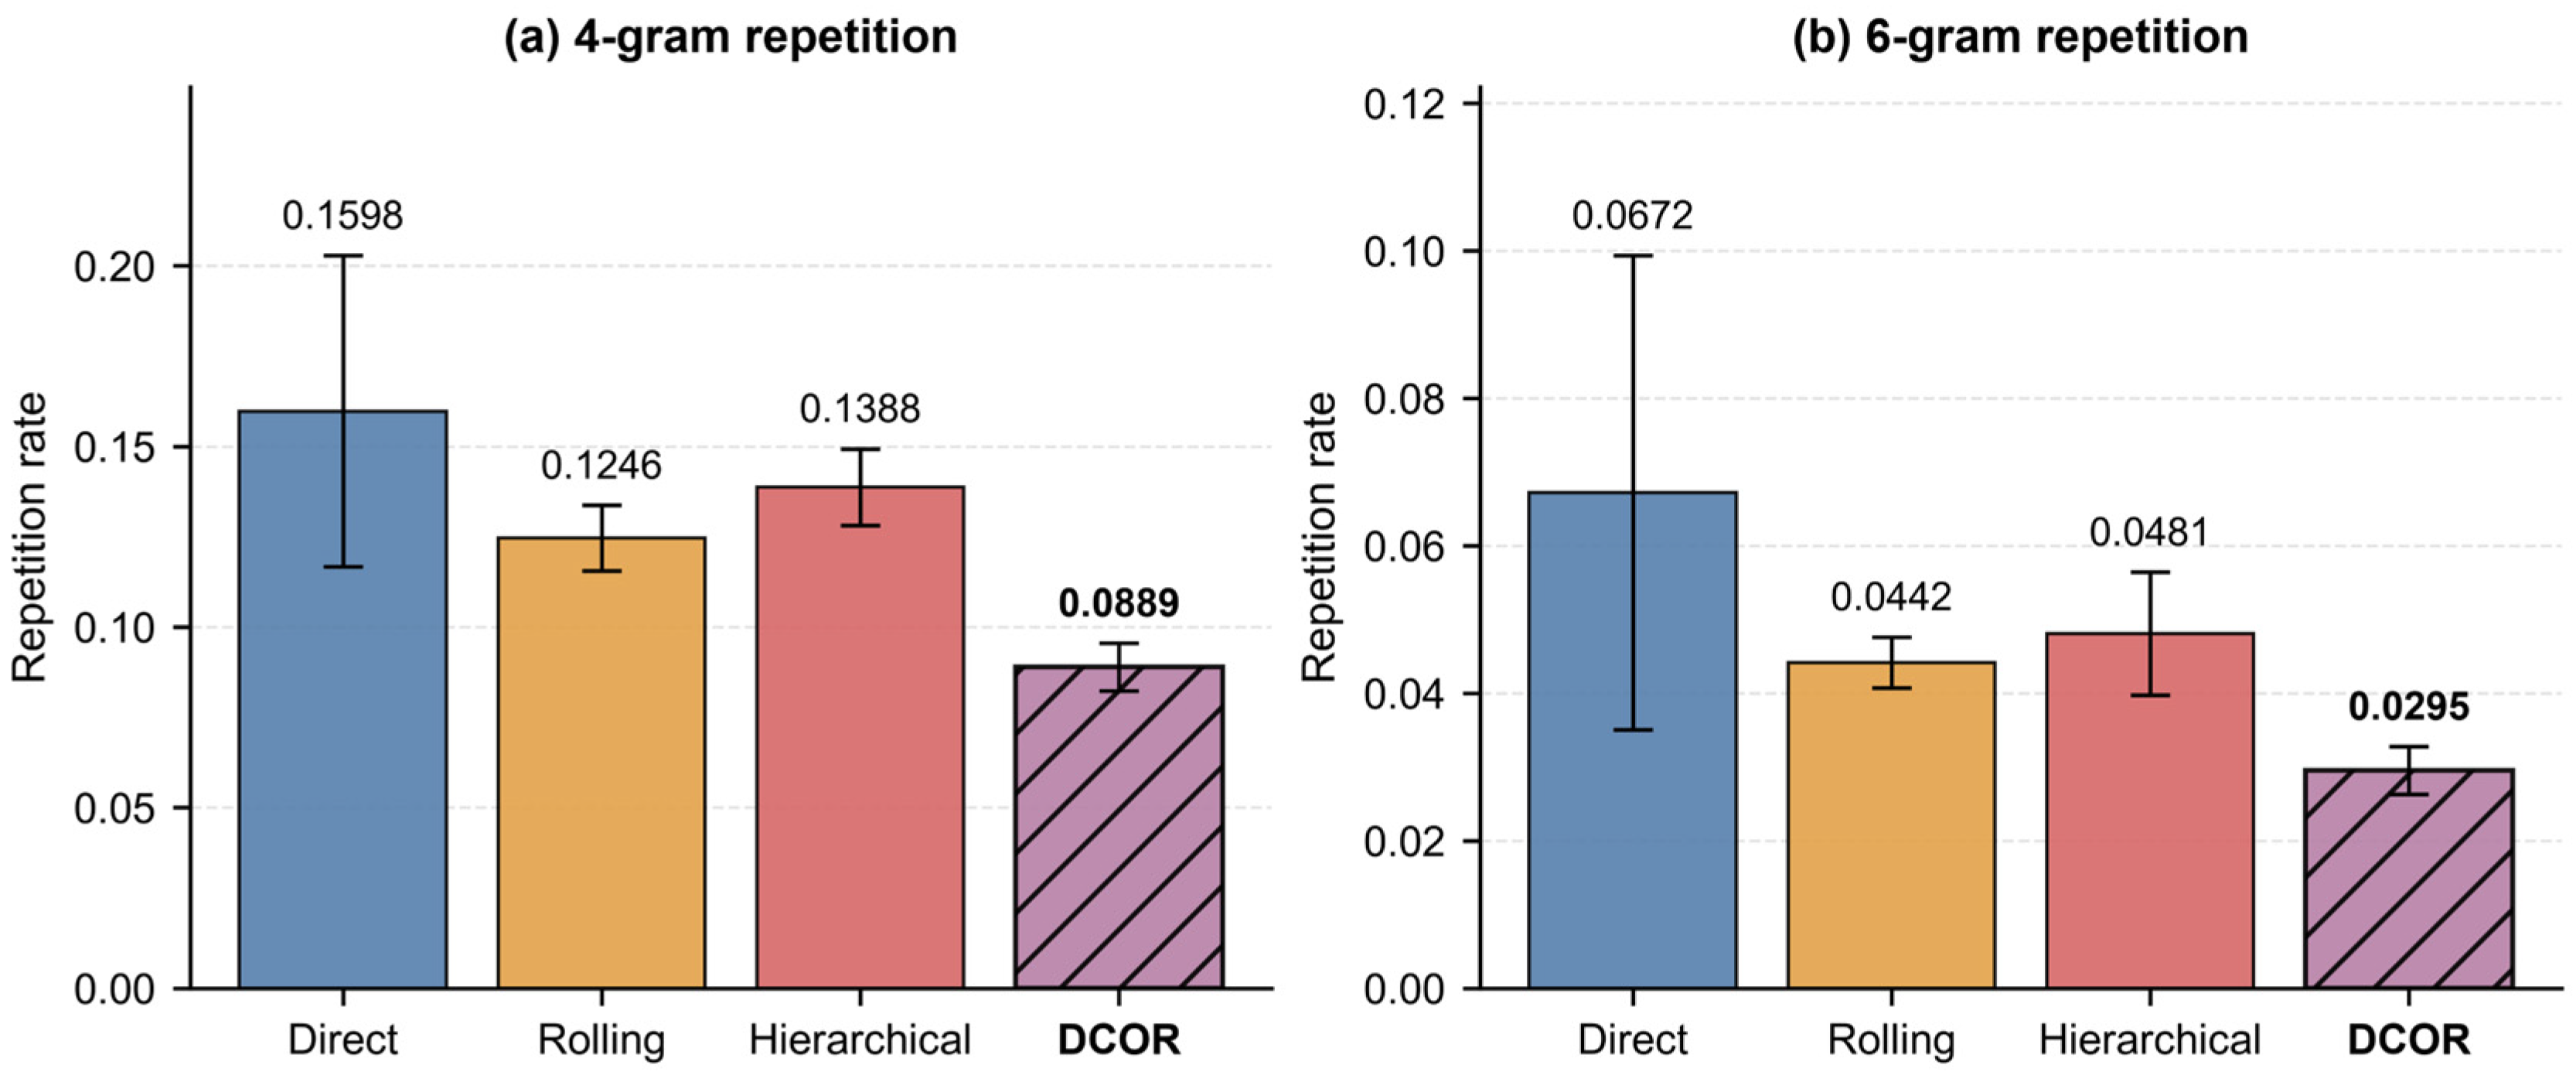
Across ten runs, DCOR achieved the lowest mean character-level repetition among the four compared methods. Its mean 4-gram repetition score was 0.0889, compared with 0.1598 for Direct Generation, 0.1246 for Rolling-Summary Generation, and 0.1388 for Hierarchical-Outline Generation. Similarly, the mean 6-gram repetition score of DCOR was 0.0295, compared with 0.0672, 0.0442, and 0.0481 for the three baselines, respectively.
These results indicate that DCOR produced fewer repeated character-level patterns in the long-form article task. The result is consistent with the design motivation of DCOR: instead of continuously accumulating all previously generated text, the workflow propagates structured topic anchors, section plans, dependencies, and transition states to guide subsequent localized generation.
The lexical-diversity results present a complementary pattern. Rolling-Summary Generation achieved the highest mean Distinct-2 and Distinct-3 scores, at 0.9896 and 1.0000, respectively. DCOR obtained mean scores of 0.9745 and 0.9944. Direct Generation obtained 0.9369 and 0.9818, while Hierarchical-Outline Generation obtained 0.9752 and 0.9990. Thus, DCOR’s principal advantage in this experiment is reflected in lower character-level repetition rather than uniformly higher lexical diversity.
4.3.3. Repetition and Lexical Diversity Analysis
Figure 6 compares character-level repetition across the four methods. DCOR achieved the lowest 4-gram and 6-gram repetition scores among the compared methods. Relative to direct generation, DCOR reduced 4-gram repetition from 0.1598 to 0.0889 and 6-gram repetition from 0.0672 to 0.0295. Relative to rolling-summary generation and hierarchical-outline generation, DCOR also produced lower repetition scores.
The corresponding pairwise statistical comparisons, including effect sizes and multiplicity-adjusted
p-values, are reported in the
Supplementary Statistical data. These analyses support the observed reduction in character-level repetition under the present experimental settings, but they are not interpreted as evidence of universal superiority across all tasks or model configurations.
The Distinct-n results provide complementary evidence regarding the output characteristics of DCOR. Although DCOR did not achieve the highest mean Distinct-2 or Distinct-3 values, its lexical-diversity scores remained high, with mean values of 0.9745 and 0.9944, respectively. This indicates that the reduction in character-level repetition was not accompanied by an obvious collapse in lexical variety.
Taken together, the results suggest that DCOR achieved a favorable balance between repetition control and lexical diversity in the long-form article generation task. Its principal advantage was the lowest mean character-level 4-gram and 6-gram repetition, while maintaining comparatively high Distinct-2 and Distinct-3 values.
4.3.4. Discussion
Among the automatic evaluations, the long-form article generation experiment provides the clearest positive evidence for DCOR. Compared with the advertisement generation task, the long-form task places stronger demands on section-level organization, argument progression, and cross-stage continuity. Under this setting, DCOR achieved the lowest mean character-level 4-gram and 6-gram repetition scores among the compared methods.
These results are consistent with the hypothesis that finite organizational-state propagation can help guide long-form generation when the full accumulated text is not repeatedly reloaded. By propagating topic anchors, structural plans, section-level relationships, and local transition states, DCOR constrains each generation stage within an organized trajectory. This may help reduce repeated local expressions and preserve the intended section-level structure.
The lexical-diversity results further characterize the output profile of DCOR. While achieving the lowest mean 4-gram and 6-gram repetition scores, DCOR maintained high Distinct-2 and Distinct-3 values of 0.9745 and 0.9944, respectively. Although these values were not the highest among the compared methods, they indicate that DCOR’s stronger repetition control was not accompanied by an evident loss of lexical variety. Therefore, the main advantage of DCOR in this task lies in reducing repeated local patterns while preserving a high level of lexical diversity.
Overall, DCOR performs well in the long-form article generation task, particularly in reducing repeated character-level patterns under restricted local-context conditions. The conclusion remains task-specific: DCOR provides the clearest benefit when a long-form workflow requires sustained organizational propagation and reduced local repetition, while alternative methods may retain advantages in lexical distinctiveness.
Moreover, the automatic metrics used in this section are proxy measures. Although they are useful for quantifying character-level repetition and surface-level lexical diversity, they cannot fully capture human-perceived coherence, or overall writing quality. To complement these automatic metrics, the next section reports a human evaluation of DCOR outputs, focusing on global coherence, structural consistency, semantic continuity, non-repetition, diversity, and overall perceived quality.
4.4. Pilot Human Evaluation
4.4.1. Evaluation Design
Automatic metrics are useful for measuring surface-level repetition and lexical diversity. However, they cannot fully capture human-perceived coherence, semantic continuity, or overall writing quality. Therefore, we conducted a small-scale, non-comparative pilot human evaluation to complement the automatic analyses.
The evaluation focused exclusively on selected DCOR outputs from the two generation tasks. For the cumulative advertisement generation task, 25 advertisement creative samples were evaluated. For the long-form article generation task, 5 generated articles were evaluated. Five human raters independently evaluated every selected sample, resulting in 125 sample-rater evaluation records for the advertisement task and 25 sample-rater evaluation records for the long-form article task, with 150 evaluation records in total.
Each sample was evaluated along six dimensions where applicable: global coherence, structural consistency, semantic continuity, non-repetition, diversity, and overall quality. Each dimension was rated using a five-point Likert scale, where a higher score indicates better perceived quality. Global coherence measures whether the generated output is understandable and internally coherent. Structural consistency measures whether the output follows a stable and recognizable organization. Semantic continuity measures whether the content progresses smoothly without abrupt topic breaks. Non-repetition measures whether the output avoids obvious repetitive expressions or redundant content. Diversity measures whether the generated content provides varied expressions or ideas across multiple generated instances. Overall quality measures the rater’s general assessment of the output.
The diversity dimension was evaluated only for the cumulative advertisement generation task, because this task produces multiple creative instances and therefore allows raters to judge variation across outputs. It was not applied to the long-form article generation task, because that task produces a single long-form article in each sample and does not involve multi-instance diversity evaluation.
It should be noted that this human evaluation assesses the perceived quality of DCOR outputs only. It is not a comparative human evaluation against the baseline methods. Therefore, the results should be interpreted as complementary evidence about the readability and perceived quality of DCOR outputs, rather than as evidence that DCOR is preferred by human raters over the baselines.
4.4.2. Results
Table 3 summarizes the human evaluation results. In the advertisement generation task, DCOR received high average ratings across all evaluated dimensions. The overall quality score was 4.66 ± 0.49. Global coherence, structural consistency, and semantic continuity were also rated highly, with scores of 4.71 ± 0.47, 4.75 ± 0.47, and 4.73 ± 0.46, respectively. These results suggest that the generated advertisement creatives were generally perceived as coherent, structurally stable, and semantically continuous.
The non-repetition and diversity dimensions received slightly lower but still positive scores, with 4.53 ± 0.50 and 4.43 ± 0.54, respectively. This is broadly consistent with the automatic evaluation in
Section 4.2, where the full-scale DCOR workflow sustained large-scale structured generation without exact duplicate creative blocks, although it did not outperform the format-matched baselines in the matched-scale comparison of lexical repetition and TF-IDF cosine diversity.
For the long-form article generation task, the human evaluation scores were more moderate. The overall quality score was 3.72 ± 0.54. Semantic continuity received the highest score among the evaluated dimensions, with 4.08 ± 0.28, suggesting that raters generally found the long-form outputs to maintain acceptable topical progression. Global coherence and structural consistency received scores of 3.60 ± 0.58 and 3.52 ± 0.59, respectively. The non-repetition score was 3.16 ± 0.37, indicating that raters still perceived some repetitive or redundant content at the discourse level. This result complements the automatic findings in
Section 4.3: although DCOR achieved the lowest mean character-level 4-gram and 6-gram repetition among the compared methods, character-level metrics do not fully capture repeated ideas, argumentative patterns, or semantic redundancy.
4.4.3. Discussion
The pilot human evaluation provides complementary evidence for interpreting the automatic results. In the advertisement generation task, the high ratings suggest that the selected DCOR outputs were generally perceived as coherent, structurally consistent, and semantically continuous. This is consistent with the automatic observation that DCOR sustained cumulative multi-instance generation while maintaining stable structured output.
The slightly lower diversity score also broadly aligns with the matched-scale automatic comparison in
Section 4.2. Although the selected DCOR creatives were still rated positively for diversity, the format-matched baselines obtained stronger lexical-repetition and TF-IDF cosine-diversity results under the fixed 30-block comparison. The human ratings therefore support the interpretation that DCOR maintained acceptable perceived variety while its principal advertisement-task advantage remained cumulative organizational scale and structured generation.
In the long-form article generation task, the evaluation results were more nuanced. Raters gave a relatively positive score for semantic continuity but more moderate scores for global coherence, structural consistency, and non-repetition. This suggests that the selected DCOR outputs maintained recognizable long-form progression, while discourse-level organization and redundancy remained more challenging than in the structured advertisement generation task.
The moderate human non-repetition score further shows that automatic character-level repetition and human-perceived redundancy capture different aspects of output quality. DCOR achieved the lowest mean character-level repetition among the compared methods, but raters could still identify repeated ideas, argumentative patterns, or semantically redundant passages that were not detected by character-level n-gram metrics.
Overall, the pilot evaluation suggests that the selected DCOR outputs were generally readable and exhibited recognizable organizational structure. The advertisement outputs received consistently high ratings, whereas the long-form outputs received moderately positive ratings with remaining weaknesses in discourse-level repetition and structural refinement. Because the evaluation involved only selected DCOR outputs, five raters, and no baseline outputs, it should not be used to claim human-preference superiority or to generalize to all possible DCOR-generated content. Instead, it provides preliminary human-centered evidence that complements the automatic analyses and identifies areas for further improvement.
4.5. Ablation Study
4.5.1. Ablation Settings
To further examine how the main organizational mechanisms of DCOR affect long-form generation, we conducted an ablation study in the long-form article generation setting. The long-form task was selected because it places stronger demands on section-level organization, argument progression, and cross-stage continuity than the advertisement generation task.
The ablation study focuses on three mechanisms in the DCOR workflow: Dimension, Organizational Relay, and Order. Dimension constrains generation within task-relevant semantic and structural directions. Organizational Relay passes finite organizational states between generation stages instead of repeatedly reloading the complete accumulated generation history. Order controls the sequential progression from input extraction, topic selection, structural planning, content expansion, to final reduction.
Based on these mechanisms, we constructed three ablation variants:
(1) Without Dimension
The Dimension constraint was removed, so generation was no longer explicitly guided by dimension-oriented organizational boundaries;
(2) Without Relay
Organizational Relay was removed or weakened, so subsequent stages received less structured organizational-state information from earlier stages;
(3) Without Order
Order was weakened, so generation relied less on sequential organizational progression.
Each ablation variant was evaluated using the same long-form article generation setting and model configuration as
Section 4.3. Each variant was repeated ten times. The outputs were evaluated primarily using character-level 4-gram and 6-gram repetition, which directly measure the local repetition behavior examined in the baseline experiment. Other descriptive output statistics were not used as the primary basis for interpreting the component effects.
4.5.2. Results
Table 4 summarizes the ablation results. Compared with the full DCOR workflow, removing Dimension, Organizational Relay, or Order led to clear changes in long-form generation behavior. The most consistent differences appeared in character-level repetition, output length, and section count.
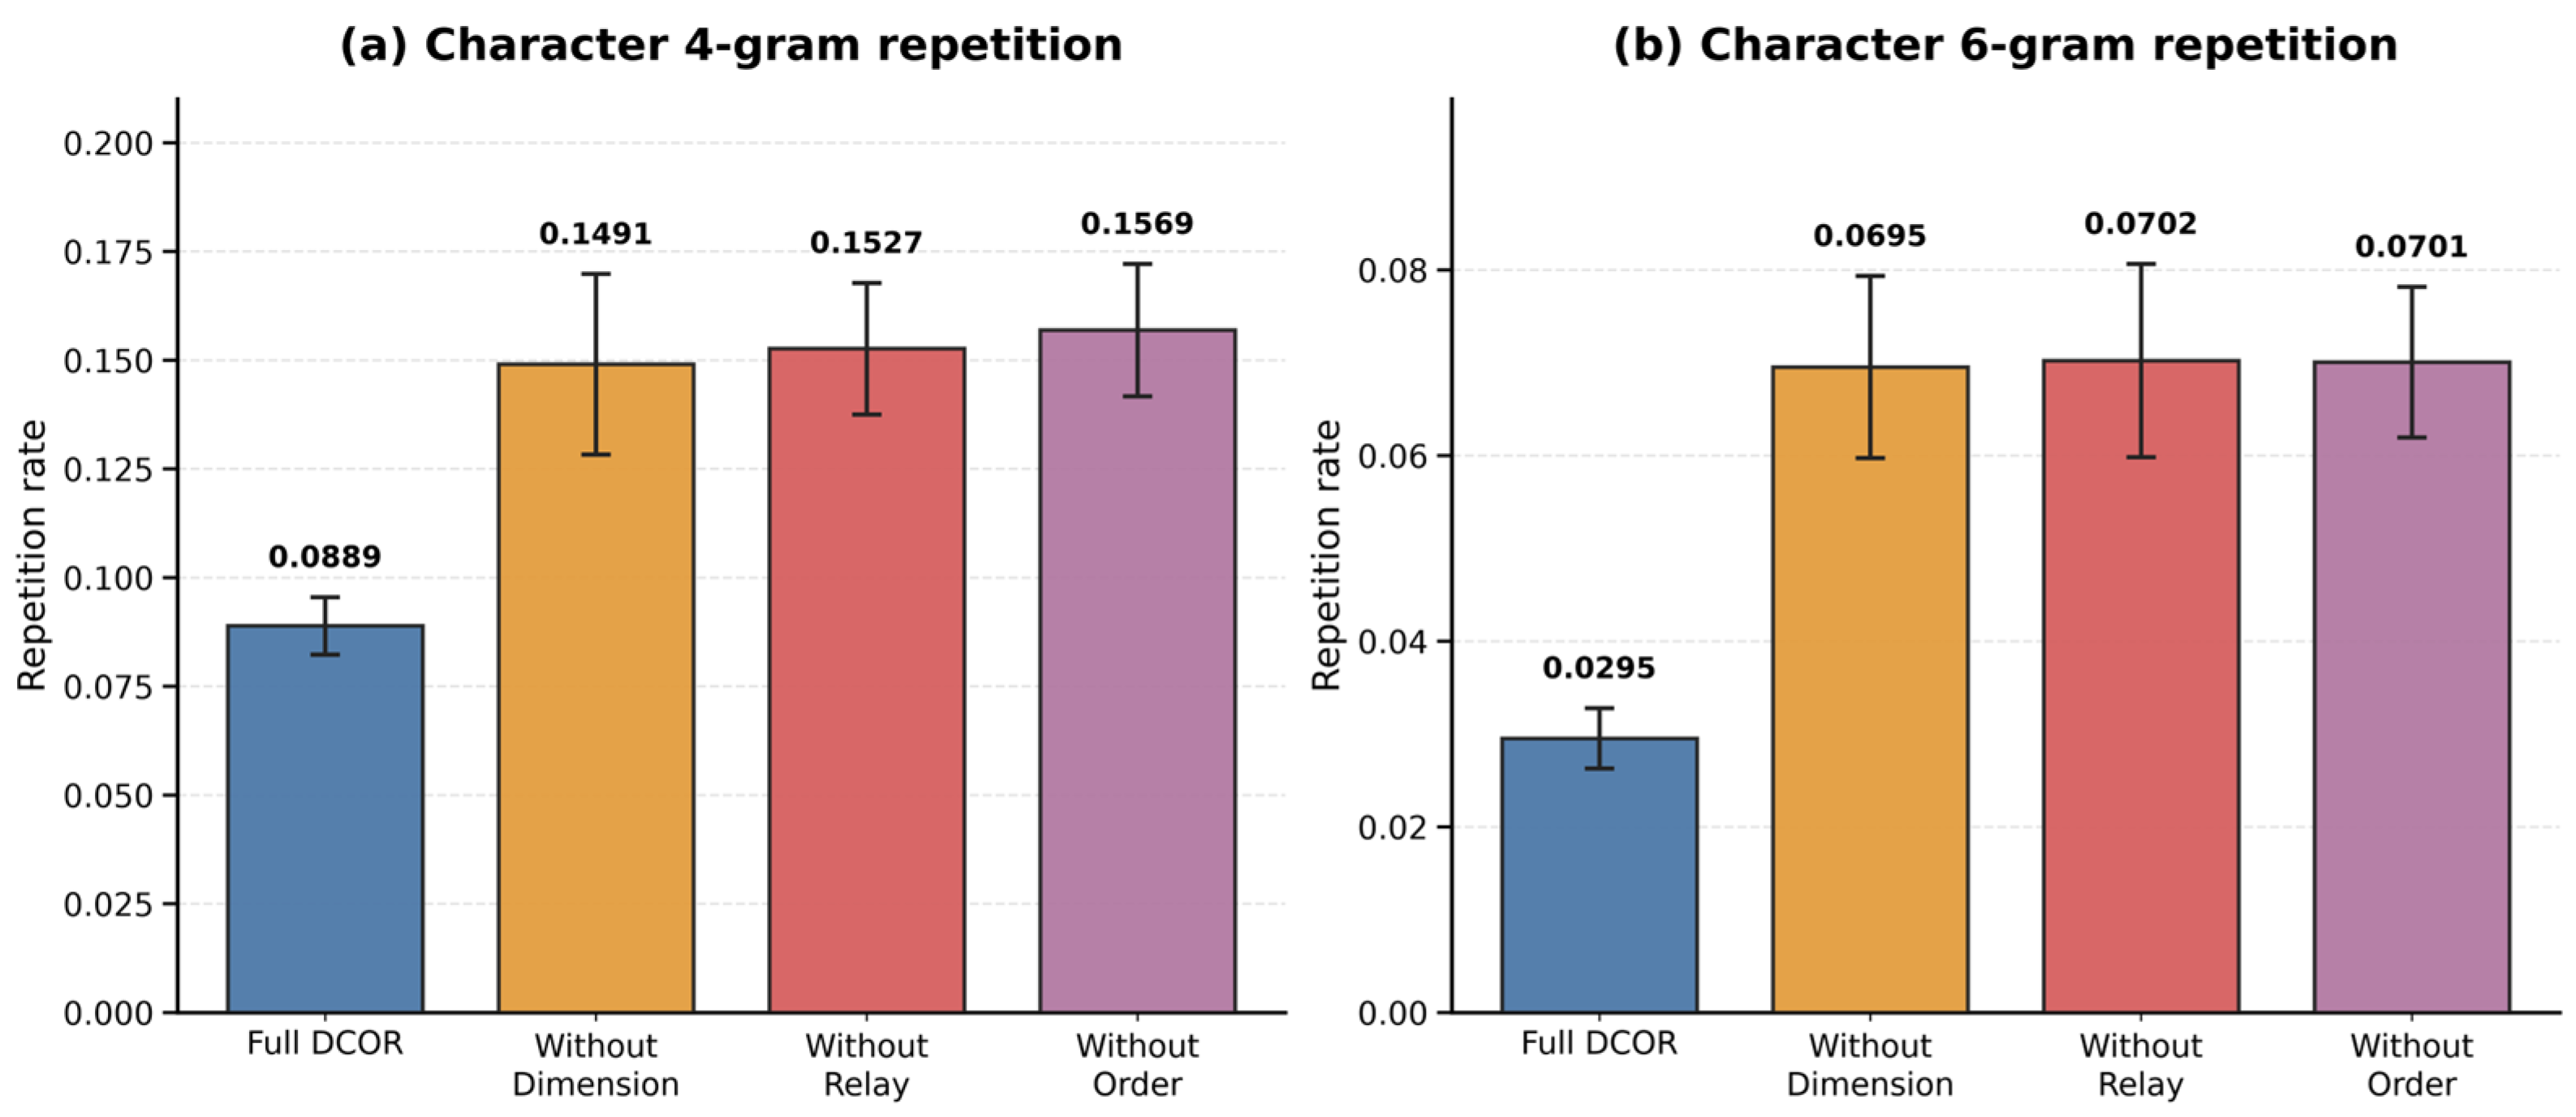
First, all three ablation variants produced higher character-level repetition than full DCOR. Full DCOR achieved a 4-gram repetition score of 0.0889 ± 0.0066 and a 6-gram repetition score of 0.0295 ± 0.0032. In contrast, the 4-gram repetition scores increased to 0.1491 ± 0.0208 without Dimension, 0.1527 ± 0.0151 without Organizational Relay, and 0.1569 ± 0.0152 without Order. The 6-gram repetition scores also increased to 0.0695 ± 0.0098, 0.0702 ± 0.0104, and 0.0701 ± 0.0081, respectively. These results indicate that removing any of the three mechanisms increased local repetitive expressions in the long-form article generation task.
Second, the ablation variants generated shorter outputs than full DCOR. Full DCOR generated 11,282.4 ± 1188.7 Chinese characters on average. The output length decreased to 7485.9 ± 1145.3 without Dimension, 8827.6 ± 823.8 without Organizational Relay, and 8409.4 ± 764.1 without Order. This suggests that the full DCOR workflow better supports sustained long-form expansion.
Third, the ablation variants produced fewer sections than full DCOR. Full DCOR generated 20.8 ± 1.9 sections on average, while the ablation variants generated 7.1 ± 2.7, 4.7 ± 2.8, and 5.9 ± 5.2 sections, respectively. This result suggests that Dimension, Organizational Relay, and Order are related to the ability of DCOR to maintain multi-section generation over a longer organizational trajectory.
The Distinct-n values remained high across all four configurations. Full DCOR obtained Distinct-2 and Distinct-3 scores of 0.9745 ± 0.0133 and 0.9944 ± 0.0050, respectively. Although some ablation variants obtained slightly higher Distinct-n values, these differences should not be interpreted independently of output length and section count, because shorter outputs can more easily produce high Distinct-n scores.
Figure 7 shows the repetition comparison between full DCOR and the three ablation variants. Full DCOR achieved the lowest 4-gram and 6-gram repetition rates. Removing Dimension, Organizational Relay, or Order consistently increased local repetition.
4.5.3. Discussion
The ablation results provide component-level evidence for the roles of Dimension, Organizational Relay, and Order in the DCOR workflow. Removing any of the three mechanisms increased character-level repetition, suggesting that these mechanisms contribute to reducing local repetitive expressions in long-form generation.
Dimension helps restrict generation to task-relevant semantic and structural directions. Without Dimension, the generation process receives less explicit guidance for maintaining stable organizational boundaries, and the repetition scores increase. Organizational Relay helps pass finite organizational states across stages. Without Relay, later stages receive less structured information from earlier stages, and the repetition scores increase further. Order helps maintain a sequential organizational trajectory from extraction to topic selection, structural planning, content expansion, and final reduction. When Order is weakened, generation also shows higher repetition and fewer sections.
The output length and section-count results further suggest that the full DCOR workflow better supports sustained long-form organizational generation. Full DCOR generated longer outputs and more sections than all three ablation variants. This does not mean that longer output is always better, but in this task the expected output is a multi-section long-form article, so the ability to sustain section-level expansion is an important part of the generation objective.
The consistent increase in repetition across all three ablation variants suggests that the observed behavior is associated with the combined organizational design rather than with a single isolated operation. Dimension constrains the direction of generation, Organizational Relay preserves finite cross-stage state, and Order maintains the progression of those states through the workflow.
At the same time, the ablation results should be interpreted conservatively. Although each configuration was evaluated across ten runs, the experiment was conducted using one long-form task setting and one primary model backbone. In addition, the automatic metrics are proxy measures. Self-plan adherence is affected by the number of sections proposed by a given configuration and is therefore retained only as an internal DCOR diagnostic rather than a cross-method quality measure. Distinct-n can also be affected by output length. Therefore, these metrics should not be overinterpreted individually.
Overall, the ablation study complements the baseline comparison in
Section 4.3. The baseline comparison shows that DCOR achieves lower character-level repetition in long-form article generation, while the ablation study further suggests that Dimension, Organizational Relay, and Order are associated with reduced repetition and sustained multi-section expansion. Together, these results are consistent with the task-dependent conclusion that DCOR is particularly useful for long-form organizational generation under restricted local-context conditions.
4.6. Comparison with a Representative Modern Baseline
4.6.1. Baseline Selection and Configuration
To complement the conventional generation-level baselines evaluated in
Section 4.2 and
Section 4.3, we further introduced a representative modern baseline. We selected a Neural RAG-Memory workflow because retrieval-augmented generation combines parametric language generation with access to an explicit non-parametric memory, providing a representative retrieval-based mechanism for supplying task-relevant context to a generator [
17]. This comparison allows us to examine the difference between retrieval-based memory access and DCOR’s explicit propagation of ordered, Dimension-constrained organizational states.
The purpose of this experiment is not to represent all existing retrieval- or memory-based systems, but to evaluate DCOR against a representative modern mechanism for localized context management. The comparison was conducted separately from the three conventional baselines because Neural RAG-Memory differs from Direct Generation, Rolling-Summary Generation, and Hierarchical-Outline Generation in both its memory mechanism and its method of selecting intermediate context.
The Neural RAG-Memory baseline stores intermediate workflow records as dense vector representations. The records were encoded locally using BAAI/bge-small-zh-v1.5, a Chinese text-embedding model from the BGE family [
44]. The model produces normalized 512-dimensional embeddings. At each generation step, the three most relevant memory records were retrieved according to cosine similarity and supplied to the generator as localized context.
Neural RAG-Memory and DCOR used the same primary generation backbone, DeepSeek v4-flash with thinking disabled, and followed the same task inputs and task-level output requirements. The comparison therefore focuses on the difference between retrieval-based memory selection and explicit organizational-state propagation rather than differences in the underlying generation model.
For the advertisement task, the task-level comparison used 30 creative blocks from each method. Specifically, DCOR was evaluated using its sampled 30-block output rather than its full cumulative output. This matched-scale setting avoids treating DCOR’s substantially larger output quantity as a direct quality advantage. The cumulative generation scale of the full DCOR workflow is analyzed separately in
Section 4.2.
4.6.2. Task-Level Comparison
Table 5 reports the task-level comparison between DCOR and the representative Neural RAG-Memory baseline.
Advertisement Generation:
In the matched 30-block advertisement comparison, Neural RAG-Memory achieved lower mean character-level repetition than DCOR. Its 4-gram and 6-gram repetition scores were 0.0463 and 0.0103, respectively, compared with 0.1744 and 0.1350 for DCOR.
DCOR obtained a slightly higher TF-IDF cosine-diversity score of 0.9001, compared with 0.8943 for Neural RAG-Memory. The difference in this metric was small and is therefore interpreted descriptively. These results indicate that, at the matched 30-block scale, Neural RAG-Memory provided stronger local repetition control, while DCOR maintained a comparably high level of TF-IDF cosine diversity.
This result further clarifies the role of DCOR in the advertisement task. Its principal advantage is not lower character-level repetition at a fixed small-batch scale, but the ability to organize and sustain cumulative generation across a substantially larger collection of structured creative blocks.
Long-Form Article Generation:
In the long-form article generation task, DCOR achieved lower mean character-level repetition than Neural RAG-Memory. The 4-gram repetition scores were 0.0889 for DCOR and 0.1053 for Neural RAG-Memory. The corresponding 6-gram repetition scores were 0.0295 and 0.0322, respectively.
DCOR also maintained high lexical-diversity values, with Distinct-2 and Distinct-3 scores of 0.9745 and 0.9944. Neural RAG-Memory obtained slightly higher values of 0.9846 and 0.9998, respectively. Although DCOR did not achieve the highest Distinct-n values, its lower character-level repetition was not accompanied by an evident collapse in lexical variety.
Taken together, the long-form results suggest that DCOR achieved a favorable balance between repetition control and lexical diversity under sustained multi-stage generation. Under the present task setting, explicit organizational-state propagation provided a clearer repetition advantage than retrieval-based access to semantically similar intermediate records.
4.6.3. Discussion
The comparison with the representative Neural RAG-Memory baseline provides a complementary evaluation beyond the conventional generation-level baselines. Rather than demonstrating uniform superiority for either method, the results reveal different strengths of retrieval-based memory and explicit organizational-state propagation across the two tasks.
In the matched-scale advertisement task, Neural RAG-Memory achieved substantially lower character-level repetition, while DCOR maintained a slightly higher TF-IDF cosine-diversity score. This result reinforces the conclusion from
Section 4.2 that DCOR’s advertisement-task advantage lies primarily in cumulative structured generation and large-scale organizational expansion rather than in matched-scale lexical-repetition control.
In the long-form article generation task, DCOR achieved lower mean 4-gram and 6-gram repetition than Neural RAG-Memory while retaining high Distinct-2 and Distinct-3 values. This suggests that explicit ordered organizational-state propagation may be beneficial when generation must follow a sustained multi-stage trajectory rather than repeatedly retrieve isolated pieces of semantically similar context.
The different task-level results reflect the distinct operating principles of the two approaches. Neural RAG-Memory retrieves intermediate records according to semantic similarity and supplies a small subset of relevant information to each generation step. DCOR instead explicitly represents task Dimensions, cross-stage organizational states, and ordered dependencies. Retrieval-based memory is therefore well suited to localized context access, whereas DCOR is designed for tasks in which generation must preserve an explicit organizational trajectory across multiple stages.
Overall, Neural RAG-Memory provides a strong modern baseline for retrieval-based context management and local repetition control. DCOR shows clearer advantages when the task requires explicit multi-stage organization, cumulative expansion, or sustained long-form generation under restricted local-context conditions. The comparison therefore supports a task-dependent interpretation rather than a claim that either mechanism is universally superior.
4.7. Cross-Backbone Replication
4.7.1. Experimental Setting
To examine whether DCOR is tied to a single language-model backbone, we conducted an additional cross-backbone replication using a Qwen-family model, Qwen3.7-Plus. The same DCOR workflow, task definitions, prompt organization, structured output schemas, and evaluation procedures were retained, while the primary generation backbone was replaced.
This experiment was conducted on both the cumulative advertisement generation task and the long-form article generation task. Each task was repeated ten times using the Qwen backbone. For the advertisement task, the evaluation used a sampled set of 30 creative blocks from each run, consistent with the matched-scale analysis in
Section 4.2. For the long-form task, each run produced one complete multi-section article.
The purpose of this experiment is to examine workflow-level portability rather than to conduct a complete cross-model benchmark. Therefore, only DCOR was replicated with the second backbone; the conventional baselines and Neural RAG-Memory baseline were not rerun using Qwen. Consequently, the results should not be interpreted as evidence of cross-model superiority over the baseline methods.
4.7.2. Results
Table 6 reports the DCOR results obtained with DeepSeek v4-flash and the Qwen backbone across the two generation tasks.
Advertisement Generation:
In the matched 30-block advertisement task, DCOR obtained mean 4-gram and 6-gram repetition scores of 0.1744 and 0.1350 with DeepSeek v4-flash. With the Qwen backbone, the corresponding scores were 0.1563 and 0.1291.
The TF-IDF cosine-diversity score was 0.9001 with DeepSeek v4-flash and 0.8742 with Qwen. Thus, the Qwen-based replication produced slightly lower character-level repetition but also a lower TF-IDF cosine-diversity score.
These differences indicate that the surface-level output profile of DCOR is affected by the underlying language model. Nevertheless, the complete multi-stage advertisement workflow remained executable with the Qwen backbone and continued to produce structured creative outputs under the same organizational procedure.
Long-Form Article Generation:
In the long-form article task, DCOR achieved mean 4-gram and 6-gram repetition scores of 0.0889 and 0.0295 with DeepSeek v4-flash. With the Qwen backbone, the corresponding scores decreased to 0.0717 and 0.0257.
The Qwen replication also obtained Distinct-2 and Distinct-3 scores of 0.9813 and 0.9959, compared with 0.9745 and 0.9944 for DeepSeek v4-flash. Under this task setting, the Qwen-based DCOR workflow therefore achieved lower character-level repetition while maintaining high lexical diversity.
The result suggests that the long-form organizational procedure can be instantiated with a second-generation backbone without losing the repetition-control behavior observed in the primary experiment.
4.7.3. Discussion
The cross-backbone replication provides preliminary evidence that the DCOR workflow is not operationally restricted to the primary DeepSeek v4-flash backbone. The same staged organizational procedure, structured-state propagation mechanism, and task-specific workflow were successfully instantiated using a Qwen-family model in both generation tasks.
The results also demonstrate backbone sensitivity. In the advertisement task, the Qwen-based workflow achieved slightly lower character-level repetition but lower TF-IDF cosine diversity. In the long-form task, Qwen obtained lower repetition and slightly higher Distinct-n values. These differences indicate that DCOR does not eliminate the influence of the underlying model on lexical realization and surface-level diversity.
The experiment should therefore be interpreted as evidence of workflow-level portability rather than model independence. DCOR specifies how generation is organized through Dimension constraints, Organizational Relay, and Order, but the quality and lexical characteristics of the generated text continue to depend on the capabilities and generation behavior of the selected backbone.
Because only DCOR was replicated with the Qwen backbone, these results demonstrate workflow-level portability rather than cross-backbone comparative superiority.
Overall, the replication shows that DCOR can be transferred to a second language-model backbone while retaining its multi-stage organizational workflow and producing stable task outputs. At the same time, the observed metric differences confirm that DCOR should be regarded as a backbone-compatible organizational framework rather than a backbone-independent generation method.
4.8. Resource Analysis
4.8.1. DCOR Resource Measurement
To characterize the practical resource requirements of DCOR, we recorded the number of language-model calls, prompt tokens, completion tokens, total model tokens, accumulated model-call latency, and wall-clock execution time for the two generation tasks.
The measurements focus primarily on DCOR because its multi-stage organizational workflow introduces explicit resource overhead beyond ordinary single-pass generation. For each task, three instrumented DCOR runs were used to collect detailed workflow-level measurements. The reported DCOR values are therefore presented as mean ± standard deviation where repeated measurements were available.
The advertisement measurements correspond to the full cumulative DCOR workflow, which generated an average of 279.3 ± 17.9 creative blocks. The long-form measurements correspond to the generation of one complete multi-section article. These resource values represent the total cost of executing the full organizational workflow, including Dimension-guided candidate generation, Organizational Relay, ordered state propagation, and final reduction.
For contextual comparison, we also report the average model-call counts of the conventional baselines and Neural RAG-Memory. Detailed token records were available only for DCOR and Neural RAG-Memory. Therefore, the comparison is intended to contextualize the resource profile of DCOR rather than to establish a complete cross-method efficiency ranking.
4.8.2. DCOR Resource Profile
Table 7 summarizes the workflow-level resource profile of DCOR.
In the advertisement generation task, DCOR required 108.33 ± 2.89 model calls per workflow. The average prompt-token and completion-token usage was 101,550 and 192,576, respectively, resulting in 294,126 ± 10,599 total tokens. The average wall-clock execution time was 225.19 ± 12.64 s.
This relatively large resource footprint reflects the cumulative structure of the advertisement workflow. DCOR does not generate only a fixed set of final advertisements. Instead, it successively expands product profiles into advantage records, scenario records, and story-oriented candidates before reducing them into final creative blocks. The large number of calls and tokens therefore corresponds to the explicit organizational expansion that produced 279.3 ± 17.9 creative blocks per workflow.
In the long-form article generation task, DCOR required 17.67 ± 1.15 model calls and consumed 56,497 ± 9020 total tokens per workflow. Its average prompt-token and completion-token usage was 25,447 and 31,050, respectively. The average wall-clock execution time was 285.19 ± 61.69 s.
Although the long-form workflow used fewer calls and tokens than the advertisement workflow, it required a longer average wall-clock duration. This difference reflects the longer section-level generations and the sequential dependencies between topic selection, structural planning, section expansion, and final integration. Therefore, model-call count, token usage, and runtime capture different aspects of DCOR’s execution behavior and should not be interpreted interchangeably.
4.8.3. Comparative Context
To contextualize the resource requirements of DCOR,
Table 8 reports model-call counts under comparable output scales. For the advertisement task, the values are normalized to 30 creative blocks, which is the fixed output scale used by the conventional baselines and Neural RAG-Memory. For the long-form task, the values are reported per generated article.
The full-scale DCOR advertisement workflow required 108.33 ± 2.89 model calls and generated 279.3 ± 17.9 creative blocks. To obtain an output-scale-matched estimate, the average call count was normalized to 30 creative blocks as follows: 108.33/279.3 × 30 ≈ 11.64.
Accordingly, DCOR required approximately 11.64 model calls per 30 creative blocks. Under the same output scale, Direct Generation and Rolling-Summary Generation each required 5.00 calls, Hierarchical-Outline Generation required 10.00 calls, and Neural RAG-Memory required 6.00 calls.
This normalized comparison shows that DCOR still required more model interactions than the comparison methods, but the difference was substantially smaller than that suggested by the unnormalized full-workflow total. In particular, comparing 108.33 calls directly with 6.00 calls would be misleading because the full DCOR workflow generated more than nine times as many creative blocks as the fixed 30-block RAG setting. The normalized value therefore provides a more appropriate description of DCOR’s call requirements at a matched output scale.
In long-form generation, all methods produced one article per workflow, so the recorded call counts can be compared directly without output-count normalization. Direct Generation required 1.00 call, Rolling-Summary Generation and Neural RAG-Memory each required 6.00 calls, and Hierarchical-Outline Generation required 9.00 calls. DCOR required 17.67 ± 1.15 calls per article. The additional calls correspond to DCOR’s explicit topic exploration, hierarchical planning, localized section generation, organizational-state updating, and final reduction.
Overall, the comparison indicates that DCOR introduces additional model interactions in exchange for explicit multi-stage organizational control. In advertisement generation, part of the large raw workflow total is attributable to its substantially greater cumulative output scale, while the remaining normalized difference reflects the additional organizational stages executed for each group of creative outputs.
Detailed token records were available for DCOR and Neural RAG-Memory. In advertisement generation, the full DCOR workflow consumed 294,126 ± 10,599 tokens while generating 279.3 ± 17.9 creative blocks, whereas Neural RAG-Memory consumed 38,231 tokens for 30 blocks. After approximately normalizing DCOR to the same 30-block scale, its estimated token usage was 31,592 tokens. This suggests that DCOR’s larger raw workflow-level token total mainly reflects its substantially larger cumulative output scale rather than higher token usage at the matched output scale.
In long-form generation, DCOR consumed 56,497 ± 9020 tokens per article, compared with 14,630 tokens for Neural RAG-Memory. These results indicate that DCOR incurs additional workflow-level token overhead when executing explicit topic exploration, structural planning, localized section generation, Organizational Relay, and final integration. The comparison therefore characterizes the resource requirements associated with DCOR’s explicit multi-stage organizational process.
4.8.4. Discussion
The resource analysis shows that DCOR incurs additional workflow overhead because it explicitly constructs, updates, and propagates organizational states. In advertisement generation, the additional calls support cumulative candidate expansion, while the output-normalized estimates show that the larger raw resource total partly reflects the substantially larger output scale. In long-form generation, the additional calls and tokens support topic exploration, structural planning, localized section generation, state propagation, and final integration.
Compared with Neural RAG-Memory, DCOR prioritizes explicit organizational control, whereas retrieval-based memory provides lighter localized context access. The measurements do not establish economic superiority because token records were unavailable for the conventional baselines, wall-clock time was unavailable for Neural RAG-Memory, and the advertisement comparison required approximate output-scale normalization. DCOR’s additional resource requirements are therefore most justified when cumulative expansion or sustained multi-stage organization is central to the task; lighter workflows may be preferable for simpler generation or retrieval requirements.
5. Discussion
5.1. Empirical Observation: Organizational Stability Under Context Decoupling
The experiments show that DCOR can sustain structured generation under restricted local-context conditions by propagating a finite organizational state , which records the workflow-defined goal, active Dimensions, relay information, structural anchors, and local status. Each stage receives only the state required for its objective, performs a schema-constrained transformation, and updates the state for subsequent operations.
The two tasks reveal different aspects of this behavior. In the cumulative advertisement generation task, DCOR produced an average of 279.3 ± 17.9 structured creative blocks across ten runs, with individual runs producing between 259 and 315 blocks. The workflow maintained format-stable structured production and produced no exact duplicate creative blocks. These results indicate that finite organizational-state propagation can support repeated candidate expansion and convergence without continuously replaying the complete generation history.
However, the matched 30-block comparison also identifies an important boundary. DCOR did not achieve the lowest character-level repetition or the highest TF-IDF cosine diversity; the conventional baselines achieved lower repetition, and some also achieved higher diversity. Its principal advantage in this task is therefore the ability to sustain large-scale cumulative structured generation rather than universal superiority in lexical diversity or repetition control.
In the long-form generation, DCOR achieved the lowest character-level 4-gram and 6-gram repetition among the evaluated methods while maintaining high Distinct-2 and Distinct-3 values. This result suggests that explicit organizational-state propagation is more beneficial when generation requires a sustained hierarchical, multi-stage, and multi-section trajectory.
Taken together, the results demonstrate task-dependent organizational stability under context decoupling. DCOR is not uniformly superior across all tasks and metrics, but the findings support its central premise that, under suitable task decomposition, workflow-level organizational continuity can be maintained without repeatedly replaying the complete historical text.
5.2. Theoretical Interpretation: Organizational Sufficiency Without Full Historical Replay
A central implication of the results is that long-horizon generation does not always require repeated replay of the complete historical text. In the evaluated workflows, later stages operated primarily on finite organizational states rather than concatenations of all previous outputs. This does not make historical information unnecessary; instead, task-relevant constraints, structural anchors, topic directions, planning results, and transition relationships are reorganized into structured states.
The claim is therefore one of task-relative organizational sufficiency rather than lossless semantic compression. An organizational state is sufficient only when it retains the control information required for the next operation to remain on the intended trajectory.
Conceptually, this relationship can be expressed as:
For the evaluated workflows, organizational continuity can instead be interpreted as depending on the stability of the propagated state sequence:
Equations (17) and (18) are interpretive relations rather than universal mathematical equivalences. They express the workflow-level hypothesis examined in this study: if the propagated state preserves the constraints and relationships required by the next stage, organizational continuity may be maintained without repeatedly restoring the complete history.
The experiments provide partial support for this interpretation. The long-form workflow sustained multi-section generation using localized state inputs and achieved lower character-level repetition than the evaluated alternatives. Conversely, the matched advertisement results show that organizational sufficiency does not ensure lexical superiority: structural direction may be preserved while similar local expressions recur. DCOR therefore does not assume that any compressed state can replace complete context; its effectiveness depends on the selected Dimensions, relay fields, anchors, and transition constraints.
From a data-centric AI perspective, DCOR changes the organization and task relevance of the information supplied at inference time rather than modifying the backbone parameters or architecture [
45]. It is therefore complementary to long-context windows, retrieval systems, and memory-augmented models: these methods expand or recover accessible content, whereas DCOR specifies which organizational structures remain active and how they evolve across stages.
5.3. Organizational States as Carriers of Task-Relevant Constraints
The evaluated workflows suggest that organizational states can carry task-relevant constraints rather than merely summarize previous text. In advertisement generation, these states retain product identity, advantage structures, usage scenarios, emotional triggers, narrative skeletons, memory anchors, and output-format constraints. In long-form generation, they retain topic direction, central viewpoint, hierarchical outline, supporting dimensions, section relations, product-integration points, and conclusion structure.
Unlike a conventional summary, an organizational state functions as a control interface: it preserves task goals, constrains local expansion, records structural commitments, and communicates transition requirements to subsequent stages. It therefore specifies not only which information should remain available, but also how that information should regulate later operations.
This distinction helps explain the task-dependent difference between DCOR and Neural RAG-Memory. Retrieval reintroduces semantically relevant historical records, whereas DCOR propagates explicitly defined organizational variables even when the corresponding text is not retrieved. Neural RAG-Memory achieved lower character-level repetition in the matched advertisement comparison, while DCOR achieved lower repetition in long-form generation. Localized retrieval may therefore be sufficient when access to prior content is central, whereas explicit state propagation is more useful when a task requires sustained topic selection, hierarchical planning, section relations, and ordered progression.
5.4. Mechanism-Level Interpretation of Dimension, Organizational Relay, and Order
DCOR can be interpreted as constrained state evolution. A conventional continuation-oriented workflow directly transitions between successive text outputs:
DCOR instead places an explicit organizational state between local generation operations:
The next text segment is generated under the constraints carried by the current state, and the resulting local output is subsequently converted into an updated state. The workflow is therefore guided by the evolution of structured organizational information rather than by unrestricted continuation from the complete historical text.
Within this process, Dimension, Organizational Relay, and Order serve different but complementary theoretical functions.
Dimension defines the active semantic or structural axes that constrain local generation. It reduces the set of feasible next outputs by specifying which aspects of the task should be expanded, evaluated, preserved, or excluded. Dimension therefore acts as a local constraint on the transition from to .
The ablation results provide component-level empirical support for these theoretical roles. Removing Dimension, Organizational Relay, or Order consistently increased both 4-gram and 6-gram repetition in the long-form task. Each ablated configuration also produced shorter outputs and fewer sections than full DCOR. The degradation across all three variants indicates that the observed behavior does not depend on one isolated prompt component. Instead, it depends on the combined operation of constraint specification, cross-stage propagation, and ordered state evolution.
The ablation findings should nevertheless be interpreted as component-level evidence rather than as a complete causal proof. The mechanisms were removed through workflow and prompt-template modifications, and their effects may interact with the underlying model and task design. However, the consistency of the observed degradation supports the theoretical argument that the organizational state is an active control structure rather than passive metadata.
The matched-scale advertisement results also clarify the limits of constrained state evolution. Reusing related organizational states can preserve product identity, format, and narrative direction, but it may also preserve similar local patterns across different creative blocks. The mechanism should therefore be understood as controlling organizational continuity, not as universally maximizing lexical diversity, creativity, or every form of coherence.
5.5. Empirical Support, Baseline Relations, and Resource Trade-Offs
The comparisons clarify both the empirical support for DCOR and its relationship to alternative approaches. Against the conventional baselines, its benefit depended on task structure. DCOR supported substantially larger cumulative advertisement generation, although the simpler methods achieved lower repetition at the matched 30-block scale. Its advantage was clearer in long-form generation, which required topic exploration, hierarchical planning, section progression, and final integration.
The Neural RAG-Memory comparison distinguishes retrieval-based access from organizational-state propagation. RAG achieved lower advertisement repetition but higher long-form repetition, indicating that the mechanisms address different requirements rather than establishing universal superiority for either method. These experiments also differ from LongBench, Lost in the Middle, and LongReD, which evaluate long-context understanding, positional failures, or short-text degradation after long-context adaptation [
4,
5,
6]. DCOR instead targets loss of organizational continuity during sustained multi-stage generation and should be viewed as a workflow-level complement to architectural, retrieval-based, and training-based methods.
The Qwen replication shows that the workflow is not operationally restricted to the primary DeepSeek backbone, while the changed metric profile confirms backbone sensitivity. Because only DCOR was replicated with Qwen, this evidence supports workflow-level portability rather than cross-backbone superiority over the baselines.
The pilot human evaluation likewise remains non-comparative. The selected advertisement outputs received generally high ratings, whereas the long-form outputs received moderately positive ratings and showed remaining discourse-level redundancy. This difference indicates that character-level repetition metrics do not fully capture repeated ideas or rhetorical structures. Because only selected DCOR outputs were evaluated by five raters, the results do not establish human preference over the baselines.
Resource measurements reveal a corresponding trade-off. At the normalized 30-block advertisement scale, DCOR required approximately 11.64 model calls versus 6.00 for Neural RAG-Memory, while its estimated token use was 31,592 versus 38,231 tokens. In long-form generation, DCOR required 17.67 ± 1.15 calls and 56,497 ± 9020 tokens per article, compared with 6.00 calls and 14,630 tokens for Neural RAG-Memory. DCOR therefore exchanges additional intermediate processing for explicit organizational control. This cost is most justified when sustained structure, cumulative expansion, or stage-level coordination is central to the task.
5.6. Limitations and Future Work
The present study has several limitations.
First, the current evaluation covers two Chinese product-oriented generation tasks. These settings examine cumulative structured production and multi-section organization but do not represent the broader range of long-horizon generation. Evaluation should be extended to academic, technical, legal, dialogue, software-documentation, and multilingual tasks.
Second, the effectiveness of DCOR is task-dependent. DCOR’s advertisement advantage concerned cumulative structured expansion rather than uniformly lower repetition or higher lexical diversity. Adaptive Dimension selection and stronger branch differentiation may reduce recurring local patterns.
Third, the modern-baseline comparison used only one Neural RAG-Memory configuration and therefore does not cover graph-based, recurrent, agent-memory, architecture-level, or other retrieval mechanisms. Broader comparisons require unified inputs, backbones, output requirements, and resource accounting.
Fourth, only DCOR was replicated with Qwen; the conventional baselines and Neural RAG-Memory were not rerun. The results therefore demonstrate portability but do not establish whether DCOR preserves the same relative performance across model families.
Fifth, the automatic metrics measure surface repetition and lexical variation but not discourse redundancy, argumentative quality, rhetorical naturalness, semantic depth, or overall writing quality. Future evaluation should include semantic-progression measures, discourse-level redundancy analysis, and task-specific quality criteria.
Sixth, the five-rater pilot evaluated selected DCOR outputs without baselines and therefore cannot establish comparative human preference. Larger blind comparisons and inter-rater reliability analysis are needed.
Seventh, the ablations provide component-level rather than complete causal evidence because they modify workflow logic and prompt templates. Finer-grained studies should vary state schemas, relay strategies, ordering policies, tasks, and backbones.
Eighth, resource and scalability evidence remains incomplete. Token records were unavailable for the conventional baselines, wall-clock runtime was unavailable for Neural RAG-Memory, and advertisement normalization used average workflow-level values rather than matched runs. The number of stages, candidate branches, topology edges, and organizational-state size was not systematically varied. The reported complexity and storage bounds therefore characterize orchestration bookkeeping and observed consumption, not end-to-end scaling efficiency, because internal LLM inference remains abstracted. Future work should use unified instrumentation and empirical scaling curves with per-output, length-normalized, monetary-cost, and quality-adjusted measures.
Ninth, no systematic sensitivity or failure-case analysis was conducted. Temperature, top-p, maximum output length, retrieval k, candidate count, stage configuration, and state schema were fixed. Potential failures include loss or distortion of task anchors, propagation of early-stage errors, overly restrictive Dimensions that reduce diversity, and conflicts among states during convergence. Controlled sensitivity analysis, state validation, rollback, and error-aware relay mechanisms are therefore needed.
Finally, the implementation relies on manually designed stages, Dimensions, state schemas, and prompt templates, which may limit transfer to substantially different domains. Future work should investigate automatic Dimension discovery, adaptive state construction, dynamic ordering, state compression, and integration with retrieval-based or architecture-level long-context systems.
6. Conclusions
This study proposed Dimension-Constrained Organizational Relay (DCOR) as a workflow-level framework for maintaining organizational continuity during long-horizon generation under restricted local-context conditions. Order characterizes the organizational abstraction level and relational complexity of the information being processed, whereas Dimension specifies the task-oriented direction along which that information is organized. DCOR represents task-relevant goals, relations, constraints, anchors, and intermediate results as finite organizational states and processes them through Organizational Set Extraction, Dimension-Constrained Generation, Organizational Relay, and Organizational Convergence. The framework therefore replaces repeated full-history replay with explicit state propagation rather than attempting to modify the internal architecture of the underlying LLM.
The experiments produced task-dependent results. In cumulative advertisement generation, the full DCOR workflow generated 259–315 structured creative blocks per run, averaging 279.3 ± 17.9 across ten runs, while maintaining the required format and producing no exact duplicate blocks. However, DCOR did not achieve the lowest character-level repetition or the highest TF-IDF cosine diversity in the matched 30-block comparison. Its principal advantage in this task was therefore cumulative structured production rather than universal lexical-diversity superiority. In long-form article generation, DCOR achieved the lowest mean character-level 4-gram and 6-gram repetition among Direct Generation, Rolling-Summary Generation, Hierarchical-Outline Generation, Neural RAG-Memory, and DCOR, while maintaining high Distinct-2 and Distinct-3 values. These findings indicate that organizational-state propagation is particularly useful when a task requires sustained topic development, hierarchical planning, localized section expansion, and final structural integration.
The supporting analyses further clarify this interpretation. Removing Dimension, Organizational Relay, or Order increased character-level repetition and reduced sustained multi-section expansion, providing component-level evidence for their combined operational role. The non-comparative pilot human evaluation indicated that the selected outputs were generally readable, while also showing that character-level metrics did not fully capture discourse-level redundancy in long-form generation. The Qwen-based replication demonstrated that the workflow could be instantiated with another backbone, but the resulting metric differences indicate backbone sensitivity rather than cross-backbone superiority. The resource analysis also showed that explicit organizational control requires additional model interactions, meaning that DCOR exchanges workflow simplicity for greater control over multi-stage generation.
These conclusions remain bounded by the present experimental scope. The evaluation covered two Chinese product-oriented generation tasks, used fixed decoding and workflow configurations, and included only one representative retrieval-based baseline. Scalability, sensitivity to major configuration choices, and failure modes were not systematically evaluated. DCOR should therefore be interpreted as a complementary organizational layer rather than a general replacement for long-context architectures, retrieval-augmented generation, or memory-based systems. Future work should examine broader tasks, languages, backbones, state schemas, and retrieval mechanisms, together with controlled sensitivity, scalability, comparative human evaluation, and failure-case analyses.