Article

A Semantic-Conditional GAN Framework for Structure-Preserving and Controllable Interior Style Generation

1
School of Civil Engineering and Architecture, Jiaozuo University, Jiaozuo 454000, China
2
Tianjin Xinfei Digital Technology Co., Ltd., No. 1 Fengze Road, Zhangjiawo Industrial Park, Xiqing District, Tianjin 300380, China
3
Faculty of Design and Architecture, Universiti Putra Malaysia, Serdang 43400, Selangor, Malaysia
*
Author to whom correspondence should be addressed.
Appl. Sci. 2026, 16(16), 7892; https://doi.org/10.3390/app16167892
Submission received: 28 May 2026 / Revised: 3 August 2026 / Accepted: 6 August 2026 / Published: 7 August 2026
(This article belongs to the Section Computing and Artificial Intelligence)

Featured Application

The proposed framework can be applied to AI-assisted interior visualization, virtual scene style exploration, and digital media content generation, where controllable style expression and spatial structure preservation are required simultaneously. It is particularly suitable for early-stage visual comparison of alternative interior styles under the same spatial layout.

Abstract

Interior style generation requires expressive visual transformation while preserving spatial layout, object boundaries, and semantic relationships. Existing generative and style-transfer methods have improved indoor scene synthesis, but they often suffer from boundary drift, furniture deformation, texture leakage, and unstable style representation when stronger style signals are introduced. To address this problem, this study proposes a semantic-conditional generative adversarial network framework for structure-preserving and controllable interior style generation. The framework constructs semantic masks, boundary maps, and semantic embeddings from indoor images and injects these semantic priors into the generator feature stream through a multi-scale conditional mechanism. A style encoding network is further introduced to represent interior style characteristics and to modulate image-level visual appearance features, including texture patterns, color tones, material-like surface appearance, and illumination-related visual cues, in a controllable manner. The model was trained and evaluated using 5000 selected indoor images from SUN RGB-D and ADE20K, together with a self-constructed style reference set of 600 images covering modern minimalist, Nordic, industrial, and neoclassical interiors. Across baseline comparisons and ablation analyses, the proposed framework achieved a semantic region consistency score of 0.91, maintained higher semantic boundary consistency under increasing style intensity, obtained style consistency scores ranging from 0.88 to 0.90, and achieved an LPIPS score of 0.128. A subjective evaluation with 20 participants also showed higher ratings for realism, style expression, and structural consistency. These results provide quantitative and perceptual evidence that semantic-conditional injection can improve the balance between spatial-semantic preservation and controllable image-level style expression in AI-assisted interior visualization.

1. Introduction

Interior style generation has become an important task in digital media design, virtual interior visualization, AI-assisted design communication, and early-stage design assistance. In interior design practice, designers and users often need to compare multiple stylistic alternatives under the same spatial layout, such as transforming a neutral living room into Nordic, industrial, modern minimalist, or neoclassical visual schemes. Recent studies on text-to-image generation and AI-assisted architectural visualization have shown that generative models can support design ideation and improve the efficiency of early visual exploration [1,2]. Meanwhile, data-driven analysis and synthesis of indoor scenes have provided computational foundations for representing spatial layouts, furniture relationships, and scene configurations [3,4]. Unlike unconstrained image generation, however, interior style generation is highly structure-sensitive. A useful generated result should not only express the target style but also preserve wall–floor relationships, window and door positions, furniture boundaries, circulation areas, and object-level semantic regions as visually consistent spatial relationships. If these elements are distorted, the image may remain visually attractive but becomes less reliable for design communication, spatial evaluation, or virtual scene production.
Existing research has advanced interior and architectural image generation in several directions. Conditional generative models have been applied to furniture layout and interior space planning, showing the potential of GAN-based approaches for spatial design tasks [5]. Layout-oriented and personalized interior design studies have further expanded the role of generative AI in producing spatial alternatives and user-oriented visual schemes [6,7,8]. More broadly, image synthesis and text-to-image generation research has demonstrated the capacity of generative models to produce diverse and visually plausible design images [9,10]. Nevertheless, many existing approaches emphasize visual diversity, layout generation, or high-level design ideation, while the relationship between style transformation and fine-grained spatial-semantic preservation remains insufficiently addressed in interior scenes. For interior visualization, this issue is particularly important because stylistic alternatives are meaningful only when the original room organization, furniture relationships, and object boundaries remain recognizable after transformation.
Style-transfer methods provide another important foundation for interior style generation. GAN-based artistic style transfer, CycleGAN-based transfer, and deep-learning-assisted architectural design-space generation have shown that texture patterns, color tones, and image-level atmospheric cues can be modified by learning style-related feature distributions [11,12,13]. Recent work on multi-style image generation based on semantic images also indicates that style control can be combined with semantic information to improve the adaptability of generated results [14]. However, feature-statistics-based style-transfer methods often treat an interior scene as a general visual field rather than as a composition of semantically meaningful regions. As a result, material-like textures, visual surface patterns, and color distributions may leak across object boundaries, for example from walls to furniture or from floors to tables. This limitation is particularly important in interior visualization and design communication, where the credibility of a generated image depends on spatial logic as well as stylistic expression.
Semantic information provides a possible way to reduce this problem. Semantic segmentation and scene parsing studies have shown that pixel-level category prediction, semantic flow, and indoor scene understanding can provide useful cues for region-level structure and object-boundary representation [15,16,17]. In semantic-guided image synthesis, segmentation maps or layout conditions can constrain the generation process and improve spatial coherence [10,14]. However, many semantic-guided methods rely mainly on semantic labels or normalization-based conditioning. Their style-control mechanisms are often coupled with semantic modulation, making it difficult to achieve continuous multi-style adjustment while maintaining stable object boundaries and spatial geometry. This problem becomes more evident in interior scenes when style intensity increases, because strong texture, color, and illumination-related visual cues may override weak structural constraints.
Structure preservation and style expression should therefore be coordinated within the generation process rather than treated as separate objectives. Region-level semantic masks, boundary-level structural cues, and feature-level semantic embeddings can guide the generation process at different spatial resolutions, while style vectors can regulate image-level texture patterns, color tones, material-like surface appearance, and illumination-related visual cues without damaging semantic organization. Previous studies on conditional GAN-based architectural layout generation and fine-tuned interior visualization models suggest that embedding spatial and stylistic constraints into generative frameworks is valuable for design-oriented image synthesis [18,19,20]. Research on interpretable latent representations also indicates that latent feature spaces can support controllable visual attributes when properly constrained [21]. However, existing studies have not sufficiently clarified how multiple semantic priors and controllable style representations jointly influence the trade-off between spatial-semantic stability and style expressiveness in interior style generation. This trade-off is central to interior visualization because stronger stylization may improve visual distinctiveness but can also increase the risk of boundary drift, object deformation, and cross-region texture leakage.
To address this gap, this study proposes a semantic-conditional GAN framework for structure-preserving and controllable interior style generation. The framework constructs semantic masks, boundary maps, and semantic embeddings from indoor scenes and injects them into the generator through a multi-scale conditional mechanism. This design allows the model to preserve global layout at low resolutions while enhancing boundary details at higher resolutions. A style encoding network is further introduced to extract latent style representations from reference images and to modulate image-level visual appearance features, including texture patterns, color tones, material-like surface appearance, and illumination-related visual cues, through controllable style vectors. The training objective combines adversarial, semantic consistency, style reconstruction, and perceptual losses to balance realism, structural stability, and style expression.
This study is designed as a quantitative evaluation of whether semantic-conditional injection improves the stability and controllability of GAN-based interior style generation. Experiments were conducted on 5000 selected indoor images from SUN RGB-D and ADE20K, together with a self-constructed style reference set of 600 images covering four representative interior styles. The proposed model was compared with StyleGAN2, AdaIN, linear style transfer, and SPADE using structure preservation, style controllability, perceptual quality, ablation, and subjective-evaluation metrics. The evaluation focuses on whether semantic conditioning can improve boundary stability, style consistency, perceptual quality, and the structure–style trade-off under controlled experimental settings. Rather than assessing visual plausibility alone, the study evaluates whether stylistic variation can be introduced while maintaining spatial-semantic correspondence with the input interior scene.
The main contributions of this study are threefold. First, it develops a task-oriented semantic-prior representation that integrates masks, boundary maps, and embeddings to support structure-preserving interior style generation. Second, it proposes a multi-scale semantic-conditional injection mechanism that embeds structural constraints into the generator feature stream and reduces boundary drift during style transformation. By combining semantic conditioning with controllable style modulation, the framework provides a task-specific way to examine and improve the structure–style balance in interior visualization. Third, it establishes a quantitative evaluation framework for assessing structure preservation, style consistency, perceptual quality, structure–style trade-off, ablation performance, and subjective perception across baseline models and controlled experimental settings. Together, these contributions position the study as a task-specific integration and evaluation of semantic priors and controllable style modulation for AI-assisted interior style generation.

2. Materials and Methods

2.1. Research Design and Framework Overview

This study adopts an engineering-oriented experimental design to evaluate whether semantic-conditional injection can improve the balance between structural preservation and controllable style representation in interior style generation. The proposed model is formulated within a generative adversarial learning framework, in which the generator synthesizes stylized interior images and the discriminator provides adversarial feedback to improve visual realism [22]. Unlike unconstrained image generation, the task addressed in this study requires the generated result to maintain the semantic-spatial organization of the input interior scene while expressing the target artistic style.
Given an interior content image x c , a semantic representation s derived from x c , and a target style reference image x s , the objective is to generate a stylized image x ^ that satisfies two conditions. First, x ^ should preserve the structural organization of x c , including object regions, wall–floor relationships, furniture contours, windows, doors, and the overall spatial layout. Second, x ^ should reflect the stylistic characteristics of x s , including color distribution, texture density, material-like surface appearance and illumination-related visual cues. In this formulation, structure preservation is defined as the consistency of semantic regions and object boundaries before and after style transformation, whereas style controllability refers to the ability to regulate style expression through a latent style vector and a continuous intensity coefficient.
The proposed framework consists of five connected components. The first component is dataset preparation and semantic prior construction. Indoor images and semantic annotations are processed to generate semantic masks, semantic boundary maps, and semantic embeddings. These three forms of semantic prior represent region-level, boundary-level, and feature-level structural information, respectively. The second component is a multi-scale semantic-conditional injection module. Inspired by semantic-guided image synthesis, in which semantic layouts are used to modulate feature activations and preserve spatial correspondence [23], this module maps semantic priors into generator-compatible modulation parameters and injects them into the feature stream at different spatial resolutions. This multi-scale arrangement allows global room organization and local object-boundary information to be represented within the same generation process.
The third component is a style encoding and modulation module. A style encoder transforms each reference style image x s into a latent style vector, which is then used to represent and modulate texture patterns, color tones, material-like surface appearance, and illumination-related visual cues. Following the principle of style-based feature modulation and modulated convolution in generative image synthesis [24], the style vector is introduced into the generator as a controllable signal rather than as a post-processing filter. This design allows style expression to be adjusted continuously while reducing the risk of disrupting semantic structure.
The fourth component is a multi-objective adversarial optimization strategy. The training objective combines adversarial loss, semantic consistency loss, style reconstruction loss, and perceptual loss. These terms jointly guide the model to improve image realism, preserve semantic regions, maintain style consistency, and retain perceptually meaningful content features. The fifth component is the evaluation protocol, which includes baseline comparison, ablation analysis, structure–style trade-off analysis, perceptual-quality measurement, computational feasibility analysis, and subjective assessment. Through this workflow, the study evaluates not only whether the proposed model generates plausible stylized interiors, but also whether semantic-conditional injection contributes to measurable improvements in structural stability and style controllability.
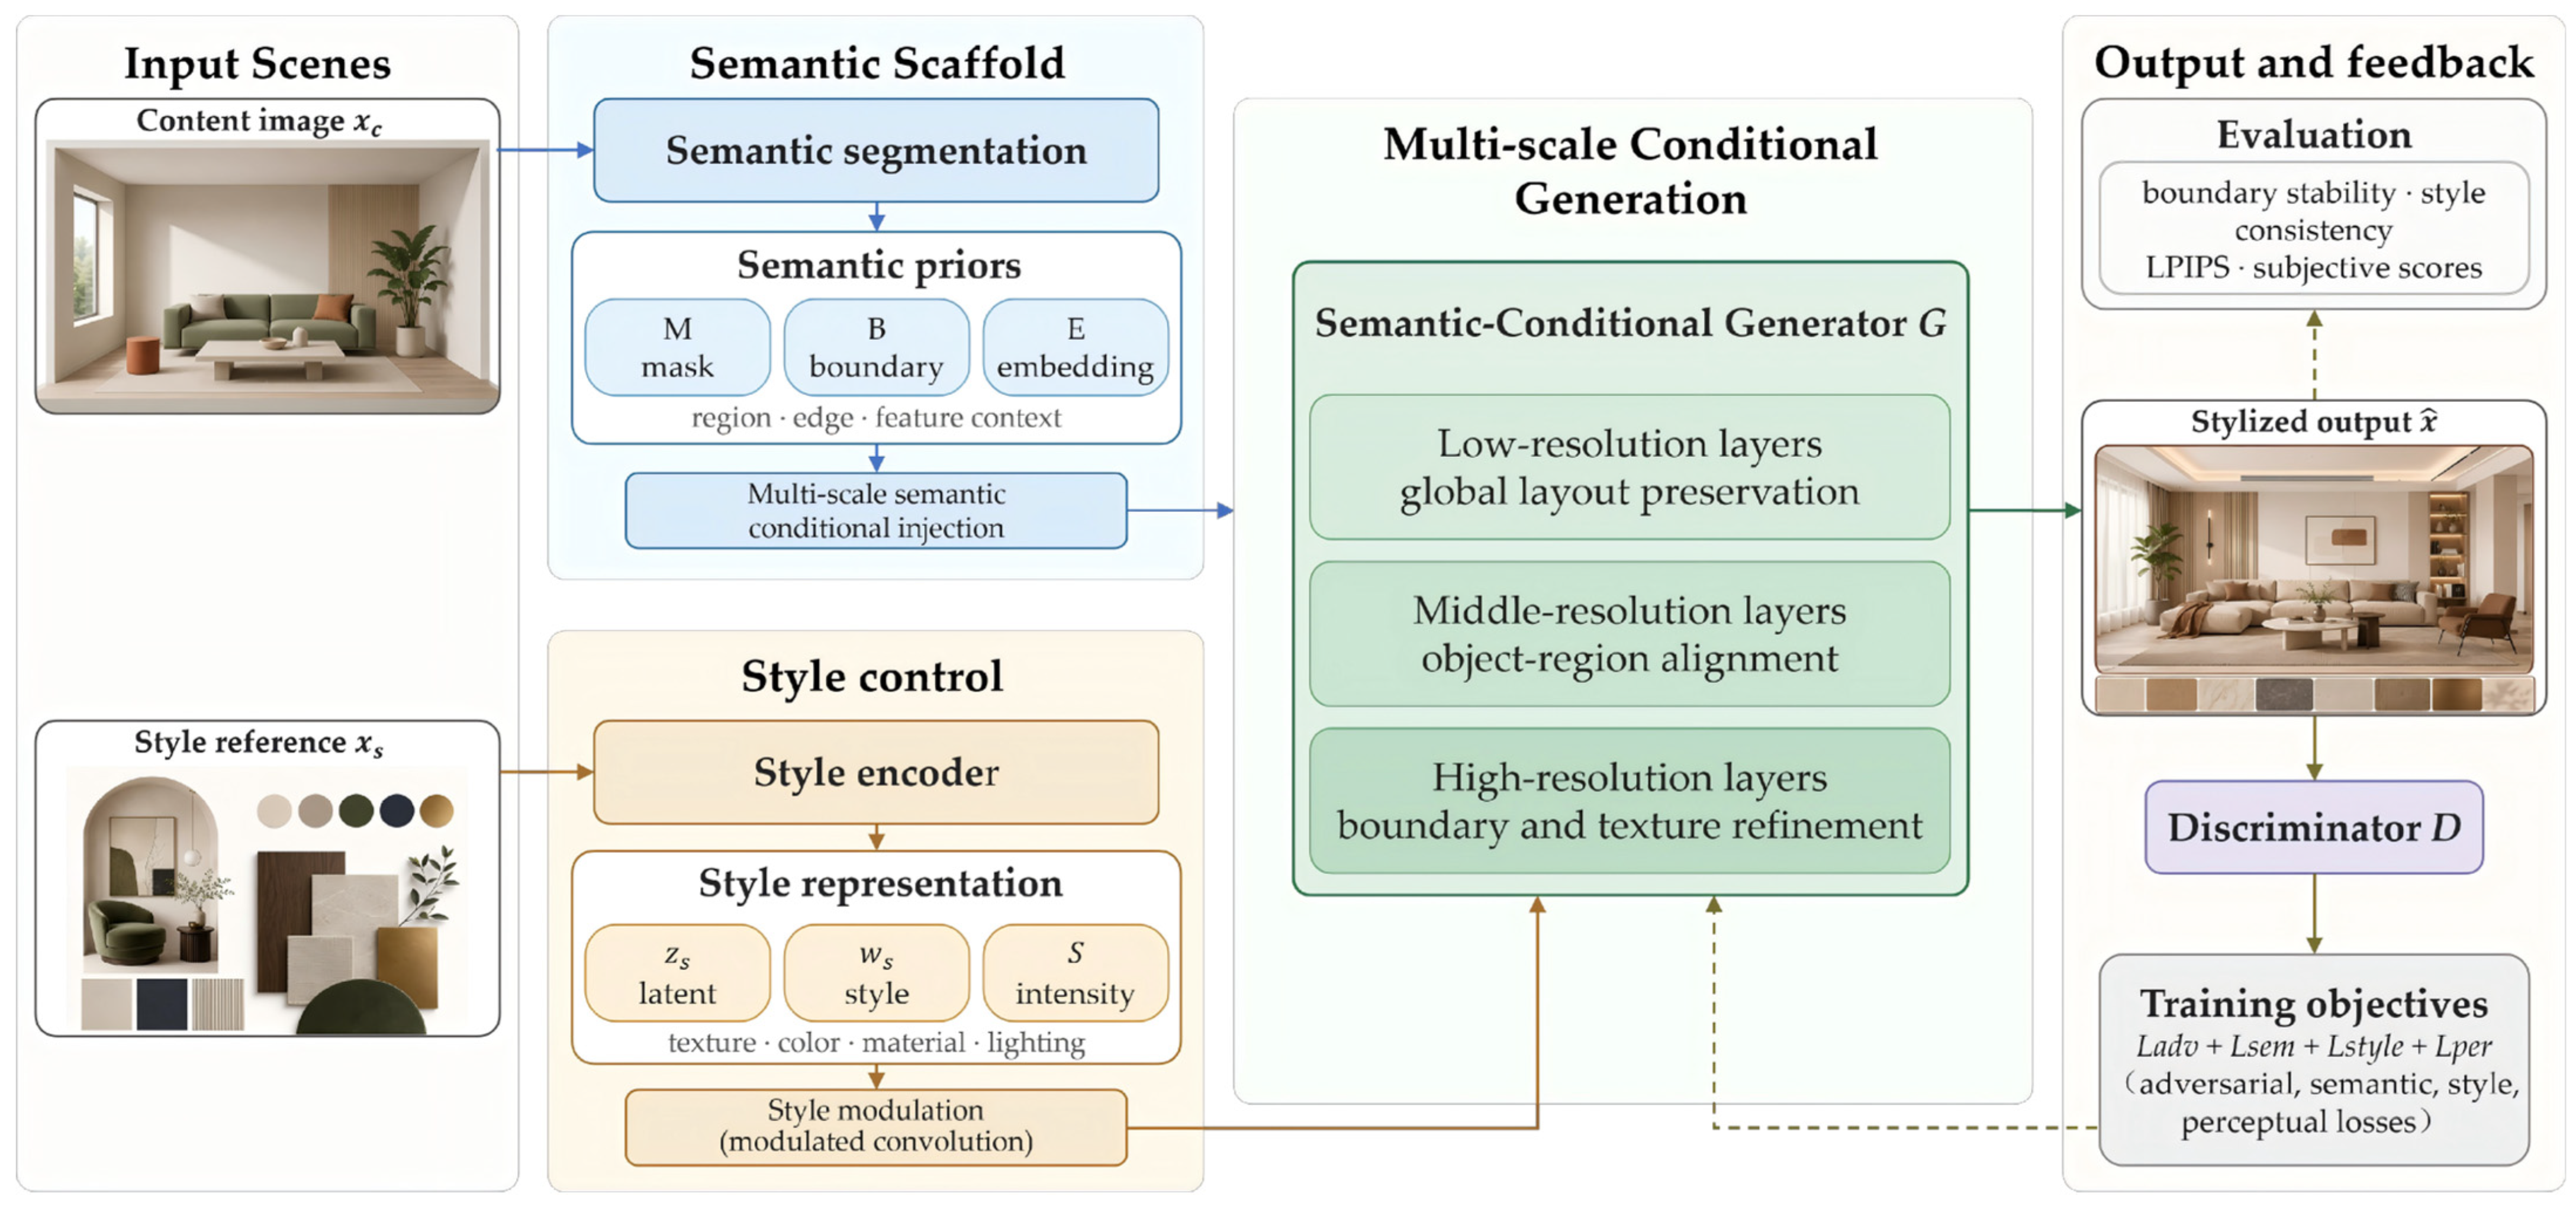
Figure 1 presents the overall framework of the proposed method. The semantic branch extracts structural constraints from the input interior image, while the style branch extracts controllable style signals from the reference image. These two branches are fused inside the generator feature stream, rather than being applied as independent post-processing operations. This design is intended to reduce the conflict between strong stylization and semantic stability by coordinating structural priors and style representation within the same generation process.

2.2. Dataset Preparation and Semantic Prior Construction

The experimental dataset was constructed from two publicly available indoor-scene datasets: SUN RGB-D and ADE20K. SUN RGB-D provides RGB-D indoor scene data for scene understanding, while ADE20K provides densely annotated scene parsing data covering diverse object and stuff categories [25,26]. These two datasets were selected because they contain indoor scenes with rich spatial components and semantic annotations, making them suitable for evaluating structure-aware interior style generation.
After data screening, 2000 images from SUN RGB-D and 3000 images from ADE20K were retained. Outdoor scenes, low-resolution images, samples with incomplete semantic annotations, images with severe occlusion, and cases with ambiguous spatial composition were excluded. Following this screening procedure, the experimental corpus comprised 5000 indoor-scene images with corresponding semantic annotations. To support model evaluation and reduce the risk of case-specific memorization, the corpus was partitioned at the image level into training, validation, and test subsets using a 7:2:1 ratio, yielding 3500 training images, 1000 validation images, and 500 test images. The validation and test subsets were kept separate from model-parameter updating and were used for validation and final evaluation, respectively. All images and corresponding semantic maps were resized to 256 × 256 pixels through a consistent preprocessing pipeline, ensuring pixel-wise alignment among RGB content images, semantic masks, boundary maps, and feature-level embeddings. The 256 × 256 resolution was adopted as a controlled experimental setting to maintain computational feasibility and enable fair comparison across baseline methods. It defines the scale of experimental image synthesis and metric computation, rather than the level of detail required for construction documentation, physical material specification, or physically based lighting simulation. All subsequent model training, ablation studies, and baseline evaluations followed this data split and preprocessing protocol unless otherwise stated. In the inference stage, the learned network parameters were fixed, and each test output was generated by providing a content image and a reference style image as inputs, without updating or fine-tuning the model for the individual scene or style case. The dataset composition and experimental split are summarized in Table 1.
A self-constructed style reference set was established to support controllable style encoding. This set contained 600 interior design images covering four representative styles: modern minimalist, Nordic, industrial, and neoclassical. Each style category contained 150 images. The images were manually screened to remove duplicates, low-resolution samples, and cases with ambiguous style features. Style labels were assigned according to dominant color palette, furniture form, material-like surface appearance, illumination-related visual cues, and decorative characteristics. The purpose of this set was not to replace the content dataset, but to provide reference distributions for style encoding and style consistency evaluation. Accordingly, the style labels describe image-level visual style attributes rather than technical material specifications or physical lighting parameters. As shown in Table 2, the four style domains were balanced in image number to reduce category bias during style representation learning.
Semantic labels from the selected indoor images were mapped into a unified set of major interior categories. The core categories included walls, floors, sofas, tables, windows, doors, cabinets, beds, lamps, and other furniture-related regions. Because SUN RGB-D and ADE20K do not use identical category granularity, semantically similar labels were merged when their fine-grained distinction was not central to the structure-preservation task. For example, related furniture subcategories were grouped into broader object categories when the objective was to preserve region boundaries and spatial organization rather than to distinguish all furniture types. This label harmonization reduced cross-dataset inconsistency and allowed the generator to receive stable semantic constraints across samples.
To examine the structural distribution of the selected indoor scenes, the pixel proportion, average number of category regions, and sample coverage of major semantic categories were calculated. Table 3 shows that walls and floors dominate the spatial background of most indoor scenes, while sofas, tables, and windows provide important object-level and boundary-level cues. This distribution is relevant to the proposed method because a generator may achieve high global visual realism while still failing to preserve smaller but perceptually important object boundaries.
Based on the unified semantic representation, three types of semantic priors were constructed. The first prior is the semantic mask M , which provides pixel-wise region information. Each semantic category is represented by a binary map, and all category maps are stacked to form a multi-channel semantic tensor. The second prior is the semantic boundary map B , which is extracted from the segmentation map by detecting category transitions along object and region borders. This boundary prior strengthens edge-level constraints, especially around furniture, windows, wall–floor intersections, and table boundaries. The third prior is the semantic embedding E , which maps discrete category labels into a continuous feature space. Compared with a pure pixel mask, the embedding representation allows semantic information to be used as a feature-level conditioning signal inside the generator.
The proposed semantic prior construction therefore combines region-level masks, boundary-level maps, and feature-level embeddings instead of relying on a single semantic representation. Region-level masks provide global semantic layout, boundary maps emphasize local geometric stability, and semantic embeddings support multi-scale feature modulation. This combined representation is consistent with the overall framework shown in Figure 1, in which semantic priors are injected into the generator feature stream to constrain structure during style transformation.
The semantic consistency loss is used to encourage region-level correspondence between the input semantic structure and the generated result. It is defined as follows:
L sem   =   1 C c = 1 C | | M c P c ( x ^ ) | | 1 ,
where M c denotes the binary semantic mask of class c in the input scene, P c ( x ^ ) denotes the predicted region mask of the generated image for the same class, C is the number of semantic categories, and | | · | | 1 denotes the L 1 distance. This term encourages the generated image to maintain semantic region correspondence with the input structure and reduces the likelihood of cross-region texture or surface-pattern leakage during style transformation.

2.3. Semantic-Conditional Generator and Style Modulation

The generator is designed as a multi-scale feature synthesis network. Its main function is to transform an interior content representation into a stylized output while maintaining semantic organization. The model follows the general adversarial generation principle, in which a generator and a discriminator are optimized jointly to improve image realism [22]. However, unlike an unconstrained GAN, the proposed generator is conditioned by semantic priors and style representations at the feature level. In the implemented framework, the trainable components include the semantic-conditional generator, the style encoding and modulation module, and the discriminator. The generator performs image synthesis during both training and inference, whereas the discriminator is used only during training to provide adversarial supervision and is not used in the final inference stage.
To preserve spatial structure during style transformation, semantic priors are injected into multiple generator layers rather than concatenated only with the input image. This design is motivated by semantic-guided image synthesis, where spatially adaptive conditioning has been shown to help preserve the correspondence between semantic layouts and generated visual content [23]. At the implementation level, the semantic representation is organized as three aligned tensors: semantic region masks, semantic boundary maps, and semantic embeddings. Before being injected into a generator layer, each semantic prior is resized or projected to the spatial resolution of the corresponding feature map. Region masks and semantic embeddings are mainly used in low- and middle-resolution layers to maintain room layout and object-region correspondence, while boundary maps are introduced in higher-resolution layers to strengthen edge-sensitive constraints around furniture contours, windows, doors, table boundaries, and wall–floor intersections.
Let S denote the semantic representation derived from the content image, and let F l denote the generator feature map at layer l . The semantic embedding function ϕ l ( S ) maps the semantic input into a layer-specific representation. A conditional mapping network then predicts two modulation parameters, γ l and β l , which control the feature magnitude and feature offset, respectively. The semantic modulation is defined as follows:
γ l   =   W l γ ϕ l ( S ) ,   β l   =   W l β ϕ l ( S ) ,
F ^ l =   γ l F l +   β l ,
where W γ and W β are learnable mapping matrices, γ l adjusts feature magnitude, β l adjusts feature offset, and denotes element-wise modulation. The parameters are broadcast to the spatial and channel dimensions of the corresponding feature layer when necessary. Equations (2) and (3) allow the generator to adjust feature synthesis according to semantic regions, thereby reducing the risk that style textures overwrite structural boundaries. In practice, this operation functions as a layer-specific affine modulation of generator features conditioned on semantic layout information, rather than as a post-processing correction after image generation.
Boundary information is further introduced to strengthen high-resolution structural constraints. A semantic boundary map B is extracted from the segmentation map and encoded through a boundary mapping network ψ ( B ) . The resulting boundary embedding is aligned with the corresponding generator layer and fused with the semantically modulated feature map:
F 1 b   =   F ^ l   +   ψ ( B ) ,
where F 1 b denotes the boundary-enhanced feature map, and ψ ( B ) denotes the layer-specific boundary embedding. The boundary term does not replace semantic masks; instead, it complements them by providing edge-sensitive information at higher resolutions. This operation is particularly useful for preserving furniture contours, window frames, table edges, and wall–floor intersections, where texture leakage and object deformation are common in semantically weak style-transfer models. In the implemented configuration, boundary-enhanced conditioning is applied mainly to the 64 × 64, 128 × 128, and 256 × 256 feature stages, where local object edges and surface transitions are most likely to be affected by strong style modulation.
The style branch is implemented through a style encoding network. Given a reference style image x s , the style encoder E s compresses its visual characteristics into a latent style variable z s . This variable is then projected by a mapping network f m a p into a style control vector w s :
z s = E s ( x s ) ,   w s   =   f m a p ( z s ) ,
The style vector is used to modulate convolutional weights inside the generator so that texture patterns, color tones, material-like surface appearance, and illumination-related visual cues can be adjusted under semantic constraints. The style intensity coefficient s is implemented as a continuous control factor applied to the projected style vector. In the experiments, s was varied within the range from 0.2 to 0.8 to evaluate whether stronger style expression could be introduced without causing excessive semantic boundary degradation.
w s a d j = s · w s ,     0 s 1 ,
where w s a d j is the adjusted style vector used for modulation. Low values of s preserve more content appearance, while high values increase texture richness, color shift, surface-appearance variation, and style-related illumination cues. This coefficient is also used in the structure–style trade-off experiment. If the proposed semantic constraints are effective, increasing s should strengthen style expression while causing a slower decline in semantic boundary consistency than in semantically weaker baselines.
Following the principle of style-based feature modulation and modulated convolution in generative image synthesis [24], the style-modulated convolution kernel at layer l is formulated as:
W l s   =   a l ( w s a d j ) W l ,
where W l is the base convolution kernel, a l ( w s a d j ) is the scale factor predicted from the adjusted style vector for layer l , and W l s denotes the style-modulated convolution kernel. This design decouples style representation from semantic structure. Semantic priors guide where generation should remain structurally stable, while style vectors regulate how image-level visual appearance is expressed within those semantic constraints. Therefore, the semantic branch and the style branch are not independent post-processing modules; they are jointly integrated inside the generator feature synthesis process.
The detailed configuration of the semantic-conditional injection module is presented in Table 4. The table reports the implemented conditioning levels, feature resolutions, semantic prior types, mapping widths, modulation parameters, and implementation roles of each injection stage, so that the semantic-conditioning strategy can be interpreted as a reproducible model configuration rather than only as a conceptual framework.
As shown in Table 4, the configuration follows a progressive conditioning strategy. Lower layers use smaller semantic dimensions to maintain the global layout, while higher layers use larger embedding dimensions and boundary-sensitive modulation to improve local structural fidelity. This progressive structure is intended to avoid two opposite problems: under-conditioning, where semantic information becomes too weak to constrain the generator, and over-conditioning, where style expression is excessively suppressed by rigid semantic masks. In this implementation, Layers 1 and 3 mainly preserve global spatial organization, Layer 5 links region-level semantics with major object boundaries, and Layers 7 and 9 refine local edges and high-resolution semantic stability. By combining semantic modulation, boundary enhancement, and style-based convolutional modulation, the generator can coordinate structural preservation and style expression within the same feature synthesis process.

2.4. Training Strategy and Optimization Objective

Training was conducted within an adversarial learning framework. The generator G aims to synthesize stylized interior images that are visually realistic, semantically stable, and consistent with the target style reference, while the discriminator D encourages the generated images to approximate the distribution of real interior images [22]. However, image realism alone is insufficient for structure-preserving interior style generation. A generated image may appear plausible at the global level while still distorting furniture boundaries, wall–floor relationships, or local semantic regions. Therefore, the adversarial objective was combined with semantic consistency, style reconstruction, and perceptual constraints.
For each training batch, the model was optimized as a content-style conditioned generation process. Each content image was paired with its aligned semantic mask, semantic boundary map, and semantic embedding as structural priors, while a reference image sampled from the style reference set provided the target style condition. The content image and semantic priors were passed to the semantic-conditional generator, and the reference style image was encoded by the style branch to obtain the style vector used for modulation. The generated stylized image was then used for adversarial discrimination, semantic consistency calculation, style reconstruction, and perceptual feature comparison.
For a content image x c , semantic representation S , and style vector w s a d j , the generated image is defined as:
x ^   =   G ( x c ,   S , w s a d j ) ,
The discriminator is trained to distinguish real interior images x from generated stylized images x ^ . Its adversarial loss is formulated as:
L D   =   E x ~ P data [ log D ( x ) ] E x c ,   S ,   w s a d j   [ log ( 1 D ( x ^ ) ) ] ,
The generator is optimized using a non-saturating adversarial objective:
L a d v   =   E x c ,   S ,   w s a d j [ log D ( x ^ ) ] ,
where D ( x ) denotes the discriminator prediction for a real image, and D ( x ^ ) denotes the prediction for the generated image. The adversarial term improves global visual plausibility, including illumination-related visual coherence, texture-pattern plausibility, and overall image naturalness. Nevertheless, because L a d v does not explicitly constrain semantic layout or style consistency, additional loss terms are required.
The semantic consistency loss L s e m , defined in Equation (1), encourages region-level correspondence between the generated image and the semantic map of the input scene. This term is assigned a relatively high weight because the main objective of the study is to preserve interior spatial structure during style transformation. In addition to semantic consistency, a style reconstruction loss is used to ensure that the generated image retains the intended style representation. After generation, the stylized image is passed through the same style encoder and mapping network, and the recovered style representation is compared with the input style vector:
L style   =   | | f m a p ( E s ( x ^ ) )   w s a d j | | 1 ,
where E s denotes the style encoder, f m a p denotes the style mapping network, and   w s a d j denotes the adjusted target style vector used for style modulation. This constraint reduces style drift and encourages the generated image to remain close to the reference style domain.
A perceptual loss is further introduced to constrain feature-level content and texture-pattern consistency. Following perceptual-loss-based image transformation methods [27], features are extracted from a pre-trained visual network and compared between the content image and the generated image:
L per   =   1 J j = 1 J | | Φ j ( x c ) Φ j ( x ^ ) | | 1 ,
where Φ j ( · ) denotes the feature representation extracted from the j - t h selected layer of the pre-trained visual network, and J is the number of selected feature layers. This term helps reduce local artifacts and improves perceptual coherence in generated texture patterns without forcing pixel-level identity between the content and generated images.
The total generator objective combines the adversarial, semantic, style reconstruction, and perceptual terms:
L t o t a l   =   λ adv L adv + λ sem L sem + λ style L style + λ per L per ,
where λ adv , λ sem , λ style , and λ per are weighting coefficients for realism, semantic stability, style reconstruction, and perceptual quality, respectively. The semantic consistency term was assigned the highest weight because the study focuses on structure-preserving interior generation. The same loss configuration was used across the main experiments to ensure that baseline comparison and ablation analysis reflected differences in model architecture rather than inconsistent training conditions. During optimization, the discriminator and generator were updated alternately. The discriminator was trained using real indoor images and generated stylized images, while the generator was optimized using the combined objective in Equation (13) under adversarial feedback from the discriminator. This alternating update procedure was applied consistently to the proposed model and to the comparable ablation variants.
The training and optimization configuration is summarized in Table 5. The Adam optimizer was used because it is widely applied in deep learning models involving noisy gradients and non-stationary objectives [28]. Gradient clipping was applied to reduce unstable adversarial updates, particularly during the early training stage when semantic constraints and style modulation compete for feature control. The proposed model and the comparable ablation variants were trained using the same input resolution, preprocessing pipeline, semantic-prior construction procedure, update strategy, and loss-weight configuration. This setting ensured that performance differences could be attributed primarily to the semantic-conditioning and style-modulation design rather than to inconsistent optimization settings. The training procedure was defined by the input composition, loss configuration, update strategy, and dataset split. The validation subset was used to monitor loss behavior and training stability, while the held-out test subset was used only for final generation and metric calculation. All test outputs were produced using the same trained model without case-specific parameter updating.
As shown in Table 5, the semantic loss weight was higher than the other loss weights to reflect the structural emphasis of the proposed framework. The style reconstruction loss was assigned an intermediate weight to maintain style consistency without suppressing semantic constraints, while the adversarial and perceptual terms were used to improve realism and feature-level visual coherence. The same configuration was used for the proposed model and comparable ablation variants, providing a consistent optimization basis for evaluating whether semantic-conditional injection improves the structure–style balance in interior style generation. After training, all test outputs were generated using the same trained model and the configuration summarized in Table 5, without case-specific parameter updating or manual adjustment during inference. This setting ensured that the quantitative results, ablation analysis, and subjective evaluation reflected the learned model behavior under a fixed experimental protocol.

2.5. Experimental Evaluation and Reproducibility Protocol

2.5.1. Baseline Models and Evaluation Protocol

The proposed framework was compared with four representative baseline methods: StyleGAN2, AdaIN, linear style transfer, and SPADE. These methods were selected because they represent the main methodological categories most closely related to the proposed framework: semantically unconstrained generation, feature-statistics-based style transfer, linear feature transformation, and semantic-guided generation. The comparison was designed as a category-based and reproducible evaluation protocol rather than as a claim that these baselines exhaust all recent generative systems. StyleGAN2 was used as a semantically unconstrained generative baseline, providing a reference for latent-space image synthesis without explicit semantic layout preservation [24]. AdaIN was selected as a representative arbitrary style-transfer method based on adaptive instance normalization, in which the mean and variance of content features are aligned with those of style features [29]. Linear style transfer was included because it learns feature transformation matrices for fast arbitrary image and video style transfer, thereby representing a stronger feature-transformation baseline than simple global statistics matching [30]. SPADE was used as a semantic-guided synthesis baseline because it uses semantic maps to modulate normalization parameters and preserve spatial correspondence between semantic layouts and generated images [23]. These methods provide controlled reference points for examining whether the proposed combination of semantic masks, boundary maps, semantic embeddings, and controllable style modulation improves the structure–style balance in interior style generation.
Because StyleGAN2 does not explicitly take semantic maps or content layouts as input, it was used as a semantically unconstrained reference rather than as a fully content-conditioned style-transfer model. Its results were evaluated using the same post-generation semantic parsing and perceptual evaluation pipeline. Therefore, structure-related results involving StyleGAN2 should be interpreted as a reference for the absence of semantic conditioning, while direct content-aligned comparisons are mainly supported by AdaIN, linear style transfer, SPADE, and the proposed framework. This distinction prevents the StyleGAN2 comparison from being overinterpreted as a one-to-one content-preservation test.
All baseline methods and the proposed framework were evaluated on the same test subset of 500 indoor images. The preprocessing settings, input resolution, semantic label mapping, style reference categories, and evaluation procedures were kept consistent across methods. For fair comparison, all methods were evaluated under the same 256 × 256 resolution and the same four style domains: modern minimalist, Nordic, industrial, and neoclassical. For trainable models or experimental variants, the training and evaluation followed the same data split described in Section 2.2; for non-trainable or pre-trained style-transfer baselines, the same test subset and evaluation pipeline were applied. This setup ensured that performance differences mainly reflected the effects of semantic-conditional injection and controllable style modulation rather than differences in input preparation, dataset split, or evaluation protocol. Table 6 summarizes the baseline models, their core mechanisms, and their corresponding structural and stylistic control strategies.
The evaluation protocol included both objective and subjective components. Objective evaluation was organized around three dimensions: structure preservation, style controllability, and perceptual quality. Structure preservation was assessed using semantic boundary offset, semantic region consistency, semantic boundary consistency, and geometric misalignment ratio. Semantic boundary offset measures the average pixel displacement between generated semantic boundaries and input semantic boundaries. Semantic region consistency evaluates the agreement between generated semantic regions and the corresponding input semantic masks. Semantic boundary consistency provides a normalized measure of boundary alignment, while geometric misalignment ratio measures the proportion of regions showing visible layout distortion or object-position mismatch.
Style controllability was evaluated using style response amplitude, style consistency score, style-domain separability, and style diversity score. Style response amplitude measures the degree of visual change produced by different style intensity coefficients. Style consistency score measures the similarity between generated image features and target style-domain features. Style-domain separability evaluates whether generated samples from different styles form distinguishable clusters in the style-feature space, while style diversity score reflects intra-domain variation under the same style category. Perceptual quality was measured using LPIPS, edge sharpness, and texture-pattern detail score. LPIPS measures learned perceptual distance using deep visual features and has been widely used to evaluate perceptual similarity in image generation tasks [31]. Edge sharpness reflects contour clarity, and the texture-pattern detail score evaluates image-level local texture richness and high-frequency detail representation rather than physical material accuracy. Table 7 lists the evaluation dimensions, metrics, units or scales, interpretations, and desired directions used in the experiments.
The desired direction of each metric was specified to ensure consistent interpretation of the quantitative results reported in the subsequent analysis. In particular, lower values indicate better performance for semantic boundary offset, geometric misalignment ratio, and LPIPS, whereas higher values indicate better performance for semantic region consistency, semantic boundary consistency, style-related scores, perceptual detail metrics, and subjective ratings. For metrics reported in figures, the corresponding unit or normalized scale was indicated in the axis label or figure caption to avoid ambiguity in quantitative interpretation.
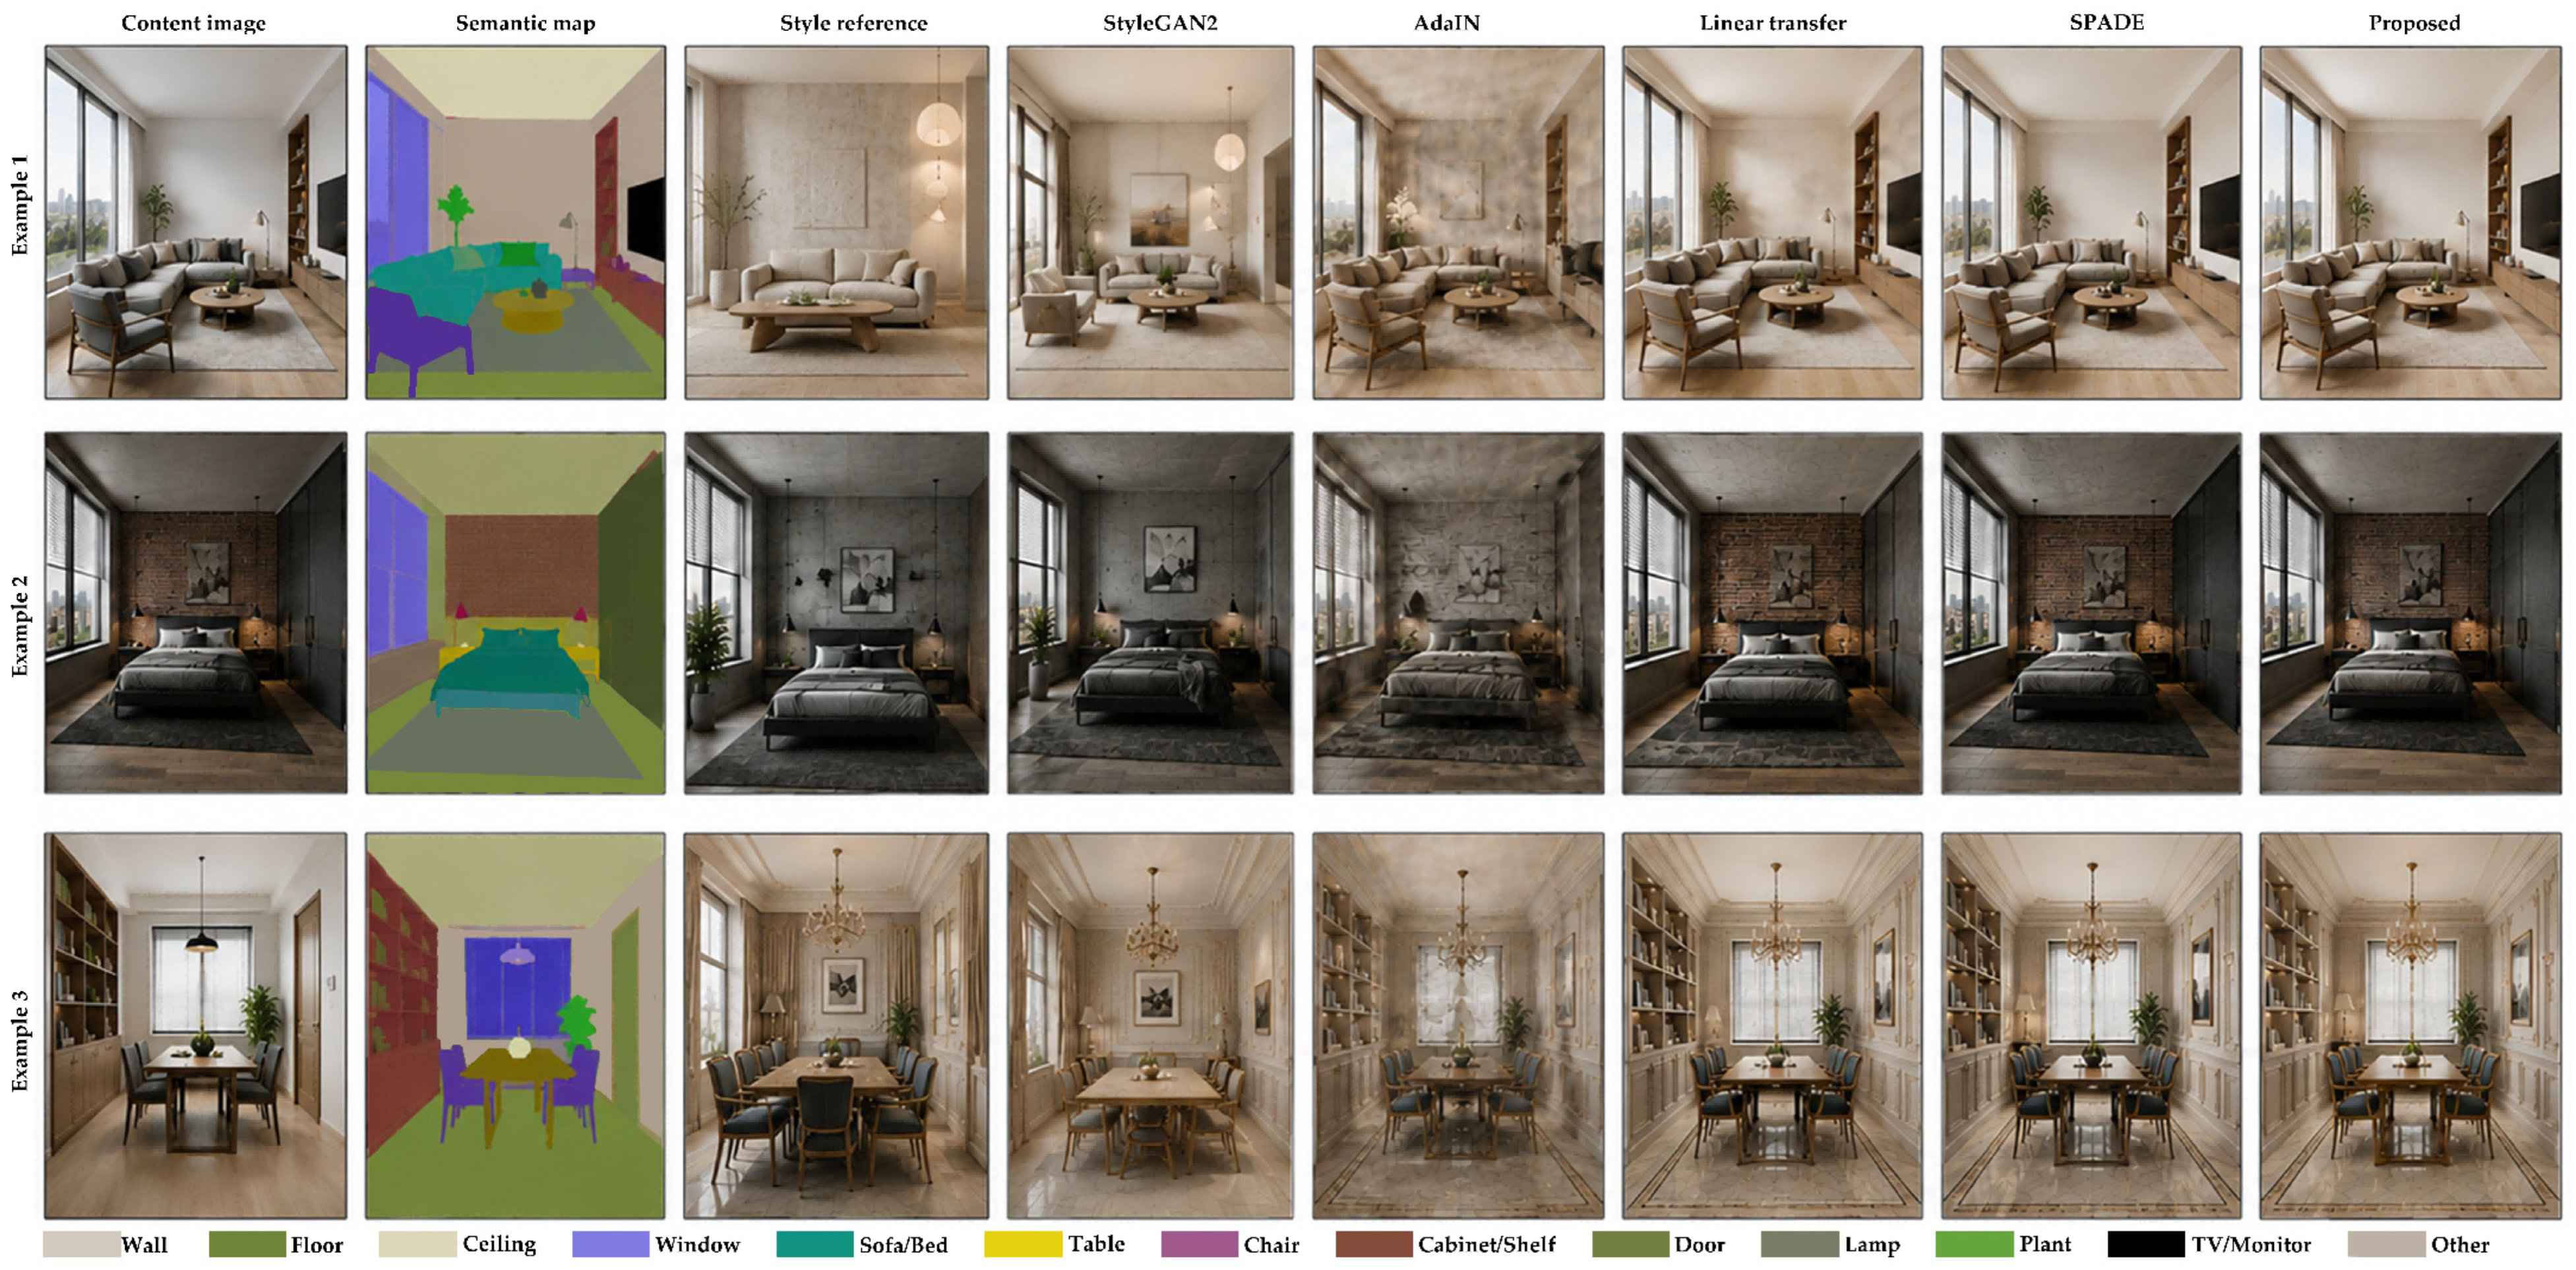
In addition to quantitative metrics, a qualitative comparison layout was designed to organize visual outputs from different methods in a consistent format. As shown in Figure 2, each row corresponds to one test sample, and the columns include the content image, semantic map, style reference, StyleGAN2 output, AdaIN output, linear style-transfer output, SPADE output, and the proposed output. For StyleGAN2, the displayed result should be interpreted as a semantically unconstrained visual reference rather than as a content-aligned transformation of the same input scene. Including all baseline outputs in the same visual layout allows the qualitative comparison to correspond directly to the baseline protocol summarized in Table 6 and the quantitative evaluation metrics listed in Table 7. This layout was used to guide qualitative inspection of typical visual differences in structure preservation, boundary stability, and style expression across methods.
Subjective evaluation was conducted with 20 participants. The group included eight participants with backgrounds in interior design or environmental art, six with backgrounds in computer science, digital media, or artificial intelligence, and six general users without professional design training. This mixed composition was used to balance design-oriented judgment, technical image-quality assessment, and general visual perception. Each participant evaluated the same set of paired outputs generated by the proposed framework and the control model under identical content, semantic-layout, and style-reference conditions. The model identities were concealed, and the presentation order of the image pairs was randomized to reduce ordering and method-recognition bias. Participants rated each output independently for realism, style expression, and structural consistency using a five-point scale. The evaluation was conducted anonymously; no sensitive personal information was collected, and informed consent was obtained before participation. All subjective scores were normalized to the range of 0–1 for comparative analysis.
All objective and subjective results reported in the subsequent Results section were obtained under the settings described above. The reported values therefore refer to the same test subset, input resolution, semantic label mapping, style reference categories, and evaluation protocol. This consistency is important for ensuring that the comparative findings reflect differences in model behavior rather than differences in experimental setup.

2.5.2. Implementation and Metric Calculation Procedure

To improve methodological transparency and support independent reproduction of the evaluation procedure, all quantitative metrics were calculated using a fixed post-generation evaluation pipeline. The proposed framework and all baseline methods were evaluated on the same held-out test subset of 500 indoor images under the inference settings described in Section 2.5.1. For each test case, the input consisted of a content image x c , its corresponding semantic label map M , and a target style-reference image x s . The generated stylized image is denoted by x ^ .
The semantic label map is represented as M { 1 , , C } H × W , where H and W denote the image height and width, respectively, and C is the number of harmonized semantic categories. Let Φ denote the fixed semantic parsing network used in the post-generation evaluation pipeline. In this study, Φ was implemented as a U-Net [32] with a ResNet50 encoder [33] using the segmentation_models_pytorch library (version 0.3.0; Pavel Iakubovskii) [34]. The encoder was initialized with ImageNet-pre-trained weights by setting encoder_name = “resnet50” and encoder_weights = “imagenet”, whereas the U-Net decoder and the C -class segmentation head were initialized by the library and subsequently optimized together with the encoder using the harmonized semantic annotations in the training subset. The segmentation head contained C output channels corresponding to the harmonized semantic categories defined in Section 2.2.
The complete segmentation model—not only its ImageNet-pre-trained encoder—was trained for semantic parsing. The checkpoint achieving the highest validation mIoU of 0.68 across the harmonized semantic categories was retained for evaluation. Validation loss was monitored during training as an auxiliary indicator but was not used as the primary criterion for model selection. No images from the held-out test subset were used for parameter optimization or checkpoint selection.
During metric calculation, all parameters of Φ were frozen, and the same checkpoint was applied to the generated outputs of every evaluated method. Each generated 256 × 256 RGB image was processed to obtain a C -channel pixel-wise logit map. The softmax function was applied across the C semantic categories to obtain the corresponding probability map. The predicted semantic label at pixel p was determined as
M ^ p = a r g m a x c { 1 , , C } Φ x ^ p , c ,
Here, Φ x ^ p , c denotes the predicted probability of semantic category c at pixel p . The input semantic map M and the predicted map M ^ were evaluated at the same 256 × 256 -pixel resolution.
Semantic boundary offset measures the average spatial displacement between the semantic boundaries of the generated image and those of the input scene. Unlike region-level overlap measures, it directly quantifies boundary drift in pixels.
The ground-truth boundary set B and predicted boundary set B ^ were extracted from the corresponding categorical label maps. A pixel was classified as a semantic boundary pixel when at least one pixel in its eight-connected neighborhood had a different semantic label:
B M = p Ω : q N 8 p , M q M p ,
Here, Ω denotes the image domain and N 8 p denotes the eight-connected neighborhood of pixel p . The same procedure was applied to M ^ to obtain B ^ . To account for both displaced and missing boundaries, semantic boundary offset was calculated as the symmetric average distance between the two boundary sets:
L o f f s e t = 1 2 [ 1 | B ^ | p B ^ m i n q B p q 2 + 1 | B | q B m i n p B ^ q p 2 ] ,
In Equation (16), p and q are two-dimensional pixel coordinates and B and | B ^ | denote the numbers of pixels in the respective boundary sets. A lower value indicates smaller boundary displacement and stronger structural preservation.
Semantic region consistency evaluates the region-level agreement between the generated semantic layout and the corresponding input semantic layout. It was calculated as the sample-level macro Intersection over Union across the semantic categories present in either the input or predicted semantic map.
Let M c and M ^ c denote the binary masks of semantic category c in M and M ^ , respectively. The set of valid categories for test sample x is defined as
C x = c : M c M ^ c > 0 ,
Semantic region consistency was then calculated as
L r e g i o n = 1 C x c C x M c M ^ c M c M ^ c + ϵ ,
Here, ϵ is a small constant used to ensure numerical stability. The score ranges from 0 to 1, with a higher value indicating stronger semantic region correspondence and better overall layout preservation.
Semantic boundary consistency provides a tolerance-based measure of the proportion of semantic boundaries reproduced by the generated image. It complements semantic boundary offset: Equation (16) measures average displacement distance, whereas semantic boundary consistency measures whether predicted and ground-truth boundary pixels correspond within an acceptable spatial tolerance.
For a tolerance t , boundary precision P t was defined as the proportion of predicted boundary pixels located within t pixels of a ground-truth boundary:
P t = 1 | B ^ | p B ^ I m i n q B p q 2 t ,
Boundary recall R t was defined as the proportion of ground-truth boundary pixels for which a predicted boundary occurred within the same tolerance:
R t = 1 B q B I m i n p B ^ q p 2 t ,
The semantic boundary consistency score was calculated as the harmonic mean of boundary precision and recall:
L b o u n d a r y t = 2 P t R t P t + R t + ϵ ,
Here, I denotes the indicator function. The tolerance was fixed at t = 3 pixels, corresponding approximately to 0.75% of the diagonal length of a 256 × 256 -pixel image and following established boundary-based semantic-segmentation evaluation practice [35]. The resulting score ranges from 0 to 1, with a higher value indicating stronger semantic boundary alignment.
Geometric misalignment ratio measures the proportion of the input image occupied by semantic components that are substantially displaced, merged, or missing after style transformation. Connected components were extracted separately for each semantic category in the input and predicted label maps.
Let R M denote the set of connected semantic components in M . For an input component r R M , the corresponding predicted component was selected from components with the same semantic label according to maximum IoU:
r ^ * = a r g m a x r ^ R ( M ^ ) , l r ^ = l r I o U r , r ^ ,
Here, l r denotes the semantic category of component r . If no predicted component of the same category existed, the corresponding IoU was set to zero. A component was classified as geometrically misaligned when its maximum matched IoU was below the predefined threshold τ = 0.1 . The geometric misalignment ratio was calculated as
R m i s a l i g n = 1 H W r R M r I [ I o U ( r , r ^ * ) < τ ] ,
Here, r denotes the area of component r in pixels. A lower value indicates that a smaller proportion of the scene exhibits severe geometric distortion.
Let F s denote the fixed style-feature extractor used throughout the evaluation. Specifically, an ImageNet-pre-trained VGG-19 network was employed to extract multi-scale feature maps from layers relu1-1, relu2-1, relu3-1, relu4-1, and relu5-1 [36,37]. For image x , the activation tensor obtained from layer l was reshaped as f l x R C l × H l W l , where C l , H l , and W l denote the number of channels, height, and width of the feature map, respectively. The normalized Gram matrix of layer l was calculated as
G l x = f l x f l x T C l H l W l ,
Each Gram matrix was vectorized and L 2 -normalized before concatenation:
F s x = c o n c a t l L v e c G l x v e c G l x 2 + ϵ ,
where L = { relu 1 _ 1 , relu 2 _ 1 , relu 3 _ 1 , relu 4 _ 1 , relu 5 _ 1 } . The VGG-19 parameters remained fixed throughout metric calculation. This feature representation was applied consistently in calculating style response amplitude, style consistency, style-domain separability, and style diversity.
Style response amplitude quantifies the magnitude of the visual change produced as the style-intensity coefficient s varies. Let x ^ s denote the image generated at intensity s , and let x ^ 0 denote the image generated from the same content–style pair with the style-intensity coefficient set to zero. The relative style-feature displacement was calculated as
d s t y l e s = F s x ^ s F s x ^ 0 2 F s x ^ 0 2 + ϵ ,
A bounded style response amplitude was then obtained as
A s t y l e s = d s t y l e s 1 + d s t y l e s ,
The score lies in the interval [ 0 , 1 ) . A higher value indicates that changing the style-intensity coefficient produces a stronger response in the extracted style-feature representation. This metric measures responsiveness rather than style correctness and was therefore interpreted together with style consistency and structure-preservation measures.
Style consistency measures the similarity between the style features of a generated image and the reference feature distribution of its target style category. For style category k , the reference centroid was calculated as
μ k = 1 N k r e f r = 1 N k r e f F s x k , r r e f ,
Here, N k r e f is the number of reference images belonging to target style category k , and x k , r r e f denotes its r -th reference image.
For a generated test image x ^ k , i conditioned on target style category k , the per-sample style consistency score was calculated as
l s t y l e _ c o n s , i k = 1 2 1 + F s x ^ k , i μ k F s x ^ k , i 2 μ k 2 + ϵ ,
Here, l s t y l e _ c o n s , i k denotes the style consistency of generated sample i in target style category k . The transformation 1 + c o s   θ / 2 maps cosine similarity from 1 , 1 to 0 , 1 . A higher value indicates stronger correspondence between the generated image and the reference feature distribution of its target style category.
The category-level style consistency score was subsequently calculated as
L s t y l e _ c o n s k = 1 N k i = 1 N k l s t y l e _ c o n s , i k ,
Here, N k is the number of generated test samples conditioned on target style category k . When an overall style consistency result was required, the four category-level scores were macro-averaged so that each target style category contributed equally. The per-sample scores defined in Equation (27a) were retained for the calculation of standard deviations, confidence intervals, and paired statistical comparisons.
Style-domain separability evaluates the discriminability of generated samples belonging to different target style domains in the predefined style-feature space. It is measured as the average pairwise Euclidean distance between the feature centroids of different style domains, reflecting the extent to which the generated style domains form distinguishable clusters in the style-feature representation.
For style domain i , its generated-feature centroid is defined as
μ i = 1 N i n = 1 N i F s x ^ i , n ,
where N i is the number of generated samples assigned to style domain i , F s is the fixed VGG-19-based style-feature representation defined in Equation (23), and K is the total number of target style domains. Style-domain separability is calculated as
D s e p = 1 K K 1 i = 1 K j = 1 K μ i μ j 2 , j i            
A higher D s e p value indicates a greater average distance between the generated style-domain centroids and, consequently, stronger separability among the target style domains. This metric evaluates between-domain separation and should be interpreted together with the style consistency and style diversity scores.
Style diversity measures the intra-domain variation among generated images belonging to the same style category. It was calculated from the normalized pairwise distance between style-feature representations:
D d i v k = 2 N k N k 1 i < j F s x ^ k , i F s x ^ k , j 2 F s x ^ k , i 2 + F s x ^ k , j 2 + ϵ ,
Here, N k is the number of generated images in style category k . The overall diversity score was obtained by averaging D d i v k across the K target style categories. A higher value indicates greater intra-domain variation, whereas a very low value may indicate that the generator produces excessively similar outputs within the same style category.
Edge sharpness measures the average local gradient magnitude of the generated image. Each generated RGB image was first converted to grayscale luminance using Y = 0.299 R + 0.587 G + 0.114 B , with luminance values retained on the 0–255 scale. Horizontal and vertical gradients, G x and G y , were calculated using the 3 × 3 Sobel operator, and the gradient magnitude at pixel p was defined as
G p = G x p 2 + G y p 2 ,
The edge-sharpness score was calculated as
S e d g e = 1 H W p Ω G p ,
A higher value indicates greater average edge strength and contour definition. Because gradient magnitude may also increase in the presence of noise or high-frequency artifacts, this measure was interpreted jointly with LPIPS, semantic boundary measures, and qualitative outputs rather than as an independent measure of perceptual quality.
Texture-pattern detail score measures the relative high-frequency content of the generated image. The luminance image Y x ^ was processed using a discrete 3 × 3 Laplacian operator. The raw high-frequency response was calculated as
T x ^ = 1 H W p Ω Δ Y x ^ p ,
where Δ denotes the discrete Laplacian operator. To obtain a comparable score between 0 and 1, the raw response was normalized using the minimum and maximum responses observed across all outputs included in the fixed evaluation protocol:
D t e x t u r e = T x ^ T m i n T m a x T m i n + ϵ ,
Here, T m i n and T m a x were fixed after applying the same calculation to the generated outputs of all evaluated methods. A higher value indicates stronger high-frequency texture-pattern representation. As with edge sharpness, this score was not interpreted independently as evidence of image quality because noise and high-frequency artifacts may also increase the response.
Learned Perceptual Image Patch Similarity (LPIPS) was used to measure the perceptual distance between each generated stylized image and its corresponding original content image [31]. The official LPIPS implementation with an AlexNet backbone and learned linear calibration layers (net = ‘alex’) was used consistently for all evaluated methods. Before feature extraction, the generated and content images were converted to RGB, resized to 256 × 256 pixels, and normalized to the input range required by the official implementation. For the fixed test subset of N content–generation pairs, the mean LPIPS score was calculated as
L L P I P S = 1 N i = 1 N d L P I P S A l e x x ^ i , x c , i ,
Here, d L P I P S A l e x , denotes the learned perceptual distance computed using the AlexNet-based LPIPS feature extractor. A lower value indicates that the generated image maintains greater perceptual correspondence with the original content image. LPIPS was therefore interpreted as a measure of perceptual content preservation rather than as a direct measure of target-style similarity.
Sample-level metrics, including semantic boundary offset, semantic region consistency, semantic boundary consistency, geometric misalignment ratio, per-sample style consistency, edge sharpness, texture-pattern detail score, and LPIPS, were first calculated separately for each test case. Dataset-level values were subsequently summarized as the arithmetic mean and standard deviation across the fixed test subset. Style response amplitude was calculated separately for each content–style pair at each tested style-intensity coefficient and then summarized across the corresponding test pairs. For style-category-specific sample-level metrics, values were first summarized within each style category and then macro-averaged across the four categories to prevent disproportionate influence from any single style domain. Style diversity was calculated separately within each style domain and then averaged across the four domains, whereas style-domain separability was calculated from the feature centroids of all four generated style domains.
Because the same content–style test pairs were evaluated across the compared methods, statistical comparisons were based on paired observations. For evaluation settings involving more than two paired methods or model variants, overall differences were examined using the Friedman test. When an omnibus difference was detected, the proposed or complete framework was compared with the strongest corresponding comparator using the Wilcoxon signed-rank test [38], with Holm correction [39] applied within each family of pairwise comparisons to control the family-wise error rate. Two-model comparisons were evaluated directly using paired Wilcoxon signed-rank tests. For metrics evaluated at multiple style-intensity settings, sample-level values were averaged across the tested settings before inferential comparison. Statistical significance was evaluated at α = 0.05 . Kendall’s W was used as the omnibus effect-size measure, and matched rank-biserial correlation was reported for paired comparisons. In addition, 95% confidence intervals for the mean paired improvements were estimated by paired bootstrap resampling of the test cases. These bootstrap confidence intervals were not adjusted for multiple comparisons, whereas the reported Wilcoxon p-values were adjusted using the Holm procedure.
The unified calculation procedure ensured that all evaluated methods were compared using identical semantic parsing, style-feature extraction, image preprocessing, metric definitions, and statistical aggregation rules. Consequently, differences in the reported results reflect differences in model outputs under the standardized evaluation protocol rather than differences in metric implementation.


2.6. Computational Feasibility Evaluation

To assess the computational feasibility of the proposed framework, all evaluated methods were tested under a unified hardware and software environment. The experiments were conducted on a workstation equipped with a single NVIDIA GeForce RTX 3090 GPU with 24 GB of memory (NVIDIA Corporation, Santa Clara, CA, USA), an Intel Core i9-12900K CPU (Intel Corporation, Santa Clara, CA, USA), and 64 GB of system RAM. The models were implemented and evaluated using Python 3.9, PyTorch (version 1.13.1; PyTorch Foundation), CUDA (version 11.7; NVIDIA Corporation, Santa Clara, CA, USA), and cuDNN (version 8.5; NVIDIA Corporation, Santa Clara, CA, USA). All computational feasibility tests were conducted at an input resolution of 256 × 256 pixels with a batch size of 1, corresponding to the single-image inference setting used in the evaluation protocol.
The computational feasibility assessment focused on three aspects: inference latency, model complexity, and resource utilization. Inference latency was measured as the average forward-pass time required to generate one stylized image from the 500-image test subset. Before measurement, each model was executed for 50 warm-up iterations to reduce initialization-related timing instability. The reported latency was then averaged over three repeated runs. GPU synchronization was applied before and after each forward pass to ensure accurate timing. Data loading, disk reading, image saving, visualization, offline semantic-map preparation, post-generation semantic parsing, and metric calculation were excluded from the latency measurement. Therefore, the reported inference time reflects the image-generation forward pass under the fixed testing condition rather than the full end-to-end time required by a complete application pipeline.
Model complexity was characterized using the number of trainable parameters, estimated floating-point operations (FLOPs), and model size under single-precision weights. The number of trainable parameters was calculated by summing the numbers of scalar elements in all model tensors for which gradient computation was enabled. FLOPs were estimated for a single image-generation forward pass using representative model inputs at a resolution of 256 × 256 pixels and a batch size of 1. The same operation-counting procedure was applied to all evaluated methods and included the convolutional and fully connected operations executed during image generation. Data loading, image preprocessing, semantic-map preparation, post-generation semantic parsing, metric calculation, and image saving were excluded from the FLOP estimates. Model size was calculated from the storage required by the trainable model parameters under 32-bit floating-point representation. Peak GPU memory was measured during the same forward-pass setting after resetting the allocated-memory statistics for each model.
All baseline methods and the proposed framework were evaluated under the same hardware environment, input resolution, batch setting, and preprocessing protocol to ensure comparability. Trainable models and experimental variants were loaded in evaluation mode, and gradient computation was disabled during inference. For style-transfer baselines and semantic-guided baselines with different input requirements, the timing boundary was kept consistent by measuring only the model forward computation required for image generation. The same principle was applied to the proposed framework, whose semantic masks, boundary maps, and style references were treated as prepared inputs during inference measurement.
The computational feasibility metrics were used to contextualize the experimental cost of each generation strategy under a controlled and comparable evaluation setting. These indicators complement the structure-preservation, style-controllability, perceptual-quality, and subjective-evaluation measures by showing the computational resources required to achieve the reported generation performance. They also provide a reproducible basis for comparing the implementation efficiency of different methods within the standardized 256 × 256 image-generation workflow.

3. Results

3.1. Structure Preservation and Perceptual Quality

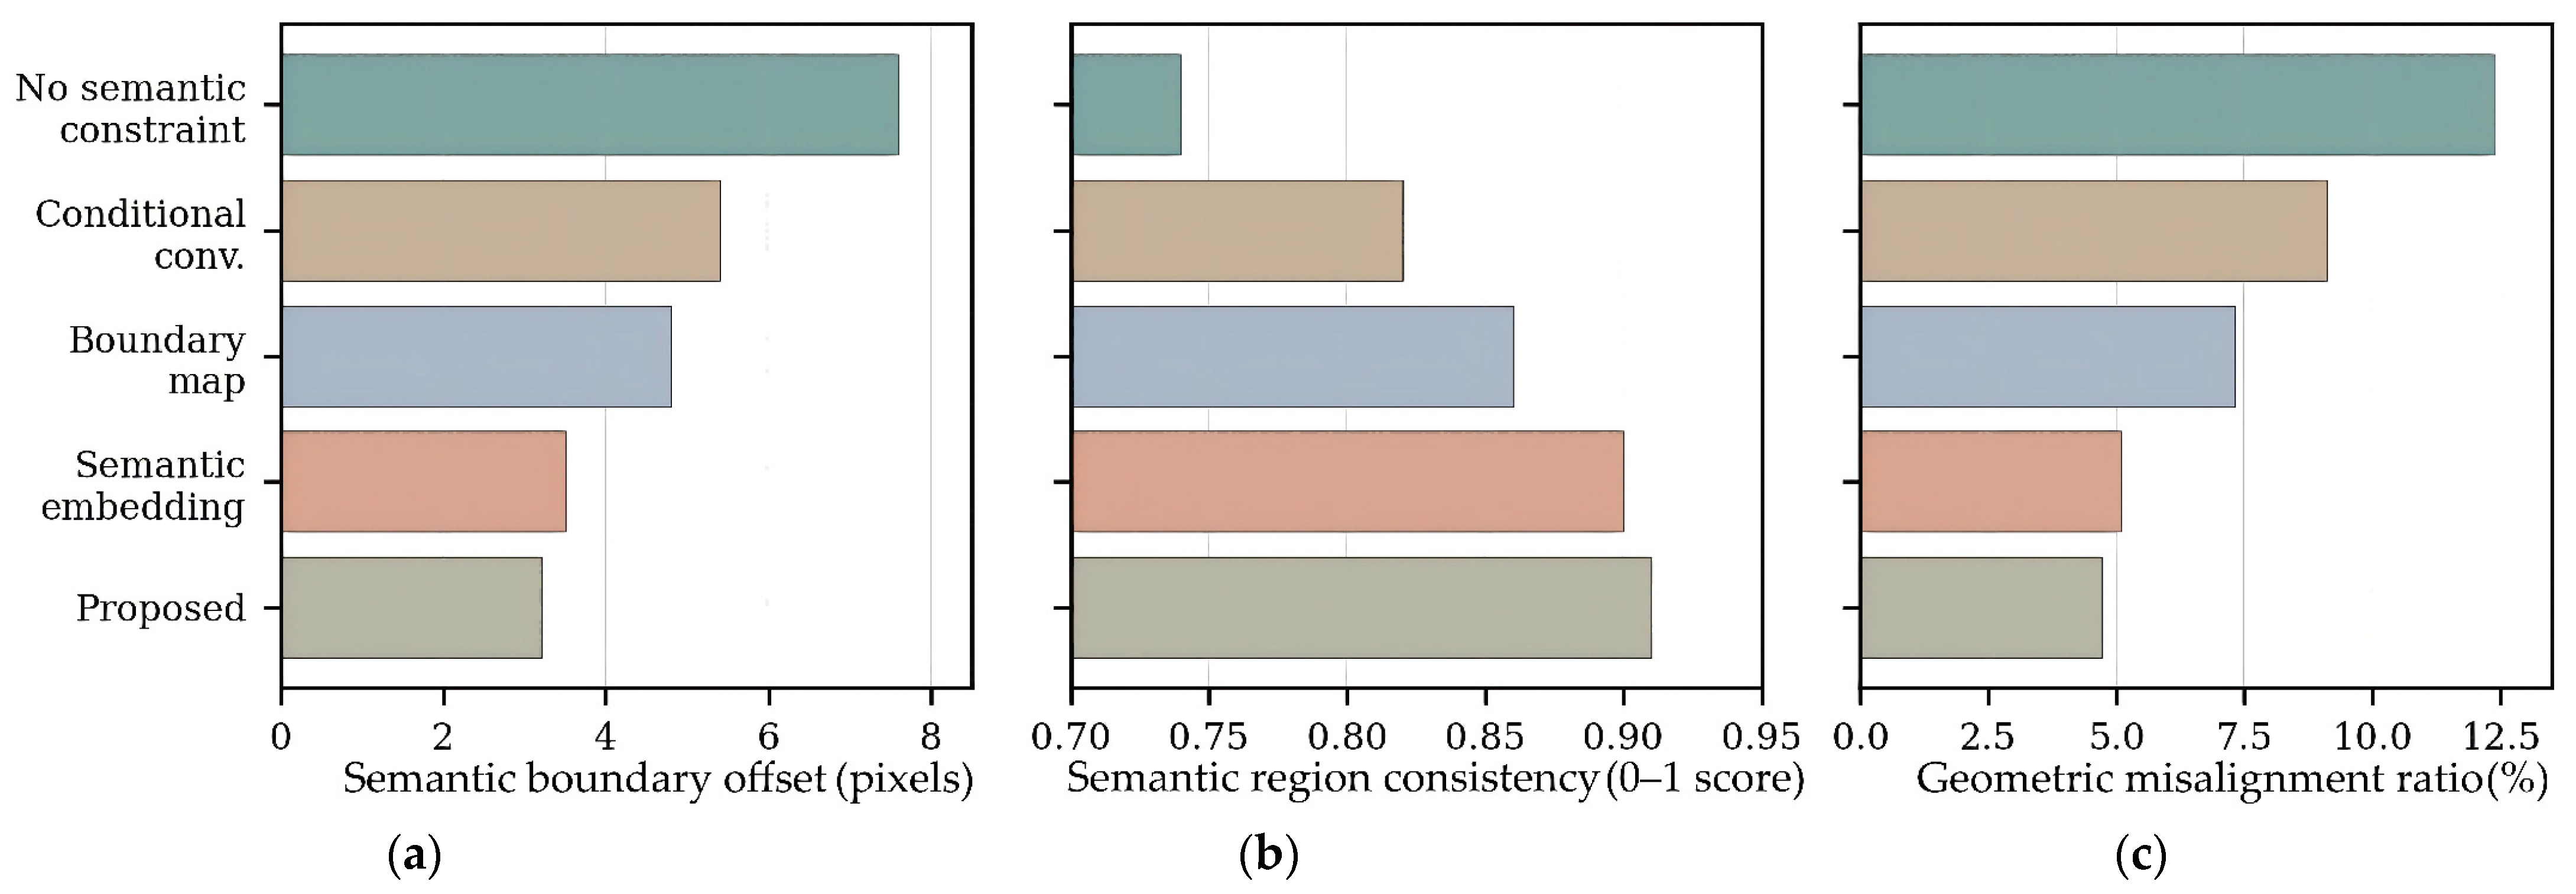
The evaluation first focused on whether the proposed framework could preserve the spatial organization of interior scenes while improving perceptual quality during style transformation. Because interior style generation requires both structural stability and visual plausibility, this section reports quantitative evidence from structure-preservation and perceptual-quality metrics. To assess structural preservation, five internal model variants used for ablation analysis were compared: a baseline model without semantic constraints, a weakly semantic version using conditional convolution, a boundary-map version, a semantic-embedding version, and the complete proposed framework. This ablation setting was used to examine the incremental contribution of different semantic-prior components, rather than to replace the baseline-model comparison described in Section 2.5.1. The comparison was conducted using three structure-related metrics: semantic boundary offset, semantic region consistency, and geometric misalignment ratio. A lower boundary offset measured in pixels and a lower misalignment ratio measured as a percentage indicate stronger geometric preservation, whereas a higher semantic region consistency score indicates better alignment between the generated image and the input semantic structure.
As shown in Figure 3a, the model without semantic constraints produced the largest semantic boundary offset, reaching 7.6 pixels. Introducing conditional convolution reduced the offset to 5.4 pixels, while adding boundary-map information further reduced it to 4.8 pixels. The semantic-embedding version achieved a boundary offset of 3.5 pixels, and the complete proposed framework achieved the lowest value of 3.2 pixels. Compared with the unconstrained baseline, this corresponds to a reduction of approximately 57.9%. This result indicates that semantic information is more effective when represented through a combination of region masks, boundary maps, and semantic embeddings rather than through a single conditioning signal.
Figure 3b shows that semantic region consistency increased from 0.74 in the unconstrained model to 0.91 in the proposed framework. This improvement suggests that multi-source semantic priors help the generator maintain stronger correspondence with the input semantic regions during style transformation. Figure 3c presents a similar trend for geometric misalignment. The misalignment ratio decreased from 12.4% in the unconstrained model to 4.7% in the proposed framework. The consistent improvement across boundary offset, region consistency, and misalignment ratio shows that semantic-conditional injection improves structural stability at both boundary and region levels.
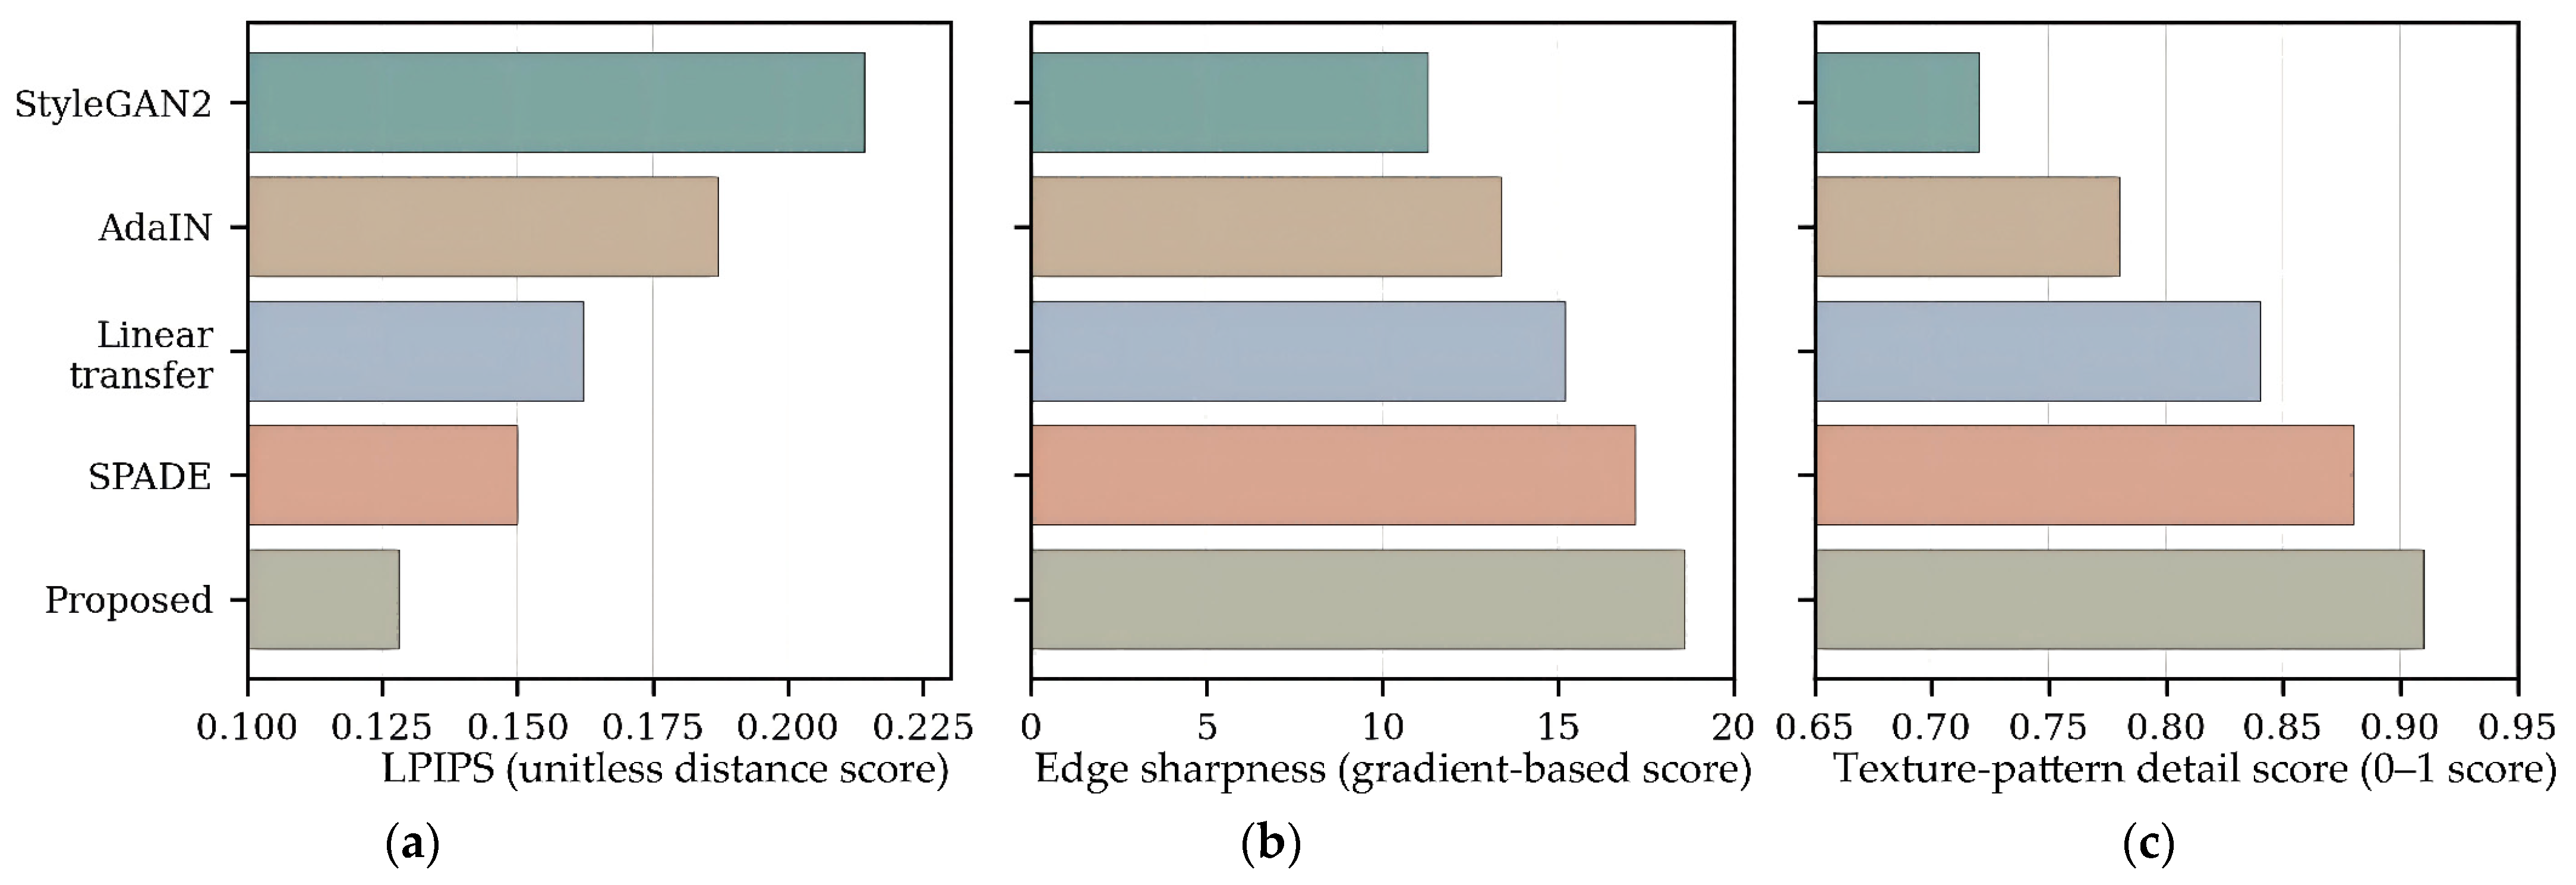
The second part of the evaluation examined perceptual quality and detail representation across the main baseline models. As shown in Figure 4a, the proposed framework achieved the lowest LPIPS value, with a score of 0.128. In comparison, StyleGAN2, AdaIN, linear style transfer, and SPADE obtained LPIPS scores of 0.214, 0.187, 0.162, and 0.150, respectively. Under the same evaluation protocol, a lower LPIPS value indicates a smaller learned perceptual distance between the generated stylized image and its corresponding original content image. The lower score of the proposed framework suggests that the combination of semantic constraints and controllable style modulation improves perceptual coherence during interior style generation.
Figure 4b presents the edge sharpness results. The proposed method achieved an edge sharpness value of 18.6, outperforming the baseline models. This improvement is consistent with the boundary-map injection mechanism described in Section 2.3, which strengthens local contour information at high-resolution generator layers. In particular, edge-sensitive semantic priors help preserve furniture contours, window frames, table boundaries, and wall–floor intersections, where texture-pattern leakage or boundary blurring commonly occurs in semantically weak style-transfer models.
As shown in Figure 4c, the proposed framework also achieved the highest texture-pattern detail score, reaching 0.91. This result indicates that semantic constraints do not necessarily suppress stylistic texture-pattern expression. Instead, when semantic priors are combined with controllable style modulation, the generator can preserve structural boundaries while maintaining rich image-level local details. Overall, the results in Figure 4 show that the proposed framework improves perceptual quality, edge clarity, and texture-pattern representation compared with the baseline methods.

3.2. Style Controllability and Structure–Style Trade-Off

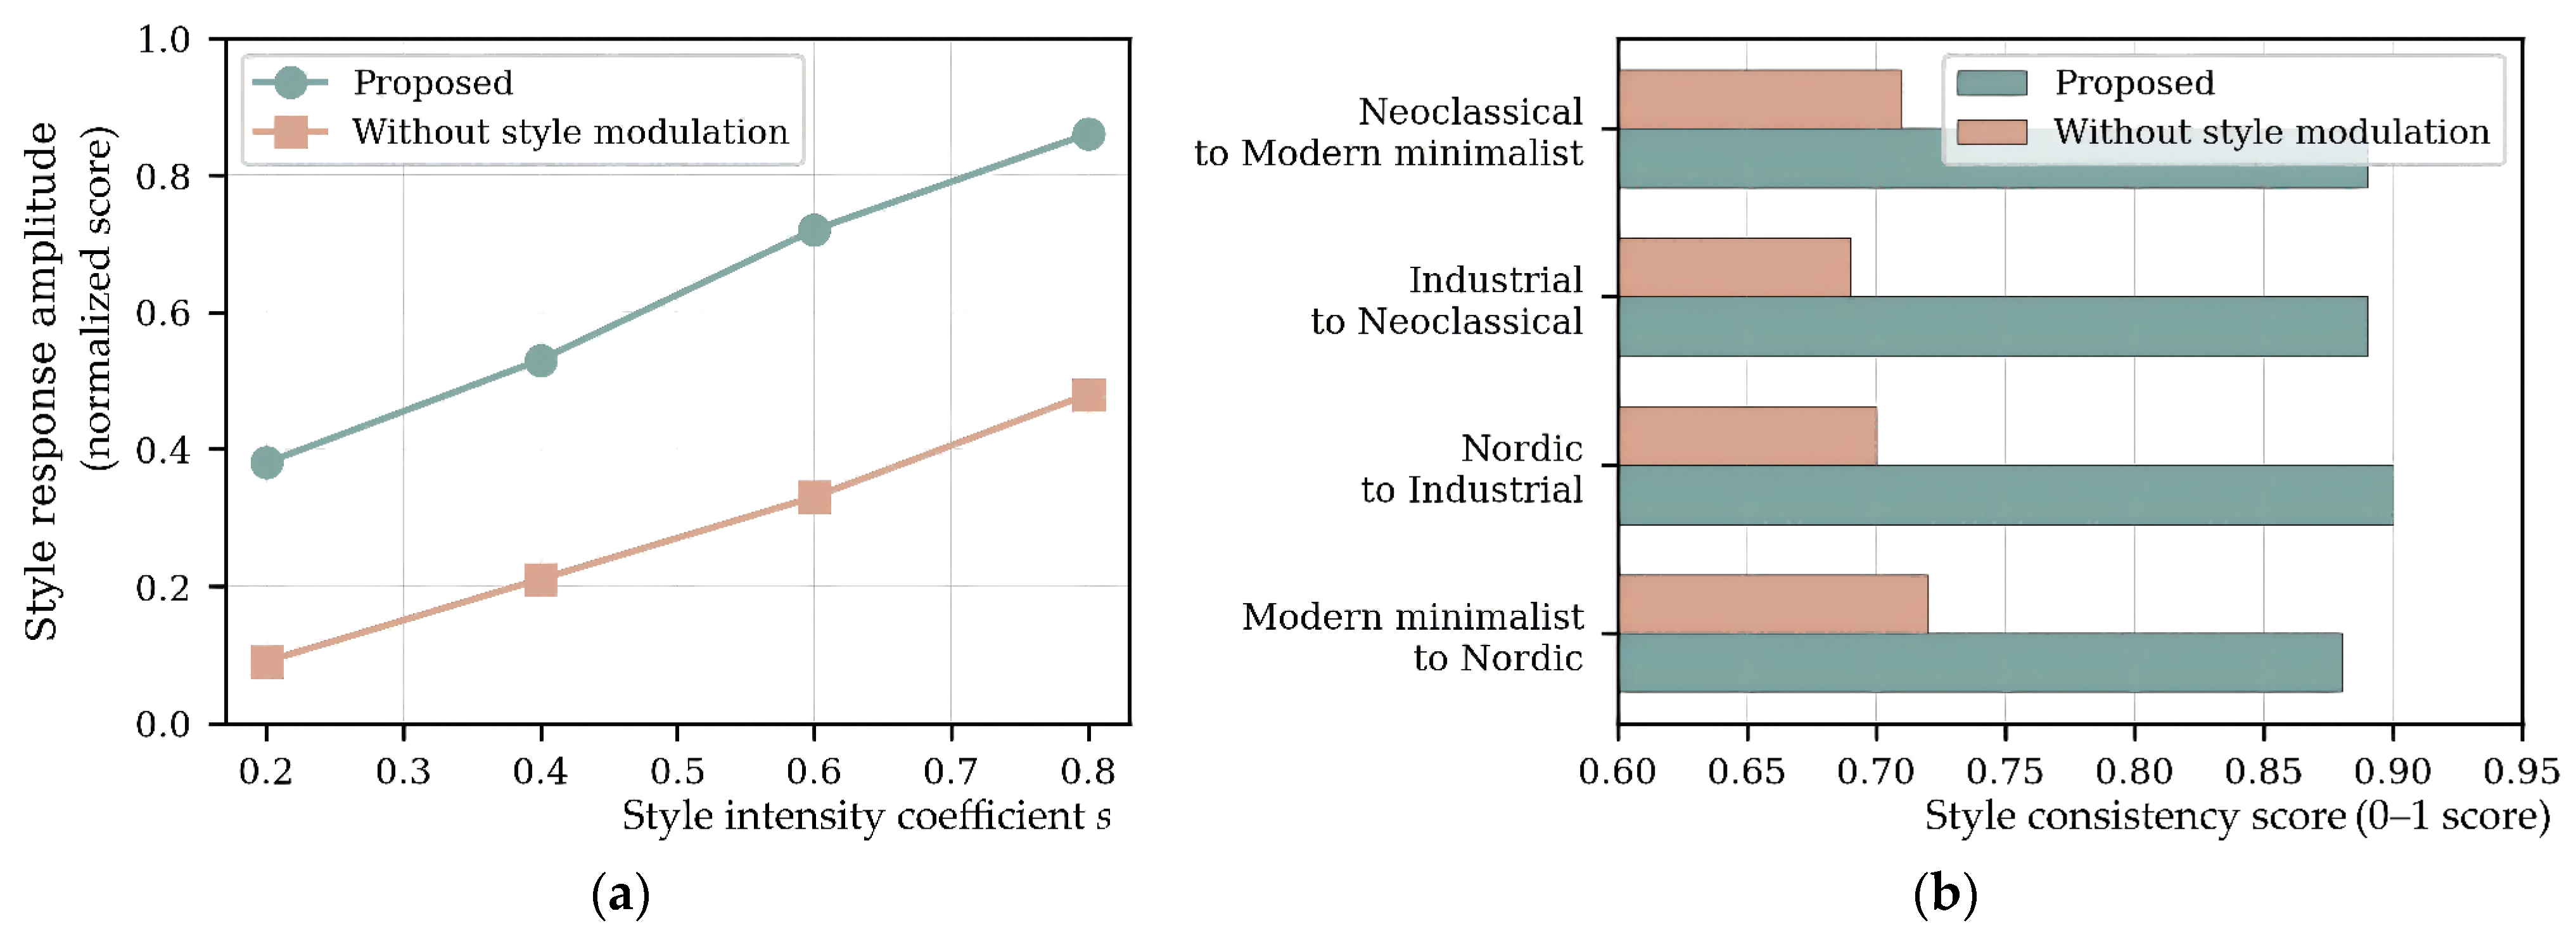
Style controllability was evaluated by adjusting the style intensity coefficient (s) and measuring the response amplitude of the generated images. As shown in Figure 5a, the proposed framework produced a continuous increase in style response from 0.38 at (s = 0.2) to 0.86 at (s = 0.8). The response curve was approximately monotonic, indicating that the style intensity coefficient provides a predictable control signal for regulating image-level visual style expression. In contrast, the model without style modulation produced a weaker response, increasing only from 0.09 to 0.48 within the same intensity range. This difference suggests that explicit style encoding and modulation are necessary for achieving controllable multi-style generation.
Figure 5b compares style consistency under cross-style transformation. The proposed framework achieved style consistency scores of 0.88, 0.90, 0.89, and 0.89 across the tested style transformations, whereas the model without style modulation remained within the range of 0.69–0.72. The higher consistency scores indicate that the style encoding module provides a more stable representation of image-level style-domain characteristics and reduces style drift during cross-domain generation. This is particularly important for interior scenes because different design styles are not defined only by color palettes, but also by texture-pattern distribution, material-like surface appearance, furniture form, and illumination-related visual cues.
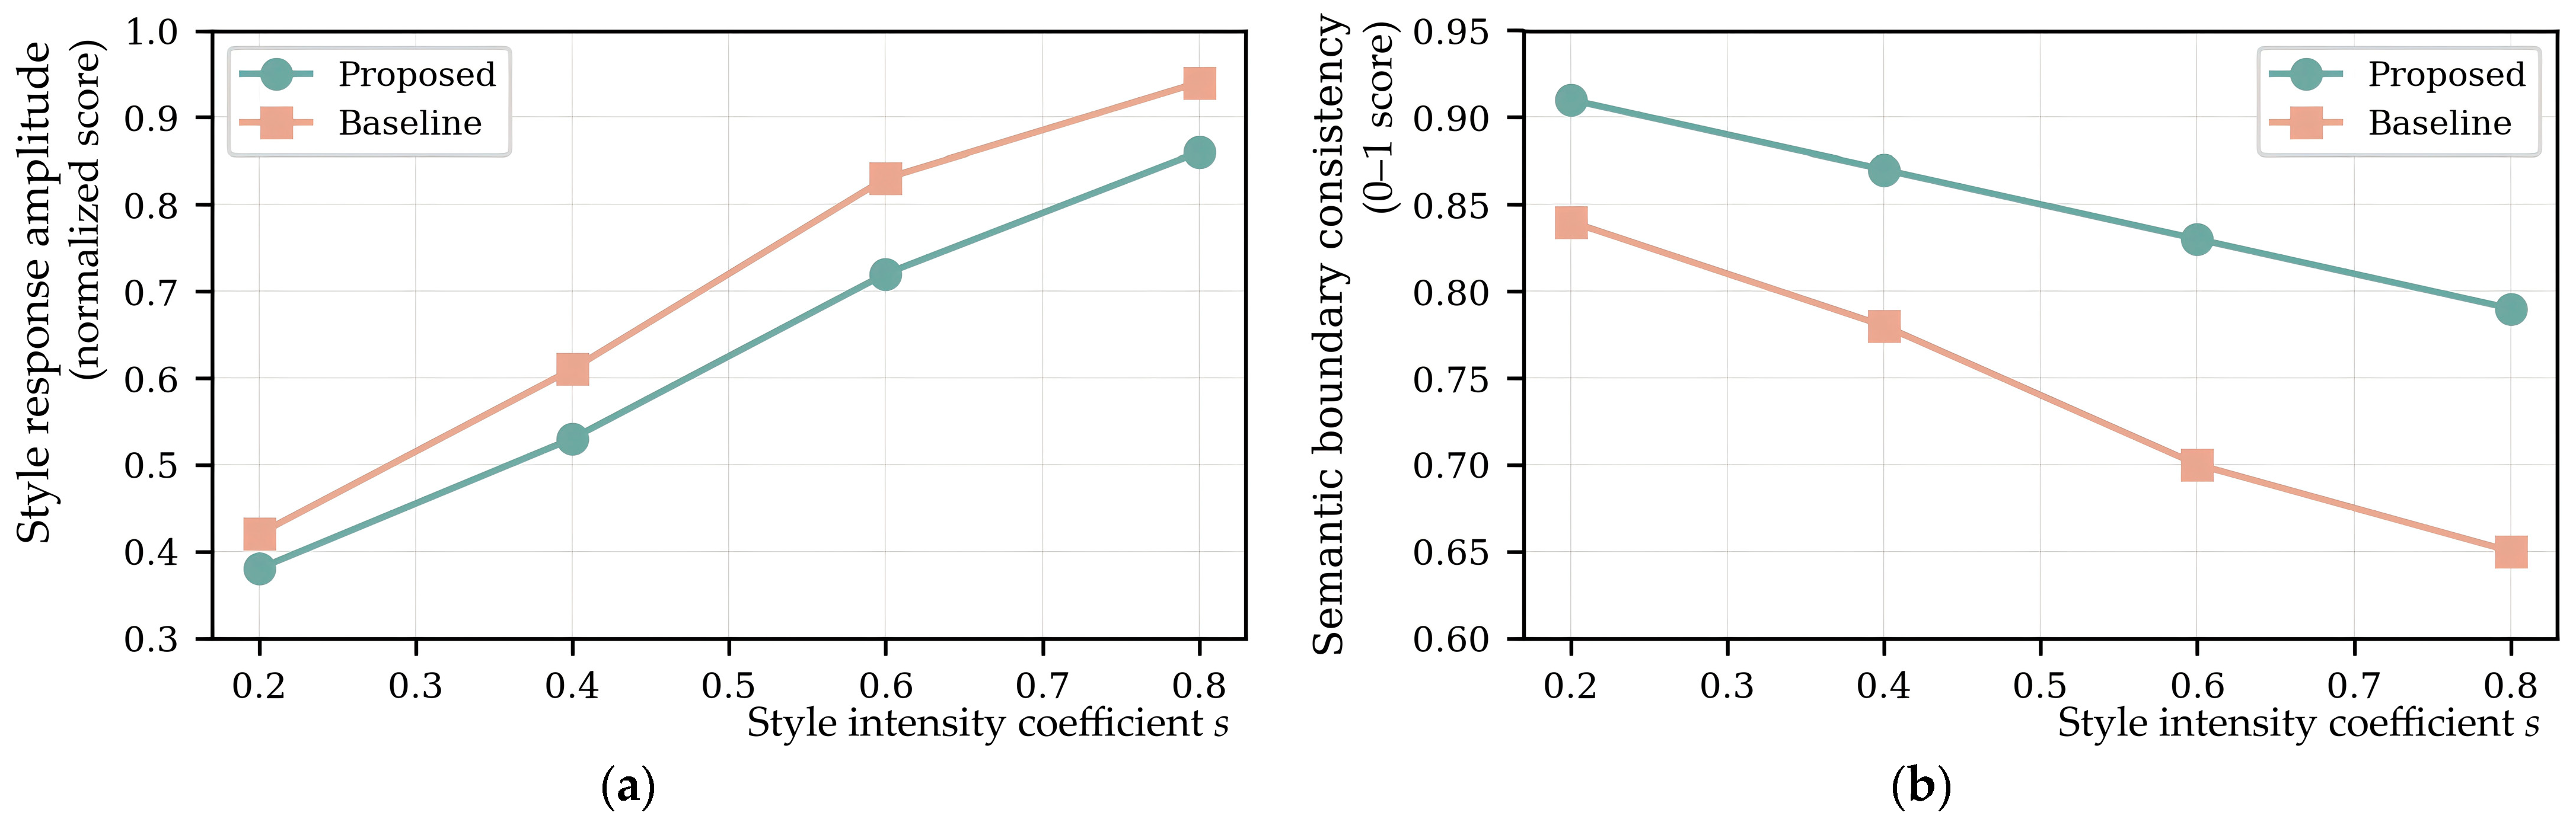
The relationship between style expression and structure preservation was further examined by increasing the style-intensity coefficient. As shown in Figure 6a, both the proposed framework and the semantically unconstrained baseline exhibited increasing style response amplitude as s increased. This trend indicates that stronger style vectors produce more pronounced changes in texture patterns, color tones, and image-level visual appearance. However, Figure 6b shows that the corresponding reduction in semantic boundary consistency was substantially slower in the proposed framework.
The first numerical reduction in semantic boundary consistency among the tested intensity settings occurred when s increased from 0.2 to 0.4. Over this interval, the score of the proposed framework decreased from 0.91 to 0.87, whereas that of the semantically unconstrained baseline decreased from 0.84 to 0.78. At s = 0.6, the corresponding scores were 0.83 and 0.70, respectively. The proposed framework remained above 0.80 through s = 0.6 and fell slightly below this level only at s = 0.8, reaching 0.79. In contrast, the semantically unconstrained baseline had already fallen below 0.80 at s = 0.4 and declined further to 0.65 at s = 0.8. Thus, within the tested intensity range, the first numerical reduction in semantic boundary consistency was observed at s = 0.4 for both models, but the deterioration was more gradual in the proposed framework.
The structure–style trade-off is central to interior style generation. If a model prioritizes style expression without sufficient structural constraints, it may produce visually expressive but spatially unreliable results. Conversely, if a model prioritizes semantic preservation too rigidly, it may generate structurally stable but stylistically weak images. The proposed framework operates between these two extremes by allowing style intensity to increase while maintaining a higher level of semantic boundary consistency than the baseline. The results in Figure 6 therefore suggest that multi-scale semantic-conditional injection improves the balance between stylistic flexibility and structural stability under the tested intensity settings.
To determine whether the quantitative differences observed in Figure 3, Figure 4, Figure 5 and Figure 6 were consistent across the fixed test subset, inferential statistical analyses were conducted using the paired evaluation protocol described in Section 2.5.2. Friedman tests were applied to the multi-model comparisons in Figure 3 and Figure 4. The proposed or complete framework was then compared with the strongest corresponding model variant or external baseline using Wilcoxon signed-rank tests [38] with Holm correction [39]. The two-model comparisons in Figure 5 and Figure 6 were evaluated directly using paired Wilcoxon signed-rank tests. Table 8 summarizes the omnibus comparisons, whereas Table 9 reports the subsequent targeted pairwise comparisons.
As shown in Table 8, the Friedman tests identified statistically detectable overall differences among the five internal model variants and among the five external methods for all six evaluated metrics (all p ≤ 0.0031). However, the corresponding Kendall’s W values ranged from 0.0080 to 0.0096, indicating small omnibus effect sizes across the full sets of compared methods. The statistical significance of the omnibus results should therefore be interpreted together with the subsequent targeted pairwise comparisons.
As shown in Table 9, the complete framework achieved favorable mean values relative to the semantic-embedding variant for semantic boundary offset, semantic region consistency, and geometric misalignment ratio. Although the unadjusted bootstrap confidence intervals for the mean paired improvements excluded zero, these comparisons did not remain statistically significant after Holm correction (all adjusted p = 0.054). The corresponding matched rank-biserial correlations indicated small pairwise effects (rᵣᵦ = 0.086–0.088). These differences are therefore interpreted as descriptive improvements relative to the strongest internal variant rather than as statistically significant pairwise effects.
In the external-method comparison, the proposed framework outperformed SPADE in LPIPS, edge sharpness, and texture-pattern detail score. All three comparisons remained statistically significant after Holm correction (all adjusted p < 0.001), with matched rank-biserial correlations ranging from 0.68 to 0.74. These results indicate substantial pairwise effects in favor of the proposed framework, and the corresponding bootstrap confidence intervals were entirely favorable to the proposed framework.
The two-model comparisons associated with Figure 5 and Figure 6 showed the same directional pattern. Relative to the model without style modulation, the complete framework achieved higher style response amplitude and style consistency, with adjusted p-values below 0.001 and matched rank-biserial correlations of 0.85 and 0.82, respectively. The proposed framework also maintained higher semantic boundary consistency than the baseline across the tested style-intensity settings (adjusted p < 0.001, rᵣᵦ = 0.78). These results provide paired statistical support for the contribution of explicit style modulation and semantic conditioning to controllable style expression and structural stability under the tested conditions.

3.3. Ablation Analysis of Style Modulation

An ablation analysis was conducted to evaluate the contribution of the style modulation mechanism to style-domain differentiation and intra-domain variation. The full model was compared with an ablated variant that retained the semantic priors but removed explicit style modulation. This comparison was designed to determine whether semantic conditioning alone was sufficient to maintain distinguishable and diverse representations of the four target style domains—modern minimalist, Nordic, industrial, and neoclassical—or whether dedicated style encoding and modulation were also required.
Two indicators were used: style-domain separability and style diversity. Style-domain separability was measured as the average Euclidean distance among the generated feature centroids of the four target style domains in the fixed VGG-19-based style-feature space. Because it summarizes the pairwise distances among all four domain centroids, one overall D s e p value was obtained for each model configuration. Style diversity was calculated separately within each target style domain to quantify the variation among generated samples belonging to that domain. Higher values indicate greater domain separation and stronger intra-domain variation, respectively.
As shown in Figure 7a, the full model achieved an overall style-domain separability value of 1.48, compared with 0.92 for the model without style modulation. This represents an increase of approximately 60.9%, indicating that explicit style modulation helped the generator maintain clearer distinctions among the four target style domains in the predefined style-feature space. In contrast, when style modulation was removed, the generated domain centroids were positioned more closely together, suggesting weaker differentiation among the target styles.
Figure 7b shows a consistent pattern for style diversity. The full model achieved diversity scores of 0.84, 0.82, 0.81, and 0.83 for the modern minimalist, Nordic, industrial, and neoclassical domains, respectively. The corresponding scores for the model without style modulation were 0.57, 0.56, 0.58, and 0.57. When macro-averaged across the four domains, the diversity score decreased from 0.825 for the full model to 0.570 for the ablated model. The relatively consistent difference across all four target style domains indicates that the effect was not restricted to a single style category.
The ablation results indicate that semantic conditioning and style modulation perform complementary functions within the proposed framework. Semantic priors provide spatial and structural constraints, whereas the style modulation mechanism supports differentiation among target style domains and variation within each domain. Retaining semantic priors while removing style modulation substantially reduced both style-domain separability and style diversity. Under the tested configuration, semantic conditioning alone was therefore insufficient to reproduce the same level of controllable multi-style representation achieved by the full model.

3.4. Subjective Evaluation

Objective metrics characterize semantic structure preservation, style controllability, and perceptual quality from computational perspectives, whereas the perceived quality of interior style generation also depends on human visual judgment. A subjective evaluation was therefore conducted to examine whether the performance patterns identified by the objective metrics were also reflected in participants’ assessments of the generated images. As described in Section 2.5.1, 20 participants evaluated paired outputs from the proposed framework and the control model without semantic constraints under identical content, semantic-layout, and style-reference conditions. The evaluation considered three dimensions: realism, style expression, and structural consistency. The results presented in this section are descriptive comparisons based on the mean normalized participant ratings.
As shown in Figure 8, the proposed framework received higher mean ratings than the control model across all three dimensions. The mean realism rating increased from 0.72 for the control model to 0.87 for the proposed framework, corresponding to an absolute difference of 0.15. The mean style-expression rating increased from 0.68 to 0.84, corresponding to a difference of 0.16. The largest difference was observed for structural consistency, for which the mean rating increased from 0.74 to 0.91, corresponding to an absolute improvement of 0.17. The relatively consistent differences across the three dimensions indicate that the proposed framework was perceived more favorably in terms of visual plausibility, target-style expression, and preservation of spatial and object-level coherence under the controlled evaluation conditions.
The subjective rating pattern is consistent with the objective findings reported in Section 3.1 and Section 3.2. In particular, the higher structural-consistency rating corresponds directionally with the lower semantic boundary offset, higher semantic region consistency, and more stable semantic boundary consistency achieved by the proposed framework. Similarly, the higher style-expression rating is consistent with the stronger style response and style consistency reported in the quantitative evaluation. These correspondences do not imply that the subjective dimensions are direct perceptual equivalents of the computational metrics; rather, they show that the objective and participant-based evaluations produced convergent performance patterns under the same generation conditions.
The subjective evaluation should be interpreted as complementary evidence rather than as an independent statistical validation or a replacement for the objective metrics. The participant group was limited to 20 individuals, and the evaluation was conducted using controlled paired comparisons drawn from the held-out test subset. The results therefore characterize perceived quality within the present experimental setting and should not be generalized to all users, interior styles, or application contexts. Within these boundaries, the subjective ratings provide additional perceptual support for the structural, stylistic, and visual-quality advantages observed in the quantitative evaluation.

3.5. Computational Feasibility Analysis

To examine the computational feasibility of the proposed framework, the computational performance of the proposed model and baseline methods was assessed using the protocol described in Section 2.6. Table 10 reports the number of trainable parameters, estimated floating-point operations, model size, inference latency, and peak GPU memory consumption for each method under the same hardware environment, input resolution, batch size, and preprocessing protocol.
As shown in Table 10, AdaIN and linear style transfer required the lowest computational cost among the compared methods. This result is expected because these methods mainly rely on feature-statistics alignment or linear feature transformation and do not include explicit multi-scale semantic conditioning. StyleGAN2 showed moderate computational demand, but its role in this study was primarily that of a semantically unconstrained generative reference rather than a content-aligned style-transfer baseline. In contrast, SPADE required the largest number of parameters, the highest estimated FLOPs, the longest inference latency, and the highest peak GPU memory consumption, reflecting the computational cost of spatially adaptive semantic modulation.
The proposed framework introduced additional computational cost compared with lightweight style-transfer baselines such as AdaIN and linear style transfer. This overhead is consistent with the architectural design of the proposed method, which integrates multi-scale semantic injection, boundary-enhanced conditioning, semantic embeddings, and controllable style modulation. However, compared with SPADE, the proposed framework required fewer parameters, lower estimated FLOPs, shorter inference latency, and lower peak GPU memory consumption. Specifically, the proposed framework reduced the parameter count by approximately 35.5%, FLOPs by approximately 19.4%, inference latency by approximately 15.9%, and peak GPU memory consumption by approximately 18.0% relative to SPADE under the same experimental setting.
These results indicate that the proposed framework is not a lightweight style-transfer model in the same sense as AdaIN or linear style transfer. Rather, it represents a structure-aware generative framework with additional semantic-conditioning cost. Nevertheless, the comparison suggests that the proposed method achieves this enhanced semantic control with a lower computational burden than SPADE. When considered together with the structure-preservation, style-controllability, perceptual-quality, and subjective-evaluation results reported in the preceding sections, the computational feasibility analysis supports the view that the proposed semantic-conditioning strategy provides a practical balance between controllable interior style generation and experimental deployment cost.
The feasibility metrics reported here characterize computational behavior under a controlled 256 × 256 experimental setting and provide reproducible reference points for comparing the evaluated methods. Computational cost was evaluated only at this standardized resolution. Because inference latency and memory consumption at higher resolutions depend on model implementation, feature-map scaling, and hardware utilization, the present results should not be extrapolated directly to higher-resolution settings. Systematic benchmarking at 512 × 512 and higher resolutions will therefore be considered in future work.

4. Discussion

4.1. Role of Semantic-Conditional Injection in Structure Preservation

The results highlight the importance of semantic-conditional injection in structure-preserving interior style generation. The improvement observed in Figure 3 is not merely a result of adding semantic maps to the input. More importantly, it is related to how semantic information is represented and where it is introduced into the generator. Semantic masks provide region-level layout constraints, boundary maps emphasize local geometric edges, and semantic embeddings provide feature-level structural context. By injecting these priors at multiple generator layers, the model receives structural information at different spatial resolutions and is therefore better able to preserve both global room organization and local object boundaries.
This mechanism corresponds to the spatial characteristics of interior scenes. Large structural regions, such as walls, floors, and ceilings, define the overall geometry of a room, whereas smaller objects, such as sofas, tables, lamps, windows, and decorative elements, require finer boundary control. If semantic information is introduced only at the input stage, it may be weakened during feature transformation and upsampling. Multi-scale injection reduces this problem by repeatedly reintroducing structural constraints into the synthesis process. The descriptive trends in Figure 3 show that the complete framework achieved lower semantic boundary offset, higher semantic region consistency, and lower geometric misalignment than the weaker semantic configurations.
The inferential results in Table 8 and Table 9 qualify the strength of this evidence. Although the Friedman tests detected overall differences among the five internal variants, the corresponding Kendall’s (W) values indicated small omnibus effect sizes. Moreover, the favorable mean differences between the complete framework and the strongest internal variant, semantic embedding, did not remain statistically significant after Holm correction (all adjusted (p = 0.054)), and the corresponding matched rank-biserial correlations were small. The Figure 3 results should therefore be interpreted as supporting an incremental descriptive pattern across the semantic configurations rather than a decisive pairwise advantage of the complete framework over the semantic-embedding variant.
The discussion also connects with previous work on semantic-guided image synthesis and semantic segmentation. Semantic-guided generation has shown that spatial layout conditions can improve the correspondence between semantic regions and generated content [23]. Semantic segmentation research further demonstrates that category-level and region-level representations are useful for object-boundary understanding and scene parsing [15,16,17]. In this study, these ideas are extended to interior style generation by combining masks, boundaries, and embeddings within the generator feature stream. Semantic information is therefore not treated as a static annotation, but as an active constraint during feature synthesis.
The results in Figure 4 and Table 9 further indicate that structure-aware conditioning can support perceptual quality. This point is important because semantic constraints are sometimes assumed to limit visual freedom. In interior scenes, however, uncontrolled texture-pattern diffusion is usually perceived as an artifact rather than as a meaningful style effect. When wall textures spread onto furniture, or floor patterns interfere with tables and cabinets, the image may lose spatial credibility even if it appears visually rich. By restricting style transformation according to semantic regions, the proposed framework is designed to reduce cross-region interference and preserve clearer local details.
Thus, semantic-conditional injection contributes to both geometric stability and perceptual coherence. Relative to SPADE, the proposed framework achieved favorable paired improvements in LPIPS, edge sharpness, and texture-pattern detail score, with all three comparisons remaining significant after Holm correction and showing substantial matched rank-biserial effect sizes. These results indicate that structural constraints did not suppress image-level style and detail representation under the tested conditions when they were coordinated with style modulation. This finding is consistent with the broader view that controllable image synthesis requires both visual realism and reliable structural conditioning [10,14]. For interior style generation, the key requirement is not simply to produce visually attractive images, but to maintain spatial legibility while allowing controlled stylistic variation.

4.2. Structure–Style Balance and Methodological Contribution

The results also clarify the relationship between style controllability and structural preservation. Figure 5 shows that the style intensity coefficient produced a relatively continuous response, indicating that image-level style expression can be adjusted in a controlled manner. Figure 6 further shows that semantic boundary consistency declined more slowly in the proposed framework than in the baseline when style intensity increased. The paired comparisons reported in Table 9 provide additional support for these patterns: style response amplitude, style consistency, and semantic boundary consistency all favored the proposed or complete framework, with Holm-adjusted (p)-values below 0.001 and substantial matched rank-biserial correlations. These findings suggest that stronger style expression does not necessarily need to be achieved at the expense of severe boundary degradation, provided that semantic priors are introduced during the synthesis process.
The ablation results in Figure 7 further support this interpretation. When explicit style modulation was removed, the generated outputs showed lower style-domain separability in the fixed VGG-19-based style-feature space and lower within-domain style diversity. The complete framework achieved a style-domain separability value of 1.48, compared with 0.92 for the variant without style modulation, while its style-diversity values remained higher across the modern minimalist, Nordic, industrial, and neoclassical domains. This indicates that semantic priors alone are useful for structure preservation, but they are not sufficient for maintaining distinguishable multi-style representations. Conversely, the structure–style trade-off observed in Figure 6 indicates that increasingly strong style expression requires adequate semantic constraints to limit boundary degradation. The two branches therefore play complementary roles: semantic conditioning supports spatial stability, whereas style modulation regulates image-level visual variation.
This point is also important for positioning the contribution of the study. The contribution of the proposed framework should not be understood as the isolated invention of a fundamentally new network block. Rather, its value lies in the task-specific integration and evaluation of semantic masks, boundary maps, semantic embeddings, and controllable style modulation for structure-sensitive interior style generation. Compared with semantically unconstrained generation, the framework provides stronger control over room layout and object boundaries. Compared with feature-statistics-based style transfer, it better preserves semantic regions during visual style transformation. Compared with semantic-guided generation methods that emphasize spatial conditioning, it further examines how semantic priors interact with style intensity and style-domain differentiation in an interior style-generation task.
In this sense, the study contributes to the specific research field by clarifying how semantic priors and style modulation can be coordinated to improve the structure–style balance. The results do not imply that semantic conditioning alone solves all problems in interior generation. Instead, they show that a controlled combination of semantic layout information and style modulation can reduce boundary drift, improve style-domain separability, and maintain higher perceived structural consistency under a fixed experimental protocol. Because the comparisons were conducted using the same test subset, style reference categories, metric definitions, and inference setting, the reported improvements can be interpreted as differences in model behavior rather than as differences in evaluation conditions. Across the reported experiments, the proposed framework exhibited a consistent pattern of favorable structural preservation, perceptual-quality, and style-controllability outcomes. The external-baseline and style-control comparisons provided particularly clear statistical support, while the internal ablation traced the incremental contribution of the individual semantic components. This combined evidence positions the contribution as a coordinated task-specific integration of semantic conditioning and style modulation for structure-sensitive interior style generation.

4.3. Applicability and Computational Feasibility in AI-Assisted Interior Visualization

The proposed framework is relevant to AI-assisted interior visualization, virtual scene visualization, and digital media content generation. In early-stage visual exploration, designers and users often need to compare different image-level style alternatives under the same spatial layout. Previous studies on AI-assisted architectural visualization and interior design generation have shown that generative models can support design ideation, user-oriented visualization, and rapid exploration of design alternatives [1,2,5,8]. Within this context, the present framework provides a structure-aware generation strategy: it changes visual style while retaining the spatial organization of the room.
The subjective evaluation in Figure 8 adds a perceptual perspective to the quantitative results. Participants assigned higher mean scores to the proposed framework in realism, style expression, and structural consistency, suggesting that the performance patterns observed in structure preservation and style controllability were also reflected directionally in participants’ visual assessments. Because the subjective comparison was descriptive and involved a limited participant group, these ratings should be interpreted as complementary perceptual evidence rather than as an independent inferential validation. This is particularly relevant for visual comparison and communication, where the generated image should remain spatially interpretable rather than merely stylistically expressive.
At the same time, the applicability of the framework should be clearly distinguished from production-ready interior design or construction-level decision-making. The model controls image-level visual attributes, including texture patterns, color tones, material-like surface appearance, and illumination-related visual cues. It does not simulate physical material specifications, installation constraints, construction processes, or real lighting direction and intensity. Therefore, the most direct application scope of the current framework is controlled interior visualization rather than technical design documentation or physically based rendering.
The computational results provide a further boundary for interpreting the method. The proposed framework is more computationally demanding than lightweight style-transfer models such as AdaIN and linear style transfer, because it integrates multi-scale semantic injection, boundary-enhanced conditioning, semantic embeddings, and controllable style modulation within the generation process. However, under the standardized 256 × 256 evaluation workflow, its computational cost remains lower than that of the SPADE baseline in terms of trainable parameters, estimated FLOPs, inference latency, and peak GPU memory consumption. This result is consistent with the feasibility analysis reported in Table 10 and places the proposed framework in an intermediate computational position: it is not the lightest evaluated method, but it achieved favorable structure-preservation and controllability outcomes while requiring fewer computational resources than SPADE under the same experimental setting.
These findings support the feasibility of the framework for controlled experimental visualization, but they should not be interpreted as evidence of real-time deployment readiness or unrestricted high-resolution production. Future applications would require further optimization of model size, inference speed, memory consumption, and interface integration, especially if the framework is extended to interactive design tools or higher-resolution visualization workflows.

4.4. Limitations and Future Work

Several limitations should be acknowledged. First, all images and semantic maps were evaluated at a resolution of 256 × 256 pixels. Although this setting supports controlled comparison of semantic preservation, style modulation, and the structure–style trade-off, it cannot fully represent fine material grain, small decorative elements, fabric textures, or complex lighting effects. Moreover, the material-like surfaces and illumination-related cues generated by the framework are image-level visual representations rather than physical material specifications or physically based lighting simulations. The current framework should therefore be interpreted as a visualization model rather than a system for construction documentation or technical design decision-making. Future work should extend the framework to higher-resolution generation and investigate integration with material databases and physically based rendering tools.
Second, the evaluation was conducted using four interior style domains: modern minimalist, Nordic, industrial, and neoclassical. These categories provide a controlled basis for examining style-domain separability and diversity but do not represent the full range of interior design practice. The evaluation pipeline also depends on a fixed semantic parsing network and VGG-19 Gram-matrix features. Parsing errors may affect the calculated region- and boundary-based metrics, while Gram-matrix features primarily represent texture statistics and cannot capture every perceptual or semantic aspect of interior style. In addition, the task-specific metrics introduced in this study are intended to complement established measures such as IoU, boundary F-score, and LPIPS rather than replace them. Their generalizability should be examined using additional datasets, style categories, semantic parsing models, and independent evaluation settings.
Third, the external validation remains limited in scope. The proposed framework was compared with StyleGAN2, AdaIN, linear style transfer, and SPADE, but not systematically with recent diffusion-based or ControlNet-based conditional generation models [40,41,42]. Future studies should compare GAN-based semantic injection and diffusion-based spatial control under consistent datasets, semantic maps, style references, and evaluation protocols. The subjective evaluation was also limited to 20 participants and was used as complementary descriptive evidence under controlled paired-comparison conditions. Larger and more diverse participant groups would be required to examine whether the perceived improvements remain stable across different user backgrounds, room types, style categories, and presentation formats.
Overall, the proposed framework should be understood as a controlled experimental model for AI-assisted interior style visualization rather than as a production-ready interior design system. Future work should focus on higher-resolution synthesis, broader style coverage, independent validation of the evaluation metrics, comparison with diffusion-based methods, larger-scale subjective evaluation, and computational optimization for interactive visualization workflows.

5. Conclusions

This study proposed a semantic-conditional GAN framework for structure-preserving and controllable interior style generation. The framework integrates semantic masks, boundary maps, and semantic embeddings as structural priors and introduces them into the generator through a multi-scale conditional mechanism. A style encoding network was further employed to regulate image-level visual style attributes, including texture patterns, color tones, material-like surface appearance, and illumination-related visual cues, under semantic constraints. The model was optimized using a multi-objective loss function combining adversarial, semantic consistency, style reconstruction, and perceptual terms and was evaluated under a standardized protocol with fixed inference settings and explicitly defined metrics.
Experiments conducted using 5000 selected indoor images from SUN RGB-D and ADE20K, together with a 600-image style reference set, produced favorable results in structure preservation, style controllability, and perceptual quality. The proposed framework achieved a semantic region consistency score of 0.91, maintained higher semantic boundary consistency under increasing style intensity, obtained style consistency scores ranging from 0.88 to 0.90, and achieved an LPIPS value of 0.128. In the external-method comparison, its improvements over SPADE in LPIPS, edge sharpness, and texture-pattern detail score remained statistically significant after Holm correction and were associated with substantial paired effect sizes. The style-control comparisons also supported the contribution of explicit style modulation to style response, style consistency, and semantic boundary stability. The ablation results further indicated that semantic conditioning and style modulation perform complementary functions: semantic priors support spatial stability, whereas explicit style modulation improves style-domain separability and within-domain diversity. The descriptive subjective evaluation produced the same directional pattern, with the proposed framework receiving higher mean ratings for realism, style expression, and structural consistency than the control model without semantic constraints.
The computational evaluation showed that the proposed framework is more resource-intensive than lightweight style-transfer methods such as AdaIN and linear style transfer but requires fewer parameters, lower estimated FLOPs, shorter inference latency, and lower peak GPU memory than SPADE under the standardized 256 × 256 experimental setting. Overall, the findings support the value of coordinating semantic-conditional injection and controllable style modulation for structure-sensitive interior style visualization. The current framework should nevertheless be understood as a controlled experimental model for image-level visualization rather than as a production-ready system for construction-level interior design, physical material specification, or physically based lighting simulation. Future work should extend the framework to higher-resolution synthesis, broader style taxonomies, more diverse interior datasets, independent validation of the evaluation metrics, larger-scale subjective evaluation, computational optimization, and systematic comparison with diffusion-based conditional generation methods.

Author Contributions

Conceptualization, T.L.; methodology, T.L.; software, C.W.; validation, T.L., C.W. and S.S.B.H.; formal analysis, T.L.; investigation, T.L. and S.S.B.H.; resources, T.L.; data curation, T.L.; writing—original draft preparation, T.L.; writing—review and editing, T.L., C.W. and S.S.B.H.; visualization, T.L.; supervision, S.S.B.H.; project administration, T.L. All authors have read and agreed to the published version of the manuscript.

Funding

This research was funded by the 2026 industry–university collaborative project between Jiaozuo University and Tianjin Xinfei Digital Technology Co., Ltd., grant number JDHX2026-001. The APC was funded by Jiaozuo University.

Institutional Review Board Statement

Ethical review and approval were waived for this study because human participation was limited to an anonymous visual evaluation of generated interior images. The study did not involve clinical intervention, biological samples, vulnerable groups, personally identifiable information, or the collection of sensitive personal data. Participants only assessed the generated images in terms of realism, style expression, and structural consistency.

Informed Consent Statement

Informed consent was obtained from all subjects involved in the study.

Data Availability Statement

The processed experimental data and evaluation results are available from the corresponding author upon reasonable request.

Acknowledgments

The authors would like to express their sincere gratitude to all participants in this study, whose insights and feedback were of great value to the research.

Conflicts of Interest

Author Chang Wen was employed by the company Tianjin Xinfei Digital Technology Co., Ltd. The remaining authors declare that the research was conducted in the absence of any commercial or financial relationships that could be construed as a potential conflict of interest. The authors declare that this study received funding from Tianjin Xinfei Digital Technology Co., Ltd. The funder had the following involvement with the study through its employee and co-author Chang Wen: software, validation, writing—review and editing.

Abbreviations

The following abbreviations are used in this manuscript:
AdaINAdaptive Instance Normalization
ADE20KA large-scale scene parsing dataset with semantic annotations
GANGenerative Adversarial Network
LPIPSLearned Perceptual Image Patch Similarity
RGB-DRed, Green, Blue and Depth
SPADESpatially Adaptive Denormalization

References

  1. Chen, J.; Shao, Z.; Hu, B. Generating Interior Design from Text: A New Diffusion Model-Based Method for Efficient Creative Design. Buildings 2023, 13, 1861. [Google Scholar] [CrossRef] [Scilit]
  2. Paananen, V.; Oppenlaender, J.; Visuri, A. Using Text-to-Image Generation for Architectural Design Ideation. Int. J. Archit. Comput. 2024, 22, 458–474. [Google Scholar] [CrossRef] [Scilit]
  3. Patil, A.G.; Patil, S.G.; Li, M.; Fisher, M.; Savva, M.; Zhang, H. Advances in Data-Driven Analysis and Synthesis of 3D Indoor Scenes. Comput. Graph. Forum 2024, 43, e14927. [Google Scholar] [CrossRef] [Scilit]
  4. Gao, L.; Sun, J.-M.; Mo, K.; Lai, Y.-K.; Guibas, L.J.; Yang, J. SceneHGN: Hierarchical Graph Networks for 3D Indoor Scene Generation with Fine-Grained Geometry. IEEE Trans. Pattern Anal. Mach. Intell. 2023, 45, 8902–8919. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  5. Tanasra, H.; Rott Shaham, T.; Michaeli, T.; Austern, G.; Barath, S. Automation in Interior Space Planning: Utilizing Conditional Generative Adversarial Network Models to Create Furniture Layouts. Buildings 2023, 13, 1793. [Google Scholar] [CrossRef] [Scilit]
  6. Feng, W.; Zhu, W.; Fu, T.-J.; Jampani, V.; Akula, A.; He, X.; Basu, S.; Wang, X.E.; Wang, W.Y. LayoutGPT: Compositional Visual Planning and Generation with Large Language Models. In Proceedings of the Advances in Neural Information Processing Systems 36 (NeurIPS 2023), New Orleans, LA, USA, 10–16 December 2023; pp. 18225–18250. [Google Scholar] [CrossRef] [Scilit]
  7. Shao, Z.; Chen, J.; Zeng, H.; Hu, W.; Xu, Q.; Zhang, Y. A New Approach to Interior Design: Generating Creative Interior Design Videos of Various Design Styles from Indoor Texture-Free 3D Models. Buildings 2024, 14, 1528. [Google Scholar] [CrossRef] [Scilit]
  8. Wang, Y.T.; Liang, C.; Huai, N.; Chen, J.; Zhang, C.J. A Survey of Personalized Interior Design. Comput. Graph. Forum 2023, 42, e14844. [Google Scholar] [CrossRef] [Scilit]
  9. Ramdurai, B.; Adhithya, P. The Impact, Advancements and Applications of Generative AI. Int. J. Comput. Sci. Eng. 2023, 10, 1–8. [Google Scholar] [CrossRef] [Scilit]
  10. Baraheem, S.S.; Le, T.-N.; Nguyen, T.V. Image Synthesis: A Review of Methods, Datasets, Evaluation Metrics, and Future Outlook. Artif. Intell. Rev. 2023, 56, 10813–10865. [Google Scholar] [CrossRef] [Scilit]
  11. Han, X.; Wu, Y.; Wan, R. A Method for Style Transfer from Artistic Images Based on Depth Extraction Generative Adversarial Network. Appl. Sci. 2023, 13, 867. [Google Scholar] [CrossRef] [Scilit]
  12. Batziou, E.; Ioannidis, K.; Patras, I.; Vrochidis, S.; Kompatsiaris, I. Artistic Neural Style Transfer Using CycleGAN and FABEMD by Adaptive Information Selection. Pattern Recognit. Lett. 2023, 165, 55–62. [Google Scholar] [CrossRef] [Scilit]
  13. Sebestyen, A.; Hirschberg, U.; Rasoulzadeh, S. Using Deep Learning to Generate Design Spaces for Architecture. Int. J. Archit. Comput. 2023, 21, 337–357. [Google Scholar] [CrossRef] [Scilit]
  14. Yu, Y.; Li, D.; Li, B.; Li, N. Multi-Style Image Generation Based on Semantic Image. Vis. Comput. 2024, 40, 3411–3426. [Google Scholar] [CrossRef] [Scilit]
  15. Emek Soylu, B.; Guzel, M.S.; Bostanci, G.E.; Ekinci, F.; Asuroglu, T.; Acici, K. Deep-Learning-Based Approaches for Semantic Segmentation of Natural Scene Images: A Review. Electronics 2023, 12, 2730. [Google Scholar] [CrossRef] [Scilit]
  16. Yang, L.; Cai, H. Cost-Efficient Image Semantic Segmentation for Indoor Scene Understanding Using Weakly Supervised Learning and BIM. J. Comput. Civ. Eng. 2023, 37, 04022062. [Google Scholar] [CrossRef] [Scilit]
  17. Li, X.; Zhang, J.; Yang, Y.; Cheng, G.; Yang, K.; Tong, Y.; Tao, D. SFNet: Faster and Accurate Semantic Segmentation via Semantic Flow. Int. J. Comput. Vis. 2024, 132, 466–489. [Google Scholar] [CrossRef] [Scilit]
  18. Aalaei, M.; Saadi, M.; Rahbar, M.; Ekhlassi, A. Architectural Layout Generation Using a Graph-Constrained Conditional Generative Adversarial Network. Autom. Constr. 2023, 155, 105053. [Google Scholar] [CrossRef] [Scilit]
  19. Lee, J.-K.; Jeong, H.; Kim, Y.; Cha, S.H. Creating Spatial Visualizations Using Fine-Tuned Interior Design Style Models Informed by User Preferences. Adv. Eng. Inform. 2024, 62, 102686. [Google Scholar] [CrossRef] [Scilit]
  20. Lee, J.-K.; Yoo, Y.; Cha, S.H. Generative Early Architectural Visualizations: Incorporating Architect’s Style-Trained Models. J. Comput. Des. Eng. 2024, 11, 40–59. [Google Scholar] [CrossRef] [Scilit]
  21. Liao, C.; Sawayama, M.; Xiao, B. Unsupervised Learning Reveals Interpretable Latent Representations for Translucency Perception. PLoS Comput. Biol. 2023, 19, e1010878. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  22. Goodfellow, I.; Pouget-Abadie, J.; Mirza, M.; Xu, B.; Warde-Farley, D.; Ozair, S.; Courville, A.; Bengio, Y. Generative Adversarial Nets. Adv. Neural Inf. Process. Syst. 2014, 27, 2672–2680. Available online: https://papers.nips.cc/paper/5423-generative-adversarial-nets (accessed on 21 May 2026).
  23. Park, T.; Liu, M.-Y.; Wang, T.-C.; Zhu, J.-Y. Semantic Image Synthesis with Spatially-Adaptive Normalization. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Long Beach, CA, USA, 15–20 June 2019; pp. 2337–2346. [Google Scholar] [CrossRef] [Scilit]
  24. Karras, T.; Laine, S.; Aittala, M.; Hellsten, J.; Lehtinen, J.; Aila, T. Analyzing and Improving the Image Quality of StyleGAN. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Seattle, WA, USA, 13–19 June 2020; pp. 8110–8119. [Google Scholar] [CrossRef] [Scilit]
  25. Song, S.; Lichtenberg, S.P.; Xiao, J. SUN RGB-D: A RGB-D Scene Understanding Benchmark Suite. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Boston, MA, USA, 7–12 June 2015; pp. 567–576. [Google Scholar] [CrossRef] [Scilit]
  26. Zhou, B.; Zhao, H.; Puig, X.; Fidler, S.; Barriuso, A.; Torralba, A. Scene Parsing through ADE20K Dataset. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Honolulu, HI, USA, 21–26 July 2017; pp. 5122–5130. [Google Scholar] [CrossRef] [Scilit]
  27. Johnson, J.; Alahi, A.; Fei-Fei, L. Perceptual Losses for Real-Time Style Transfer and Super-Resolution. In Proceedings of the European Conference on Computer Vision, Amsterdam, The Netherlands, 8–16 October 2016; pp. 694–711. [Google Scholar] [CrossRef] [Scilit]
  28. Kingma, D.P.; Ba, J. Adam: A Method for Stochastic Optimization. In Proceedings of the 3rd International Conference on Learning Representations (ICLR 2015), San Diego, CA, USA, 7–9 May 2015. [Google Scholar]
  29. Huang, X.; Belongie, S. Arbitrary Style Transfer in Real-Time with Adaptive Instance Normalization. In Proceedings of the IEEE International Conference on Computer Vision, Venice, Italy, 22–29 October 2017; pp. 1501–1510. [Google Scholar] [CrossRef] [Scilit]
  30. Li, X.; Liu, S.; Kautz, J.; Yang, M.-H. Learning Linear Transformations for Fast Image and Video Style Transfer. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Long Beach, CA, USA, 15–20 June 2019; pp. 3809–3817. [Google Scholar] [CrossRef] [Scilit]
  31. Zhang, R.; Isola, P.; Efros, A.A.; Shechtman, E.; Wang, O. The Unreasonable Effectiveness of Deep Features as a Perceptual Metric. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Salt Lake City, UT, USA, 18–23 June 2018; pp. 586–595. [Google Scholar] [CrossRef] [Scilit]
  32. Ronneberger, O.; Fischer, P.; Brox, T. U-Net: Convolutional Networks for Biomedical Image Segmentation. In Medical Image Computing and Computer-Assisted Intervention—MICCAI 2015; Navab, N., Hornegger, J., Wells, W.M., Frangi, A.F., Eds.; Lecture Notes in Computer Science; Springer: Cham, Switzerland, 2015; Volume 9351, pp. 234–241. [Google Scholar] [CrossRef] [Scilit]
  33. He, K.; Zhang, X.; Ren, S.; Sun, J. Deep Residual Learning for Image Recognition. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR), Las Vegas, NV, USA, 27–30 June 2016; pp. 770–778. [Google Scholar] [CrossRef] [Scilit]
  34. Yakubovskiy, P. Segmentation Models PyTorch, version 0.3.0. Computer Software. Python Software Foundation: Wilmington, DE, USA, 2022. Available online: https://pypi.org/project/segmentation-models-pytorch/0.3.0/ (accessed on 1 August 2026).
  35. Csurka, G.; Larlus, D.; Perronnin, F. What Is a Good Evaluation Measure for Semantic Segmentation? In Proceedings of the British Machine Vision Conference 2013, Bristol, UK, 9–13 September 2013; pp. 32.1–32.11. [Google Scholar] [CrossRef] [Scilit]
  36. Simonyan, K.; Zisserman, A. Very Deep Convolutional Networks for Large-Scale Image Recognition. In Proceedings of the 3rd International Conference on Learning Representations, San Diego, CA, USA, 7–9 May 2015. [Google Scholar]
  37. Gatys, L.A.; Ecker, A.S.; Bethge, M. Image Style Transfer Using Convolutional Neural Networks. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Las Vegas, NV, USA, 27–30 June 2016; pp. 2414–2423. [Google Scholar] [CrossRef] [Scilit]
  38. Wilcoxon, F. Individual Comparisons by Ranking Methods. Biom. Bull. 1945, 1, 80–83. [Google Scholar] [CrossRef] [Scilit]
  39. Holm, S. A Simple Sequentially Rejective Multiple Test Procedure. Scand. J. Stat. 1979, 6, 65–70. [Google Scholar]
  40. Ho, J.; Jain, A.; Abbeel, P. Denoising Diffusion Probabilistic Models. Adv. Neural Inf. Process. Syst. 2020, 33, 6840–6851. Available online: https://proceedings.neurips.cc/paper/2020/hash/4c5bcfec8584af0d967f1ab10179ca4b-Abstract.html (accessed on 21 May 2026).
  41. Rombach, R.; Blattmann, A.; Lorenz, D.; Esser, P.; Ommer, B. High-Resolution Image Synthesis with Latent Diffusion Models. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, New Orleans, LA, USA, 18–24 June 2022; pp. 10684–10695. [Google Scholar] [CrossRef] [Scilit]
  42. Zhang, L.; Rao, A.; Agrawala, M. Adding Conditional Control to Text-to-Image Diffusion Models. In Proceedings of the IEEE/CVF International Conference on Computer Vision, Paris, France, 2–6 October 2023; pp. 3836–3847. [Google Scholar] [CrossRef] [Scilit]
Figure 1. Overall framework of the proposed semantic-conditional GAN for structure-preserving and controllable interior style generation. The arrows indicate the direction of data and information flow between the components.
Applsci 16 07892 g001
Figure 2. Illustrative layout for qualitative comparison of interior style generation. Colors are used only for visual distinction and do not encode quantitative information or specific categories.
Applsci 16 07892 g002
Figure 3. Quantitative comparison of semantic structure preservation. (a) Semantic boundary offset (pixels); (b) semantic region consistency (0–1 score); (c) geometric misalignment ratio (%).
Applsci 16 07892 g003
Figure 4. Quantitative comparison of perceptual quality and detail representation. (a) LPIPS (unitless distance score); (b) edge sharpness (gradient-based score); (c) texture-pattern detail score (0–1 score).
Applsci 16 07892 g004
Figure 5. Quantitative analysis of style controllability and consistency. (a) Style response amplitude (normalized score) under different style intensity coefficients; (b) style consistency scores (0–1 score) under cross-style transformation.
Applsci 16 07892 g005
Figure 6. Structure–style trade-off under increasing style intensity. (a) Style response amplitude (normalized score) under different style-intensity coefficients; (b) semantic boundary consistency (0–1 score) under different style-intensity coefficients.
Applsci 16 07892 g006
Figure 7. Ablation analysis of style-domain separability and diversity. (a) Overall style-domain separability, D s e p , calculated as the average Euclidean distance among the generated feature centroids of the four target style domains; (b) style diversity scores, D d i v k , for the modern minimalist, Nordic, industrial, and neoclassical target style domains.
Applsci 16 07892 g007
Figure 8. Descriptive comparison of mean normalized participant ratings for the proposed framework and the control model without semantic constraints across realism, style expression, and structural consistency.
Applsci 16 07892 g008
Table 1. Dataset composition and experimental split.
Data SourceSelected ImagesMain UseTrainingValidationTest
SUN RGB-D2000Interior content images and structure priors1400400200
ADE20K3000Indoor semantic annotations and scene parsing2100600300
Combined indoor dataset5000Model training and evaluation35001000500
Style reference set600Style encoding and controllable modulation---
Table 2. Composition of the self-constructed style reference set.
Style CategoryNumber of ImagesRepresentative Visual Characteristics
Modern minimalist150Neutral palette, clean lines, simplified furniture, limited decoration
Nordic150Light wood appearance, soft illumination cues, pale colors, natural surface textures
Industrial150Exposed brick or concrete appearance, dark metal, high contrast, rough surface patterns
Neoclassical150Symmetrical composition, decorative moldings, refined furniture, warm visual atmosphere
Total600Four balanced style domains for style encoding and consistency evaluation
Table 3. Semantic category distribution of selected indoor scenes.
Semantic CategoryAverage Pixel Proportion (%)Average Number of Category RegionsSample Coverage (%)
Wall32.51.098.0
Floor21.81.097.2
Sofa9.01.464.5
Table6.81.259.0
Window4.21.143.0
Table 4. Implementation configuration of the semantic-conditional injection module.
Injection LevelFeature ResolutionSemantic Prior UsedEmbedding DimensionMapping WidthModulation ParametersMain Implementation Role
Layer 116 × 16Region mask + semantic embedding64128gamma, beta: 64 × 2Global room layout and wall–floor organization
Layer 332 × 32Region mask + semantic embedding64128gamma, beta: 64 × 2Coarse furniture placement and major semantic regions
Layer 564 × 64Region mask + boundary map + semantic embedding128256gamma, beta: 128 × 2Furniture contours, window frames, and table edges
Layer 7128 × 128Boundary-enhanced semantic map + embedding128256gamma, beta: 128 × 2Local object boundaries and surface transitions
Layer 9256 × 256Boundary-enhanced semantic map + high-dimensional embedding256512gamma, beta: 256 × 2Final edge refinement and high-resolution semantic stability
Table 5. Training and optimization configuration used for the proposed framework and comparable ablation variants.
Configuration ItemSettingDescription
Content inputRGB interior content imageProvides the spatial scene to be stylized
Semantic priorsSemantic mask, semantic boundary map, and semantic embeddingProvides region-level, boundary-level, and feature-level structural constraints
Style inputReference image sampled from the style reference setProvides the target image-level style condition
Input resolution256 × 256Unified size for RGB images and semantic representations
Batch size16Number of training samples per optimization batch
OptimizerAdamOptimizer for adversarial and multi-objective training
Initial learning rate0.0001Initial learning rate for model optimization
Learning-rate scheduleReduced by 0.5 every 50 epochsStabilizes optimization during later training stages
Training epochs200Total number of training epochs
Update strategyAlternating discriminator and generator updatesMaintains the adversarial training procedure
Adversarial loss weight1.0Controls global visual realism
Semantic loss weight10.0Strengthens semantic structure preservation
Style reconstruction loss weight5.0Maintains consistency with the target style representation
Perceptual loss weight1.0Preserves feature-level content and texture-pattern coherence
Adam β10.5First-moment decay rate
Adam β20.999Second-moment decay rate
Gradient clipping threshold0.1Reduces unstable adversarial updates
Validation useLoss behavior and training stability monitoringDoes not participate in parameter updating
Test useFinal generation and metric calculationHeld out from model training and validation
Inference settingFixed learned parameters without per-scene fine-tuningEnsures that test results are produced under a consistent model state
Table 6. Baseline models and evaluation configuration.
Model CategoryRepresentative MethodCore MechanismStructural ConstraintStyle Control
Semantically unconstrained generationStyleGAN2Latent-space image generationNo explicit semantic constraintLatent variable control
Feature-statistics style transferAdaINAdaptive instance normalizationNo explicit semantic constraintGlobal style-feature injection
Linear style transferLinear transferLinear transformation of feature statisticsNo explicit semantic constraintLinear feature transformation
Semantic-guided generationSPADESpatially adaptive normalization using semantic mapsSemantic-map-based modulationSemantic-conditioned synthesis with limited explicit style-intensity control
Proposed frameworkSemantic-conditional GANMulti-scale semantic injection and style modulationSemantic masks, boundary maps, and embeddingsDecoupled style encoding and intensity control
Table 7. Evaluation metrics used in the experiments.
Evaluation DimensionMetricUnit/ScaleInterpretationDesired Direction
Structure preservationSemantic boundary offsetPixelsAverage pixel displacement between generated semantic boundaries and input semantic boundariesLower is better
Structure preservationSemantic region consistency0–1 scoreAgreement between generated semantic regions and input semantic masksHigher is better
Structure preservationSemantic boundary consistency0–1 scoreNormalized boundary-alignment score between generated and input semantic structuresHigher is better
Structure preservationGeometric misalignment ratioRatio/percentageProportion of regions showing layout distortion or object-position mismatchLower is better
Style controllabilityStyle response amplitudeNormalized scoreMagnitude of visual style change under different style intensity coefficientsHigher response indicates stronger controllability
Style controllabilityStyle consistency score0–1 scoreSimilarity between generated image features and target style-domain featuresHigher is better
Style controllabilityStyle-domain separabilityFeature-space distanceDistance between generated style-domain clusters in the feature spaceHigher is better
Style controllabilityStyle diversity scoreNormalized scoreIntra-domain variation in generated samples under the same style categoryHigher is better
Perceptual qualityLPIPSUnitless distance scoreLearned perceptual distance between each generated image and its corresponding original content imageLower is better
Perceptual qualityEdge sharpnessGradient-based scoreGradient-based measure of contour clarity and edge definitionHigher is better
Perceptual qualityTexture-pattern detail score0–1 scoreImage-level local texture-pattern richness and detail representationHigher is better
Subjective qualityRealismNormalized participant scoreParticipant assessment of visual plausibilityHigher is better
Subjective qualityStyle expressionNormalized participant scoreParticipant assessment of target-style recognizabilityHigher is better
Subjective qualityStructural consistencyNormalized participant scoreParticipant assessment of spatial and object-level stabilityHigher is better
Table 8. Omnibus statistical comparisons among the evaluated methods and model variants.
FigureEvaluation SettingMetrickNFriedman χ2dfp-ValueKendall’s W
Figure 3Internal semantic-prior variantsSemantic boundary offset ↓550018.440.00100.0092
Figure 3Internal semantic-prior variantsSemantic region consistency ↑550017.240.00180.0086
Figure 3Internal semantic-prior variantsGeometric misalignment ratio ↓550016.840.00210.0084
Figure 4External baseline methodsLPIPS ↓550019.14<0.0010.0096
Figure 4External baseline methodsEdge sharpness ↑550016.540.00240.0083
Figure 4External baseline methodsTexture-pattern detail score ↑550015.940.00310.0080
Note: ↓ indicates that a lower value represents better performance, whereas ↑ indicates that a higher value represents better performance.
Table 9. Paired statistical comparisons between the proposed or complete framework and the strongest corresponding comparator.
FigureMetricComparisonProposed/FullComparatorImprovement [95% CI]Holm-Adjusted prᵣᵦ
Figure 3Semantic boundary offset ↓Full vs. semantic embedding3.2 ± 1.4 3.5 ± 1.6 0.3 [0.17, 0.43] 0.0540.086
Figure 3Semantic region consistency ↑Full vs. semantic embedding0.91 ± 0.040.87 ± 0.050.040 [0.036, 0.044]0.0540.087
Figure 3Geometric misalignment ratio ↓Full vs. semantic embedding4.7 ± 2.1%5.7 ± 2.4%1.0 [0.81, 1.19]%0.0540.088
Figure 4LPIPS ↓Proposed vs. SPADE0.128 ± 0.0150.150 ± 0.0180.022 [0.021, 0.023]<0.0010.72
Figure 4Edge sharpness ↑Proposed vs. SPADE18.6 ± 2.416.2 ± 2.82.4 [2.27, 2.53]<0.0010.68
Figure 4Texture-pattern detail score ↑Proposed vs. SPADE0.91 ± 0.030.82 ± 0.050.090 [0.088, 0.093]<0.0010.74
Figure 5Style response amplitude ↑Full vs. no style modulation0.62 ± 0.140.29 ± 0.110.330 [0.325, 0.335]<0.0010.85
Figure 5Style consistency score ↑Full vs. no style modulation0.89 ± 0.040.70 ± 0.060.190 [0.187, 0.193]<0.0010.82
Figure 6Semantic boundary consistency ↑Proposed vs. baseline0.85 ± 0.050.75 ± 0.070.100 [0.097, 0.103]<0.0010.78
Note: ↓ indicates that a lower value represents better performance, whereas ↑ indicates that a higher value represents better performance.
Table 10. Computational feasibility metrics.
ModelParameters (M)FLOPs (G)Model Size (MB)Inference Latency
(ms/Image)
Peak GPU Memory
(GB)
StyleGAN230.044.5120.031.0 ± 1.71.90
AdaIN23.518.594.018.2 ± 1.21.14
Linear style transfer22.226.288.824.2 ± 1.41.30
SPADE93.085.0372.056.5 ± 3.03.78
Proposed framework60.068.5240.047.5 ± 2.53.10
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content.