Article

BHM-IDS: Behavior-Driven Hierarchy and Multi-Dataset Training for Cross-Dataset Generalization

by
Mounira Zekiouk
1,2,*,
Madjed Bencheikh Lehocine
1,3,*,
Yehya Bouzeraa
1,3,
Ahlam Bouanane
1,
Georgi Hristov
4 and
Plamen Zahariev
4
1
Computer Science Department, University of Abdelhafid Boussouf-Mila, Mila 43000, Algeria
2
MISC Laboratory, University of Constantine 2-Abdelhamid Mehri, Constantine 25016, Algeria
3
LISI Laboratory of Intelligent Systems and Informatics, University of Mila, Mila 43000, Algeria
4
Department of Telecommunications, University of Ruse “Angel Kanchev”, 7017 Ruse, Bulgaria
*
Authors to whom correspondence should be addressed.
Appl. Sci. 2026, 16(16), 7885; https://doi.org/10.3390/app16167885
Submission received: 26 June 2026 / Revised: 3 August 2026 / Accepted: 5 August 2026 / Published: 7 August 2026

Abstract

Digital infrastructures are increasingly exposed to diverse and evolving cyber threats, highlighting the need for robust intrusion detection systems (IDSs). Although machine learning (ML)-based IDSs have achieved strong performance, most existing frameworks are still developed and evaluated mainly under intra-dataset settings, providing limited evidence of their ability to generalize across unseen environments. Moreover, few studies go beyond simply reporting cross-dataset performance to propose dedicated mechanisms for improving generalization. To address this limitation, we propose BHM-IDS, a three-stage hierarchical intrusion detection framework that combines behavior-driven hierarchy with multi-dataset training to improve generalization. The first stage performs binary detection of benign versus malicious traffic, while the second stage classifies malicious traffic into two behaviorally distinct groups: the first corresponding to flood and exhaustion attacks and the second to infiltration and exploitation attacks. The final stage performs fine-grained attack classification through two specialized multi-class classifiers. To expose the framework to more diverse attacks, CIC-IDS2017 is enriched with CIC-DDoS2019 during training, while CSE-CIC-IDS2018 is used as an external test dataset to evaluate generalization. The cross-dataset validation results yielded stage-wise accuracies of 0.93, 0.96, and 0.99, respectively, while the complete end-to-end framework achieved a weighted recall of 0.93. Recall values ranging from 0.76 to 1.00 were obtained for several major classes, including benign traffic, Patator, DoS, and DDoS, although limitations remained for certain attack categories, particularly Web Attack. Overall, the proposed framework demonstrated promising and competitive performance compared with simpler frameworks and existing state-of-the-art approaches. These findings highlight the potential of combining behavior-driven hierarchical classification with multi-dataset training to improve cross-dataset generalization in IDSs.

1. Introduction

Modern society increasingly depends on interconnected digital infrastructures to sustain the operation of critical sectors such as finance, healthcare, industrial control, and public services [1,2]. As these environments grow in scale and complexity, and as connectivity between systems becomes more pervasive, the corresponding attack surface expands accordingly, creating more opportunities for sophisticated cyber threats to emerge and propagate [3]. Such threats can inflict significant economic damage, disrupt essential operations, and compromise the confidentiality of sensitive information [4]. Under these conditions, traditional preventive mechanisms, including firewalls and access control policies, are no longer sufficient on their own; effective defense also requires real-time monitoring and anomaly detection mechanisms capable of identifying and mitigating malicious activity before serious harm occurs. In this context, IDSs have become a fundamental component of defense in depth strategies, enabling continuous traffic analysis and supporting timely incident response across diverse network environments [5,6].
The design of effective IDSs has progressively shifted from signature-based and rule-driven paradigms toward ML-based methodologies. ML techniques offer the capacity to learn high-dimensional patterns from complex traffic data, adapt to evolving attack tactics, and move beyond manually crafted heuristics [7,8,9]. Within the literature on ML-based IDSs, several major research directions have emerged. One prominent line of research focuses on feature engineering and feature selection, with the goal of identifying discriminative attributes while reducing dimensionality and noise [10,11]. Another important direction concerns class balancing techniques, including resampling methods and synthetic samples generation [12,13]. At the architectural level, researchers have proposed various structural designs for IDSs, including flat models [14,15,16,17,18], hierarchical architectures [19,20,21,22,23,24,25,26,27], and cascade-based frameworks [28,29], in order to organize the classification tasks in a more structured and efficient manner. In addition, hyperparameter optimization [30,31] and regularization strategies [32] have been widely investigated. Taken together, these research efforts seek to develop IDSs that achieve not only high accuracy on benchmark datasets but also robustness, adaptability, and maintainability in realistic and evolving network environments.
Despite the substantial body of work on ML-based IDSs, most proposed frameworks are optimized and validated using intra-dataset protocols, offering limited insight into models’ behavior on unseen data. Cross-dataset evaluation has been attempted in only a limited number of studies, and none systematically address how generalization can be improved. This reveals a clear gap: the mechanisms required to achieve robust cross-dataset generalization remain largely absent from the literature.
In this paper, we address this gap by focusing on two complementary strategies that directly target generalization: hierarchical design and multi-dataset training. Our central hypothesis is that a carefully structured hierarchy can reduce interference between heterogeneous attack behaviors and produce transferable decision boundaries, while exposure to diverse datasets enables the model to learn a broader range of attack patterns. To assess this hypothesis, we instantiate these two strategies in BHM-IDS, a hierarchical IDS framework, and evaluate its generalization using cross-dataset validation.
BHM-IDS adopts a three-stage architecture that progressively refines the decision process, starting with benign and malicious traffic separation, followed by behavior-based binary classification of attacks, and finally fine-grained attack classification. The behavior-based classification in the second stage aims to capture attack patterns that remain more stable and transferable across environments. To further reduce dataset-specific bias and improve generalization, a multi-dataset training strategy is adopted, in which CIC-IDS2017 serves as the primary dataset and is enriched with the CIC-DDoS2019 dataset to provide a broader representation of attacks. The effectiveness of the proposed design is then assessed in a cross-dataset setting using the CSE-CIC-IDS2018 dataset.
The main contributions of this work are:
  • We propose a three-stage hierarchical IDS that incorporates behavior-based classification at the second stage.
  • We introduce a multi-dataset training strategy that enriches CIC-IDS2017 with CIC-DDoS2019, enabling the model to learn from a broader and more diverse set of attacks.
  • We perform a rigorous evaluation under both intra-dataset and cross-dataset settings using CSE-CIC-IDS2018 as an external test dataset, ensuring a realistic assessment of generalization capability.
  • We conduct a detailed ablation study that isolates the respective roles of behavior-driven hierarchy and multi-dataset training, showing that their combination yields strong generalization gains.
The remainder of this paper is organized as follows. Section 2 reviews the related work on ML-based IDSs, focusing on architectural developments, generalization-oriented studies, and multi-dataset training strategies, while identifying the gaps that motivate the present study. Section 3 introduces the proposed framework. Section 4 presents the experimental results and the corresponding ablation study. Section 5 discusses the impact of behavior-driven hierarchy and multi-dataset training on generalization, compares the proposed framework with existing approaches, and outlines the main limitations and future research directions.

2. Related Work

Recent advances in ML and deep learning (DL) have substantially transformed the design of IDSs, enabling data-driven models to learn complex attack patterns directly from network traffic rather than relying on static rule sets. Historically significant benchmarks such as KDD’99 [33] and NSL-KDD [34] paved the way for this transition, while contemporary datasets such as the CIC and CSE-CIC families [35] now provide larger-scale and more realistic representations of modern attacks. Building on these resources, the IDS literature has expanded along several major directions. These directions differ in their specific objectives, but they converge on common challenges.
In line with these trends, this section organizes the related work around three research axes directly connected to the proposed framework: (i) architectural advances in ML-based IDSs, especially hierarchical designs; (ii) multi-dataset training strategies aimed at improving exposure to diverse traffic; and (iii) generalization-oriented studies focusing on cross-dataset evaluation.

2.1. Architectural Advances in ML-Based IDS

Recent advances in intrusion detection have led to the development of a wide range of ML-based architectures for classifying cyber threats at different levels of granularity. Despite this diversity, the flat or single-stage architecture remains a common design choice. In this paradigm, a single classifier operates on the full feature space and directly performs either binary classification or multi-class classification. Its popularity stems from its simplicity, ease of implementation, and low operational complexity.
This single-stage design is reflected in several studies that employ conventional ML techniques. For instance, Khan et al. [14] developed a flat IDS using the CIC-IDS2017 dataset to classify seven traffic classes, including benign traffic. Several classifiers were then evaluated, including decision tree, random forest, and XGBoost.
Similarly, Lu et al. [15] introduced a random forest-based IDS designed to improve classification performance while addressing high dimensionality and class imbalance, with experiments conducted on the UNSW-NB15 dataset. In another study, Srivastav et al. [16] proposed an enhanced flat IDS architecture on the UNSW-NB15 dataset by integrating weighted learning and particle swarm optimization-based feature selection to reduce the feature space.
More recent DL approaches largely retain the same single-stage structure. For example, Cao et al. in [17] proposed a hybrid CNN-GRU model, where convolutional layers are used to extract spatial features and GRU layers capture temporal dependencies before directly performing attack classification. Similarly, Qazi et al. in [18] introduced a one-dimensional convolutional neural network-based IDS, in which 1D-CNN layers learn discriminative traffic representations and directly classify network flows. Although these approaches exploit deeper architectures and advanced feature-learning capabilities, they still follow a flat decision structure.
The studies reviewed above demonstrate the practical appeal of flat IDS models, particularly in scenarios requiring low latency and simple deployment. However, their single-step classification structure may limit their effectiveness in detecting complex or low-frequency attacks. To address this limitation, an increasing number of studies have investigated hierarchical intrusion detection architectures, which decompose classification into successive decision stages. The most common form is two-stage design, in which an initial classifier separates benign from malicious traffic, while a second classifier further categorizes the detected attacks.
For instance, Verkerken et al. in [19] adopted this pattern on the CIC-IDS2017 dataset by combining an anomaly detection stage based on autoencoder and one-class SVM models with a supervised multi-class classification stage using random forest and neural network models. Similarly, Alin et al. in [20] applied this two-stage scheme across KDD’99, NSL-KDD, UNSW-NB15, and CIC-IDS2017 datasets, comparing several classical algorithms, including Naïve Bayes, Decision Tree, and Logistic Regression.
Hewapathirana et al. in [21] further extended the two-stage hierarchical design on the CSE-CIC-IDS2018 dataset by comparing a Stacked Autoencoder-based approach with an Apache Spark-based approach. In both approaches, the hierarchical process consists of two stages: a binary classifier first distinguishes benign from attack traffic and generates probability scores, which are then combined with a reduced feature representation and passed to a second-stage multi-class classifier for attack-type prediction.
As modern network traffic datasets include an increasing number of attack types with overlapping characteristics, several studies have extended two-stage IDS designs into three-stage hierarchical architectures by introducing an intermediate attack grouping stage. In such designs, the first stage typically separates benign from malicious traffic, the second stage assigns malicious samples to broader attack groups, and the third stage performs fine-grained classification within each group. This intermediate grouping stage helps reduce classes confusions by resolving coarse-grained distinctions before predicting specific attack subtypes. The main differences among three-stage studies lie in how the intermediate attack groups are defined.
One line of research relies on semantic taxonomies to construct Stage 2 groups. For example, Uddin et al. in [22] adopted a Cyber Kill Chain-based grouping strategy, in which malicious traffic is assigned to coarse categories corresponding to phases of the intrusion lifecycle, before specific attack subtypes are predicted. In this context, cyber kill chain grouping [23] organizes attacks according to the phase that best represents their dominant behavior or role in the attack progression, such as Reconnaissance, Weaponization, Delivery, Exploitation, Installation, Command and Control, and Objectives. The study evaluated both ML and DL models across several IDSs datasets, including CIC-DoS2017, CIC-DDoS2019, and BoT-IoT.
Similarly, Kim et al. in [24] introduced a three-stage IDS architecture evaluated on CIC-IDS2017 and UNSW-NB15. In their framework, Stage 2 groups malicious traffic into four attack families based on a NIST-inspired taxonomy [25]. This taxonomy groups attacks according to their intent into Reconnaissance, Access, Denial of Service, and Malware.
In contrast, another direction defines intermediate groups using an error-driven strategy rather than predefined taxonomies. In [26], the authors derived the grouping from the confusion matrix of a baseline flat classifier on UNSW-NB15. Attack classes with lower detection performance, namely DoS and Exploit, are isolated into a dedicated group, while the remaining classes are assigned to a second group. This strategy therefore organizes the hierarchy according to detection difficulty rather than attack semantics.
A further three-stage variant in [27] introduced explicit handling of unknown attacks: Stage 1 still separates benign and attack traffic, Stage 2 distinguishes known from unknown attacks using one-class classifiers, and Stage 3 performs multi-class classification over known attacks while clustering unknown ones for iterative retraining. This architecture is evaluated on a broad range of IDS datasets, including NSL-KDD, ToN-IoT-Network, ToN-IoT-Linux, CIC-DDoS2019, CIC-DDoS2017, and UNSW-NB15.
Beyond explicit multi-stage designs, some IDS frameworks can also be regarded as hierarchical because they rely on cascaded binary decompositions, particularly one-vs-rest strategies. For example, Mohd et al. in [28] implemented a cascaded hierarchy on KDD’99 through successive binary splits between five traffic categories: Normal, DoS, R2L, U2R, and Probing. Several classifiers were evaluated within this structure, and high detection accuracy was reported. Similarly, ElDahshan et al. in [29] adopted a cascaded decomposition on UNSW-NB15 and CICIDS2017, where the original multi-class task is reformulated as a sequence of binary classification problems. Each binary classifier was implemented using an extreme learning machine model optimized through metaheuristic algorithms, and the final intrusion label is obtained by aggregating the outputs of the binary classifiers.
The studies most closely related to the BHM-IDS framework are summarized in Table 1.

2.2. Multi-Dataset Training for ML-Based IDSs

A limited but emerging line of research has begun to examine multi-dataset training as a means to alleviate the limitations of training IDS models on a single benchmark.
In [36], the authors introduced Reliable NIDS (R-NIDS) and proposed UNK22, a dataset constructed by merging three widely used benchmarks: UGR’16, UNSW-NB15, and NSL-KDD. Their results show that models trained on the combined dataset outperform those trained on each constituent dataset separately. The authors further evaluate the trained models on samples drawn from the individual source datasets and present this setting as cross-dataset validation. However, because these datasets are already included in the merged training corpus, this setting does not fully capture generalization to an independent and previously unseen environment. Similarly, the authors in [24] merged CIC-IDS2017 and UNSW-NB15 to enable training on a more heterogeneous corpus and reported strong performance under intra-dataset validation. Nevertheless, in both studies, the effect of dataset integration on cross-dataset generalization remains insufficiently examined, since evaluation is mainly confined to the merged or constituent datasets and does not include an additional independent benchmark reserved for unseen traffic.
A comparative summary of these studies is provided in Table 2, highlighting the merged datasets, architectural design, adopted ML/DL models, and validation setting.
Overall, all the studies presented in the two preceding subsections report strong performance under intra-dataset validation; however, they do not incorporate cross-dataset validation to assess generalization to unseen environments. Only a limited number of studies, generally based on simpler models, explicitly address this issue. These studies are discussed in the next subsection.

2.3. Generalization in ML-Based IDSs

Recent works have increasingly emphasized the need to assess and improve generalization in IDSs. This issue has become a central concern in modern IDS research.
In [37], the authors examined cross-dataset generalization across UNSW-NB15, CIC-CSE-IDS2018, BoT-IoT, and ToN-IoT datasets, showing that performance depends strongly on the train–test dataset pairing. UNSW-NB15 and CIC-CSE-IDS2018 showed better mutual transferability, while BoT-IoT exhibited weaker generalization with the other datasets.
A similar conclusion is reported in [38], where the authors conducted an extensive cross-dataset analysis of four classifiers across CIC-IDS2017, CSE-CIC-IDS2018, LycoS-IDS2017, and LycoS-Unicas-IDS2018 datasets. While intra-dataset evaluation yields near-perfect performance, cross-dataset testing reveals substantial degradation that depends strongly on the train–test pairing. The weakest generalization is observed when training on LycoS-IDS2017 and testing on LycoS-Unicas-IDS2018, whereas the strongest transfer occurs when training on CSE-CIC-IDS2018 and testing on CIC-IDS2017.
A comparable finding regarding the favorable transfer from CSE-CIC-IDS2018 to CIC-IDS2017 is reported in [39,40]. In [39], the authors investigated IDS generalization using four unsupervised anomaly detection methods. Their results showed that generalization remains challenging even between closely related benchmarks and that transfer performance is highly direction-dependent. Similarly, Ref. [40] proposed a few-shot intrusion detection framework that integrates multi-domain feature fusion, a bidirectional cross-attention mechanism, and a modified Mamba-based hierarchical encoder. Experimental evaluation was conducted as a five-class multiclass intrusion detection task, where the proposed approach demonstrated strong cross-dataset generalization.
Extending this line of analysis, Layeghy et al. in [41] evaluated supervised and unsupervised models on UNSW-NB15, CIC-CSE-IDS2018, ToN-IoT, and BoT-IoT datasets. They benchmarked eight models, including tree-based learners, neural networks, and unsupervised anomaly detectors. Their results show that no single model generalizes consistently across all train–test combinations and that generalization is often highly asymmetric. Overall, unsupervised methods tend to generalize better than supervised ones.
A comparative summary of generalization-oriented studies discussed in this subsection is provided in Table 3.

2.4. Research Gaps and Motivation

Across the studies presented in the above subsections, several fundamental gaps emerge that directly motivate our work. Prior architectural advances, whether based on flat models or hierarchical designs, have almost exclusively been trained and evaluated in intra-dataset settings. As a result, their findings provide limited insight into robustness on unseen data, particularly how a hierarchical architecture can affect generalization. Another line of work combines multiple IDS datasets for training, but this is usually done to increase data volume, without rigorously quantifying how such multi-dataset training impacts generalization. In parallel, studies that explicitly examine generalization predominantly play a diagnostic role by documenting performance scores of relatively simple models when moving to new environments, but they rarely propose concrete techniques or architectural strategies dedicated to improving generalization.
By proposing BHM-IDS, we treat hierarchical design and multi-dataset training not merely as simple architectural or data-related choices but as dedicated generalization strategies. Together, these strategies target generalization from two complementary angles: one shapes the structure of the learned representations and enables the model to learn more transferable patterns, while the other broadens their coverage across diverse traffic types. To the best of our knowledge, BHM-IDS is the first framework to explicitly couple these two strategies with the goal of improving cross-dataset generalization, moving beyond purely descriptive studies and providing a concrete, empirically validated design that addresses a central limitation of current IDS research.

3. BHM-IDS Framework: Design and Methodology

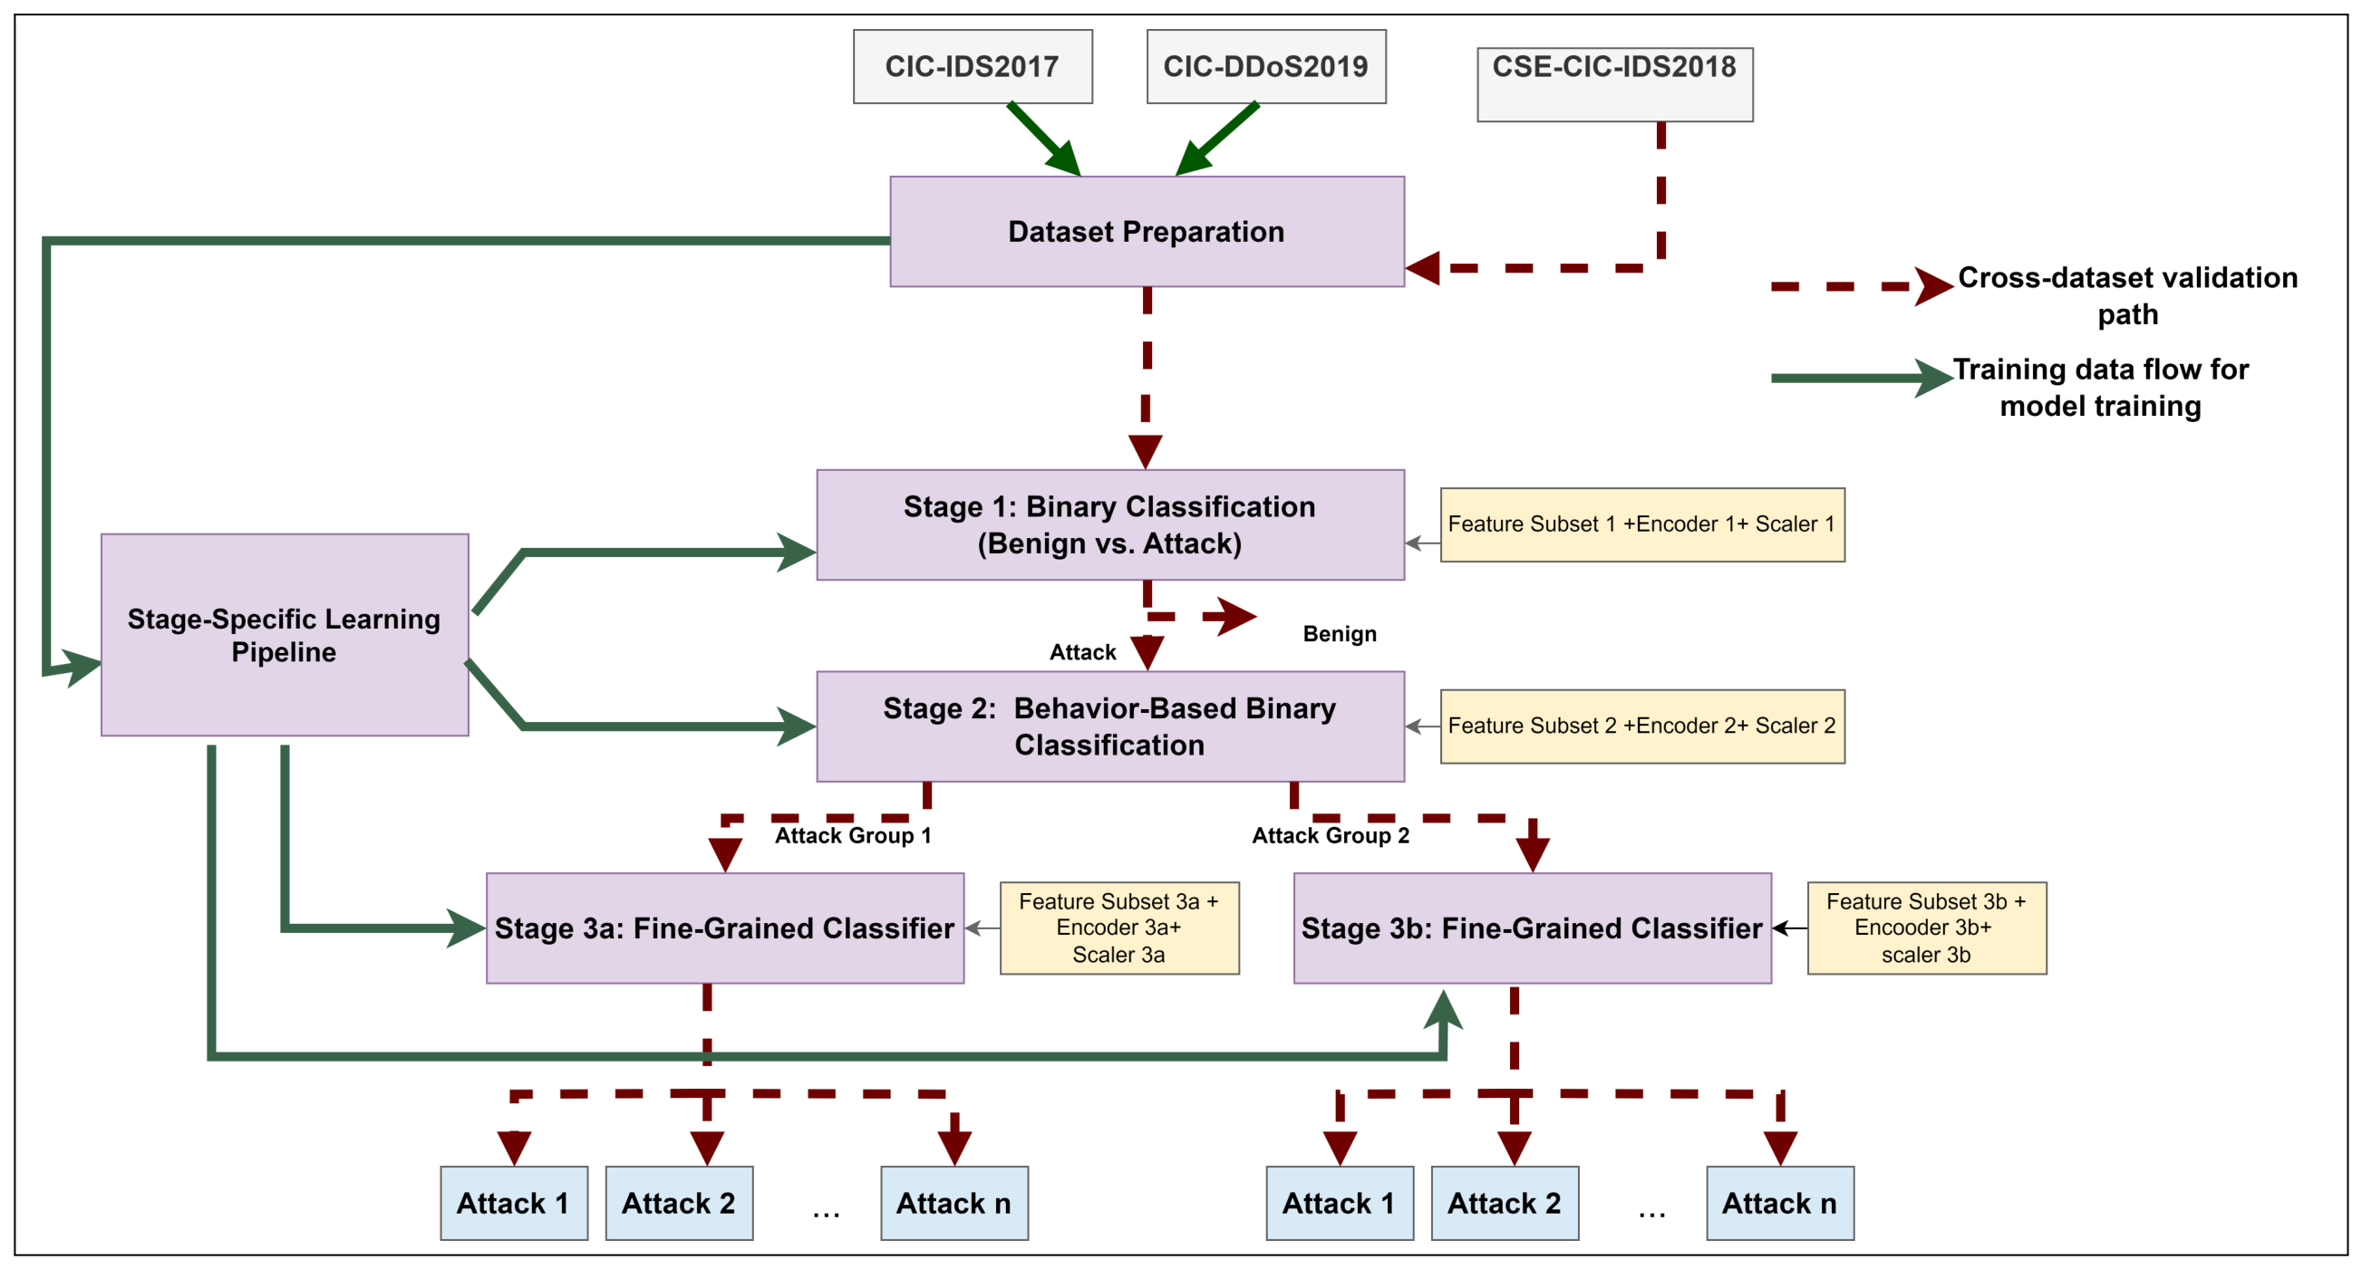
This section presents the proposed BHM-IDS framework. As illustrated in Figure 1, it encompasses a comprehensive pipeline that covers all design and evaluation steps, including dataset preparation for multi-dataset training, the behavior-based three-stage hierarchical architecture, and cross-dataset generalization assessment. Beyond these main steps, BHM-IDS employs stage-specific learning pipelines, where each stage uses tailored features, class-balancing strategies, and scaling techniques. The following subsections describe each component in detail.

3.1. Hierarchical Design and Behavioral Grouping

Our framework follows a three-stage hierarchical design inspired by prior three-stage IDS architectures, while differing fundamentally in the technique used to group malicious traffic at the second stage. Instead of relying on predefined semantic taxonomies, such as Cyber Kill Chain or NIST-inspired grouping, BHM-IDS adopts a behavioral grouping strategy. The goal is to structure malicious traffic according to how it manifests in network flow data and to capture behavioral properties that are expected to remain more stable across environments.
More precisely, attacks are divided into two broad behavioral groups. The first group corresponds to flood and exhaustion attacks, typically characterized by high-volume, high-rate, repetitive packet patterns targeting a specific service or host. The second group comprises infiltration and exploitation attacks, which are generally associated with low-to-normal volume, session-level, directional, and often protocol-compliant interactions.
Based on this grouping, Stage 3 performs fine-grained classification using two dedicated classifiers, each trained only on the attack classes belonging to one group. This design reduces the complexity of the decision space and limits interference between behaviorally different attacks. As a result, the classifiers at all stages are better positioned to learn robust decision boundaries that are more closely aligned with stable traffic-level properties, thereby improving the transferability of the learned patterns across datasets.
To further justify this design choice, Table 4 compares the proposed behavioral grouping with the Cyber Kill Chain and NIST-based grouping. Unlike these semantic strategies, the proposed grouping is grounded in observable traffic behavior. This makes it more closely aligned with the feature space learned by the model and less dependent on contextual interpretation or dataset labeling conventions. As a result, it offers greater stability across datasets, better captures intrinsic behavioral similarities and differences between attacks, and provides a more suitable basis for ML representation learning.

3.2. Multi-Dataset Training and Generalization Assessment

In addition to the behavior-based hierarchical design, generalization is further strengthened through multi-dataset training. We adopt an enrichment strategy in which CIC-IDS2017 is combined with CIC-DDoS2019.
CIC-IDS2017 serves as the primary dataset, providing a diverse set of attack categories. However, it contains a relatively limited representation of DDoS attack patterns. To compensate for this limitation, CIC-DDoS2019 is incorporated as a complementary source, as it focuses specifically on a wide variety of DDoS attack types. This enrichment is particularly important given the high variability of DDoS attacks across environments.
To evaluate whether the proposed framework can generalize beyond the datasets used during training, CSE-CIC-IDS2018 is employed as an external cross-environment test set.
The objective of this work is not to exhaustively evaluate all existing IDS datasets, but rather to demonstrate, in a coherent and practically meaningful setting, that the proposed behavioral hierarchical design combined with multi-dataset training improves cross-dataset generalization. From this perspective, the adopted three-dataset configuration represents a deliberate and balanced compromise between methodological consistency and controlled evaluation. In particular, the choice of CIC-IDS2017 as a core training dataset, and the evaluation of the framework on a richer and more complex dataset such as CSE-CIC-IDS2018, is in itself a challenging setting, which makes this evaluation especially relevant for validating the robustness of BHM-IDS.
While the framework is intended to remain dataset-agnostic, extending the analysis to a broader range of datasets is left for future work.

3.3. Dataset Preparation

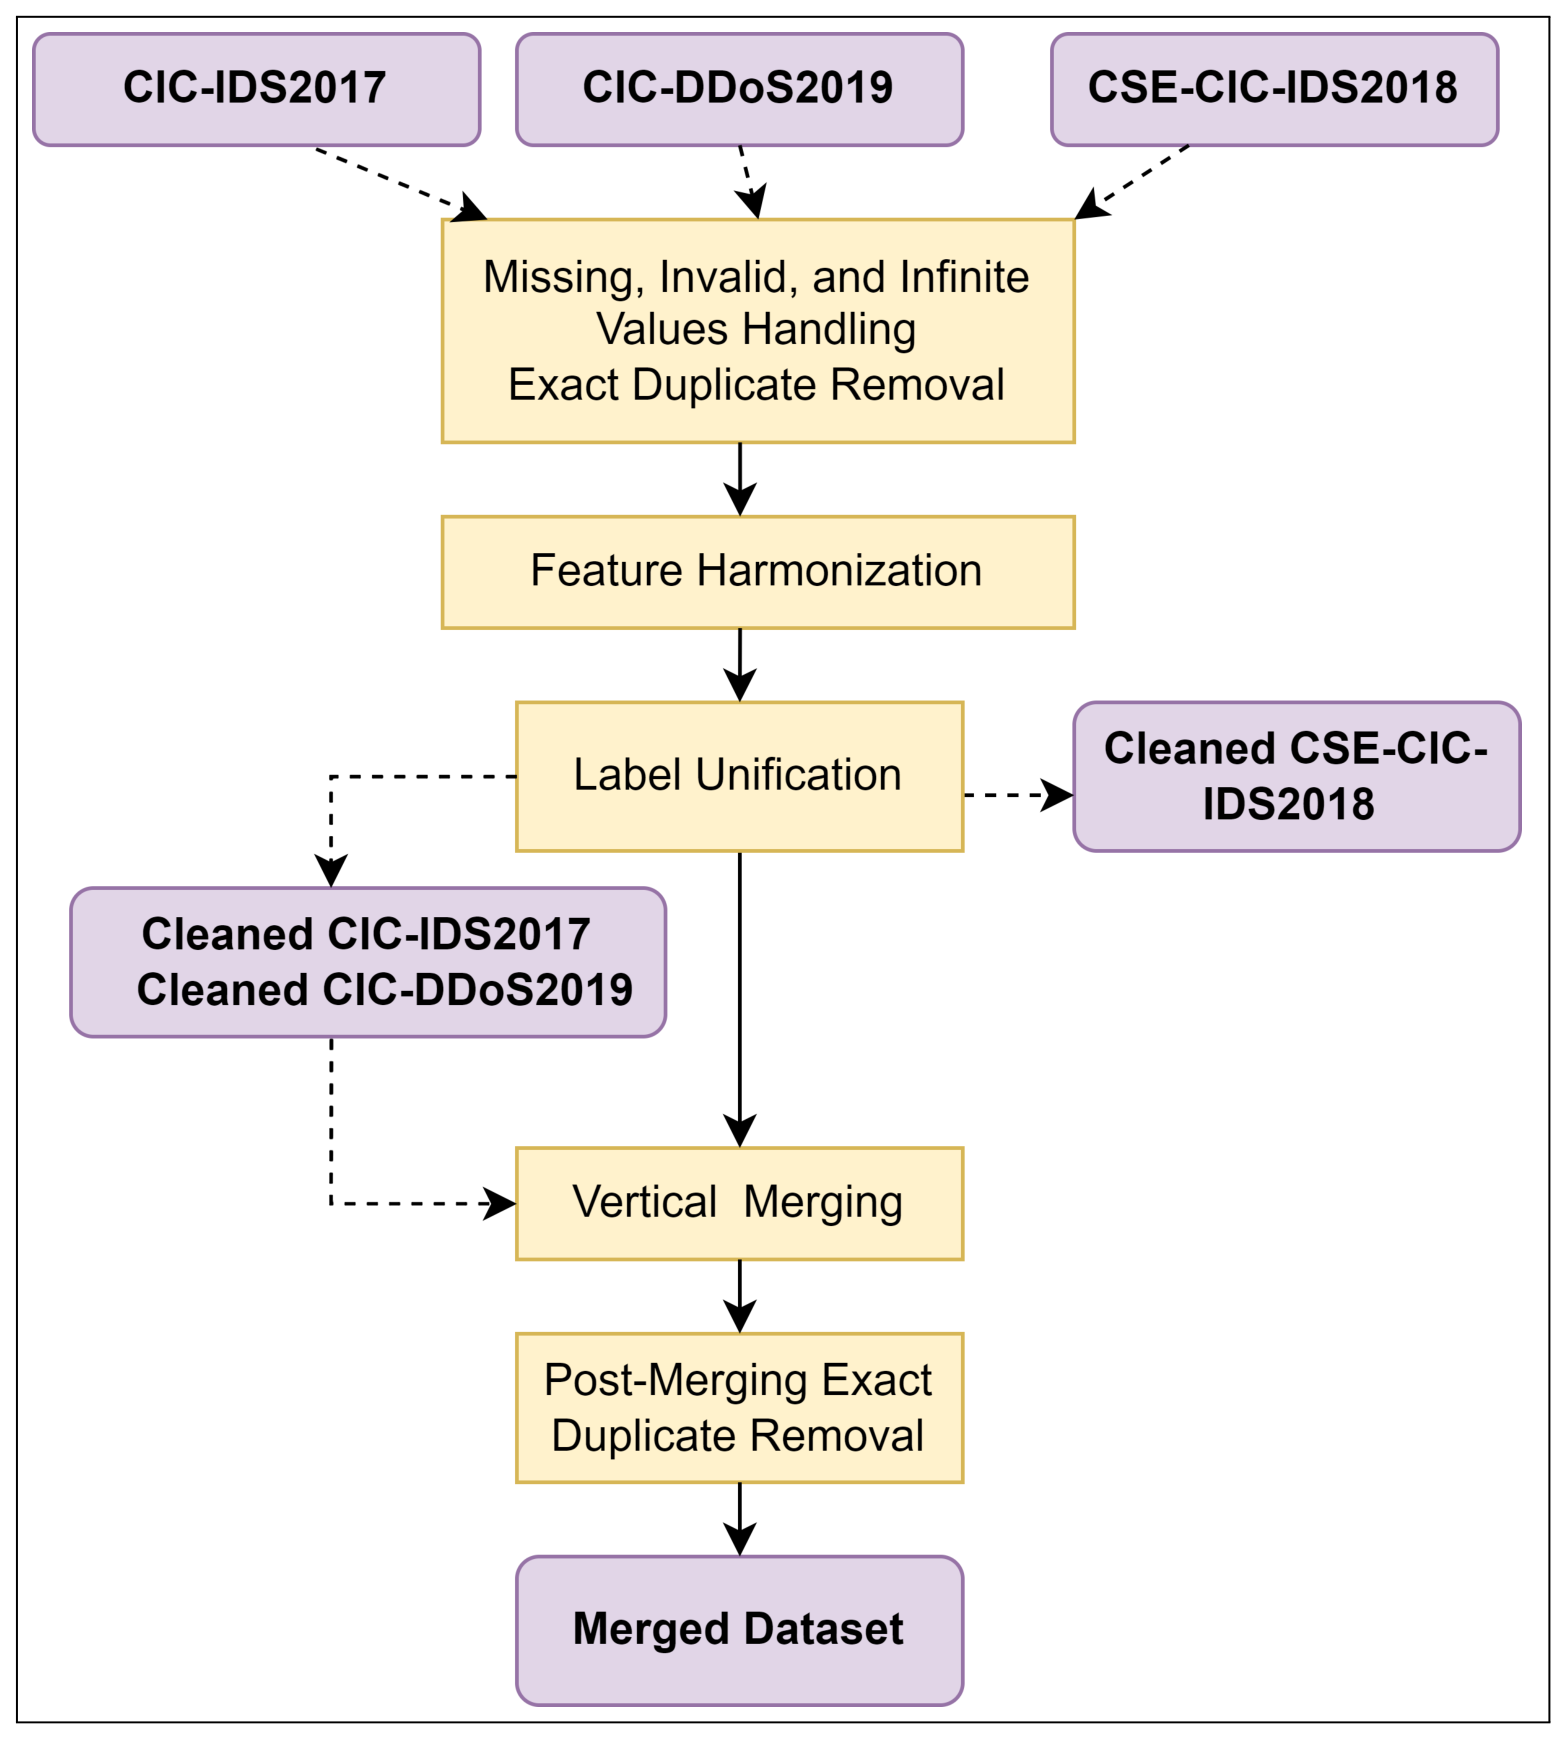
Multi-dataset training and cross-dataset evaluation require a structured and consistent preparation of the three selected datasets: CIC-IDS2017, CIC-DDoS2019, and CSE-CIC-IDS2018. As illustrated in Figure 2, the preparation procedure was organized into many consecutive stages: dataset-specific cleaning, feature harmonization, label unification, merging of the two training datasets, and post-merging exact duplicate removal. Each dataset was first cleaned independently by handling missing, invalid, and infinite values and eliminating exact duplicate records. Performing this initial cleaning separately preserved the original structure of each dataset and enabled the number of removed and retained observations to be documented for every dataset.
Following dataset-specific cleaning, feature harmonization was conducted across all three datasets to establish a common and consistent feature space. Feature correspondence was determined according to semantic equivalence rather than name similarity alone; therefore, the feature definition, traffic direction, measurement unit, and data type were verified before two attributes were considered equivalent. After equivalent features had been renamed consistently, only the features available in all three datasets were retained.
Once the common feature space had been established, label unification was subsequently performed to create a consistent target taxonomy across CIC-IDS2017, CIC-DDoS2019, and CSE-CIC-IDS2018, which use different naming conventions and levels of class granularity. The original attack labels were mapped to five unified categories: DoS, DDoS, Patator, Bot, and Web Attack. As summarized in Table 5, each category groups attack subtypes that share a common attack mechanism. Specifically, the DoS category includes GoldenEye, Slowloris, Hulk, and SlowHTTPTest; the DDoS category includes LOIC-HTTP, LOIC-UDP, and HOIC; the Patator category includes SSH-Patator and FTP-Patator; the Bot category contains botnet-related traffic; and the Web Attack category groups Web Brute Force, XSS, and SQL Injection.
These five unified categories define the final attack-label taxonomy used throughout model training and evaluation. Because CIC-DDoS2019 is focused on DDoS scenarios and represents them through multiple fine-grained flooding, reflection, and amplification subtypes, all retained attack labels from this dataset were mapped to the unified DDoS category, as detailed in Table 6.
Following the establishment of a common feature space and a unified attack-label taxonomy, CIC-IDS2017 and CIC-DDoS2019 were vertically concatenated to construct the merged dataset. A second exact duplicate-removal step was subsequently performed on the integrated data, as observations originating from different source datasets could become identical after being represented within the common aligned feature space. The resulting dataset was then used as input to the stage-specific learning pipelines, as presented in the following subsection.

3.4. Stage-Specific Learning Pipeline

This subsection describes the stage-specific learning pipelines adopted in BHM-IDS. Each stage is treated as an independent learning problem, with its own data split, label-encoding procedure, feature subset, class-balancing strategy, and scaling method.
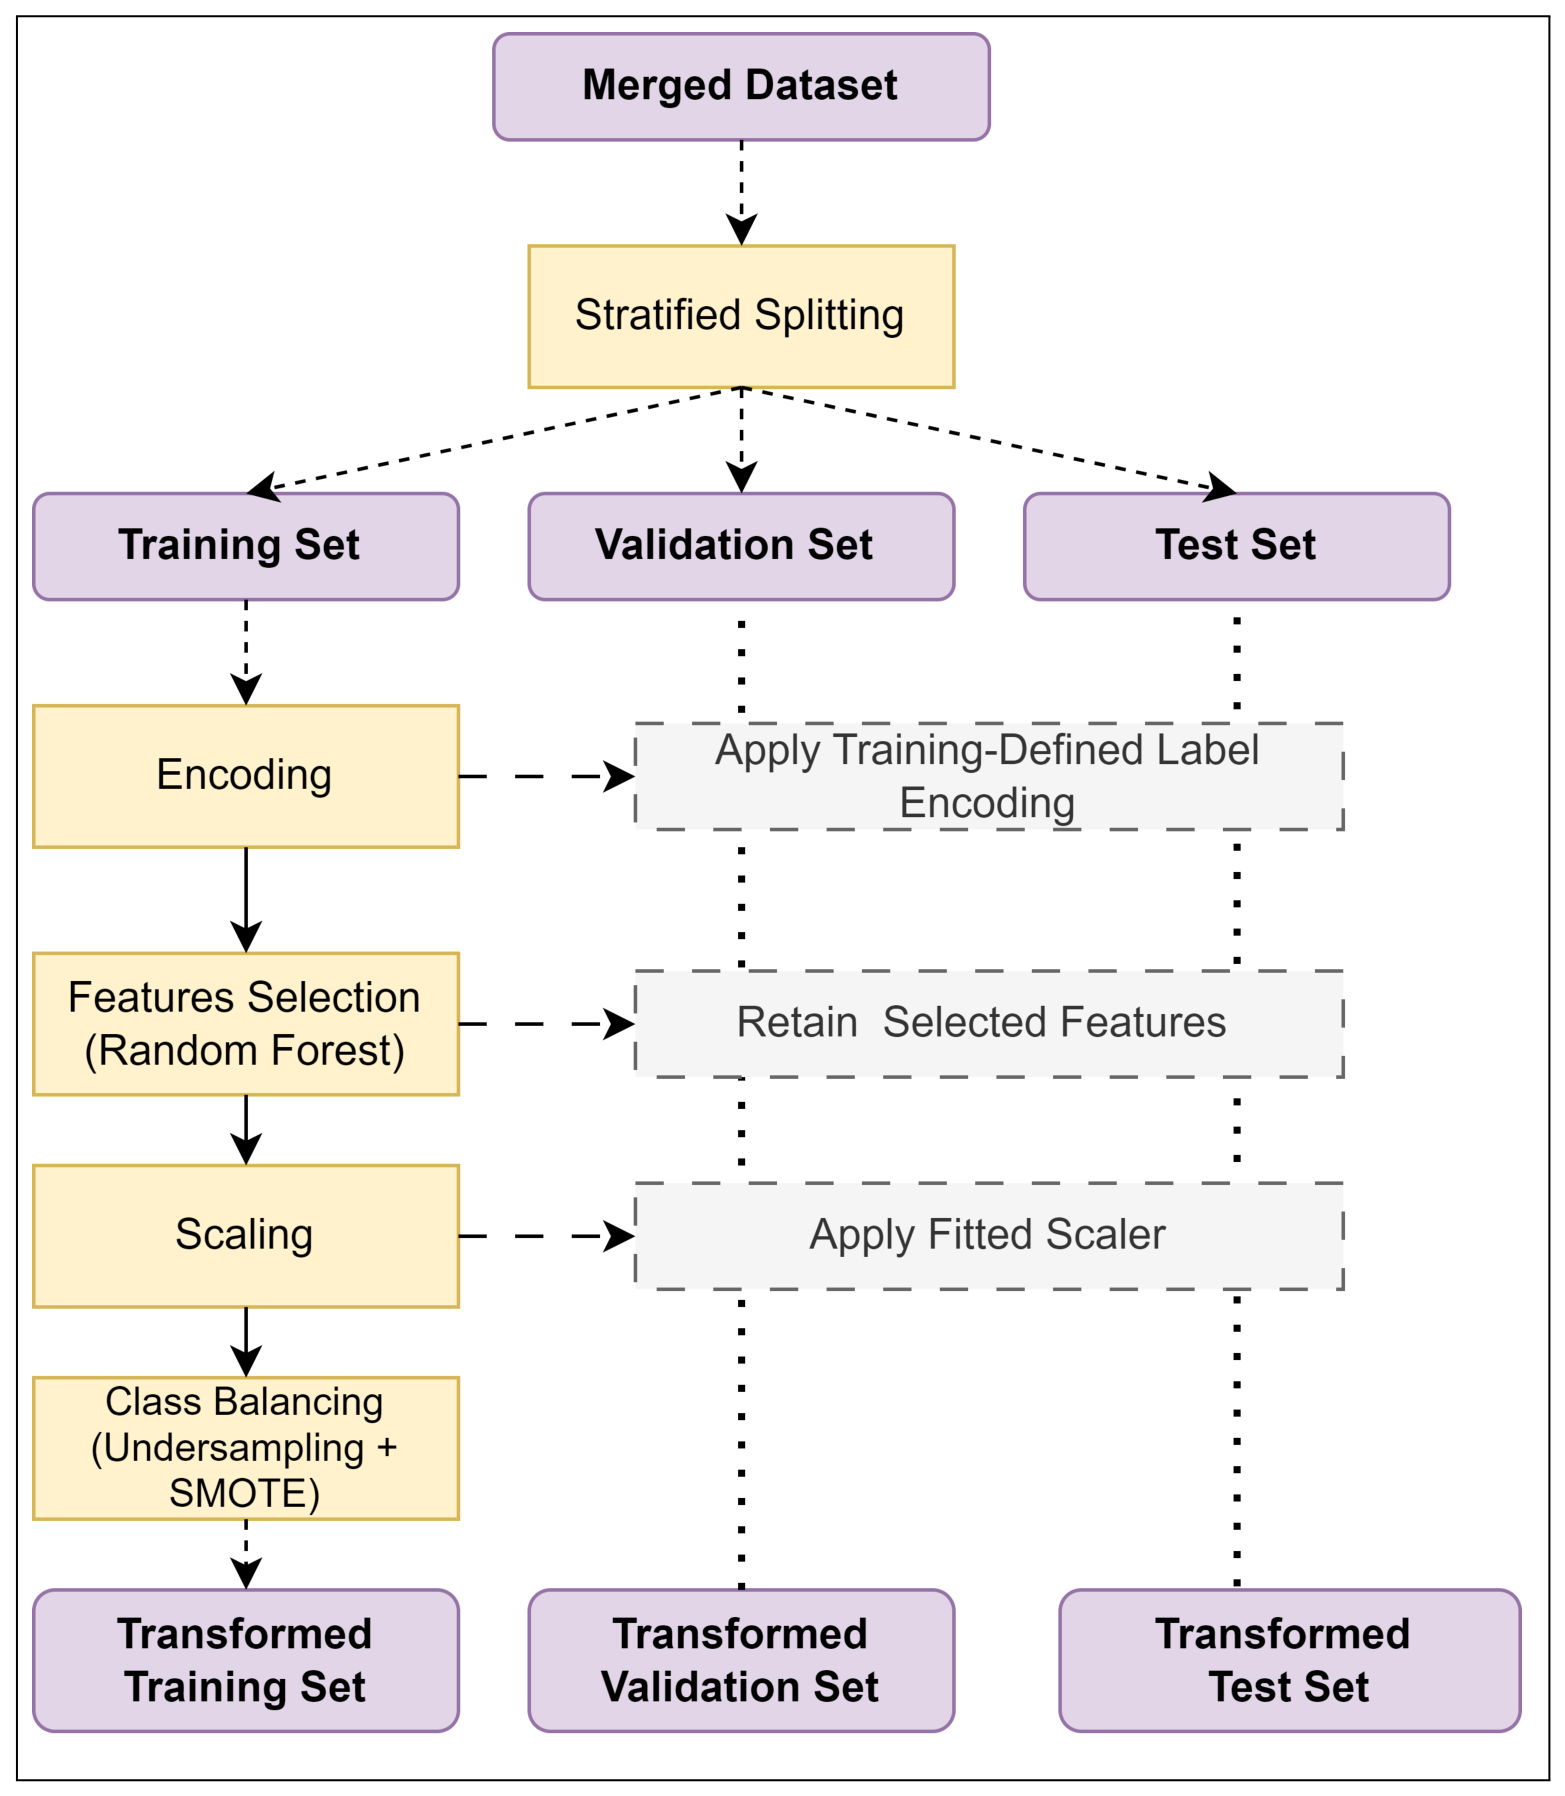
As illustrated in Figure 3, the stage-specific learning pipeline begins by dividing the corresponding dataset into training, validation, and test subsets using a stratified 70%–10%–20% split. Stratification preserves the class proportions associated with each classification stage. Importantly, data splitting was performed before applying any transformation to prevent data leakage and preserve the independence of validation and test subsets from all information learned during model development.
Following data partitioning, class labels were numerically encoded using a separate stage-specific LabelEncoder. Feature selection was then performed using importance scores obtained from a Random Forest model. The features were ranked in descending order of importance, and candidate subsets comprising the top 20 to 55 features, evaluated in increments of five, were assessed using stratified five-fold cross-validation. The optimal subset size was defined as the one achieving the highest mean macro-recall across the validation folds, thereby favoring balanced predictive performance across all classes.
The retained training features were then scaled using parameters estimated solely from the training subset. Thus, as indicated by the three branches in Figure 3—Apply Training-Defined Label Encoding, Retain Selected Features, and Apply Fitted Scaler—the encoding scheme, selected feature subset, and scaler are consistently applied to both the validation and test subsets.
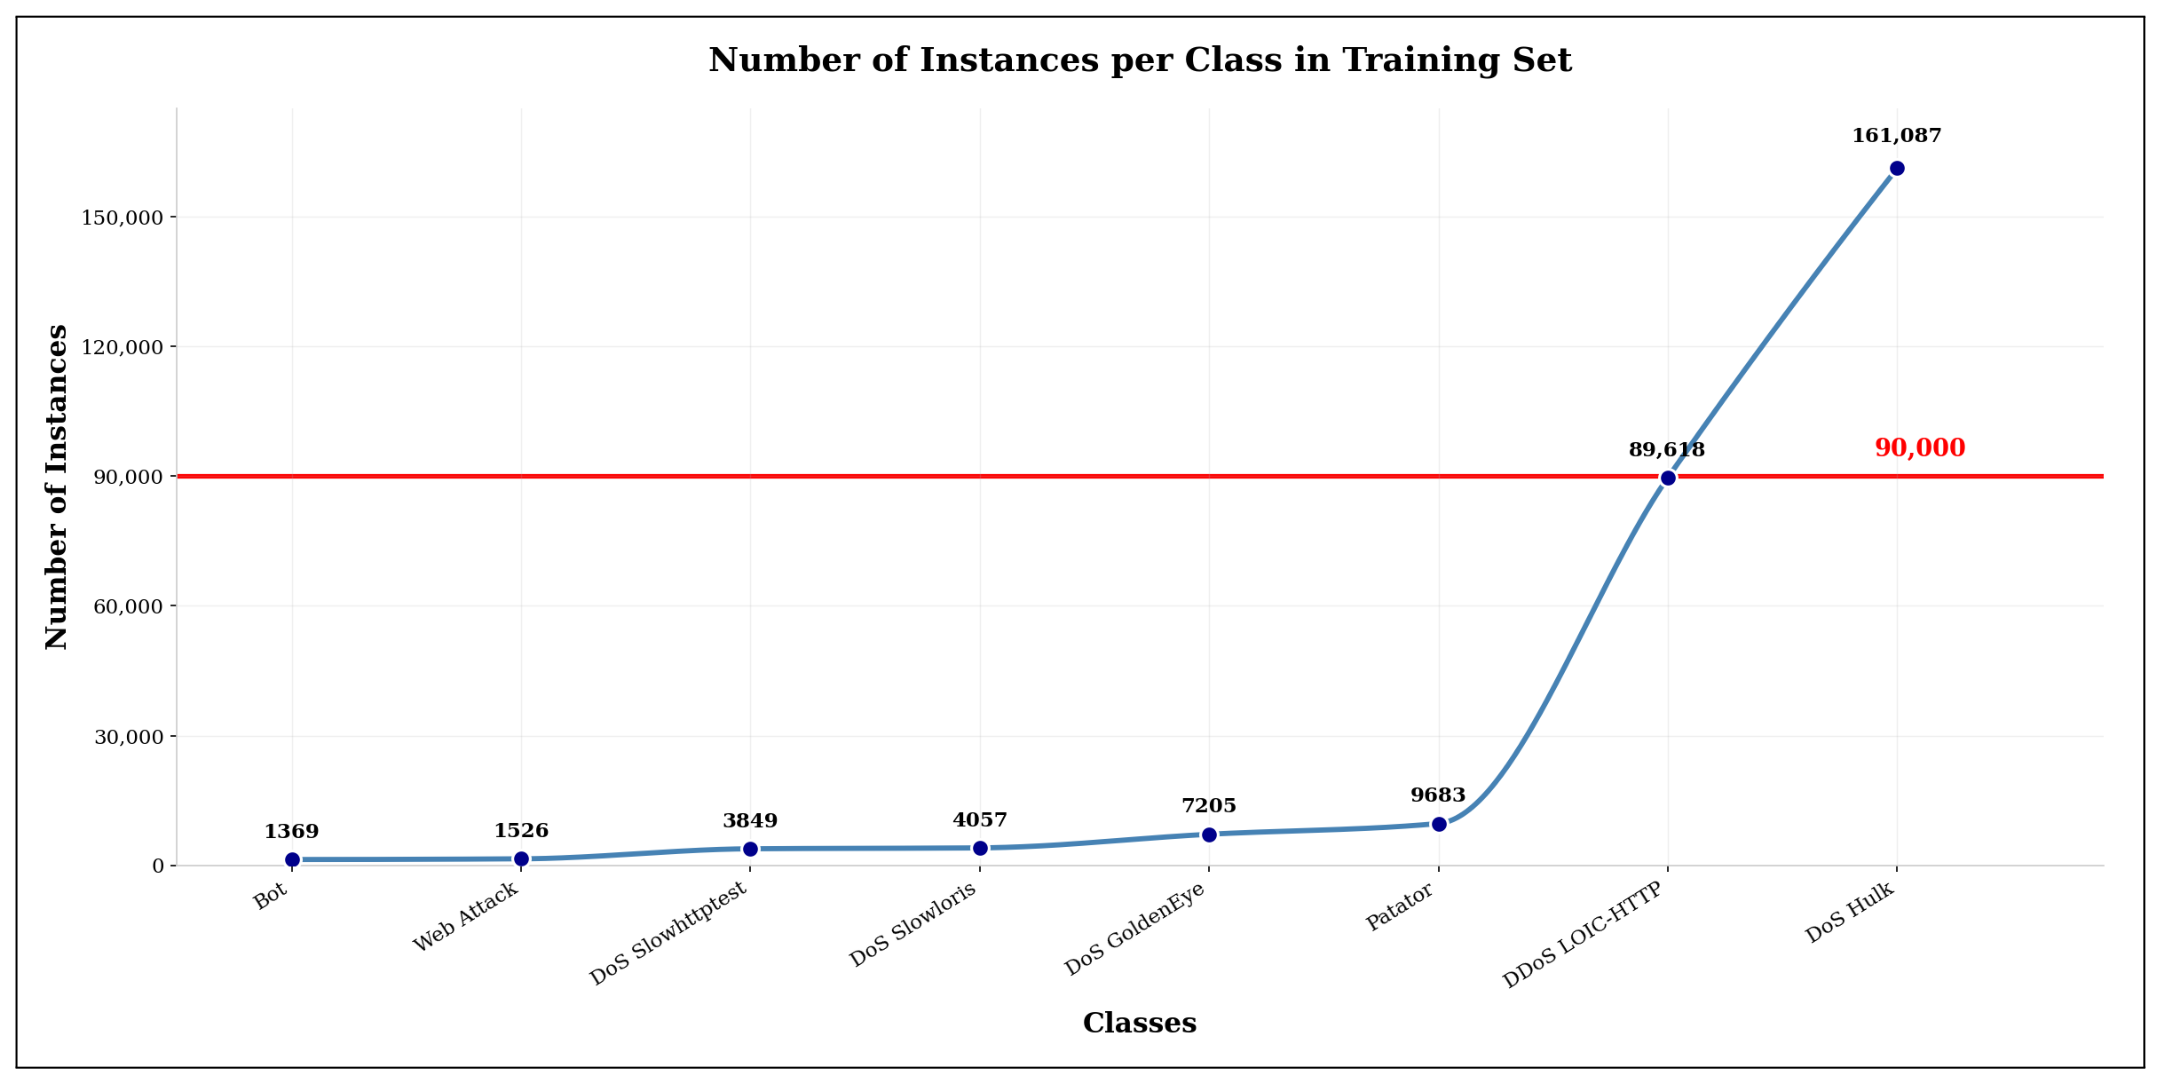
Finally, class imbalance was addressed exclusively within the training set through a hybrid resampling strategy combining majority-class undersampling and SMOTE-based minority-class oversampling. Random undersampling was performed using a fixed random seed of 42 without replacement, meaning that each retained majority-class sample was selected only once and no duplicate samples were introduced. SMOTE was configured with five nearest neighbors and the same fixed random seed of 42. As illustrated in Figure 4, the 90,000 threshold aligns almost exactly with the natural size of DDoS LOIC-HTTP, the second-largest class, thereby grounding this choice in the observed data distribution. By restricting undersampling to a single class, DoS Hulk, at a moderate rate of 44%, and keeping minority-class oversampling ratios well below those required by a higher threshold, 90,000 represents an equilibrium point that minimizes both information loss from the majority class and excessive dominance of synthetic minority samples.

3.4.1. Stage 1

As the entry point of BHM-IDS, Stage 1 performs a binary classification that separates benign from malicious traffic. At this level, all attack instances, regardless of their specific type, are merged into a single attack category, yielding a binary labeling scheme (Benign vs. Attack). This stage relies on a dedicated subset of 40 features. Min–Max scaling was applied to normalize all continuous features. Table 7 summarizes the ten most influential features identified for this stage, while the complete list of selected features is provided in Appendix A, Table A1.
To address class imbalance, benign traffic was undersampled to 540,000 samples to reduce its disproportionate influence on model training. Although this stage operates on a binary separation between benign and attack traffic, each attack type was individually balanced. For minority attack classes, namely Patator, Web Attack, and Bot, oversampling was applied to raise each class to 90,000 samples. The DoS and DDoS classes were undersampled to 90,000 instances each. A total of 90,000 diversified DDoS samples were selected from CIC-DDoS2019 to ensure representative coverage of different DDoS attack behaviors. Consequently, the balanced training set contained a total of 540,000 attack samples.

3.4.2. Stage 2

This stage performs a behavior-based binary classification of malicious traffic, where attacks are classified according to the groups defined previously. Since this study considers five attack classes, namely DoS, DDoS, Web Attack, Bot, and Patator, each class is assigned to its corresponding behavioral group. DoS and DDoS are assigned to the flood and exhaustion group, as they aim to cause resource unavailability through sustained and repetitive traffic. Bot, Web Attack, and Patator are assigned to the infiltration and exploitation group, as they rely on protocol-compliant, session-level interactions to achieve their objectives.
This stage operates on a dedicated subset of 45 features. These features are scaled using a Robust Scaler, which centers each feature on its median and rescales it according to its interquartile range. The ten highest-ranked features from this subset are reported in Table 7; the full set of features retained for Stage 1 is listed in Appendix A, Table A2.
For class balancing, the DoS and DDoS classes from CIC-IDS-2017 and the DDoS class from CIC-DDoS-2019 are each undersampled to 90,000 instances and relabeled as Attack Group 1, while Patator, Web Attack, and Bot from CIC-IDS-2017 are each oversampled to 90,000 instances and relabeled as Attack Group 2.

3.4.3. Stage 3

At the final level of BHM-IDS, Stage 3 is responsible for fine-grained attack classification. It is decomposed into two specialized classifiers.
The first classifier distinguishes between DoS and DDoS traffic. The DoS class is constructed by combining the four DoS subtypes, with each subtype adjusted to 90,000 samples. Specifically, DoS GoldenEye, DoS Slowloris, and DoS Slowhttptest were oversampled to 90,000 instances each, while DoS Hulk was undersampled to the same size. The DDoS class is constructed by merging undersampled DDoS traffic from both datasets, comprising 90,000 samples from CIC-IDS2017 and 270,000 samples from CIC-DDoS2019.
Since CIC-DDoS2019 includes multiple DDoS variants, these 270,000 samples are selected in equal proportions from each attack type, ensuring a balanced representation of DDoS behaviors.
The second classifier is designed to distinguish among Patator, Web Attack, and Bot traffic. Since these classes are underrepresented compared with other attack categories, each class is oversampled to 90,000 instances.
Each Stage 3 classifier operates on its own dedicated subset of 40 features, with a separate Robust Scaler fitted for each classifier. The ten highest-ranked features selected for these classifiers are reported in Table 7, whereas the complete feature sets are provided in Appendix A, Table A3 and Table A4.

3.5. Learning Models and Hyperparameter Settings

To determine the most suitable classifier for each stage of the proposed hierarchy, three gradient-boosting algorithms were evaluated: XGBoost [42], CatBoost [43], and LightGBM [44]. Hyperparameter optimization was performed separately for each classifier and each stage because the stages address different classification tasks and may therefore require different model configurations. Two complementary optimization strategies were employed: Grid Search [45] and Optuna [46].
For both optimization strategies, candidate models were fitted using the training set and evaluated on the validation set. The optimization objective was to maximize validation macro recall, as this metric assigns equal importance to all classes. Grid Search exhaustively evaluated the 243 hyperparameter combinations defined for each algorithm in Table 8. In comparison, Optuna initiated 150 trials for each algorithm at each model position using the Tree-structured Parzen Estimator (TPE) sampler.
During Optuna optimization, a Median Pruner was employed to terminate trials exhibiting unpromising intermediate performance. Pruning was disabled during the first 10 completed trials and before the first 20 boosting iterations of each subsequent trial. In addition, early stopping with a patience of 20 boosting rounds was applied.
Accordingly, the optimization budget comprised 243 Grid Search evaluations and 150 initiated Optuna trials for each algorithm at each model stage. The final selected hyperparameters are reported in Table 8.

3.6. Evaluation Strategies and Performance Metrics

To assess both the effectiveness and generalization capability of BHM-IDS, two complementary evaluation strategies are adopted. First, intra-dataset evaluation is conducted on a combined test set derived from CIC-IDS2017 enriched with CIC-DDoS2019. Second, cross-dataset validation is performed using CSE-CIC-IDS2018 as a fully unseen test dataset.
In both evaluation settings, accuracy is reported together with complementary metrics that provide more informative insight into classification behavior.
Accuracy measures the overall proportion of correctly classified samples.
A c c u r a c y = T P + T N T P + T N + F P + F N .
Precision quantifies the ability of the classifier to avoid false alarms by measuring the correctness of positive predictions.
P r e c i s i o n = T P T P + F P .
Recall evaluates the capability of the system to detect actual attacks and minimize undetected intrusions.
R e c a l l = T P T P + F N .
F1 score is defined as the harmonic mean of Precision and Recall.
F 1 = 2 · P r e c i s i o n · R e c a l l P r e c i s i o n + R e c a l l .
Macro Recall evaluates the average capability of the system to detect actual instances of each class in a multi-class setting, giving equal importance to all classes regardless of their size.
M a c r o - R e c a l l = 1 C i = 1 C T P i T P i + F N i .

4. Results

We present our experimental results in three parts to assess BHM-IDS’s performance. First, we report intra-dataset evaluation results. Then, we examine generalization through cross-dataset validation on the target CSE-CIC-IDS2018 dataset. Finally, we provide an ablation study that isolates and verifies the performance gains attributed to behavior-based hierarchy and multi-dataset training.

4.1. Intra-Dataset Validation

Under intra-dataset validation, BHM-IDS achieves consistently high performance across all stages. At the first stage, the results reported in Table 9 indicate that LightGBM achieved the best overall performance, with an accuracy of 0.9987. It also obtained very high recall values of 0.9983 for benign traffic and 0.9992 for attack traffic, confirming its effectiveness as a first-line detector.
According to Table 10, the highest performance at Stage 2 is achieved by both CatBoost and LightGBM, which produce identical results with an overall accuracy of 0.9999. Both models also attain exceptionally high recall, reaching 0.9999 for Attack Group 1 and for Attack Group 2, thereby demonstrating highly reliable attack classification.
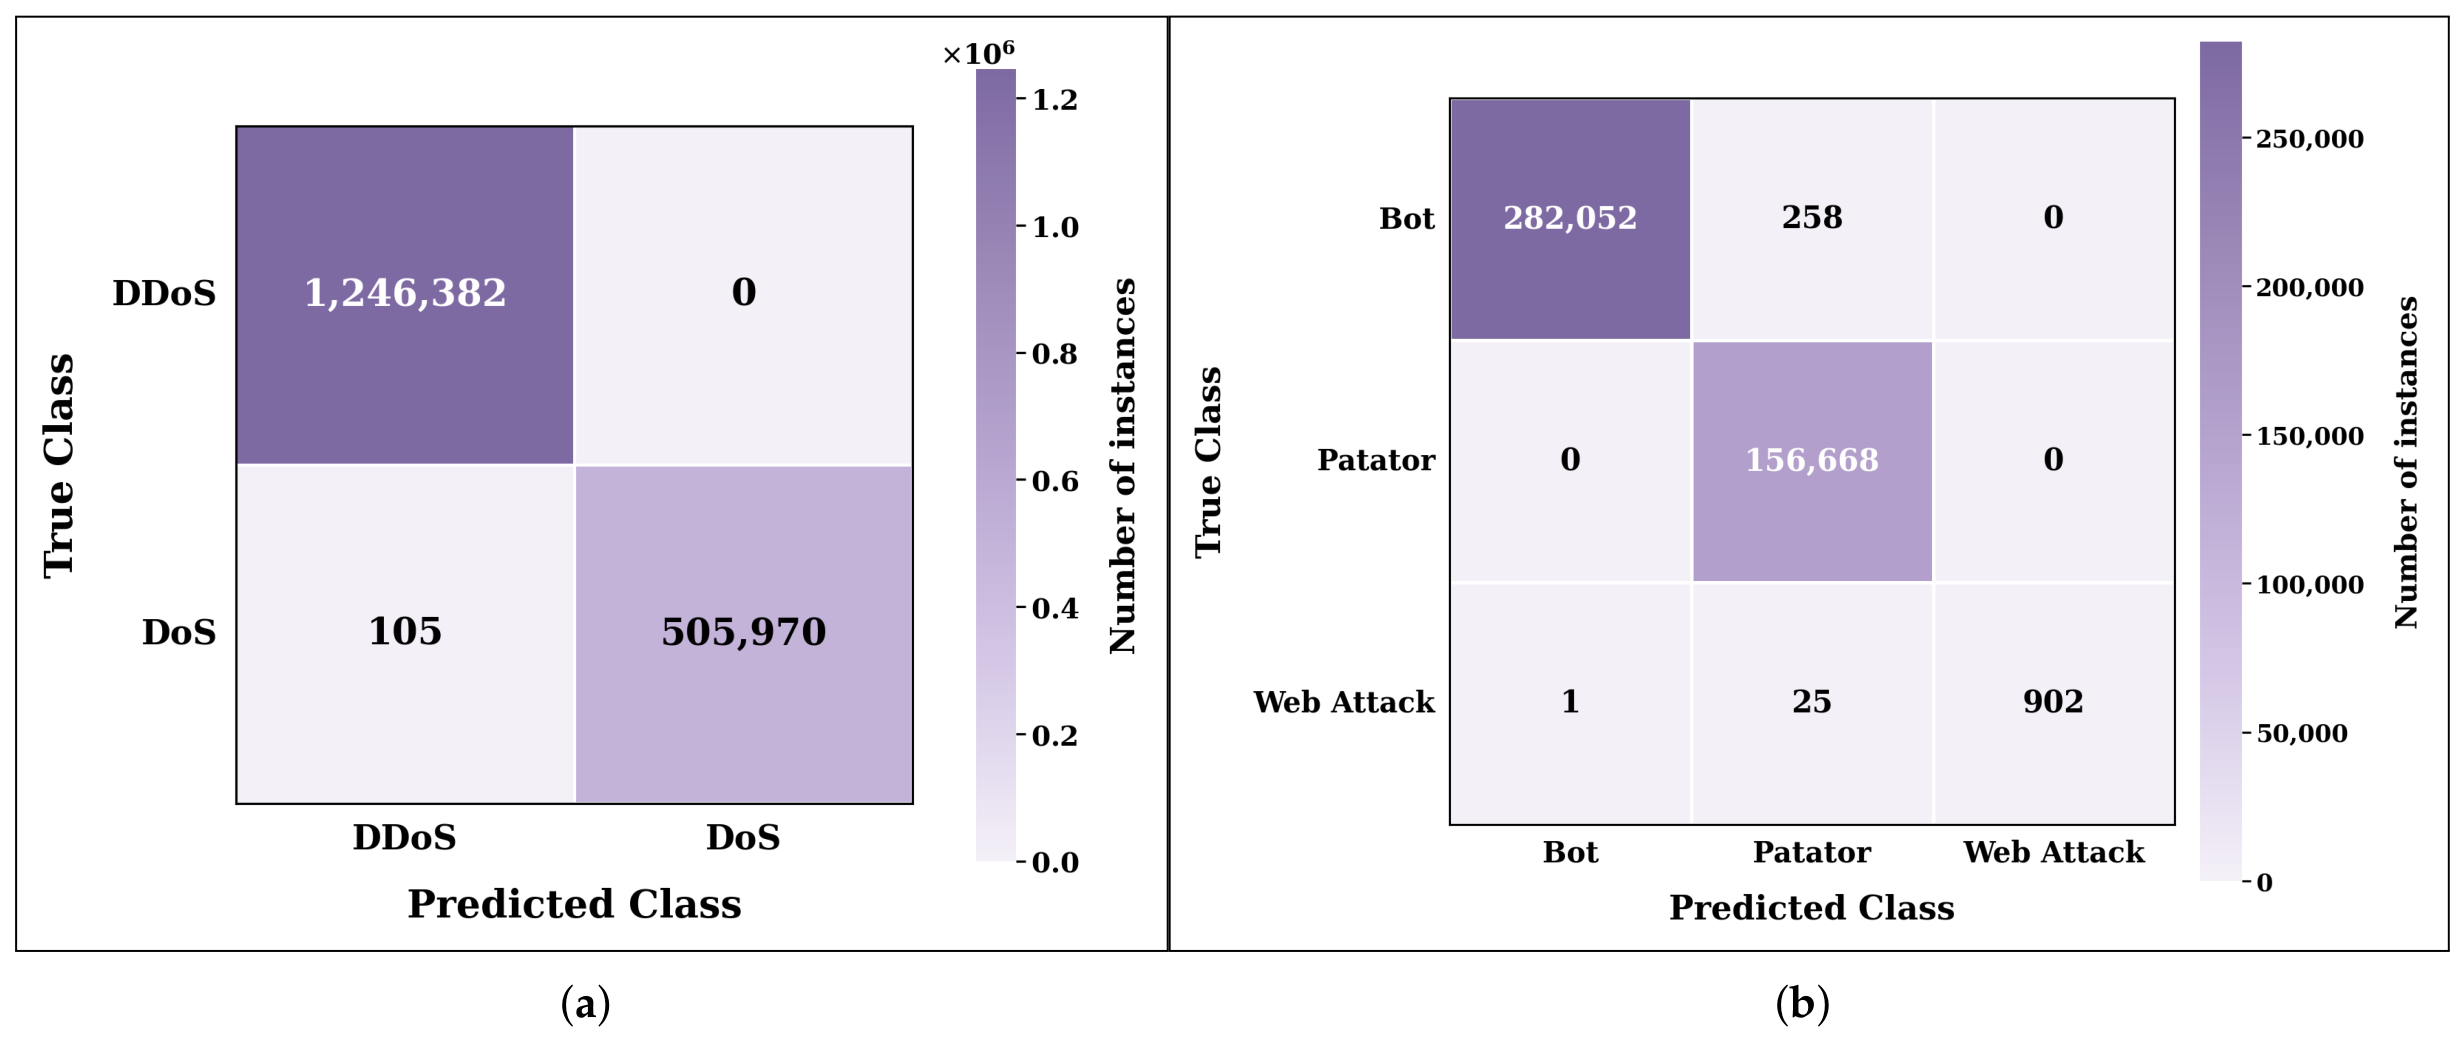
At the final stage, the DoS/DDoS classifier achieves its best performance with CatBoost, as shown in Table 11, with an accuracy of 0.9999 and recall values of 0.9999 for both classes. Similarly, Table 12 shows that, for the classifier dedicated to Bot, Web Attack, and Patator, all three ML models achieve identical perfect scores.

4.2. Cross-Dataset Validation

We now address the cross-dataset validation results. The performance of each stage is reported in detail, and the corresponding confusion matrices are provided to highlight the main sources of misclassification. This validation is conducted on 5,292,116 benign samples and 2,192,363 attack samples from CSE-CIC-IDS2018.
  • Stage 1:
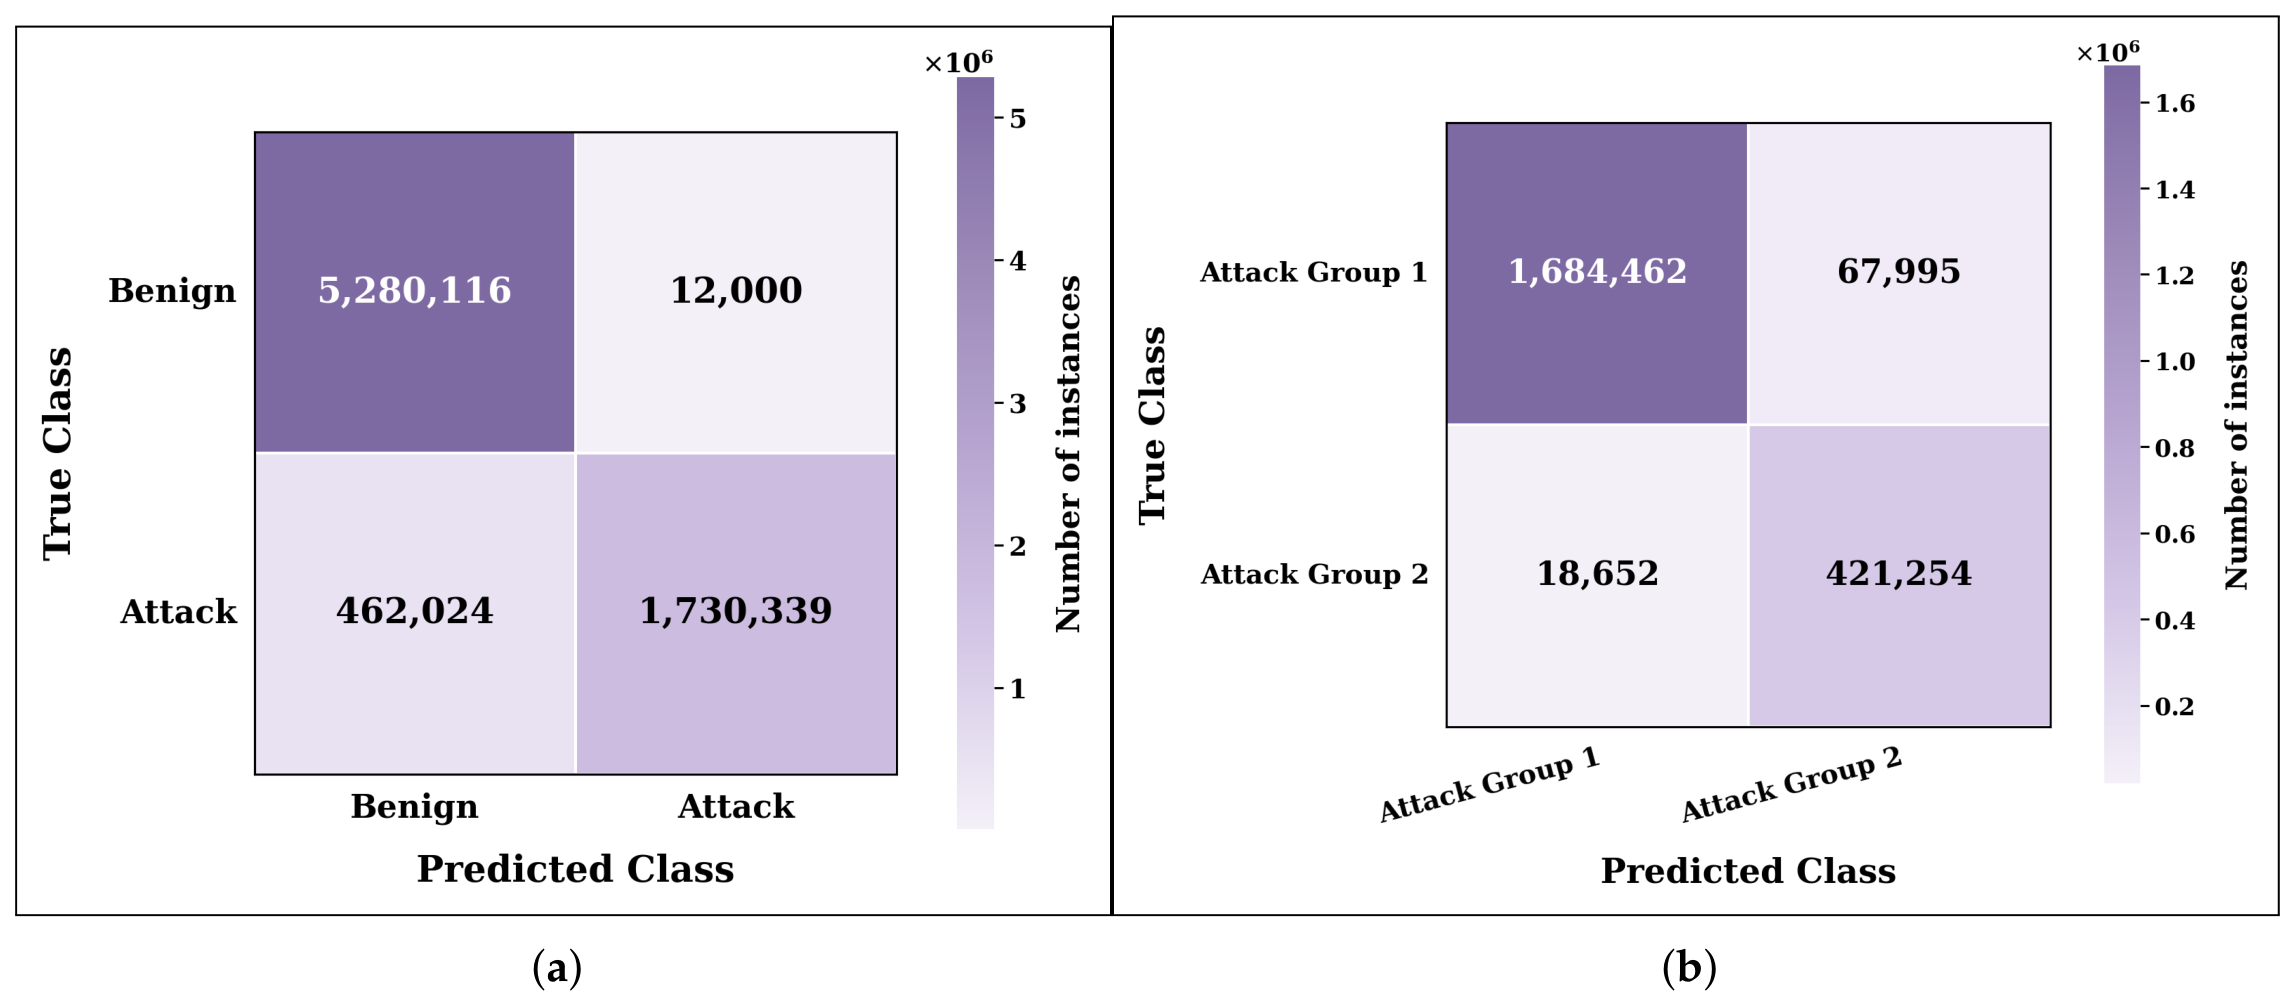
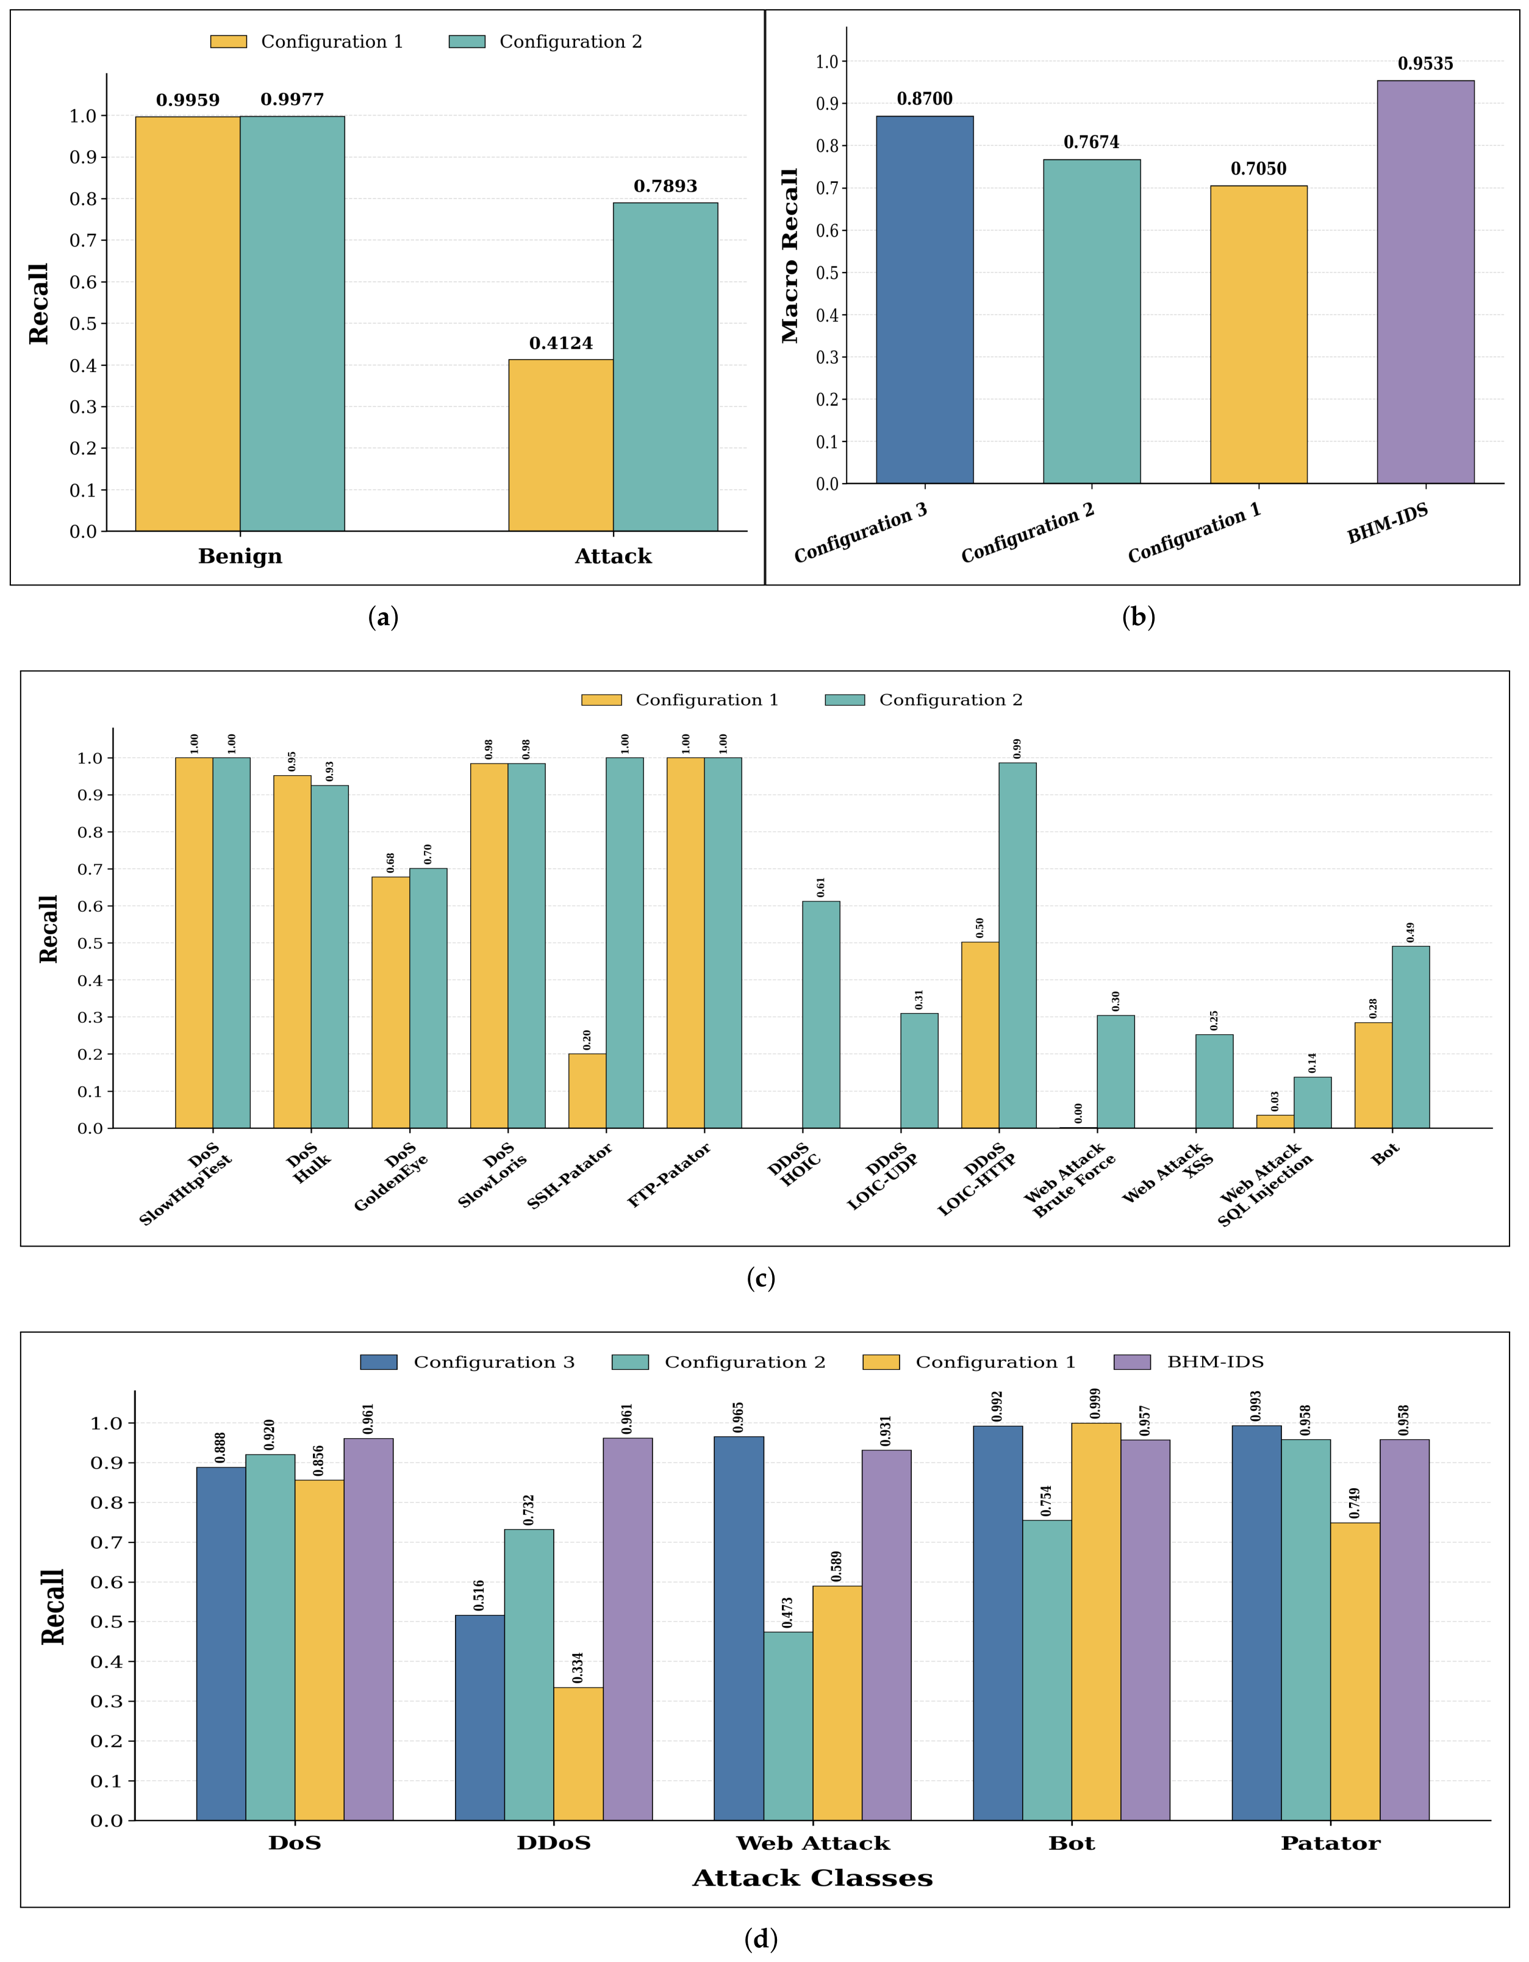
    The results reported in Table 13 present the cross-dataset comparison of XGBoost, CatBoost, and LightGBM. XGBoost provides the best overall performance, achieving the highest accuracy (0.9367). The main difference between the models appears in their ability to detect attack samples, where XGBoost reaches the highest Attack recall (0.7893), compared with LightGBM (0.6369) and CatBoost (0.5002). In contrast, all models achieve high recall for the Benign class, indicating that normal traffic is consistently well identified across the three classifiers. This behavior is consistent with the confusion matrix of XGBoost model in Figure 5a.
    To provide a more detailed analysis of Stage 1 performance, Table 14 reports the per-attack recall obtained by the XGBoost classifier. The results show that several attack categories are identified with near-perfect scores. In particular, recall reaches 1 for DoS SlowHttpTest, SSH-Patator, and FTP-Patator, while DoS Slowloris and DoS Hulk achieve recall values of 0.9845 and 0.9253, respectively. DDoS LOIC-HTTP is also detected with high reliability, reaching a recall of 0.9866. The results remain relatively lower for some other DDoS variants, Bot, and Web attack variants.
  • Stage 2: The results of the three models are summarized in Table 15. LightGBM achieves the best overall performance, with the highest accuracy (0.9604) and balanced recall for both attack groups. In particular, it maintains high recall for Attack Group 1 (0.9612) and Attack Group 2 (0.9576). This result is further supported by the confusion matrix in Figure 5b. XGBoost provides competitive results but remains slightly below LightGBM, whereas CatBoost shows weaker generalization due to its limited ability to detect Attack Group 2.
  • Stage 3: Under cross-dataset validation, Stage 3 classifiers exhibit excellent generalization performance, achieving near-perfect accuracy and consistently high recall. For the first classifier, dedicated to DoS/DDoS classification, CatBoost achieves the best overall performance, as shown in Table 16. It reaches an accuracy of 0.9999, with high recall values. This result is further supported by the confusion matrix in Figure 6a, which shows very little misclassification between the two categories.
    For the second classifier, which distinguishes between Web Attack, Bot, and Patator, XGBoost provides the most balanced results, as reported in Table 17. It attains an overall accuracy of 0.9994 while maintaining high recall across all classes. The corresponding confusion matrix in Figure 6b confirms this behavior.
    Finally, Table 18 reports the combined recall achieved by attack classification stages (Stage 2 and Stage 3). This metric serves as a crucial indicator of the system’s ability to correctly classify threats once they have passed the initial detection stage. It is calculated as the product of the class-specific recall values obtained from the best-performing models in Stage 2 and Stage 3. The results demonstrate high performance across all categories, with scores exceeding 0.96 for DoS and DDoS and remaining above 0.93 for Web attack, Bot, and Patator attacks. The final macro combined recall of 0.9535 further indicates that the proposed behavior-based design preserves strong attack classification capability under cross-dataset validation.

4.3. End-to-End Cross-Dataset Performance Evaluation of BHM-IDS

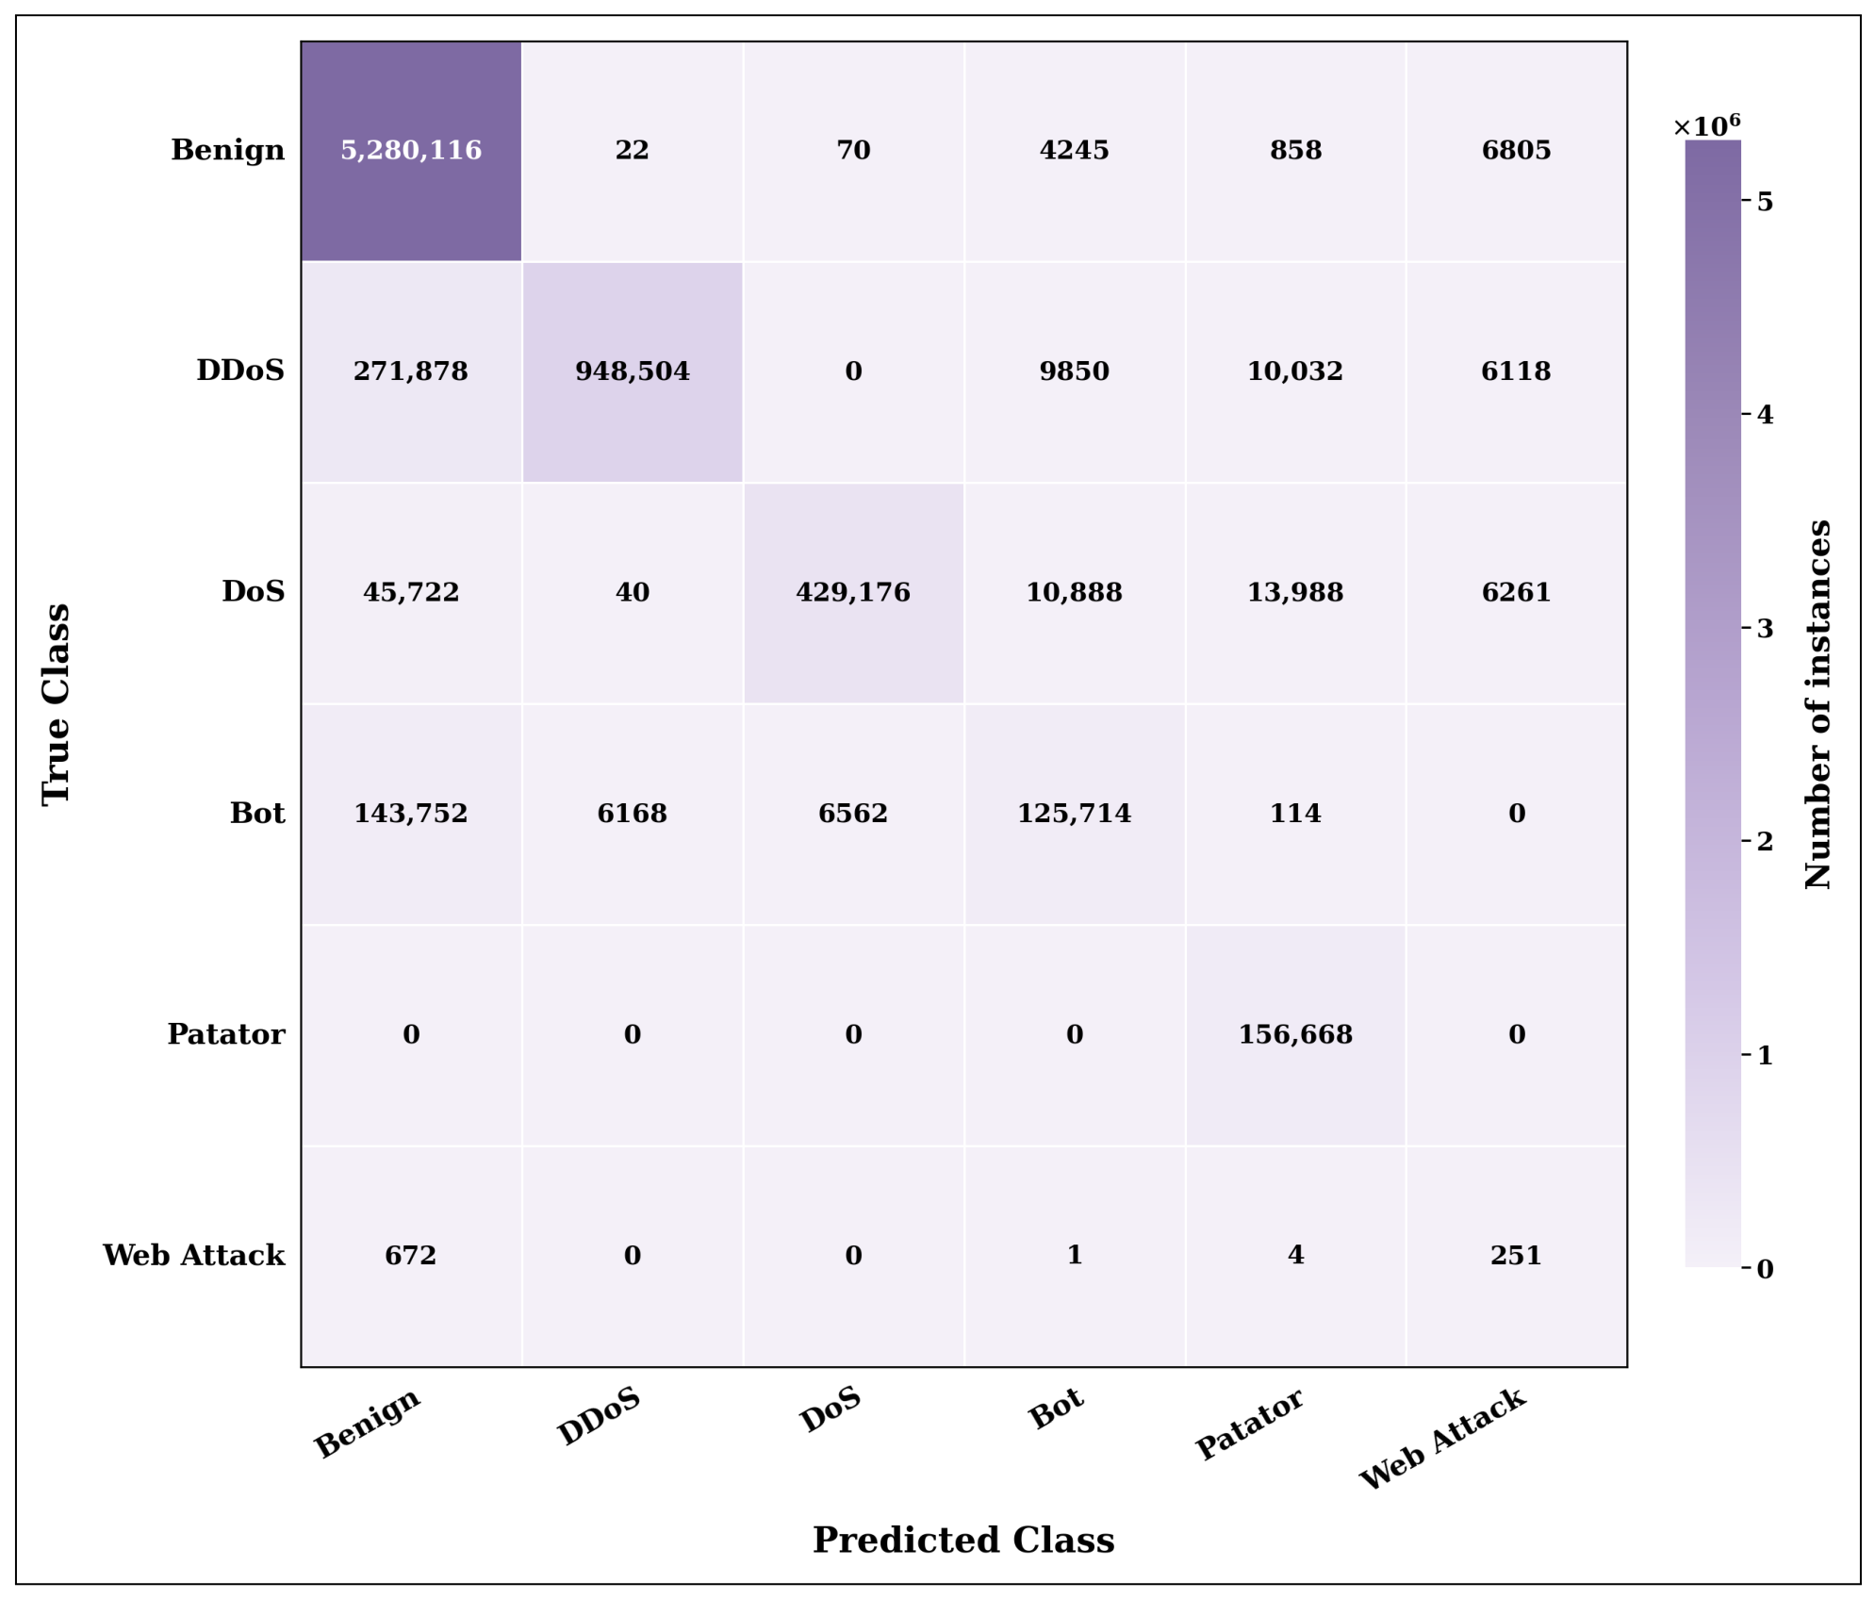
Figure 7 presents the end-to-end confusion matrix of the complete BHM-IDS framework, while Table 19 reports the corresponding performance metrics. Among the 7,484,479 evaluated instances, 6,940,429 were correctly classified, yielding an overall accuracy of 0.9273. The highest recall values were obtained for Patator and Benign, reaching 1.0000 and 0.9977, respectively. DoS achieved a precision of 0.9848, a recall of 0.8480, and an F1-score of 0.9113, whereas DDoS obtained a precision of 0.9935, a recall of 0.7610, and an F1-score of 0.8618.
At the aggregate level, the weighted precision, recall, and F1-score were 0.9317, 0.9273, and 0.9231, respectively, whereas the corresponding macro-averaged values were 0.7679, 0.7204, and 0.7103. This difference between the weighted and macro-averaged metrics indicates that the strong overall performance is largely influenced by the more frequent and better-recognized classes and does not reflect uniform performance across all attack categories.
A closer examination of the class-specific results reveals substantial limitations in detecting minority and low-frequency attack categories. Web Attack achieved a precision of 0.0129, a recall of 0.2705, and an F1-score of 0.0247, while Bot traffic obtained a recall of 0.4453. Because the Web Attack class comprises only 928 instances, its weak performance is largely masked by the weighted-average metrics, which are dominated by more frequent and better-recognized classes. Consequently, the strong aggregate results should not be interpreted as evidence that BHM-IDS generalizes uniformly across all attack categories. Although the framework improves overall cross-dataset generalization, Web Attack and Bot traffic remain particularly challenging to detect reliably.

4.4. Ablation Study

BHM-IDS relies on two main strategies to improve cross-dataset generalization: behavior-based hierarchy and multi-dataset training. Isolating their impacts is necessary to verify that each strategy independently improves performance and that their combination produces a greater gain. For this purpose, an ablation study was conducted using three configurations. The structure of each configuration is first described, followed by the presentation of the corresponding results.

4.4.1. Ablation Study Configurations

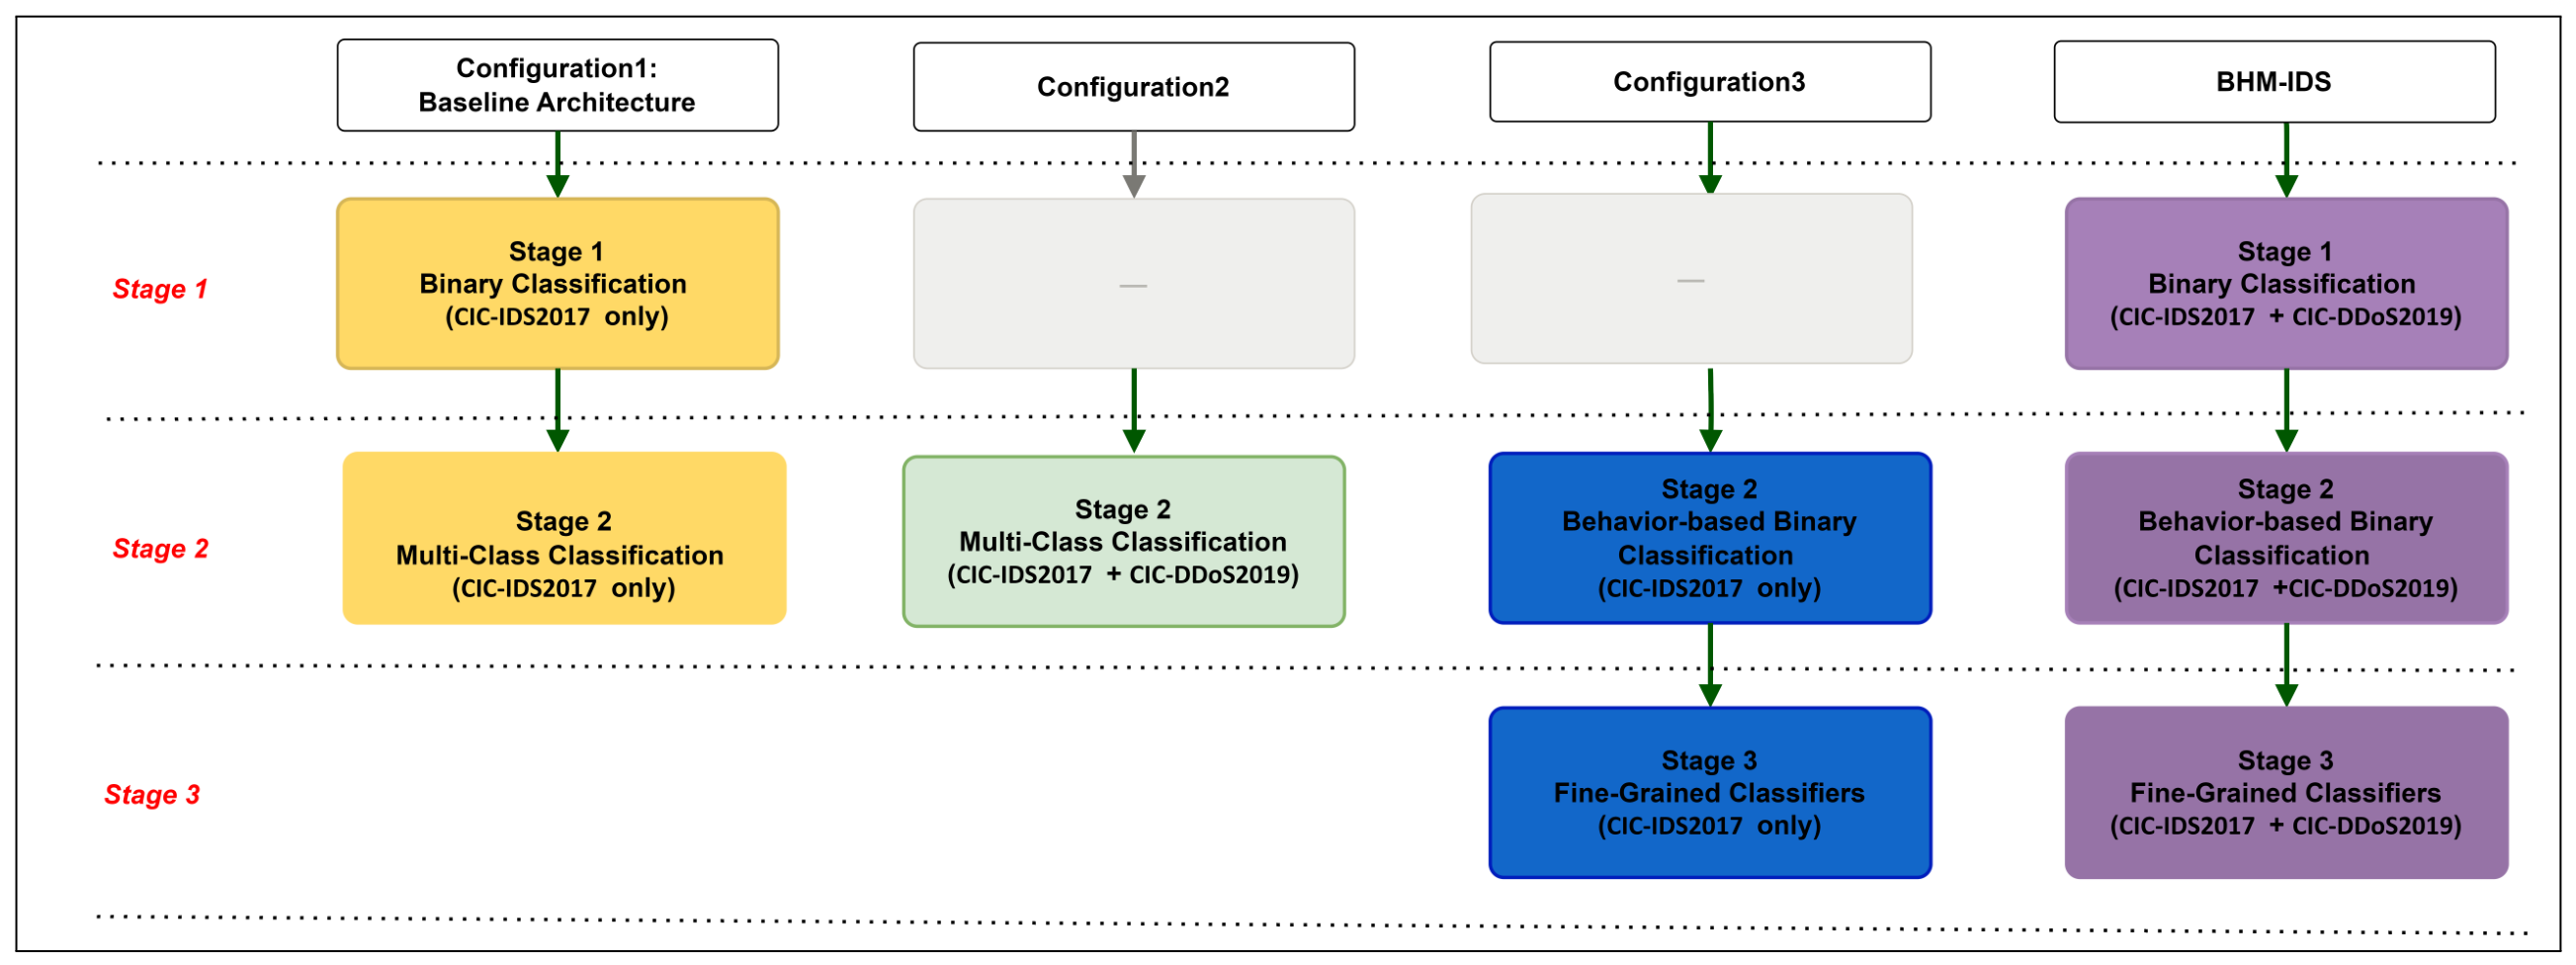
As illustrated in Figure 8, the three configurations represent simplified versions of BHM-IDS:
  • Configuration 1 represents a conventional two-stage architecture composed of a binary classifier followed by a flat multi-class classifier, both trained exclusively on CIC-IDS2017. This configuration serves as the baseline architecture because it does not incorporate multi-dataset training or the behavior-based hierarchy introduced in BHM-IDS.
  • Configuration 2 keeps the same structure used in Configuration 1, but changes the training setting by incorporating multi-dataset training. Since this configuration does not introduce behavior-based hierarchy, it allows the effect of multi-dataset training to be evaluated independently.
  • Configuration 3 has the same structure as BHM-IDS, while restricting the training process to CIC-IDS2017 only. By relying on single-dataset training, this configuration isolates the impact of behavior-based hierarchy.
Since Stage 1 classifiers in Configuration 2 and Configuration 3 correspond to those of the BHM-IDS framework and Configuration 1, respectively, their results are not reported again to avoid redundancy. The gray rectangles in Figure 8 indicate these stages.

4.4.2. Ablation Study Results

In contrast to the earlier evaluation of BHM-IDS, which reported the performance of XGBoost, CatBoost, and LightGBM to demonstrate consistency across classifiers, the ablation study is restricted to the best-performing model among the three. Furthermore, since all variants achieve strong performance under intra-dataset evaluation, we present only cross-dataset validation results on CSE-CIC-IDS2018, where generalization differences between the three configurations are most pronounced. The results are presented sequentially for the three configurations:
  • Configuration 1: The performance of the baseline architecture at Stage 1 is reported in Table 20. LightGBM achieves an overall accuracy of 0.8250, but its low attack recall of 0.4124 indicates limited effectiveness in detecting attack traffic despite strong benign classification performance.
    At the individual attack level, Stage 1 recall shows clear variability, as reported in Table 21. While some attacks such as DoS Slowhttptest and FTP-Patator are perfectly detected, others, including DDoS HOIC, DDoS LOIC-UDP, Web Attack, SSH-Patator, and Bot, show critically weak or zero detection.
    At Stage 2, the baseline architecture shows degraded attack classification performance, with an overall accuracy of 0.569, as reported in Table 22. While the Bot class achieves exceptional detection (Recall: 0.9991, Precision: 1.0), other classes exhibit remarkable drops in performance.
  • Configuration 2:
    Under the multi-dataset training setting, Stage 2 of Configuration 2 achieves an overall accuracy of 0.7950 and a macro recall of 0.7674, as reported in Table 23. The configuration demonstrates relatively better performance for Patator, DoS, and DDoS, while Web Attack remains the main limitation, with a very low F1-score of 0.0158.
  • Configuration 3:
    The results of the Stage 2 and Stage 3 classifiers are presented in Table 24, Table 25 and Table 26, respectively. At Stage 2, the classifier achieves a high overall accuracy of 0.9097; it is better at detecting Attack Group 2 and more precise when predicting Attack Group 1.
    At Stage 3, the DoS and DDoS classifier achieves a lower accuracy of 0.7013, mainly due to the reduced DDoS recall of 0.5804, despite its high precision of 0.9994. In contrast, the Web Attack, Bot, and Patator classifier achieves excellent performance, with an accuracy of 0.9994 and all class metrics exceeding 0.97.
Finally, Table 27 reports the combined recall achieved by attacks classification stages (Stage 2 and Stage 3).

5. Comparative Discussion

The cross-dataset evaluation conducted in this study provides critical insight into how behavior-based hierarchy and multi-dataset training jointly enhance the generalization capability of IDSs. The experimental results demonstrate that BHM-IDS achieves robust cross-dataset generalization on CSE-CIC-IDS2018, significantly outperforming simpler architectural configurations evaluated in the ablation study. While Stage 1 exhibits localized recall drops for specific attack types, BHM-IDS achieves remarkable recovery and refinement in Stage 2 and Stage 3, which deliver substantially enhanced classification performance. The following subsections examine the individual impact of each strategy and then discuss their synergistic effect. The discussion concludes with a comparative assessment against state-of-the-art approaches.
Given that benign traffic detection is consistently near-perfect across all tested configurations, our discussion focuses primarily on attack detection and classification performance.

5.1. Impact of Multi-Dataset Training

The comparison between Configuration 1 and Configuration 2 indicates that multi-dataset training improves overall attack detection and classification across both stages; however, the magnitude of this improvement is strongly class-dependent.
For Stage 1, as shown in Figure 9a,c, the improvement is clear, with an absolute gain of 0.38 in attack recall. This gain extends to several attack categories that were difficult to detect under Configuration 1. The per-class results reported in Table 14 and Table 21 further show that Web Attack subtypes, including Brute Force, XSS, and SQL Injection, which were completely missed by Configuration 1, become partially detectable under Configuration 2. Similarly, Bot recall improves by 0.21, while the DDoS family shows marked gains: DDoS LOIC-HTTP improves by 0.49, and previously undetected variants such as DDoS HOIC and DDoS LOIC-UDP reach recall gains of 0.61 and 0.30, respectively.
At Stage 2, the improvement remains evident in the results reported in Table 22 and Table 23. Configuration 2 increases the overall accuracy by 0.2252 and improves macro recall by 0.0624 compared with Configuration 1. This gain is mainly reflected in the improved detection of DoS, DDoS, and Patator classes, with F1-score gains of 0.2145, 0.3172, and 0.0637, respectively.
Nevertheless, these improvements are not uniformly distributed across all attack categories. Since CIC-DDoS2019 mainly enriches the training set with DDoS-related and high-volume attack patterns, the largest gains are observed for DDoS and related volumetric classes. This is reflected in the substantial improvements obtained for DDoS LOIC-HTTP, DDoS HOIC, and DDoS LOIC-UDP. In contrast, the improvements obtained for Web Attack and Bot traffic remain more limited because these attack types are not substantially represented or diversified by CIC-DDoS2019. Therefore, the contribution of multi-dataset training should not be interpreted as a uniform enhancement across all classes but rather as an improvement that depends on the attack patterns contributed by the additional training dataset.
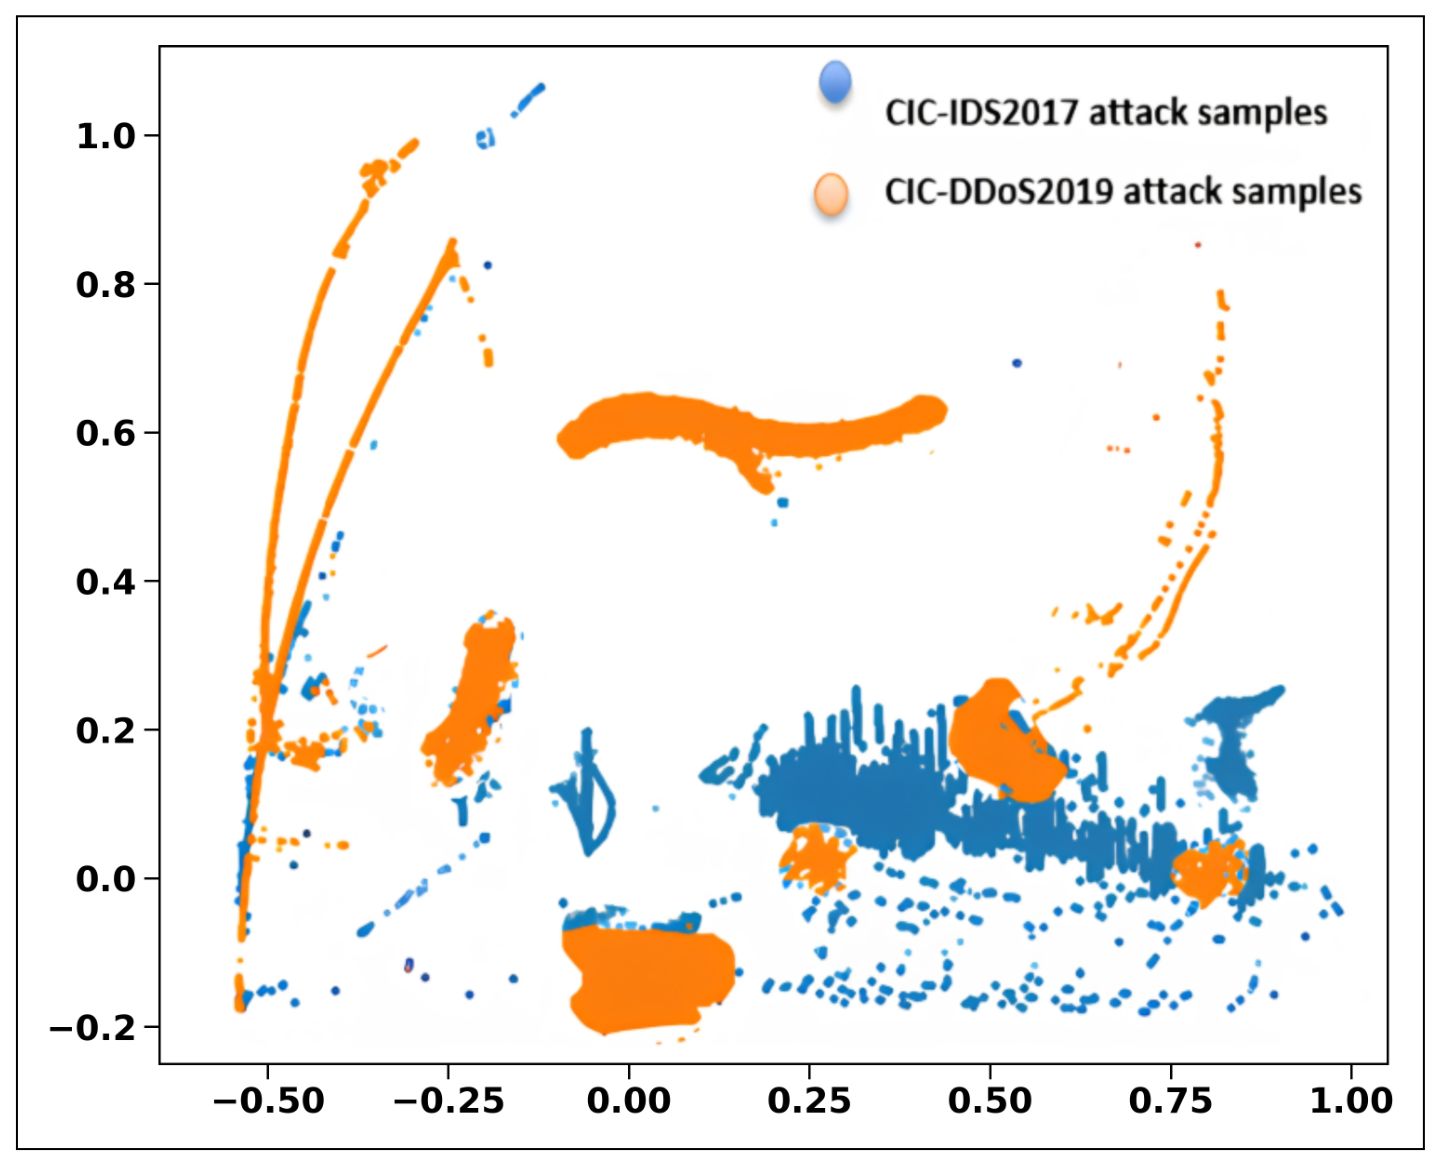
A clearer explanation of this improvement can be observed from the t-SNE visualization in Figure 10. Attacks from CIC-IDS2017 and DDoS attacks from CIC-DDoS2019 occupy partially overlapping regions in the feature space, while the CIC-DDoS2019 samples also fill large areas that are not populated by CIC-IDS2017 attacks. Although t-SNE is only a qualitative visualization tool, this result suggests that CIC-DDoS2019 introduces additional attack profiles rather than redundant samples, thereby expanding the attack space observed during training. These findings indicate that combining CIC-DDoS2019 with CIC-IDS2017 enriches the feature space and strengthens the model’s capacity to identify a broader range of attack patterns during cross-dataset evaluation on the CSE-CIC-IDS2018 dataset.

5.2. Impact of Behavior-Driven Hierarchy

The impact of behavior-driven hierarchy is most clearly observed at the attack classification stages. To assess this impact, we compare Stage 2 of Configuration 1, which performs flat multi-class classification over all attack categories in a single step, with Stage 2 and Stage 3 of Configuration 3, where attack classification is decomposed into two successive steps. As shown in Table 22 and Table 27, macro recall increases substantially, from approximately 0.71 in Configuration 1 to about 0.87 in Configuration 3, corresponding to an absolute gain of nearly 0.16. This improvement is mainly driven by better recognition of the most challenging attack categories. Web Attack achieves the largest recall gain, increasing by approximately 0.38, followed by Patator and DDoS, with gains of about 0.24 and 0.18, respectively.
As mentioned previously, all configurations achieve near-perfect performance under intra-dataset evaluation. Therefore, the additional improvements achieved by Configuration 3 during cross-dataset evaluation are primarily attributable to enhanced generalization capability rather than to a better fit to the training data.
In Configuration 1, all attack classes are learned simultaneously within a single decision space, despite their heterogeneous and sometimes overlapping traffic patterns. This increases the risk of learning dataset-specific artifacts instead of stable attack-related behaviors, which explains the performance degradation observed on CSE-CIC-IDS2018. In contrast, the behavior-driven hierarchical attack classification in Configuration 3 uses the intermediate stage as a behavioral filtering mechanism, reducing interference between attacks with different characteristics and allowing each final classifier to specialize in a more homogeneous classification task. As a result, the learned decision boundaries are more closely aligned with transferable traffic behaviors.

5.3. Synergistic Effect of Behavior-Driven Hierarchy and Multi-Dataset Training

The synergistic effect between behavior-driven hierarchy and multi-dataset training is mainly observed at Stages 2 and 3 of BHM-IDS, where the two strategies are effectively combined. As illustrated in Figure 9b, BHM-IDS achieves the highest macro combined recall compared with the macro recall of Configuration 1 and Configuration 2, and the macro combined recall of Configuration 3. This demonstrates the superior performance of BHM-IDS in the attack classification task.
Although Configurations 2 and 3, in which multi-dataset training and behavior-driven hierarchy are used separately, both improve generalization at the attack classification stages to some extent compared with Configuration 1, each configuration remains limited for certain attack categories, as shown in Figure 9d.
This indicates that simply adding more training data is not sufficient. Although multi-dataset training increases attack diversity, it may also introduce greater distributional complexity, making it more difficult for the model to focus on stable behavioral properties that are essential for cross-dataset generalization. Therefore, an appropriate structure is needed to organize and exploit this additional variability effectively.
Conversely, behavior-based hierarchy reduces class confusion and enhances generalization. However, when used alone, it cannot fully compensate for the limited diversity of attack patterns in the CIC-IDS2017 dataset.
This confirms that the observed improvement does not result from a simple accumulation of strategies but from their complementary interaction.

5.4. Error Propagation Analysis

Although BHM-IDS demonstrated the effectiveness of the adopted techniques and achieved promising end-to-end classification performance compared with simpler configurations, its hierarchical structure remains inherently susceptible to error propagation across successive decision stages. In such a framework, a classification error introduced at an early stage directly affects all subsequent decisions.
The end-to-end confusion matrix in Figure 7 shows that Stage 1 incorrectly classified 462,024 attack instances as Benign, thereby preventing them from reaching the subsequent stages, while 12,000 Benign instances were incorrectly forwarded to the attack-classification stages. Of the 1,730,339 attack samples correctly detected and forwarded by Stage 1, 1,660,313 were ultimately assigned to their correct attack class, whereas 70,026 were assigned to another attack category. Overall, the system produced 532,050 final errors, of which 462,024 originated at Stage 1, corresponding to 86% of all errors, whereas the remaining errors, representing 14%, were introduced after the samples entered the subsequent stages.
The most pronounced error-propagation effects were observed for the Bot and Web Attack classes. Their Stage 1 attack-detection recalls were only 0.4908 and 0.2759, respectively, which constrained their final end-to-end recalls to 0.4453 and 0.2705. Confusion occurred in both directions between benign traffic and the Bot and Web Attack classes. Of the 12,000 benign instances incorrectly forwarded to the attack branch, 4245 were classified as Bot and 6805 as Web Attack, together accounting for 11,050 cases, or 92.08% of all benign misclassifications. Conversely, 143,752 Bot instances and 672 Web Attack instances were incorrectly classified as benign. This bidirectional confusion indicates substantial overlap between the traffic patterns of these classes within the selected feature space, making their separation particularly challenging under cross-dataset validation.
In contrast, the architecture achieved promising and considerably more stable results for benign traffic and for the DDoS, DoS, and Patator attack classes, with end-to-end recall values of 0.9977, 0.7610, 0.8480, and 1.0000, respectively. These classes constitute the dominant proportion of the external test dataset, and their performance indicates that BHM-IDS introduced comparatively limited error propagation. In particular, Patator instances were classified without any end-to-end recall loss, while benign, DoS, and DDoS traffic maintained strong detection performance throughout the hierarchical classification process.
Overall, these findings show that BHM-IDS generalizes effectively for the most prevalent attack categories, whereas its main limitations are concentrated in Bot and Web Attack traffic.

5.5. Comparison with State-of-the-Art Approaches

In this subsection, we compare BHM-IDS with state-of-the-art approaches that explicitly examined cross-dataset generalization under training and evaluation settings comparable to ours, i.e., models trained at least on CIC-IDS2017 and tested on CSE-CIC-IDS2018. Because prior studies typically addressed either binary classification or multi-class attack classification, but rarely both within a single unified framework, the comparison adopted in this work follows a stage-wise strategy: the first stage of BHM-IDS, devoted to binary classification, is evaluated against two representative binary detection methods from the literature [38,39], while the later stages, which perform attack classification, are compared with a multi-class classification approach reported in [40]. Such a comparison method ensures that each stage of the proposed framework is benchmarked against the most relevant existing methods, while maintaining full consistency in terms of datasets and evaluation conditions. The shared characteristics between BHM-IDS and the selected works, summarized in Table 28, confirm the relevance and fairness of the comparison.
The authors in [38] evaluated multiple binary classification models and reported a peak F1-score of only 0.39. In contrast, our first-stage classifiers achieve substantially higher performance, with an F1-score of 0.87, corresponding to an absolute gain of more than 0.48. Beyond this quantitative improvement, our study also addresses a broader evaluation scope by explicitly considering complex DDoS variants that were excluded in [38]. For these challenging attacks, BHM-IDS reports encouraging generalization performance, with recall values of approximately 0.66 for DDoS-HOIC and 0.33 for DDoS-LOIC-UDP.
Furthermore, while the authors in [38] concluded that only a limited subset of attacks, namely DoS Hulk, DoS Slowloris, SSH-Patator, and FTP-Patator, exhibits strong generalization, our framework demonstrates near-perfect generalization across a broader set of attacks, including DoS SlowHttpTest, DoS Slowloris, DoS Hulk, SSH-Patator, FTP-Patator, and DDoS-LOIC-HTTP.
The performance of our first stage is also evident in comparison with [39], where several unsupervised models are evaluated using approximately 1,100,000 attack and 400,000 benign samples from CSE-CIC-IDS2018. As shown in Table 29, although [39] reports a higher attack-class recall than our approach (0.9305 vs. 0.7893), this comes at a substantial cost in precision: their model achieves a precision of only 0.7748, whereas our first-stage classifier attains 0.9931, an improvement of more than 0.21. This precision gap implies a much higher false-alarm rate, which is problematic in operational deployments. Overall, our framework yields a higher F1-score (0.8795 vs. 0.8455), despite being evaluated on a substantially larger portion of CSE-CIC-IDS2018, comprising more than 2,000,000 attack and 5,000,000 benign samples.
After demonstrating the competitive cross-dataset performance of Stage 1 in BHM-IDS, the focus now shifts to the subsequent stages. As shown in Table 30, in comparison with [40], which reported high macro recall across four attack classes (DoS, DDoS, Bot, and Patator), BHM-IDS achieves consistently comparable recall values for the corresponding attack categories while simultaneously detecting an additional attack class, Web Attack, which is absent in [40].

5.6. Limitations and Future Work

Although the obtained results highlight the effectiveness of the proposed framework, they should be interpreted in light of certain methodological limitations. Most notably, the generalization study relies on a single external dataset (CSE-CIC-IDS2018), which constrains the extent to which the findings can be confidently generalized to broader, real-world deployment conditions. Furthermore, while the proposed multi-dataset training strategy demonstrates that enriching CIC-IDS2017 with CIC-DDoS2019 improves cross-dataset generalization, the benefits remain class-dependent, particularly at Stage 1. Because CIC-DDoS2019 predominantly contains DDoS traffic, its contribution is most pronounced for resource-exhaustion attacks, providing limited additional coverage for categories such as Bot and Web Attacks, which exhibited lower cross-dataset recall.
To address these limitations and further refine the BHM-IDS framework, future research will focus on three key areas:
  • Expanded Cross-Dataset Validation: Additional datasets will be incorporated into the evaluation pipeline to ensure broader and more robust cross-dataset validation.
  • Class-Specific Failure Analysis: The factors underlying the weak detection performance observed for challenging attack categories, particularly Web Attack, will be investigated. To determine whether these limitations are associated with cross-dataset distribution shifts, the distributions of the most relevant Stage 1 features will be systematically analyzed and compared across the three adopted datasets. This analysis will combine quantitative measures, including the Kolmogorov–Smirnov statistic, Wasserstein distance, Jensen–Shannon divergence, Population Stability Index, and Maximum Mean Discrepancy, with visual techniques such as kernel-density estimation, empirical cumulative distribution plots, box and violin plots, and PCA/UMAP projections. These complementary analyses will help identify the causes of the observed class-specific performance degradation, provide deeper insight into dataset shift, and support the selection of more complementary and synergistic dataset combinations.
  • Preprocessing Optimization: A broader range of preprocessing configurations will be explored, with a specific focus on stage-specific feature-selection methods, class-balancing strategies, and scaling techniques. Systematically optimizing these steps will help reduce dataset-specific bias and further enhance the robustness of BHM-IDS.

6. Conclusions

This work addressed a central weakness of ML-based IDSs: their limited ability to generalize beyond the datasets used for training. To overcome this issue, we proposed a three-stage hierarchical framework specifically designed to enhance cross-dataset generalization through a behavior-driven hierarchy and a multi-dataset training strategy. The framework consists of a benign/attack detection stage, a behavior-based binary classification stage, and a final stage dedicated to attack-type identification.
The second stage represents the core of the architecture because it organizes malicious traffic according to how it manifests in network flow data rather than relying on predefined semantic labels. This encourages the model to learn decision boundaries aligned with more stable attack behaviors. In parallel, the multi-dataset training strategy exposes the model to more diverse attack patterns.
The experimental results confirmed the effectiveness of these two strategies in improving cross-dataset generalization. In particular, the ablation study showed that the observed performance gains could not be attributed to either strategy independently. Instead, the improvement resulted from their joint contribution.
The complete end-to-end evaluation provides a more realistic assessment of BHM-IDS than the independent stage-wise evaluations. Although the proposed framework improved overall cross-dataset generalization across several attack categories, its performance was not uniform across all classes. In particular, Web Attack and Bot traffic remained difficult to detect reliably. These findings demonstrate that strong stage-wise performance does not necessarily translate into equally strong final predictions, as errors introduced during the first stage may propagate through the hierarchical architecture and adversely affect the final classification outcomes. Future work should therefore focus on strengthening the early-stage classifier and mitigating error propagation throughout the complete framework.
Regarding the operational deployment of the proposed framework, it is important to clarify that BHM-IDS is not currently presented as a standalone, production-ready solution for immediate real-world deployment. Although the results demonstrate strong potential, some class-specific limitations remain. Accordingly, the proposed framework is positioned as a foundational proof of concept that opens new research directions in the IDS domain. More specifically, it demonstrates the potential of behavior-driven hierarchical classification and multi-dataset training as viable strategies for addressing the persistent challenge of cross-dataset generalization, while encouraging further research into more sophisticated strategies capable of achieving stronger and more consistent generalization across heterogeneous network environments.

Author Contributions

Conceptualization, M.Z. and M.B.L.; methodology, M.Z. and M.B.L.; software, M.Z. and A.B.; validation, M.B.L., P.Z. and G.H.; formal analysis, M.Z.; investigation, M.B.L.; resources, M.Z., A.B. and Y.B.; data curation, M.Z.; writing—original draft preparation, M.Z.; writing—review and editing, M.B.L. and P.Z.; visualization, M.Z.; supervision, M.B.L.; project administration, M.B.L.; funding acquisition, G.H. and P.Z. All authors have read and agreed to the published version of the manuscript.

Funding

This research was funded by Project BG16RFPR002-1.014-0004, Centre of Excellence “Universities for Science, Informatics and Technologies in e-Society (UNITe)”, under the Program “Research, Innovation and Digitalization for Smart Transformation (PRIDST)”, co-funded by the European Union through the European Regional Development Fund (ERDF).

Institutional Review Board Statement

Not applicable.

Informed Consent Statement

Not applicable.

Data Availability Statement

The datasets used in this study are publicly available from the Canadian Institute for Cybersecurity (CIC): CIC-IDS2017 https://www.unb.ca/cic/datasets/ids-2017.html (accessed on 20 May 2025), CIC-DDoS2019 https://www.unb.ca/cic/datasets/ddos-2019.html (accessed on 25 May 2025), and CSE-CIC-IDS2018 https://www.unb.ca/cic/datasets/ids-2018.html (accessed on 28 May 2025).

Conflicts of Interest

The authors declare no conflicts of interest.

Appendix A

The complete feature sets retained for each stage and classifier of the proposed BHM-IDS architecture are provided in Table A1, Table A2, Table A3 and Table A4.
Table A1. Selected features used in Stage 1.
Packet Length StdSubflow Fwd PacketsBwd Packets/s
Packet Length VarianceFwd IAT MaxFlow IAT Max
Avg Bwd Segment SizePSH Flag CountFwd IAT Total
Max Packet LengthFlow IAT StdFlow Packets/s
Bwd Packet Length MaxBwd Header LengthIdle Min
Total Length of Bwd PacketsIdle MeanFlow Duration
Bwd Packet Length StdFwd IAT Std
Average Packet SizeFwd Header Length
Subflow Fwd BytesInit_Win_bytes_forward
Fwd Packet Length Maxact_data_pkt_fwd
Total Length of Fwd PacketsFlow Bytes/s
Subflow Bwd BytesFwd Packet Length Std
Fwd Packet Length MeanFwd IAT Mean
Avg Fwd Segment SizeInit_Win_bytes_backward
Packet Length MeanFlow IAT Mean
Bwd Packet Length Meanmin_seg_size_forward
Total Fwd PacketsSubflow Bwd Packets
Table A2. Selected features used in Stage 2.
Init_Win_bytes_backwardFwd Header LengthDestination Port
Subflow Fwd BytesSubflow Fwd PacketsIdle Min
Bwd Packet Length Minact_data_pkt_fwdAvg Bwd Segment Size
Total Length of Fwd PacketsFlow IAT MaxBwd Packet Length Mean
Fwd Packet Length MeanFlow IAT MeanMax Packet Length
Fwd Packet Length MaxAverage Packet SizeFwd IAT Min
Fwd Packet Length StdPacket Length MeanFlow Bytes/s
Bwd Header LengthFlow IAT StdPacket Length Variance
Fwd IAT MeanBwd Packet Length MaxPacket Length Std
Avg Fwd Segment SizeFlow Packets/sIdle Max
Fwd IAT MaxInit_Win_bytes_forwardFwd IAT Std
Fwd IAT TotalFlow DurationTotal Backward Packets
min_seg_size_forwardSubflow Bwd BytesFlow IAT Min
Total Fwd PacketsFwd Packets/sBwd Packet Length Std
Bwd Packets/sTotal Length of Bwd PacketsBwd IAT Total
Table A3. Selected features used by Classifier 1 in Stage 3.
min_seg_size_forwardFwd IAT TotalPacket Length Mean
Flow Packets/sAvg Fwd Segment SizeAverage Packet Size
Flow DurationFwd Packet Length StdIdle Min
Flow IAT MeanFwd IAT MinSubflow Bwd Bytes
Init_Win_bytes_backwardFlow IAT MinSubflow Bwd Packets
Flow IAT MaxFwd Header LengthBwd Packet Length Max
Fwd Packets/sTotal Length of Fwd PacketsMax Packet Length
Init_Win_bytes_forwardFwd Packet Length MeanPacket Length Std
Fwd IAT MaxACK Flag CountBwd IAT Max
Min Packet LengthTotal Fwd PacketsAvg Bwd Segment Size
act_data_pkt_fwdBwd Header Length
Flow Bytes/sIdle Max
Destination PortFwd Packet Length Max
Subflow Fwd BytesBwd Packet Length Min
Fwd IAT MeanFlow IAT Std
Table A4. Selected features used by Classifier 2 in Stage 3.
Destination PortAverage Packet SizeFwd Packets/s
min_seg_size_forwardPacket Length MeanFlow Duration
Max Packet LengthSubflow Bwd BytesBwd Header Length
Packet Length StdFlow IAT MaxTotal Fwd Packets
Bwd IAT MinBwd Packet Length MaxFwd Header Length
Init_Win_bytes_backwardPacket Length VarianceAvg Bwd Segment Size
Flow IAT MeanFwd Packet Length MeanFwd IAT Min
Bwd Packet Length MinFwd IAT StdBwd IAT Total
Fwd Packet Length MaxBwd Packet Length MeanDown/Up Ratio
Flow IAT StdFlow Bytes/sSubflow Fwd Packets
Subflow Fwd BytesTotal Length of Bwd Packets
Fwd IAT MaxInit_Win_bytes_forward
Fwd Packet Length StdFlow Packets/s
Total Length of Fwd PacketsAvg Fwd Segment Size
Fwd IAT MeanBwd Packets/s

References

  1. AlNuaimi, B.K.; Singh, S.K.; Ren, S.; Budhwar, P.; Vorobyev, D. Mastering digital transformation: The nexus between leadership, agility, and digital strategy. J. Bus. Res. 2022, 145, 636–648. [Google Scholar] [CrossRef] [Scilit]
  2. Ly, B.; Ly, R.; Ma, S. Digital transformation and flexibility in public services: Knowledge, culture and digital infrastructures. J. Innov. Knowl. 2026, 13, 100947. [Google Scholar] [CrossRef] [Scilit]
  3. ENISA (European Union Agency for Cybersecurity). ENISA Threat Landscape 2022. Report, European Union Agency for Cybersecurity, 2022. Available online: https://www.enisa.europa.eu/publications/enisa-threat-landscape-2022 (accessed on 25 June 2025).
  4. Aljundi, I.; Rawashdeh, M.; Al-Fayoumi, M.; Al-Badarneh, A.; Al-Haija, Q.A. Protecting Critical National Infrastructures: An Overview of Cyberattacks and Countermeasures. In Proceedings of the Intelligent Sustainable Systems; Nagar, A.K., Jat, D.S., Mishra, D., Joshi, A., Eds.; Springer: Singapore, 2024; pp. 295–317. [Google Scholar] [CrossRef] [Scilit]
  5. Diana, L.; Dini, P.; Paolini, D. Overview on Intrusion Detection Systems for Computers Networking Security. Computers 2025, 14, 87. [Google Scholar] [CrossRef] [Scilit]
  6. Arnob, A.K.B.; Chowdhury, R.R.; Chaiti, N.A.; Saha, S.; Roy, A. A comprehensive systematic review of intrusion detection systems: Emerging techniques, challenges, and future research directions. J. Edge Comput. 2025, 4, 73–104. [Google Scholar] [CrossRef] [Scilit]
  7. Pinto, A.; Herrera, L.C.; Donoso, Y.; Gutierrez, J.A. Survey on Intrusion Detection Systems Based on Machine Learning Techniques for the Protection of Critical Infrastructure. Sensors 2023, 23, 2415. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  8. Hozouri, A.; Mirzaei, A.; Effatparvar, M. A comprehensive survey on intrusion detection systems with advances in machine learning, deep learning and emerging cybersecurity challenges. Discov. Artif. Intell. 2025, 5, 314. [Google Scholar] [CrossRef] [Scilit]
  9. Ahmad, Z.; Shahid Khan, A.; Wai Shiang, C.; Abdullah, J.; Ahmad, F. Network intrusion detection system: A systematic study of machine learning and deep learning approaches. Trans. Emerg. Telecommun. Technol. 2021, 32, e4150. [Google Scholar] [CrossRef] [Scilit]
  10. Yu, H.; Zhang, W.; Kang, C.; Xue, Y. A feature selection algorithm for intrusion detection system based on the enhanced heuristic optimizer. Expert Syst. Appl. 2025, 265, 125860. [Google Scholar] [CrossRef] [Scilit]
  11. Qi, Z.; Fei, J.; Wang, J.; Li, X. An Intrusion Detection Feature Selection Method Based on Improved Mutual Information. In Proceedings of the 2023 IEEE 6th Information Technology, Networking, Electronic and Automation Control Conference (ITNEC); IEEE: Piscataway, NJ, USA, 2023; Volume 6, pp. 1584–1590. [Google Scholar] [CrossRef] [Scilit]
  12. Rahma, F.; Rachmadi, R.F.; Pratomo, B.A.; Purnomo, M.H. Assessing the Effectiveness of Oversampling and Undersampling Techniques for Intrusion Detection on an Imbalanced Dataset. In Proceedings of the 2023 IEEE Industrial Electronics and Applications Conference (IEACon); IEEE: Piscataway, NJ, USA, 2023; pp. 92–97. [Google Scholar] [CrossRef] [Scilit]
  13. Othman, T.S.; Abdullah, S.M. Machine Learning Techniques Evaluation with SMOTE on IoT-23 Dataset. In Proceedings of the 2023 9th International Engineering Conference on Sustainable Technology and Development (IEC); IEEE: Piscataway, NJ, USA, 2023; pp. 7–13. [Google Scholar] [CrossRef] [Scilit]
  14. Khan, F.A.; Shah, A.A.; Alshammry, N.; Saif, S.; Khan, W.; Malik, M.O.; Ullah, Z. Balanced Multi-Class Network Intrusion Detection Using Machine Learning. IEEE Access 2024, 12, 178222–178236. [Google Scholar] [CrossRef] [Scilit]
  15. Lu, C.; Cao, Y.; Wang, Z. Research on Intrusion Detection Based on an Enhanced Random Forest Algorithm. Appl. Sci. 2024, 14, 714. [Google Scholar] [CrossRef] [Scilit]
  16. Srivastav, N.; Singh, R. An Optimized Machine Learning Based Network Intrusion Detection Systems for Identification of Low-Occurrence Attacks. SN Comput. Sci. 2025, 6, 820. [Google Scholar] [CrossRef] [Scilit]
  17. Cao, B.; Li, C.; Song, Y.; Qin, Y.; Chen, C. Network Intrusion Detection Model Based on CNN and GRU. Appl. Sci. 2022, 12, 4184. [Google Scholar] [CrossRef] [Scilit]
  18. Qazi, E.U.H.; Almorjan, A.; Zia, T. A One-Dimensional Convolutional Neural Network (1D-CNN) Based Deep Learning System for Network Intrusion Detection. Appl. Sci. 2022, 12, 7986. [Google Scholar] [CrossRef] [Scilit]
  19. Verkerken, M.; D’hooge, L.; Sudyana, D.; Lin, Y.D.; Wauters, T.; Volckaert, B.; De Turck, F. A Novel Multi-Stage Approach for Hierarchical Intrusion Detection. IEEE Trans. Netw. Serv. Manag. 2023, 20, 3915–3929. [Google Scholar] [CrossRef] [Scilit]
  20. Alin, F.; Chemchem, A.; Nolot, F.; Flauzac, O.; Krajecki, M. Towards a Hierarchical Deep Learning Approach for Intrusion Detection. In Proceedings of the Machine Learning for Networking; Boumerdassi, S., Renault, É., Mühlethaler, P., Eds.; Springer: Cham, Switzerland, 2020; pp. 15–27. [Google Scholar] [CrossRef] [Scilit]
  21. Hewapathirana, I.U. A Comparative Study of Two-Stage Intrusion Detection Using Modern Machine Learning Approaches on the CSE-CIC-IDS2018 Dataset. Knowledge 2025, 5, 6. [Google Scholar] [CrossRef] [Scilit]
  22. Uddin, M.A.; Aryal, S.; Bouadjenek, M.R.; Al-Hawawreh, M.; Talukder, M.A. Hierarchical classification for intrusion detection system: Effective design and empirical analysis. Ad Hoc Netw. 2025, 178, 103982. [Google Scholar] [CrossRef] [Scilit]
  23. Mihai, I.C.; Pruna, S.; Barbu, I.D. Cyber Kill Chain Analysis. Int. J. Inf. Secur. Cybercrime 2014, 3, 37–42. [Google Scholar] [CrossRef] [Scilit]
  24. Kim, Y.; Kim, J.; Kim, D. Hi-MLIC: Hierarchical Multilayer Lightweight Intrusion Classification for Various Intrusion Scenarios. IEEE Access 2024, 12, 120098–120115. [Google Scholar] [CrossRef] [Scilit]
  25. Blank, R.; Gallagher, P. Guide for Conducting Risk Assessments; Technical Report NIST Special Publication 800-30 Revision 1; National Institute of Standards and Technology (NIST): Gaithersburg, MD, USA, 2012. [Google Scholar] [CrossRef] [Scilit]
  26. Sarıkaya, A.; Kılıç, B.G. A Class-Specific Intrusion Detection Model: Hierarchical Multi-class IDS Model. SN Comput. Sci. 2020, 1, 202. [Google Scholar] [CrossRef] [Scilit]
  27. Uddin, M.A.; Aryal, S.; Bouadjenek, M.R.; Al-Hawawreh, M.; Talukder, M.A. A dual-tier adaptive one-class classification IDS for emerging cyberthreats. Comput. Commun. 2025, 229, 108006. [Google Scholar] [CrossRef] [Scilit]
  28. Mohd, N.; Singh, A.; Bhadauria, H.S. Intrusion Detection System Based on Hybrid Hierarchical Classifiers. Wirel. Pers. Commun. 2021, 121, 659–686. [Google Scholar] [CrossRef] [Scilit]
  29. ElDahshan, K.A.; AlHabshy, A.A.; Hameed, B.I. Meta-Heuristic Optimization Algorithm-Based Hierarchical Intrusion Detection System. Computers 2022, 11, 170. [Google Scholar] [CrossRef] [Scilit]
  30. Kilichev, D.; Kim, W. Hyperparameter Optimization for 1D-CNN-Based Network Intrusion Detection Using GA and PSO. Mathematics 2023, 11, 3724. [Google Scholar] [CrossRef] [Scilit]
  31. Sahu, P.; Vyas, O.P.; Barnwal, R.; Singla, A.; Priyanshu. Enhancing Industrial IoT Intrusion Detection with Hyperparameter Optimization. In Proceedings of the 2024 15th International Conference on Computing Communication and Networking Technologies (ICCCNT); IEEE: Piscataway, NJ, USA, 2024; pp. 1–6. [Google Scholar] [CrossRef] [Scilit]
  32. Hairab, B.I.; Said Elsayed, M.; Jurcut, A.D.; Azer, M.A. Anomaly Detection Based on CNN and Regularization Techniques Against Zero-Day Attacks in IoT Networks. IEEE Access 2022, 10, 98427–98440. [Google Scholar] [CrossRef] [Scilit]
  33. Tavallaee, M.; Bagheri, E.; Lu, W.; Ghorbani, A.A. A detailed analysis of the KDD CUP 99 data set. In Proceedings of the IEEE Symposium on Computational Intelligence for Security and Defense Applications (CISDA); IEEE: Piscataway, NJ, USA, 2009; pp. 1–6. [Google Scholar] [CrossRef] [Scilit]
  34. Choudhary, S.; Kesswani, N. Analysis of KDD-Cup’99, NSL-KDD and UNSW-NB15 Datasets using Deep Learning in IoT. Procedia Comput. Sci. 2020, 167, 1561–1573. [Google Scholar] [CrossRef] [Scilit]
  35. Sharafaldin, I.; Lashkari, A.H.; Ghorbani, A.A. Toward Generating a New Intrusion Detection Dataset and Intrusion Traffic Characterization. In Proceedings of the 4th International Conference on Information Systems Security and Privacy (ICISSP); Springer: Cham, Switzerland, 2018; pp. 108–116. [Google Scholar] [CrossRef] [Scilit]
  36. Magán-Carrión, R.; Urda, D.; Diaz-Cano, I.; Dorronsoro, B. Improving the Reliability of Network Intrusion Detection Systems Through Dataset Integration. IEEE Trans. Emerg. Top. Comput. 2022, 10, 1717–1732. [Google Scholar] [CrossRef] [Scilit]
  37. Iwanowski, M.; Olszewski, D.; Graniszewski, W.; Krupski, J.; Pelc, F. The Choice of Training Data and the Generalizability of Machine Learning Models for Network Intrusion Detection Systems. Appl. Sci. 2025, 15, 8466. [Google Scholar] [CrossRef] [Scilit]
  38. Cantone, M.; Marrocco, C.; Bria, A. Machine Learning in Network Intrusion Detection: A Cross-Dataset Generalization Study. IEEE Access 2024, 12, 144489–144508. [Google Scholar] [CrossRef] [Scilit]
  39. Verkerken, M.; D’hooge, L.; Wauters, T.; Volckaert, B.; De Turck, F. Towards Model Generalization for Intrusion Detection: Unsupervised Machine Learning Techniques. J. Netw. Syst. Manag. 2021, 30, 12. [Google Scholar] [CrossRef] [Scilit]
  40. Xu, C.; Li, D.; Liu, Z.; Yang, J.; Shen, Q.; Tong, N. Few-shot network intrusion detection method based on multi-domain fusion and cross-attention. PLoS ONE 2025, 20, e0327161. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  41. Layeghy, S.; Portmann, M. Explainable Cross-domain Evaluation of ML-based Network Intrusion Detection Systems. Comput. Electr. Eng. 2023, 108, 108692. [Google Scholar] [CrossRef] [Scilit]
  42. Chen, T.; Guestrin, C. XGBoost: A Scalable Tree Boosting System. In Proceedings of the 22nd ACM SIGKDD International Conference on Knowledge Discovery and Data Mining (KDD); ACM: Singapore, 2016; pp. 785–794. [Google Scholar] [CrossRef] [Scilit]
  43. Prokhorenkova, L.; Gusev, G.; Vorobev, A.; Dorogush, A.V.; Gulin, A. CatBoost: Unbiased Boosting with Categorical Features. In Proceedings of the Advances in Neural Information Processing Systems; Curran Associates, Inc.: Red Hook, NY, USA, 2018; Volume 31, pp. 6639–6649. Available online: https://proceedings.neurips.cc/paper/2018/hash/14491b756b3a51daac41c24863285549-Abstract.html (accessed on 20 December 2025).
  44. Ke, G.; Meng, Q.; Finley, T.; Wang, T.; Chen, W.; Ma, W.; Ye, Q.; Liu, T.Y. LightGBM: A Highly Efficient Gradient Boosting Decision Tree. In Proceedings of the Advances in Neural Information Processing Systems; Curran Associates, Inc.: Red Hook, NY, USA, 2017; Volume 30, Available online: https://proceedings.neurips.cc/paper/2017/hash/6449f44a102fde848669bdd9eb6b76fa-Abstract.html (accessed on 26 December 2025).
  45. Bergstra, J.; Bengio, Y. Random search for hyper-parameter optimization. J. Mach. Learn. Res. 2012, 13, 281–305. [Google Scholar]
  46. Akiba, T.; Sano, S.; Yanase, T.; Ohta, T.; Koyama, M. Optuna: A Next-generation Hyperparameter Optimization Framework. In Proceedings of the 25th ACM SIGKDD International Conference on Knowledge Discovery & Data Mining (KDD); ACM: Singapore, 2019; pp. 2623–2631. [Google Scholar] [CrossRef] [Scilit]
Figure 1. BHM-IDS architecture.
Applsci 16 07885 g001
Figure 2. Dataset preparation steps.
Applsci 16 07885 g002
Figure 3. Learning pipeline.
Applsci 16 07885 g003
Figure 4. Resampling threshold selection.
Applsci 16 07885 g004
Figure 5. Cross-dataset validation confusion matrices: (a) XGBoost confusion matrix for Stage 1 and (b) LightGBM confusion matrix for Stage 2.
Applsci 16 07885 g005
Figure 6. Cross-dataset validation confusion matrices: (a) Confusion matrix CatBoost (Classifier1) and (b) Confusion matrix XGBoost (Classifier2).
Applsci 16 07885 g006
Figure 7. End-to-end confusion matrix.
Applsci 16 07885 g007
Figure 8. Ablation study configurations.
Applsci 16 07885 g008
Figure 9. (a) Stage 1 recall comparison (Configuration 1 vs. Configuration 2). (b) Macro (combined) recall comparison across configurations. (c) Stage 1 per-class recall comparison (Configuration 1 vs. Configuration 2). (d) Per-class recall (combined recall) comparison across configurations.
Applsci 16 07885 g009
Figure 10. t-SNE visualization of attack traffic from CIC-IDS2017 and CIC-DDoS2019.
Applsci 16 07885 g010
Table 1. Comparison of multi-stage hierarchical architectures.
StudyStagesAttack
Grouping
Technique
No. of GroupsDatasetsML/DL Models
[19]2CIC-IDS2017Autoencoder, OCSVM, Random Forest
[20]2KDD-99, NSL-KDD, UNSW-NB15, CIC-IDS2017Naïve Bayes, Decision Tree, MLP, Logistic Regression, KNN
[21]2CSE-CIC-IDS2018Autoencoder, MLP, Logistic Regression, Random Forest
[22]3Cyber kill chain-basedDataset dependentCIC-DoS2017, CIC-DDoS2019, NSL-KDD, ToN-IoTRandom Forest, Decision Tree, Logistic Regression, MLP, Gaussian NB, Extra Trees
[24]3NIST-Based4CIC-IDS2017, UNSW-NB15Random Forest, MLP, Decision Tree, KNN
[26]3Error-driven approach2UNSW-NB15Random Forest
Table 2. Comparison of multi-dataset training studies.
StudyCombined DatasetsArchitectural DesignML/DL ModelsCross-Dataset Validation
[36]UGR-16, UNSW-NB15, NSL-KDD.BHFlatLogistic Regression, Random Forest.Evaluation mainly on the new and the constituent datasets; no systematic testing on an additional independent dataset
[24]CIC-IDS2017, UNSW-NB15HierarchicalRandom Forest, Multilayer Perceptron, Decision Tree, K-Nearest Neighbor.Evaluation confined to the new dataset; no separate unseen dataset used
Table 3. Comparison of IDS generalization studies.
StudyDatasetsMulti Class ClassificationBinary ClassificationML/DL ModelsBest Train–Test Pair
[37]UNSW-NB15, CIC-CSE-IDS2018, BoT-IoT, ToN-IoTXDecision Tree, Random ForestCSE-IDS2018–UNSW-NB15
[38]CIC-IDS2017, CSE-CIC-IDS2018, Lycos-IDS2017, Lycos-Unicas-IDS2018XLinear Discriminant Analysis, Decision Tree, Random Forest, XGBoostCIC-IDS2018–
CIC-IDS2017
[39]CIC-IDS2017, CSE-CIC-IDS2018XIsolation Forest, Autoencoder, OCSVMCIC-IDS2018–
CIC-IDS2017
[40]CIC-IDS2017, CSE-CIC-IDS2018XMulti-Layer PerceptronCIC-IDS2018–
CIC-IDS2017
[41]UNSW-NB15, CIC-CSE-IDS2018, ToN-IoT, BoT-IoTXDecision Tree, Random Forest, Extra TreesUNSW-NB15–
BoT-IoT
Table 4. Attack grouping technique comparison.
CriterionCyber Kill Chain-BasedNIST-BasedBehavioral-Based
Grouping PrincipleAttacks are grouped according to their dominant role in the attack lifecycle.Attacks are grouped according to operational impact.Attacks are grouped according to observable traffic behavior.
Nature of GroupingSemantic and stage basedSemantic and impact basedData driven and behavior based
Relation to Feature SpaceIndirect.Indirect.Direct: grouping is aligned with measurable traffic features.
Dependence on Contextual InterpretationHigh: requires interpretation of the attack’s role within a broader scenarioHigh: depends on how attack categories are defined and labeledLow: grouping is driven by traffic patterns, without requiring interpretation of attack intent or context
Consistency Across DatasetsLimited: the same attack may be assigned differently depending on scenario interpretationLimited: category definitions and label granularity may vary across datasetsHigh: behavioral patterns are more stable across datasets than semantic labels
Suitability for MLModerateModerateHigh
Expected Cross-Dataset TransferabilityModerateModerateHigh
Table 5. Distribution of traffic types in the CIC-IDS2017 and CSE-CIC-IDS2018 datasets.
Traffic TypeCIC-IDS2017%CSE-CIC-IDS2018%New Label
Benign2,271,32085.099%13,390,24983.812%Benign
DoS GoldenEye10,2930.386%41,5080.260%DoS
DoS Slowloris57960.217%10,9900.069%
DoS Hulk230,1248.622%461,9122.891%
DoS Slowhttptest54990.206%139,8900.876%
DDoS LOIC-HTTP128,0254.797%576,1913.606%DDoS
DDoS LOIC-UDP00.000%17300.011%
DDoS HOIC00.000%686,0124.294%
SSH-Patator58970.221%187,5891.174%Patator
FTP-Patator79350.297%193,3541.210%
Botnet19560.073%286,1911.791%Bot
Web Attack—Brute Force15070.056%6110.004%Web Attack
Web Attack—XSS6520.024%2300.001%
Web Attack—SQL Injection210.001%870.001%
Total2,669,025100%15,976,544100%
Table 6. Distribution of traffic types in the CIC-DDoS2019 dataset.
Traffic TypeInstances%New Label
Benign2,273,0971.8978%Benign
DDoS-DNS5,071,0114.2338%DDoS
DDoS-LDAP21,799,83018.2009%
DDoS-MSSQL4,522,4923.7759%
DDoS-NTP1,202,6421.0041%
DDoS-SNMP5,159,8704.3080%
DDoS-NetBIOS4,093,2793.4175%
DDoS-SSDP26,106,51121.7966%
DDoS-SYN15,822,88913.2107%
DDoS-TFTP2,008,2581.6767%
DDoS-UDP31,346,45526.1715%
DDoS-UDPLag366,4610.3060%
DDoS-WebDDoS4390.0004%
Total119,773,234100%
Table 7. Top ten selected features for each stage.
StageTop Ten Selected Features
Stage 1
Benign/Attack
1.   
Packet Length Std
2.   
Packet Length Variance
3.   
Avg Bwd Segment Size
4.   
Max Packet Length
5.   
Bwd Packet Length Max
6.   
Total Length of Bwd Packets
7.   
Bwd Packet Length Std
8.   
Average Packet Size
9.   
Subflow Fwd Bytes
10. 
Fwd Packet Length Max
Stage 2
Attack Group 1/Attack Group 2
1.   
Init_Win_bytes_backward
2.   
Subflow Fwd Bytes
3.   
Bwd Packet Length Min
4.   
Total Length of Fwd Packets
5.   
Fwd Packet Length Mean
6.   
Fwd Packet Length Max
7.   
Fwd Packet Length Std
8.   
Bwd Header Length
9.   
Fwd IAT Mean
10. 
Avg Fwd Segment Size
Stage 3 (Classifier 1)
DoS/DDoS
1.   
min_seg_size_forward
2.   
Flow Packets/s
3.   
Flow Duration
4.   
Flow IAT Mean
5.   
Init_Win_bytes_backward
6.   
Flow IAT Max
7.   
Fwd Packets/s
8.   
Init_Win_bytes_forward
9.   
Fwd IAT Max
10. 
Min Packet Length
Stage 3 (Classifier 2)
Bot/Patator/Web Attack
1.   
Destination Port
2.   
min_seg_size_forward
3.   
Max Packet Length
4.   
Packet Length Std
5.   
Bwd IAT Min
6.   
Init_Win_bytes_backward
7.   
Flow IAT Mean
8.   
Bwd Packet Length Min
9.   
Fwd Packet Length Max
10. 
Flow IAT Std
Table 8. Hyperparameter search spaces and optimal values selected for each stage.
ML ModelHyperparameterSearch SpaceStage 1Stage 2Stage 3
Classifier 1Classifier 2
XGBoostn_estimators [ 50 , 100 , 300 ] 300100300300
max_depth [ 3 , 6 , 10 ] 1010106
learning_rate [ 0.005 , 0.05 , 0.1 ] 0.050.020.050.05
subsample [ 0.5 , 0.7 , 0.9 ] 0.90.90.90.7
min_child_weight [ 1 , 2 , 5 ] 5555
CatBoostiterations [ 100 , 250 , 500 ] 500250500500
depth [ 3 , 6 , 10 ] 6101010
learning_rate [ 0.05 , 0.01 , 0.1 ] 0.010.010.010.01
rsm [ 0.5 , 0.7 , 0.9 ] 0.70.70.70.9
l2_leaf_reg [ 1 , 3 , 5 ] 3353
LightGBMn_estimators [ 100 , 300 , 500 ] 500500500300
max_depth [ 3 , 6 , 10 ] 6363
learning_rate [ 0.05 , 0.01 , 0.1 ] 0.050.010.010.01
colsample_bytree [ 0.5 , 0.7 , 0.9 ] 0.70.70.90.7
num_leaves [ 23 , 43 , 63 ] 63436363
Table 9. Intra-dataset validation results (Stage 1).
ML ModelClassAccPreRecF1
XGBoostBenign0.99500.99470.99540.9950
Attack0.99540.99470.9950
CatBoostBenign0.99770.99850.99700.9977
Attack0.99700.99850.9977
LightGBMBenign0.99870.99920.99830.9987
Attack0.99830.99920.9987
Table 10. Intra-dataset validation results (Stage 2).
ML ModelAttack GroupAccPreRecF1
XGBoostAttack Group 10.99930.99990.99870.9993
Attack Group 20.99870.99990.9993
CatBoostAttack Group 10.999910.99990.9999
Attack Group 20.999910.9999
LightGBMAttack Group 10.999910.99990.9999
Attack Group 20.999910.9999
Table 11. Intra-dataset validation results (Stage 3: classifier 1).
ML ModelAttack TypeAccPreRecF1
XGBoostDoS0.99970.999410.9997
DDoS10.99940.9997
CatBoostDoS0.99990.99990.99990.9999
DDoS0.99990.99990.9999
LightGBMDoS0.99980.999710.9998
DDoS10.99970.9998
Table 12. Intra-dataset validation results (Stage 3: Classifier 2).
ML ModelAttack TypeAccPreRecF1
XGBoostWeb attack1111
Bot111
Patator111
CatBoostWeb attack1111
Bot111
Patator111
LightGBMWeb attack1111
Bot111
Patator111
Table 13. Cross-dataset validation results for Stage 1.
ML ModelClassAccPreRecF1
CatBoostBenign0.85310.82870.99770.9061
Attack0.98900.50020.6647
LightGBMBenign0.89440.86900.99770.9294
Attack0.99140.63690.7743
XGBoostBenign0.93670.91950.99770.9570
Attack0.99310.78930.8795
Macro
avg
0.95630.89350.9183
Table 14. Per-attack recall (Stage 1).
Attack TypeRecall Value
DoS SlowHttpTest1
DoS Hulk0.9253
DoS GoldenEye0.7011
DoS SlowLoris0.9845
SSH-Patator1
FTP-Patator1
DDoS HOIC0.6126
DDoS LOIC-UDP0.3094
DDoS LOIC-HTTP0.9866
Web Att BruteForce0.3044
Web Att XSS0.2522
Web Att SQL Injection0.1379
Bot0.4908
Table 15. Cross-dataset validation results for Stage 2.
ML ModelClassAccPreRecF1
XGBoostAttack Group 10.95410.98580.95640.9709
Attack Group 20.84470.94500.8920
CatBoostAttack Group 10.86210.86790.95620.9188
Attack Group 20.81110.40800.5429
LightGBMAttack Group 10.96040.98900.96120.9749
Attack Group 20.86090.95760.9067
Macro
avg
0.92500.95940.9408
Table 16. Cross-dataset validation results for Stage 3, Classifier 1.
ModelMetricDoSDDoSAccuracyMacro
Average
XGBoostPrecision1.00000.96520.97430.9826
Recall0.91111.00000.9556
F1-Score0.95350.98230.9679
LightGBMPrecision1.00000.98460.98890.9923
Recall0.96151.00000.9808
F1-Score0.98040.99240.9864
CatBoostPrecision1.00000.99990.99991.0000
Recall0.99981.00000.9999
F1-Score0.99991.00001.0000
Table 17. Cross-dataset validation results for Stage 3, Classifier 2.
ModelMetricWebBotPatatorAverageMacro
AttackAccuracy
XGBoostPrecision1.00001.00000.99820.99940.9994
Recall0.97200.99911.00000.9904
F1-Score0.98580.99950.99910.9948
LightGBMPrecision0.99610.99950.99820.99910.9979
Recall0.83190.99901.00000.9436
F1-Score0.90660.99930.99910.9683
CatBoostPrecision1.00001.00000.99820.99920.9994
Recall0.96660.99900.99910.9882
F1-Score0.98300.99950.99910.9939
Table 18. Combined recall (Stage 2 × Stage 3).
Attack ClassWeb AttackDoSDDoSBotPatator
Combined Recall0.93090.96100.96120.95670.9576
Macro Combined Recall0.9535
Table 19. End-to-end classification performance of the proposed BHM-IDS.
LevelClass/MetricPrecisionRecallF1-ScoreSupport
Class-levelBenign0.91950.99770.95705,292,116
Patator0.86241.00000.9261156,668
DoS0.98480.84800.9113506,075
DDoS0.99350.76100.86181,246,382
Bot0.83420.44530.5807282,310
Web Attack0.01290.27050.0247928
AggregateMacro average0.76790.72040.71037,484,479
Weighted average0.93170.92730.92317,484,479
OverallAccuracy 0.9273 7,484,479
Table 20. Cross-dataset validation results (Configuration 1: Stage 1).
ModelClassAccuracyPrecisionRecallF1 Score
LightGBMBenign0.82500.80360.99590.8895
Attack0.97670.41240.5799
Table 21. Per-attack recall (Configuration 1: Stage 1).
Attack TypeRecall Value
DoS SlowHttpTest1
DoS Hulk0.9519
DoS GoldenEye0.6780
DoS SlowLoris0.9845
SSH-Patator0.2003
FTP-Patator1
DDoS HOIC0
DDoS LOIC-UDP0
DDoS LOIC-HTTP0.5022
Web Att BruteForce0.0016
Web Att XSS0
Web Att SQL Injection0.0345
Bot0.2847
Table 22. Cross-dataset validation results (Configuration 1: Stage 2).
ClassWeb AttackDoSDDoSBotPatatorAccuracy
Precision0.00870.37120.999610.99760.5698
Recall0.58940.85550.33410.99910.7488
F1-Score0.01710.51780.50080.99950.8555
Macro recall0.705
Table 23. Cross-dataset validation results (Configuration 2: Stage 2).
ClassWeb AttackDoSDDoSBotPatatorAccuracy
Precision0.00800.60810.92761.00000.88390.7950
Recall0.47350.92010.73160.75450.9574
F1-Score0.01580.73230.81800.86010.9192
Macro recall0.7674
Table 24. Cross-dataset validation results (Configuration 3: Stage 2).
ModelMetricAttack Group 1Attack Group 2Accuracy
XGBoostPrecision0.99800.69170.9097
Recall0.88890.9927
F1-Score0.94030.8153
Table 25. Cross-dataset validation results (Configuration 3: Stage 3. Classifier 1).
ModelMetricDoSDDoSAccuracy
XGBoostPrecision0.49160.99940.7013
Recall0.99910.5804
F1-Score0.65890.7343
Table 26. Cross-dataset validation results (Configuration 3: Stage 3. Classifier 2).
ModelMetricWeb AttackBotPatatorAccuracy
XGBoostPrecision110.99820.9994
Recall0.97200.99911
F1-Score0.98580.99950.9991
Table 27. Combined recall (Configuration 3: Stage 2 × Stage 3).
AttackWeb AttackDoSDDoSBotPatator
Combined recall(StageStage3)0.96490.88800.51590.99180.9927
Macro combined recall0.870
Table 28. Shared characteristics between BHM-IDS and related studies.
Characteristics[38][39][40]BHM-IDS
Training DatasetCIC-IDS2017CIC-IDS2017CIC-IDS2017CIC-IDS2017 + CIC-DDoS2019
Testing DatasetCSE-CIC-IDS2018CSE-CIC-IDS2018CSE-CIC-IDS2018CSE-CIC-IDS2018
Binary Classification×
Multi-class Classification××
Evaluation Metrics Shared with BHM-IDSF1-scoreRecall, F1-score, PrecisionRecall_
Table 29. Performance Comparison of BHM-IDS and [39].
Metric[39]BHM-IDS
Precision0.77480.9931
Recall0.93050.7893
F1-Score0.84550.8795
Table 30. Performance Comparison of BHM-IDS and [40].
Attack Class[40]BHM-IDS
DoS0.95880.9610
DDoS0.96370.9612
Bot0.95130.9567
Patator0.96320.9576
Web Attack0.9309
Macro Recall0.95930.9535
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content.