1. Introduction
Climate change has increased the frequency and intensity of extreme weather events worldwide, placing growing stress on the resilience of water resource infrastructure. To address this challenge, a real-time and high-precision hydrological information system is essential for national-scale flood monitoring and early warning [
1]. This system is of high importance for mitigating the significant risks of flooding by enabling the rapid detection of rising water levels in both rivers and reservoirs during heavy rainfall events.
The agricultural sector is particularly vulnerable to water scarcity. Agricultural reservoirs, numbering approximately 17,240 nationwide in South Korea, serve as critical infrastructure, supplying about 60% of the agricultural water demand [
2]. However, only about 10% of these reservoirs are equipped with automatic water level gauges. The majority rely on manual observation by managers or irregular on-site visits for water level data collection [
3]. This leads to various issues, including excessive water use, water loss due to inefficient management, and unbalanced distribution, highlighting the pressing need for a quantitative and real-time water management system.
Traditional water level monitoring typically involves sensor-based measurement. However, during flood events, sensor systems often fail due to submersion, physical damage, or data transmission errors. Consequently, water level and flood discharge prediction technologies utilizing video information (e.g., CCTV, drones) are gaining attention as resilient alternatives that enable continuous visual assessment and real-time flood monitoring, even under harsh conditions. While satellite imagery provides broad area coverage, its daily observation cycle can miss rapid flood events. In contrast, CCTV footage can be captured at minute-level intervals for immediate detection of water level changes, and leveraging existing infrastructure reduces additional installation costs. Even for river water levels, which have traditionally been measured with gauges attached to bridges, there is an accelerating shift towards video-based water level monitoring due to installation constraints and reduced data reliability [
4]. Yu et al. [
5] proposed a differential imaging technique that applies Otsu’s thresholding by analyzing differences between consecutive frames, while Hiroi et al. [
6] developed an infrared image-based water level sensor system for urban flood prediction.
The advancement of video-based water level measurement technologies has been significantly driven by the progress in deep learning, enabling enhanced precision and real-time capabilities. Ma et al. [
7] proposed an automatic water level measurement system from CCTV footage using a deep learning model based on Convolutional Neural Networks (CNNs), and Kim et al. [
8] and Lee et al. [
9] improved real-time prediction accuracy by integrating a physical model with Long Short-Term Memory (LSTM) and Logistic Regression, respectively. Concurrently, research on high-resolution imaging and preprocessing techniques is underway to overcome challenges posed by varying illumination conditions, water surface reflections, and image quality differences in diverse environments. Bhang et al. [
10] and Seo et al. [
11] confirmed that image resolution and observation conditions affect the accuracy of water level prediction. Li et al. [
12], Dhara et al. [
13], and Dal Sasso et al. [
14] proposed image resolution enhancement and AI-based image quality improvement techniques.
In the agricultural sector, research on estimating reservoir storage rates and quantitatively predicting agricultural water supply is also becoming increasingly active. Hong et al. [
15] improved an existing water balance model to assess supply adequacy by comparing supply and demand, while Kim et al. [
16] addressed the issue of inefficient water level gauging networks and proposed an optimal network configuration. Yang et al. [
17], Kim et al. [
18], and Kwon et al. [
19] developed models for estimating water levels in irrigation canals and agricultural reservoirs using CCTV images and CNNs, demonstrating the applicability of video-based water level prediction technology in the agricultural sector.
Video-based water level prediction technology is recognized as a core technology for flood and drought response and for enhancing water usage efficiency, especially possessing high potential for application in agricultural reservoir management. However, relevant research in the agricultural sector is still in its early stages, with a notable lack of field-optimized application cases. Therefore, the primary objective of this study is to identify the most suitable deep learning model for video-based water level recognition in ungauged agricultural reservoirs. To this end, three representative architectures—CNN, ResNet, and EfficientNet—were compared and evaluated. Our goal is to support real-time, data-driven agricultural water management under climate change.
2. Materials and Methods
2.1. Study Area
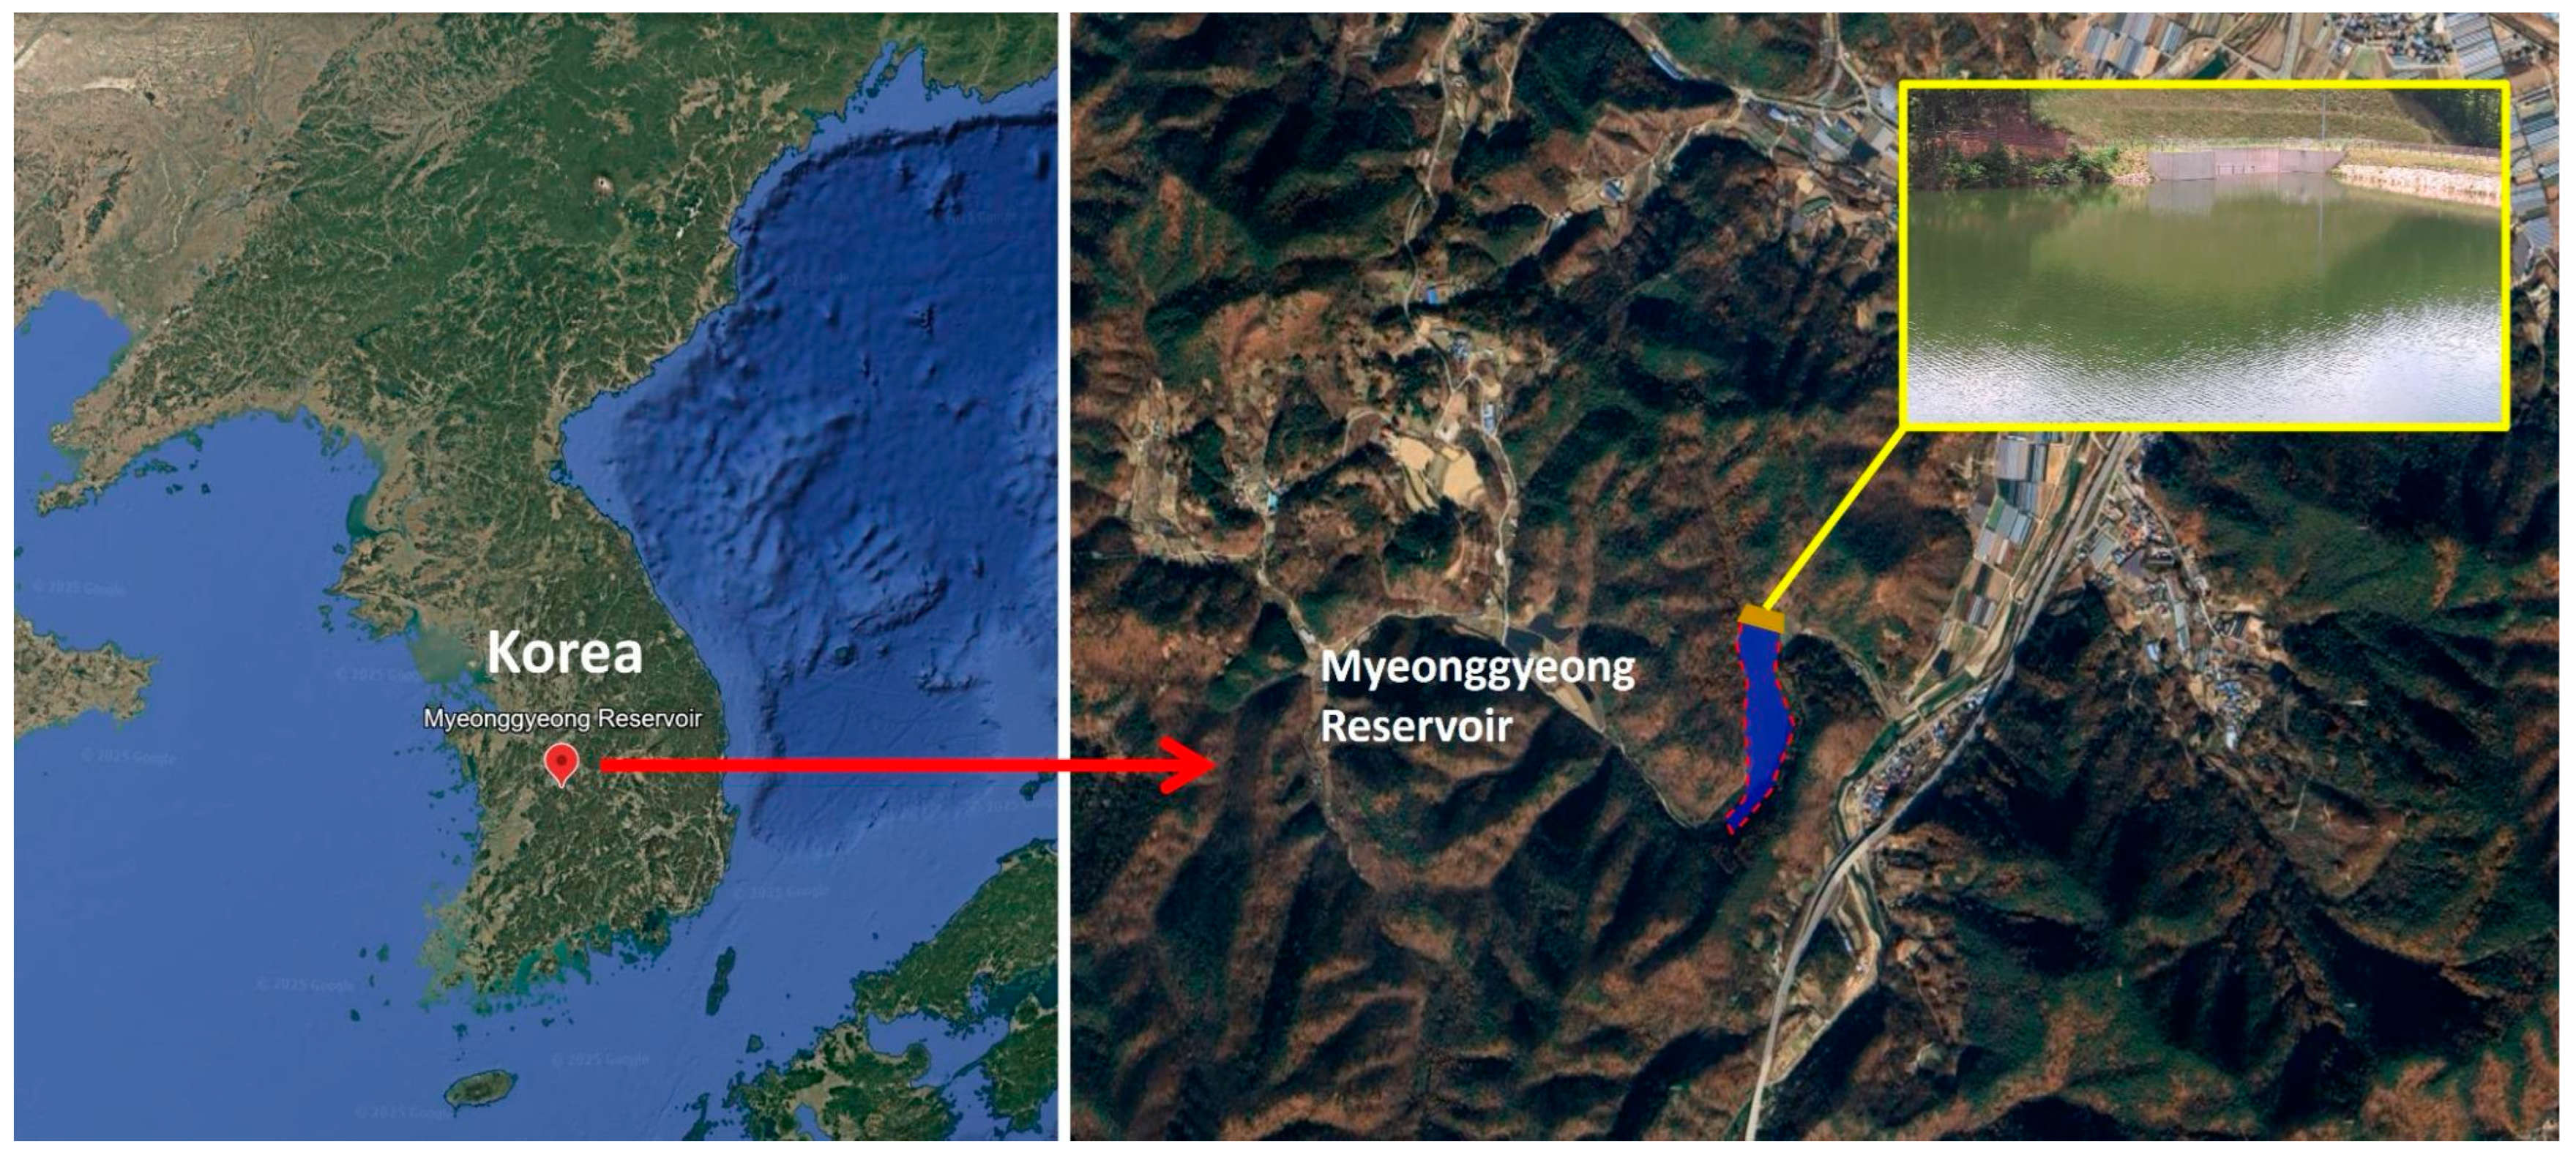
This study was conducted at the Myeonggyeong Reservoir, located in Sangji-ri, Gunseo-myeon, Okcheon-gun, Chungcheongbuk-do. The Myeonggyeong Reservoir is a small to medium-sized agricultural reservoir constructed in 1956 and managed by the Okcheon-Yeongdong Regional Office of Korea Rural Community Corporation (KRC), Chungbuk Regional Headquarters. The embankment is a zone fill dam with a height of 19.4 m and a length of 109 m. Its watershed area is 367 ha, benefited area is 88 ha, full water surface area is 6.5 ha, and total storage capacity is 414,000 m
3. The region experiences a humid continental climate, with an average annual precipitation of approximately 1200 mm. Most rainfall occurs during the monsoon season (June–August), when heavy convective storms can raise daily totals above 100 mm, while winter months (December–February) receive less than 50 mm per month. These climatic characteristics influence reservoir inflow patterns and pose challenges for both drought and flood management. This study developed a deep learning model for water level estimation based on video data collected from a fixed CCTV camera installed on the road adjacent to the reservoir embankment.
Figure 1 shows the satellite map of the study area.
2.2. Dataset Configuration
2.2.1. Video Data Collection
The video data used in this study consist of footage captured at one-hour intervals from an internal server of the Korea Rural Community Corporation, spanning approximately two years from 8 July 2020 to 18 July 2022. From a total of 17,784 time-series water level records, 11,727 images were initially secured after removing entries with missing values. Among these, 1432 images with clear visibility and accurate water level annotations were selected for manual segmentation and model training. This selection process was designed to ensure reliable labeling and high-quality learning input, but we acknowledge that this filtering may introduce potential bias, which is addressed in the Discussion Section. Although the original data were recorded as CCTV video, only still images (in JPG format) were extracted at fixed time intervals and used for the analysis. The image resolution is 1920 × 1080 pixels, and the average file size is approximately 82 KB. Each image is linked with water level (m) and storage rate (%) information at the time of collection, with a measurement error of ±0.01 m. Water levels range from 141.80 m (storage rate 42.5%) to a maximum of 146.42 m (storage rate 103.5%).
2.2.2. Data Preprocessing and Labeling
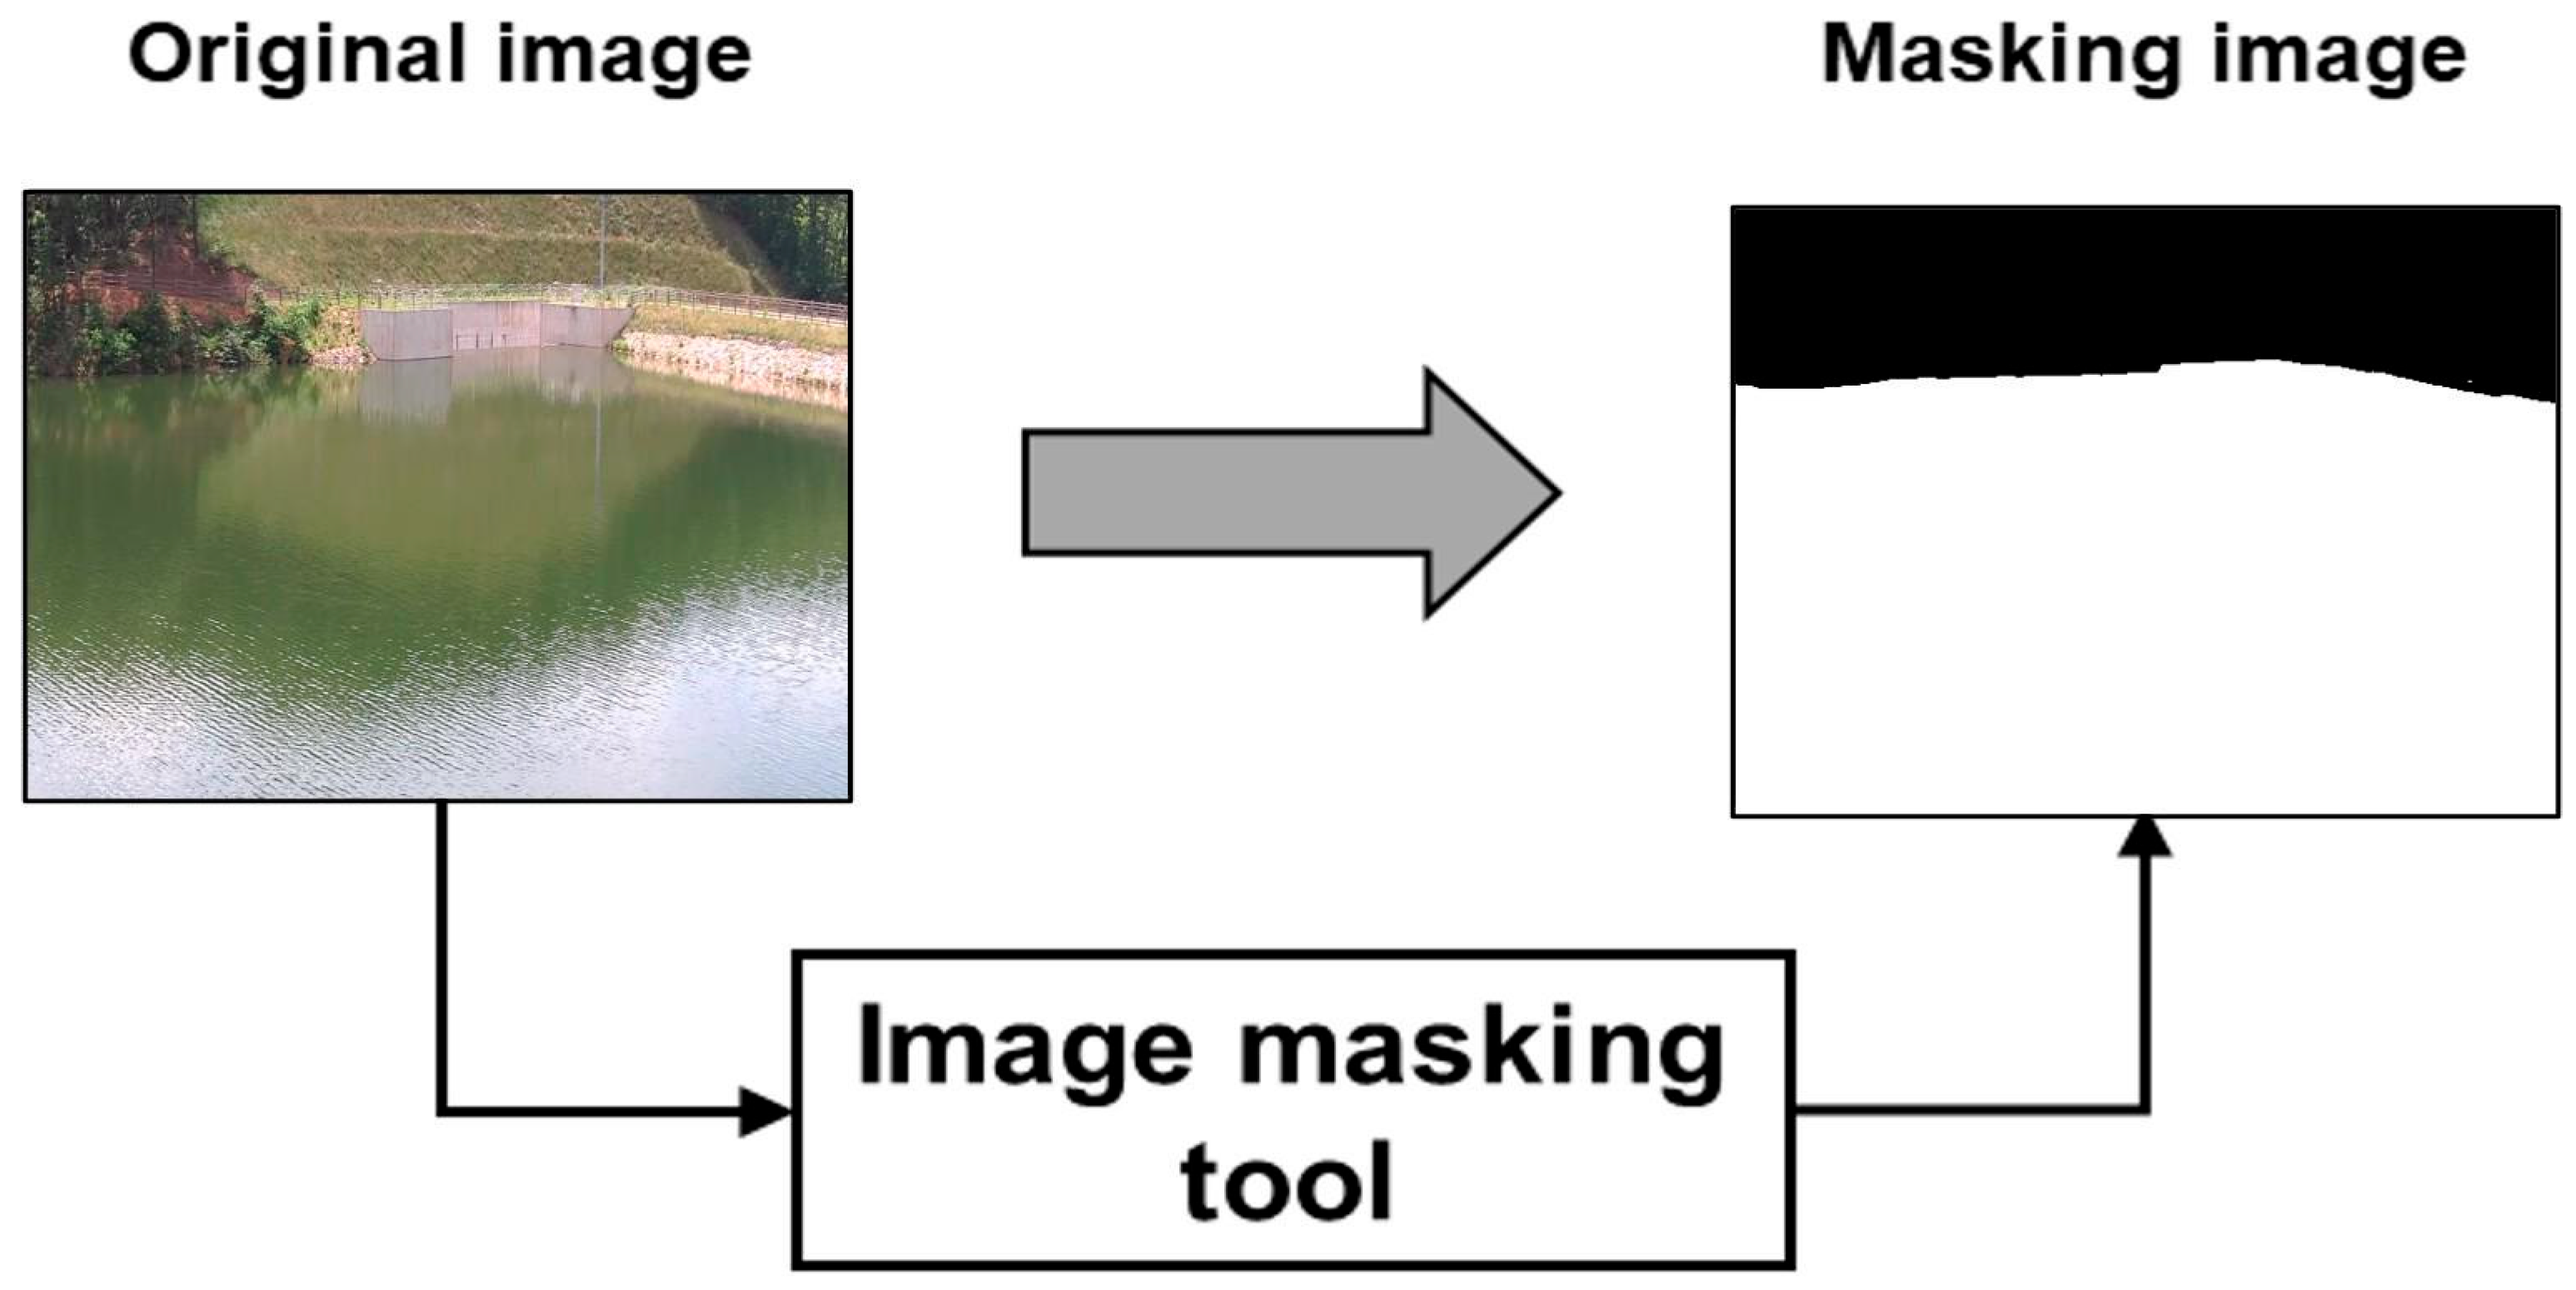
To train the deep learning model for video-based water level recognition, labeling and masking operations were performed on the collected video data. Each image file was assigned labels including the date (year, month, day), time, and water level values. Binary masking images for 1432 images were created using remove.bg, a web-based background removal tool, followed by manual correction. Water areas were labeled in white and non-water areas in black (
Figure 2). This process serves as a crucial step toward ensuring the accuracy and consistency of model training [
20,
21].
2.2.3. Water Level Interval Classification Method
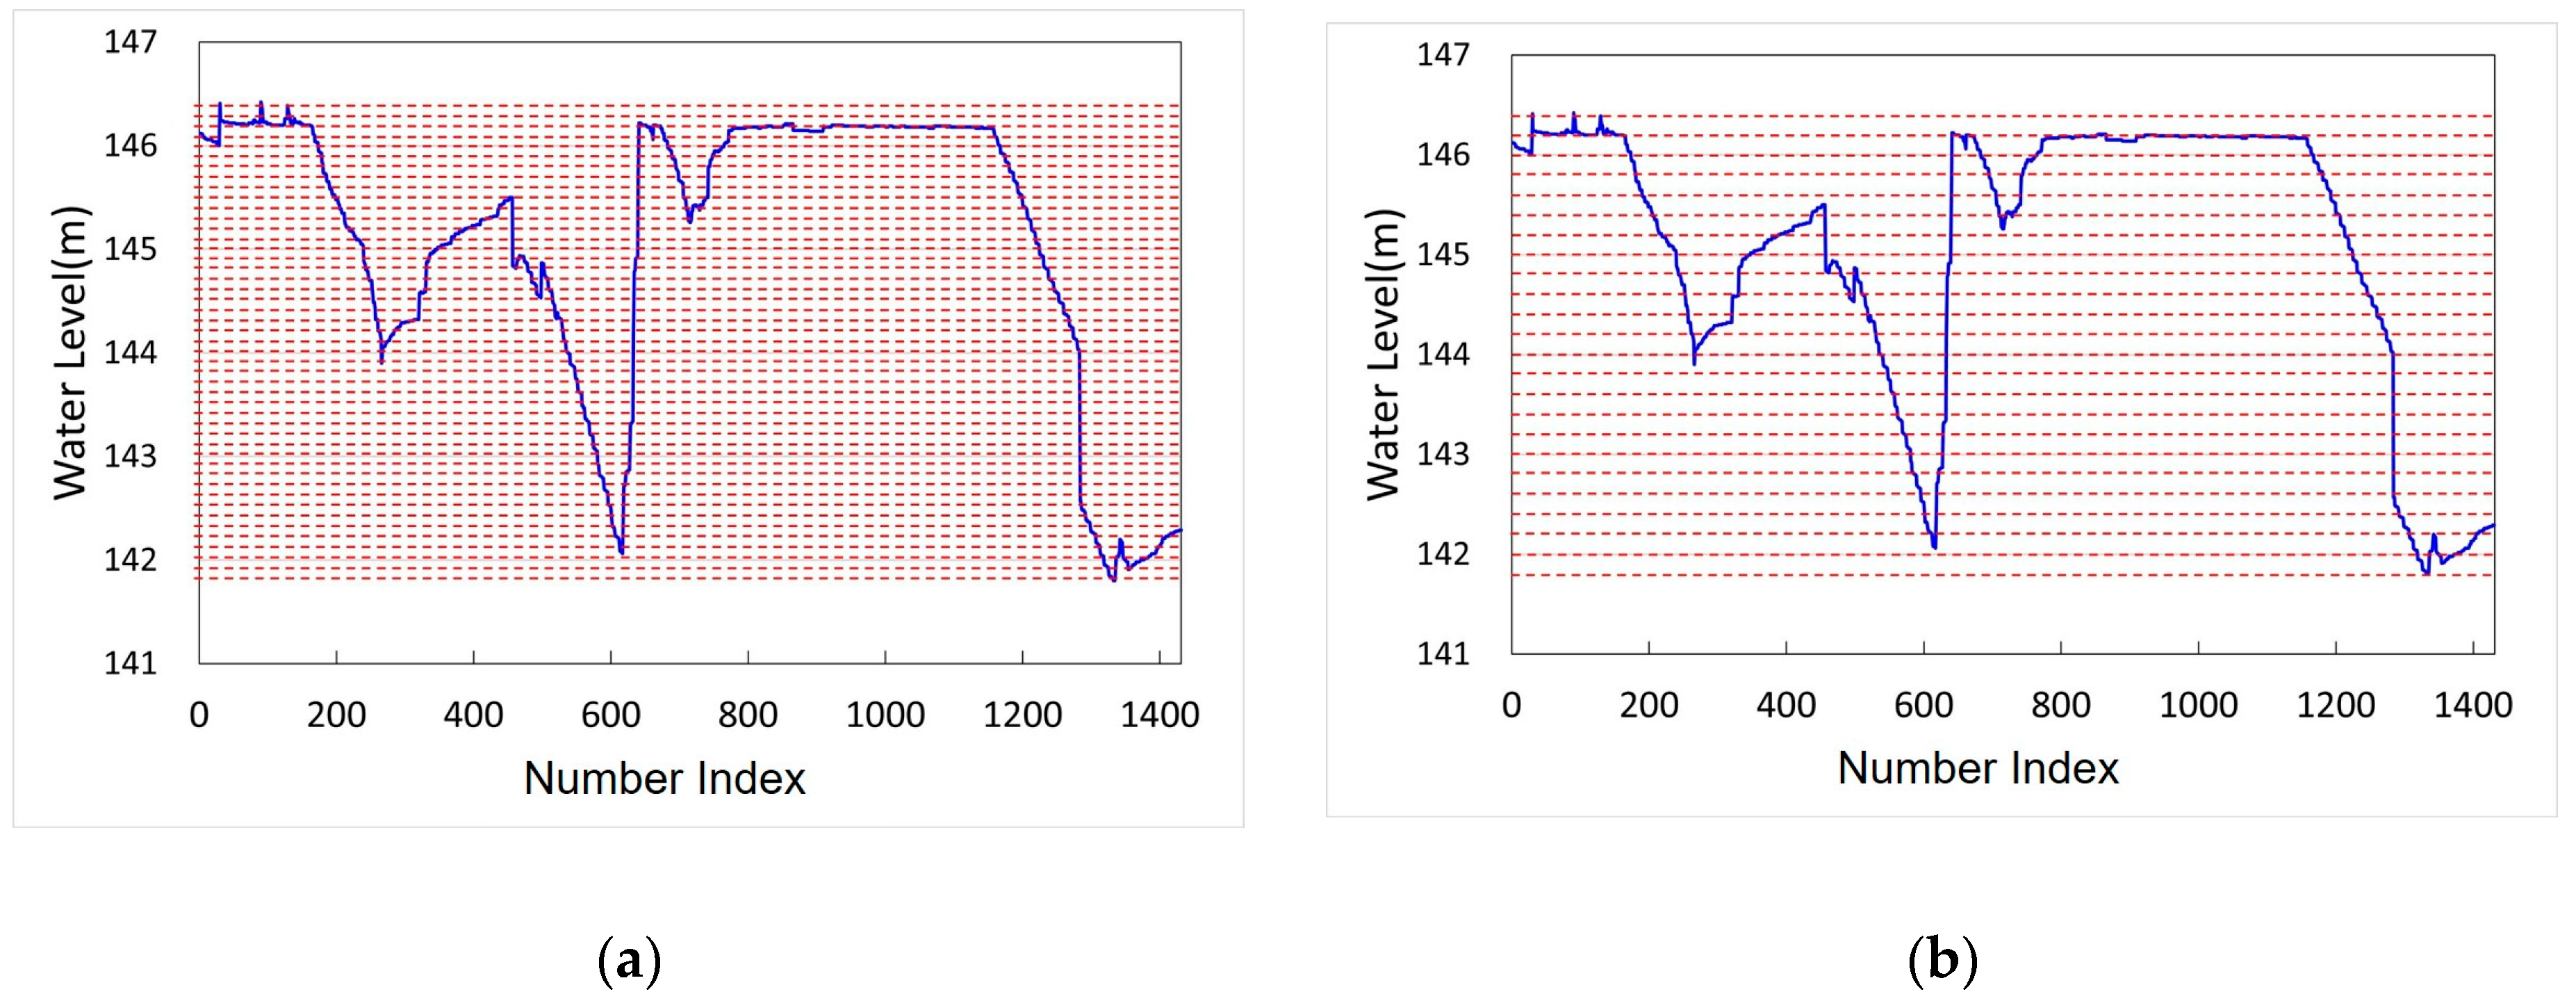
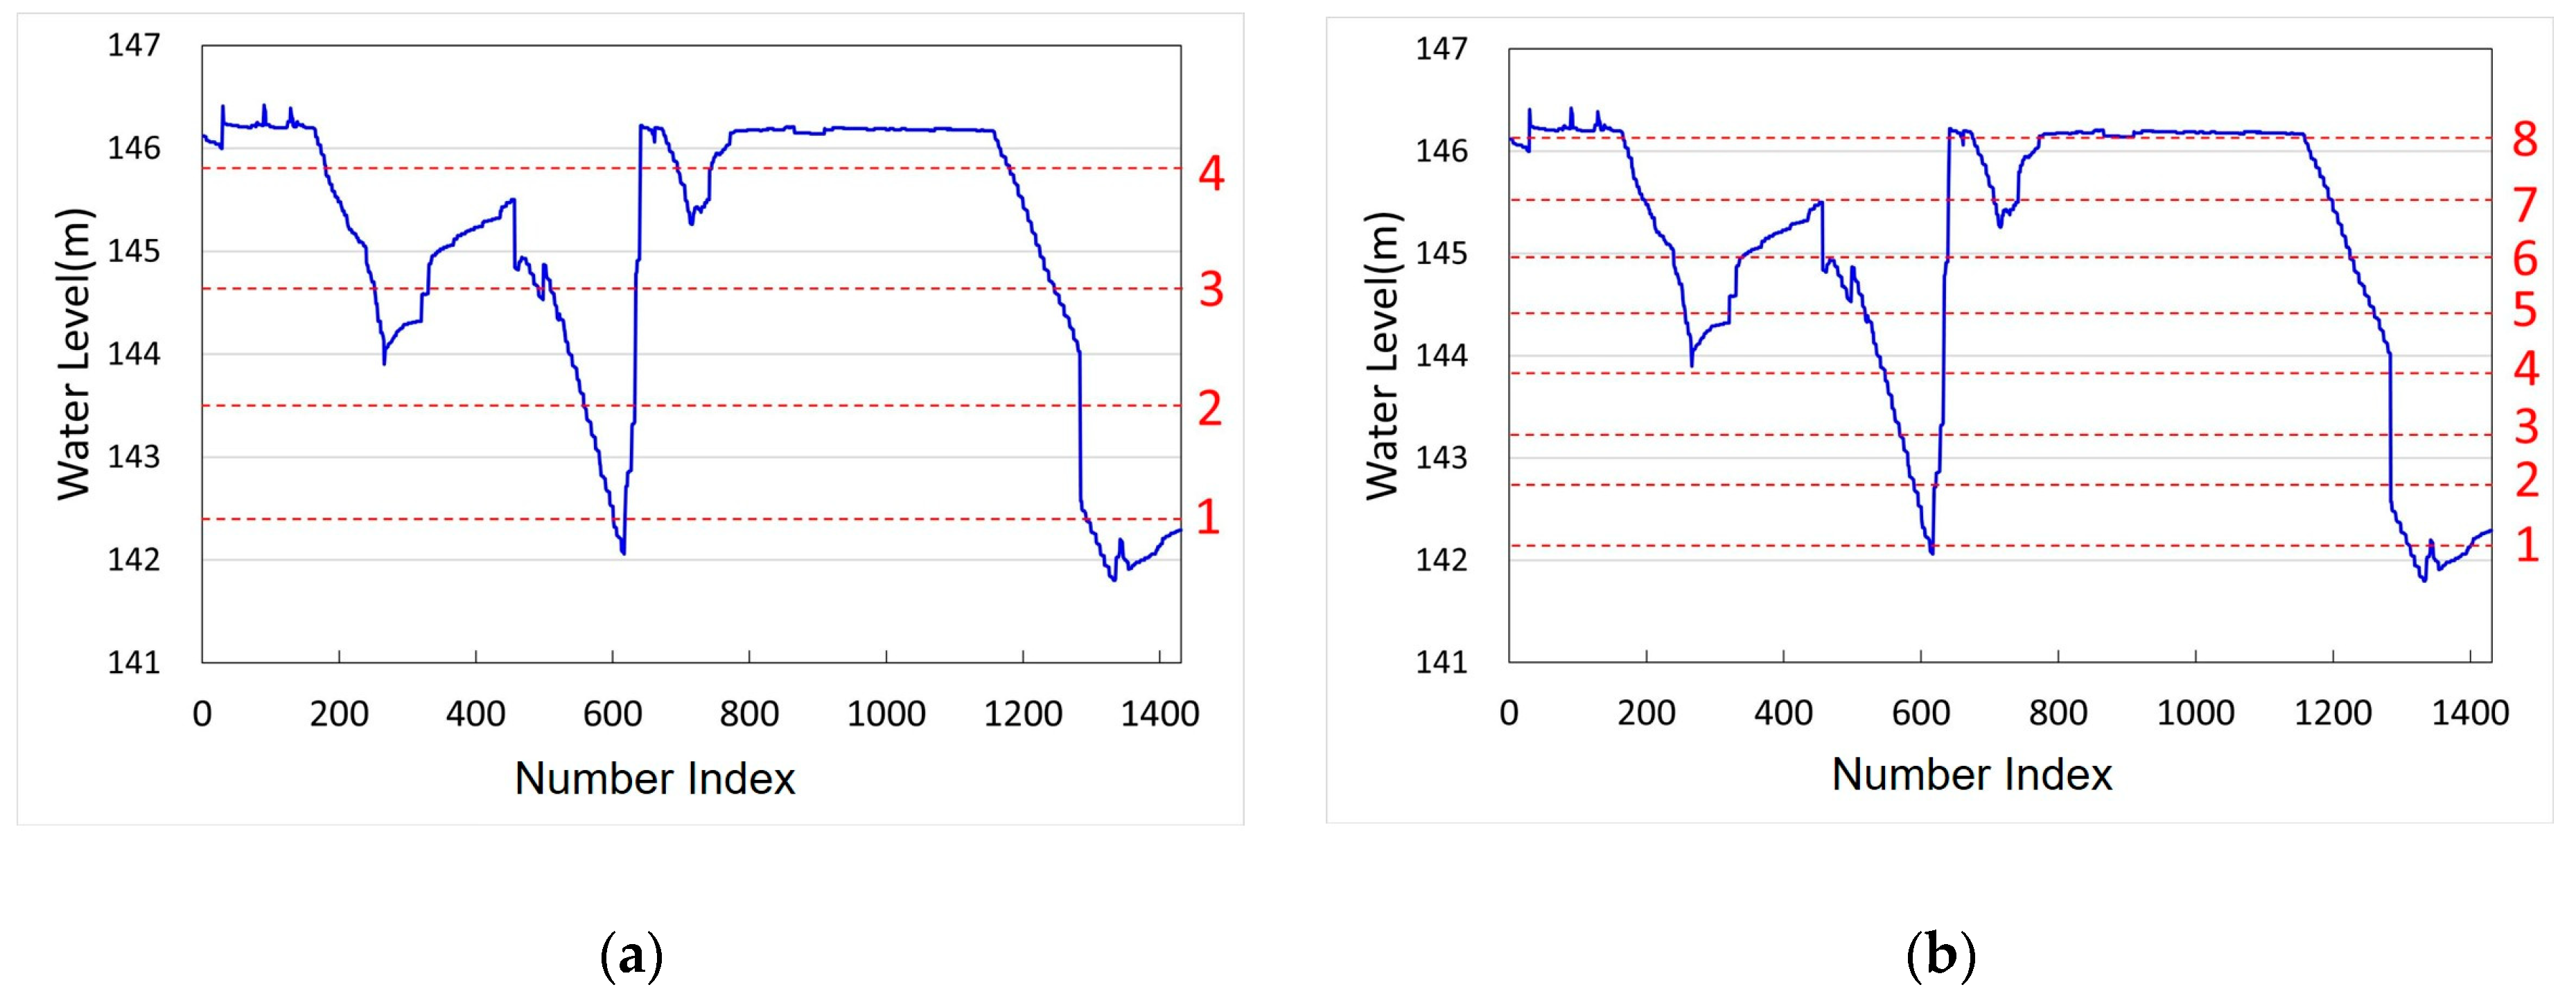
To enhance the learning efficiency for water level recognition, water level intervals were classified. The first method involved setting intervals at equal increments of 10 cm and 20 cm (
Figure 3). The second method utilized the Jenks Natural Breaks algorithm to classify water levels into four and eight statistically optimal groups, respectively, for separate classification experiments (
Figure 4). The Jenks method helps compensate for data distribution imbalances and enables a balanced distribution of training data within each interval, contributing to improved generalization performance [
22].
2.3. Image Segmentation Model
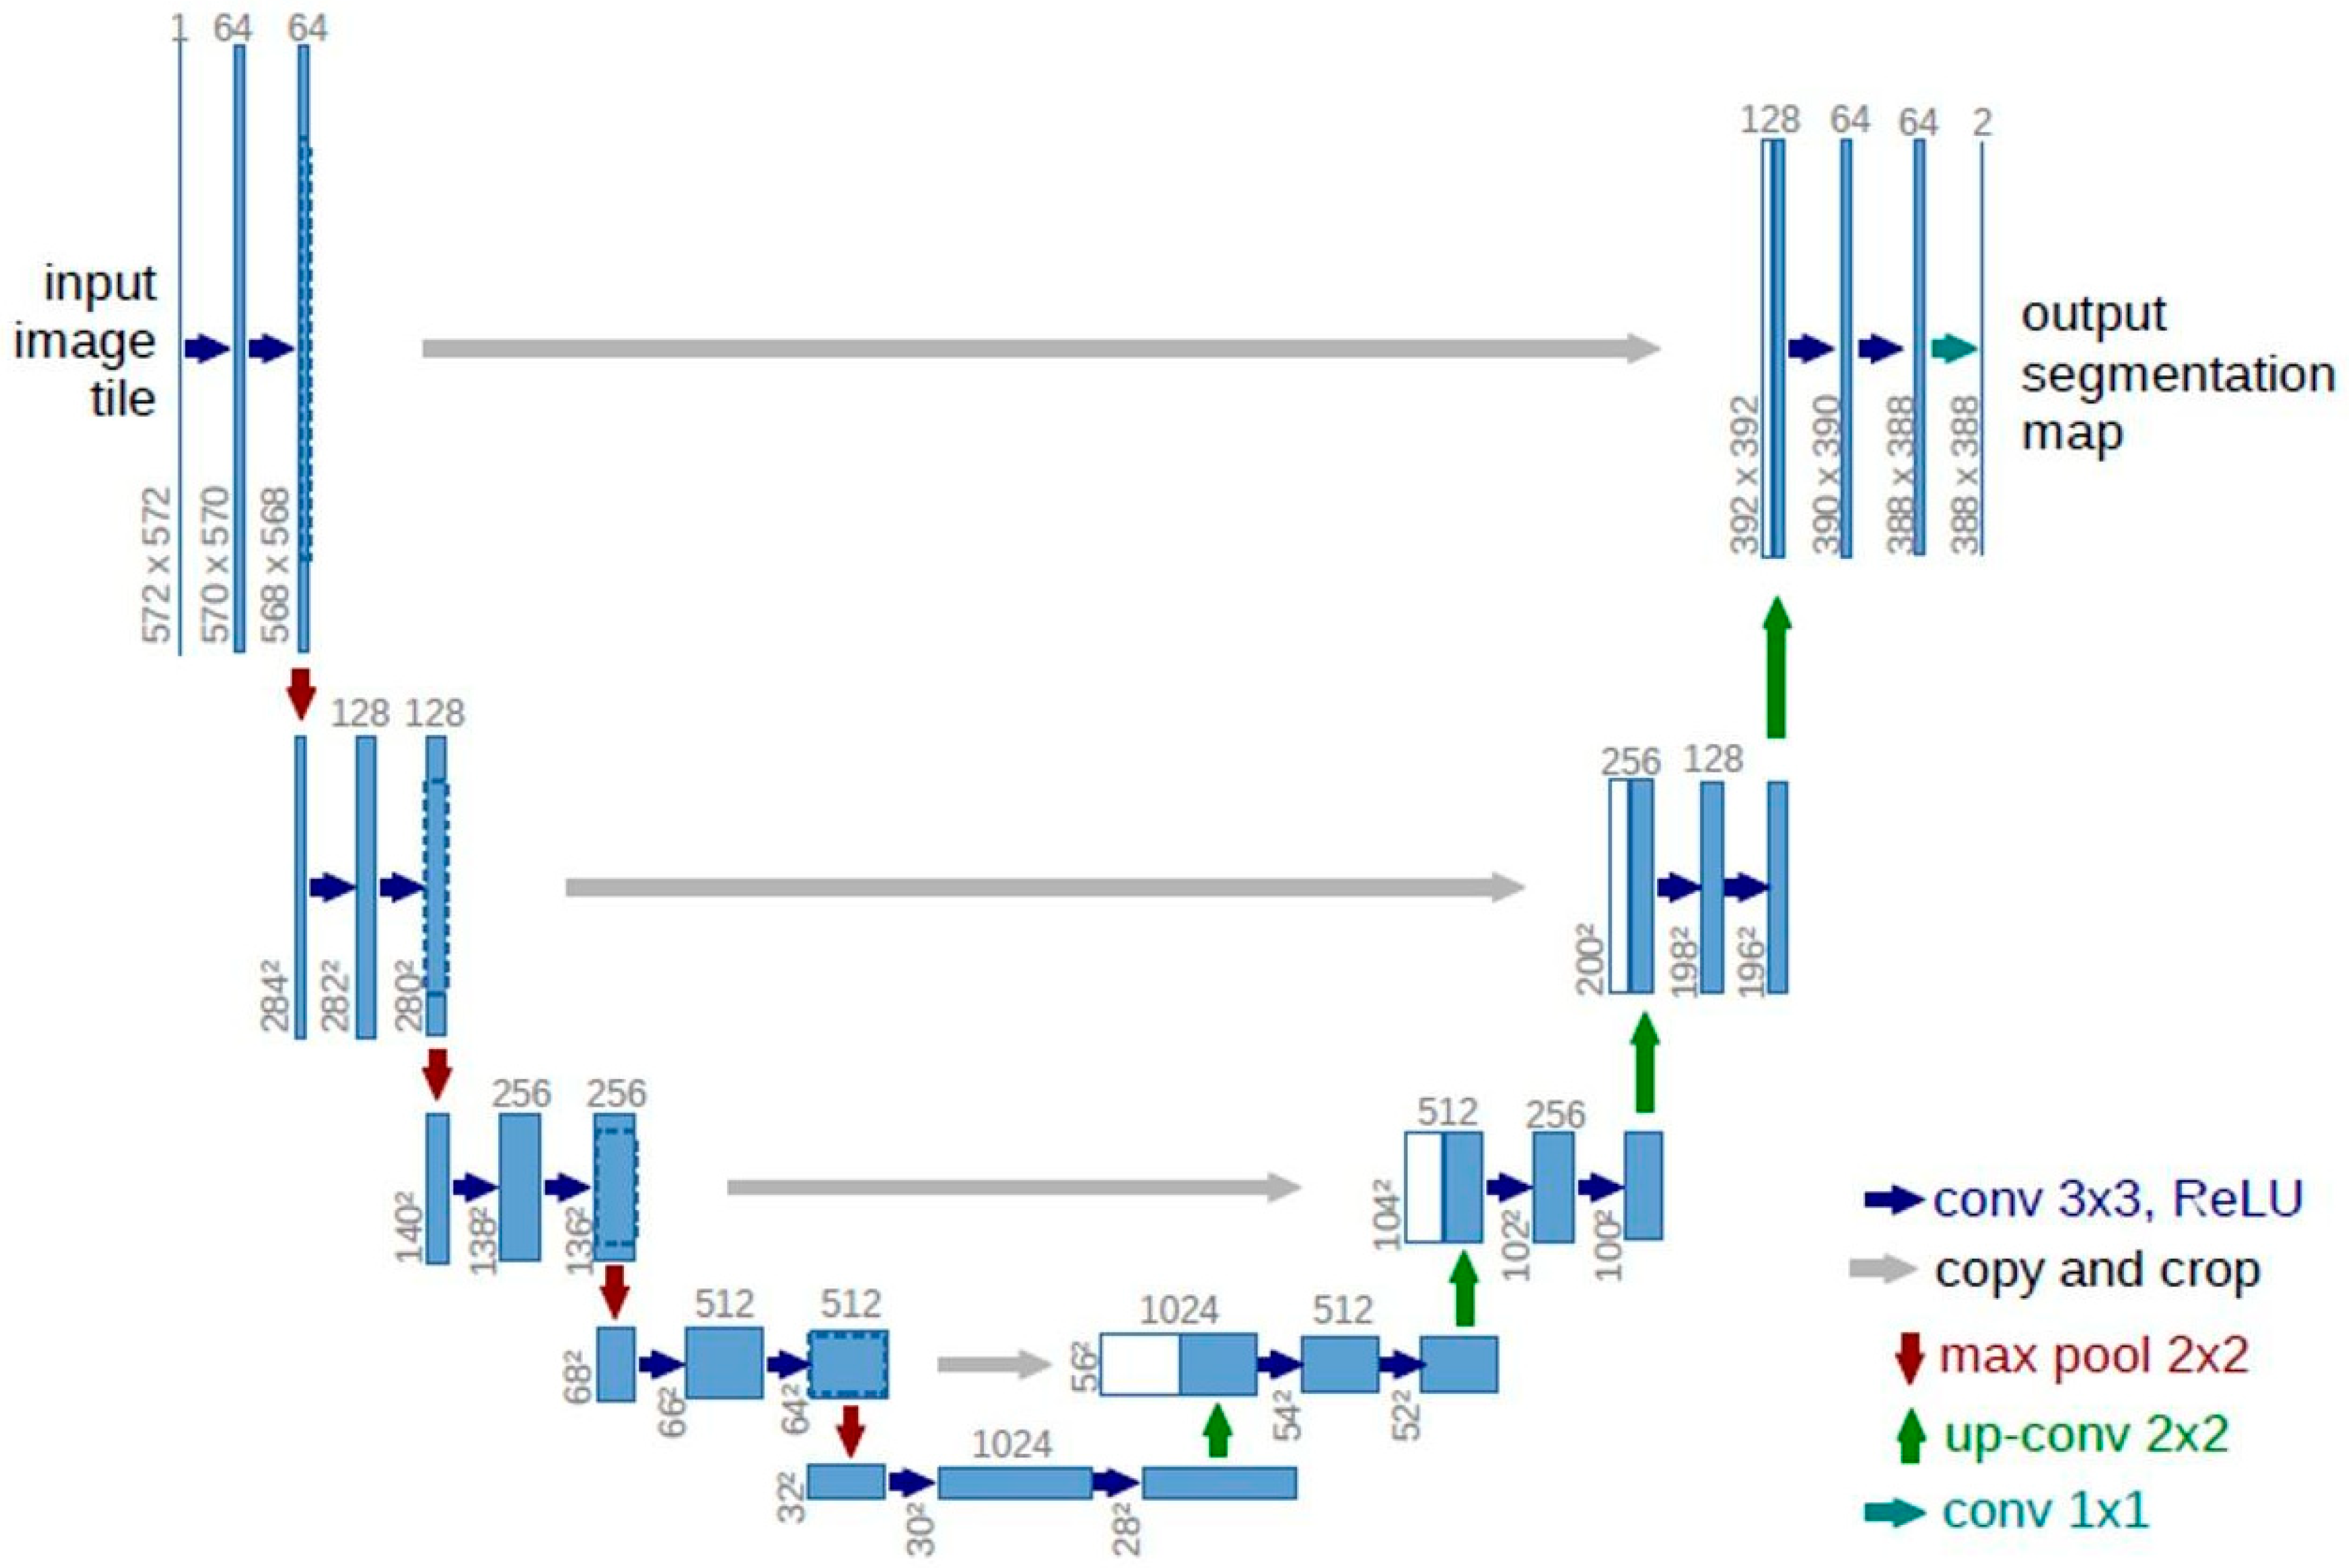
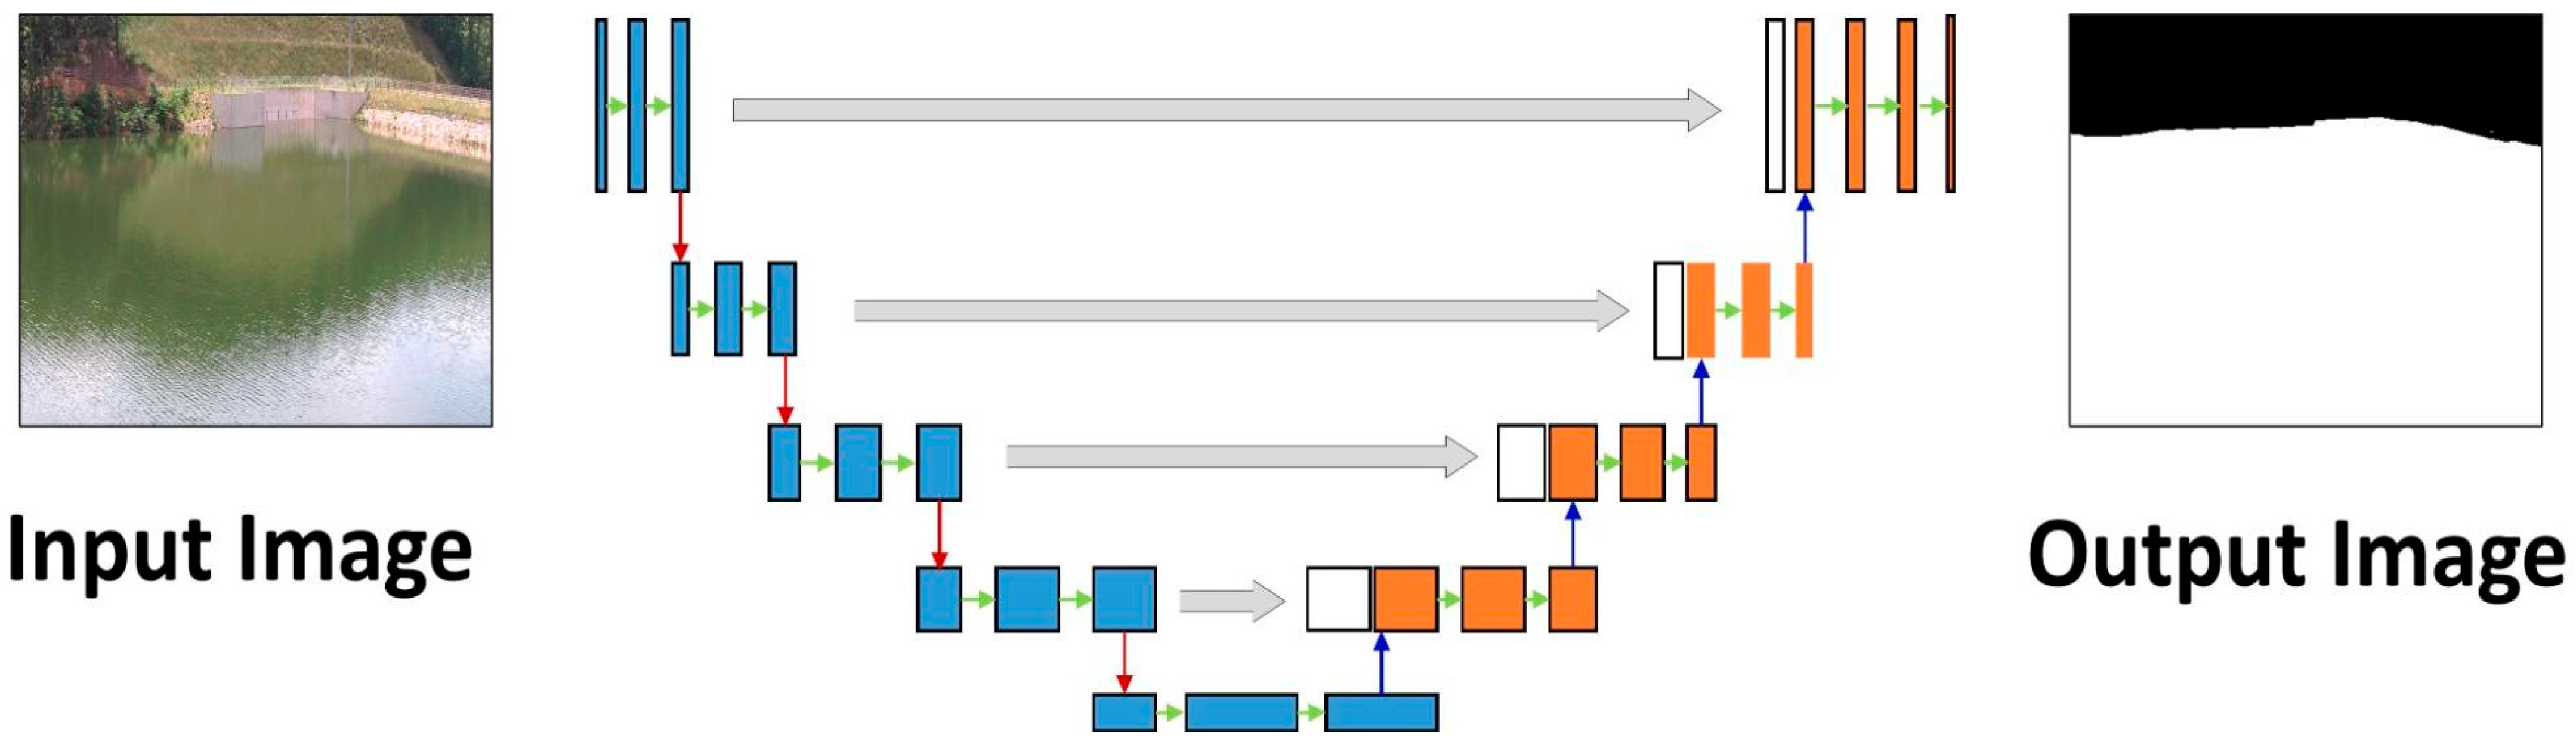
Image segmentation is the process of assigning a class to each pixel within an image. In this study, the U-Net [
21] model was applied to distinguish between water surface and non-water surface regions. U-Net, based on a symmetric encoder–decoder architecture with skip connections to restore high-resolution features, was used. It is popular in medical and hydrological imaging. Compared to existing models such as the Fully Convolutional Network (FCN; Long et al., 2015) [
23], SegNet (Badrinarayanan et al., 2017) [
20], and DeepLabV3 (Chen et al., 2017) [
24], U-Net minimizes the spatial information loss of objects and is suitable for pixel-level precise segmentation (
Figure 5).
2.4. Image Classification Model
Image classification involves categorizing a given input into one of predefined classes. In this study, three models, CNN, ResNet (He et al., 2016) [
25], and EfficientNet (Tan and Le, 2019) [
26], were used to compare water level recognition accuracy.
2.4.1. CNN
CNN is a representative deep learning architecture for extracting features and classifying images. It effectively learns input image features through convolutional layers, pooling layers, and ReLU activation functions (LeCun and Bengio, 1995) [
27]. This model is well suited for recognizing visual patterns associated with water level changes and is widely used as a standard model in various fields.
2.4.2. ResNet
ResNet introduces the concept of residual connections to prevent performance degradation with increasing network depth, addressing the vanishing gradient problem that can occur in very deep neural networks. It demonstrates learning stability and high generalization performance, making it highly applicable to video-based water level recognition [
25].
2.4.3. EfficientNet
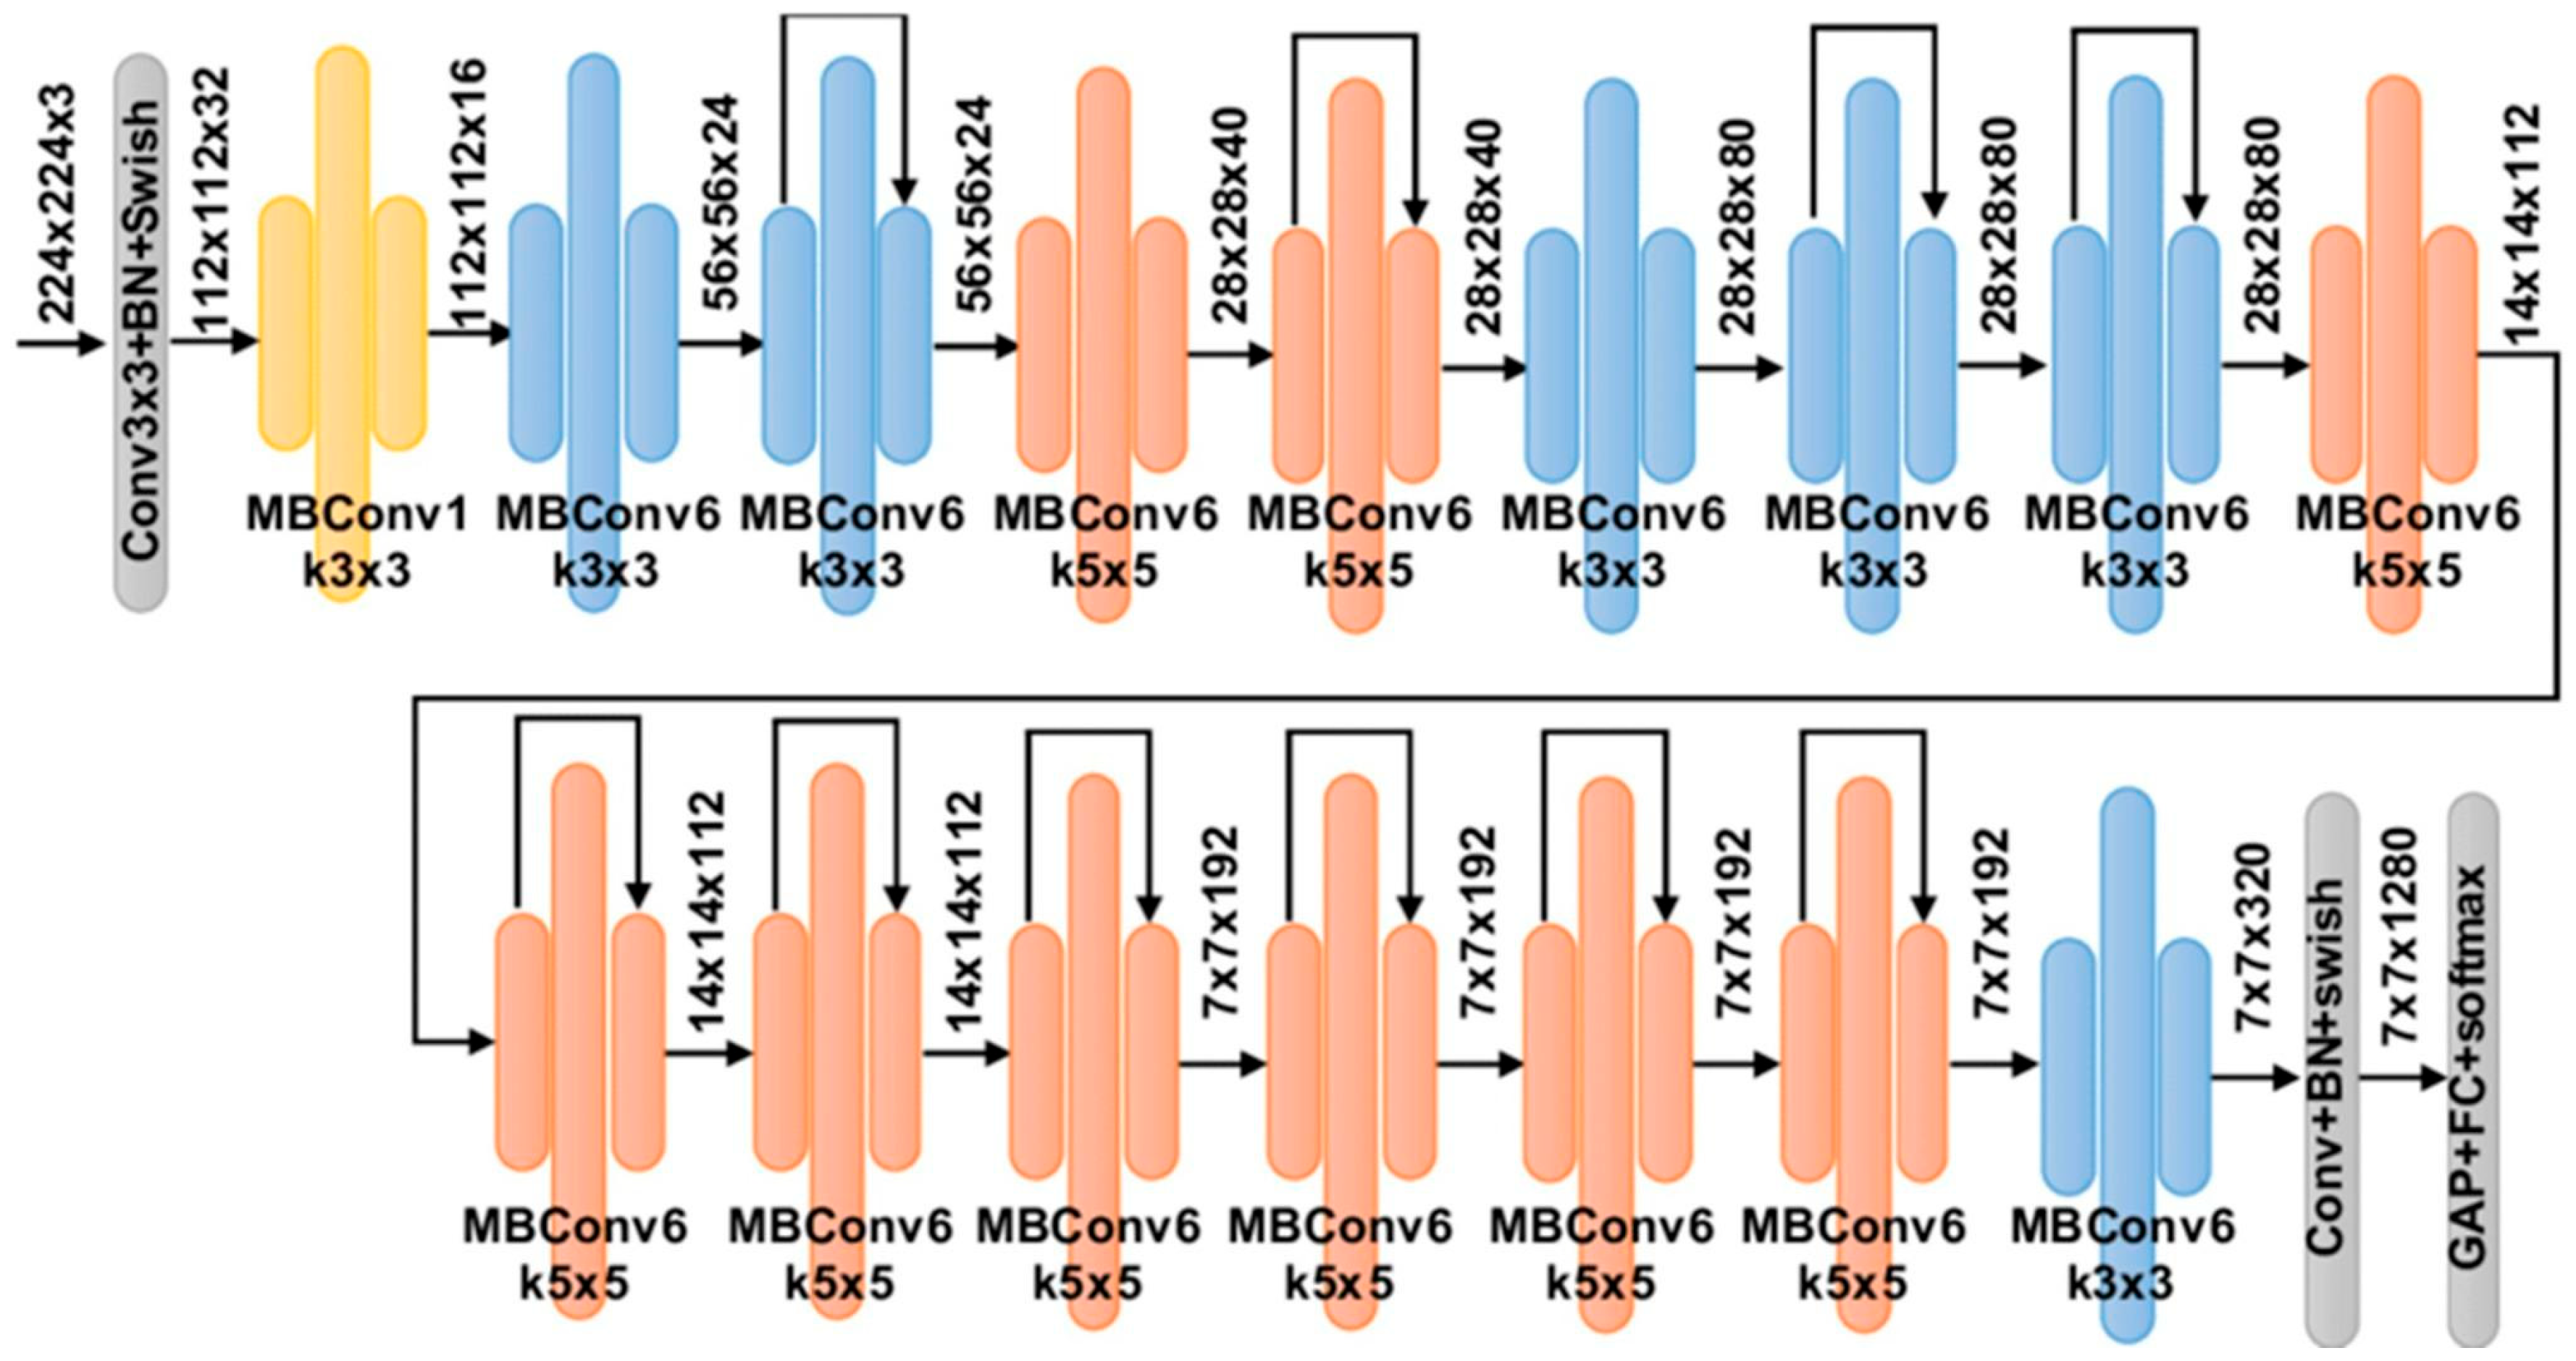
EfficientNet uses a compound scaling method that uniformly scales network depth, width, and resolution, providing high accuracy within limited resources. Designed based on the Neural Architecture Search (NAS), it encompasses various architectures from B0 to B7, achieving both lightweightness and performance in image classification and object detection tasks (
Figure 6) [
26].
2.5. Performance Evaluation Metrics
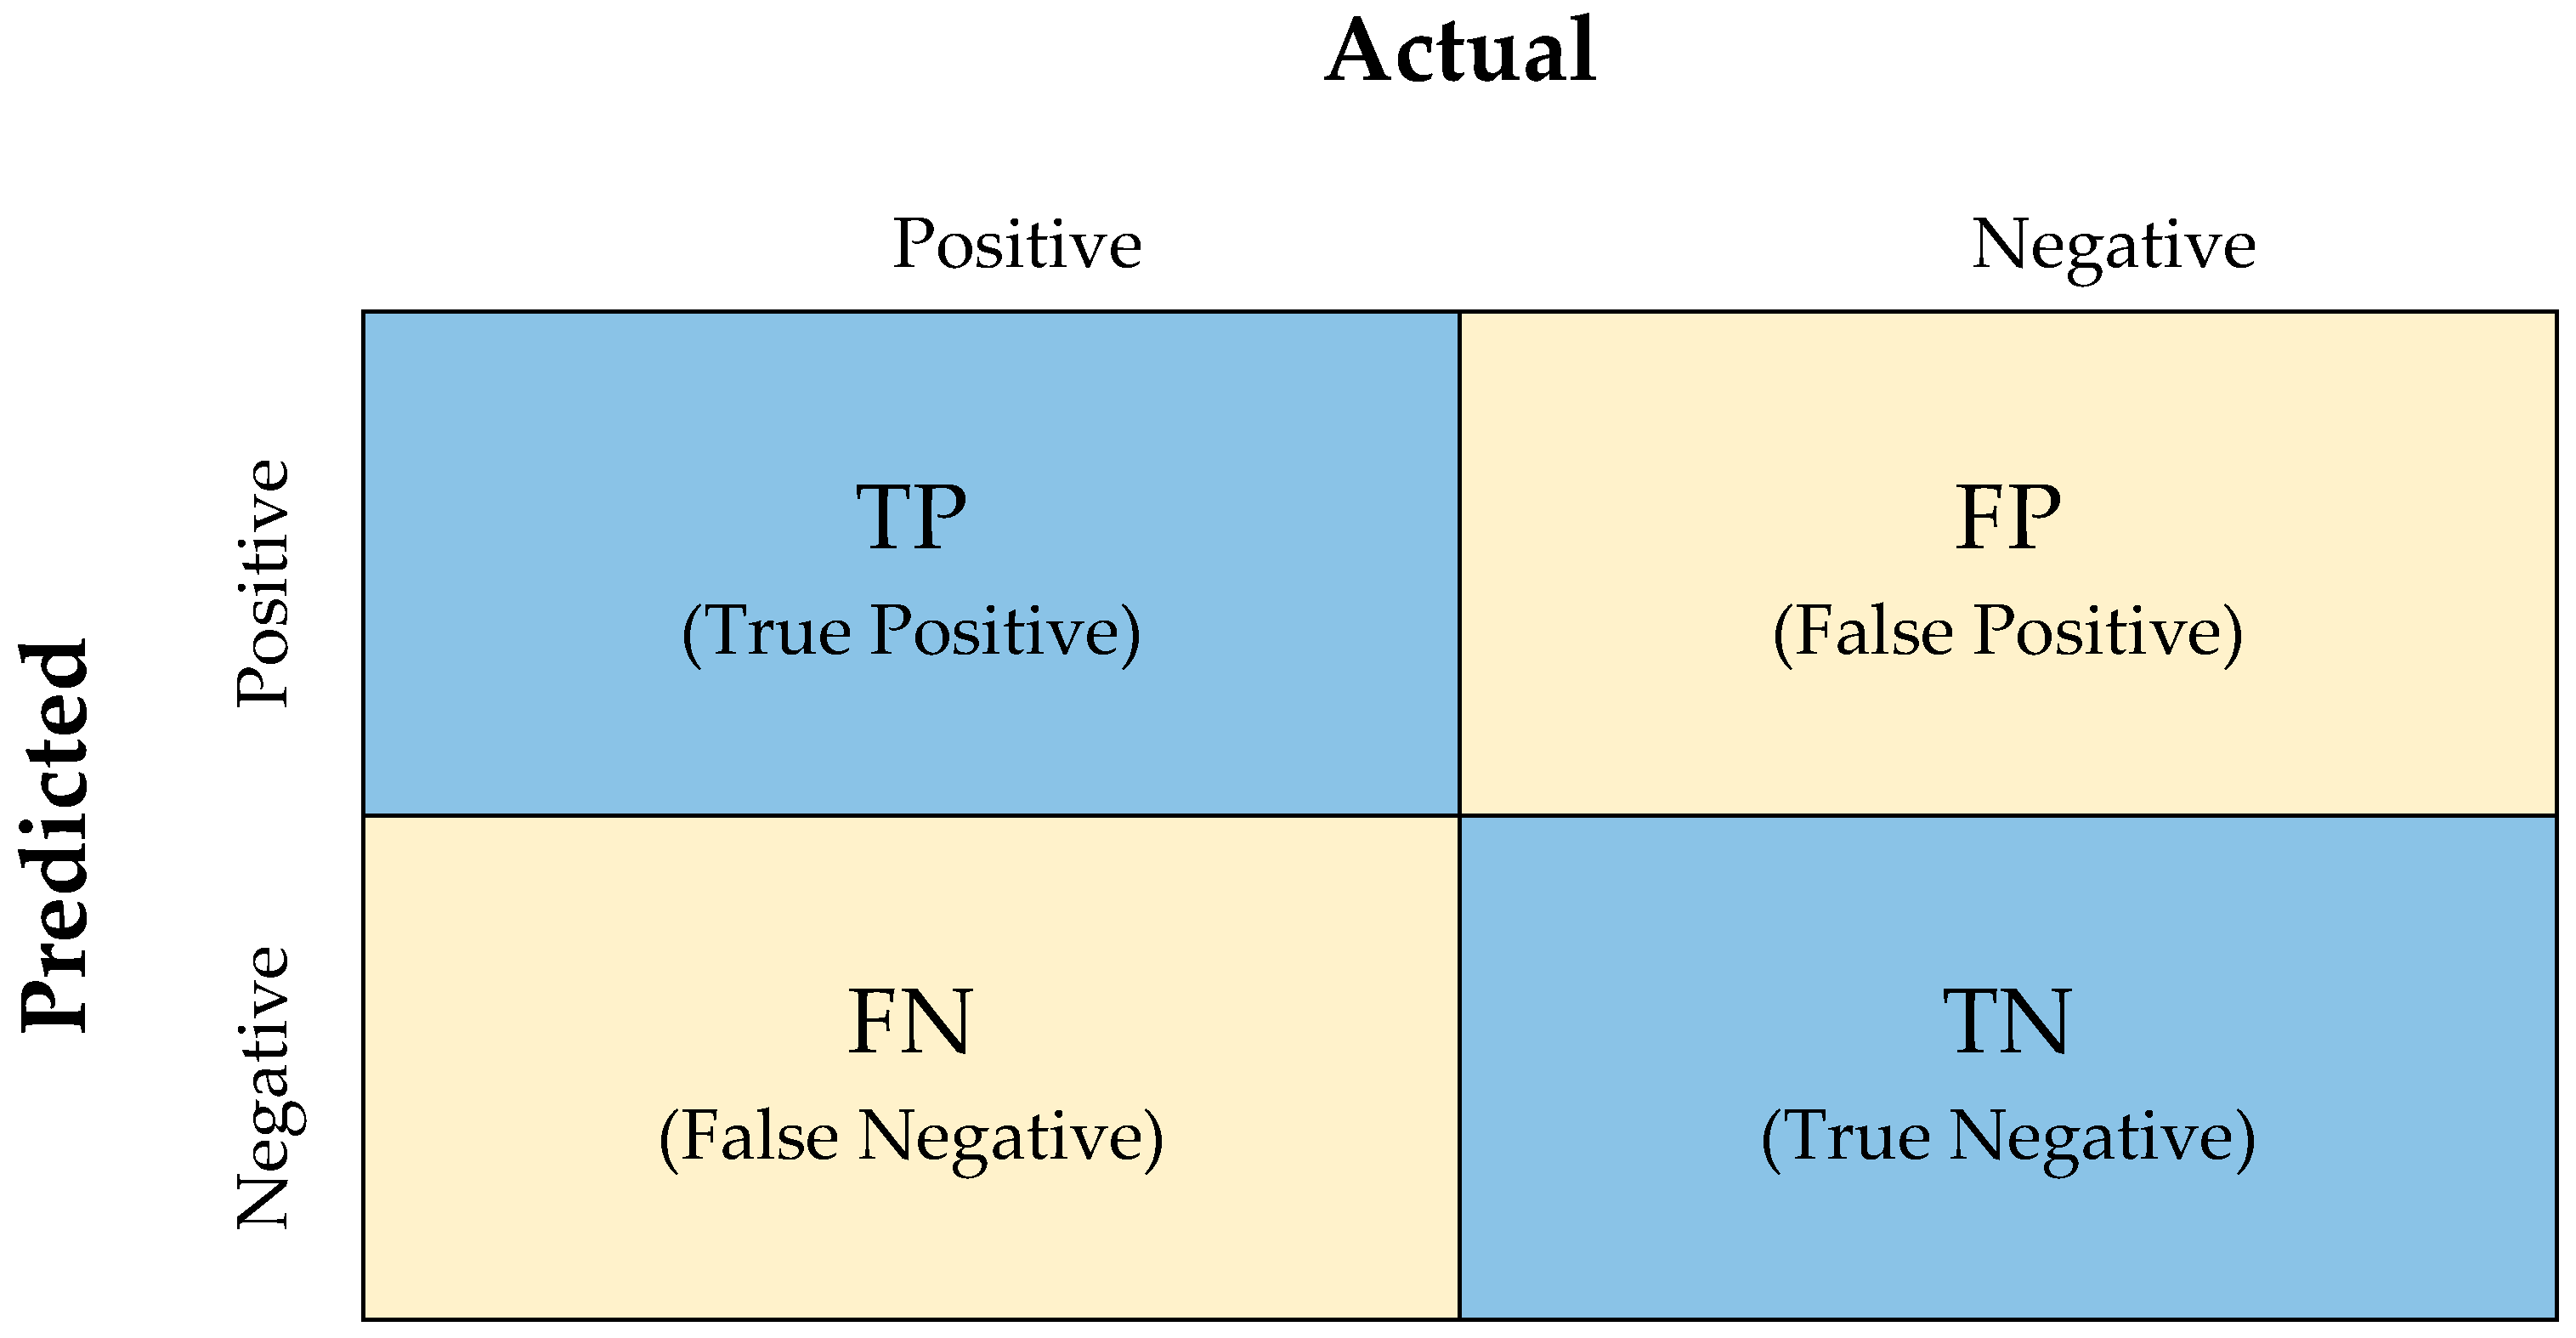
Model performance was evaluated using key metrics: Accuracy, Precision, Recall, F1 Score, and Intersection over Union (IoU). Based on the Confusion Matrix, TP, TN, FP, and FN are defined, and each evaluation metric is defined as follows (
Figure 7) [
28,
29]:
2.6. Deep Learning Model Parameters and Operating Environment
The deep learning model for water level recognition implemented in this study was developed using Python and trained and validated using the TensorFlow framework. The Adam Optimizer provided by TensorFlow was adopted as the optimizer, and the total training was set for 200 epochs. To prevent overfitting during training, early stopping was applied based on validation loss. The training was halted if no improvement was observed for 30 consecutive epochs. Sparse Categorical Cross-Entropy (SCCE), one of Keras’s built-in functions, was used as the loss function, and the training batch size was set to 16, considering both training stability and processing speed.
Within the network architecture, Batch Normalization, ReLU activation functions, and 3 × 3 kernels were applied. Early Stopping was enabled to prevent overfitting and enhance the model’s generalization performance. Model training was performed on a Windows 11 (64-bit) operating system with hardware specifications including an AMD Ryzen 9 5900X 3.70 GHz 12-Core CPU, 32 GB RAM, and an NVIDIA GeForce RTX 3080 GPU. The development environment consisted of Python 3.7.0, Keras 2.7.0, TensorFlow 2.x, and CUDA 11.2. This configuration was designed to efficiently process high-resolution video data and facilitate large-scale deep learning training.
2.7. Research Procedure
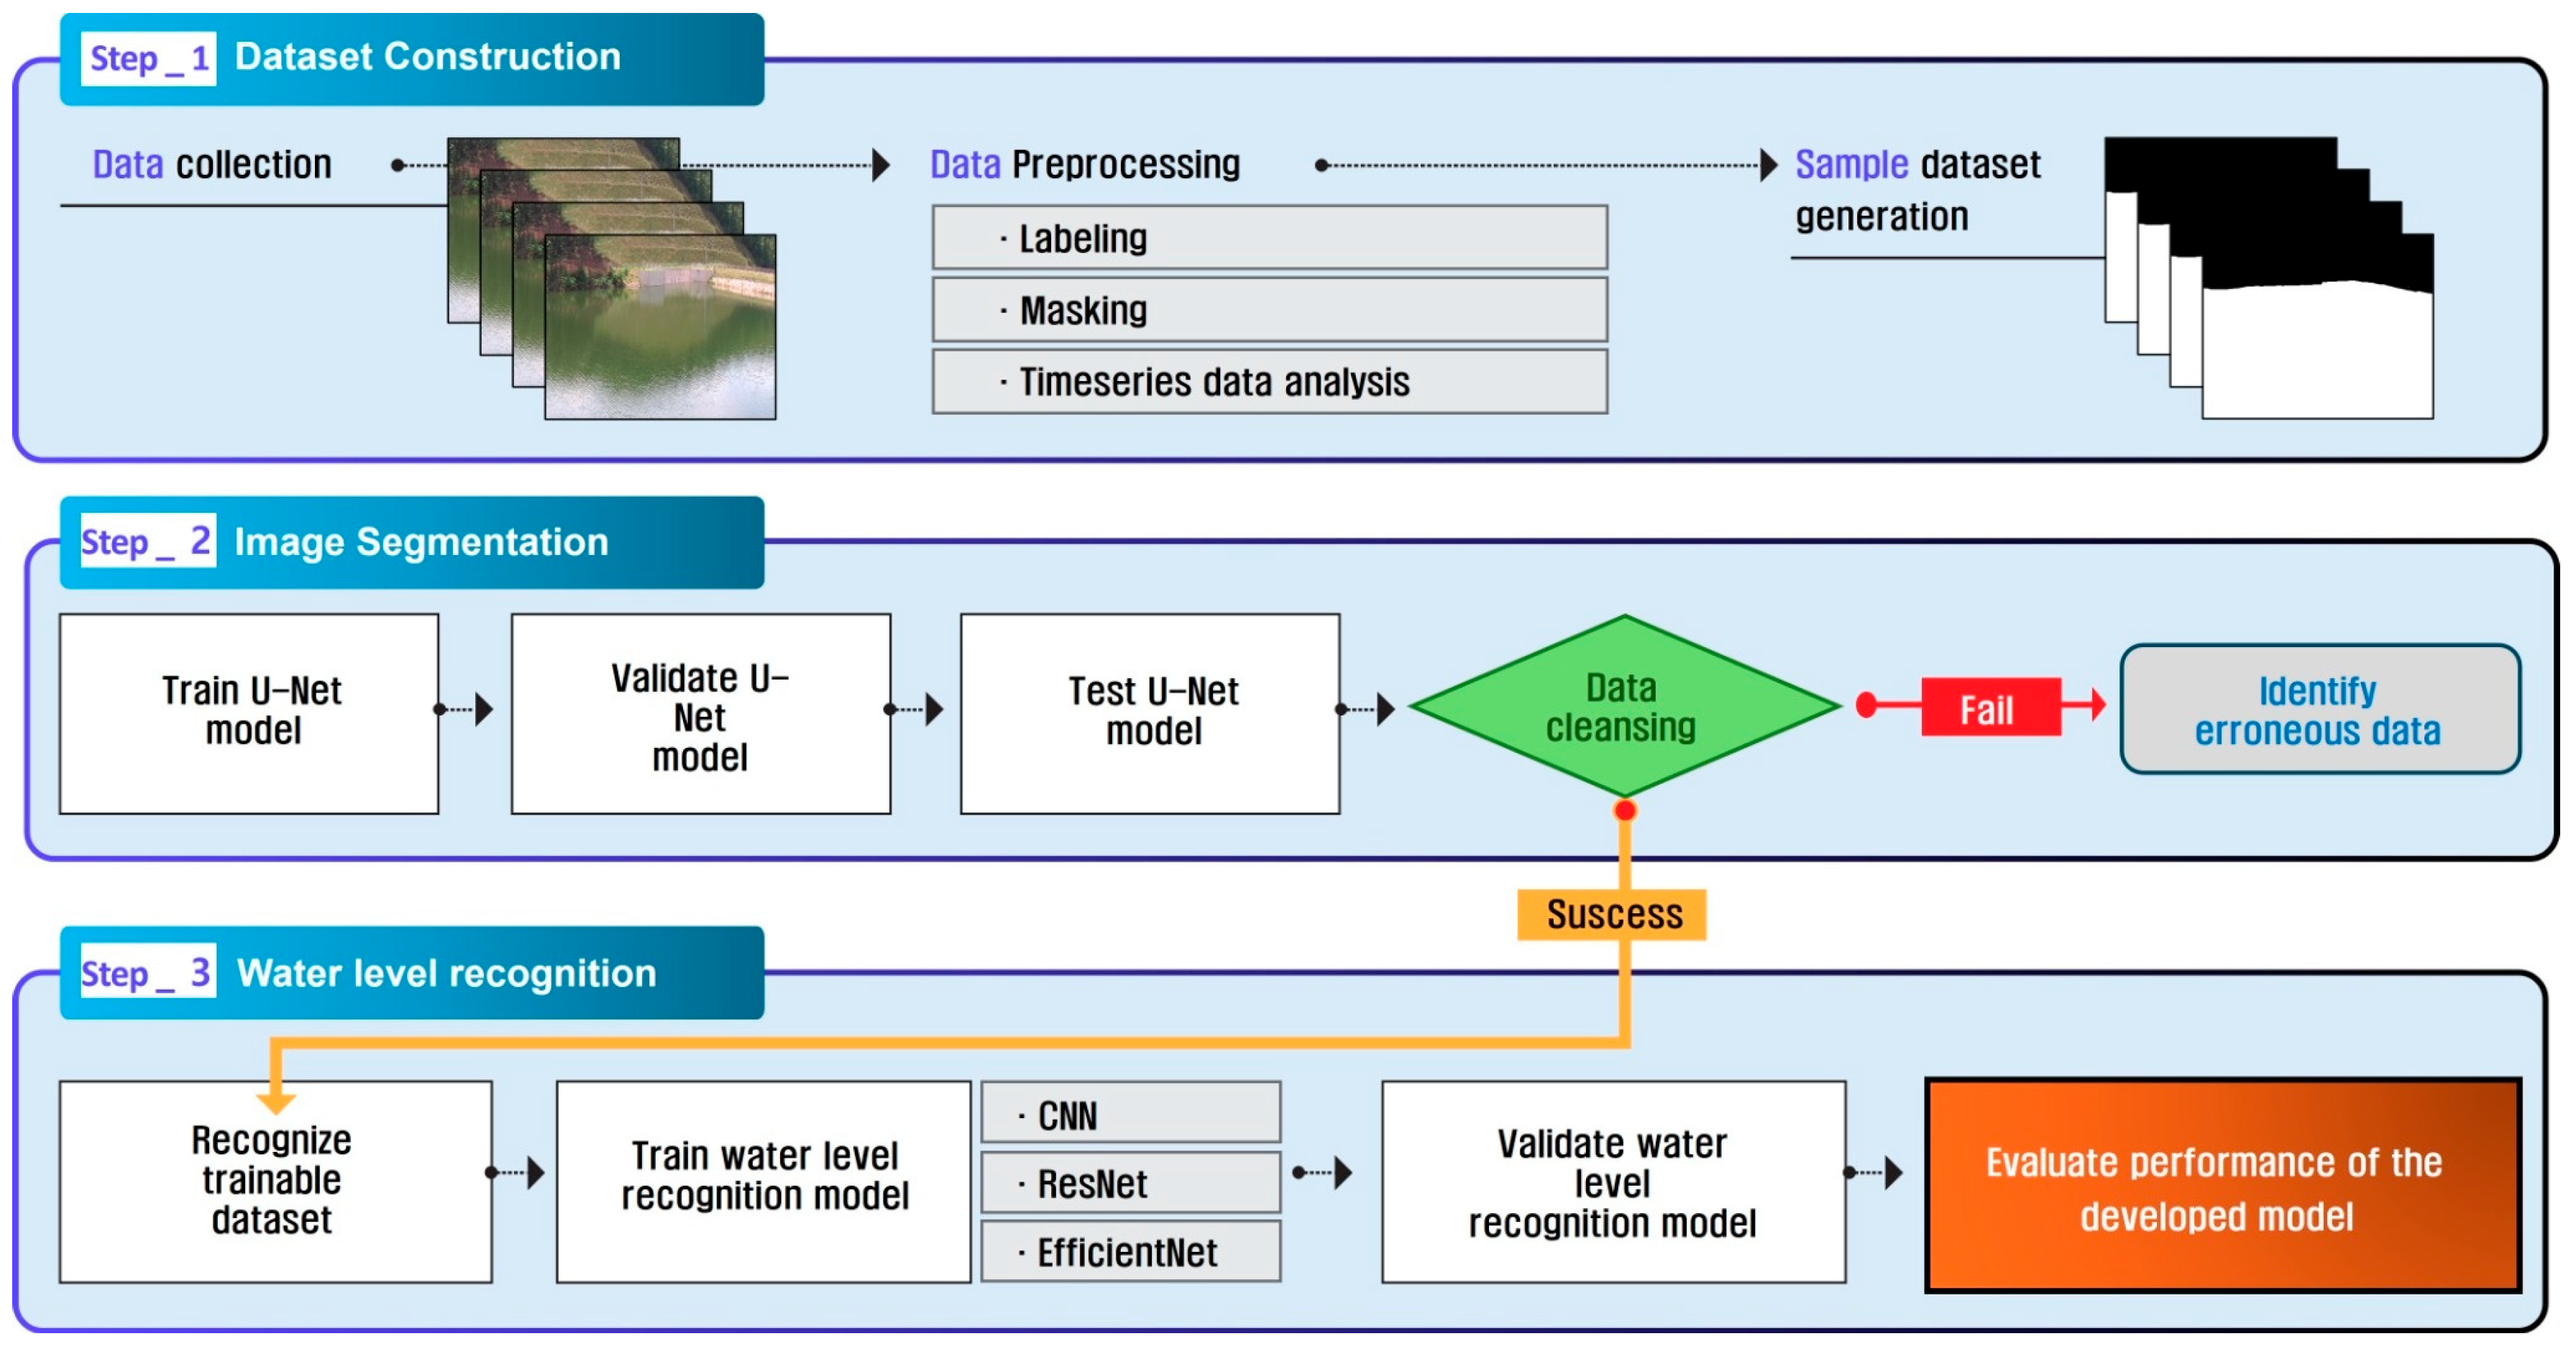
The overall research procedure of this study, based on the flowchart presented in
Figure 8, consists of three main stages, each aiming to improve the precision and practical applicability of the water level recognition deep learning model.
Stage 1 involves the construction of a CCTV-based video dataset. Video information was collected at one-hour intervals for approximately two years from the CCTVs installed at Myeonggyeong Reservoir, ensuring consistency with water level time-series data. Missing videos were removed, and the collected images were labeled based on metadata such as the date, time, and water level. Additionally, 1432 images underwent manual masking of water surface and non-water surface areas, which were used for training, validation, and evaluation of the U-Net-based image segmentation model [
18,
19]. These annotated masks served as ground truth labels in the segmentation phase, and the trained model was subsequently applied to the full dataset to generate inputs for the classification models.
Stage 2 focused on accurate image segmentation and water level interval configuration, which served as the foundation for evaluating model performance in subsequent steps. The U-Net model [
21] was used to extract the water surface region, and two interval-setting methods (equally spaced and Jenks Natural Breaks [
22]) were applied to divide water levels into representative categories. These interval definitions were designed to mitigate data imbalance and improve the generalizability of classification models [
22,
30]. The segmentation output was used as preprocessed input for classification. The segmentation performance was quantitatively evaluated using metrics such as Accuracy, Precision, Recall, F1 Score, and IoU [
28,
29], confirming the robustness of the U-Net model for distinguishing water surface areas with high accuracy.
Stage 3 focused on training and evaluating three classification models (CNN, ResNet, and EfficientNet) under identical conditions, with the goal of identifying the most suitable deep learning architecture for video-based water level recognition in agricultural reservoirs. The performance comparison was primarily based on training loss and accuracy trends, which were visualized across various water level interval settings. Although other evaluation metrics such as Precision, Recall, F1 Score, and IoU were defined, they were not explicitly reported in this study. Based on the observed accuracy and training stability, EfficientNet demonstrated the best performance and was evaluated as the most appropriate model for practical implementation in automated hydrological monitoring systems [
26,
27,
31].
3. Results
3.1. Image Segmentation Model Construction
A total of 1432 images were manually masked by the researchers. To match the input image size allowed by the deep learning architecture, the original resolution (1920 × 1080) was reduced to 512 × 512 for model training, and the output results were restored to their original resolution [
20]. The learning rate was set to 0.001, scaling factor to 0.2, and the dataset was divided into training–validation–evaluation ratios of 7:1:2. After model validation, additional masking was performed on the remaining video data. Manual masking is a crucial preprocessing step for ensuring training accuracy, designed to clearly distinguish between water surface and non-water surface areas. This binary classification mask contributed to improving the precision of water level prediction.
Figure 9 presents a conceptual diagram of the U-Net-based image segmentation model, which was employed for pixel-wise classification of water and non-water areas.
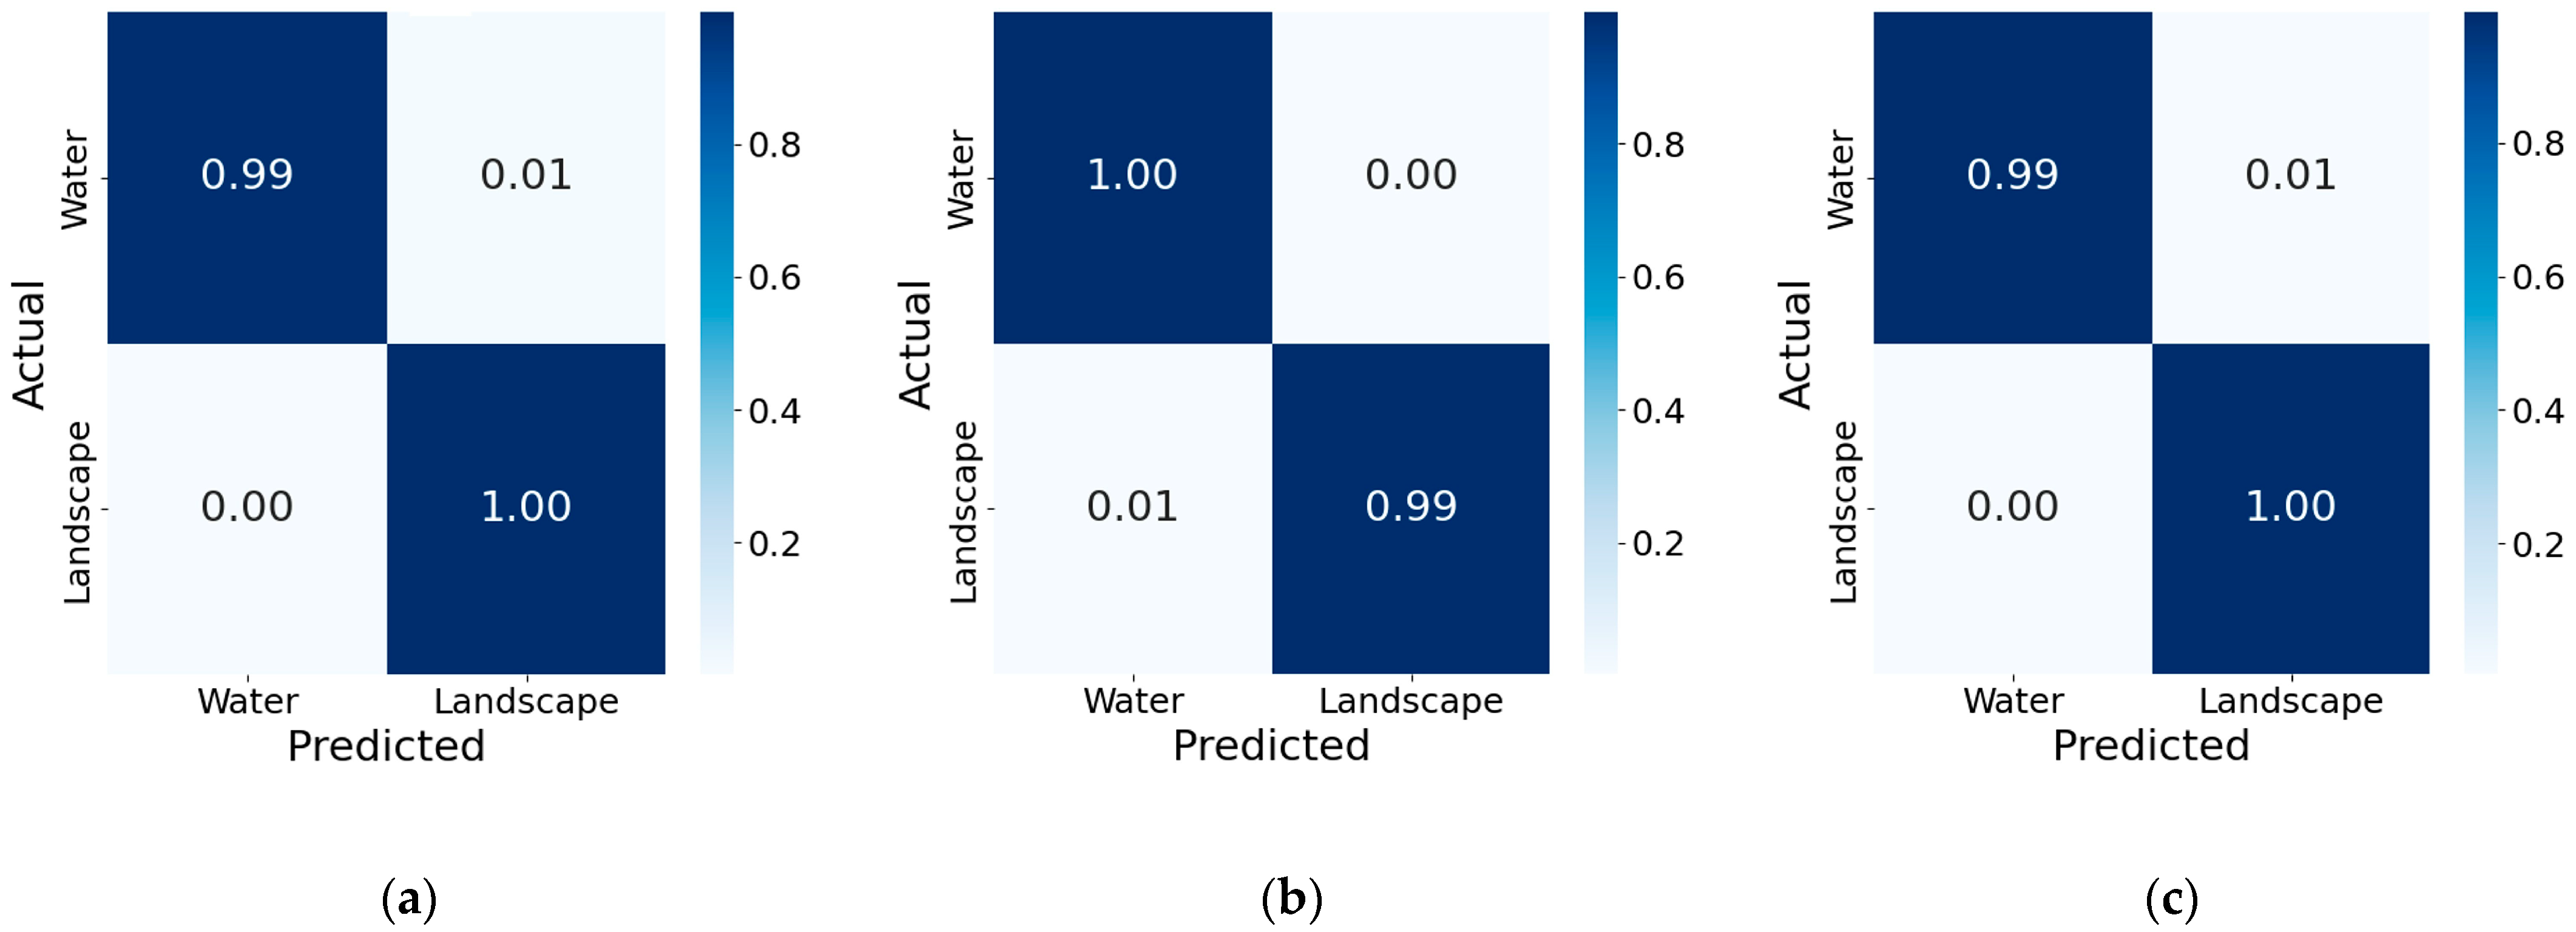
We trained the model on Myeonggyeong Reservoir images and evaluated it using confusion matrices, as seen in
Figure 10. The pixel-wise accuracy reached approximately 99%, with very few misclassifications. These results demonstrate the model’s high precision and robustness at the pixel level [
21]. Particularly, high performance was observed with high-resolution images during daytime, while some performance degradation occurred at night or in adverse weather conditions. These instances can serve as valuable data for future improvements.
Table 1 presents the loss and accuracy during training and validation. Loss values converged stably to 0.008 and 0.040, respectively, and accuracy was very high, at 99% during training and 96–98% during validation. This indicates that high generalization performance was achieved without overfitting, validating the effectiveness of U-Net among CNN-based segmentation architectures.
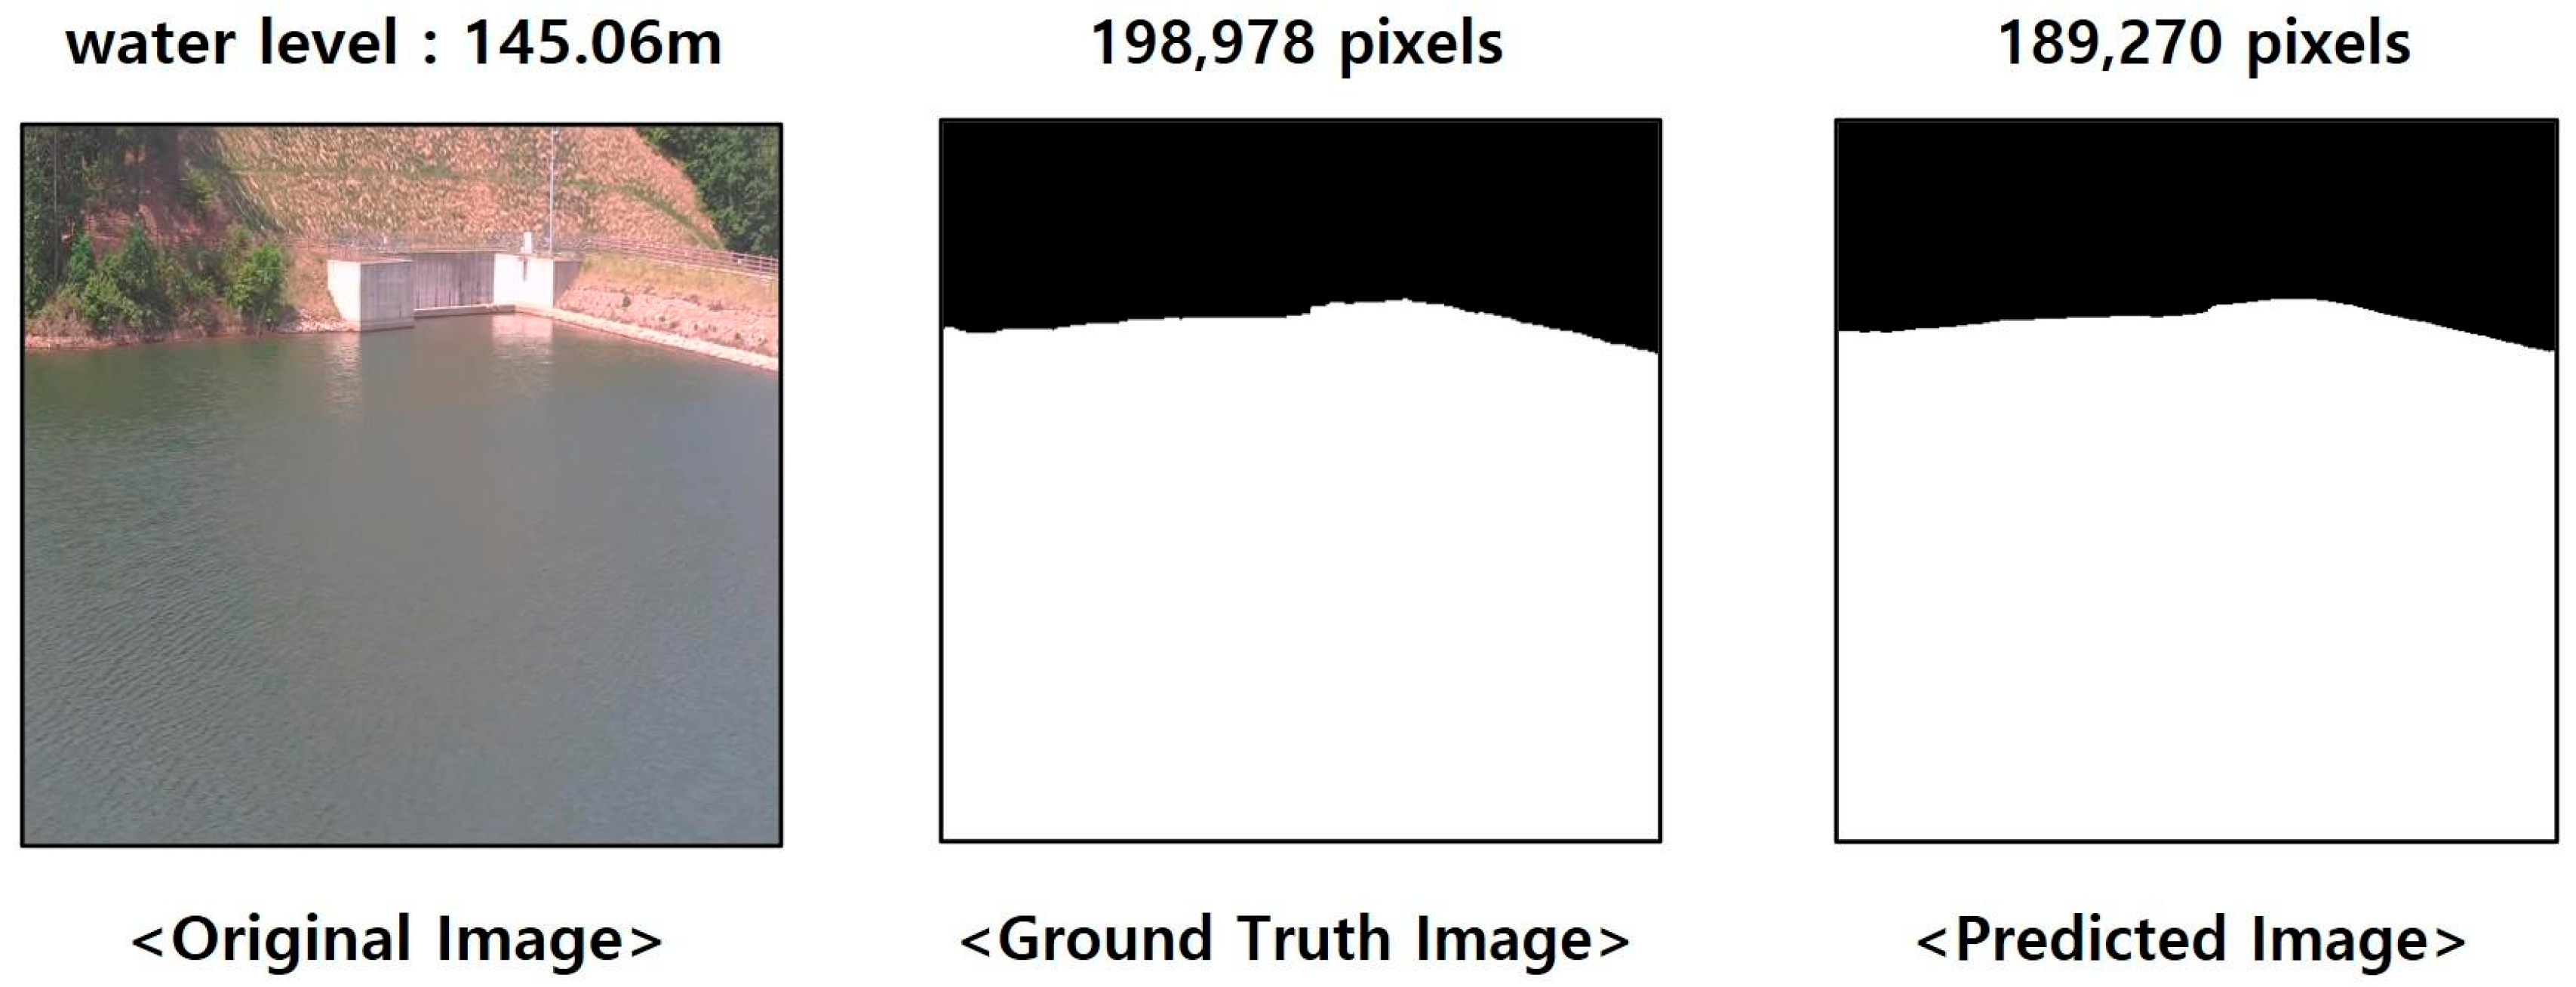
The comparison between ground truth and predicted images is shown in
Figure 11, revealing that only approximately 800 pixels out of a total of 262,144 pixels showed errors, confirming high accuracy. This error rate—less than 0.3% of the total pixels—suggests the potential for real-time water level estimation.
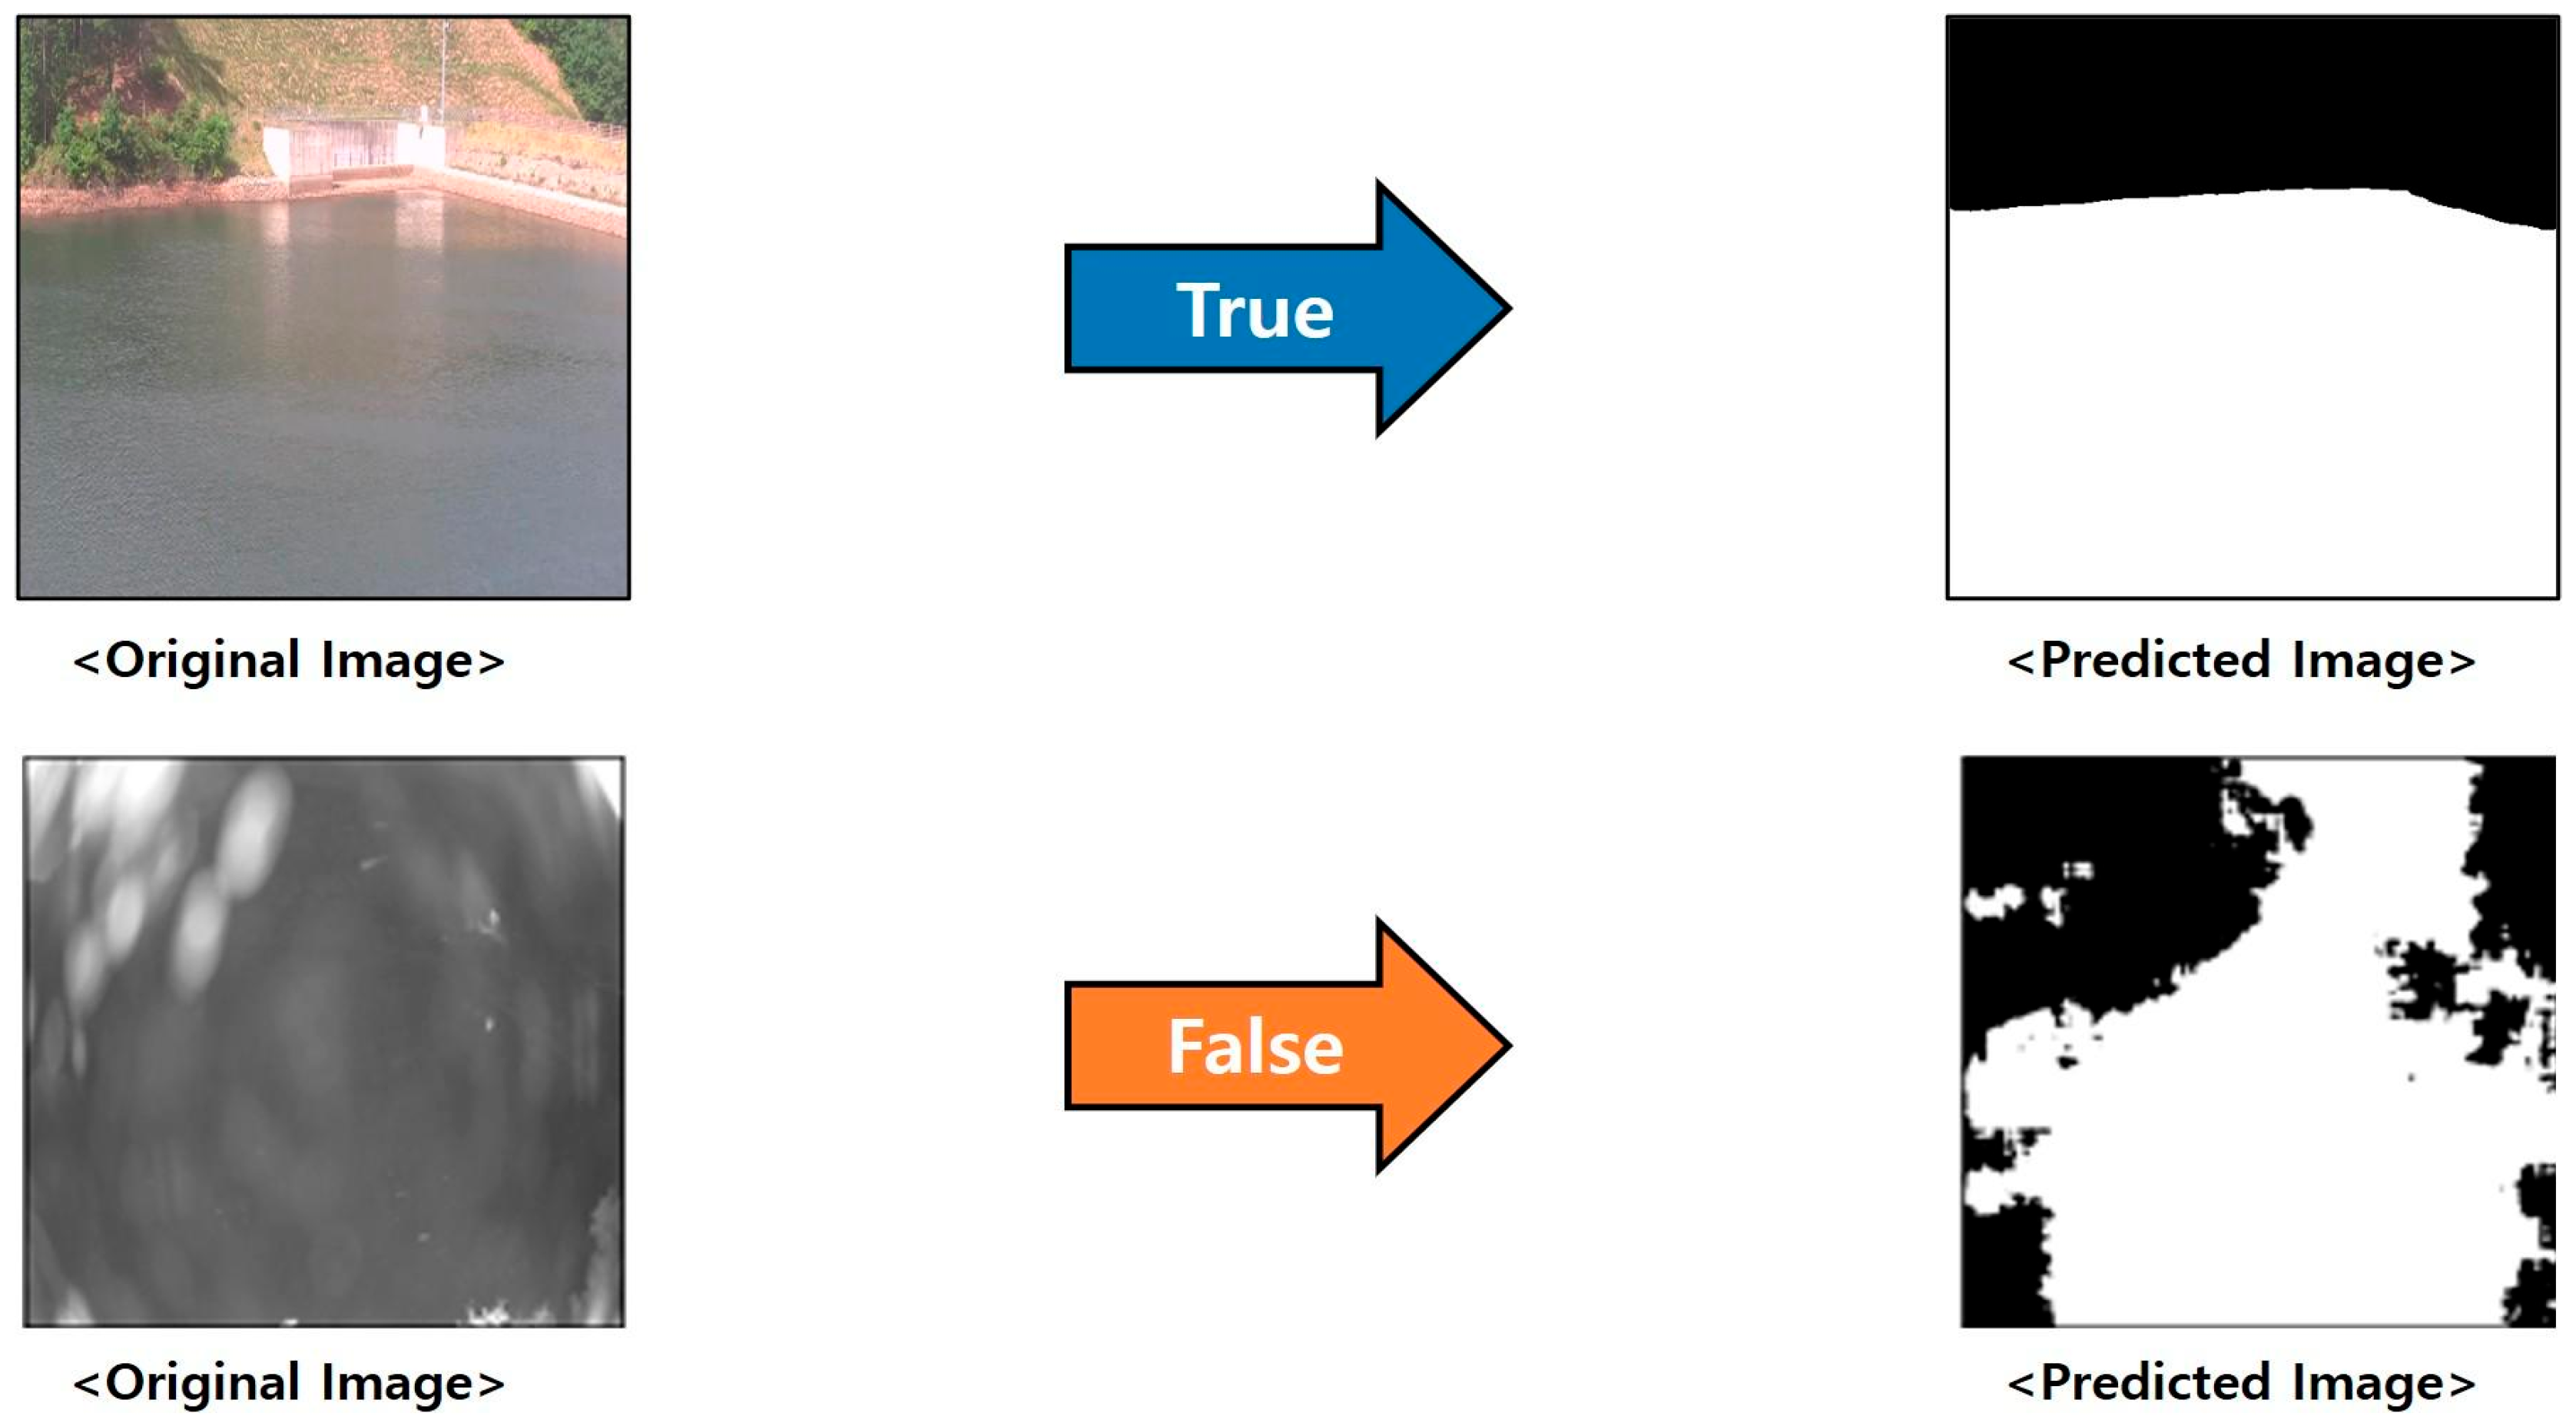
Figure 12 displays examples of high and low accuracy prediction results under different lighting conditions. In the daytime images, the model successfully identifies the water surface with clear boundaries and minimal noise. However, the nighttime examples show less distinct segmentation, likely due to reduced illumination and increased image noise. Although a formal quantitative comparison was not conducted, these visual differences suggest that lighting conditions have a significant impact on model performance. This underscores the need for future work to include systematic evaluations under various lighting environments and to incorporate image enhancement methods tailored for low-light or nighttime scenarios.
3.2. Water Level Recognition Model Construction
In this study, water level recognition models were developed using three deep learning architectures: CNN, ResNet, and EfficientNet. All models were trained under the same hyperparameter conditions, using Adam as the optimizer, SCCE (Sparse Categorical Cross Entropy) as the loss function, and 200 epochs. All models were implemented in TensorFlow and Keras environments, leveraging a GPU-based training environment (NVIDIA GeForce RTX 3080, CUDA 11.2).
3.2.1. CNN Results
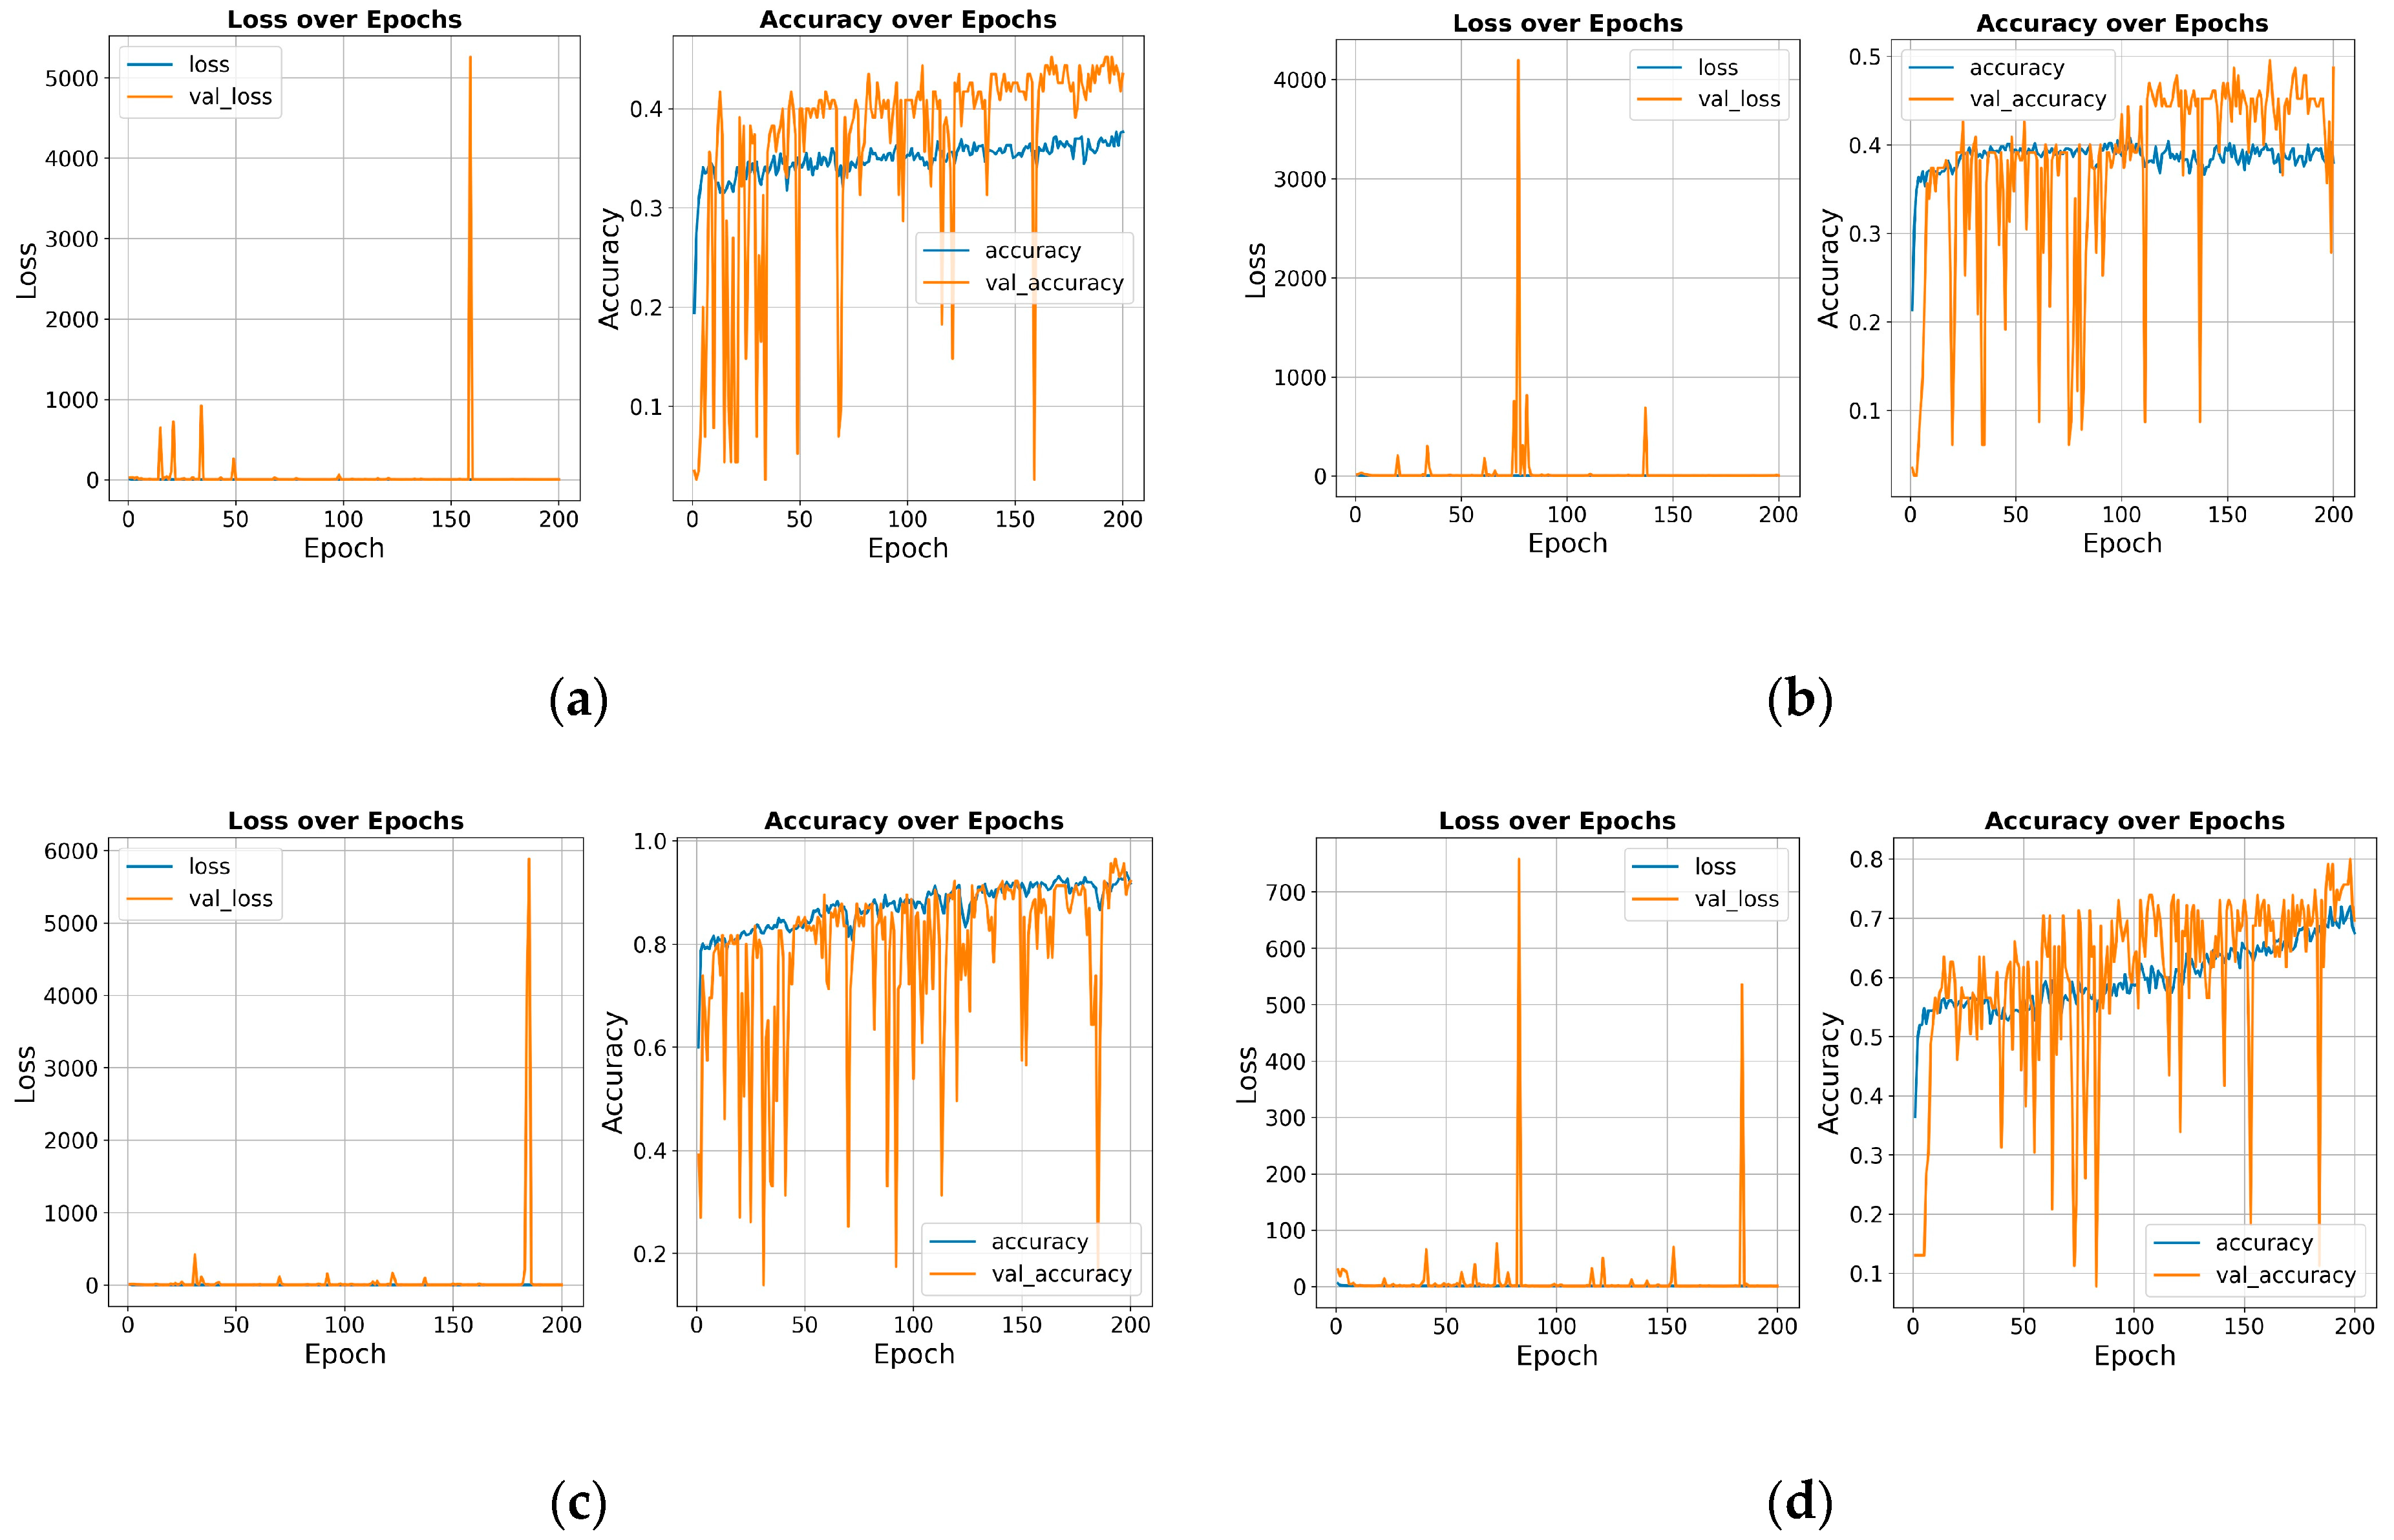
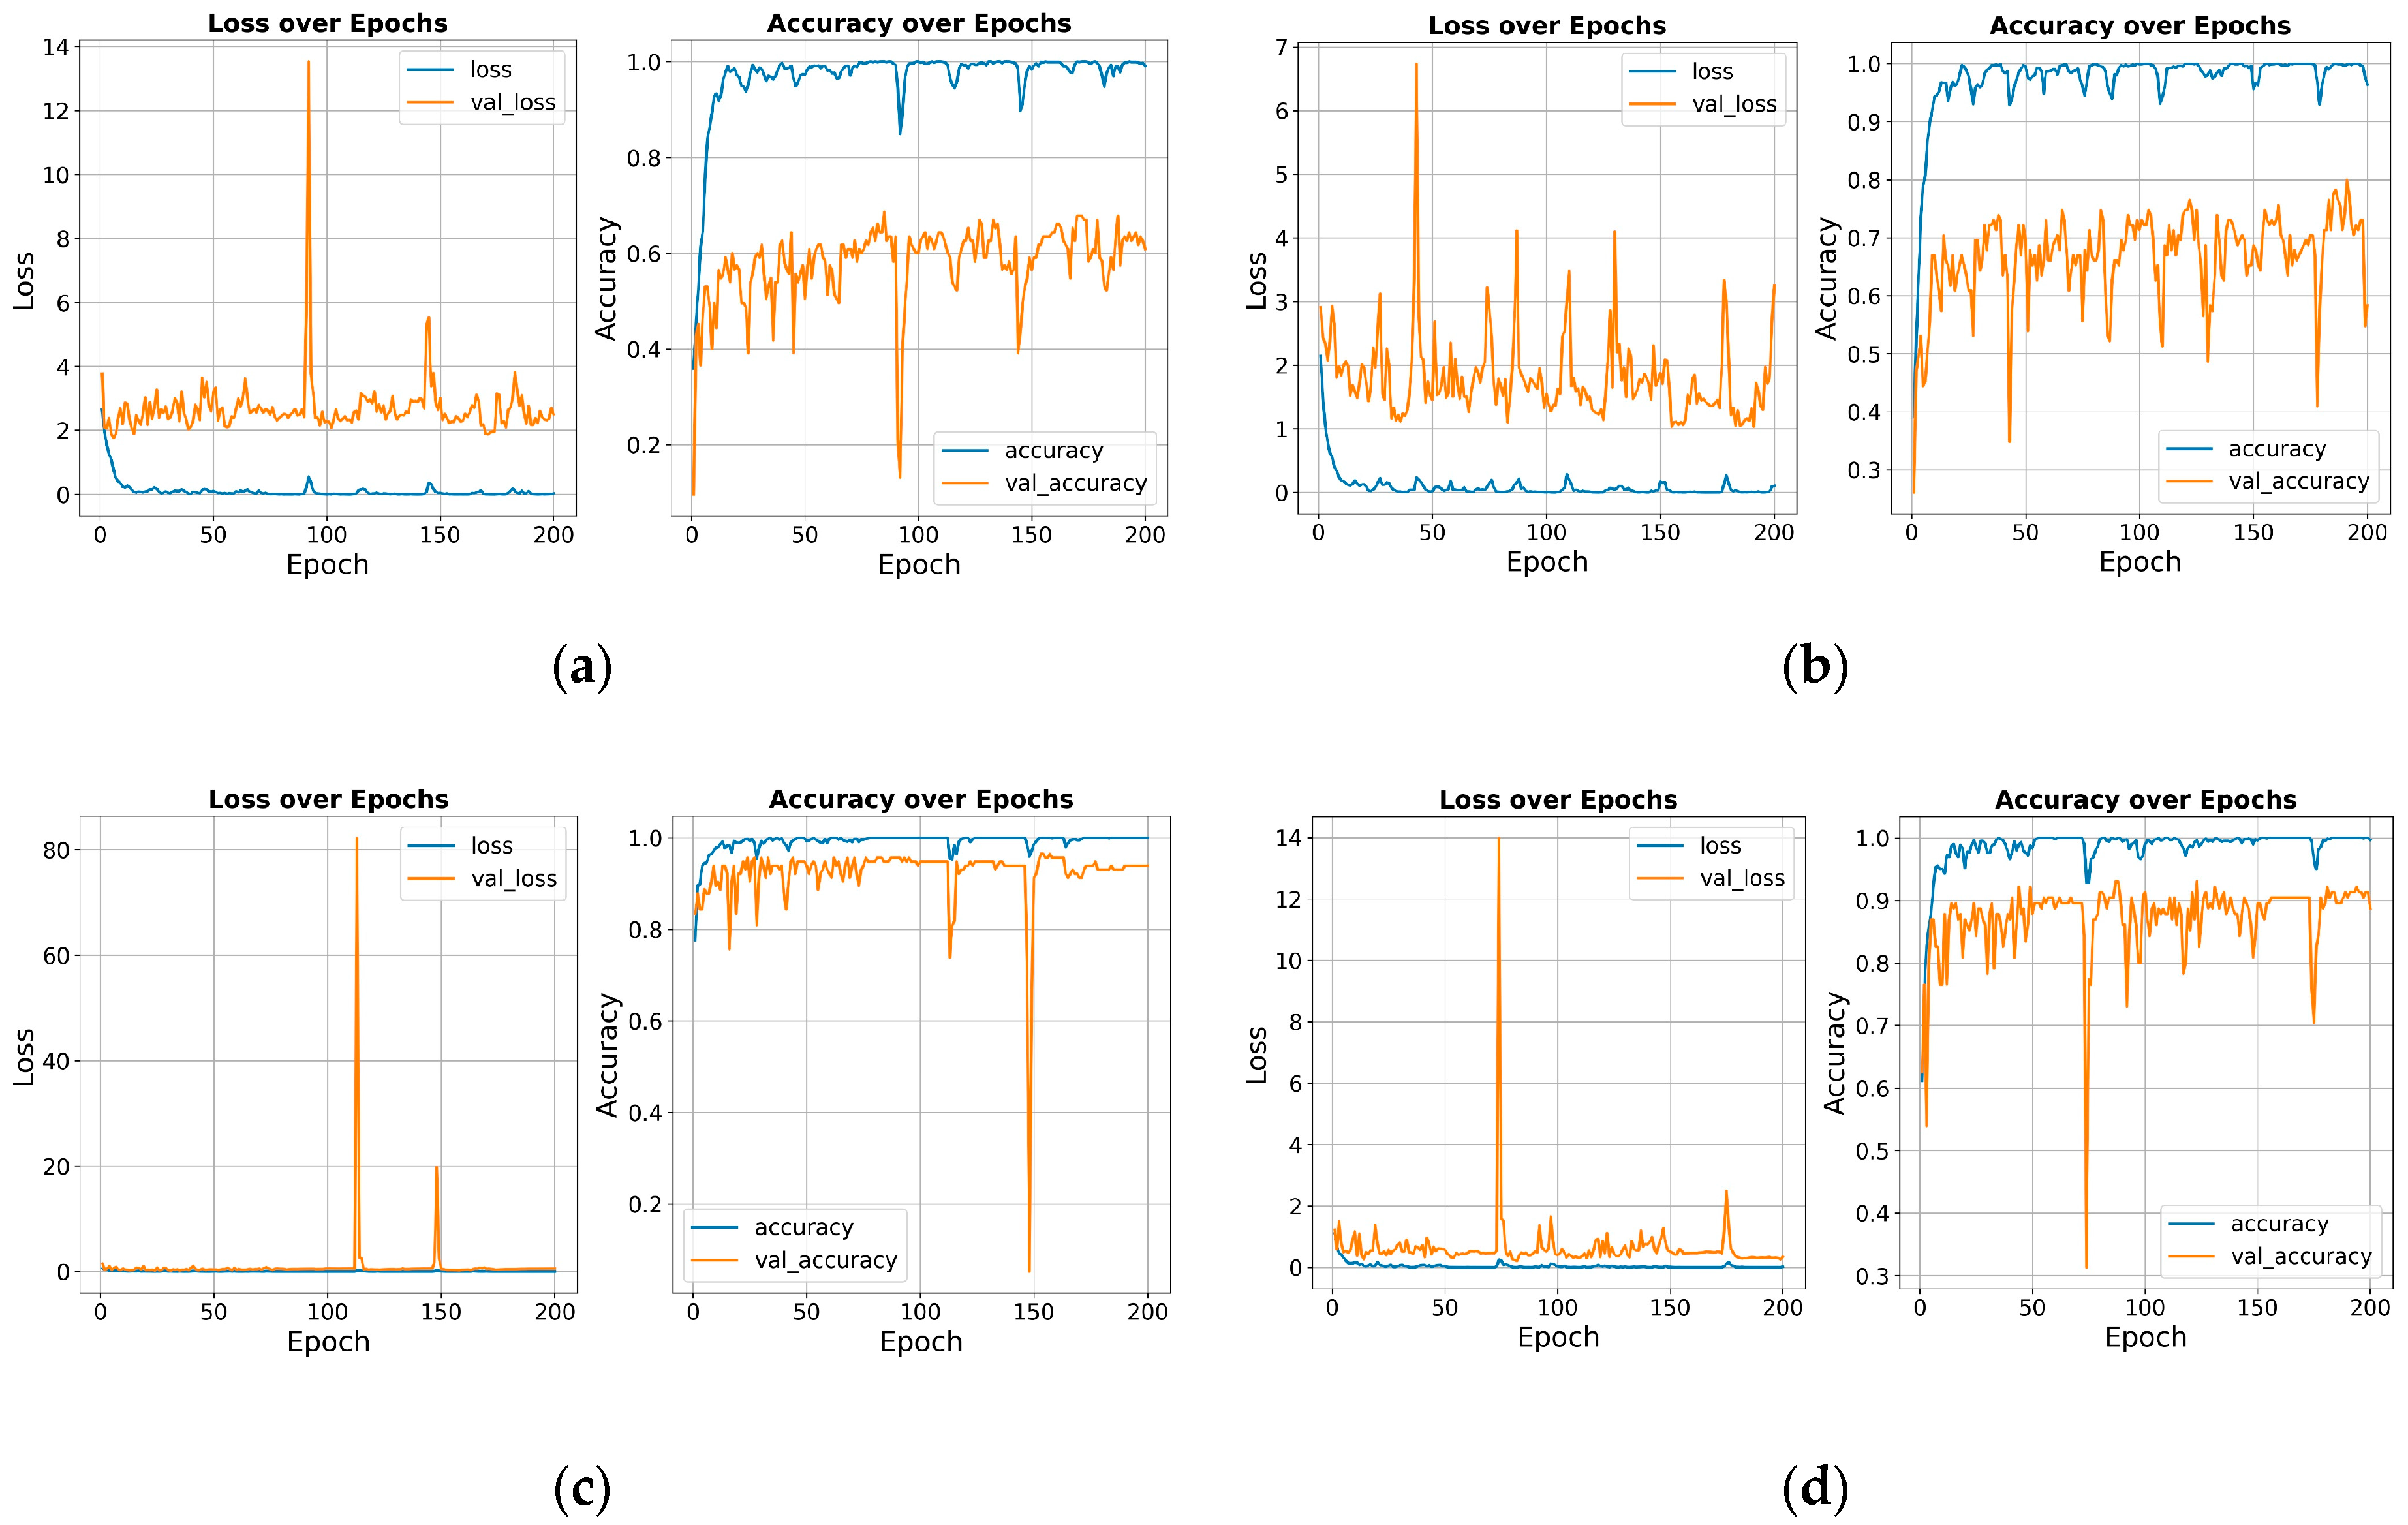
Figure 13 shows the loss and accuracy curves according to training epochs. CNN, due to its simpler architecture, showed faster convergence but performed better with Jenks 8 intervals than with 10 cm/20 cm equal intervals. The sharp increase in validation loss around epochs 150 and 75 suggests overfitting. Although high accuracy was observed initially, performance variability increased with more epochs, indicating limited generalization performance.
3.2.2. ResNet Results
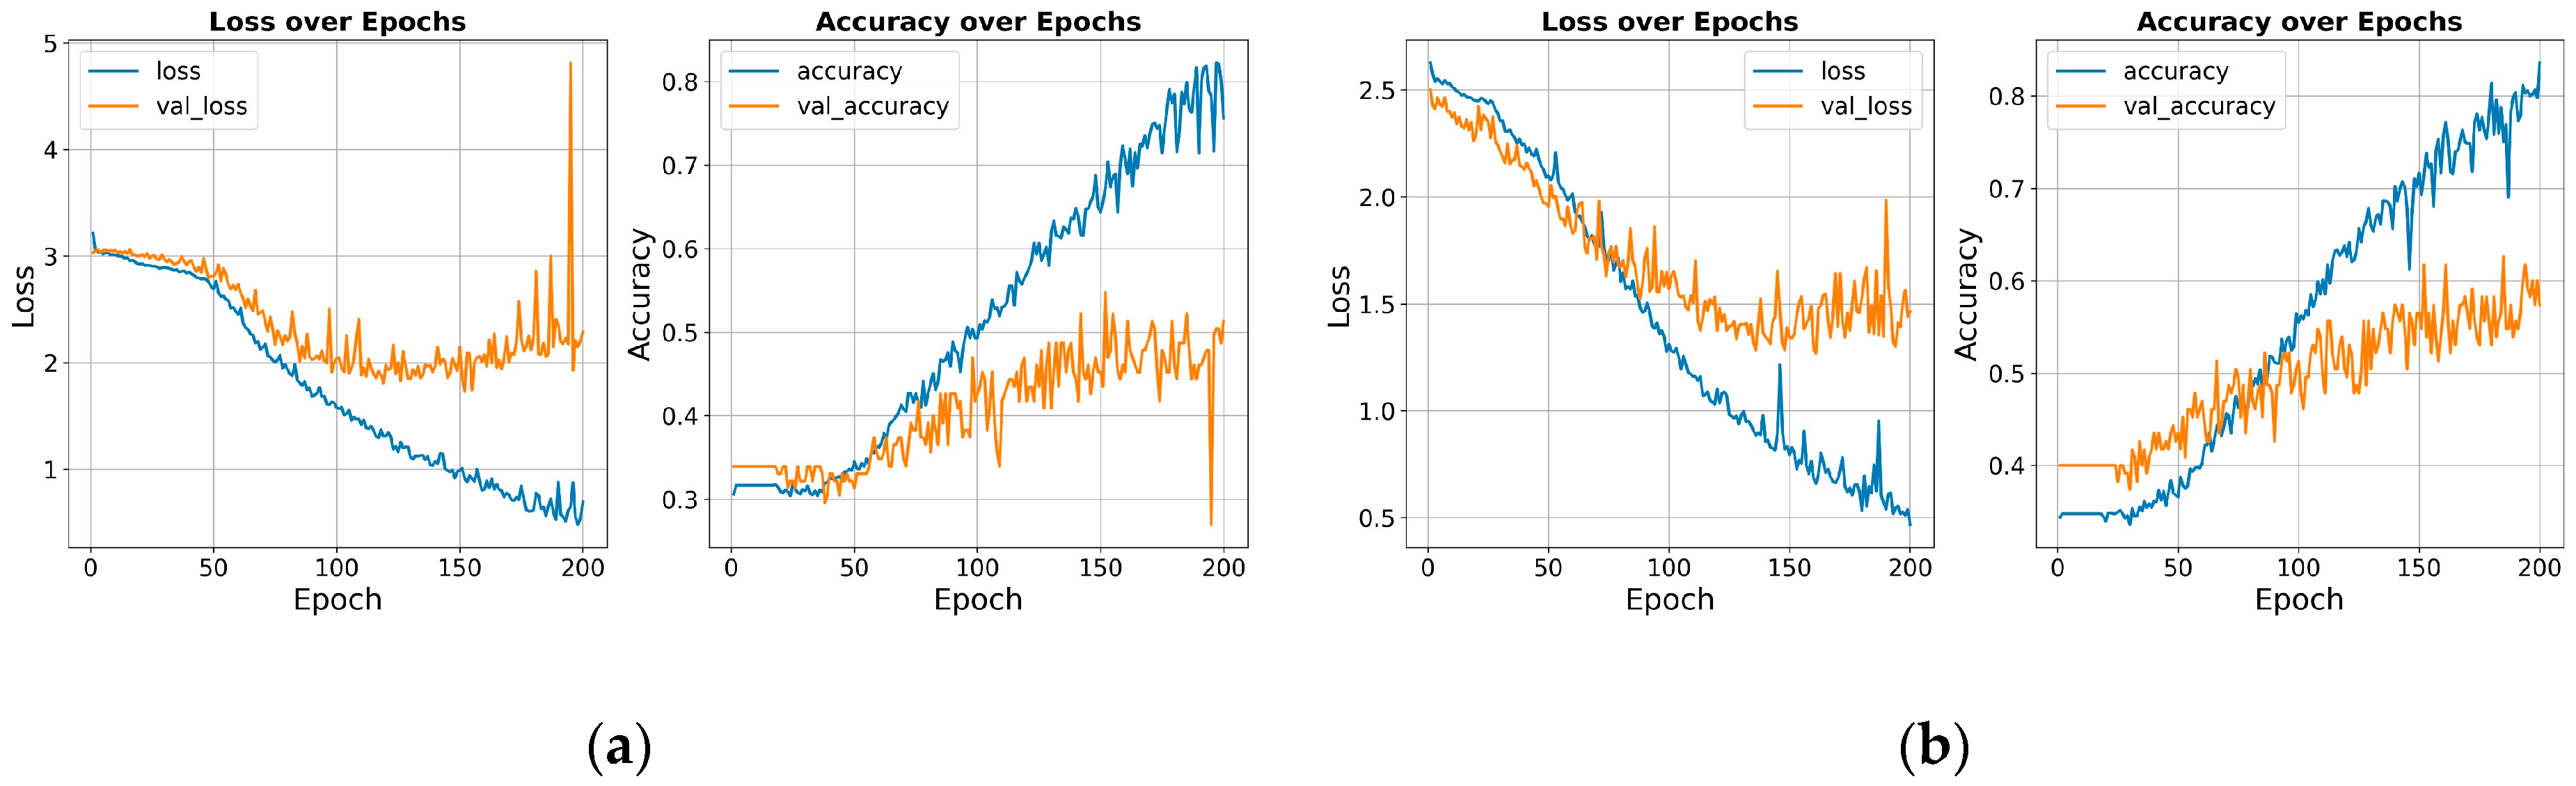
ResNet, with its deeper structure and Residual Blocks, showed slower convergence but achieved superior final loss and accuracy compared to CNN. Particularly, it exhibited the most stable results with Jenks 8-interval classification, with accuracy continuously increasing even in the latter stages of training (
Figure 14) [
25]. The stable training curve and consistent increase in validation accuracy suggest a learning structure that effectively suppresses overfitting.
The relatively small batch size might have contributed to the instability of the loss curve. However, overall, ResNet demonstrated stable training and high performance. Notably, it was capable of learning higher dimensional patterns, allowing for the recognition of subtle differences between water level classifications.
3.2.3. EfficientNet Results
EfficientNet demonstrated the most superior performance across all metrics.
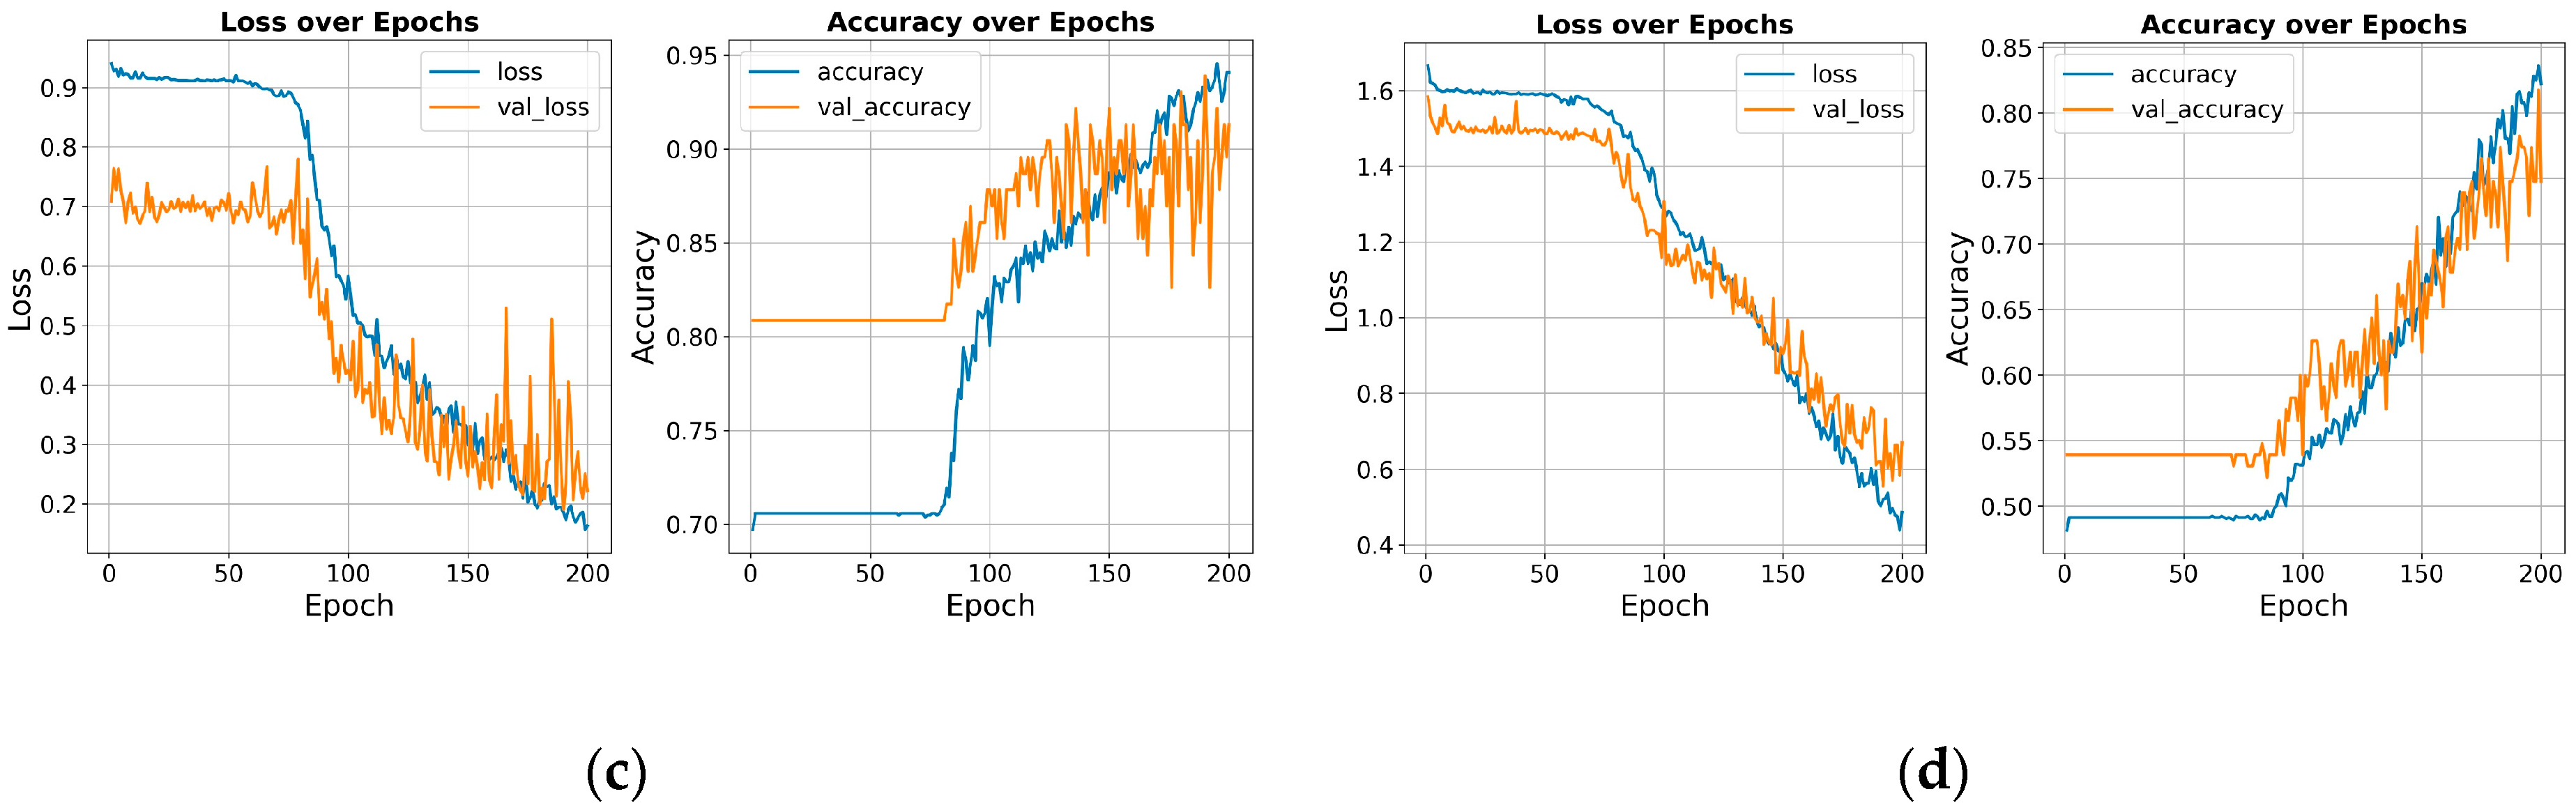
Figure 15 illustrates the changes in loss and accuracy with training epochs; the initial loss convergence was slow, but the final loss converged almost to zero. Accuracy was high from the early stages of training, with the highest performance observed in the Jenks eight-interval classification.
Intermittent fluctuations in validation performance suggest the possibility of noise or a distribution mismatch. Solutions such as diversifying data and employing early stopping techniques are proposed. EfficientNet’s compound scaling architecture is well suited for extracting diverse visual features related to water levels, enhancing its applicability for actual automated hydrological monitoring.
4. Discussion
We tested two interval-setting methods (10 cm, 20 cm equal spacing and Jenks Natural Breaks) on Myeonggyeong Reservoir data. We then compared three deep learning models: CNN, ResNet, and EfficientNet. The observed water level range of Myeonggyeong Reservoir is from 141.80 m to 146.42 m, a total range of 4.62 m, which requires relatively fine interval partitioning for real-time water level prediction. The equal interval method offers advantages in simplicity and consistency but lacks the ability to reflect the density or natural characteristics of water level distribution. In contrast, the Jenks Natural Breaks method is evaluated as a more effective approach for segmenting non-uniformly distributed hydrological data by reflecting its natural clustering characteristics.
The comparison of model performance revealed that the EfficientNet model showed the most superior results in terms of accuracy and training stability, while ResNet exhibited stable training curves and high accuracy. Although the CNN model exhibited rapid convergence during the initial training phases, it showed relatively lower classification accuracy and limited generalization capability, particularly under more complex classification scenarios such as the Jenks eight-interval case. This is interpreted as a structural limitation of the CNN architecture, which, due to its insufficient depth, cannot adequately learn water level-related features extractable from images.
Another important limitation is related to the dataset selection process. Although the initial dataset consisted of 17,784 time-series images, only 1432 images were selected for model training and validation due to issues such as low resolution, occlusion, or missing metadata. While this filtering ensured reliable manual segmentation and high-quality input, it inevitably introduces a risk of sampling bias, especially in representing rare or extreme conditions. To mitigate this, we intentionally selected images spanning multiple seasons and water levels to capture diverse environmental scenarios. This trade-off between data quality and quantity is a common challenge in hydrological machine learning, as noted in the recent literature [
31,
32]. Future work will aim to automate the image quality assessment and incorporate data augmentation techniques to expand usable datasets.
While this study focuses on real-time water level recognition based on CCTV imagery, the proposed methodology has strong potential to be extended for flood forecasting applications [
33,
34]. The continuous water level data derived from video sources can be used as input for short-term hydrological models, particularly when combined with rainfall data, reservoir inflow observations, or physical simulations. Integrating this image-based monitoring system with predictive frameworks could enable early warning systems in ungauged or poorly monitored reservoirs. This approach aligns with recent studies on AI-based flood forecasting, such as Sharma et al. [
35], and represents a promising direction for future research.
Furthermore, the batch size among the model’s hyperparameters was found to significantly influence the stability of the loss curve and the model’s generalization performance. Future research requires systematic optimization of hyperparameters such as the learning rate, optimizer selection, batch size, and dropout ratio. Concurrently, given that the deep learning models’ response characteristics vary depending on the water level interval setting method, future studies should explore the interaction between model structure and classification granularity. In particular, EfficientNet demonstrated the best balance of accuracy, generalization, and learning stability, making it the most suitable model for practical deployment in automated video-based water level monitoring systems.
5. Conclusions
We developed and validated a deep learning model for water level recognition in agricultural reservoirs. For this purpose, captured video frames were preprocessed, and water level regions were extracted through U-Net-based image segmentation. Subsequently, the accuracy of water level recognition was analyzed using three deep learning classification models: CNN, ResNet, and EfficientNet. Among 17,784 collected CCTV video frames, only 1432 high-quality samples were retained after excluding those affected by adverse weather, poor nighttime visibility, or missing data.
After U-Net-based segmentation and training, EfficientNet achieved the highest accuracy (~99%) and demonstrated excellent training stability, followed by ResNet. In contrast, CNN, due to its simpler architecture, showed fast initial convergence but exhibited lower accuracy and high loss variability in more challenging classifications. This is attributed to its inability to fully capture the spatio-temporal diversity and complexity inherent in reservoir water level videos.
Moreover, this study emphasizes that environmental factors, such as CCTV installation location, camera angle, and weather conditions, can affect model performance. Since these factors directly impact video quality and data reliability, future research should aim to standardize video acquisition conditions and adopt correction techniques such as low-light enhancement, noise filtering, and data augmentation.
The limitations of this study are as follows. First, approximately 92% of the total videos were analyzed as missing or unusable data, thereby limiting the size of the dataset available for model training. Second, the performance of video segmentation and water level classification was sensitive to model hyperparameter settings, suggesting that automated machine learning (AutoML) techniques for model optimization will be necessary in the future. Third, although model evaluation was primarily based on Accuracy, it is essential to incorporate additional performance metrics such as Precision, Recall, and F1-score in future research to more comprehensively assess the strengths and weaknesses of different models including CNN, ResNet, and EfficientNet. This will allow for a more nuanced understanding of classification performance, in line with emerging practices in the recent literature [
36,
37].
This video-based water level recognition technique can contribute to the digital transformation of practical water resource management, including the establishment of automatic water level monitoring systems for unmonitored agricultural reservoirs, quantitative water demand prediction, and drought response infrastructure development. Especially, when integrated with precision water management technologies such as smart farm water management, automatic irrigation systems, and demand-based water allocation, it holds significant potential for integration into advanced hydrological information systems. Future research should also involve developing multi-sensor fusion video models and infrared- and thermal imaging-based recognition models to address diverse weather conditions and seasonal changes. In addition, as EfficientNet has been identified as the most suitable model among the candidates, further optimization and field application studies based on this architecture are expected to enhance the practical utility and generalizability of the proposed system.
Author Contributions
Conceptualization and Methodology, S.L. and B.K.; validation, W.J. and H.J.; writing—original draft preparation, W.J., J.K. and B.K.; writing—review and editing, W.J., J.K. and B.K. All authors have read and agreed to the published version of the manuscript.
Funding
This work was supported by Korea Environment Industry & Technology Institute (KEITI) through the R&D Program for Innovative Flood Protection Technologies against Climate Crisis Project, funded by the Korea Ministry of Environment (MOE) (2480000599).
Data Availability Statement
The raw data supporting the conclusions of this article will be made available by the authors on request.
Acknowledgments
The authors gratefully acknowledge the editor and anonymous reviewers for their valuable comments on this manuscript. The authors also appreciate the financial support from the Korea Environment Industry & Technology Institute (KEITI) of Korea Ministry of Environment (MOE).
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Kim, S.; Shin, J.; Lee, G.; Park, J.; Sung, K. Future Changes in Precipitation Extremes over South Korea Based on Observations and CMIP6 SSP Scenario. Water 2025, 17, 1702. [Google Scholar] [CrossRef] [Scilit]
- Kim, J.; Kang, H.; Park, Y. Evaluation of the Agricultural Reservoir Management Efficiency Based on Water Use Data in Korea. Water 2021, 13, 1249. [Google Scholar] [CrossRef] [Scilit]
- Park, J.; Kwon, H.; Jang, C. Optimal Allocation of Agricultural Water Resources in South Korea Using Reservoir Operation Modeling. Water 2020, 12, 1084. [Google Scholar] [CrossRef] [Scilit]
- Wu, Z.; Huang, Y.; Huang, K.; Yan, K.; Chen, H. A Review of Non-Contact Water Level Measurement Based on Computer Vision and Radar Technology. Water 2023, 15, 3233. [Google Scholar] [CrossRef] [Scilit]
- Yu, J.; Liu, Z.; Zhang, H. River Stage Detection Using Difference Image and Otsu Method. J. Hydroinformatics 2010, 12, 311–323. [Google Scholar] [CrossRef] [Scilit]
- Hiroi, N.; Nishio, M.; Kobayashi, H.; Fukami, K. Real-Time Monitoring System of River Stage Using Infrared Camera. Hydrol. Res. Lett. 2016, 10, 14–18. [Google Scholar]
- Kurekin, A.A.; Land, P.E.; Miller, P.I. CNN-Based Water Level Detection Using Surveillance Video. Remote Sens. 2020, 12, 2476. [Google Scholar] [CrossRef] [Scilit]
- Kim, H.I.; Kim, B.H. Flood Hazard Rating Prediction for Urban Areas Using Random Forest and LSTM. KSCE J. Civ. Eng. 2020, 24, 3884–3896. [Google Scholar] [CrossRef] [Scilit]
- Lee, J.Y.; Kim, B.H. Scenario-Based Real-Time Flood Prediction with Logistic Regression. Water 2021, 13, 1191. [Google Scholar] [CrossRef] [Scilit]
- Bhang, K.; Park, S.; Lee, J. Application of High-Resolution Image in Water Level Monitoring. KSCE J. Civ. Eng. 2014, 18, 1462–1471. [Google Scholar] [CrossRef] [Scilit]
- Seo, D.; Lee, J.; Kim, Y. Monitoring Techniques of River Stages Using Images. Water 2017, 9, 956. [Google Scholar] [CrossRef] [Scilit]
- Li, X.; Wu, J.; Zhang, C. Video Super-Resolution Using Deep CNN. IEEE Trans. Image Process. 2019, 28, 1651–1665. [Google Scholar] [CrossRef] [Scilit]
- Dhara, A.; Patra, A.; Mitra, P. Deep Learning for Image Enhancement in Environmental Monitoring. Environ. Model. Softw. 2020, 124, 104578. [Google Scholar] [CrossRef] [Scilit]
- Dal Sasso, S.F.; Benassi, G.; Manfreda, S. Enhancing Flood Image Resolution for AI Training. Nat. Hazards 2023, 115, 271–290. [Google Scholar]
- Hong, S.; Kim, H.; Yoon, J. Evaluation of Adequacy of Agricultural Water Supply Using Water Balance Model. Korean J. Agric. Eng. 2014, 56, 87–95. [Google Scholar]
- Kim, T.; Park, S.; Choi, Y. Design of Optimal Water Level Monitoring Network for Agricultural Water Management. J. Korean Soc. Agric. Eng. 2016, 58, 33–41. [Google Scholar]
- Yang, J.; Han, S.; Lee, D.; Park, Y.; Choi, J. Deep Learning Model for Agricultural Water Supply Estimation Using CCTV Images. Sensors 2021, 21, 3125. [Google Scholar] [CrossRef] [Scilit]
- Kim, K.H.; Kim, M.G.; Yoon, P.R.; Bang, J.H.; Myoung, W.H.; Choi, J.Y.; Choi, G.H. Application of CCTV image and semantic segmentation model for water level estimation of irrigation channel. J. Korean Soc. Agric. Eng. 2022, 64, 63–72. [Google Scholar] [CrossRef]
- Kwon, S.H.; Ha, C.Y.; Lee, S.Y. A Study on the Application of the Agricultural Reservoir Water Level Recognition Model Using CCTV Image Data. J. Korea Water Resour. Assoc. 2023, 56, 245–259. [Google Scholar] [CrossRef]
- Badrinarayanan, V.; Kendall, A.; Cipolla, R. SegNet: A Deep Convolutional Encoder–Decoder Architecture for Image Segmentation. IEEE Trans. Pattern Anal. Mach. Intell. 2017, 39, 2481–2495. [Google Scholar] [CrossRef] [Scilit]
- Ronneberger, O.; Fischer, P.; Brox, T. U-Net: Convolutional Networks for Biomedical Image Segmentation. In Proceedings of the International Conference on Medical Image Computing and Computer-Assisted Intervention (MICCAI), Munich, Germany, 5–9 October 2015; Lecture Notes in Computer Science. Volume 9351, pp. 234–241. [Google Scholar] [CrossRef] [Scilit]
- Jenks, G.F. The Data Model Concept in Statistical Mapping. Int. Yearb. Cartogr. 1967, 7, 186–190. [Google Scholar]
- Long, J.; Shelhamer, E.; Darrell, T. Fully Convolutional Networks for Semantic Segmentation. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR), Boston, MA, USA, 7–12 June 2015; pp. 3431–3440. [Google Scholar] [CrossRef] [Scilit]
- Chen, L.-C.; Papandreou, G.; Kokkinos, I.; Murphy, K.; Yuille, A.L. DeepLab: Semantic Image Segmentation with Deep Convolutional Nets, Atrous Convolution, and Fully Connected CRFs. IEEE Trans. Pattern Anal. Mach. Intell. 2018, 40, 834–848. [Google Scholar] [CrossRef] [Scilit]
- He, K.; Zhang, X.; Ren, S.; Sun, J. Deep Residual Learning for Image Recognition. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR), Las Vegas, NV, USA, 27–30 June 2016; pp. 770–778. [Google Scholar] [CrossRef] [Scilit]
- Tan, M.; Le, Q.V. EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks. In Proceedings of the 36th International Conference on Machine Learning (ICML), Long Beach, CA, USA, 9–15 June 2019; Volume 97, pp. 6105–6114. [Google Scholar] [CrossRef] [Scilit]
- LeCun, Y.; Bengio, Y. Convolutional Networks for Images, Speech, and Time Series. In The Handbook of Brain Theory and Neural Networks; MIT Press: Cambridge, MA, USA, 1995; pp. 255–258. [Google Scholar]
- Powers, D.M.W. Evaluation: From Precision, Recall and F-Measure to ROC, Informedness, Markedness and Correlation. J. Mach. Learn. Technol. 2011, 2, 37–63. [Google Scholar]
- Kim, J.; Jonoski, A.; Solomatine, D.P. A Classification-Based Machine Learning Approach to the Prediction of Cyanobacterial Blooms in Chilgok Weir, South Korea. Water 2022, 14, 542. [Google Scholar] [CrossRef] [Scilit]
- Li, Y.; Yu, C.; Shi, Y.; Huang, Y.; Yang, Y. Water Level Detection from Surveillance Video Based on Deep Learning. Remote Sens. 2019, 11, 2118. [Google Scholar] [CrossRef] [Scilit]
- Hasan, F.; Medley, P.; Drake, J.; Chen, G. Advancing Hydrology through Machine Learning: Insights, Challenges, and Future Directions Using the CAMELS, Caravan, GRDC, CHIRPS, PERSIANN, NLDAS, GLDAS, and GRACE Datasets. Water 2024, 16, 1904. [Google Scholar] [CrossRef] [Scilit]
- Goodarzi, M.R.; Vazirian, M. A Geostatistical Approach to Estimate Flow Duration Curve Parameters in Ungauged Basins. Appl. Water Sci. 2023, 13, 178. [Google Scholar] [CrossRef] [Scilit]
- Zhang, B.; Ouyang, C.; Cui, P.; Wang, D.; Zhang, F.; Li, Z.; Fan, L.; Lovati, M.; Liu, Y.; Zhang, Q. Deep Learning for Cross-Region Streamflow and Flood Forecasting at a Global Scale. Innovation 2024, 5, 100617. [Google Scholar] [CrossRef] [Scilit]
- Goodarzi, M.R.; Poorattar, M.J.; Vazirian, M.; Talebi, A. Evaluation of a Weather Forecasting Model and HEC-HMS for Flood Forecasting: Case Study of Talesh Catchment. Appl. Water Sci. 2024, 14, 34. [Google Scholar] [CrossRef] [Scilit]
- Sharma, V.K.; Shukla, A.K.; Chowdary, V.M. Integration of Recurrent Neural Network Models and Flood Inundation Extent Libraries for Flood Forecasting. Remote Sens. Appl. Soc. Environ. 2025, 40, 101649. [Google Scholar] [CrossRef] [Scilit]
- Goodarzi, M.R.; Bafrouei, H.B.; Vazirian, M. Insight into Groundwater Level Prediction with Feature Effectiveness: Comparison of Machine Learning and Numerical Methods. Hydrol. Res. 2025, 56, 74–92. [Google Scholar] [CrossRef] [Scilit]
- Goodarzi, M.R.; Vazirian, M. A Machine Learning Approach for Predicting and Localizing the Failure and Damage Point in Sewer Networks Due to Pipe Properties. J. Water Health 2024, 22, 487–509. [Google Scholar] [CrossRef] [Scilit] [PubMed]
| Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).