Article

Symbolic Artificial Intelligence for Ground-Level Ozone Prediction Through Association Rule Mining

1
Univ. Lille, CNRS, Centrale Lille, UMR 9189 CRIStAL, F-59000 Lille, France
2
Atmo Hauts-de-France, Air Quality Observatory in Northern France, F-59000 Lille, France
3
LIRMM, Department of Robotics, University of Montpellier, CNRS, F-34095 Montpellier, France
4
Univ. Lille, ULR 4515—LGCgE, Laboratoire de Génie Civil et géo-Environnement, F-59000 Lille, France
*
Author to whom correspondence should be addressed.
Atmosphere 2026, 17(8), 798; https://doi.org/10.3390/atmos17080798
Submission received: 30 June 2026 / Revised: 3 August 2026 / Accepted: 13 August 2026 / Published: 19 August 2026

Abstract

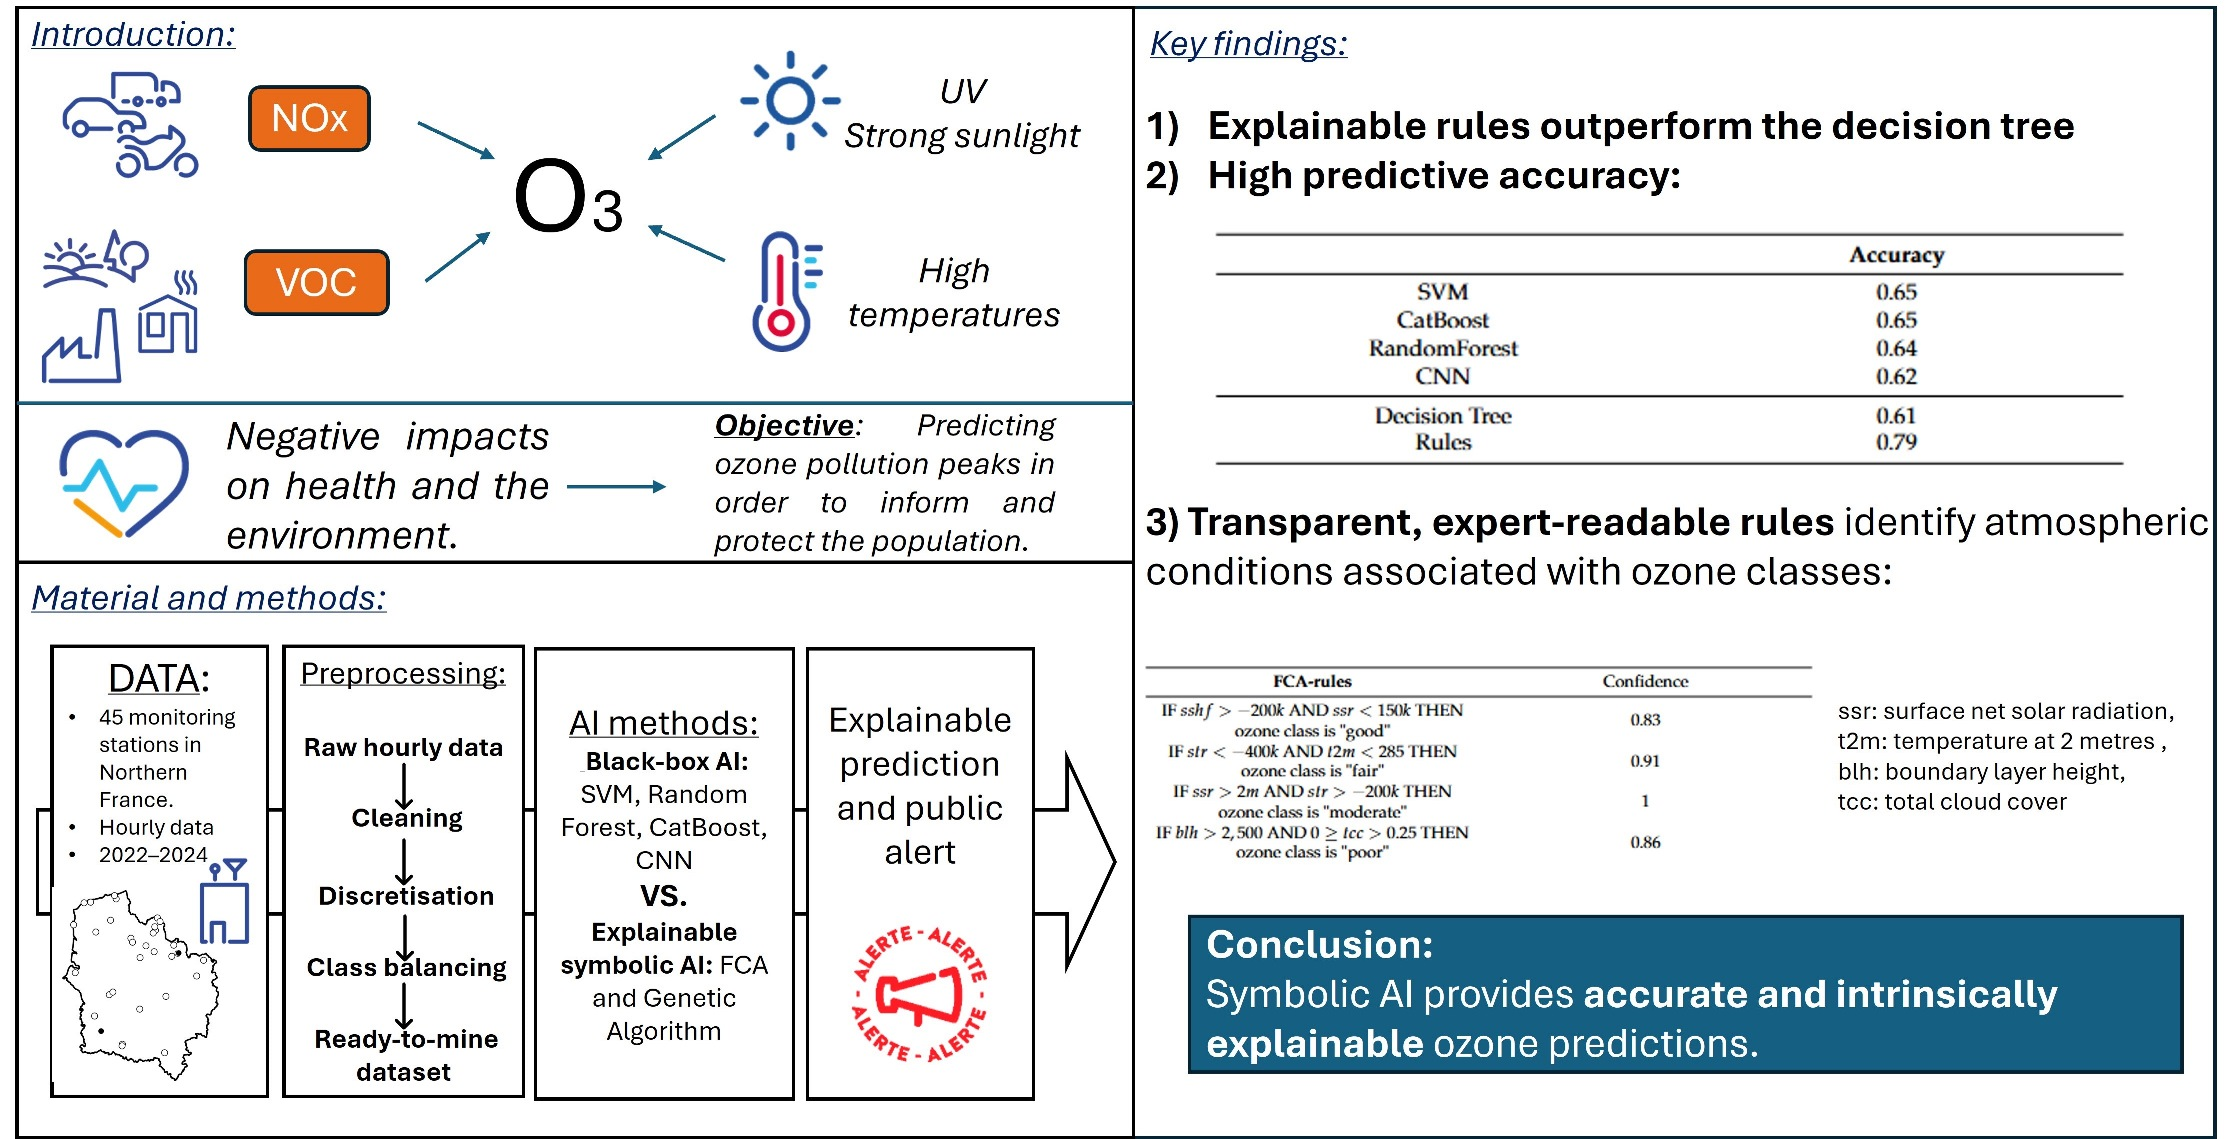
Accurate air quality prediction is essential for environmental monitoring and public health protection. Among atmospheric pollutants, ground-level ozone remains particularly difficult to predict because of the complex and nonlinear interactions governing its formation. Although recent advances have achieved promising predictive performance using machine learning and deep learning, most existing approaches rely on black-box models whose explanations are provided only through post hoc explainability techniques. This work presents an alternative symbolic artificial intelligence framework based on association rule mining for intrinsically explainable ozone prediction. Hourly atmospheric observations collected from ground-level monitoring stations in the Hauts-de-France region (France) are preprocessed through cleaning, discretization, and class balancing before rule extraction. Two complementary symbolic AI approaches, Formal Concept Analysis (FCA) and a Genetic Algorithm (GA), are employed to automatically discover human-readable association rules linking meteorological and atmospheric variables to ozone concentration classes. The extracted rules provide transparent and directly interpretable decision mechanisms that can be readily validated by air quality experts. The experimental results show that both rule-mining approaches produce substantially more precise rule sets than decision trees, with average rule precisions of 0.76 for FCA and 0.79 for GA. Furthermore, the resulting rule-based classifier achieves an accuracy of approximately 0.79, outperforming the evaluated machine learning baselines while preserving intrinsic interpretability. These results demonstrate that symbolic AI constitutes a promising alternative for trustworthy air quality prediction and knowledge discovery.

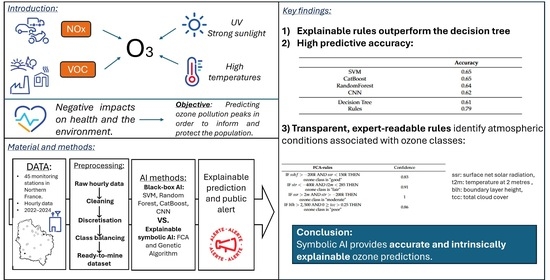
Graphical Abstract

1. Introduction

Tropospheric (ground-level) ozone is currently the only regulated pollutant in the Hauts-de-France region of Northern France whose concentrations have increased since monitoring began in the 1990s [1]. As a secondary pollutant, it is not directly emitted into the atmosphere but is formed through photochemical reactions involving nitrogen oxides (NOx) and volatile organic compounds (VOCs) in the presence of solar radiation [2,3]. Because of its secondary nature, ozone concentrations are strongly influenced by meteorological conditions. In particular, high temperatures enhance photochemical activity and are frequently associated with elevated ozone concentrations during summer pollution episodes, while meteorological conditions also govern the transport and dispersion of ozone and its precursors over regional scales [2,4]. Therefore, meteorological variables provide valuable information for accounting for ozone variability, although they do not explicitly represent the underlying atmospheric chemistry. Ground-level ozone has well-documented adverse effects on human health [5], vegetation [6], and ecosystems [7], making it a major contributor to the adverse impacts of air pollution [8].
Ground-level ozone concentrations are regulated through air quality standards established at both international and European levels. The World Health Organisation (WHO) [9] recommends a maximum daily 8 h mean concentration of 100 μg m−3 to protect human health. In the European Union, ozone has long been regulated under Directive 2008/50/EC [10], which sets a target value of 120 μg m−3 for the maximum daily 8 h mean concentration. According to this directive, this threshold should not be exceeded on more than 25 days per calendar year, averaged over three consecutive years. The recently adopted Directive (EU) 2024/2881 [11] strengthens ozone regulation by reducing the allowed number of days exceeding the 120 μg m−3 target value from 25 to 18 days per year from 2030 onwards. However, ozone remains regulated through target values and long-term objectives rather than legally binding thresholds. Consequently, a significant gap persists between the European regulatory framework and the more stringent WHO guideline value. These European requirements are implemented in France through national air quality legislation, and are monitored by regional air quality monitoring agencies such as Atmo Hauts-de-France. Information and alert thresholds are set to 180 μg m−3 and 240 μg m−3, respectively, for hourly concentrations. Despite these regulatory frameworks, accurately forecasting ozone pollution episodes remains challenging because of the complex and nonlinear processes governing ozone formation, transport, and accumulation. Early prediction of high-ozone events is crucial for informing the population and supporting air quality management strategies. Over recent decades, numerous approaches ranging from statistical methods to machine learning have been proposed to predict ozone concentrations and classify air quality conditions.
Nevertheless, forecasting performance remains imperfect, with models often under- or overestimating ozone levels under specific meteorological conditions.
Ground-level ozone forecasting has traditionally relied on three complementary families of approaches. Statistical methods, including multiple linear regression, generalized additive models, and time-series techniques, exploit the historical relationships between ozone concentrations and meteorological variables to provide computationally efficient forecasts. Deterministic chemical transport models, such as CHIMERE [12] and CMAQ [13], explicitly simulate atmospheric transport, emissions, and photochemical processes, providing physically consistent predictions at regional scales. More recently, hybrid approaches combining deterministic chemical transport models (CTMs) with machine learning techniques have emerged as a promising direction for air quality forecasting. These methods exploit the physically consistent representation of atmospheric transport and chemistry provided by CTMs such as CMAQ and CHIMERE while using machine learning algorithms to correct systematic model biases and improve predictive accuracy [14,15]. Recent developments have further integrated deep learning architectures, physics-informed neural networks, and multimodal data fusion to combine atmospheric simulations, meteorological forecasts, emission inventories, and monitoring observations within unified forecasting frameworks [14,16]. Despite their excellent predictive performance, most of these approaches remain difficult to interpret because they rely on complex black-box models. This limitation motivates the development of intrinsically explainable symbolic artificial intelligence methods capable of extracting transparent decision rules while maintaining competitive predictive performance. Within this context, the objective of the present work is not to replace existing forecasting systems but to investigate whether symbolic artificial intelligence can complement these approaches by providing intrinsically interpretable decision rules that support ozone forecasting and facilitate expert interpretation.
In this context, artificial intelligence (AI) is increasingly being employed for air quality prediction, owing to its ability to model complex and nonlinear relationships within environmental data [17]. Numerous studies have focused specifically on predicting ozone concentrations in particular, which constitute a key indicator of air quality and have significant implications for public health and environmental management [18]. Other studies have investigated ozone prediction using AI techniques, including [19,20,21]. These studies have demonstrated the ability of AI to accurately predict ozone concentrations by capturing complex nonlinear relationships and interactions among atmospheric variables that are difficult to model using conventional statistical approaches. Nevertheless, the vast majority of existing methods rely on sub-symbolic AI, including machine learning and deep learning models, whose predictive performance is achieved at the expense of interpretability. Consequently, the interpretation of their predictions generally depends on post hoc explainability techniques, which provide explanations after model training rather than being intrinsically integrated into decision-making processes [22].
In this context, explainable artificial intelligence (XAI) can be broadly divided into two main families of approaches. The first consists of intrinsically interpretable models, whose prediction mechanisms are directly and inherently understandable by humans, such as decision trees, rule-based systems and symbolic AI. The second family includes post hoc explainability techniques, which generate explanations after a prediction has been produced by an otherwise opaque model. Popular examples include LIME [23] and SHAP [24], which estimate the contribution of each input feature to individual predictions without modifying the underlying model. As shown in [25], while post hoc techniques improve the explainability of black-box models by highlighting influential features, they do not make the underlying prediction mechanism transparent or directly interpretable. Furthermore, Kalasampath et al. [26] distinguish two complementary concepts related to explainability: transparency and interpretability. Regarding transparency, the goal of this study is to provide a model that can support further meteorological studies, hence the necessity of a transparent model whose prediction mechanism is explicitly described and directly understandable. As for interpretability, it focuses on explaining individual predictions, i.e., the outputs of the model. Symbolic rule-based models naturally provide interpretability, since each decision is computed through a readable succession of rule applications, while post hoc methods only provide insight into which features influenced each decision. Moreover, following an analysis of [26], we find that post hoc methods may produce explanations that are inconsistent or potentially misleading. To ensure that the proposed framework can be effectively used by air quality forecasters, it focuses on transparent and intrinsically interpretable models rather than relying on post hoc explainability. Instead of explaining the behaviour of a black-box predictor after inference, it directly produces human-readable rules that constitute the prediction model itself. Consequently, explanations are available for every prediction without requiring an additional post hoc explanation method.
Among intrinsically interpretable approaches, rule-based systems and association rule mining (ARM) have long been investigated as knowledge-discovery tools for extracting explicit relationships from complex datasets. Early work on association rule mining, initiated by the Apriori Algorithm [27], laid the methodological foundations for numerous applications in environmental sciences. Subsequently, rule-based approaches have been applied to environmental modelling and air quality analysis to identify relationships between meteorological variables, pollutant concentrations and environmental conditions, thereby supporting environmental monitoring and decision making [28,29]. More recently, advances in evolutionary association rule mining have improved the quality and efficiency of rule extraction [30], and these approaches have been successfully applied to air quality studies by combining association rule mining with Genetic Algorithms to analyse pollution factors and discover interpretable environmental knowledge [31]. Nevertheless, most of these studies focus on descriptive knowledge extraction or pollution factor analysis rather than on the development of intrinsically explainable predictive models for ground-level ozone forecasting.
More specifically, symbolic and rule-based approaches have been applied to other pollutants; for instance, a granular computing rule-extraction technique has been proposed for explainable PM2.5 air quality classification, linking atmospheric variables to air quality classes through human-readable rules [32]. Nevertheless, relatively few previous studies have investigated intrinsically explainable approaches for ozone prediction. However, to the best of our knowledge, none of them simultaneously satisfy all the requirements identified in this study, namely ground-level prediction, hourly temporal resolution, reliable multi-class prediction, and intrinsic interpretability, as summarized in Table 1. The table summarizes the most relevant studies identified in the literature according to the following criteria:
  • Ground-level prediction—ozone concentrations are predicted at ground level over a specific geographical area, providing information that is directly relevant to human exposure.
  • Hourly temporal resolution—accurate monitoring of ozone dynamics requires hourly predictions that capture the temporal evolution of meteorological conditions throughout the day.
  • Per-class prediction—to ensure that sudden increases or decreases in ozone concentrations are not overlooked, the model should provide reliable predictions across all considered ozone concentration classes.
  • Intrinsic interpretability—to support operational decision making, each prediction should be accompanied by a human-readable explanation derived directly from the prediction model.
Although several symbolic association rule-mining approaches have been reported in the literature, there is still a lack of unified methodological frameworks dedicated to intrinsically explainable ozone prediction. The methodological novelty of this work lies in the design of a unified symbolic artificial intelligence framework specifically designed for this purpose. The proposed framework combines a preprocessing methodology tailored to symbolic association rule mining, including data cleaning, ozone-oriented feature discretization, categorical encoding, and class balancing, with two complementary symbolic rule-mining strategies.
In the present work, Formal Concept Analysis (FCA) was selected because it provides a mathematically grounded framework for systematically deriving interpretable association rules from concept lattices [37]. In contrast, Genetic Algorithms (GAs) formulate rule mining as an optimization problem, enabling an efficient heuristic exploration of large search spaces to identify high-quality rules through evolutionary optimisation [31]. These two methods were deliberately selected because they represent two complementary symbolic AI paradigms: lattice-based reasoning and evolutionary optimisation. By contrast, algorithms such as Apriori [27] and FP-Growth [38] primarily aim to exhaustively discover frequent item sets based on support constraints, whereas RIPPER [39] is a sequential covering algorithm designed for predictive rule induction. Rather than providing an exhaustive comparison of all existing rule-mining algorithms, the objective of this work is to investigate two fundamentally different symbolic strategies for generating intrinsically interpretable prediction rules within a common preprocessing and evaluation framework. By integrating these complementary symbolic learning strategies within a common preprocessing and evaluation pipeline, the framework enables a consistent comparison of rule-extraction methods while preserving intrinsic interpretability throughout the prediction process.
To the best of our knowledge, no previous study has proposed such a unified symbolic AI framework for hourly, multi-class, ground-level ozone prediction in Europe. Moreover, this work focuses on real-world atmospheric data collected by Atmo Hauts-de-France using hourly observations and demonstrates that symbolic AI can achieve competitive predictive performance while producing decision rules that are directly interpretable by air quality experts. Consequently, unlike post hoc explainability methods, the proposed framework provides both a globally interpretable prediction model and locally interpretable individual predictions through explicit logical rules. This enables domain experts not only to understand individual decisions but also to analyse the overall reasoning process governing ozone prediction.

2. Materials and Methods

This section describes the proposed symbolic rule-mining framework. It first presents the atmospheric dataset and the data acquisition process, followed by the data preprocessing and association-rule-extraction procedures. Since the objective is to predict ground-level ozone concentrations relevant to human exposure, the study relies on hourly observations collected from ground-level monitoring stations.

2.1. Data Extraction

2.1.1. Study Area

The study area is located in the Hauts-de-France region in Northern France and covers approximately 31,800 km2. With a population of nearly six million inhabitants, it is one of the most densely populated regions in the country. The main urban centres include Lille, Amiens and Dunkirk. The northern part of the region is bordered by the North Sea and is characterised by a maritime climate together with significant industrial and port activities, particularly around the Dunkirk and Calais areas. In contrast, the southern part is predominantly rural, consisting of agricultural landscapes and lower population densities. Despite its more rural character, this area may also be influenced by long-range pollutant transport from the Paris metropolitan area. Air quality issues are particularly pronounced in urban and industrial zones, where elevated concentrations of particulate matter with aerodynamic diameters smaller than 10 µm (PM10) and 2.5 µm (PM2.5), nitrogen dioxide (NO2) and ozone (O3) are frequently observed.

2.1.2. Air Quality Monitoring and Data Acquisition

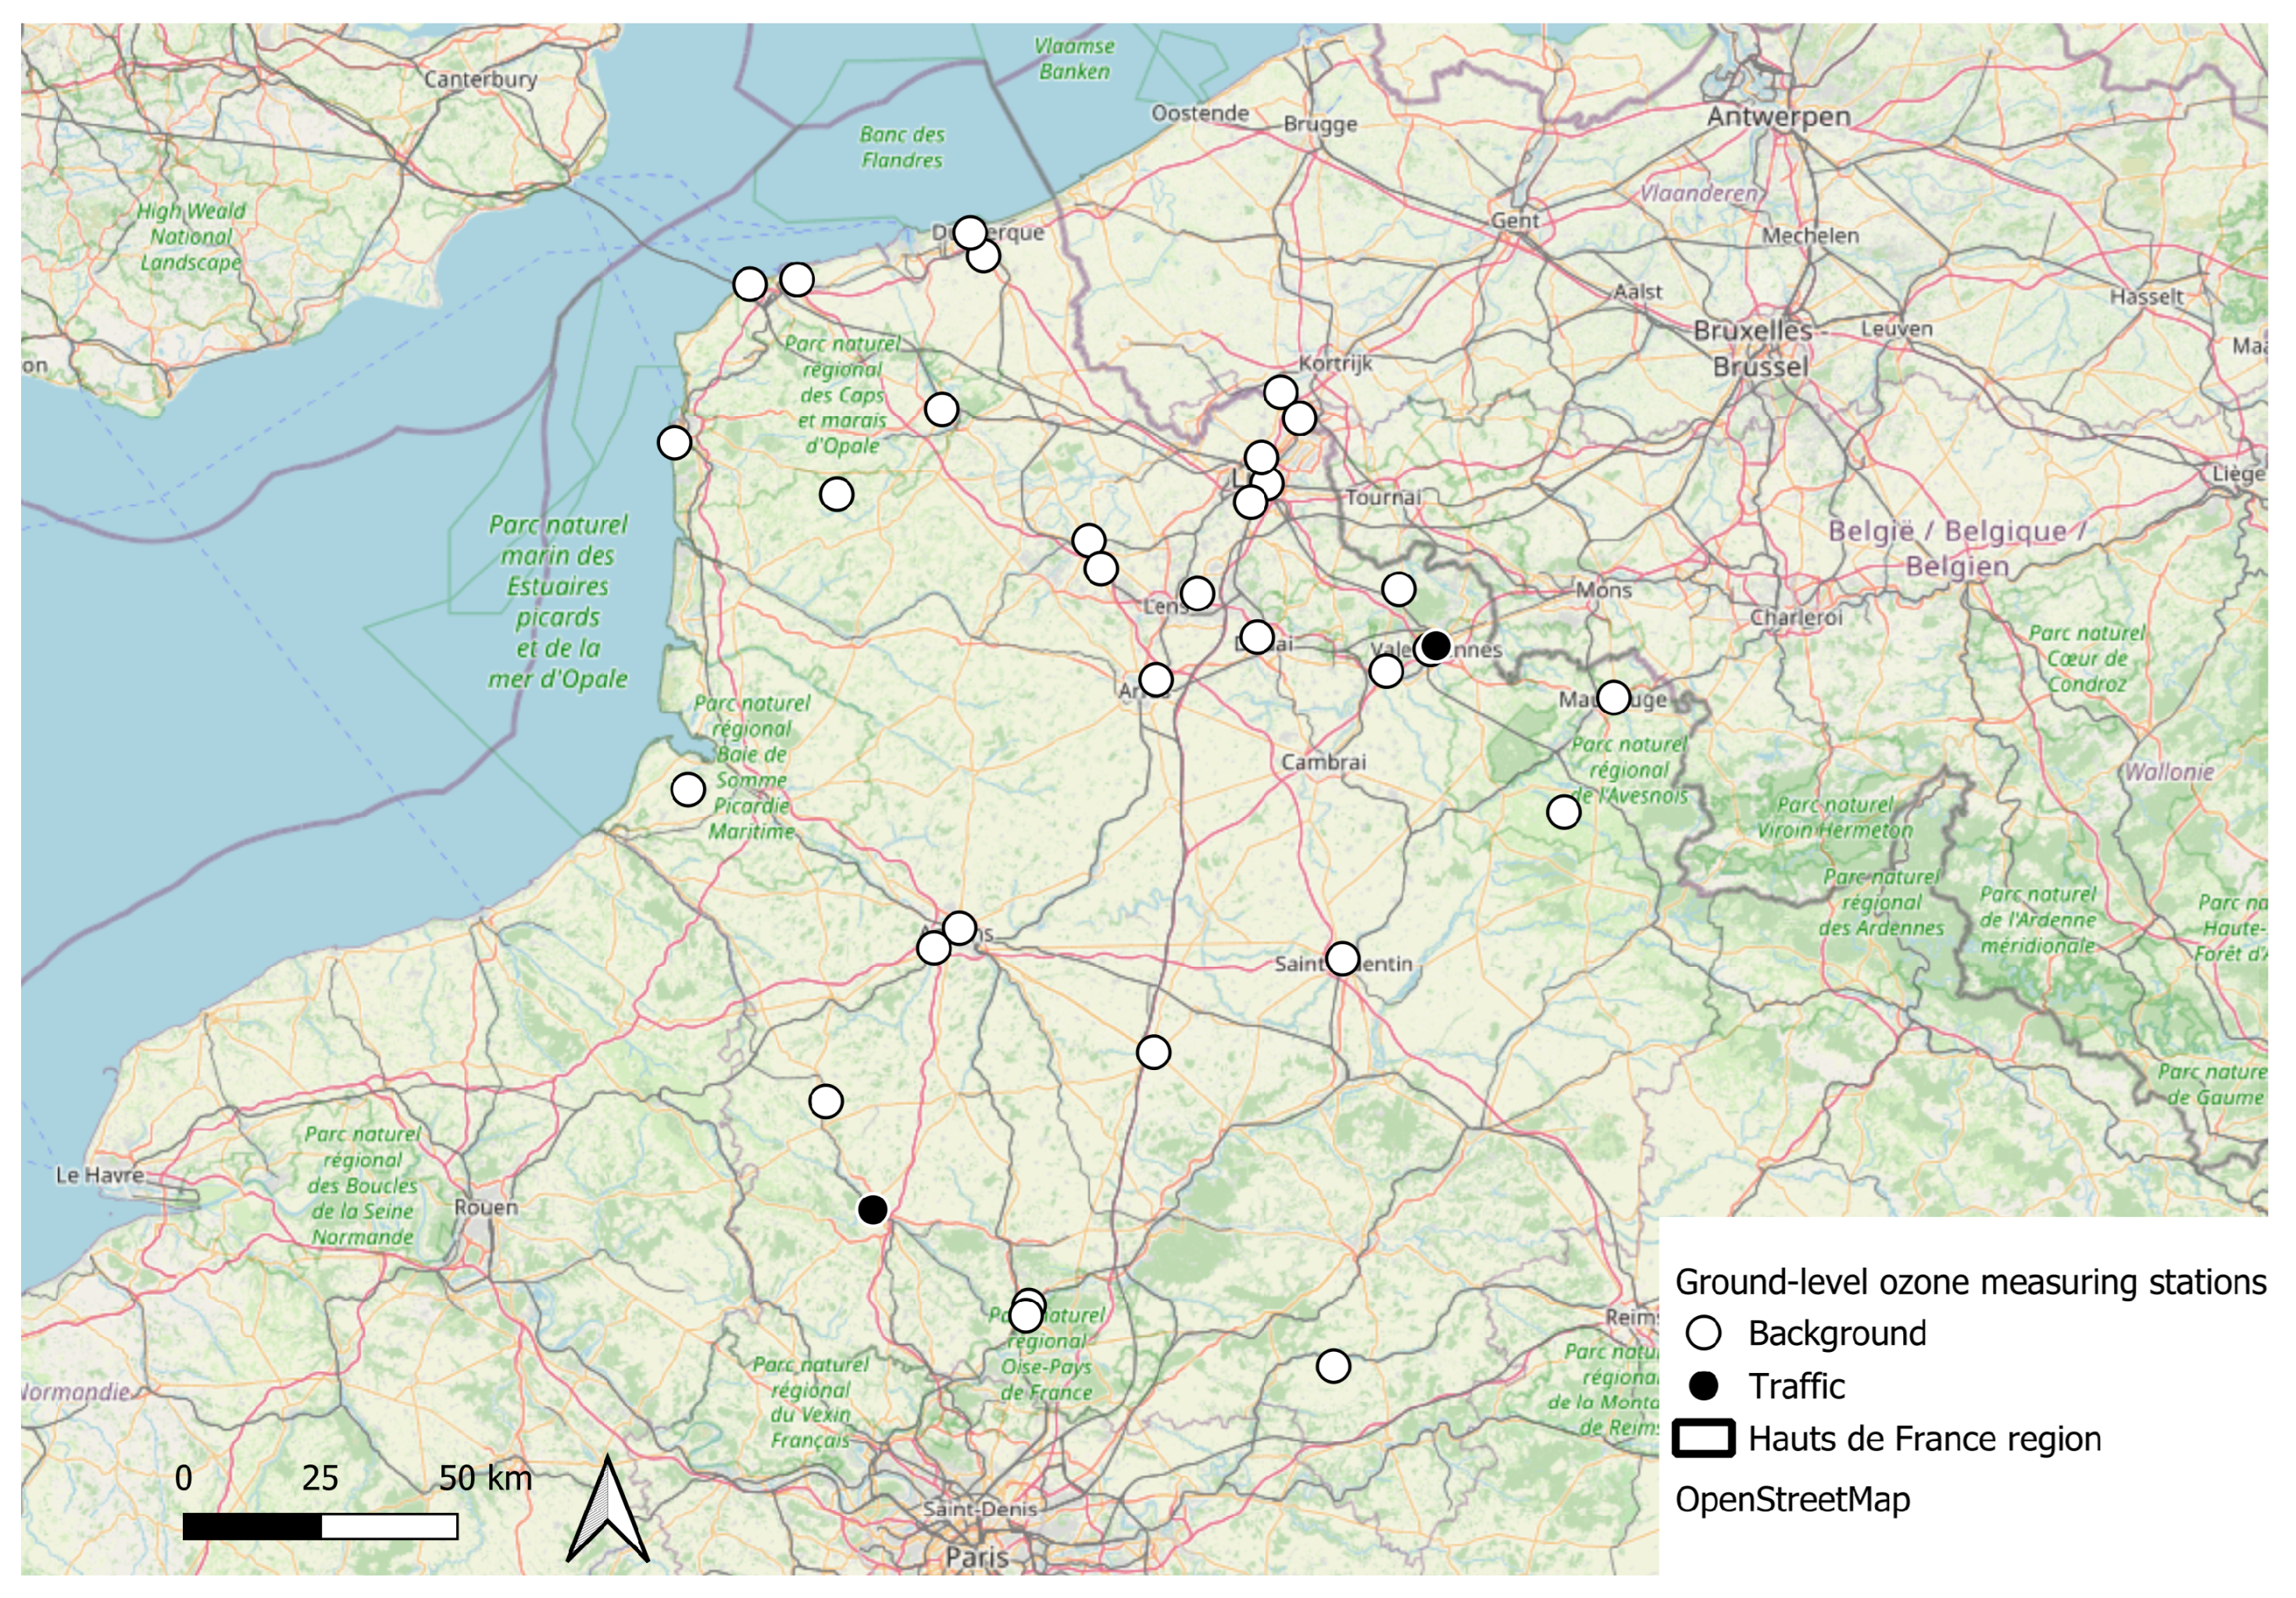
Hourly ozone concentration data were obtained from the air quality monitoring network operated by Atmo Hauts-de-France. The network consists of 45 monitoring stations distributed across the five departments of the Hauts-de-France region. These stations are categorised according to their surrounding environment (urban, suburban or rural) and their dominant influence (background, traffic or industrial), following the European Environment Agency classification scheme. The geographical distribution of the stations included in this study is shown in Figure 1.
The data used in this study were collected between 2022 and 2024 from the air quality monitoring network operated by Atmo Hauts-de-France. Measurements were acquired, quality-controlled and validated according to the organisation’s internal procedures before being extracted and processed for research purposes. The dataset was prepared within the framework of the IARISQ project (“Design and development of an artificial intelligence-based decision-support system for predicting air quality and determining the health risks of particulate matter”—https://anr.fr/Projet-ANR-25-CE56-3679, accessed on 8 August 2026; IARISQ), whose objective is to improve the assessment of the health impacts associated with air pollution by accounting for the complexity of pollutant mixtures and their interactions.
Once the data are extracted, the prediction of the ozone concentration regarding atmospheric features can begin. In that regard, two kinds of methods, presented below, are used: sub-symbolic methods and symbolic methods.

2.2. Meteorological Data

Meteorological variables were obtained from the ERA5 hourly reanalysis dataset produced by the European Centre for Medium-Range Weather Forecasts (ECMWF) within the Copernicus Climate Change Service (C3S) [4,40]. ERA5 provides hourly estimates of atmospheric variables on a global grid with a horizontal resolution of approximately 0.25° × 0.25°. The required variables were extracted for the study area and matched with the corresponding air quality observations according to their spatial and temporal coordinates.

2.3. Data Preprocessing

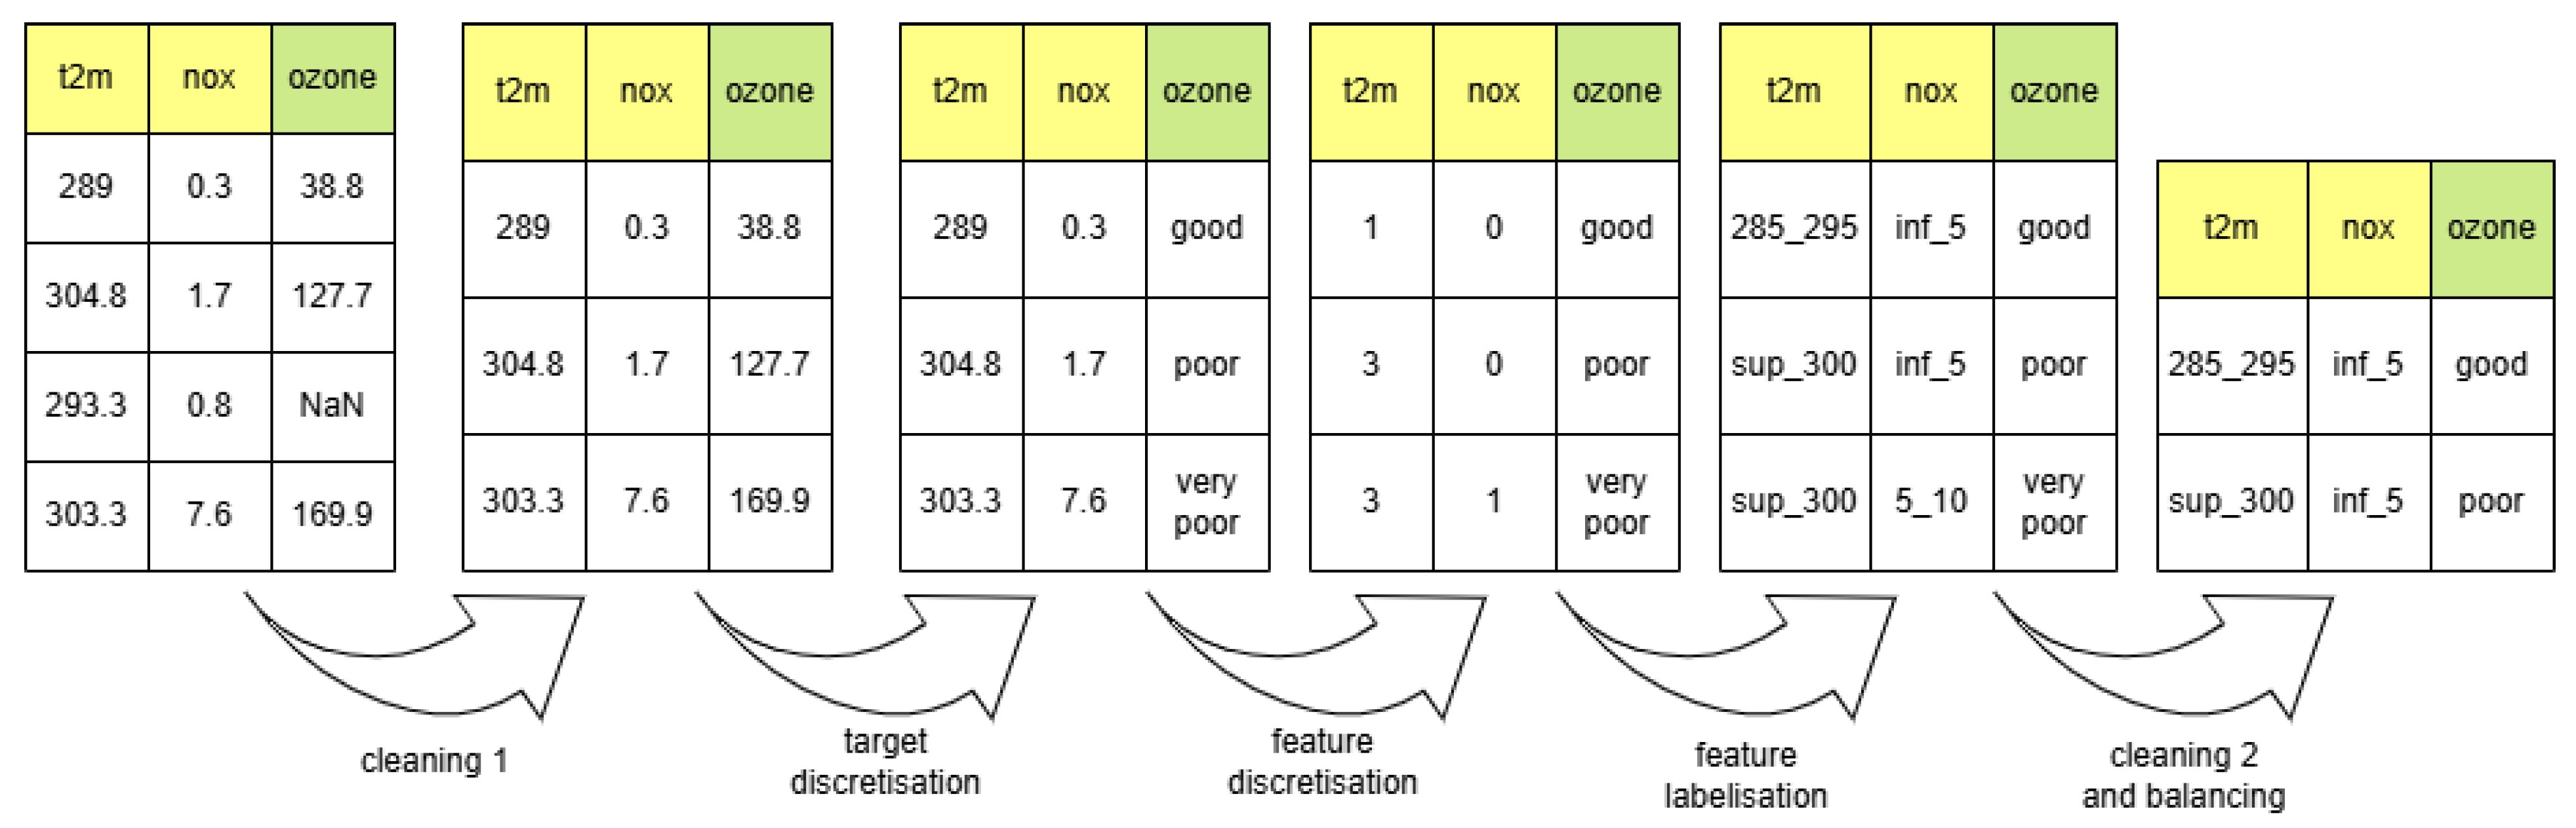
Following data collection, a dataset with 1,437,624 observations was obtained. For the purpose of this study, an observation refers to a sample of atmosphere for a given hour, taken at a given air quality station. To prepare the dataset for model development and evaluation, several preprocessing procedures were performed. In fact, to prepare the data for the mining task, it must be clean, have both inter- and intra-class balance, and each value in the dataset must be a categorical value, i.e., every continuous feature must be discretized. To meet these requirements, the following five-step process was adopted (Figure 2):
  • Initial data cleaning.
  • Discretization of the target variable.
  • Discretization of the input features.
  • Feature labelling.
  • Final data cleaning and class balancing to avoid statistical bias while mining rules.
Figure 2. Five-stage preprocessing pipeline transforming raw atmospheric measurements into discretized, balanced categorical data for association rule mining. t2m: air temperature at 2 m above ground level (K); nox: nitrogen oxide (NO and NO2) concentrations (μg m−3); ozone: ground-level ozone concentration (μg m−3).
Atmosphere 17 00798 g002
The whole preprocessing phase is implemented in python with the library pandas https://pandas.pydata.org/docs/index.html (accessed on 8 August 2026). After preprocessing, the resulting dataset contains 75,368 observations. Each step of the process is detailed and illustrated below.

2.3.1. Initial Data Cleaning

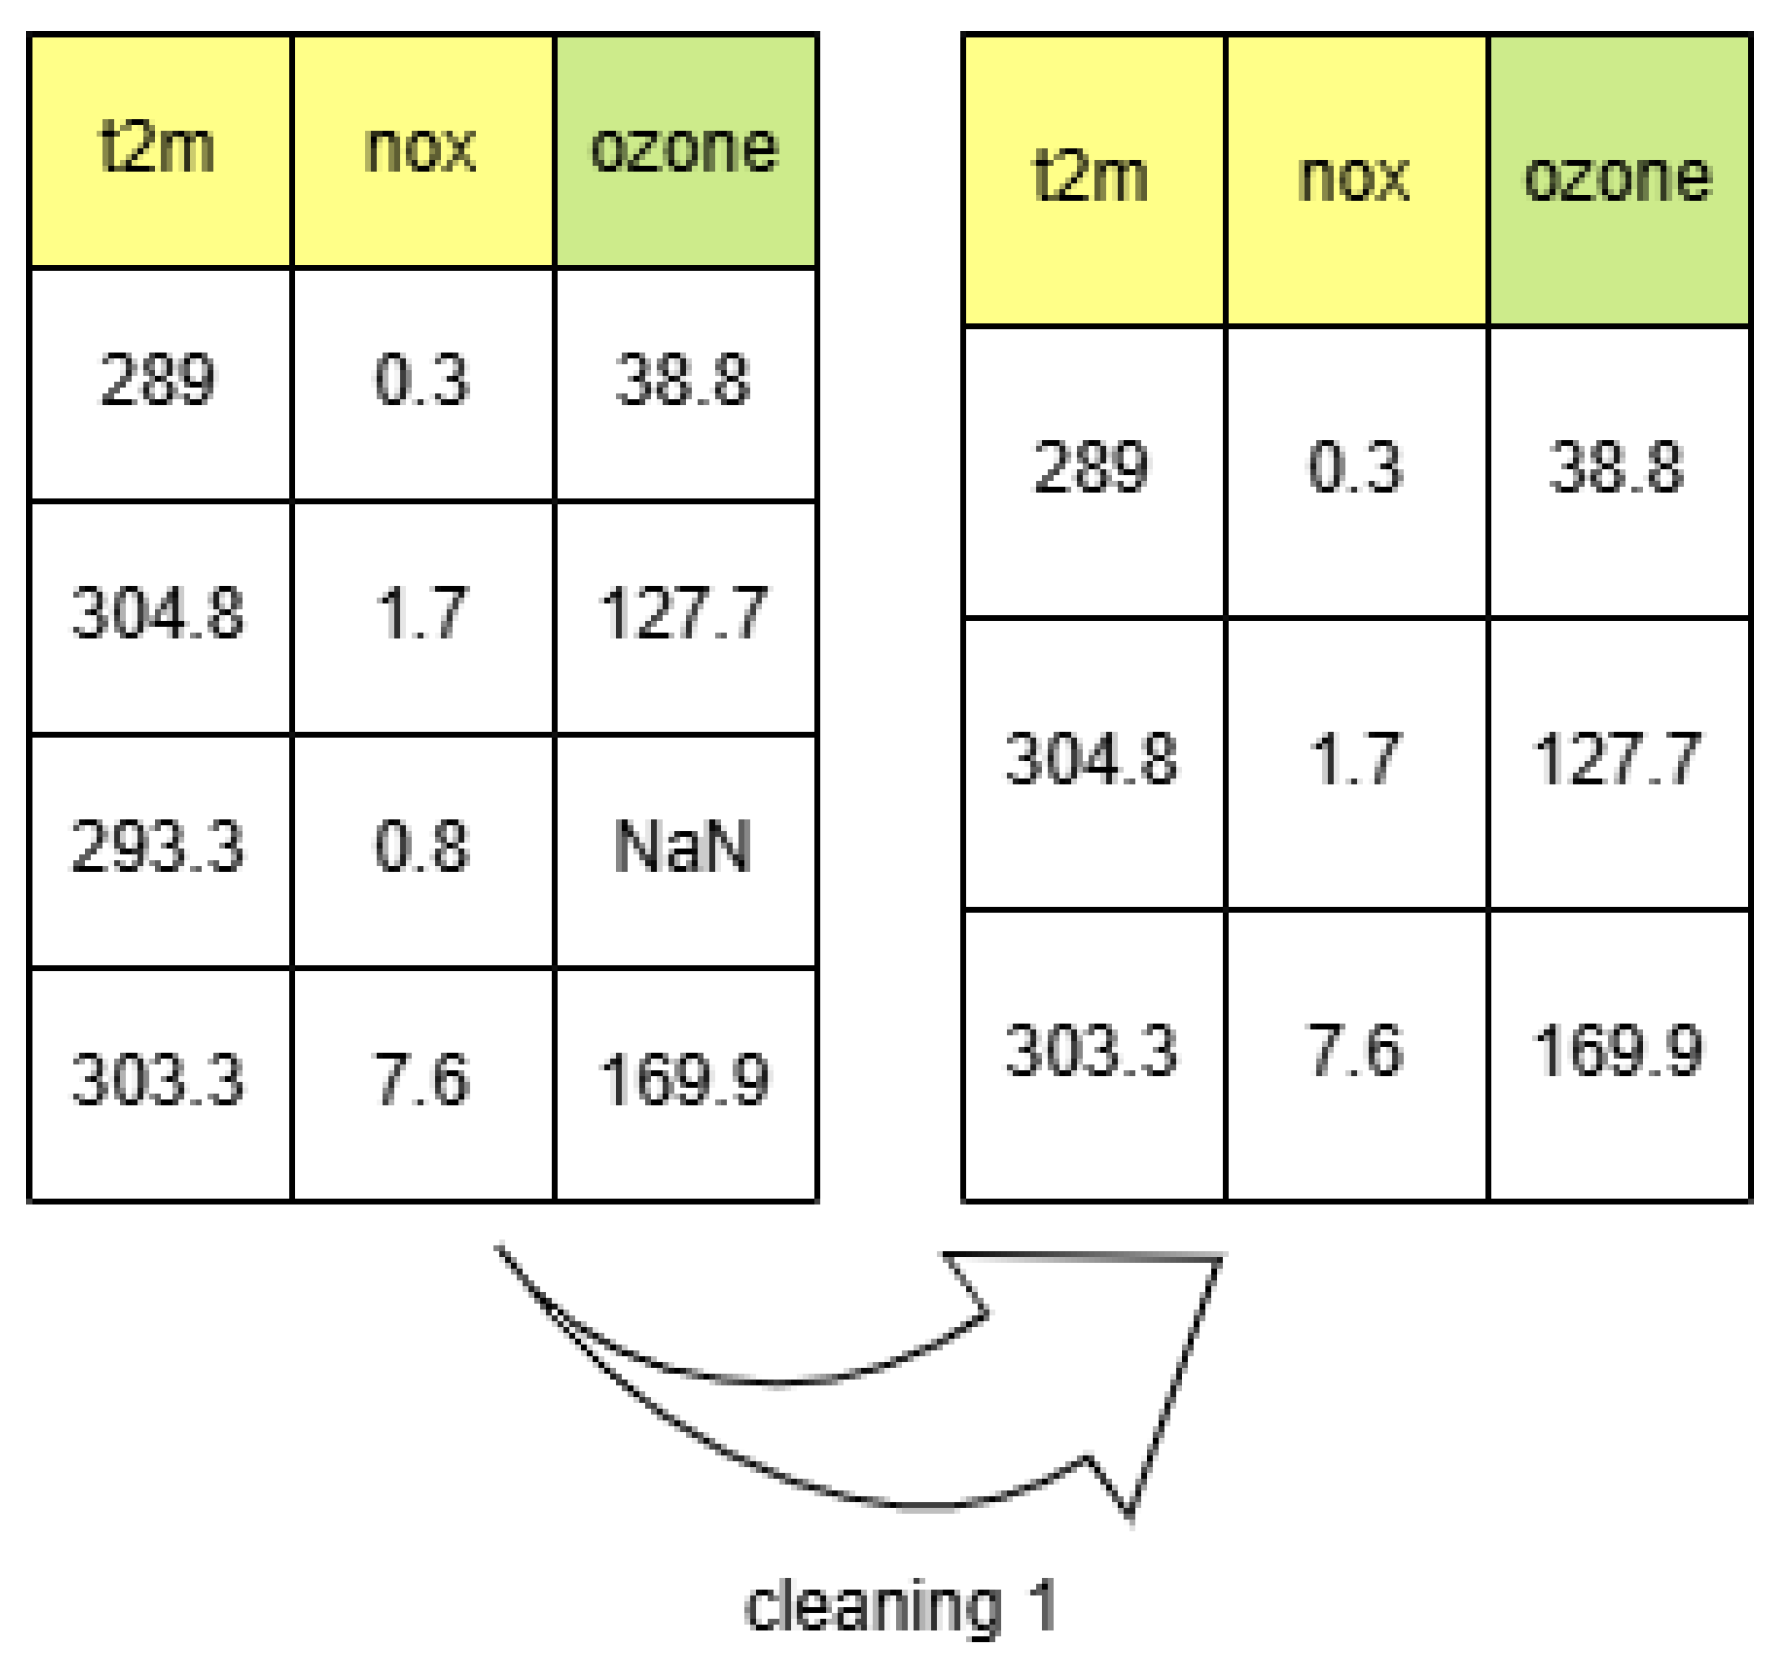
Observations with missing ozone values are excluded, as they do not provide a valid target value. Observations with missing NOx values are excluded, since these are important features that are well known to have chemical impacts on ozone concentration. The dataset used for this experiment has a 38.80% ratio of observations with missing values. This initial cleaning step is illustrated in Figure 3.
Since the objective is to extract association rules for ozone concentration prediction, such observations (observations with missing ozone or NOx values) do not provide meaningful information for identifying relationships between the target variable (ozone concentration) and the other variables in the dataset.

2.3.2. Discretization of the Target Variable: Ozone Quality Index Classes

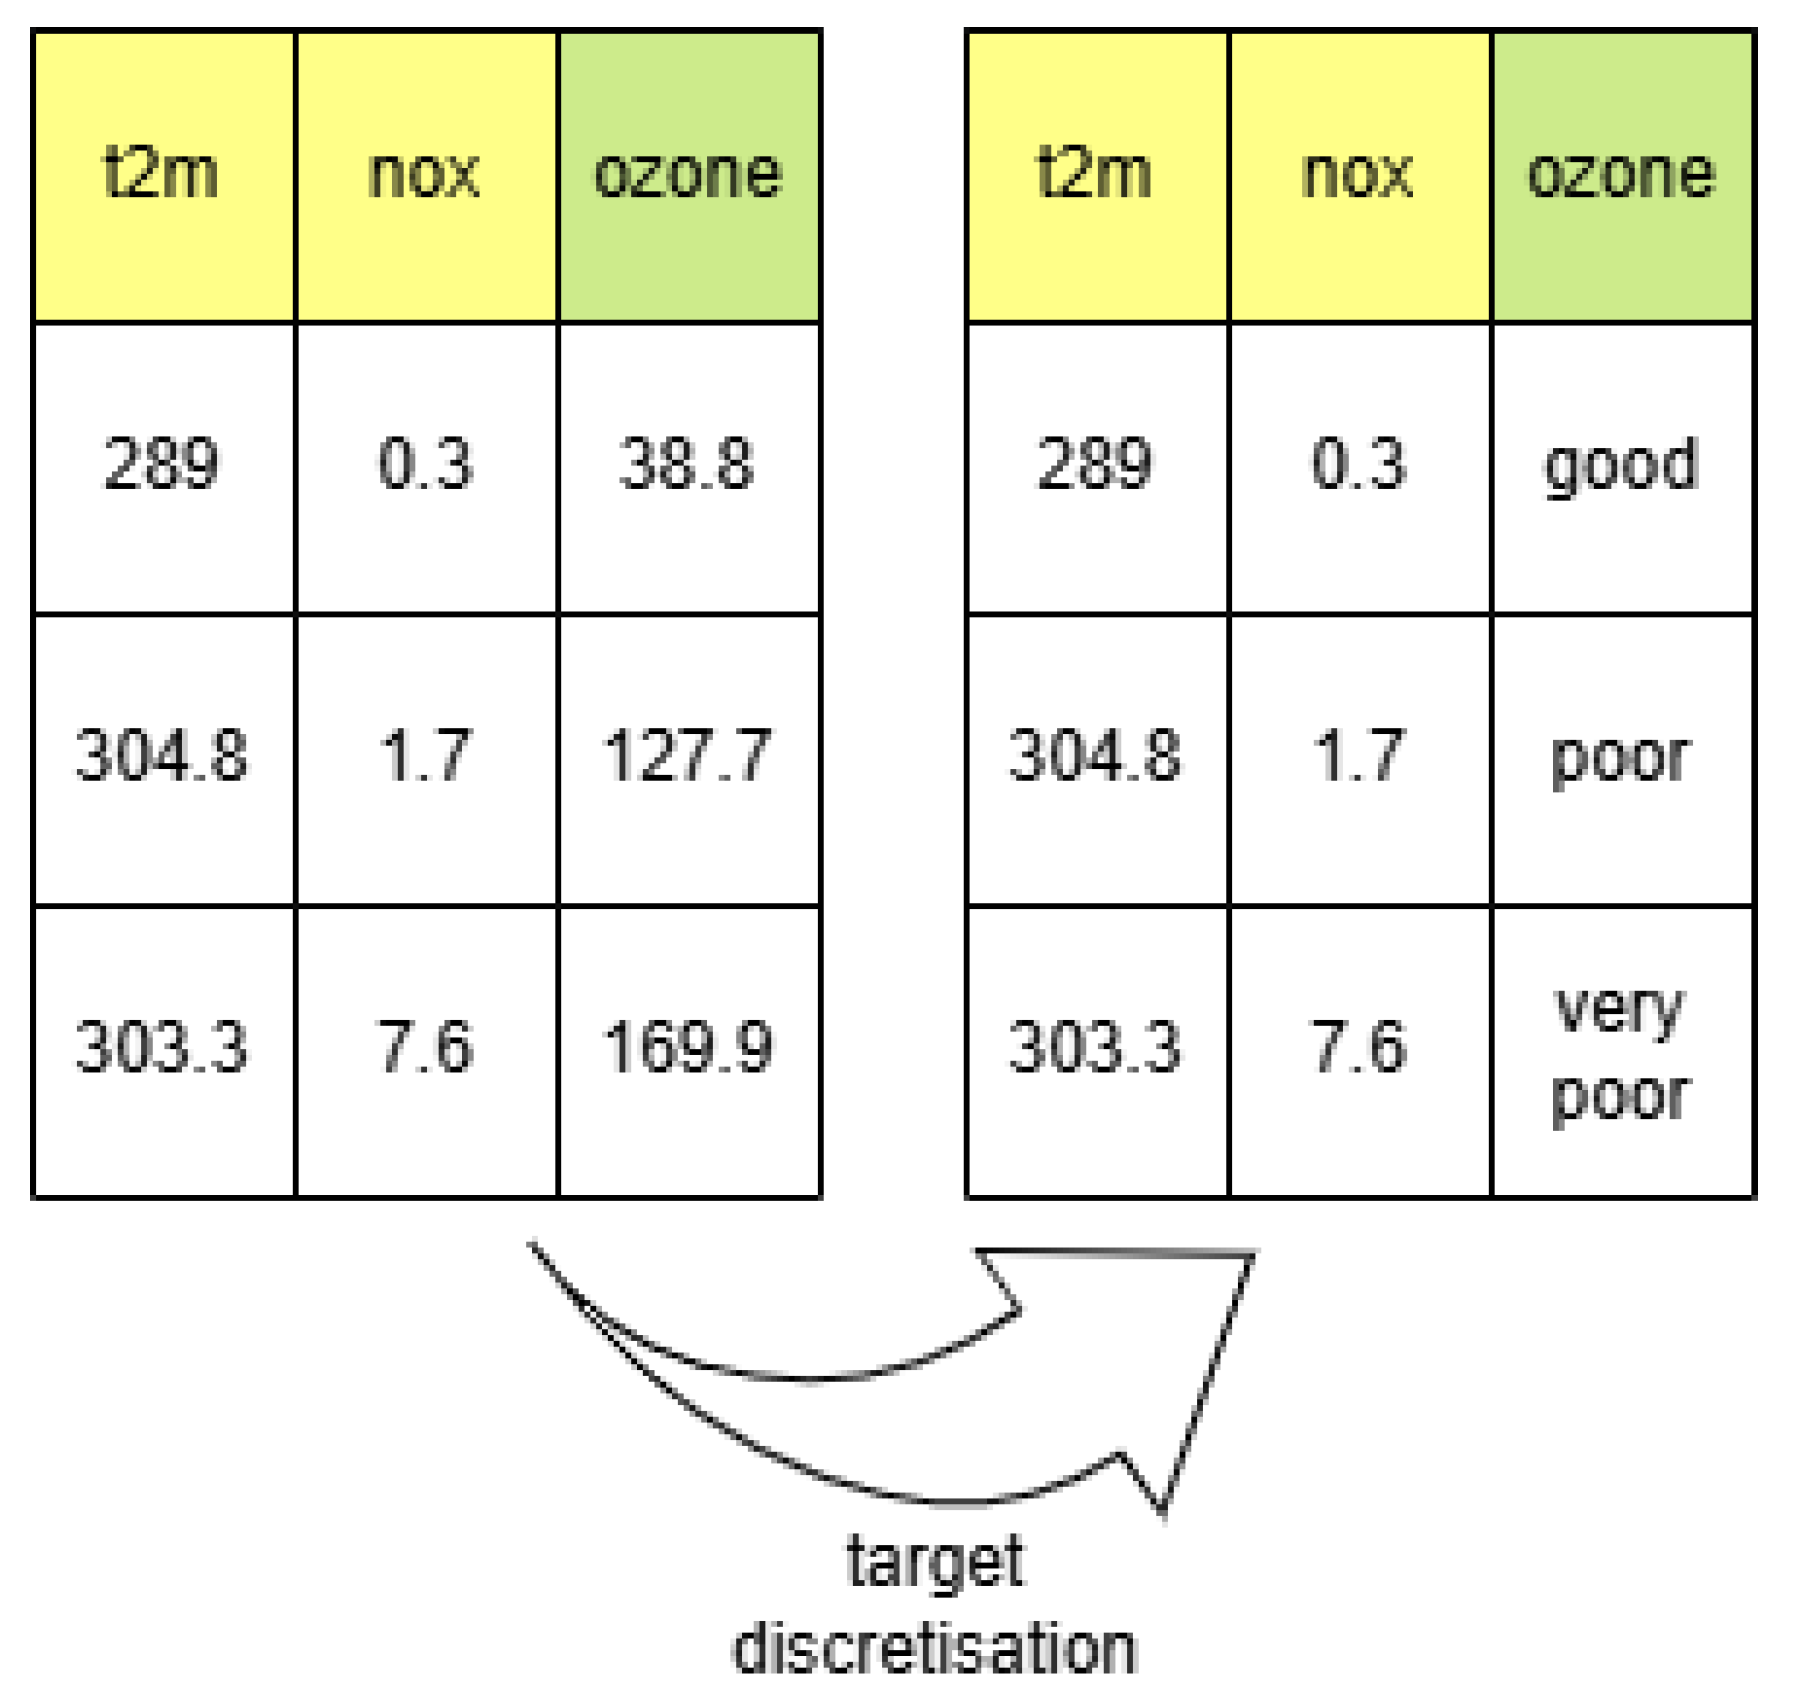
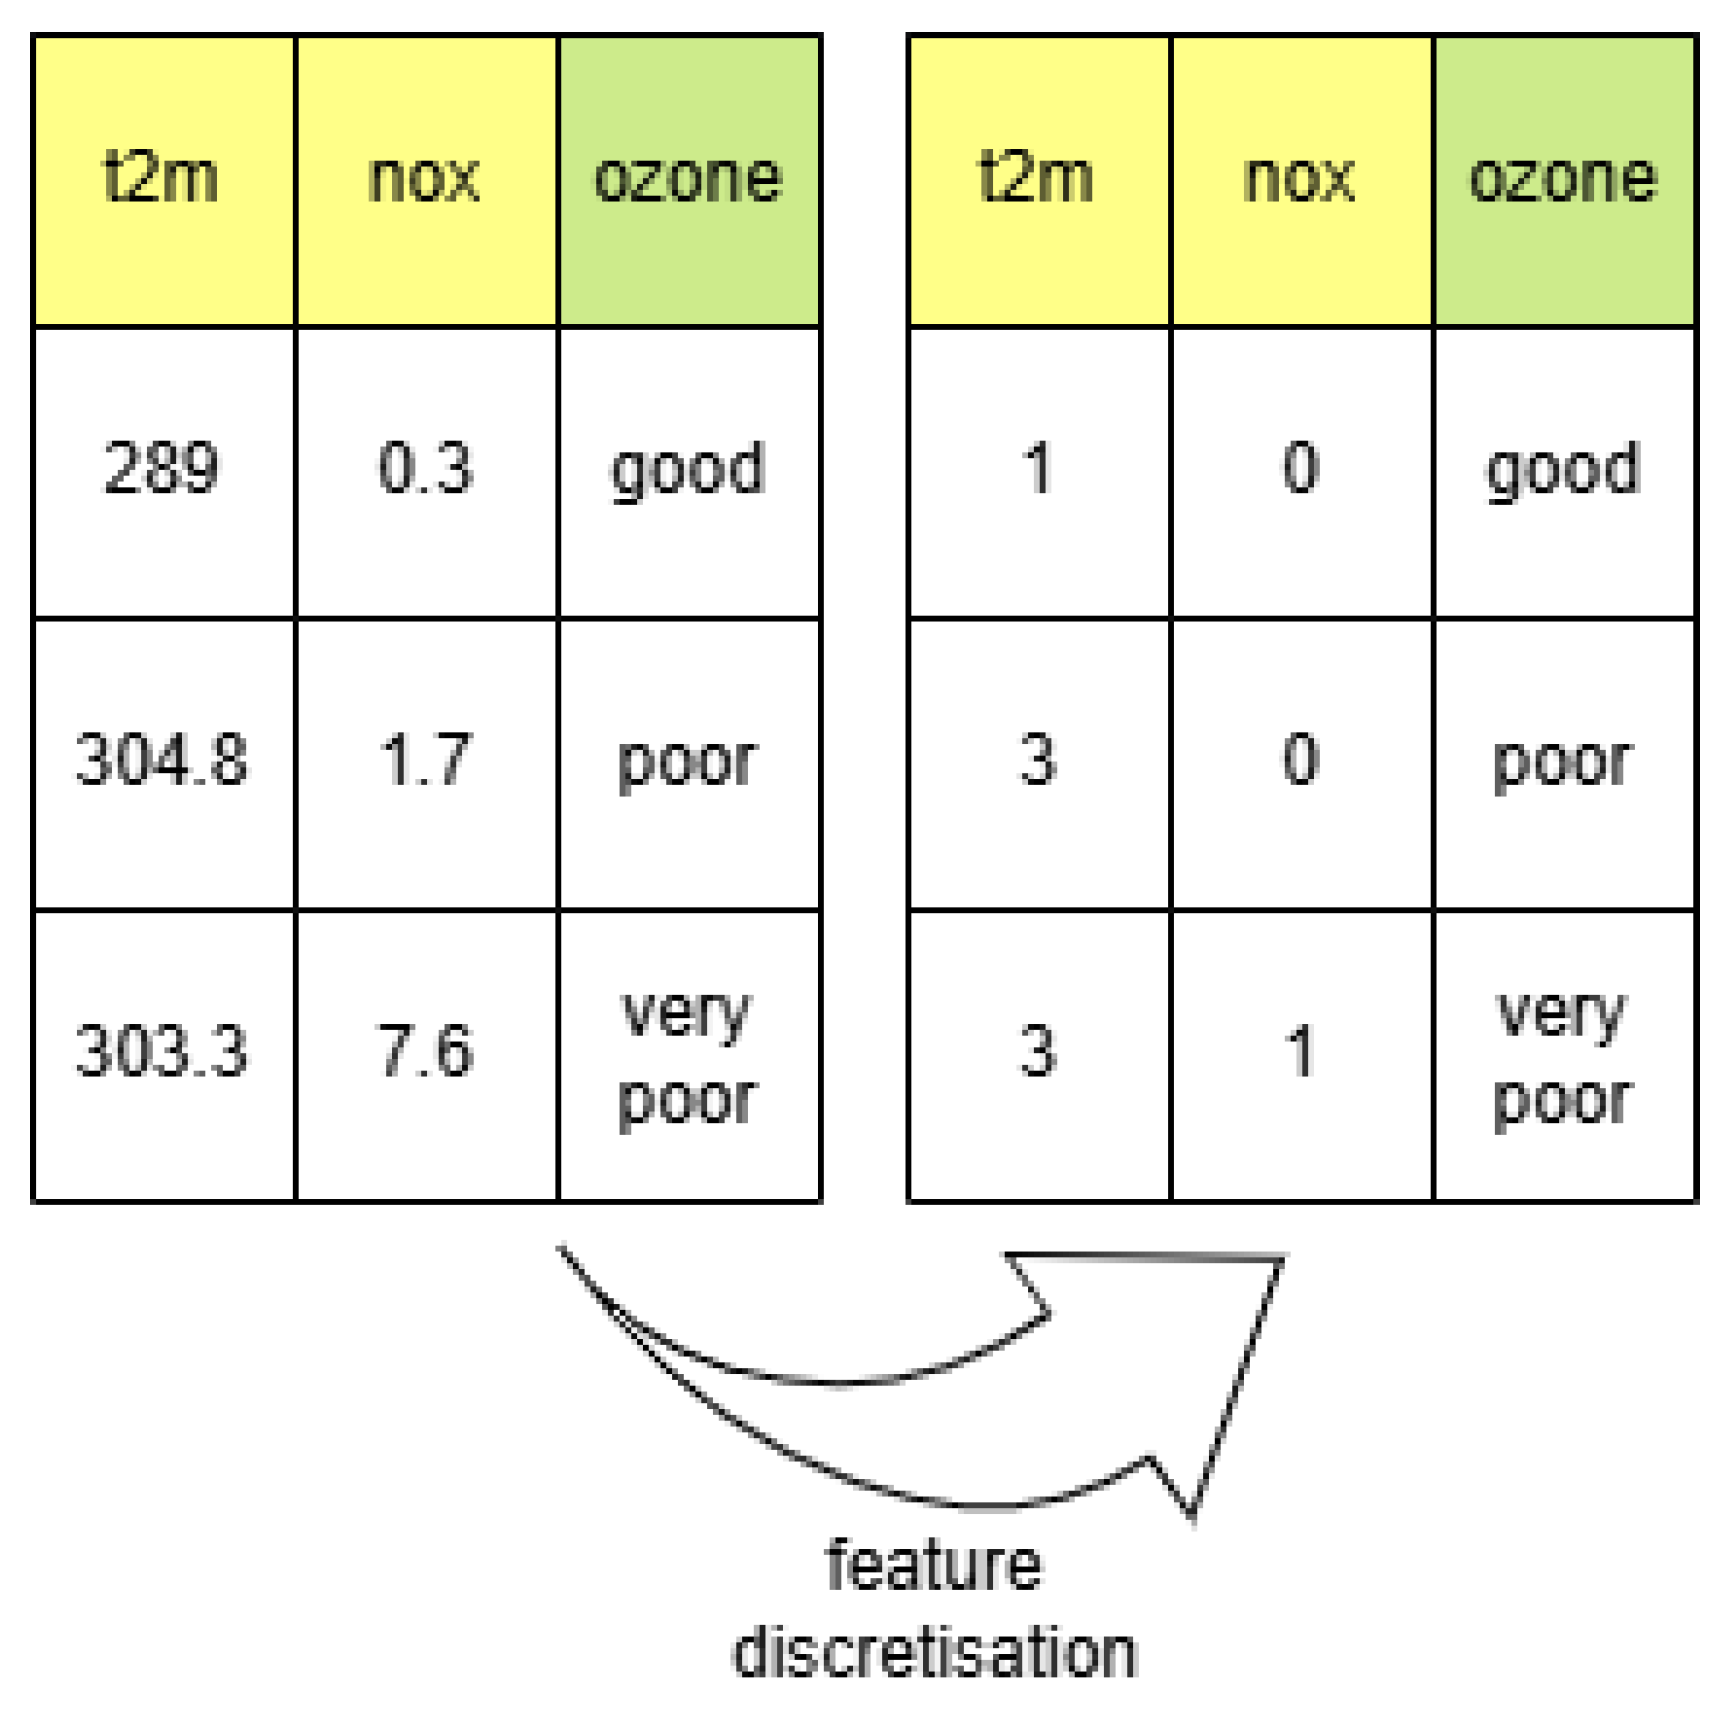
As shown in Figure 4, ozone values were split into six classes according to the European Environment Agency classification (https://www.eea.europa.eu/en/analysis/maps-and-charts/index, accessed on 8 August 2026):
  • Good—if ozone concentration < 61 μg m−3.
  • Fair—if 61 μg m−3 ≤ ozone concentration < 101 μg m−3.
  • Moderate—if 101 μg m−3 ≤ ozone concentration < 121 μg m−3.
  • Poor—if 121 μg m−3 ≤ ozone concentration < 161 μg m−3.
  • Very poor—if 161 μg m−3 ≤ ozone concentration < 181 μg m−3.
  • Extremely poor—if ozone concentration ≥ 181μg m−3.
Figure 4. Target variable discretization: numerical ozone concentrations are replaced by their corresponding class labels. t2m: air temperature at 2 m above ground level (K); nox: nitrogen oxide (NO and NO2) concentrations (μg m−3); ozone: ground-level ozone concentration (μg m−3).
Atmosphere 17 00798 g004
By applying European standards, this work relies on the common ground shared by the countries in the European Union (EU); hence, it can be compared to other work or air quality reports produced inside the EU.

2.3.3. Discretization of the Input Features

To perform the actual mining, every numeric feature must be split into different categories, i.e., continuous values must be discretized into bins, as illustrated in Figure 5.
Each bin has edges that define the category it represents, e.g., bin “400_500” has two edges, 400 and 500, and contains every observation whose feature value is between 400 and 500. To discretize each feature, the distribution of its values is analysed for each ozone class. Throughout the remainder of this paper, the term range refers to the set of values that a feature can take in the dataset.
By examining the value range of each feature across the different ozone classes, appropriate discretization categories are manually defined to facilitate ozone concentration prediction. To determine the most appropriate discretization, several commonly used discretization methods were evaluated before selecting the proposed strategy:
  • Uniform: data are discretized by cutting the range into equal-value spaces.
  • Quartiles: data are discretized by cutting the range into n bins, such that each bin contains the same number of observations.
  • K-Means: data are discretized by cutting the range into n bins, such that each observation in a bin has a value not too far from the mean value of the bin.
However, none of these methods achieved a predictive performance comparable to that of the proposed manual discretization. Although the discretization process is largely empirical, it follows a number of guiding principles. The main rules of thumb used to define the bin boundaries are presented below.
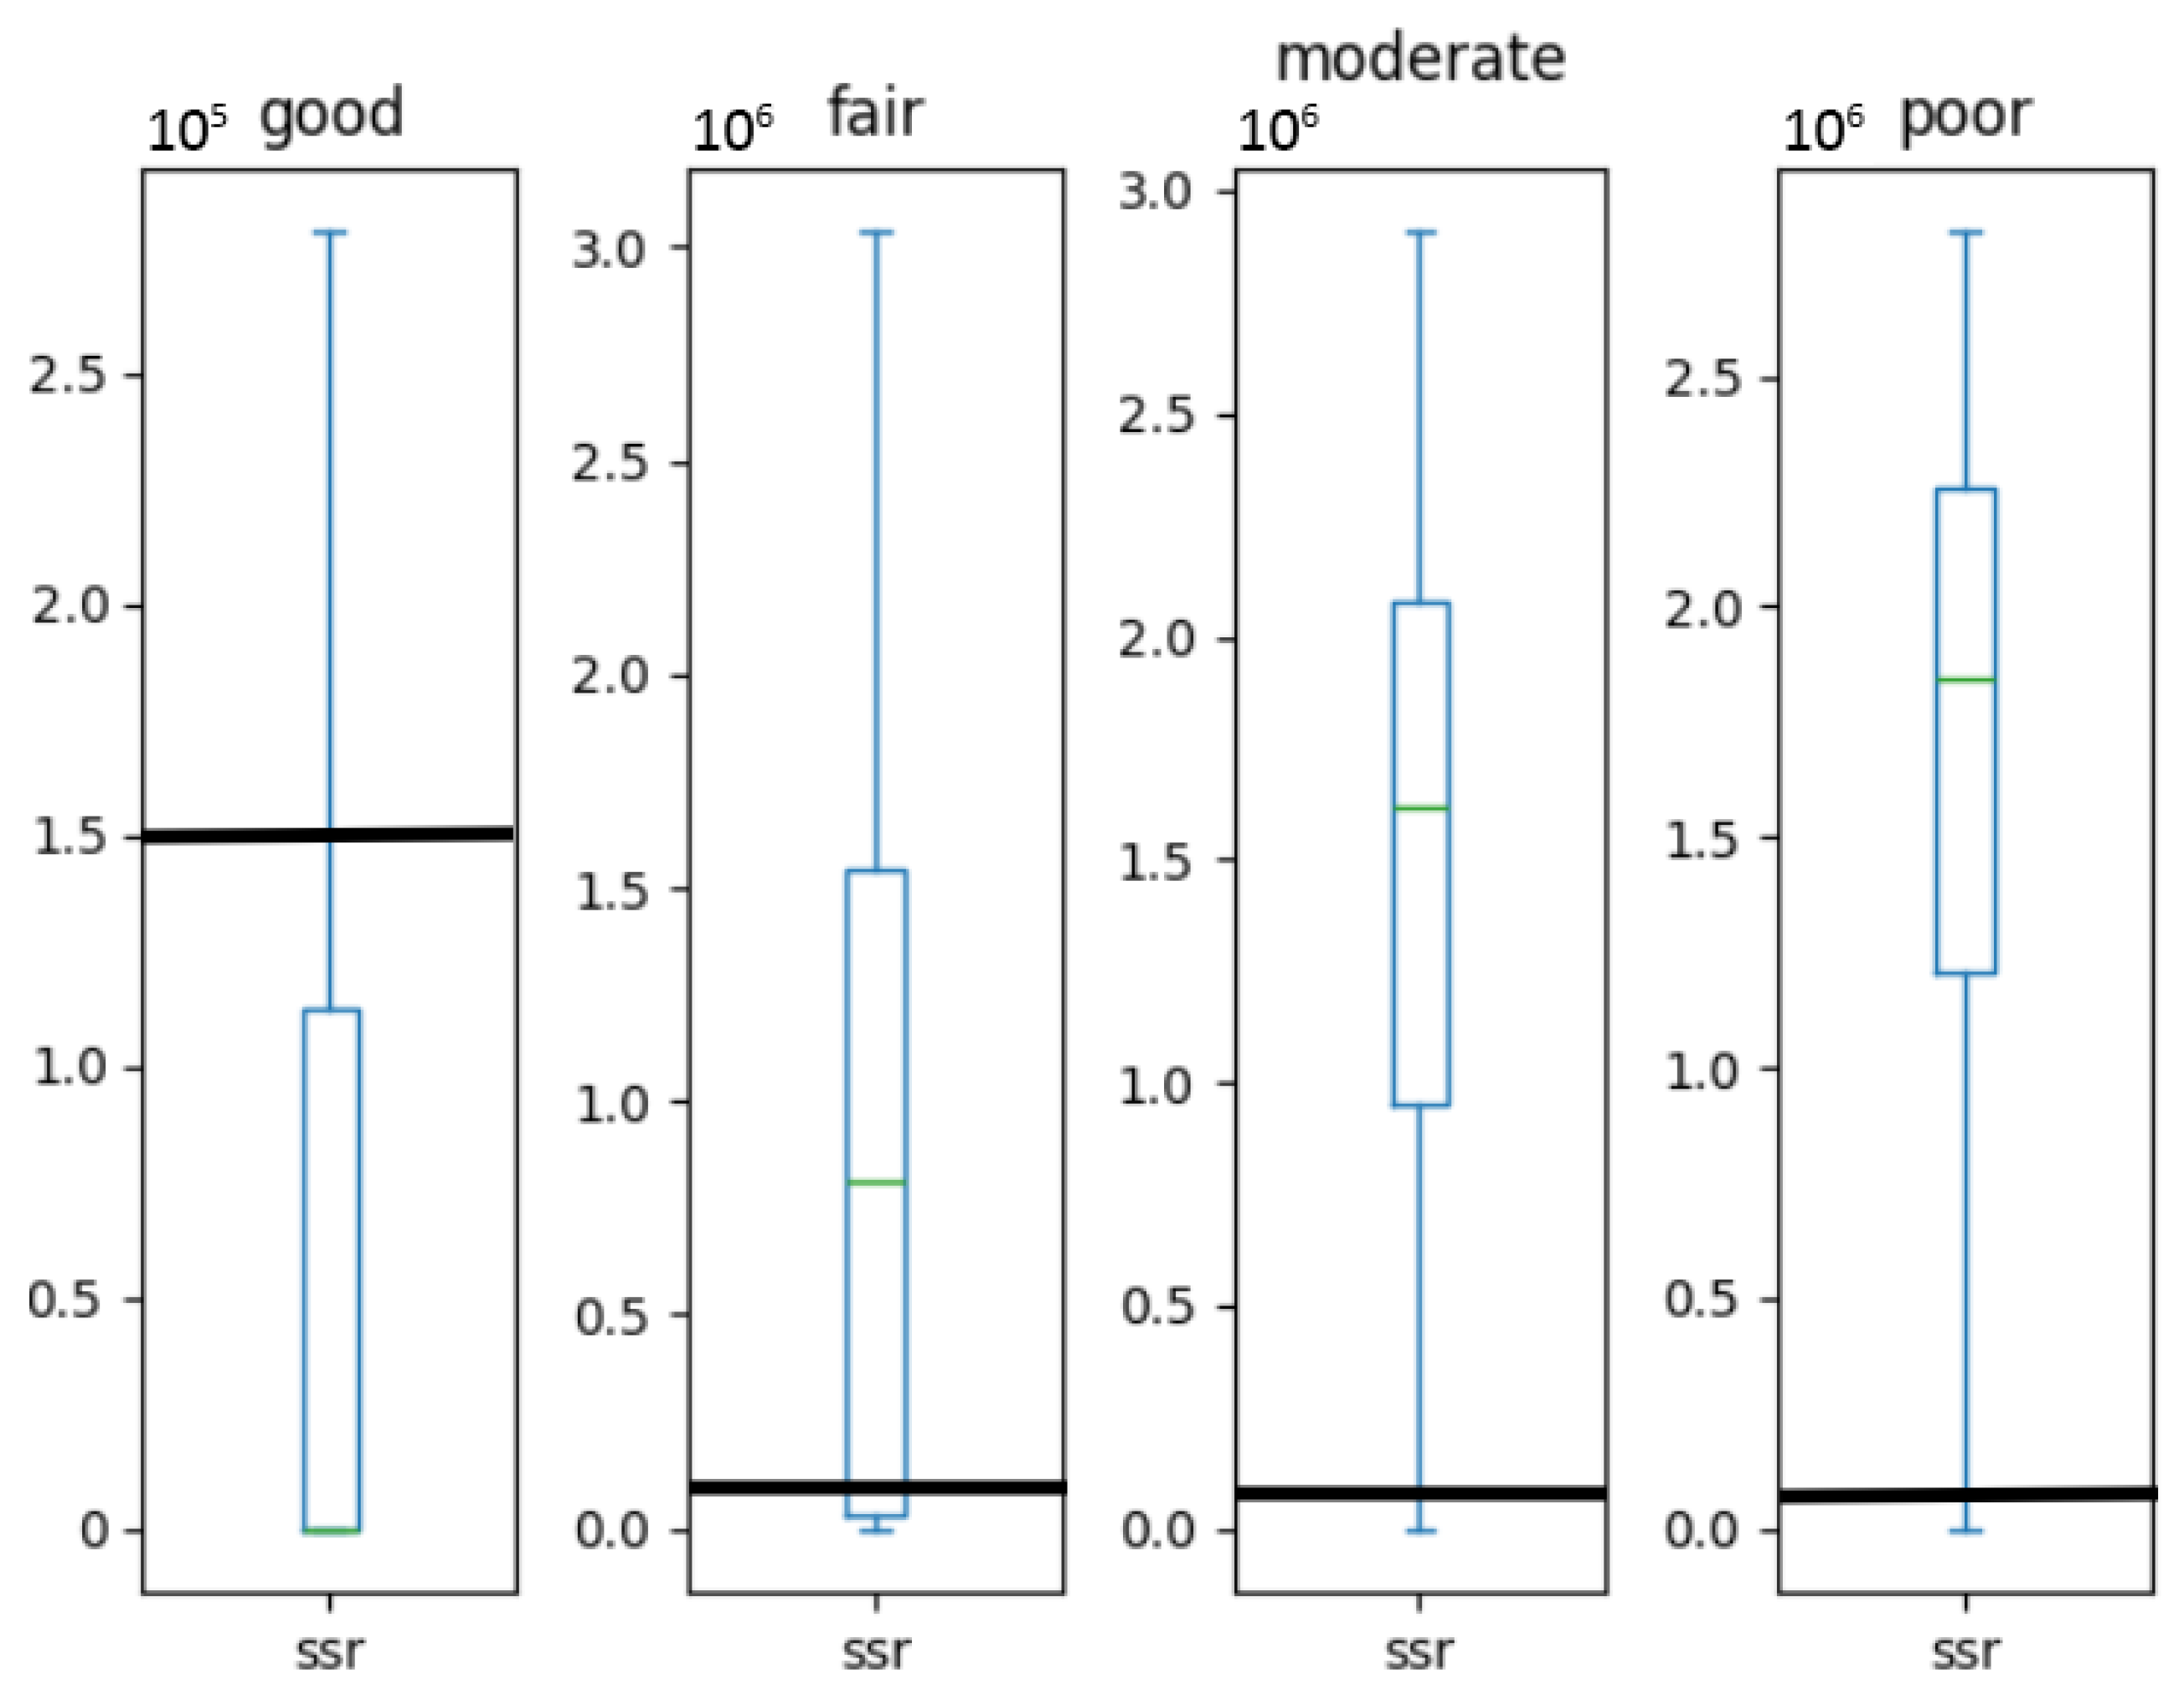
  • If approximately 75% of the observations within a given value range belong to the same ozone class, that range is considered sufficiently discriminative to define a dedicated bin, as illustrated in Figure 6.
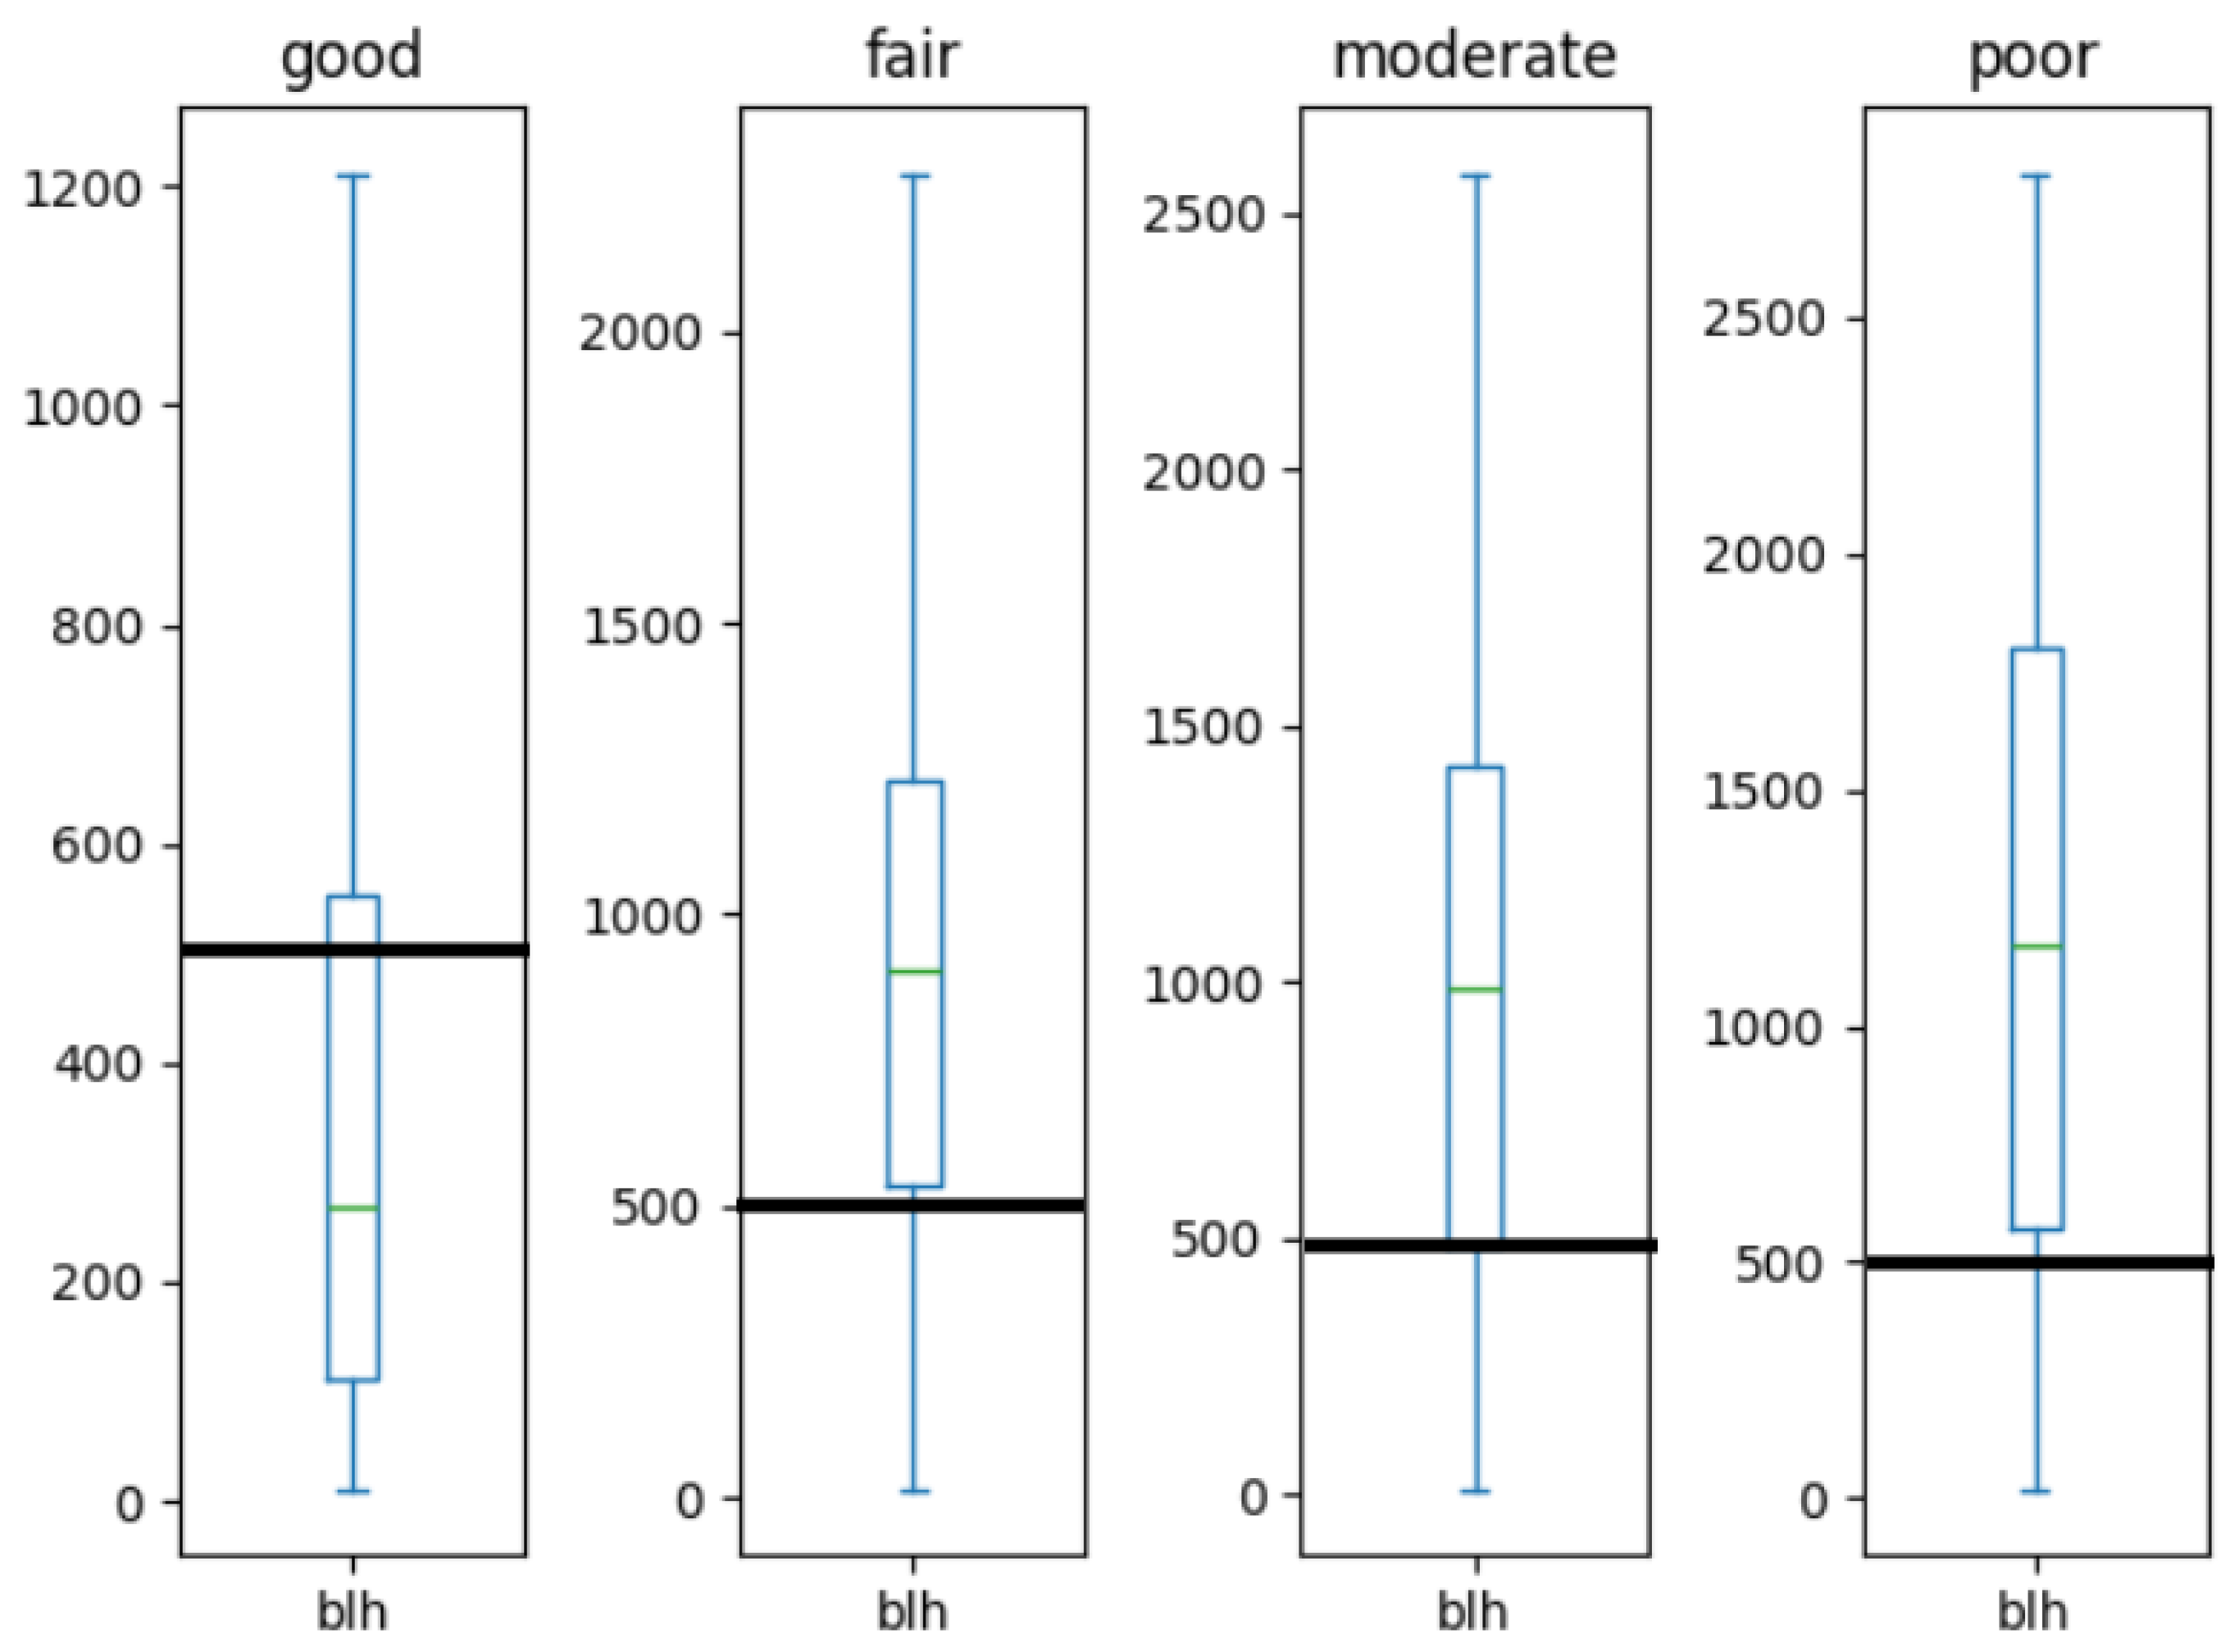
  • If a value interval contains the vast majority (approximately 75%) of the observations belonging to a given ozone class, while containing only a few observations from the remaining classes, the interval is considered sufficiently discriminative to define a bin boundary. Figure 7 illustrates this principle: for the blh feature, nearly all observations from the good ozone class are below 500, whereas relatively few observations from the other ozone classes fall within this interval.
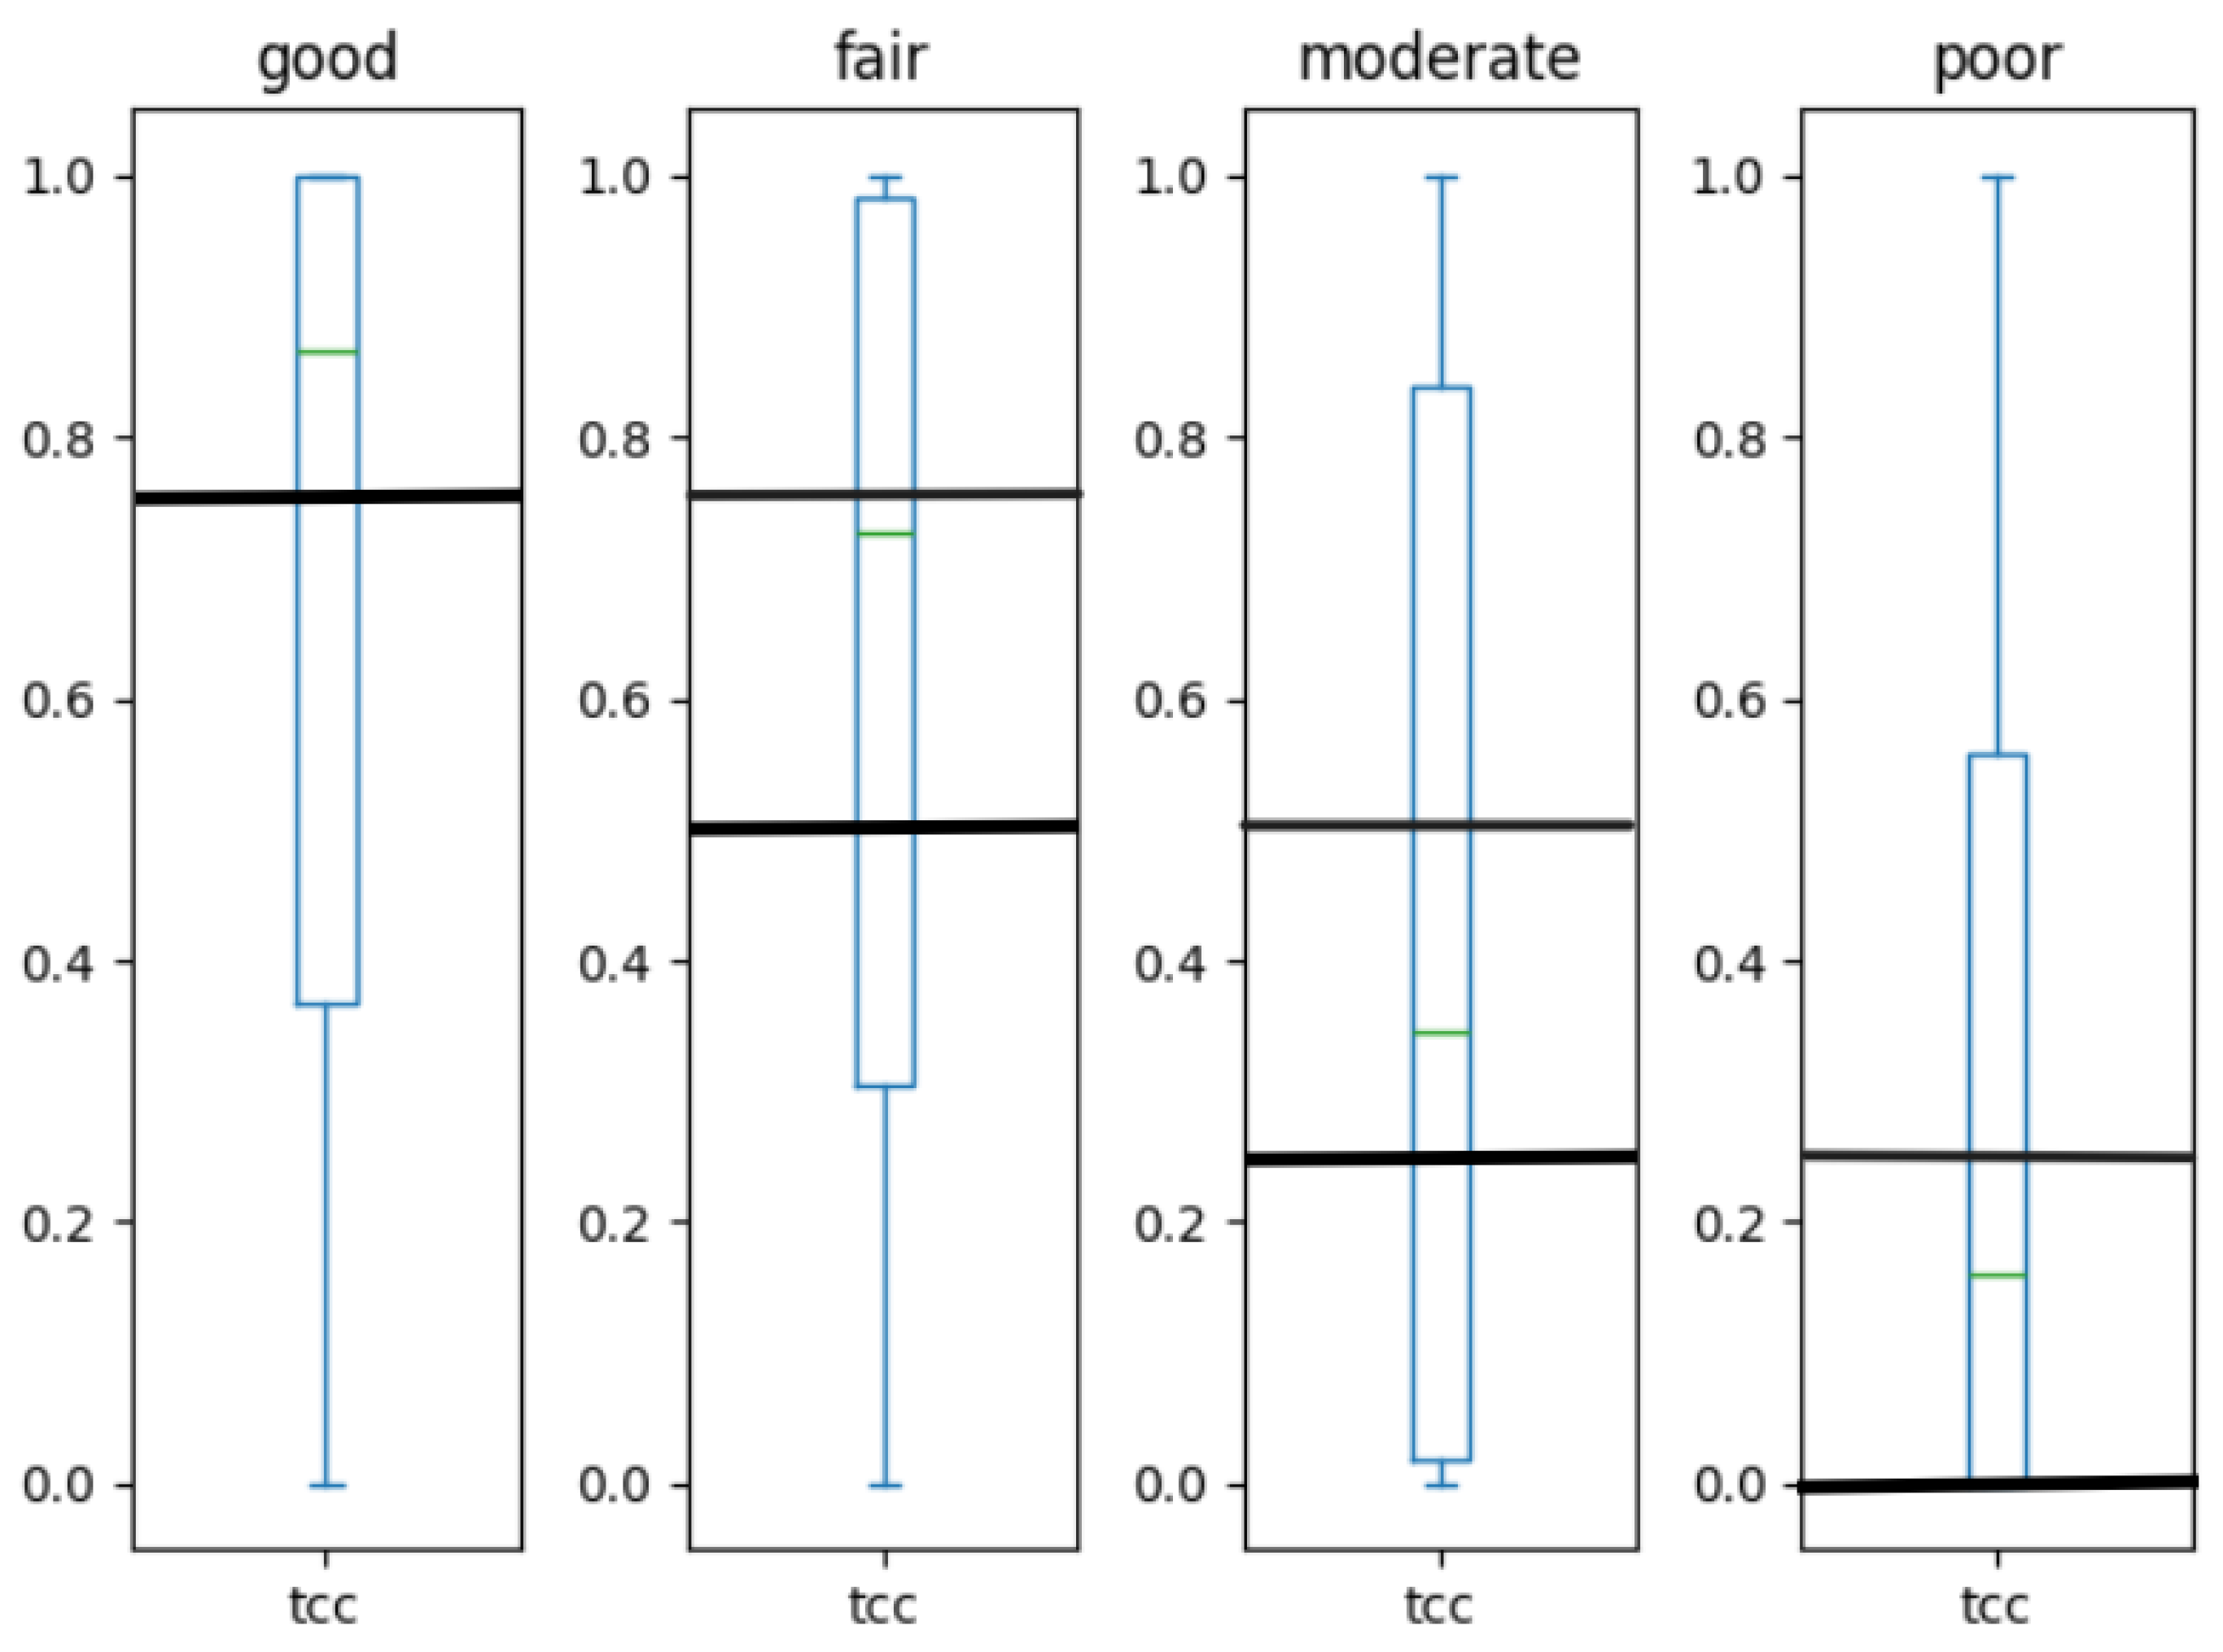
  • If the first two criteria do not identify sufficiently discriminative thresholds, the bin boundaries are defined using the medians of the ozone classes. Figure 8 illustrates this principle. Medians are preferred over means because they provide a robust estimate of the central tendency of each class while being less sensitive to extreme observations, which are common in atmospheric data. Using class medians ensures that each ozone class is represented by the central value of the feature space, thereby improving the discriminative ability to extract association rules.

2.3.4. Feature Labelling

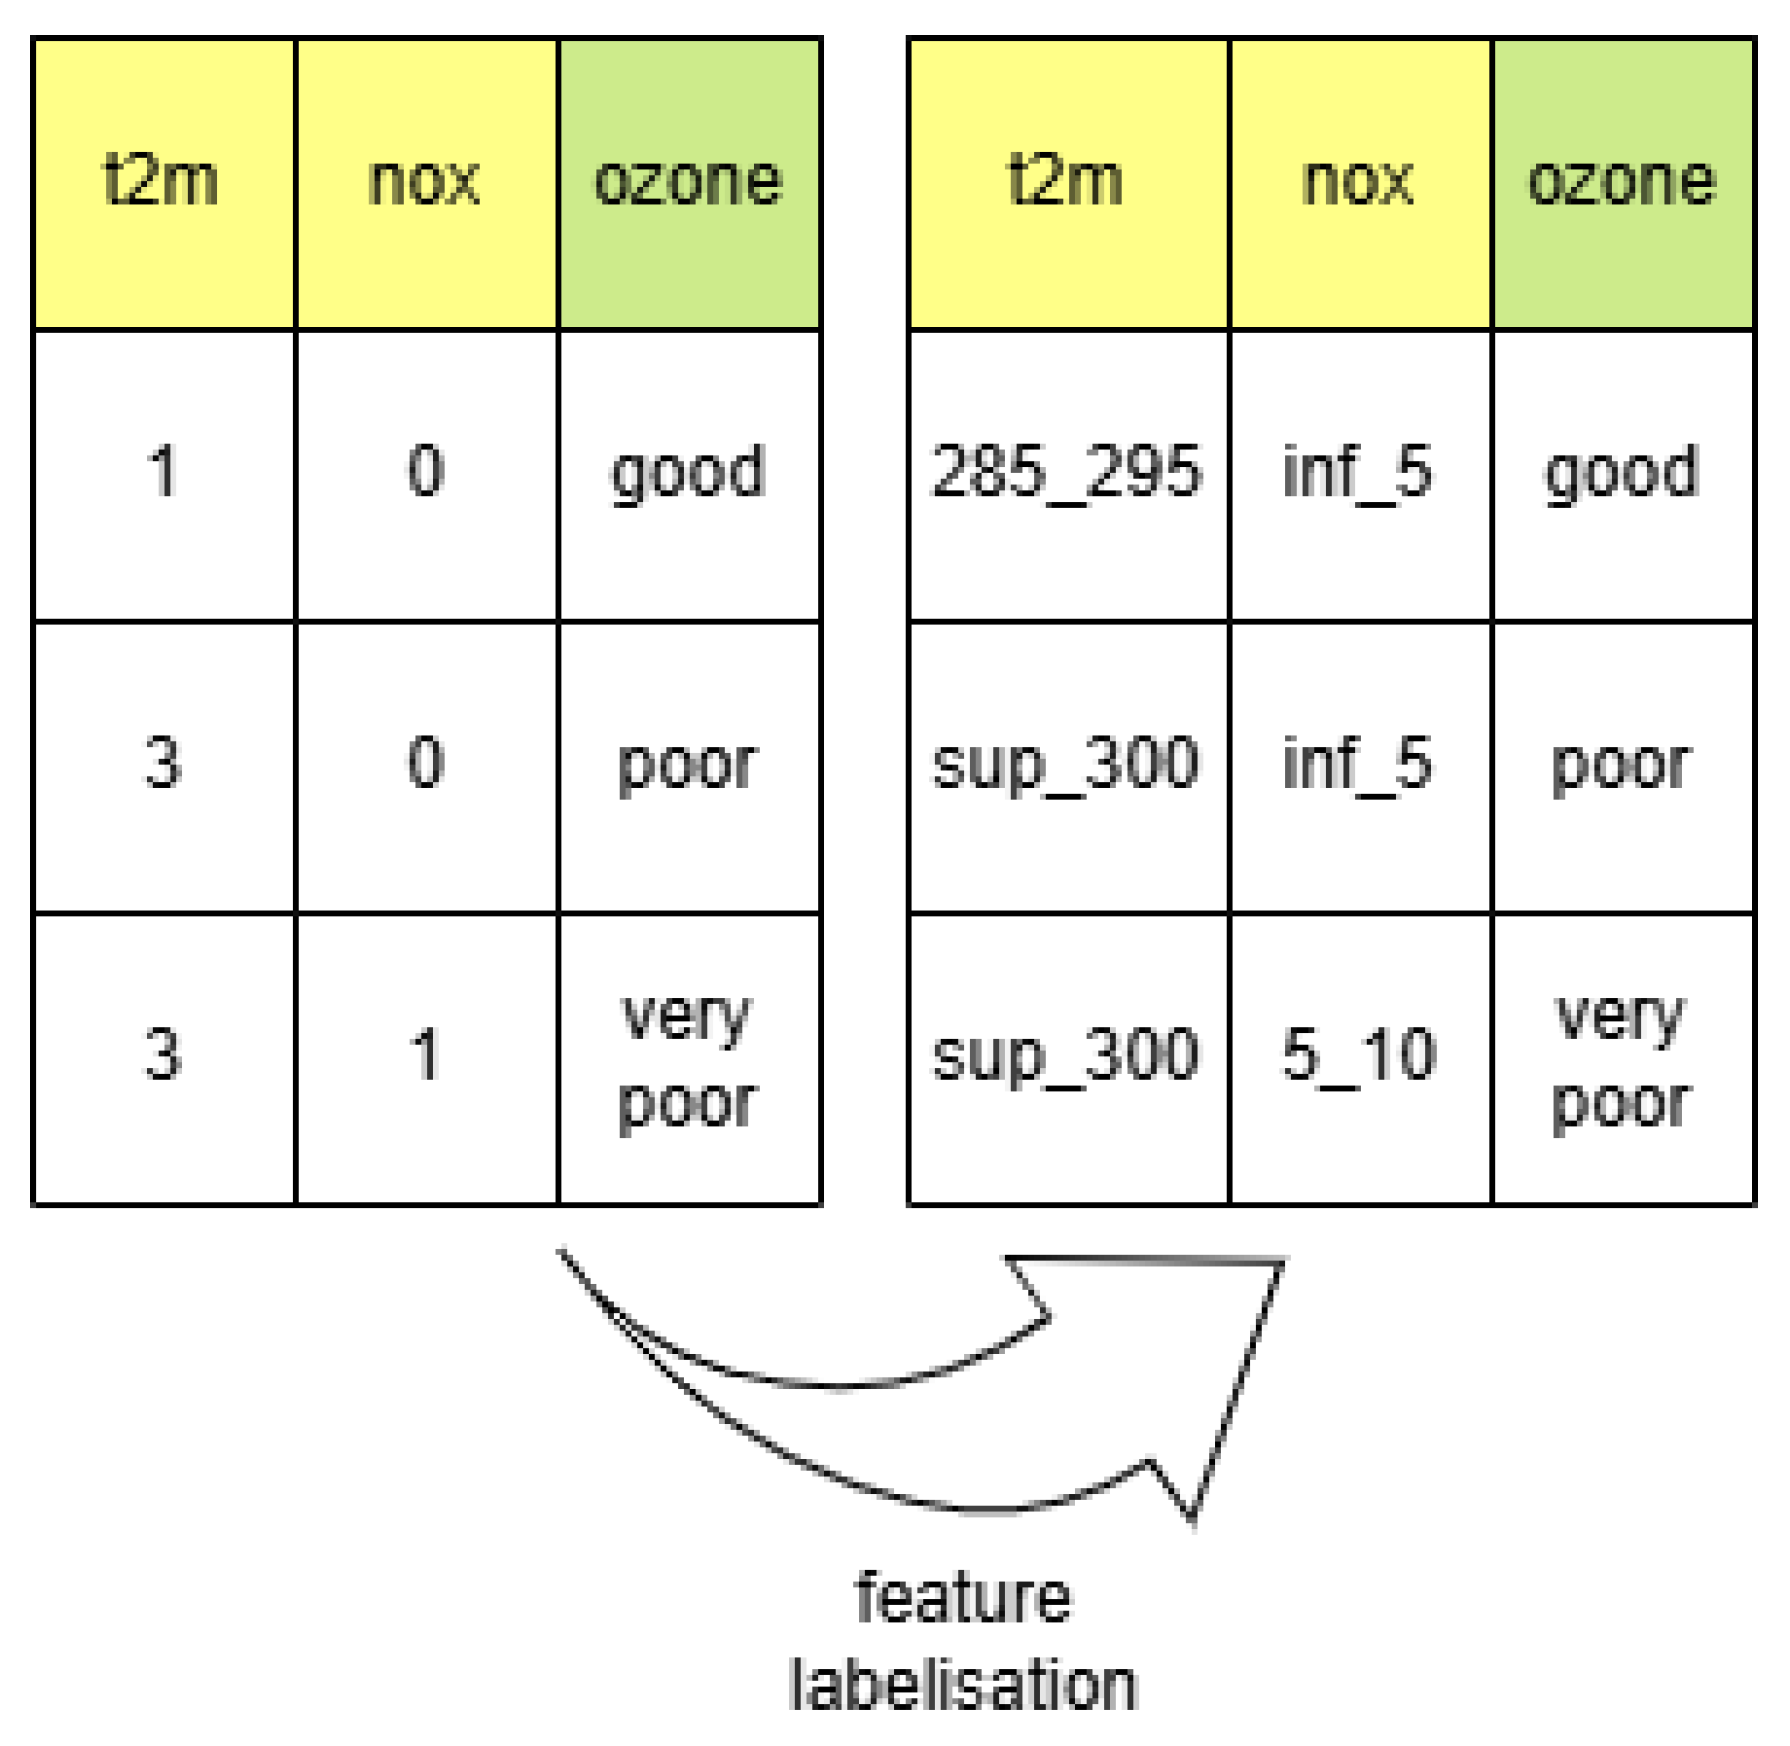
Continuous values are replaced by categorical labels indicating the interval to which they belong. Labels are constructed using the format “lowerBound_upperBound”, for example, “400_500”. However, to improve readability and simplify the parsing of the data, a few conventions are adopted:
  • A k means the value must be multiplied by 1000: “4k_5k” means the original value is between 4000 and 5000.
  • An m means the value must be multiplied by 10 6 : “4m_5m” means the original value is between 4 × 10 6 and 5 × 10 6 .
  • An n means the value is negative: “n5_n4” means the original value is between −5 and −4.
  • An x is used to replace the commas: “0x5_0x75” means the original value is between 0.5 and 0.75.
  • If there is no lower bound, inf indicates the lower bound. Similarly, if there is no upper bound, it is indicated by sup, e.g., “inf_4” means the original value is below 4 and “sup_5” means the original value is above 5.
The feature labelling step is illustrated in Figure 9.
This step is not required for the prediction task itself. However, it is essential to achieve the objective of producing human-readable rules that can be used to explain the model’s predictions. Overall, the proposed discretization strategy was designed as a supervised, knowledge-guided preprocessing step whose objective is to maximize the discriminative power for association rule extraction. During the development of the framework, numerous preliminary experiments were conducted by varying the discretization boundaries, the number of bins, and alternative preprocessing configurations. The final preprocessing strategy was retained because it consistently provided the best compromise between predictive performance, rule interpretability, statistical representativeness, and computational efficiency. Although a formal sensitivity analysis is beyond the scope of the present work, systematically evaluating the influence of preprocessing parameters will constitute an important direction for future research.

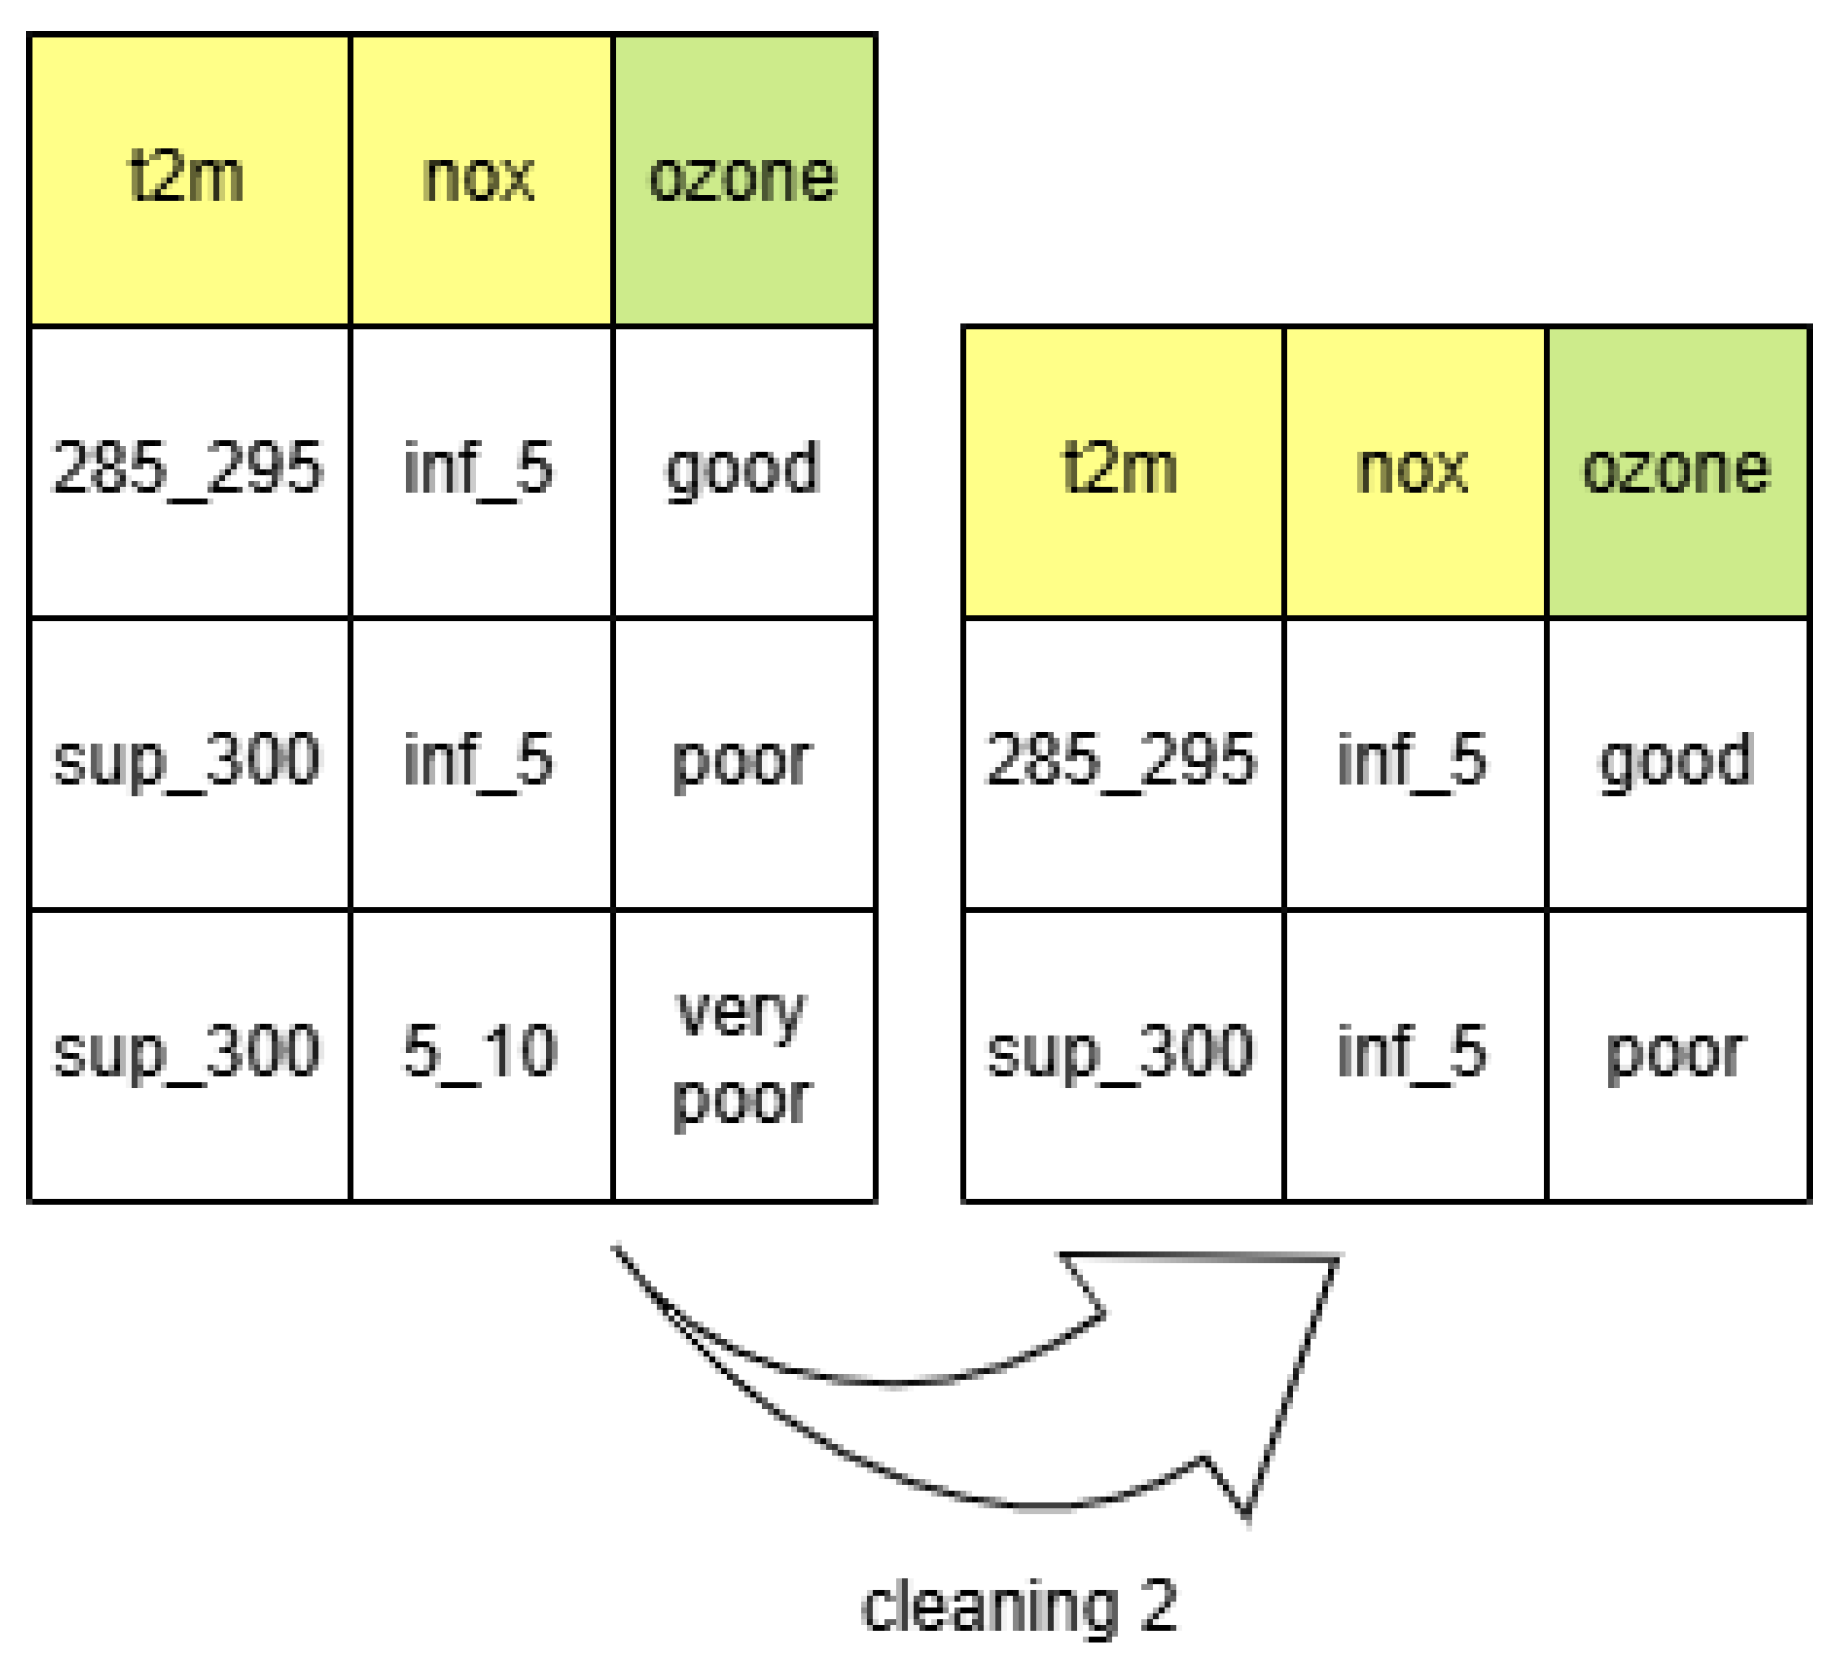
2.4. Final Data Cleaning and Class Balancing

Once the dataset contains only categorical values, any feature containing a single unique value is removed, as it does not provide any discriminative information. In the current dataset, no such feature is found, since every feature contains more than one distinct value.
To ensure that each ozone class is represented by a sufficient number of observations, the number of observations belonging to each class is computed. Classes represented by fewer than 2000 observations are considered too small to support reliable model training and evaluation. Consequently, all observations belonging to these classes are removed from the dataset.
In the current dataset, the very poor and extremely poor ozone classes contain fewer than 2000 observations and are therefore excluded from the study. The remainder of this paper consequently focuses on the good, fair, moderate, and poor ozone classes. This final data cleaning and class balancing step is illustrated in Figure 10.
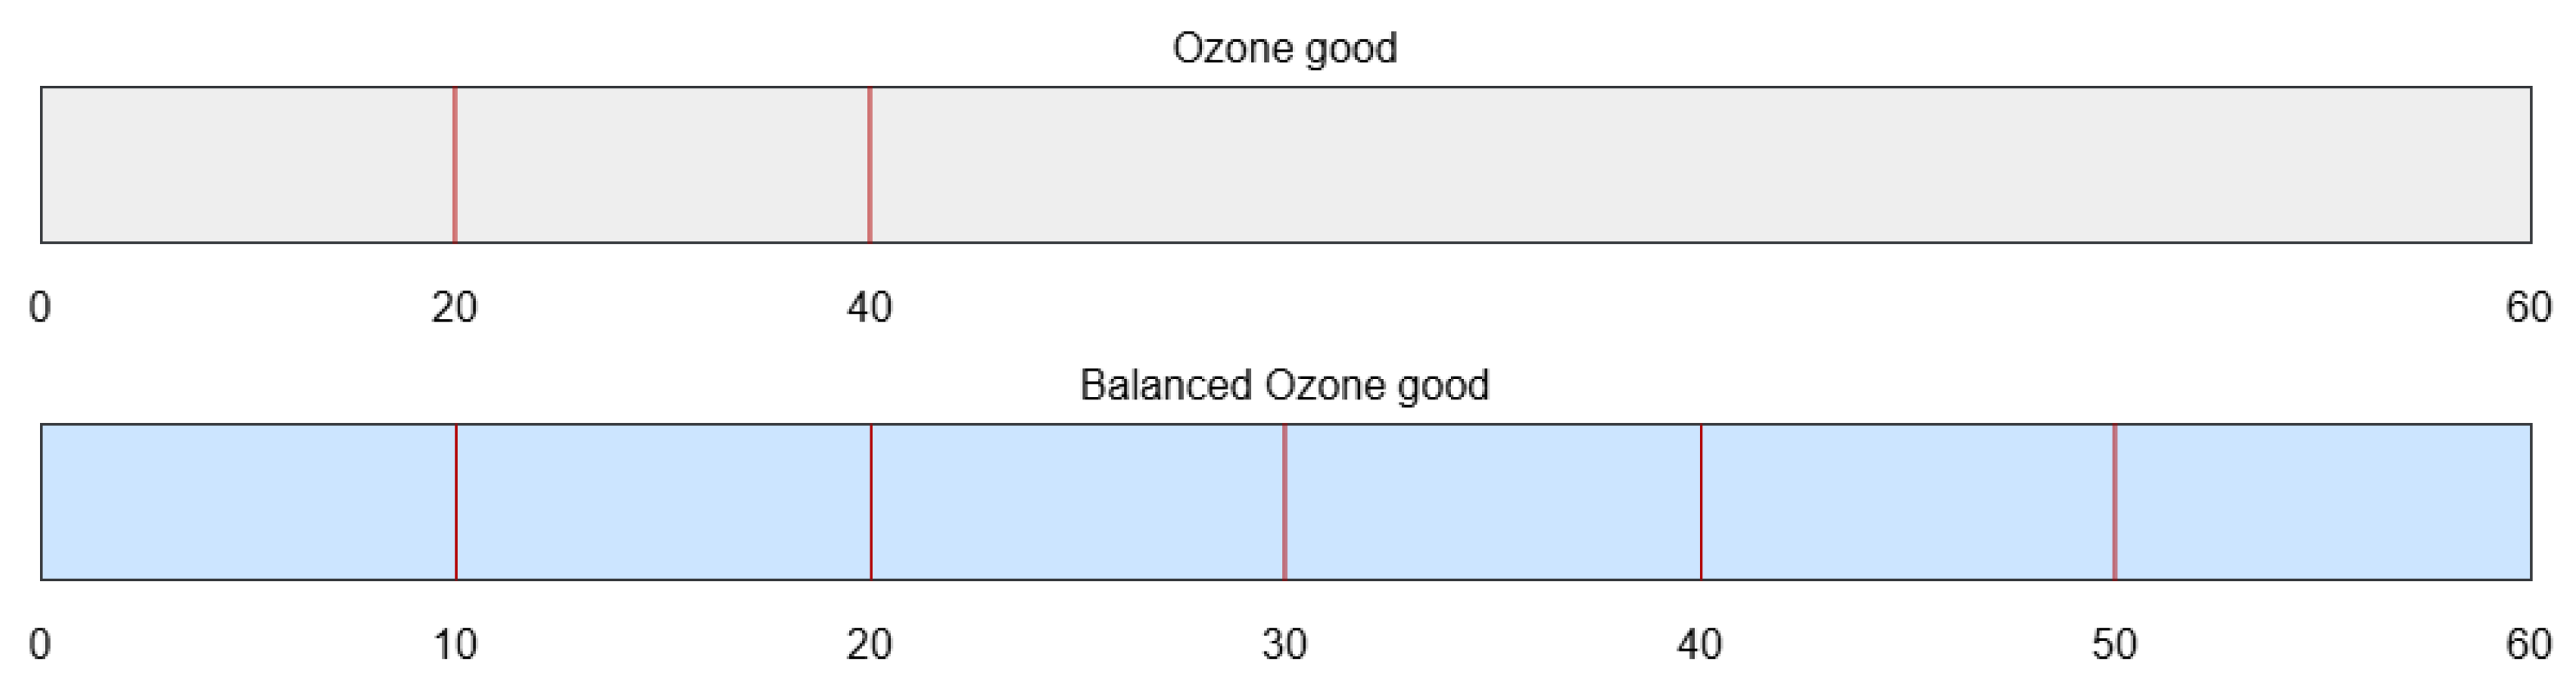
Finally, the preprocessing ends with a step of undersampling for each ozone class, i.e., for each ozone class, there is diversity in the values, e.g., for the good ozone class, there must be as many observations between 0 and 10 μg m−3 as there are between 40 and 50 μg m−3. In fact, rules must be mined efficiently for any feature value. Therefore, to eliminate statistical biases, there must be an intra-class balance in the dataset. To balance the dataset, each range of values inside ozone class is cut into bins; then, the same number of observations is taken in each bin, as illustrated in Figure 11. The amount taken in each bin is equal to the smallest amount available in one of the obtained bin. To define the edges of the bins, rules of thumb have been specified to ensure each bin has a significant amount of observations, i.e., there are not too many bins, as that would have made bins semantically meaningless, but there are enough to cover the whole range. To preserve intra-class variability while maintaining a sufficient number of observations in each interval, the number of bins was adapted to the concentration range of each ozone class. The “good” class spans the largest interval (0–60 μg m−3) and was therefore divided into six bins of 10 μg m−3. The remaining classes cover narrower concentration ranges and were divided into four bins, which provided a satisfactory compromise between interval resolution and statistical representativeness for rule extraction. The cutting bins are as follows:
  • The “good” ozone class is cut into 6 bins with a step of 10 between each bin (i.e., from 0 to 10, 10 to 20, 20 to 30, 30 to 40, 40 to 50 and 50 to 60).
  • The “fair” ozone class is cut into 4 bins with a step of 10 between each bin (i.e., from 60 to 70, 70 to 80, 80 to 90 and 90 to 100).
  • The “moderate” ozone class is cut into 4 bins with a step of 5 between each bin (i.e., from 100 to 105, 105 to 110, 110 to 115 and 115 to 120).
  • The “poor” ozone class is cut into 4 bins with a step of 10 between each bin (i.e., from 120 to 130, 130 to 140, 140 to 150 and 150 to 160).
Figure 11. Intra-class undersampling.
Atmosphere 17 00798 g011
This ends the preprocessing steps to build the whole dataset. It can now be split into training and testing datasets for both the mining and prediction tasks with different models. In fact, two datasets are now created: a training dataset from which models will learn and a testing dataset on which models will predict.
To eliminate statistical biases and ensure correct predictions in any case, an inter-class balance must be ensured, i.e., there should be as many observations of the “good” ozone class as there are of the “poor” ozone class. Otherwise, a model that predicts mostly “good” ozone labels will be mostly right while being unable to detect the ozone peaks belonging to the “poor” ozone class, as those events are rare in the initial data. Since the model must be used in health-related applications, it must efficiently predict any ozone class, regardless of how rare they are. That is why inter-class balance is important. Since there are not many observations from the “poor” ozone class (1428) after preprocessing, it has been decided to randomly take 1000 observations from each ozone class to create the training dataset. This amount of observation is a good trade-off between statistical representativeness for each ozone class and performance for the mining task. This configuration was selected after preliminary experiments evaluating different class sizes and sampling strategies. It provided the most satisfactory balance between computational cost, statistical representativeness, and predictive performance for the symbolic rule-mining process. Similarly, 400 observations were randomly selected from each ozone class to create the testing dataset. The models can now be trained and rules can be extracted from the training dataset before the prediction task. To ensure the explainability of the predictions, symbolic AI with rule-based models will be used. They will then be compared to simpler sub-symbolic AI models to identify the gains and drawbacks of the different models. Below, both approaches are presented with a quick overview of the used models and methods.

2.5. AI Methods

2.5.1. Sub-Symbolic AI Methods

Sub-symbolic methods, as defined in [41], include black-box clustering and classification algorithms. These methods generally lack intrinsic interpretability, meaning that the reasoning underlying their predictions cannot be directly understood. Consequently, it is not possible to explain why a given sample is assigned to a particular class without relying on additional post hoc explanation techniques. Four black-box benchmark models have been implemented in Python with the scikit-learn library (https://scikit-learn.org/stable/index.html, accessed on 9 August 2026, version 1.8.0): Support Vector Machine (SVM), CatBoost, RandomForest, and Convolutional Neural Network (CNN). Although CNNs are commonly associated with spatially structured data, they have also been successfully applied to large tabular and time-series datasets [42]. Given the large volume of observations available in this study, we considered it worthwhile to include a CNN among the benchmark models and evaluate its predictive performance. So, these methods are the most used in similar contexts, i.e., pollutant prediction in atmospheric prediction, and have already shown good results [43].
The implementation details of each black-box benchmark model are provided below:
  • SVM has been implemented by instantiating an SVC class from the scikit-learn 1.8.0 library with the value ‘linear’ for the parameter ‘kernel’.
  • CatBoost has been implemented by instantiating the CatBoostClassifier class from the scikit-learn 1.8.0 library. The different parameter values have been selected from previous work in a similar context [32], namely: 100 iterations, a depth of 3, a learning rate of 0.1 and a loss function equal to ‘MultiClass’.
  • RandomForest has been implemented with the RandomForestClassifier class from the scikit-learn 1.8.0 library with every parameter set to the default.
  • A Convolution Neural Network has been implemented with the MLPClassifier class from the scikit-learn 1.8.0 library. The parameters were selected from empirical studies. Many experiments have been conducted to find values that give good precision, recall and F1-Scores for each ozone class within a reasonable delay (a few minutes). For this work, the following parameter values have been retained: an alpha equal to 10−5, a random state of 1, a maximum iteration equal to 1000 and a number of layers equal to 5.
A more extensive comparison with additional black-box models is left for future work.
In addition, a decision tree (DT) was included as an intrinsically interpretable benchmark model for comparison with the proposed symbolic approaches. It was implemented using the DecisionTreeClassifier class from the scikit-learn library, version 1.8.0. The CART algorithm with the Gini impurity criterion was used. The remaining hyperparameters were kept at their default values, and cost complexity pruning was not applied.
The goal is to explain predictions; hence, a symbolic AI method must be implemented. It was decided to implement a rule-based method that is well suited for prediction tasks. This method is implemented in Java (java development kit version 25.0.2) with the Eclipse environment, version 4.38.0 (https://eclipseide.org/, accessed on 9 August 2026), and the InteGraal library, version 2.0.7 (https://rules.gitlabpages.inria.fr/integraal/, accessed on 9 August 2026). In order to implement such a method, it is required to extract association rules from meteorologic data.

2.5.2. Symbolic AI Methods

Symbolic methods, as defined in [41], represent data with symbols and use either algebra or logical operators to perform the prediction task. Hence, a prediction can be explained for an observation with the sequences of operators applied to the data in order to compute the prediction. To perform a prediction task while being explainable, symbolic AI must find relations in data to find an explicit link between inputs and outputs. This explicit link can be seen as an association rule that associates an input with its output through implication, e.g., temperature >285 and vertical wind >2 implies a good ozone concentration.
To mine and evaluate the quality of the association found in the data, two metrics are used: confidence and comprehension.
In this paper, the confidence of a rule is the ratio between the number of observations where both the hypotheses and consequences of the rule are present and the number of observations where the hypotheses are present. Confidence can be computed with this formula:
Confidence = n hypotheses consequent n hypotheses
If a rule is always checked, there is no observation where the hypotheses appear without the consequent. However, this case is overly optimistic, and to ensure rules also have good coverage, i.e., can be applied to many observations, rules with confidence below one are tolerated.
Comprehension, as defined in [44], evaluates how many hypotheses a rule has. The fewer hypotheses a rule has, the higher the comprehension is. For a given context, the maximum number of hypotheses that a rule can contain is denoted by n h . It corresponds to the total number of categories and intervals defined for all features. Indeed, n h is equal to the total number of categories and intervals present in the data for every feature. With this number, comprehension of a rule containing k hypotheses can be computed through the formula
Comprehension = n h k n h 1
With those metrics, association rules can be mined through two methods: Genetic Algorithm (GA) [45] and Formal Concept Analysis (FCA) [46]. Each one is implemented in Java with the Eclipse environment. The GA is implemented with the library Jenetics (https://jenetics.io/, accessed on 9 August 2026). Both GA and FCA are presented in the subsections below.
Genetic Algorithm
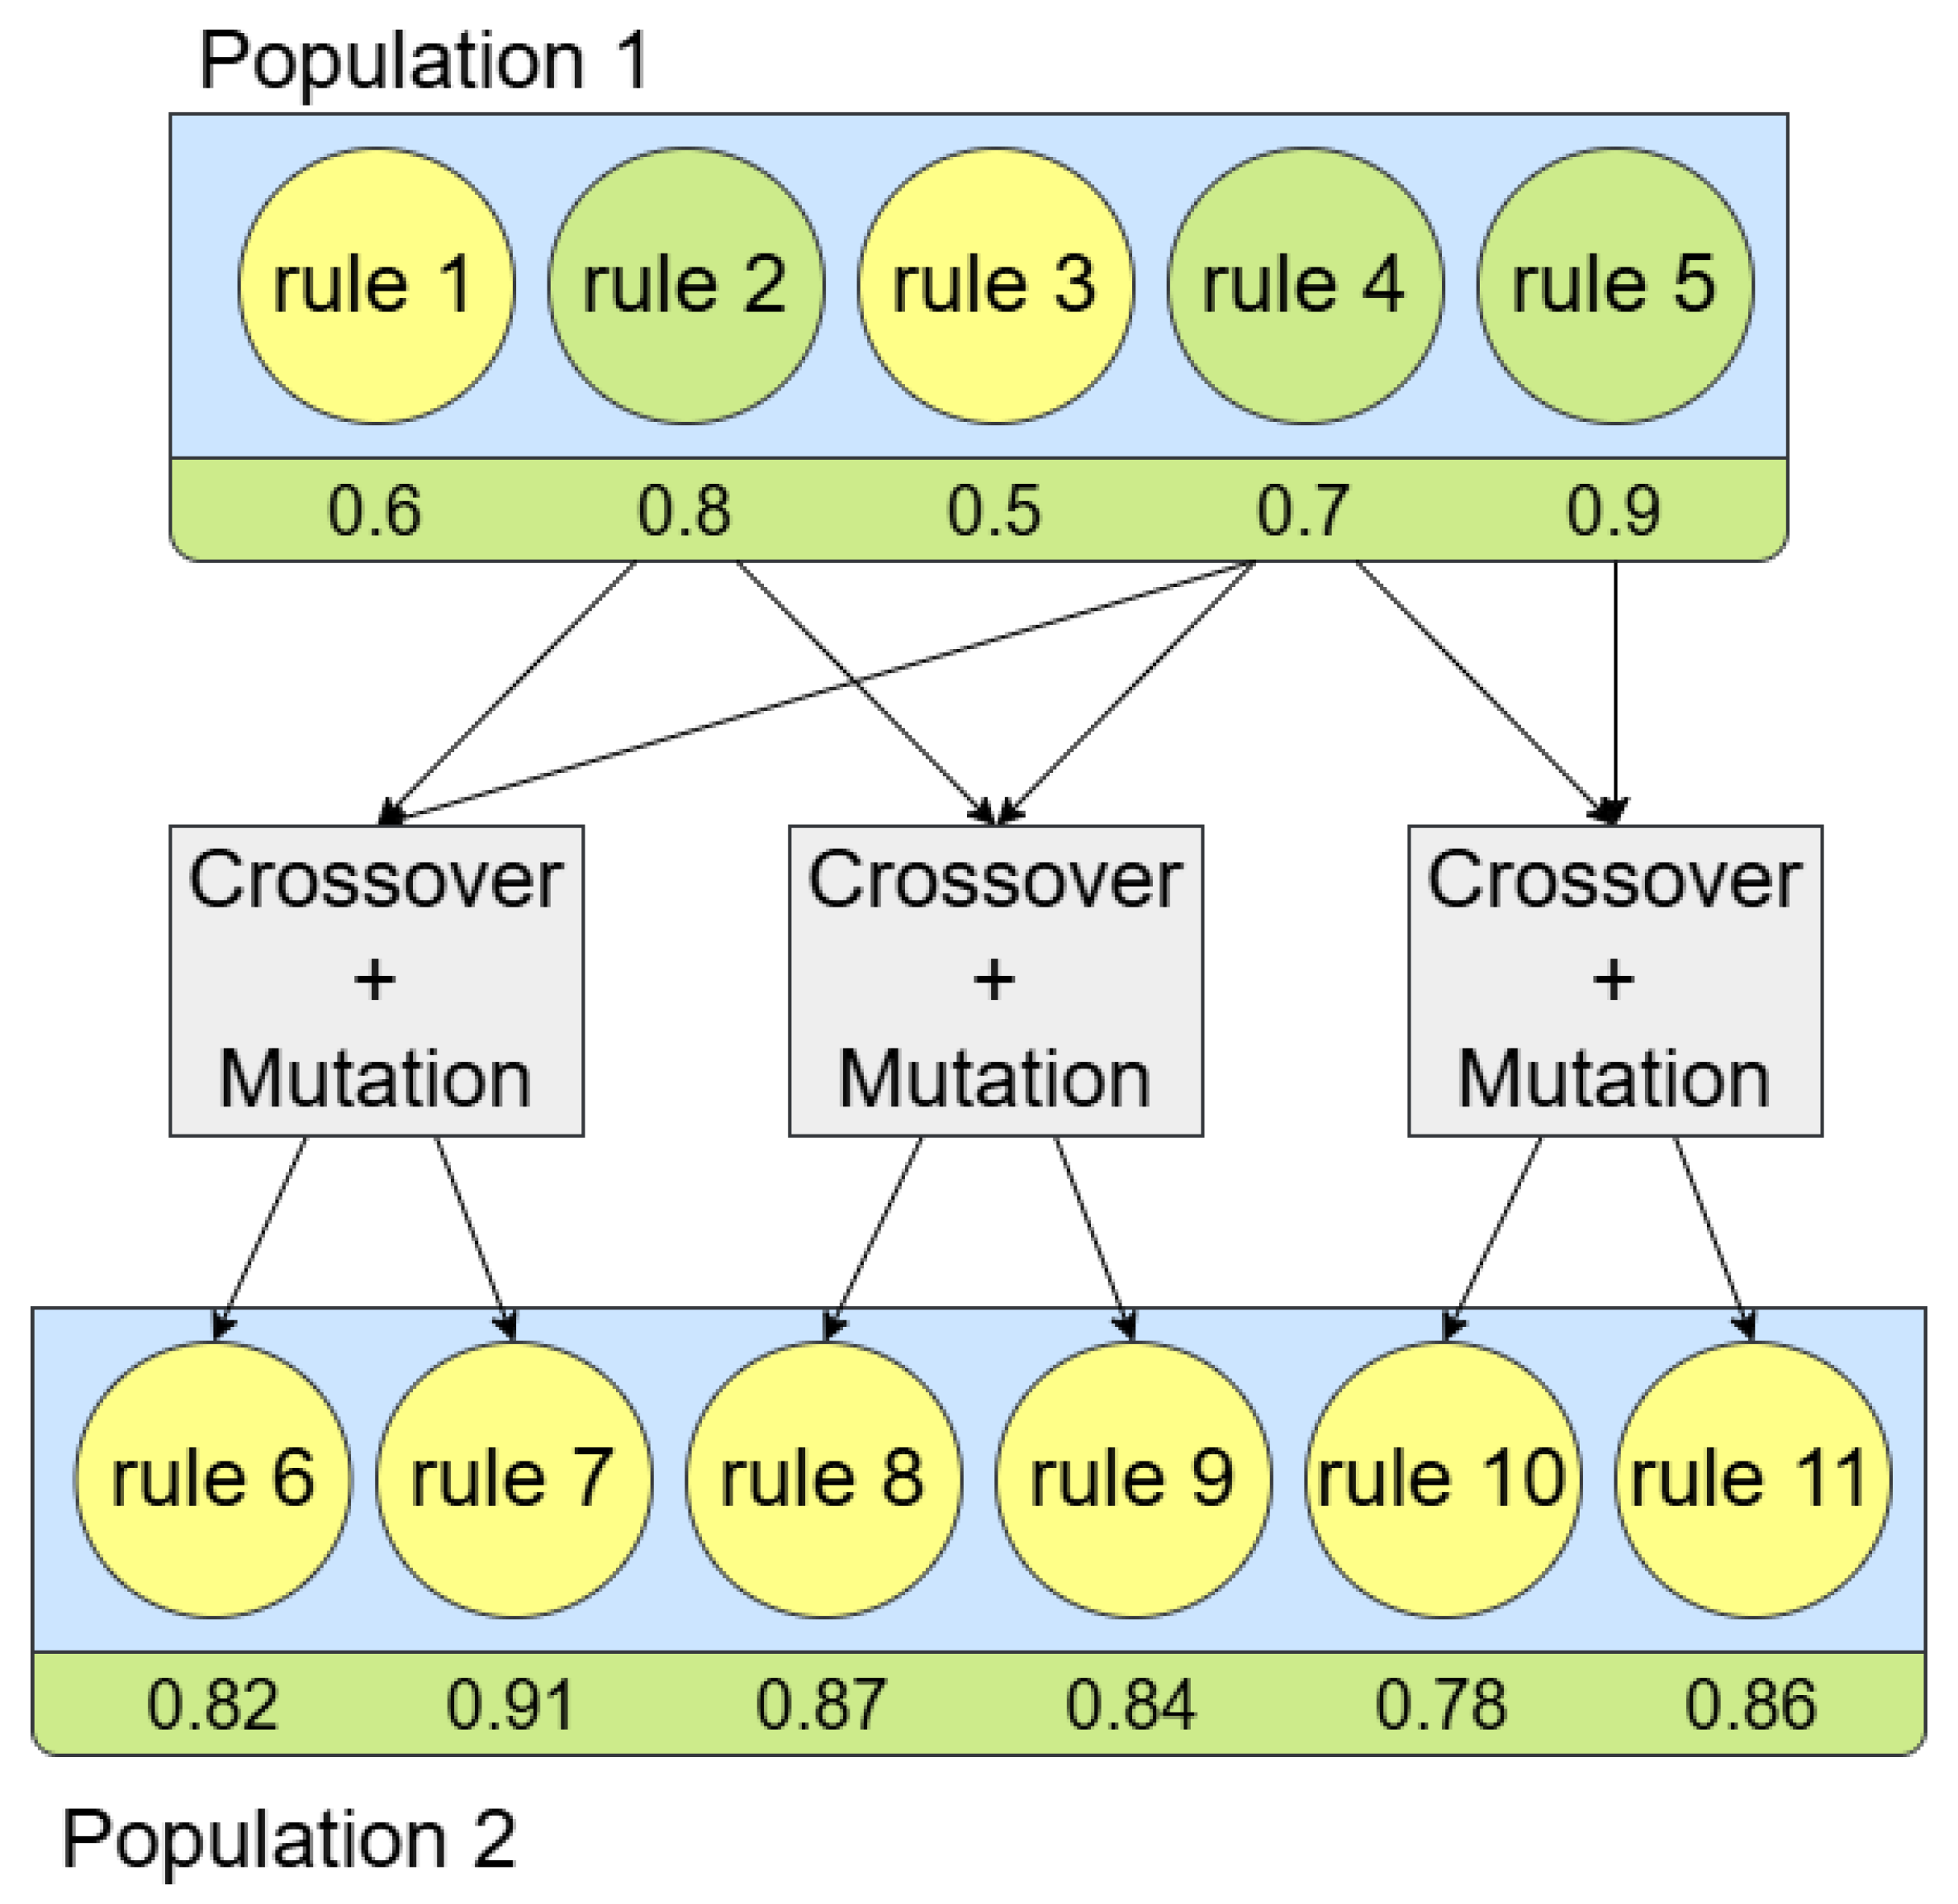
Inspiration is taken from [28], and a Genetic Algorithm is used to mine association rules in the ozone prediction context. A Genetic Algorithm (GA) is an algorithm that takes an initial population and a fitness function as inputs to output a new population that has a better fitness score. The initial population is iteratively modified to create new individuals with new fitness scores. For each iteration, the individuals with the best fitness scores are selected, mixed through a crossover operator, and altered through a mutator operator, to create a new population with increasingly better fitness scores. This process is illustrated in Figure 12.
In this case, the initial population is a set of rules and the fitness function returns a weighted sum of the confidence and comprehension of a rule.
Fitness = 0.1 Comprehension + 0.9 Confidence .
The main goal is to compute correct rules regarding first-order logic, i.e., there are few observations with hypotheses and without consequents. This is why confidence must be as high as possible and has a superior weight. Comprehension is only here to help the Genetic Algorithm to converge to a solution by reducing the number of predicates in iteratively built rules. Therefore, it must have a small weight. In order to guide the evolutionary process, observations are taken as an initial population, i.e., for each observation, a rule is created where the consequent is the ozone class of the observation and the hypotheses are the features of the observation.
To represent the individuals of the evolutionary engine, the idea of [47] is reused to represent an individual (a rule in this case) as a set of booleans; each boolean determines whether the individual has a given hypothesis or not. Inspiration from [44] is also taken and each hypothesis of the built rules can be an interval, e.g., X has a temperature between 285 and 300 which is suited for the training dataset. The parametrization of the evolutionary engine relies on the lessons learnt from [44] and our own experiments. The parameters of the engine are listed below:
  • Survivors of a population are elected through a tournament selector that keeps the best five candidates.
  • A double crossover operator with a recombination probability of 16%.
  • A mutator operator with a 1% probability of mutation.
  • Offspring are selected via an elite selector.
  • The iteration limit is set at 10 6 .
  • Iteration stops if the fitness score does not improve after 1000 iterations.
The number of iterations was chosen after a series of experiments which showed that many iterations were necessary to converge to better rules. The other parameters were selected after taking advice from [44]. The evolutionary engine runs 10 times for each ozone class. The threshold of 0.75 was retained after the preliminary experiments, evaluating several fitness thresholds, as it provided the best compromise between rule precision, coverage, and the number of extracted rules. This is a trade-off between 0.5, which generates rules whose classifications are incorrect many times, and 1, which generates rules that are almost always correct, but admit no exception. A total of 381 rules are found for every ozone class with this method. However, there are some duplicates.
Formal Concept Analysis (FCA)
Formal Concept Analysis (FCA) is used to extract association rules from a concept lattice, following the approach proposed in [48]. A lattice is a semi-ordered set of concepts. A concept can be defined either by its extension or by its intension. The extension of a concept is the set of individuals that belong to the concept, e.g., the concept “planet of the solar system” can be defined by its extension, i.e., the “things” that belong to this concept: Mercury, Venus, Earth, Jupiter, Mars, Saturn, Uranus, and Neptune. Now, for the intension of a concept, it is the maximal set of attributes shared by the individuals of the concept, e.g., the concept “adult” is the set of persons that have, as a common point, an age older than 18 years old.
It is important to note that concepts are always maximal sets, i.e., for each concept, c, (i) there is no individual that has the intension of c without belonging to c and (ii) there is no attribute that is shared by the individuals of c without belonging to c.
A concept can then be seen as a pair of two maximal sets, its extension and its intension. The extension of a concept, c, is noted as e x t ( c ) and the intension of a concept, c, is noted as i n t ( c ) .
In order to extract rules from concepts, they must first be ordered into a lattice. In a lattice, there is a relation, ≥, from concept c 1 to concept c 2 if c 1 is more general than c 2 , i.e., i n t ( c 1 ) is a subset of i n t ( c 2 ) . With this single rule, a partial order over concepts is obtained, from which rules can be mined.
To that end, a two-step method is followed:
  • Select every couple of concepts, c 1 and c 2 , such that c 1 c 2 ; c 1 does not have an ozone class attribute in its intension and c 2 has an ozone class attribute in its intension.
  • If C o n f i d e n c e 0.75 , with:
    Confidence = n hypotheses consequent n hypotheses = | e x t ( c 2 ) | | e x t ( c 1 ) | .
    It means that many individuals which have the attributes of c 1 also have the ozone class attribute of c 2 ; hence, a rule, i n t ( c 1 ) o z o n e c l a s s o f c 2 , is built. The confidence threshold of 0.75 was also confirmed through preliminary experiments as an appropriate compromise between rule reliability, rule coverage, and the number of extracted association rules.
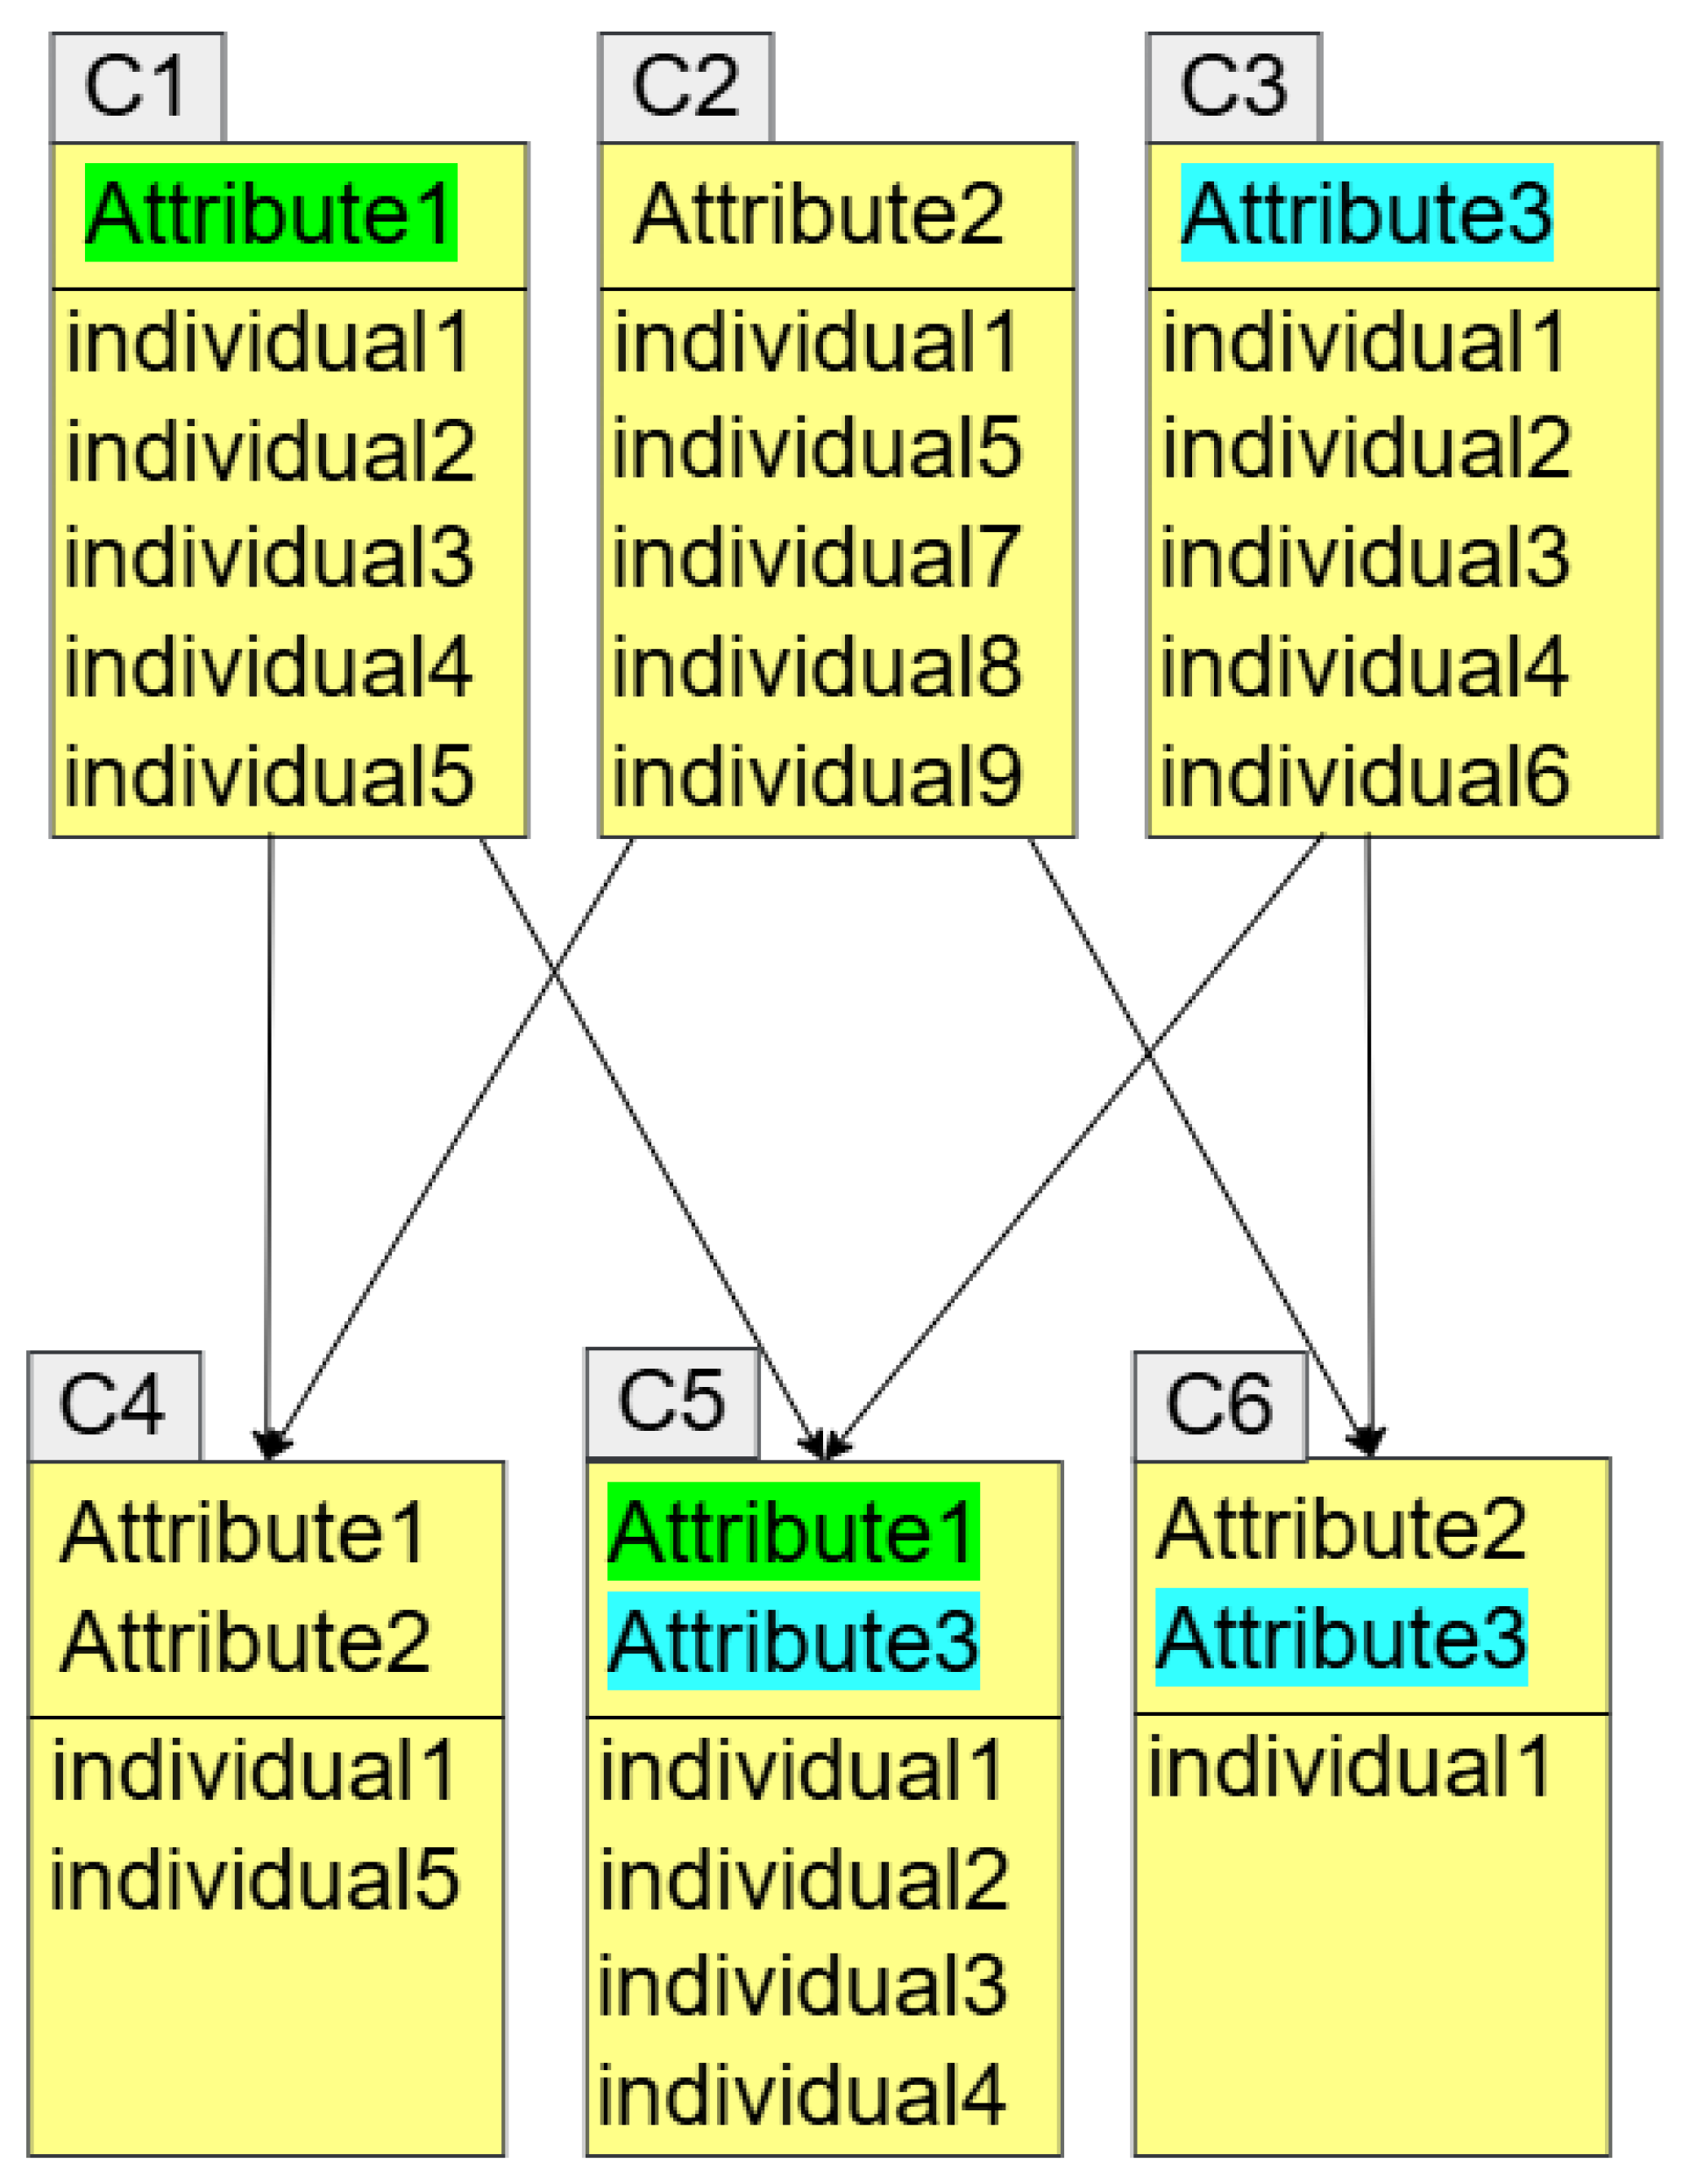
This process is shown in Figure 13.
Below is an example with three elementary concepts, where each has one attribute. Consider a case where one wants to compute rules whose consequent is attribute 3. To do so, for each concept that does not have attribute 3, the sub-concepts that possess attribute 3 are selected. In this case, concepts C 1 and C 2 with sub-concepts C 5 and C 6 are considered. Then, the extension ratio between the sub-concept and the initial concept is computed, to check if it is above 0.75. In this case, for C 5 , 4 5 = 0.8 0.75 , while for C 6 , 1 5 = 0.2 0.75 . Therefore, a rule, i n t ( C 1 ) A t t r i b u t e 3 or A t t r i b u t e 1 A t t r i b u t e 3 , is built.
In theory, many rules can be mined with this method for any class. However, in practice, the building of the lattice and rule-extraction process takes a lot of time (many hours). For this first experiment, the two first steps of the lattice from the union of the intension and the intersection of the extension could be built. This allowed us to obtain results in a reasonable amount of time (around 1 h), which permitted us to conduct multiple experiments and test different discretization techniques, different training and testing dataset sizes, and different feature selections. For now, the experiments have been conducted with a computer with the following specifications:
  • CPU: 12th Gen Intel(R) Core(TM) i5-12450H (2.50 GHz).
  • RAM: 32.0 Go (4800 MT/s).
  • GPU: NVIDIA GeForce RTX 4060 Laptop GPU (8 Go) Intel(R) UHD Graphics (128 Mo).
  • OS: Windows 11 64 bits.
With the constraints of time, with a response in approximately one hour, 71 rules were found through the FCA. The predictive performance reported for FCA should therefore be interpreted as that of a preliminary implementation rather than as an upper bound of the method itself. A complete lattice construction would likely generate additional rules with greater coverage, at the expense of substantially higher computational cost.
Once the rules are extracted, metrics are used to evaluate and compare them to other AI models, as discussed below.

2.6. Evaluated Metrics

Models are evaluated using four metrics, as defined in [49]: accuracy, precision, recall, and F1-Score.
Precision measures the proportion of predicted positive instances that are correctly classified. It is defined as:
Precision = TruePositive TruePositive + FalsePositive .
Accuracy measures the proportion of correctly classified instances. It is defined as:
Accuracy = TruePositive + TrueNegative TruePositive + FalsePositive + TrueNegative + FalseNegative .
Recall measures the proportion of actual positive instances that are correctly classified. It is defined as:
Recall = TruePositive TruePositive + FalseNegative .
Finally, the F1-Score is the harmonic mean of precision and recall. It is defined as:
F 1 - score = 2 × Precision × Recall Precision + Recall .
These four metrics are widely used to evaluate AI models and quantify their predictive performance. Since the objective of this work is to extract association rules, the correctness of the generated rules must also be assessed. In particular, a rule is considered correct if the observations satisfying its hypotheses also satisfy its consequent. Accordingly, rule quality is evaluated in terms of precision and accuracy. To further assess their practical relevance, the extracted rules have been shared with domain experts from Atmo Hauts-de-France as part of an ongoing collaborative evaluation process. Since this expert assessment is still in progress, no conclusions are drawn from it in the present study.

3. Results and Discussion

This section evaluates both the quality of the extracted rules and the predictive performance of explainable and non-explainable models. To improve the robustness and reliability of the experimental evaluation, all models were assessed using a five-fold cross-validation, a widely adopted validation strategy in machine learning which is a well-established methodology [50] and is still used nowadays, as in [51]. The results reported in the following sections correspond to the mean performance across the five folds, while the associated standard deviations are also provided to quantify the variability in the results. The performance was consistent across the five folds, indicating that the proposed approach is not sensitive to a particular data partition. The analysis begins with an assessment of the quality of the extracted rules produced by the explainable approaches.
A limitation of the present study is the exclusion of the very poor and extremely poor ozone classes because of the insufficient number of available observations for reliable model training. Although these rare episodes are of particular operational interest, especially in the context of forecasting exceedance of the French information threshold (180 μg m−3), they also represent one of the most challenging situations for both deterministic chemistry-transport models and data-driven approaches due to their rarity and the complexity of the atmospheric processes involved. Consequently, the models developed in this work should not be considered suitable for predicting the most severe ozone episodes. Nevertheless, the proposed methodology remains relevant from both operational and public health perspectives. Air quality management also requires anticipating moderate ozone pollution levels to support forecasting activities and optimize operational resources. In addition, the World Health Organization emphasizes that adverse health effects may occur at ozone concentrations below the current European regulatory thresholds [9]. Therefore, improving the prediction and interpretation of these more frequent pollution levels represents an important contribution while awaiting more comprehensive datasets for extreme events. Future work will focus on extending the historical database to include a larger number of high-ozone episodes, allowing the investigation of methods specifically designed for imbalanced datasets, such as cost-sensitive learning or synthetic oversampling. Such developments should improve the prediction of rare events while preserving the interpretability required for operational decision support.

3.1. Rules Extracted from Explainable Approaches

The rules were written following Prolog syntax [52]:
consequent ( X ) : hypothesis 1 ( X ) , , hypothesis K ( X ) .
Predicates—i.e., properties associated with the hypotheses—were defined according to the following convention:
shortNameOfTheFeature_categoricalValue
Here, the categorical value was assigned according to the discretization method described in Section efsec:datapreprocess.
Table 2 summarizes the features included in the dataset and their corresponding abbreviations.
Table 3 shows an example of extracted rules written in natural language. These rules establish a link between the ozone class and the features listed above. For the sake of illustration, they display a higher level of confidence and fewer than five hypotheses.
All extracted rules were presented to Atmo Hauts-de-France. They are currently being examined and interpreted with the aim of producing valuable knowledge for air quality experts.

3.2. Comparing the Explainable Models

First, the overall precision of the different rule sets was compared. As a baseline, the extracted rules were compared with those generated by a decision tree, a widely used interpretable model [53].
A decision tree is a hierarchical predictive model composed of internal decision nodes and terminal leaf nodes. Each internal node evaluates the value of a feature, and the outcome of such test determines the branch to follow. This process is repeated recursively until a leaf node—corresponding to the predicted target class—is reached. Each root-to-leaf path can then be translated into an interpretable decision rule, enabling a direct comparison with the association rules generated by the proposed approach.
The quality of the extracted rules was assessed in terms of its precision (Section efsec:Evaluated metrics). This comparison included the rules extracted using FCA (see the Formal Concept Analysis (FCA) Section), those generated by the GA (see the Genetic Algorithm Section), and those derived from the decision tree [53]. A summary of the results can be found in Table 4. This table, as for every table in this section, represents the average result across every fold with standard deviation.
These results show that the FCA- and GA-derived rule sets achieve higher average precision values than the decision tree within the experimental setting considered in this study. However, these differences should be interpreted cautiously in the absence of a formal statistical significance test. The high precision of the extracted rule sets may be partly explained by the fact that each rule is generated independently and selected according to its confidence.
Overall, the rule models, extracted by either FCA or GA, achieved the best performance. First, a lower precision for the “good” ozone class using FCA-extracted rules is observed. This can be explained both by the variability inside this ozone class, hence making the computation of exclusive attributes difficult, and by the fact that this is a truncated version of FCA that only computes general rules with few hypotheses (only two hypotheses for each rule), which leads to rules that tend to accept too many observations and incorrectly classify observations in the “good” ozone class.
Moreover, a significant decrease in precision was observed for the “moderate” ozone class. This can be explained by the narrow range defining this class (100–120), which makes it difficult to distinguish it from its neighbouring classes, namely “fair” and “poor”. Consequently, the GA struggles to identify combinations of predicates in the antecedent that effectively discriminate observations belonging to the “moderate” ozone class. In contrast, the FCA-based approach derived rules directly from statistical correlations, enabling the extraction of a highly precise rule for this class with low coverage (only one sample is covered by the rule).
Although decision trees, linear models and conventional rule-based classifiers are also considered to be intrinsically interpretable, they differ substantially from the proposed symbolic association rule-mining framework. Decision trees organize decisions as a hierarchical sequence of binary splits, resulting in a single decision path for each prediction. Linear models provide transparent coefficients describing the average contribution of each predictor but assume predominantly additive linear relationships that may not fully capture the complex interactions governing ozone formation. Conventional predictive rule-based classifiers generally induce sequential rule sets in which the order of the rules influences the final prediction. By contrast, the proposed framework extracts independent association rules that explicitly describe combinations of atmospheric conditions associated with each ozone class. Multiple complementary rules may therefore coexist for the same class, providing alternative explanations for similar atmospheric situations while preserving explicit semantic relationships between variables. This richer symbolic representation offers domain experts greater flexibility for analysing ozone-formation mechanisms without sacrificing intrinsic interpretability. Nevertheless, these different interpretable approaches should be regarded as complementary rather than competing paradigms, each presenting specific advantages depending on the prediction task, the complexity of the data and the desired balance between predictive performance and interpretability.
Finally, the explainable models were compared in terms of accuracy. However, due to the models being different, we have not yet been able to develop a method to compute accuracy for each ozone class. We give here the first results for the average accuracies of the models. The results are summarized in Table 5.
The results indicate that the FCA- and GA-derived rule sets achieved very similar average accuracies, suggesting that both approaches provided comparable predictive performances. The observed differences between FCA and GA remained small and should therefore be interpreted with caution. Furthermore, both symbolic approaches achieved higher average accuracy than the decision tree within the experimental setting considered in this study. This difference may be partly explained by the fact that rule-based approaches may leave some observations unclassified when no rule is applicable, whereas a decision tree systematically assigns a class to every observation.

3.3. Comparison with Non-Explainable Models

To assess whether intrinsic explainability can be achieved without compromising predictive performance, the proposed symbolic AI approaches were compared with non-explainable models. Since the precision of the different rule-extraction methods had already been evaluated, the complete rule set was then evaluated irrespective of the underlying rule-generation method. The comparison then focused on the predictive performance of the resulting intrinsically explainable model with respect to non-explainable approaches.
The comparison focused on the predictive performance of the resulting intrinsically explainable model with respect to non-explainable approaches. Since the objective is to analyse the predictive performance of each ozone class, Table 6, Table 7 and Table 8 report the class-wise precision, recall and F1-Score, respectively. Overall accuracy is reported separately in Table 9.
These results indicate that the black-box models achieve comparable precision across most ozone classes. The proposed rule-based approach also achieves high precision, with the exception of the “good” ozone class. This can be explained by the lower precision performance observed in the FCA-extracted rules.
The current process, oriented to discover rules with high confidence, also leads to low recall and F1-Score results. Since the main goal is to find correct rules regarding first-order logic, i.e., there are few observations that check a hypothesis without a consequent, such rules are too restrictive and too rigid to capture many observations. To the best of our knowledge, it is not possible in this case to have both high precision and high recall with a rule-based system. The hypotheses that can explain this are as follows:
  • The European standards make classification difficult. It is not possible to find sets of attributes that are exclusive to one European ozone class. Hence, it is difficult to have high recall for the intermediary ozone classes such as “fair” and “moderate”.
  • The attributes considered in this study are not enough to capture every ozone evolution or the overall complexity of ozone concentration.
Despite these results still being relatively low, the first discovered rules in this study still show characteristic interactions that are relevant for predicting, in certain cases, ozone concentration. Being able to extend what has already been achieved to capture every ozone observation is part of future work.
The accuracy of the proposed rule-based approach can now be compared with that of the non-explainable models. Again, due to the models being different, we were not able yet to develop a method to compute accuracy for each ozone class. We give here first results for the average accuracies. The results are summarized in Table 9.
As previously observed for the decision tree, the black-box models assign a class to every observation, which increases the number of false positives. In contrast, the proposed symbolic AI approach leaves observations unclassified when no applicable rule is available, resulting in a larger number of true negatives and, consequently, higher accuracy. Overall, these preliminary results demonstrate the potential of the proposed symbolic AI approach, while also highlighting several directions for future improvements.
These results illustrate the classical trade-off frequently discussed in the XAI literature between predictive performance and interpretability. While black-box models may sometimes achieve slightly better predictive performance, symbolic AI provides explanations that are directly embedded into the prediction process, thereby improving transparency and facilitating expert validation.

4. Conclusions and Future Work

This study proposed an intrinsically explainable symbolic artificial intelligence framework for ground-level ozone prediction based on association rule mining. By combining Formal Concept Analysis (FCA) and Genetic Algorithms (GAs), the proposed methodology automatically extracts human-readable association rules linking meteorological and atmospheric variables to ozone concentration classes. Unlike conventional black-box approaches that require post hoc explanation techniques, the proposed framework provides transparent prediction mechanisms that can be directly interpreted and validated by domain experts. For now, the rules have been presented to experts from Atmo, and are waiting to be examined and evaluated.
The experimental evaluation shows that the proposed symbolic AI framework can achieve competitive predictive performance while preserving intrinsic interpretability within the scope of the considered benchmark. In particular, the extracted rule sets exhibited high precision across ozone classes and achieved higher precision and accuracy than the decision tree baseline evaluated in this study. The comparison with conventional machine learning models should, however, be interpreted with caution, as the current FCA implementation deliberately relies on a truncated lattice construction to maintain reasonable computation times on the considered dataset. Consequently, the reported FCA results should be regarded as preliminary and demonstrate the feasibility of applying FCA to large-scale atmospheric data rather than the full predictive potential of the method. The present work nevertheless highlights several limitations. In particular, the current FCA implementation explores only a restricted portion of the concept lattice, thereby limiting rule coverage and reducing the classification of some observations. A more exhaustive lattice construction is expected to improve rule coverage, although this was beyond the scope of the present study because of computational constraints. In addition, the computational complexity of symbolic rule extraction constrains the exploration of larger search spaces and richer combinations of hypotheses.
Future work will therefore focus on improving rule coverage and predictive performance, particularly with respect to recall and F1-Score, through more exhaustive lattice exploration and optimized evolutionary search strategies. The comparison will be extended to a broader range of state-of-the-art machine learning and deep learning models, while dedicated high-performance computing resources will enable larger-scale experiments. Future developments will also investigate additional symbolic rule-mining techniques, hybrid neuro-symbolic approaches, and richer atmospheric representations integrating complementary meteorological and chemical variables. Future studies will further investigate and refine the granular computing rule-extraction approach [32], extending it to the prediction of the ground-level ozone under diverse climatic and geographical conditions, as well as to other atmospheric pollutants, in order to establish a generalizable symbolic framework for explainable air quality prediction. Ultimately, this research contributes to the development of trustworthy symbolic AI-based decision-support tools capable of combining predictive performance, transparent reasoning, and actionable environmental knowledge for air quality management. Finally, future work will include a systematic quantitative comparison of the rule sets generated by different symbolic rule-mining approaches. In particular, characteristics such as the number of extracted rules, rule complexity, redundancy, and rule overlap will be investigated to better understand the complementary strengths and limitations of FCA, GA, and other symbolic rule-mining strategies.

Author Contributions

Conceptualisation, H.Z.-B., L.C. and A.R.; methodology, D.C., A.B. and N.P.-S.; validation, H.Z.-B. and N.P.-S.; writing—original draft preparation, D.C., A.R., I.J. and H.Z.-B.; writing—review and editing, H.Z.-B., A.B., L.C., and A.R.; visualisation, D.C. and A.R.; supervision, H.Z.-B. and N.P.-S.; funding acquisition, H.Z.-B., L.C. and A.R. All authors have read and agreed to the published version of the manuscript.

Funding

This work was supported by the French National Research Agency (Agence Nationale de la Recherche, ANR) through an ANR project, IARISQ (grant number ANR-25-CE56-3679).

Institutional Review Board Statement

Not applicable.

Informed Consent Statement

Not applicable.

Data Availability Statement

The air quality data used in this study originate from the ATMO Hauts-de-France monitoring network and are subject to the organization’s data access and dissemination policies. Therefore, these data are available from the corresponding author upon reasonable request, subject to approval by ATMO Hauts-de-France. The meteorological data used in this study are the publicly available ERA5 reanalysis data provided by the Copernicus Climate Change Service. The source code used for data processing and model development is available from the corresponding author upon reasonable request, provided that it does not include restricted data.

Conflicts of Interest

The authors declare no conflicts of interest.

References

  1. Atmo Hauts-de-France. CAP Région Hauts-de-France, 2025. Available online: https://www.atmo-hdf.fr/publications/atmo-hauts-de-france-vous-presente-le-cap-territorial-trajectoire-2025 (accessed on 24 June 2026).
  2. Monks, P.S.; Archibald, A.T.; Colette, A.; Cooper, O.R.; Coyle, M.; Derwent, R.G.; Fowler, D.; Granier, C.; Law, K.S.; Mills, G.; et al. Tropospheric Ozone and Its Precursors from the Urban to the Global Scale: A Synthesis of Current Understanding. Atmos. Chem. Phys. 2015, 15, 8889–8973. [Google Scholar] [CrossRef] [Scilit]
  3. Derwent, R.G.; Jenkin, M.E. Ozone and Other Secondary Photochemical Pollutants: Chemical Processes Governing Their Formation in the Planetary Boundary Layer. Atmos. Environ. 2000, 34, 2499–2527. [Google Scholar] [CrossRef] [Scilit]
  4. Hersbach, H.; Bell, B.; Berrisford, P.; Hirahara, S.; Horányi, A.; Muñoz-Sabater, J.; Nicolas, J.; Peubey, C.; Radu, R.; Schepers, D.; et al. The ERA5 Global Reanalysis. Q. J. R. Meteorol. Soc. 2020, 146, 1999–2049. [Google Scholar] [CrossRef] [Scilit]
  5. Soares, A.R.; Silva, C. Review of ground-level ozone impact in respiratory health deterioration for the past two decades. Atmosphere 2022, 13, 434. [Google Scholar] [CrossRef] [Scilit]
  6. Yang, N.; Cotrozzi, L.; Liu, C.; Qiao, Q.; Wang, X.; Zheng, F.; Hoshika, Y.; Nali, C.; Paoletti, E.; Pisuttu, C.; et al. Development trend, evolution of themes, gaps, and challenges of the research investigating ozone effects on vegetation. Environ. Rev. 2025, 33, 1–13. [Google Scholar] [CrossRef] [Scilit]
  7. Wang, L.; Oduor, A.M.; Liu, Y. Elevated ozone mitigates negative impact of herbivory on the growth of invasive plant species. Oikos 2026, 1, e11652. [Google Scholar] [CrossRef] [Scilit]
  8. United States Environmental Protection Agency. Ground-Level Ozone Basics. 2025. Available online: https://www.epa.gov/ground-level-ozone-pollution/ground-level-ozone-basics (accessed on 24 June 2026).
  9. World Health Organization. WHO Global Air Quality Guidelines: Particulate Matter (PM2.5 and PM10), Ozone, Nitrogen Dioxide, Sulfur Dioxide and Carbon Monoxide; World Health Organization: Geneva, Switzerland, 2021.
  10. European Parliament and Council of the European Union. Directive 2008/50/EC of the European Parliament and of the Council of 21 May 2008 on Ambient Air Quality and Cleaner Air for Europe; Official Journal of the European Union: Luxembourg, 2008; pp. 1–44. [Google Scholar]
  11. European Parliament and Council of the European Union. Directive (EU) 2024/2881 of the European Parliament and of the Council of 23 October 2024 on Ambient Air Quality and Cleaner Air for Europe (Recast); Official Journal of the European Union: Luxembourg, 2024. [Google Scholar]
  12. Menut, L.; Bessagnet, B.; Khvorostyanov, D.; Beekmann, M.; Blond, N.; Colette, A.; Coll, I.; Curci, G.; Foret, G.; Hodzic, A.; et al. CHIMERE 2013: A Model for Regional Atmospheric Composition Modelling. Geosci. Model Dev. 2013, 6, 981–1028. [Google Scholar] [CrossRef] [Scilit]
  13. Byun, D.; Schere, K.L. Review of the Governing Equations, Computational Algorithms, and Other Components of the Models-3 Community Multiscale Air Quality (CMAQ) Modeling System. Appl. Mech. Rev. 2006, 59, 51–77. [Google Scholar] [CrossRef] [Scilit]
  14. Hu, M.; Lu, X.; Chen, Y.; Li, Z.; Wang, Y.; Fung, J.C.H. AirQFormer: Improving Regional Air Quality Forecast with a Hybrid Deep Learning Model. Sustain. Cities Soc. 2025, 119, 106113. [Google Scholar] [CrossRef] [Scilit]
  15. Gao, Z.; Zhou, X. A Review of the CAMx, CMAQ, WRF-Chem and NAQPMS Models: Application, Evaluation and Uncertainty Factors. Environ. Pollut. 2024, 343, 123183. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  16. Chianese, E. Multi-Model Ensemble Approaches in Air Quality Prediction: A Comprehensive Review from Chemical Transport Models to Hybrid Machine Learning. Atmosphere 2026, 17, 689. [Google Scholar] [CrossRef] [Scilit]
  17. El Mghouchi, Y.; Udristioiu, M.T. On the Prediction and Forecasting of PMs and Air Pollution: An Application of Deep Hybrid AI-Based Models. Appl. Sci. 2025, 15, 8254. [Google Scholar] [CrossRef] [Scilit]
  18. Lippmann, M. Health effects of ozone a critical review. Japca 1989, 39, 672–695. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  19. Alnuaim, A.; Sun, Z.; Islam, D. AI for improving ozone forecasting. In Artificial Intelligence in Earth Science; Elsevier: Amsterdam, The Netherlands, 2023; pp. 247–269. [Google Scholar]
  20. El Mghouchi, Y.; Udristioiu, M.T. Seasonal and diurnal variations of ozone concentration and influencing factors: An application of deep hybrid AI models in Craiova city. Eur. Phys. J. Plus 2026, 141, 160. [Google Scholar] [CrossRef] [Scilit]
  21. Udristioiu, M.T.; El Mghouchi, Y. Deep Hybrid AI Models Applied to Predict, Model, and Forecast the Next Upcoming Periods of Ozone in Craiova City. Appl. Sci. 2025, 15, 12187. [Google Scholar] [CrossRef] [Scilit]
  22. Fania, A.; Lorusso, G.; Cilli, R.; Amoroso, N.; Adamo, M.; Aquilino, M.; Bellantuono, L.; De Lucia, M.; Lacalamita, A.; La Rocca, M.; et al. High-Resolution NO2, O3, and PMs Estimation in Puglia: Leveraging AI and Explainability Techniques. Atmosphere 2026, 17, 209. [Google Scholar] [CrossRef] [Scilit]
  23. Ribeiro, M.T.; Singh, S.; Guestrin, C. “Why Should I Trust You?”: Explaining the Predictions of Any Classifier. In Proceedings of the 22nd ACM SIGKDD International Conference on Knowledge Discovery and Data Mining, San Francisco, CA, USA, 13–17 August 2016; pp. 1135–1144. [Google Scholar] [CrossRef] [Scilit]
  24. Lundberg, S.M.; Lee, S.I. A Unified Approach to Interpreting Model Predictions. In Proceedings of the Advances in Neural Information Processing Systems (NeurIPS), Long Beach, CA, USA, 4–9 December 2017; Volume 30. [Google Scholar]
  25. Ortigossa, E.S.; Gonçalves, T.; Nonato, L.G. Explainable artificial intelligence (xai)—From theory to methods and applications. IEEE Access 2024, 12, 80799–80846. [Google Scholar] [CrossRef] [Scilit]
  26. Kalasampath, K.; Spoorthi, K.; Sajeev, S.; Kuppa, S.S.; Ajay, K.; Maruthamuthu, A. A literature review on applications of explainable artificial intelligence (XAI). IEEE Access 2025, 13, 41111–41140. [Google Scholar] [CrossRef] [Scilit]
  27. Agrawal, R.; Srikant, R. Fast Algorithms for Mining Association Rules. In Proceedings of the 20th International Conference on Very Large Data Bases (VLDB), Santiago, Chile, 12–15 September 1994; pp. 487–499. [Google Scholar]
  28. Martínez-Ballesteros, M.; Salcedo-Sanz, S.; Riquelme, J.C.; Casanova-Mateo, C.; Camacho, J.L. Evolutionary association rules for total ozone content modeling from satellite observations. Chemom. Intell. Lab. Syst. 2011, 109, 217–227. [Google Scholar] [CrossRef] [Scilit]
  29. Li, Z.; Zhou, W.; Liu, X.; Qian, Y.; Wang, C.; Xie, Z.; Ma, H. Research on Association Rules Mining of Atmospheric Environment Monitoring Data. In Technology-Inspired Smart Learning for Future Education; Springer: Singapore, 2020; Volume 1216, pp. 86–98. [Google Scholar] [CrossRef] [Scilit]
  30. Telikani, A.; Gandomi, A.H.; Shahbahrami, A. A Survey of Evolutionary Computation for Association Rule Mining. Inf. Sci. 2020, 524, 318–352. [Google Scholar] [CrossRef] [Scilit]
  31. Wu, X.; Wen, Q.; Zhu, J. Association Rule Mining with a Special Rule Coding and Dynamic Genetic Algorithm for Air Quality Impact Factors in Beijing, China. PLoS ONE 2024, 19, e0299865. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  32. Jairi, I.; Ben-Othman, S.; Canivet, L.; Zgaya-Biau, H. Explainable based approach for the air quality classification on the granular computing rule extraction technique. Eng. Appl. Artif. Intell. 2024, 133, 108096. [Google Scholar] [CrossRef] [Scilit]
  33. Cheng, N.; Jing, D.; Gu, Z.; Cai, X.; Shi, Z.; Li, S.; Chen, L.; Li, W.; Wang, Q. Observation-based ozone formation rules by gradient boosting decision trees model in typical chemical industrial parks. Atmosphere 2024, 15, 600. [Google Scholar] [CrossRef] [Scilit]
  34. Wang, Q.; Sheng, D.; Wu, C.; Zhao, J.; Li, F.; Yao, S.; Ou, X.; Li, W.; Chen, J. Exploring ozone formation rules and concentration response to the change of precursors based on artificial neural network simulation in a typical industrial park. Heliyon 2023, 9, e20125. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  35. Caceres, S.Z.; Lopez, J.T. Association Rules in the measurement of air pollution in the city of Santiago de Chile. Int. J. Syst. Appl. Eng. Dev. 2021, 15, 15–20. [Google Scholar] [CrossRef] [Scilit]
  36. Othman, Z.A.; Ismail, N.; Bakar, A.A.; Latif, M.T.; Abdullah, S.M.S. Rules discovery of high ozone in Klang areas using data mining approach. Int. J. Adv. Sci. Eng. Inf. Technol. 2018, 8, 2683–2689. [Google Scholar] [CrossRef] [Scilit]
  37. Hu, M.; Wang, Z. A Three-Way Confirmatory Approach to Formal Concept Analysis in Classification. Appl. Soft Comput. 2024, 155, 111448. [Google Scholar] [CrossRef] [Scilit]
  38. Han, J.; Pei, J.; Yin, Y. Mining Frequent Patterns without Candidate Generation. In Proceedings of the ACM SIGMOD International Conference on Management of Data, Dallas, TX, USA, 16–18 May 2000; pp. 1–12. [Google Scholar] [CrossRef] [Scilit]
  39. Cohen, W.W. Fast Effective Rule Induction. In Proceedings of the Twelfth International Conference on Machine Learning (ICML), Tahoe City, CA, USA, 9–12 July 1995; pp. 115–123. [Google Scholar]
  40. Copernicus Climate Change Service (C3S). ERA5 Hourly Data on Single Levels from 1940 to Present. 2026. Available online: https://cds.climate.copernicus.eu/datasets/reanalysis-era5-single-levels?tab=overview (accessed on 8 August 2026).
  41. Ilkou, E.; Koutraki, M. Symbolic vs. sub-symbolic AI methods: Friends or enemies? In Proceedings of the CIKM 2020 Workshops, Galway, Ireland, 19–23 October 2020; Volume 2699. [Google Scholar]
  42. Borisov, V.; Leemann, T.; Seßler, K.; Haug, J.; Pawelczyk, M.; Kasneci, G. Deep Neural Networks and Tabular Data: A Survey. IEEE Trans. Neural Netw. Learn. Syst. 2024, 35, 7499–7519. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  43. Jairi, I.; Rekbi, A.; Ben-Othman, S.; Hammadi, S.; Canivet, L.; Zgaya-Biau, H. Enhancing particulate matter risk assessment with novel machine learning-driven toxicity threshold prediction. Eng. Appl. Artif. Intell. 2025, 139, 109531. [Google Scholar] [CrossRef] [Scilit]
  44. Al-Maqaleh, B.M.; Shahbazkia, H. A genetic algorithm for discovering classification rules in data mining. Int. J. Comput. Appl. 2012, 41, 40–44. [Google Scholar] [CrossRef] [Scilit]
  45. Mathew, T.V. Genetic algorithm. Rep. Submitt. Iit Bombay 2012, 53, 18–19. [Google Scholar]
  46. Ganter, B.; Wille, R. Formal Concept Analysis; Springer: Berlin/Heidelberg, Germany, 1999; Volume 150. [Google Scholar]
  47. Abdullah, N.N.B.; Liquiere, M.; Cerri, S.A. Ga s rule for knowledge discovery. Appl. Artif. Intell. 2003, 17, 399–417. [Google Scholar] [CrossRef] [Scilit]
  48. Godin, R.; Mineau, G.; Missaoui, R.; Mili, H. Méthodes de classification conceptuelle basées sur les treillis de Galois et applications. Rev. D’Intelligence Artif. 1995, 9, 105–137. [Google Scholar]
  49. Miller, C.; Portlock, T.; Nyaga, D.M.; O’Sullivan, J.M. A review of model evaluation metrics for machine learning in genetics and genomics. Front. Bioinform. 2024, 4, 1457619. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  50. Hastie, T.; Tibshirani, R.; Friedman, J. The Elements of Statistical Learning: Data Mining, Inference, and Prediction, 2nd ed.; Springer: New York, NY, USA, 2009. [Google Scholar]
  51. Rastogi, D.; Johri, P.; Tiwari, V.; Elngar, A.A. Multi-class classification of brain tumour magnetic resonance images using multi-branch network with inception block and five-fold cross validation deep learning framework. Biomed. Signal Process. Control 2024, 88, 105602. [Google Scholar] [CrossRef] [Scilit]
  52. Wielemaker, J.; Schrijvers, T.; Triska, M.; Lager, T. Swi-prolog. Theory Pract. Log. Program. 2012, 12, 67–96. [Google Scholar] [CrossRef] [Scilit]
  53. Quinlan, J.R. Learning decision tree classifiers. ACM Comput. Surv. (CSUR) 1996, 28, 71–72. [Google Scholar] [CrossRef] [Scilit]
Figure 1. Regional monitoring stations used to collect background and traffic-related concentration data for ozone in the Hauts-de-France region. These stations might have different implantations, namely urban, suburban and rural.
Atmosphere 17 00798 g001
Figure 3. Removal of observations with missing ozone values (NaN). t2m: air temperature at 2 m above ground level (K); nox: nitrogen oxide (NO and NO2) concentrations (μg m−3); ozone: ground-level ozone concentration (μg m−3).
Atmosphere 17 00798 g003
Figure 5. Feature discretization: numerical feature values are replaced by their corresponding discrete categories. t2m: air temperature at 2 m above ground level (K); nox: nitrogen oxide (NO and NO2) concentrations (μg m−3); ozone: ground-level ozone concentration (μg m−3).
Atmosphere 17 00798 g005
Figure 6. Since nearly all observations with surface net solar radiation ( s s r ) values below 0.15 × 10 6 belong to the “good” ozone class, a bin boundary is introduced at 0.15 × 10 6 .
Atmosphere 17 00798 g006
Figure 7. A bin boundary is introduced at 500 because nearly all observations belonging to the good ozone class have a blh value below this threshold. blh: boundary layer height.
Atmosphere 17 00798 g007
Figure 8. Bin boundaries are defined so that the median of each ozone class falls within a distinct bin. tcc: total cloud cover.
Atmosphere 17 00798 g008
Figure 9. Feature labelling: numerical category identifiers are replaced by descriptive interval labels. t2m: air temperature at 2 m above ground level (K); nox: nitrogen oxide (NO and NO2) concentrations (μg m−3); ozone: ground-level ozone concentration (μg m−3).
Atmosphere 17 00798 g009
Figure 10. A second cleaning step is performed where every row representing an observation with an under-represented class is removed. t2m: air temperature at 2 m above ground level (K); nox: nitrogen oxide (NO and NO2) concentrations (μg m−3); ozone: ground-level ozone concentration (μg m−3).
Atmosphere 17 00798 g010
Figure 12. A GA mutates and crosses the individuals of population 1 to create population 2, the individuals of which have higher fitness scores.
Atmosphere 17 00798 g012
Figure 13. Illustration of Formal Concept Analysis (FCA): concepts C1–C6, where each pair has an intent (shared attributes, highlighted) and an extent (covered individuals). Arrows denote sub-concept relationships, from which association rules are extracted.
Atmosphere 17 00798 g013
Table 1. Comparison of existing explainable approaches for ground-level ozone prediction. The comparison and classifications were compiled by the authors based on the cited studies.
AuthorsYearMethodGround-LevelHourly BasisPer-Class PredictionInterpretability
Fania, Alessandro et al. [22]2026Linear model + XGBoostYesNoNoNo
Cheng, Nana et al. [33]2024Gradient-boosted decision treeYesNoYesNo
Wang, Qiaoli et al. [34]2023Artificial neural networkYesNoNoNo
Caceres, Santiago Zapata, and Juan Torres Lopez [35]2021Statistical correlationYesNoNoNo
Othman, Zulaiha Ali et al. [36]2018Apriori AlgorithmYesYesYesOnly in high concentrations
Martínez-Ballesteros, M. et al. [28]2011evolutionary algorithmNoYesNoYes
Table 2. Atmospheric and meteorological variables used for association rule mining.
Short NameLong NameDescription
implantationImplantationThe type of area in which the station is located.
influenceInfluenceThe type of area that affects a specific air quality variable where the monitoring station is located.
blhBoundary layer heightHeight of the atmospheric boundary layer in metres.
sshfSurface sensible heat fluxsurface sensible heat flux in J   m −2. Positive downwards.
ssrSurface net solar radiationNet solar flux (short-wave) at the surface in J   m −2. Positive downwards.
strSurface net thermal radiationNet surface heat flux (long-wave) in J   m −2. Positive downwards.
t2mTemperature at 2 mTemperature at 2 m in kelvin.
tccTotal cloud coverCloud cover (the portion of the sky obscured by clouds, between 0 and 1).
u10U wind speed at 10 mU (eastward) component of wind speed at 10 m in m   s −1.
v10V wind speed at 10 mV (northward) component of wind speed at 10 m in m   s −1.
noxNOx: Nitrogen oxidesConcentration of both NO and NO2 in μg m−3.
Table 3. A sample of extracted rules with FCA and GA. sshf: surface sensible heat flux; ssr: surface net solar radiation; t2m: temperature at 2 m; blh: boundary layer height; tcc: total cloud cover; nox: nitrogen oxides; u10: U wind speed at 10 m; v10: V wind speed at 10 m.
FCA-RulesConfidence
IF s s h f > 0.2 × 10 6 AND s s r < 0.15 × 10 6 THEN ozone class is “good”0.83
IF s t r < 0.4 × 10 6 AND t 2 m < 285 THEN ozone class is “fair”0.91
IF s s r > 2 × 10 6 AND s t r > 0.2 × 10 6 THEN ozone class is “moderate”1
IF b l h > 2500 AND 0 t c c > 0.25 THEN ozone class is “poor”0.86
GA-RulesFitness
IF n o x > 20 AND s s r < 0.15 × 10 6 AND t 2 m < 285 AND 0 v 10 > 3 THEN ozone class is “good”0.90
IF 1 × 10 6 s s r > 2 × 10 6 AND t 2 m < 285 AND u 10 > 2 THEN ozone class is “fair”0.89
IF s s h f > 0 AND s t r < 0.4 × 10 6 AND 0 t c c > 0.25 THEN ozone class is “moderate”0.89
IF b l h > 2500 AND u 10 < 3 THEN ozone class is “poor”0.90
Table 4. Per-class precision and average precision of the explainable models.
GoodFairModeratePoorMean Precision
Decision Tree0.74 ± 0.030.52 ± 0.010.49 ± 0.010.66 ± 0.010.60 ± 0.01
FCA0.62 ± 0.030.78 ± 0.061.00 ± 0.000.79 ± 0.060.79 ± 0.07
EvolutionAlgo0.95 ± 0.020.76 ± 0.060.52 ± 0.060.82 ± 0.030.76 ± 0.03
Table 5. Accuracy of the explainable models.
Accuracy
Decision Tree0.60 ± 0.02
FCA0.79 ± 0.01
GA0.79 ± 0.00
Table 6. Comparison of the precision of explainable and black-box models.
GoodFairModeratePoorAverage Precision
SVM0.79 ± 0.020.61 ± 0.040.52 ± 0.020.65 ± 0.010.64 ± 0.01
CatBoost0.78 ± 0.020.63 ± 0.020.51 ± 0.020.65 ± 0.020.64 ± 0.01
RandomForest0.78 ± 0.010.59 ± 0.020.53 ± 0.030.68 ± 0.020.64 ± 0.02
CNN0.76 ± 0.030.55 ± 0.020.50 ± 0.020.68 ± 0.030.61 ± 0.03
Decision Tree0.74 ± 0.030.52 ± 0.010.49 ± 0.010.66 ± 0.010.61 ± 0.01
Rules0.61 ± 0.040.74 ± 0.040.52 ± 0.060.78 ± 0.050.66 ± 0.05
Table 7. Comparison of the recall of explainable and black-box models.
GoodFairModeratePoorAverage Recall
SVM0.78 ± 0.020.64 ± 0.040.40 ± 0.050.75 ± 0.020.64 ± 0.01
CatBoost0.79 ± 0.030.59 ± 0.040.43 ± 0.030.78 ± 0.020.65 ± 0.01
RandomForest0.77 ± 0.010.58 ± 0.020.49 ± 0.020.72 ± 0.030.64 ± 0.01
CNN0.75 ± 0.020.55 ± 0.030.51 ± 0.040.67 ± 0.030.62 ± 0.00
Decision Tree0.71 ± 0.020.55 ± 0.020.48 ± 0.010.65 ± 0.020.60 ± 0.01
Rules0.83 ± 0.040.17 ± 0.030.09 ± 0.010.34 ± 0.070.36 ± 0.01
Table 8. Comparison of the F1-Score of explainable and black-box models.
GoodFairModeratePoorAverage F1-Score
SVM0.79 ± 0.010.62 ± 0.020.45 ± 0.030.70 ± 0.020.64 ± 0.01
CatBoost0.79 ± 0.010.61 ± 0.010.47 ± 0.020.71 ± 0.010.64 ± 0.01
RandomForest0.77 ± 0.010.59 ± 0.010.51 ± 0.010.70 ± 0.010.64 ± 0.01
CNN0.76 ± 0.020.55 ± 0.020.51 ± 0.020.67 ± 0.020.62 ± 0.00
Decision Tree0.73 ± 0.020.54 ± 0.010.48 ± 0.010.66 ± 0.010.60 ± 0.01
Rules0.70 ± 0.020.27 ± 0.040.14 ± 0.010.46 ± 0.070.39 ± 0.02
Table 9. Model accuracy.
Accuracy
SVM0.64 ± 0.01
CatBoost0.65 ± 0.01
RandomForest0.65 ± 0.01
CNN0.62 ± 0.01
Decision Tree0.60 ± 0.02
Rules0.79 ± 0.01
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content.