
SSPA: Enhancing Pseudo-Corpus Quality on Tibetan Machine Translation via Semantic-Syntax Prealignment

Abstract
1. Introduction
- 1.
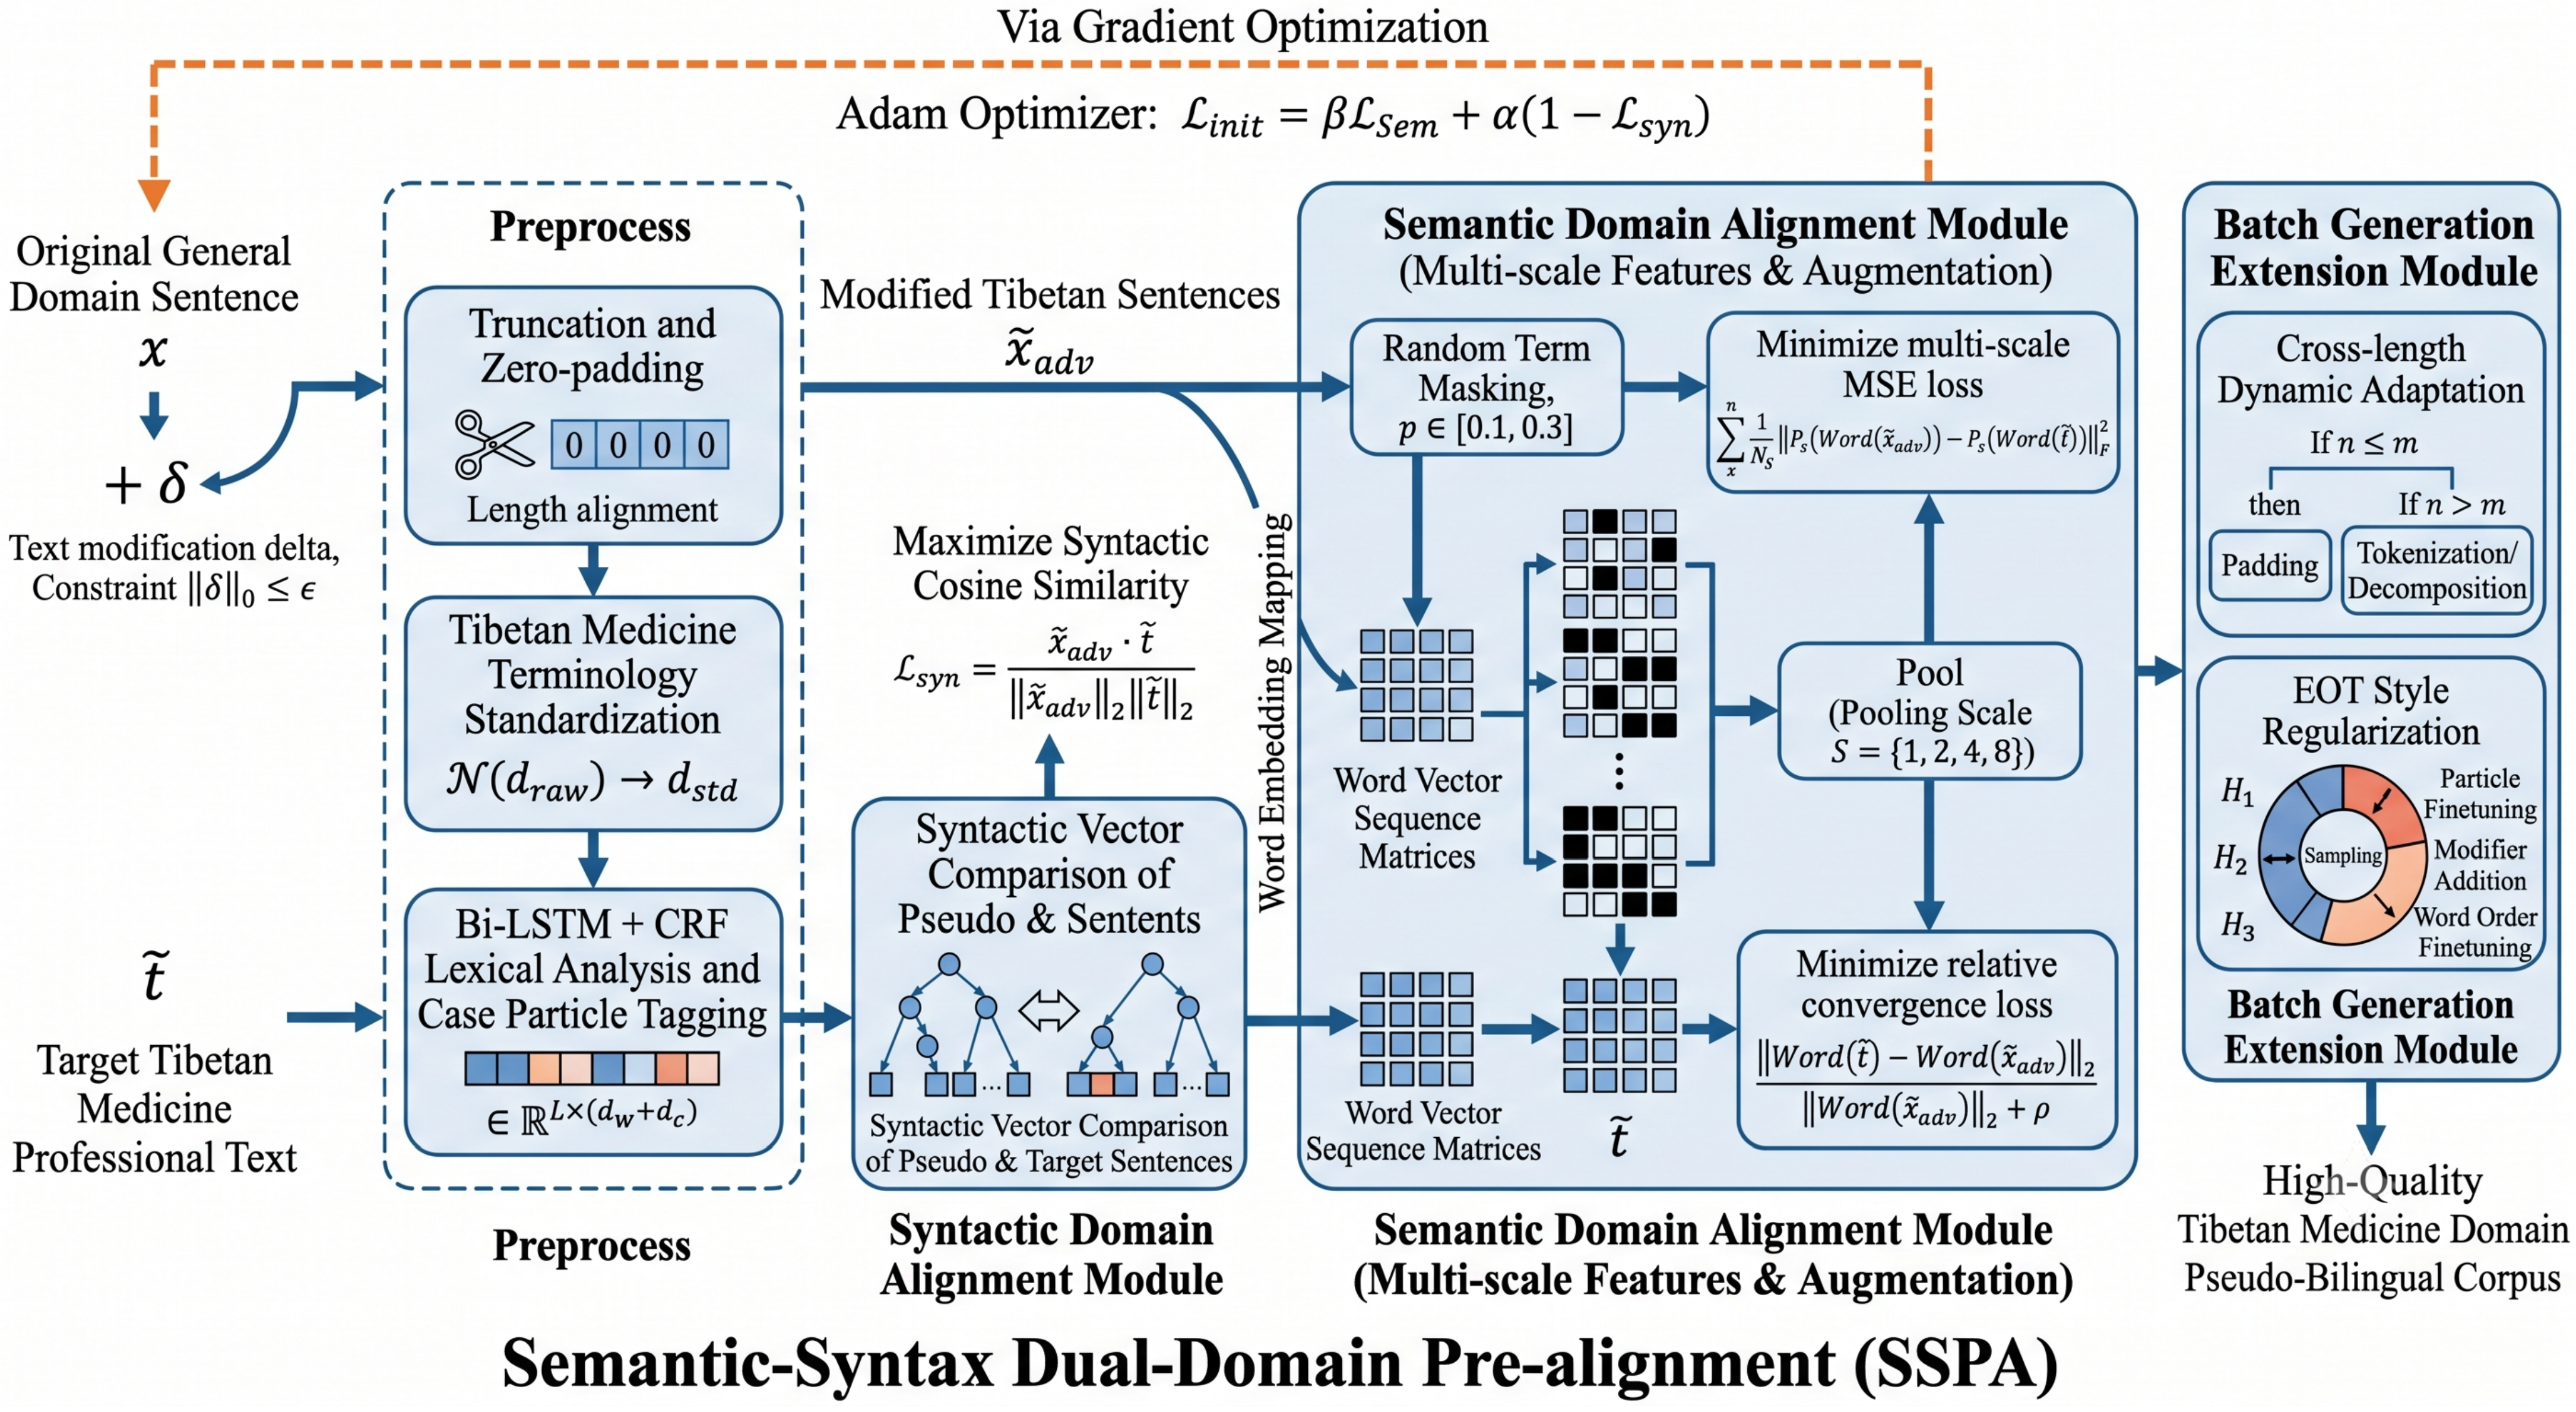
- We propose SSPA, a Tibetan low-resource pseudo-corpus generation framework based on semantic-syntactic dual-domain prealignment. By jointly optimizing syntactic cosine similarity loss and multi-scale semantic loss, SSPA substantially mitigates the core issues of grammatical errors and semantic misalignment prevalent in traditional data augmentation methods.
- 2.
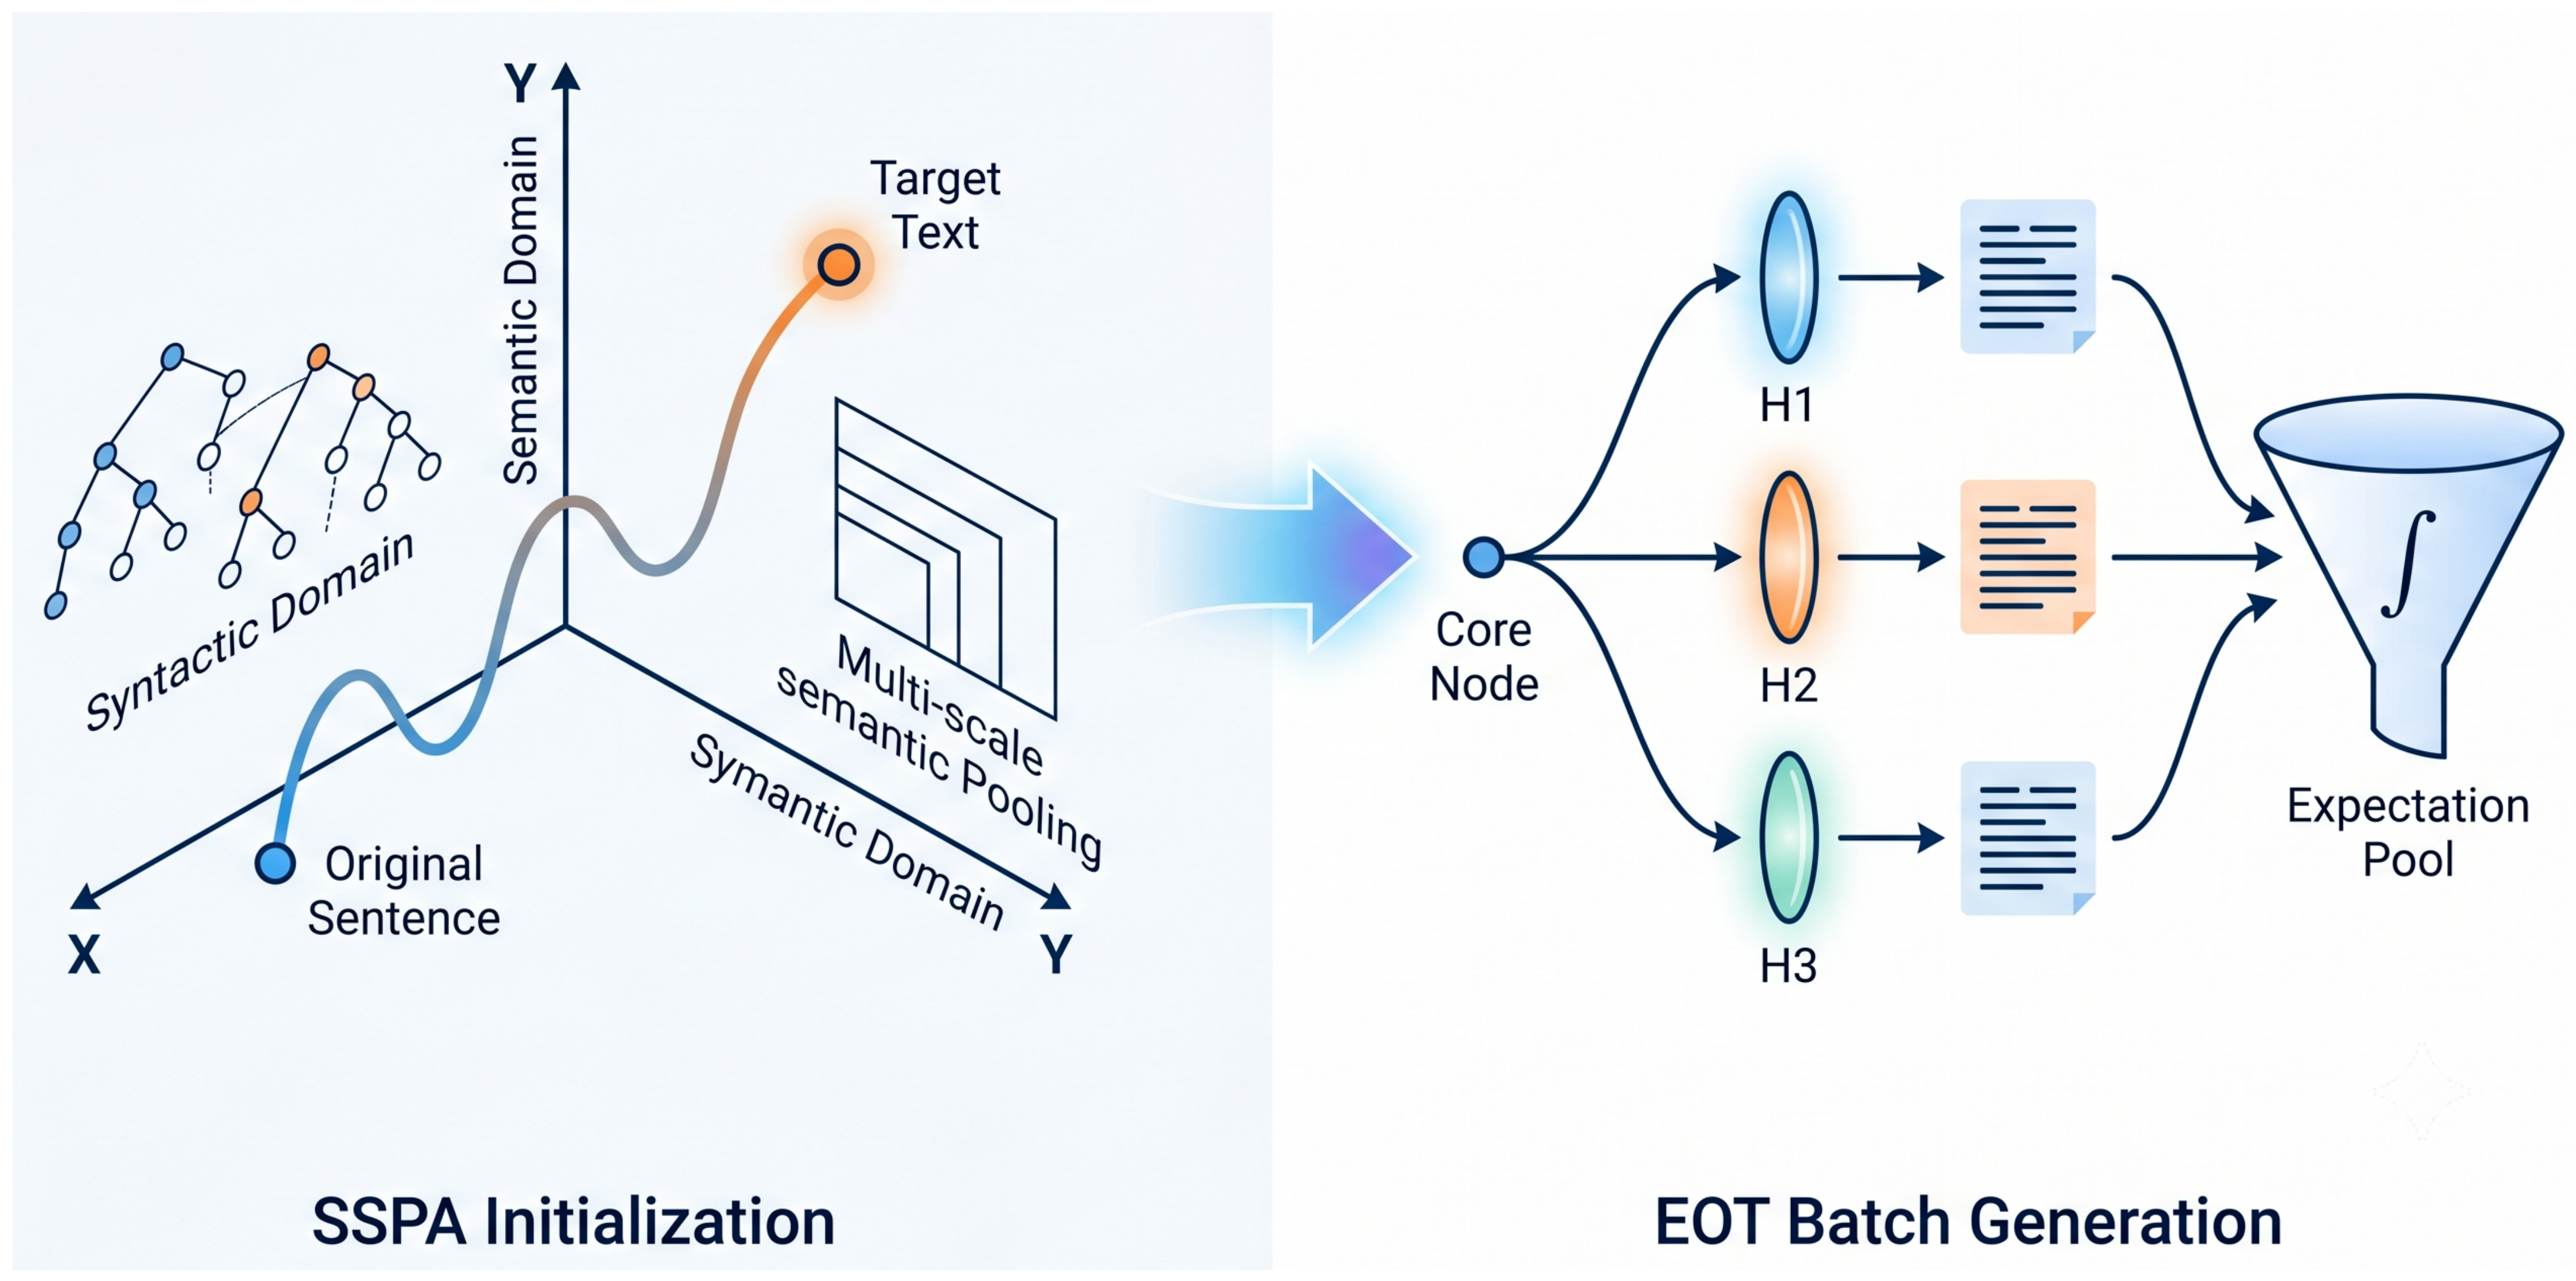
- A dynamically adaptive filling mechanism designed for cross-length domain syntactic frameworks and an EOT-style regularization module are developed. These components enable the batch generation of pseudo-parallel corpora covering diverse sub-domains using only a small set of annotated Tibetan medicine domain syntactic templates and terminology dictionaries.
- 3.
- While the data generation utilizes optimization feedback from the translation model via a differentiable Gumbel-Softmax bottleneck, the SSPA framework remains architecturally decoupled. Specifically, it avoids the necessity to modify the translation model’s internal network topology or introduce additional inference overhead. This makes our approach a versatile data augmentation solution applicable to various low-resource Tibetan translation tasks.
2. Related Work
2.1. Neural Machine Translation in Low-Resource Scenarios
2.2. Data Augmentation and Pseudo-Corpus Generation
3. Proposed Method
3.1. Framework Overview
3.2. Semantic-Syntax Prealignment
| Algorithm 1 Single-Sample SSPA Initialization Algorithm |
| Require: Original general Tibetan-English sentence x, target Tibetan medicine reference text y, maximum iteration rounds T, single-term modification constraint , learning rate , static global word embedding matrix Ensure: Pseudo-sentence modification increment optimized via dual-domain alignment |
|
3.3. Robust Batch Pseudo-Corpus Generation
3.3.1. Dynamic Syntactic Length Adaptation
3.3.2. EOT-Based Robust Optimization
3.3.3. Bilingual Collaborative Response Under EOT Perturbations
- 1.
- Silent Absorption of Semantically Equivalent Transformations: If the perturbation only involves changes in synonymous case markers unique to Tibetan (e.g., replacing a conjunctive case marker), the English target remains unchanged. This silent absorption accurately models “many-to-one” semantic equivalence, compelling the translation model to learn semantic invariance amidst complex Tibetan morphological noise.
- 2.
- Joint Mapping of Explicit Modifiers: If the transformation explicitly adds or deletes modifiers (e.g., adding an adjective indicating “acute/severe” before a disease name), the system synchronously triggers a predefined English attachment rule base to attach or remove the corresponding English modifier at the aligned syntax tree node.
| Algorithm 2 Robust Batch Pseudo-Corpus Generation Algorithm |
| Require: Initial template set , Reference , Standardized syntactic vector , Term dictionary , Transformation H, Iterations , constraint , rate , static word embedding matrix Ensure: Batch-generated pseudo-parallel corpus |
|
4. Experiments
4.1. Experimental Setup
4.1.1. Datasets
4.1.2. Training Details
4.1.3. Comparison Methods
4.1.4. Evaluation Metrics
4.2. Experimental Results and Analysis
4.2.1. Tibetan Medicine Domain Translation Performance
4.2.2. Cross-Domain Generalization Analysis
4.2.3. Human Evaluation
4.2.4. Analysis of Pseudo-Corpus Quality
4.2.5. Robustness Under Data Scale Limitation and Statistical Significance Verification
4.2.6. Morphological Robustness Evaluation
4.3. Ablation Studies
4.3.1. Ablation of Core Architecture Components
4.3.2. Effectiveness of Dual-Domain Alignment Loss
4.3.3. Sensitivity Analysis of Hyperparameters
4.3.4. Computational Overhead and Architectural Independence Analysis
4.3.5. Robustness Under Extreme Data Scarcity
4.3.6. Removal-Based Ablations of the Complete SSPA Model
4.3.7. Generalization Analysis via Leave-One-Template-Out Evaluation
5. Conclusions
- 1.
- Developing unsupervised anchor induction techniques to automatically extract syntactic frames from unannotated corpora.
- 2.
- Extending the prealignment mechanism to other low-resource agglutinative languages and professional domains to validate the framework’s broader applicability.
Author Contributions
Funding
Data Availability Statement
Use of Artificial Intelligence
Conflicts of Interest
References
- Ataman, D.; Aziz, W.; Birch, A. A Latent Morphology Model for Open-Vocabulary Neural Machine Translation. In Proceedings of the International Conference on Learning Representations, Addis Ababa, Ethiopia, 26–30 April 2020; pp. 102–114. [Google Scholar]
- Gong, Z.; Xu, X.; Zhao, Y. Tibetan–Chinese speech-to-speech translation based on discrete units. Sci. Rep. 2025, 15, 117–126. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Li, F.; Zhao, Z.; Wang, L.; Deng, H. Tibetan Sentence Boundaries Automatic Disambiguation Based on Bidirectional Encoder Representations from Transformers on Byte Pair Encoding Word Cutting Method. Appl. Sci. 2024, 14, 2989. [Google Scholar] [CrossRef] [Scilit]
- Javed, A.; Zan, H.; Mamyrbayev, O.; Abdullah, M.; Ahmed, K.; Oralbekova, D.; Dinara, K.; Akhmediyarova, A. Transformer-Based Re-Ranking Model for Enhancing Contextual and Syntactic Translation in Low-Resource Neural Machine Translation. Electronics 2025, 14, 243. [Google Scholar] [CrossRef] [Scilit]
- Liu, H.; Zhao, W.; Yu, X.; Wu, J. A Chinese to Tibetan Machine Translation System with Multiple Translating Strategies. Himal. Linguist. 2016, 15, 149–166. [Google Scholar] [CrossRef] [Scilit]
- Sun, Y.; Liu, S.; Deng, J.; Zhao, X. TiBERT: Tibetan Pre-trained Language Model. In Proceedings of the 2022 IEEE International Conference on Systems, Man, and Cybernetics (SMC), Prague, Czech Republic, 9–12 October 2022; pp. 2956–2961. [Google Scholar]
- Liu, R.; Zhao, Y.; Xu, X. Multi-Task Self-Supervised Learning Based Tibetan-Chinese Speech-to-Speech Translation. In Proceedings of the 2023 International Conference on Asian Language Processing (IALP), Singapore, 18–20 November 2023; pp. 45–49. [Google Scholar] [CrossRef] [Scilit]
- Zhou, M.; Gesang, Q.; Qun, N.; Nyima, T.; Rinchen, D. Tibetan-Chinese Machine Translation Enhanced on Cross-Lingual Pre-Trained Model. In Proceedings of the 2024 IEEE International Conference on Systems, Man, and Cybernetics (SMC), Kuching, Malaysia, 6–10 October 2024; pp. 1618–1623. [Google Scholar] [CrossRef] [Scilit]
- He, C.; Gesang, Q.; Qun, N.; Luosang, G.; Nyima, T. Research on Tibetan-Chinese Machine Translation Method Based on Graphic Multimodal Fusion Alignment. In Proceedings of the 2024 6th International Conference on Internet of Things, Automation and Artificial Intelligence (IoTAAI), Guangzhou, China, 26–28 July 2024; pp. 714–717. [Google Scholar] [CrossRef] [Scilit]
- Zhou, M. Research on Tibetan-Chinese Neural Machine Translation Integrating Statistical Method. In Proceedings of the 2023 6th International Conference on Machine Learning and Natural Language Processing; MLNLP ’23; Association for Computing Machinery: New York, NY, USA, 2024; pp. 126–129. [Google Scholar] [CrossRef] [Scilit]
- Wang, Q.; Wang, Y.; Amini, M.; Xian, M.; Fu, Z. Quality assessment of Tibetan–Chinese poetry translation: Integrating automated metrics and qualitative insights through a cross-system comparison of dedicated NMT engines and a prompted LLM. Lang. Resour. Eval. 2026, 60, 42. [Google Scholar] [CrossRef] [Scilit]
- Ganesh, S.; Dhotre, V.; Patil, P.; Pawade, D. A Comprehensive Survey of Machine Translation Approaches. In Proceedings of the 2023 6th International Conference on Advances in Science and Technology (ICAST), Mumbai, India, 8–9 December 2023; pp. 160–165. [Google Scholar] [CrossRef] [Scilit]
- Fraser, A.; Weller, M.; Cahill, A.; Cap, F. Modeling Inflection and Word Formation in SMT. In Proceedings of the 13th Conference of the European Chapter of the Association for Computational Linguistics, Avignon, France, 23–27 April 2012; pp. 664–674. [Google Scholar]
- Dyer, C.; Chahuneau, V.; Smith, N.A. A Simple, Fast, and Effective Reparameterization of IBM Model 2. In Proceedings of the 2013 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Atlanta, GA, USA, 9–14 June 2013; pp. 644–648. [Google Scholar]
- Zhuoma, C.; Jia, C.; Sangjie, D.; Yangmao, Z.; Zhuoma, Z. Tibetan medical named entity recognition study for Tibetan clinical electronic medical records. In Proceedings of the Conference on Computer Science and Communication Technology, Beijing, China, 30–31 July 2022; pp. 1132–1141. [Google Scholar]
- Hwang, Y.S.; Watanabe, T.; Sasaki, Y. Empirical study of utilizing morph-syntactic information in SMT. In Proceedings of the Second International Joint Conference on Natural Language Processing; IJCNLP’05; Springer: Berlin/Heidelberg, Germany, 2005; pp. 474–485. [Google Scholar] [CrossRef] [Scilit]
- Vinh, N.; Nguyen, P.T.; Nguyen, V.; Ha, T.L.; Nguyen, L. An Efficient Method for Generating Synthetic Data for Low-Resource Machine Translation. Appl. Artif. Intell. 2022, 36, 2101755. [Google Scholar] [CrossRef] [Scilit]
- Liu, S.; Zhu, J.; Li, Z.; Luo, Z. Research on Tibetan-Chinese Machine Translation Based on Multi-Strategy Processing. In Proceedings of the 2021 IEEE 2nd International Conference on Pattern Recognition and Machine Learning (PRML), Chengdu, China, 16–18 July 2021; pp. 292–297. [Google Scholar] [CrossRef] [Scilit]
- Jiang, T.; Sun, H.; Dai, Y.G.; Liu, D. Tibetan-Chinese Neural Machine Translation Combining Attention Mechanism. J. Phys. Conf. Ser. 2020, 1607, 012001. [Google Scholar] [CrossRef] [Scilit]
- Vaswani, A.; Shazeer, N.; Parmar, N.; Uszkoreit, J.; Jones, L.; Gomez, A.N.; Kaiser, L.; Polosukhin, I. Attention is all you need. In Proceedings of the 31st International Conference on Neural Information Processing Systems; NIPS’17; Curran Associates Inc.: Red Hook, NY, USA, 2017; pp. 6000–6010. [Google Scholar]
- Cho, K.; van Merriënboer, B.; Gulcehre, C.; Bahdanau, D.; Bougares, F.; Schwenk, H.; Bengio, Y. Learning Phrase Representations using RNN Encoder–Decoder for Statistical Machine Translation. In Proceedings of the 2014 Conference on Empirical Methods in Natural Language Processing (EMNLP), Doha, Qatar, October 2014; Moschitti, A., Pang, B., Daelemans, W., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2014; pp. 1724–1734. [Google Scholar] [CrossRef] [Scilit]
- Sutskever, I.; Vinyals, O.; Le, Q.V. Sequence to sequence learning with neural networks. In Proceedings of the 28th International Conference on Neural Information Processing Systems; NIPS’14; MIT Press: Cambridge, MA, USA, 2014; Volume 2, pp. 3104–3112. [Google Scholar]
- Bahdanau, D.; Cho, K.; Bengio, Y. Neural Machine Translation by Jointly Learning to Align and Translate. arXiv 2014, arXiv:1409.0473. [Google Scholar]
- Chu, C.; Wang, R. A Survey of Domain Adaptation for Neural Machine Translation. arXiv 2018, arXiv:1806.00258. [Google Scholar]
- Zhang, J.; Gao, F.; Yeshi, L.; Tashi, D.; Wang, X.; Tashi, N.; Luosang, G. Cross-Domain Tibetan Named Entity Recognition via Large Language Models. Electronics 2025, 14, 111. [Google Scholar] [CrossRef] [Scilit]
- Britz, D.; Le, Q.; Pryzant, R. Effective Domain Mixing for Neural Machine Translation. In Proceedings of the Second Conference on Machine Translation, Copenhagen, Denmark, 7–8 September 2017; pp. 118–126. [Google Scholar] [CrossRef] [Scilit]
- Zhou, L.; Gao, H.; Gao, D.; Zhao, Q. Recognition of Ellipsoid-like Herbaceous Tibetan Medicinal Materials Using DenseNet with Attention and ILBP-Encoded Gabor Features. Entropy 2023, 25, 847. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Pecina, P.; Toral, A.; Papavassiliou, V.; Prokopidis, P.; Tamchyna, A.; Way, A.; Van Genabith, J. Domain adaptation of statistical machine translation with domain-focused web crawling. Lang. Resour. Eval. 2015, 49, 147–193. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Miceli Barone, A.V.; Haddow, B.; Germann, U.; Sennrich, R. Regularization techniques for fine-tuning in neural machine translation. In Proceedings of the 2017 Conference on Empirical Methods in Natural Language Processing, Copenhagen, Denmark, September 2017; Palmer, M., Hwa, R., Riedel, S., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2017; pp. 1489–1494. [Google Scholar] [CrossRef] [Scilit]
- Liang, J.; Zhao, C.; Wang, M.; Qiu, X.; Li, L. Finding Sparse Structures for Domain Specific Neural Machine Translation. In Proceedings of the AAAI Conference on Artificial Intelligence, 2021; Association for the Advancement of Artificial Intelligence: Washington, DC, USA, 2021; Volume 35, pp. 13333–13342. [Google Scholar] [CrossRef] [Scilit]
- Liu, Y.; Wang, H.; Zhou, H.; Li, M.; Hou, Y.; Zhou, S.; Wang, F.; Hoetzlein, R.; Zhang, R. A review of reinforcement learning for natural language processing and applications in healthcare. J. Am. Med. Inform. Assoc. 2024, 31, 2379–2393. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Saunders, D.; DeNeefe, S. Domain adapted machine translation: What does catastrophic forgetting forget and why? In Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing, Miami, FL, USA, November 2024; Al-Onaizan, Y., Bansal, M., Chen, Y.N., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2024; pp. 12660–12671. [Google Scholar] [CrossRef] [Scilit]
- Liu, Y.; Zhang, L.; Zhang, Y. Neural Machine Translation Transfer Model Based on Mutual Domain Guidance. IEEE Access 2022, 10, 101595–101608. [Google Scholar] [CrossRef] [Scilit]
- Abdulmumin, I.; Galadanci, B.; Isah, A.; Kakudi, H.; Sinan, I. A Hybrid Approach for Improved Low Resource Neural Machine Translation using Monolingual Data. Eng. Lett. 2021, 29, 1478–1493. [Google Scholar] [CrossRef] [Scilit]
- Tran, K.T.; O’Sullivan, B.; Nguyen, H. Irish-based Large Language Model with Extreme Low-Resource Settings in Machine Translation. In Proceedings of the Seventh Workshop on Technologies for Machine Translation of Low-Resource Languages (LoResMT 2024), Bangkok, Thailand, August 2024; Ojha, A.K., Liu, C.H., Vylomova, E., Pirinen, F., Abbott, J., Washington, J., Oco, N., Malykh, V., Logacheva, V., Zhao, X., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2024; pp. 193–202. [Google Scholar] [CrossRef] [Scilit]
- Razuvayevskaya, O.; Wu, B.; Leite, J.A.; Heppell, F.; Srba, I.; Scarton, C.; Bontcheva, K.; Song, X. Comparison between parameter-efficient techniques and full fine-tuning: A case study on multilingual news article classification. PLoS ONE 2024, 19, e0301738. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Zhou, S.; Zeng, X.; Zhou, Y.; Anastasopoulos, A.; Neubig, G. Improving Robustness of Neural Machine Translation with Multi-task Learning. In Proceedings of the Fourth Conference on Machine Translation (Volume 2: Shared Task Papers, Day 1), Florence, Italy, August 2019; Bojar, O., Chatterjee, R., Federmann, C., Fishel, M., Graham, Y., Haddow, B., Huck, M., Yepes, A.J., Koehn, P., Martins, A., et al., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2019; pp. 565–571. [Google Scholar] [CrossRef] [Scilit]
- Lin, K.Y.; Zhou, J.; Qiu, Y.; Zheng, W.S. Adversarial Partial Domain Adaptation by Cycle Inconsistency. In Proceedings of the Computer Vision—ECCV 2022; Lecture Notes in Computer Science; Avidan, S., Brostow, G., Cissé, M., Farinella, G.M., Hassner, T., Eds.; Springer Nature: Cham, Switzerland, 2022; Volume 13693, pp. 1451–1463. [Google Scholar] [CrossRef] [Scilit]
- Sennrich, R.; Haddow, B.; Birch, A. Improving Neural Machine Translation Models with Monolingual Data. In Proceedings of the 54th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers); Association for Computational Linguistics: Stroudsburg, PA, USA, 2016; pp. 86–96. [Google Scholar] [CrossRef] [Scilit]
- Hoang, V.; Koehn, P.; Haffari, G. Iterative Back-Translation for Neural Machine Translation. In Proceedings of the 2nd Workshop on Neural Machine Translation and Generation; Association for Computational Linguistics: Stroudsburg, PA, USA, 2018; pp. 18–24. [Google Scholar] [CrossRef] [Scilit]
- Edunov, S.; Ott, M.; Auli, M.; Grangier, D. Understanding Back-Translation at Scale. In Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing; Association for Computational Linguistics: Stroudsburg, PA, USA, 2018; pp. 489–500. [Google Scholar] [CrossRef] [Scilit]
- Liu, Y.; Gu, J.; Goyal, N.; Li, X.; Edunov, S.; Ghazvininejad, M.; Lewis, M.; Zettlemoyer, L. Multilingual Denoising Pre-training for Neural Machine Translation. Trans. Assoc. Comput. Linguist. 2020, 8, 726–742. [Google Scholar] [CrossRef] [Scilit]
- Conneau, A.; Khandelwal, K.; Goyal, N.; Chaudhary, V.; Wenzek, G.; Guzmán, F.; Grave, E.; Ott, M.; Zettlemoyer, L.; Stoyanov, V. Unsupervised Cross-lingual Representation Learning at Scale. In Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics, Online, 5–10 July 2020; pp. 8440–8451. [Google Scholar]
- Houlsby, N.; Giurgiu, A.; Jastrzebski, S.; Morrone, B.; De Laroussilhe, Q.; Gesmundo, A.; Attariyan, M.; Gelly, S. Parameter-Efficient Transfer Learning for NLP. In Proceedings of the International Conference on Machine Learning (ICML); PMLR: New York, NY, USA, 2019; pp. 2790–2799. [Google Scholar]
- Hu, E.J.; Shen, Y.; Wallis, P.; Allen-Zhu, Z.; Li, Y.; Wang, S.; Wang, L.; Chen, W. LoRA: Low-Rank Adaptation of Large Language Models. In Proceedings of the International Conference on Learning Representations (ICLR), Virtual, 25–29 April 2022. [Google Scholar]
- Li, X.L.; Liang, P. Prefix-Tuning: Optimizing Continuous Prompts for Generation. In Proceedings of the 59th Annual Meeting of the Association for Computational Linguistics and the 11th International Joint Conference on Natural Language Processing (Volume 1: Long Papers); Association for Computational Linguistics: Stroudsburg, PA, USA, 2021; pp. 4582–4597. [Google Scholar]
- Khayrallah, H.; Koehn, P. On the Impact of Various Types of Noise on Neural Machine Translation. In Proceedings of the 2nd Workshop on Neural Machine Translation and Generation; Association for Computational Linguistics: Stroudsburg, PA, USA, 2018; pp. 74–83. [Google Scholar] [CrossRef] [Scilit]
- Brown, T.; Mann, B.; Ryder, N.; Subbiah, M.; Kaplan, J.D.; Dhariwal, P.; Neelakantan, A.; Shyam, P.; Sastry, G.; Askell, A.; et al. Language models are few-shot learners. Adv. Neural Inf. Process. Syst. 2020, 33, 1877–1901. [Google Scholar] [CrossRef] [Scilit]
- Raffel, C.; Shazeer, N.; Roberts, A.; Lee, K.; Narang, S.; Matena, M.; Zhou, Y.; Li, W.; Liu, P.J. Exploring the limits of transfer learning with a unified text-to-text transformer. J. Mach. Learn. Res. 2020, 21, 5485–5551. [Google Scholar] [CrossRef] [Scilit]
- Ji, Z.; Lee, N.; Frieske, R.; Yu, T.; Su, D.; Xu, Y.; Ishii, E.; Bang, Y.; Madotto, A.; Fung, P. Survey of hallucination in natural language generation. ACM Comput. Surv. 2023, 55, 1–38. [Google Scholar] [CrossRef] [Scilit]
- Lample, G.; Conneau, A.; Denoyer, L.; Ranzato, M. Unsupervised Machine Translation Using Monolingual Corpora Only. In Proceedings of the International Conference on Learning Representations (ICLR), Vancouver, BC, Canada, 30 April–3 May 2018. [Google Scholar]
- Gyatso, K.; Liu, P.; Jing, Y.; Li, Y.; Tashi, N.; Xiao, T.; Zhu, J. CCMT2023 Tibetan-Chinese Machine Translation Evaluation Technical Report. In Machine Translation; Feng, Y., Feng, C., Eds.; Communications in Computer and Information Science; Springer: Singapore, 2023; Volume 1922, pp. 28–36. [Google Scholar] [CrossRef] [Scilit]
- Paszke, A.; Gross, S.; Massa, F.; Lerer, A.; Bradbury, J.; Chanan, G.; Killeen, T.; Lin, Z.; Gimelshein, N.; Antiga, L.; et al. PyTorch: An Imperative Style, High-Performance Deep Learning Library. In Advances in Neural Information Processing Systems; Curran Associates Inc.: Red Hook, NY, USA, 2019; Volume 32, pp. 8024–8035. [Google Scholar]
- Kingma, D.P.; Ba, J. Adam: A Method for Stochastic Optimization. arXiv 2014, arXiv:1412.6980. [Google Scholar]
- Costa-jussà, M.R.; Cross, J.; Çelebi, O.; Elbayad, M.; Heafield, K.; Heffernan, K.; Kalbassi, E.; Krishnan, J.; Lignos, C.; Lam, J.; et al. No Language Left Behind: Scaling Human-Centered Machine Translation. arXiv 2022, arXiv:2207.04672. [Google Scholar]
- Cui, Y.; Che, W.; Liu, T.; Qin, B.; Wang, S.; Hu, G. CINO: A Chinese Minority Pre-trained Language Model. In Proceedings of the 29th International Conference on Computational Linguistics, Gyeongju, Republic of Korea, 12–17 October 2022; pp. 5687–5698. [Google Scholar]
- Guo, D.; Kim, Y.; Rush, A.M. Sequence-Level Mixed Sample Data Augmentation. In Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP), Online, 16–20 November 2020; pp. 5547–5552. [Google Scholar] [CrossRef] [Scilit]
- Touvron, H.; Lavril, T.; Izacard, G.; Martinet, X.; Lachaux, M.A.; Lacroix, T.; Rozière, B.; Goyal, N.; Hambro, E.; Azhar, F.; et al. Llama: Open and Efficient Foundation Language Models. arXiv 2023, arXiv:2302.13971. [Google Scholar]
- Kim, Y.; Rush, A.M. Sequence-Level Knowledge Distillation. In Proceedings of the 2016 Conference on Empirical Methods in Natural Language Processing; Association for Computational Linguistics: Stroudsburg, PA, USA, 2016; pp. 1317–1327. [Google Scholar] [CrossRef] [Scilit]
- Post, M. A Call for Clarity in Reporting BLEU Scores. In Proceedings of the Third Conference on Machine Translation: Research Papers; Association for Computational Linguistics: Stroudsburg, PA, USA, 2018; pp. 186–191. [Google Scholar] [CrossRef] [Scilit]



| Method | Content/Translation Output |
|---|---|
| Example 1 | |
| Tibetan Source | རླུང་ནད་ཀྱིས་མགོ་འཁོར་ཞིང་ལུས་ཤུགས་ཉམས། |
| Transformer | The wind disease causes dizziness and weakness. |
| General Back-Translation | Wind disorder leads to dizziness and fatigue. |
| SSPA (Ours) | Rlung imbalance manifests as vertigo and constitutional lassitude. |
| Example 2 | |
| Tibetan Source | སྨན་འདི་མཁྲིས་པའི་ནད་དང་ཕོ་བའི་ནད་ལ་ཕན་པ་ཡོད། |
| Transformer | This medicine is good for bile disease and stomach disease. |
| General Back-Translation | This remedy benefits bile disorders and stomach illnesses. |
| SSPA (Ours) | This decoction is indicated for tripa imbalance and gastric disorders. |
| Example 3 | |
| Tibetan Source | སྨན་པས་སྨན་རྫས་བཞི་བསྡེབས་ནས་སྨན་བཟོ་བ། |
| Transformer | The doctor uses four herbs to make medicine. |
| General Back-Translation | Physicians prepare medicine with four medicinal herbs. |
| SSPA (Ours) | Practitioners compound the formulation using four herbal ingredients. |
| Processing Phase | Specific Content Display | In-Depth Mechanism Explanation |
|---|---|---|
| 1. Original Pair/Template Extraction | Original Tibetan reference: ཨ་རུ་ར་འདི་ནི་ནད་དང་རིམས་ལ་ཕན་ནོ། Original English reference: This medicine is effective in treating illness and plague. Abstract bilingual template (Tibetan): [S1_Med] འདི་ནི་ [P1_Dis] དང་ [P2_Dis] ལ་ཕན་ནོ། Abstract bilingual template (English): This [S1_Med] is effective in treating [P1_Dis] and [P2_Dis]. | The system performs morphological disassembly on original high-quality domain sentences. Specific medical entities are stripped while preserving core Tibetan case markers (e.g., “དང་”, “ལ་”) and the English predicate structure, forming strictly hard-bound isomorphic placeholder templates. |
| 2. Selected Terms and Mapping | Tibetan terms: 1. གྲུམ་བུ. 2. ཚད་པ. 3. གུར་གུམ. English mapped terms: 1. Rheumatism. 2. Fever. 3. Saffron. | Terms are sampled from a professional dictionary. The system obtains uniquely corresponding English translations via direct dictionary mapping, reliably preventing reliance on fuzzy inference or external translation models. |
| 3. Intermediate Semantic-Syntactic Representation Reconstruction | Tibetan syntax dependency control vectors: - Node_S: [S1_Med] - Node_V: ཕན་ནོ། - Node_O: [P1_Dis] དང་ [P2_Dis] + ལ་ English syntax vector synchronous constraints: - Node_S: This [S1_Med] - Node_V: is effective in treating - Node_O: [P1_Dis] and [P2_Dis] | Memory addresses of placeholders are locked using parts of speech and case marker boundaries. Because the slots align in this instance, no truncation or zero-padding operation is activated. |
| 4. Modified Tibetan Sentence Generation | Generated modified Tibetan sentence: གུར་གུམ་འདི་ནི་གྲུམ་བུ་དང་ཚད་པ་ལ་ཕན་ནོ། | Terms are embedded into the template. The conjunctive marker “དང་” and objective case marker “ལ་” are correctly attached, ensuring no agglutinative rules are violated, forming a grammatically valid declarative sentence. |
| 5. Final English Target Synchronous Updating | Generated final English target sentence: This saffron is effective in treating rheumatism and fever. | Utilizing the explicit bilingual mapping mechanism, the English side executes strict isomorphic replacement within the English syntactic space without retaining original literature terms. |
| Configuration Specification | CINO Transformer/SSPA Backbone | NLLB-200 (Few-Shot Baseline) | SemiAdapt-LoRA | Tagged Back-Translation (via LLaMA-3) |
|---|---|---|---|---|
| Exact Model/Checkpoint | hfl/cino-base-v2 | facebook/nllb-200-distilled-600M | hfl/cino-base-v2 + LoRA Matrix | meta-llama/Meta-Llama-3-8B |
| Architecture Type | Dense Encoder-Decoder | Dense Encoder-Decoder | Dense Encoder-Decoder w/PEFT | Decoder-only LLM |
| Parameter Count | ∼186 Million | ∼600 Million (Distilled Version) | Base: 186M + Trainable: ∼6M | ∼8 Billion Parameters |
| Tokenizer Model | SentencePiece (BPE) | NLLB specific SP Tokenizer | SentencePiece (BPE) | BPE (Tiktoken) |
| Vocabulary Size | 25,000 (Optimized for Tibetan) | 256,206 (200-language capacity) | 25,000 | 128,000 |
| Number of Authentic Pairs | 200,000 (News) + 400 (Train) | 200,000 (News) + 400 (Train) | 200,000 (News) + 400 (Train) | N/A (Zero/Few-shot Generative) |
| Number of Pseudo-Pairs | 5000 (via SSPA Dual-domain) | 5000 (via SeqMix/Random) | 5000 (via Random Word Replacement) | N/A |
| Training Epochs | Max 30 Epochs | Max 15 Epochs | Max 30 Epochs | N/A (Inference-only prompts) |
| Learning Rate (Peak) | 0.002 | N/A | 0.002 (Applied to Adapters) | N/A |
| LR Schedule & Optimizer | Inverse Sq-Root/Adam | Linear Decay/AdamW | Cosine Annealing/AdamW | N/A |
| Warmup Steps | 4000 steps | 2500 steps | 4000 steps | N/A |
| Global Batch Size | 64 (Gradient Accumulation) | 32 (Due to the 600M-parameter memory footprint) | 64 | N/A |
| Specific Hyperparameters | Max modified words | Beam Size = 4, Rep. Penalty = 1.2 | LoRA Rank, Alpha | Temperature = 0.1, Top-p = 0.9 |
| Early-Stopping Rule | Patience = 5 (Monitored on Val Loss) | Patience = 3 (Monitored on Val Loss) | Patience = 5 (Monitored on Val Loss) | N/A |
| Model-Selection Criterion | Highest Val BLEU Score | Highest Val BLEU Score | Highest Val BLEU Score | N/A |
| Random Seeds | 12345 (Fixed for reproducibility) | 12345 | 12345 | N/A |
| Method | TM-TE (Medical Domain) | CCMT2020 | CCMT2023 | |||
|---|---|---|---|---|---|---|
| BLEU-4 | TER | CHRF++ | BLEU-4 | BLEU-4 | ||
| Pre-trained Model | NLLB-200 | 16.8 ± 0.0 | 65.2 ± 0.0 | 35.7 ± 0.0 | 32.7 ± 0.0 | 32.0 ± 0.0 |
| Transformer | Base CINO Transformer (No Augmentation) | 22.1 ± 0.5 | 58.3 ± 0.6 | 41.5 ± 0.4 | 38.7 ± 0.6 | 37.2 ± 0.5 |
| Data Augmentation | SeqMix | 25.7 ± 1.1 | 53.2 ± 1.2 | 45.8 ± 1.0 | 50.3 ± 1.3 | 48.6 ± 1.2 |
| LLaMA-3 (Zero-shot) | 24.3 ± 0.0 | 54.7 ± 0.0 | 44.2 ± 0.0 | 49.5 ± 0.0 | 39.8 ± 0.0 | |
| Tagged Back Translation | 28.9 ± 0.8 | 49.6 ± 0.9 | 49.1 ± 0.7 | 40.2 ± 0.9 | 38.6 ± 0.8 | |
| Domain Adaptation | SemiAdapt-LoRA | 27.5 ± 0.6 | 51.3 ± 0.7 | 47.6 ± 0.5 | 36.5 ± 0.6 | 35.1 ± 0.5 |
| Knowledge Distillation | 29.2 ± 0.4 | 48.9 ± 0.5 | 49.5 ± 0.4 | 39.4 ± 0.5 | 37.9 ± 0.4 | |
| Ours | SSPA | 36.2 * ± 0.3 | 40.1 ± 0.4 | 57.3 ± 0.3 | 39.1 ± 0.4 | 37.8 ± 0.3 |
| Pseudo-Corpus Scale | CINO + Random Word Replacement | Tagged Back Translation | SSPA |
|---|---|---|---|
| 0k | 22.1 | 22.1 | 22.1 |
| 0.5k | 23.5 | 24.8 | 28.7 |
| 1k | 24.2 | 26.1 | 31.4 |
| 2k | 25.0 | 27.3 | 33.9 |
| 5k | 25.6 | 28.9 | 36.2 |
| 10k | 26.1 | 29.7 | 37.5 |
| Sentence Length | Proportion | Base CINO Transformer (No Augmentation) | Tagged Back Translation | SSPA |
|---|---|---|---|---|
| <10 words | 42% | 26.3 | 31.5 | 37.8 |
| 11–20 words | 26% | 21.7 | 28.2 | 35.9 |
| >21 words | 32% | 16.8 | 23.1 | 34.9 |
| Method | TM-TE | TM-TE | CCMT2020 | CCMT2020 | Generalization Performance Evaluation |
|---|---|---|---|---|---|
| Base CINO | 22.1 | Baseline | 38.7 | Baseline | Lacks professional domain adaptation capabilities. |
| SeqMix | 25.7 | +3.6 | 50.3 | +11.6 | Unbalanced generalization; syntactic destruction. |
| Tagged BT | 28.9 | +6.8 | 40.2 | +1.5 | Constrained by monolingual data scale/style. |
| SSPA (Ours) | 36.2 | +14.1 | 39.1 | +0.4 | Ideal zero-forgetting generalization. |
| Method | Domain Performance (BLEU-4) | Cross-Domain Avg. | Domain-SD (Penalty) | ||
|---|---|---|---|---|---|
| News | Law | Tibetan Med | |||
| NLLB-200 | 32.7 | 30.6 | 16.8 | 26.7 | ±8.6 |
| CINO Transformer | 38.7 | 26.2 | 22.1 | 29.0 | ±8.7 |
| SeqMix | 50.3 | 22.7 | 25.7 | 32.9 | ±15.2 |
| LLaMA-3 (Zero-shot) | 49.5 | 18.0 | 24.3 | 30.6 | ±16.6 |
| Tagged Back Translation | 40.2 | 24.5 | 28.9 | 31.2 | ±8.1 |
| SemiAdapt-LoRA | 36.5 | 30.2 | 27.5 | 31.4 | ±4.6 |
| Knowledge Distillation | 39.4 | 26.8 | 29.2 | 31.8 | ±6.7 |
| SSPA (Ours) | 39.1 | 28.2 | 36.2 | 34.5 | ±5.6 |
| Evaluation Dimension | SSPA Mean (SD) | KD Mean (SD) | p-Value (t-Test) | Fleiss’ | Consistency Rating |
|---|---|---|---|---|---|
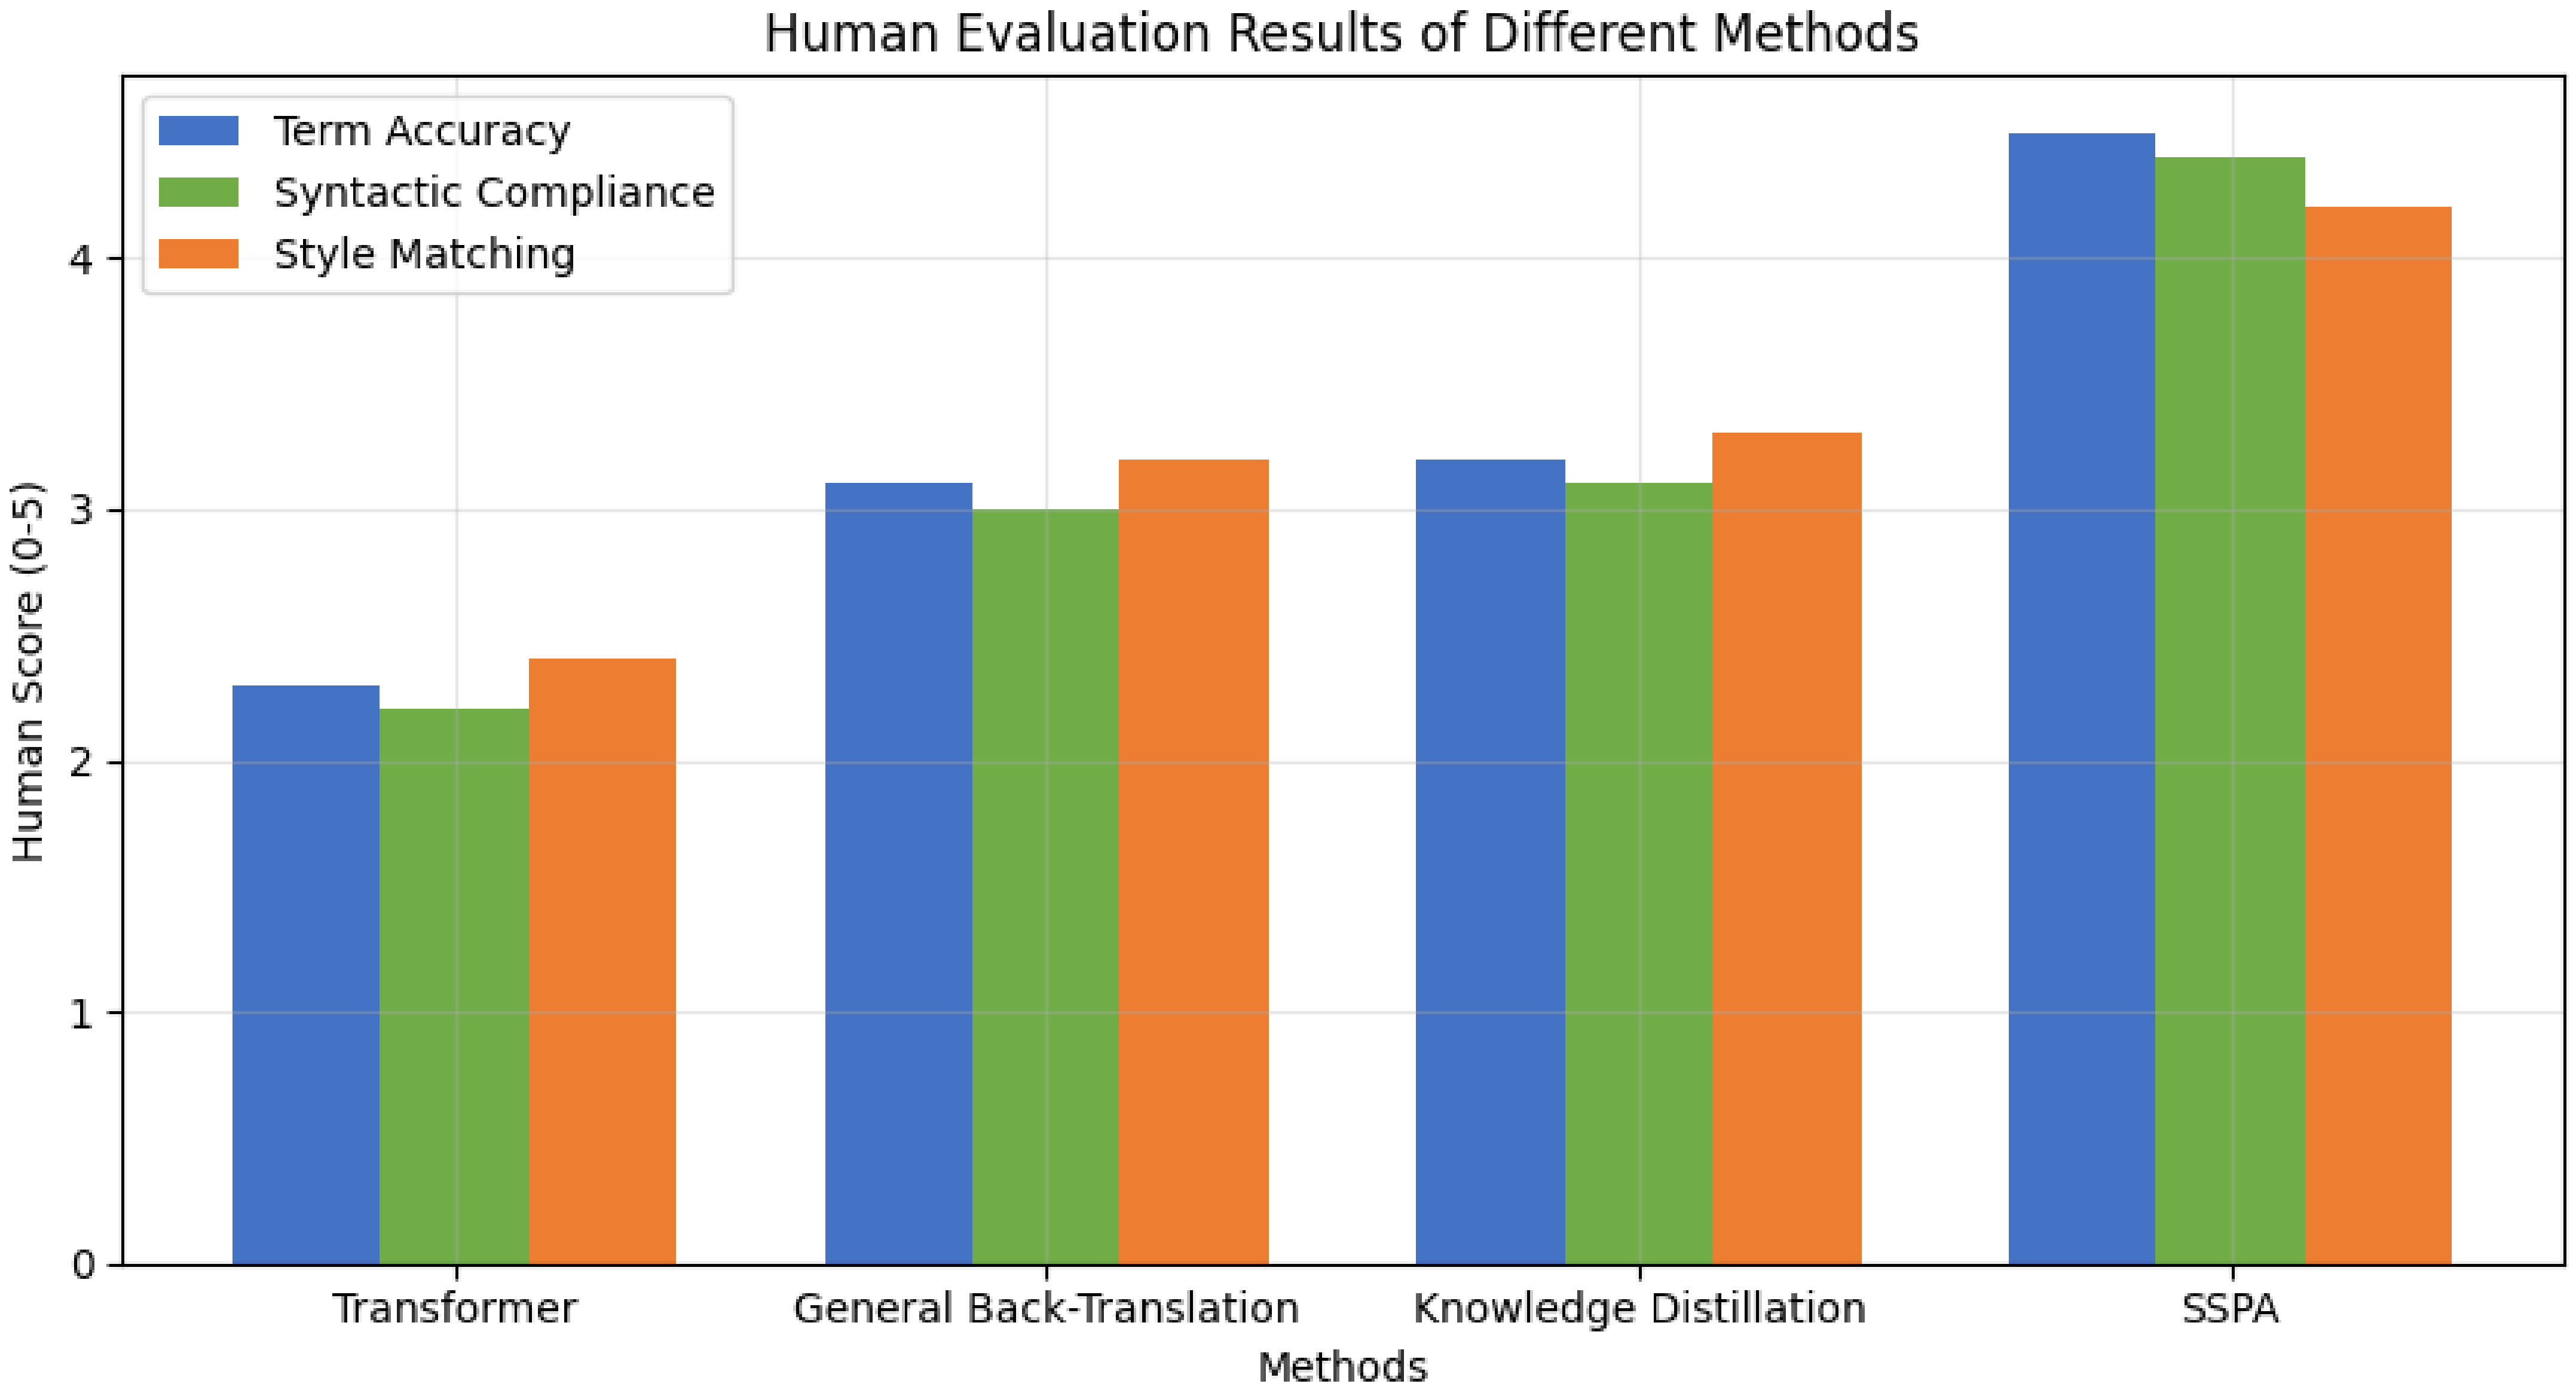
| Terminology Accuracy | 4.50 (0.42) | 3.70 (0.58) | <0.0001 | 0.882 | Almost Perfect |
| Syntactic Compliance | 4.40 (0.48) | 3.60 (0.61) | <0.0001 | 0.762 | Substantial |
| Style Matching Degree | 4.20 (0.51) | 3.50 (0.59) | <0.0001 | 0.704 | Substantial |
| Comprehensive Score | 4.37 (0.35) | 3.62 (0.41) | <0.0001 | 0.780 | Substantial |
| Injected Error Type | Precision | Recall | F1-Score | Overall Accuracy |
|---|---|---|---|---|
| Missing Case-markers | 93.4% | 95.2% | 94.3% | - |
| Mismatched Case-markers | 91.8% | 89.7% | 90.7% | - |
| Missing Constituents | 88.5% | 85.1% | 86.8% | - |
| Word Order Confusion | 85.2% | 83.6% | 84.4% | - |
| Macro-Average | 89.7% | 88.4% | 89.0% | 91.2% |
| Method | Native Parser (Bi-LSTM+CRF) | Heterogeneous Parser (XLM-R) | Domain Expert (Human) | Bias Delta |
|---|---|---|---|---|
| SeqMix | 61.5% | 59.2% | 58.6% | +2.9% |
| Tagged Back Translation | 78.3% | 76.5% | 75.1% | +3.2% |
| SSPA (Ours) | 96.2% | 95.1% | 94.8% | +1.4% |
| Method | Lexical Distribution Similarity | Syntactic Structure Similarity | Average Style Similarity |
|---|---|---|---|
| SeqMix | 0.52 | 0.38 | 0.45 |
| Tagged Back Translation | 0.67 | 0.59 | 0.63 |
| SSPA | 0.89 | 0.85 | 0.87 |
| Method | BLEU-4 | 95% Confidence Interval (Bootstrap B = 1000) | Paired Hypothesis Test against SSPA |
|---|---|---|---|
| NLLB-200 | 16.8 | [15.2, 18.5] | |
| CINO Transformer | 22.1 | [20.4, 23.8] | |
| LLaMA-3 (Zero-shot) | 24.3 | [22.6, 26.2] | |
| SeqMix | 25.7 | [24.1, 27.5] | |
| SemiAdapt-LoRA | 27.5 | [25.8, 29.3] | |
| Tagged Back Translation | 28.9 | [27.3, 30.7] | |
| Knowledge Distillation | 29.2 | [27.6, 31.0] | |
| SSPA (Ours) | 36.2 | [34.5, 37.9] | - |
| Fold ID | CINO Transformer | Tagged Back Translation | Knowledge Distillation | SSPA (Ours) |
|---|---|---|---|---|
| Fold 1 (Original Test Set) | 22.1 | 28.9 | 29.2 | 36.2 |
| Fold 2 | 21.8 | 29.1 | 28.8 | 35.8 |
| Fold 3 | 22.5 | 28.4 | 29.5 | 36.5 |
| Fold 4 | 21.4 | 27.9 | 28.6 | 35.9 |
| Fold 5 | 22.6 | 29.3 | 29.4 | 36.7 |
| Fold 6 | 21.9 | 28.5 | 29.0 | 35.5 |
| Fold 7 | 22.3 | 28.8 | 29.1 | 36.1 |
| Fold 8 | 22.0 | 28.6 | 28.9 | 36.3 |
| Fold 9 | 22.7 | 29.2 | 29.7 | 36.6 |
| Fold 10 | 21.6 | 28.2 | 28.5 | 35.7 |
| Global Mean ± SD | 22.09 ± 0.42 | 28.69 ± 0.44 | 29.07 ± 0.38 | 36.13 ± 0.39 |
| Method | TM-TE chrF++ | CCMT2020 chrF++ | CCMT2023 chrF++ | Grammatical Compliance | Cosine Similarity |
|---|---|---|---|---|---|
| Base CINO | 41.5 | 49.8 | 48.3 | N/A | N/A |
| SeqMix | 45.8 | 53.2 | 51.7 | 61.5% | 0.52 |
| Tagged BT | 49.1 | 51.4 | 50.2 | 78.3% | 0.67 |
| SSPA (Ours) | 57.3 | 52.8 | 51.9 | 96.2% | 0.89 |
| Model Configuration | BLEU-4 | TER | CHRF++ |
|---|---|---|---|
| Base CINO Transformer (No Augmentation) | 22.1 | 58.3 | 41.5 |
| with Random Term Padding | 25.7 | 53.2 | 45.8 |
| with SSPA initialization | 31.4 | 46.7 | 52.1 |
| with Cross-length Padding | 33.8 | 43.5 | 54.7 |
| with EOT Regularization | 36.2 | 40.1 | 57.3 |
| Loss Function | BLEU-4 | TER | CHRF++ | Terminology Accuracy | Grammatical Compliance Rate |
|---|---|---|---|---|---|
| Random Initialization without constraints | 25.7 | 53.2 | 45.8 | 62.3% | 61.5% |
| only Semantic Loss | 28.3 | 50.1 | 48.6 | 71.5% | 74.2% |
| only Syntactic Loss | 27.9 | 51.4 | 47.9 | 68.7% | 82.6% |
| Fixed-Weight Dual-Domain Loss with | 30.1 | 48.2 | 50.7 | 75.2% | 89.1% |
| Adaptive-Weight Dual-Domain Loss with | 31.4 | 46.7 | 52.1 | 78.9% | 91.3% |
| BLEU-4 | TER | CHRF++ | Grammatical Compliance Rate | Average Number of Modified Words | |
|---|---|---|---|---|---|
| 1 | 29.7 | 48.2 | 50.3 | 97.8% | 0.92 |
| 2 | 31.4 | 46.7 | 52.2 | 91.3% | 1.87 |
| 3 | 30.2 | 47.7 | 50.8 | 82.5% | 2.71 |
| 4 | 28.6 | 49.8 | 49.2 | 73.1% | 3.54 |
| Pooling Scale Combinations | BLEU-4 | TER | CHRF++ | Semantic Consistency |
|---|---|---|---|---|
| {1,2} = Word, Bigram | 29.5 | 48.8 | 50.1 | 72.3% |
| {1,2,4} = Word, Bigram, Phrase | 30.7 | 47.5 | 51.4 | 76.8% |
| {1,2,4,8} = Word, Bigram, Phrase, Sentence | 31.4 | 46.7 | 52.1 | 78.9% |
| {1,2,4,8,16} = Word, Bigram, Phrase, Sentence, Long Sentence | 31.2 | 46.9 | 51.9 | 78.5% |
| Composition of the Transformation Set | BLEU-4 | TER | CHRF++ | Domain Style Similarity |
|---|---|---|---|---|
| without EOT | 33.8 | 43.5 | 54.7 | 0.79 |
| only H1 (Particle Fine-Tuning) | 34.5 | 42.7 | 55.4 | 0.82 |
| only H2 (Modifier Addition/Deletion) | 34.9 | 42.3 | 55.8 | 0.83 |
| only H3 (Word Order Fine-Tuning) | 34.2 | 43.0 | 55.1 | 0.81 |
| H1+H2+H3 (Full Transformation Set) | 36.2 | 40.1 | 57.3 | 0.87 |
| Total Scale of Generated Pseudo-Pairs | Cumulative Preprocessing (s) | Cumulative Parser (s) | Cumulative Gradient Optimization (s) | Cumulative Postprocessing (s) | End-to-End Total Time (s) | Total Time Equivalent (Minutes) |
|---|---|---|---|---|---|---|
| 500 pairs | 2.40 | 3.85 | 92.50 | 7.75 | 106.50 | ∼1.77 |
| 1000 pairs | 4.80 | 7.70 | 185.00 | 15.50 | 213.00 | ∼3.55 |
| 5000 pairs | 24.00 | 38.50 | 925.00 | 77.50 | 1065.00 | ∼17.75 |
| 10,000 pairs | 48.00 | 77.00 | 1850.00 | 155.00 | 2130.00 | ∼35.50 |
| Method | 100 Pairs | 300 Pairs | 500 Pairs | 1000 Pairs |
|---|---|---|---|---|
| SemiAdapt LoRA | 22.4 | 24.8 | 27.5 | 30.2 |
| Knowledge Distillation | 23.1 | 26.3 | 29.2 | 32.5 |
| SSPA (Ours) | 31.8 | 34.1 | 36.2 | 37.9 |
| Model Variant | BLEU-4 ↑ | Relative BLEU Loss | TER ↓ | CHRF++ ↑ | Term Accuracy (%) ↑ | Grammatical Compliance (%) ↑ |
|---|---|---|---|---|---|---|
| Full SSPA (Complete Model) | 36.2 | - | 40.1 | 57.3 | 85.4 | 96.2 |
| w/o Semantic Loss | 32.1 | −4.1 | 45.2 | 51.8 | 72.1 | 88.3 |
| w/o Syntactic Loss | 32.5 | −3.7 | 44.6 | 52.6 | 79.5 | 76.4 |
| w/o Dynamic Length Adapt. | 33.8 | −2.4 | 43.5 | 54.7 | 81.2 | 91.5 |
| w/o EOT Regularization | 33.8 | −2.4 | 43.5 | 54.7 | 82.6 | 92.8 |
| w/ Fixed Weights | 34.6 | −1.6 | 42.1 | 55.2 | 80.8 | 92.1 |
| w/ Random Templates | 29.8 | −6.4 | 47.1 | 49.8 | 66.3 | 68.2 |
| Fold (Hidden Template) | Baseline CINO (No Augmentation) | SSPA (All Templates) | SSPA (LOTO Isolated) | Performance Degradation | Absolute Net Improvement |
|---|---|---|---|---|---|
| Fold 1 | BLEU-4: 21.8 TER: 59.1 | BLEU-4: 35.8 TER: 41.2 | BLEU-4: 34.2 TER: 43.1 | BLEU-4: −1.6 TER: +1.9 | BLEU-4: +12.4 TER: −16.0 |
| Fold 2 | BLEU-4: 22.4 TER: 57.8 | BLEU-4: 36.5 TER: 39.8 | BLEU-4: 33.9 TER: 42.7 | BLEU-4: −2.6 TER: +2.9 | BLEU-4: +11.5 TER: −15.1 |
| Fold 3 | BLEU-4: 22.1 TER: 58.4 | BLEU-4: 36.1 TER: 40.5 | BLEU-4: 34.5 TER: 41.8 | BLEU-4: −1.6 TER: +1.3 | BLEU-4: +12.4 TER: −16.6 |
| Fold 4 | BLEU-4: 21.5 TER: 59.8 | BLEU-4: 35.6 TER: 41.9 | BLEU-4: 33.1 TER: 44.2 | BLEU-4: −2.5 TER: +2.3 | BLEU-4: +11.6 TER: −15.6 |
| Fold 5 | BLEU-4: 22.7 TER: 57.2 | BLEU-4: 36.9 TER: 39.0 | BLEU-4: 34.8 TER: 41.5 | BLEU-4: −2.1 TER: +2.5 | BLEU-4: +12.1 TER: −15.7 |
| Average 5-Fold | BLEU-4: 22.10 TER: 58.46 | BLEU-4: 36.18 TER: 40.48 | BLEU-4: 34.10 TER: 42.66 | BLEU-4: −2.08 TER: +2.18 | BLEU-4: +12.00 TER: −15.80 |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.
Share and Cite
Sun, Y.; Liu, D.; Zhang, J.; Wang, Y. SSPA: Enhancing Pseudo-Corpus Quality on Tibetan Machine Translation via Semantic-Syntax Prealignment. Computers 2026, 15, 576. https://doi.org/10.3390/computers15090576
Sun Y, Liu D, Zhang J, Wang Y. SSPA: Enhancing Pseudo-Corpus Quality on Tibetan Machine Translation via Semantic-Syntax Prealignment. Computers. 2026; 15(9):576. https://doi.org/10.3390/computers15090576
Chicago/Turabian StyleSun, Yidong, Dongxu Liu, Jiale Zhang, and Youcheng Wang. 2026. "SSPA: Enhancing Pseudo-Corpus Quality on Tibetan Machine Translation via Semantic-Syntax Prealignment" Computers 15, no. 9: 576. https://doi.org/10.3390/computers15090576
APA StyleSun, Y., Liu, D., Zhang, J., & Wang, Y. (2026). SSPA: Enhancing Pseudo-Corpus Quality on Tibetan Machine Translation via Semantic-Syntax Prealignment. Computers, 15(9), 576. https://doi.org/10.3390/computers15090576