Article

FuseCLIP: Semantic-Guided Multidomain Fusion for Few-Shot Radar Active Jamming Recognition

1
School of Electronics and Information Engineering, Anhui University, Hefei 230601, China
2
Xi’an Branch of China Academy of Space Technology, Xi’an 710100, China
3
School of Electronic Science, National University of Defense Technology, Changsha 410073, China
*
Author to whom correspondence should be addressed.
Remote Sens. 2026, 18(17), 2967; https://doi.org/10.3390/rs18172967
Submission received: 21 July 2026 / Revised: 20 August 2026 / Accepted: 30 August 2026 / Published: 2 September 2026
(This article belongs to the Section AI Remote Sensing)

Highlights

What are the main findings?
  • FuseCLIP combines time-domain, frequency-domain, and STFT features for few-shot radar active jamming recognition.
  • It compares fused signal features with CLIP text prototypes for classification and improves recognition under different shot numbers and JNR levels.
What are the implications of the main finding?
  • Multidomain features provide complementary information for recognizing jamming types with limited labeled samples.
  • CLIP text prototypes add semantic information and support radar anti-jamming recognition in complex electromagnetic environments.

Abstract

Radar active jamming recognition is an essential component of radar anti-jamming processing and cognitive radar decision making. As jamming categories proliferate and electromagnetic environments become more complex, collecting sufficient labeled samples for every possible jamming condition can be challenging in practical scenarios. Thus, it becomes necessary to exploit the recognition capability under few-shot conditions, especially in the face of varying jamming-to-noise ratio (JNR) and compound interference. Existing methods commonly rely on a single signal representation or treat jamming categories as discrete labels, which may underuse the complementary evidence available across signal domains and the semantic knowledge associated with jamming categories. This paper proposes FuseCLIP, a semantic-guided multidomain fusion framework for few-shot radar active jamming recognition. FuseCLIP jointly encodes time-domain sequences, frequency-domain sequences, and short-time Fourier transform (STFT) spectrograms to capture waveform, spectral, and time-varying spectral characteristics. The resulting features are adaptively fused and mapped into a unified representation space, where they are matched with fixed Contrastive Language–Image Pre-training (CLIP) text prototypes generated from task-related jamming descriptions. By combining multidomain physical information with category-level semantic priors, the proposed framework is intended to make more effective use of limited labeled data. Experiments on a simulated radar active jamming dataset under different shot numbers and JNR levels demonstrate the effectiveness of FuseCLIP relative to representative baselines. Ablation experiments further indicate the complementary contributions of the time-domain, frequency-domain, and time-frequency inputs.

1. Introduction

Radar is a fundamental sensing modality for surveillance, target detection [1,2,3], navigation, remote observation [4], etc. Its capability to acquire information under day–night and adverse-weather conditions makes it central to many civilian and defense-oriented sensing systems. With the development and widespread application of digital radio-frequency memory (DRFM) technology, modern jammers can sample and store intercepted radar signals, apply flexible modulation, and retransmit the resulting waveforms [5,6]. Such capability has enabled active jamming signals that can mask useful echoes or generate false responses, thereby degrading radar detection and tracking performance [7]. Practical jamming signals may further vary with JNR levels, parameter settings, propagation conditions, and compound interference modes.These variations can alter their observable signatures across signal domains and complicate the timely selection of countermeasures. Accurate and timely recognition of active jamming types is therefore a prerequisite for adaptive anti-jamming decision making and cognitive radar operation. A recognition error can cause a countermeasure-selection module to allocate radar resources to an inappropriate threat hypothesis; it may therefore reduce suppression effectiveness or unnecessarily disrupt normal radar processing.
Early radar-jamming recognition methods generally relied on handcrafted descriptors extracted from time-domain, frequency-domain, time–frequency, or higher-order statistical representations, followed by conventional classifiers or decision rules [8]. For example, variational mode decomposition has been used to separate deceptive-jamming signals into intrinsic mode functions, from which selected features are constructed for the recognition of DRFM-based and composite deceptive jamming [9]. Bispectrum-derived features combined with kernel density estimation and Bayesian decision theory have also been used for deception-jamming recognition [10]. Such approaches can offer useful interpretability and can be effective when signal models and operating conditions are well characterized. Nevertheless, their performance is strongly dependent on manually selected features and decision rules. Designing a feature set that remains discriminative across changing JNRs, parameter configurations, and compound jamming mechanisms is difficult; consequently, handcrafted approaches may not adequately represent the multiscale, nonstationary, and mixed characteristics of realistic active jamming signals.
With the rapid development of deep learning, data-driven representation learning has been increasingly introduced into radar-jamming recognition, providing an alternative to manually designed feature pipelines. Recent studies have explored several complementary directions, including improving the robustness of spectral representations [11], jointly modeling multiple signal components for compound-jamming recognition [12], and integrating complementary time–frequency representations [13]. In addition, a deep fusion method based on 1D-CNN and 2D-CNN was proposed for radar-jamming signal classification [14]. Further work has investigated multidomain feature interaction and fusion [15,16,17], as well as learning strategies designed for imperfect supervision or joint recognition tasks [18,19]. These studies demonstrate the potential of deep models to exploit diverse signal evidence when sufficient labeled data are available. In practical radar scenarios, however, acquiring representative labeled samples for every jamming type and operating condition is often difficult.
In radar-jamming applications, the scarcity of labeled samples across jamming types, JNRs, and parameter configurations makes the extraction of stable discriminative features and the training of reliable deep models difficult. Collecting and annotating representative samples for every operating condition can be costly, whereas novel and compound interference patterns may be sparsely observed. To alleviate these limitations, few-shot studies have explored knowledge transfer and ensemble learning [20], distillation-guided time–frequency representation learning [21], prototype-based class representation [22], and the joint use of complementary signal components [23]. These approaches improve data efficiency by transferring prior knowledge, strengthening class-level representations, or recovering complementary information from the received signal. Meanwhile, the rapid progress of foundation models and vision–language learning has created new opportunities for few-shot recognition, because their pretrained semantic knowledge can complement limited task-specific labels [24]. Vision–language models for few-shot and zero-shot recognition [25,26] have therefore been explored as a way to introduce category semantics as an additional prior beyond purely signal-driven classification.
Despite this progress, two issues remain important in few-shot recognition. First, each jamming sample contains complementary energy fluctuation characteristics, spectral distributions, and time-varying spectral structures. Time-domain sequences preserve waveform-level behavior, frequency-domain representations reveal global spectral distributions, and STFT spectrograms expose localized spectral evolution. Limiting recognition to a restricted subset of these representations can constrain the information available for learning reliable class boundaries, particularly under low-JNR conditions where a discriminative cue may be weak in one domain but remain observable in another. Second, although prototype-based, label-prior, and vision–language approaches have demonstrated the value of semantic information [27,28], the unified alignment of multidomain signal evidence with task-specific category semantics remains insufficiently explored. A framework that combines multidomain physical evidence with semantic class references may make more effective use of the limited labeled data available in few-shot settings.
To position the present work within these developments, Table 1 compares representative radar-jamming recognition approaches in terms of their input domains and training strategy.
As summarized in Table 1, multidomain fusion methods primarily integrate complementary signal features but usually do not use language-derived class references, whereas vision–language methods commonly align a time–frequency representation with textual descriptions without jointly exploiting the original time-domain and frequency-domain signal evidence. FuseCLIP is designed to bridge these two directions by adaptively fusing time-domain, frequency-domain, and STFT features and matching the resulting representation with fixed CLIP text prototypes in a unified few-shot framework.
To address these issues, this paper proposes FuseCLIP, a semantic-guided multidomain fusion framework for few-shot radar active jamming recognition. FuseCLIP jointly encodes time-domain sequences, frequency-domain sequences, and short-time Fourier transform (STFT) spectrograms, then maps their adaptively fused representation into a CLIP-guided semantic prototype space [29]. Rather than treating every class only as a discrete output index, task-related jamming descriptions are encoded by a fixed CLIP text encoder to form text prototypes. Classification is then performed through similarity matching between the fused signal representation and these semantic prototypes. This design combines the complementary physical observations available from multiple signal domains with category-level information conveyed by textual descriptions. The main contributions of this work can be summarized as follows:
  • A three-domain signal representation framework is developed to jointly exploit complementary waveform, spectral, and time–frequency characteristics for radar active jamming recognition.
  • An adaptive fusion and semantic-prototype matching strategy is introduced to align multidomain signal features with task-related textual descriptions, incorporating category-level semantic priors beyond discrete label indices in few-shot learning.
  • The effectiveness of FuseCLIP is evaluated under different numbers of labeled training samples and JNR levels through comparisons with representative baselines, ablation experiments, and feature-distribution visualizations.
The remainder of this paper is organized as follows. Section 2 introduces the signal model and multidomain representations. Section 3 details the proposed FuseCLIP framework. Section 4 presents the experimental settings and results. Section 5 discusses the implications and limitations of the findings. Section 6 concludes this paper.

2. Materials

2.1. LFM Radar Signal and Received Observation

This paper considers a linear frequency modulation (LFM) radar signal as the transmitted waveform. The transmitted pulse is written as
s ( t ) = rect t T exp j 2 π f c t + 1 2 K t 2 ,
where T is the pulse width, f c is the carrier frequency, K = B / T is the chirp rate, and B is the signal bandwidth. The rectangular window limits the effective duration of the pulse.
Since this work focuses on radar active jamming recognition, the received sample is modeled as a superposition of the jamming signal and additive noise:
x ( t ) = j ( t ) + n ( t ) ,
where j ( t ) denotes the active jamming signal and n ( t ) denotes additive white Gaussian noise.

2.2. Active Jamming Signal Models

The simulated dataset contains both suppressive and deceptive active jamming types. Suppressive jamming mainly affects radar detection by injecting noise-like or spectrum-covering interference that is not necessarily related to the intercepted radar waveform, whereas deceptive jamming generates false target-like structures by delaying, sampling, forwarding, frequency-shifting, or noise-modulating the intercepted waveform. The signal models below give simplified mathematical forms for the main jamming mechanisms considered in this paper.

2.2.1. Suppressive Jamming

Frequency modulation (FM) jamming is a representative noise modulation jamming form. It uses noise to modulate the instantaneous frequency of the jamming signal, producing a spectrum with random fluctuation around the carrier frequency. It is modeled as
j F M ( t ) = A J exp j 2 π f J t + 2 π K F M 0 t u ( τ ) d τ + φ 0 ,
where A J is the jamming amplitude, f J is the jamming center frequency, K F M is the frequency modulation coefficient, u ( τ ) denotes the modulation noise, and φ 0 is the initial phase. The bandwidth and modulation coefficient determine the spectral coverage of FM jamming.

2.2.2. Deceptive Jamming

Range multiple target (RMT) jamming generates several delayed replicas of the radar signal to form multiple false targets in the range dimension. Its simplified expression is
j R M T ( t ) = m = 1 M r A m s ( t τ m ) ,
where M r is the number of false targets, and A m and τ m are the amplitude and time delay of the mth false target, respectively. Different delays correspond to different apparent target ranges after pulse compression.
Smeared spectrum (SMSP) jamming first forms a forwarded sub-pulse by modifying the chirp rate of the intercepted LFM signal. For the ith sub-pulse, this operation can be written as
s i ( t ) = A i exp j π k i t 2 s ( t ) ,
where A i is the amplitude coefficient and k i denotes the additional chirp-rate modulation applied to the intercepted waveform. Repeating the modified sub-pulses over the pulse interval produces the SMSP signal:
j S M S P ( t ) = i = 0 M s 1 s i t i T M s ,
where M s is the number of forwarded sub-pulses and T / M s is their repetition interval. The chirp-rate modulation and repeated forwarding broaden the spectral distribution and smear the matched-filter response.
Interrupted-sampling repeater jamming (ISRJ) periodically samples slices of the intercepted radar pulse and retransmits them. Let the sampling pulse train be
p ( t ) = n = 0 N s 1 rect t n T s T I ,
where T I is the sampling duration, T s is the sampling period, and N s is the number of sampled slices. The sampled signal is
s I ( t ) = p ( t ) s ( t ) ,
and the retransmitted ISRJ signal can be written as
j I S R J ( t ) = m = 1 M I A m s I ( t m τ I ) ,
where M I is the number of retransmissions and τ I is the forwarding delay. Because only part of the pulse is sampled and repeated, ISRJ usually produces structured false targets and characteristic time–frequency discontinuities.
Comb spectrum jamming (COMB) is modeled as a set of frequency-shifted forwarded replicas of the intercepted radar waveform. Its simplified form is
j C O M B ( t ) = m = 0 M c 1 A m s ( t τ m ) exp j 2 π m Δ f t ,
where M c is the number of comb components, Δ f is the frequency interval between adjacent components, and A m and τ m are the amplitude and delay of the mth forwarded replica, respectively. The frequency-shifted replicas generate a comb-like spectrum while retaining the waveform structure of the intercepted radar signal.
Masking noise jamming (MNJ) is represented as noise-modulated delayed replicas of the intercepted radar waveform:
j M N J ( t ) = m = 1 M n A m n m ( t ) s ( t τ m ) ,
where M n is the number of noise-modulated forwarding components, A m and τ m are the amplitude and delay of the mth component, and n m ( t ) is a band-limited Gaussian noise modulation term. This construction preserves the noise-like masking property while generating delayed waveform-dependent structures that can act as deceptive responses.

2.2.3. Compound Jamming

Compound jamming is generated by superimposing two basic jamming mechanisms. In this paper, three compound categories are considered: COMB–ISRJ, FM–ISRJ, and MNJ–ISRJ. Their general form is
j c o m p ( t ) = j a ( t ) + j I S R J ( t ) ,
where j a ( t ) denotes the auxiliary component selected from COMB, FM, or MNJ. Compound jamming combines the spectral, frequency-modulated, or noise-modulated characteristics of the auxiliary component with the slice-retransmission characteristics of ISRJ. This makes the recognition task more challenging, especially when only a few labeled samples are available.

2.3. Multidomain Representation and STFT

Radar active jamming signals show different characteristics in different domains. Therefore, each sample is represented by a time-domain sequence x T , a frequency-domain sequence x F , and a time–frequency spectrogram x T F . The frequency-domain sequence is obtained by FFT:
X ( f ) = x ( t ) exp ( j 2 π f t ) d t .
The STFT is further used to describe the temporal evolution of the spectrum:
X S T F T ( τ , f ) = x ( t ) w ( t τ ) exp ( j 2 π f t ) d t ,
where w ( t τ ) is a sliding analysis window centered at time τ . The corresponding spectrogram is
x T F ( τ , f ) = X S T F T ( τ , f ) 2 .
The time-domain sequence preserves energy fluctuation characteristics, the frequency-domain sequence reflects the spectral distribution, and the STFT spectrogram describes time-varying spectral structures. These three representations provide complementary views of the same jamming sample and are used as the inputs of FuseCLIP.

3. Proposed Approach

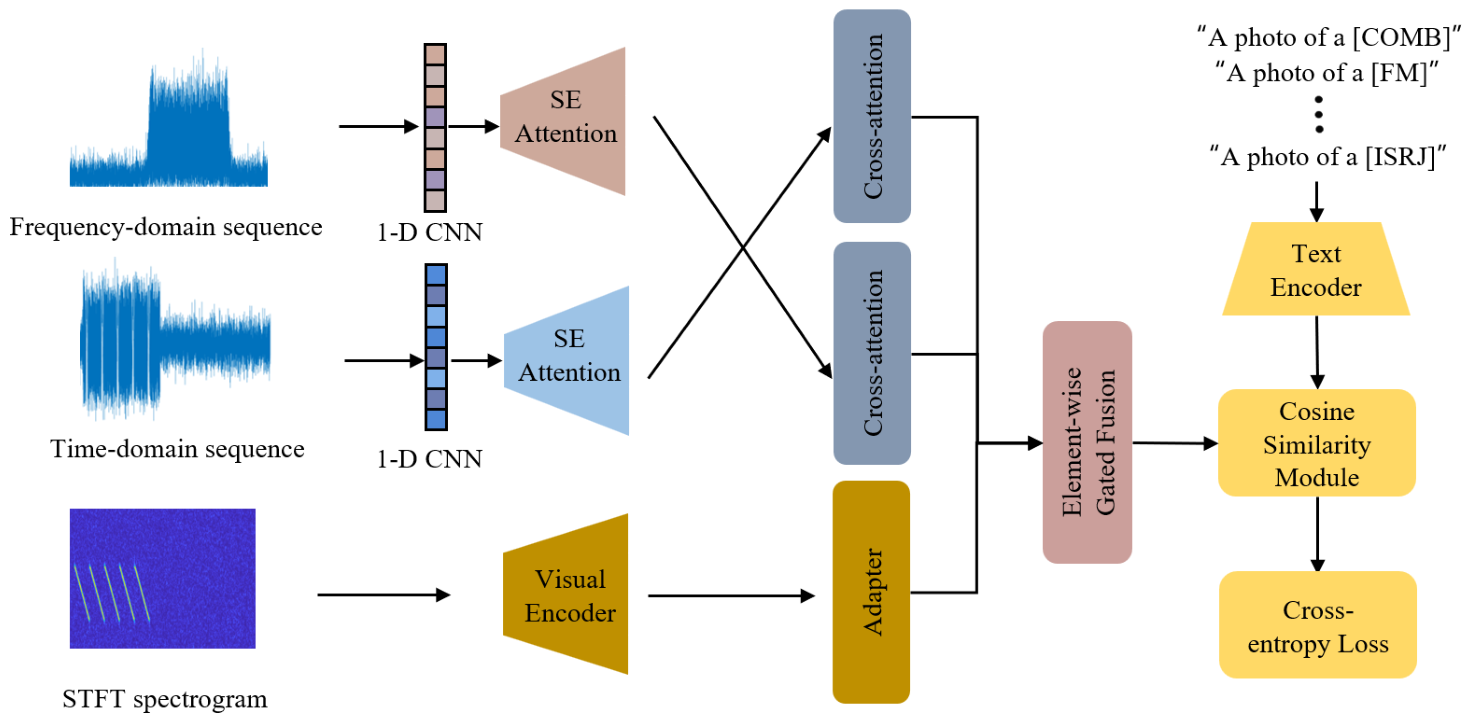
This section presents the proposed FuseCLIP framework. As shown in Figure 1, the key idea is to represent each radar-jamming sample in multiple signal domains and map the fused representation into a CLIP-guided semantic prototype space. The framework contains three main parts: multidomain feature encoding, adaptive three-modal fusion, and text-prototype-based classification. Compared with directly training a classifier on discrete category labels, FuseCLIP uses fixed text prototypes generated from jamming descriptions as semantic class references. Therefore, the decision space is guided not only by labeled signal samples, but also by category-level semantic information encoded in CLIP.

3.1. Overview of the FuseCLIP Framework

For each radar-jamming sample, FuseCLIP uses three inputs:
x T , x F , x T F ,
where x T denotes the time-domain sequence, x F denotes the frequency-domain sequence, and x T F denotes the STFT spectrogram. These three inputs describe the same sample from different views. The time-domain branch focuses on waveform changes caused by modulation and forwarding operations. The frequency-domain branch emphasizes bandwidth occupation, spectral spreading, and frequency-domain structures. The STFT branch further describes the temporal evolution of spectral components and is suitable for visual representation learning.
The three features are encoded into a common 512-dimensional space and then fused by an element-wise gating module. The fused signal representation is normalized and compared with normalized text prototypes generated by the CLIP text encoder. The final prediction is obtained by scaled cosine similarity. This design keeps the signal feature learning and semantic prototype matching in a unified embedding space.

3.2. Time- and Frequency-Domain Feature Encoding

The time-domain and frequency-domain inputs are one-dimensional sequences. FuseCLIP therefore uses lightweight one-dimensional convolutional neural network (1D-CNN) branches to extract local waveform and spectral patterns. The two branches are denoted as
F T = E T ( x T ) , F F = E F ( x F ) ,
where E T ( · ) and E F ( · ) denote the time-domain and frequency-domain CNN encoders, respectively. The output features F T and F F retain local structural information along the sequence dimension.
Because not all channels are equally useful for jamming discrimination, a squeeze-and-excitation (SE) attention module is used to recalibrate the channel responses of the two branches. For a branch feature F R C × L , global average pooling first produces a channel descriptor:
u c = 1 L l = 1 L F c , l , c = 1 , 2 , , C .
The channel weights are then generated by a lightweight gating function:
s = σ W 2 δ ( W 1 u ) ,
where δ ( · ) is the nonlinear activation function, σ ( · ) is the sigmoid function, and W 1 and W 2 are learnable parameters. The recalibrated feature is obtained by channel-wise multiplication:
F c , l = s c F c , l .
This operation helps the network emphasize informative modulation-related responses and suppress redundant channels before cross-domain interaction.

3.3. Cross-Attention Between Time and Frequency Branches

The time-domain and frequency-domain branches describe different but related aspects of the same jamming signal. To exchange information between these two one-dimensional representations, FuseCLIP applies cross-attention before projection. The cross-attention module uses the first input as the query source and the second input as the key–value source. In the implemented framework, the interaction is performed sequentially:
F ^ T = CA ( F T , F F ) ,
F ^ F = CA ( F F , F ^ T ) ,
where CA ( · ) denotes the cross-attention operation. The first step updates the time-domain representation by attending to the frequency-domain feature. The second step refines the frequency-domain representation using the updated time-domain feature. This sequential form provides bidirectional information exchange while preserving the actual computation order of the model.
After cross-attention, the time-domain and frequency-domain features are flattened and projected into the CLIP-compatible embedding dimension:
z T = P T ( F ^ T ) , z F = P F ( F ^ F ) ,
where P T ( · ) and P F ( · ) are projection layers for the time and frequency features, respectively, and z T , z F R 512 . This projection aligns the two signal-domain branches with the CLIP feature dimension.

3.4. STFT Spectrogram Encoding with CLIP Visual Features

The STFT spectrogram x T F contains time-varying spectral structures and can be regarded as an image-like representation of the radar-jamming signal. FuseCLIP uses the CLIP visual encoder to extract the spectrogram feature:
v T F = E V ( x T F ) ,
where E V ( · ) denotes the CLIP visual encoder. In the experiments, ViT-B/32 is used as the CLIP backbone.
Although CLIP is pretrained on natural image–text pairs, its visual encoder can still provide useful representation ability for structured spectrogram inputs. To adapt it to radar spectrograms, only the last five transformer blocks and the final LayerNorm of the visual encoder are fine-tuned, while the remaining layers are kept frozen. Meanwhile, a lightweight adapter is added after the CLIP visual encoder:
z T F = A ( v T F ) ,
where A ( · ) denotes the CLIP adapter and z T F R 512 . The adapter provides task-specific adjustment for radar spectrograms while keeping the overall representation space compatible with CLIP. In this way, the STFT branch contributes time–frequency structural information without being forced into the one-dimensional cross-attention between the time and frequency branches.

3.5. Element-Wise Three-Modal Fusion

After obtaining z T , z F , and z T F , the three domain features are fused by an element-wise gate. Instead of assigning a single scalar weight to each branch, the gate predicts a weight for each feature dimension and each modality. This is useful because different dimensions of the embedding may correspond to different discriminative factors.
The three features are first concatenated and passed into a gating network:
H = G ( [ z T , z F , z T F ] ) ,
where G ( · ) denotes the gating network and H R 512 × 3 . A softmax operation is then applied along the modality dimension:
W d , m = exp ( H d , m ) m { T , F , T F } exp ( H d , m ) , d = 1 , 2 , , 512 ,
where m { T , F , T F } denotes the modality index. The corresponding element-wise weights are written as W T , W F , and W T F . The fused signal representation is then computed as
z = W T z T + W F z F + W T F z T F ,
where ⊙ denotes element-wise multiplication. Since the weights are normalized across the three branches at each feature dimension, the model can adaptively select waveform, spectral, or time–frequency information according to the input sample.

3.6. CLIP Text Prototypes and Semantic Matching

To introduce category-level semantic priors, FuseCLIP constructs fixed text prototypes from task-related jamming descriptions. For each jamming class c, a text prompt p c is encoded by the CLIP text encoder. Following the CLIP convention, each prompt is constructed from a fixed template “a photo of a 〈class〉,” where the class is the corresponding jamming category.
q c = E t e x t ( p c ) ,
where E t e x t ( · ) denotes the CLIP text encoder. The text prototype is obtained by 2 normalization:
t c = q c q c 2 .
The text encoder is frozen and is used only once to compute these prototypes; it is not updated during training. These text prototypes serve as semantic class references in the CLIP embedding space. Compared with a randomly initialized classifier, this prototype-based classifier allows the recognition space to be associated with textual descriptions of jamming categories. This is especially helpful in few-shot settings, where the number of labeled signal samples is limited.
Before similarity calculation, the fused signal feature is also normalized:
z ¯ = z z 2 .
The classification logits are obtained by scaled cosine similarity:
l c = τ z ¯ T t c ,
where τ is the temperature scale, T denotes transpose, and z ¯ T t c is the cosine similarity between the fused signal representation and the text prototype of class c. The prediction is given by
y ^ = arg max c l c .
During training, the scaled similarity logits are optimized using cross-entropy loss with label smoothing:
L = 1 N i = 1 N c = 1 C q i , c log exp ( l i , c ) k = 1 C exp ( l i , k ) ,
where N is the batch size, C is the number of classes, and q i , c is the smoothed label distribution. Label smoothing reduces overconfident predictions and improves training stability when only a few labeled samples are available. In this way, FuseCLIP maps multidomain radar signal features into a CLIP-guided semantic prototype space for few-shot radar active jamming recognition.

4. Experimental Results and Analysis

4.1. Experimental Setting

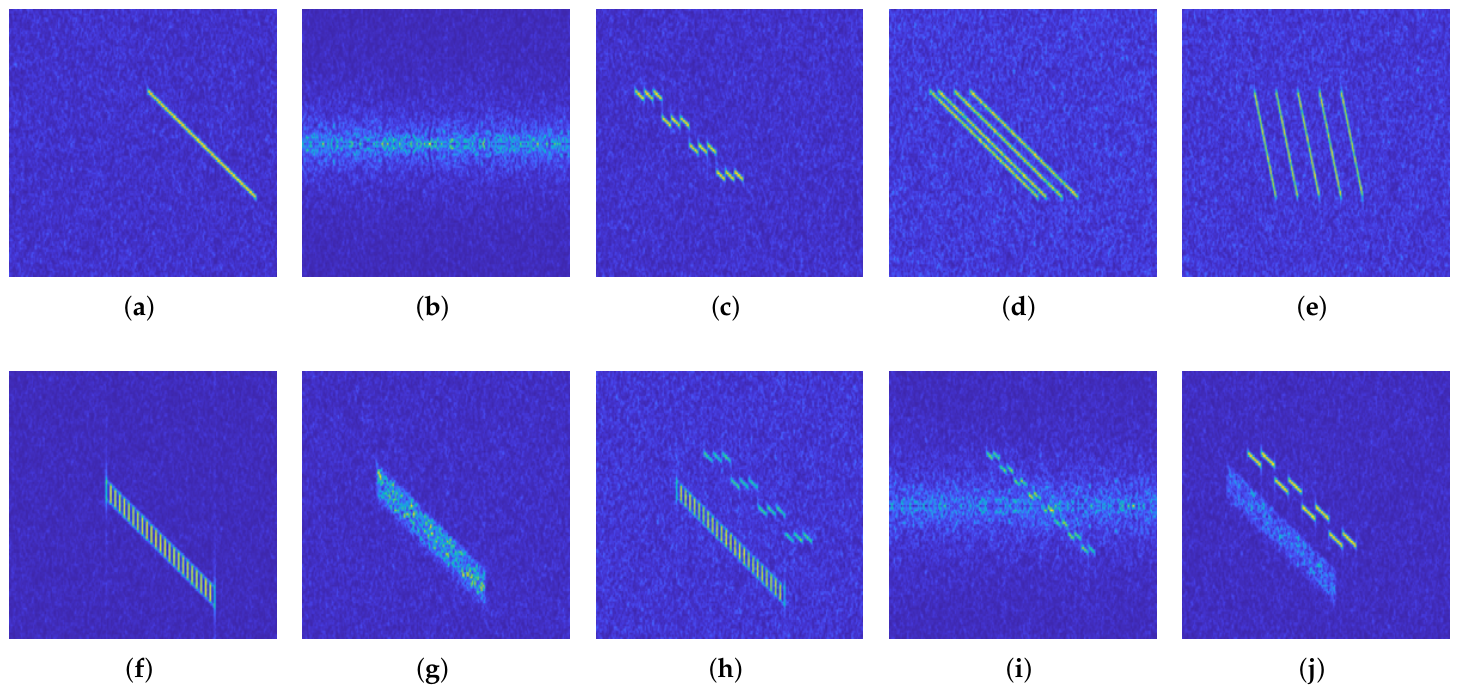
A simulated radar active jamming dataset is used to evaluate the proposed method. It contains ten categories: LFM, FM, ISRJ, RMT, SMSP, COMB, MNJ, COMB–ISRJ, FM–ISRJ, and MNJ–ISRJ. Among them, COMB–ISRJ, FM–ISRJ, and MNJ–ISRJ are compound jamming types generated by superimposing ISRJ with COMB, FM, and MNJ, respectively. For each sample, the time-domain sequence, frequency-domain sequence, and STFT spectrogram are used as the three inputs. Representative STFT spectrograms of the ten jamming categories are shown in Figure 2. These examples illustrate that different jamming mechanisms present distinguishable time–frequency patterns, such as continuous chirp-like structures, noise-like spectral coverage, delayed replicas, and compound structures produced by superposition. The JNR is defined as
JNR = 10 log 10 P J P N ,
where P J and P N are the average powers of the jamming signal and noise, respectively. To evaluate classification performance from multiple perspectives, we report accuracy and Cohen’s kappa. Accuracy is defined as the ratio of correctly classified samples to the total number of samples,
Accuracy = 1 N i = 1 N I y ^ i = y i ,
where N is the total number of test samples, y i and y ^ i are the true and predicted labels of the i-th sample, and I ( · ) is the indicator function. Kappa corrects the observed agreement for chance agreement and is defined as
Kappa = p o p e 1 p e ,
where
p o = 1 N c = 1 C n c c , p e = 1 N 2 c = 1 C j = 1 C n c j j = 1 C n j c .
Here, n c j is the number of samples with true class c predicted as class j, and C is the total number of classes. The simulated dataset contains JNR levels from 12 dB to 20 dB, with 100 samples per class at each available level. The data are randomly split into training, validation, and testing sets with a ratio of 5:1:4. The main generation parameters of different jamming categories are listed in Table 2.
The CLIP backbone is ViT-B/32. The text prompts are fixed task-related category descriptions, the CLIP text encoder is frozen, and the visual encoder is partially fine-tuned. For each of five independent random seeds, the training set is randomly shuffled before each run, and K samples per class are selected without replacement for every K-shot experiment. The final results are averaged over the five seeds. Model selection is performed using the best checkpoint on the validation set, and the main training settings are listed in Table 3.

4.2. Recognition Performance of the Proposed Method

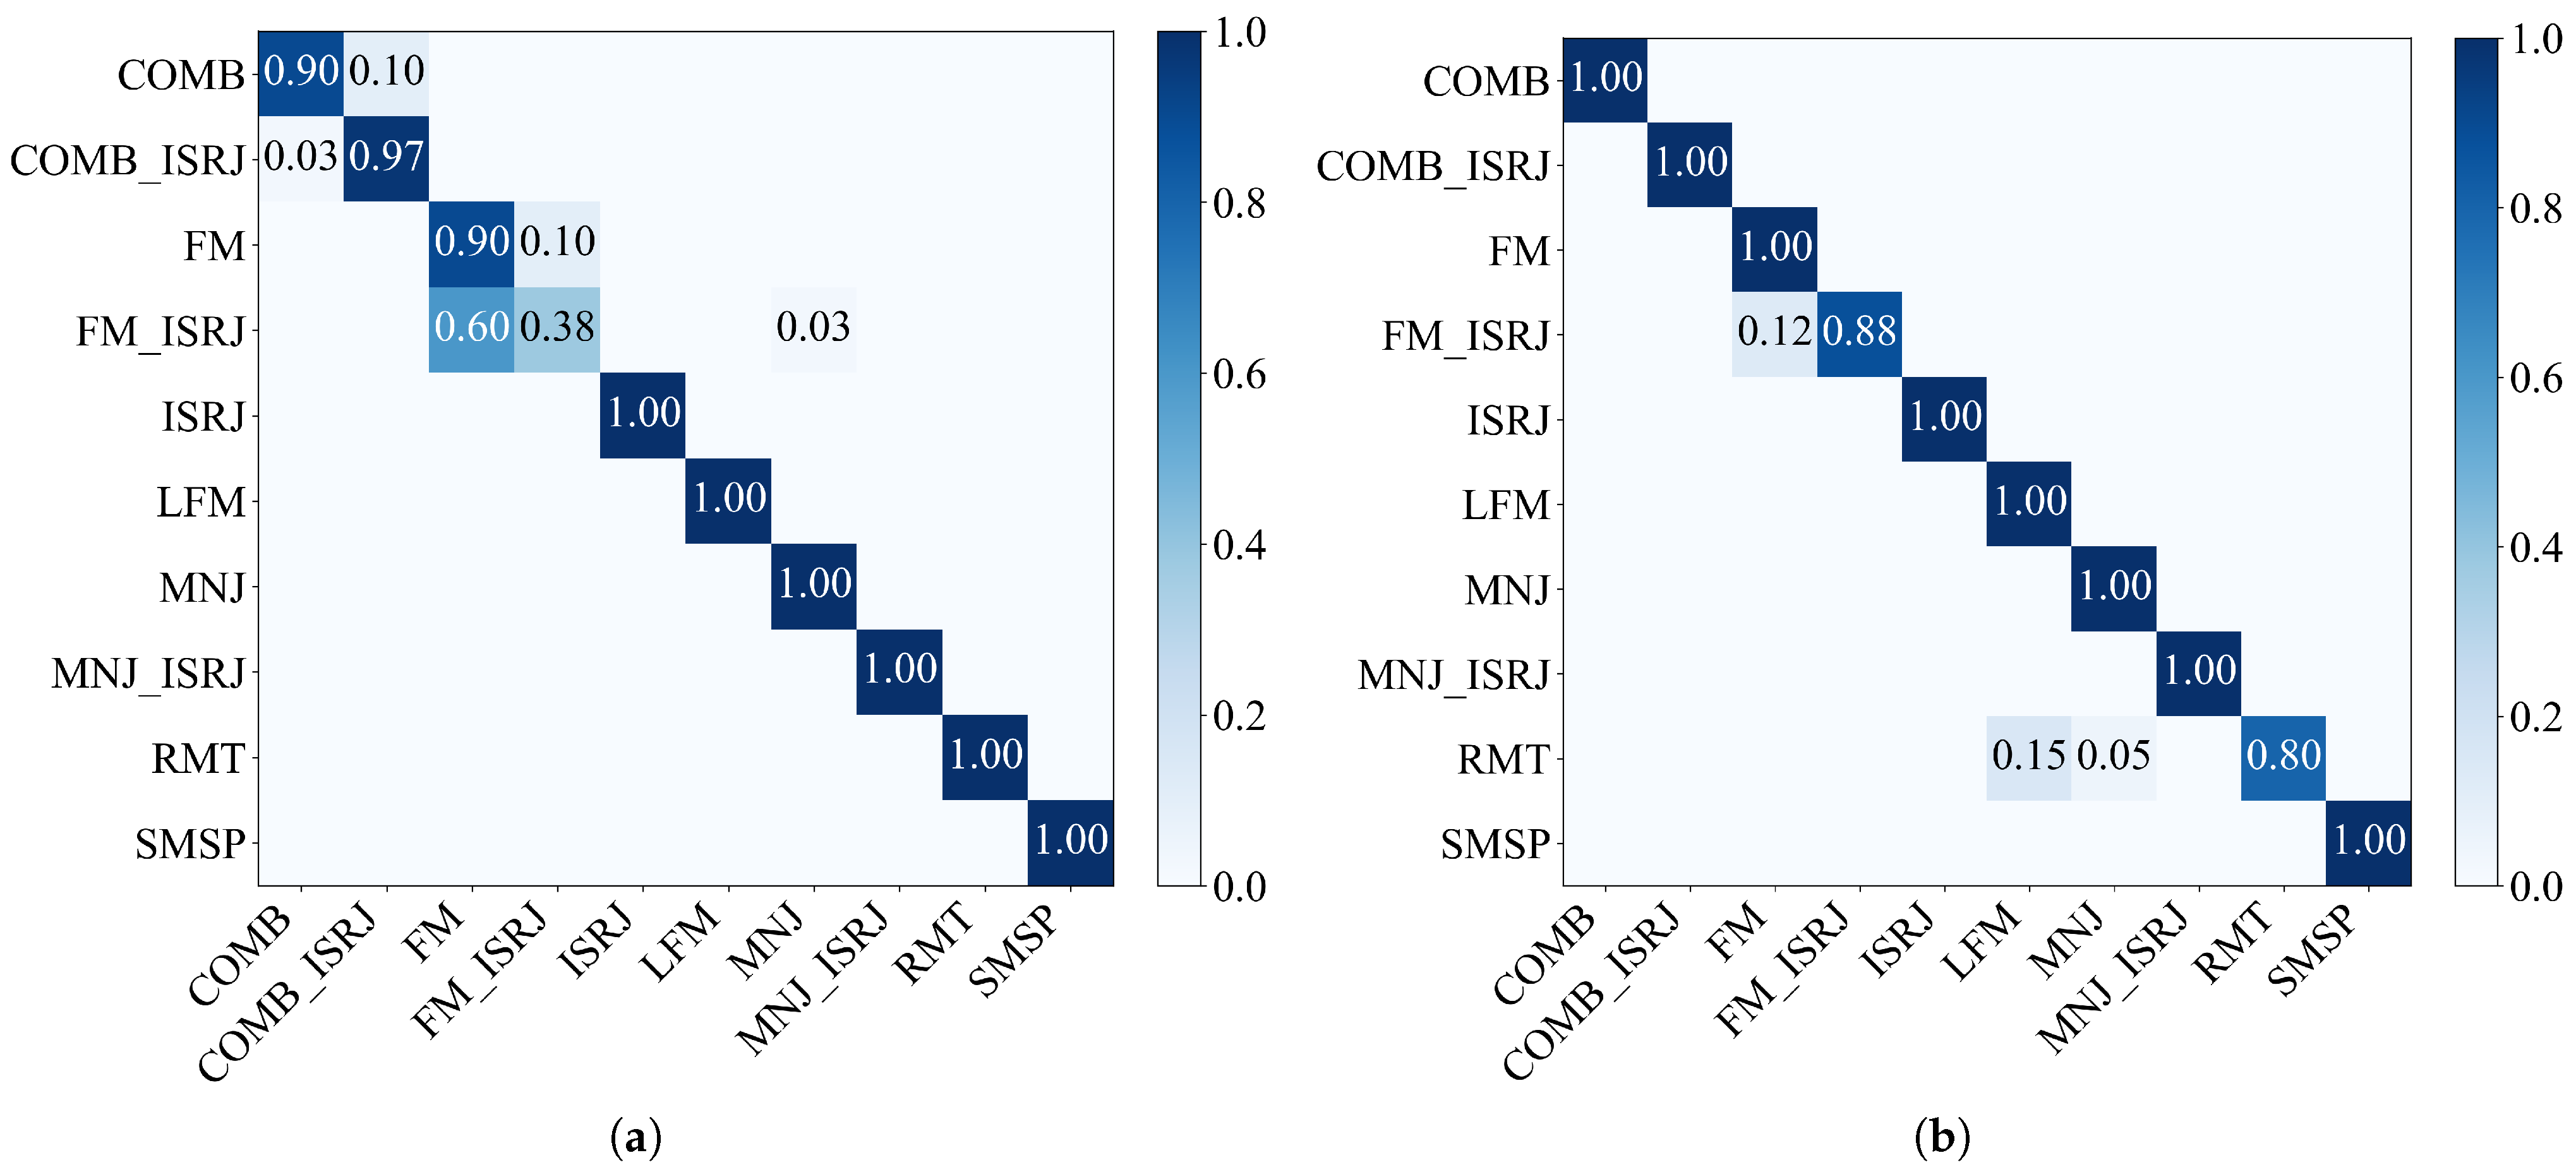
Figure 3 shows FuseCLIP confusion matrices for the 5-shot setting at JNRs of 4 dB and 4 dB. In both conditions, predictions are concentrated on the main diagonal, indicating class-level discrimination with limited labels. At lower JNR, misclassifications often occur between individual jamming types and their compound variants, as they share partially similar time–frequency features; at 4 dB, such confusion is markedly reduced, yielding a more concentrated diagonal. These qualitative patterns show that FuseCLIP retains discriminative structure under stronger noise while benefiting, as expected, from improved signal observability.

4.3. Comparison with Other Methods

We compare DFCNN [14], WECNN-TL [20], a standalone spectrogram–text CLIP baseline [29], ResNet-50 [30], MMFCNN [31], and FuseCLIP under the same data partitions, five random seeds, JNR condition, and model-selection rule. DFCNN extracts one-dimensional features from the real, imaginary, magnitude, and phase components of the original signal and fuses them with two-dimensional STFT features. WECNN-TL constructs multiple subsets from these four STFT components and combines transfer-learned CNNs by weighted voting. The CLIP baseline aligns an STFT image with a text prototype, whereas ResNet-50 classifies the STFT image using a residual CNN. MMFCNN separately encodes time-domain, FFT-based frequency-domain, and time–frequency inputs and combines their features through cross-attention fusion. All methods are evaluated under the same per-class shot settings: 5, 9, and 13.
Table 4 reports the matched five-seed results at each shot count under 0 dB JNR. Here, T and F denote time-domain and frequency-domain signals, respectively; TF denotes the short-time Fourier-transform spectrogram, and R/I/M/P denote the real, imaginary, magnitude, and phase channels.
Table 4 compares methods using different signal domains under 5, 9, and 13-shot training. FuseCLIP achieves the highest accuracy at every shot count, increasing from 97.50% to 98.75% while retaining low variance across runs. The STFT-only ResNet-50 and the spectrogram–text CLIP baseline perform competitively but rely primarily on time–frequency images, which may omit waveform fluctuations and global spectral distributions that distinguish related jamming patterns. DFCNN supplements STFT features with multiple signal components, and MMFCNN integrates time, frequency, and time–frequency branches; however, their results suggest that simply introducing multiple inputs may not always ensure equally stable few-shot fusion. These observations are consistent with the combined contributions of three-domain representation, element-wise adaptive fusion, and text-prototype matching, which offer complementary evidence and fixed category-level references to help stabilize decisions when labeled samples are limited.
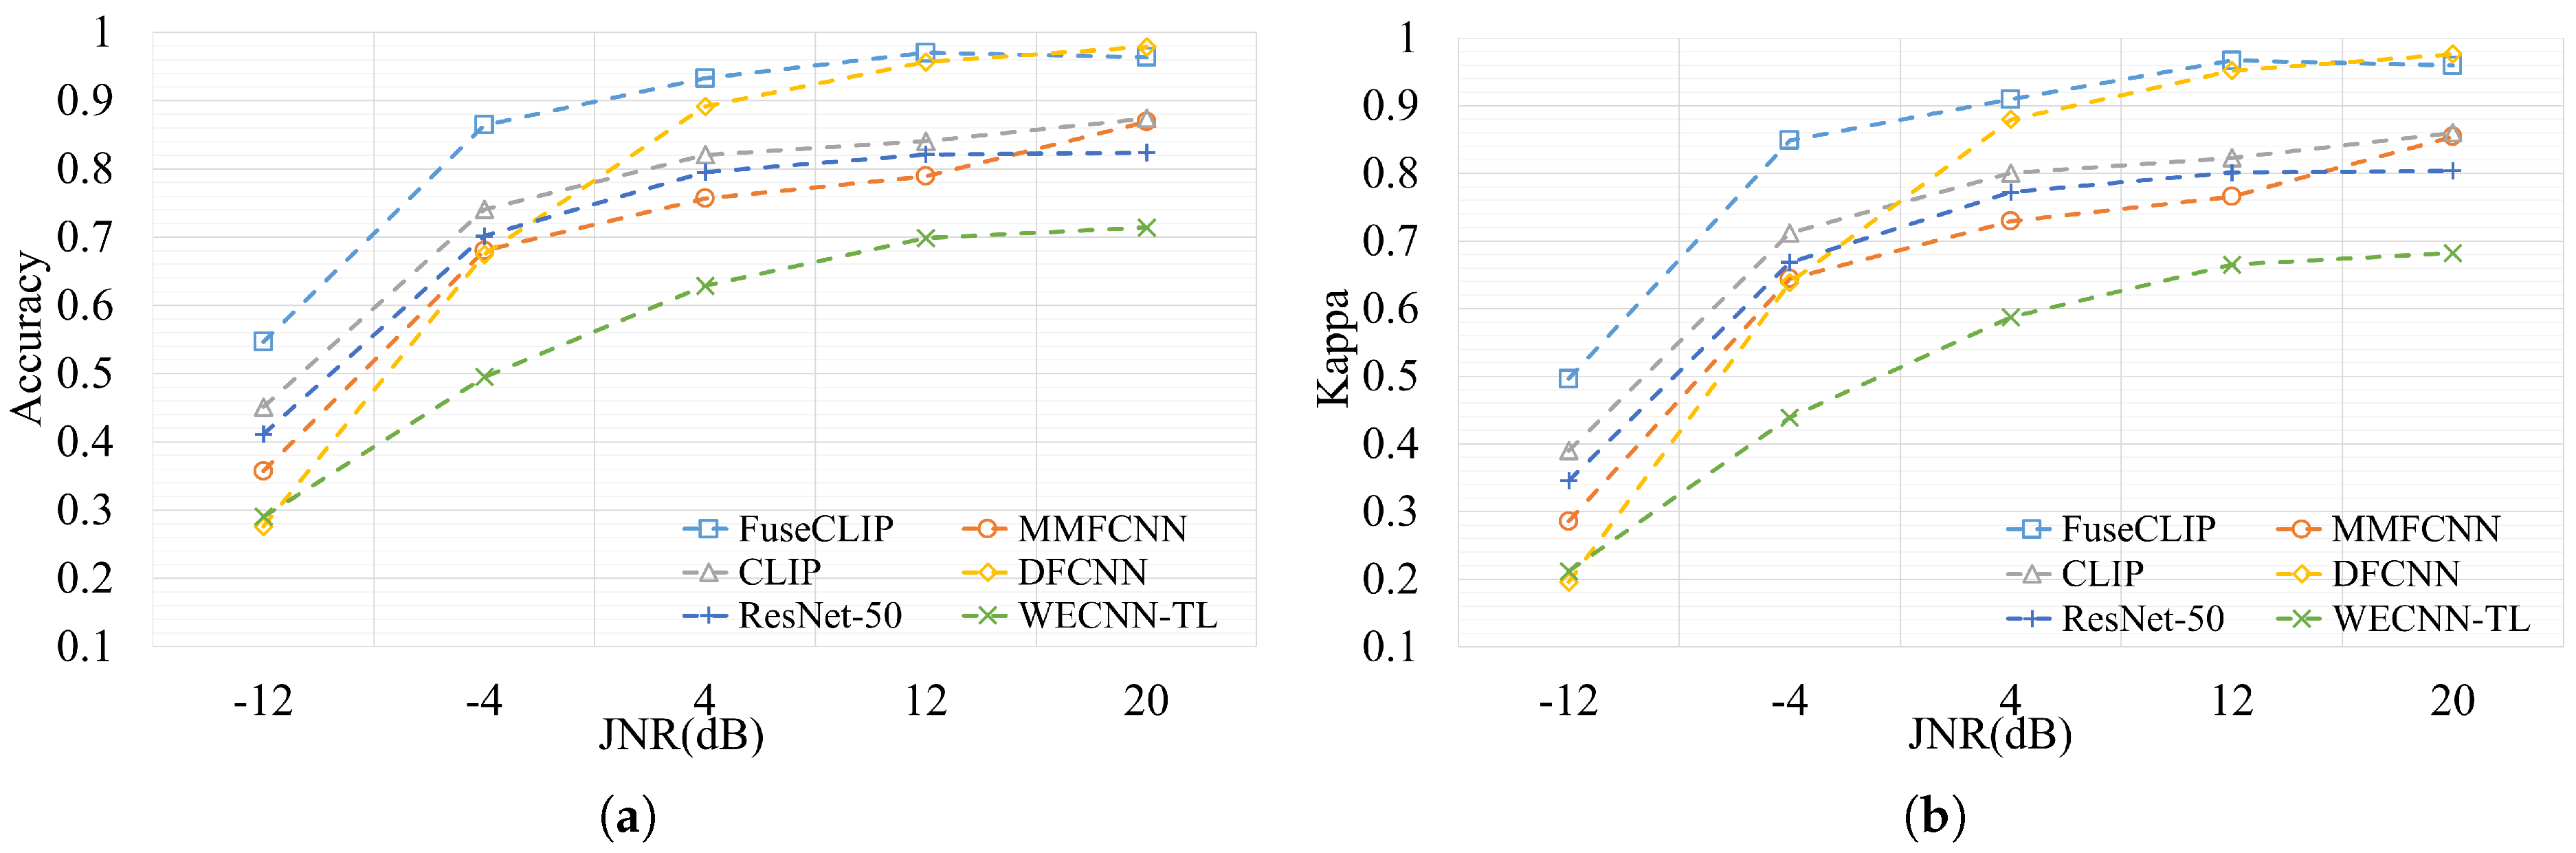
Figure 4 compares the six methods over JNRs from 12 to 20 dB. Performance improves with JNR for all methods, as the jamming signatures become progressively more observable. FuseCLIP shows a clear advantage in the more challenging low-JNR conditions, reaching approximately 55.0% accuracy at 12 dB and 84.9% at 4 dB. At higher JNRs, its performance remains competitive with DFCNN, and the two methods approach similarly high recognition levels when the signal evidence is sufficiently clear. The STFT-based CLIP and ResNet-50 baselines retain useful recognition capability, but their reliance on a time–frequency representation alone may make them more sensitive when localized spectral structures are obscured by stronger noise. MMFCNN also benefits from multidomain inputs, although its results are lower than those of FuseCLIP across the displayed JNR range in this experiment.
To complement recognition accuracy, Table 5 compares resource use and timing under a fixed experimental environment. All methods were evaluated on an NVIDIA RTX 5090 GPU with 32 GiB memory using PyTorch 2.9.1 and identical input settings. FLOPs, and mean per-image training and inference times were measured using the same profiling procedure.
Table 5 makes the accuracy–cost trade-off explicit. FuseCLIP requires more parameters and longer per-image times than lightweight DFCNN and single-spectrogram ResNet-50 because it combines a CLIP visual backbone with one-dimensional encoders, cross-attention, adaptive fusion, and projection. Partial CLIP freezing nevertheless constrains the number of adapted parameters. WECNN-TL combines multiple channel subsets and ensembles several CNN members through weighted voting, which multiplies its computational cost and latency.
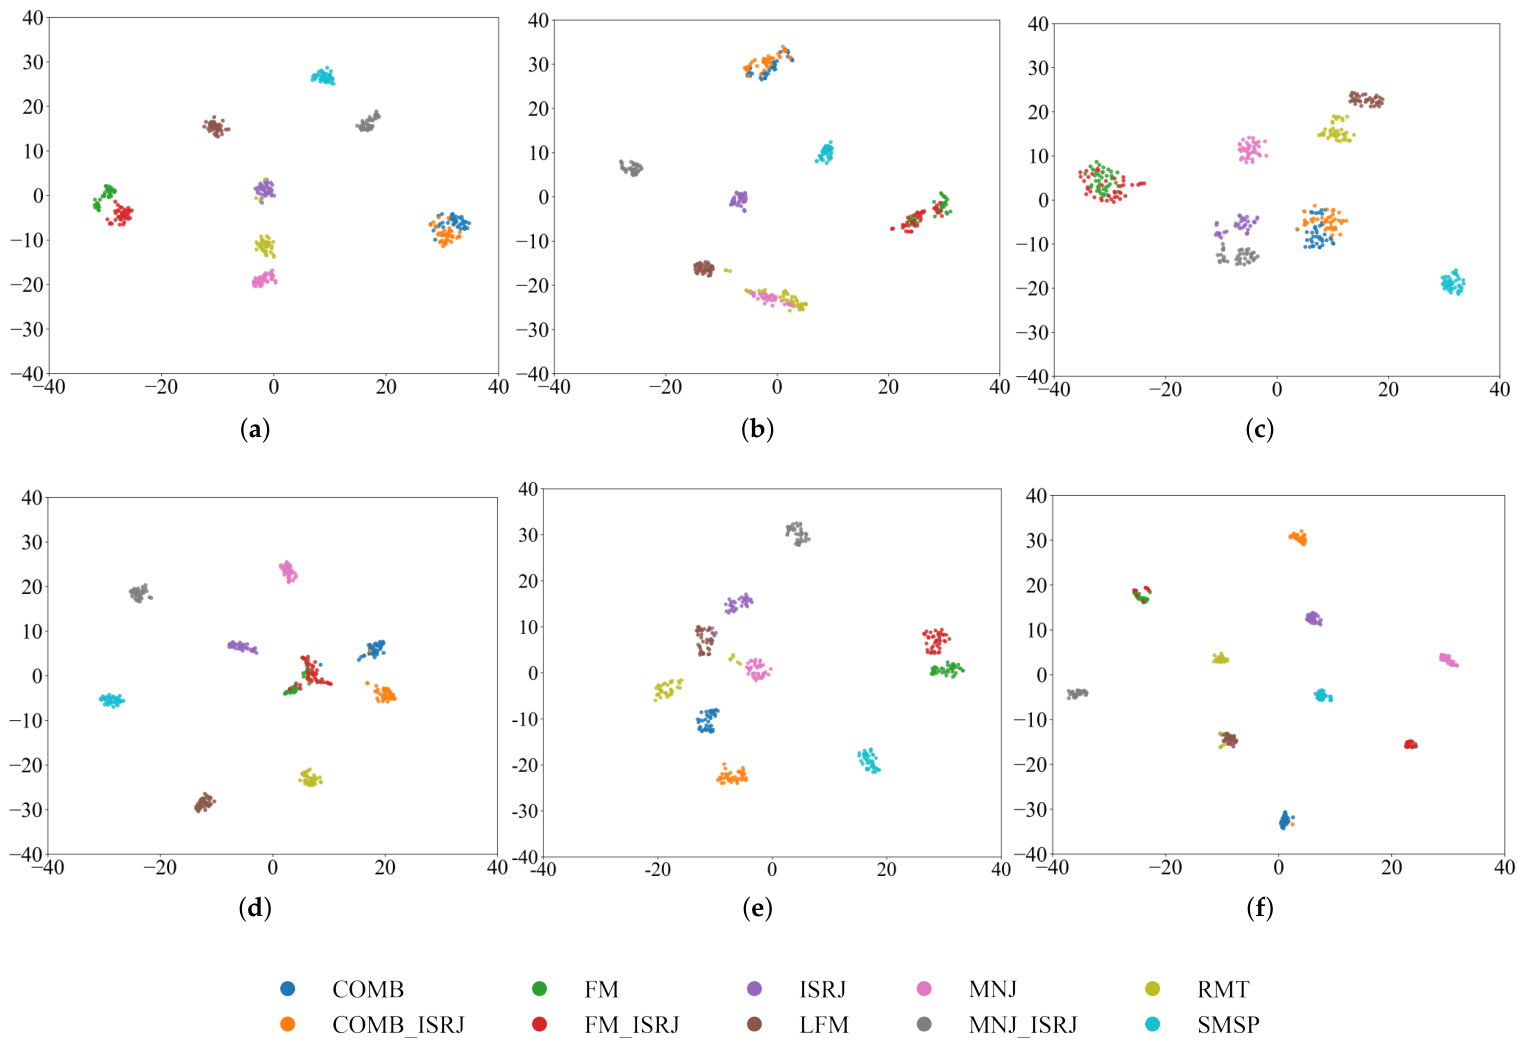
Figure 5 qualitatively visualizes the feature distributions learned by the compared methods. All methods form recognizable category-wise clusters, while the degree of local separation varies across representations. FuseCLIP shows relatively compact clusters with clearer spacing between most categories, consistent with its use of complementary multidomain features and prototype-guided classification.

4.4. Prompt and Prototype Specification

FuseCLIP classifies a fused multidomain signal representation by matching it with CLIP text prototypes. Beyond the above recognition results, to demonstrate that the results are not caused solely by the matching architecture, we also examine the contribution of the semantic information carried by the prototypes to few-shot jamming recognition. Table 6 compares the default fixed template with several alternative prototype constructions under the same data split, 0 dB JNR, 5-shot per class, and five random seeds. The class name setting uses only the jamming-category label, whereas manual uses a fixed class-specific radar time–frequency description. CoOp [32] replaces the fixed “a photo of a” template with a set of learnable context tokens shared by all classes, forming prompts of the form “[context tokens] [class name]”; only these context tokens are optimized during training while the CLIP encoders remain frozen. CoCoOp [33] further conditions these context tokens on each input image through a lightweight meta-network, so the prompt is generated dynamically from the input rather than being static. The random setting uses seeded unit-normalized Gaussian prototype vectors as a non-semantic control. For a controlled comparison, all other model and training hyperparameters are fixed; only the prompt/prototype construction is changed.
Under this controlled comparison, the fixed template provides the most effective prototype construction. Its simple wording may be more compatible with the pretrained CLIP space than class names or manually engineered radar descriptions, while the limited-data regime can make learned context unstable. The weaker random control further indicates that category-related prototype structure, rather than matching alone, contributes to recognition.

4.5. Generalization Under Distribution Shifts

4.5.1. Cross-JNR Evaluation

To assess generalization across interference conditions, all methods are trained and validated using only the 0 dB dataset. The selected models are then evaluated, without retraining or fine-tuning, on test sets generated at 4 dB and 4 dB. Base-signal identities are partitioned before JNR-specific variants are generated, preventing variants of the same underlying signal from appearing in both the source and target sets. Table 7 reports the five-seed results.
All methods perform better at 4 dB than at 4 dB, consistent with the clearer jamming signatures at higher JNR. FuseCLIP attains the highest mean accuracy under both target conditions. We attribute this to two properties of the FuseCLIP design. First, FuseCLIP encodes the time–frequency representation with a vision transformer pretrained within CLIP on large-scale image–text data; such features are comparatively stable when noise corrupts the spectrogram at low JNR. By contrast, the compared methods encode the time–frequency representation with CNNs trained from scratch on the few-shot 0 dB samples. Second, FuseCLIP classifies by cosine similarity against fixed CLIP text prototypes, which provide data-independent class references that do not shift with the input distribution; the compared methods instead learn softmax decision boundaries from the 0 dB training distribution. The complementary time-, frequency-, and time–frequency branches further allow the fusion to favor whichever representation remains reliable as the JNR changes.

4.5.2. Unseen-Parameter Generalization

Cross-JNR evaluation probes robustness to a change in interference strength, whereas the following experiment examines whether a model can recognize the same jamming categories when their physical parameters lie outside the ranges observed during model development. The six methods retain the original training and validation sets, train–validation protocol, selected saved weights, and all other settings. No retraining or fine-tuning is performed. Only the original test set is replaced by a newly generated held-out test set with unseen parameter values. This design evaluates parameter extrapolation under a fixed learned model.
Table 8 summarizes the parameter ranges. For compound jamming, the original data use within-category combinations whose component parameters fall in the seen ranges. The held-out test set uses the same within-category combination principle, but draws the relevant component parameters from the corresponding unseen ranges.
Table 9 reports fixed-model performance when the test-set physical parameters fall outside the ranges used during training and validation. Without retraining or fine-tuning, FuseCLIP achieves the highest mean accuracy and Kappa among the compared methods, with a 2.85-point accuracy advantage over MMFCNN. The result suggests that combining time-domain, frequency-domain, and time–frequency representations can retain useful category information when signal parameters vary beyond the training range.

4.6. Ablation Study

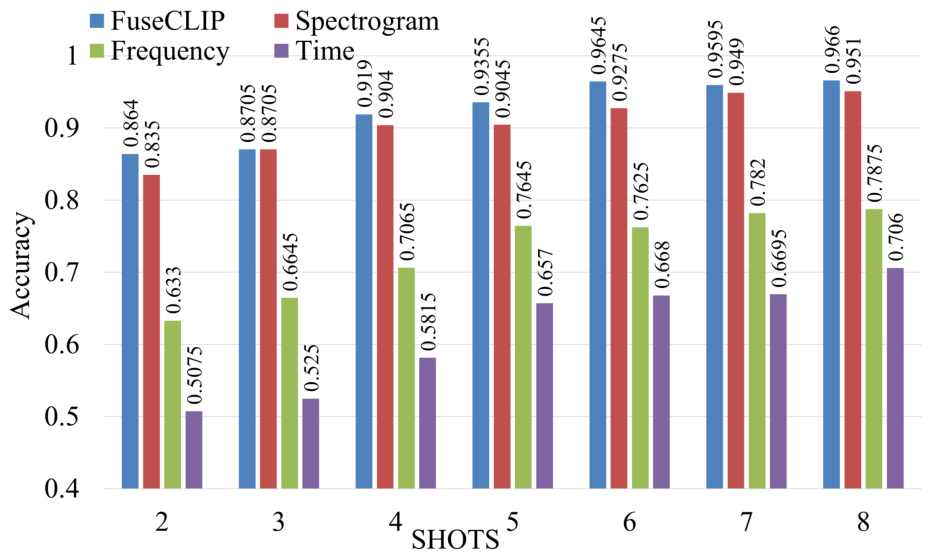
The branch ablation compares the complete FuseCLIP model with single-branch variants retaining only the spectrogram, frequency-domain, or time-domain branch.
Figure 6 provides complete evidence on input-domain complementarity, separately from the mechanism ablation below. The time-domain branch captures waveform fluctuations, the frequency-domain branch captures global spectral distributions, and the STFT branch captures time-varying spectral structure. The full-model result relative to the single-branch variants shows the value of integrating these distinct views, particularly when limited labeled data make any single representation incomplete.
Table 10 progressively adds the three variable mechanisms. The sequence moves from equal fusion with a linear classifier to element-wise adaptive fusion, text-prototype classification, and finally the CLIP adapter; the last row is the complete model. All configurations use the same 2-shot protocol and repeated evaluation procedure.
Table 10 shows a progressive improvement from the base configuration to the complete FuseCLIP model under the common 2-shot protocol. The largest increase follows the introduction of adaptive fusion, which is consistent with allowing the model to adjust the contribution of time-domain, frequency-domain, and time–frequency features rather than treating them equally. The subsequent improvements after text-prototype classification and the CLIP adapter indicate that, after multidomain features are fused, prototype-based matching and task-oriented adaptation of spectrogram features can further refine the final decision space.

5. Discussion

The results indicate that FuseCLIP is particularly useful when labeled samples are scarce or jamming signals are affected by noise. The time-domain, frequency-domain, and STFT inputs provide different views of the same signal. Together, these representations provide complementary information about the same signal and support a more complete characterization of different jamming patterns. This helps explain the improved performance in few-shot and low-JNR settings. Some confusion remains between basic jamming types and their ISRJ-based compound forms at lower JNRs. This is expected because these signals can share similar time–frequency patterns. In this case, adaptive fusion can help the model rely more on the representation that provides clearer information for a given sample.
The improved recognition performance comes with additional computational cost. FuseCLIP is larger than lightweight baselines because it includes a CLIP visual encoder, one-dimensional signal branches, and a fusion module. The required inputs, namely the FFT spectrum and the STFT representation, are also compatible with common radar signal-processing procedures. This makes the framework suitable for further study in practical radar-recognition systems. Still, the present evaluation uses simulated data. Future work should examine measured signals and more diverse propagation, device, and interference conditions.

6. Conclusions

This paper presents FuseCLIP, a semantic-guided multidomain framework for few-shot radar active-jamming recognition. The method represents each sample from complementary time-domain, frequency-domain, and STFT views: the time-domain branch preserves waveform fluctuations, the frequency-domain branch describes global spectral distributions, and the STFT branch captures time-varying spectral structure. Bidirectional cross-attention exchanges information between the time- and frequency-domain branches, after which element-wise adaptive fusion adjusts the contribution of the three representations across feature dimensions. The resulting fused feature is matched with fixed CLIP-derived text prototypes through cosine similarity, and the CLIP adapter further adapts spectrogram features to the multidomain recognition space.
The experiments show that FuseCLIP achieves the highest mean accuracy in the matched 5, 9, and 13-shot comparisons. The controlled prototype comparison identifies the fixed template as the most effective of the tested constructions. The progressive ablation also shows improved recognition as adaptive fusion, text-prototype classification, and the CLIP adapter are incorporated. Under the cross-JNR protocol, FuseCLIP demonstrates strong performance across the evaluated JNR levels; on the held-out unseen-parameter test set, it exceeds MMFCNN by 2.85 percentage points in mean accuracy.
These recognition results require additional memory and computational cost relative to simpler single-domain models. In addition, the evaluation is based on controlled simulated radar active-jamming data, including the specified JNR and parameter ranges. Future work will examine measured field data, cross-device and cross-environment validation, broader operating conditions, and resource-aware deployment methods.


Author Contributions

Conceptualization, Z.Y. and G.C.; methodology, Z.Y. and G.C.; software, Z.Y.; validation, Z.Y.; formal analysis, Z.Y. and G.C.; investigation, Z.Y.; writing—original draft preparation, Z.Y.; writing—review and editing, G.C., W.W., Y.K., X.W. and Z.H.; supervision, G.C., X.W. and Z.H.; funding acquisition, G.C. and Z.H. All authors have read and agreed to the published version of the manuscript.

Funding

This work was supported in part by the National Natural Science Foundation of China under Grant 62371001; in part by the National Natural Science Foundation of China under Grant U23B2007; in part by the Anhui University Research Start-up Fund for Talent Introduction; and in part by the China Postdoctoral Science Foundation under Grant 2025M784462.

Data Availability Statement

The original contributions presented in this study are included in the article material. Further inquiries can be directed to the corresponding author.

Acknowledgments

During preparation of this manuscript, the authors used DeepSeek-V4 for language polishing and spelling correction. The authors have reviewed and edited the output and take full responsibility for the content of this publication. The authors would like to thank the editor who handled the manuscript and the anonymous reviewers for their valuable comments and suggestions.

Conflicts of Interest

Author Wei Wen was employed by the company Xi’an Branch of China Academy of Space Technology. The remaining authors declare that the research was conducted in the absence of any commercial or financial relationships that could be construed as a potential conflict of interest.

References

  1. Zhang, H.; Quan, S.; Xing, S.; Wang, J.; Li, Y.; Wang, P. Shadow-Based False Target Identification for SAR Images. Remote Sens. 2023, 15, 5259. [Google Scholar] [CrossRef] [Scilit]
  2. Wang, X.; Cui, G.; Wang, Y.; Zhao, W.; Xiong, K. Marine Target Detection via Spatial-Temporal Graph Neural Network. IEEE Trans. Instrum. Meas. 2025, 74, 2505514. [Google Scholar] [CrossRef] [Scilit]
  3. Li, X.; Sun, X.; Li, J.; Ji, Y.; Ma, M. Adaptive Graph Construction Learning for Automotive Radar Object Detection. IEEE Trans. Intell. Transp. Syst. 2026, early access. [Google Scholar] [CrossRef] [Scilit]
  4. Vijay Kumar, S.; Sun, X.; Wang, Z.; Goldsbury, R.; Cheng, I. A U-Net Approach for InSAR Phase Unwrapping and Denoising. Remote Sens. 2023, 15, 5081. [Google Scholar] [CrossRef] [Scilit]
  5. Riabukha, V.P.; Semeniaka, A.V.; Katiushyn, Y.A.; Atamanskiy, D.V. Pulse DRFM Jamming Formation and Its Mathematical Simulation. In Proceedings of the 2022 IEEE 2nd Ukrainian Microwave Week (UkrMW), Kharkiv, Ukraine, 14–18 November 2022; pp. 654–659. [Google Scholar] [CrossRef] [Scilit]
  6. Feng, D.; Xu, L.; Pan, X.; Wang, X. Jamming Wideband Radar Using Interrupted-Sampling Repeater. IEEE Trans. Aerosp. Electron. Syst. 2017, 53, 1341–1354. [Google Scholar] [CrossRef] [Scilit]
  7. Li, N.J.; Zhang, Y.T. A Survey of Radar ECM and ECCM. IEEE Trans. Aerosp. Electron. Syst. 1995, 31, 1110–1120. [Google Scholar] [CrossRef] [Scilit]
  8. Wang, Z.; Guo, Z.; Shu, G.; Li, N. Radar Jamming Recognition: Models, Methods, and Prospects. IEEE J. Sel. Top. Appl. Earth Obs. Remote Sens. 2025, 18, 3315–3343. [Google Scholar] [CrossRef] [Scilit]
  9. Zhou, H.; Wang, Z.; Wu, R.; Xu, X.; Guo, Z. Jamming Recognition Algorithm Based on Variational Mode Decomposition. IEEE Sens. J. 2023, 23, 17341–17349. [Google Scholar] [CrossRef] [Scilit]
  10. Zhou, H.; Dong, C.; Wu, R.; Xu, X.; Guo, Z. Feature Fusion Based on Bayesian Decision Theory for Radar Deception Jamming Recognition. IEEE Access 2021, 9, 16296–16304. [Google Scholar] [CrossRef] [Scilit]
  11. Qu, Q.; Wei, S.; Liu, S.; Liang, J.; Shi, J. JRNet: Jamming Recognition Networks for Radar Compound Suppression Jamming Signals. IEEE Trans. Veh. Technol. 2020, 69, 15035–15045. [Google Scholar] [CrossRef] [Scilit]
  12. Meng, Y.; Yu, L.; Wei, Y. Multi-Label Radar Compound Jamming Signal Recognition Using Complex-Valued CNN with Jamming Class Representation Fusion. Remote Sens. 2023, 15, 5180. [Google Scholar] [CrossRef] [Scilit]
  13. Chen, H.; Chen, H.; Lei, Z.; Zhang, L.; Li, B.; Zhang, J.; Wang, Y. Compound Jamming Recognition Based on a Dual-Channel Neural Network and Feature Fusion. Remote Sens. 2024, 16, 1325. [Google Scholar] [CrossRef] [Scilit]
  14. Shao, G.; Chen, Y.; Wei, Y. Deep Fusion for Radar Jamming Signal Classification Based on CNN. IEEE Access 2020, 8, 117236–117244. [Google Scholar] [CrossRef] [Scilit]
  15. Kong, Y.; Wang, X.; Wu, C.; Yu, X.; Cui, G. Active Deception Jamming Recognition in the Presence of Extended Target. IEEE Geosci. Remote Sens. Lett. 2022, 19, 4024905. [Google Scholar] [CrossRef] [Scilit]
  16. Chen, X.; Liu, Y.; Wang, C. Multi-Domain Fusion Network for Active Jamming Recognition in Cognitive Radar. Remote Sens. 2025, 17, 1723. [Google Scholar] [CrossRef] [Scilit]
  17. Zhang, Z.; Zhou, H.; Sun, J.; Greco, M.S.; Gini, F.; Bai, X.; Zhou, F. Semantic Graph Reasoning Over Multidomain Fusion for Radar Jamming Recognition. IEEE Trans. Aerosp. Electron. Syst. 2026, 62, 2993–3005. [Google Scholar] [CrossRef] [Scilit]
  18. Zhang, M.; Chen, Y.; Zhang, Y. Weakly Supervised Transformer for Radar Jamming Recognition. Remote Sens. 2024, 16, 2541. [Google Scholar] [CrossRef] [Scilit]
  19. Lu, J.; Guo, Y.; Feng, W.; Hu, X.; Gong, J.; Zhang, Y. Intelligent Recognition and Parameter Estimation of Radar Active Jamming Based on Oriented Object Detection. Remote Sens. 2025, 17, 2646. [Google Scholar] [CrossRef] [Scilit]
  20. Lv, Q.; Quan, Y.; Feng, W.; Sha, M.; Dong, S.; Xing, M. Radar Deception Jamming Recognition Based on Weighted Ensemble CNN with Transfer Learning. IEEE Trans. Geosci. Remote Sens. 2022, 60, 5107511. [Google Scholar] [CrossRef] [Scilit]
  21. Luo, Z.; Cao, Y.; Yeo, T.S.; Wang, Y.; Wang, F. Few-Shot Radar Jamming Recognition Network via Time-Frequency Self-Attention and Global Knowledge Distillation. IEEE Trans. Geosci. Remote Sens. 2023, 61, 5105612. [Google Scholar] [CrossRef] [Scilit]
  22. Zhou, H.; Cai, X.; Peng, P.; Guo, Z. Prototype Features Driven High-Performance Few-Shot Radar Active Jamming Recognition. IEEE Trans. Radar Syst. 2025, 3, 430–440. [Google Scholar] [CrossRef] [Scilit]
  23. Luo, Z.; Cao, Y.; Yeo, T.S.; Wang, F. Few-Shot Radar Jamming Recognition Network via Complete Information Mining. IEEE Trans. Aerosp. Electron. Syst. 2024, 60, 3625–3638. [Google Scholar] [CrossRef] [Scilit]
  24. Zhao, Y.; Wang, X.; Cao, S.; Huang, Z. Zero-Shot Automatic Modulation Recognition Using a Large Vision-Language Model. IEEE Trans. Commun. 2025, 73, 15765–15782. [Google Scholar] [CrossRef] [Scilit]
  25. Wu, Z.; Wang, T.; Cao, Y.; Zhang, M.; Guo, W.; Yang, L. Few-Shot Radar Active Jamming Recognition Under Label Prior Information Reuse. IEEE Geosci. Remote Sens. Lett. 2025, 22, 3501305. [Google Scholar] [CrossRef] [Scilit]
  26. Cao, X. Few-Shot and Zero-Shot Radar Active Jamming Recognition Based on a Vision-Language Model. IEEE Trans. Aerosp. Electron. Syst. 2025, 61, 14795–14808. [Google Scholar] [CrossRef] [Scilit]
  27. Du, Q.; Yang, S.; Lei, X. Few-Shot Compound Jamming Recognition Network Based on Image-Semantics Matching Mechanism. IEEE Trans. Cogn. Commun. Netw. 2026, 12, 1803–1820. [Google Scholar] [CrossRef] [Scilit]
  28. Wu, Z.; Shi, W.; Cao, Y.; Cui, J.; Wang, T.; Zhang, L. A Unified Multimodal Framework with Cache Model for Few-Shot Radar Compound Jamming Recognition. IEEE Trans. Aerosp. Electron. Syst. 2026, 62, 10326–10339. [Google Scholar] [CrossRef] [Scilit]
  29. Radford, A.; Kim, J.W.; Hallacy, C.; Ramesh, A.; Goh, G.; Agarwal, S.; Sastry, G.; Askell, A.; Mishkin, P.; Clark, J.; et al. Learning Transferable Visual Models From Natural Language Supervision. In Proceedings of the 38th International Conference on Machine Learning, Virtual, 18–24 July 2021; pp. 8748–8763. [Google Scholar]
  30. He, K.; Zhang, X.; Ren, S.; Sun, J. Deep Residual Learning for Image Recognition. In Proceedings of the 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), Las Vegas, NV, USA, 27–30 June 2016; pp. 770–778. [Google Scholar] [CrossRef] [Scilit]
  31. Lu, H.; Zhu, Y.; Yin, M.; Yin, G.; Xie, L. Multimodal Fusion Convolutional Neural Network with Cross-Attention Mechanism for Internal Defect Detection of Magnetic Tile. IEEE Access 2022, 10, 60876–60886. [Google Scholar] [CrossRef] [Scilit]
  32. Zhou, K.; Yang, J.; Loy, C.C.; Liu, Z. Learning to Prompt for Vision-Language Models. Int. J. Comput. Vis. 2022, 130, 2337–2348. [Google Scholar] [CrossRef] [Scilit]
  33. Zhou, K.; Yang, J.; Loy, C.C.; Liu, Z. Conditional Prompt Learning for Vision-Language Models. In Proceedings of the 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), New Orleans, LA, USA, 18–24 June 2022; pp. 16795–16804. [Google Scholar] [CrossRef] [Scilit]
Figure 1. Overall framework of the proposed FuseCLIP.
Remotesensing 18 02967 g001
Figure 2. Representative STFT spectrograms of the ten radar active jamming categories used in the simulated dataset. (a) LFM. (b) FM. (c) ISRJ. (d) RMT. (e) SMSP. (f) COMB. (g) MNJ. (h) COMB–ISRJ. (i) FM–ISRJ. (j) MNJ–ISRJ.
Remotesensing 18 02967 g002
Figure 3. FuseCLIP confusion matrices at 5 shots: (a) JNR = 4 dB and (b) JNR = 4 dB.
Remotesensing 18 02967 g003
Figure 4. Recognition across JNR settings under the 2-shot setting: (a) accuracy and (b) Kappa.
Remotesensing 18 02967 g004
Figure 5. t-SNE projections of method-specific feature distributions. (a) DFCNN. (b) WECNN-TL. (c) CLIP. (d) ResNet-50. (e) MMFCNN. (f) FuseCLIP.
Remotesensing 18 02967 g005
Figure 6. Input-branch ablation across shot counts.
Remotesensing 18 02967 g006
Table 1. Brief comparison of representative fusion and radar-jamming recognition approaches. T, F, and TF denote time-domain, frequency-domain, and time–frequency representations, respectively.
Method/ReferenceInput DomainTraining Strategy
DFCNN [14]T + TFStandard supervised training
WECNN-TL [20]TFTransfer learning with weighted ensemble
JR-TFSAD [21]TFSelf-attention with global knowledge distillation
Prototype-feature method [22]TFPrototype features with attention-based enhancement
VTA-Net [25]TF + textContrastive learning with label-prior reuse
Vision–language method [26]TF + textFew-shot and zero-shot vision–language matching
FuseCLIP (this work)T + F + TF + textThree-domain fusion with prototype matching
Table 2. Jamming parameter setting.
Signal TypeParameterValue
LFMChirp bandwidth40 MHz
Pulse width40 μs
FMBandwidth30–50 MHz
Modulation coefficient8–11 MHz
ISRJSampling times4–10
Repeater times2–4
RMTTime delay1–5 μs
Number of false targets3–5
SMSPNumber of forwarding times3–5
COMBNumber of comb teeth9–12
Frequency interval0.5–0.8 MHz
MNJBandwidth5–11 MHz
Table 3. Training settings for the few-shot experiments.
SettingValue
OptimizerAdamW
Batch size32
Learning rate 1 × 10 4
Weight decay0.01
Maximum epochs500
Learning-rate scheduleCosine annealing
Early stoppingPatience = 80; Δ Acc. < 10 4
Table 4. Few-shot recognition under the matched protocol.
MethodSignal Inputs5-Shot9-Shot13-Shot
Accuracy (%)KappaAccuracy (%)KappaAccuracy (%)Kappa
DFCNNT(R/I/M/P) + TF89.70 ± 5.300.886 ± 0.05994.70 ± 2.610.941 ± 0.02997.95 ± 1.580.977 ± 0.018
WECNN-TLTF(R/I/M/P)77.80 ± 3.590.753 ± 0.04083.95 ± 4.010.822 ± 0.04592.85 ± 2.720.921 ± 0.030
CLIPTF + text89.55 ± 2.220.884 ± 0.02593.75 ± 0.840.931 ± 0.00993.00 ± 0.740.922 ± 0.008
ResNet-50TF87.15 ± 2.360.857 ± 0.02692.35 ± 2.550.915 ± 0.02891.60 ± 2.440.907 ± 0.027
MMFCNNT + F + TF91.80 ± 2.050.909 ± 0.02397.85 ± 0.600.976 ± 0.00781.65 ± 4.760.796 ± 0.053
FuseCLIPT + F + TF + text97.50 ± 0.530.972 ± 0.00697.95 ± 0.740.977 ± 0.00898.75 ± 0.530.986 ± 0.006
Bold values indicate the best accuracy and Kappa scores.
Table 5. Resource and timing comparison.
MethodTotal Params.Trainable Params.FLOPsTrain Time/ImageInference/Image
DFCNN0.99 M0.99 M0.93 G1.49 ms0.45 ms
WECNN-TL11.69 M11.69 M69.05 G25.28 ms6.52 ms
CLIP88.11 M0.26 M8.73 G0.62 ms0.77 ms
ResNet-5023.53 M14.99 M8.17 G0.64 ms0.51 ms
MMFCNN30.30 M30.30 M1.36 G1.11 ms0.30 ms
FuseCLIP96.77 M44.76 M8.76 G1.91 ms0.99 ms
Table 6. Prompt sensitivity analysis.
StrategyPrototype ConstructionAccuracy (%)Kappa
Class name“{class}.”89.75 ± 1.610.886 ± 0.018
Manual description“a time-frequency plot of radar {class}”87.8 ± 2.670.864 ± 0.030
CoOpLearned context vectors88.55 ± 3.340.873 ± 0.037
CoCoOpImage-conditioned context vectors88.90 ± 2.400.877 ± 0.027
Random controlRandom vectors84.35 ± 3.130.826 ± 0.035
Fixed template (ours)“a photo of a {class}.”97.50 ± 0.530.972 ± 0.006
Bold values indicate the best accuracy and Kappa scores.
Table 7. Cross-JNR results with 0 dB training and validation.
MethodTrainingTest: 4 dBTest: 4 dB
Acc. (%)KappaAcc. (%)Kappa
DFCNN0 dB23.00 ± 6.680.144 ± 0.07444.70 ± 1.900.386 ± 0.021
WECNN-TL0 dB30.70 ± 9.140.230 ± 0.10239.65 ± 5.130.329 ± 0.057
CLIP0 dB77.15 ± 4.600.746 ± 0.05190.00 ± 2.870.889 ± 0.032
ResNet-500 dB56.90 ± 7.860.521 ± 0.08762.50 ± 8.400.583 ± 0.093
MMFCNN0 dB48.70 ± 8.890.430 ± 0.09961.80 ± 10.270.576 ± 0.114
FuseCLIP0 dB88.25 ± 6.430.869 ± 0.07195.80 ± 3.910.953 ± 0.043
Bold values indicate the best accuracy and Kappa scores.
Table 8. Held-out (unseen) jamming parameter ranges.
Jamming TypeParameterUnseen Range
FMBandwidth20–40 MHz
Modulation coefficient6–8 MHz
ISRJSampling period13–14 μs
Repeater times5–6
RMTTime delay6–10 μs
SMSPNumber of forwarding times6–8
COMBNumber of comb teeth13–16
Frequency interval0.9–1.2 MHz
MNJBandwidth13–17 MHz
Table 9. Fixed-model recognition on unseen parameter ranges under the 0 dB and 5-shot setting.
MethodAccuracy (%)Kappa
DFCNN70.45 ± 9.000.672 ± 0.100
WECNN-TL52.40 ± 5.020.471 ± 0.056
CLIP65.15 ± 6.140.613 ± 0.068
ResNet-5074.00 ± 4.600.711 ± 0.051
MMFCNN78.45 ± 3.370.761 ± 0.037
FuseCLIP81.30 ± 8.020.792 ± 0.089
Bold values indicate the best accuracy and Kappa scores.
Table 10. Progressive 2-shot ablation.
ConfigurationAdaptive
Fusion
Text
Prototype
CLIP AdapterAccuracy (%)Kappa
equal fusion + linear classifier82.910.810
+adaptive fusion84.920.832
+text-prototype classifier85.250.836
Full FuseCLIP86.400.849
Bold values indicate the best accuracy and Kappa scores.
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content.