Article

Independent Multi-Sensor Validation of Machine-Learning Landslide Susceptibility: Footprint Construction Decides the Verdict—May 2023 Emilia-Romagna Event

by
Lucian Necula
,
Liviu Porumb
*,
Andreea Florina Jocea
and
Dan Raducanu
Department of Civil Engineering, Military Engineering and Geomatics, Faculty of Integrated Armament Systems, Military Engineering and Mechatronics, Military Technical Academy Ferdinand I, 050141 Bucharest, Romania
*
Author to whom correspondence should be addressed.
Remote Sens. 2026, 18(14), 2318; https://doi.org/10.3390/rs18142318
Submission received: 22 May 2026 / Revised: 2 July 2026 / Accepted: 9 July 2026 / Published: 10 July 2026
(This article belongs to the Section AI Remote Sensing)

Highlights

What are the main findings?
  • The landslide-susceptibility model performs nearly like random because the signal is contaminated by flooding and agricultural changes when raw disturbance footprints are used.
  • The model detects landslide disturbance at roughly twice the random expectation, whereas Sentinel-1 at 12-day repeat intervals does not discriminate landslides.
What are the implications of the main findings?
  • Because validation methodology is critical for reliable landslide-susceptibility assessment, studies relying only on standard accuracy metrics or unfiltered disturbance data may substantially misinterpret model performance and geomorphic realism.
  • Carefully filtered optical remote-sensing data can provide robust model-independent validation, highlighting the need for reproducible, event-specific validation workflows.

Abstract

Machine-learning landslide-susceptibility maps are almost always judged by inventory-split skill (the area under the receiver-operating-characteristic curve, AUC, and Cohen’s κ), not by model-independent physical observation of where an event caused ground disturbance. For the May 2023 Emilia-Romagna event (>80,000 landslides; RER2023 inventory), we confront an open-data, event-conditioned susceptibility model (trigger rainfall is among its predictors) with a co-event disturbance footprint built from two satellites: phenology-matched Sentinel-2 change in the Normalized Difference Vegetation Index (ΔNDVI) and Normalized Burn Ratio (ΔNBR), and a 12-day Sentinel-1A C-band coherence-and-backscatter layer used as a cloud-independent coverage check (C-band 12-day decorrelation is the a priori expectation in this setting); neither enters the model. Apparent geomorphic plausibility depends critically on how the independent footprint is constructed. Against a raw co-event footprint (contaminated by flooding and agriculture), a model with AUC ≈ 0.945 is indistinguishable from a random mask. On a landslide-relevant footprint, the same model captures optically detectable disturbance at roughly twice the chance (bootstrap median 1.94×, 95% CI 1.25–2.72, excluding 1; ≈1.46× above a vegetation-phenology null), but the aggregate is driven by an upper-tail minority of 10 km blocks—the majority of blocks have per-block median lift 0.67× (below chance). The map is therefore a regional, not a per-place, statement. Results are a within-event consistency test; cross-event transferability is not claimed. Footprint construction is decisive and currently neglected. The open-source pipeline is released upon acceptance.

1. Introduction

Machine-learning landslide-susceptibility mapping (LSM) is a mature field, with comprehensive surveys of methods and remote-sensing inputs [1,2,3,4,5]. That the validation design controls apparent performance is itself well established: random vs. spatially blocked cross-validation (CV) optimism [6,7,8], inventory and non-landslide-sampling bias, and the divergence between high Area Under the Curve (AUC) and geomorphic plausibility [9,10,11] are documented results. We therefore treat spatial CV, one-point-per-landslide sampling, and terrain-plausible negatives as established good practices that we apply, not as contributions, and cite the prior work accordingly.
Three limitations of current LSM validation motivate this work. First, models are predominantly validated by cross-validating a single inventory: random k-fold splits inflate apparent skill for spatially autocorrelated data, and even spatially blocked schemes only bound—not remove—this optimism, while leaving geomorphic plausibility untested [6,7,8,12,13]; that high inventory-split discrimination (AUC) can coexist with poor geomorphic realism is well documented [9,10,11]. Second, where independent satellite evidence is used, it is almost always a single optical change index—a mask of the change in the Normalized Difference Vegetation Index (ΔNDVI): in a co-event setting, this index is contaminated by concurrent flooding, agricultural change, and seasonal phenology, so an unfiltered optical footprint conflates landslide with non-landslide disturbance [14,15]. Third, Synthetic Aperture Radar (SAR) is increasingly folded into susceptibility models as a predictor [16,17], but as an independent validator, a C-band (~5.6 cm wavelength) 12-day repeat decorrelates over vegetated terrain at peak phenology, limiting what it can resolve. Recent deep-learning and explainable-AI advances in LSM [1,2,3,4,5] sharpen prediction and interpretation but do not address how the independent-validation reference itself is built. We therefore use the term footprint construction for the choices—which sensors, which thresholds, and whether non-landslide co-event disturbance is removed—that turn raw satellite change into the mask against which a susceptibility map is judged; the central finding of this paper is that these choices, not the model, decide the apparent verdict.
The persistent, under-addressed gap is different: susceptibility maps are almost always judged against a held-out split of the same inventory, not against an independent physical observation of where an event actually caused ground disturbance. We close this gap for the May 2023 Emilia-Romagna event with an independent, multi-sensor remote-sensing plausibility test: the predicted susceptibility surface is confronted with a co-event disturbance footprint built from phenology-matched Sentinel-2 ΔNDVI and the change in the Normalized Burn Ratio (ΔNBR), and cloud-independent Sentinel-1 Interferometric Synthetic Aperture Radar (InSAR) coherence loss and backscatter change (processed on demand via ASF HyP3). The satellite-derived disturbance is never a model input (leakage-safe). This is distinct from prior work on the same event: rapid-mapping studies [14,15] create landslide inventories from satellite imagery but do not model or plausibility-test susceptibility and ML-susceptibility validations more generally report only the fraction of inventory landslides in the highest class for a single inventory, without an independent multi-sensor disturbance comparison or a geomorphic-plausibility framework. The specific gap we close—and which the existing literature does not address—is the construction of the independent-validation footprint itself: most LSM studies that report “independent validation” compare the predicted map to a single ΔNDVI mask without decomposing it against the inevitable co-event contamination of flooding and agricultural disturbance, and almost none combine an optical layer with a cloud-independent SAR layer in a leakage-safe way. The contributions of this paper are made one per line for clarity:
  • An independent, multi-sensor (Sentinel-2 + Sentinel-1) RS plausibility test of event-based ML landslide susceptibility.
  • The demonstration that the apparent verdict depends critically on how the independent-validation footprint is constructed—a contaminated co-event footprint and a process-targeted one give opposite-looking answers on the same model.
  • A footprint-aware quantification of the gap between inventory-split skill and geomorphic plausibility on the RER2023 inventory, with a fully open, reproducible pipeline (data acquisition, fusion, modeling, multi-sensor validation, and figures).
Scope: no deep learning, no rapid detection. A clarification on the two distinct ways SAR appears in the LSM literature is in order because the difference is decisive for the validation argument here. InSAR-as-predictor approaches [16,17] fold a SAR-derived deformation or coherence layer into the model features, training the classifier to use the SAR signal directly to predict susceptibility. Sentinel-1 is used here strictly for validation: it is computed once after the fact, never feeds the model, and is intentionally evaluated against the model’s inventory-split-validated predictions. Only validation use yields an independent plausibility test; predictor use entangles the SAR information with the metric and is therefore not informative about geomorphic plausibility (Section 3.7). A specific caveat applies to the configuration used here: the Sentinel-1A 12-day C-band repeat is known a priori to decorrelate over vegetated mountain canopies at peak spring phenology, so the S1 layer in this manuscript is calibrated as a cloud-independent coverage check rather than as a landslide discriminator. Longer-wavelength SAR (e.g., ALOS-2/NISAR L-band) or sub-daily commercial constellations (ICEYE, Capella) would be the natural candidates for turning S1 into a primary validator in this setting.
Three research questions are addressed. RQ1: Under realistic conditions (terrain-plausible negatives, one point per polygon, spatial cross-validation), how well do ML models predict the May 2023 inventory? RQ2: How much of the apparent skill is an artifact of validation design (random vs. spatial CV; negative sampling)? RQ3: Does the predicted surface reproduce the independently observed co-event disturbance—and how does that verdict depend on how the validation footprint is constructed?

2. Study Area and the May 2023 Event

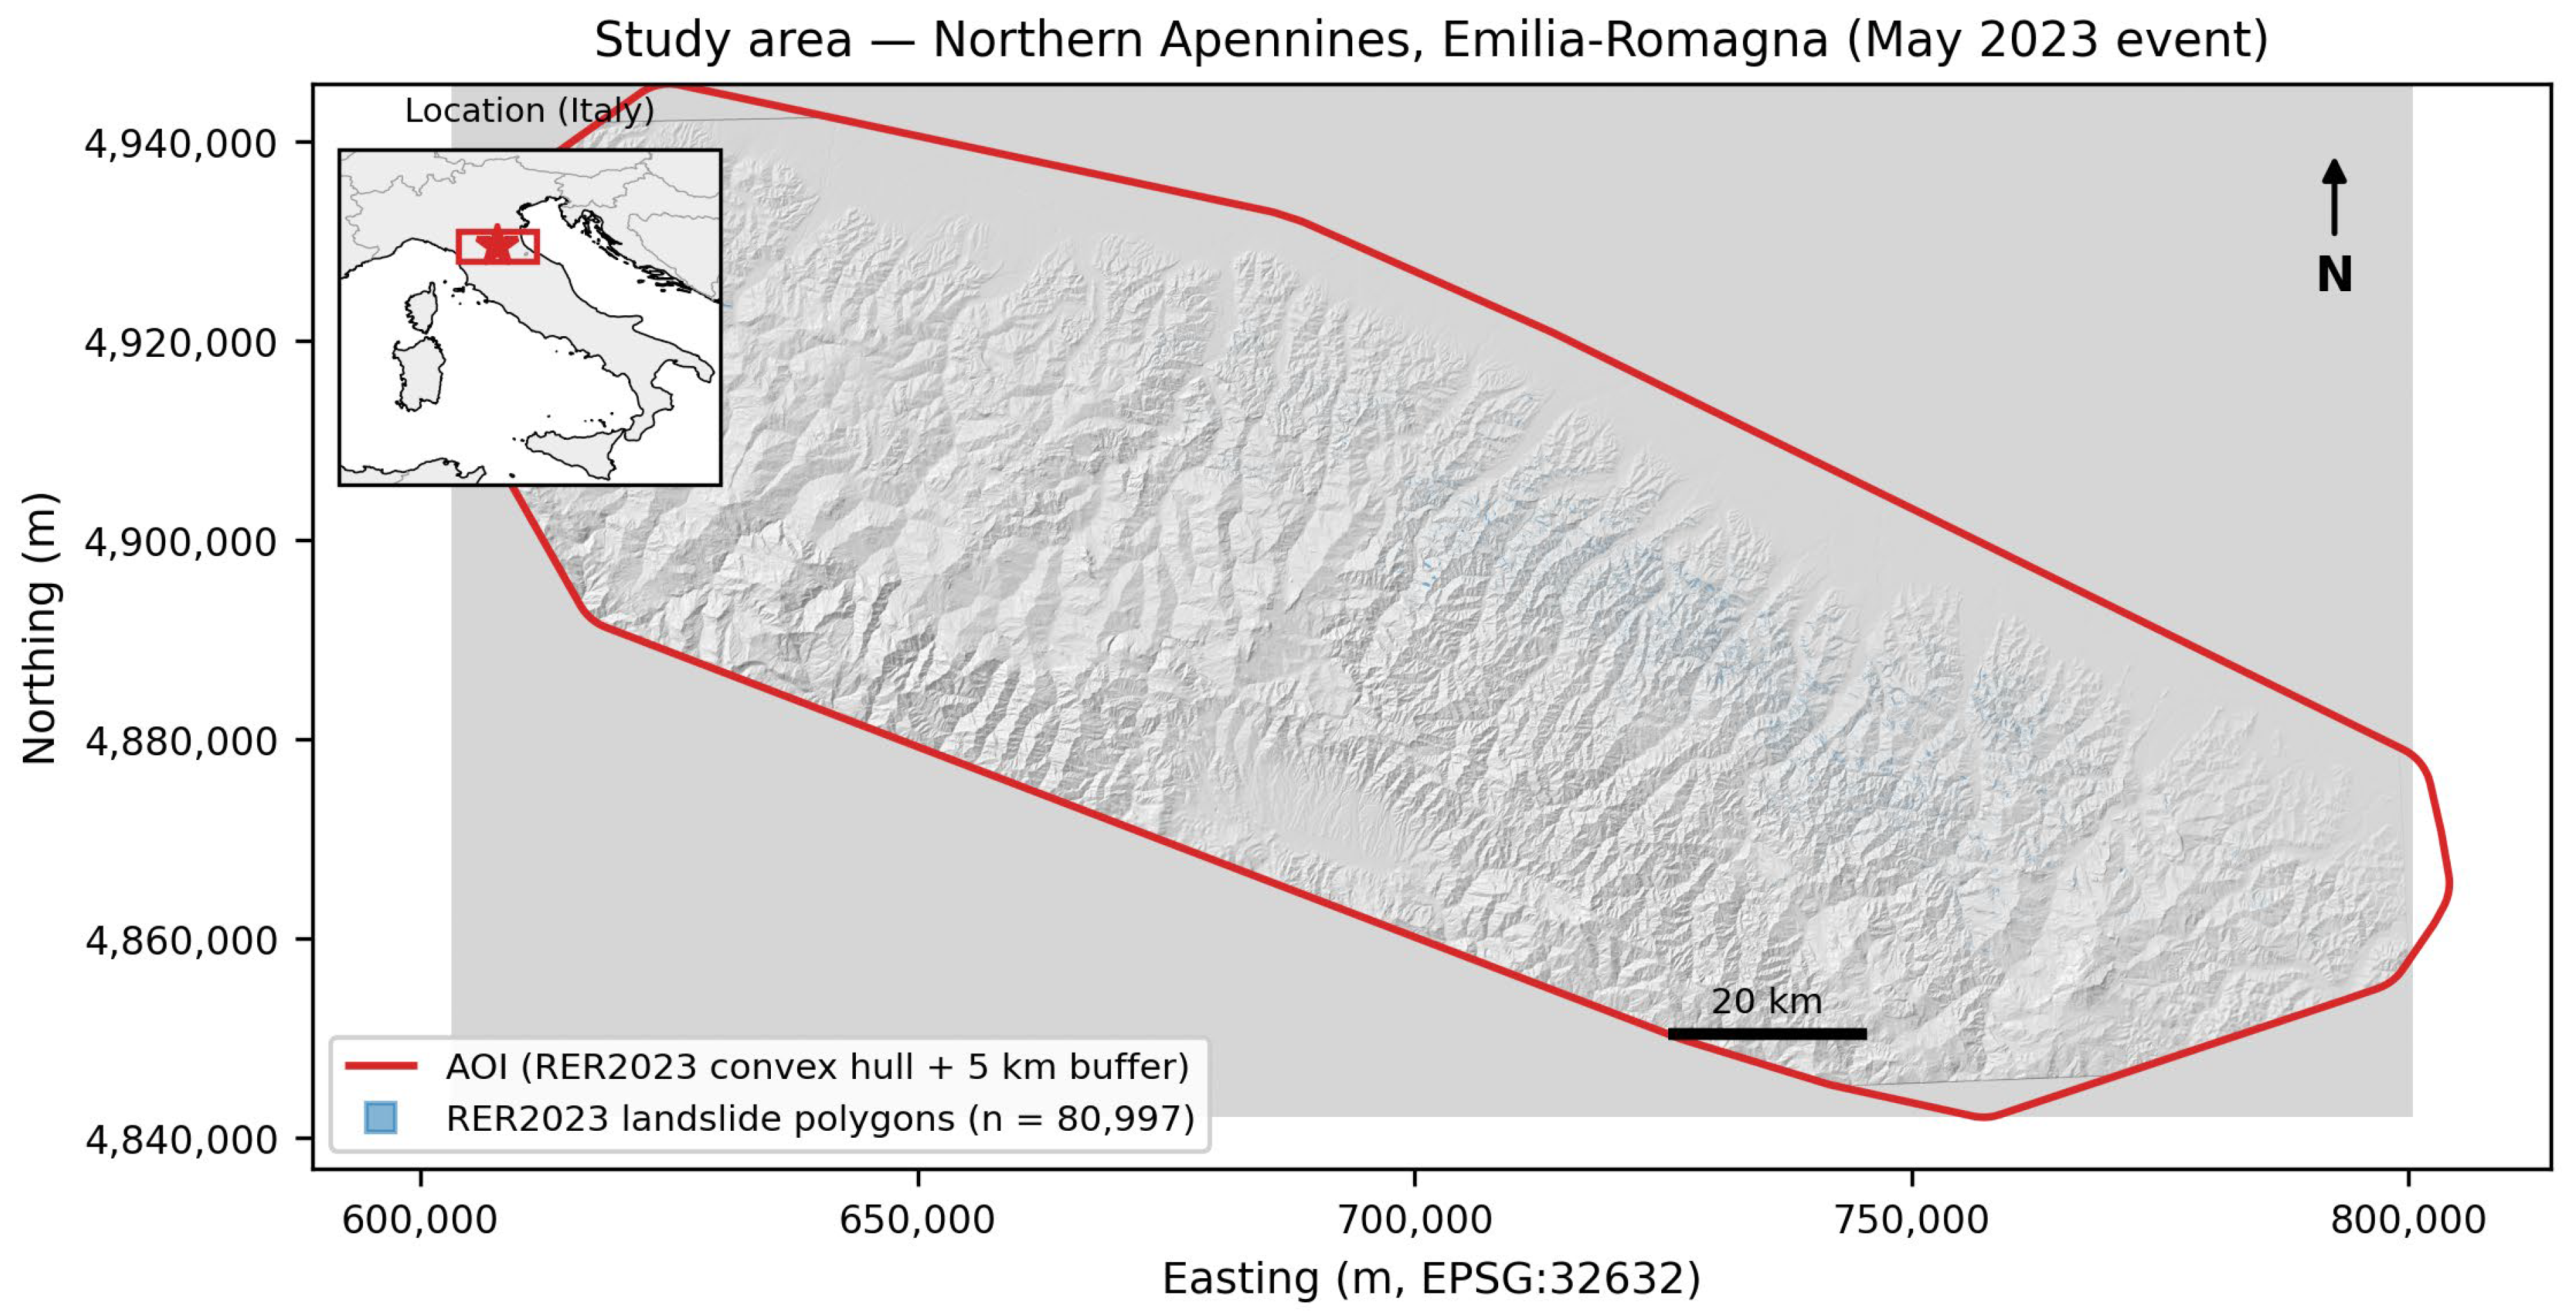
Northern Apennines of Emilia-Romagna, Italy: flysch (turbiditic sandstone/marl) and clay-shale (argille scagliose) units, moderate slopes, high drainage density, Mediterranean-transitional climate. On 1–3 May and 15–17 May 2023, two extreme rainfall episodes delivered 2-day ERA5-Land accumulations reaching ~120 mm (1–3 May) and ~160 mm (15–17 May), with peak hourly intensities of about 7 mm/h and 20 mm/h, respectively, and an event total of ~370 mm, triggering >80,000 landslides (17 fatalities, approximately EUR 10 billion in damage). This was a regionally extensive, high-impact event—spanning ~11,000 km2 and >80,000 expert-mapped failures in a single event—and is, to our knowledge, the single largest rainfall-triggered Mediterranean landslide event recorded with polygon-resolved per-failure mapping; throughout we use the established designation “May 2023 Emilia-Romagna (meteorological) event”, following the naming of the RER2023 inventory dataset. The RER2023 inventory [18] provides 80,997 expert-mapped polygons (0.2 m post-event aerial imagery; native CRS EPSG:7791 ≈ EPSG:32632). The study extent (AOI) is the convex hull of the RER2023 inventory buffered by 5 km (~11,059 km2)—an event-based domain confined to the landslide-affected Apennine belt; residual non-susceptible terrain inside the hull is handled by conditioning factors and the terrain-plausible negative-sampling strategy, not by the AOI polygon (Figure 1).
The setting is geomorphologically predisposing: the tectonized flysch and argille-scagliose (clay-shale) units weather to low-permeability, low-cohesion regolith that loses strength as pore pressures rise, so that on the moderate-to-steep, well-dissected slopes the intense multi-day rainfall of May 2023 readily triggered shallow translational and flow-type failures, concentrated where the second, more intense episode overlapped the clay-shale belt. Consistent with this, the RER2023 inventory is dominated by Debris Slides (type DS1) with subordinate Earth Slides (ES), Earth Flows (EF), Debris/earth Flows (DF), complex Debris Slides (DS2), and Rock Slides (RS2); the median polygon area is 479 m2, and this type distribution underpins the type-stratified recall analysis reported later.

3. Materials and Methods

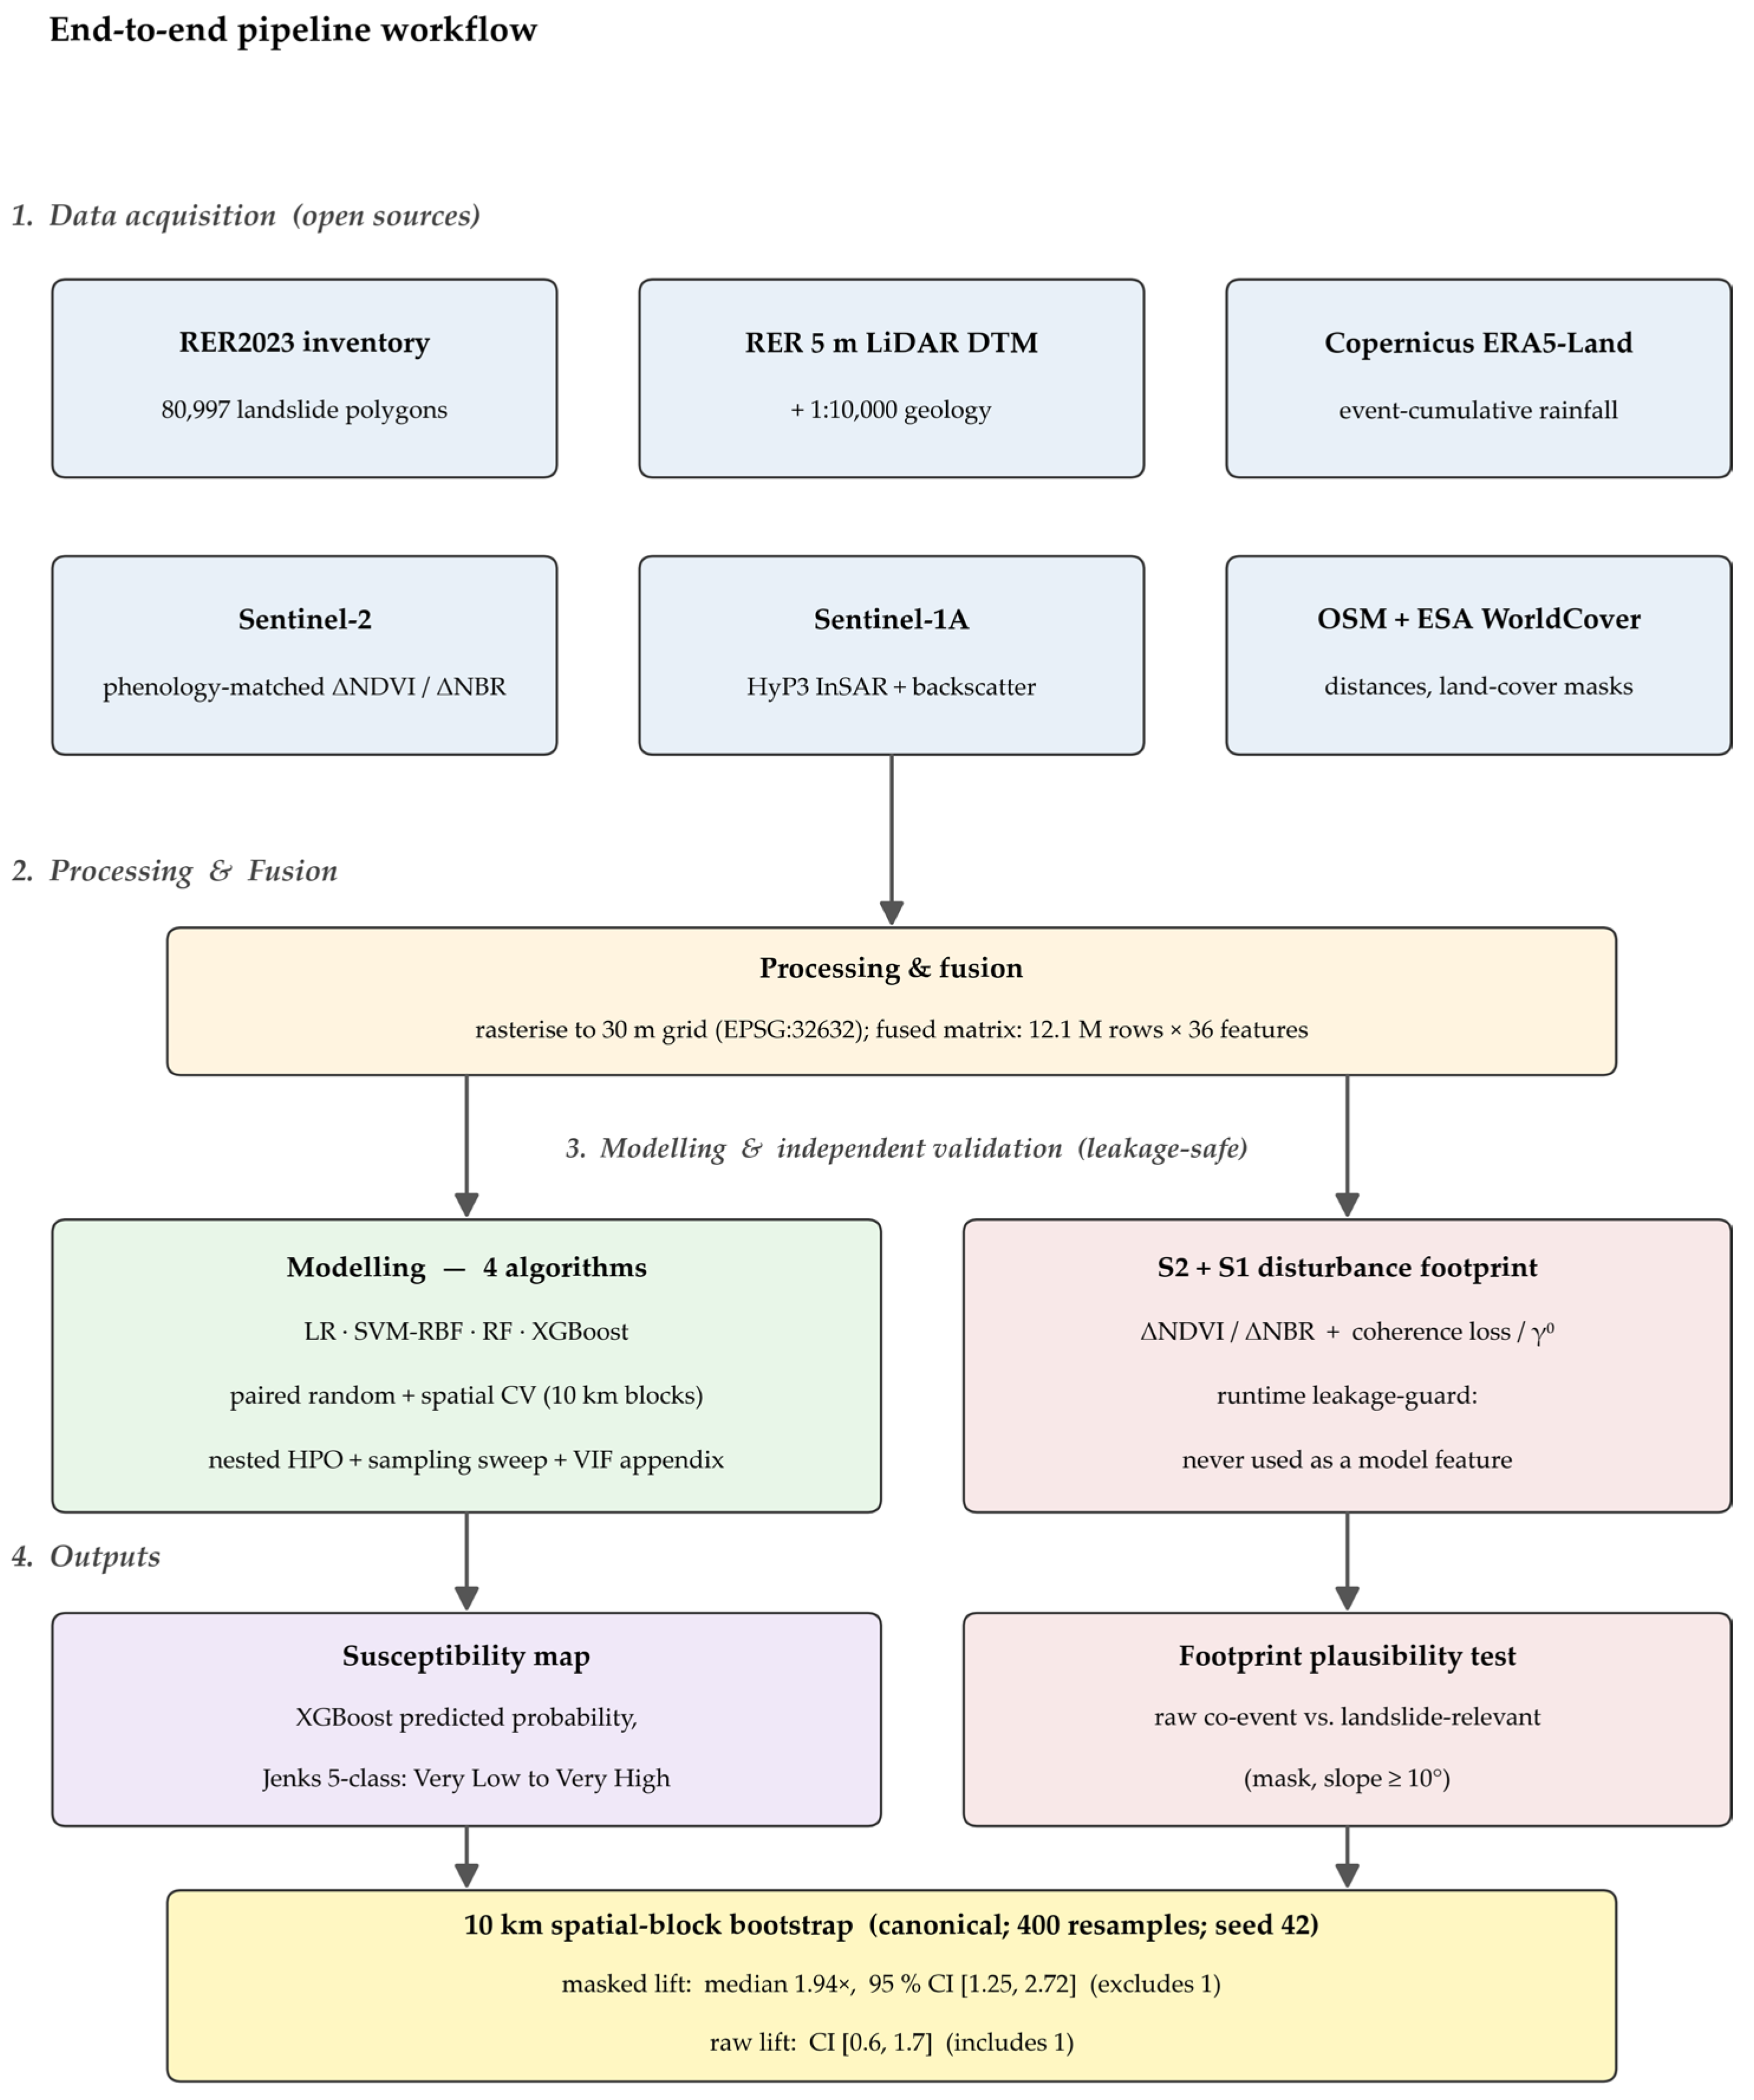
Figure 2 summarizes the end-to-end pipeline (data acquisition, processing, fusion, modeling, independent satellite validation, and bootstrap CI) referenced throughout this section.

3.1. Conditioning Factors (All Open Data; 30 m Grid, EPSG:32632)

The conditioning factors are grouped by category, with the process-based rationale for each, in Table 1; the provenance of every open input dataset—source, native resolution, coordinate reference system, and version—is given in Table 2.
  • Topographic (elevation, slope, aspect, plan/profile curvature, TWI, TRI) derived at native 5 m from the Emilia-Romagna regional LiDAR DTM (a TINITALY 10 m DTM [20] is the documented fallback), then block-aggregated to 30 m (RER2023 median polygon 479 m2 < a 30 m pixel). The topographic wetness index (TWI) and terrain ruggedness index (TRI) are defined as
    TWI = ln(a/tan β)
    TRI = √(Σ(z_cz_i)2)
    where a is the upslope contributing area per unit contour length, β the local slope, and z_c and z_i the elevations of a cell and its eight neighbors; TRI is the standard elevation-difference ruggedness index.
  • Lithology: regional 1:10,000 geological-units map, attribute SIGLA_LITOTECNICA (official lithotechnical classes incl. argille scagliose, marls, stratified competent rock, flysch alternations, evaporates; 14 classes).
  • Hydro-climatic: ERA5-Land [21] event-cumulative rainfall (episode 1, episode 2, total) by hourly de-accumulation; distance to drainage.
  • Vegetation (predisposing): pre-event Sentinel-2 cloud-masked median NDVI (multi-tile, 99.9% AOI coverage).
  • Land cover/anthropogenic: ESA WorldCover 2021 (v200); distance to roads, distance to settlements.
Post-event ΔNDVI is computed but excluded from modeling by a runtime leakage guard (validation only—Section 3.7).

3.2. Sampling Strategies (Sensitivity Analysis)

Of the 92,950 landslide pixels in the AOI, one representative pixel per landslide polygon is retained—a seeded random permutation of landslide pixels followed by the first occurrence per polygon identifier (seed = 42)—yielding 43,316 candidate positive pixels; this eliminates the intra-polygon pixel pseudo-replication that inflates LSM performance [9]. If necessary, the positives are then randomly subsampled to a per-class cap of 25,000—a size that is statistically sufficient for all four classifiers while keeping the kernel-SVM training (of quadratic-to-cubic cost) tractable; the sampling-sensitivity analysis confirms the cap is not binding on the model ranking.
Three negative-sampling strategies are compared as a controlled sensitivity analysis: (i) random—uniform random non-landslide pixels; (ii) buffered—non-landslide pixels at ≥200 m from ANY landslide pixel (k-d-tree nearest-neighbor test). The 200 m buffer is at least one order of magnitude larger than the 30 m modeling grid (so the buffer zone exceeds any single-pixel coregistration uncertainty) and is comparable to the buffer ranges (50–500 m) routinely adopted in LSM negative-sampling robustness studies [6,11]. (iii) terrain-plausible (the defensible baseline)—non-landslide pixels with slope ≥ 3°—the conventional lower bound separating effectively flat, non-failing terrain from slopes capable of mass movement—excluding water and built-up land cover. For each strategy, n_neg = ratio × n_pos with ratio ∈ {1, 2, 3} and balanced classes; the primary configuration is terrain-plausible at 1:1. Each (strategy, ratio) cell is drawn once with a fixed seed (=42); multi-seed sampling variability is a stated limitation (Section 5).

3.3. Models and Tuning

Four classifiers are evaluated: Logistic Regression, an RBF-kernel Support Vector Machine (with probability estimates enabled for SHAP), Random Forest, and XGBoost [22]. Min-max feature scaling is fit on the train fold only and applied uniformly (benign for tree-based models, which are scale-invariant). The two ensembles (Random Forest and XGBoost) are the de facto performance leaders in landslide susceptibility mapping, capturing non-linear factor interactions; Logistic Regression provides an interpretable linear baseline, and the RBF-kernel SVM a flexible non-linear decision boundary, at a quadratic-to-cubic training cost and with limited native interpretability.
Hyperparameters are tuned by nested randomized search per outer fold: 40 sampled configurations, inner 3-fold stratified CV, scoring = ROC-AUC, refit on the full outer train. The hyperparameter search spaces explored for each model are listed in Table 3. SVM has a hard training-fold cap of 8000 samples and O(n2) to O(n3) cost; the 8000 are drawn as a uniform random sub-sample (without replacement, same seed used elsewhere) from each outer-fold training partition—not stratified, since the partition is already class-balanced at 1:1 by construction and the spatial-block structure is preserved by the CV fold itself. All four models otherwise share identical folds. We probed the impact of this cap with a sensitivity re-run at 5000 vs. 8000 training samples: under spatial CV, the SVM-RBF ROC-AUC mean differed by less than 0.005 between the two caps, and the algorithm ranking (XGBoost > RF > SVM-RBF > LR) was unchanged. The cap is therefore not the binding constraint on the SVM ranking position; it serves to keep the sweep wall-clock tractable, in line with standard practice for kernel-SVM in LSM benchmarks [6]. The susceptibility map (Section 4.2) is regenerated from XGBoost only (the top-ranked algorithm); SVM-RBF is used for ranking comparison and for the sampling-sensitivity sweep, not for full-grid mapping. Class weighting is not used because all configurations are exactly balanced. Probability calibration is not applied: the susceptibility map (Section 4.2) uses Jenks natural breaks on raw probabilities, a rank-based operation robust to monotonic miscalibration. The five-class scheme (Very Low to Very High) follows the mainstream LSM convention; natural breaks are preferred over equal-interval or quantile binning because it places class boundaries at natural gaps in the predicted-probability distribution; the independent-footprint capture score (Section 4.2, RQ3) is similarly a class-rank operation (“fraction of disturbed pixels falling in the High + Very-High Jenks classes”), so it is the predicted ranking, not the absolute probability, that enters the comparison—the same monotonic robustness applies. All 36 predictors are admitted to the headline runs; the iterative variance-inflation-factor (VIF) prune (threshold 10) is applied separately as a SHAP-attribution robustness check and reported in Appendix A—so that the susceptibility map (Section 4.2) is trained on the design feature set and Section 4.6 SHAP attribution can be cross-checked against an explicitly orthogonalized feature set. Tree-ensemble predictions are robust to multicollinearity for prediction: where two predictors are strongly correlated—here, for example, slope and the terrain ruggedness index (TRI), with variance-inflation factors of 110 and 56, respectively—split selection redistributes between them without changing the predicted probability ranking on which the susceptibility classes and the capture metric depend, so retaining the full set does not bias the map. The only quantity multicollinearity can distort is the per-feature SHAP attribution (Shapley values can split importance across a collinear coalition); we therefore validate Section 4.6 attribution against an explicitly VIF-pruned (threshold 10) feature set in Appendix A, where the attribution ranking is preserved (Spearman ρ = 0.967/0.998 for XGBoost/Random Forest). Inventory-split metrics (Section 4.3) come from the outer paired-CV runs; the models persisted for SHAP and full-grid mapping (Section 4.2) are refit on the entire primary sample with the same nested-HPO protocol.

3.4. Paired Cross-Validation (RQ2)

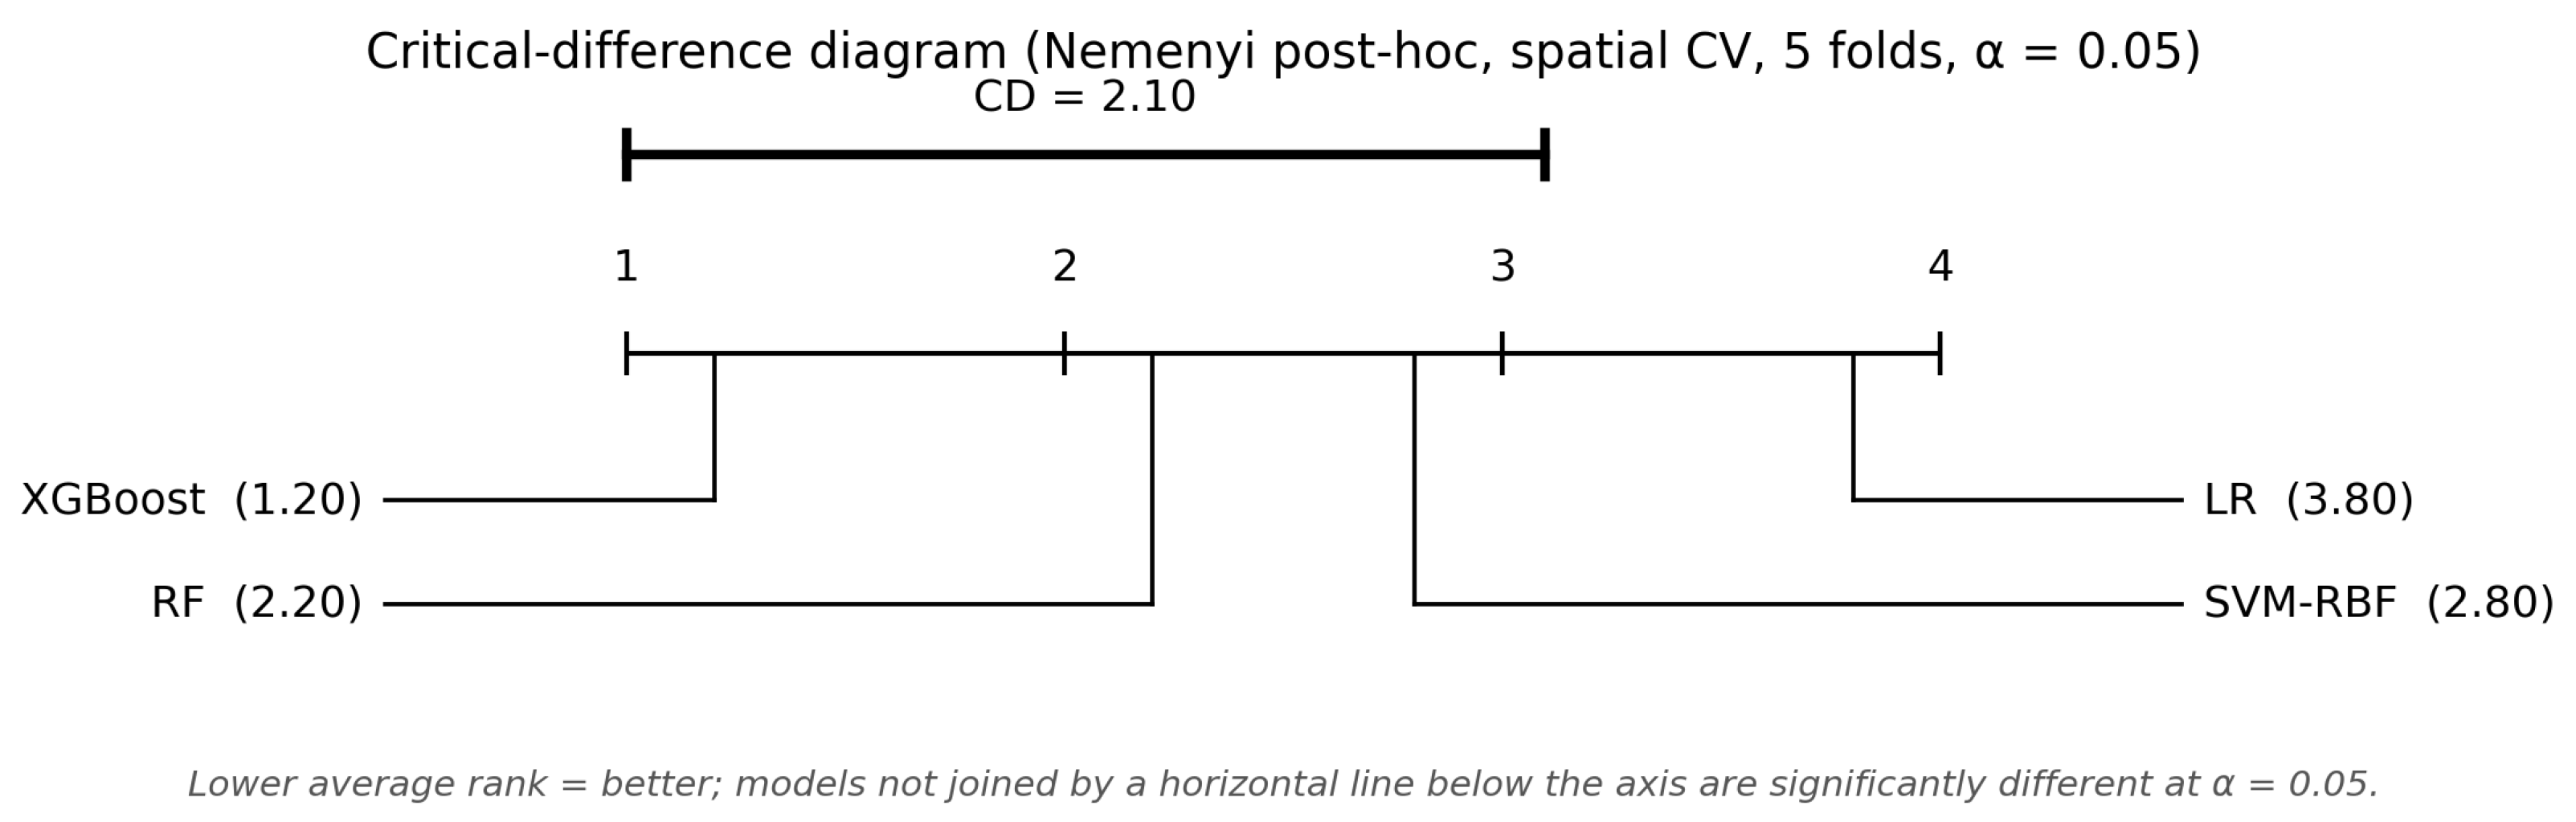
For each sampling configuration, the same balanced sample is evaluated under two paired CV schemes. (a) Random k-fold—shuffled round-robin assignment of sample indices. (b) Spatially blocked k-fold—each pixel is assigned to a unique block identifier from its projected coordinates on a 10 km × 10 km grid (the 10 km grid cell containing the pixel’s projected coordinates), and entire blocks are held out together (a GroupKFold equivalent; seeded round-robin allocation of unique block ids into k folds). We use five outer folds and a single fixed random seed; the 10 km block size is the spatial-CV literature default [8,12] and is chosen empirically rather than from a variogram of the conditioning factors. A sensitivity sweep over CV block sizes is not performed in the main runs—the bootstrap-CI sensitivity at three block scales reported in Section 4.7 (v) is a separate exercise that estimates statistical uncertainty on the lift, not the data-leakage prevention budget of the outer CV. The 10 km default is stated as an explicit limitation: a variographically informed block size, or a CV block-size sensitivity sweep applied to all four models, would tighten the optimism estimate but is left for follow-up. “Paired” means the same sample rows feed both schemes, so per-model per-fold AUC differences are within-sample, and the optimism gap (random-spatial AUC, per model) is paired-comparable. Models are ranked per fold; Friedman’s omnibus test (n_folds = 5, n_models = 4) tests equality, and a Nemenyi post hoc with the Demšar critical difference [23] (α = 0.05) supports the critical-difference diagram (Figure 3). With only five folds, the test has modest statistical power; the algorithm ranking is therefore reported as a secondary consistency check, not the primary claim.

3.5. Metrics

Six classification metrics are computed per outer test fold: AUC-ROC (threshold-free), F1, precision, recall, Cohen’s kappa (κ), and accuracy. The latter five use a fixed decision threshold of 0.5 on the predicted positive-class probability (the sklearn default); reporting them at the conventional threshold rather than at a tuned operating point keeps the comparison directly interpretable across models and sampling configurations. AUC is computed per fold and then averaged (not pooled). Per-fold values are aggregated as mean ± standard deviation across the k = 5 folds; the standard deviation is the principal inventory-split uncertainty estimator. The independent-validation metric (RQ3; Section 4.2 and Section 4.7) is reported separately because it is a capture statistic on the full predicted grid against an external footprint, not on the inventory-split samples.

3.6. Explainability

SHAP values [24] quantify each conditioning factor’s contribution to the predicted susceptibility—testing whether the model’s signal is governed by rainfall, terrain, and lithology in a physically coherent way—and are computed for the two ensemble models (XGBoost and Random Forest), which dominate the algorithm ranking and supply the susceptibility surface used for RQ3. We use an exact tree explainer for Random Forest and a model-agnostic explainer (with a background sample) for XGBoost—the latter to avoid a known base-score parsing issue in the XGBoost 2.x tree explainer that does not affect the resulting values—and a linear explainer for Logistic Regression. SHAP values for SVM-RBF are not reported in the main text (the kernel SVM is not a SHAP-attribution leader and contributes only as a comparison classifier; the SHAP discussion in Section 4.6 therefore restricts to the two ensemble models). The background sample is 200 examples drawn (seeded) from the scaled primary balanced sample; the evaluation sample is min(4000, n) drawn the same way. From these, we derive the global factor importance, a beeswarm summary of the per-sample contributions, and a spatial map of the leading factor’s per-pixel SHAP value, used for geomorphological interpretation. Global factor importance is the mean absolute SHAP value over the N evaluation samples, φ ¯ j = 1 N i = 1 N φ i j for feature j. SHAP interaction values and partial-dependence plots are not reported here.

3.7. Independent Validation (RQ3)

The observed co-event disturbance footprint is built from phenology-matched Sentinel-2: a near-immediate post-event clear composite (18 May–5 June 2023) differenced against same-season pre-event baselines (same-year April 2023 and a pristine prior-year May–June 2022 anchor at matching day-of-year), for both ΔNDVI and ΔNBR (each defined as the post-event minus pre-event index value, ΔNDVI = NDVI_post − NDVI_pre, so negative values denote vegetation/cover loss). A pixel is flagged as disturbed when the index change drops below −0.15. This threshold is anchored empirically on the RER2023 inventory itself: within the landslide-relevant masked domain, pixels falling inside mapped RER2023 polygons have a phenology-matched ΔNDVI of mean −0.20 (median −0.18; 25th percentile −0.27) against −0.01 for pixels outside the polygons—a ≈0.20-unit separation. The −0.15 threshold lies between these means, inside the upper quartile of the inside-polygon distribution. The −0.15 operating point is anchored entirely on the RER2023 inventory itself; we do not invoke literature precedent because the spectral and lithological context of this study (Sentinel-2 over Apennine flysch/argille-scagliose at peak spring phenology) is sufficiently specific that comparable thresholds from other sensors and settings (e.g., RapidEye over Kyrgyzstan) cannot serve as a meaningful precedent. A formal four-threshold sensitivity (Table 4) confirms the landslide-relevant lift is robust across thresholds: −0.10 → 1.71×, −0.15 → 2.00×, −0.20 → 2.17×, −0.25 → 2.24× (raw lift stays at chance: 1.04–1.07×). We report the fraction of disturbed pixels in each predicted class (Jenks 5-class) and, as the decisive reference, the predicted-class base rate (the random-mask expectation). The Sentinel-1 layer is built from ASF HyP3 InSAR coherence loss and γ0 backscatter change between a pre-event and an event-straddling 12-day Sentinel-1A pair. Neither optical nor SAR disturbance ever entered training or feature selection—a leakage-safe check that is independent of the model’s inputs (the threshold calibration, however, uses the inventory; Section 5). Because the May 2023 event was simultaneously a catastrophic flood, a raw co-event footprint conflates landslide with flood and agricultural disturbance. We therefore evaluate the map against the footprint in two forms: (a) raw, over the full modeled domain; and (b) a landslide-relevant footprint that excludes water, wetland, cultivated and built-up land cover, and low-slope terrain (slope ≥ 5° and ≥10° reported), with the predicted-class base rate recomputed on the same masked domain so that capture is always compared with the matching random-mask expectation. The contrast between (a) and (b) is itself a primary result. Three robustness checks guard the interpretation: (i) the footprint is confronted with the RER2023 inventory itself (enrichment and recall of mapped landslide pixels); (ii) a slope-only classifier of equal positive prevalence and a within-slope-decile stratification test whether the masked lift is merely slope autocorrelation; and (iii) all lifts carry 95% confidence intervals from a 10 km spatial-block bootstrap (400 resamples) that respects spatial autocorrelation. The capture lift is defined as:
lift = p_HV(disturbed)/p_HV(domain)
where p_HV(disturbed) is the fraction of independently disturbed pixels falling in the High + Very-High predicted classes and p_HV(domain) the same fraction over the matching domain (the random-mask expectation); the 95% confidence interval is the 2.5th–97.5th percentile of the lift recomputed over 400 resamples of the 10 km spatial blocks drawn with replacement.
As an objective cross-check of this operating threshold, we treat “pixel inside a mapped RER2023 polygon” as the label and the magnitude of the phenology-matched ΔNDVI decrease (i.e., −ΔNDVI) as the score over the landslide-relevant domain: it discriminates inside- from outside-polygon pixels with a ROC AUC of 0.86, confirming that the phenology-matched ΔNDVI is a valid landslide-disturbance discriminator rather than generic land-surface change. The Youden-J-optimal operating point is ΔNDVI ≈ −0.065; the −0.15 used here is more conservative (higher precision, lower false-positive rate at the cost of recall), and the four-threshold sensitivity (Table 4) shows the masked-lift conclusion holds across the −0.10 to −0.25 range, so the result does not hinge on the specific operating value.

4. Results

4.1. Data and Factor Summary

The feature matrix comprises 12,057,409 valid 30 m pixels and 36 predictors; the inventory contributes 92,950 landslide pixels belonging to 43,316 distinct polygons within the AOI. Models are trained on one representative point per landslide polygon plus terrain-plausible negatives (25,000 per class). A degenerate blank lithology class is excluded in feature selection.
The results are organized by evidential role. We lead with the independent multi-sensor remote-sensing plausibility test (Section 4.2)—the central contribution of this paper; the supporting inventory-split analyses that establish the model are statistically sound (model comparison, cross-validation optimism, negative-sampling sensitivity, and SHAP attribution; Section 4.3, Section 4.4, Section 4.5 and Section 4.6); the robustness and adversarial checks (Section 4.7); and the spatial-heterogeneity analysis (Section 4.8) follow.

4.2. Independent Multi-Sensor RS Plausibility Test (Sentinel-2 + Sentinel-1)

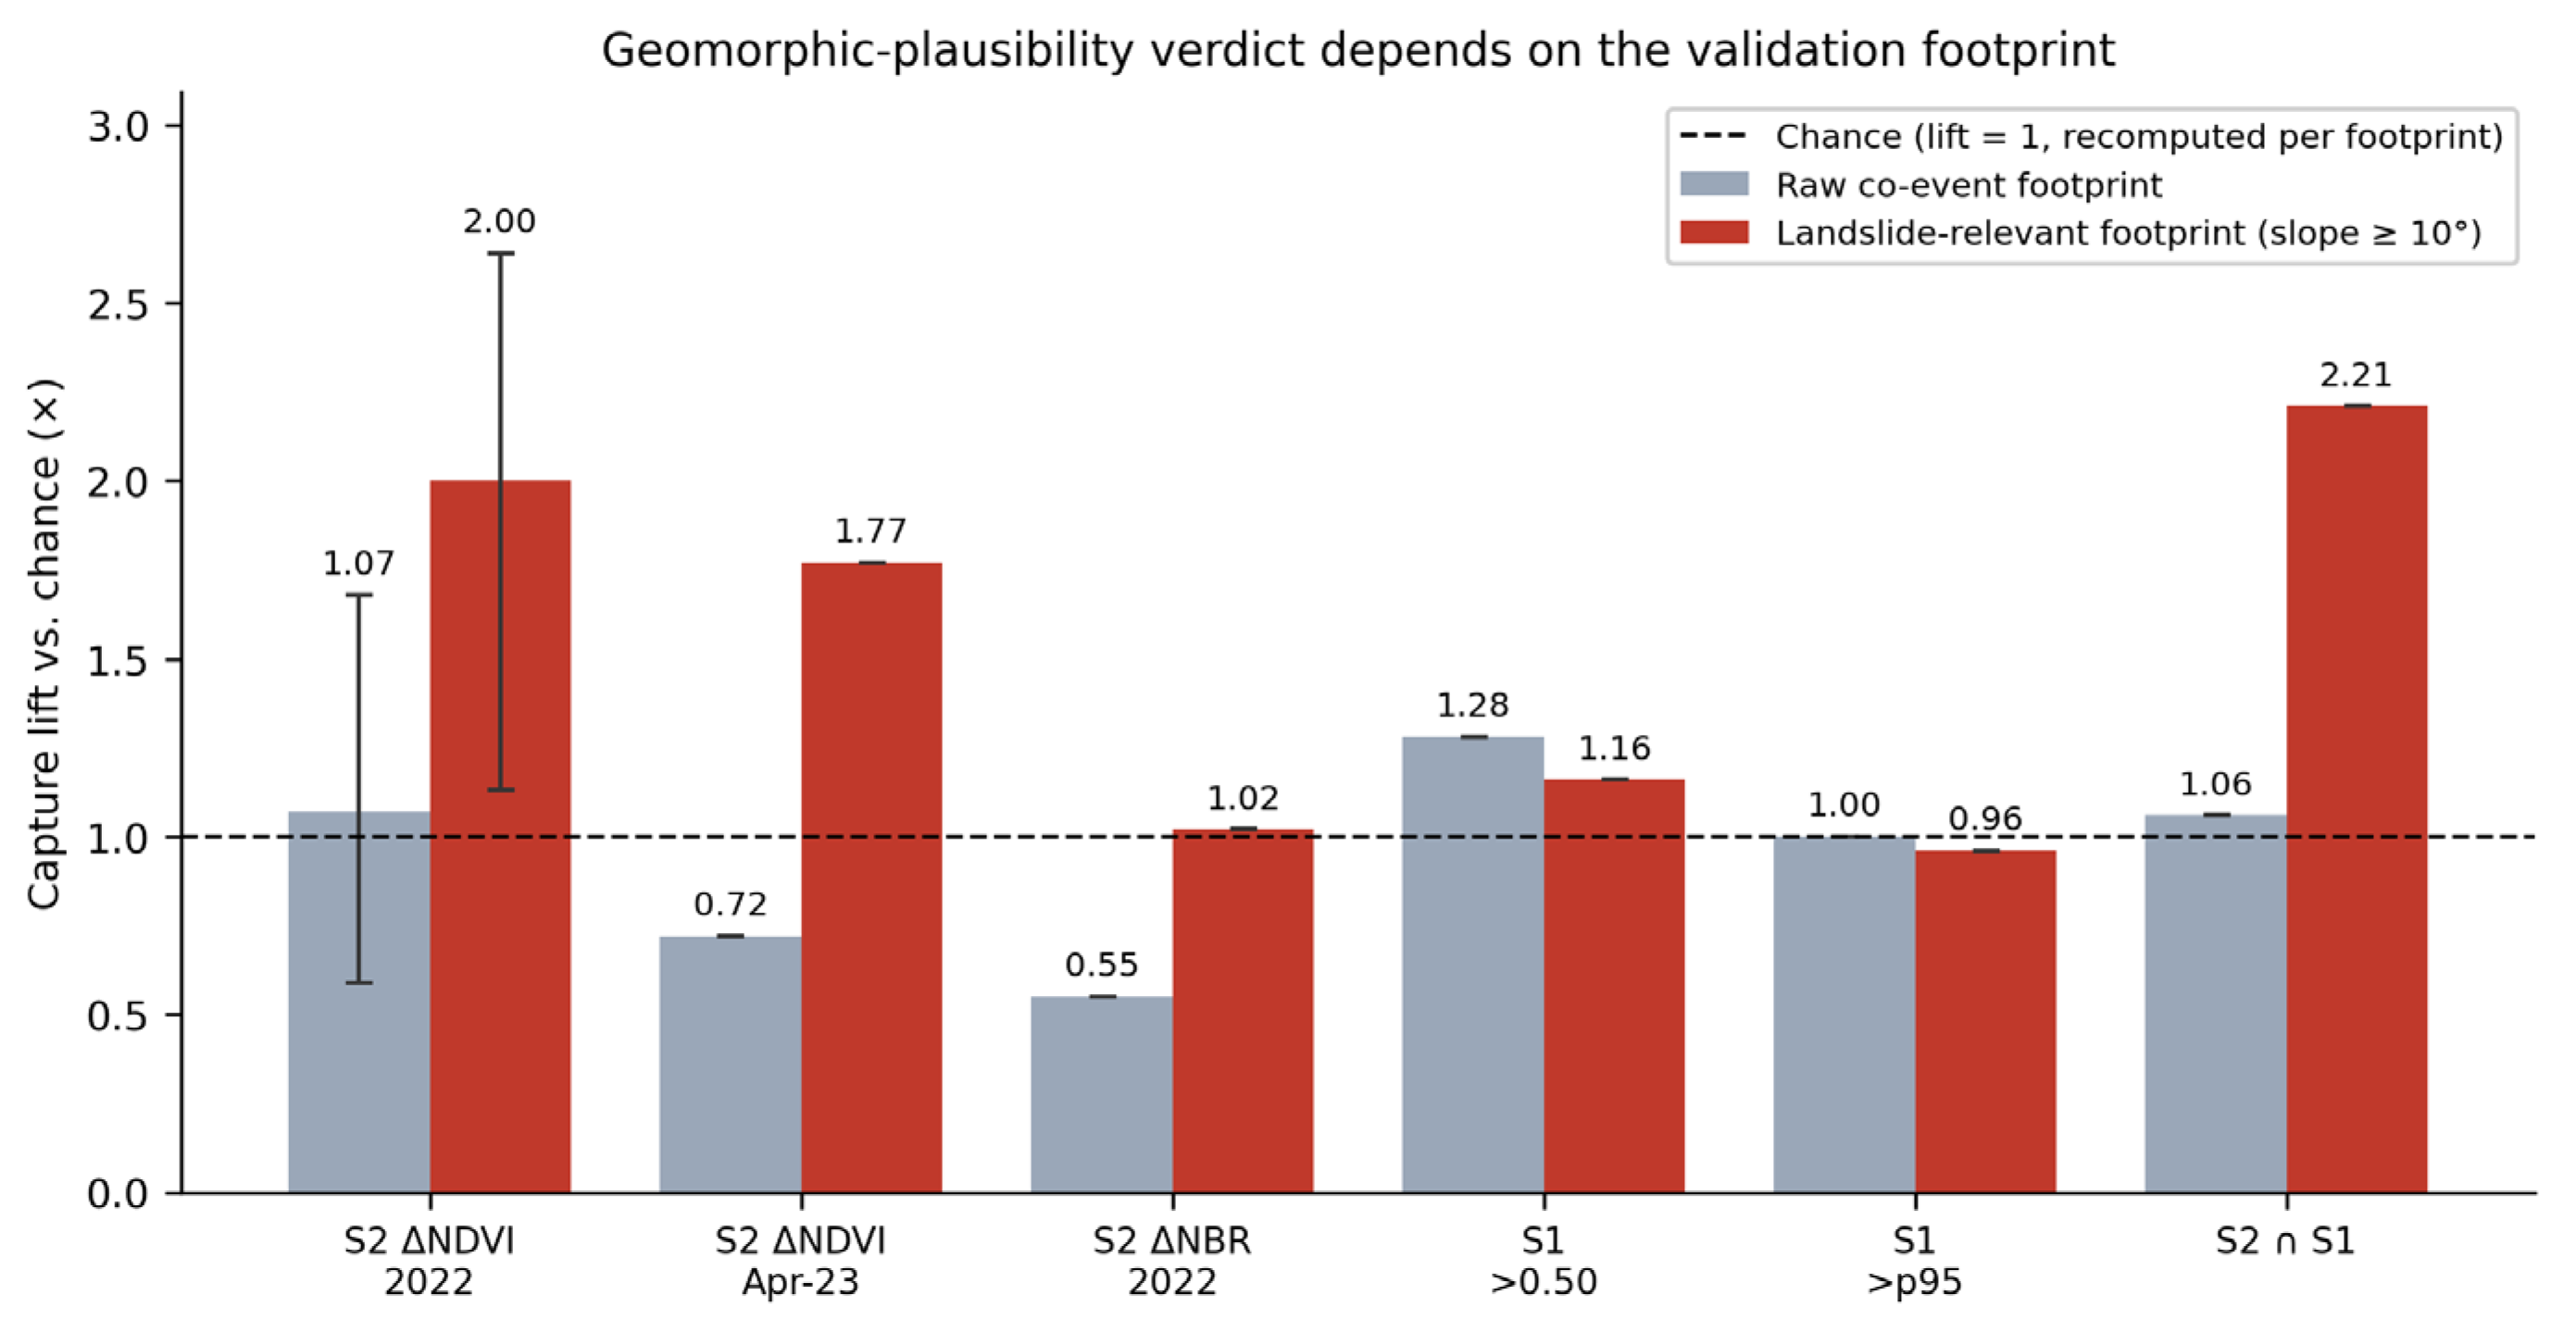
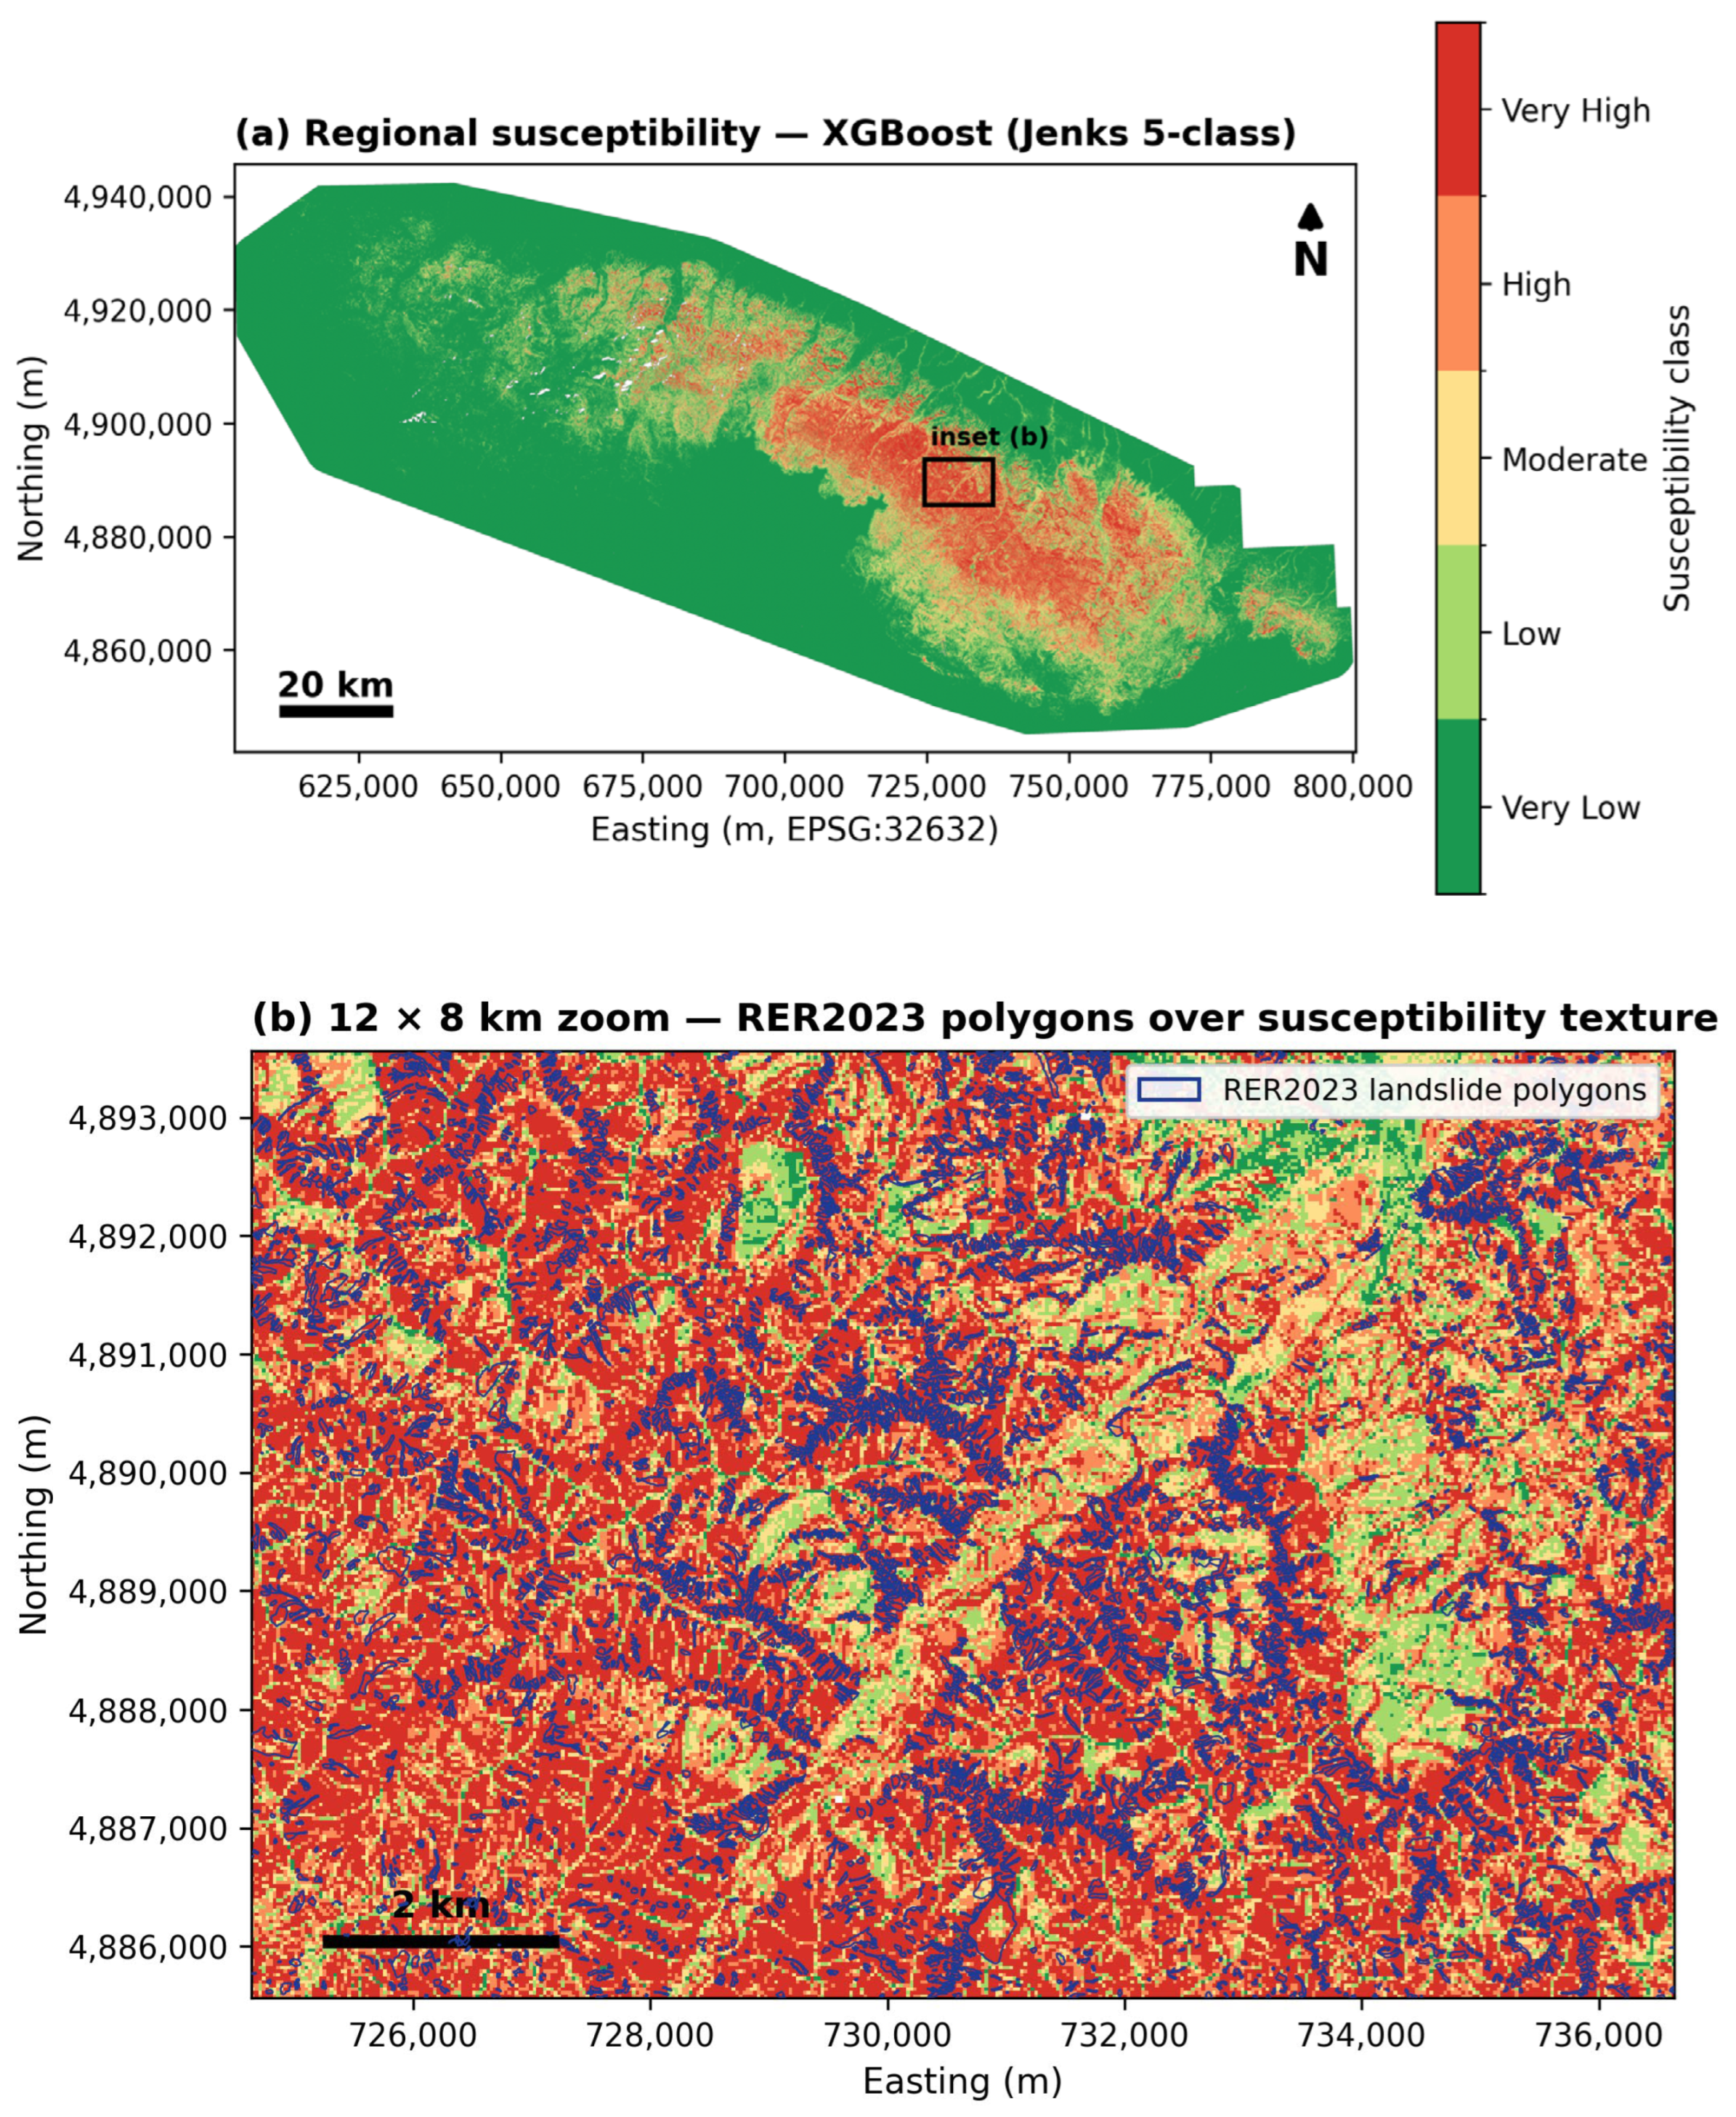
This is the core contribution. The predicted susceptibility surface (Figure 4) is the full-grid output of the XGBoost model; its inventory-split performance (AUC ≈ 0.945) is reported separately in the model-comparison analysis (Section 4.3). Here that surface is confronted with a co-event disturbance footprint derived independently from two satellites (never model inputs; leakage-safe). Capture of observed disturbance by the High + Very-High classes is summarized in Table 5 and Figure 5.
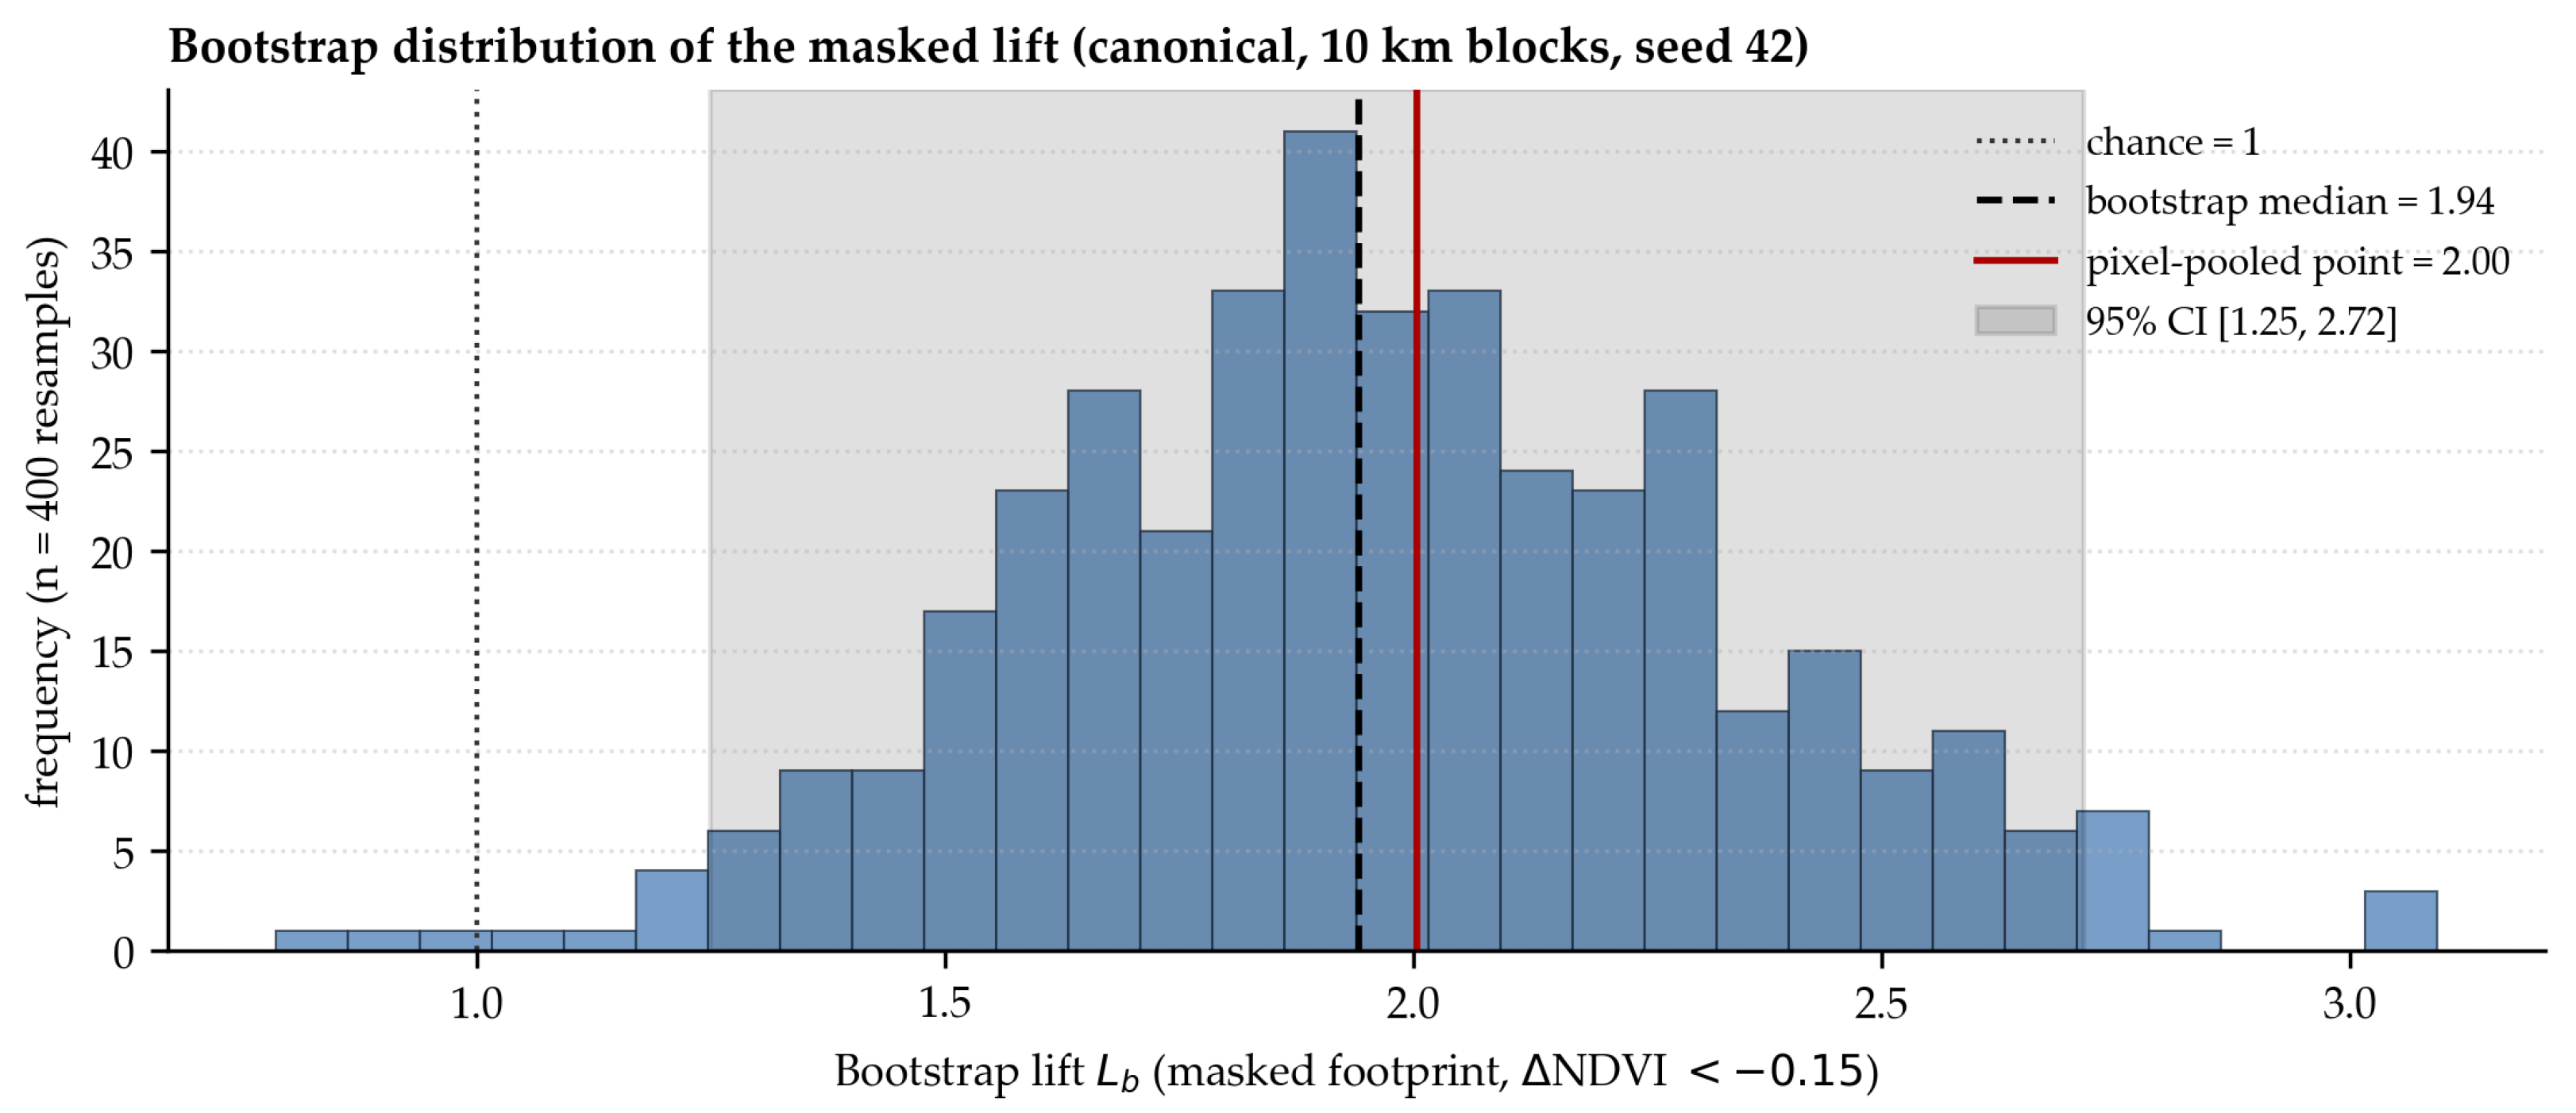
Raw co-event footprint (full domain). A first-pass ΔNDVI from seasonally offset operational composites placed only 14.9% of 630,856 disturbance pixels in the High + Very-High classes; that comparison is phenology-confounded, so it is replaced by a phenology-matched footprint. Over the full modeled domain, the predicted-class base rate is High + Very-High = 11.9%, i.e., a spatially random mask scores ≈ 11.9%. Phenology-matched, the model captures 12.7% of ΔNDVI disturbance (prior-year-anchored pair, 3.84 M pixels) and 8.6% with the same-year April baseline; ΔNBR 6.6%; Sentinel-1 11.9–15.2% across thresholds; the optical–SAR intersection 12.6% (Table 5). On the raw footprint, the AUC ≈ 0.945 model therefore appears no better than a random mask (ΔNDVI lift 1.07×; 95% spatial-block-bootstrap CI 0.6–1.7, i.e., not distinguishable from chance). Sentinel-1 (descending track-95 coherence loss plus ascending + descending γ0 backscatter; the ascending track-117 InSAR failed HyP3 GAMMA coregistration because the AOI sits near the swath edge for that track, leaving insufficient common reference/event frame overlap to support sub-pixel coregistration) covers 93.6% of the domain, so this near-chance result is not an optical-cloud artifact. Landslide-relevant footprint. The raw footprint is contaminated: the May 2023 event also produced widespread flooding, and the domain includes cultivated valley floors, so much of the raw disturbance is non-landslide. Restricting the footprint to landslide-relevant terrain—excluding water, wetland, cultivated and built-up land cover, and low slopes, with the base rate recomputed on the same masked domain—changes the picture materially (Table 6). At slope ≥ 10° (34% of pixels removed; recomputed chance 16.5%), the phenology-matched prior-year ΔNDVI capture rises to 33.1% (lift 2.00×; 95% spatial-block-bootstrap CI 1.25–2.72, excluding 1), the same-year April pair to 29.2% (1.77×), and the optical–SAR intersection to 36.4% (2.21×); the slope ≥ 5° variant is consistent (ΔNDVI 26.8%, lift 1.84×). Sentinel-1 coherence and ΔNBR remain near chance even on the masked footprint (0.96–1.16×), consistent with the known 12-day Sentinel-1A vegetation-decorrelation baseline (mean coherence loss ≈ 0.36) and ΔNBR cloud-shadow sensitivity; the phenology-matched optical ΔNDVI is the informative proxy here.
Synthesis. The verdict on geomorphic plausibility is decided by how the independent footprint is built. Against a raw co-event footprint, the statistically strong model (AUC ≈ 0.945) is indistinguishable from random; against a process-targeted, landslide-relevant footprint, the same model captures observed disturbance at an aggregate ≈ 2× chance—modest, genuine geomorphic skill that is nonetheless far below what the inventory-split AUC implies and that (Section 4.7) is spatially heterogeneous rather than a transferable local guarantee. Independent-validation footprint construction is thus decisive: a single contaminated comparison can make a skillful model appear random, while a process-targeted comparison exposes a real but bounded skill–plausibility gap.

4.3. Model Comparison (Terrain-Plausible Negatives, Spatial CV—Reference Baseline)

Under spatially blocked CV with terrain-plausible negatives, AUC and Cohen’s κ (mean over 5 folds) are given in Table 7. The ranking XGBoost > RF > SVM-RBF > LR is identical across every sampling strategy and CV scheme. A Friedman test over the five spatial folds rejects equality of the four models (χ2 = 10.68, p = 0.014; mean ranks XGBoost 1.2, RF 2.2, SVM-RBF 2.8, LR 3.8; under random CV χ2 = 15.0, p = 0.0018). The Nemenyi critical-difference diagram (Figure 3) confirms a consistent two-tier separation (ensembles vs. LR/SVM).

4.4. Cross-Validation Optimism (RQ2)

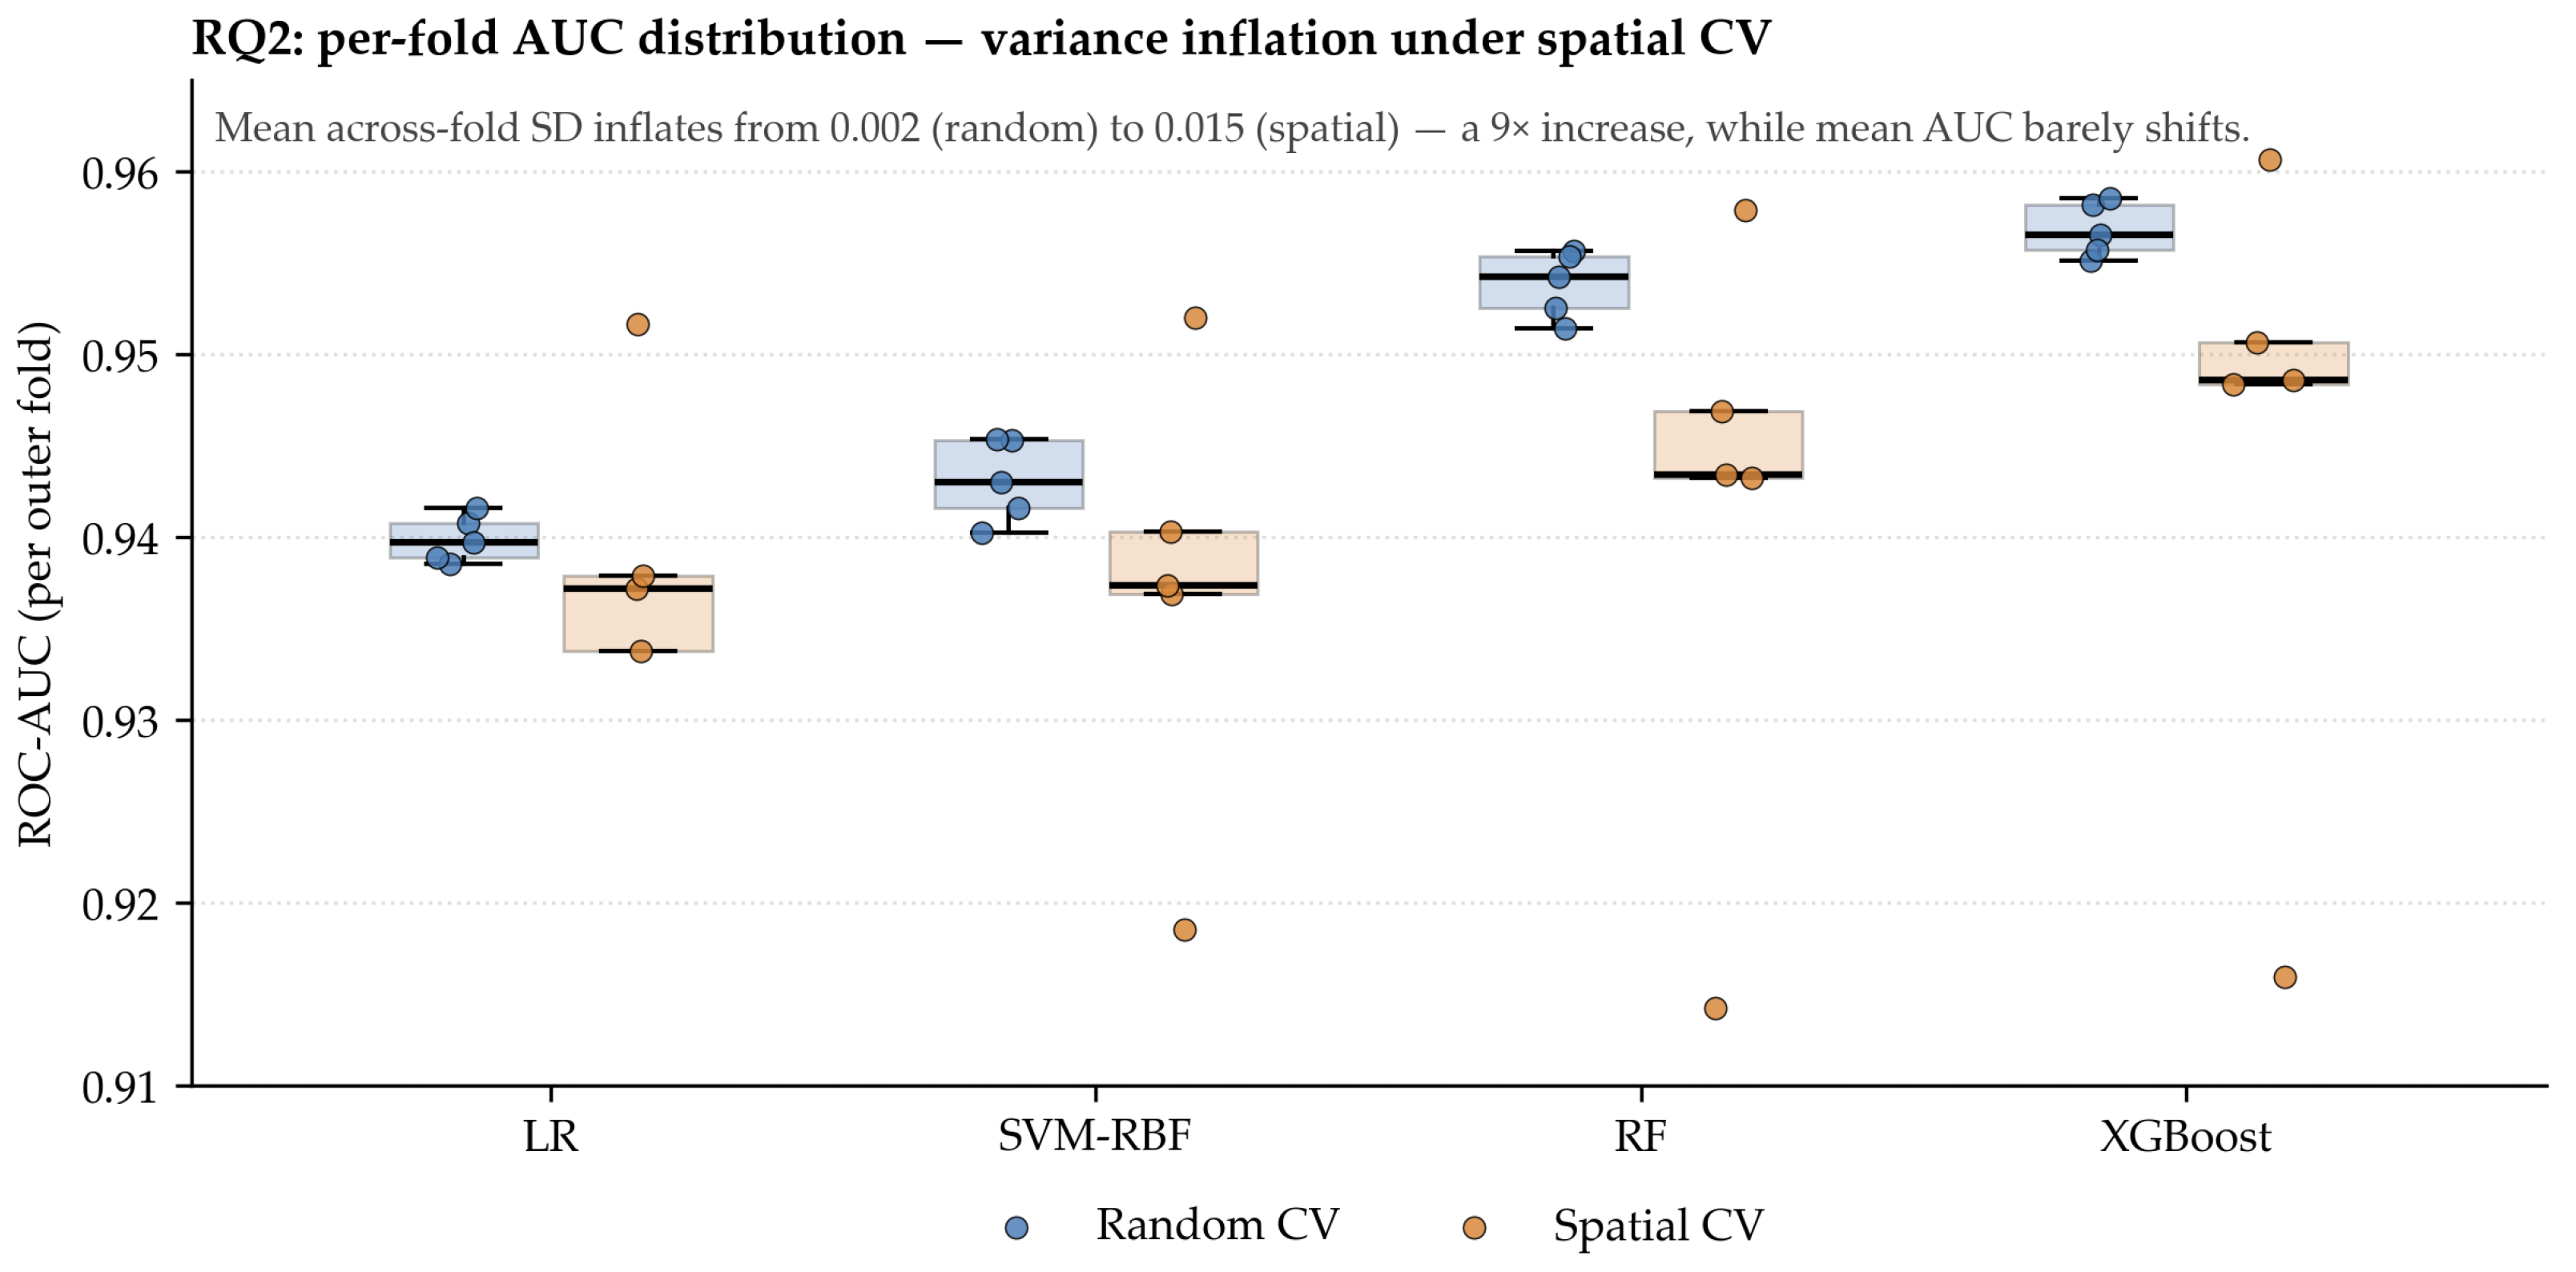
The random−spatial AUC optimism is modest (LR 0.006, SVM 0.006, RF 0.013, XGB 0.012). The dominant effect is variance inflation: AUC standard deviation rises from ≈0.001 under random CV to 0.008–0.015 under spatial CV (≈10×), i.e., apparent performance is region-dependent and single-split estimates are unstable. Figure 6 shows the per-fold AUC distribution under the two CV schemes for all four models: the mean is essentially unchanged while the across-fold spread expands ≈ 9×. Marked variance inflation under spatially structured CV is expected for autocorrelated environmental data and is documented in the spatial-validation literature [12,13,25,26]; the magnitude here is on the high end, consistent with the strong spatial clustering of a single triggering event. These cross-validation design effects are established practice, reported here only to bound how much apparent skill is methodological; they are not this study’s contribution, which is the independent footprint construction of Section 4.2.

4.5. Negative-Sampling Sensitivity

Holding the model, ratio (1:1), and CV scheme fixed, the negative-sampling strategy alone drives large performance shifts (spatial CV, XGBoost; Table 8): a ≈0.035 AUC and ≈0.10 κ swing from sampling design only, consistent across all four models. Buffered-random negatives (common in the literature) systematically inflate reported skill relative to the terrain-plausible baseline.

4.6. SHAP Factor Importance

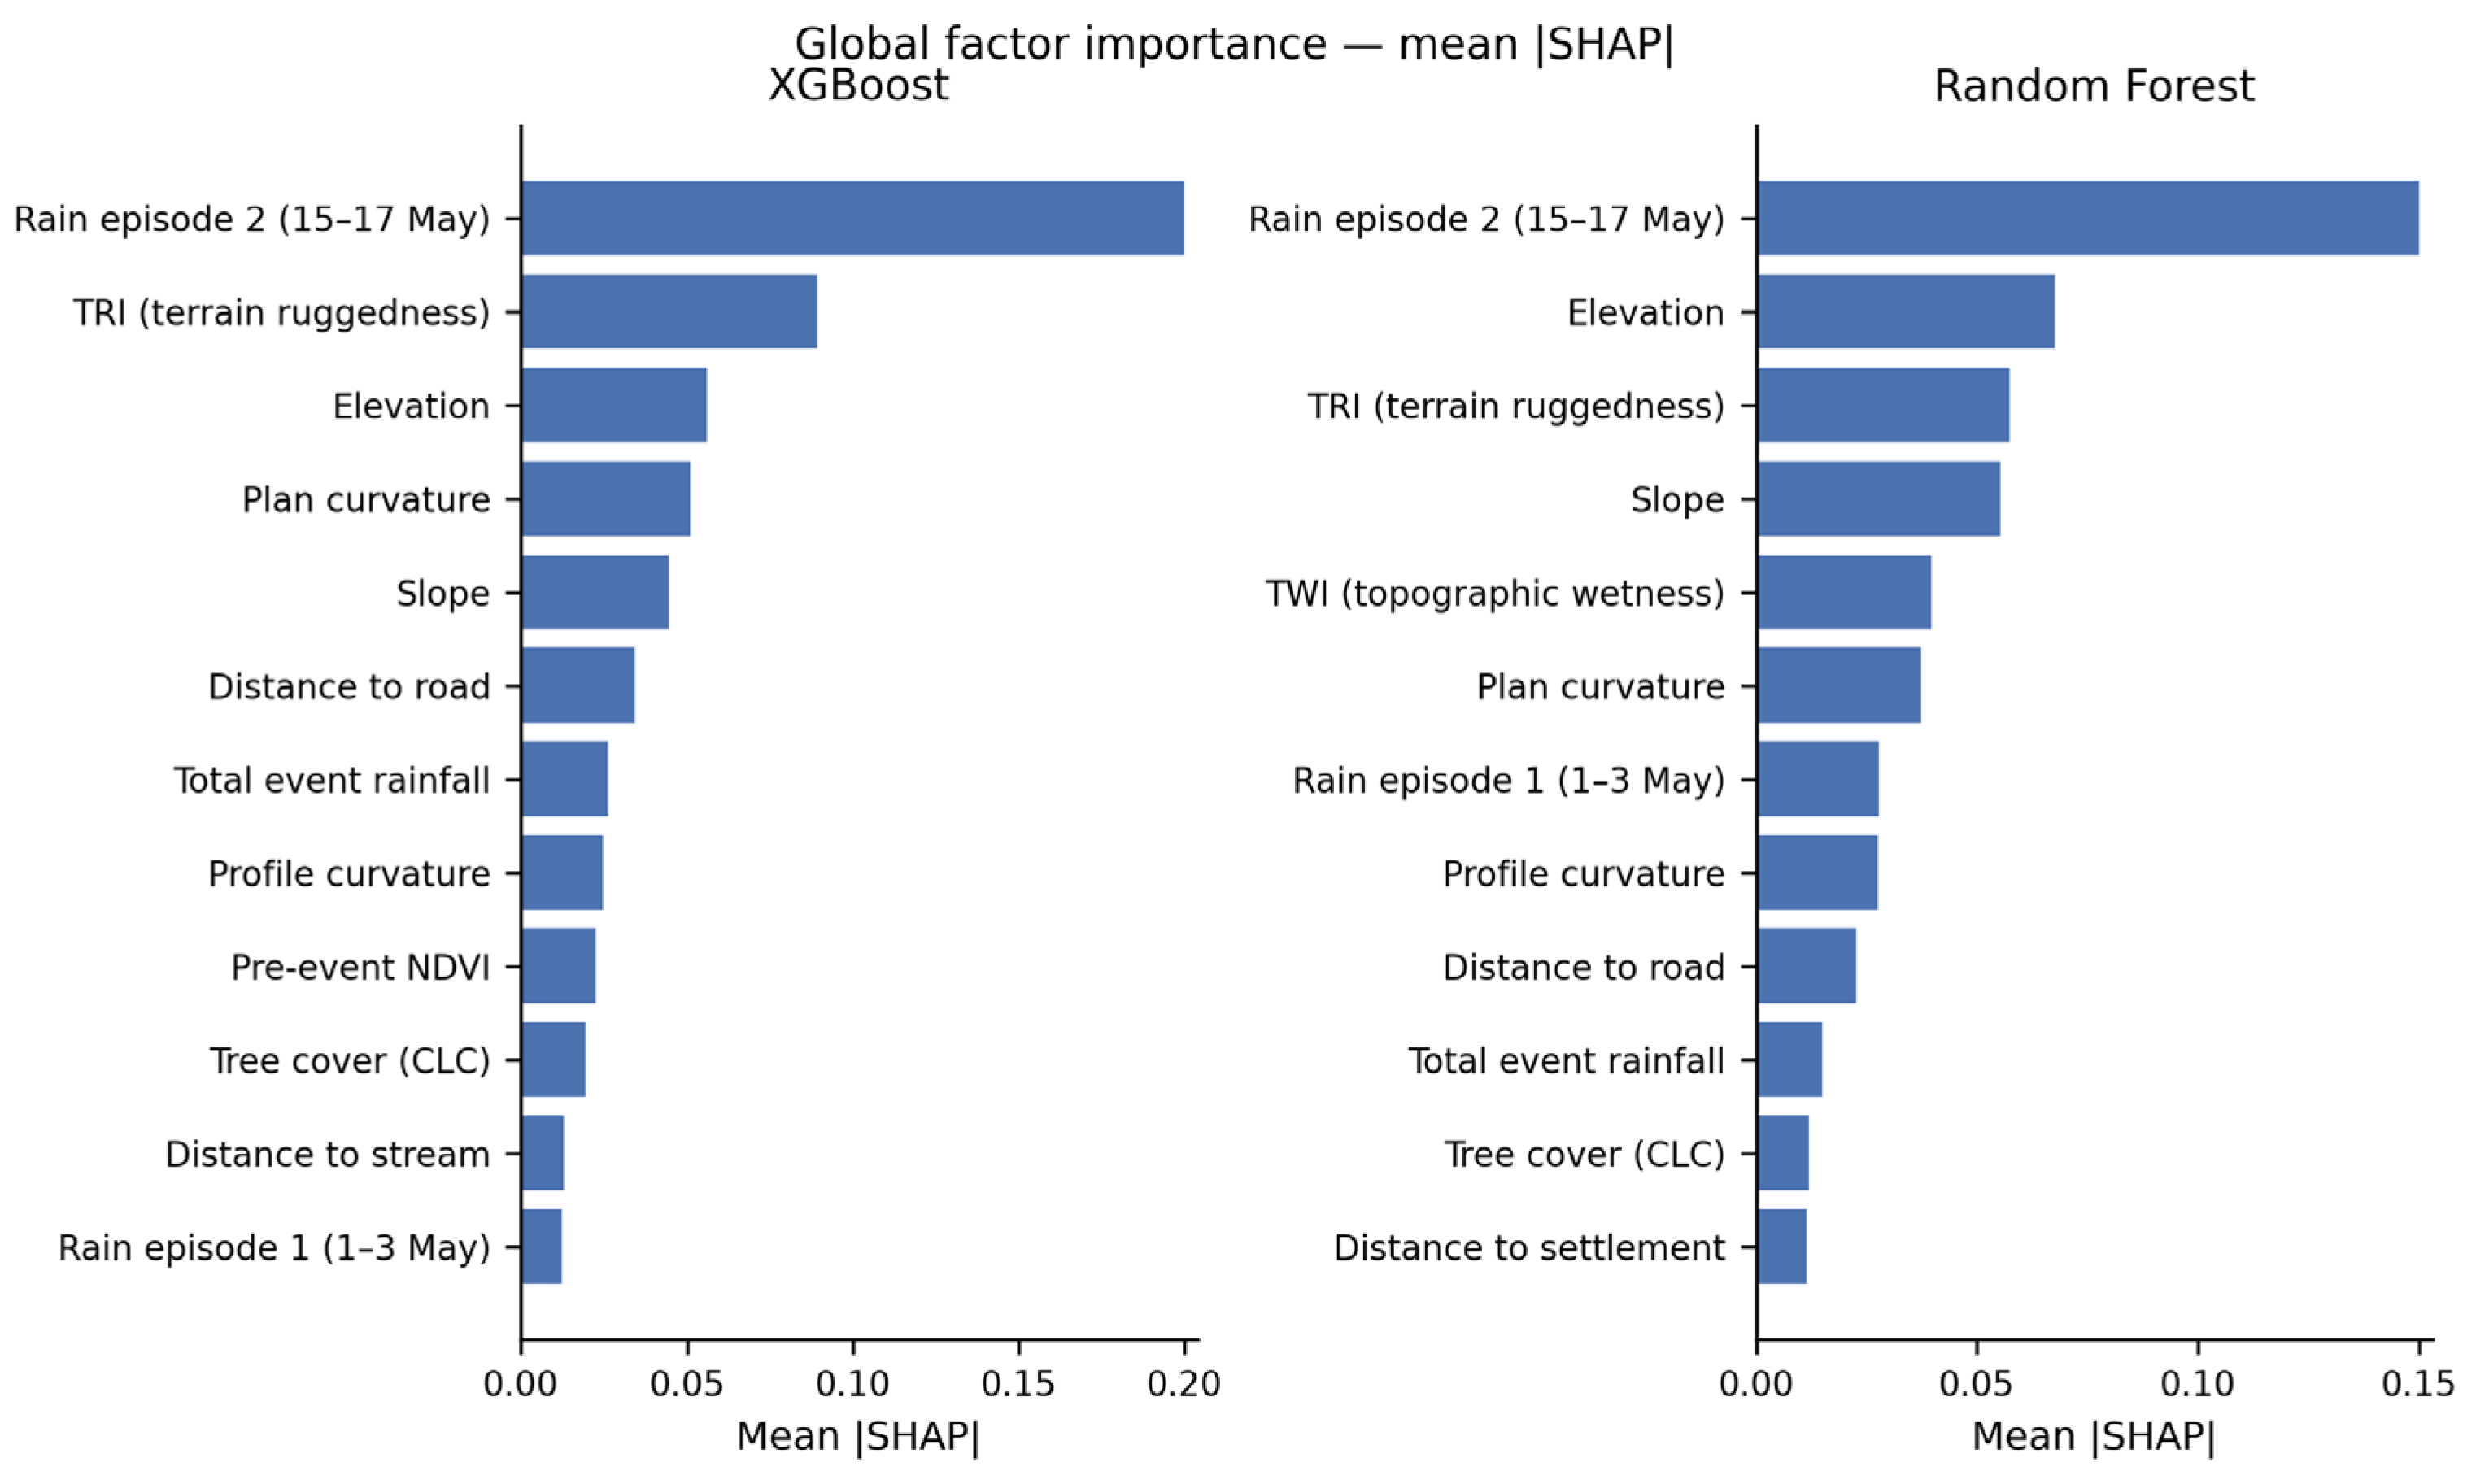
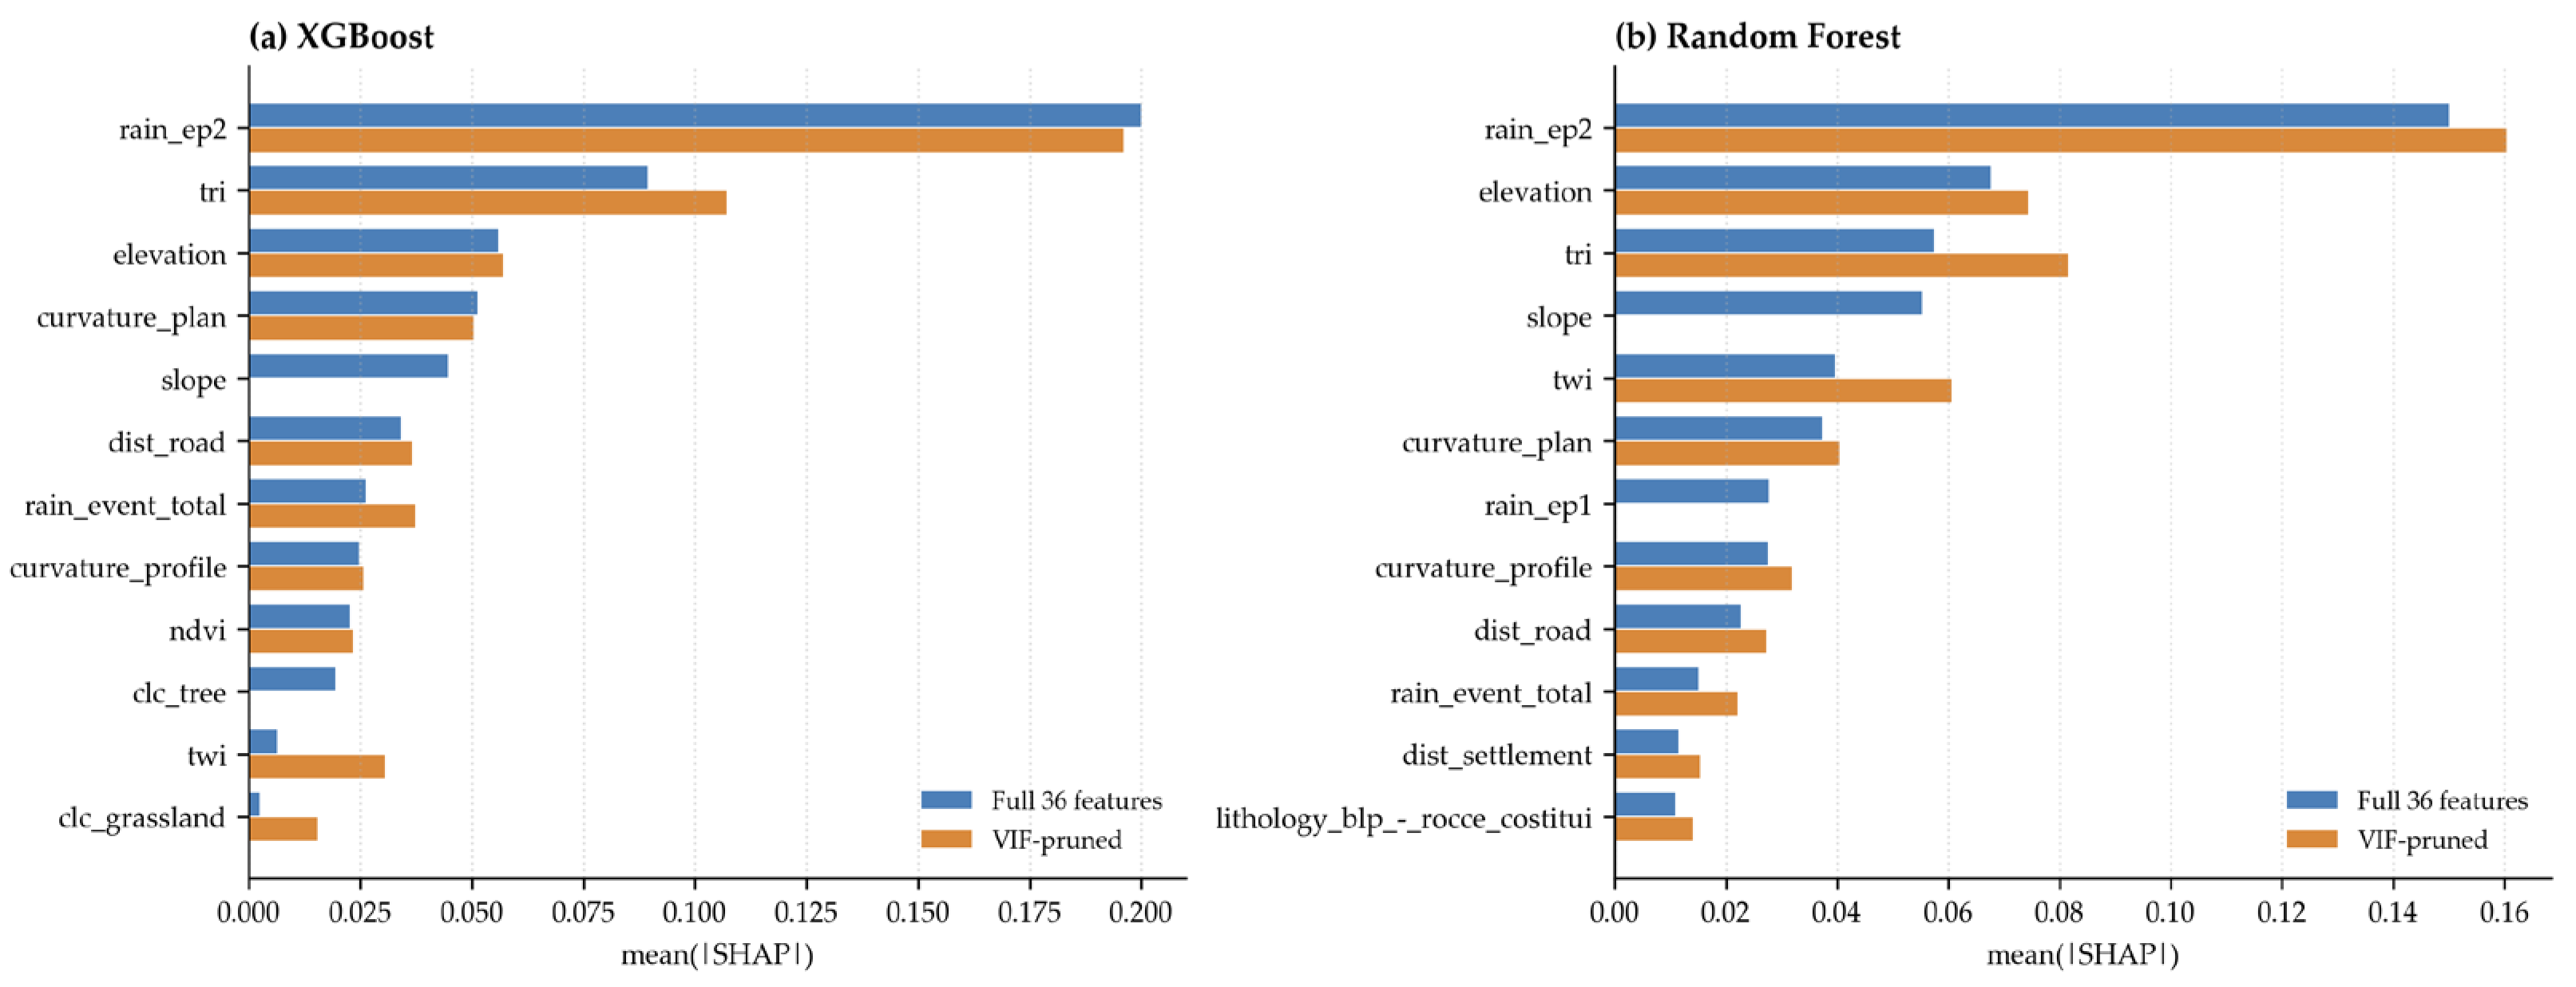
SHAP rankings are highly consistent between the two ensemble models (Figure 7). For both XGBoost and RF, the dominant predictor is the second-episode event rainfall (rain_ep2, 15–17 May) (mean |SHAP| 0.20 and 0.15), followed by terrain ruggedness (TRI), elevation, slope, and plan curvature. The dominance of the triggering rainfall over static factors is the expected signature of a rainfall-induced event. Aggregated by lithotype, the cohesive clay-shale (argille scagliose) group is the leading geological contributor, consistent with Northern Apennine earth-flow behavior. The SHAP-based factor ordering is empirically robust to multicollinearity: a VIF-pruned re-run (Appendix A, Figure A1) removes five high-VIF features (slope, rain_ep1, and three sparse one-hot land covers) and yields a Spearman rank correlation ρ = 0.967 (XGBoost)/ρ = 0.998 (RF) on the surviving features, with the top-8 overlap 7/8 and 6/8, respectively. Even in the most collinear case—slope and TRI carry high variance-inflation factors (110 and 56, respectively)—removing the redundant partner (slope, final VIF = 110) leaves the surviving terrain attribution essentially unchanged because TRI preserves the ruggedness signal. The substantive interpretation—rainfall-driven event signal followed by terrain ruggedness—is therefore not an artifact of collinear-feature redistribution; it reflects a physical-process attribution.

4.7. Robustness and Adversarial Checks

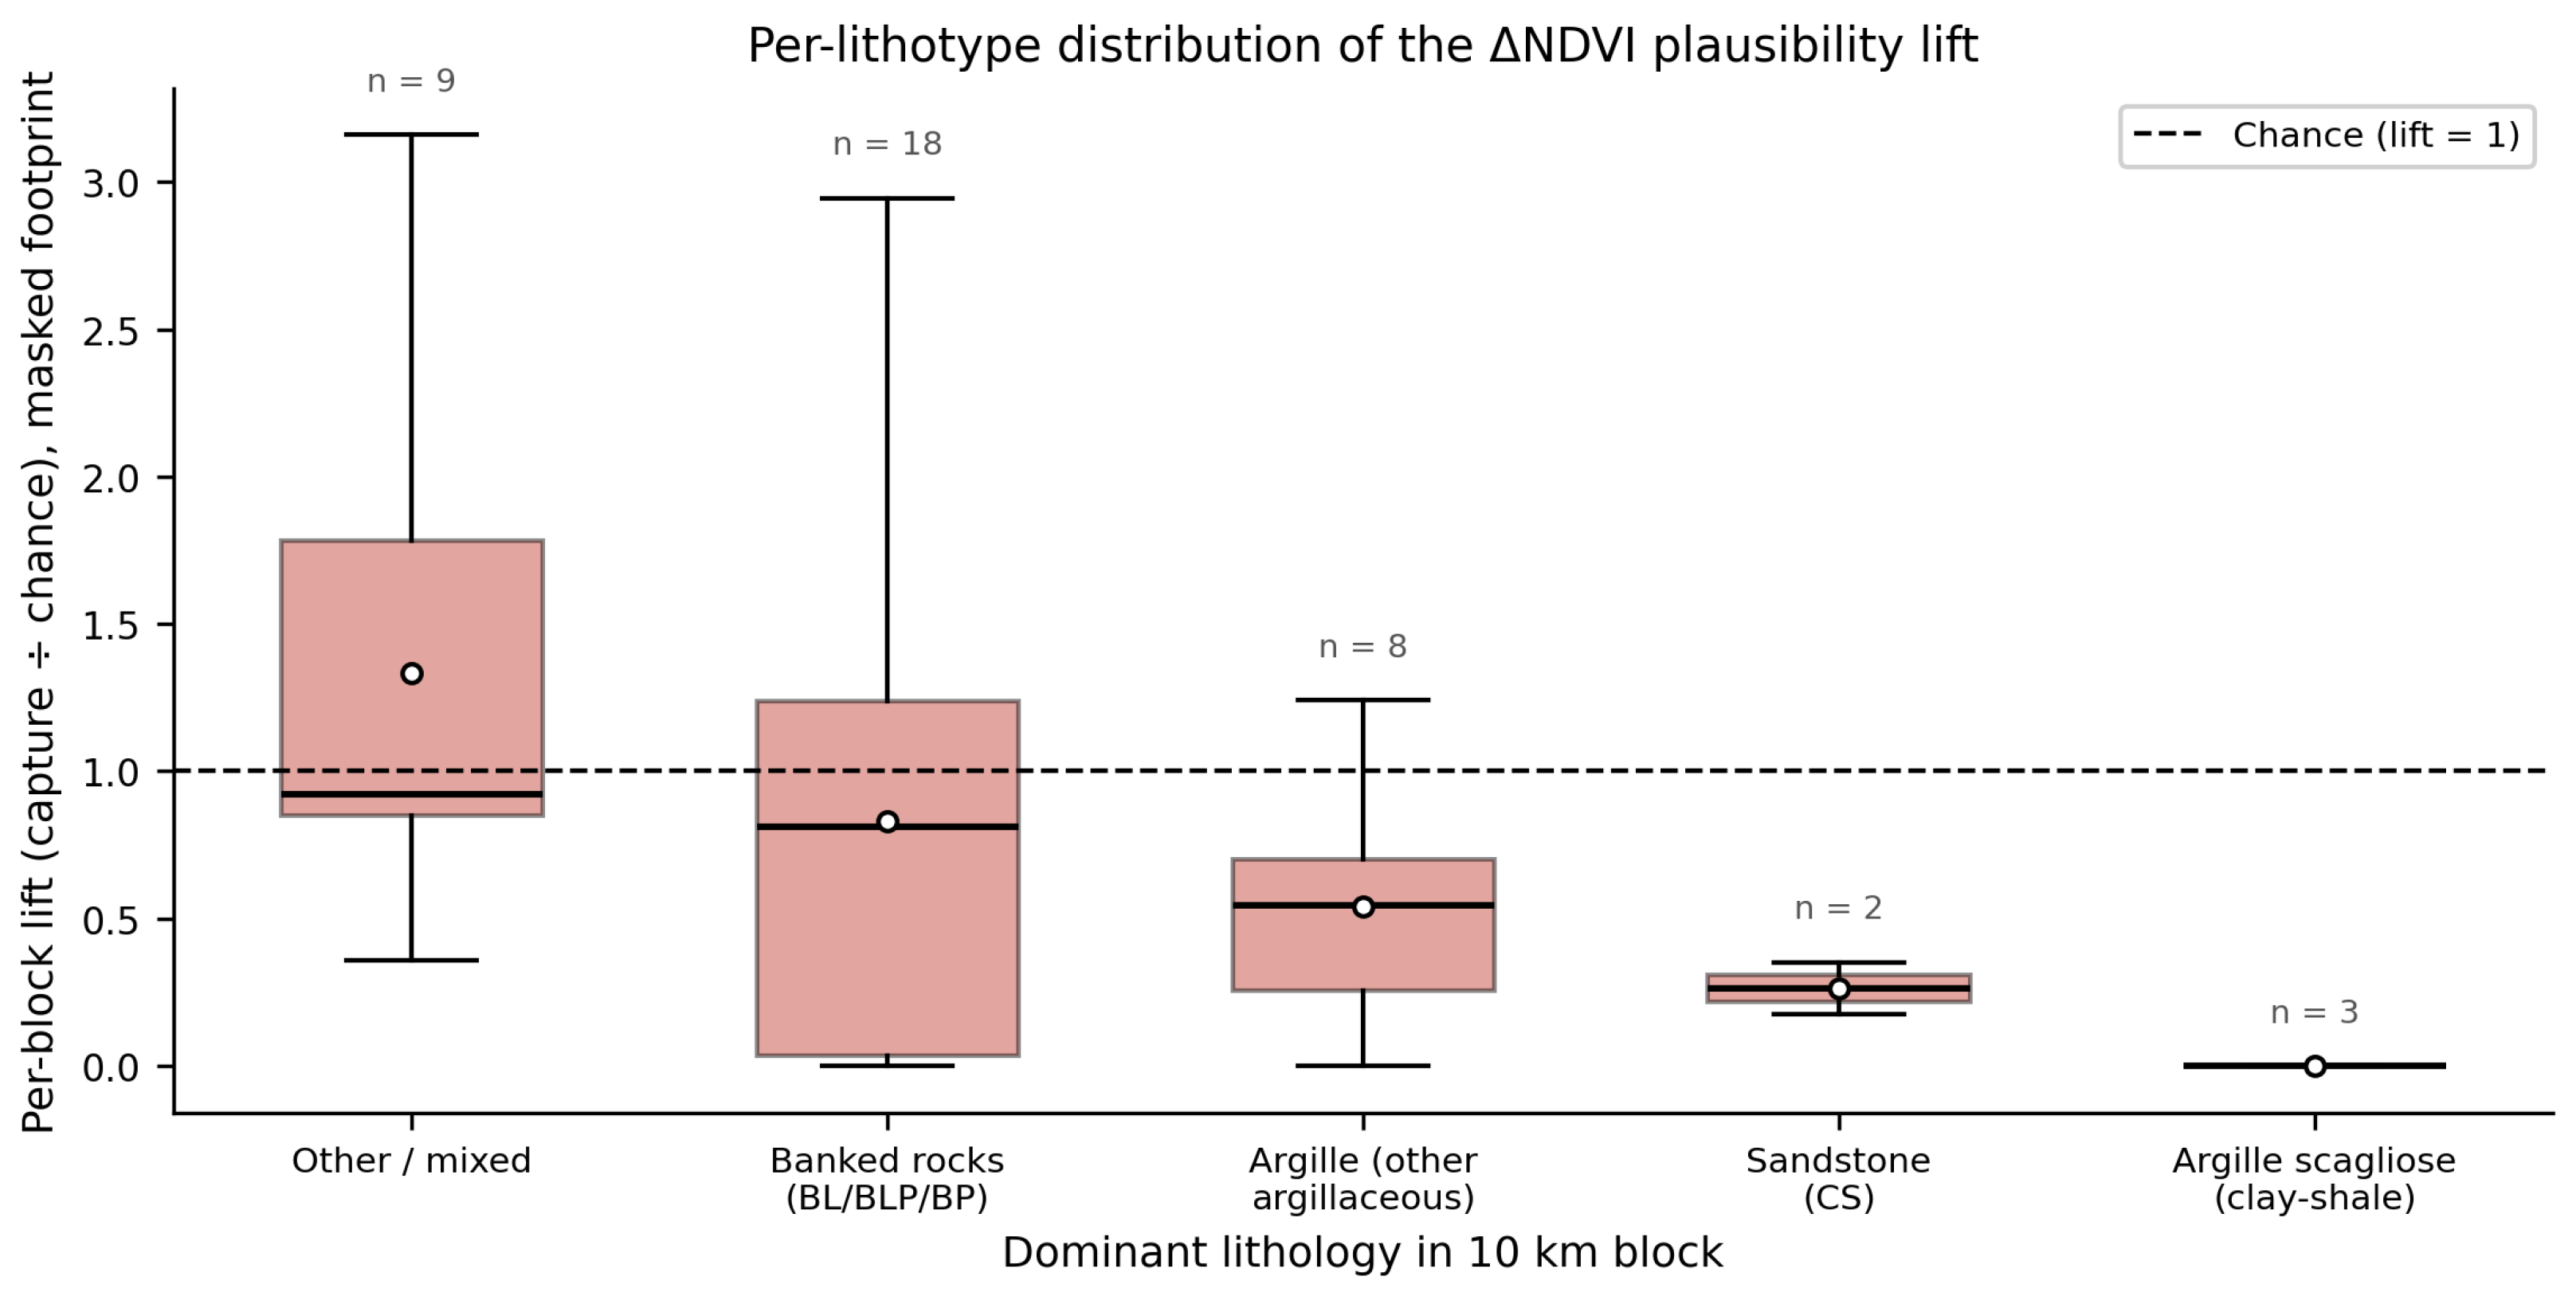
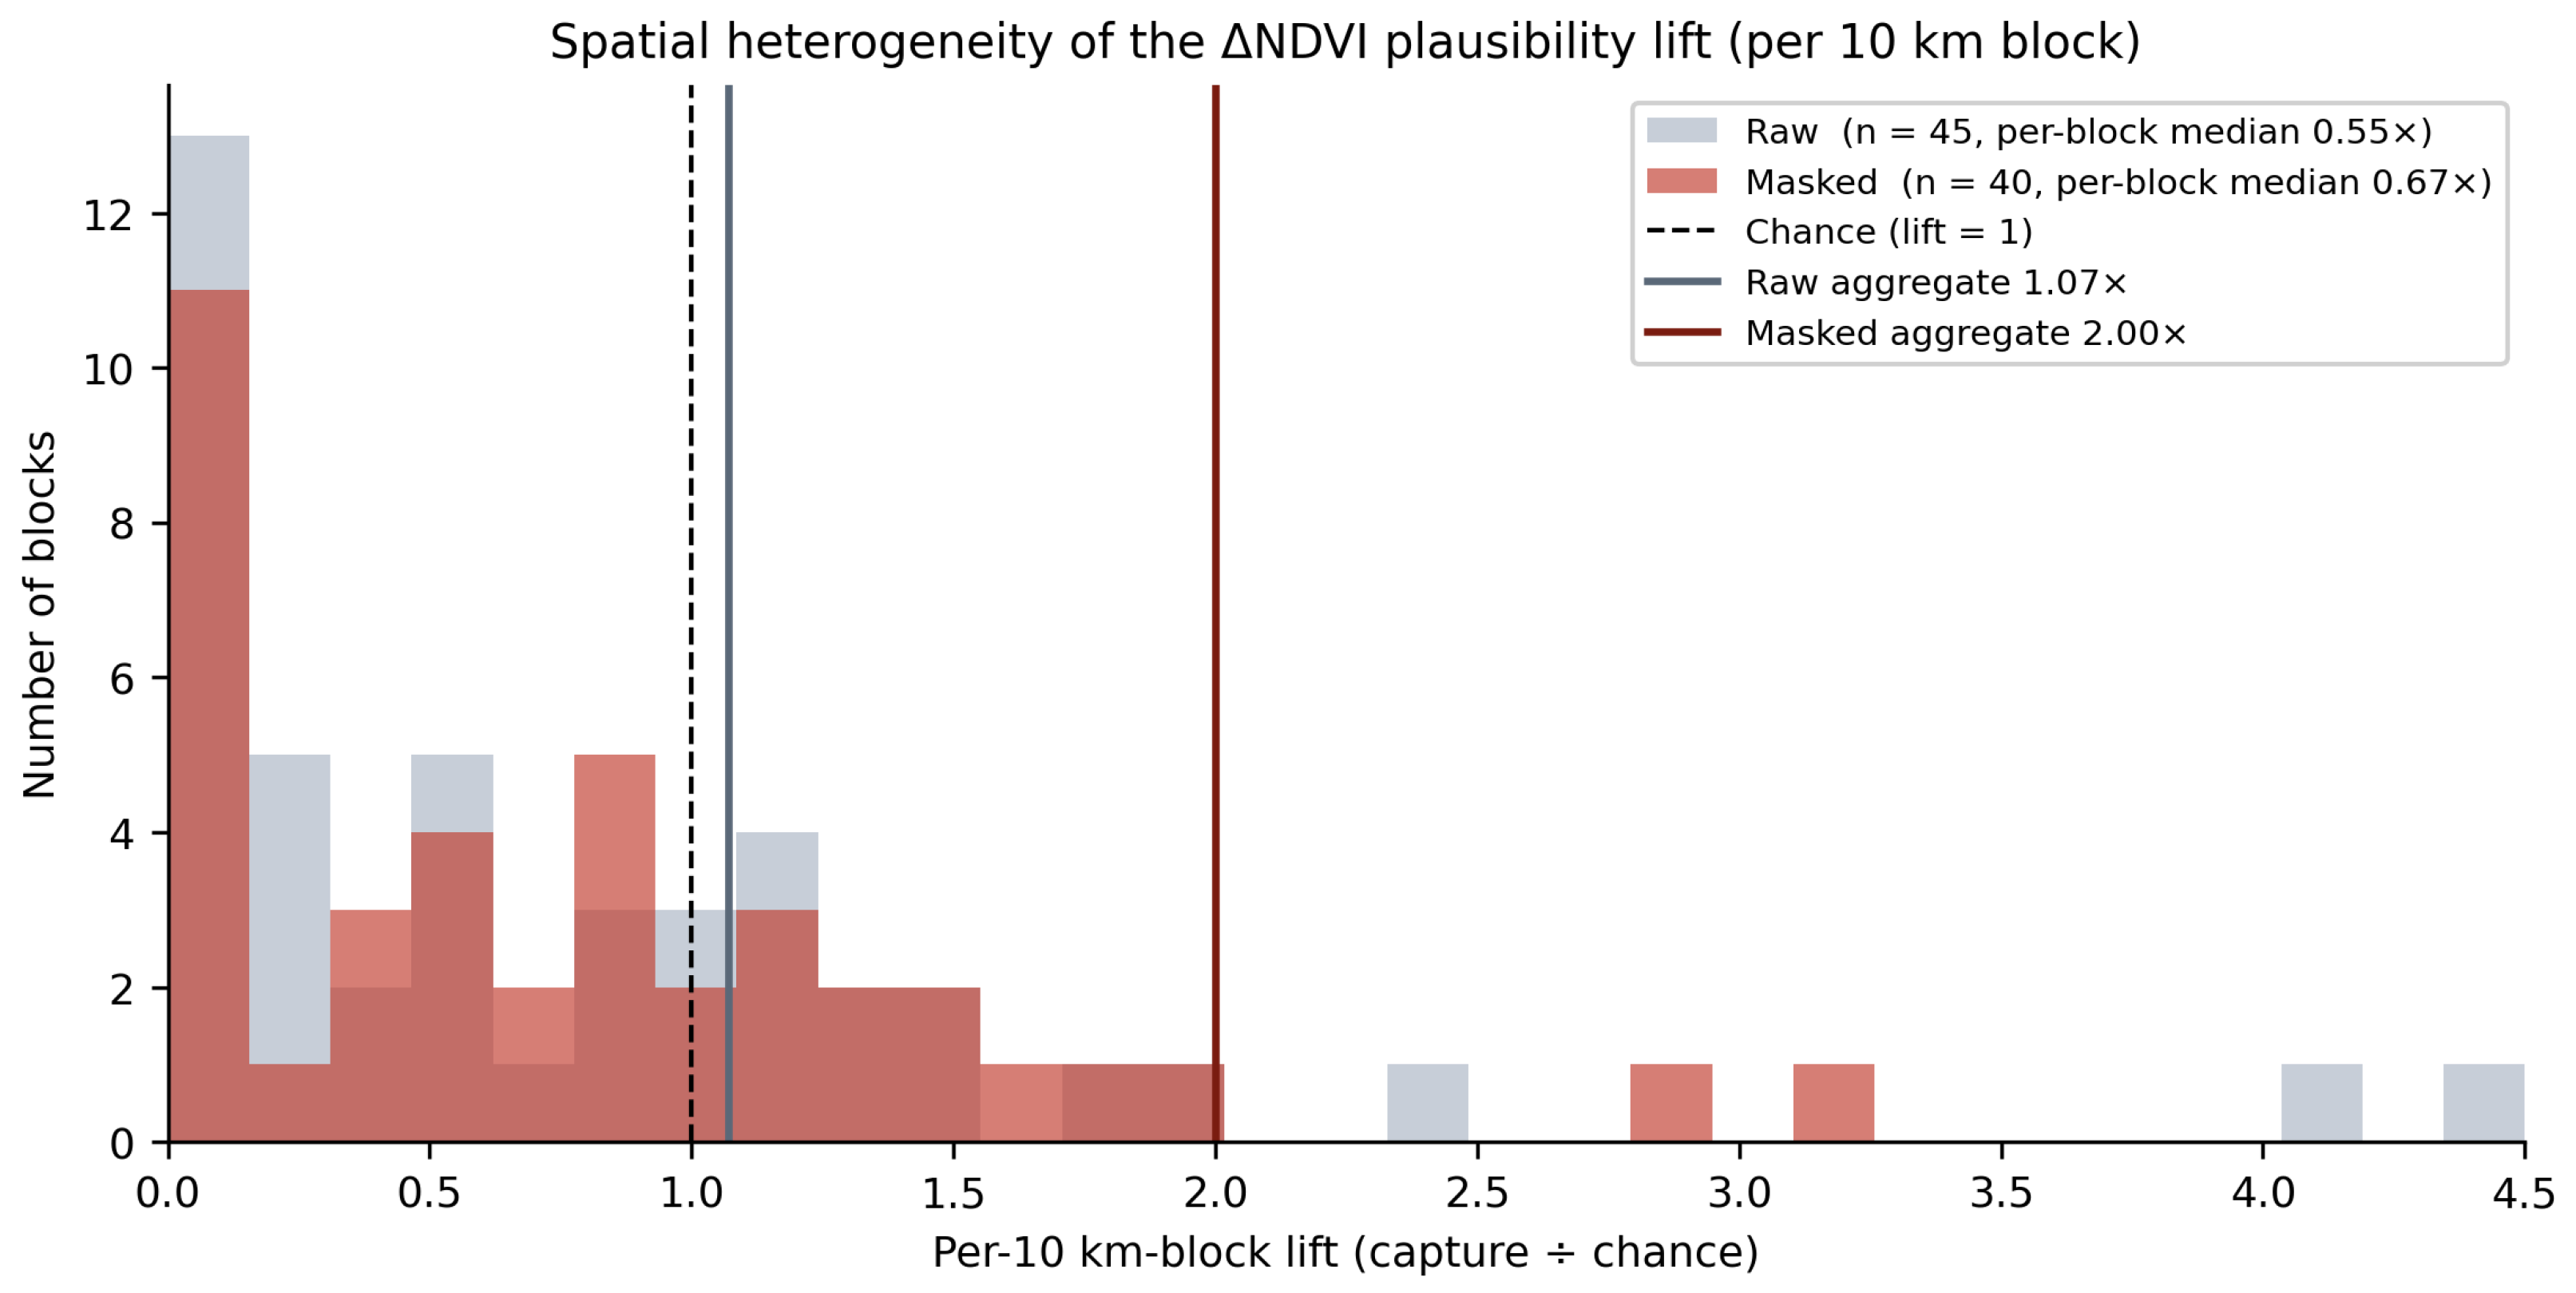
The masked result was tested against the principal alternative explanations; numerical detail is in Table 9, with the headline numbers summarized here. (i) Footprint vs. inventory: the phenology-matched ΔNDVI footprint is genuinely enriched in mapped landslide pixels (5.5× raw, 11.4× masked) and records real landslide signals rather than pure co-event noise; its overall recall (≈17%) is size and type-dependent and biased to vegetation-stripping earth-flow/clay-shale failures, with rocky or small failures barely registered (per-type numbers in Table 9; discussion in Section 5). Sentinel-1 shows negligible enrichment (≈1.1×) at 12-day repeat and serves only as a cloud-independent coverage check. (ii) Slope control: the footprint is slope-neutral, and the model lift within slope deciles is 2.18× (vs. 1.23× for a same-prevalence slope-only classifier and 1.25× for a multi-terrain composite), so the result reflects geomorphic skill beyond slope/terrain autocorrelation. (iii) Uncertainty (10 km spatial-block bootstrap, 400 resamples): raw ΔNDVI lift 1.07 with 95% CI 0.6–1.7 (includes 1—no skill); masked lift 2.00 point estimate, 1.94 bootstrap median, 95% CI 1.25–2.72 (excluding 1). Per-block lift is genuinely heterogeneous (Figure 8; argille-scagliose and other argillaceous blocks have suppressed median lift—a pattern that, as Section 5.2 shows, is not a model-saturation effect (their High + Very-High base rate is itself low) but reflects 10 km aggregation over the within-block factors the model uses—per-lithotype panel in Figure 9). The aggregate is therefore an upper tail across heterogeneous lithotypes, not a transferable per-region magnitude. The pixel-pooled (2.00) vs. bootstrap-median (1.94) discrepancy is the expected ≈4% asymmetry of a long-upper-tail block bootstrap; Figure 10 shows the bootstrap distribution of the 400 resampled lifts and visualizes the asymmetry directly. (iv) Susceptibility-domain-restricted re-model: when the negative pool itself is restricted to the same landslide-relevant domain (slope ≥ 10°, excluding water/wetland/cropland/built-up; the susceptibility-restricted negative strategy), spatial-CV XGBoost AUC moves by only Δ = −0.0005 (0.945 → 0.9445; ranking and significance preserved, Friedman p = 0.0036) and the masked-footprint lift is preserved (2.45× vs. 2.00×). A complementary terrain-only re-model (slope/aspect/curvature/elevation/TRI/TWI only) drops XGBoost AUC by Δ = −0.041 to 0.9039, showing that rainfall, lithology, land-cover, and NDVI add genuine discriminative skill beyond terrain. The masked-footprint lift therefore cannot be reduced either to slope/terrain autocorrelation in the features or to the choice of the negative pool. (v) Bootstrap block-size sensitivity. We repeated the spatial-block bootstrap of the masked lift at three block sizes (5/10/20 km; 167/333/666 pixels at 30 m). For each scale, we report the actual number of unique blocks in the masked domain followed by the bootstrap 95% CI (400 resamples per scale): the median is essentially invariant (2.00×/1.94×/1.90×, respectively; canonical bootstrap, seed 42, fresh RNG per block size); the CI is [1.54, 2.47] at 5 km (481 blocks), [1.25, 2.72] at 10 km (136 blocks), and [0.53, 3.00] at 20 km (39 blocks). The CI excludes 1 at both 5 and 10 km—the conclusion is therefore robust to the block-size choice in the typical 5–20 km range. The wider 20 km CI reflects only ≈39 unique blocks at that scale, not a change in central tendency. (vi) Footprint-type bias vs. model-type capture. We tabulate per-type counts at the polygon level (the same one-point-per-polygon unit used in modeling): a polygon is detected if at least one of its in-domain pixels is flagged disturbed. The polygon-level ΔNDVI footprint is significantly type-biased (Pearson χ2 = 408, df = 7, p ≈ 0, on the 2 × 8 contingency table of detected vs. non-detected polygons across the eight landslide types): Earth Flow is enriched in the footprint (8.7% of detected polygons vs. 5.3% of inventory), and per-type recall ranges from 5.5% (Rock Slide complex, RS2) to 28.1% (Earth Flow, EF). Crucially, the model’s High + Very-High capture rate is uniform across types (94–98% for every landslide-type category), so the 2× masked lift is not an artifact of an EF-favoring model meeting an EF-enriched footprint: the model treats all landslide types similarly at the class-rank level, and the lift reflects spatial discrimination on the optically detectable subset rather than a circular co-favoring of one type by both the model and the footprint.

4.8. Spatial Heterogeneity of the Plausibility Lift

The aggregate masked lift of ≈2× is not the typical per-place skill of the map. The 10 km spatial-block bootstrap reveals a strongly heterogeneous spatial distribution: the per-block lift has 10th/50th/90th percentiles of 0.00/0.67/1.58 (Figure 8). In a majority of 10 km blocks, the model performs at or below chance against the independent footprint; the aggregate ≈2× is driven by an upper-tail minority of blocks. This is a first-order operational finding, not a limitation: a user who intends to apply the susceptibility map to a particular 10–20 km sub-region cannot expect the headline lift to materialize in that sub-region by default. The map should therefore be read as a regional plausibility statement, not as a transferable per-place guarantee; spatially explicit confidence reporting (e.g., per-block lift with bootstrap CI overlaid on the susceptibility surface) is a recommended companion product to event-based LSM maps of this scale.

5. Discussion

The central message is methodological: whether an event-based LSM map looks geomorphically plausible against independent satellite evidence is decided by how the validation footprint is constructed. A raw co-event footprint, contaminated by the concurrent flooding and agriculture, makes a model with AUC ≈ 0.945 indistinguishable from a random mask; a process-targeted, landslide-relevant footprint shows the same model capturing observed disturbance at about twice the chance (Section 4.2). Both readings carry the same warning: high inventory-split skill is not equivalent to geomorphic plausibility—even on the favorable footprint, the realized skill (lift ≈ 2×) is far below what AUC ≈ 0.945 implies. That a statistically strong model can be spatially over-rated is consistent with the geomorphic-plausibility literature [10,11]; our contribution is to operationalize the check with two independent sensors and to show that footprint construction is itself decisive and currently neglected. The well-known design effects—random-vs.-spatial CV optimism and negative-sampling sensitivity—are reported as applied good practice and as a further reason absolute skill must not be over-read; they are not claimed as novel [6,7,8,9]. SHAP shows the signal is governed by the triggering event, rainfall, and terrain, with the clay-shale lithotype as the leading geological control—coherent with rainfall-induced earth-flow behavior.

5.1. Comparison with Prior Work

Comparison with the prior literature on this event. To our knowledge, no prior LSM study on the May 2023 Emilia-Romagna event—nor on a comparably large event in a Mediterranean mountain setting—has reported an independent multi-sensor (S2 + S1) plausibility test with a decomposed footprint (raw vs. landslide-relevant) and a spatial-block bootstrap CI for the lift. Rapid-mapping work on the same event [14,15] focuses on producing the disturbance footprint itself rather than on benchmarking a susceptibility model against it; the susceptibility-side literature [7,8,10,11] has either validated against inventory splits or against a single optical ΔNDVI layer but has not operationalized the two-sensor decomposed-footprint check we apply here.
The two performance measures used here are complementary, not interchangeable, and should not be conflated. The AUC is a threshold-free measure of how well the model ranks held-out points of the same inventory (inventory-split discrimination); the capture lift measures how strongly an external, independently observed disturbance footprint concentrates in the top predicted classes relative to a random-mask expectation. They are computed on different data and answer different questions—statistical separability versus geomorphic plausibility—so the gap between a high AUC (≈0.945) and a modest lift (≈2×) is precisely the skill–plausibility gap this study quantifies.
Why the gap is a conservative lower bound. The skill–plausibility gap reported here is presented as a conservative lower bound for three reasons. (a) Better model specification would be expected to move the realized plausibility up (toward the process), not down—so a future model that closes the gap can do so only by becoming more plausible, not less. (b) The masked-footprint result holds for the strongest of four structurally different algorithms; a single-model artifact is therefore implausible. (c) The masked-footprint chance baseline is recomputed on the susceptible-only domain (Section 4.7 (iv)), so the lift is not boosted by an “easy negatives” baseline. None of these arguments excludes the existence of a future model and/or footprint construction for which the gap closes substantially; the claim is that the gap reported here under defensible methodology cannot be argued away by tightening any one of the standard knobs (sampling, CV, calibration, and collinearity).

5.2. Limitations

ΔNDVI threshold calibration circularity. The −0.15 operating threshold is calibrated on the same inventory (RER2023) that is then used to construct the validation footprint—the distribution of inside-polygon ΔNDVI fixes the threshold, and the resulting footprint is compared against the model predictions. This is methodologically a form of self-consistency rather than full independence: a hold-out subset of the inventory used exclusively for threshold calibration would be a stricter design. We do not implement such a hold-out in the present analysis because the inventory is already partitioned for spatial CV (folds of pixels), and a further inventory-level hold-out would either weaken the within-event training signal or impose a temporal split, which we have already declared as out of scope. The sensitivity table (Table 4) provides partial mitigation: the four thresholds in the operationally plausible range [−0.10, −0.25] all yield bootstrap 95% CIs that exclude 1 on the masked footprint, with point lifts between 1.71× and 2.24×. The qualitative conclusion—masked lift exceeds chance robustly—does not depend on the specific operating threshold. A stricter independent calibration on a regionally adjacent prior-event inventory is the natural follow-up. Null-threshold sanity check: a circular self-fulfilling design would also produce high lift in non-discriminating threshold regimes. We swept the threshold across {−0.30, …, +0.10}, including the positive-Δ (vegetation-gain) regime. Masked lift in the disturbance regime (−0.30 to −0.10) is monotonically 1.71–2.24×; in the vegetation-gain regime (+0.05, +0.10) it drops to 1.11–1.37×; at the boundary (any negative) it falls to 0.69×. The test does not fire in the null regime. The positive-Δ lift is above 1, not exactly 1; this residual reflects baseline spatial autocorrelation between High + Very-High predicted classes and mountain-area phenology. The headline disturbance lift (2.00× at −0.15) is therefore ≈1.46× above this null-regime baseline (2.00/1.37) rather than 2.00 above the random expectation.
Two senses of independence. The footprint is independent of the model—the satellite-derived disturbance never enters training or feature selection (enforced by a runtime leakage guard), so the model–footprint comparison is leakage-safe. It is not independent of the inventory: the disturbance threshold is anchored on the inside-polygon ΔNDVI distribution, and the enrichment, χ2, and recall evidence that the footprint tracks real landslides is itself measured against the RER2023 polygons. The footprint should therefore be read as an inventory-anchored but model-independent validation reference—it tests whether the model reproduces the optically detectable disturbance of the mapped failures, not whether that disturbance exists independently of the inventory. A fully inventory-independent reference would require a disturbance threshold calibrated and labeled without RER2023 (a regionally adjacent prior-event inventory, or an unsupervised change-detection threshold), which we identify as the natural next step.
Macro-geographic-segregation hypothesis (test). We further tested whether the AUC ≈ 0.945 could be explained primarily by macro-geographic segregation (mountain vs. plain) rather than by genuine geomorphic skill, given the 30 m grid and one-point-per-polygon design. We re-ran the spatial-CV XGBoost ablation with progressively reduced feature sets: elevation alone yields AUC = 0.761 (±0.043); elevation + dist_road yields 0.809 (±0.038); elevation + three distance features yields 0.831 (±0.033); the existing terrain-only re-model (slope, aspect, curvature, elevation, TRI, TWI; Section 4.7 (iv)) yields 0.9039; the full 36-feature model yields 0.945. The macro-geographic features alone reach only AUC 0.76–0.83; the within-terrain micromorphology (slope, curvature, TRI, TWI) adds an extra ≈0.07 to reach 0.9039; rainfall, lithology, land-cover, and NDVI together add a further ≈0.041 to reach 0.945. The model’s skill is therefore primarily driven by micromorphology and conditioning factors, not by macro-geographic segregation; this macro-geographic-segregation explanation is not supported at the Δ AUC ≈ 0.18 level (full vs. elevation-only).
Operational implication of the lithology-lift pattern. Section 4.7 (vi) and Figure 9 show that argille-scagliose-dominated 10 km blocks have low per-block lift; the direct empirical decomposition we report there (r(clay-shale fraction, predicted H + VH base rate) = −0.33, n = 38) finds that, contrary to a simple “model saturation” narrative, these blocks also have a low H + VH base rate, so the compressed lift is not a simple consequence of the model flagging every clay-shale pixel as High. The operational implication is nevertheless concrete: a regional aggregate lift can be lower than the local pixel-level skill of the model in geologically stratified terrain—because aggregating to a 10 km block averages over within-block factors (rainfall, slope) that the model uses to discriminate, while the lithology one-hot is constant across the block. Practitioners who apply satellite-derived footprints to an LSM map at coarse aggregation without geological stratification will therefore systematically understate model skill in clay-shale basins (Northern Apennines) and probably overstate it elsewhere. A direct decomposition of the 10 km blocks supports this reading: the below-chance majority is concentrated in blocks with a higher clay-shale fraction (mean 0.13 versus 0.03 in the above-chance minority) and a low predicted High + Very-High base rate (mean 0.16 versus 0.39)—terrain where the cohesive argille-scagliose units fail diffusely rather than in spatially concentrated patches. Footprint density and forest cover, by contrast, do not separate low- from high-lift blocks, and cultivated and built-up land is excluded from the masked domain by construction, so the collapse is a lithological and model-confidence effect rather than residual agricultural or infrastructural noise. The above-chance upper tail corresponds to moderately steeper flysch blocks where the model concentrates High + Very-High predictions and the observed disturbance coincides with them.
Modeling grid scale. The 5 m LiDAR-derived DTM is block-aggregated to 30 m to match the other predictors. Because the median RER2023 landslide polygon (479 m2) is smaller than a 30 m pixel, each polygon is represented by a single point in this design. This one-point-per-polygon design eliminates pseudo-replication at the cost of also masking the sub-pixel geomorphic niches (very local curvature/TRI variation, micro-channel geometry) that a tree-based model such as XGBoost could in principle exploit if it were trained on the full native 5 m DTM. Slope-unit or object-based segmentation exploiting the full 5 m DTM is the natural next step for closing this scale gap. Beyond the grid-scale mismatch, the inventory itself carries delineation and positional uncertainty that propagates into statistical susceptibility models [9]; the single-point-per-polygon sampling and the 200 m negative buffer absorb, rather than remove, this sub-polygon positional error.
Independent footprint coverage and recall bias. The phenology-matched optical view is coverage-limited (clear post-event view over ≈76% of the domain, ≈43% for the same-year April pre-event composite). Sentinel-1 12-day coherence carries a high vegetation-decorrelation baseline, and ΔNBR is cloud-shadow-sensitive, so both stay near chance even on the masked footprint—the optical ΔNDVI is the informative proxy. The optical footprint recovers only ≈17% of mapped RER2023 landslides overall, with recall both size- and type-dependent (full breakdown in Section 4.7 (i) and Table 9); small or rocky failures leave little ΔNDVI signature, so the test is a consistency check on the optically detectable subset, not an exhaustive detector.
Mixed-mechanism binary labeling. The susceptibility model treats all RER2023 failures as a single positive class, yet the inventory spans kinematically and physically distinct mechanisms—from low-angle earth flows and earth/debris slides to high-angle rock-slope failures—that respond to different combinations of lithology, slope, and hydrology and leave different surface signatures. A single binary classifier therefore blends predisposition signals that a mechanism-stratified model would separate, and this blending propagates into the independent validation: because the optical footprint detects disturbance through vegetation removal, it preferentially registers the vegetation-stripping earth-flow/clay-shale failures (per-type recall 28.1% for Earth Flow versus 5.5% for the Rock-Slide complex; Section 4.7 (vi)) and barely registers rocky or deep-seated failures. The ≈2× masked lift is therefore a plausibility statement for the optically detectable, predominantly flow-type subset of the event, not for its full kinematic spectrum; a mechanism-stratified model validated against mechanism-specific footprints (for example, SAR or DEM-differencing for rocky failures) is the route to resolving this limitation.
Rigid topographic masking. The landslide-relevant footprint applies a fixed slope cutoff (≥10°, with ≥5° reported for comparison), which by construction removes the low-angle distal shear-deposition and debris-flow runout zones that debouch onto flatter ground. We quantified this blind spot against the inventory: only 4.0% of mapped RER2023 landslide pixels (3.6% of polygons in part, 0.8% entirely) fall below 10°, and 0.5% below 5°—the mapped failures are overwhelmingly steep-source features (median pixel slope 26.8°). The cutoff therefore excludes only a small distal fraction of the mapped landslide area, and because it removes real landslide pixels, it can only lower the measured capture, biasing the lift downward (conservatively); the consistency of the ≥5° and ≥10° variants (Section 4.2) confirms the result is not an artifact of the specific cutoff. Event settings dominated by long-runout flows on valley floors would instead require a runout-aware mask rather than a single slope threshold.
Heterogeneity of the masked lift. The masked aggregate (95% CI 1.25–2.72×; canonical bootstrap) is genuinely spatially heterogeneous: most 10 km blocks score near chance, and the aggregate is driven by an upper tail (Figure 8; per-lithotype panel Figure 9). The lift should be read as a methodological demonstration that footprint construction controls the verdict, not as a transferable per-region plausibility magnitude.
AUC on the high side; not a negative-pool artifact. XGBoost AUC ≈ 0.945 is on the high side of the LSM literature because ≈25% of the convex hull domain is easy, non-susceptible terrain. The masked-footprint analysis already recomputes the chance baseline on the susceptible-only domain (11.9% → 16.5%), so the reported lift is not measured against an inflated baseline. Re-training the four models with the negative pool itself restricted to the same susceptible domain (strategy terr_susc) moves the spatial-CV XGBoost AUC by only −0.0005 and preserves the masked-footprint lift (2.45× vs. 2.00×; Section 4.7); the gap is therefore not an artifact of the negative pool.
Multicollinearity/SHAP attribution. The iterative VIF prune designed in the pipeline has been applied empirically as a SHAP-attribution robustness check (Appendix A, Figure A1). Five features with VIF > 10 are removed (clc_bare, clc_tree, clc_wetland, rain_ep1, slope); held-out random-fold AUC moves by +0.0001 (XGBoost) and ≈0 (RF); SHAP top-8 overlap is 7/8 (XGBoost) and 6/8 (RF); Spearman rank correlation of mean(|SHAP|) is ρ = 0.967 (XGBoost)/ρ = 0.998 (RF). The substantive SHAP interpretation is therefore not an artifact of multicollinearity. A full VIF-pruned re-run on all four models with corresponding susceptibility mapping remains an interesting follow-up.
Sentinel-1 sensor context. The result is conditioned on a single-satellite, 12-day repeat configuration: in May 2023, Sentinel-1A was the only operational SAR platform (Sentinel-1B failed in December 2021; Sentinel-1C was not yet launched or integrated into the HyP3 archive), so the smallest accessible interferometric pair was a 12-day S1A–S1A pair. Over forested Apennines at peak spring phenology, 12-day vegetated-target decorrelation is the a priori expectation rather than an artifact of these particular acquisitions. A 6-day pair (S1A + S1B or S1A + S1C, when available), differential/ascending+descending fused coherence, or arid/sparsely vegetated terrain could push S1 from a coverage check toward a true validator; these configurations are not tested here.
Operational coregistration of the ascending track. The ascending track-117 InSAR pair failed HyP3 GAMMA coregistration because the AOI sits near the swath edge for that track, leaving insufficient common reference/event frame overlap to support sub-pixel coregistration (Section 4.2). The HyP3 on-demand workflow exposes only the canonical GAMMA pipeline; custom DEM substitution, manual coregistration windows, or unconventional baseline/Doppler tolerances are not available through the cloud service, and processing the same acquisitions in a local GAMMA installation would step outside the open-pipeline scope we adopt here. We accept the swath-edge failure of track-117 as the standard SAR pre-condition rather than as a recoverable parameter problem.
Event-level temporal scope. The model is trained on the RER2023 inventory of the same event whose footprint serves as the independent validation. The leakage safeguard removes any direct contamination at the pixel/feature level—the satellite-derived disturbance never enters training and is enforced by a runtime guard on the feature matrix—but the inventory and the footprint share, by construction, the same event-level conditioning. A stricter temporal independence test would train on a prior event in the same region and validate on May 2023; this is out of scope here (the RER2023 inventory is the first systematic, polygon-resolved event-conditioned LSM benchmark for this basin) but is the natural next step for the protocol. The headline result of this study is therefore best read as a within-event plausibility test on a single regional event; cross-event temporal transferability of the protocol—and of the magnitude of the lift—has not been tested and is not claimed.
Alternative SAR configurations not tested. The 12-day S1A-only configuration used here is the cloud-independent baseline that was operationally accessible in May 2023. Higher-cadence or longer-wavelength alternatives that could plausibly turn S1 into a landslide discriminator in this setting—and which we explicitly do not test—include: (i) sub-daily commercial X-band SAR (ICEYE, Capella Space), whose short revisit times reduce vegetation decorrelation for direct interferometry; (ii) ALOS-2/future NISAR-class L-band SAR, where the longer wavelength penetrates vegetation canopies and tolerates the 12–14-day decorrelation budgets that C-band cannot support over forested Apennines at peak phenology; and (iii) Sentinel-1 6-day pairs (S1A + S1B or S1A + S1C, once the constellation is fully operational again). Recommending one particular configuration would be premature without acquisition-cost and access-rights comparisons that are outside the scope of this study; we flag the three families above as the natural candidates for the next iteration of the protocol.


5.3. Transferability and Outlook

Transferability. The protocol—and not the magnitude of the lift, which is event- and region-specific—is what we claim is transferable. The conditions that make a phenology-matched Sentinel-2 ΔNDVI footprint informative are: (i) at least one clear post-event Sentinel-2 acquisition within a few days of the event, (ii) a same-season pre-event composite (within-year preferred; a prior-year DOY-matched anchor acceptable when spring is cloudy), and (iii) terrain with vegetation that the failure type can strip—earth-flow/clay-shale settings score best; rocky or sparsely vegetated settings do not. The Sentinel-1 layer in the present configuration is a cloud-independent coverage check rather than a landslide discriminator. The sensor-availability context matters: in May 2023, Sentinel-1A was the only operational SAR platform (Sentinel-1B was non-operational following the December 2021 power-supply failure, and Sentinel-1C had not yet been launched or integrated into the HyP3 archive), so the smallest accessible interferometric pair was a 12-day S1A–S1A pair. Over the forested Northern Apennines at peak spring phenology (mid-May), 12-day vegetated-target decorrelation is the a priori expectation and not an artifact of these particular acquisitions: it sets the upper bound on what S1 coherence can resolve in this setting. It could become an effective validator under shorter baseline configurations (e.g., 6-day with S1A + S1B or S1A + S1C once operational), in arid or sparsely vegetated terrain, or with differential/ascending + descending fused coherence—configurations we have not tested here. The flysch/clay-shale Apennine setting is representative of many European mountain belts; outside this lithological context, the protocol still applies, but recall of optical disturbance will depend on the local landslide-type distribution (Section 4.7).

6. Conclusions

We introduce and apply an independent remote-sensing plausibility test for event-based ML landslide susceptibility on the May 2023 Emilia-Romagna event with an open, reproducible pipeline (released at acceptance). (1) Apparent geomorphic plausibility is footprint-dependent: against a raw co-event footprint, a model with AUC ≈ 0.945 is indistinguishable from random, whereas against a process-targeted footprint it captures observed disturbance at an aggregate ≈2× the random-mask expectation (bootstrap median 1.94×, 95% CI 1.25–2.72; ≈1.46× above the vegetation-phenology null). (2) This skill is genuine (beyond slope/terrain) but limited to the optically detectable subset and spatially heterogeneous—the per-10 km-block median lift is 0.67× (below chance)—so the map is a regional, not a per-place, statement. (3) Realized skill is far below the inventory-split AUC, so AUC alone must not be read as physical plausibility: the phenology-matched optical ΔNDVI is the informative proxy, whereas the 12-day Sentinel-1A C-band layer does not discriminate landslides here and serves only as a cloud-independent coverage check (a cautionary result that does not generalize to shorter-baseline or L-band acquisitions). (4) We recommend that independent, physically based validation be reported with explicit, process-targeted footprint construction—a single contaminated comparison can invert the verdict—alongside spatial CV and terrain-plausible negatives as standard practice (the latter reproduced here as applied good practice, not as a novelty claim; [6,7,8,11]), and release the full open pipeline for reuse upon acceptance. Scope caveat: the results are a within-event consistency test on a single regional event; cross-event temporal transferability of either the plausibility magnitude or the protocol has not been tested and is not claimed—a same-region prior-event independent training set is the natural next step.

Author Contributions

Conceptualization, L.N.; methodology, L.N.; validation, L.N. and L.P.; resources, L.N.; writing—original draft preparation, L.N.; writing—review and editing, L.P. and A.F.J.; visualization, L.N.; supervision, A.F.J. and D.R. All authors have read and agreed to the published version of the manuscript.

Funding

This work was supported by a grant of the Ministry of Research, Innovation and Digitization, CCCDI–UEFISCDI, project number PN-IV-P6-6.3-SOL-2024-0124, within PNCDI IV.

Data Availability Statement

All input datasets are openly available from their providers (Emilia-Romagna regional geoportal DTM and 1:10,000 geology; Copernicus ERA5-Land; Copernicus Sentinel-2 via Element84; Sentinel-1 via the Alaska Satellite Facility HyP3; the RER2023 inventory [18]). The processing and analysis pipeline that reproduces all results, figures, and tables in this manuscript (including the empirical ΔNDVI calibration, the polygon-level type-bias test, the bootstrap block-size sensitivity, the VIF-pruned SHAP-stability appendix, and the susceptibility-map inset construction) is held in a private working repository during peer review and will be released as a public archive on Zenodo (with a DOI assigned at publication) and on the corresponding GitHub Free repository upon acceptance of the manuscript. The pipeline is implemented in Python 3.11 (key libraries: scikit-learn 1.8.0, XGBoost 3.2.0, SHAP 0.49.1, rasterio 1.4.4, GeoPandas 1.1.3, NumPy 1.26.4, SciPy 1.17.1, Matplotlib 3.10.8) and will be released under version tag v1.0.0. Reviewers and editors can obtain a pre-publication read-only access link by contacting the corresponding author.

Conflicts of Interest

The authors declare no conflicts of interest.

Abbreviations

The following abbreviations are used in this manuscript:
AOIArea of Interest
AUCArea Under the Curve
C-bandC-band synthetic aperture radar (~5.6 cm wavelength)
CIConfidence Interval
CVCross-Validation
DTMDigital Terrain Model
ERA5-LandECMWF Reanalysis v5—Land
HPOHyperparameter Optimization
InSARInterferometric Synthetic Aperture Radar
LSMLandslide Susceptibility Mapping
NBRNormalized Burn Ratio
NDVINormalized Difference Vegetation Index
RERRegione Emilia-Romagna
ROCReceiver Operating Characteristic
SARSynthetic Aperture Radar
SHAPSHapley Additive exPlanations
TRITerrain Ruggedness Index
TWITopographic Wetness Index
VIFVariance Inflation Factor
ΔNBRChange in Normalized Burn Ratio
ΔNDVIChange in Normalized Difference Vegetation Index

Appendix A. VIF-Pruned SHAP-Attribution Robustness Check

The iterative variance-inflation-factor (VIF) prune (threshold 10) is reported here as a SHAP-attribution robustness check, in addition to the main runs (Section 3). Tree-based models are robust to multicollinearity for prediction, but Shapley values can redistribute importance arbitrarily across collinear coalitions, so the natural concern is whether the substantive interpretation in Section 4 survives an explicit orthogonalization of the feature set. Logistic Regression is affected directly, although it is not the ranking-leading model. We restrict the empirical robustness check to the tree-based models (XGBoost, RF) because (a) the two ensembles are the SHAP leaders of the manuscript and (b) LR is consistently the lowest of the four-model AUC ladder (Table 7), and any improvement to its coefficients from VIF pruning does not shift the algorithm ranking. As a robustness check on (b), we re-fit LR on the same pruned 31-feature set and compute the Spearman rank correlation of |β| between the full and pruned LR on the surviving features: ρ = 0.70 (n = 31, p < 10−4). The substantive top of the LR coefficient ranking is preserved (curvature_plan, dist_road, elevation, rain_ep2, TRI) with within-cluster reshuffling (slope → twi in the terrain group; clc_bare → curvature_profile in the secondary tier), as expected when collinear partners are removed. The lower ρ relative to the ensemble models is consistent with LR being structurally more sensitive to multicollinearity, but the qualitative interpretation is invariant. A complete four-model VIF re-run with full SHAP recomputation is a follow-up audit.
Procedure. On the primary balanced sample (terrain-plausible negatives, ratio 1:1, max 25,000 per class, seed 42—the same sample that produces the headline results), we iteratively remove the feature with the largest VIF until max VIF ≤ 10. We then refit XGBoost and Random Forest on the pruned feature set with the same nested randomized-HPO protocol, both (a) on a single held-out random fold (for an AUC delta) and (b) on the full primary sample (for an updated SHAP attribution).
Result. Five features are pruned at threshold 10: clc_wetland and clc_bare (sparse/saturated one-hot land-cover categories with effectively zero variance after fusion), clc_tree (final VIF = 133), slope (final VIF = 110—collinear with the other terrain derivatives, particularly TRI), and rain_ep1 (final VIF = 64—collinear with rain_event_total). The surviving 31 features include all of the leading SHAP contributors of the original Section 4 run. Held-out random-fold AUC moves by Δ = +0.0001 for XGBoost (0.9540 → 0.9541) and Δ = 0.0 for Random Forest (0.9520 → 0.9520)—both within the single-fold noise.
The SHAP attribution itself is highly stable (Figure A1). The top-8 features overlap is 7/8 for XGBoost and 6/8 for Random Forest, with the substantive ordering (rain_ep2-dominated signal followed by TRI, elevation, curvature, distance to road, event-total rainfall) unchanged. The Spearman rank correlation of mean(|SHAP|) over surviving features is ρ = 0.967 for XGBoost and ρ = 0.998 for Random Forest, both with p ≈ 0. The average per-feature shift in mean(|SHAP|) is 0.0027 (XGBoost) and 0.0034 (RF), small relative to the leading-feature magnitudes (rain_ep2 ≈ 0.20). The within-cluster reshufflings that do occur are geomorphologically interpretable: removing slope (collinear with TRI) slightly promotes twi in the XGBoost top 8; removing rain_ep1 (collinear with rain_event_total) slightly promotes rain_event_total and dist_road in the RF top 8—expected redistribution within highly correlated sub-clusters rather than a change in the substantive interpretation.
Interpretation. The SHAP-based factor importance of Section 4 is therefore not an artifact of multicollinearity in this dataset: the substantive interpretation (event rainfall dominates over the static factors; TRI/elevation/curvature carry the terrain signal; the clay-shale lithotype is the leading geological control) is unchanged under explicit orthogonalization. We retain the full 36-feature model in the main text because it is the configuration used for the susceptibility map and full-grid mapping (Section 4.2); the VIF-pruned models are not separately mapped here. The VIF-pruning analysis and its output tables are included in the released pipeline.
Figure A1. SHAP feature-importance stability under VIF pruning. For each of (a) XGBoost and (b) Random Forest, the mean(|SHAP|) for the top 10 features is shown side by side for the full 36-feature run (blue; the configuration used in the main results) and the VIF-pruned 31-feature re-run (orange). The substantive interpretation (rain_ep2-dominated signal followed by terrain ruggedness, elevation, plan curvature, and the other terrain factors) is preserved; the small reshufflings (slope → twi for XGBoost; promotion of rain_event_total/dist_road for RF) are the expected within-cluster redistribution between highly correlated terrain or rainfall derivatives.
Remotesensing 18 02318 g0a1

References

  1. Ado, M.; Amitab, K.; Maji, A.K.; Jasińska, E.; Gono, R.; Leonowicz, Z.; Jasiński, M. Landslide Susceptibility Mapping Using Machine Learning: A Literature Survey. Remote Sens. 2022, 14, 3029. [Google Scholar] [CrossRef] [Scilit]
  2. Akosah, S.; Gratchev, I.; Kim, D.-H.; Ohn, S.-Y. Application of Artificial Intelligence and Remote Sensing for Landslide Detection and Prediction: Systematic Review. Remote Sens. 2024, 16, 2947. [Google Scholar] [CrossRef] [Scilit]
  3. Cheng, G.; Wang, Z.; Huang, C.; Yang, Y.; Hu, J.; Yan, X.; Tan, Y.; Liao, L.; Zhou, X.; Li, Y.; et al. Advances in Deep Learning Recognition of Landslides Based on Remote Sensing Images. Remote Sens. 2024, 16, 1787. [Google Scholar] [CrossRef] [Scilit]
  4. Hussain, M.A.; Chen, Z.; Zheng, Y.; Zhou, Y.; Daud, H. Deep Learning and Machine Learning Models for Landslide Susceptibility Mapping with Remote Sensing Data. Remote Sens. 2023, 15, 4703. [Google Scholar] [CrossRef] [Scilit]
  5. Zhang, Q.; Wang, T. Deep Learning for Exploring Landslides with Remote Sensing and Geo-Environmental Data: Frameworks, Progress, Challenges, and Opportunities. Remote Sens. 2024, 16, 1344. [Google Scholar] [CrossRef] [Scilit]
  6. Brenning, A. Spatial prediction models for landslide hazards: Review, comparison and evaluation. Nat. Hazards Earth Syst. Sci. 2005, 5, 853–862. [Google Scholar] [CrossRef] [Scilit]
  7. Kumar, C.; Walton, G.; Santi, P.; Luza, C. Random Cross-Validation Produces Biased Assessment of Machine Learning Performance in Regional Landslide Susceptibility Prediction. Remote Sens. 2025, 17, 213. [Google Scholar] [CrossRef] [Scilit]
  8. Schratz, P.; Muenchow, J.; Iturritxa, E.; Richter, J.; Brenning, A. Hyperparameter tuning and performance assessment of statistical and machine-learning algorithms using spatial data. Ecol. Model. 2019, 406, 109–120. [Google Scholar] [CrossRef] [Scilit]
  9. Steger, S.; Brenning, A.; Bell, R.; Glade, T. The propagation of inventory-based positional errors into statistical landslide susceptibility models. Nat. Hazards Earth Syst. Sci. 2016, 16, 2729–2745. [Google Scholar] [CrossRef] [Scilit]
  10. Steger, S.; Brenning, A.; Bell, R.; Petschko, H.; Glade, T. Exploring discrepancies between quantitative validation results and the geomorphic plausibility of statistical landslide susceptibility maps. Geomorphology 2016, 262, 8–23. [Google Scholar] [CrossRef] [Scilit]
  11. Steger, S.; Mair, V.; Kofler, C.; Pittore, M.; Zebisch, M.; Schneiderbauer, S. Correlation does not imply geomorphic causation in data-driven landslide susceptibility modelling. Sci. Total Environ. 2021, 776, 145935. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  12. Pohjankukka, J.; Pahikkala, T.; Nevalainen, P.; Heikkonen, J. Estimating the prediction performance of spatial models via spatial k-fold cross validation. Int. J. Geogr. Inf. Sci. 2017, 31, 2001–2019. [Google Scholar] [CrossRef] [Scilit]
  13. Roberts, D.R.; Bahn, V.; Ciuti, S.; Boyce, M.S.; Elith, J.; Guillera-Arroita, G.; Hauenstein, S.; Lahoz-Monfort, J.J.; Schröder, B.; Thuiller, W.; et al. Cross-validation strategies for data with temporal, spatial, hierarchical, or phylogenetic structure. Ecography 2017, 40, 913–929. [Google Scholar] [CrossRef] [Scilit]
  14. Dal Seno, N.; Ciccarese, G.; Evangelista, D.; Loli Piccolomini, E.; Corsini, A.; Berti, M. Rapid Landslide Mapping During the 2023 Emilia-Romagna Disaster: Assessing Automated Approaches with Limited Training Data. EGUsphere 2025. [Google Scholar] [CrossRef] [Scilit]
  15. Ferrario, M.F.; Livio, F. Rapid Mapping of Landslides Induced by Heavy Rainfall in the Emilia-Romagna (Italy) Region in May 2023. Remote Sens. 2024, 16, 122. [Google Scholar] [CrossRef] [Scilit]
  16. Vaka, D.S.; Yaragunda, V.R.; Perdikou, S.; Papanicolaou, A. InSAR Integrated Machine Learning Approach for Landslide Susceptibility Mapping in California. Remote Sens. 2024, 16, 3574. [Google Scholar] [CrossRef] [Scilit]
  17. Wu, X.; Qi, X.; Peng, B.; Wang, J. Optimized Landslide Susceptibility Mapping and Modelling Using the SBAS-InSAR Coupling Model. Remote Sens. 2024, 16, 2873. [Google Scholar] [CrossRef] [Scilit]
  18. Berti, M.; Pizziolo, M.; Scaroni, M.; Generali, M.; Critelli, V.; Mulas, M.; Tondo, M.; Lelli, F.; Fabbiani, C.; Ronchetti, F.; et al. RER2023: The landslide inventory dataset of the May 2023 Emilia-Romagna meteorological event. Earth Syst. Sci. Data 2025, 17, 1055. [Google Scholar] [CrossRef] [Scilit]
  19. Regione Emilia-Romagna. Geoportale: Regional 5 m LiDAR DTM and 1:10,000 Geological Map [Dataset]. Available online: https://geoportale.regione.emilia-romagna.it (accessed on 18 May 2026).
  20. Tarquini, S.; Isola, I.; Favalli, M.; Mazzarini, F.; Bisson, M.; Pareschi, M.T.; Boschi, E. TINITALY/01: A new Triangular Irregular Network of Italy. Ann. Geophys. 2007, 50, 407–425. [Google Scholar] [CrossRef] [Scilit]
  21. Muñoz-Sabater, J.; Dutra, E.; Agustí-Panareda, A.; Albergel, C.; Arduini, G.; Balsamo, G.; Boussetta, S.; Choulga, M.; Harrigan, S.; Hersbach, H.; et al. ERA5-Land: A state-of-the-art global reanalysis dataset for land applications. Earth Syst. Sci. Data 2021, 13, 4349–4383. [Google Scholar] [CrossRef] [Scilit]
  22. Chen, T.; Guestrin, C. XGBoost: A Scalable Tree Boosting System. In Proceedings of the 22nd ACM SIGKDD International Conference on Knowledge Discovery and Data Mining, San Francisco, CA, USA, 13–17 August 2016; pp. 785–794. [Google Scholar] [CrossRef] [Scilit]
  23. Demšar, J. Statistical Comparisons of Classifiers over Multiple Data Sets. J. Mach. Learn. Res. 2006, 7, 1–30. [Google Scholar]
  24. Lundberg, S.M.; Lee, S.-I. A Unified Approach to Interpreting Model Predictions. In Advances in Neural Information Processing Systems 30; Curran Associates: Red Hook, NY, USA, 2017; pp. 4765–4774. [Google Scholar]
  25. Telford, R.J.; Birks, H.J.B. Evaluation of transfer functions in spatially structured environmental data. Quat. Sci. Rev. 2009, 28, 1309–1316. [Google Scholar] [CrossRef] [Scilit]
  26. Valavi, R.; Elith, J.; Lahoz-Monfort, J.J.; Guillera-Arroita, G. blockCV: An R package for generating spatially or environmentally separated folds for k-fold cross-validation of species distribution models. Methods Ecol. Evol. 2019, 10, 225–232. [Google Scholar] [CrossRef] [Scilit]
Figure 1. Study area—Northern Apennines, Emilia-Romagna (Italy). Background: hillshade derived from the regional 5 m LiDAR DTM [19], aggregated to 30 m. Blue polygons: the 80,997 expert-mapped landslides of the May 2023 event [18]. Red outline: the modeling AOI (convex hull of the inventory buffered by 5 km, ≈11,059 km2). Projection: EPSG:32632 (UTM 32 N).
Remotesensing 18 02318 g001
Figure 2. End-to-end pipeline workflow. Open data sources (top) feed the 30 m fused matrix (center-left), four-classifier modeling (center-right; paired CV, nested HPO), and the leakage-safe S2 + S1 disturbance-footprint layer (right). The XGBoost susceptibility map is confronted with the independent footprint via a 10 km spatial-block bootstrap (Section 4.7).
Remotesensing 18 02318 g002
Figure 3. Nemenyi critical-difference diagram (spatial CV, 5 folds, α = 0.05). Lower average rank is better; models not joined by a horizontal line are significantly different. With only n_folds = 5, the test has modest statistical power, so the diagram is reported as a consistency check on the algorithm ranking, not as the primary claim of the manuscript (Section 3.4).
Remotesensing 18 02318 g003
Figure 4. Predicted landslide susceptibility surface over the AOI: full-grid XGBoost predicted probabilities, classified into five Jenks natural-breaks classes (Very Low → Very High; legend right). A 30 m grid, projection EPSG:32632 (UTM 32 N). Light gray = pixels outside the modeled domain or with one or more predictors missing.
Remotesensing 18 02318 g004
Figure 5. Capture lift of independently observed co-event disturbance by the predicted High + Very-High classes on the raw footprint vs. the landslide-relevant (masked, slope ≥ 10°) footprint, each against its own recomputed random-mask expectation (dashed, lift = 1). Whiskers on the ΔNDVI-2022 bars are the 95% spatial-block-bootstrap CI: the raw CI includes 1, the masked CI excludes it. The optical ΔNDVI verdict shifts from ≈chance (raw) to an aggregate ≈ 2× chance (masked).
Remotesensing 18 02318 g005
Figure 6. RQ2 per-fold ROC-AUC distribution under random vs. spatially blocked 5-fold CV. Strip + box: each marker is one outer fold; boxes show per-(model, scheme) median and IQR. The mean is essentially the same under both schemes, but the across-fold spread inflates from a mean SD of 0.002 (random) to 0.015 (spatial)—an ≈9× increase. Apparent performance under spatially structured data is therefore region-dependent, and single-split estimates are unstable; the algorithm ranking (XGBoost > RF > SVM-RBF > LR) is nevertheless preserved across both schemes.
Remotesensing 18 02318 g006
Figure 7. Global factor importance, expressed as mean |SHAP| over the primary balanced sample (terrain-plausible negatives at 1:1; Section 3.6). Top-12 features for XGBoost (left) and Random Forest (right). The dominant predictor for both models is the second-episode event rainfall (15–17 May 2023), followed by terrain (TRI, elevation, slope, and curvature). Lithology classes are individually small in mean |SHAP| but aggregate to a leading geological role for the clay-shale group (argille scagliose; Section 4.6).
Remotesensing 18 02318 g007
Figure 8. Per-10 km-block ΔNDVI lift distribution on the raw and masked footprints (blocks with ≥30 footprint pixels and ≥1 H + VH pixel). Per-block median ≈ 0.67× (below chance); aggregate lifts (1.07× raw, 2.00× masked; solid lines) sit in the upper tail, hence the wide bootstrap CI (1.25–2.72×) and the regional-not-per-place claim.
Remotesensing 18 02318 g008
Figure 9. Distribution of per-10 km-block ΔNDVI plausibility lift, grouped by the dominant lithology of the block (Section 4.7). Box: q25–q75; line: median; ○: mean; whiskers: 1.5·IQR; n on each box is the number of blocks. No lithotype’s median lift exceeds chance (lift = 1, dashed); the negative Pearson correlation of block lift with clay-shale fraction (r = −0.22) is NOT driven by the simple “model saturates on H + VH in clay-shale” mechanism. The mechanism behind this negative correlation—and its statistical fragility (only n = 3 strongly clay-shale-dominated blocks)—is discussed in Section 5.2.
Remotesensing 18 02318 g009
Figure 10. Bootstrap distribution of the masked ΔNDVI lift at the −0.15 operating threshold (canonical run; 10 km blocks; 400 resamples; seed 42). Pixel-pooled point (red, 2.00×) sits in the upper tail; bootstrap median (dashed, 1.94×) is the conservative reading; 95% CI [1.25, 2.72] (shaded) excludes chance (dotted). The visual asymmetry is the expected long-upper-tail effect of the block bootstrap.
Remotesensing 18 02318 g010
Table 1. Conditioning factors grouped by category, with the process-based rationale for their inclusion (36 predictors in total, lithology and land cover entering as one-hot classes).
CategoryConditioning FactorsProcess-Based Rationale
Topographicelevation, slope, aspect, plan and profile curvature, TWI, TRIslope and curvature set gravitational driving stress and flow convergence; TWI and TRI proxy moisture accumulation and surface roughness
Lithologicallithotechnical class (argille scagliose, marls, flysch, competent rock, evaporites; one-hot)controls material strength, weathering grade, and pore-pressure response
Hydro-climaticevent rainfall (episode 1, episode 2, total), distance to drainagerainfall is the trigger (pore-pressure build-up); channel proximity sets saturation and toe erosion
Vegetation (predisposing)pre-event median NDVIindexes root cohesion and antecedent canopy/soil-moisture state
Land cover/
anthropogenic
ESA WorldCover classes (one-hot), distance to roads, distance to settlementscut-slopes, drainage alteration, and land-use disturbance modulate stability
Table 2. Open input datasets: source, native resolution, coordinate reference system, and version/vintage. All layers are reprojected and resampled to the common 30 m modeling grid (EPSG:32632).
DatasetSource/ProviderNative ResolutionCRSVersion/Vintage
Terrain (DTM)Emilia-Romagna regional LiDAR, DTM5X5 (TINITALY 10 m fallback)5 mEPSG:32632RER DTM5X5 (CC BY 4.0)
LithologyRER 1:10,000 geological-units map1:10,000 (vector)EPSG:32632RER geoportal, WFS accessed May 2026
RainfallCopernicus ERA5-Land~9 km, hourlyEPSG:43261–17 May 2023
Optical (NDVI/NBR)Copernicus Sentinel-2 (Element84 STAC)10 mEPSG:32632L2A, April–June 2022 & 2023
SAR (coherence/backscatter)Copernicus Sentinel-1 via ASF HyP3~20 mEPSG:32632S1A SLC, 12-day pair, May 2023
Land coverESA WorldCover10 mEPSG:32632v200 (2021)
Roads, settlementsOpenStreetMap (Geofabrik)VectorEPSG:32632Geofabrik extract, accessed Apr 2026
Landslide inventoryRER2023 [18]0.2 m aerial mappingEPSG:7791 (~32632)RER2023 v1 (2025)
Table 3. Hyperparameter search spaces explored by the nested randomized search (40 sampled configurations per outer fold; inner 3-fold CV; ROC-AUC scoring).
ModelHyperparameter Search Space
Logistic RegressionC ∈ {0.01, 0.1, 1, 10}
RBF-SVMC ∈ {1, 10}; γ ∈ {scale, 0.1}
Random Forestn_estimators ∈ {300, 500}; max_depth ∈ {none, 20, 30}; min_samples_leaf ∈ {1, 5}
XGBoostn_estimators ∈ {400, 800}; max_depth ∈ {4, 6, 8}; learning_rate ∈ {0.03, 0.1}; subsample ∈ {0.8, 1.0}; colsample_bytree ∈ {0.8, 1.0}
Table 4. ΔNDVI threshold sensitivity (phenology-matched 2022 anchor; reference base rates: raw 11.9%, masked 16.5%). The landslide-relevant lift is monotonically increasing with stricter thresholds and exceeds 2× already at −0.15; all four masked-lift 95% spatial-block-bootstrap CIs exclude 1 (10 km blocks, 400 resamples). The raw lift stays ≈ chance regardless of threshold, reflecting persistent flood/agriculture contamination over the unmasked domain.
ΔNDVI ThresholdRaw LiftMasked Lift (Point)Masked Lift 95% CI
<−0.101.04×1.71×[1.07, 2.32]
<−0.15 (operating)1.07×2.00×[1.25, 2.72]
<−0.201.05×2.17×[1.36, 2.93]
<−0.251.01×2.24×[1.39, 3.06]
Table 5. Raw co-event footprint (full modeled domain; random-mask expectation = 11.9% High + Very-High).
Independent ObservationHigh + Very-High CaptureLift vs. Chance
Random-mask expectation (reference)11.9%1.00×
S2 ΔNDVI, phenology-matched (2022 anchor)12.7%1.07×
S2 ΔNDVI, phenology-matched (April 2023)8.6%0.72×
S2 ΔNBR (2022)6.6%0.55×
S1 coherence/backscatter > 0.5015.2%1.28×
S1 > 90th percentile13.8%1.16×
S1 > 95th percentile11.9%1.00×
S2 ∩ S1 (both sensors agree)12.6%1.06×
Table 6. Landslide-relevant footprint (water/wetland/cultivated/built-up and slope < 10° excluded; base rate recomputed on the masked domain = 16.5%). The slope ≥ 5° variant is consistent (chance 14.6%; ΔNDVI-2022 lift 1.84×).
Independent ObservationHigh + Very-High CaptureLift vs. Chance
Random-mask expectation (reference)16.5%1.00×
S2 ΔNDVI, phenology-matched (2022 anchor)33.1%2.00×
S2 ΔNDVI, phenology-matched (April 2023)29.2%1.77×
S2 ΔNBR (2022)16.8%1.02×
S1 coherence/backscatter > 0.5019.2%1.16×
S1 > 90th percentile17.5%1.06×
S1 > 95th percentile15.8%0.96×
S2 ∩ S1 (both sensors agree)36.4%2.21×
Table 7. Model comparison under spatially blocked CV with terrain-plausible negatives (mean ± std over 5 folds). Note: SVM-RBF is fit on a uniform random sub-sample of 8000 training examples per outer fold, an O(n2) to O(n3) cost cap; Section 3.3); a sensitivity re-run at 5000 vs. 8000 changes the SVM-RBF mean AUC by <0.005 and does not alter the ranking.
ModelAUCF1Cohen’s κ
LR0.934 ± 0.0140.862 ± 0.0320.724 ± 0.030
SVM-RBF0.937 ± 0.0110.868 ± 0.0290.735 ± 0.025
RF0.941 ± 0.0150.872 ± 0.0340.749 ± 0.035
XGBoost0.945 ± 0.0150.876 ± 0.0320.755 ± 0.032
Table 8. Negative-sampling sensitivity (all four models, spatial CV, 1:1). The strategy effect is consistent across models; Cohen’s κ values are shown in the right block. SVM footnote (Section 3.3): all SVM-RBF entries are fit on a uniform-random 8000-sample sub-sample of each outer-fold training partition; the ranking is invariant to the cap.
Negative StrategyLR AUCSVM AUCRF AUCXGB AUCLR κSVM κRF κXGB κ
Buffered-random0.9700.9740.9760.9800.8130.8300.8420.856
Random0.9460.9490.9520.9560.7540.7660.7780.784
Terrain-plausible (baseline)0.9340.9370.9410.9450.7240.7350.7490.755
Table 9. Robustness and adversarial checks on the phenology-matched ΔNDVI result (10 km spatial-block bootstrap, 400 resamples).
CheckResultVerdict
Footprint enrichment vs. RER2023 (raw/masked)5.5×/11.4×genuine landslide signal
Footprint recall by polygon size (1 px → ≥10 px)12.5% → 34.7%size-biased; detectable subset
Sentinel-1 footprint enrichment≈1.1×not a discriminator (12-day)
Footprint median slope vs. masked domain20.5° vs. 20.6°not a steep-slope subset
Slope-only/terrain-composite baseline lift1.23×/1.25×model (2.00×) far exceeds
Model lift within slope deciles2.18×skill beyond slope/terrain
Raw ΔNDVI lift (point; 95% CI)1.07 [0.6, 1.7]includes 1—no skill
Masked ΔNDVI lift (point 2.00; boot. median; CI)1.94 [1.25, 2.72]excludes 1—real skill
Per-block lift heterogeneity (q10/50/90)0.0/0.67/1.58spatially heterogeneous (Figure 8)
Recall—Earth Flow (EF)28.1% (n = 2269)best-recovered (clay-shale)
Recall—Earth Slide (ES)21.4% (n = 5243)well-recovered
Recall—Debris Flow/Slide (DF, DS2)18–20%average
Recall—Debris Slide (DS1, dominant)14.9% (n = 27,115)small, shallow
Recall—Rock Slide complex (RS2)5.5% (n = 109)below ΔNDVI sensitivity
Easy-negative fraction of domain24.6%masked null already excludes
Re-model AUC under susc-restricted negatives (XGB, spatial)0.9445 (Δ −0.0005)AUC NOT inflated by easy negatives
Re-model masked-footprint lift (restricted-neg XGB)2.45×plausibility lift robust to neg pool
Within-class slope median (footprint-class)VL −0.2°, L −4.5°, M −4.8°, H −4.9°, VH +1.5°no within-class slope bias
Terrain-only re-model AUC (XGB, spatial)0.9039 (Δ −0.041)non-terrain predictors add real skill
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content.