Article

Physics-Informed Semantic Prompt Learning for Few-Shot Low-Altitude Radar Target Recognition in Remote Sensing

1
School of Electronic Information and Electrical Engineering, Yangtze University, Jingzhou 434023, China
2
School of Computer and Software, Hangzhou Dianzi University, Hangzhou 310018, China
*
Author to whom correspondence should be addressed.
Remote Sens. 2026, 18(14), 2316; https://doi.org/10.3390/rs18142316
Submission received: 22 May 2026 / Revised: 3 July 2026 / Accepted: 8 July 2026 / Published: 10 July 2026
(This article belongs to the Section AI Remote Sensing)

Highlights

What are the main findings?
  • A physics-informed semantic prompt learning framework is proposed to conquer severe data scarcity by translating multidimensional radar observations into physics-enriched structured textual prompts, utilizing adaptive feature aggregation, and innovatively integrating a relation-based meta-learning network for optimized similarity matching.
  • The framework demonstrates robust few-shot recognition capabilities for challenging low-altitude radar targets, achieving a mean F1-score of 78.34% under 1-shot conditions, and surging to a remarkable 90.63% at the 20-shot setting.
What are the implications of the main findings?
  • This approach fundamentally breaks the reliance on large-scale datasets for accurate target recognition, effectively resolving the high financial costs and practical execution challenges associated with extensive real-world radar data collection.
  • By enabling robust identification with minimal labeled samples, the method facilitates continuous airspace supervision of radar targets including unmanned aerial vehicles, birds, and other similar objects to proactively prevent potential hazards.

Abstract

Low-altitude radar target recognition is important for intelligent airspace monitoring, unmanned aerial vehicle (UAV) supervision, airport bird-strike prevention, and low-altitude remote sensing. Reliable recognition remains difficult because birds, balloons, and UAVs often produce weak radar responses, share similar trajectory-level signatures, and are difficult to annotate at scale. To address these challenges, this paper proposes a physics-informed semantic prompt learning framework for few-shot low-altitude radar target recognition. The framework converts radar point-track and track measurements into structured textual prompts that combine statistical descriptors, radar-domain physical knowledge, and task-specific instructions. A partially fine-tuned Generative Pre-trained Transformer 2 (GPT-2) encoder is then used to extract semantic representations that preserve motion and scattering-related information. An adaptive feature aggregation module further weights informative hidden states across temporal positions and semantic levels, and a relation-based meta-learning network models query-support similarity for few-shot classification. Experiments on a real low-altitude radar dataset with four target categories, namely birds, balloons, small rotary-wing UAVs, and light rotary-wing UAVs, show that the proposed method consistently outperforms conventional machine learning, deep learning, and representative few-shot baselines. Under the 20-shot setting, it achieves mean 90.85% precision, 90.47% recall, and 90.63% F1-score. The results indicate that embedding radar physical semantics into language-model-based representation learning can improve sample efficiency and recognition robustness for low-altitude radar remote sensing.

1. Introduction

In recent years, the rapid development of the low-altitude economy [1] has increased the demand for reliable airspace monitoring in urban security, border surveillance, airport bird-strike prevention, and unmanned aerial vehicle (UAV) supervision. Radar is well suited to these applications because it provides active, all-weather, and day-and-night sensing capability [2]. Nevertheless, low-altitude target recognition remains difficult in practice. Birds, balloons, light rotary-wing UAVs, and small rotary-wing UAVs often have weak scattering responses, limited spatial extent, and overlapping motion patterns. Their trajectories are also affected by wind, maneuvering behavior, clutter, and intermittent detection. At the same time, high-quality labeled radar data are expensive to collect and annotate. Deep learning methods typically require large-scale labeled datasets, and when only limited training data are available, they become more susceptible to overfitting [3]. These factors make few-shot low-altitude radar target recognition an important and challenging problem in radar remote sensing.
Existing radar recognition methods have progressed from physical modeling and signal processing to traditional machine learning and deep learning. Signal-processing approaches describe targets through scattering characteristics, Doppler signatures, trajectory statistics, and handcrafted motion descriptors, offering interpretability but limited flexibility in complex low-altitude environments [4]. Traditional classifiers such as support vector machines, decision trees, random forests, and ensemble models can learn decision boundaries from engineered radar features, yet their performance depends strongly on feature design and degrades when inter-class differences are subtle [5]. Deep neural networks, including convolutional, recurrent, and Transformer-based architectures, can learn richer representations, but they typically require large labeled datasets and may not generalize reliably under few-shot conditions [6]. Therefore, an effective recognition framework should combine the interpretability of radar physical knowledge with the representation capacity of data-driven models while maintaining strong sample efficiency [7].
To address these issues, this paper proposes a physics-informed semantic prompt learning framework for few-shot low-altitude radar target recognition. The central idea is to transform numerical point-track and track measurements into structured textual prompts that explicitly describe statistical features, radar-domain physical meanings, and the classification objective. This transformation is not merely an input adaptation for large language models; through the [Domain] segment, it also makes implicit physical links among radar variables explicit, such as the maneuvering state reflected by coupled multi-axis velocity changes, thereby compensating for the limited ability of purely data-driven methods to directly exploit prior physical knowledge [8]. These prompts allow a language-model encoder to process radar measurements as semantically organized sequences rather than isolated numerical vectors [9]. Specifically, the prompts are encoded by a partially fine-tuned GPT-2 model to extract motion- and scattering-related semantic features. An adaptive feature aggregation module then selects informative hidden states across temporal positions and semantic levels. Finally, a relation-based meta-learning network [10] estimates the similarity between support and query samples and performs classification under the n-way k-shot setting. By integrating physical semantics, language-model representation learning, and relation-based meta-learning, the proposed framework reduces dependence on large-scale annotated radar data. The main contributions of this paper are summarized as follows:
  • A physics-informed semantic prompt learning framework is proposed for few-shot low-altitude radar target recognition. The framework is designed to address the limited labeled data problem in low-altitude radar remote sensing by integrating radar physical knowledge with language-model-based representation learning.
  • A structured prompt construction strategy is developed to convert radar point-track and track measurements into textual prompts containing statistical descriptors, domain knowledge, and task instructions. This strategy enables the language model to capture both numerical patterns and physical semantics of low-altitude targets.
  • An adaptive feature aggregation module and a relation-based meta-learning classifier are introduced to enhance discriminative representation learning and query-support similarity modeling, improving few-shot recognition performance under different shot settings.
  • Experiments on a real low-altitude radar dataset with four target categories demonstrate that the proposed method outperforms conventional machine learning, deep learning, and few-shot learning baselines, achieving strong recognition performance under limited supervision.
The remainder of this paper is organized as follows: Section 2 reviews related work in low-altitude radar target recognition. Section 3 describes the proposed framework in detail. Section 4 presents experimental results and comprehensive comparisons. Finally, Section 5 and Section 6 conclude the paper and discuss directions for future research.

2. Related Work

2.1. Low-Altitude Radar Remote Sensing Target Recognition

Low-altitude radar remote sensing target recognition aims to distinguish aerial objects such as UAVs, birds, balloons, and other small targets from radar observations. Early studies mainly relied on physical scattering models, micro-Doppler analysis, high-resolution range profiles, trajectory statistics, and other handcrafted descriptors. These features are valuable because they connect the recognition decision to measurable target properties, such as amplitude stability, radial velocity, heading variation, and vertical motion. However, low-altitude scenes often contain ground clutter, intermittent tracks, weak echoes, and targets with similar sizes or motion ranges. As a result, purely handcrafted features may not provide enough discriminative information when the number of labeled samples is limited.
Machine learning and deep learning methods have therefore been introduced to improve representation learning for radar recognition. Conventional classifiers can exploit point-track or track-level features and are relatively efficient on small datasets, but they still depend on the quality of manually selected features. Deep models, including Convolutional Neural Network, Recurrent Neural Network, graph neural networks, and Transformer-based architectures, provide stronger nonlinear modeling capability and have achieved promising results in radar target recognition. For example, Jiang et al. [11] reviewed the development of deep learning methods in Radar Automatic Target Recognition, highlighting their effectiveness in radar feature extraction and target recognition across various radar characteristics and target types. Chen et al. [12] combined dynamic graph neural networks with meta-learning for few-shot High-Resolution Range Profile recognition, and Li et al. [13] explored self-supervised learning for SAR automatic target recognition. These works indicate that modern representation learning is useful for radar applications. Nevertheless, most existing methods operate at the signal or feature level and rarely make radar physical semantics explicit in the input representation, leaving room for a framework that can connect numerical radar measurements with domain-aware semantic reasoning. From a radar signal processing perspective, most existing recognition pipelines can be understood within a unified measurement to representation process. Raw radar echoes are first converted into intermediate physical signals such as range profiles, Doppler spectra, or point track trajectories. These intermediate signals are then further summarized into handcrafted feature representations including radial velocity, acceleration, amplitude statistics, and signal to noise ratio. Traditional machine learning methods typically perform classification directly on these manually designed features. In contrast, deep neural networks learn nonlinear mappings that transform radar measurements into latent representation spaces in an implicit way. Although these approaches differ in modeling strategy, they both rely mainly on numerical feature representations and do not explicitly incorporate the underlying radar signal generation process or physical semantics. This limitation becomes more serious in low altitude environments, where weak target reflections, strong clutter interference, and overlapping Doppler patterns make it difficult for purely data driven representations to maintain clear class separability.

2.2. Few-Shot Learning for Radar and Remote Sensing Tasks

Few-shot learning addresses the problem of learning transferable decision rules from only a small number of labeled samples. Representative methods include metric-based models, such as Matching Networks [14], Prototypical Networks [15], and Siamese Networks [16]; optimization-based models, such as MAML and its variants [17]; and attention-based or relation-based meta-learning models [18]. These approaches usually train on many small episodes so that the model learns how to compare support and query samples rather than memorizing fixed class boundaries. This paradigm is particularly relevant to radar and remote sensing, where field collection is costly, target categories may change, and some classes appear only rarely.
Recent radar and remote sensing studies have adapted few-shot learning to emitter recognition, High Resolution Range Profile classification, SAR interpretation, and scene understanding. However, directly transferring few-shot algorithms from natural images to radar data is not straightforward [19]. Radar observations are sequential, noisy, and physically constrained; their discriminative cues may lie in velocity trends, amplitude fluctuation, heading changes, and track stability rather than visual texture. Many few-shot methods also treat input features as generic embeddings and do not explicitly encode the physical meaning of radar variables. Consequently, few-shot radar recognition still needs domain-aware representation learning that can preserve physical interpretability while supporting robust query-support comparison [20].

2.3. Large Language Models and Semantic Prompting for Sensor Data Understanding

Large language models and Transformer encoders have shown strong ability in sequence modeling, contextual representation, and few-shot generalization [21,22]. Prompt-based learning further provides a flexible mechanism for injecting task instructions and prior knowledge into the input. Beyond natural language processing, structured prompting has begun to appear in time-series analysis, multimodal understanding, and sensor data interpretation, where numerical observations are converted into text-like or semantically annotated sequences [23,24,25]. This strategy is attractive for radar recognition because radar variables have clear physical meanings that can be described explicitly.
Despite this potential, language-model-based prompting for radar sensing remains underexplored. Most existing prompt-learning studies focus on natural language or vision-language tasks, while radar data pose different challenges, including limited samples, irregular temporal behavior, heterogeneous feature types, and physically meaningful but noisy measurements. The present work is motivated by this gap. It constructs physics-informed prompts from radar point-track and track data, uses a partially fine-tuned GPT-2 encoder to obtain semantic representations, and combines these representations with adaptive aggregation and relation-based meta-learning for few-shot low-altitude target recognition.

3. Method

3.1. Overview

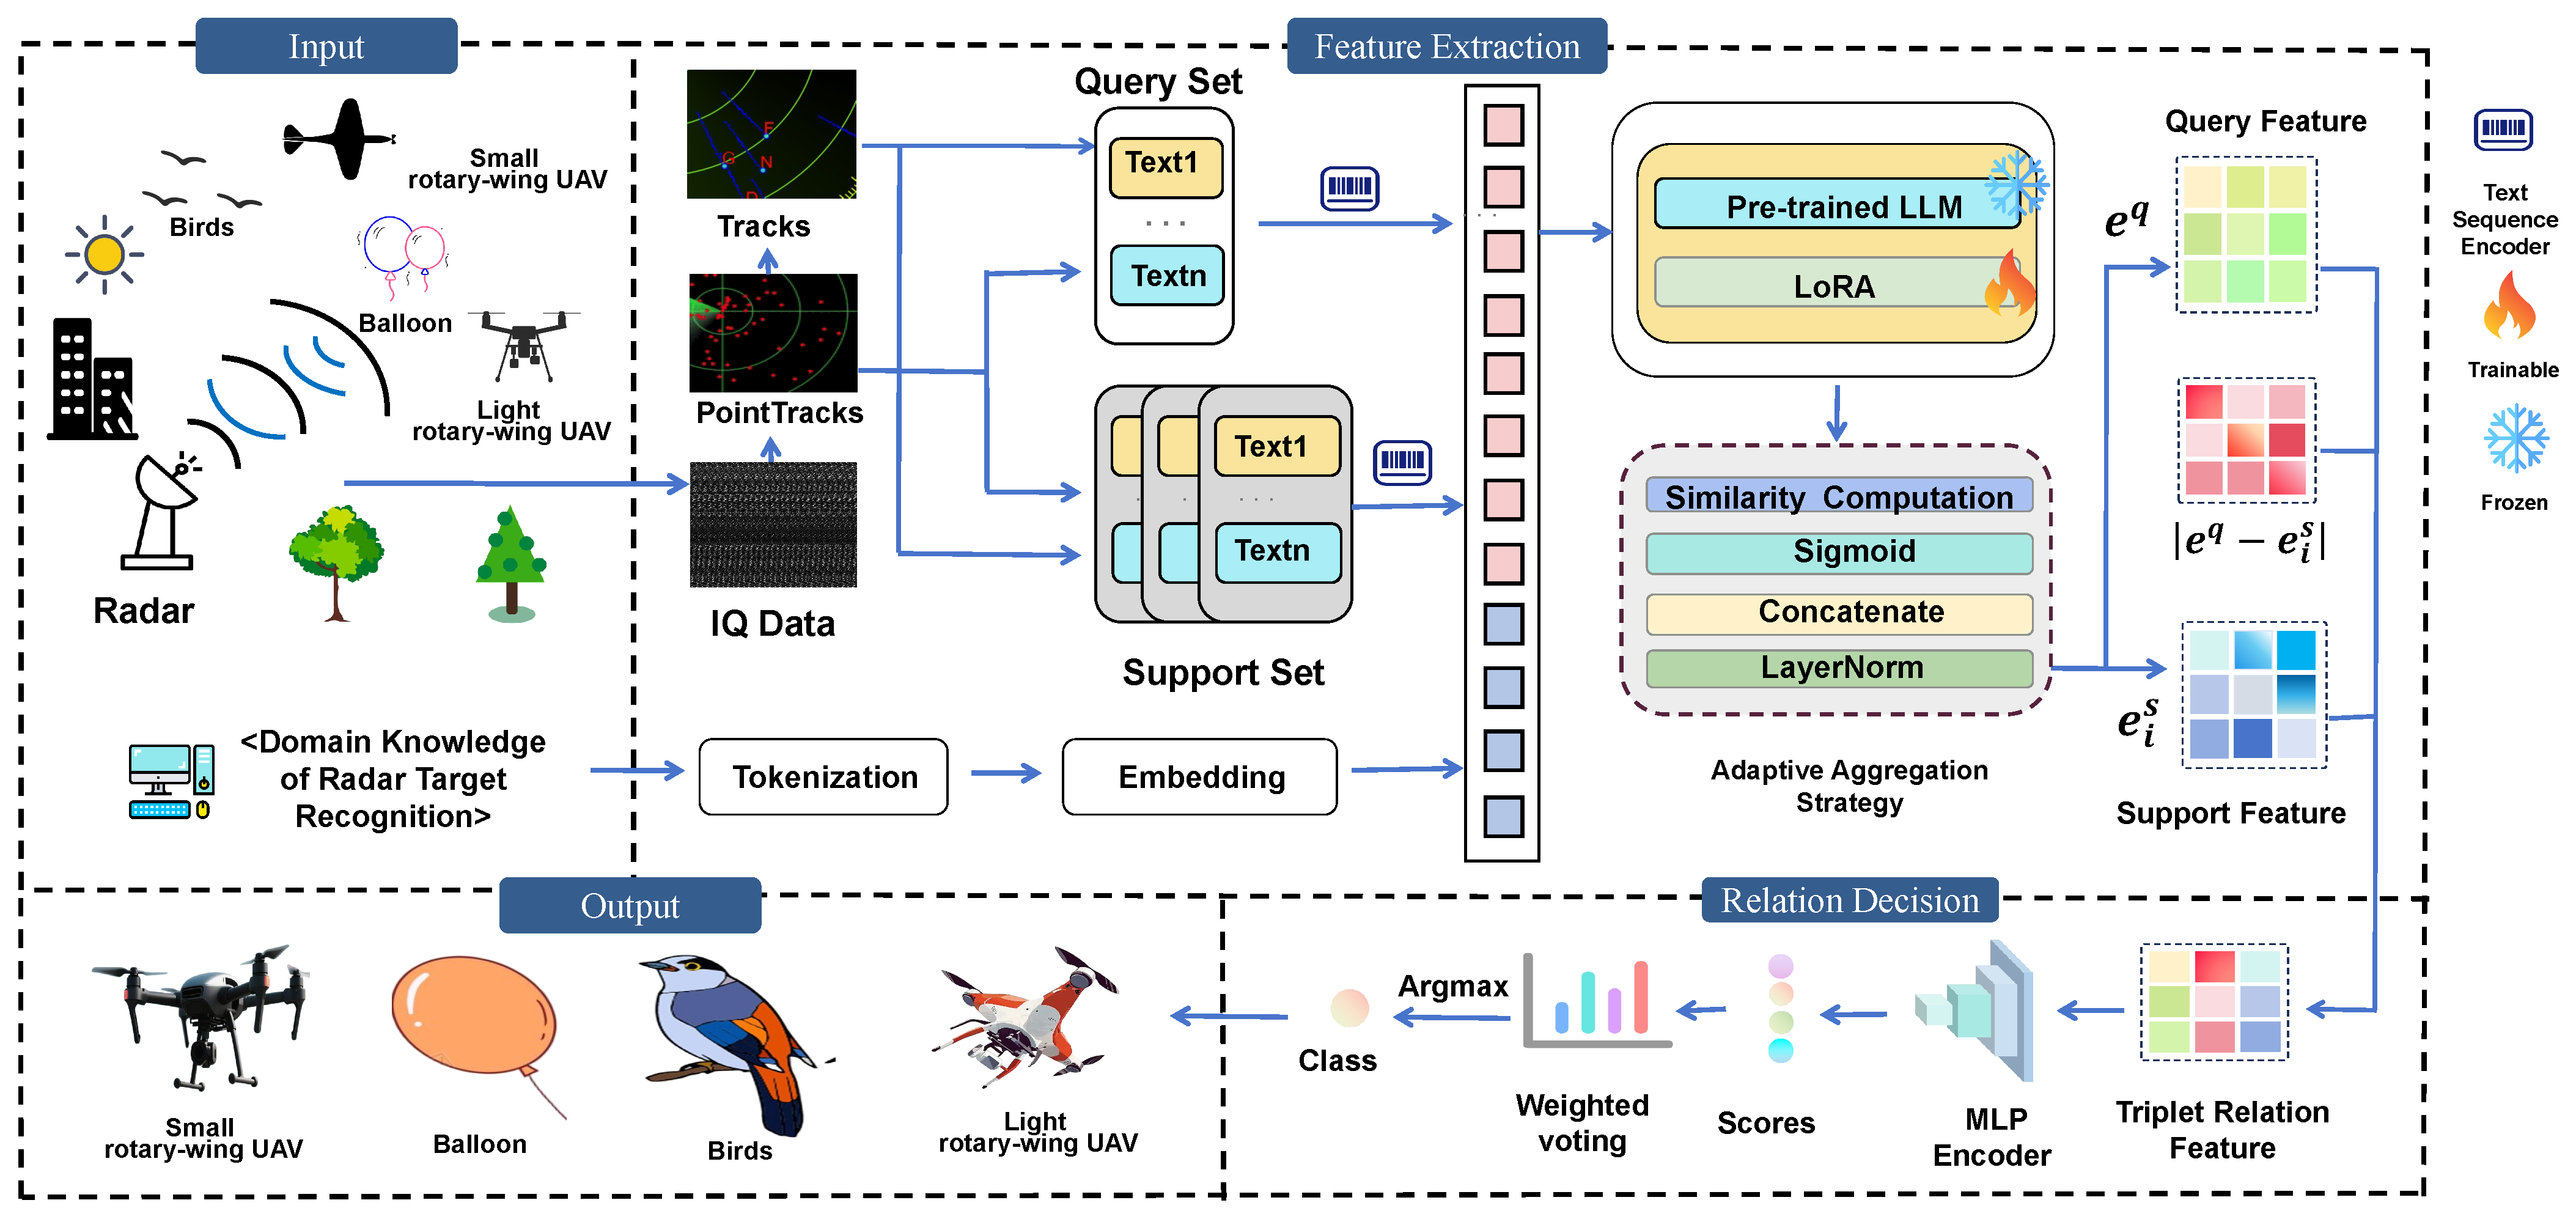
The overall framework consists of five major stages: radar data preparation, physics-informed semantic prompt construction, semantic feature extraction, adaptive feature aggregation, and relation-based few-shot classification. The proposed framework is illustrated in Figure 1. Given radar point-track and track data, the framework first organizes the original measurements into structured prompt sequences containing statistical descriptions, domain prior knowledge, and task instructions. These prompts are encoded by a partially fine-tuned GPT-2 model to generate multi-layer hidden representations. The adaptive aggregation module then weights informative hidden states across temporal positions and semantic levels to form compact task-relevant embeddings. Finally, within an episodic meta-learning setting, the relation decision network compares query embeddings with support embeddings and predicts the target class through relation score voting.

3.2. Few-Shot Learning Framework

Few-shot learning is introduced because practical low-altitude radar systems often encounter new or weakly represented target categories before sufficient labeled samples can be collected. In this setting, a conventional classifier trained with fixed class boundaries is easily biased by the small training set. The purpose of this module is therefore to expose the model to many small support-query tasks during training, so that it learns a transferable similarity function suitable for recognizing targets from only a few examples.
The framework follows the classical n-way k-shot episodic paradigm. In each training episode t, n distinct classes are sampled from the full class set, and k support instances are selected from each class to form the support set S t . A query sample from one of the selected classes is then used to form the query set Q t . Each episode therefore defines a complete n-class few-shot classification task. In this paper, n = 4 and k { 1 , 3 , 5 , 10 , 15 , 20 } . The sampling process is defined in Equation (1).
T t = { S t , Q t } ,
where the support set S t = { ( x i s , y i s ) } i = 1 n k comprises n classes with k samples per class, and the query set Q t = { ( x q , y q ) } contains a single query sample satisfying y q { y 1 s , , y n s } . Through this episodic construction, the model is repeatedly exposed to realistic generalization scenarios under few-shot constraints and thereby acquires transferable meta-knowledge.
The adoption of GPT-2 in this framework is motivated by two principal considerations. First, GPT-2 naturally accommodates dynamically varying input sequences, which is essential for processing digital text prompts of different lengths derived from heterogeneous radar targets. Second, as a large-scale model built upon the Transformer architecture, GPT-2 possesses powerful feature extraction capabilities that enable it to capture complex semantic patterns from limited raw data. Building on these advantages, the model first employs a fine-tuned pre-trained GPT-2 model to extract deep semantic features from the digital text prompt sequences of both support and query samples. An adaptive feature aggregation mechanism then performs dynamic weighted fusion over the multi-layer outputs of GPT-2 to obtain a physically enriched feature sequence. This combined process of fine-tuned GPT-2 feature extraction and adaptive aggregation constitutes the embedding function f θ ( · ) , which directly yields the high-dimensional representations for the query and support samples, denoted as e q and e i s , respectively, as presented in Equation (2).
e q = f θ ( x q ) , e i s = f θ ( x i s ) , i = 1 , , n k .
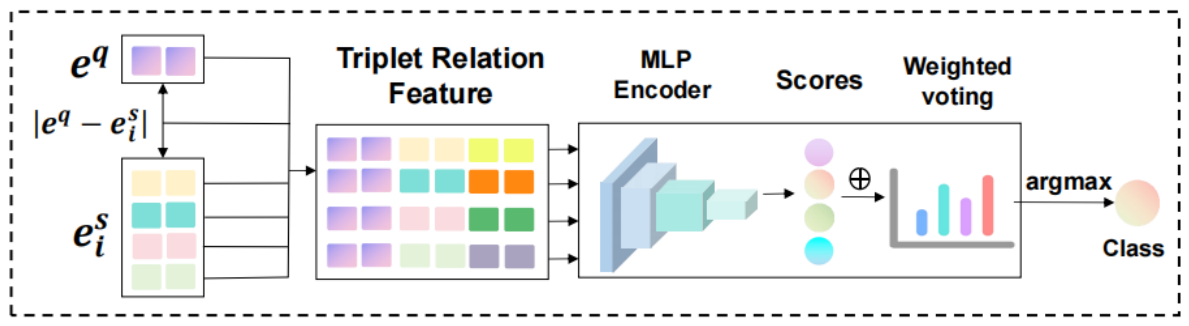
To measure the relation between the query and each support sample, the query embedding e q and each support embedding e i s are concatenated with their absolute difference | e q e i s | to form a triplet representation c i = [ e q ; e i s ; | e q e i s | ] R 3 d , where d denotes the embedding dimension. The relation decision network g ϕ ( · ) then maps this triplet to a confidence score r i = g ϕ ( c i ) indicating whether the query and the support sample belong to the same class. During training, a binary cross-entropy loss with positive sample reweighting is adopted for end-to-end optimization, as defined in Equation (3).
L ( θ , ϕ ) = 1 n k i = 1 n k w · y i log σ ( r i ) + ( 1 y i ) log ( 1 σ ( r i ) ) ,
where y i = 1 if the support sample and the query sample belong to the same class, and y i = 0 otherwise. The weight w is the positive sample weight used to compensate for the imbalance between positive and negative pairs to mitigate the severe imbalance between positive and negative samples within the support set. During inference, the framework computes the relation scores between the query sample and all support samples and converts them into relation probabilities. The final category prediction is then obtained by averaging the relation probabilities of support samples from each candidate class, as defined in Equation (4).
y ^ = arg max c C t 1 k i : y i s = c σ ( r i ) .
By integrating fine-tuned GPT-2 based semantic feature extraction, adaptive aggregation, and the relation decision network, the proposed meta-learning framework reduces dependence on labeled data and improves robustness and generalization ability in complex environments, thereby offering an efficient and scalable solution for low-altitude airspace security. The complete training procedure is summarized in Algorithm 1.
Algorithm 1 Training Procedure
  • Require: Dataset D , learning rate η , number of episodes E, n-way, k-shot
  1:
Initialize parameters θ , ϕ for embedding network and relation network
  2:
for episode = 1 to E do
  3:
    Sample n classes from D
  4:
    Sample support set S t = { ( x i s , y i s ) } i = 1 n k from selected classes
  5:
    Sample query set Q t = { ( x j q , y j q ) } from selected classes
  6:
    for each sample ( x , y ) in S t Q t  do
  7:
        Construct physics-semantic prompt p using Equation (5)
  8:
        Extract semantic embedding e through GPT-2 encoder
  9:
        Aggregate features using Equation (7)
10:
    end for
11:
    Compute relation scores r i = g ϕ ( e q , e i s ) for all query-support pairs
12:
    Calculate loss L using Equation (3)
13:
    Update parameters: θ θ η θ L , ϕ ϕ η ϕ L
14:
end for
15:
return Trained parameters θ , ϕ

3.3. Prompts with Physical Semantics

The prompt construction module is designed to bridge the gap between numerical radar measurements and the semantic input format expected by a language-model encoder. Radar point-track and track variables are not arbitrary numbers: amplitude reflects echo strength, signal-to-noise ratio describes measurement reliability, velocity components indicate motion state, and heading changes reveal maneuvering behavior. Encoding these variables with their physical meanings helps the model distinguish targets whose raw numerical ranges may overlap but whose motion mechanisms differ.
This paper therefore constructs physics-semantic digital text prompts from the fused radar sequence. The method integrates point-track and track data through feature selection, normalization, temporal sliding windows, and semantic encoding. The original trajectory data provide rich electromagnetic, kinematic, and dynamic attributes for multiple targets; however, not all features contribute positively to the final recognition task. To reduce redundancy in radar measurements correlated with spatial coordinates, a feature compression strategy is applied. It compacts correlated motion and scattering information to improve the robustness of semantic representations. This aligns with attribute based radar recognition methods that emphasize key physical features while suppressing redundant information [7]. The raw dataset contains N samples, each with point data P i and trajectory data t i , which are normalized into a fused feature sequence X ˜ i R 7 . To handle the 1024 token limit of GPT 2, a sliding window strategy is used. This allows the model to focus on short term temporal patterns in multivariate radar sequences while keeping computation efficient. Such window based processing is commonly used in radar trajectory and motion analysis to capture local dynamics [7]. For each window, the selected features are converted into a statistical description segment denoted as [ Statistics ] . For the n-th sliding window, [ Statistics ] n is defined as a key-value text sequence, as shown in Equation (5).
[ Statistics ] n = Time : T ˜ , Amplitude : p ˜ , SNR : SNR ˜ , Total Velocity : V ˜ total , Z - Velocity : V ˜ z , Heading : H ˜ , Raw Points : N ˜
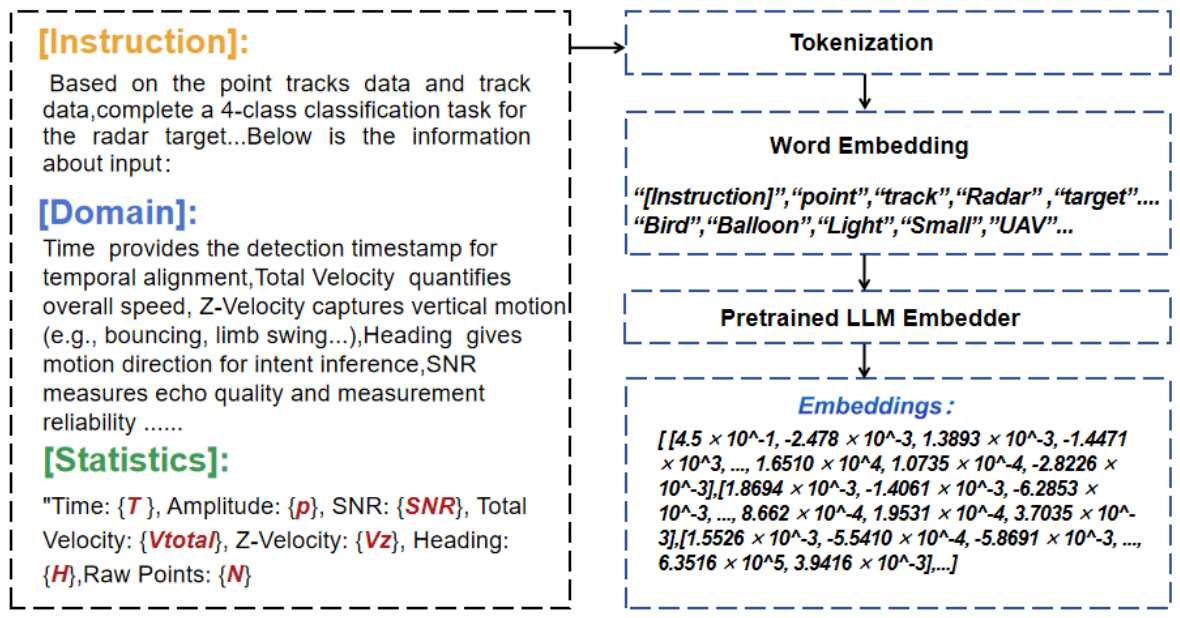
To further enhance the understanding of radar physical semantics, two background knowledge segments are prepended to the prompt: the context segment [ Domain ] and the instruction segment [ Instruction ] , as shown in Figure 2. The [ Domain ] segment provides domain knowledge of key physical quantities, indicating that radar point and trajectory data reflect target motion characteristics and behavioral patterns through multiple physical variables. For example, the velocity components along the X, Y, and Z axes characterize the three-dimensional trajectory and motion state of the target. The [ Instruction ] segment specifies the task objective and directs the model to perform a four-class classification task. The four categories include Bird, Balloon, Small rotary-wing UAV and Light rotary-wing UAV. The final prompt adopts a three-part structure. The complete prompt sequence is defined in Equation (6).
Prompt n = [ Statistics ] n , [ Domain ] , [ Instruction ]
As the sliding window advances by one step, a new prompt sequence is generated and fed as tokens into the fine-tuned large language model.

3.4. Adaptive Feature Aggregation

The adaptive feature aggregation module is introduced because the hidden states produced by GPT-2 contain information at different temporal positions and semantic levels, but their usefulness for radar recognition is uneven. Some tokens describe highly discriminative physical changes, such as abrupt velocity variation or stable amplitude patterns, whereas others may correspond to repeated instructions or weakly informative context. The role of this module is to emphasize the hidden states that are most relevant to target discrimination and suppress redundant or noisy information before relation comparison.
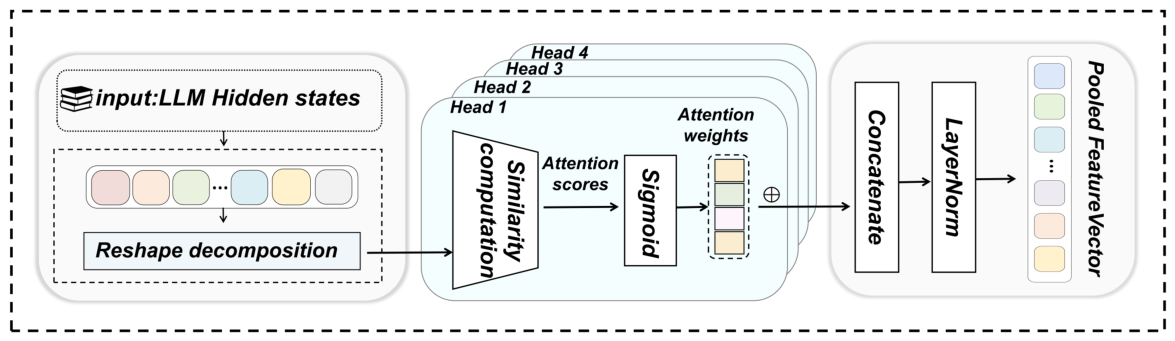
As shown in Figure 3, the module consists of four consecutive aggregation blocks that dynamically weight the sequence-level hidden states and produce a fixed-dimensional pooled feature vector. Given hidden states H R B × L × D , where B denotes the batch size, L denotes the sequence length, and D denotes the hidden dimension, a reshape operation is first applied to obtain a multi-head representation H R B × L × h × d . Here h = 4 denotes the number of attention heads, matching the number of target categories, and d = D / h denotes the dimension of each head. A set of learnable attention vectors A R h × d is introduced as query references. In each block, a similarity computation module calculates the dot product between the hidden states and the attention vectors to obtain similarity scores, as defined in Equation (7).
att _ scores b , i , k = j = 1 d H b , i , k , j · A k , j
Here b indexes the batch, i indexes the temporal position in the sequence, k indexes the attention head, and j indexes the feature dimension. The sigmoid function σ is then applied to map the similarity scores into the interval [ 0 , 1 ] , yielding the attention weights α b , i , k = σ ( att _ scores b , i , k ) . These weights adaptively reflect the importance of different features for the recognition task. Features strongly correlated with target motion state, velocity variation, and electromagnetic scattering properties receive higher weights, whereas redundant or noisy features are suppressed. After obtaining the attention weights for each block, the hidden states are weighted accordingly. The weighted features from the four blocks are then concatenated. Finally, a layer normalization operation is applied to produce the pooled feature vector z, as shown in Equation (8).
z = LayerNorm Concat k = 1 h i = 1 L α b , i , k · H b , i , k
The principal advantage of this mechanism lies in its adaptivity. The learnable attention vectors A dynamically assign weights to different temporal steps and feature layers according to the input characteristics. This enables the model to focus on discriminative temporal patterns such as abrupt velocity changes, heading transitions, and significant fluctuations in signal-to-noise ratio, while attenuating the influence of redundant or noisy information. The proposed adaptive aggregation mechanism captures essential information within the sequence more effectively and enhances representational capacity and robustness through its multi-head design and dynamic weighting, thereby providing high-quality task-oriented embeddings for the subsequent few-shot relation decision network.

3.5. Relation Decision Network

The relation decision network is introduced to make the final classifier consistent with the few-shot setting. Because only a small number of labeled samples are available in each episode, directly learning a conventional softmax classifier may overfit to the sampled classes. Instead, the network learns whether a query sample and a support sample belong to the same class. This pairwise decision mechanism allows the model to transfer its comparison ability across shot settings and supports class prediction by aggregating relation scores.
As shown in Figure 4, the input first passes through the embedding component, which maps each text prompt sequence into a high-dimensional semantic representation. Given a tokenized sequence x R B × L , the embedding component produces a vector e = f ( x ) R d e , where f ( · ) combines GPT-2 feature extraction and adaptive aggregation. After obtaining the query embedding e q R d e and the support embeddings { e i s } i = 1 N s , where N s = n × k , the relation module constructs a composite feature for each query-support pair. For support sample i, the triplet relation feature is defined as c i = [ e q ; e i s ; | e q e i s | ] R 3 d e . This representation includes the query feature, the support feature, and their absolute difference, enabling the network to model both similarity and discrepancy between samples.
The composite feature c i is fed into the relation decision network g ϕ ( · ) , which adopts an MLP-based encoder. The encoder takes h 0 = c i as input and propagates it through five stacked layers. For k = 1 , 2 , the transformation includes LayerNorm, LeakyReLU, and Dropout; for k = 3 , LayerNorm and LeakyReLU are used; and for k = 4 , LeakyReLU is retained. The weight matrices are configured as W 1 R 1024 × 3 d e , W 2 R 512 × 1024 , W 3 R 128 × 512 , and W 4 R 64 × 128 , forming a progressively compressed representation. The final layer produces the scalar relation logit r i . The forward propagation is formulated in Equations (9) and (10).
h k = f k ( W k h k 1 + b k ) , k = 1 , 2 , 3 , 4
r i = W 5 h 4 + b 5 , W 5 R 1 × 64
The encoder outputs a scalar logit r i as the relation score. During training, a binary cross-entropy loss with positive sample reweighting is adopted for end-to-end optimization. During inference, for a given query embedding e q , the model computes relation scores with all support samples and determines the final predicted class through a weighted voting mechanism, as defined in Equation (11).
y ^ = arg max c C 1 k i y i s = c r i
Through this explicit relation modeling mechanism, the proposed network does not depend on traditional prototype-based classifiers or direct softmax mapping. Instead, it acquires a meta-level capability for feature comparison and direct relation scoring under few-shot constraints. This design enhances sensitivity to subtle differences among low-altitude, slow-speed, and small-size targets and demonstrates strong generalization ability.

3.6. Training and Inference Algorithms

The training and inference algorithm summarizes how the above modules interact in an end-to-end few-shot pipeline. Its purpose is to ensure that prompt construction, semantic encoding, adaptive aggregation, and relation scoring are optimized under the same episodic objective used at test time. This alignment between training and inference reduces the mismatch that often occurs when a model is trained as a standard classifier but evaluated under few-shot conditions. The complete training procedure is summarized in Algorithm 1. The model is trained episode by episode, where each episode contains a support set and a query set sampled from the same classes. Parameters are updated through backpropagation by minimizing the binary cross-entropy loss defined in Equation (3).

4. Experimental Results

4.1. Dataset

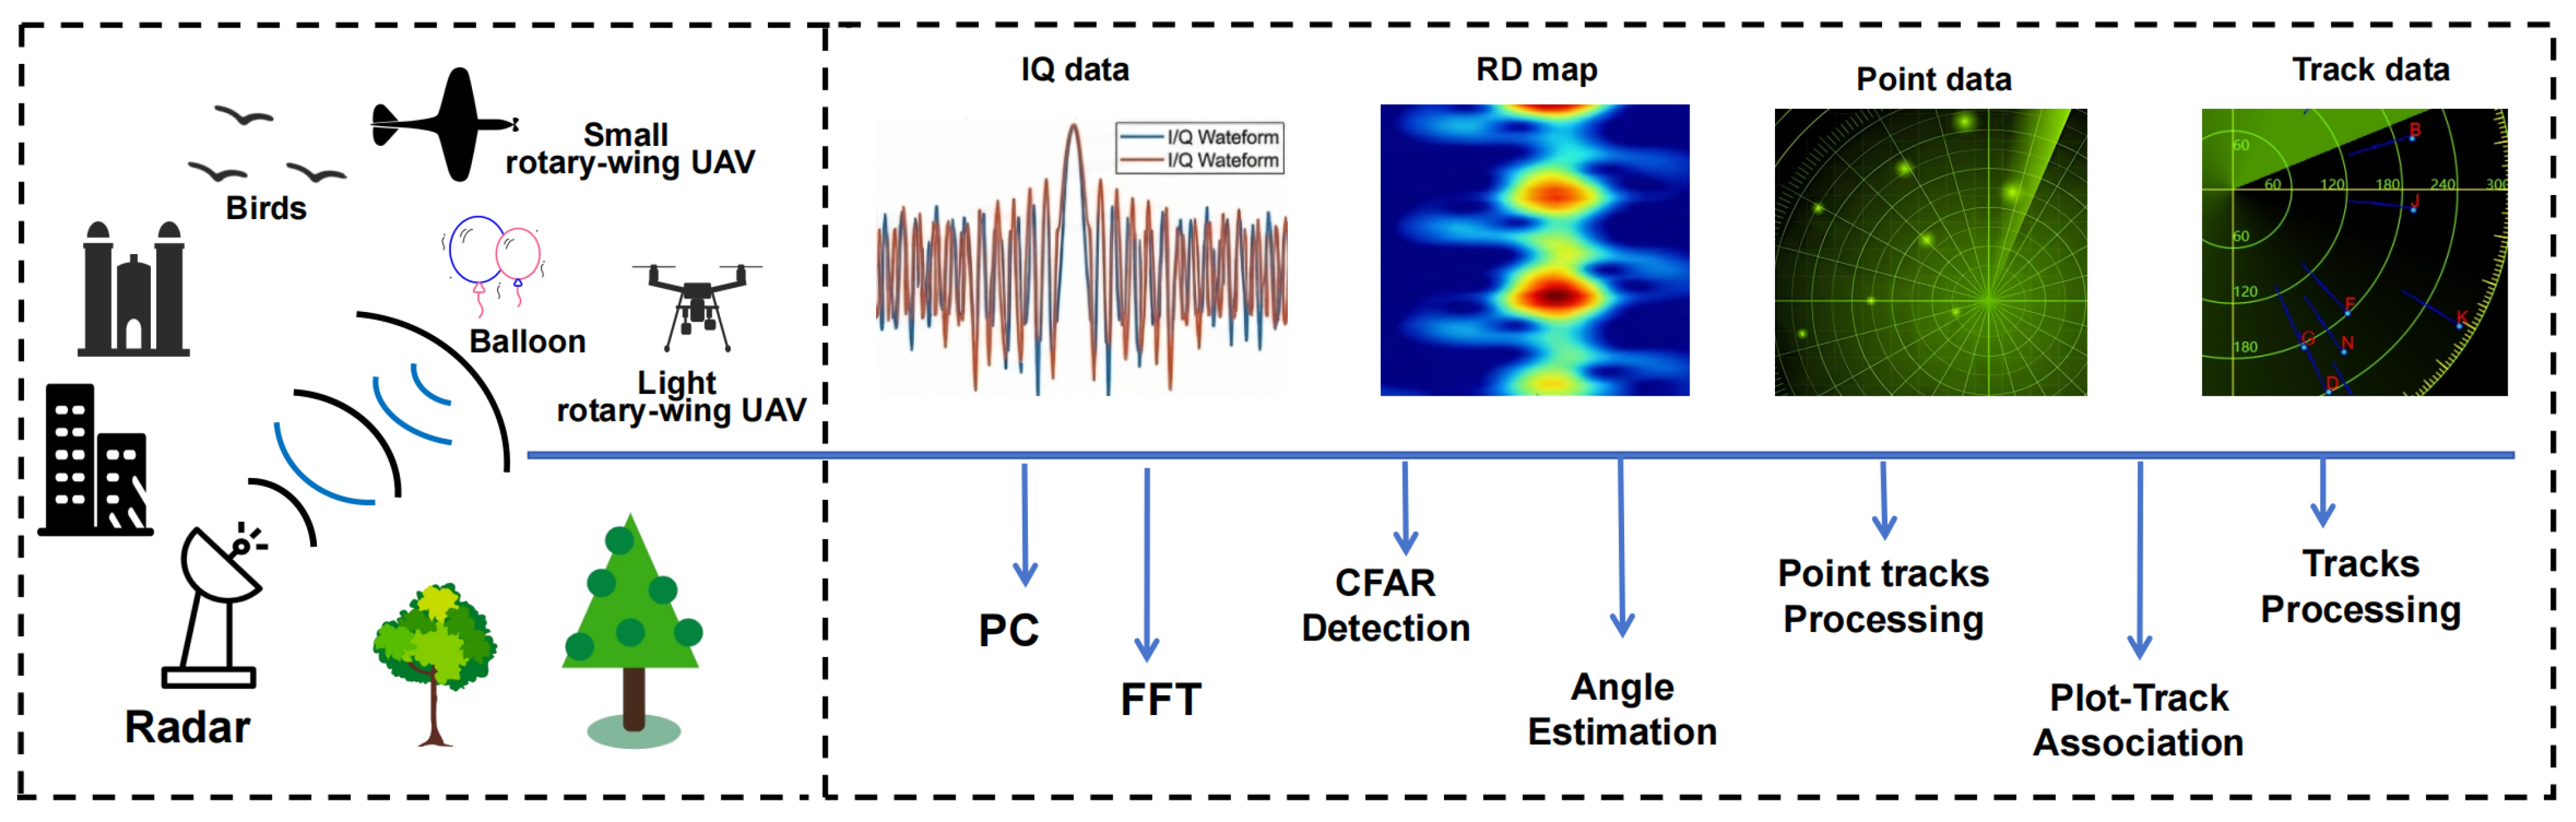
To evaluate the proposed method, a real low-altitude radar dataset collected through field measurement is used. Each sample contains raw echo data, point trajectory data, and track data. The raw echoes are pulse-compressed single-polarization signals that record amplitude and phase information over specific range bins and pulse intervals. The point trajectory data are generated through moving-target detection, constant false alarm rate processing, and trajectory aggregation; their feature vector includes timestamp, batch index, range, azimuth, elevation, Doppler velocity, amplitude, signal-to-noise ratio, and raw point count. The track data are obtained by associating and filtering point trajectories, and include timestamp, batch index, filtered range, filtered azimuth, filtered elevation, total velocity, three-axis velocity components, and heading angle. The processing pipeline is shown in Figure 5. The dataset contains four categories: light rotary-wing UAVs labeled as 1, small rotary-wing UAVs labeled as 2, birds labeled as 3, and floating balloons labeled as 4. Each category contains 350 samples, giving 1400 samples in total.

4.2. Experimental Settings

All experiments are conducted on a workstation equipped with an NVIDIA RTX A6000 GPU with 48 GB memory (NVIDIA Corporation, Santa Clara, CA, USA). The software environment uses Python 3.10.9 (Python Software Foundation, Wilmington, DE, USA), PyTorch 2.5.1 (Meta Platforms Inc., Menlo Park, CA, USA), and CUDA Toolkit 12.1 (NVIDIA Corporation, Santa Clara, CA, USA). The proposed framework is trained under a 4-way k-shot episodic setting, where k 1 , 3 , 5 , 10 , 15 , 20 . The embedding network and relation decision network are jointly optimized by the Adam optimizer. Training lasts for 100 epochs with 100 episodes per epoch, resulting in 10,000 training episodes. In each episode, a 4-way k-shot support set and one query sample are drawn from the training split, following the procedure described in Section 3.2. The loss is binary cross-entropy with positive-sample reweighting, where the positive weight is set to w = 3.0 to reflect the ratio of negative to positive pairs in a 4-way episode. The proposed method is compared with conventional machine learning models, including XGBoost [26], LightGBM [27], Random Forest [28], Gradient Boosting [29], Extra Trees [30], SVM [31], Logistic Regression [32], and AdaBoost [33]; deep learning models, including LSTM [34], GRU [35], BiGRU [36], CNN-LSTM [37], and CNN-Transformer [38]; and representative few-shot learning baselines, including Siamese Network, Prototypical Networks, and Matching Network.

4.3. Evaluation Metrics

To comprehensively assess recognition performance, Precision (P), Recall (R), and F1-score are adopted as the primary evaluation metrics. These metrics collectively provide a balanced characterization of classification accuracy, sensitivity, and overall robustness under class-imbalanced or challenging classification conditions. In addition, confusion matrices are provided to visualize inter-class confusion patterns, particularly across varying shot settings.

4.4. Comparison Under Standard Dataset Settings

To assess the influence of different radar information sources under standard dataset settings, all methods are evaluated using PointTracks, Tracks, and the fusion of PointTracks and Tracks. As shown in Table 1, the proposed method achieves the best performance under all three input configurations. With PointTracks as input, the precision, recall, and F1-score reach 86.19%, 86.26%, and 85.62%, respectively, exceeding those of the strongest baseline, LightGBM, by 2.27, 2.85, and 2.25 percentage points. When only Tracks are used, the corresponding metrics increase to 88.01%, 87.88%, and 87.77%, indicating that trajectory-level motion information provides more stable and discriminative cues than point-level observations alone. The best overall results are obtained by combining PointTracks and Tracks, for which the precision, recall, and F1-score further rise to 90.85%, 90.47%, and 90.63%, respectively. Compared with LightGBM under the same fused-input setting, the improvements are 4.61, 4.41, and 4.61 percentage points. In addition, feature fusion increases the F1-score by 5.01 percentage points over PointTracks alone and by 2.86 percentage points over Tracks alone, confirming the complementarity between local scattering-related measurements and global trajectory characteristics. Conventional machine-learning methods generally outperform the standard deep-learning baselines, while several deep models exhibit relatively large fluctuations, suggesting greater susceptibility to overfitting on the limited radar dataset. The superior performance of the proposed method mainly benefits from physics-informed semantic prompting, which organizes heterogeneous radar variables according to their physical meanings, and adaptive feature aggregation, which emphasizes informative motion and scattering patterns while suppressing redundant or noisy observations.

4.5. Comparison with Few-Shot Learning Baselines

To evaluate recognition performance under limited labeled supervision, the proposed method is compared with the Siamese Network, Prototypical Network, and Matching Network under 1-, 3-, 5-, 10-, 15-, and 20-shot settings. As shown in Table 2, the proposed method consistently achieves the best results across all support sizes. Under the most challenging 1-shot setting, the precision, recall, and F1-score reach 78.51%, 78.36%, and 78.34%, respectively, exceeding those of the strongest baseline, the Matching Network, by 22.44, 20.83, and 21.85 percentage points. As the number of support samples increases, the performance of all methods generally improves, but the proposed method maintains a clear advantage. In the 5-shot setting, the F1-score reaches 85.82%, compared with 61.54% for the Matching Network and 61.35% for the Siamese Network. Under the 20-shot setting, the precision, recall, and F1-score further increase to 90.85%, 90.47%, and 90.63%, respectively, outperforming the Matching Network by 17.84, 17.99, and 18.22 percentage points. The relatively small standard deviations also indicate stable performance across repeated episodic sampling. This advantage mainly arises from the explicit incorporation of radar-domain physical semantics, which strengthens the representation of motion, scattering, and trajectory characteristics. Meanwhile, the adaptive aggregation module emphasizes informative hidden states and suppresses redundant observations, while the relation decision network learns a nonlinear query–support comparison function instead of relying on fixed distances or simple class prototypes. These findings show that the proposed framework remains effective in extremely low-data conditions and can continue to benefit from additional support samples across different few-shot regimes.

4.6. N-Way K-Shot Few-Shot Performance

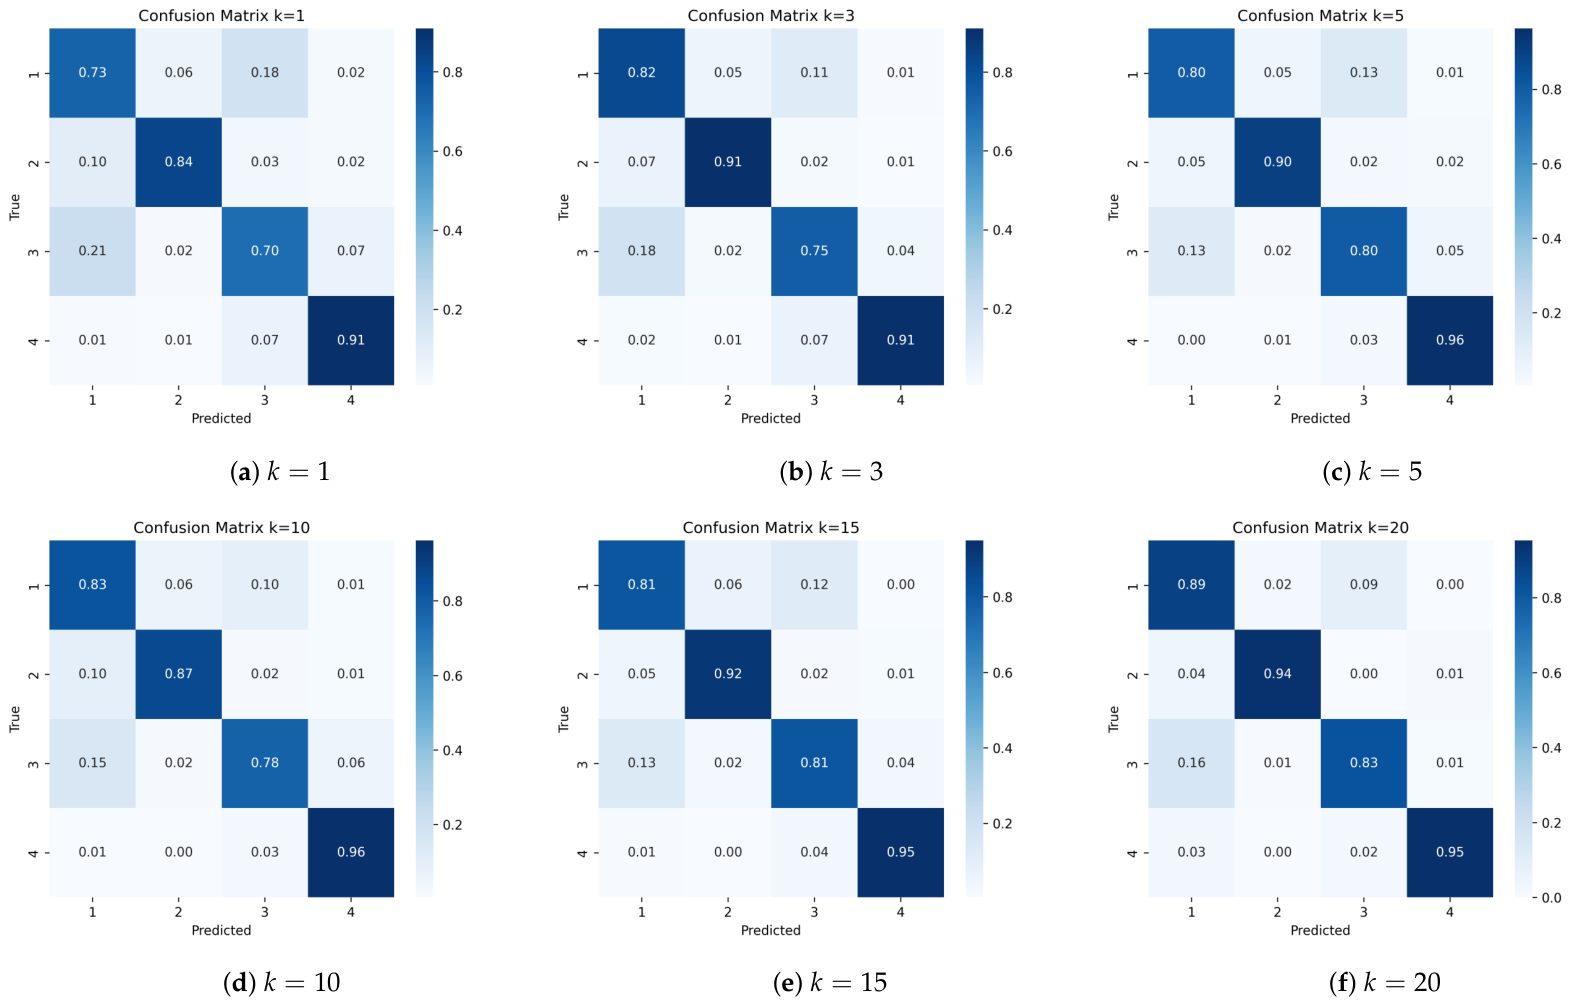
To investigate the influence of support-set size on recognition performance, all methods are evaluated under 4-way 1-, 3-, 5-, 10-, 15-, and 20-shot settings, with the quantitative results and class-level confusion patterns reported in Table 3 and Figure 6, respectively. The proposed method consistently achieves the highest precision, recall, and F1-score across all settings. Under the most challenging 1-shot condition, the precision, recall, and F1-score reach 78.51%, 78.36%, and 78.34%, respectively, whereas the best baseline F1-score is only 54.37%, obtained by ExtraTrees. As the number of support samples increases, the F1-score of the proposed method rises to 84.22%, 85.82%, 86.64%, 87.25%, and 90.63% under the 3-, 5-, 10-, 15-, and 20-shot settings, respectively. In the 20-shot setting, it still exceeds ExtraTrees by 11.15 percentage points in F1-score. Figure 6 further shows that the predictions become increasingly concentrated along the main diagonal as the support size grows, while off-diagonal errors gradually decrease. This indicates that additional support samples improve class separability and reduce confusion among targets with similar motion or scattering characteristics. The relatively small standard deviations also demonstrate stable performance across different random samplings. This advantage mainly arises because the physics-informed prompts explicitly organize radar measurements according to their physical meanings, enabling the semantic encoder to capture informative motion and scattering patterns even when labeled samples are scarce. The adaptive aggregation module further suppresses noisy or redundant information, while episodic relation learning establishes a transferable nonlinear comparison function between query and support samples. Therefore, the proposed method performs reliably under extremely limited supervision and effectively exploits additional support samples to improve recognition accuracy.

4.7. Ablation Study

To validate the contribution of each core component, ablation experiments are conducted on the physics-semantic prompting strategy (PPS) and the adaptive feature aggregation module (AFA). The results are presented in Table 4. Removing both modules produces the weakest performance. Introducing PPS alone raises the 1-shot F1-score from 46.12% to 74.53%, showing that explicit physical semantics are highly beneficial when only one labeled example is available. Adding AFA without PPS also improves performance, but the gain is smaller because the model still lacks domain-aware prompt information. The full model achieves the best results, reaching 79.31% F1-score in the 1-shot setting and maintaining the strongest performance at 3 and 5 shots. These results demonstrate that PPS and AFA are complementary: PPS enriches the input representation with radar-domain meaning, while AFA selects the most discriminative hidden states from the language-model encoder.
This framework employs GPT-2 Base as the text encoder. The model contains 12 Transformer blocks, a hidden dimension of 768, and approximately 124 million parameters. To adapt the pre-trained encoder to radar-domain prompts while controlling overfitting, a partial fine-tuning strategy is adopted: layers 0 to 6 are frozen, and layers 7 to 11 together with the downstream modules are updated. The maximum token length is set to 1024, and the GPT-2 end-of-sequence token is used as the padding token for variable-length prompts. To verify this choice, Table 5 compares a fully frozen encoder with two partial fine-tuning settings. The fully frozen strategy performs worst, confirming that task-specific adaptation is necessary. Fine-tuning layers 6–11 achieves the best overall performance, suggesting that updating higher Transformer layers provides sufficient domain adaptation while preserving useful general linguistic representations in the lower layers.
The physics-semantic prompt construction uses a temporal sliding window to segment each radar point-track sequence into overlapping subsequences. To determine the window size, a sensitivity analysis is performed with W { 3 , 4 , 5 , 6 , 7 } while keeping all other settings fixed. As shown in Table 6, performance improves as W increases from 3 to 5 because larger windows capture more complete local motion context [7]. When W 6 , performance begins to decline, likely because longer windows introduce redundant or weakly related temporal information and increase prompt length toward the 1024-token limit. Therefore, W = 5 is adopted as the best balance between temporal coverage and prompt compactness.

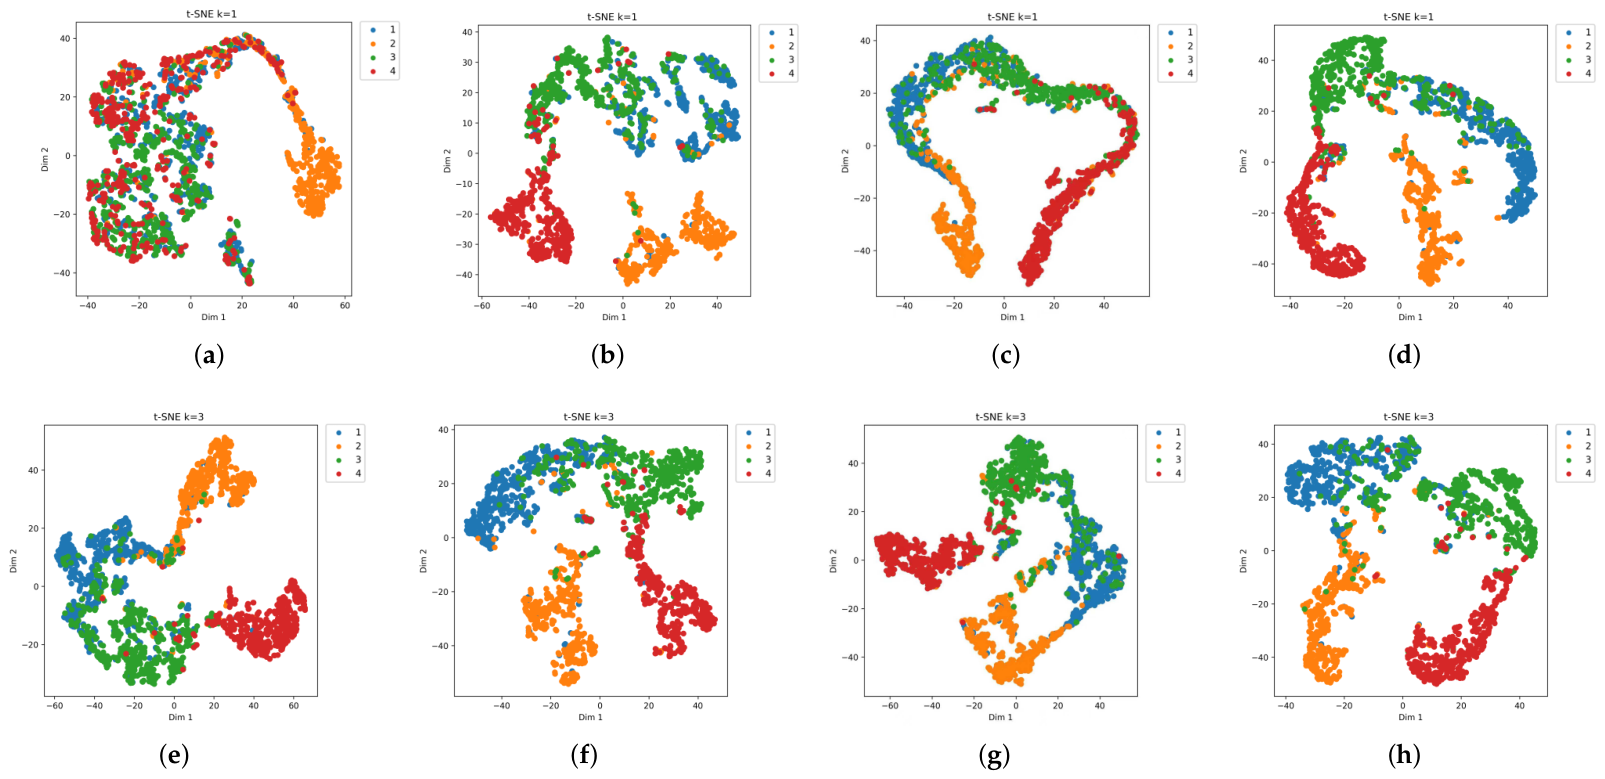
4.8. Visualization Analysis

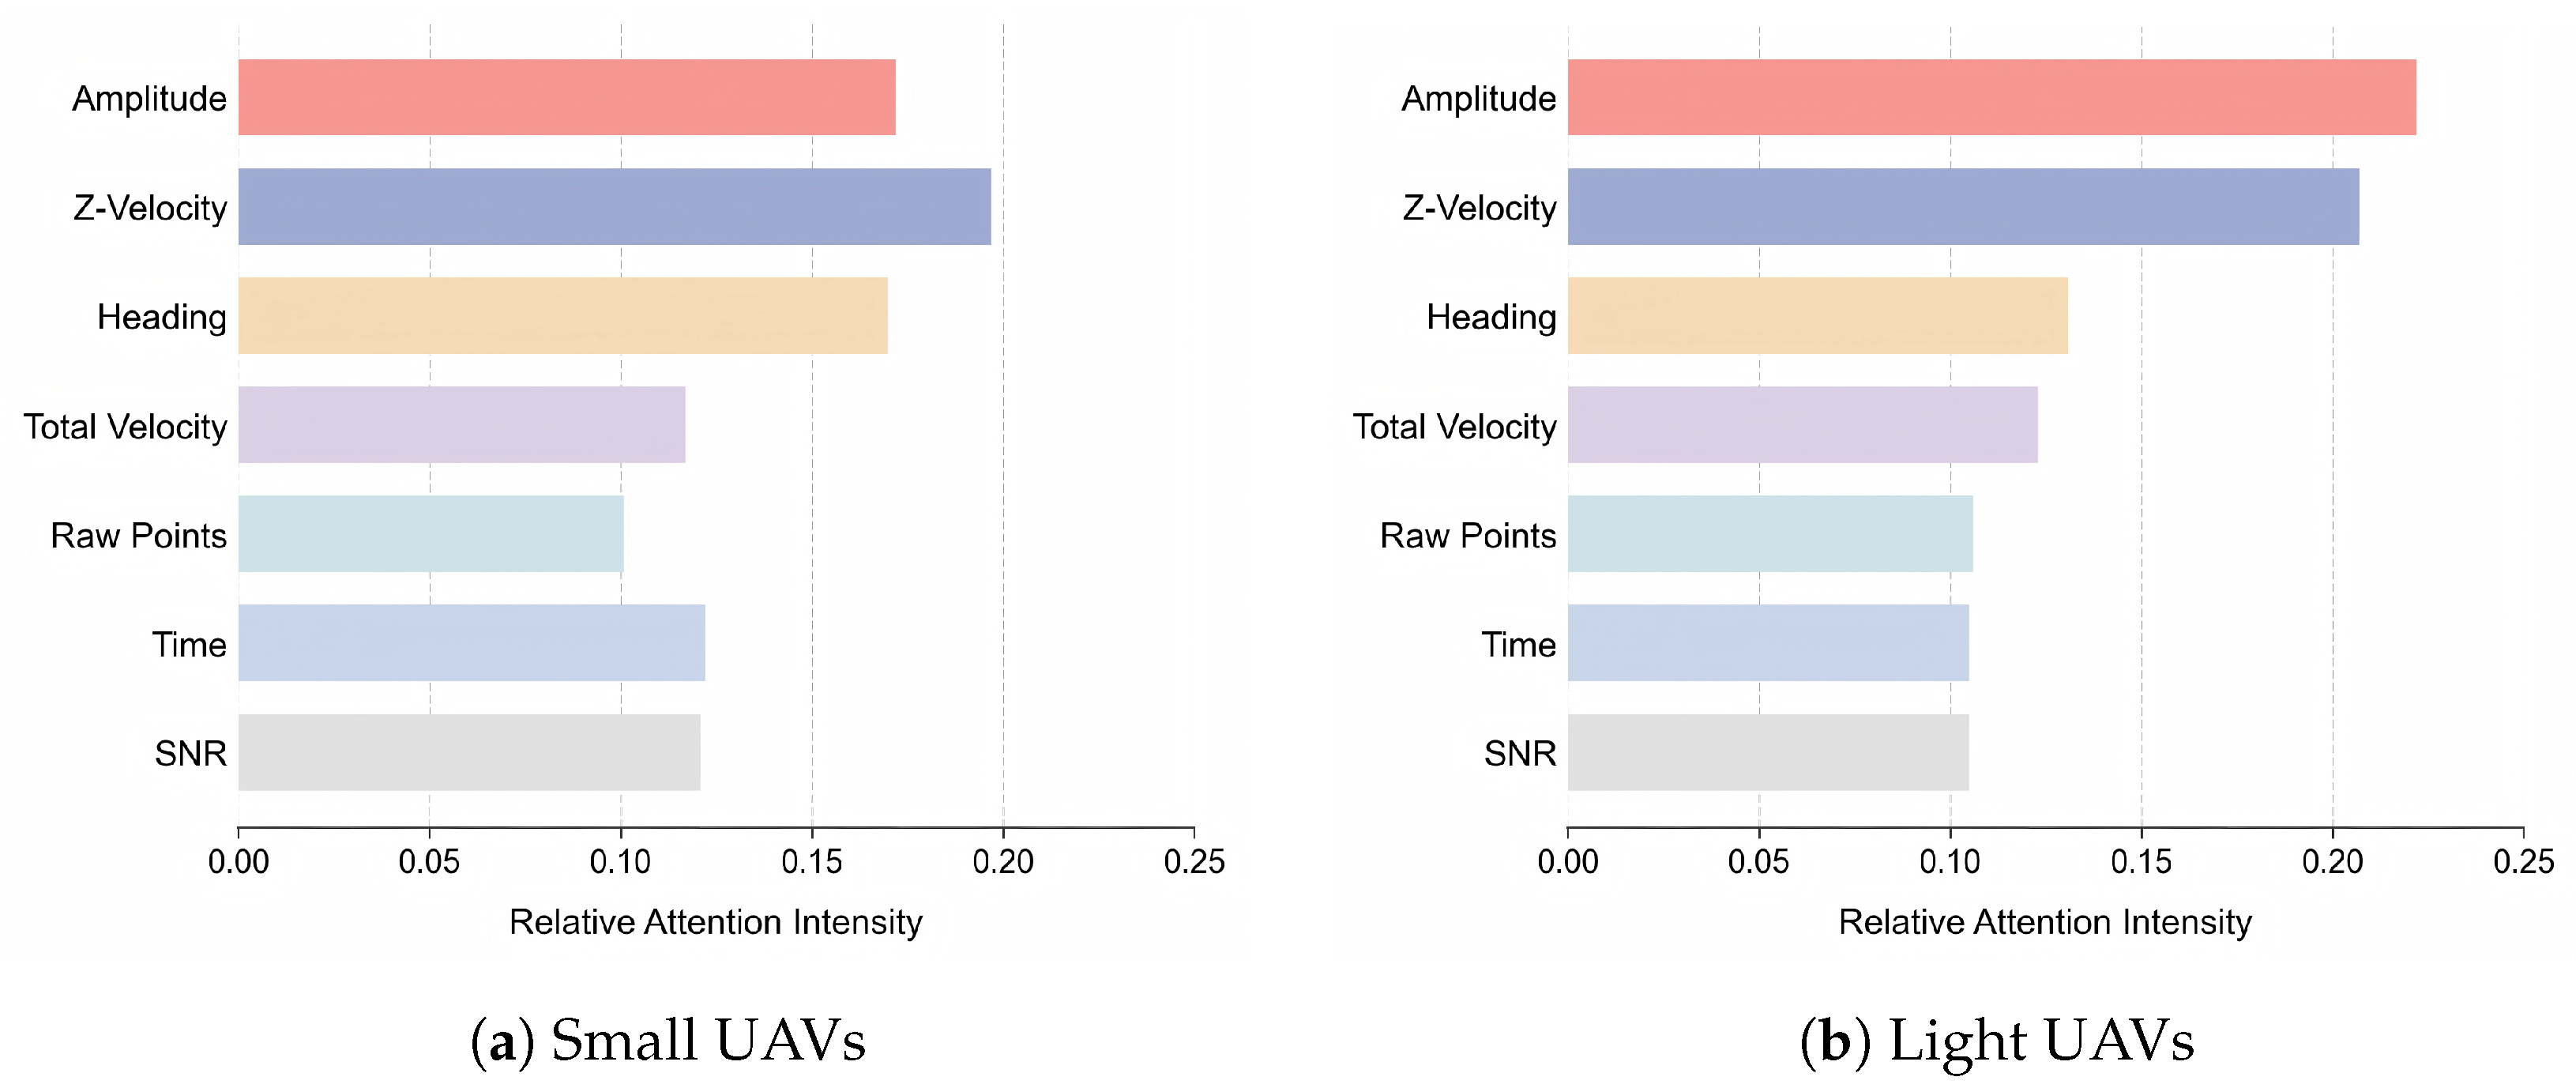
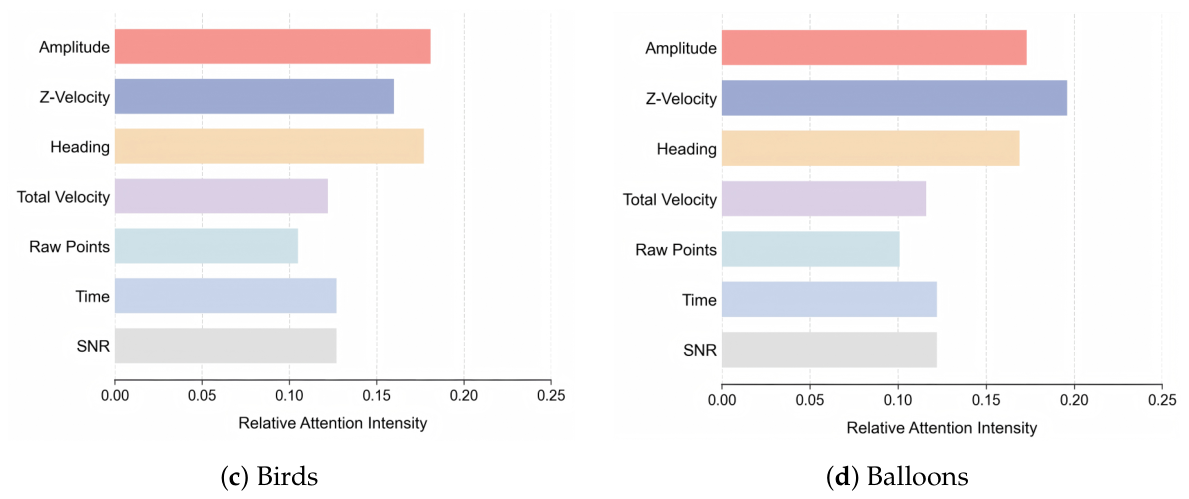
To evaluate interpretability, t-SNE plots are used to compare feature distributions before and after module integration, as shown in Figure 7. The visualizations indicate that the combination of PPS and AFA produces more compact intra-class clusters and clearer inter-class separation than the incomplete configurations. PPS improves clustering by converting radar measurements into domain-aware semantic descriptions, while AFA further separates categories by emphasizing discriminative hidden states. The category-level AFA visualization in Figure 8 shows that the model assigns different importance to features such as amplitude, vertical velocity, and heading variation. This behavior is physically meaningful: UAVs often exhibit stronger and more stable radar returns from rigid structures, as well as more regular vertical and heading changes; birds show irregular motion related to flapping and maneuvering; and balloons tend to follow smoother wind-driven trajectories. These observations are consistent with the quantitative improvements reported in the ablation study.

5. Discussion

The experimental results demonstrate that physics-informed semantic prompt learning is effective for few-shot low-altitude radar target recognition. In Table 4, adding PPS alone improves the 1-shot F1-score from 46.12% to 74.53%, which confirms that radar-domain semantic descriptions help the model interpret numerical measurements when supervision is extremely limited. The full model further improves the 1-shot F1-score to 79.31%, showing that adaptive aggregation provides additional benefit by selecting informative hidden states from the GPT-2 encoder.
The comparison experiments also clarify the role of different data sources. Table 1 shows that fusing point-track and track features produces the best result. Point-track data retain detection-level information such as amplitude, SNR, Doppler velocity, and raw point count, while track data provide smoothed kinematic information such as total velocity, vertical velocity, and heading. Their fusion gives the prompt a richer physical description of target behavior. This is important for distinguishing lightweight UAVs, small UAVs, birds, and balloons, because some classes overlap in a single feature dimension but differ when motion stability, vertical movement, and echo strength are considered together.
The confusion matrices in Figure 6 indicate that the model maintains balanced performance across the four classes, but some confusion remains between lightweight and small UAVs. This is expected because both are rotary-wing targets with similar radar cross-section ranges and maneuvering patterns. In contrast, birds and balloons are easier to separate from UAVs because their motion mechanisms are different: birds show more irregular velocity and heading fluctuations, while balloons usually move smoothly under wind influence. The visualization results in Figure 7 and Figure 8 support this interpretation by showing improved feature separation and physically meaningful feature weighting.
Several limitations should be noted. First, the current framework mainly uses point-track and track-level features; raw echo signatures and micro-Doppler information are not yet incorporated. These signal-level cues may further improve recognition, especially for targets with similar trajectories. Second, GPT-2 Base may be larger than necessary for this task, and lightweight encoders should be explored for real-time deployment. Third, the experiments are conducted on one measured dataset, so cross-platform and cross-scene generalization should be evaluated in future work.

6. Conclusions

This paper presents a physics-informed semantic prompt learning framework for few-shot low-altitude radar target recognition. The method converts radar point-track and track measurements into structured prompts, extracts semantic representations with a partially fine-tuned GPT-2 encoder, aggregates informative hidden states through an adaptive feature aggregation module, and performs classification with a relation-based meta-learning network. Without changing the few-shot task setting, the framework incorporates radar physical knowledge directly into the input representation and learns a transferable query-support comparison mechanism.
Experiments on a real four-class low-altitude radar dataset show that the proposed method outperforms conventional machine learning models, deep learning models, and representative few-shot baselines. Under the 20-shot setting, the model reaches average Precision, Recall, and F1-scores of 90.85%, 90.47%, and 90.63%, respectively. Ablation and visualization analyses further confirm that physics-semantic prompting and adaptive aggregation both contribute to improved recognition performance, especially when labeled samples are scarce. Future work will extend the framework to more target categories and more diverse sensing scenes, incorporate raw echo and micro-Doppler information, evaluate cross-platform generalization, and investigate lightweight deployment for practical low-altitude radar systems.

Author Contributions

Conceptualization, J.T. (Jihui Tu); methodology, J.T. (Jihui Tu); experimental design and manuscript revision guidance, J.T. (Jihui Tu) and W.F.; validation, J.T. (Junrong Tu) and Z.L.; formal analysis, J.T. (Junrong Tu); investigation, J.T. (Junrong Tu) and Z.L.; data curation, J.T. (Junrong Tu) and Z.L.; writing—original draft preparation, J.T. (Junrong Tu) and J.T. (Jihui Tu); writing—review and editing, J.T. (Jihui Tu); visualization, J.T. (Junrong Tu) and Z.L.; supervision, J.T. (Jihui Tu) and W.F.; project administration, J.T. (Jihui Tu). All authors have read and agreed to the published version of the manuscript.

Funding

This research was supported by the Open Fund Program of Yunnan Key Laboratory of Intelligent Monitoring and Spatiotemporal Big Data Governance of Natural Resources (202449CE340023), and the 2024 Annual Open Fund of the Collaborative Application Technology Innovation Center for Remote Sensing Mapping in the South China Sea of the Ministry of Natural Resources (RSSMCA-2024-B011).

Data Availability Statement

Due to the confidentiality requirements imposed by the data provider, the data generated or analyzed during this study are not publicly available.

Conflicts of Interest

The authors declare no conflict of interest.

References

  1. Tang, J. Can Low Altitude Economy Development Bring Economic and Environmental Dividends?—Evidence from Chinese Cities. J. Air Transp. Manag. 2026, 131, 102919. [Google Scholar] [CrossRef] [Scilit]
  2. Tang, Z.; Ma, H.; Qu, Y.; Mao, X. UAV Detection with Passive Radar: Algorithms, Applications, and Challenges. Drones 2025, 9, 76. [Google Scholar] [CrossRef] [Scilit]
  3. Zhao, X.; Lv, X.; Cai, J.; Guo, J.; Zhang, Y.; Qiu, X.; Wu, Y. Few-Shot SAR-ATR Based on Instance-Aware Transformer. Remote Sens. 2022, 14, 1884. [Google Scholar] [CrossRef] [Scilit]
  4. Zhang, T.; Song, X. A Classification Algorithm of UAV and Bird Target Based on L/K Dual-Band Micro-Doppler and Mamba. Drones 2026, 10, 265. [Google Scholar] [CrossRef] [Scilit]
  5. Liu, J.; Huang, P.; Zeng, C.; Liao, G.; Xu, J.; Tao, H.; Juwono, F.H. Light Gradient Boosting Machine-Based Low–Slow–Small Target Detection Algorithm for Airborne Radar. Remote Sens. 2024, 16, 1737. [Google Scholar] [CrossRef] [Scilit]
  6. Yin, J.; Duan, C.; Wang, H.; Yang, J. A Review on the Few-Shot SAR Target Recognition. IEEE J. Sel. Top. Appl. Earth Obs. Remote Sens. 2024, 17, 16411–16425. [Google Scholar] [CrossRef] [Scilit]
  7. Zhou, X.; Gao, X.; Liu, S.; Han, J.; Su, X.; Zhang, J. Structural Attributes Injection Is Better: Exploring General Approach for Radar Image ATR with a Attribute Alignment Adapter. Remote Sens. 2024, 16, 4743. [Google Scholar] [CrossRef] [Scilit]
  8. Xia, D.; Lv, L.; Zhang, Y.; Lu, Y.; Li, F.; Liu, L.; Liu, X.; Zeng, Y.; Ge, Z. Physics-Guided Variational Causal Intervention Network for Few-Shot Radar Jamming Recognition. Sensors 2026, 26, 1900. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  9. Wang, Y.; Sun, T.; Cheng, L.; Xu, S. Physics-Informed Semantic Feature Fusion for Low-Altitude Drone Detection: A Domain-Knowledge-Driven Approach. Drones 2026, 10, 156. [Google Scholar] [CrossRef] [Scilit]
  10. Zhang, L.; Liu, M.; Wu, Q.; Zhao, J. Relation-Based Meta-Learning for Few-Shot Radar Target Recognition in Complex Environments. Sensors 2024, 24, 1215. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  11. Jiang, W.; Wang, Y.; Li, Y.; Lin, Y.; Shen, W. Radar Target Characterization and Deep Learning in Radar Automatic Target Recognition: A Review. Remote Sens. 2023, 15, 3742. [Google Scholar] [CrossRef] [Scilit]
  12. Chen, L.; Pan, Z.; Liu, Q.; Hu, P. HRRPGraphNet++: Dynamic Graph Neural Network with Meta-Learning for Few-Shot HRRP Radar Target Recognition. Remote Sens. 2025, 17, 2108. [Google Scholar] [CrossRef] [Scilit]
  13. Li, W.; Yang, W.; Liu, T.; Hou, Y.; Li, Y.; Liu, Z.; Liu, Y.; Liu, L. Predicting Gradient is Better: Exploring Self-Supervised Learning for SAR ATR with a Joint-Embedding Predictive Architecture. arXiv 2024, arXiv:2311.15153. [Google Scholar]
  14. Vinyals, O.; Blundell, C.; Lillicrap, T.; Kavukcuoglu, K.; Wierstra, D. Matching networks for one shot learning. In Proceedings of the 30th International Conference on Neural Information Processing Systems (NeurIPS), Barcelona, Spain, 5–10 December 2016; pp. 3630–3638. Available online: https://proceedings.neurips.cc/paper/2016/hash/90e1357833654983612fb05e3ec9148c-Abstract.html (accessed on 7 July 2026).
  15. Snell, J.; Swersky, K.; Zemel, R. Prototypical networks for few-shot learning. In Proceedings of the 31st International Conference on Neural Information Processing Systems (NIPS), Long Beach, CA, USA, 4–9 December 2017; pp. 4080–4090. Available online: https://papers.nips.cc/paper/6996-prototypical-networks-for-few-shot-learning (accessed on 7 July 2026).
  16. Koch, G.; Zemel, R.; Salakhutdinov, R. Siamese Neural Networks for One-Shot Image Recognition. In Proceedings of the 32nd International Conference on Machine Learning (ICML) Deep Learning Workshop, Lille, France, 6–11 July 2015; Volume 2. Available online: https://www.cs.cmu.edu/~rsalakhu/papers/oneshot1.pdf (accessed on 7 July 2026).
  17. Finn, C.; Abbeel, P.; Levine, S. Model-agnostic meta-learning for fast adaptation of deep networks. In Proceedings of the 34th International Conference on Machine Learning (ICML), Sydney, Australia, 6–11 August 2017; pp. 1126–1135. Available online: https://proceedings.mlr.press/v70/finn17a.html (accessed on 7 July 2026).
  18. Sung, F.; Yang, Y.; Zhang, L.; Xiang, T.; Torr, P.H.; Hospedales, T.M. Learning to compare: Relation network for few-shot learning. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR), Salt Lake City, UT, USA, 18–23 June 2018; pp. 1199–1208. [Google Scholar] [CrossRef] [Scilit]
  19. Petrov, M.; Pandilova, E.; Dimitrovski, I.; Trajanov, D.; Spasev, V.; Kitanovski, I. Few-Shot Semantic Segmentation in Remote Sensing: A Review on Definitions, Methods, Datasets, Advances and Future Trends. Remote Sens. 2026, 18, 637. [Google Scholar] [CrossRef] [Scilit]
  20. Rostami, M.; Kolouri, S.; Eaton, E.; Kim, K. Deep Transfer Learning for Few-Shot SAR Image Classification. Remote Sens. 2019, 11, 1374. [Google Scholar] [CrossRef] [Scilit]
  21. Brown, T.; Mann, B.; Ryder, N.; Subbiah, M.; Kaplan, J.D.; Dhariwal, P.; Neelakantan, A.; Shyam, P.; Sastry, G.; Askell, A.; et al. Language models are few-shot learners. In Proceedings of the 34th International Conference on Neural Information Processing Systems (NeurIPS), Online, 6–12 December 2020; pp. 1877–1901. Available online: https://proceedings.neurips.cc/paper/2020/file/1457c0d6bfcb4967418bfb8ac142f64a-Paper.pdf (accessed on 7 July 2026).
  22. Liu, P.; Yuan, W.; Fu, J.; Jiang, Z.; Hayashi, H.; Neubig, G. Pre-train, prompt, and predict: A systematic survey of prompting methods in natural language processing. ACM Comput. Surv. 2023, 55, 1–35. [Google Scholar] [CrossRef] [Scilit]
  23. Jin, M.; Wang, S.; Ma, L.; Chu, Z.; Zhang, J.Y.; Wang, X.; Zhou, K.; Sun, Y.; Chen, H.; Li, Y.; et al. Time-LLM: Time series forecasting by reprogramming large language models with text prototypes. In Proceedings of the International Conference on Learning Representations (ICLR), Vienna, Austria, 7–11 May 2024; Available online: https://openreview.net/forum?id=9YfU5987Vp (accessed on 7 July 2026).
  24. Chang, C.; Peng, W.C.; Chen, T.F. LLM4TS: Two-stage fine-tuning for time-series forecasting with pre-trained LLMs. arXiv 2023, arXiv:2308.08469. [Google Scholar] [CrossRef] [Scilit]
  25. Zhang, W.; Cai, M.; Zhang, T.; Zhuang, Y.; Mao, X. EarthGPT: A Universal Multimodal Large Language Model for Multisensor Image Comprehension in Remote Sensing Domain. IEEE Trans. Geosci. Remote Sens. 2024, 62, 5917820. [Google Scholar] [CrossRef] [Scilit]
  26. Chen, T.; Guestrin, C. XGBoost: A Scalable Tree Boosting System. In Proceedings of the 22nd ACM SIGKDD International Conference on Knowledge Discovery and Data Mining, San Francisco, CA, USA, 13–17 August 2016; pp. 785–794. [Google Scholar] [CrossRef] [Scilit]
  27. Ke, G.; Meng, Q.; Finley, T.; Wang, T.; Chen, W.; Ma, W.; Ye, Q.; Liu, T.Y. LightGBM: A Highly Efficient Gradient Boosting Decision Tree. In Proceedings of the 31st International Conference on Neural Information Processing Systems (NIPS), Long Beach, CA, USA, 4–9 December 2017; pp. 3149–3157. [Google Scholar]
  28. Breiman, L. Random Forests. Mach. Learn. 2001, 45, 5–32. [Google Scholar] [CrossRef] [Scilit]
  29. Friedman, J.H. Greedy Function Approximation: A Gradient Boosting Machine. Ann. Stat. 2001, 29, 1189–1232. [Google Scholar] [CrossRef] [Scilit]
  30. Geurts, P.; Ernst, D.; Wehenkel, L. Extremely Randomized Trees. Mach. Learn. 2006, 63, 3–42. [Google Scholar] [CrossRef] [Scilit]
  31. Cortes, C.; Vapnik, V. Support-Vector Networks. Mach. Learn. 1995, 20, 273–297. [Google Scholar] [CrossRef] [Scilit]
  32. Cox, D.R. The Regression Analysis of Binary Sequences. J. R. Stat. Soc. Ser. B (Methodol.) 1958, 20, 215–242. [Google Scholar] [CrossRef] [Scilit]
  33. Freund, Y.; Schapire, R.E. A Decision-Theoretic Generalization of On-Line Learning and an Application to Boosting. J. Comput. Syst. Sci. 1997, 55, 119–139. [Google Scholar] [CrossRef] [Scilit]
  34. Hochreiter, S.; Schmidhuber, J. Long Short-Term Memory. Neural Comput. 1997, 9, 1735–1780. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  35. Cho, K.; Van Merriënboer, B.; Gulcehre, C.; Bahdanau, D.; Bougares, F.; Schwenk, H.; Bengio, Y. Learning Phrase Representations using RNN Encoder–Decoder for Statistical Machine Translation. In Proceedings of the 2014 Conference on Empirical Methods in Natural Language Processing (EMNLP), Doha, Qatar, 25–29 October 2014; pp. 1724–1734. [Google Scholar] [CrossRef] [Scilit]
  36. Schuster, M.; Paliwal, K.K. Bidirectional Recurrent Neural Networks. IEEE Trans. Signal Process. 1997, 45, 2673–2681. [Google Scholar] [CrossRef] [Scilit]
  37. Donahue, J.; Anne Hendricks, L.; Guadarrama, S.; Rohrbach, M.; Venugopalan, S.; Saenko, K.; Darrell, T. Long-Term Recurrent Convolutional Networks for Visual Recognition and Description. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR), Boston, MA, USA, 7–12 June 2015; pp. 2625–2634. [Google Scholar] [CrossRef] [Scilit]
  38. Gulati, A.; Qin, J.; Chiu, C.C.; Parmar, N.; Zhang, Y.; Yu, J.; Han, W.; Wang, S.; Zhang, Z.; Wu, Y.; et al. Conformer: Convolution-Augmented Transformer for Speech Recognition. In Proceedings of the 21st Annual Conference of the International Speech Communication Association (Interspeech), Shanghai, China, 25–29 October 2020; pp. 5036–5040. [Google Scholar] [CrossRef] [Scilit]
Figure 1. Overall framework of the proposed physics-semantic prompt learning method for few-shot low-altitude radar target recognition.
Remotesensing 18 02316 g001
Figure 2. Illustration of physics-semantic prompt construction. Radar point-track and track features are transformed into structured text prompts containing three components: Domain knowledge, Statistical descriptions, and Task Instructions.
Remotesensing 18 02316 g002
Figure 3. Architecture of the adaptive feature aggregation module. Multi-layer hidden states from GPT-2 are dynamically weighted through learnable attention vectors to produce discriminative task-relevant embeddings.
Remotesensing 18 02316 g003
Figure 4. Architecture of the relation decision network. The triplet relation feature combines query embedding, support embedding, and their difference for similarity modeling.
Remotesensing 18 02316 g004
Figure 5. Data processing pipeline.
Remotesensing 18 02316 g005
Figure 6. Confusion matrices of the proposed method under different shot settings with seed 42. All values are rounded to two decimal places.
Remotesensing 18 02316 g006
Figure 7. t-SNE visualization of feature distributions under different configurations: (ad) k = 1 , including (a) without PPS and AFA, (b) with PPS but without AFA, (c) with AFA but without PPS, and (d) with both PPS and AFA; (eh) k = 3 , with the same configuration order.
Remotesensing 18 02316 g007
Figure 8. AFA visualization for different target categories. The model learns to focus on different feature dimensions for different target types.
Remotesensing 18 02316 g008aRemotesensing 18 02316 g008b
Table 1. Performance comparison of different baseline methods under three input configurations. The results of our proposed method are averaged over different random seeds under the 20-shot setting for each input configuration.
MethodsMetricsPointTracksTracksPointTracks + Tracks
XGBoost [26]Precision 82.05 ± 0.09 85.12 ± 0.08 85.29 ± 0.16
Recall 81.48 ± 0.10 84.92 ± 0.08 84.99 ± 0.17
F1-score 81.44 ± 0.11 84.89 ± 0.08 84.93 ± 0.16
LightGBM [27]Precision 83.92 ± 0.16 85.92 ± 0.15 86.24 ± 0.10
Recall 83.41 ± 0.16 85.62 ± 0.15 86.06 ± 0.10
F1-score 83.37 ± 0.16 85.58 ± 0.15 86.02 ± 0.10
RandomForest [28]       Precision 82.39 ± 0.08 83.91 ± 0.15 84.14 ± 0.05
Recall 81.78 ± 0.07 83.64 ± 0.18 83.53 ± 0.05
F1-score 81.61 ± 0.07 83.54 ± 0.18 83.43 ± 0.06
GradientBoosting [29]Precision 78.72 ± 0.17 81.62 ± 0.13 82.00 ± 0.24
Recall 77.42 ± 0.03 81.24 ± 0.08 81.50 ± 0.17
F1-score 77.25 ± 0.04 81.14 ± 0.08 81.36 ± 0.17
ExtraTrees [30]Precision 82.07 ± 0.18 84.00 ± 0.14 84.79 ± 0.16
Recall 81.64 ± 0.17 83.45 ± 0.15 84.55 ± 0.19
F1-score 81.46 ± 0.17 83.31 ± 0.15 84.46 ± 0.19
SVM [31]Precision 80.06 ± 0.14 81.83 ± 0.20 83.60 ± 0.36
Recall 78.87 ± 0.14 81.30 ± 0.18 83.17 ± 0.43
F1-score 78.67 ± 0.19 81.27 ± 0.16 83.12 ± 0.40
LogisticRegression [32]Precision 76.46 ± 0.08 80.51 ± 0.05 82.70 ± 0.02
Recall 76.59 ± 0.08 80.40 ± 0.04 82.70 ± 0.02
F1-score 76.43 ± 0.08 80.40 ± 0.04 82.66 ± 0.02
AdaBoost [33]Precision 75.88 ± 0.42 80.59 ± 0.25 80.82 ± 0.47
Recall 75.32 ± 0.34 80.31 ± 0.32 80.52 ± 0.42
F1-score 75.14 ± 0.13 80.27 ± 0.28 80.52 ± 0.38
LSTM [34]Precision 49.20 ± 5.91 66.18 ± 4.52 77.57 ± 2.89
Recall 48.98 ± 4.82 64.61 ± 4.70 76.44 ± 3.14
F1-score 47.11 ± 5.90 64.21 ± 4.84 76.22 ± 3.11
GRU [35]Precision 46.65 ± 3.31 66.57 ± 0.93 77.53 ± 4.01
Recall 46.84 ± 2.06 62.71 ± 3.08 76.77 ± 4.00
F1-score 44.57 ± 5.80 62.55 ± 2.97 76.65 ± 4.00
BiGRU [36]Precision 48.28 ± 3.36 65.92 ± 3.10 78.11 ± 3.90
Recall 47.09 ± 3.09 64.76 ± 2.79 77.43 ± 3.79
F1-score 46.62 ± 3.06 64.51 ± 2.61 77.34 ± 3.84
CNN_LSTM [37]Precision 45.49 ± 5.66 67.71 ± 3.59 76.93 ± 2.56
Recall 44.46 ± 5.15 67.38 ± 3.60 75.77 ± 2.75
F1-score 43.64 ± 5.29 67.01 ± 3.80 75.84 ± 2.68
CNN_Transformer [38]Precision 51.47 ± 4.62 65.33 ± 3.22 74.26 ± 2.35
Recall 51.59 ± 4.54 58.43 ± 3.01 73.71 ± 2.23
F1-score 50.20 ± 5.16 57.24 ± 3.10 73.68 ± 2.29
Proposed methodPrecision 86.19 ± 0.10 88.01 ± 0.03 90.85 ± 0.11
Recall 86.26 ± 0.08 87.88 ± 0.06 90.47 ± 0.36
F1-score 85.62 ± 0.14 87.77 ± 0.06 90.63 ± 0.25
Table 2. Comparison results under different shot settings (1, 3, 5, 10, 15, 20). The results of our proposed method are averaged over different random seeds.
FL BaselinesMetricsShot = 1Shot = 3Shot = 5Shot = 10Shot = 15Shot = 20
Siamese network [16]Precision51.94 ± 0.7856.08 ± 0.3061.12 ± 0.7362.78 ± 0.1663.67 ± 0.2864.60 ± 0.30
Recall52.79 ± 0.5057.11 ± 0.1861.74 ± 0.6663.21 ± 0.1164.24 ± 0.3465.06 ± 0.41
F1-score52.22 ± 0.6556.45 ± 0.2161.35 ± 0.6962.95 ± 0.0963.91 ± 0.3064.81 ± 0.35
Prototypical network [15]Precision42.44 ± 1.1844.22 ± 0.8844.78 ± 0.4245.95 ± 0.1446.63 ± 0.1647.67 ± 0.32
Recall30.51 ± 0.9932.91 ± 2.0235.58 ± 1.1137.20 ± 0.3238.71 ± 0.8837.92 ± 0.30
F1-score35.24 ± 1.0137.40 ± 1.6639.44 ± 0.8640.81 ± 0.2442.12 ± 0.6141.94 ± 0.23
Matching network [14]Precision56.07 ± 0.0758.63 ± 0.3361.55 ± 0.7465.60 ± 1.0069.43 ± 0.6373.01 ± 0.49
Recall57.53 ± 0.3959.04 ± 1.1762.02 ± 0.7764.29 ± 2.9470.39 ± 0.6472.48 ± 0.79
F1-score56.49 ± 0.1658.65 ± 0.7061.54 ± 0.3664.61 ± 2.1769.14 ± 1.0372.41 ± 0.42
Proposed methodPrecision78.51 ± 0.7884.26 ± 0.9985.79 ± 0.6386.57 ± 0.3387.25 ± 0.2890.85 ± 0.11
Recall78.36 ± 0.8384.31 ± 0.5985.91 ± 0.8186.75 ± 0.3887.32 ± 0.1390.47 ± 0.36
F1-score78.34 ± 0.8484.22 ± 0.8485.82 ± 0.7286.64 ± 0.3587.25 ± 0.1590.63 ± 0.25
Table 3. Comparison results under different shot settings (1, 3, 5, 10, 15, 20). The results of our proposed method are averaged over different random seeds.
MethodMetricShot = 1Shot = 3Shot = 5Shot = 10Shot = 15Shot = 20
XGBoost [26]Precision7.59 ± 0.0056.29 ± 9.4562.66 ± 8.7469.27 ± 4.7171.87 ± 4.0474.84 ± 2.24
Recall27.55 ± 0.0054.34 ± 7.8760.84 ± 7.7568.90 ± 4.3571.90 ± 3.9374.69 ± 2.00
F1-score11.90 ± 0.0053.42 ± 8.4660.32 ± 8.0468.68 ± 4.5171.74 ± 3.9974.54 ± 2.13
LightGBM [27]Precision30.41 ± 13.3957.05 ± 6.7264.87 ± 5.1967.43 ± 3.9771.80 ± 4.8174.87 ± 1.91
Recall39.43 ± 8.8156.13 ± 6.3664.10 ± 5.0766.72 ± 3.9171.51 ± 4.7174.45 ± 2.26
F1-score32.65 ± 10.7255.62 ± 6.6863.46 ± 5.6166.60 ± 4.0771.40 ± 4.8674.43 ± 2.22
RandomForest [28]Precision54.98 ± 6.2962.57 ± 5.0569.16 ± 5.4572.75 ± 2.8376.47 ± 1.5978.15 ± 1.00
Recall50.87 ± 5.1961.00 ± 5.2568.51 ± 5.7772.42 ± 2.9876.37 ± 1.5477.84 ± 1.05
F1-score49.00 ± 5.6660.25 ± 5.4868.37 ± 5.7272.39 ± 2.8576.29 ± 1.6177.78 ± 1.08
GradientBoosting [29]Precision51.69 ± 7.5955.88 ± 8.5360.68 ± 10.5868.80 ± 3.6771.44 ± 4.3976.00 ± 1.28
Recall47.58 ± 6.4854.51 ± 7.4658.64 ± 9.7968.03 ± 3.5470.96 ± 4.3675.28 ± 1.72
F1-score45.03 ± 6.3653.38 ± 6.9958.37 ± 10.0868.04 ± 3.5771.01 ± 4.4275.44 ± 1.60
ExtraTrees [30]Precision59.33 ± 7.3664.42 ± 7.0369.20 ± 6.1575.89 ± 2.4678.00 ± 1.8579.66 ± 1.59
Recall56.07 ± 4.5263.60 ± 6.4268.76 ± 6.4275.69 ± 2.4978.00 ± 1.6979.62 ± 1.45
F1-score54.37 ± 5.7262.59 ± 7.2368.26 ± 6.6775.57 ± 2.5277.88 ± 1.8379.48 ± 1.56
SVM [31]Precision56.13 ± 7.2255.58 ± 6.0660.93 ± 3.1063.10 ± 10.1669.87 ± 5.8873.13 ± 3.84
Recall46.14 ± 5.9954.22 ± 5.0658.80 ± 5.5462.38 ± 10.0568.58 ± 6.2571.74 ± 3.47
F1-score43.95 ± 7.0050.81 ± 7.3256.76 ± 5.8760.94 ± 10.8667.88 ± 6.6171.19 ± 3.52
LogisticRegression [32]Precision54.37 ± 7.8856.87 ± 6.5660.05 ± 5.8963.94 ± 7.0467.86 ± 5.8970.93 ± 4.82
Recall45.77 ± 7.4755.42 ± 5.5559.44 ± 5.6863.88 ± 5.7867.65 ± 5.4970.51 ± 4.01
F1-score43.37 ± 8.5053.88 ± 6.1958.11 ± 6.0862.85 ± 6.6266.83 ± 5.9869.92 ± 4.38
AdaBoost [33]Precision38.36 ± 7.5752.23 ± 9.5156.15 ± 5.8964.86 ± 4.4769.75 ± 3.5374.65 ± 2.37
Recall34.18 ± 5.4450.56 ± 9.2055.18 ± 5.0562.89 ± 4.6968.83 ± 3.6174.13 ± 2.41
F1-score30.48 ± 6.3250.27 ± 9.0154.88 ± 5.6262.79 ± 4.5069.00 ± 3.6674.22 ± 2.39
LSTM [34]Precision58.93 ± 4.1662.05 ± 7.5663.46 ± 4.2865.89 ± 5.4472.25 ± 2.8874.87 ± 3.24
Recall52.35 ± 4.8559.10 ± 5.9060.76 ± 5.1364.09 ± 5.0970.93 ± 2.6573.35 ± 3.13
F1-score50.93 ± 5.6158.82 ± 5.9760.41 ± 5.1263.03 ± 6.4170.68 ± 2.8173.38 ± 3.23
GRU [35]Precision59.73 ± 5.1060.48 ± 2.9866.18 ± 4.5269.57 ± 4.2969.88 ± 3.3172.24 ± 2.40
Recall51.78 ± 5.3758.53 ± 2.8664.61 ± 4.7068.60 ± 4.1869.07 ± 2.9771.35 ± 2.95
F1-score50.81 ± 5.2257.70 ± 2.4464.21 ± 4.8468.34 ± 4.4068.79 ± 2.9971.18 ± 3.17
BiGRU [36]Precision55.34 ± 3.3357.85 ± 4.8164.81 ± 3.6169.85 ± 4.0573.00 ± 2.6273.67 ± 1.61
Recall47.08 ± 5.7854.96 ± 5.4562.85 ± 4.1568.79 ± 4.1672.64 ± 2.6073.11 ± 1.76
F1-score45.93 ± 5.8754.10 ± 5.2262.71 ± 3.8668.70 ± 4.2472.65 ± 2.6172.97 ± 1.82
CNN-LSTM [37]Precision46.88 ± 3.0552.42 ± 3.8156.01 ± 6.7161.06 ± 2.9762.70 ± 2.4764.22 ± 2.81
Recall42.20 ± 4.5053.29 ± 4.1254.39 ± 5.3358.19 ± 1.9762.31 ± 2.4463.58 ± 2.33
F1-score39.89 ± 5.5951.92 ± 3.2753.80 ± 5.3557.81 ± 1.2462.32 ± 2.3563.54 ± 2.42
CNN-Transformer [38]Precision49.23 ± 1.3150.67 ± 2.4453.16 ± 2.9861.22 ± 4.6062.24 ± 1.5963.01 ± 2.04
Recall51.54 ± 1.1843.71 ± 5.7252.73 ± 4.0459.86 ± 5.0462.55 ± 1.8062.79 ± 1.83
F1-score49.84 ± 1.1841.18 ± 8.1851.28 ± 4.5159.25 ± 4.3562.02 ± 1.7262.03 ± 1.81
Proposed methodPrecision78.51 ± 0.7884.26 ± 0.9985.79 ± 0.6386.57 ± 0.3387.25 ± 0.2890.85 ± 0.11
Recall78.36 ± 0.8384.31 ± 0.5985.91 ± 0.8186.75 ± 0.3887.32 ± 0.1390.47 ± 0.36
F1-score78.34 ± 0.8484.22 ± 0.8485.82 ± 0.7286.64 ± 0.3587.25 ± 0.1590.63 ± 0.25
Table 4. Ablation study of different module combinations under different shot settings with seed 42. PPS: Physics-Semantic Prompting Strategy; AFA: Adaptive Feature Aggregation; P, R, and F1 denote Precision, Recall, and F1-score, respectively.
Ablation StudyShot = 1Shot = 3Shot = 5
PPS AFA P R F1 P R F1 P R F1
46.6245.7246.1282.8183.1982.9883.6083.8083.61
65.9665.4865.3483.7083.9583.8284.8985.1284.98
74.1775.1474.5383.6783.9083.7584.8285.0984.92
79.3979.3179.3185.0584.8684.9186.4986.8086.62
Table 5. Performance of different fine-tuning strategies under different shot settings with seed 42. P, R, and F1 denote Precision, Recall, and F1-score, respectively.
ConfigShot = 1Shot = 3Shot = 5
P R F1 P R F1 P R F1
Frozen34.9535.0034.8047.7147.7247.5852.6153.3052.80
Fine-Tuning 0–576.3976.2576.3183.2883.2383.2485.3785.7485.44
Fine-Tuning 6–1179.3979.3179.3185.0584.8684.9186.4986.8086.62
Table 6. Performance with different sliding window sizes under different shot settings with seed 42. P, R, and F1 denote Precision, Recall, and F1-score, respectively.
WindowShot = 1Shot = 3Shot = 5
P R F1 P R F1 P R F1
370.6871.1970.9180.4481.0780.7081.2681.7681.48
469.6168.5669.0481.2681.7681.4883.9384.4684.15
579.3979.3179.3185.0584.8684.9186.4986.8086.62
677.1776.0976.5683.4583.8683.6284.3785.0784.47
776.0276.8976.3683.5384.1483.7785.0885.3685.03
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content.