1. Introduction
The rapid development of remote sensing technology has produced dense archives of multi-temporal imagery for monitoring land-surface dynamics [
1,
2]. Orthophotos are particularly useful for change detection because they are geometrically corrected, georeferenced, and presented at a near-uniform scale. Comparing orthophotos acquired at different times is therefore a common way to locate building construction, land cover transitions, urban expansion, and disaster damage, supporting urban planning, emergency assessment, and environmental management [
3,
4].
In operational orthophoto change detection, the desired output is not a map of every pixel-level difference between two images. The desired output is a map of real land cover change. This distinction is important because multi-temporal orthophotos are rarely perfectly matched, even after standard preprocessing [
5,
6]. Differences in illumination, solar altitude angle, atmospheric condition, sensor response, and acquisition season can change image radiometry. Terrain relief, building displacement, off-nadir viewing, residual registration error, orthorectification uncertainty, and shadow movement can also create local geometric inconsistencies [
7,
8]. These factors are usually nuisance variations rather than target changes, but they often appear along building edges, roads, and object boundaries, where many change detectors are most sensitive [
9,
10,
11].
This problem matters in practical mapping. In many monitoring tasks, unchanged areas occupy most of the image, and only a small fraction contains real change. A detector that responds strongly to residual misalignment or brightness differences may obtain visually plausible masks but still generate many false alarms. These false alarms increase manual verification effort and can hide the true change signal in downstream statistics. Therefore, the goal of this study is not to detect small perturbations themselves. The goal is to make the change detector less sensitive to small geometric and radiometric differences that should be ignored while preserving sensitivity to real land cover change.
Traditional remote sensing change detection methods include image differencing, image ratioing, change vector analysis, and principal component analysis [
12]. These methods are efficient but usually rely on handcrafted features or manually selected thresholds, and thus their performance can degrade under illumination variation, registration residuals, and heterogeneous land cover changes. Deep learning methods, especially convolutional neural network (CNN)-based models, have improved feature representation for change detection. Representative models include FC-EF, FC-Siam-Diff, and FC-Siam-Conc. Nevertheless, many existing methods still focus mainly on standard benchmark accuracy and do not explicitly train or evaluate the ability to reject false responses caused by nuisance variation [
13,
14,
15].
Generative adversarial networks (GANs) [
16] have been widely used for image generation, image translation, and representation learning [
17,
18]. In change detection, adversarial supervision can encourage predicted change maps to be more spatially coherent. However, adversarial training alone does not tell the model which image differences should be ignored. A change detector also needs negative evidence, namely examples in which two images are different in appearance but should still be labeled as unchanged. This motivates the use of perturbation-negative samples in this study.
To address the above issues, this study proposes an attention-based generative adversarial network (Attention-GAN) for false alarm-resistant orthophoto change detection. The model combines a Siamese CNN backbone, a multi-scale spatial attention module, a channel attention module, and a PatchGAN discriminator. In addition, controlled geometric and radiometric perturbations are applied to construct perturbation-negative image pairs with all-zero change masks. These samples do not define a new semantic class. They are used to teach the model that residual misalignment and radiometric differences are nuisance variables when no land cover change is present. We emphasize that the individual modules are established components; the contribution lies in their task-oriented integration with a reproducible negative-sample training and evaluation protocol for reducing false alarms. Extensive experiments on multiple public datasets show competitive or moderately improved accuracy compared with the selected representative approaches, together with lower false change rates under the evaluated perturbation settings.
The remainder of this study is organized as follows.
Section 2 reviews the related work.
Section 3 presents the problem formulation and the proposed network architecture.
Section 4 describes the datasets, test areas, implementation details, and comparison methods.
Section 5 reports the experimental results and analysis.
Section 6 discusses the main findings and limitations of the proposed method. Finally,
Section 7 concludes the paper and outlines future research directions.
3. Methodology
3.1. Problem Definition
The objective of the change detection task is to identify regions that have undergone real land cover changes in a pair of bi-temporal remote sensing images , where H, W, and C denote the image’s height, width, and number of channels, respectively. The objective is to learn a mapping from the input image pair to a binary change map , in which represents a changed pixel and represents an unchanged pixel.
In this formulation, “unchanged” does not mean that the two image patches are numerically identical. It means that no target land cover transition is present. Small residual shifts, illumination differences, and other acquisition-related discrepancies are treated as nuisance variation. A useful model should therefore satisfy two requirements at the same time: it should respond to real object-level change, and it should remain conservative when the observed differences can be explained by nuisance variation.
To this end, we formulate the task within a conditional generative adversarial network (cGAN) framework. The generator
G learns to predict the change map
conditioned on the bi-temporal images, whereas the discriminator
D aims to distinguish the real change map
Y from the generated one
under the same condition. By optimizing the two networks in an adversarial manner, the proposed framework encourages the generator to produce more realistic and structurally coherent change maps, thereby improving the quality of the change detection results.
3.2. Network Architecture Overview
In this study, we used a conditional adversarial network with multi-scale spatial attention and channel attention. The generator was constructed on a dual-tower Siamese CNN [
14,
22]; the two towers extract features from
and
separately with shared weights, and the fused features are then processed by the Multi-Scale Spatial Attention Module (MSAM) and the Squeeze-and-Excitation (SE) channel attention module [
29,
31,
32]. This design combines temporal feature comparison with spatial and channel feature reweighting. The decoder then generates the final change probability map.
The discriminator employs the PatchGAN structure, which makes local judgments about image patches rather than the entire image. This local patch-based discrimination helps the model capture fine details in the change map. The generator and discriminator were optimized adversarially to improve the quality of the generated change map.
The proposed model differs from STANet and SNUNet mainly in its training objective and supervision structure. STANet focuses on spatiotemporal attention for correspondence modeling, and SNUNet relies on dense Siamese feature fusion. The Attention-GAN combines multi-scale spatial attention, channel recalibration, PatchGAN supervision, and perturbation-negative samples so that unchanged but visually inconsistent pairs are explicitly represented during training. The contribution is therefore the task-oriented integration and evaluation protocol, not the invention of the MSAM, SE, or PatchGAN.
3.3. Generator Network
3.3.1. Dual-Tower Siamese CNN Backbone
The generator adopts a dual-tower Siamese CNN as the backbone for change detection [
14,
22]. In this architecture, the two towers process the bi-temporal images
and
separately while sharing the same network parameters. This weight-sharing strategy ensures that both images are encoded in a common feature space, enabling consistent comparison of features at corresponding spatial locations.
Compared with early-fusion strategies that concatenate
and
before a single encoder, the dual-tower design explicitly models temporal correspondence and typically yields better performance in change detection tasks [
14,
20].
Each tower employs the same CNN encoder
E (e.g., ResNet blocks [
35] or VGG-style convolutional layers) to extract hierarchical features over
L stages. The feature maps at stage
l are defined as follows:
where
denotes the shared encoder up to stage
l. The feature maps
and
have dimensions
.
The two branches operate in parallel, and their outputs are fused through channel-wise concatenation:
where
. This fusion strategy preserves complementary spatial and semantic information from both temporal observations and provides the basis for subsequent attention-based feature refinement.
3.3.2. Multi-Scale Spatial Attention Module (MSAM)
To capture change patterns at different spatial scales, we introduce the MSAM. Given the fused feature map
, parallel convolution operations with different kernel sizes are applied:
where
denotes the ReLU activation function. The multi-scale features are then aggregated:
Next, a spatial attention map is generated:
where
denotes the sigmoid activation. The final spatially enhanced feature is obtained by
This module enables the network to emphasize spatial regions corresponding to potential changes while suppressing irrelevant responses.
3.3.3. Squeeze-and-Excitation (SE) Module
To further enhance feature discrimination, we incorporated the Squeeze-and-Excitation (SE) module to model channel-wise dependencies. Given the spatially refined feature
, global average pooling is applied first:
Then, two fully connected layers capture channel interactions:
where
denotes the ReLU and
denotes sigmoid activation. The channel-refined feature is
where
s is broadcast along spatial dimensions. This mechanism adaptively highlights informative channels while suppressing redundant features.
3.3.4. Decoder
The decoder progressively restores the spatial resolution of encoded features to generate the final change map. Let
denote the decoder feature at stage
l. The decoding process can be written as follows:
where
denotes upsampling, ⊕ represents feature concatenation, and
denotes convolution followed by nonlinear activation.
Finally, a
convolution followed by sigmoid activation produces the change probability map:
Each pixel value in represents the probability that the corresponding location belongs to the changed class.
3.4. Discriminator Network
The discriminator adopts a PatchGAN structure, which performs local patch-based discrimination rather than judging the entire image. In the conditional adversarial setting, the discriminator receives the bi-temporal input pair together with either the reference change map or the predicted change map. It then outputs a patch-wise probability map:
where each element represents the probability that the corresponding local patch belongs to the real distribution. This local discrimination strategy encourages the generator to produce spatially consistent and realistic change patterns, which is particularly beneficial for fine-grained change detection tasks.
3.5. Loss Functions
The generator is trained with a composite loss consisting of adversarial loss, segmentation loss, and perceptual loss. The three terms target different aspects of the prediction: local realism, pixel-level accuracy, and structural consistency.
3.5.1. Adversarial Loss
The adversarial objective is written separately for the discriminator and generator. The discriminator is trained to distinguish the reference change map from the generated change map under the same image pair condition:
The generator is trained to make the predicted change map difficult for the discriminator to distinguish from a reference map:
3.5.2. Segmentation Loss
Segmentation loss measures the pixel-wise difference between the generated change map and the real change map. We use the binary cross-entropy (BCE) loss to calculate the error between the predicted and true change maps:
where
is the ground-truth change map and
is the predicted change map.
3.5.3. Perceptual Loss
To maintain structural consistency, we use the perceptual loss [
36] to measure the difference between the generated and real change maps in a feature space. In the implementation, both the predicted probability map and the binary reference map are replicated to three channels and fed into an ImageNet-pretrained VGG-16 network. Features from layer
relu3_3 are used to compute the perceptual loss, while VGG parameters are frozen during training. We selected
relu3_3 because it provides a compromise between local boundary information and mid-level structural representation; lower layers were more sensitive to pixel noise, whereas deeper layers were less responsive to small building changes. Perceptual loss encourages the predicted change map to remain close to the reference map in this feature space:
where
denotes the frozen VGG-16 feature extractor at layer
relu3_3.
3.5.4. Total Loss
The final optimization objective is to combine the three losses into a total loss function:
where
and
are hyperparameters used to balance the different components of the loss. In this study,
and
were determined on the validation set. We first fixed the BCE segmentation loss as the main supervised objective (
), because pixel-level change labels provide the most direct training signal for binary change detection. We then tested
and selected
, which provided the best trade-off between validation F1 and boundary smoothness without suppressing small changed objects. Larger perceptual loss weights produced smoother but less complete change maps, whereas smaller weights had a limited regularization effect. The adversarial term was kept with the unit weight because reducing it weakened the PatchGAN regularization, while increasing it led to less stable generator–discriminator training. Therefore, the final settings were
,
, and
.
3.6. Optimization Strategy
The generator and discriminator are trained alternately. We used the Adam optimizer to minimize the generator loss
and the discriminator loss
. Both the generator and discriminator use Adam with
and
. The lower first-moment coefficient follows common cGAN and PatchGAN training practice and helps reduce excessive momentum accumulation during alternating adversarial updates. The initial learning rate was set to
for both networks. We used the same optimizer type and learning rate for the two networks after validation-based tuning because this setting produced stable adversarial training with the PatchGAN discriminator in our experiments. We also tested a lower discriminator learning rate (
), but it slowed discriminator convergence and did not improve the validation F1 or FCR. A cosine annealing schedule was used after a 10-epoch warm-up, and the minimum learning rate was set to
for both networks. The validation F1 and validation FCR were evaluated after each epoch. The model checkpoint with the highest validation F1 was selected for the standard benchmark tables; when two checkpoints have the same F1 within 0.1 percentage points, the one with the lower validation FCR is selected. Early stopping is applied if the validation F1 does not improve for 30 consecutive epochs. The maximum number of epochs is 200:
No test set information was used for checkpoint selection or hyperparameter adjustment.
The change data in this paper were experimentally validated on three publicly available datasets. The detailed data sources, scene characteristics, and preprocessing protocol are presented in
Section 4.1 to avoid separating the dataset description from the experimental design. To reduce false alarms caused by geometric or radiometric differences, we additionally generated perturbation-negative samples by applying controlled nuisance perturbations to existing image pairs and assigning them all-zero change masks. A hybrid training strategy was used, which is described below.
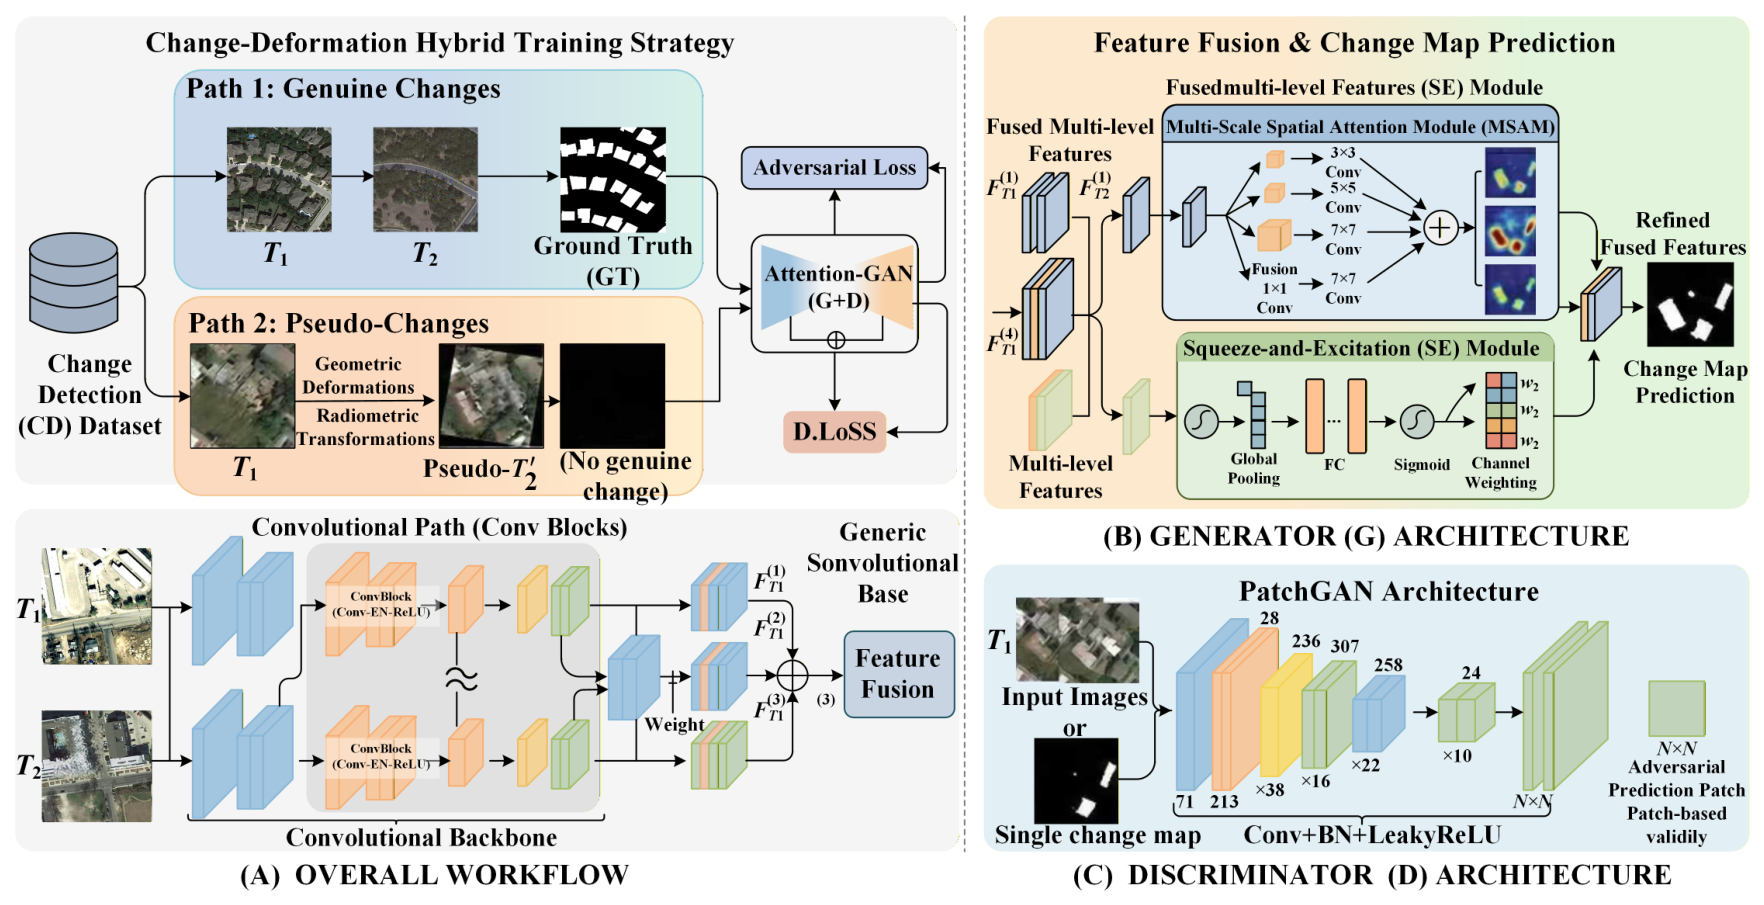
Figure 1 illustrates the training workflow and architecture of the proposed Attention-GAN model. The model takes two input images
and
and processes them through a dual-tower Siamese CNN backbone for feature extraction; the fused features are then passed through the MSAM and SE for feature refinement, and the decoder restores the image to its original resolution and outputs the predicted change map. Perturbation-negative samples are included as unchanged examples during hybrid training. A PatchGAN discriminator performs patch-based classification to distinguish between real and generated change maps, contributing to adversarial training. The model is optimized using the segmentation loss, perceptual loss, and adversarial loss.
5. Experimental Results and Analysis
5.1. Quantitative Analysis
Table 4 shows the performance comparison of different methods on the LEVIR-CD dataset. Attention-GAN achieved the best results across all metrics, with an F1 score of 91.2%, a 1.0 percentage point improvement over the second-best method, TinyCD. Because the margin was modest, this result is interpreted together with the repeated-run statistical analysis in
Table 7, where the paired test against TinyCD gave
.
Table 5 and
Table 6 present the results on the WHU-CD and DSIFN-CD datasets, respectively. The proposed method obtained the highest F1 and IoU among the selected baselines on both datasets. The improvements were moderate, but the repeated-run paired tests against TinyCD remained significant on WHU-CD (
) and DSIFN-CD (
), as reported in
Table 7.
Across the three datasets, the gain over the second-best method was consistent but modest. The results support the usefulness of combining attention, adversarial supervision, and perturbation-negative training, but they should not be read as a large performance leap over recent methods. The higher F1 on DSIFN-CD (93.18%) than on LEVIR-CD (91.2%) may also reflect dataset-specific scene composition and annotation characteristics.
Table 7 summarizes the repeated-run statistics corresponding to
Table 4,
Table 5 and
Table 6. Attention-GAN obtained a higher mean F1 on all three datasets, with
under the three-run paired-test protocol. The effect size was still moderate, and thus the results are interpreted as statistically supported but incremental improvements.
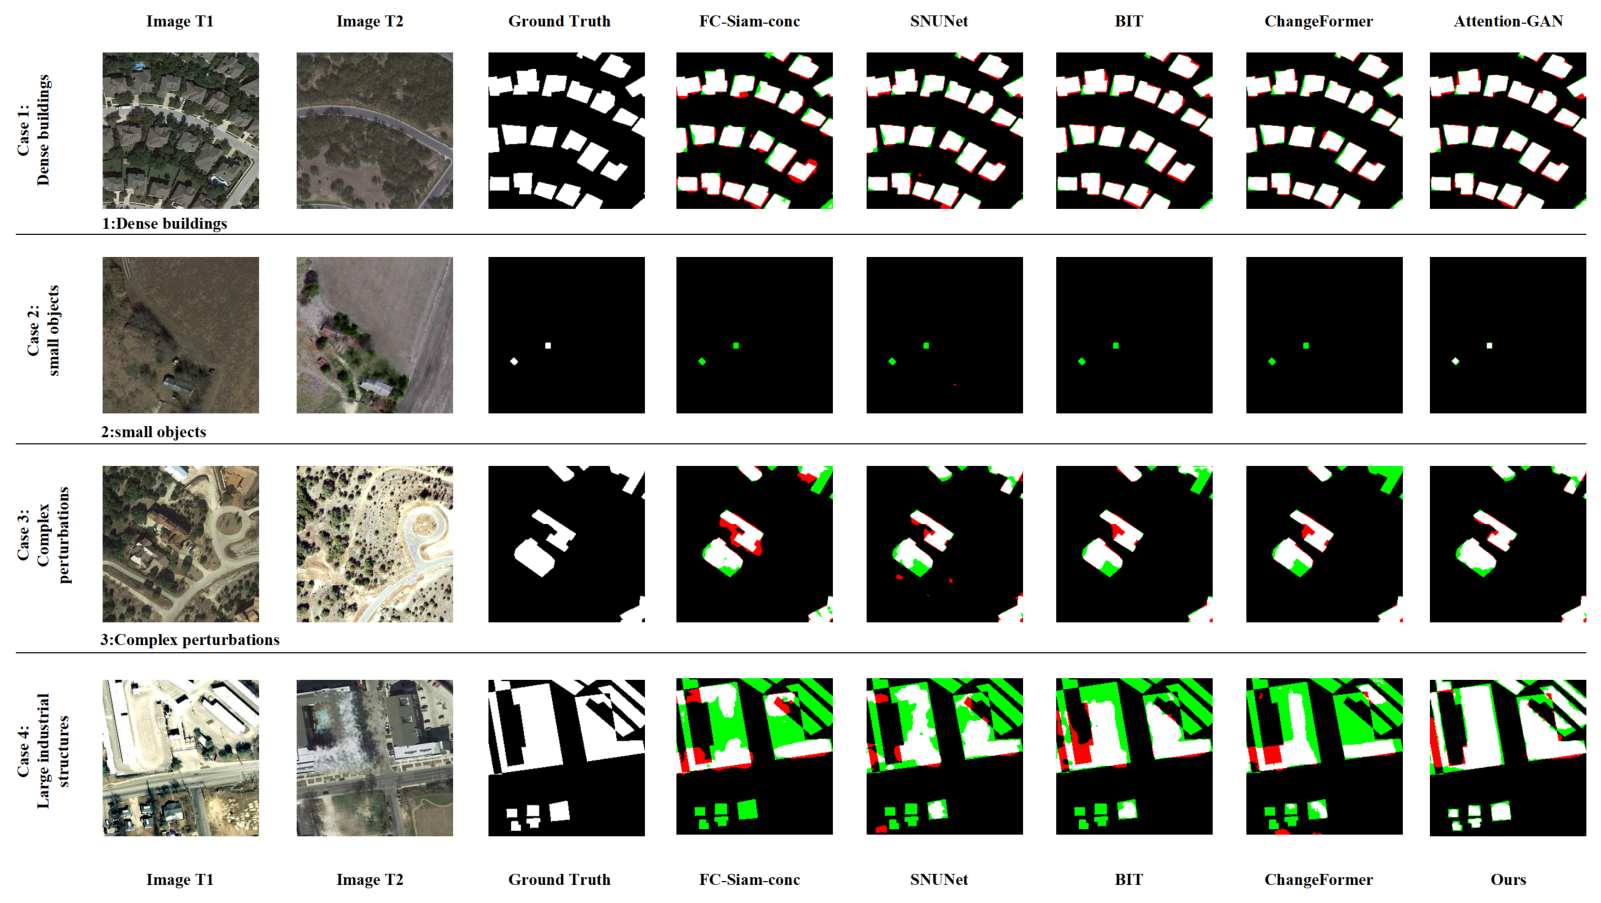
Figure 2 presents the representative results from four test scenes. The columns show the first image, second image, ground truth, selected baseline predictions, and proposed Attention-GAN prediction. The proposed method produced more continuous changed regions and fewer isolated false alarms in these examples.
5.2. Ablation Experiments
Ablation experiments were conducted on the LEVIR-CD split used in
Table 4. The baseline was a Siamese encoder–decoder trained with BCE loss only. The MSAM, SE, PatchGAN supervision, and perturbation-negative samples were then evaluated individually and in combination. All variants used the same data split, optimizer, learning rate schedule, batch size, and checkpoint selection rule; thus, the changes in F1 and FCR mainly reflected the contribution of the added component.
In
Table 8, M, S, P, and N denote the MSAM, SE, PatchGAN supervision, and perturbation-negative samples, respectively. The MSAM and SE both improved the F1 score over the Siamese baseline and reduced the FCR. Using the MSAM and SE together increased the F1 by 2.5 percentage points and lowered the FCR by 3.9 percentage points. Adding PatchGAN supervision raised the F1 from 90.1% to 90.6% and lowered the FCR from 10.9% to 9.8%. Adding perturbation-negative samples without PatchGAN raised the F1 to 90.8% and lowered the FCR to 6.3%, showing that the proposed negative-sample strategy mainly contributes to false alarm suppression. The full model obtained the best F1 and the lowest FCR, suggesting that local adversarial supervision and perturbation-negative training are complementary.
The qualitative ablation results followed the same pattern. The baseline model often produced fragmented changed regions, blurred object boundaries, and isolated false alarms in unchanged backgrounds. After adding the MSAM, changed objects became more spatially continuous, and missed detections of small or narrow changed regions were reduced. Adding SE further suppressed background noise and improved the separation between changed and unchanged semantic regions. When the MSAM and SE were used together, the predicted maps showed clearer object-level boundaries, fewer nuisance responses, and more complete small-object changes.
A data ratio sensitivity analysis was also conducted on LEVIR-CD. As shown in
Table 9, the F1 decreased as fewer training samples were used. Attention-GAN remained usable at 50% and 75% of the training data, but the recall dropped more clearly at 25%, indicating that diverse real-change annotations were still needed. The mini-batches included both changed and perturbation-negative examples to reduce class imbalance effects.
5.3. Visualization Analysis
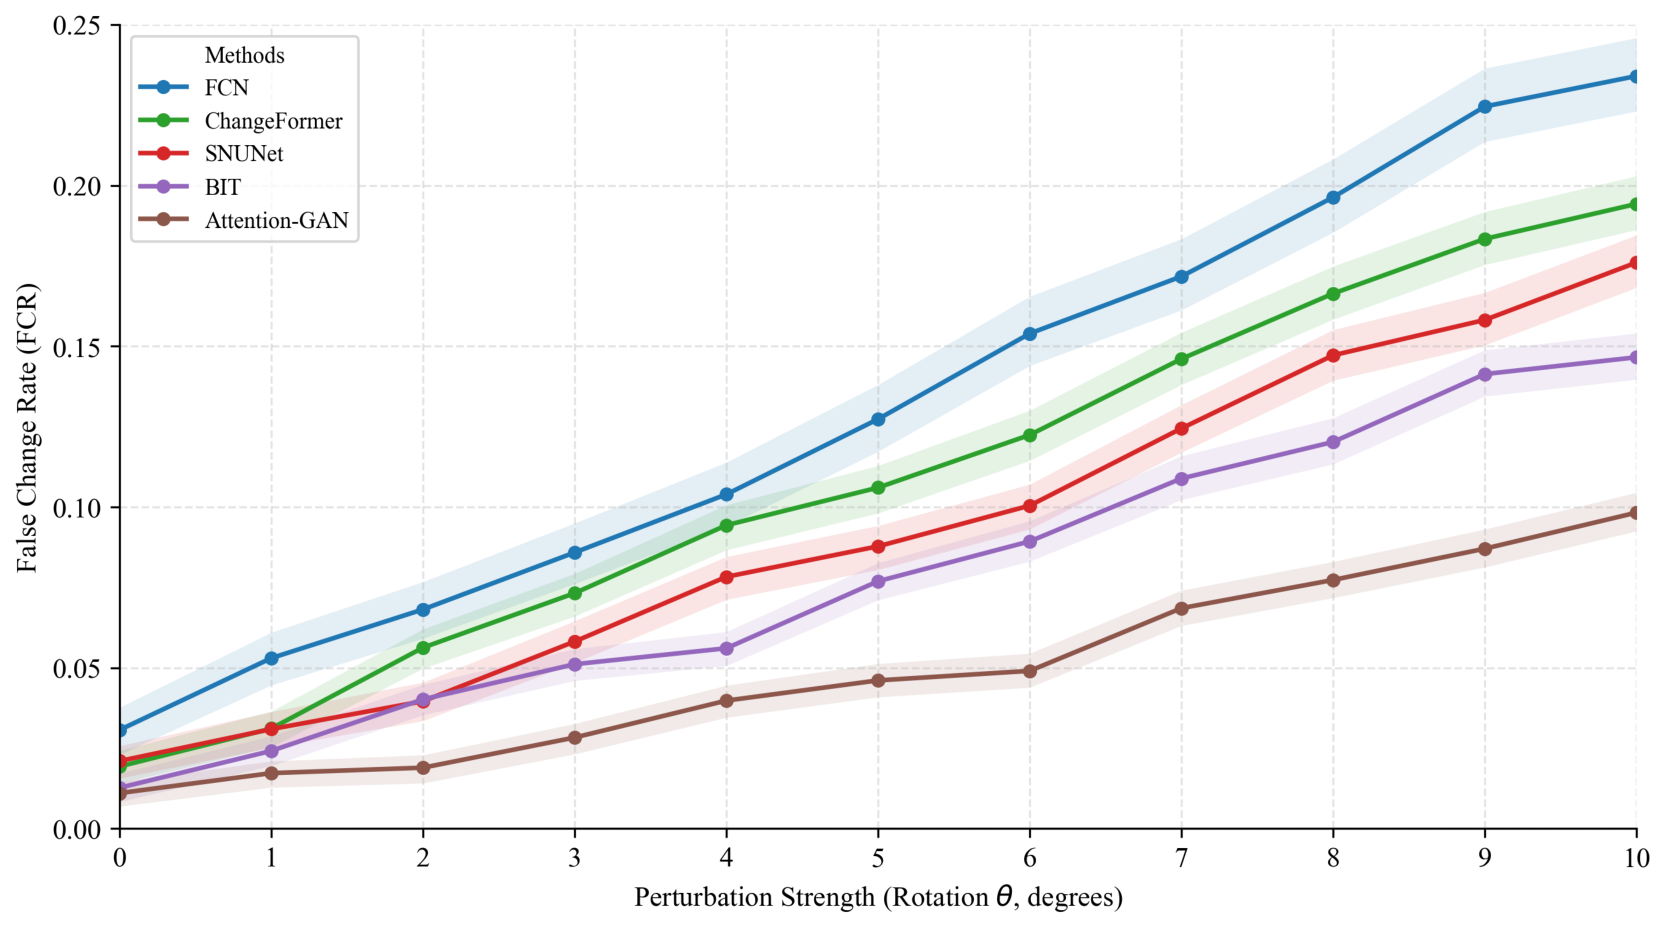
Figure 3 shows the FCR under controlled rotation perturbation, with
. Each curve reports the mean over three runs, and the shaded region shows the standard deviation. FCN denotes the fully convolutional early-fusion baseline used in this robustness comparison.
The FCR increased for all methods as the rotation became stronger. Attention-GAN had the lowest FCR across the evaluated range and degraded more slowly than the compared baselines. Since perturbation-negative samples were used during training, this result should be interpreted as improved robustness within the evaluated perturbation family and not as unrestricted robustness to all real-world distortions.
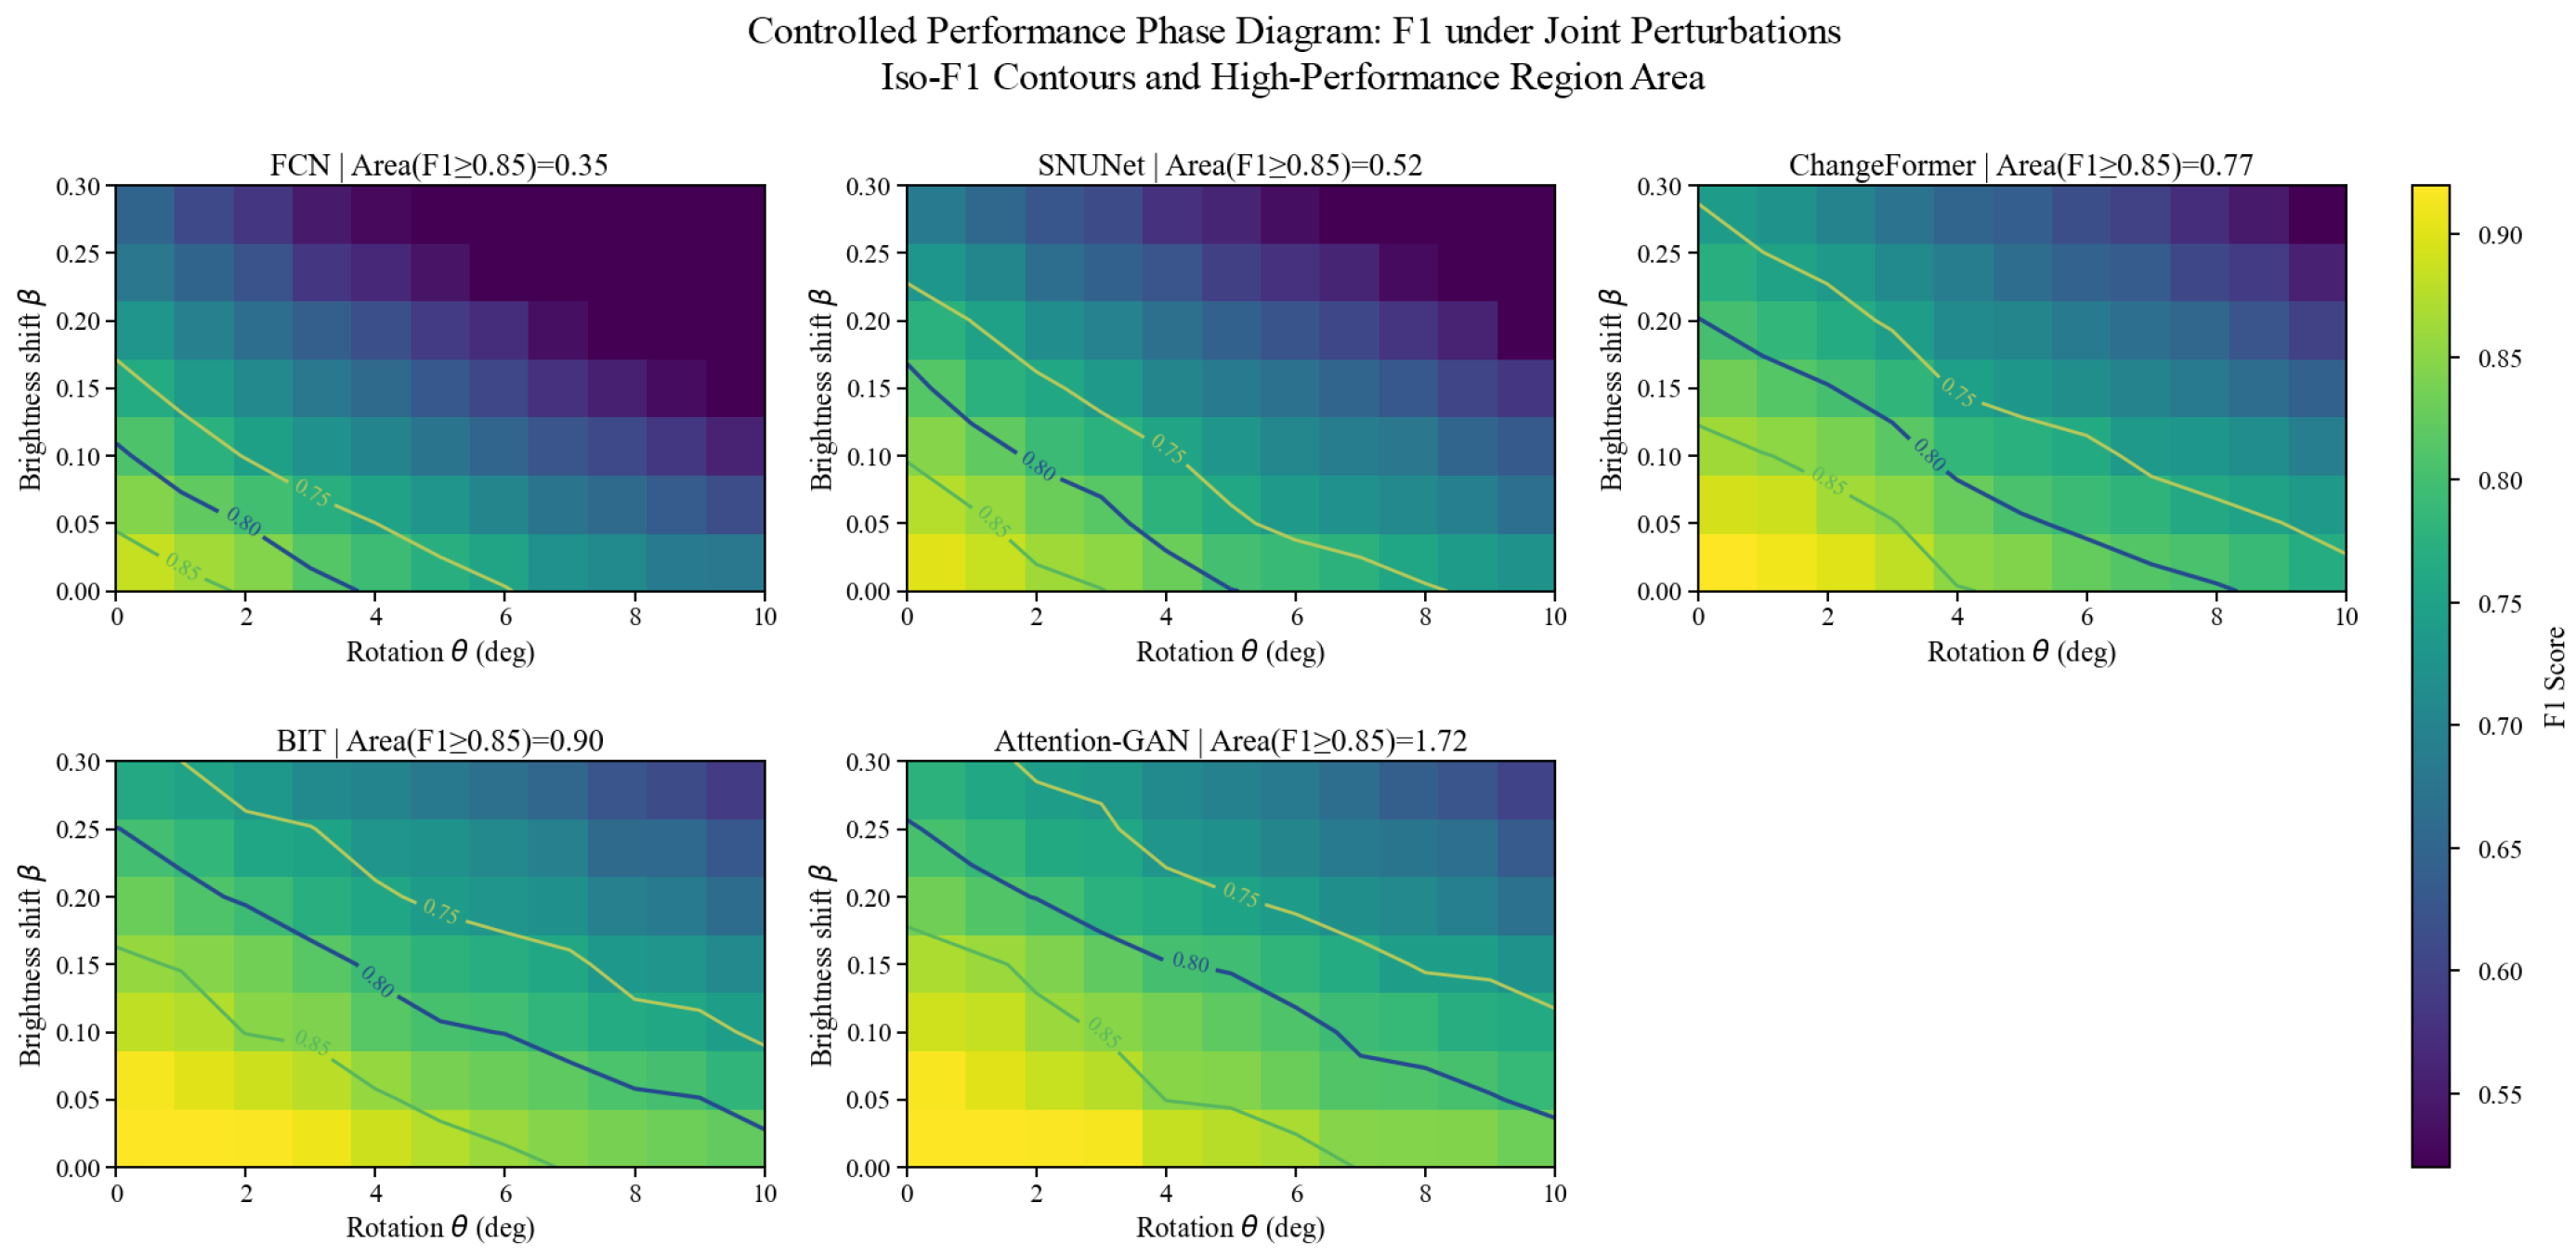
Figure 4 reports the F1 under joint rotation and brightness perturbations. The horizontal axis is
, and the vertical axis is the brightness shift
. The color map gives F1 scores on perturbed held-out test pairs with valid reference masks, and the contour lines mark the F1
region.
All methods degraded as the rotation or brightness disturbance increased. Attention-GAN preserved a larger F1 region than the compared methods, indicating better stability within the controlled compound perturbation range.
6. Discussion
6.1. Interpretation of Results
On LEVIR-CD, WHU-CD, and DSIFN-CD, Attention-GAN gave the highest F1 among the selected baselines. The margins were modest, even though the paired tests were significant under the three-run protocol. The results are therefore best interpreted as incremental gains from combining attention, adversarial supervision, and perturbation-negative training. The ablation study suggests that the MSAM improved spatial continuity, SE improved channel discrimination, PatchGAN improved local regularity, and perturbation-negative samples reduced false alarms under the evaluated nuisance perturbations.
The robustness experiments (
Figure 3 and
Figure 4) show that the method degraded more slowly under geometric and radiometric perturbations than the representative baselines shown in those figures. This is important for orthophoto change detection because mild misalignment or radiometric inconsistency should not by itself produce a large change mask. At the same time, the training and testing perturbations belonged to the same broad family of affine and radiometric transformations. Thus, the robustness results demonstrate generalization within a controlled perturbation distribution rather than unrestricted robustness to all real-world nuisance sources. The test perturbation parameters were continuously sampled on held-out image pairs and not reused from the training samples, but the results should not be interpreted as evidence of robustness to parallax, strong seasonal variation, atmospheric artifacts, DEM errors, or cross-sensor distortions.
The model is related to recent intertemporal attention-guided change detection networks, including the Multi-Level Intertemporal Attention-Guided Network. The difference is that Attention-GAN couples attention modules with PatchGAN supervision and perturbation-negative samples. Its purpose is false alarm-resistant change detection and not a new semantic class formulation or a replacement for existing change detection paradigms.
6.2. Training Stability of the GAN Framework
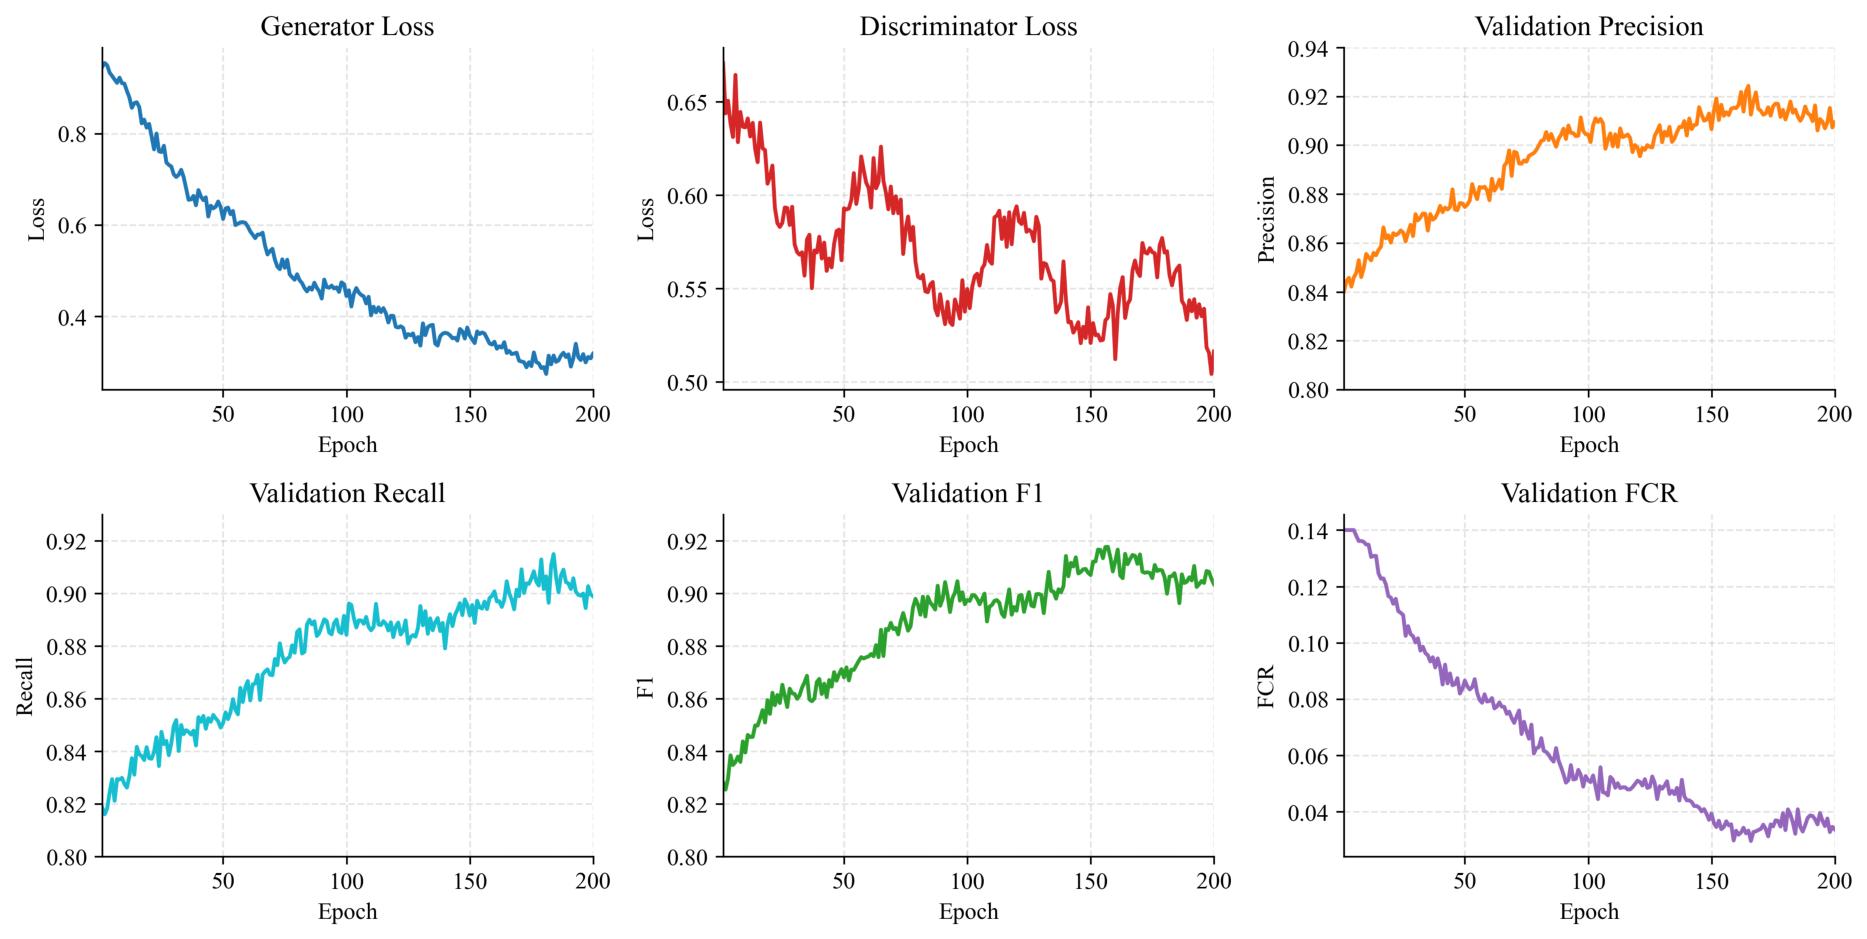
GAN training can be unstable because the discriminator may dominate or collapse. To reduce this risk, the discriminator uses local PatchGAN supervision, and the adversarial loss is combined with pixel-wise segmentation and perceptual losses. The generator loss, discriminator loss, validation precision, recall, F1, and FCR were monitored after each epoch.
Figure 5 shows the representative curves; the generator loss decreased and stabilized, the discriminator loss did not collapse to zero, the validation F1 converged after the middle training stage, and the validation FCR decreased. If strong oscillation was observed, then the adversarial weight was reduced while keeping the segmentation loss unchanged.
6.3. Limitations
Several limitations remain. First, the dual-tower Siamese CNN backbone increases the parameter count and inference cost. The experiments were conducted on a single GPU with a fixed input size and augmentation setting, and thus performance under different patch sizes, extremely high resolutions, and cross-sensor settings was not fully examined. Second, the affine and radiometric perturbations used here covered only controlled nuisance sources. Real scenes may contain parallax, off-nadir viewing effects, relief displacement, occlusion, seasonal variation, atmospheric artifacts, DEM errors, shadow displacement, or cross-sensor differences. The reported robustness therefore applies to the evaluated perturbation family and not to all real-world distortions. Third, the experiments mainly used LEVIR-CD, WHU-CD, and DSIFN-CD. Broader validation on vegetation dynamics, water body change, cropland change, disaster damage, and cross-sensor datasets is needed. Future work should evaluate real multi-view and cross-sensor benchmarks, include stronger recent baselines under a reproducible protocol, and test more severe low-annotation and class imbalance settings.
7. Conclusions
This study presented an attention-guided generative adversarial network for false alarm-resistant change detection in remote sensing orthophotos. The model integrates multi-scale spatial attention and channel attention into a Siamese change detection framework, and it uses perturbation-negative samples to indicate that mild geometric and radiometric differences should remain unchanged when no land cover transition is present. PatchGAN supervision further improves the local regularity of the predicted change maps.
Experiments on three public datasets showed that Attention-GAN achieved competitive or moderately higher accuracy than the selected baselines. The robustness results indicated lower false alarm rates under the controlled affine and radiometric perturbations evaluated in this study.
The framework is intended for orthophoto-based change detection in scenarios where imperfect co-registration and radiometric inconsistency can create false alarms. It is most relevant to monitoring workflows in which candidate change maps are reviewed manually or used in downstream spatial analysis.
Practical implications and future work: The approach is suited to orthophoto-based urban and land cover monitoring when co-registration and radiometric consistency are imperfect. Future work will focus on lighter backbones, multi-temporal or multi-sensor inputs, semantic change maps, and uncertainty-based human verification.