Article

A Multi-Stage Outlier Removal Method for Point Clouds with High Outlier Ratio

School of Artificial Intelligence, Nanjing University of Information Science and Technology, Nanjing 210044, China
*
Author to whom correspondence should be addressed.
Remote Sens. 2026, 18(14), 2289; https://doi.org/10.3390/rs18142289
Submission received: 26 May 2026 / Revised: 27 June 2026 / Accepted: 30 June 2026 / Published: 8 July 2026
(This article belongs to the Section Remote Sensing Image Processing)

Highlights

What are the main findings?
  • We provide a multi-stage outlier removal method for point clouds with high outlier ratios by combining coarse LRD-DPC outlier removal, structure-adaptive refinement, and reference-guided completion.
  • By incorporating pairwise scale consistency and local plane residual scoring, the proposed method effectively classifies outliers and achieves robust performance on both synthetic point clouds and real-world single-photon 3D scanned data.
What are the implications of the main findings?
  • The full reference quality assessment of point clouds is introduced into the completion-based outlier removal framework for the first time, which can reduce the irreversible loss of valid geometric structures under severe outlier contamination.
  • By identifying and removing outliers while preserving valid geometric structures, the proposed method provides reliable preprocessing for downstream tasks such as 3D reconstruction, surface modeling, and LiDAR-based mapping.

Abstract

Point clouds acquired by LiDAR typically contain a large number of outliers, which can substantially degrade downstream processing. Existing outlier removal methods suffer from significant performance degradation on point clouds with high outlier ratios. In this study, we propose a multi-stage outlier removal method called MORPH for point clouds with high outlier ratios. The proposed method first employs local reachability density combined with density-peak clustering to coarsely eliminate prominent outliers while preserving the global structural skeleton. Subsequently, a structure-adaptive refinement stage is introduced to generate incomplete point clouds and candidate points. Finally, a completion strategy that integrates pairwise scale consistency with local plane residual score is proposed to identify inlier points from the candidate points. Outlier removal is completed by using the obtained inlier points to fill the incomplete point clouds. Experimental results on synthetic high-contamination point clouds and real-world scanned point clouds demonstrate that MORPH achieves robust outlier removal performance while better preserving valid geometric structures.

1. Introduction

LiDAR point clouds have become an important data representation for 3D remote sensing and are widely used in applications such as 3D reconstruction, object detection, scene understanding, and LiDAR-based mapping [1,2,3,4]. However, raw point clouds acquired under challenging sensing conditions often contain a large number of outliers caused by environmental interference, sensor noise, and reconstruction uncertainty. When the outlier ratio becomes high, these outliers can severely corrupt local density, statistical, and geometric features, making reliable outlier removal difficult and degrading downstream point cloud processing. Therefore, robust outlier removal is an essential preprocessing step for point clouds with high outlier ratios [5].
Traditional outlier removal methods typically follow a common paradigm: they process point clouds using manually designed criteria for outlier removal and can be broadly categorized as statistical-based, density-based, or geometry-based approaches. These methods are generally efficient, interpretable, and easy to implement. However, their effectiveness largely depends on the reliability of local statistics or geometric features, which may be severely degraded in high outlier ratio point clouds. In such cases, outliers and valid structural points may exhibit similar local characteristics, making reliable discrimination difficult. Consequently, when processing such point clouds, traditional methods often remove outliers together with inlier points that have similar characteristics, resulting in suboptimal outlier removal performance. Learning-based approaches leverage neural networks to distinguish outliers from inlier points, enabling more effective removal of outliers while preserving local geometric features [6,7]. Despite these advantages, they rely on annotated datasets, require substantial computational resources for training, and often perform poorly on point clouds with high outlier ratios. Therefore, the main challenge in outlier removal methods is to reliably identify and remove outliers while preserving local geometric features, particularly under high outlier ratios.
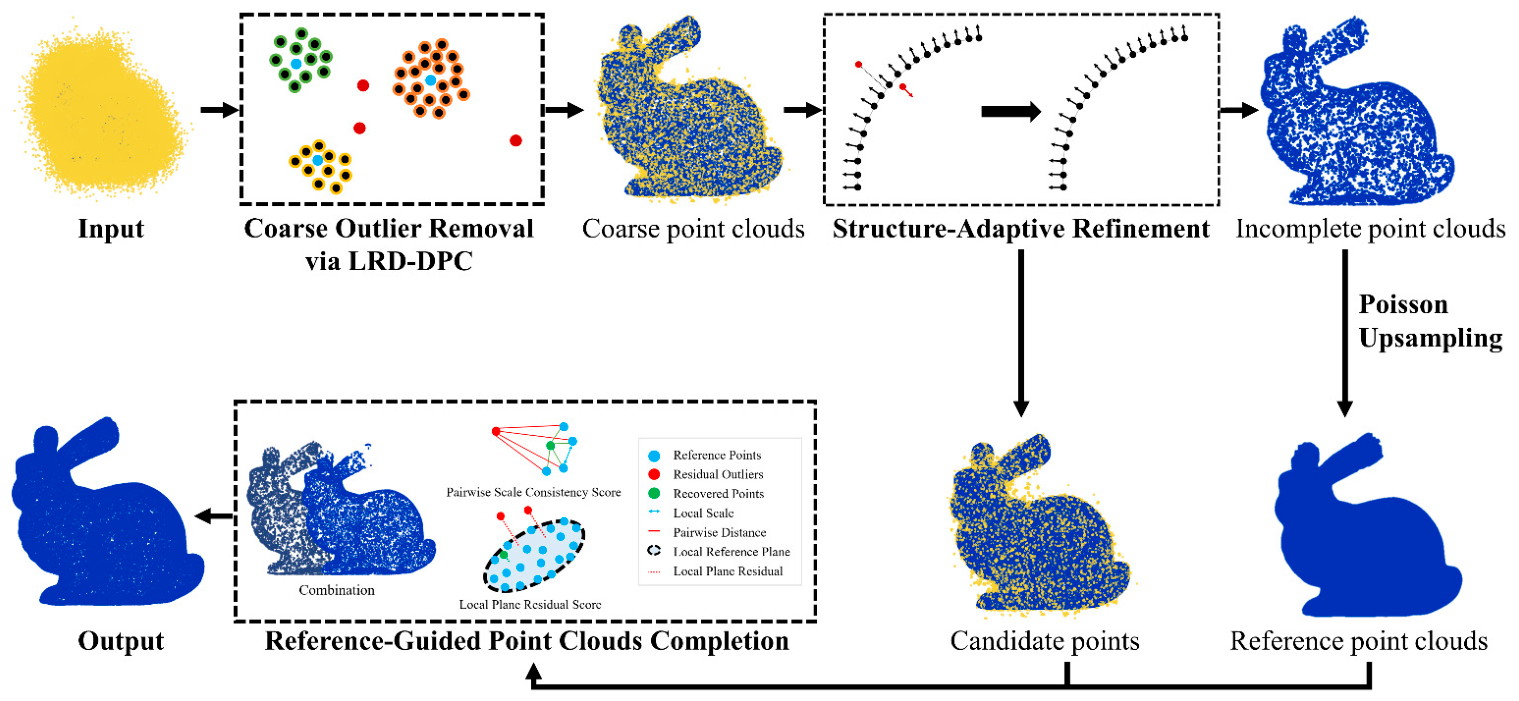
In this study, we propose a multi-stage outlier removal method (called MORPH). MORPH extends our previous work [8] for the filtering of point clouds with high outlier ratios and operates in three stages. For the raw point clouds, the coarse outlier removal stage uses local reachability density combined with density-peak clustering (LRD-DPC) to remove prominent noisy points while maximizing the preservation of the point clouds’ features. Building on this, the structure-adaptive refinement stage addresses residual outliers in regions with varying point densities by applying cluster-wise adaptive thresholds derived from local residuals and normal consistency, producing incomplete point clouds and candidate points. Finally, inspired by full reference point cloud quality assessment [9], the reference-guided completion stage reconstructs a dense reference point cloud via incomplete point clouds and Poisson upsampling. We proposed a completion strategy by fusing the pairwise scale consistency with local plane residual scores. Based on the completion strategy and the reference point clouds, inlier points are identified from candidate points and utilized to complete the incomplete point clouds. Experimental results indicate that MORPH achieves strong performance on both the synthetic dataset and real-world scanned point clouds. Our main contributions are as follows:
  • We propose MORPH, a multi-stage outlier removal method designed for point clouds with high outlier ratios, and evaluate its effectiveness on synthetic data and real-world single-photon 3D scanned data.
  • We design a structure-adaptive refinement module to remove residual outliers in locally ambiguous regions where valid structural points and outliers are difficult to distinguish.
  • A reference-guided completion strategy is proposed based on the joint assessment of scale consistency and orthogonal residuals to recover mistakenly removed inlier points.

2. Related Work

Existing point cloud outlier removal methods can be broadly categorized into four groups: statistical-based methods, clustering-based methods, geometry-based methods, and learning-based methods. Statistical-based methods usually identify outliers according to neighborhood distance or density distributions. Clustering-based methods distinguish outliers by analyzing local density variations and cluster structures. Geometry-based methods rely on local or non-local geometric features, such as normals, curvature, and surface residuals, to detect abnormal points. Learning-based methods further employ neural networks to learn complex structural priors from data. This section reviews these methods and discusses their limitations under high outlier ratios.

2.1. Statistical-Based Methods

Statistical-based methods have been widely adopted for point cloud outlier removal due to their simplicity and computational efficiency. Rusu et al. proposed the statistical outlier removal (SOR) method [10], which detects outliers by modeling the distribution of local neighborhood distances and applying global thresholding strategies. Building upon this paradigm, Balta et al. proposed a fast statistical outlier removal method [11], where voxelization and clustering are introduced to improve computational efficiency for large-scale point clouds. Zeybek further discussed the inlier preservation problem in SOR-based filtering for airborne laser scanning point clouds [12], showing that valid points may also be mistakenly removed during statistical outlier removal. Furthermore, Roriz et al. introduced DIOR [13], which extends statistical filtering to remove environment-induced noise, including adverse weather effects. In addition, our previous work [8] proposed a layered statistical outlier removal method that removes outliers in a layer-wise manner along the depth direction and incorporates an improved Mahalanobis distance to better handle anisotropic and non-uniform point distributions. Despite these improvements, existing statistical-based methods remain effective only when inlier points dominate local statistical characteristics. As the outlier ratio increases, outliers progressively disrupt the statistical stability of local distance distributions, reducing the separability between inlier points and outliers in the feature space. As a result, these methods often fail to reliably distinguish the two, leading to degraded performance on point clouds with high outlier ratios.

2.2. Clustering-Based Methods

Clustering-based methods detect outliers by analyzing variations in local point density and relative distances within neighborhoods. Rodriguez et al. proposed Density Peak Clustering (DPC) [14], which identifies cluster centers as points with both high local density and large relative distance, enabling natural separation between dense regions and potential outliers. Xia et al. proposed an optimized density peak clustering method [15], which introduces adaptive density metrics and a K-means-derived objective function to enhance performance under noisy conditions. Xie et al. further improved density estimation by introducing a K-nearest neighbor-based density region modeling strategy [16], which captures local density variations more effectively through neighborhood relationships. In addition, Wang et al. proposed a variational density peak clustering method [17], which incorporates probabilistic formulations into density estimation and center selection, thereby improving clustering stability. However, as the outlier ratio increases, numerous outliers can disrupt the intrinsic cluster structures of the point clouds and even form pseudo-clusters. In sparse regions and around sharp features, inlier points often exhibit local densities similar to those of outliers, making reliable discrimination difficult for clustering-based methods.

2.3. Geometry-Based Methods

Geometry-based methods detect outliers and remove noise by leveraging local and non-local geometric features to preserve fine structural details. Wang et al. proposed a granular-ball center isolation and region consistency strategy [5], evaluating points against local geometric centers, though sparse points in thin structures may be misclassified due to unstable density estimation. Nurunnabi et al. leveraged robust normal and curvature estimation in mobile laser scanning data to detect deviations from local surface properties [18], while performance can degrade under severe noise or irregular sampling. Xi et al. utilized neighborhood-derived geometric indicators for threshold-based filtering [19], retaining structural integrity in well-sampled regions but struggling with highly non-uniform surfaces. Xu et al. employed a generalized error metric with robust surface fitting to preserve geometry in noisy regions [20], and Chen et al. applied curvature entropy and γ-norm minimization to enforce non-local geometric consistency [21], further improving performance in moderately noisy environments. Geometry-based methods typically rely on local neighborhoods to estimate geometric quantities such as normal vectors, curvature, and planar residuals, all of which are highly sensitive to the distribution of points within the neighborhood. When geometry-based methods are applied to point clouds with a high proportion of outliers, these geometric quantities can be severely distorted by outlier contamination, thereby compromising their effectiveness.

2.4. Learning-Based Methods

Learning-based methods leverage neural networks to automatically model complex local and non-local structures for point cloud outlier removal. Convolutional architectures such as PointCleanNet [22] and FCNet [23] predict clean point positions from noisy input via encoder–decoder networks. Although they can remove most outliers effectively, they often rely on extensive labeled datasets for training. Methods that integrate multi-point or neighborhood information, such as 4DenoiseNet [24], improve robustness under challenging noise, while hierarchical networks like DHE-Net [6] capture multi-scale geometric features to enhance outlier removal accuracy at the cost of increased computational complexity. Latent-space adaptive approaches, exemplified by LaPDA [25], adjust learned feature representations dynamically for varying noise levels, yet still depend on representative pretraining. Overall, learning-based methods show excellent performance in outlier removal. However, their effectiveness often depends on the quality of the dataset and the corresponding training process. Moreover, existing methods have not been sufficiently investigated on point clouds with high outlier ratios.

3. Materials and Methods

3.1. Overall Framework

The framework of the proposed MORPH is illustrated in Figure 1. MORPH consists of three stages: coarse outlier removal, structure-adaptive refinement, and reference-guided point cloud completion. The coarse outlier removal stage takes the raw point clouds as input and employs LRD-DPC to eliminate prominent outliers. This stage prioritizes structure preservation, thereby producing coarse point clouds. The structure-adaptive refinement stage further processes coarse point clouds to generate incomplete point clouds and candidate points. In this stage, the remaining outliers should be removed as thoroughly as possible, while misclassification of inlier points is acceptable. The reference-guided point cloud completion stage applies Poisson upsampling [26] to the incomplete point clouds to construct reference point clouds. By comparing the pairwise scale consistency and local plane residual score between the candidate points and the reference point clouds, the inlier points can be identified from the candidate points. Finally, the filtered inlier points are merged back into the incomplete point clouds, thereby completing the outlier removal process. The details are presented as follows.

3.2. Coarse Outlier Removal via LRD-DPC

Given raw point clouds P = { p i } i = 1 N , where N is the number of points. To characterize the global isolation of each point, a global outlier score is defined as the sum of its neighbor distances:
G i = j = 1 k d i j
where d i j = p i p i j 2 is the Euclidean distance between p i and its j th nearest neighbor p i j .
We adopt the LRD to further describe the local density distribution. Specifically, for a point p i and its k -nearest neighbor p j N k ( p i ) , the reachability distance d r ( p i ) is defined as
d r ( p i ) = max ( d k ( p i j ) , d ( p i , p i j ) )
where d k ( p i ) denote the distance from p i to its k th nearest neighbor. Based on the reachability distance, the LRD of point p i is defined as
ρ ( p i ) = ( 1 k j = 1 k d r ( p i , p i j ) ) 1
For each point p i , we search within its local neighborhood N k ( p i ) for points with higher density and define the set H i :
H i = { p j N k ( p i ) | ρ j > ρ i }
The relative distance δ ( p i ) is defined as follows:
δ ( p i ) = { min p ij H i d ( p i ,   p i j ) , i f   H max p ij N k ( p i ) d ( p i ) , o t h e r w i s e
The density peak indicator is then given by
γ ( p i ) = ρ ( p i ) δ ( p i )
Points with the largest γ ( p i ) values are selected as cluster centers. Following the DPC assignment rule [14], each remaining point is assigned to the same cluster as its nearest neighbor with higher local density. Thus, the point clouds are partitioned into local clusters. For each cluster C m , we compute its average local density as
ρ ¯ C m = 1 | C m | p j C m ρ ( p j )
where | C m | denotes the number of points in cluster C m . The local anomaly score of a point p i C m is then defined as
L ( p i ) = ρ ¯ C m ρ ( p i )
where ρ ¯ C m denotes the average local density of cluster C m . A larger L ( p i ) indicates that p i is locally sparser than the average density level of its assigned cluster.
Finally, the global isolation and local sparsity are jointly considered by defining the overall anomaly score O ( p i ) as
O ( p i ) = G ( p i ) L ( p i )
A larger O ( p i ) suggests that the point is more likely to be an outlier in both the global and local senses. All points are then sorted in descending order according to O ( p i ) , and the top M points are removed as coarse outliers. The remaining points constitute the coarse point clouds P c o a r s e = { p i } i = 1 N c , where N c denotes the number of retained points.
By jointly considering global isolation and local sparsity, the coarse outlier removal stage suppresses prominent outliers in high outlier ratio point clouds while preserving the main structural skeleton, thereby providing a cleaner input for the subsequent structure-adaptive refinement stage.

3.3. Structure-Adaptive Refinement

To further eliminate residual outliers after the coarse outlier removal stage, a structure-adaptive refined outlier removal stage is introduced to separate them from nearby inlier points.
Specifically, the coarse point clouds P c o a r s e = { p i } i = 1 N c are first partitioned into structural clusters using LRD-DPC. Two geometric features are constructed to characterize the local structure of each point for subsequent outlier discrimination.
The first feature is the point-to-local-plane residual, defined as the distance from p i to its local fitted plane:
R ( p i ) = | n i T ( p i c i ) |
where p i P c o a r s e , n i is the estimated local normal vector based on the local neighborhood N k r ( p i ) , c i is the centroid of N k r ( p i ) . A larger R ( p i ) indicates that the point deviates more from the underlying local surface and is therefore more likely to be an outlier.
The second feature is the normal consistency, which measures the structural coherence between the point and its k c neighbors:
C ( p i ) = 1 k c j = 1 k c | n i n j |
where n j denotes the normal vector of the j th neighbor. This feature reflects the variation in local surface orientation. Points in smooth regions usually have more consistent normal directions and thus larger c i , whereas points near outliers or structural boundaries tend to yield smaller values. For numerical stability, the consistency value is constrained to [ 0 , 1 ] .
For each structural cluster, adaptive decision thresholds are then estimated from the feature distributions within that cluster. For the residual feature, a robust threshold τ r ( m ) is defined as follows:
τ r ( m ) = m e d i a n ( R ( p i ) ) + α M A D ( R ( p i ) )
where R ( p i ) is the local residual, m e d i a n ( ) denotes the median,   M A D ( ) denotes the median absolute deviation, and α is a scaling factor.
For the consistency feature, the cluster-wise threshold   τ c ( m ) is obtained as follows:
τ c ( m ) = m e d i a n ( C ( p i ) ) β M A D ( C ( p i ) )
where C ( p i ) denotes the normal vector consistency and β is a balancing factor.
Let C m denote the m th cluster. A point p i C m is classified as an outlier if r i > τ r ( m ) or c i < τ c ( m ) .
To improve decision reliability, clusters with very small cardinality are exempted from aggressive filtering due to insufficient statistical support. In this way, the proposed refinement removes residual outliers and produces clean but incomplete point clouds P i n c o m p l e t e for the subsequent stage. And the candidate points P c a n d i d a t e = { p i } i = 1 N c a n d are defined as the points removed during refinement but present in coarse point clouds:
P c a n d i d a t e = P c o a r s e P i n c o m p l e t e
By separating the coarse point clouds into an incomplete clean subset and a candidate set, the structure-adaptive refinement stage provides the necessary inputs for the subsequent reference-guided completion stage.

3.4. Reference-Guided Point Clouds Completion

The incomplete point clouds P i n c o m p l e t e   contain few outliers, and the features extracted based on P i n c o m p l e t e will hardly be disturbed by outliers. Therefore, in this stage, by designing a completion strategy and combining with P i n c o m p l e t e , the inlier points in P c a n d i a t e can be effectively acquired. By filling the extracted inlier points into P i n c o m p l e t e , high precision removal of outliers in the point clouds can be achieved.
To guide the evaluation of candidate points, we first generate dense reference point clouds P r e f e r = { p i r } i = 1 N r from P i n c o m p l e t e using Poisson upsampling [26]:
P r e f e r = Φ ( P i n c o m p l e t e )
where Φ ( · ) denotes the reference generation operator.
For each point p i P c a n d i d a t e , we retrieve its k r -nearest reference neighborhood as follows:
N k r e f ( p i ) = { p i m r } m = 1 k r P r e f e r
For each reference neighbor p i m r N k r ( p i ) , its local scale is estimated as follows [27]:
s i m = 1 k q j = 1 k q p i m r p m j r 2
where p m j r N k q ( p i m r ) , and k q is the neighborhood size.
Using local scale s i m , the distance from candidate point p i to its reference neighbor is normalized as
ρ i m = d i m s i m + ϵ
where d i m = p i p i m 2 is the Euclidean distance, and ϵ > 0 is a small constant added for numerical stability. To improve scale invariance, a logarithmic transform is then applied as follows:
z i m = log ( ρ i m )
After computing the log-transformed normalized distances z i m , the candidate point p i is evaluated by minimizing the truncated deviation energy:
E i ( μ i ) = m = 1 k r min ( ( z i m μ i ) 2 , τ p 2 )
where μ i denotes the optimal local scale offset and τ p is the truncation parameter used to suppress the influence of abnormal neighbors.
The pairwise scale consistency S p ( p i ) are then defined as
S p ( p i ) = exp ( 1 k r E i ( μ i * ) )
where μ i * = arg min μ i E i ( μ i ) . A larger S p ( p i ) indicates that the candidate point closely conforms to the true structure in the reference point clouds, indicating it is probably a inlier point.
Moreover, we use local plane residual score to evaluate how well a candidate point aligns with the local surface estimated from the reference point clouds. The orthogonal residual from p i to the local reference plane is computed as
e i = | ( p i q ¯ i ) T n i |
where q ¯ i is the centroid and n i is the normal vector of the reference plane fitted to the local neighborhood of p i in P r e f e r using principal component analysis (PCA).
Since the local point density may vary across different regions, directly using e i may introduce scale bias. Therefore, the residual is further normalized by the representative local reference scale s ¯ i , yielding normalized residual e ^ i as
e ^ i = e i s ¯ i + ε
where ε > 0 is a small constant for numerical stability, and s ¯ i is obtained as
s ¯ i = 1 k r m = 1 k r s i m
Based on the normalized residual, the local plane residual score S g ( p i ) is defined as
S g ( p i ) = exp ( e ^ i 2 2 σ g 2 )
where σ g is the scale parameter for geometric residuals. A larger S g ( p i ) indicates that the candidate point is better aligned with the local reference surface, suggesting that it is more likely to be a inlier point.
The two scores are combined into a unified completion score:
S ( p i ) = λ S p ( p i ) + ( 1 λ ) S g ( p i )
where λ [ 0 , 1 ] is a balancing factor.
All candidate points are ranked according to S ( p i ) , and those with sufficiently high scores are selected as follows:
P r e c o v e r = S O R { p i P c a n d i d a t e | S ( p i ) > τ q }
where τ q is the q -quantile of the score distribution over P c a n d i d a t e , and candidate points with scores higher than τ q are preserved. SOR [10] is then applied to these retained points, obtaining the recovered point clouds P r e c o v e r .
The final point clouds P r e s u l t are then obtained as
P r e s u l t = P c l e a n P r e c o v e r
where the operator represents the union operation, which merges the retained clean points and the recovered inlier points to form the final point clouds. The reference-guided completion stage compensates for the possible loss of valid structural points during aggressive filtering. By recovering mistakenly removed inlier points from the candidate points, this stage improves the balance between outlier removal and geometric structure preservation.

4. Results

4.1. Test Conditions

To quantitatively evaluate the performance of MORPH, three criteria are adopted, including precision, recall and accuracy [16]. In our evaluation, Precision measures the proportion of inlier points among all retained points, while Recall measures the proportion of inlier points that are correctly retained. Accuracy reflects the overall correctness of the classification results. The metrics are defined as follows:
P r e c i s i o n = T P T P + F P
R e c a l l = T P T P + F N
A c c u r a c y = T P + T N T P + T N + F P + F N
where T P denotes the number of retained inlier points, T N denotes the number of removed outliers, F P denotes the number of retained outliers, F N denotes the number of removed inlier points.
The proposed method is compared with several outlier removal methods on the synthetic PointCleanNet dataset [22]. For evaluation, sixteen point cloud models are selected, and two outlier ratios, 50% and 70%, are considered for each model. In addition, real-world single-photon 3D scanned data are used as a representative challenging application scenario to evaluate the practical effectiveness of the proposed method under real high-outlier-ratio acquisition conditions. The real-world scanned point clouds were acquired using a single-photon avalanche diode (SPAD)-based 3D imaging prototype [28]. Inlier and outlier labels of the real-world scanned point clouds are manually annotated according to the 3D spatial distribution and local geometric consistency of the points. The annotated real scanned point clouds have an outlier ratio of approximately 50–60%.
The proposed method is compared with ten state-of-the-art methods, i.e., the SOR method [10], the local density method [29], the non-iterative method [30], the TBORF method [31], the CIMD method [8], the PointCVaR method [7], the PointCleanNet method [22], the STORED method [32], the MHD method [33], and the SDOR method [34]. All methods are implemented in Python (v3.12) and all experiments were conducted on a laptop equipped with a 13th Gen Intel Core i9-13980HX CPU and 16 GB RAM.
In the following experiments, synthetic data are first used to evaluate the effectiveness of the proposed method under controlled outlier settings, and the results of PointCleanNet [22] and PointCVaR [7] are obtained using their pre-trained models. For parameter settings of the remaining traditional baselines, the balance between recall and precision is taken into consideration.

4.2. Performance Evaluation on Synthetic Data

Table 1 shows the performance evaluation results on the synthetic PointCleanNet dataset with outlier ratios of 50% and 70%. Under the 50% outlier ratio, MORPH obtains the highest average precision and accuracy, reaching 0.9495 and 0.9427, respectively, while maintaining the second-best recall of 0.9375. These results indicate that MORPH can effectively remove outliers while preserving most valid geometric structures. Meanwhile, MHD achieves the second-best precision of 0.9361, which is mainly attributed to its multiscale hierarchical strategy that can suppress outliers at different structural scales. PointCVaR also shows highly competitive performance because its risk-based strategy learns point-wise risk through gradient attribution, enabling it to identify and remove high-risk outliers while maintaining a relatively balanced result. Traditional methods such as SOR and local density perform relatively poorly because their decision criteria are easily affected by dense outliers. Among the traditional methods, non-iterative, CIMD, and SDOR achieve relatively better results, suggesting that multi-stage outlier removal strategies are more effective than single-criterion outlier removal methods.
When the outlier ratio increases to 70%, most methods exhibit clear performance degradation because dense outliers become dominant in the point clouds and severely corrupt local neighborhood information, including distance distributions, density estimates, and local geometric structures. SOR is the most severely affected method, with precision and accuracy dropping to 0.0909 and 0.3141, respectively, indicating that simple distance-based filtering is almost ineffective when local statistics are dominated by outliers. PointCleanNet maintains a high recall of 0.9513, but its precision decreases sharply to 0.5750, mainly because the extremely high outlier ratio corrupts the local patches used by its PCPNet-based outlier detector, making it difficult to learn reliable local surface structures and causing many outliers to be retained. MHD achieves the second-best precision and accuracy of 0.8501 and 0.9094, respectively, which can be attributed to its multiscale hierarchical strategy that reduces the dependence on a single local neighborhood and helps suppress outliers at different structural scales. In contrast, MORPH achieves the highest precision and accuracy under the 70% outlier ratio, reaching 0.9099 and 0.9440, respectively, while maintaining the second-best recall of 0.9062. These results demonstrate that MORPH provides a more reliable trade-off between outlier removal and inlier preservation under severe contamination.
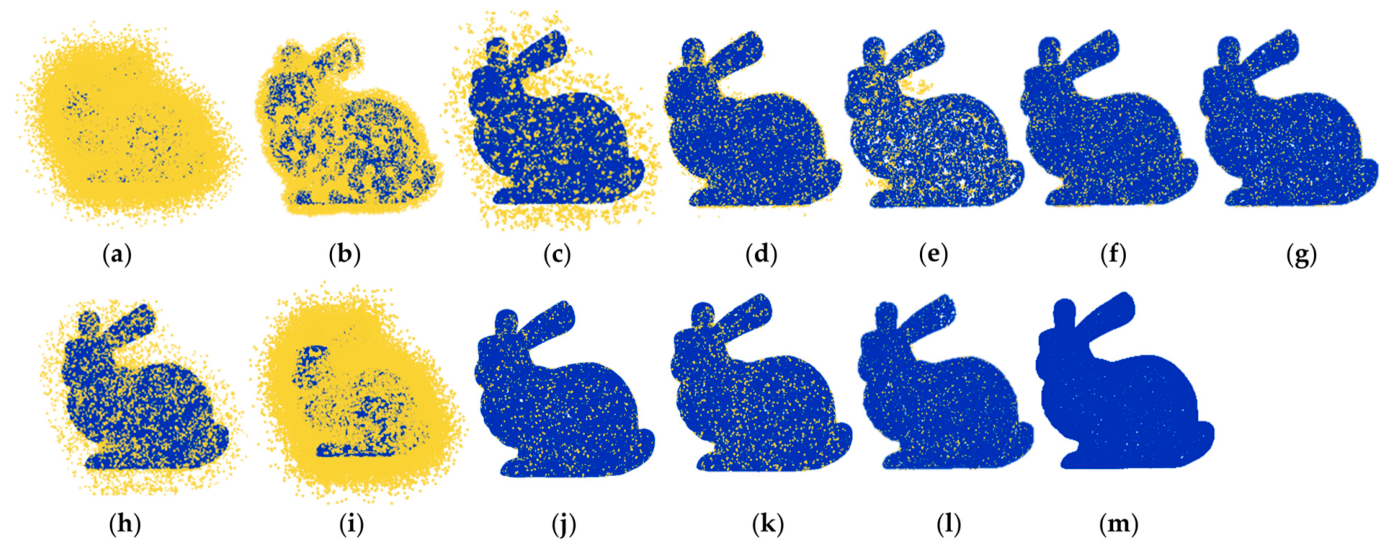
Figure 2 presents the visual comparison of the Bunny model under 50% outlier contamination. SOR and STORED retain a large number of outliers, indicating that their filtering criteria are not sufficiently robust when outliers are densely distributed around the object. CIMD, PointCVaR, MHD, and SDOR remove more surrounding outliers than SOR and STORED, but noticeable structural loss can be observed. This indicates that these methods may mistakenly remove valid inlier points while suppressing outliers, leading to incomplete geometric structures. Among all compared methods, MORPH achieves the cleanest visual result, with only a small number of residual outliers while maintaining the overall shape and boundary details of the Bunny. This indicates that the proposed multi-stage strategy can effectively suppress dense outliers while preserving valid geometric structures.
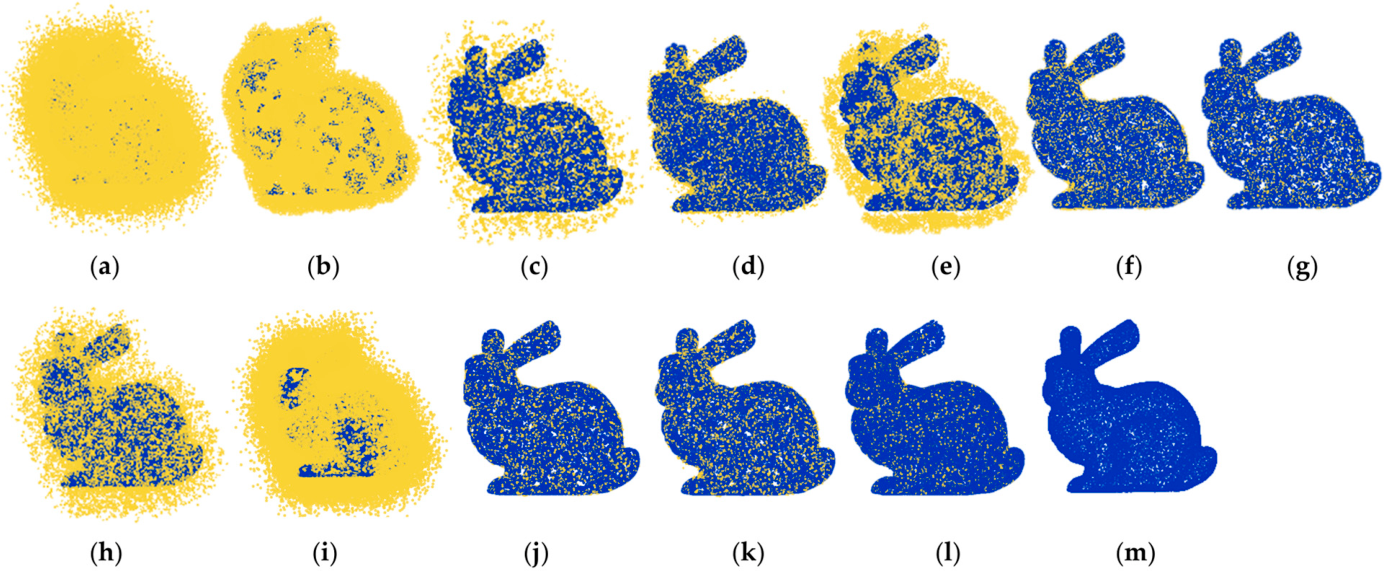
Figure 3 shows the visual comparison of the Bunny model under 70% outlier contamination. Compared with the results in the 50% case, all the comparative algorithms show a significant performance drop. PointCleanNet preserves the main object structure but also retains many surrounding outliers, which is consistent with its conservative point-preservation behavior under severe contamination. MORPH produces the cleanest result, with the fewest residual outliers and the most complete Bunny structure, making it closest to the clean point clouds. This demonstrates the superiority of the proposed multi-stage removal and reference-guided completion strategy in balancing outlier suppression and geometric structure preservation under severe contamination.

4.3. Performance Evaluation on Real-World Single-Photon 3D Scanned Data

To further evaluate the practical robustness of MORPH, we conduct experiments on point clouds acquired in a single-photon 3D imaging scenario. Unlike synthetic data, outliers in SPAD-acquired point clouds are not simply uniformly distributed random noise. Instead, due to background responses, dark counts, and uncertainties in photon counting and depth reconstruction, these point clouds often suffer from severe and spatially uneven outlier contamination [28]. Moreover, such outliers are frequently interleaved with valid geometric structures, making reliable discrimination between inliers and outliers more challenging. Therefore, SPAD-acquired point clouds provide a real-world scenario for evaluating the robustness of point clouds outlier removal methods under high outlier ratio conditions.
As shown in Table 2, SOR and local density perform poorly, with average accuracy values of only 0.3931 and 0.6030, respectively, mainly because uneven density and irregular outliers make simple distance-based criteria unreliable. CIMD shows strong performance, with average accuracy values of 0.9730. This can be attributed to CIMD’s completion-based processing strategy, which helps preserve valid structures and improve robustness across different spatial scales. PointCleanNet achieves the highest average recall of 0.9799 but a lower precision of 0.8418, indicating that its pretrained model tends to preserve points conservatively and retains many outliers. In contrast, MORPH achieves the best average precision and accuracy, both reaching 0.9802, while maintaining a high average recall of 0.9714. These results demonstrate that MORPH achieves superior performance in removing outliers from real-world scanned SPAD data.
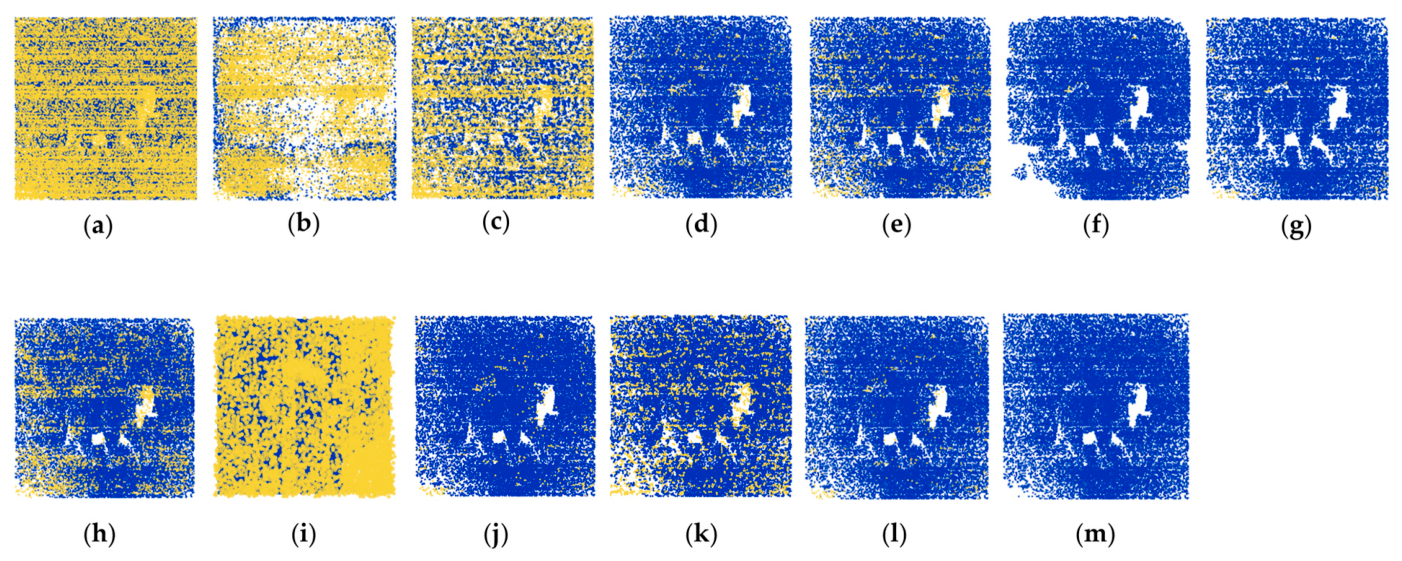
Figure 4 presents the visual comparison of real-world single-photon 3D imaging point clouds, where the outliers are more irregularly distributed and strongly mixed with the underlying geometric structures. SOR and local density remove only part of the obvious outliers, while many noisy points are still retained. PointCleanNet also leaves substantial residual outliers, suggesting limited generalization when the real noise distribution differs from the synthetic training setting. STORED performs poorly in this case, as a large number of outliers are still retained. MHD achieves relatively competitive visual performance by preserving the main structure more clearly than several other compared methods, which benefits from its multiscale hierarchical strategy. MORPH produces cleaner point clouds that are visually closer to the clean references while preserving object contours and local structural details. These results further demonstrate the practical robustness of the proposed method.
Although the quantitative and visual results demonstrate that MORPH can effectively suppress spatially irregular outliers and preserve major geometric structures in real-world scanned point clouds, its recovery capability is still limited in extremely sparse regions. Specifically, when valid inlier points are isolated or weakly supported by neighboring structures, the reference point clouds generated from the incomplete point clouds may not provide sufficient geometric cues to distinguish them from residual outliers. As a result, a small number of valid structural points may remain unrecovered after the completion stage. This suggests that more effective use of local geometric information may help improve the recovery of valid inlier points in sparsely sampled regions.

4.4. Ablation Study

To analyze the contribution of each component in MORPH, an ablation study is conducted by progressively adding the structure-adaptive refinement and reference-guided completion stages to the coarse removal baseline. This experiment is performed under the 70% outlier-ratio setting, and the reported results are averaged over all sixteen synthetic point cloud models.
As shown in Table 3, the coarse outlier removal stage achieves an accuracy, recall, and precision of 0.9058, 0.8410, and 0.8444, respectively, showing that it can remove obvious outliers but remains limited in ambiguous and structurally complex regions. After introducing the structure-adaptive refinement module, all three metrics improve to 0.9177, 0.8620, and 0.8641, respectively, indicating that local structure-aware refinement enhances decision reliability and reduces both residual outliers and falsely removed inlier points. With the full MORPH framework, the results are further improved to 0.9440 in accuracy, 0.9062 in recall, and 0.9099 in precision, which are the best among all settings. This confirms that the combination of the three components achieves the best performance in outlier removal.

4.5. Module-Level Comparison Between CIMD and MORPH

To further distinguish the proposed MORPH from our previous work CIMD and clarify the contribution of each redesigned component, a module-level comparison is conducted. The comparison is conducted on the PointCleanNet synthetic dataset under the 70% outlier-ratio setting, and the reported results are averaged over all sixteen point clouds models.
As shown in Table 4, MORPH consistently outperforms CIMD across different module levels. In the coarse outlier removal stage, where both methods take the raw point clouds as input, MORPH-COR achieves higher precision, recall, and accuracy than CIMD-COR, reaching 0.7624, 0.9984, and 0.9062, respectively. This improvement shows that the LRD-DPC-based coarse removal strategy can effectively eliminate prominent outliers while preserving most inlier points. After refinement, MORPH-R further improves precision to 0.9826 and accuracy to 0.8743 compared with CIMD-R, despite a slight decrease in recall, indicating stronger suppression of residual outliers. In the completion stage, MORPH-PCC achieves the best performance among the compared completion modules, with precision, recall, and accuracy of 0.9099, 0.9062, and 0.9440, respectively. This result verifies the effectiveness of the reference-guided completion strategy in identifying valid candidate points and restoring mistakenly removed inliers. Moreover, the full MORPH framework clearly outperforms the full CIMD framework; these results confirm that MORPH demonstrates a module-level performance advantage over CIMD for point clouds with a high ratio of outliers.

4.6. Computation Time Cost of Processing

Table 5 presents the computational cost comparison of different methods, measured in seconds. All methods were implemented in Python (v3.12) and evaluated on the same hardware platform. PointCVaR and PointCleanNet, as learning-based methods, were executed with CUDA acceleration, while all other methods were executed on the CPU. The reported results represent the average runtime over 30 repeated runs for each method.
As shown in Table 5, SOR achieves the shortest runtime on all datasets because it adopts a simple single-stage statistical filtering strategy. Local density, non-iterative, TBORF, CIMD, STORED, MHD, and SDOR also show relatively low computational costs compared with learning-based methods or completion-based methods with reference construction. PointCVaR requires more time than most non-learning-based methods due to neural network inference, whereas PointCleanNet shows the longest runtime because of its patch-based point-wise feature extraction and prediction process. Although MORPH achieves the best overall outlier removal performance, its runtime is higher than that of most non-learning-based methods, with average computation times of 24.2988 s, 25.1201 s, and 7.1615 s on the Synthetic-50%, Synthetic-70%, and real-world scanned datasets, respectively. This additional computational cost mainly comes from the reference-guided completion stage, where Poisson upsampling is used to construct the reference point clouds.

4.7. Parameter Selection and Adjustment

The proposed MORPH contains several stage-related parameters that have a direct influence on outlier removal performance. The representative parameter values used in the experiments are described below, together with their selection principles.
(1) Coarse outlier removal parameters. The parameters k and M are used in the LRD-DPC-based coarse outlier removal stage. Specifically, k controls the local neighborhood size for estimating local reachability density and density-peak characteristics. Since the raw point clouds contain a large number of outliers, a relatively larger neighborhood is preferred to obtain stable density estimation. In this study, k = 20 is adopted, and a reasonable range is usually [ 10 ,   30 ] . The parameter M denotes the number of points removed in the coarse removal stage. A larger M removes more obvious outliers, but may also increase the risk of discarding weak-return inlier points; a smaller M preserves more valid points, but may leave more residual outliers for subsequent refinement. In this study, M = 65,000 is used as the representative setting for 140k-scale point clouds, and reasonable values are generally in the range of [ 40,000 ,   85,000 ] for the tested datasets.
(2) Structure-adaptive refinement parameters. The parameters k c , σ r , α , and β control the structure-adaptive refinement stage. Here, k c determines the neighborhood size for local plane fitting and normal estimation. A larger k c provides more stable geometric estimation, whereas an excessively large value may smooth local details. Therefore, k c = 50 is adopted, with a recommended range of [ 30 , 70 ] . The parameters σ r , α , and β further control the strictness of refinement: σ r affects the residual-based threshold, α adjusts the robust statistics-based threshold, and β regulates the normal-consistency criterion. Smaller values lead to stricter filtering and remove more residual outliers, but may also discard valid inliers in sparse or weak-return regions; larger values preserve more points but may retain residual noise. In this study, σ r = 0.1 , α = 0.1 , and β = 1 are used. The recommended ranges are [ 0.1 , 1.0 ] for σ r , [ 0.1 , 1.0 ] for α , and [ 0.5 , 1.5 ] for β .
(3) Reference-guided completion parameters. The parameters k r and k q determine the local neighborhoods used in the reference-guided completion stage. The parameter k r controls the reference neighborhood size for scale-consistency estimation, while k q controls the query neighborhood size for candidate point scoring. Larger values provide more stable local geometric estimation, but excessively large neighborhoods may smooth local details. In this study, k r = 50 and k q = 20 are used, with recommended ranges of [15, 50] and [5, 30], respectively. The parameter λ balances the contributions of pairwise scale consistency and local plane residual scoring. A larger λ increases the influence of scale consistency, whereas a smaller value emphasizes local plane residuals. In this study, λ = 0.5 , and reasonable values are in the range of [0.3, 0.7]. The parameter q controls the quantile threshold for selecting recovered candidate points. A smaller q leads to stricter recovery and fewer residual outliers, while a larger q recovers more inlier points but may introduce additional noise. In this study, q = 0.38 , and the recommended range is [0.05, 0.40].

5. Discussion

5.1. Limitations

Although MORPH achieves robust outlier removal performance, several aspects can be further improved. First, its computational cost is relatively high, mainly because Poisson upsampling is required to construct dense reference point clouds in the completion stage, making the current implementation more suitable for offline preprocessing than strict real-time applications. Moreover, the labels of real SPAD-acquired point clouds are obtained through manual annotation. Although the labels were carefully checked, minor labeling uncertainties may still exist due to the ambiguity of some real scanned points. In addition, when processing some point clouds, the recovery of valid inlier points in extremely sparse regions may remain challenging.

5.2. Future Work

Future work will mainly focus on improving the computational efficiency of MORPH and broadening its real-world evaluation. More efficient reference point cloud generation strategies will be investigated to reduce the computational cost of the completion stage while maintaining or further enhancing outlier removal performance. In addition, reliable real-world benchmark datasets will be constructed based on robust annotation methods, such as multi-view verification and consensus-based annotation, to support more accurate quantitative evaluation and fair comparison of outlier removal algorithms. Beyond constructing reliable benchmark datasets for SPAD-acquired point clouds, future work will further explore SPAD-oriented point cloud outlier removal strategies that incorporate acquisition-specific noise characteristics, such as spatially non-uniform outliers, background responses, and photon-counting uncertainty.

6. Conclusions

In this study, we proposed MORPH, a multi-stage outlier removal method for point clouds with high outlier ratios. The proposed method consists of three complementary stages: coarse outlier removal, structure-adaptive refinement, and reference-guided completion. In the first stage, LRD-DPC is used to remove prominent outliers while preserving the main structural skeleton of the input point clouds. In the second stage, a structure-adaptive refinement strategy further removes residual outliers by exploiting cluster-wise geometric features, producing clean but incomplete point clouds together with candidate points. In the final stage, the dense reference point clouds are constructed from the refined clean subset, and a reference-guided completion strategy is developed by combining pairwise scale consistency and local plane residuals to recover falsely removed valid structural points. Experiments on synthetic high outlier ratio point clouds and real-world single-photon scanned data demonstrate that MORPH achieves robust outlier removal performance and better preserves geometric structures compared with existing methods. The ablation study further verifies the contribution of each component and confirms the effectiveness of reference-guided completion for recovering misclassified inlier points.

Author Contributions

Methodology, Z.M. and C.Q.; software, Z.M. and P.C.; validation, Z.M. and Y.T.; formal analysis, Z.M., C.Q., P.C. and Y.T.; data curation, Z.M., C.Q. and P.C.; writing—original draft, Z.M.; writing—review and editing, Z.M., C.Q. and P.C.; visualization, Y.T. All authors have read and agreed to the published version of the manuscript.

Funding

This work was supported in part by the Basic Research Program of Jiangsu, China (BK20250739).

Data Availability Statement

The data presented in this study are available on request from the corresponding author.

Conflicts of Interest

The authors declare no conflicts of interest.

References

  1. Lai, Q.; Xin, Q.; Tian, Y.; Chen, X.; Li, Y.; Wu, R. Structural analysis and 3D reconstruction of underground pipeline systems based on LiDAR point clouds. Remote Sens. 2025, 17, 341. [Google Scholar] [CrossRef] [Scilit]
  2. Yao, R.; Wang, H.; Guo, Y.; Xie, Z. A real-time fusion of two-stage point cloud clustering and saliency image for water surface object detection. Remote Sens. 2025, 17, 3708. [Google Scholar]
  3. Li, M.; Li, M.; Li, M.; Xu, L. Building lightweight 3D indoor models from point clouds with enhanced scene understanding. Remote Sens. 2025, 17, 596. [Google Scholar] [CrossRef] [Scilit]
  4. Wang, G.; Gao, X.; Zhang, T.; Xu, Q.; Zhou, W. LiDAR odometry and mapping based on neighborhood information constraints for rugged terrain. Remote Sens. 2022, 14, 5229. [Google Scholar] [CrossRef] [Scilit]
  5. Wang, R.; Wan, J.; Li, X.; Tan, S. Fast and robust outlier detection: A granular-ball center isolation and region consistency approach. Pattern Recognit. 2026, 176, 113212. [Google Scholar] [CrossRef] [Scilit]
  6. Li, W.; Yang, Y.; Zhang, W.; Gao, Y.; Jin, Z. DHE-Net: Dual-encoder hierarchical network for real-world low-cost LiDAR point cloud denoising. IEEE Trans. Ind. Inform. 2026, 22, 2770–2781. [Google Scholar]
  7. Li, X.; Lu, J.; Ding, H.; Sun, C.; Zhou, J.T.; Chee, Y.M. PointCVaR: Risk-optimized outlier removal for robust 3D point cloud classification. In Proceedings of the AAAI Conference on Artificial Intelligence, Vancouver, BC, Canada, 20–27 February 2024; Volume 38, pp. 21340–21348. [Google Scholar]
  8. Qu, C.; Zhang, Y.; Huang, K.; Wang, S.; Yang, Y. Point clouds outlier removal method based on improved Mahalanobis and completion. IEEE Robot. Autom. Lett. 2022, 8, 17–24. [Google Scholar] [CrossRef] [Scilit]
  9. Watanabe, R.; Sridhara, S.N.; Hong, H.; Pavez, E.; Nonaka, K.; Kobayashi, T.; Ortega, A. Full reference point cloud quality assessment using support vector regression. Signal Process. Image Commun. 2025, 131, 117239. [Google Scholar]
  10. Rusu, R.B.; Marton, Z.C.; Blodow, N.; Dolha, M.; Beetz, M. Towards 3D point cloud based object maps for household environments. Robot. Auton. Syst. 2008, 56, 927–941. [Google Scholar] [CrossRef] [Scilit]
  11. Balta, H.; Velagic, J.; Bosschaerts, W.; De Cubber, G.; Siciliano, B. Fast statistical outlier removal based method for large 3D point clouds of outdoor environments. IFAC-PapersOnLine 2018, 51, 348–353. [Google Scholar] [CrossRef] [Scilit]
  12. Zeybek, M. Inlier point preservation in outlier points removed from the ALS point cloud. J. Indian Soc. Remote Sens. 2021, 49, 2347–2363. [Google Scholar] [CrossRef] [Scilit]
  13. Roriz, R.; Campos, A.; Pinto, S.; Gomes, T. DIOR: A hardware-assisted weather denoising solution for LiDAR point clouds. IEEE Sens. J. 2021, 22, 1621–1628. [Google Scholar]
  14. Rodriguez, A.; Laio, A. Clustering by fast search and find of density peaks. Science 2014, 344, 1492–1496. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  15. Xia, H.; Zhou, Y.; Li, J.; Bai, L.; Li, J.; Zhou, F. Outlier detection via optimized density peaks clustering and K-means-derived objective function. Chaos Solitons Fractals 2025, 199, 116791. [Google Scholar]
  16. Xie, J.; Zhong, C.; Tian, Y.; Hu, L.; Pan, T. Robust density clustering based on density peak regions and K-nearest neighbors. Pattern Recognit. 2025, 174, 113021. [Google Scholar] [CrossRef] [Scilit]
  17. Wang, Y.; Wang, D.; Zhou, Y.; Zhang, X.; Quek, C. VDPC: Variational density peak clustering algorithm. Inf. Sci. 2023, 621, 627–651. [Google Scholar]
  18. Nurunnabi, A.; West, G.; Belton, D. Outlier detection and robust normal-curvature estimation in mobile laser scanning 3D point cloud data. Pattern Recognit. 2015, 48, 1404–1419. [Google Scholar] [CrossRef] [Scilit]
  19. Xi, G.; Wang, C.; Liu, X.; Xiao, B.; Ding, Y. Point cloud denoising method based on local neighborhood features. Opt. Laser Technol. 2026, 193, 114144. [Google Scholar]
  20. Xu, Q.C.; Yang, Y.L.; Deng, B. Point cloud denoising using a generalized error metric. Graph. Models 2024, 133, 101216. [Google Scholar] [CrossRef] [Scilit]
  21. Chen, J.; Gao, F.; Chen, P.; Lin, W. Efficient non-local point cloud denoising using curvature entropy and γ-norm minimization. IEEE Trans. Vis. Comput. Graph. 2025, 31, 8738–8754. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  22. Rakotosaona, M.J.; La Barbera, V.; Guerrero, P.; Mitra, N.J.; Ovsjanikov, M. PointCleanNet: Learning to denoise and remove outliers from dense point clouds. Comput. Graph. Forum 2020, 39, 185–203. [Google Scholar]
  23. Wang, X.; Cui, W.; Xiong, R.; Fan, X.; Zhao, D. FCNet: Learning noise-free features for point cloud denoising. IEEE Trans. Circuits Syst. Video Technol. 2023, 33, 6288–6301. [Google Scholar] [CrossRef] [Scilit]
  24. Seppanen, A.; Ojala, R.; Tammi, K. 4DenoiseNet: Adverse weather denoising from adjacent point clouds. IEEE Robot. Autom. Lett. 2023, 8, 456–463. [Google Scholar]
  25. Du, P.; Wang, X.; Wu, Z.; Ru, X.; Granier, X.; He, Y. LaPDA: Latent-space point cloud denoising with adaptivity. IEEE Trans. Vis. Comput. Graph. 2026, 32, 1525–1539. [Google Scholar] [PubMed]
  26. Jiao, X.; Lv, C.; Zhao, J.; Yi, R.; Wen, Y.H.; Pan, Z.; Wu, Z.; Liu, Y.J. Weighted Poisson-disk resampling on large-scale point clouds. In Proceedings of the AAAI Conference on Artificial Intelligence, Philadelphia, PA, USA, 25 February–4 March 2025; Volume 39, pp. 4084–4092. [Google Scholar]
  27. Lee, S.H.; Civera, J.; Vandewalle, P. PCR-99: A practical method for point cloud registration with 99 percent outliers. In Computer Vision—ECCV 2024 Workshops; Del Bue, A., Canton, C., Pont-Tuset, J., Tommasi, T., Eds.; Springer Nature: Cham, Switzerland, 2025; pp. 14–29. [Google Scholar]
  28. Lindell, D.B.; O’Toole, M.; Wetzstein, G. Single-Photon 3D Imaging with Deep Sensor Fusion. ACM Trans. Graph. 2018, 37, 113. [Google Scholar] [CrossRef] [Scilit]
  29. Ning, X.; Li, F.; Tian, G.; Wang, Y. An efficient outlier removal method for scattered point cloud data. PLoS ONE 2018, 13, e0201280. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  30. Zhou, S.; Liu, X.; Wang, C.; Yang, B. Non-iterative denoising algorithm based on a dual threshold for a 3D point cloud. Opt. Lasers Eng. 2020, 126, 105921. [Google Scholar] [CrossRef] [Scilit]
  31. Ge, L.; Feng, J. Type-based outlier removal framework for point clouds. Inf. Sci. 2021, 580, 436–459. [Google Scholar] [CrossRef] [Scilit]
  32. Kim, I.; Singh, S.K. 3D point cloud denoising via Gaussian processes regression. Vis. Comput. 2025, 41, 10481–10496. [Google Scholar] [CrossRef] [Scilit]
  33. Liu, S.; Mohd Jaki, B.M.; Huang, Y.; Dong, M.; Liu, Q. Multiscale hierarchy denoising method for heritage building point cloud model noise removal. npj Herit. Sci. 2025, 13, 199. [Google Scholar] [CrossRef] [Scilit]
  34. Shin, S.; Joo, J.; Lee, H.; Kim, S.C. Spatially divided outlier removal for LiDAR de-noising in adverse weather conditions. Sci. Rep. 2026, 16, 11480. [Google Scholar] [PubMed]
Figure 1. Illustration of the proposed MORPH framework.
Remotesensing 18 02289 g001
Figure 2. Visual comparison of outlier removal results on the PointCleanNet synthetic dataset under 50% outlier contamination, using the bunny model as a representative example. Different methods are compared: (a) original point clouds; (b) SOR; (c) local density; (d) non-iterative; (e) TBORF; (f) CIMD; (g) PointCVaR; (h) PointCleanNet; (i) STORED; (j) MHD; (k) SDOR; (l) MORPH; (m) clean point clouds. Blue and yellow points indicate inlier points and outliers, respectively.
Remotesensing 18 02289 g002
Figure 3. Visual comparison of outlier removal results on the PointCleanNet synthetic dataset under 70% outlier contamination, using the bunny model as a representative example. Different methods are compared: (a) original point clouds; (b) SOR; (c) local density; (d) non-iterative; (e) TBORF; (f) CIMD; (g) PointCVaR; (h) PointCleanNet; (i) STORED; (j) MHD; (k) SDOR; (l) MORPH; (m) clean point clouds. Blue and yellow points indicate inlier points and outliers, respectively.
Remotesensing 18 02289 g003
Figure 4. Visual comparison of outlier removal results on real-world single-photon 3D imaging point clouds, with the elephant model shown as a representative example. Different methods are compared: (a) original point clouds; (b) SOR; (c) local density; (d) non-iterative; (e) TBORF; (f) CIMD; (g) PointCVaR; (h) PointCleanNet; (i) STORED; (j) MHD; (k) SDOR; (l) MORPH; (m) clean point clouds. Blue and yellow points indicate inlier points and outliers, respectively.
Remotesensing 18 02289 g004
Table 1. Quantitative comparison of different outlier removal methods under 50% and 70% outlier-ratio conditions.
Method50% Outlier Ratio70% Outlier Ratio
PrecisionRecallAccuracyPrecisionRecallAccuracy
SOR0.45330.45730.45400.09090.14460.3141
Local Density0.86480.86490.86480.73490.74180.8422
Non-iterative0.89850.90360.90070.77030.76650.8615
TBORF0.93350.93510.93440.79490.79410.8767
CIMD0.92440.92780.92600.80670.81450.8847
PointCVaR0.93310.93720.93510.84820.85270.9089
PointCleanNet0.84010.97910.89640.57500.95130.7745
STORED0.47760.47770.47770.26790.30010.5322
MHD0.93610.93290.93460.85010.84720.9094
SDOR0.89550.90350.89900.7791 0.77240.8647
MORPH0.94950.93750.94270.90990.90620.9440
Note: Bold indicates the best result, and the underline indicates the second-best result.
Table 2. Quantitative comparison on real-world single-photon 3D imaging point clouds.
MethodMetricElephantCheckerboardHallwayKitchenLampAverage
SORPrecision0.36260.80950.10140.23210.15000.3311
Recall0.41260.78890.12570.24780.19100.3532
Accuracy0.37950.77710.24740.30220.25950.3931
Local DensityPrecision0.54890.61420.53030.55650.51870.5537
Recall0.56150.61890.53800.53610.54180.5593
Accuracy0.57460.56750.64470.60450.62370.6030
Non-IterativePrecision0.96190.94070.93570.91940.90770.9331
Recall0.96160.94640.94610.96650.93340.9508
Accuracy0.96390.93640.95500.94750.93670.9479
TBORFPrecision0.94730.93950.88090.92560.87300.9133
Recall0.95270.95330.86440.94370.85830.9145
Accuracy0.95250.93930.90440.94130.89560.9266
CIMDPrecision0.99540.96530.96140.97460.96580.9725
Recall0.96690.94900.97420.97610.97570.9684
Accuracy0.98220.95220.97540.97810.97700.9730
PointCVaRPrecision0.85650.96690.97910.96920.95570.9455
Recall0.99650.94670.97070.98260.97630.9746
Accuracy0.91940.95190.97430.97840.97310.9594
PointCleanNetPrecision0.84040.83010.88000.85870.80000.8418
Recall0.99370.96580.98170.97020.98830.9799
Accuracy0.92200.88810.94840.92560.92560.9219
STOREDPrecision0.77380.88210.80190.82420.77580.8116
Recall0.77110.87780.80740.81980.71050.7973
Accuracy0.78520.86540.85160.84240.71510.8119
MHDPrecision0.97710.96750.97180.97800.98720.9763
Recall0.99290.94730.97540.96960.96070.9692
Accuracy0.98560.95250.98000.97680.97980.9749
SDORPrecision0.89180.94000.93750.90900.85850.9074
Recall0.90650.96710.93660.89350.85720.9122
Accuracy0.90380.94690.95230.91300.88870.9209
MORPHPrecision0.98160.97580.97640.97760.98940.9802
Recall0.99250.96840.96170.97400.96020.9714
Accuracy0.98770.97760.97670.97850.98040.9802
Note: Bold indicates the best result, and the underline indicates the second-best result.
Table 3. Ablation study results.
Included StagesVariantCORRPCCPrecisionRecallAccuracy
Stage 1: CORw/o R and PCC 0.84440.84100.9058
Stage 2: COR + Rw/o PCC 0.86410.86200.9177
Stage 3: COR + R + PCCFull MORPH0.90990.90620.9440
Note: w/o means without. COR means coarse outlier removal; R means refinement; PCC means point cloud completion. The best results among all variants are highlighted in bold.
Table 4. Module-level quantitative comparison between CIMD and MORPH under 70% outlier ratio condition.
Input DataModulePrecisionRecallAccuracy
Raw point cloudsCIMD-COR0.65870.98280.8421
MORPH-COR0.76240.99840.9062
MORPH-COR outputCIMD-R0.86420.59780.8487
MORPH-R0.98260.59170.8743
MORPH candidate pointsCIMD-PCC0.87870.86170.9228
MORPH-PCC 0.90990.90620.9440
Raw point cloudsCIMD-FULL0.81180.82080.8891
MORPH-FULL0.90990.90620.9440
Note: COR means coarse outlier removal, R means refinement, and PCC means point cloud completion. The best result within each stage is highlighted in bold.
Table 5. Runtime comparison of different outlier removal methods on synthetic and scanned datasets.
DatasetSORLocal DensityNon-IterativeTBORFCIMDPointCVaRPointCleanNetSTOREDMHDSDORMORPH
Synthetic-50% 0.56202.32652.56211.92881.287413.3162209.70033.41298.64203.221924.2988
Synthetic-70% 0.58972.45882.60442.05981.363918.1325212.54023.023511.33583.834225.1201
Scanned data0.44080.77940.82070.57980.59234.563386.23641.86212.60181.14067.1615
Note: Runtime is reported in seconds. Bold indicates the shortest runtime for each dataset.
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content.