Article

RESC: A Rubric-Guided Error–Score Consistency Framework for Action Quality Assessment in Vocational Fitter Training


1
School of Automation, Guangxi University of Science and Technology, Liuzhou 545006, China
2
Guangxi Low-Altitude Unmanned Aircraft Key Technologies Engineering Research Center, Liuzhou 545616, China
*
Author to whom correspondence should be addressed.
Sensors 2026, 26(17), 5575; https://doi.org/10.3390/s26175575
Submission received: 25 July 2026 / Revised: 25 August 2026 / Accepted: 31 August 2026 / Published: 2 September 2026

Abstract

Action quality assessment in vocational fitter training is constrained by limited expert-annotated data and insufficiently interpretable predictions. To achieve accurate scoring and rubric-aligned, auditable explanations with limited data, this study proposes RESC, a rubric-guided error–score consistency framework. RESC uses human pose as its primary visual evidence and converts an instructor rubric into error semantics and scoring constraints. It therefore predicts an overall score while producing rubric-aligned error diagnoses and model-derived itemized deduction contributions. We constructed Fitter-AQA, a dataset of 134 filing videos from 25 participants, and evaluated the framework using strict leave-one-subject-out cross-validation. RESC achieved a mean absolute error of 4.450, a Pearson linear correlation coefficient of 0.902, and a Spearman rank correlation coefficient of 0.852, corresponding to the lowest pooled scoring errors and highest pooled correlations among the evaluated methods. Error diagnosis reached a Macro-F1 of 0.770 and a macro-average balanced accuracy of 0.824. These results indicate stable cross-subject scoring under limited-data conditions and transform model predictions into an auditable score decomposition aligned with rubric semantics. RESC thus provides an accurate and interpretable approach to automated assessment in vocational skills training.

1. Introduction

Action quality assessment (AQA) quantifies how well a human action is performed. It extends deep learning-based human action analysis from category recognition to skill evaluation [1]. Unlike action recognition, which mainly determines what action is being performed, AQA must distinguish subtle differences in technical compliance and execution quality within the same action. These differences must then be translated into meaningful quality judgements. With advances in three-dimensional convolutional networks, spatiotemporal graph convolutional networks, and Transformers, RGB videos and human pose sequences have become the main inputs for AQA [2,3,4]. Contrastive regression, relative ranking, and procedural parsing further improve the representation of quality levels and local execution differences [5,6,7,8]. These advances have extended AQA from competitive sports to rehabilitation and professional skill assessment. Most deep learning-based AQA methods learn a direct mapping from full-video spatiotemporal representations to an overall score. This strategy captures stage relations and overall execution quality from continuous motion. However, in vocational training, video-level score supervision may encourage models to exploit quality-related patterns that lack instructional meaning. Differences in body shape, movement habits, and operating speed can further impair generalization to unseen trainees, even when training-set fitting is satisfactory. A total score can indicate whether an action was performed well, but it cannot locate an error or quantify its severity and associated deduction. Therefore, vocational skill AQA requires both reliable cross-subject scoring and evaluation evidence that instructors and trainees can understand.
The collection and annotation of authentic vocational skill videos are constrained by workstation conditions, participant coordination, and the cost of expert assessment [9,10,11,12,13]. Unlike isolated actions that can be repeatedly recorded under standardized conditions, manual filing in fitter training involves continuous interaction between the body and the tool. The recording process is also affected by workstation occlusion, lighting variation, and individual differences in stance. Quality differences are often concentrated in local body cues. Consequently, each error category contains relatively few valid samples, and repeated recording does not readily produce a balanced data distribution. Limited sample size is therefore an inherent characteristic of industrial training data. Under these conditions, high-capacity models are more likely to learn incidental correlations with body shape, clothing, or the recording environment. Strict cross-subject evaluation can thus better reflect generalization to new trainees than random data splitting. Automated assessment in vocational training also serves a different instructional purpose from conventional video regression. If a model predicts only an overall score, it is difficult to determine whether that prediction is based on the correct motion evidence. Attention maps and key-segment visualizations may indicate where the model focuses, but they do not directly correspond to rubric items or deductions. Converting the assessment rubric into a structured prior can narrow the evaluation space that the model must discover independently. It can also establish an auditable relationship between identified errors and the final score.
To address these questions, we propose RESC, a rubric-guided error–score consistency framework. RESC begins with human keypoint sequences extracted by deep pose estimation and introduces the instructor rubric as a structured prior for quality modeling. This design focuses the model on posture evidence directly associated with operating standards and explains the overall score through rubric-aligned diagnoses and a model-derived deduction decomposition. Task knowledge is used to reduce learning difficulty under limited-data conditions while supporting model inspection and human review.
The main contributions of this study are as follows:
1.
We propose RESC, a rubric-guided AQA framework for small-sample vocational training. It combines deep pose representations with instructor scoring rules to improve cross-subject scoring and provide traceable error evidence and model-derived deduction contributions for the final score.
2.
We build a video acquisition system in an authentic training workshop and construct the Fitter-AQA dataset. The dataset contains 134 operation videos from 25 participants with different skill levels and provides instructor-consensus scores, error categories, and severity labels for small-sample AQA research in realistic industrial training environments.
3.
We systematically evaluate scoring, ranking, and error diagnosis under strict leave-one-subject-out cross-validation. Comparisons with feature-learning, elastic-alignment, and rubric-guided methods, together with multiple ablation studies, demonstrate the value of structured rubric priors under limited-data conditions.

2. Related Work

2.1. Deep-Learning-Based Action Quality Assessment

Deep-learning-based AQA typically encodes a continuous video or skeleton sequence into a spatiotemporal representation and then estimates quality through regression, ranking, or score-distribution prediction. Early studies mainly used video-level convolutional features and recurrent networks [14,15,16,17]. SlowFast networks, spatiotemporal attention, graph convolution, and Transformers subsequently improved the modeling of long-range dependencies and inter-joint relationships [4,18,19,20,21,22]. Score supervision has also progressed from absolute score regression to pairwise ranking, group-aware contrastive regression, and uncertainty-aware distribution learning [5,6,23,24]. Deep spatiotemporal models can learn complex quality patterns from large video collections, but their performance depends on sufficiently representative training data. Recent skeleton-based AQA research likewise identifies annotation dependence and cross-domain generalization as key constraints on deployment [25]. When the training set is small and subject variation is pronounced, increased model capacity does not necessarily yield stable gains. Task-oriented representations and prior constraints remain important for improving sample efficiency.

2.2. Limited-Sample Learning and Cross-Subject Generalization

Unlike large action-recognition datasets, task-specific AQA datasets rarely contain abundant videos with expert labels. Models are therefore more vulnerable to subject appearance, scene background, and a small number of atypical samples. Early studies used segment-level training and pretrained spatiotemporal features to ease optimization with limited data [15]. In professional skill assessment, Yanik et al. used meta-learning for one-shot or few-shot adaptation across surgical tasks [26]. Related few-shot action-recognition studies improved the use of scarce examples through prototype-centered representations [27] and two-stage temporal alignment [28]. These findings show that transferring existing representations and explicitly modeling sample relationships can reduce data requirements. However, current work focuses mainly on novel-class recognition or cross-task skill-level transfer, with less attention to continuous quality scoring under strict cross-subject protocols. Limited-sample AQA for professional skills must suppress identity-related bias while retaining quality information aligned with evaluation rules. This study therefore examines whether structured rubric priors improve cross-subject scoring stability.

2.3. Pose-Aware and Fine-Grained Process Modeling

Human pose estimation converts RGB video into keypoint sequences with an explicit body topology, offering a compact representation that is less sensitive to background interference. Skeleton-based graph neural networks model spatial joint relations and their temporal evolution [4,22], while joint angles, relative distances, and motion trajectories describe local operating standards in vocational tasks [29,30,31,32,33,34]. Other studies improve fine-grained understanding by modeling action stages and human-centered regions. FineDiving organizes complete actions using procedural semantics [7,35], whereas FineParser, TSA-Net, and the Temporal Parsing Transformer identify score-relevant processes through spatiotemporal parsing, local attention, and stage relations [8,20,21]. These studies show that pose structure and process decomposition help distinguish quality differences among visually similar videos. Nevertheless, a key segment or attended region does not directly identify the violated operating criterion or quantify its effect on the final score. Pose evidence must be linked to domain evaluation rules before it can support rubric-aligned diagnosis.

2.4. Rubric-Driven Interpretable Scoring

Interpretability research in AQA is shifting from post hoc attention visualization toward intrinsic explanations directly associated with scoring semantics. Gradient attribution, concept activation, and prototype learning identify important regions or intelligible concepts [36,37,38,39]. Fine-grained parsing and causal modeling further reduce background interference and reveal spatiotemporal evidence that affects scores [7,8,20,21,40]. For professional evaluation, IRIS organizes action segments and subscore explanations using a scoring rubric [41]; RICA2 encodes action steps and scoring criteria as structured relations [42]; and NS-AQA and RCS generate fine-grained assessments from expert rules or natural-language rubrics [43,44]. These studies demonstrate the value of domain rules for trustworthy AQA. Most, however, address phases, technical elements, or subscores in competitive actions. Itemized error diagnosis and deduction consistency in small-sample vocational training remain underexplored. RESC uses rubric priors to improve cross-subject scoring and interpretability, while monotonic constraints align changes in error severity with changes in deduction magnitude [45,46,47].

3. Materials and Methods

3.1. Data Acquisition System

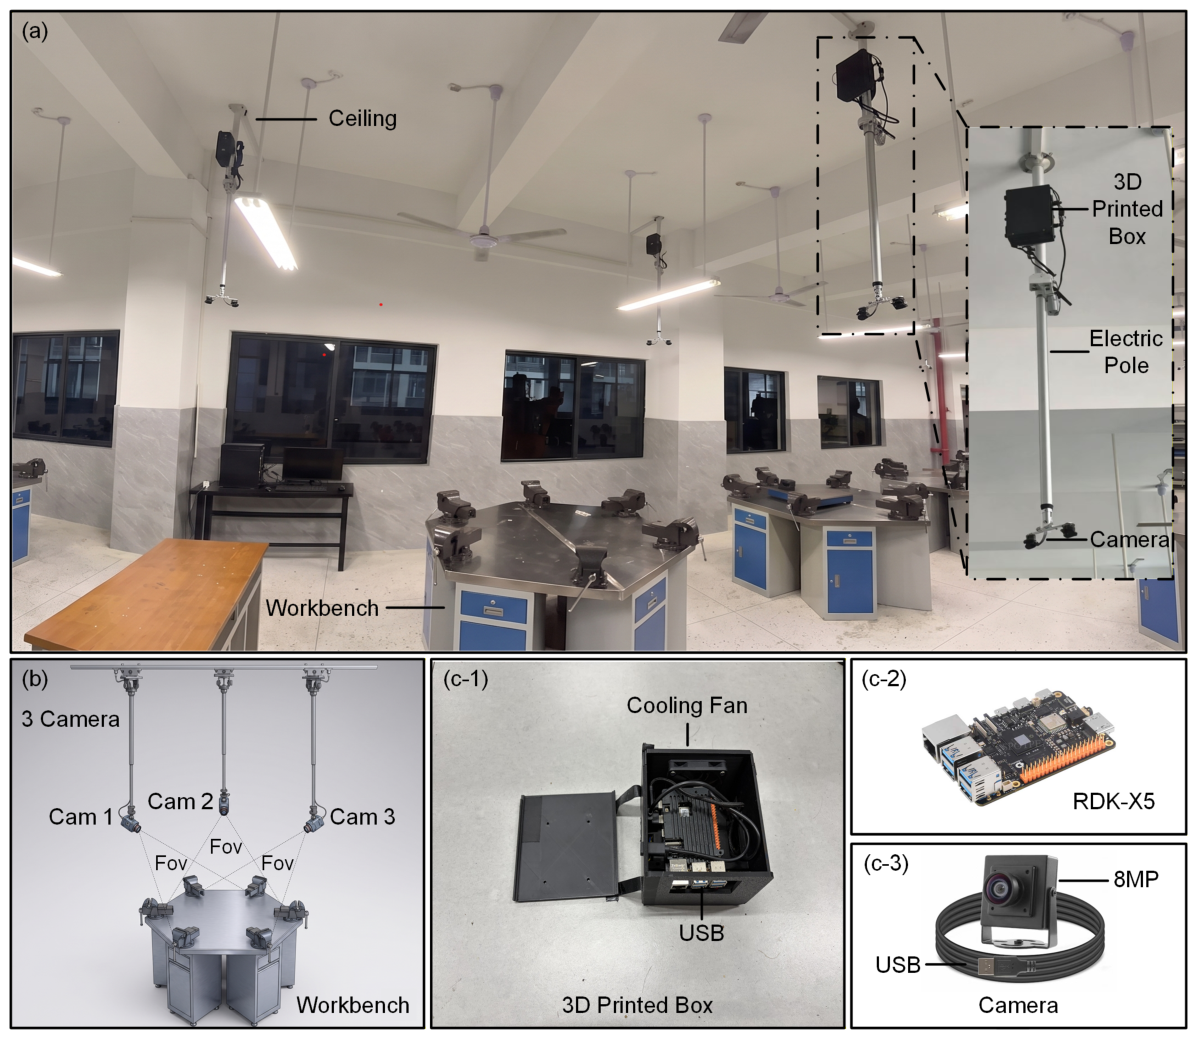
We installed a fixed overhead acquisition system in a vocational fitter training workshop to record authentic filing practice. The acquisition area covered both the workbench and the trainee’s standing space, allowing the system to capture the torso and the filing stroke. A ceiling-mounted camera reduced scale changes and viewpoint disturbances and minimized interference with normal practice. Figure 1 presents the system configuration. Three identical acquisition units were installed above one group of workbenches, with overlapping overhead fields of view covering six workstations. Each unit was suspended from the ceiling by a motorized boom, and the edge-computing board transmitted the video stream over Wi-Fi. The fixed layout maintained consistent acquisition conditions while retaining realistic disturbances, including occlusion by tools and benches, illumination variation, and partial pose invisibility. Video-level camera and workstation identifiers were not retained during the original collection, and participants were not assigned to balanced acquisition-unit strata. The acquisition unit associated with an individual video therefore cannot be reconstructed from the current metadata.

3.2. Dataset Construction and Quality Control

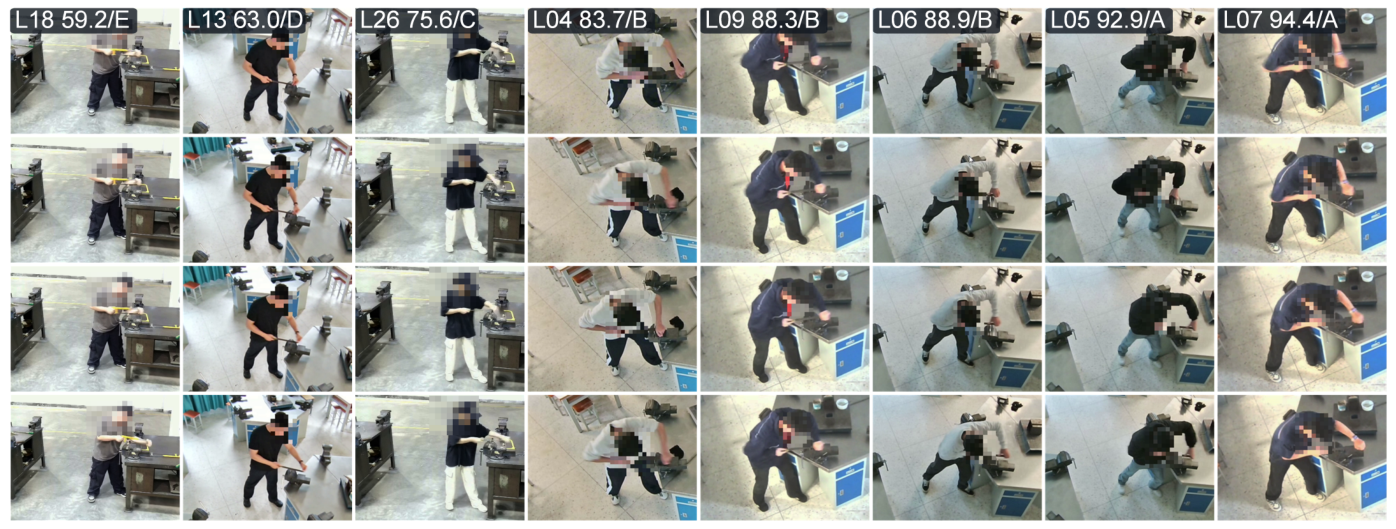
The acquisition system was used to collect and curate filing-practice videos from beginners, award-winning skills competitors, and experienced instructors. Each video was reviewed for decodability and action completeness. The resulting Fitter-AQA dataset contains 134 videos from 25 participants, with a mean duration of 30.8 s. Individual participants contributed between 1 and 7 videos, with a median of 2 videos per participant. Four instructors experienced in vocational fitter training jointly reviewed each video using a common rubric. Each of the six errors was assigned a four-level ordinal label from 0 to 3, with severity determined according to the magnitude, persistence, and functional influence of the observed deviation. Error occurrence, severity, and the overall score were determined collectively by the four instructors. These consensus annotations supervise the model-derived itemized deduction contributions because the instructional rubric assigns the final score holistically. The operational definitions and corresponding pose evidence are summarized in Table 1. Scores ranged from 53.2 to 100, with a mean of 79.76 and a standard deviation of 13.35. For auxiliary quality-level supervision, scores were categorized as level A (≥90), level B (80– 89.9 ), level C (70– 79.9 ), level D (60– 69.9 ), and level E (<60). We did not resample quality levels, thereby preserving the natural score distribution of authentic instruction. All subsequent experiments used this dataset. Representative samples are shown in Figure 2.

3.3. Task Definition and Overview of RESC

Action quality assessment in vocational training involves score prediction, error recognition, and deduction explanation. Instructors typically inspect key postures and the operation process, identify error types, and then assign a quality score. We therefore formulate automated AQA as a rubric-evidence-driven multi-output inference problem. Given the ith video V i and an expert rubric R , the model jointly outputs an overall score, probabilities for six errors, their severities, adaptive deduction gates, and model-derived itemized deduction contributions:
y ^ i , p i , s ^ i , r ^ i , d ^ i = F Θ ( V i , R ) .
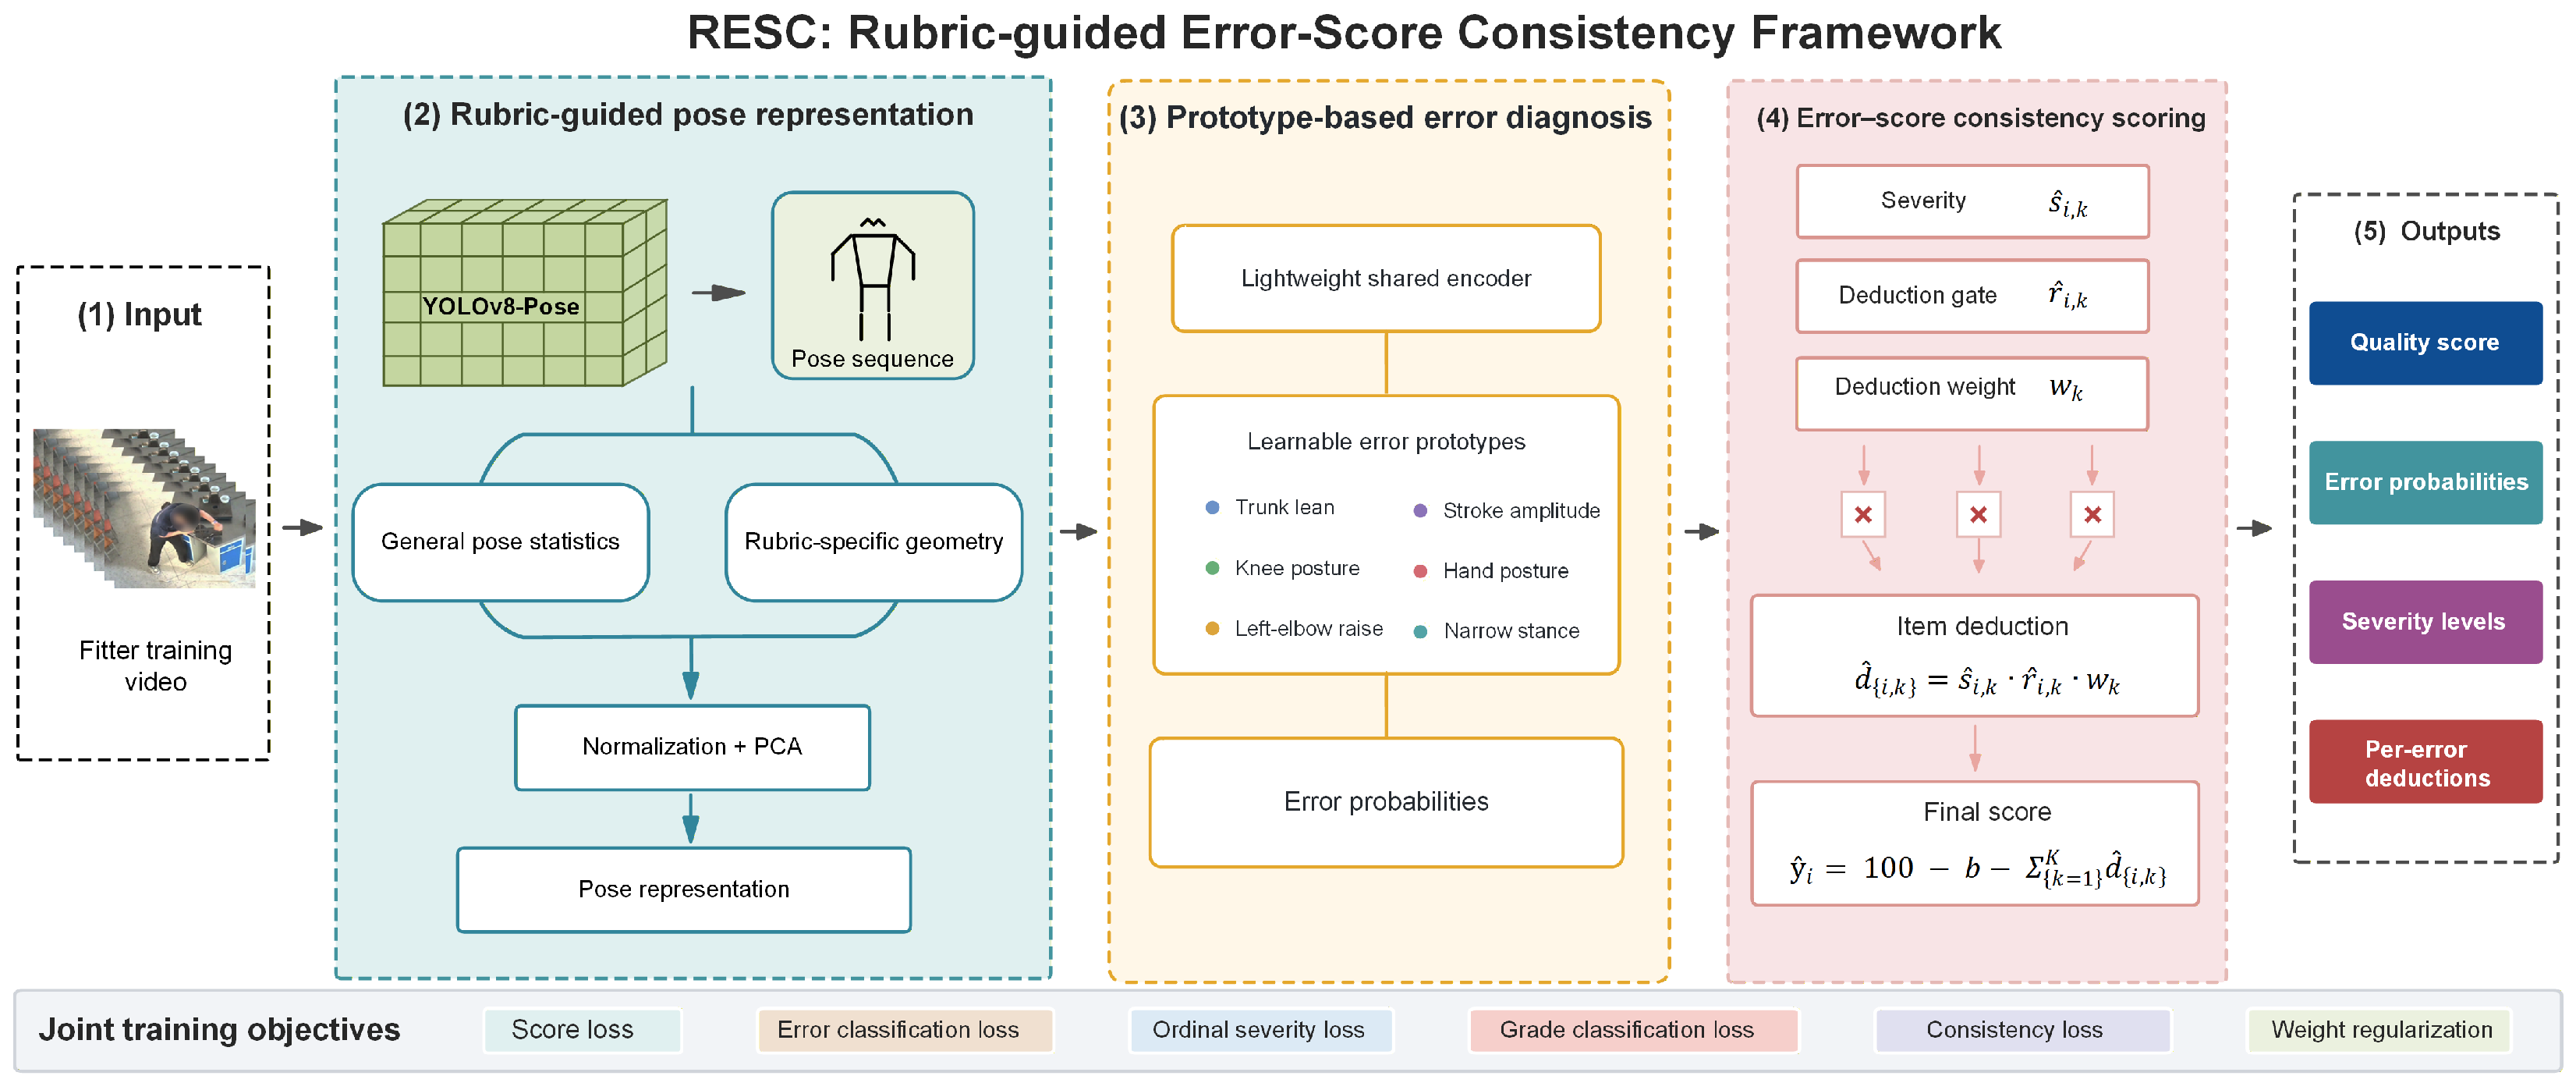
Here, y ^ i is the predicted overall score, and K = 6 is the number of error categories. The K-dimensional vectors p i , s ^ i , r ^ i , and d ^ i contain the error probabilities, expected severities, adaptive deduction gates, and model-derived itemized deduction contributions, respectively. Their components are indexed by k = 1 , , K . The itemized contributions are estimated from the instructor-assigned overall score under joint error-category and severity supervision. An overview of the proposed RESC framework is illustrated in Figure 3.

3.4. Rubric-Guided Pose Geometry

The main quality differences in filing are reflected in body support, trunk stability, elbow–wrist relations, and the reciprocating filing trajectory. We therefore use pose geometry as the primary visual evidence. For each video V i , T = 64 temporal positions are sampled at equal normalized intervals over the complete valid timeline, providing coverage of the full operation. YOLOv8-Pose then extracts J = 17 body keypoints and their confidence scores. The pose sequence is defined as
P i = u i , t , j , q i , t , j t = 1 , , T ; j = 1 , , J , J = 17 ,
where T is the number of sampled time points and J = 17 is the number of body keypoints. The vector u i , t , j is the two-dimensional coordinate of keypoint j at time t in video i, and q i , t , j is its confidence. We use P i , t = { ( u i , t , j , q i , t , j ) } j = 1 J to denote the frame-level pose at time t. Before sampling, the frame sequence is checked for validity. Frames that cannot be decoded, contain abrupt visual corruption, or clearly fall outside the effective operation are removed. Uniform sampling is then performed over the remaining valid interval. A keypoint with q i , t , j < 0.20 is treated as missing. Its normalized coordinates are encoded as zero, and temporal interpolation is not applied. If YOLOv8-Pose does not detect a valid person at a sampled position, the complete frame-level descriptor for that position is set to zero.
The pose representation comprises general pose statistics and category-specific rubric geometry. Filing is strongly periodic, so posture distributions and inter-sample changes are compressed into stable video-level statistics. This design reduces the risk of overfitting a high-capacity temporal model to limited data. Keypoint coordinates are first normalized to body scale. Relative distances, angles, displacements, and adjacent-sample changes among the shoulders, hips, elbows, wrists, knees, and ankles are then calculated. A statistical operator Γ aggregates the general pose descriptors:
g i base = Γ ψ base ( P i , t ) t = 1 T ,
Γ = mean , std , min , max , Q 25 , Q 50 , Q 75 , mean ( | Δ | ) , mean ( Δ 2 ) .
Here, ψ base denotes the general pose descriptor. The symbols Q 25 , Q 50 , and Q 75 denote its feature-wise 25th, 50th, and 75th percentiles. The operator Δ denotes the feature-wise first-order difference between descriptors at adjacent sampled times. Means and quantiles characterize typical posture, standard deviations and extrema describe stability and range, and the difference statistics capture local motion continuity. The implementation uses 28 frame-level general descriptors covering detection confidence, normalized body scale, joint angles, relative joint positions, and inter-joint distances. Their temporal statistics and four sequence-level summaries produce the 200-dimensional general-pose block. Appendix A, Table A2 provides the complete compact dimensional specification.
Rubric geometry explicitly encodes the body regions inspected by instructors. The keypoint sets for the six errors are
J rubric = J inc = { 6 , 12 , 14 , 16 } , J knee = { 11 , 13 , 15 } , J elbow = { 5 , 7 , 9 } , J amp = { 9 , 10 } , J hand = { 7 , 8 , 9 , 10 } , J foot = { 15 , 16 } .
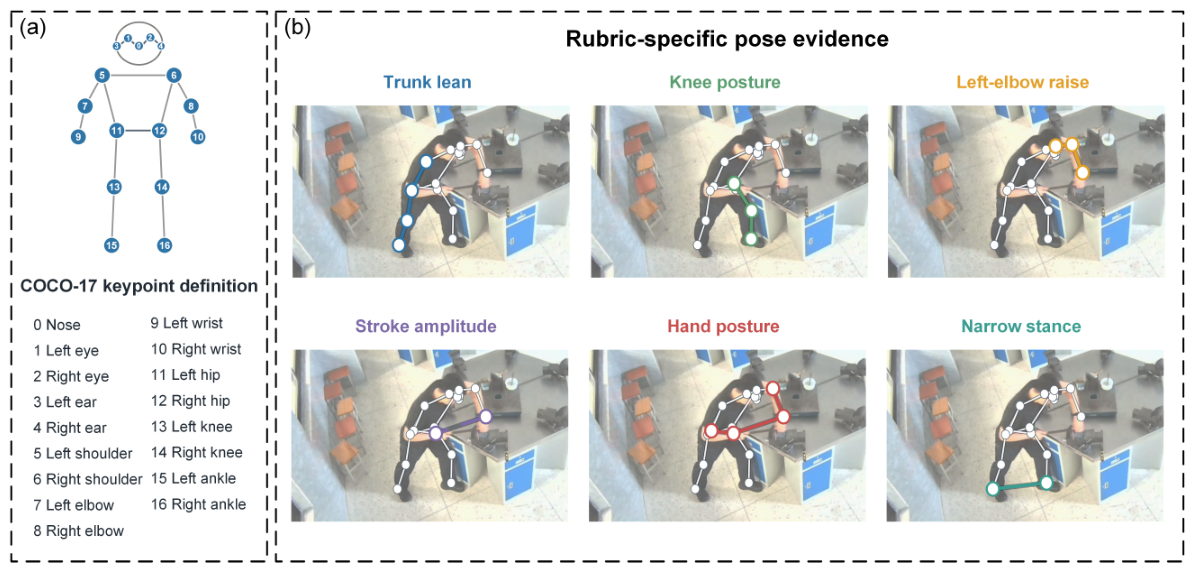
The indices follow the COCO-17 convention used by YOLOv8-Pose. Figure 4 shows both the keypoint definition and the body geometry associated with each rubric item.
Using these sets, the category-specific rubric features are calculated as
g i rubric = Γ ψ k P i , t ; J k rubric t = 1 T , k = 1 , , K ,
where ψ k is the geometric function for error category k. Appendix A, Table A2 summarizes the scalar descriptors, aggregation rules, and dimensional contribution of each feature block. The general and rubric-specific features are concatenated into a 438-dimensional raw vector. It comprises 200 general-pose dimensions and 238 rubric-specific dimensions. Within each training fold, this vector is standardized and reduced to 12 principal components. Ten standardized rubric-specific temporal descriptors are retained alongside the PCA components. The final representation is
u i = Norm [ g i base ; g i rubric ] R 438 , x i = PCA 12 ( u i ) ; Norm ( a i rubric ) R 22 ,
where a i rubric R 10 denotes the 10-dimensional directly retained rubric-specific descriptor block. In the present implementation, this block represents the narrow-stance evidence. Because it contains only 10 dimensions, whereas the other feature families contribute substantially more dimensions, its contribution to the dominant covariance directions may be limited when PCA is fitted to the complete 438-dimensional vector. Its criterion-specific signal may therefore be attenuated. We standardize these ten descriptors separately and concatenate them with the 12 PCA components, allowing the encoder to retain explicit narrow-stance evidence while also modeling global pose variation. x i is the final pose representation for video i. Standardization and principal component analysis were fitted only on the outer-training participants and then applied to the corresponding outer-test participant.

3.5. Error Prototype Diagnosis Module

After obtaining the pose representation, RESC forms an error-semantic diagnostic layer before generating the score. This design follows the instructional process in which deductions are assigned to specific errors and prevents the overall-score supervision from obscuring different error combinations. A lightweight encoder maps x i into a latent space:
z i = f θ ( x i ) .
The encoder f θ is a lightweight two-layer multilayer perceptron, where θ Θ denotes its trainable parameters. A first linear projection and GELU activation produce a smooth nonlinear response. Layer normalization stabilizes feature scale, and dropout suppresses feature co-adaptation under limited-data training. A second linear layer generates the latent representation z i for prototype matching. To align the latent space with rubric semantics, a prototype vector c k is learned for each error. Each prototype represents the typical evidence center of one error. Its cosine similarity to a sample is
e i , k = cos ( z i , c k ) = z i T c k z i 2 c k 2 .
The similarity is converted into an error logit and probability:
i , k = softplus ( α k ) e i , k , p i , k = σ ( i , k ) .
Here, e i , k is the prototype similarity for video i and error k, and σ ( · ) denotes the sigmoid function. Applying softplus to the category scale α k keeps the multiplier positive. Unlike independent multilabel heads, the prototypes define shared semantic coordinates against which evidence from different samples can be compared. They also provide a common semantic input to severity estimation and deduction calculation.

3.6. Ordered Severity and Adaptive Deduction Gating

Error severity has an ordinal structure from no error to a severe error. Treating levels 0–3 as unrelated classes would discard this ordering, where 0 indicates an absent or negligible error and 3 indicates a major effect on action quality. RESC therefore uses a cumulative-link model based on i , k :
P ( s i , k m ) = σ γ k , m ( i , k τ k , m ) , m = 1 , 2 , 3 ,
s ^ i , k = m = 1 3 P ( s i , k m ) .
Here, s i , k is the observed severity, γ k , m is a nonnegative slope constrained by softplus, and τ k , m is a category-specific threshold. The three thresholds are sorted during the forward pass so that τ k , 1 τ k , 2 τ k , 3 . Equation (12) converts the three cumulative probabilities into the expected severity s ^ i , k . This preserves ordinal information while producing a continuous quantity for the deduction branch. Ordinal loss is evaluated only where valid severity labels are available.
The contribution of a predicted severity depends on the sample representation and its category-specific diagnostic evidence. RESC models this variation with a learnable adaptive deduction gate. Let e i = [ e i , 1 , , e i , K ] denote the prototype-similarity vector. The six gate values are computed as
r ^ i = σ h ϕ [ z i ; e i ] ( 0 , 1 ) K ,
where h ϕ is a two-layer gate network with dimensions 134–64–6 and a GELU activation between the two linear transformations. The sigmoid function maps each component to a sample- and item-specific gate r ^ i , k . Its parameters ϕ Θ are optimized jointly with the encoder, error prototypes, severity branch, and scoring branch through the total training objective.

3.7. Nonnegative Deductions and Conditional Error–Score Consistency

Vocational skill assessment has a clear directional constraint: all else being equal, greater error severity should reduce the final score. RESC generates an interpretable score through an explicit deduction branch. The model-derived deduction contribution for error k is
d ^ i , k = softplus ( w k ) r ^ i , k s ^ i , k ,
where softplus ( w k ) is a nonnegative deduction weight. Its initial value is obtained by fitting the observed severity of each error to the total deduction 100 y i using nonnegative linear regression within the training fold, and it is further updated during joint training. The final score is calculated by subtracting all itemized deductions from the full-score reference:
y ^ i = clip 100 softplus ( b ) k = 1 K d ^ i , k , 0 , 100 .
The nonnegative bias softplus ( b ) is initialized from the intercept of the same training-fold regression and updated during training. It calibrates the baseline contribution not covered by the six errors, while clip constrains predictions to 0–100. The bias is reported separately from the six rubric deductions as a residual score-calibration term. For fixed nonnegative weights and gate values, the item deduction is nondecreasing in expected severity; for fixed severity, it is nondecreasing in the gate value. These conditional directional constraints define the local behavior of the deduction equation. Section 4.3.3 evaluates the complete learned mapping when prototype evidence, severity, and gate values change jointly. The branch exposes an auditable model-derived contribution for every error.

3.8. Training Objective and Inference

During training, RESC is jointly supervised by instructor scores, quality levels, error categories, and error severities. The total objective combines score regression, error classification, ordinal severity, quality-level classification, score consistency, and deduction-weight regularization:
L = λ s L score + λ e L err + λ o L ord + λ l L level + λ c L cons + λ w L w .
L score combines Smooth L1 supervision of the deduction-chain score with a lower-weight Smooth L1 term from an auxiliary direct-scoring head. The auxiliary head concatenates z i , the six prototype similarities, and the normalized expected severities, and maps them through a 128-unit GELU–LayerNorm–Dropout block and a sigmoid output to the interval 0–100. During inference, the deduction-chain branch provides the final score, while the direct head contributes auxiliary supervision during training. L err is binary cross-entropy weighted by the positive-class proportion in each training fold. L ord combines binary cross-entropy on cumulative probabilities with the absolute error of expected severity and masks missing severity labels. L level is cross-entropy for the quality level. L cons constrains pairwise rankings between predicted and instructor scores and prevents scores from increasing as the predicted total severity burden grows. Finally, L w prevents learned nonnegative deduction weights from drifting excessively from their training-fold initialization. Their explicit definitions are
L cons = 1 | P y | ( i , j ) P y softplus sgn ( y i y j ) ( y ^ i y ^ j ) 5 + 0.35 | P s | ( i , j ) P s softplus sgn ( S i S j ) ( y ^ i y ^ j ) 5
L w = 1 K k = 1 K SmoothL1 softplus ( w k ) , w k ( 0 ) ,
where S i = k s ^ i , k , P y = { ( i , j ) : | y i y j | > 1 } , and P s = { ( i , j ) : | S i S j | > 0.25 } . The value w k ( 0 ) is the nonnegative training-fold initialization described above. Empty valid-pair sets contribute zero to the corresponding term. The coefficients λ s through λ w control the contribution of each objective. Together, these losses supervise different levels of the scoring chain so that the model learns overall quality, error semantics, and ordinal severity jointly.

4. Experiments and Results

4.1. Training Environment and Evaluation Metrics

The models were implemented in PyTorch 2.5.1 with CUDA 12.1 and trained on an NVIDIA GeForce RTX 4090 Laptop GPU with 24 GB of memory. Cross-subject performance was evaluated using outer LOSO cross-validation, with one participant reserved for testing in each fold. Among the remaining participants, one complete participant formed the inner validation set for early stopping and threshold selection, while the others were used for gradient-based optimization. All preprocessing statistics, initialization quantities, and model-selection operations were confined to the outer-training fold. Binary error thresholds maximized balanced accuracy on inner-validation predictions; when a category contained only one validation class, the corresponding inner-training threshold was used. The three severity cut points minimized discrete severity MAE over values from 0.2 to 2.8 at intervals of 0.1. All thresholds were fixed before outer-test evaluation. The fixed architecture, optimization settings, early-stopping objective, and loss coefficients are summarized in Appendix A, Table A1.
The inner-validation participant was selected deterministically within each outer-training fold. Participants contributing at least three videos were considered first, and the participant whose video count was closest to 10% of the outer-training videos was selected; ties were resolved by participant identifier. If no participant met this condition, the last identifier in sorted order was used. The selection rule depends only on participant identifiers and video counts and does not use scores, error labels, or outer-test predictions. The PCA output dimension (12), the ten retained rubric-specific descriptors, the encoder and gate widths, and the loss coefficients were fixed as model-design settings before the reported outer LOSO runs and were held constant in all 25 folds. Standardization and PCA transformation parameters were fitted separately within each outer-training fold. These design settings remained fixed throughout the outer LOSO evaluation and were determined independently of the pooled outer-test results.
Model performance was evaluated using four complementary metrics, whose definitions are given in Equations (19)–(22). The Spearman rank correlation coefficient (SRCC) measures rank-order agreement between predicted and instructor scores, whereas the Pearson linear correlation coefficient (PLCC) measures their linear agreement. Mean absolute error (MAE) reports the average magnitude of score errors, while root mean square error (RMSE) gives greater weight to large deviations.
SRCC = 1 6 i = 1 N d i 2 N ( N 2 1 ) ,
PLCC = Cov ( y , y ^ ) σ y σ y ^ ,
MAE = 1 N i = 1 N | y i y ^ i | ,
RMSE = 1 N i = 1 N ( y i y ^ i ) 2 .
In Equations (19)–(22), N is the total number of test videos, while y i and y ^ i denote the instructor-assigned and predicted scores for video i, respectively. In Equation (19), d i is the difference between the ranks of y i and y ^ i . In Equation (20), y and y ^ are the instructor-assigned and predicted score vectors, Cov ( y , y ^ ) is their covariance, and σ y and σ y ^ are their standard deviations. The four metrics were calculated by pooling the predictions from all 25 outer-test folds. All comparison and ablation experiments report these four metrics.

4.2. Comparison with Representative Baselines

To evaluate cross-subject generalization across different assessment paradigms, we considered three groups of baselines: elastic alignment based on global sequence distance, feature-learning methods based on video or skeleton representations, and structured methods that explicitly incorporate rubrics or scoring rules. Because Fitter-AQA is newly constructed, every reported method was trained and tested on this dataset. For methods whose published implementation could not be transferred directly to Fitter-AQA, we constructed principle-based adaptations that preserve the core mechanisms described in the original publications and align their inputs and outputs with Fitter-AQA. These implementations are labelled “adapted”. All baselines used the same outer LOSO partitions as RESC, and their preprocessing, parameter selection, and model selection were restricted to the corresponding outer-training participants. The outer-test participant in each fold was used only for final evaluation. Table 2 summarizes the core interpretation of each structured method, the modification made for comparison with RESC, and its training configuration.

4.2.1. Elastic-Alignment Quality Assessment

Table 3 reports the elastic sequence-alignment results. The variants differ in their strengths for absolute calibration and rank correlation, indicating that a single global distance does not optimize both objectives simultaneously. RESC produced the lowest pooled errors and highest pooled correlations in this comparison. Relative to the strongest alignment baseline for each corresponding metric, MAE decreased from 7.730 to 4.450 and SRCC increased from 0.652 to 0.852. These pooled point estimates favor structured error evidence over whole-sequence similarity for cross-subject quality discrimination.
Elastic alignment can absorb variation in action speed and phase duration, but its prediction remains dominated by cumulative distance over the full sequence. In filing, quality differences often occur as brief and local postural deviations. These cues can be diluted by normal periodic motion during global matching. RESC instead organizes local geometric evidence by rubric item and explicitly models the direction from error to deduction, retaining scoring resolution even when participants follow similar overall motion patterns.

4.2.2. End-to-End Feature-Learning Methods

To compare RESC with end-to-end feature learning, we evaluated representative AQA baselines based on skeleton topology, score distributions, relative regression, and temporal parsing. Table 4 shows that feature-learning methods generally outperform elastic-alignment baselines, but remain limited in both error and correlation under strict cross-subject evaluation. In the pooled outer-test predictions, RESC reduced MAE and RMSE by 33.3% and 37.5%, respectively, relative to USDL, while increasing PLCC by 0.164 and SRCC by 0.182. These values describe pooled point-estimate differences; their participant-level uncertainty is reported in Appendix A, Table A3.
The difference reflects supervision granularity and task structure. Global representation learning captures motion rhythm and overall motion patterns, and distributional or ranking supervision improves uncertainty estimates and relative order. Under limited-sample cross-subject evaluation, however, video-level mappings may still exploit non-quality cues such as body shape and clothing. RESC grounds supervision in local posture evidence specified by the rubric. This representation directs learning toward action errors, reduces reliance on subject-specific variation unrelated to the rubric, and is consistent with the improved pooled cross-subject results.

4.2.3. Structured Scoring Methods

To determine whether rubrics and scoring rules improve small-sample skill assessment, structured scoring methods were evaluated separately in Table 5. These methods decompose the overall score into action steps or technical elements with explicit intermediate semantics. Because their semantic structures differ, each method was adapted while preserving its central mechanism.
Methods that convert local pose evidence into error symbols and score them using explicit rules adapted more effectively to this task than the preceding two groups. This finding indicates that structured priors are most useful when linked to concrete instructional errors. Relative to the strongest structured baseline, RESC reduced MAE by 33.7% and improved PLCC and SRCC by 0.100 and 0.182, respectively. Decomposing an action into steps or technical elements alone does not ensure stable cross-subject scoring because intermediate diagnostic errors can propagate during score aggregation. RESC jointly optimizes error prototypes, ordinal severity, and monotonic deduction. Local evidence therefore supports both diagnosis and final-score constraints within one consistent assessment chain.
We additionally compared RESC with USDL and NS-AQA-adapted using 10,000 paired participant-cluster bootstrap resamples (Appendix A, Table A3). All point differences favored RESC. For NS-AQA-adapted, the 95% intervals excluded zero for all four metrics. For USDL, the intervals crossed zero, indicating that the observed pooled advantage over this feature-learning baseline does not constitute a formal significance claim at the participant level.

4.2.4. Controlled Same-Input Comparison and Statistical Stability

To separate the effect of the input representation from that of the structured scoring mechanism, we added three controlled comparisons. Ridge regression and a two-layer multilayer perceptron used the same 438-dimensional pose and rubric feature set, the same fold-fitted standardization and PCA, and the same overall-score labels as RESC. The auxiliary direct-score head additionally shared the RESC encoder and multi-objective training supervision and mapped the shared representation directly to the score. All four outputs were evaluated using the same outer LOSO splits. To quantify subject-level variability, 95% confidence intervals were obtained from 10,000 bootstrap resamples using the outer-test participant as the clustering unit. Detailed results are presented in Table 6.
Under identical pose evidence, Full RESC achieved the lowest MAE and RMSE and the highest PLCC and SRCC among the four controlled models. It also improved all four metrics over the auxiliary direct-score head, which shared the same representation and multi-task supervision, supporting the additional contribution of deduction-chain aggregation. Across 10,000 participant-cluster resamples, the PLCC and SRCC intervals remained within 0.837–0.944 and 0.665–0.887, respectively, indicating stable score agreement under subject-level variation. Across the 25 held-out participants, the subject-level MAE had a median of 4.60 and an interquartile range of 3.21–7.93.

4.3. Ablation Studies

4.3.1. Feature-Evidence Ablation

To evaluate the independent and complementary roles of general pose statistics and rubric geometry, we trained RESC with each evidence source separately and with their fusion. Table 7 shows that general pose statistics favor absolute score calibration, producing an MAE of 6.749 when used alone. Rubric geometry preserves quality order more effectively, reaching an SRCC of 0.721. Their fusion reduced MAE to 4.450 and increased SRCC to 0.852. Overall motion context and local rubric evidence are therefore complementary, supporting the dual-evidence design of RESC.
General statistics summarize motion stability and individual movement scale, whereas rubric geometry directly represents scoring evidence. The former supplies the global context needed for score calibration, and the latter establishes the evaluation direction for fine-grained quality differences. Their combination yields the strongest overall performance.

4.3.2. Component Ablation

To determine how each component contributes to scoring and structural consistency, we removed one key design at a time and retrained the model. Table 8 shows that error prototypes have the largest effect: their removal increased MAE to 7.546 and reduced SRCC to 0.645. Removing ordinal severity or adaptive deduction gating also degraded overall performance. Without monotonicity or consistency constraints, individual metrics approached the full model, but scoring error and rank correlation did not remain strong simultaneously. The complete RESC consequently provides the best joint behavior.
Error prototypes provide semantic anchors for local postural deviations. Ordinal severity and adaptive deduction gating then determine sample-specific deduction magnitude, while monotonicity and consistency stabilize the direction between error burden and final score. Their combined effect allows RESC to balance numerical accuracy, ranking stability, and deduction logic.

4.3.3. Counterfactual Directional-Consistency Analysis

To empirically examine the directional behavior of the complete deduction mapping, we performed a counterfactual stress test on the outer-LOSO predictions. For one rubric item at a time, its prototype evidence was varied over the observed value ± 0.50 while the shared representation was held fixed; the corresponding severity and adaptive deduction gate were then recomputed. For every pair of adjacent intervention levels, we tested whether stronger error evidence produced a nondecreasing item deduction and a nonincreasing final score. Detailed statistics for the counterfactual stress test are summarized in Table 9.
Across all 29,309 adjacent interventions, increasing the prototype evidence consistently increased the corresponding item deduction. The final score followed the expected direction in 99.22% of the comparisons. The remaining 228 reversals were confined to narrow stance and had a maximum magnitude of only 0.0016 points. All comparisons satisfied directional consistency under a numerical tolerance of 0.01 points.

4.4. Error Diagnosis

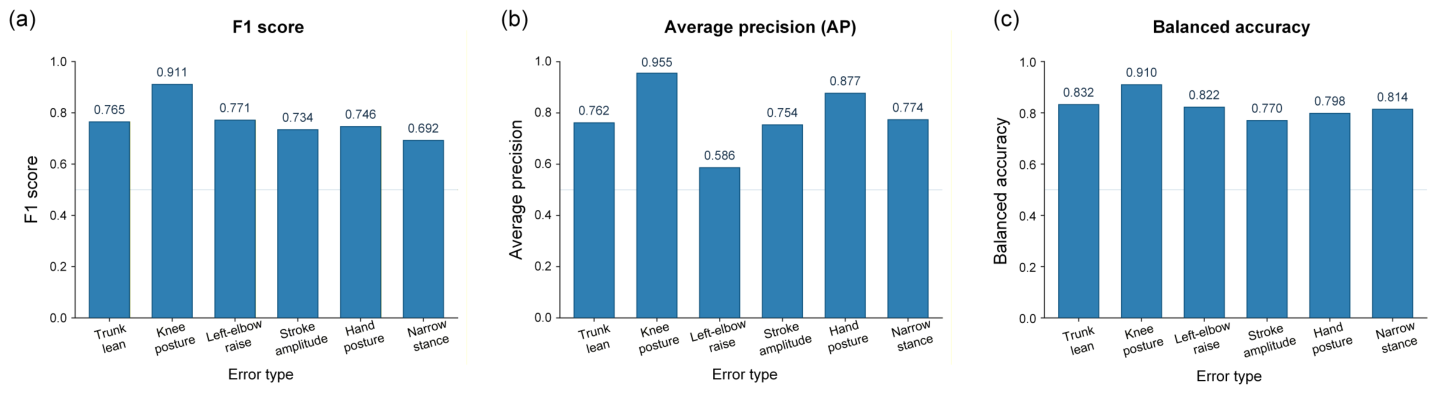
To evaluate whether RESC identifies specific rubric errors under cross-subject conditions, we performed category-level analysis using predictions from the outer LOSO test folds. A video may contain several errors, so each rubric item was treated as an independent binary task. F1 balances error recall and prediction precision at the selected threshold. Average precision (AP) evaluates confidence ranking over all decision thresholds. Balanced accuracy weights error and no-error samples equally, reducing the influence of class imbalance. Together, the metrics assess fixed-threshold discrimination, confidence ordering, and class-balanced recognition.
As shown in Figure 5, F1 ranged from 0.692 to 0.911, with a Macro-F1 of 0.770. RESC therefore maintained a useful balance between detecting true errors and rejecting no-error cases. Knee posture exceeded 0.90 on all three metrics, indicating stable pose evidence and a clear class boundary. Left-elbow raise achieved strong F1 and balanced accuracy but a lower AP, showing that thresholded discrimination was effective even though confidence ranking remained less stable. Narrow stance had the lowest F1, while its balanced accuracy remained 0.814; its main difficulty was therefore the precision–recall trade-off rather than a failure to separate error and no-error samples. The complementary results show that score-relevant pose evidence can be converted into diagnoses with explicit rubric semantics.
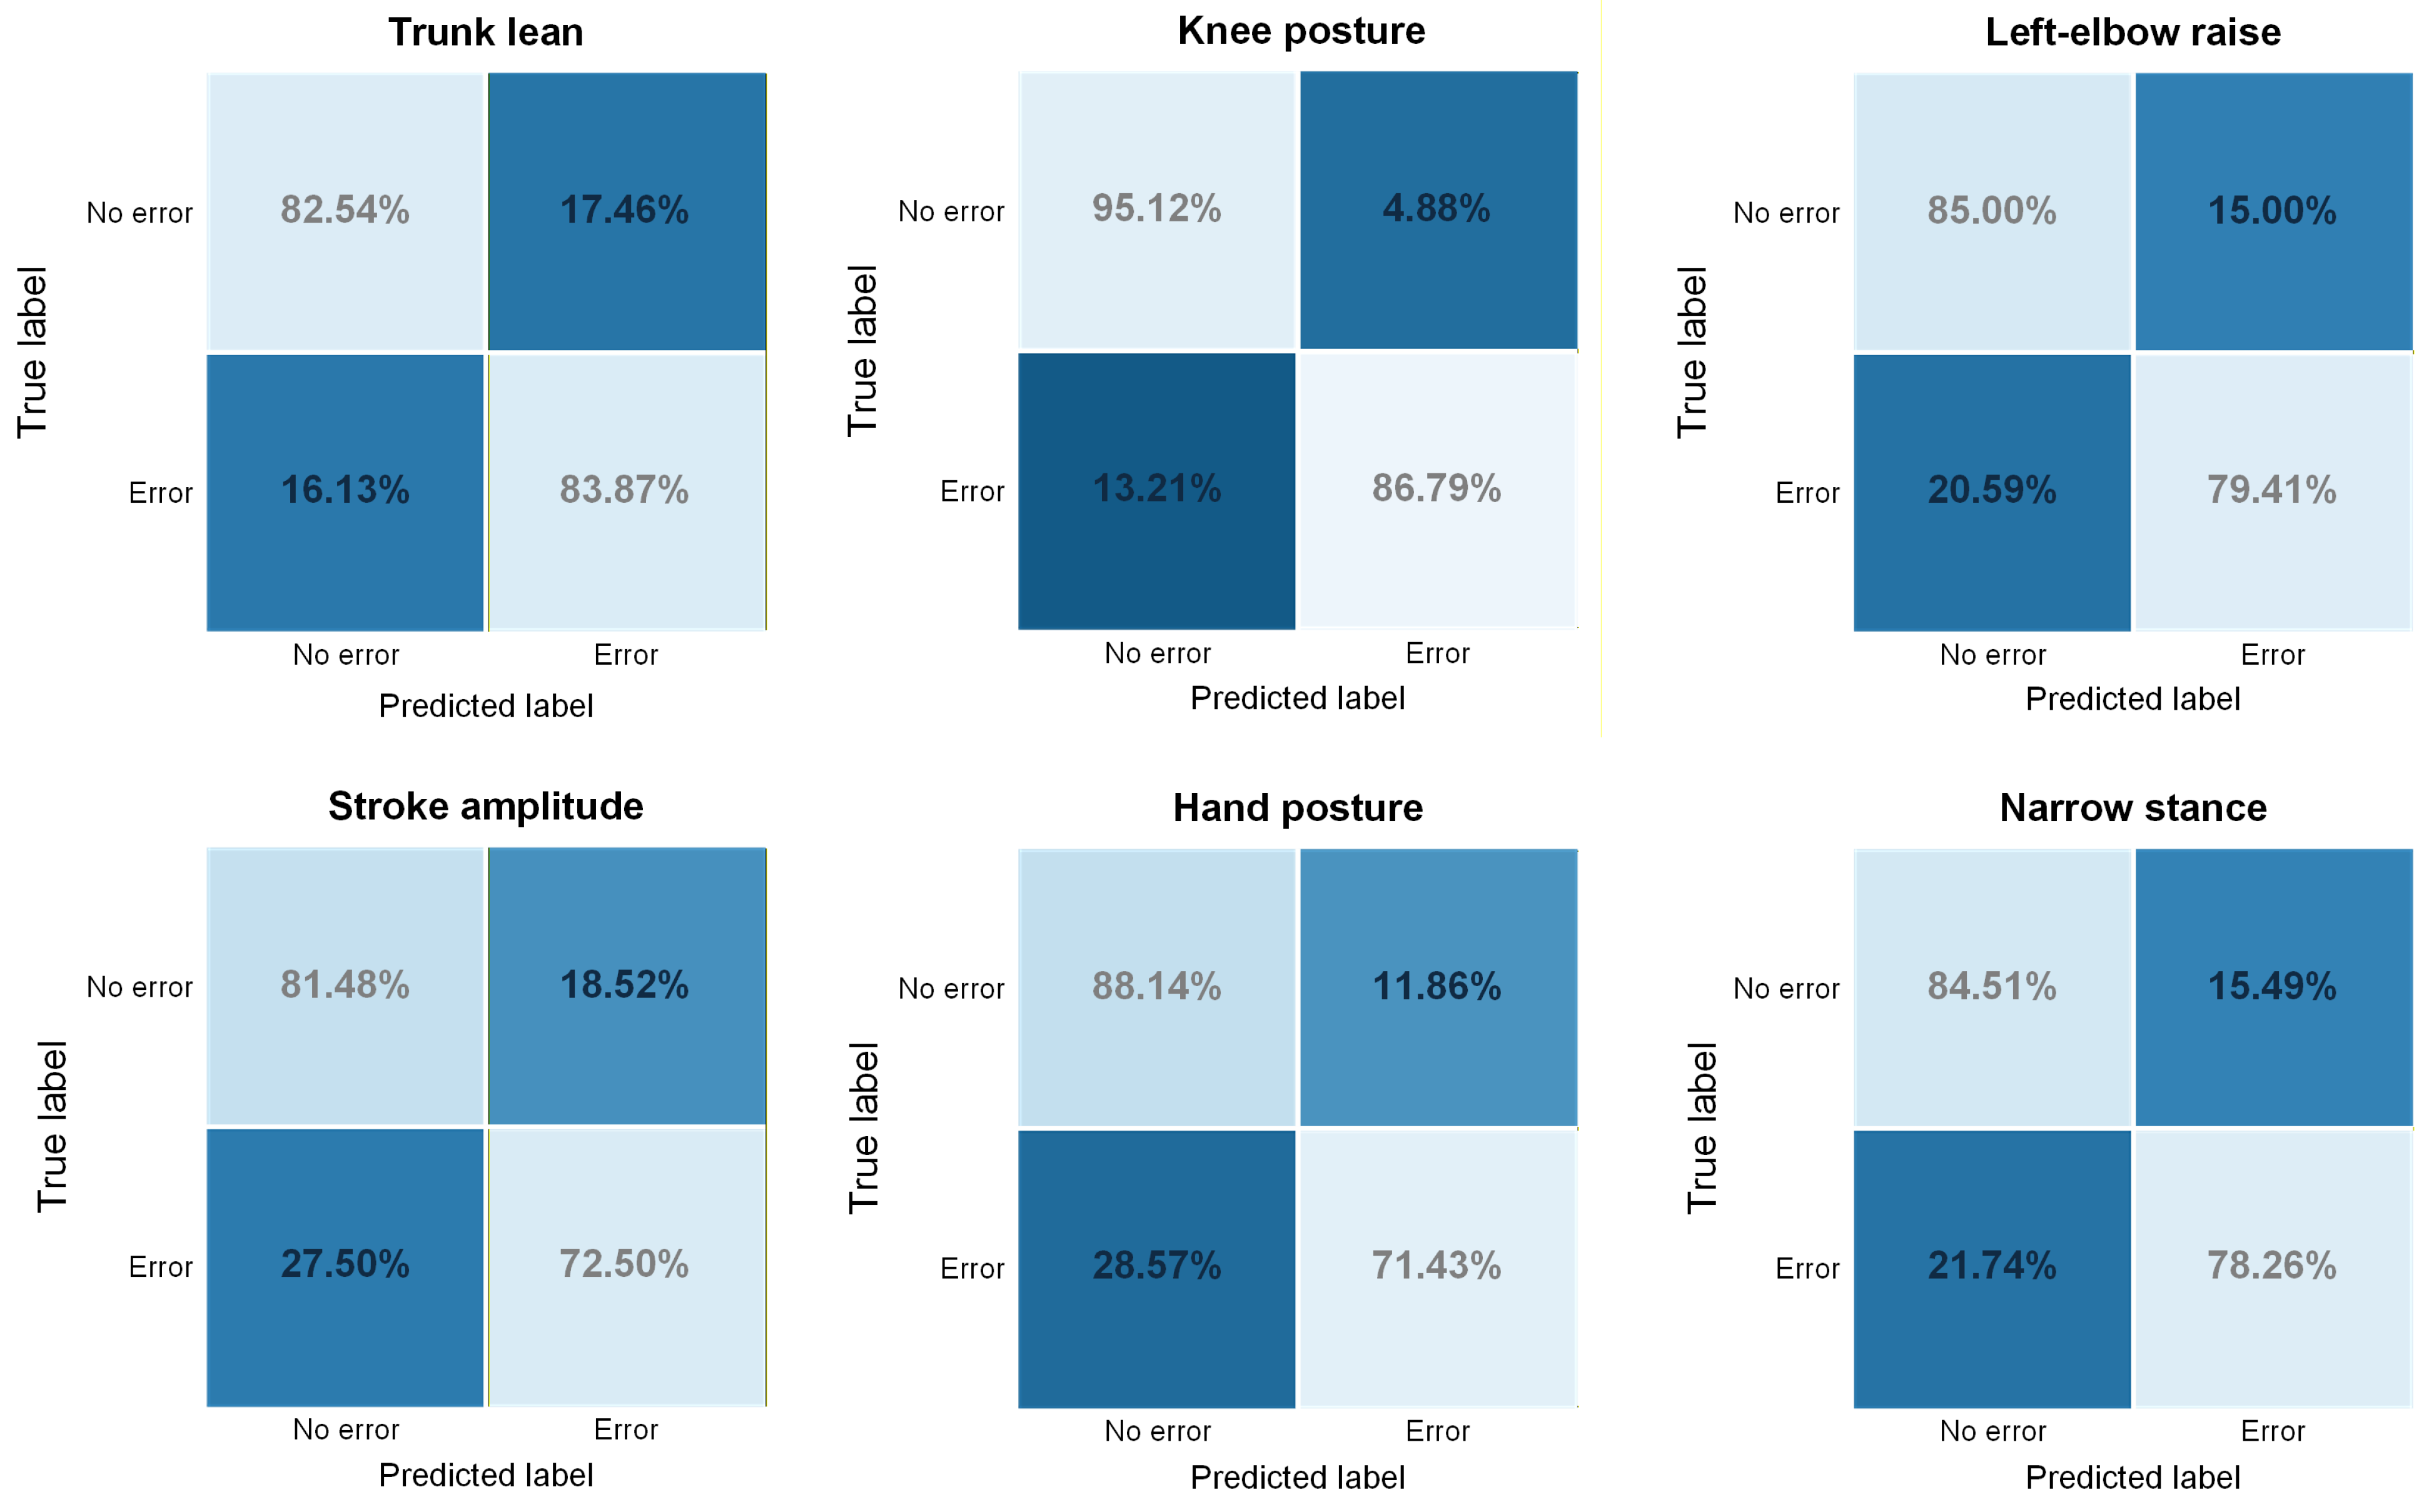
Figure 6 provides a direct view of detection behavior. Specificity ranged from 81.48% to 95.12%, and recall ranged from 71.43% to 86.79%. Thus, every category correctly rejected at least 81.48% of no-error samples and detected at least 71.43% of true errors. Specificity exceeded recall for most categories, indicating a relatively conservative decision policy in which the remaining errors primarily arise from missed detections. Together with F1 and balanced accuracy, these matrices show that the diagnostic results are not an artifact of the majority class and can support itemized deductions.

Ordinal Severity Evaluation

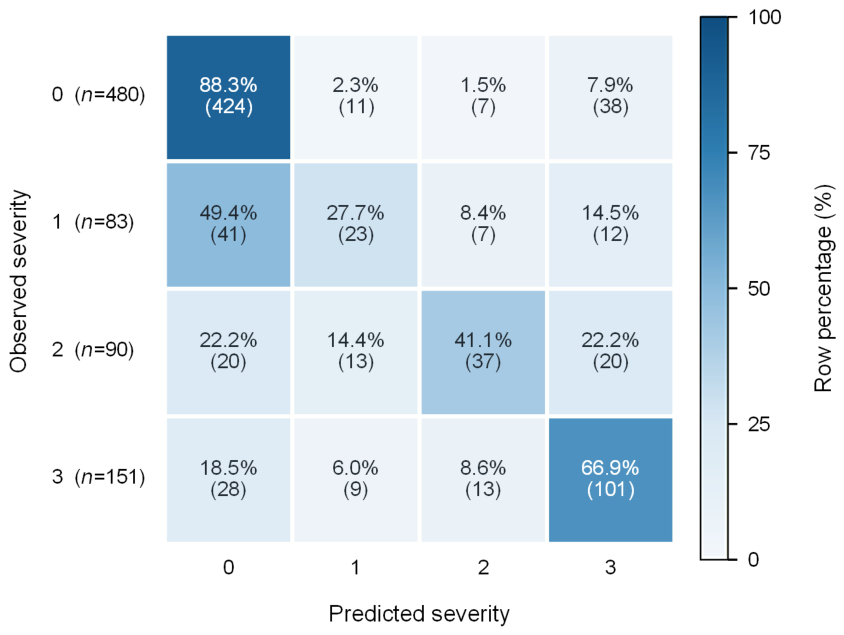
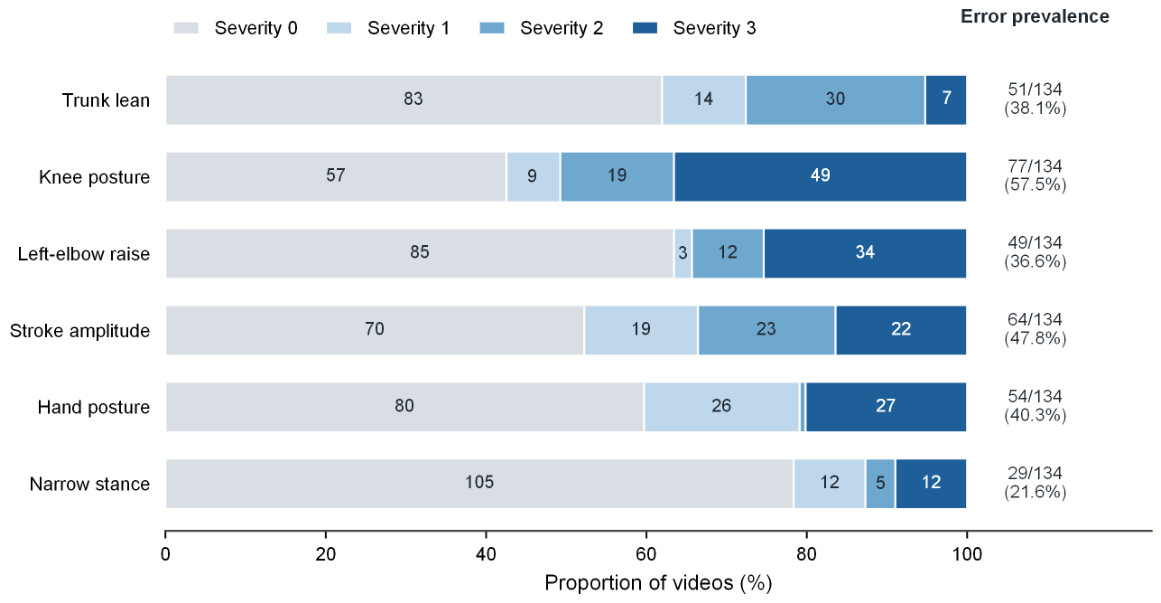
The ordinal branch was evaluated over all 804 rubric-item labels obtained by pooling the six error categories across the 134 outer-LOSO test videos. Discrete-level MAE and exact accuracy evaluate the decoded levels 0–3. Within-one-level accuracy measures the proportion of predictions differing from the observed level by at most one grade. Quadratic-weighted Cohen’s kappa (QWK) additionally accounts for the ordered distance between grades. Table 10 summarizes the ordinal metrics, while Figure 7 and Figure 8 present the confusion pattern and label distribution, respectively.
RESC achieved an exact ordinal accuracy of 72.76%, a within-one-level accuracy of 85.82%, and a QWK of 0.631. Figure 7 shows that levels 0 and 3 were identified more consistently, whereas levels 1 and 2 were more frequently assigned to the endpoints. Figure 8 shows that the two intermediate levels were substantially less represented than level 0 in the pooled labels. This imbalance limits the training evidence available for learning adjacent severity boundaries and contributes to the lower stability of intermediate-grade predictions. The model therefore captured the broad progression from absent to severe error more reliably than the distinction between adjacent intermediate grades.

4.5. Visualization of Interpretable Scoring

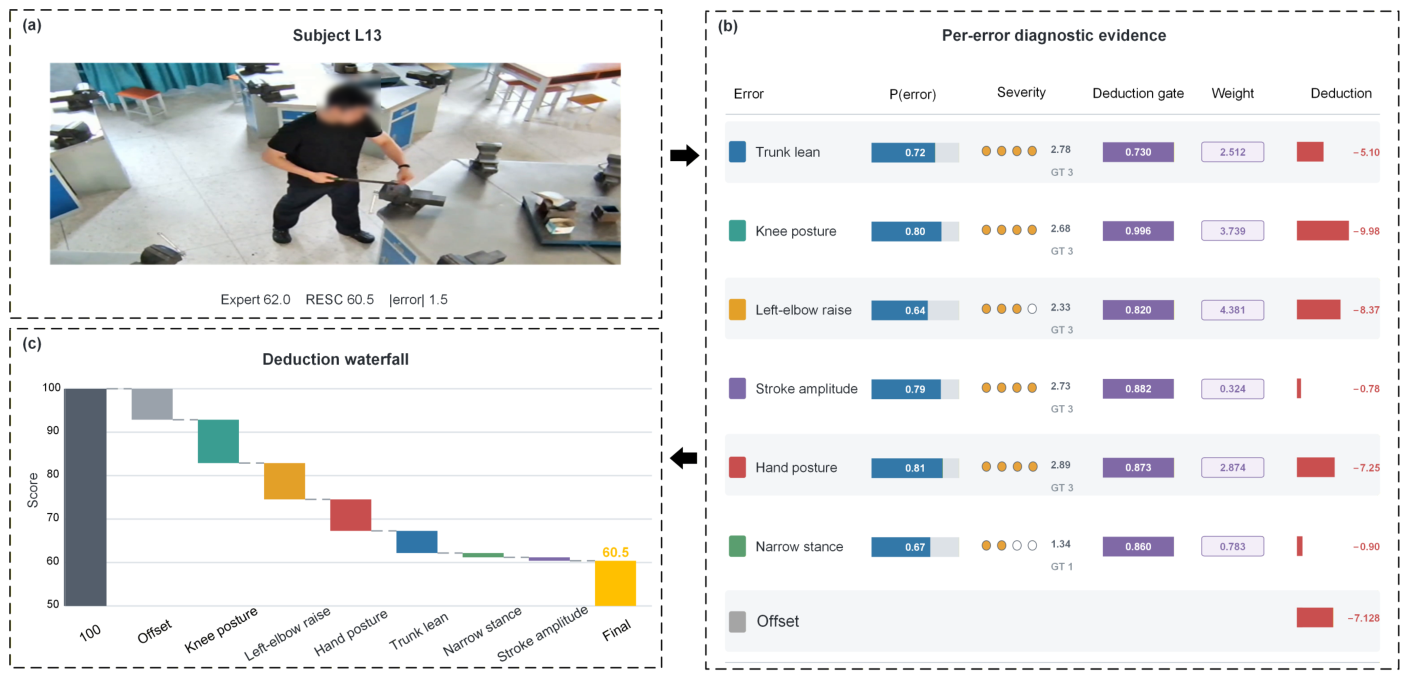
To illustrate the auditability of RESC’s scoring process, we visualized its complete scoring process. Figure 9 uses participant L13 from an outer LOSO test fold and presents both the instructor score and model prediction. Diagnostic evidence for each rubric item is converted into a model-derived deduction contribution, and a waterfall chart aggregates those contributions into the final score. The instructor score for this sample was 62.0, whereas RESC predicted 60.5, giving an absolute error of 1.5 points. Starting from 100, the residual calibration term accounted for 7.128 points of the predicted deduction, and the six rubric errors deducted a further 32.28 points. Knee posture, left-elbow raise, and hand posture were the main sources of score loss, contributing 9.88, 8.37, and 7.25 points, respectively. Stroke amplitude and narrow stance each contributed less than one point.
By converting a score into auditable rubric evidence, the visualization allows an instructor to identify which errors contributed to a low predicted score and prioritize corrective review. Each displayed deduction is a model-derived component linked to a specific rubric item and estimated under overall-score, error-category, and severity supervision. Figure 9 therefore demonstrates the auditability of the model’s score decomposition. The figure establishes traceability within the model and provides a basis for future instructor studies of the pedagogical correctness and practical usefulness of these explanations.

5. Discussion

This study shows that an assessment rubric can provide an effective prior linking deep pose representations to vocational skill evaluation. Under strict cross-subject evaluation with 25 participants and 134 videos, RESC reported the lowest pooled errors and highest pooled correlations among the evaluated methods. The observed differences are consistent with a narrower assessment space: pose representations reduce appearance and scene variation, while rubric-aligned evidence further restricts learning to body relations directly associated with operating standards. The model is therefore less dependent on discovering scoring rules from data alone, which is especially valuable for the limited datasets typical of authentic industrial training.
The experiments further demonstrate the traceability of the scoring process. Category-level diagnoses and deduction visualizations connect model outputs to rubric items and decompose the final score into auditable, model-derived contributions. Compared with explanations that only highlight regions or action segments, these outputs provide an explicit representation that can be inspected against the scoring rubric. The present evidence supports rubric alignment and model auditability. Claims about instructional correctness, feedback effectiveness, or user benefit require evaluation by instructors and trainees.
The results further suggest that vocational-skill AQA need not follow the same modeling paradigm as large-scale sports video assessment. When the overall procedure is stable and quality differences are concentrated in local operating standards, combining deep pose estimation with domain rules can preserve critical quality information while controlling model complexity. This finding is consistent with recent pose-aware, fine-grained, and rubric-driven AQA studies that emphasize human-centered evidence and structured explanations [22,25,40,41,42]. Its applicability still depends on the clarity of the scoring rules and on whether the relevant operating evidence can be reliably observed from visual pose.
The current framework relies on body pose and therefore primarily captures gross-body kinematics. COCO-17 keypoints provide reliable evidence for posture and limb coordination but offer limited representation of fine hand–tool coordination, tool orientation, and tool–workpiece contact. Dimensional accuracy and surface quality are properties of the finished workpiece and require direct measurement. RESC therefore evaluates the pose-observable component of filing performance. A more comprehensive assessment should combine body pose with hand and tool tracking, contact-aware visual evidence, and direct workpiece-quality measurements.
The ordinal severity analysis also identifies a limitation in fine-grained grading. The separation of severity levels 1 and 2 was less stable than that of the endpoint levels. Intermediate-grade samples were relatively sparse, and adjacent levels were distinguished according to deviation magnitude, persistence, and functional influence, whose visual boundaries may overlap in pose-based observations. The observed confusion therefore reflects both the current ordinal branch’s limited resolution between adjacent grades and the intrinsic difficulty of four-level severity assessment under a small and imbalanced dataset. The present evidence supports error-category recognition and broad severity progression, while precise differentiation between adjacent intermediate grades remains limited.
The current evaluation is also limited to one filing task recorded in a single vocational training workshop. The unequal number of videos contributed by individual participants reflects the natural collection process. Because video-level camera and workstation identifiers were not retained, camera- or workstation-related confounding cannot be excluded, and acquisition-unit sensitivity cannot be estimated from the present dataset. Generalization to different workshops, acquisition layouts, trainee cohorts, and other vocational operations requires further evaluation.

6. Future Work

Future research will integrate operation-process assessment with evaluation of the manufactured workpiece. RESC currently assesses action quality mainly through human pose and rubric errors, whereas the goals of fitter training also include dimensional accuracy, surface quality, and form error. Hand keypoints, tool and workpiece detection, and direct workpiece measurements could complement the current pose evidence. Linking action videos with workpiece measurements could reveal relationships between operating errors and manufacturing defects. Such a system would provide a more complete assessment of procedural correctness, process stability, and output quality, while explaining how specific motion deviations affect the finished workpiece.
Future work will expand Fitter-AQA by including more participants, training workshops, acquisition conditions, and vocational tasks. Targeted collection of the underrepresented intermediate severity levels will improve label balance, support more reliable ordinal learning, and enable broader evaluation of cross-scenario generalization.
Reducing instructor annotation cost is another important direction. The current training process uses supervision at several semantic levels, which limits rapid dataset expansion. Semi-supervised learning, active learning, and pseudo-labeling could route the most informative or least confident samples to instructors and use a small amount of detailed annotation to exploit larger collections of unlabeled video. These strategies may reduce repetitive labeling while preserving scoring reliability. They may also make it easier to transfer rubric-guided assessment to other vocational trades, where the evidence definitions and scoring rules differ but the need for interpretable cross-subject evaluation remains. A future instructor study will separately assess the pedagogical correctness, clarity, and practical usefulness of the model-derived diagnoses and deduction decomposition.

Author Contributions

Conceptualization, methodology, validation and investigation, W.M.; resources, funding acquisition and project administration, W.M., S.W. and J.H.; data curation, W.M. and J.H.; writing—original draft preparation, W.M. and S.W.; writing—review and editing, all authors. All authors have read and agreed to the published version of the manuscript.

Funding

This research was funded by the Guangxi Natural Science Foundation, grant number 2025GXNSFHA069207; the Innovation Project of Guangxi Graduate Education, grant number YCSW2026621; and the Innovation Project of Guangxi University of Science and Technology Graduate Education, grant number GKYC202618.

Institutional Review Board Statement

This study was ethically reviewed and approved by the School of Automation, Guangxi University of Science and Technology (review date: 29 July 2026). Since this study does not involve medical experiments, human-organ-related experiments, animal experiments or invasive procedures, an ethics approval number is not assigned. All participants were fully informed of this study and gave their consent.

Informed Consent Statement

Informed consent was obtained from all subjects involved in the study. All manuscript images with facial data are blurred.

Data Availability Statement

The video data and associated annotations are not publicly available because they contain recordings of human participants and are part of an ongoing study. Requests for non-commercial academic access may be directed to the first author at mfkeyman@163.com and will be considered subject to participant consent, privacy protection, and applicable institutional requirements.

Conflicts of Interest

The authors declare no conflicts of interest.

Abbreviations

The following abbreviations are used in this manuscript:
AQAAction quality assessment
APAverage precision
KRRKernel ridge regression
LOSOLeave-one-subject-out
QWKQuadratic-weighted Cohen’s kappa

Appendix A. RESC Configuration

Table A1. Model configuration and training settings of RESC. Fold-fitted quantities were estimated exclusively from the outer-training participants.
SettingValue or Selection Rule
Raw feature dimension438.
PCA output and retention rule12 dimensions, predefined for all folds; fitted within each fold using training participants only.
Encoder input dimension22, comprising 12 PCA components and 10 directly retained rubric-specific descriptors.
Encoder dimensions22–128–128.
Adaptive-gate dimensions134–64–6, using the concatenated 128-dimensional latent representation and six prototype similarities; sigmoid output.
ActivationGELU in the encoder and adaptive gate.
NormalizationLayerNorm after each encoder linear layer.
Dropout0.18, applied to the encoder.
OptimizerAdamW.
Initial learning rate0.001.
Weight decay0.0002.
Batch size16.
Maximum training epochs240.
Early stoppingPatience 28, based on the inner-validation objective.
Early-stopping objectiveWeighted inner-validation loss: deduction score 1.6; error classification 0.75; ordinal severity 0.65.
Random seed42.
Score-loss coefficientsDeduction-chain score 2.3; auxiliary direct score 0.2.
Diagnostic-loss coefficientsQuality level 0.35; error classification 1.15.
Severity-loss coefficientsOrdinal severity 0.9; expected-severity absolute error 0.2.
Structural-loss coefficientsScore consistency 0.55; deduction-weight regularization 0.05.
Table A2. Compact specification and dimensional decomposition of the 438-dimensional pose feature vector.
Feature BlockScalar Descriptors and AggregationDim.
General poseDetection confidence and body scale (4); trunk angle (1); bilateral knee angle/flexion (4); bilateral elbow angle/relative height (4); wrist, shoulder, hip, and ankle midpoint coordinates (8); normalized inter-joint distances (7). Seven temporal statistics per scalar plus four sequence summaries.200
Trunk leanFive shoulder–hip–knee–ankle alignment and line-deviation scalars, each summarized by nine temporal statistics.45
Knee/supportSix lower-limb angle, flexion, and support-line scalars, each summarized by nine temporal statistics.54
Left-elbow raiseThree relative-height and joint-angle scalars, each summarized by nine temporal statistics.27
Stroke amplitudeSix wrist-position scalars with nine temporal statistics, plus 12 path-length, range, and displacement summaries.66
Hand postureFour normalized wrist–elbow distance scalars, each summarized by nine temporal statistics.36
Narrow stanceOne normalized stance-distance scalar summarized by ten temporal and validity statistics.10
Total 438
Table A3. Paired participant-cluster bootstrap differences between RESC and the strongest feature-learning and structured baselines. Each interval was obtained from 10,000 resamples of the 25 outer-test participants. Positive differences favor RESC.
Baseline Δ MAE Δ RMSE Δ PLCC Δ SRCC
USDL2.224
( 0.774 –5.344)
3.525
( 0.760 –7.400)
0.164
( 0.015 –0.429)
0.182
( 0.062 –0.402)
NS-AQA-adapted2.259
(0.428–3.863)
2.189
(0.389–3.926)
0.100
(0.019–0.198)
0.182
(0.008–0.398)
Δ MAE and Δ RMSE are computed as baseline minus RESC; Δ PLCC and Δ SRCC are computed as RESC minus baseline. Values in parentheses are participant-cluster bootstrap 95% confidence intervals.

References

  1. Liu, J.; Wang, H.; Stawarz, K.; Li, S.; Fu, Y.; Liu, H. Vision-based human action quality assessment: A systematic review. Expert Syst. Appl. 2025, 263, 125642. [Google Scholar] [CrossRef] [Scilit]
  2. Tran, D.; Bourdev, L.; Fergus, R.; Torresani, L.; Paluri, M. Learning Spatiotemporal Features with 3D Convolutional Networks. In Proceedings of the 2015 IEEE International Conference on Computer Vision (ICCV); IEEE: Piscataway, NJ, USA, 2015; pp. 4489–4497. [Google Scholar] [CrossRef] [Scilit]
  3. Carreira, J.; Zisserman, A. Quo Vadis, Action Recognition? A New Model and the Kinetics Dataset. In Proceedings of the 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR); IEEE: Piscataway, NJ, USA, 2017; pp. 4724–4733. [Google Scholar] [CrossRef] [Scilit]
  4. Yan, S.; Xiong, Y.; Lin, D. Spatial Temporal Graph Convolutional Networks for Skeleton-Based Action Recognition. Proc. AAAI Conf. Artif. Intell. 2018, 32, 912. [Google Scholar] [CrossRef] [Scilit]
  5. Doughty, H.; Damen, D.; Mayol-Cuevas, W. Who’s Better? Who’s Best? Pairwise Deep Ranking for Skill Determination. In Proceedings of the 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition; IEEE: Piscataway, NJ, USA, 2018; pp. 6057–6066. [Google Scholar] [CrossRef] [Scilit]
  6. Yu, X.; Rao, Y.; Zhao, W.; Lu, J.; Zhou, J. Group-aware Contrastive Regression for Action Quality Assessment. In Proceedings of the 2021 IEEE/CVF International Conference on Computer Vision (ICCV); IEEE: Piscataway, NJ, USA, 2021; pp. 7899–7908. [Google Scholar] [CrossRef] [Scilit]
  7. Xu, J.; Rao, Y.; Yu, X.; Chen, G.; Zhou, J.; Lu, J. FineDiving: A Fine-grained Dataset for Procedure-aware Action Quality Assessment. In Proceedings of the 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR); IEEE: Piscataway, NJ, USA, 2022; pp. 2939–2948. [Google Scholar] [CrossRef] [Scilit]
  8. Xu, J.; Yin, S.; Zhao, G.; Wang, Z.; Peng, Y. FineParser: A Fine-Grained Spatio-Temporal Action Parser for Human-Centric Action Quality Assessment. In Proceedings of the 2024 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR); IEEE: Piscataway, NJ, USA, 2024; pp. 14628–14637. [Google Scholar] [CrossRef] [Scilit]
  9. Sturm, F.; Hergenroether, E.; Reinhardt, J.; Vojnovikj, P.S.; Siegel, M. Challenges of the Creation of a Dataset for Vision Based Human Hand Action Recognition in Industrial Assembly. In Lecture Notes in Networks and Systems; Springer: Cham, Switzerland, 2023; pp. 1079–1098. [Google Scholar] [CrossRef] [Scilit]
  10. Zheng, H.; Lee, R.; Lu, Y. HA-ViD: A Human Assembly Video Dataset for Comprehensive Assembly Knowledge Understanding. In Proceedings of the Advances in Neural Information Processing Systems 36; Neural Information Processing Systems Foundation, Inc. (NeurIPS): San Diego, CA, USA, 2023; pp. 67069–67081. [Google Scholar] [CrossRef] [Scilit]
  11. Sturm, F.; Trat, M.; Sathiyababu, R.; Allipilli, H.; Menz, B.; Hergenroether, E.; Siegel, M. Self-supervised representation learning for robust fine-grained human hand action recognition in industrial assembly lines. Mach. Vis. Appl. 2025, 36, 19. [Google Scholar] [CrossRef] [Scilit]
  12. Tamantini, C.; Cordella, F.; Lauretti, C.; Zollo, L. The WGD—A Dataset of Assembly Line Working Gestures for Ergonomic Analysis and Work-Related Injuries Prevention. Sensors 2021, 21, 7600. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  13. Sener, F.; Chatterjee, D.; Shelepov, D.; He, K.; Singhania, D.; Wang, R.; Yao, A. Assembly101: A Large-Scale Multi-View Video Dataset for Understanding Procedural Activities. In Proceedings of the 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR); IEEE: Piscataway, NJ, USA, 2022; pp. 21064–21074. [Google Scholar] [CrossRef] [Scilit]
  14. Pirsiavash, H.; Vondrick, C.; Torralba, A. Assessing the Quality of Actions. In Lecture Notes in Computer Science; Springer International Publishing: Berlin/Heidelberg, Germany, 2014; pp. 556–571. [Google Scholar] [CrossRef] [Scilit]
  15. Parmar, P.; Morris, B.T. Learning to Score Olympic Events. In Proceedings of the 2017 IEEE Conference on Computer Vision and Pattern Recognition Workshops (CVPRW); IEEE: Piscataway, NJ, USA, 2017; pp. 76–84. [Google Scholar] [CrossRef] [Scilit]
  16. Parmar, P.; Morris, B. Action Quality Assessment Across Multiple Actions. In Proceedings of the 2019 IEEE Winter Conference on Applications of Computer Vision (WACV); IEEE: Piscataway, NJ, USA, 2019; pp. 1468–1476. [Google Scholar] [CrossRef] [Scilit]
  17. Parmar, P.; Morris, B.T. What and How Well You Performed? A Multitask Learning Approach to Action Quality Assessment. In Proceedings of the 2019 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR); IEEE: Piscataway, NJ, USA, 2019; pp. 304–313. [Google Scholar] [CrossRef] [Scilit]
  18. Feichtenhofer, C.; Fan, H.; Malik, J.; He, K. SlowFast Networks for Video Recognition. In Proceedings of the 2019 IEEE/CVF International Conference on Computer Vision (ICCV); IEEE: Piscataway, NJ, USA, 2019; pp. 6201–6210. [Google Scholar] [CrossRef] [Scilit]
  19. Bertasius, G.; Wang, H.; Torresani, L. Is Space-Time Attention All You Need for Video Understanding? In Proceedings of the 38th International Conference on Machine Learning; PMLR: Red Hook, NY, USA, 2021; Volume 139, pp. 813–824. [Google Scholar]
  20. Wang, S.; Yang, D.; Zhai, P.; Chen, C.; Zhang, L. TSA-Net: Tube Self-Attention Network for Action Quality Assessment. In Proceedings of the 29th ACM International Conference on Multimedia; ACM: New York, NY, USA, 2021; pp. 4902–4910. [Google Scholar] [CrossRef] [Scilit]
  21. Bai, Y.; Zhou, D.; Zhang, S.; Wang, J.; Ding, E.; Guan, Y.; Long, Y.; Wang, J. Action Quality Assessment with Temporal Parsing Transformer. In Lecture Notes in Computer Science; Springer Nature: Cham, Switzerland, 2022; pp. 422–438. [Google Scholar] [CrossRef] [Scilit]
  22. Liu, J.; Wang, H.; Zhou, W.; Stawarz, K.; Corcoran, P.; Chen, Y.; Liu, H. Adaptive Spatiotemporal Graph Transformer Network for Action Quality Assessment. IEEE Trans. Circuits Syst. Video Technol. 2025, 35, 6628–6639. [Google Scholar] [CrossRef] [Scilit]
  23. Tang, Y.; Ni, Z.; Zhou, J.; Zhang, D.; Lu, J.; Wu, Y.; Zhou, J. Uncertainty-Aware Score Distribution Learning for Action Quality Assessment. In Proceedings of the 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR); IEEE: Piscataway, NJ, USA, 2020; pp. 9836–9845. [Google Scholar] [CrossRef] [Scilit]
  24. Zhang, B.; Chen, J.; Xu, Y.; Zhang, H.; Yang, X.; Geng, X. Auto-encoding score distribution regression for action quality assessment. Neural Comput. Appl. 2024, 36, 929–942. [Google Scholar] [CrossRef] [Scilit]
  25. Fu, W.; Fang, W.; Huang, J.; Zhu, K.; Chen, R.; Feng, C. Skeleton-Based Action Quality Assessment with Anomaly-Aware DTW Optimization for Intelligent Sports Education. Sensors 2025, 25, 7160. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  26. Yanik, E.; Schwaitzberg, S.; Yang, G.; Intes, X.; Norfleet, J.; Hackett, M.; De, S. One-shot skill assessment in high-stakes domains with limited data via meta learning. Comput. Biol. Med. 2024, 174, 108470. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  27. Zhu, X.; Toisoul, A.S.; Perez-Rua, J.M.; Zhang, L.; Martinez, B.; Xiang, T. Few-shot Action Recognition with Prototype-centered Attentive Learning. In Proceedings of the British Machine Vision Conference 2021; British Machine Vision Association: Durham, UK, 2021. [Google Scholar] [CrossRef] [Scilit]
  28. Li, S.; Liu, H.; Qian, R.; Li, Y.; See, J.; Fei, M.; Yu, X.; Lin, W. TA2N: Two-Stage Action Alignment Network for Few-Shot Action Recognition. Proc. AAAI Conf. Artif. Intell. 2022, 36, 1404–1411. [Google Scholar] [CrossRef] [Scilit]
  29. Gao, Y.; Vedula, S.S.; Reiley, C.E.; Ahmidi, N.; Varadarajan, B.; Lin, H.C.; Tao, L.; Zappella, L.; Bejar, B.; Yuh, D.D.; et al. JHU-ISI Gesture and Skill Assessment Working Set (JIGSAWS): A Surgical Activity Dataset for Human Motion Modeling. In Proceedings of the MICCAI Workshop on Modeling and Monitoring of Computer Assisted Interventions, Boston, MA, USA, 14–18 September 2014. [Google Scholar]
  30. Kasa, K.; Burns, D.; Goldenberg, M.G.; Selim, O.; Whyne, C.; Hardisty, M. Multi-Modal Deep Learning for Assessing Surgeon Technical Skill. Sensors 2022, 22, 7328. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  31. Benmansour, M.; Malti, A.; Jannin, P. Deep neural network architecture for automated soft surgical skills evaluation using objective structured assessment of technical skills criteria. Int. J. Comput. Assist. Radiol. Surg. 2023, 18, 929–937. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  32. Liu, D.; Li, Q.; Jiang, T.; Wang, Y.; Miao, R.; Shan, F.; Li, Z. Towards Unified Surgical Skill Assessment. In Proceedings of the 2021 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR); IEEE: Piscataway, NJ, USA, 2021; pp. 9517–9526. [Google Scholar] [CrossRef] [Scilit]
  33. Zhao, W.; Wang, L.; Li, Y.; Liu, X.; Zhang, Y.; Yan, B.; Li, H. A Multi-Scale and Multi-Stage Human Pose Recognition Method Based on Convolutional Neural Networks for Non-Wearable Ergonomic Evaluation. Processes 2024, 12, 2419. [Google Scholar] [CrossRef] [Scilit]
  34. Senjaya, W.F.; Yahya, B.N.; Lee, S.L. Sensor-Based Motion Tracking System Evaluation for RULA in Assembly Task. Sensors 2022, 22, 8898. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  35. Shao, D.; Zhao, Y.; Dai, B.; Lin, D. FineGym: A Hierarchical Video Dataset for Fine-Grained Action Understanding. In Proceedings of the 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR); IEEE: Piscataway, NJ, USA, 2020; pp. 2613–2622. [Google Scholar] [CrossRef] [Scilit]
  36. Selvaraju, R.R.; Cogswell, M.; Das, A.; Vedantam, R.; Parikh, D.; Batra, D. Grad-CAM: Visual Explanations from Deep Networks via Gradient-Based Localization. In Proceedings of the 2017 IEEE International Conference on Computer Vision (ICCV); IEEE: Piscataway, NJ, USA, 2017; pp. 618–626. [Google Scholar] [CrossRef] [Scilit]
  37. Kim, B.; Wattenberg, M.; Gilmer, J.; Cai, C.; Wexler, J.; Viegas, F.; Sayres, R. Interpretability Beyond Feature Attribution: Quantitative Testing with Concept Activation Vectors (TCAV). In Proceedings of the 35th International Conference on Machine Learning; PMLR: Red Hook, NY, USA, 2018; Volume 80, pp. 2668–2677. [Google Scholar]
  38. Chen, C.; Li, O.; Tao, C.; Barnett, A.J.; Su, J.; Rudin, C. This Looks Like That: Deep Learning for Interpretable Image Recognition. In Proceedings of the Advances in Neural Information Processing Systems 32, Vancouver, BC, Canada, 8–14 December 2019. [Google Scholar]
  39. Koh, P.W.; Nguyen, T.; Tang, Y.S.; Mussmann, S.; Pierson, E.; Kim, B.; Liang, P. Concept Bottleneck Models. In Proceedings of the 37th International Conference on Machine Learning; PMLR: Red Hook, NY, USA, 2020; Volume 119, pp. 5338–5348. [Google Scholar]
  40. Han, R.; Zhou, K.; Atapour-Abarghouei, A.; Liang, X.; Shum, H.P. FineCausal: A Causal-Based Framework for Interpretable Fine-Grained Action Quality Assessment. In Proceedings of the 2025 IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW); IEEE: Piscataway, NJ, USA, 2025; pp. 6008–6017. [Google Scholar] [CrossRef] [Scilit]
  41. Matsuyama, H.; Kawaguchi, N.; Lim, B.Y. IRIS: Interpretable Rubric-Informed Segmentation for Action Quality Assessment. In Proceedings of the 28th International Conference on Intelligent User Interfaces; ACM: New York, NY, USA, 2023; pp. 368–378. [Google Scholar] [CrossRef] [Scilit]
  42. Majeedi, A.; Gajjala, V.R.; GNVV, S.S.S.N.; Li, Y. RICA2: Rubric-Informed, Calibrated Assessment of Actions. In Lecture Notes in Computer Science; Springer Nature: Cham, Switzerland, 2024; pp. 143–161. [Google Scholar] [CrossRef] [Scilit]
  43. Rai, A.; Kovashka, A. Rubric-Constrained Figure Skating Scoring. In Proceedings of the 2025 IEEE/CVF Winter Conference on Applications of Computer Vision (WACV); IEEE: Piscataway, NJ, USA, 2025; pp. 9105–9113. [Google Scholar] [CrossRef] [Scilit]
  44. Okamoto, L.; Parmar, P. Hierarchical NeuroSymbolic Approach for Comprehensive and Explainable Action Quality Assessment. In Proceedings of the 2024 IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW); IEEE: Piscataway, NJ, USA, 2024; pp. 3204–3213. [Google Scholar] [CrossRef] [Scilit]
  45. You, S.; Ding, D.; Canini, K.; Pfeifer, J.; Gupta, M. Deep Lattice Networks and Partial Monotonic Functions. In Proceedings of the Advances in Neural Information Processing Systems 30, Long Beach, CA, USA, 4–9 December 2017. [Google Scholar]
  46. Wehenkel, A.; Louppe, G. Unconstrained Monotonic Neural Networks. In Proceedings of the Advances in Neural Information Processing Systems 32, Vancouver, BC, Canada, 8–14 December 2019. [Google Scholar]
  47. Runje, D.; Shankaranarayana, S.M. Constrained Monotonic Neural Networks. In Proceedings of the 40th International Conference on Machine Learning; PMLR: Red Hook, NY, USA, 2023; Volume 202, pp. 29338–29353. [Google Scholar]
  48. Sakoe, H.; Chiba, S. Dynamic programming algorithm optimization for spoken word recognition. IEEE Trans. Acoust. Speech Signal Process. 1978, 26, 43–49. [Google Scholar] [CrossRef] [Scilit]
  49. Keogh, E.J.; Pazzani, M.J. Derivative Dynamic Time Warping. In Proceedings of the 2001 SIAM International Conference on Data Mining. Society for Industrial and Applied Mathematics, Chicago, IL, USA, 5–7 April 2001; pp. 1–11. [Google Scholar] [CrossRef] [Scilit]
  50. Jeong, Y.S.; Jeong, M.K.; Omitaomu, O.A. Weighted dynamic time warping for time series classification. Pattern Recognit. 2011, 44, 2231–2240. [Google Scholar] [CrossRef] [Scilit]
  51. Zhao, J.; Itti, L. shapeDTW: Shape Dynamic Time Warping. Pattern Recognit. 2018, 74, 171–184. [Google Scholar] [CrossRef] [Scilit]
  52. Cuturi, M.; Blondel, M. Soft-DTW: A Differentiable Loss Function for Time-Series. In Proceedings of the 34th International Conference on Machine Learning; PMLR: Red Hook, NY, USA, 2017; Volume 70, pp. 894–903. [Google Scholar]
  53. Marteau, P.F. Time Warp Edit Distance with Stiffness Adjustment for Time Series Matching. IEEE Trans. Pattern Anal. Mach. Intell. 2009, 31, 306–318. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  54. Herrmann, M.; Webb, G.I. Amercing: An intuitive and effective constraint for dynamic time warping. Pattern Recognit. 2023, 137, 109333. [Google Scholar] [CrossRef] [Scilit]
  55. Shi, L.; Zhang, Y.; Cheng, J.; Lu, H. Two-Stream Adaptive Graph Convolutional Networks for Skeleton-Based Action Recognition. In Proceedings of the 2019 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR); IEEE: Piscataway, NJ, USA, 2019; pp. 12018–12027. [Google Scholar] [CrossRef] [Scilit]
  56. Chen, Y.; Zhang, Z.; Yuan, C.; Li, B.; Deng, Y.; Hu, W. Channel-wise Topology Refinement Graph Convolution for Skeleton-Based Action Recognition. In Proceedings of the 2021 IEEE/CVF International Conference on Computer Vision (ICCV); IEEE: Piscataway, NJ, USA, 2021; pp. 13339–13348. [Google Scholar] [CrossRef] [Scilit]
Figure 1. (a) Video environment and an enlarged view of the acquisition unit; (b) installation layout; and (c) hardware components, including (c-1) the 3D-printed enclosure integrating the RDK-X5 board, power supply, and cooling system, (c-2) the low-cost RDK-X5 edge-computing board (Shenzhen D-Robotics Co., Ltd., Shenzhen, China), and (c-3) the 8-megapixel USB industrial camera (Shenzhen Jierui Weitong Electronic Technology Co., Ltd., Shenzhen, China).
Sensors 26 05575 g001
Figure 2. Examples from the Fitter-AQA dataset. Videos from eight participants are ordered from lower to higher expert scores. Each column shows four temporal positions from one video, and the participant identifier, expert score, and quality level are shown above the column.
Sensors 26 05575 g002
Figure 3. Overview of RESC. Skeleton features are first extracted and concatenated. Rubric-aligned error prototypes then diagnose the six error categories. Their model-derived severity-dependent deduction contributions are aggregated to produce the quality score, together with error categories, severity levels, and itemized deductions.
Sensors 26 05575 g003
Figure 4. COCO-17 keypoint definition and rubric-specific pose evidence. (a) The 17 keypoints and indices used by YOLOv8-Pose; (b) rubric-specific keypoint combinations for the six error categories.
Sensors 26 05575 g004
Figure 5. Category-level recognition results for the six rubric errors: (a) F1; (b) average precision (AP); and (c) balanced accuracy. All metrics were calculated from outer-LOSO test predictions for 134 videos from 25 participants. The vertical scale is 0–1.
Sensors 26 05575 g005
Figure 6. One-vs.-rest row-normalized confusion matrices for the six rubric errors. Rows denote observed labels and columns denote predicted labels. The upper-left cell in each panel is the correctly rejected error rate, the lower-right cell is the correctly detected error rate, and every row sums to 100%.
Sensors 26 05575 g006
Figure 7. Row-normalized confusion matrix for ordinal severity prediction. The analysis contains 804 rubric-item labels from 134 outer-LOSO test videos. Rows denote observed levels and columns denote predicted levels; each cell reports its row percentage and sample count.
Sensors 26 05575 g007
Figure 8. Severity-level distribution and error prevalence for the six rubric categories. Each horizontal bar contains 134 videos and is divided by observed severity level. Sample counts are displayed within segments where space permits. Error prevalence is the number and proportion of videos with severity levels 1–3.
Sensors 26 05575 g008
Figure 9. Example of interpretable RESC scoring for test participant L13. (a) Input video and scoring result; (b) diagnostic evidence and model-derived deduction contribution for each rubric item; and (c) waterfall chart that derives the final score from the 100-point reference.
Sensors 26 05575 g009
Table 1. Operational definitions, pose evidence, and severity protocol for the six Fitter-AQA rubric errors.
(a) Error Definitions and Pose Evidence
Error categoryInstructional definitionPose evidence
Trunk leanInsufficient or excessive forward trunk lean, or pronounced trunk sway during filing.Angle and temporal variation of the right shoulder–hip–knee–ankle alignment.
Knee postureKnee hyperextension, insufficient or excessive flexion, or unstable lower-body support.Left hip–knee–ankle angle and its temporal variation.
Left-elbow raiseNoncompliant left-elbow height or failure to maintain a stable elbow position.Relative height and joint angle of the left shoulder, elbow, and wrist.
Stroke amplitudeThe filing stroke is too short and the effective reciprocating range is insufficient.Horizontal trajectory lengths of both wrists.
Hand postureGrip, force application, or coordination between the two hands does not comply with the operating requirements.Elbow–wrist configuration, inter-wrist distance, and wrist-position proxy features.
Narrow stanceFoot spacing is too narrow to provide a stable base for standing and force application.Inter-ankle distance, its body-scale-normalized value, and temporal variation.
(b) Common ordinal severity scale
Severity levelOperational definition
0—AbsentNo observable violation of the corresponding rubric criterion.
1—MildA small or occasional deviation with limited influence on execution.
2—ModerateA clear or recurrent deviation that affects stability or compliance.
3—SevereA pronounced or persistent deviation that substantially affects action quality.
Table 2. Core mechanisms, Fitter-AQA adaptations, and training settings of the structured AQA baselines. RICA2-adapted, RCS-adapted, and IRIS-adapted used a common 48 × 1024 I3D sequence with training-fold standardization and PCA(64), whereas NS-AQA-adapted used six rubric-specific pose groups. All methods used the same 134 videos and outer LOSO splits.
MethodCore InterpretationAdaptation to Fitter-AQATraining Settings
RICA2-adaptedModels rubric criteria as graph nodes and propagates criterion evidence to an uncertainty-aware score.The graph was rebuilt with six error nodes and one score root. Outputs were aligned to error evidence, severity, and continuous score using the common I3D input.One-layer Transformer, hidden dimension 64, four heads, dropout 0.15; AdamW, learning rate 0.001, weight decay 0.002; maximum 260 epochs, patience 35; 24 Monte Carlo samples; seeds 17, 42, and 73.
RCS-adaptedUses text-defined rubric queries to extract criterion evidence and aggregate criterion scores.The six fitter rubric descriptions replaced the original task criteria, and temporal attention learned criterion-relevant segments directly from video-level supervision.Same temporal backbone and optimizer as RICA2-adapted; maximum 260 epochs, patience 35; attention regularization 0.02; seeds 17, 42, and 73.
IRIS-adaptedUses rubric-item queries to obtain item-level evidence and subscores before global scoring.Six video-level error items replaced action-segment criteria, and weak item localization learned item-relevant evidence from video-level labels.Same temporal backbone and optimizer as RICA2-adapted; maximum 260 epochs, patience 35; attention regularization 0.02; seeds 17, 42, and 73.
NS-AQA-adaptedRepresents criteria as neural symbols and combines ordered severity states through nonnegative rules.Six rubric-specific pose groups generated four-level severity symbols and rule-based score deductions.Per-criterion MLP, hidden dimension 32, dropout 0.15; AdamW, learning rate 0.002, weight decay 0.002; maximum 500 epochs, patience 50; seeds 17, 42, and 73.
Table 3. Cross-subject scoring performance of RESC and elastic sequence-alignment methods. Down and up arrows indicate that lower and higher values are better, respectively. The best value in each column is shown in bold.
MethodMAE ↓RMSE ↓PLCC ↑SRCC ↑
CDTW-KRR [48]8.99111.9510.4880.418
DDTW-KRR [49]8.50610.2860.6920.652
WDTW-KRR [50]9.16112.2200.4630.407
ShapeDTW-KRR [51]9.10012.1100.4730.407
Soft-DTW-KRR [52]8.36211.2820.5440.459
TWED-KRR [53]7.73010.1580.6660.533
ADTW-KRR [54]9.07012.1020.4740.413
RESC4.4505.8700.9020.852
Table 4. Cross-subject scoring performance of RESC and representative feature-learning AQA methods. Skeleton networks use the same skeleton-sequence input, while video-based AQA methods use a common I3D temporal representation. Down and up arrows indicate that lower and higher values are better, respectively. The best value in each column is shown in bold.
MethodMAE ↓RMSE ↓PLCC ↑SRCC ↑
ST-GCN [4]9.17811.7830.4910.467
2s-AGCN [55]9.01111.8070.5500.498
USDL [23]6.6749.3950.7380.670
CoRe [6]8.35210.4680.6300.632
CTR-GCN [56]9.37111.9380.5350.482
TPT [21]8.83211.8860.5670.586
RESC4.4505.8700.9020.852
Table 5. Cross-subject scoring performance of RESC and rubric- or rule-guided AQA methods. The adapted RICA2, RCS, and IRIS variants use a common I3D temporal representation, while NS-AQA-adapted uses the six groups of rubric-aligned pose geometry. Down and up arrows indicate that lower and higher values are better, respectively. The best value in each column is shown in bold.
MethodMAE ↓RMSE ↓PLCC ↑SRCC ↑
IRIS-adapted [41]8.62711.1990.5630.577
RICA2-adapted [42]8.07410.8300.6160.607
NS-AQA-adapted [44]6.7098.0590.8020.670
RCS-adapted [43]8.56910.8680.5910.584
RESC4.4505.8700.9020.852
Table 6. Controlled scoring comparison under identical pose evidence and outer LOSO splits. Values in parentheses are participant-cluster bootstrap 95% confidence intervals. Arrows ↓ denote lower metrics indicate better performance, and arrows ↑ denote higher metrics indicate better performance. Bold values represent the best-performing results for each metric.
MethodMAE ↓RMSE ↓PLCC ↑SRCC ↑
Same-input Ridge7.286
(4.943–9.591)
9.162
(6.432–11.407)
0.745
(0.588–0.887)
0.710
(0.408–0.859)
Same-input MLP6.732
(3.769–11.380)
10.007
(5.124–15.466)
0.691
(0.302–0.926)
0.579
(0.058–0.816)
Auxiliary direct-score head4.580
(3.095–6.396)
6.264
(4.628–8.041)
0.890
(0.800–0.941)
0.833
(0.629–0.876)
Full RESC4.450
(3.199–6.139)
5.870
(4.367–7.701)
0.902
(0.837–0.944)
0.852
(0.665–0.887)
Table 7. Ablation of general pose statistics and rubric-aligned geometric evidence. The three settings differ only in input evidence; model architecture and training strategy remain unchanged. Down and up arrows indicate that lower and higher values are better, respectively. The best value in each column is shown in bold.
Input EvidenceMAE ↓RMSE ↓PLCC ↑SRCC ↑
General pose statistics6.7499.2640.7140.644
Rubric geometry7.0129.2910.7120.721
General pose statistics + rubric geometry4.4505.8700.9020.852
Table 8. Ablation of RESC components. Each variant removes one design from the complete framework, which is shown in the final row. Down and up arrows indicate that lower and higher values are better, respectively. The best value in each column is shown in bold.
VariantMAE ↓RMSE ↓PLCC ↑SRCC ↑
w/o error prototypes7.5468.6140.6960.645
w/o ordinal severity5.7696.7710.7970.744
w/o adaptive deduction gate5.8085.9630.8020.767
w/o monotonicity4.5036.0760.8800.804
w/o consistency4.5075.8990.9080.831
RESC4.4505.8700.9020.852
Table 9. Counterfactual directional-consistency stress test under adjacent prototype-evidence interventions.
Rubric ItemAdjacent InterventionsItem-Deduction Consistency (%)Final-Score Consistency (%)Maximum Reverse Score Change (Points)
Trunk lean4763100.00100.000.0000
Knee posture4699100.00100.000.0000
Left-elbow raise4841100.00100.000.0000
Stroke amplitude5169100.00100.000.0000
Hand posture4882100.00100.000.0000
Narrow stance4955100.0095.400.0016
Overall29,309100.0099.220.0016
Table 10. Ordinal severity performance of RESC on pooled outer-LOSO test predictions.
MetricValue
Discrete-level MAE0.496
Exact ordinal accuracy (%)72.76
Within-one-level accuracy (%)85.82
Quadratic-weighted kappa (QWK)0.631
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content.