1. Introduction
Cloud computing, the Internet of Things, and microservice architectures have made distributed services a central part of modern computing infrastructure. Their scale and inter-service dependencies also amplify reliability risks: a local resource, configuration, or communication anomaly can propagate through a service graph and produce system-wide symptoms [
1,
2,
3]. Accurate fault localization and root-cause analysis are therefore essential for maintaining service continuity.
Existing diagnosis methods can be broadly grouped into rule/statistical, data-driven, knowledge-driven, and LLM-assisted approaches. Rule-based methods remain transparent but require extensive manual maintenance, while statistical approaches infer abnormal changes from monitored distributions. Isukapalli and Srirama surveyed fault-tolerant solutions for distributed analytics [
4], and BARO applies multivariate Bayesian online change-point detection to robust microservice root-cause analysis [
5]. These methods provide useful baselines, although high-dimensional and evolving service environments continue to challenge manually engineered features and fixed rules.
Data-driven methods learn fault patterns directly from monitoring data. Outage-Watch introduces extreme-event regularization for early outage prediction [
6], while Transformer and temporal-convolution architectures model global and local dependencies in system logs [
7]. Deep models can be highly accurate when training and test distributions are aligned, but their transfer to unseen topologies, workloads, or fault combinations remains a central concern [
2,
8].
Knowledge-driven methods explicitly model component dependencies, causal relations, and propagation paths. Liang et al. construct reusable meta-causal knowledge for cloud-native root-cause analysis [
9], and KGroot combines a knowledge graph with graph learning to identify event associations and candidate root causes [
10]. Such methods offer transparent constraints and traceable paths, but graph construction and maintenance can be costly, and purely graph-based rules may be insufficient when symptoms are ambiguous or partially observed.
The proposed framework is motivated by the iterative workflow used in expert diagnosis: observe anomalies, formulate a candidate, reason through plausible propagation paths, compare predicted effects with measured evidence, and revise the hypothesis when the evidence is insufficient. LLMs provide flexible semantic and causal reasoning, but they cannot independently guarantee access to current monitoring values or system-specific topology. The KG therefore supplies explicit domain constraints, while the LLM organizes candidate generation and causal-chain construction.
Recent fault-diagnosis research also provides strong data-driven alternatives. Physical fault testing with time–frequency networks and sparse-attention Transformers improves train suspension diagnosis [
11]; deep adversarial capsule networks address multidomain generalization [
12]; time–frequency fully connected graph neural networks learn multiscale dependencies from multisource measurements [
13]; traceable algorithm-unrolling networks expose sparse diagnostic computations [
14]; and robust weight-shared capsule networks improve machinery diagnosis under noise and limited data [
15]. These methods motivate stronger comparisons in representation learning, generalization, and interpretability, but they do not provide the same combination of a numerical fault KG, counterfactual causal-chain refinement, and deterministic iterative verification developed here.
For LLM-assisted root-cause analysis, chaos-engineering evaluations show that unconstrained zero-shot diagnosis remains unreliable even when detailed context is supplied [
16]. Domain knowledge and data fusion can improve multi-fault reasoning [
17], and recent KG-enhanced LLM frameworks demonstrate the value of causal evidence chains in industrial and medical diagnosis [
18,
19]. The unresolved issue is how to couple flexible LLM reasoning with numerical, train-only KG constraints so that every accepted diagnosis has an explicit and reproducible evidence path.
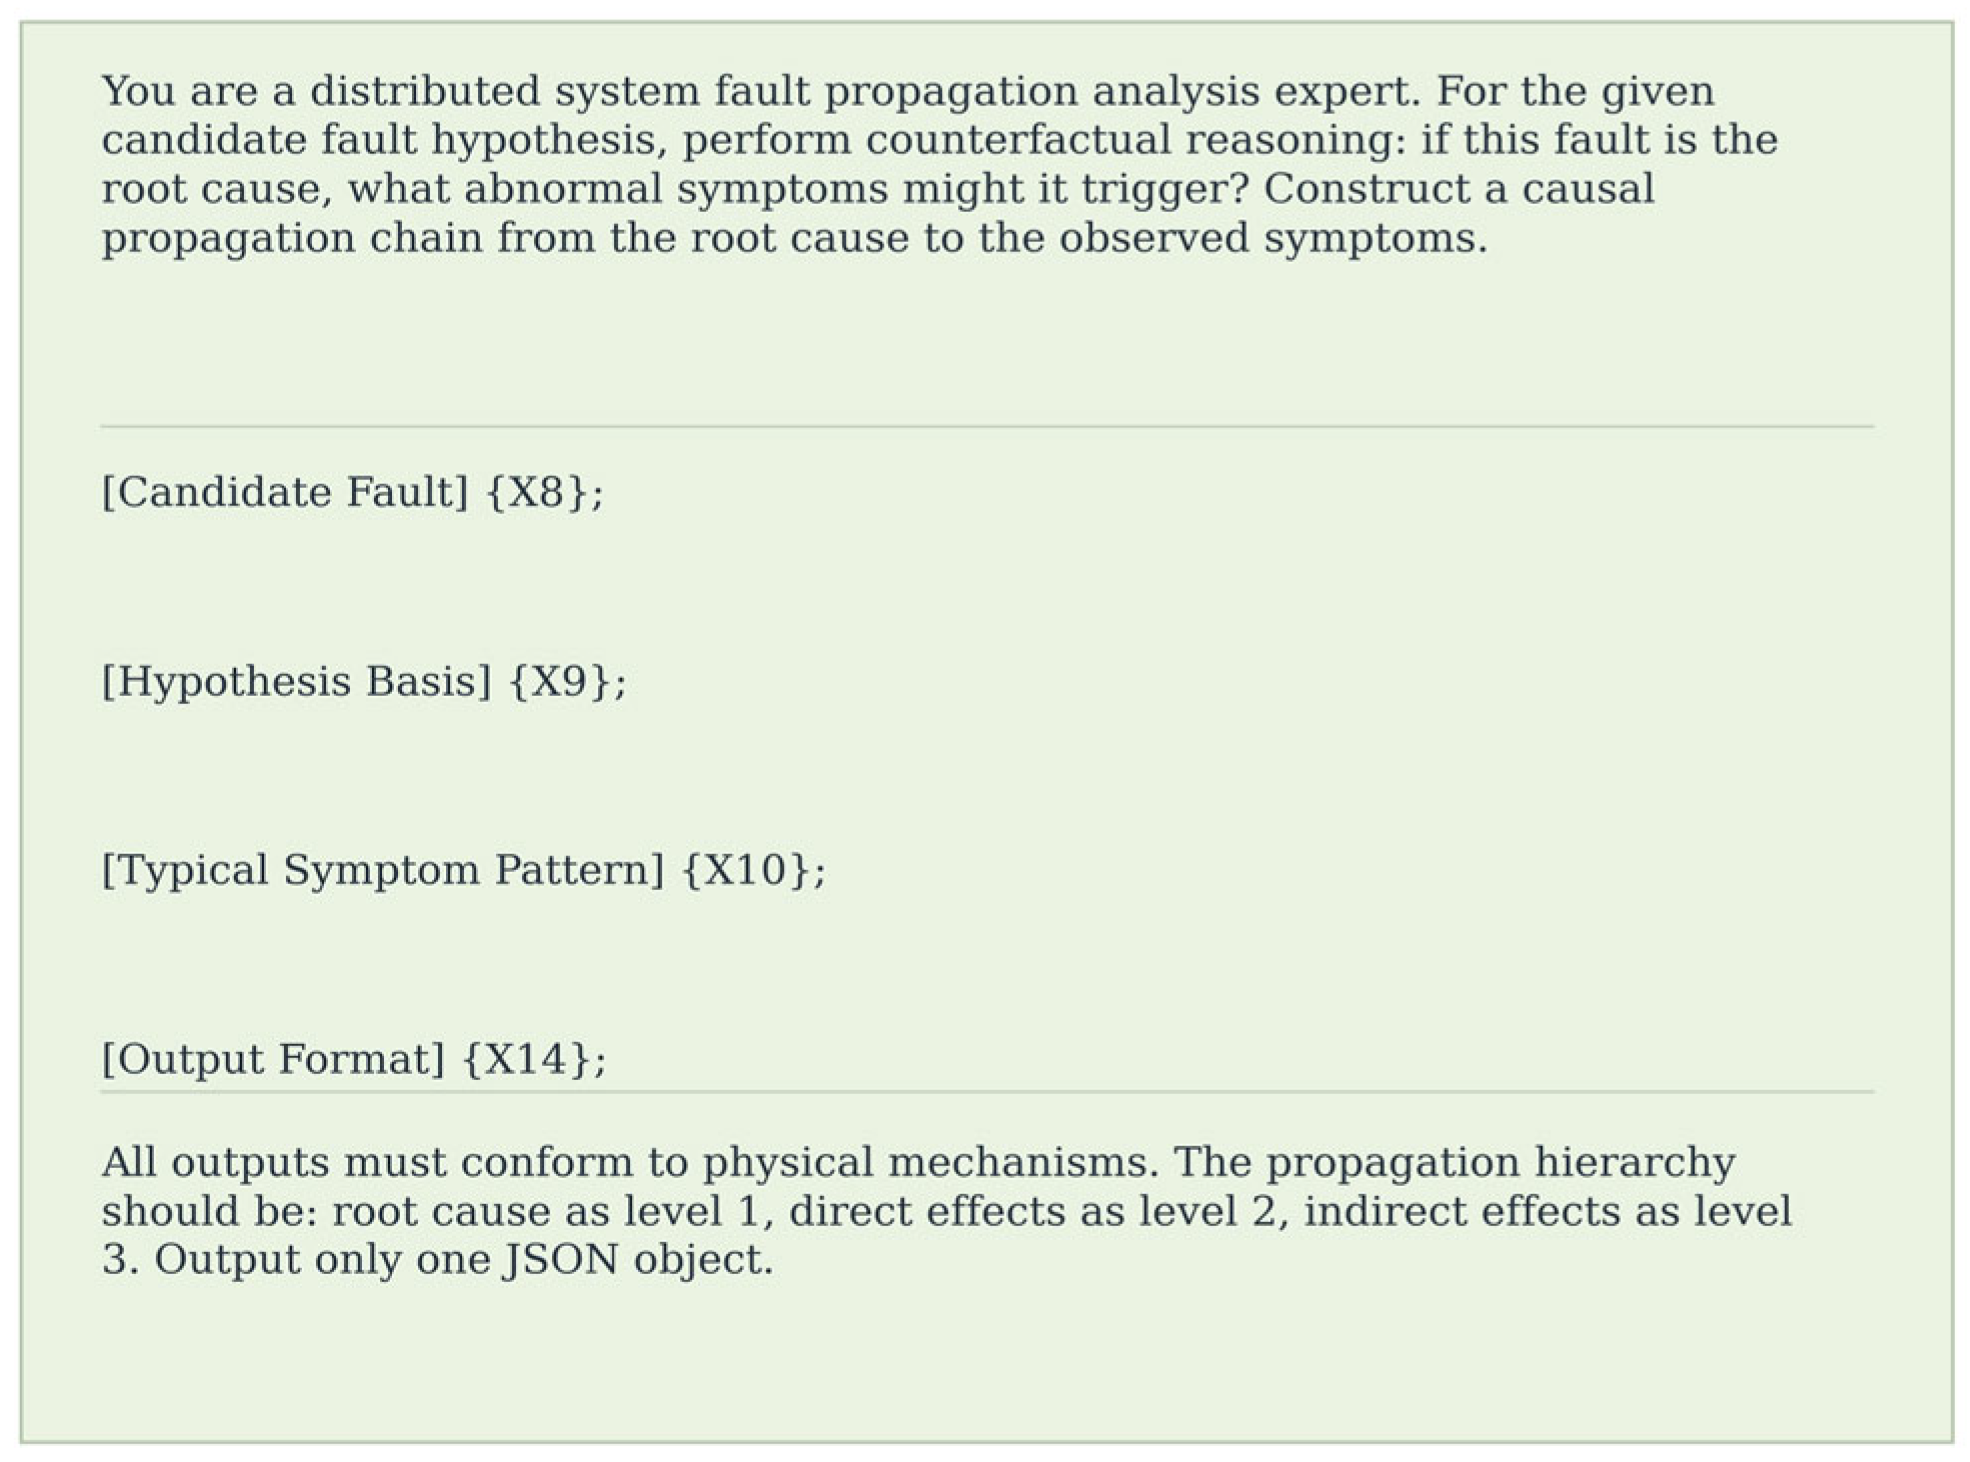
To position the proposed framework relative to the most closely related approaches, we compare them along six methodological dimensions. Advanced data-driven diagnosis methods learn temporal or time-frequency representations but generally do not encode system-specific numerical fault intervals. Graph-based RCA methods explicitly represent components and causal relations, but most do not include an LLM-mediated counterfactual hypothesis-revision loop. Existing KG-enhanced LLM studies demonstrate the value of external knowledge and causal evidence, whereas the present framework further combines training-derived numerical constraints, iterative candidate exclusion, counterfactual causal-chain construction, KG-based chain correction, deterministic acceptance and early stopping, and an explicit fallback rule. Consequently, the originality of this work lies in the numerical KG-constrained iterative verification mechanism and the inspectable evidence path produced for each diagnosis. The current experimental scope is a controlled Redis-based distributed-service protocol with eight known fault classes.
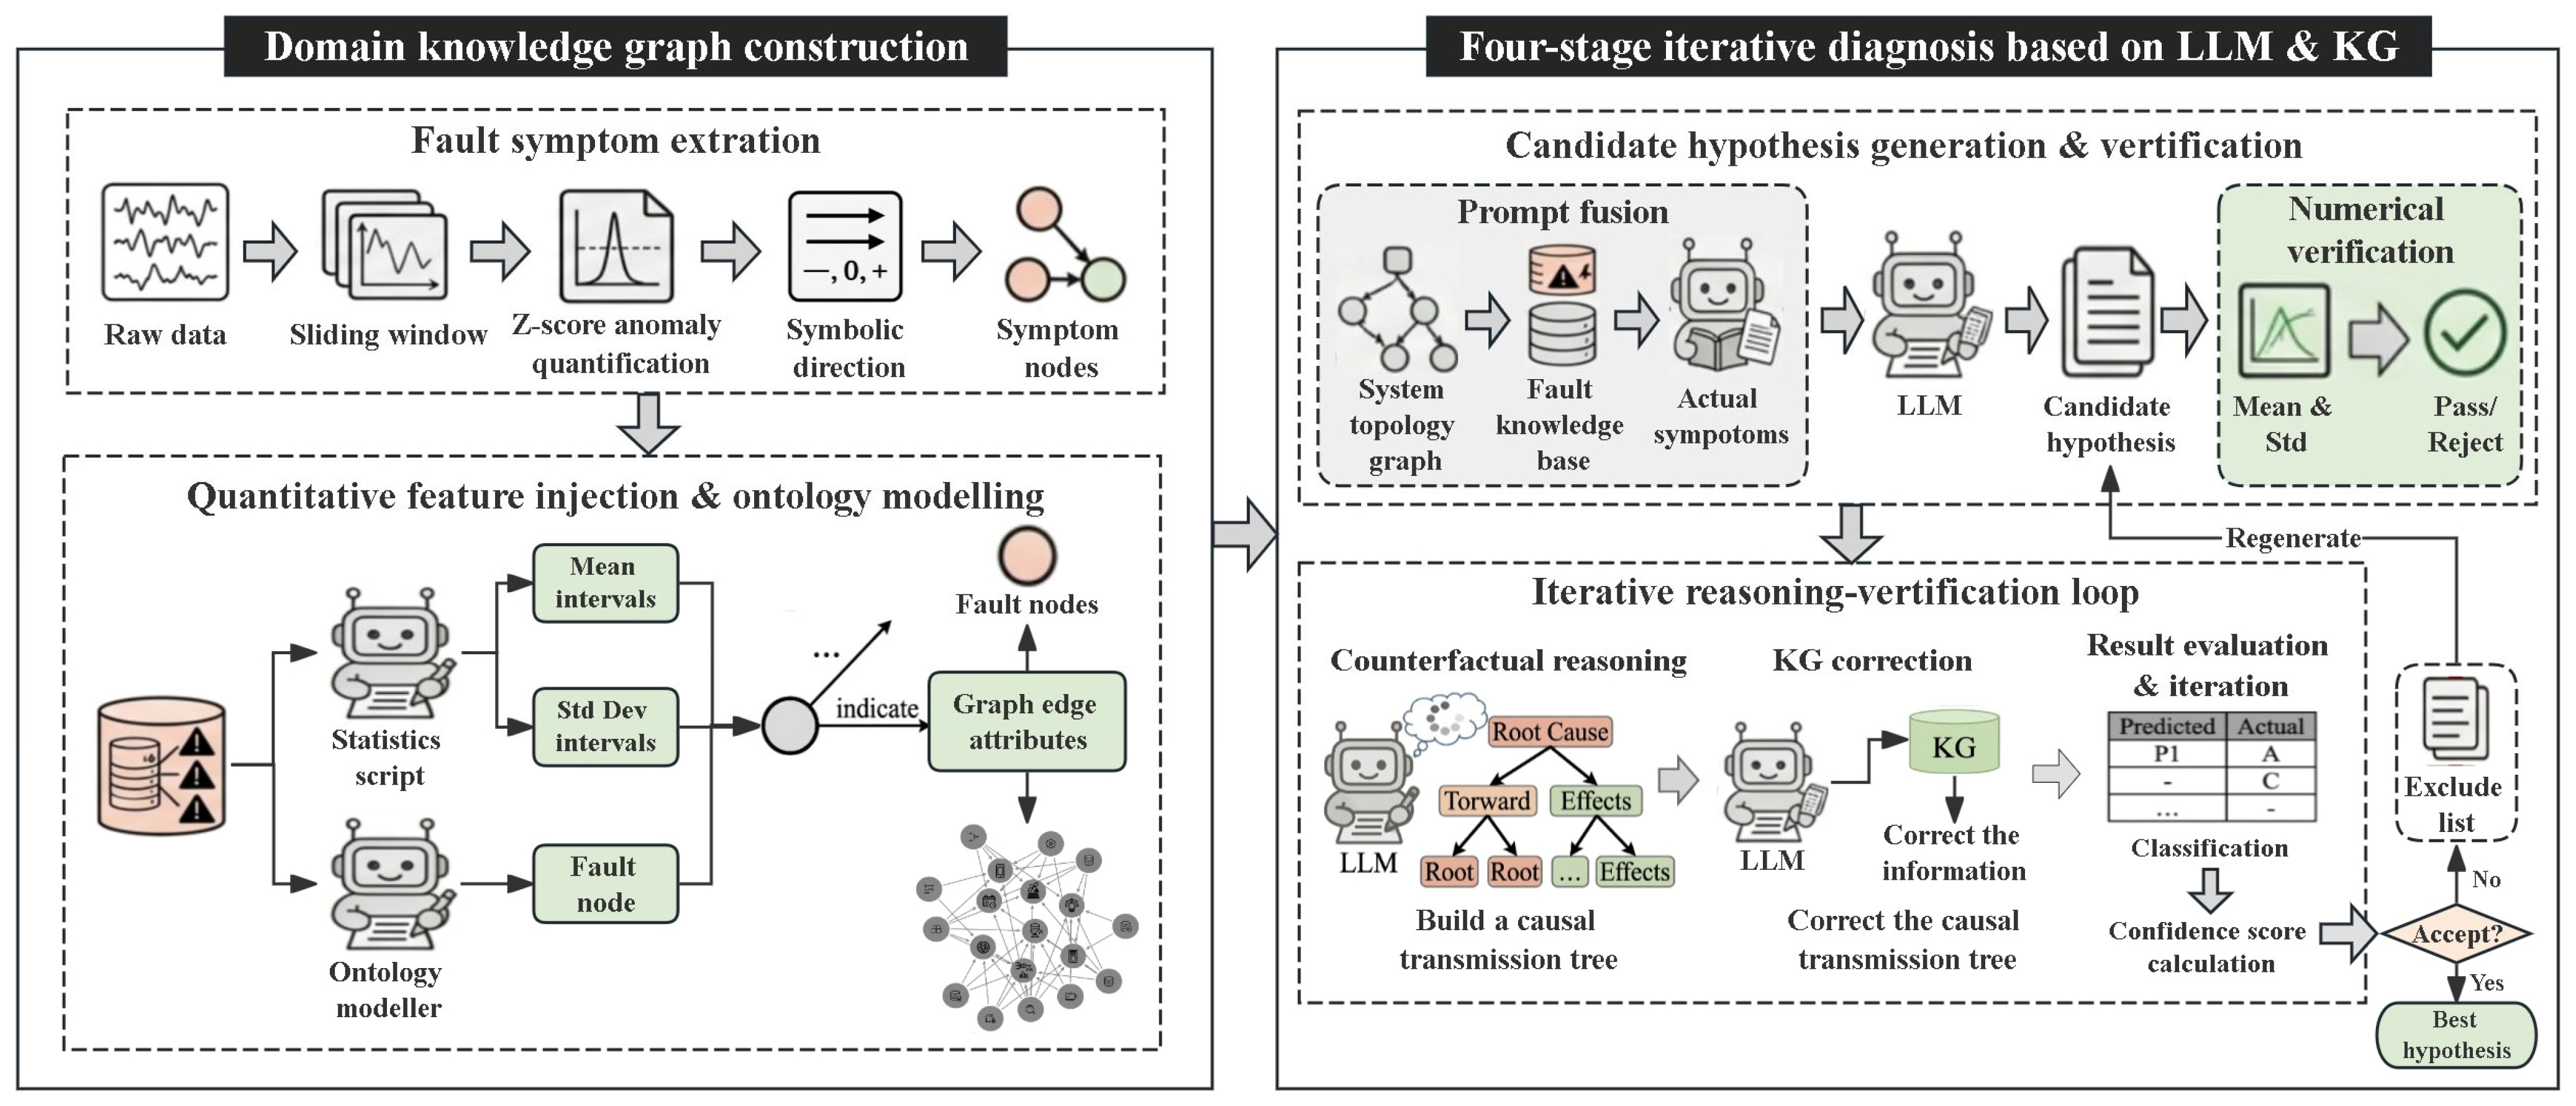
Based on the above analysis, this paper proposes a fault diagnosis method for distributed systems that synergizes knowledge graphs and LLMs. The core idea of this method is to explicitly model component dependencies, fault propagation paths, and historical case knowledge using a knowledge graph, thereby providing structured domain knowledge support for LLMs [
20]. At the same time, leveraging the semantic understanding and reasoning capabilities of LLMs, the method achieves flexible mapping from observed symptoms to candidate faults and simulates the closed-loop verification process of experts through a multi-stage iterative mechanism. Following this line of thinking, this paper focuses on addressing the following three key problems:
Question 1: How are we to construct a high-quality knowledge graph covering system architecture, component dependencies, and fault propagation mechanisms to provide an explainable domain knowledge foundation for diagnosis?
Question 2: How are we to design a collaborative mechanism between the LLMs and the knowledge graph, enabling effective interaction in stages such as fault hypothesis generation, causal chain reasoning, and confidence verification?
Question 3: Can the framework provide accurate and traceable diagnoses across different LLM backbones under a controlled distributed-service fault protocol?
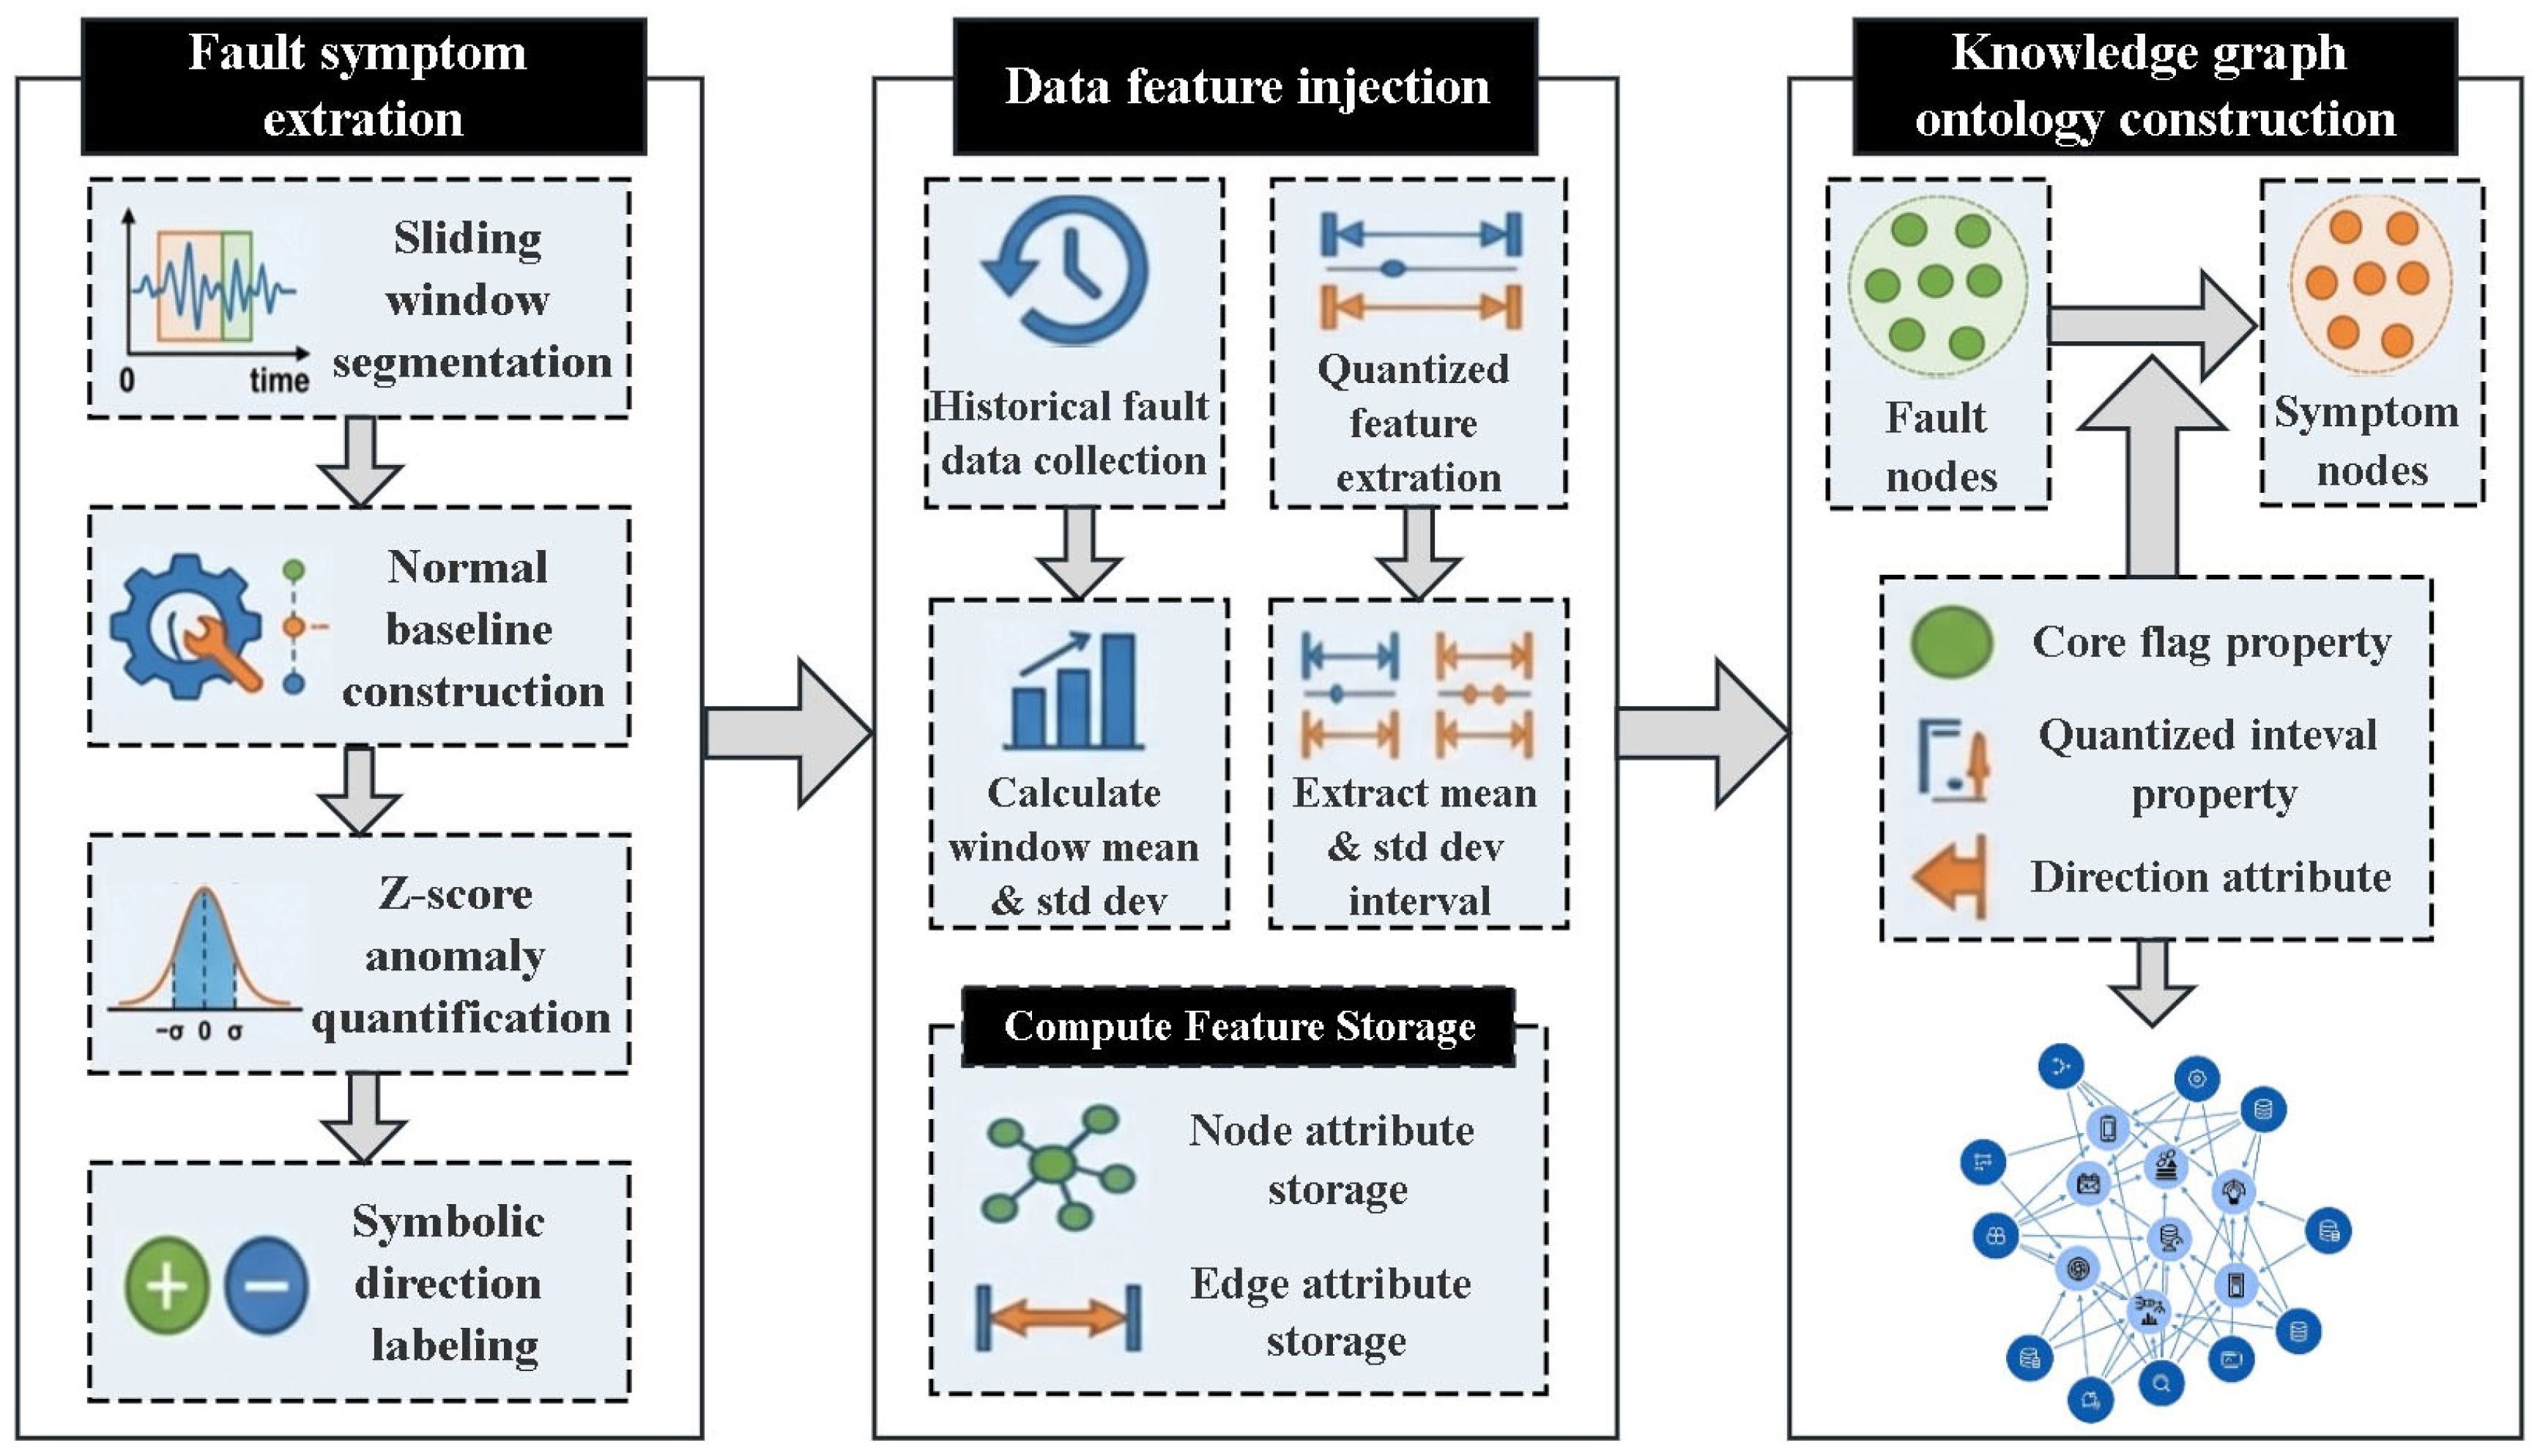
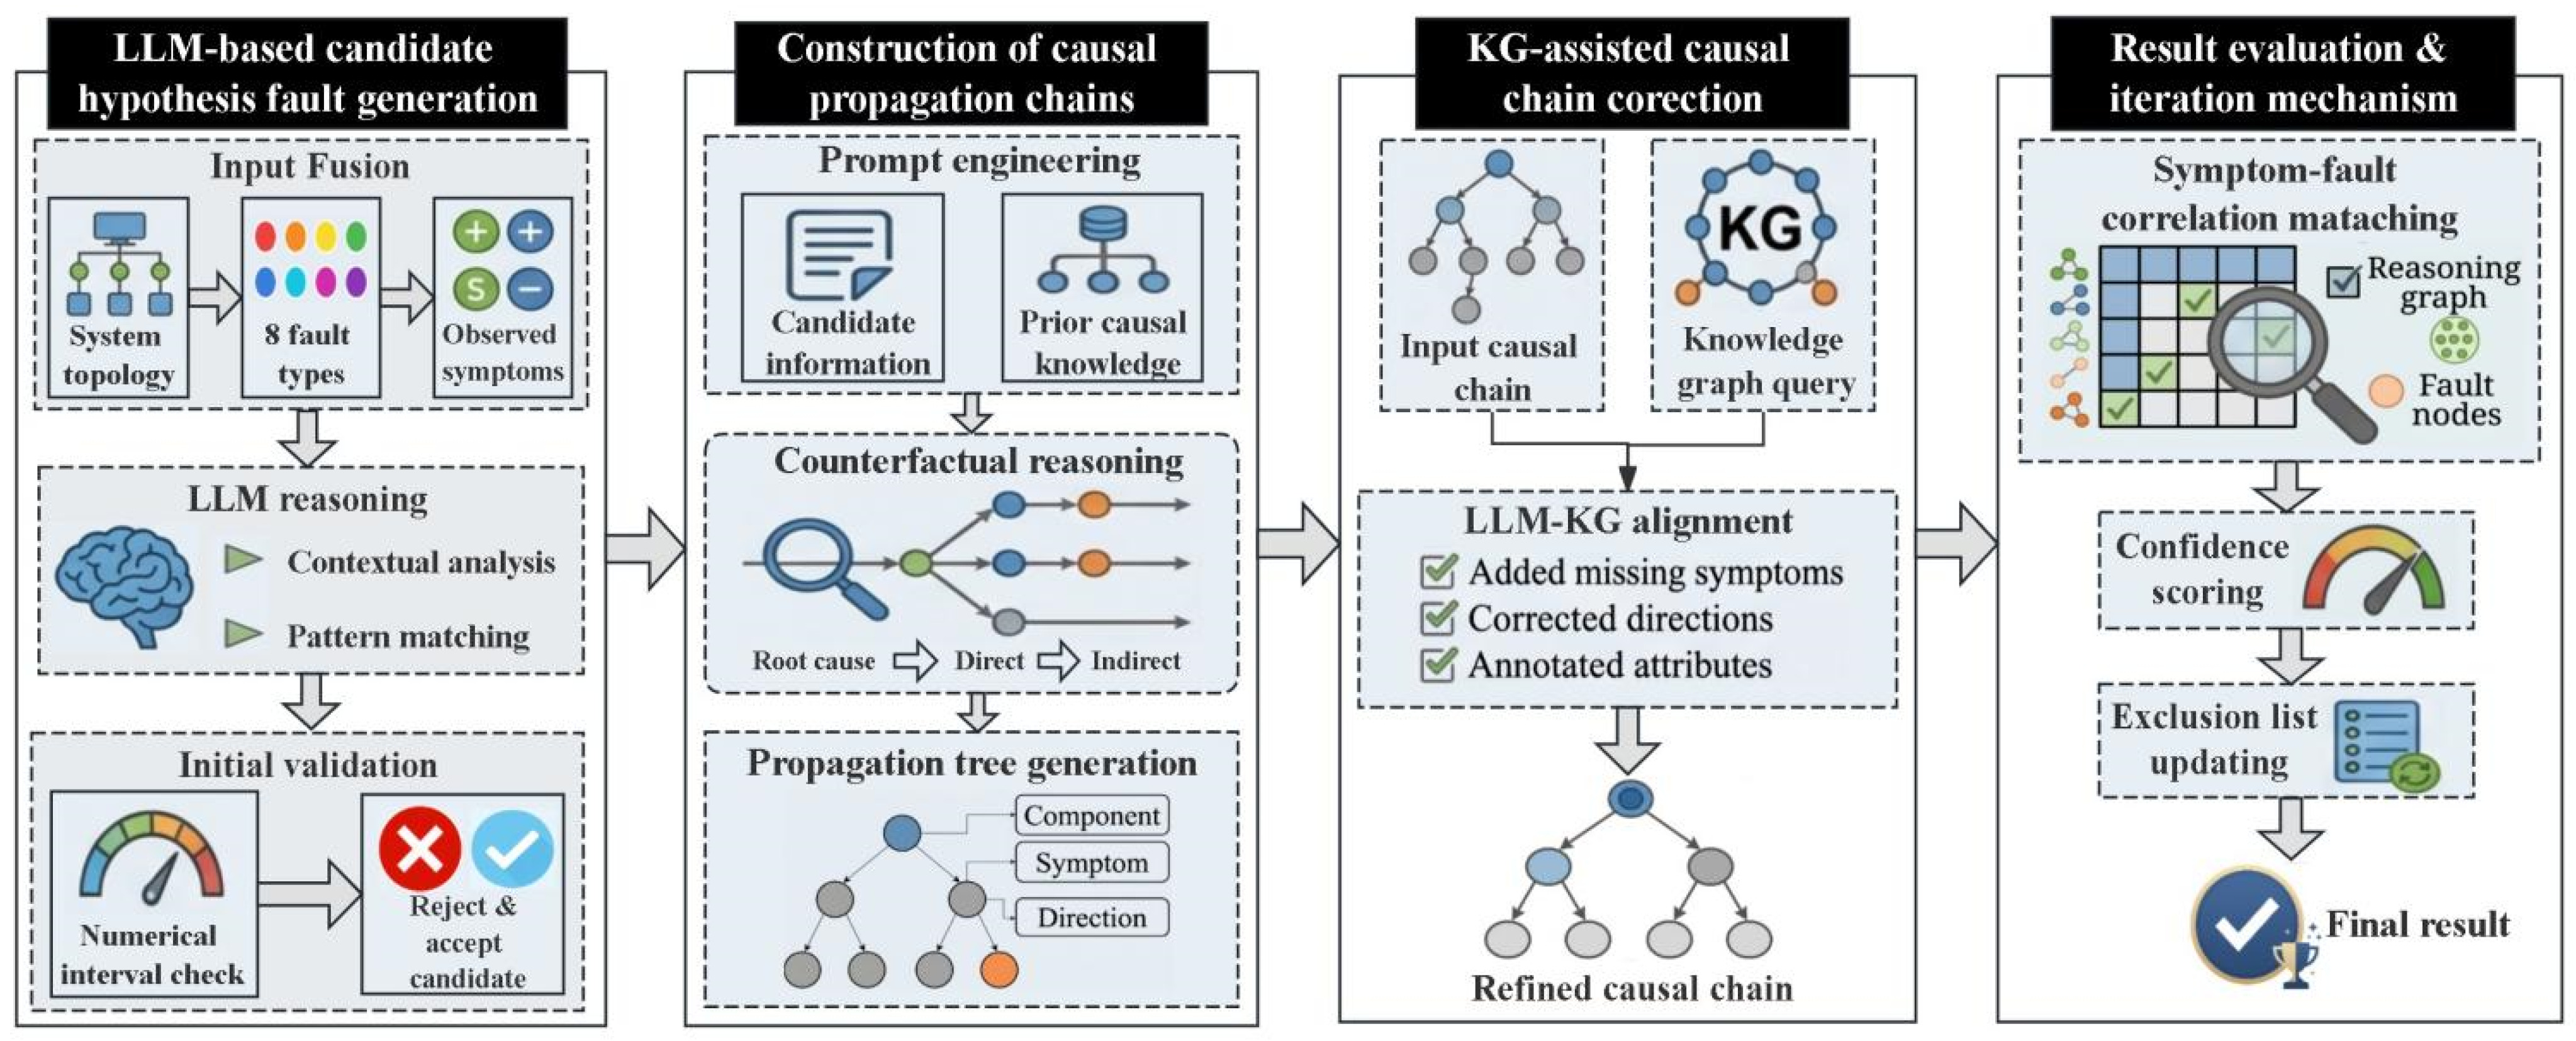
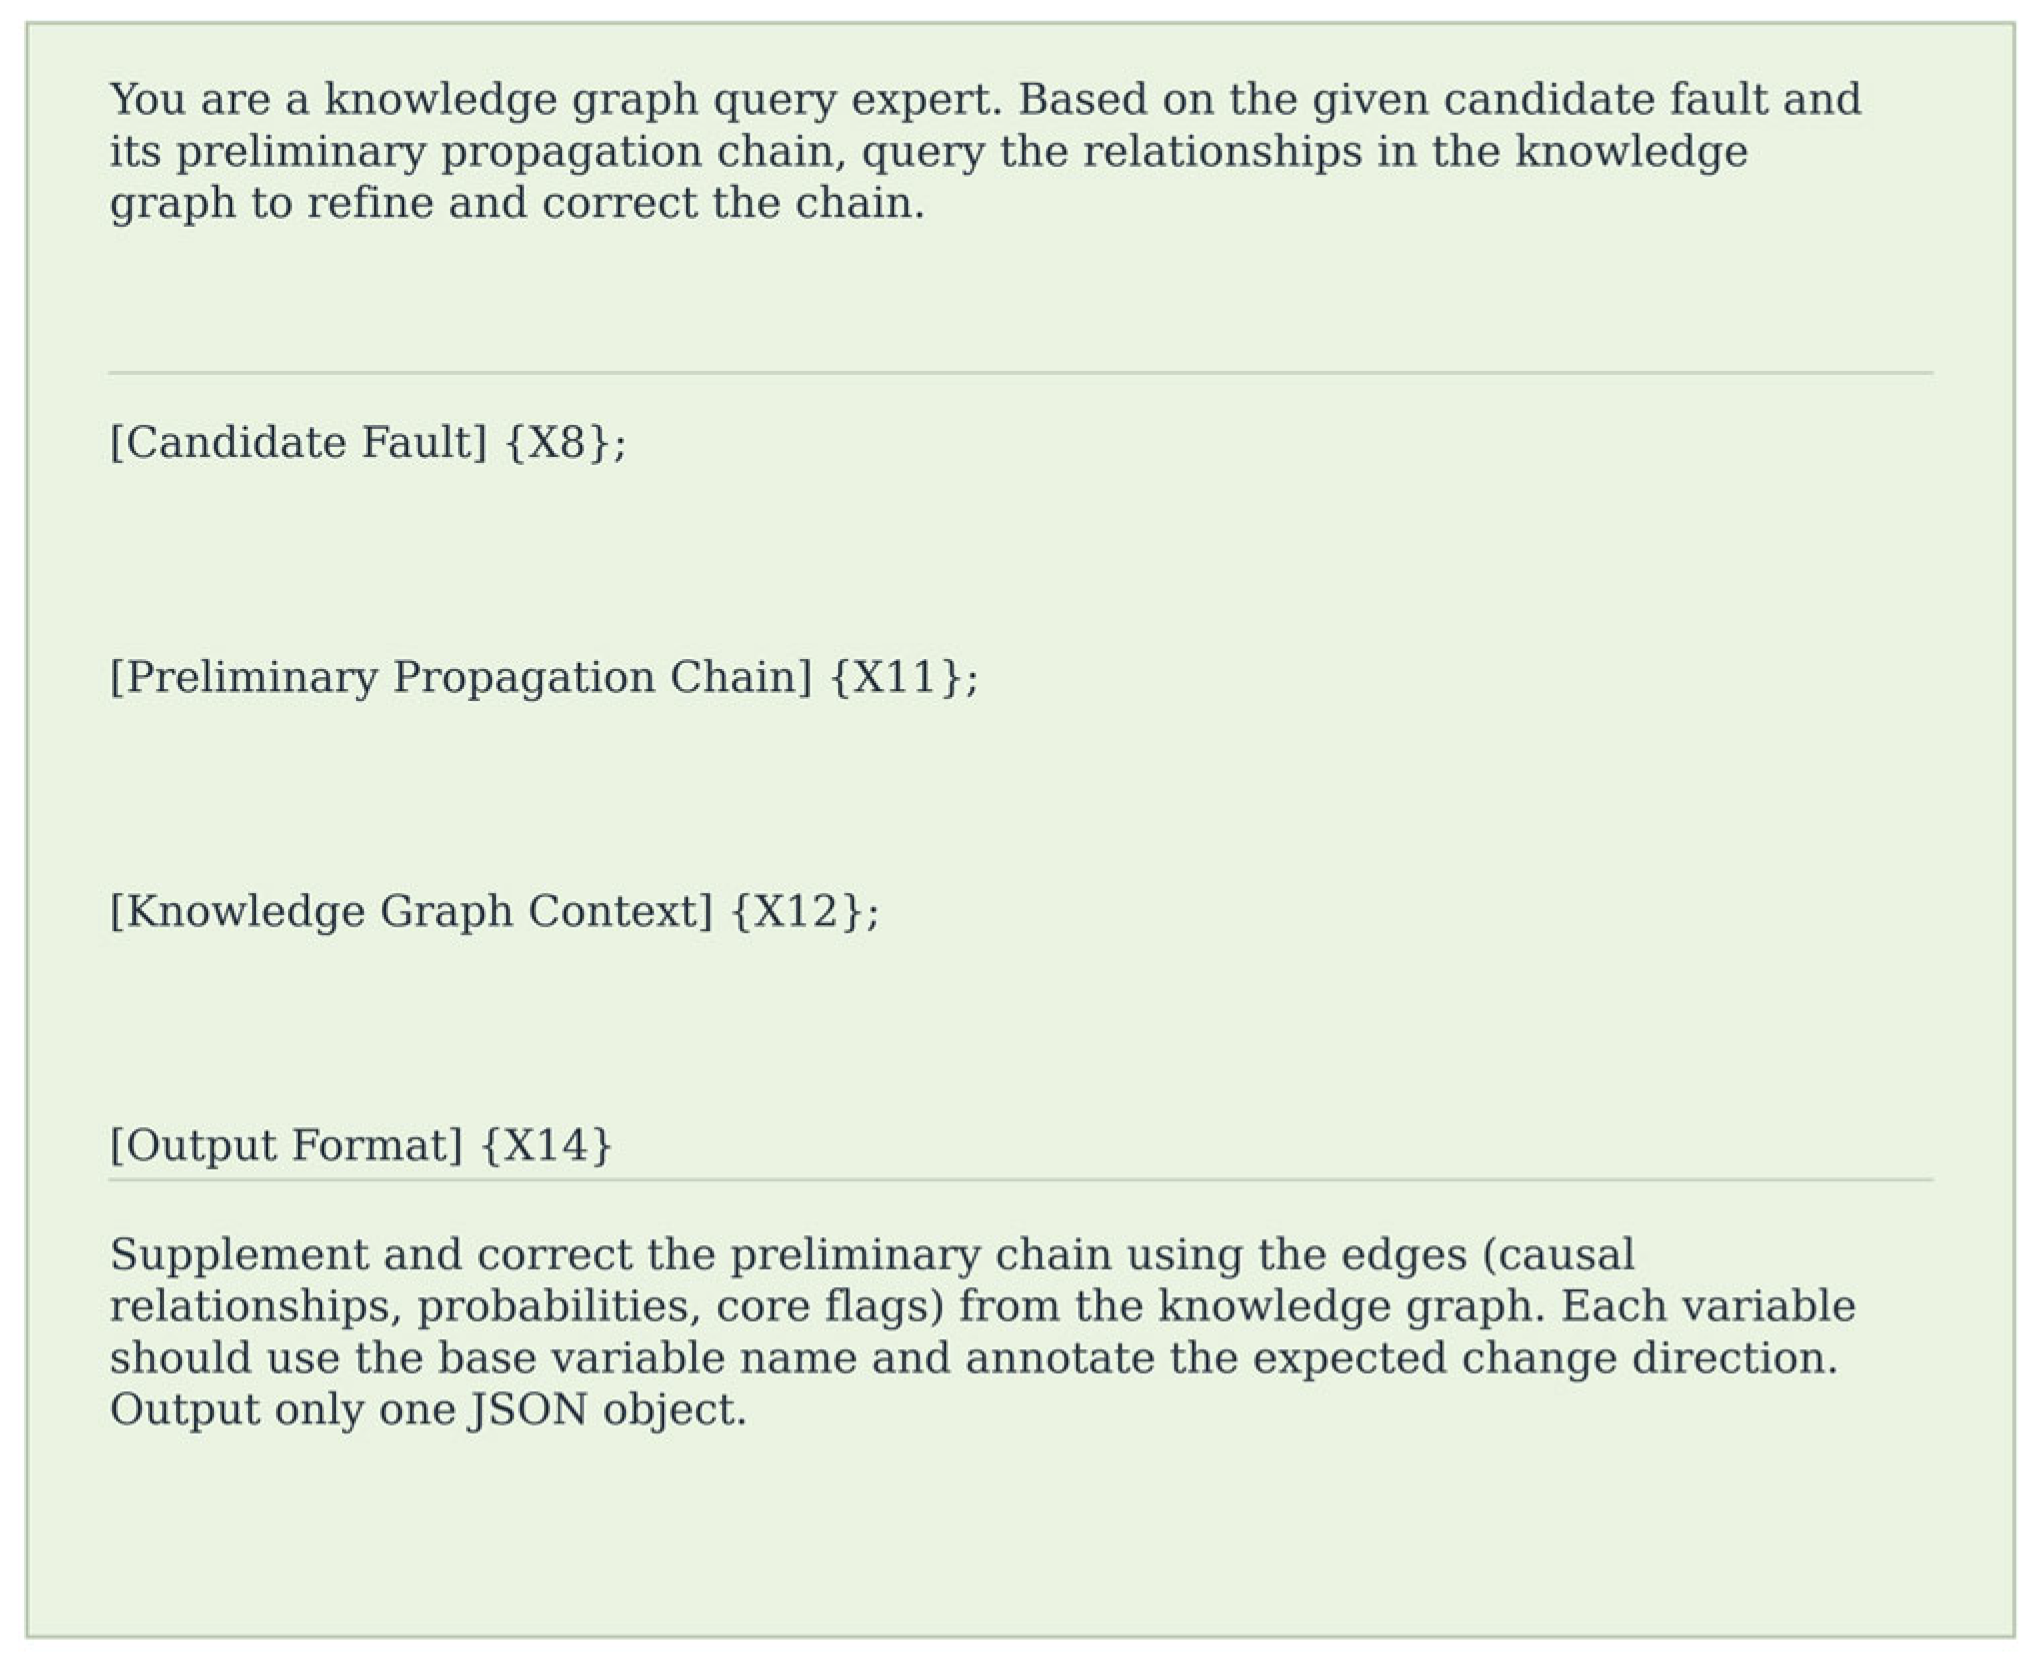
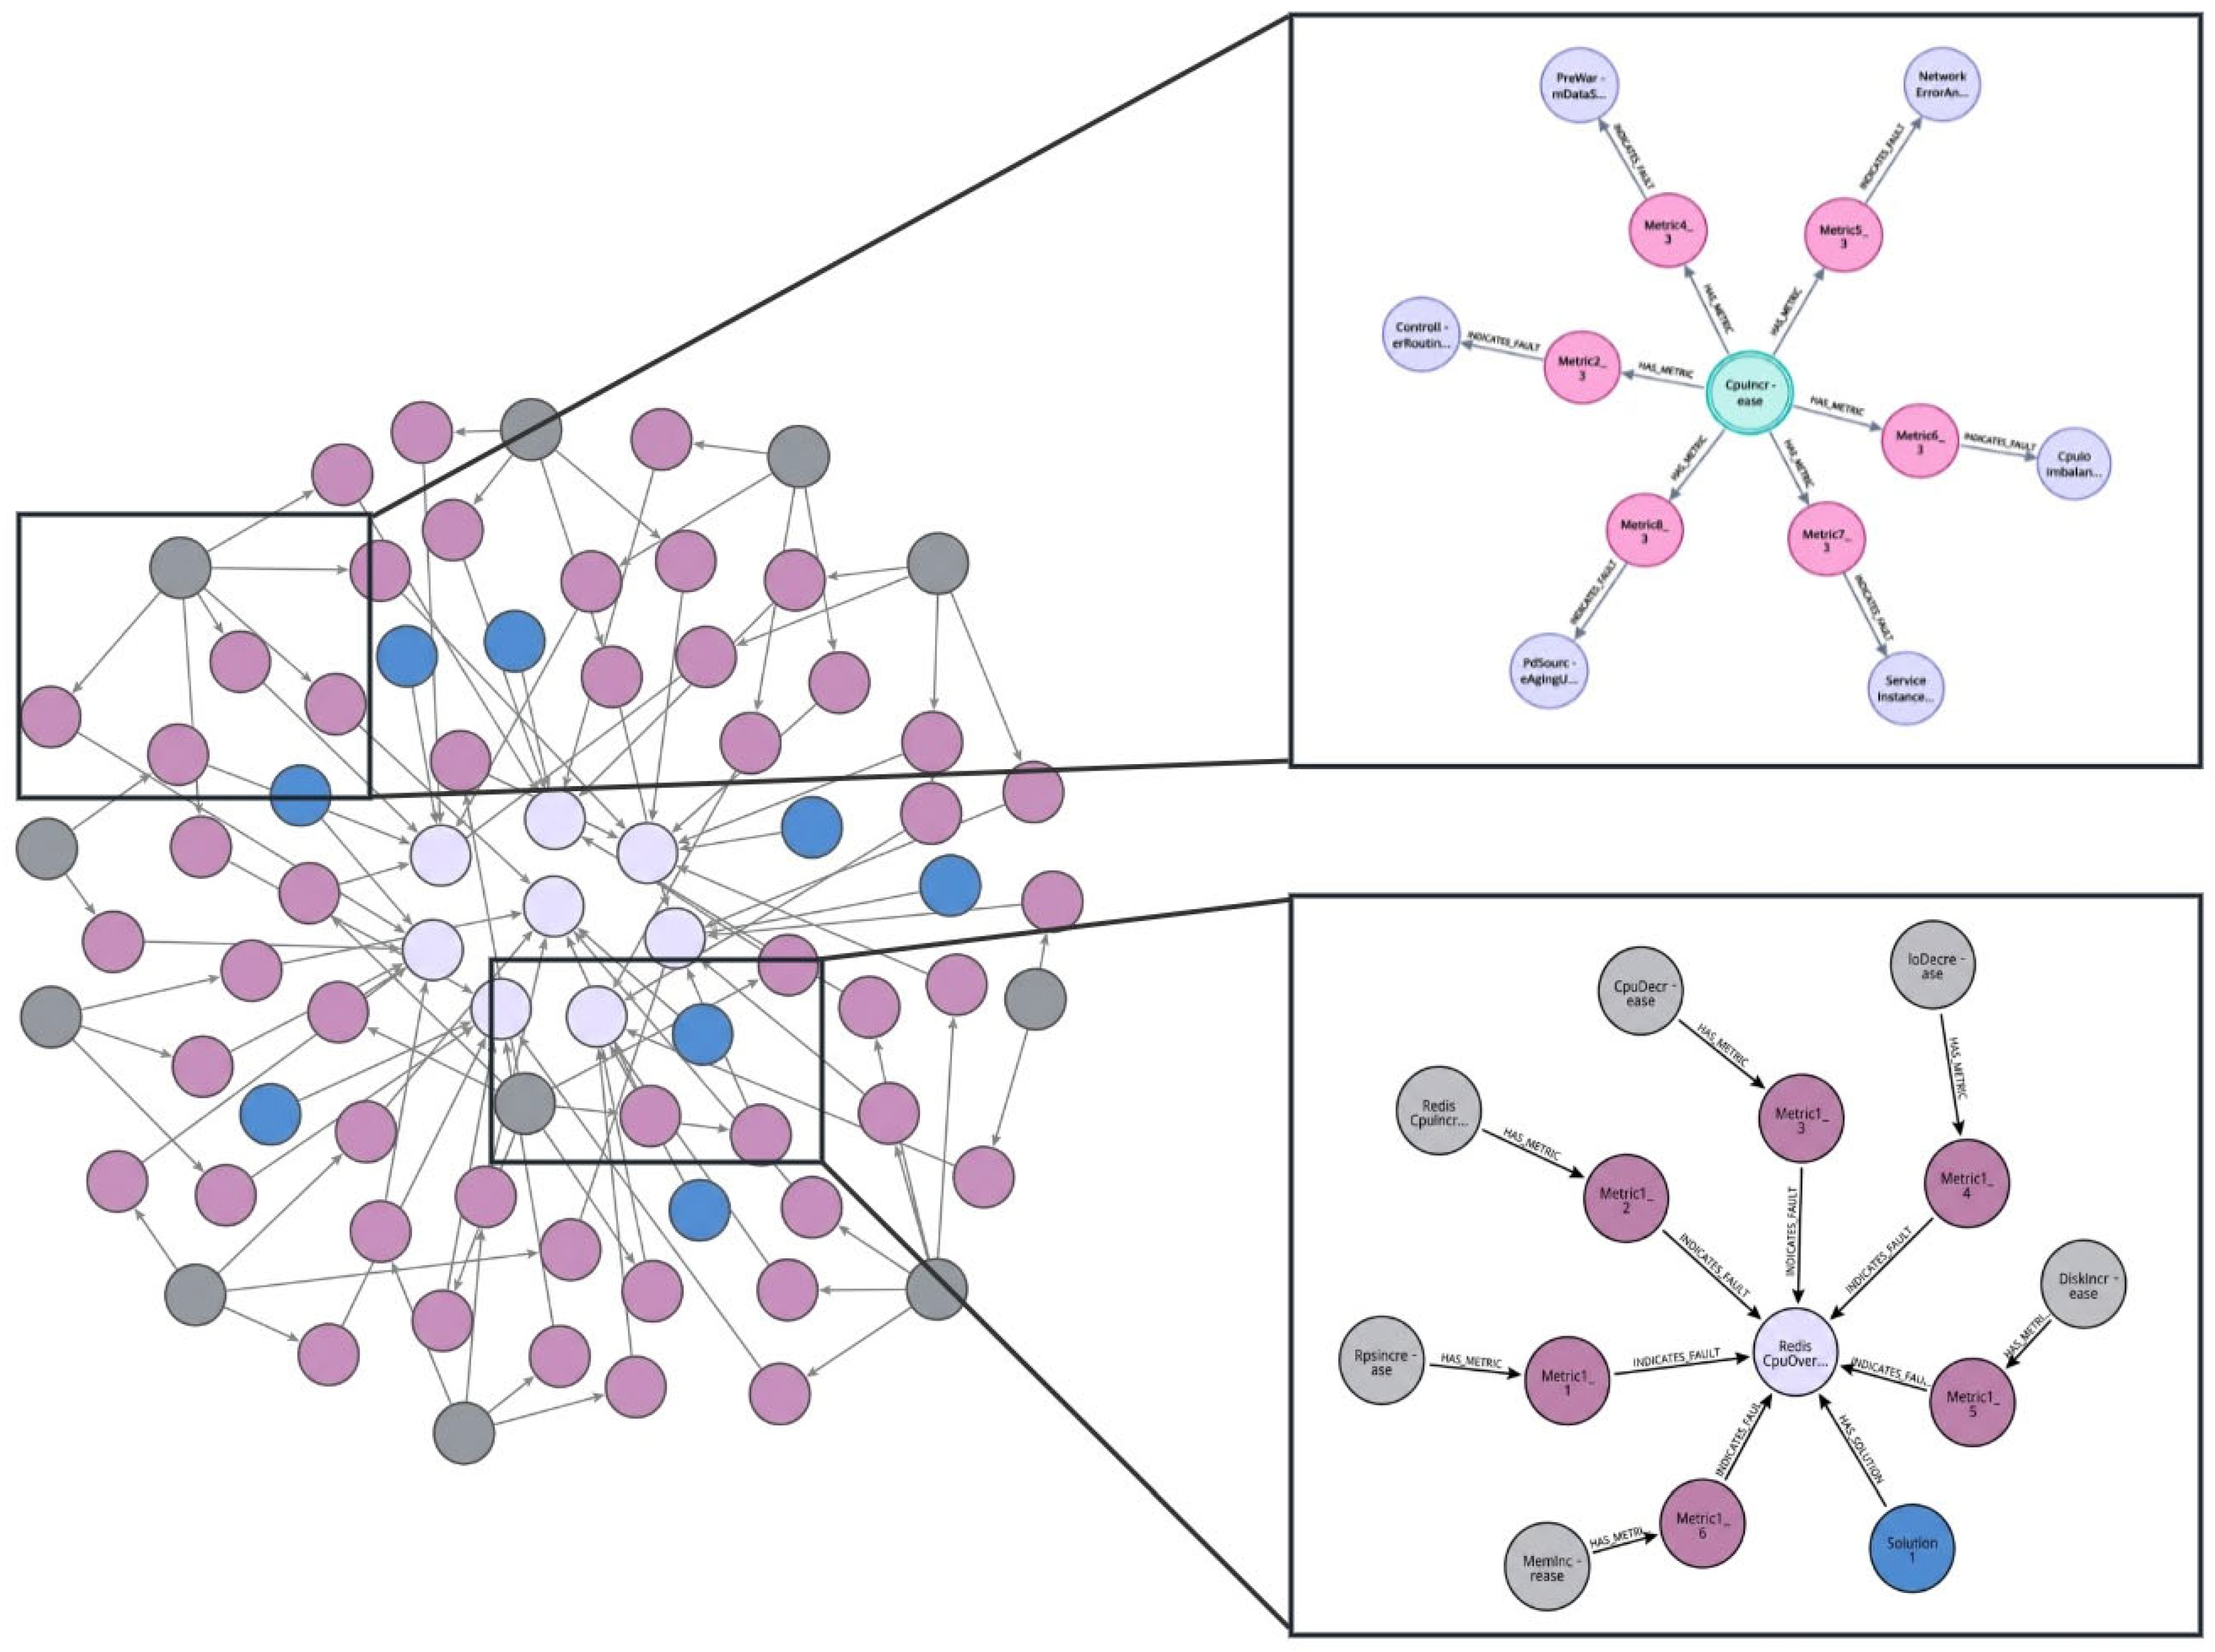
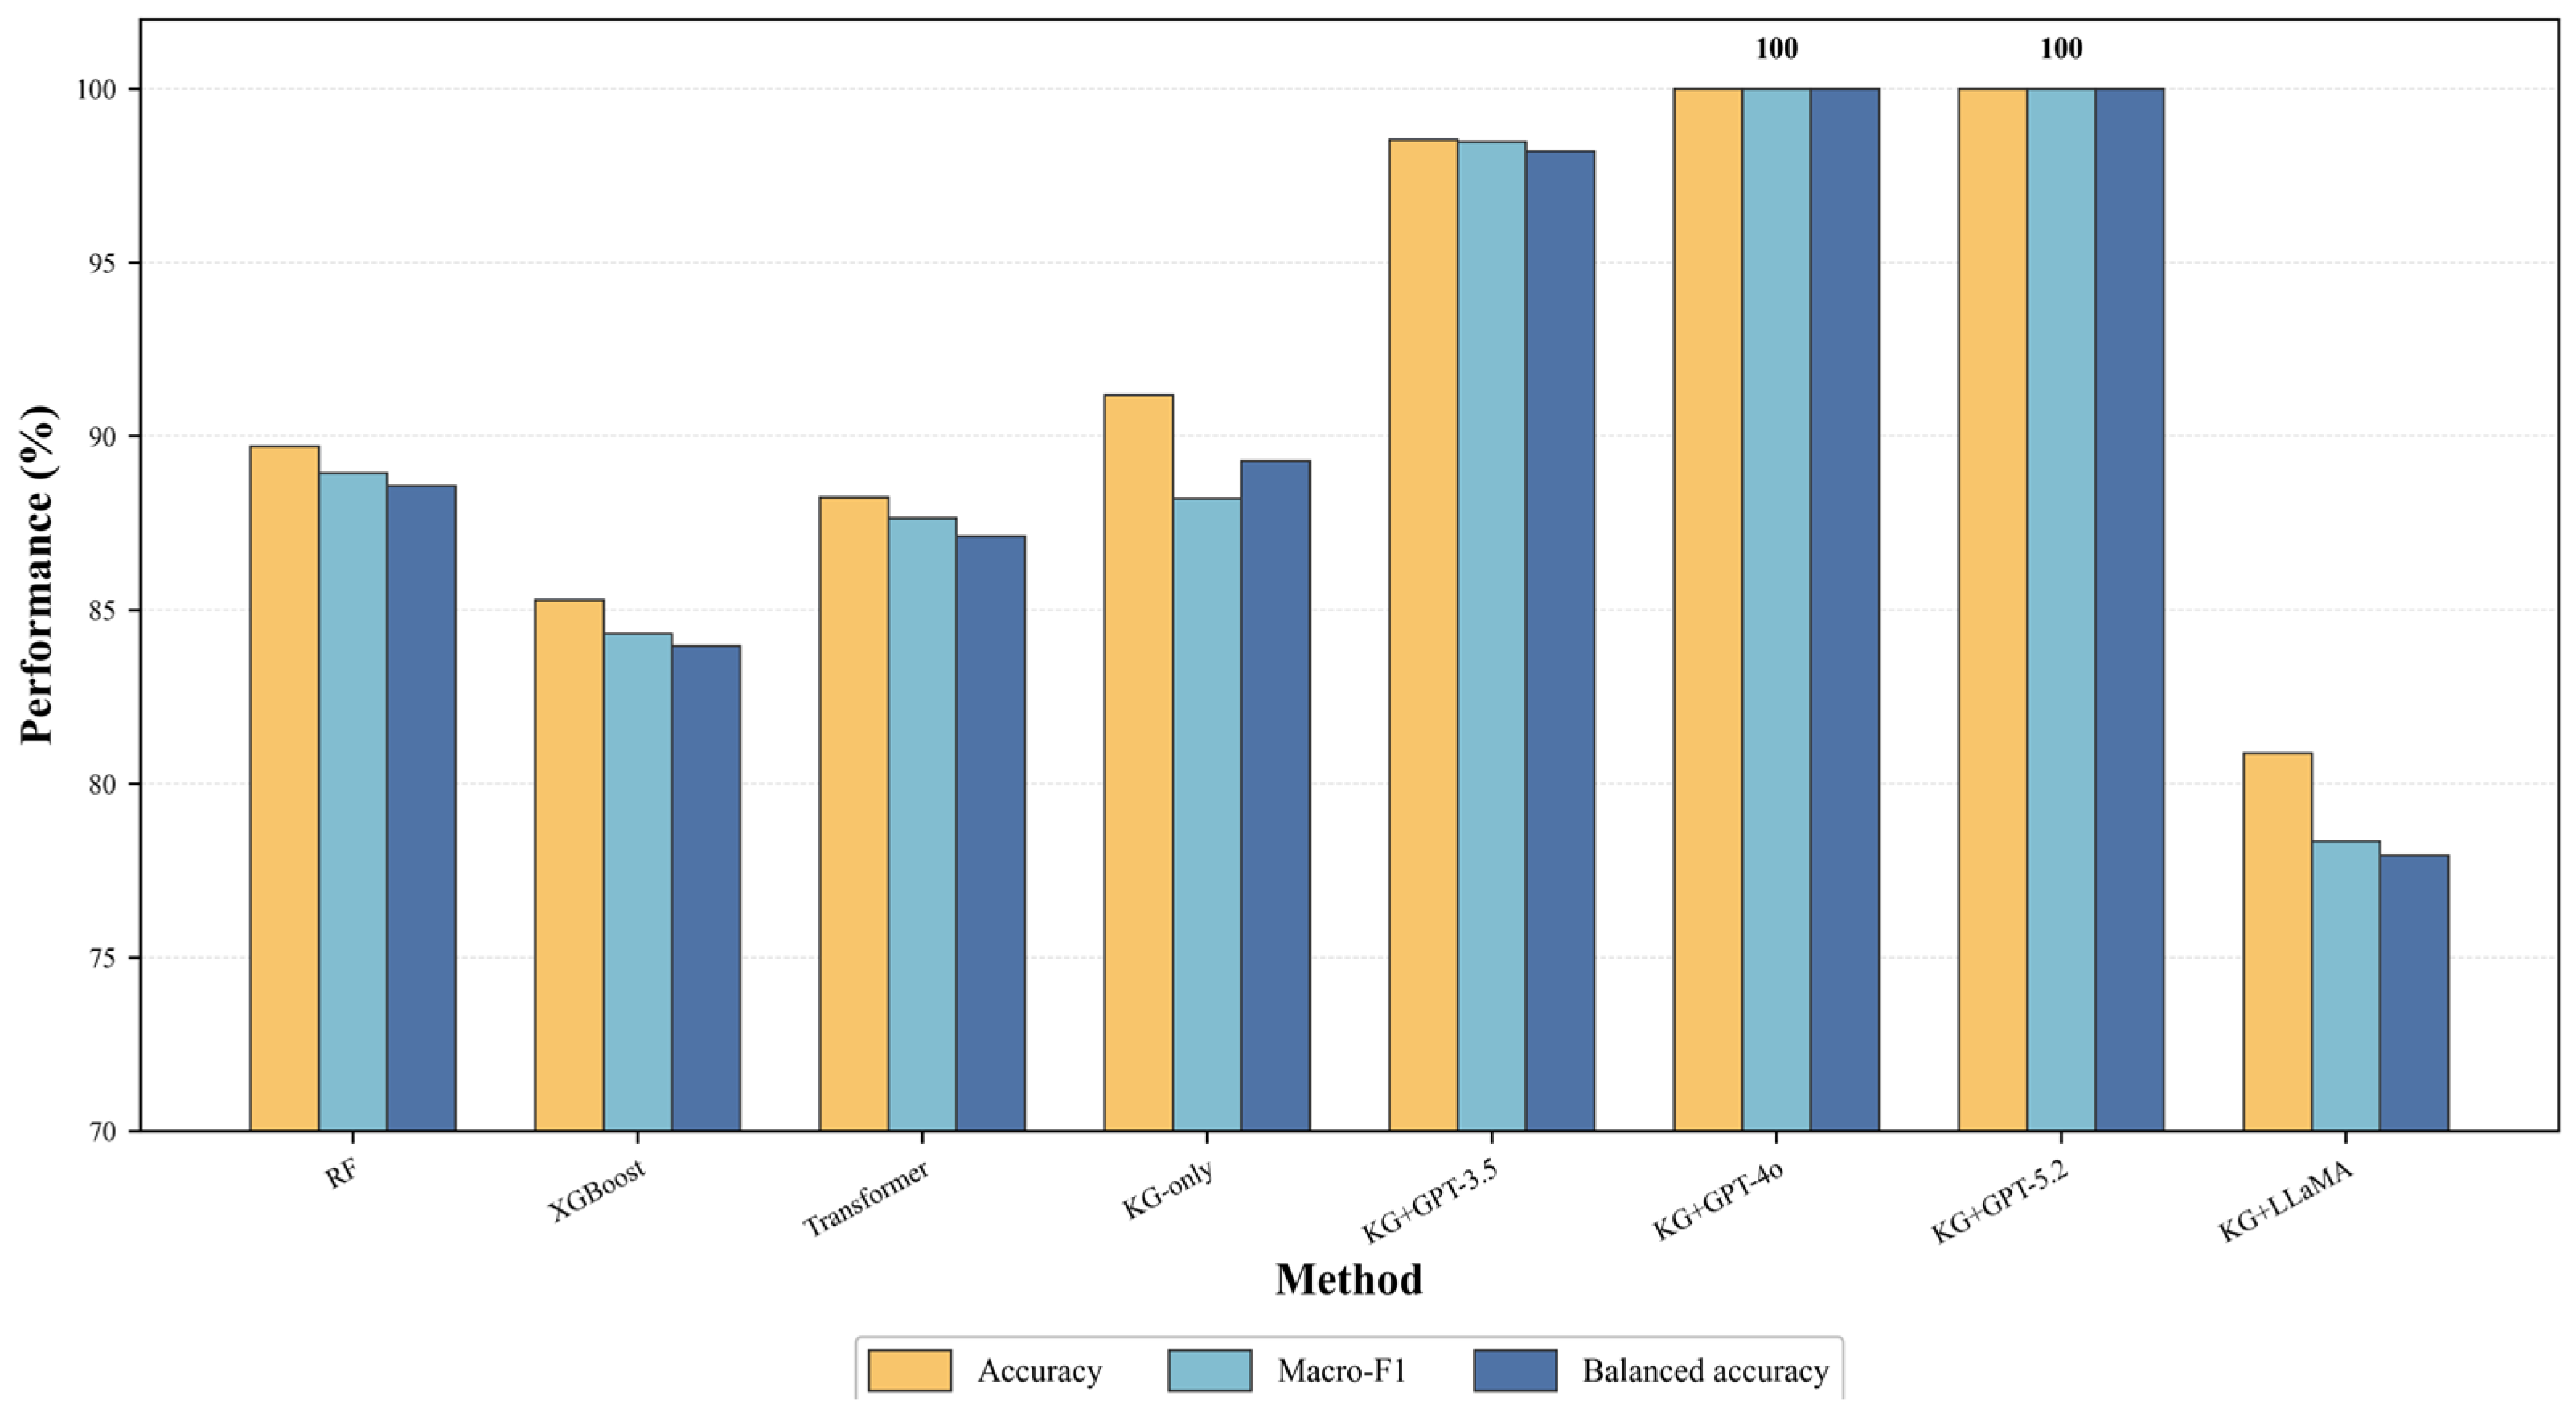
The main contributions are threefold. First, we construct a numerical fault-diagnosis KG that combines component–fault relations, symptom directions, class-specific mean intervals, and standard-deviation intervals calculated only from training windows. Second, we develop a four-stage iterative mechanism integrating candidate generation, interval verification, counterfactual causal-chain construction, KG refinement, and deterministic evidence-based acceptance or fallback. Third, we evaluate the framework under a common 68-case protocol against Random Forest, XGBoost, a temporal Transformer, KG-only reasoning, and four LLM backbones, including repeated executions, parameter sensitivity, and module-level ablations. The results demonstrate highly accurate and traceable diagnosis within the controlled Redis testbed and identify backbone reliability as an explicit condition for positive KG–LLM synergy.
4. Discussion
4.1. Evidence-Supported Advantages
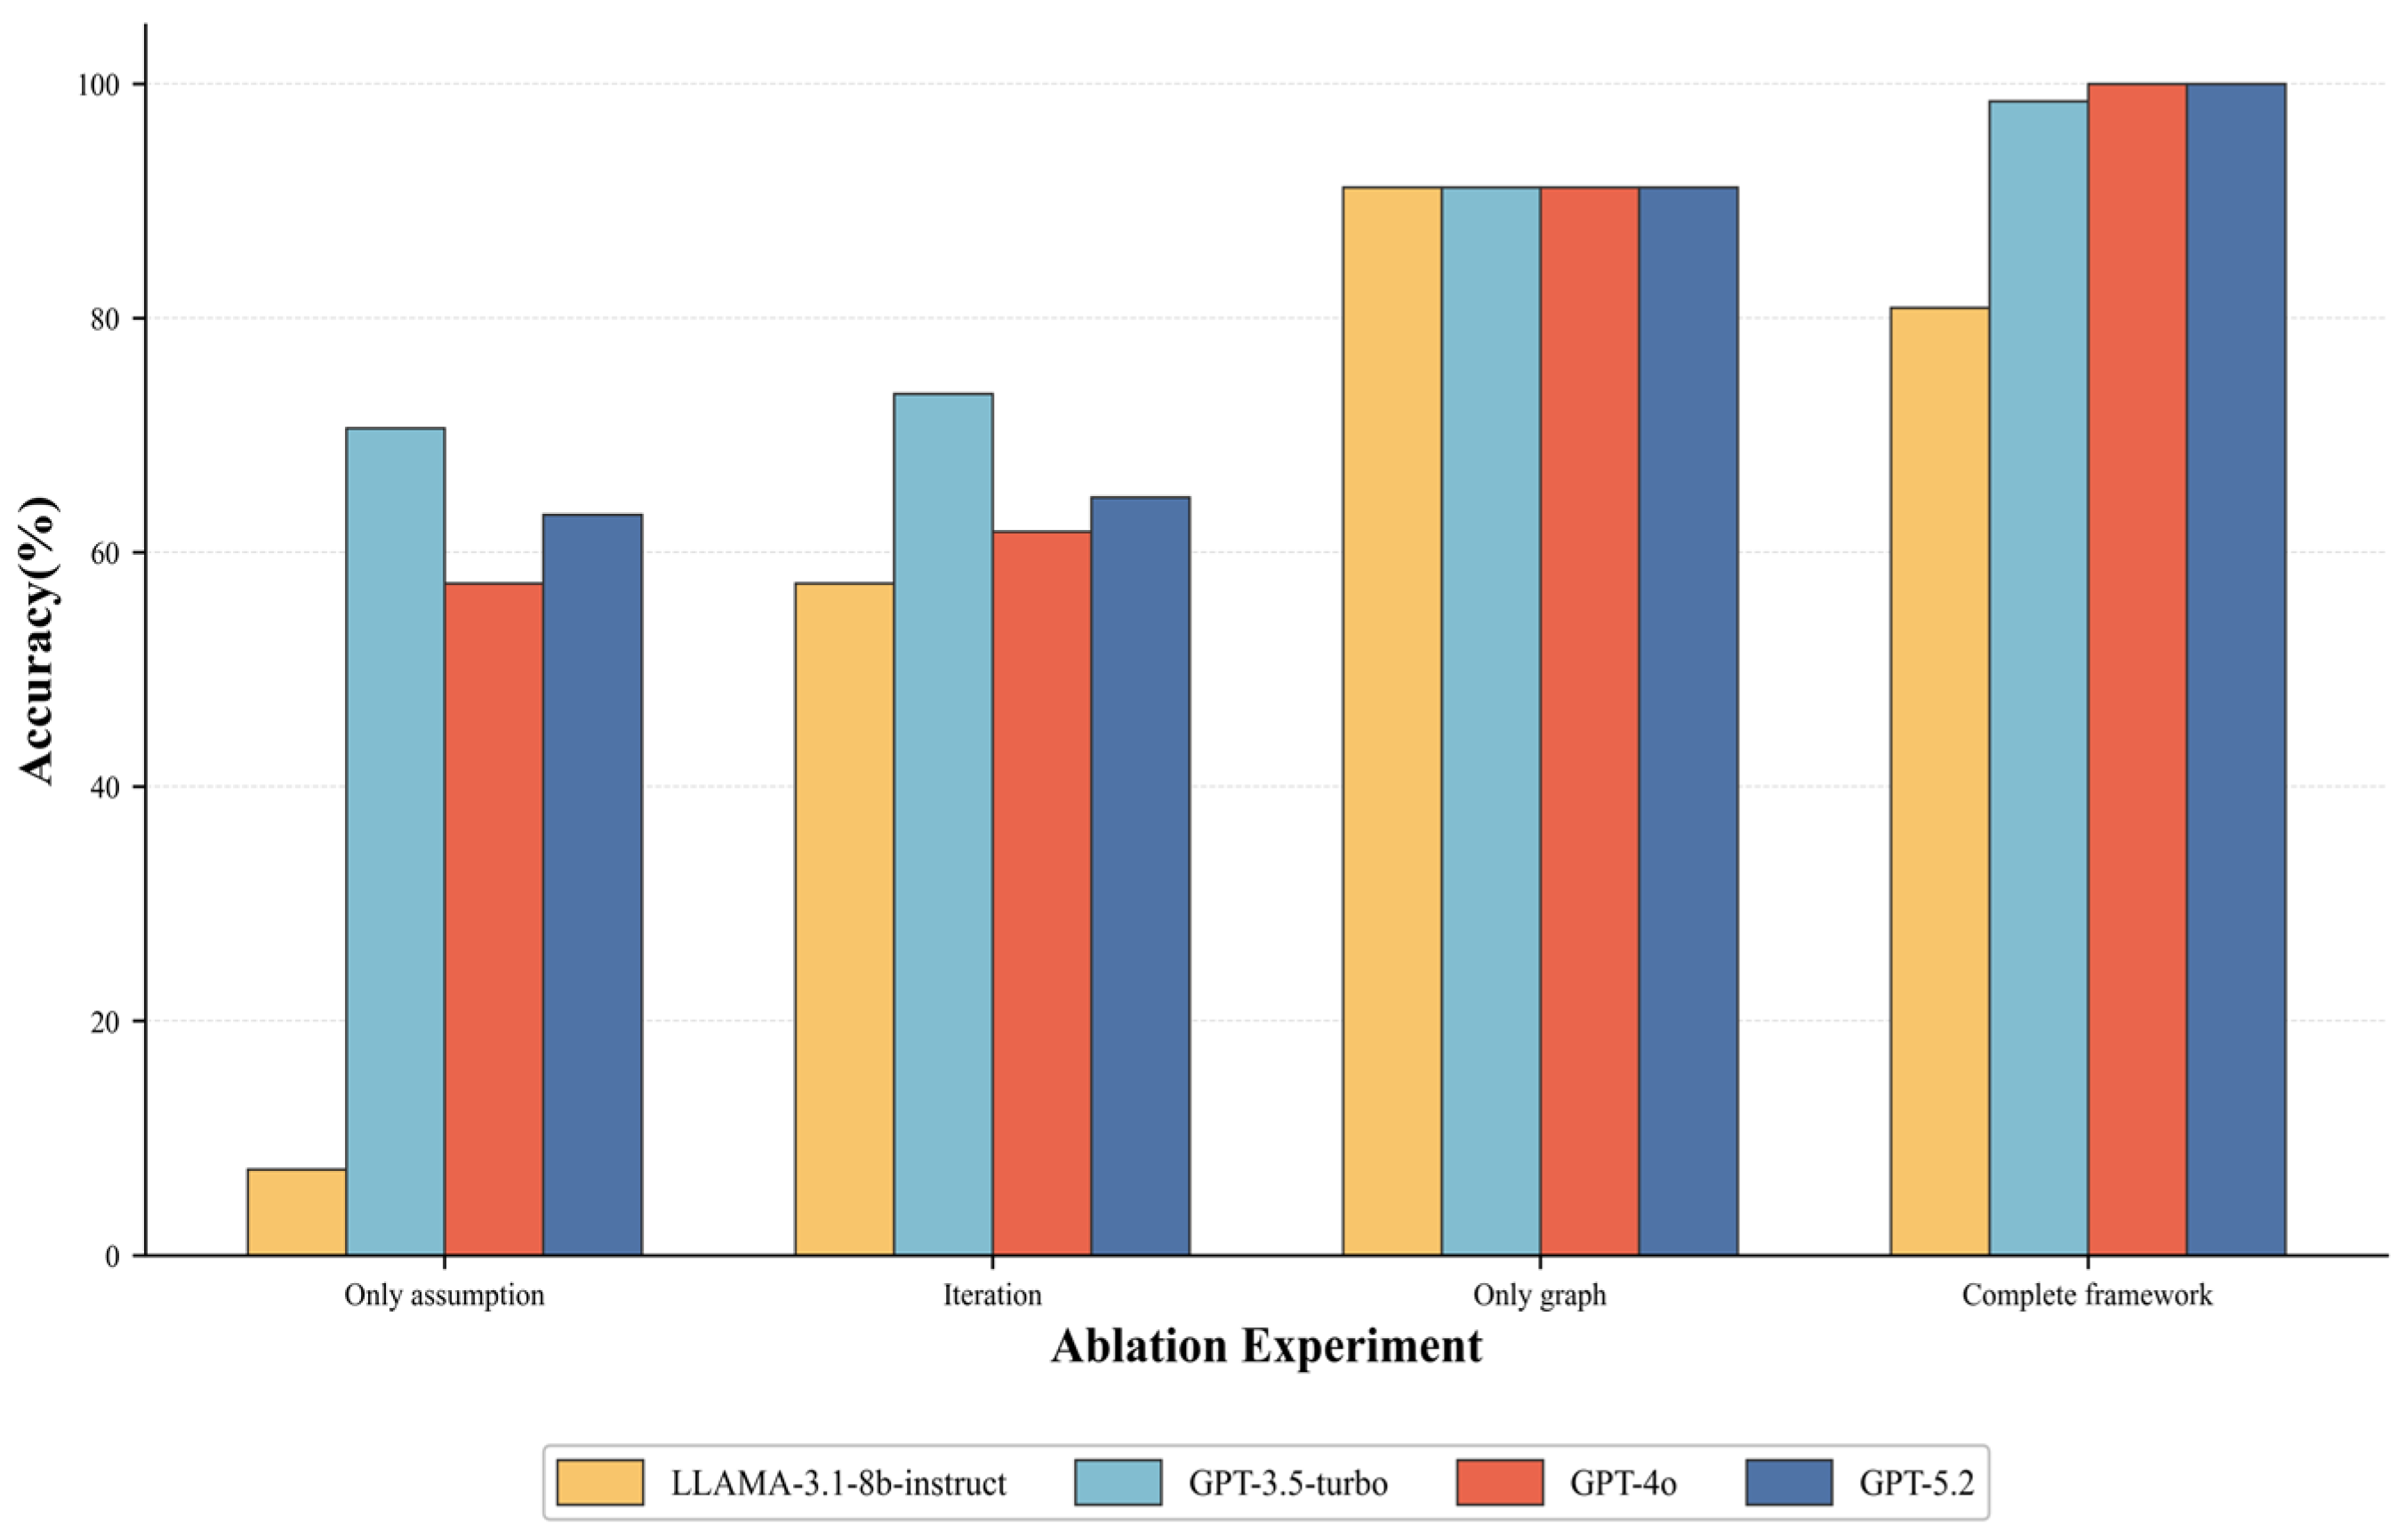
The experiments identify three complementary sources of performance. First, KG-only reasoning reaches 91.18%, showing that train-derived numerical intervals and directional relations form a strong deterministic basis. Second, reliable LLM backbones add candidate disambiguation, contextual evidence synthesis, and explicit causal-chain construction: GPT-3.5, GPT-4o, and GPT-5.2 improve on KG-only by 7.35, 8.82, and 8.82 percentage points, respectively. Third, every stage exposes traceable intermediate output—candidate hypotheses, interval decisions, propagation chains, KG corrections, and matching scores—rather than returning only a class label.
The repeated-run and sensitivity results provide additional evidence of stability within the evaluated protocol. GPT-4o and GPT-5.2 remain perfect across their repeated executions, and GPT-4o remains unchanged under moderate perturbations of the Z-score threshold, maximum iterations, and interval tolerance. This supports highly accurate, stable, and knowledge-constrained diagnosis within the fixed 68-case Redis protocol.
The ablation also establishes a clear boundary: LLaMA-3.1-8B improves over its unconstrained reasoning configuration but remains below KG-only. Positive KG–LLM synergy is therefore backbone-dependent, and the deterministic KG should remain available as a safety-oriented fallback when model reasoning is unreliable.
4.2. Limitations and Future Research Directions
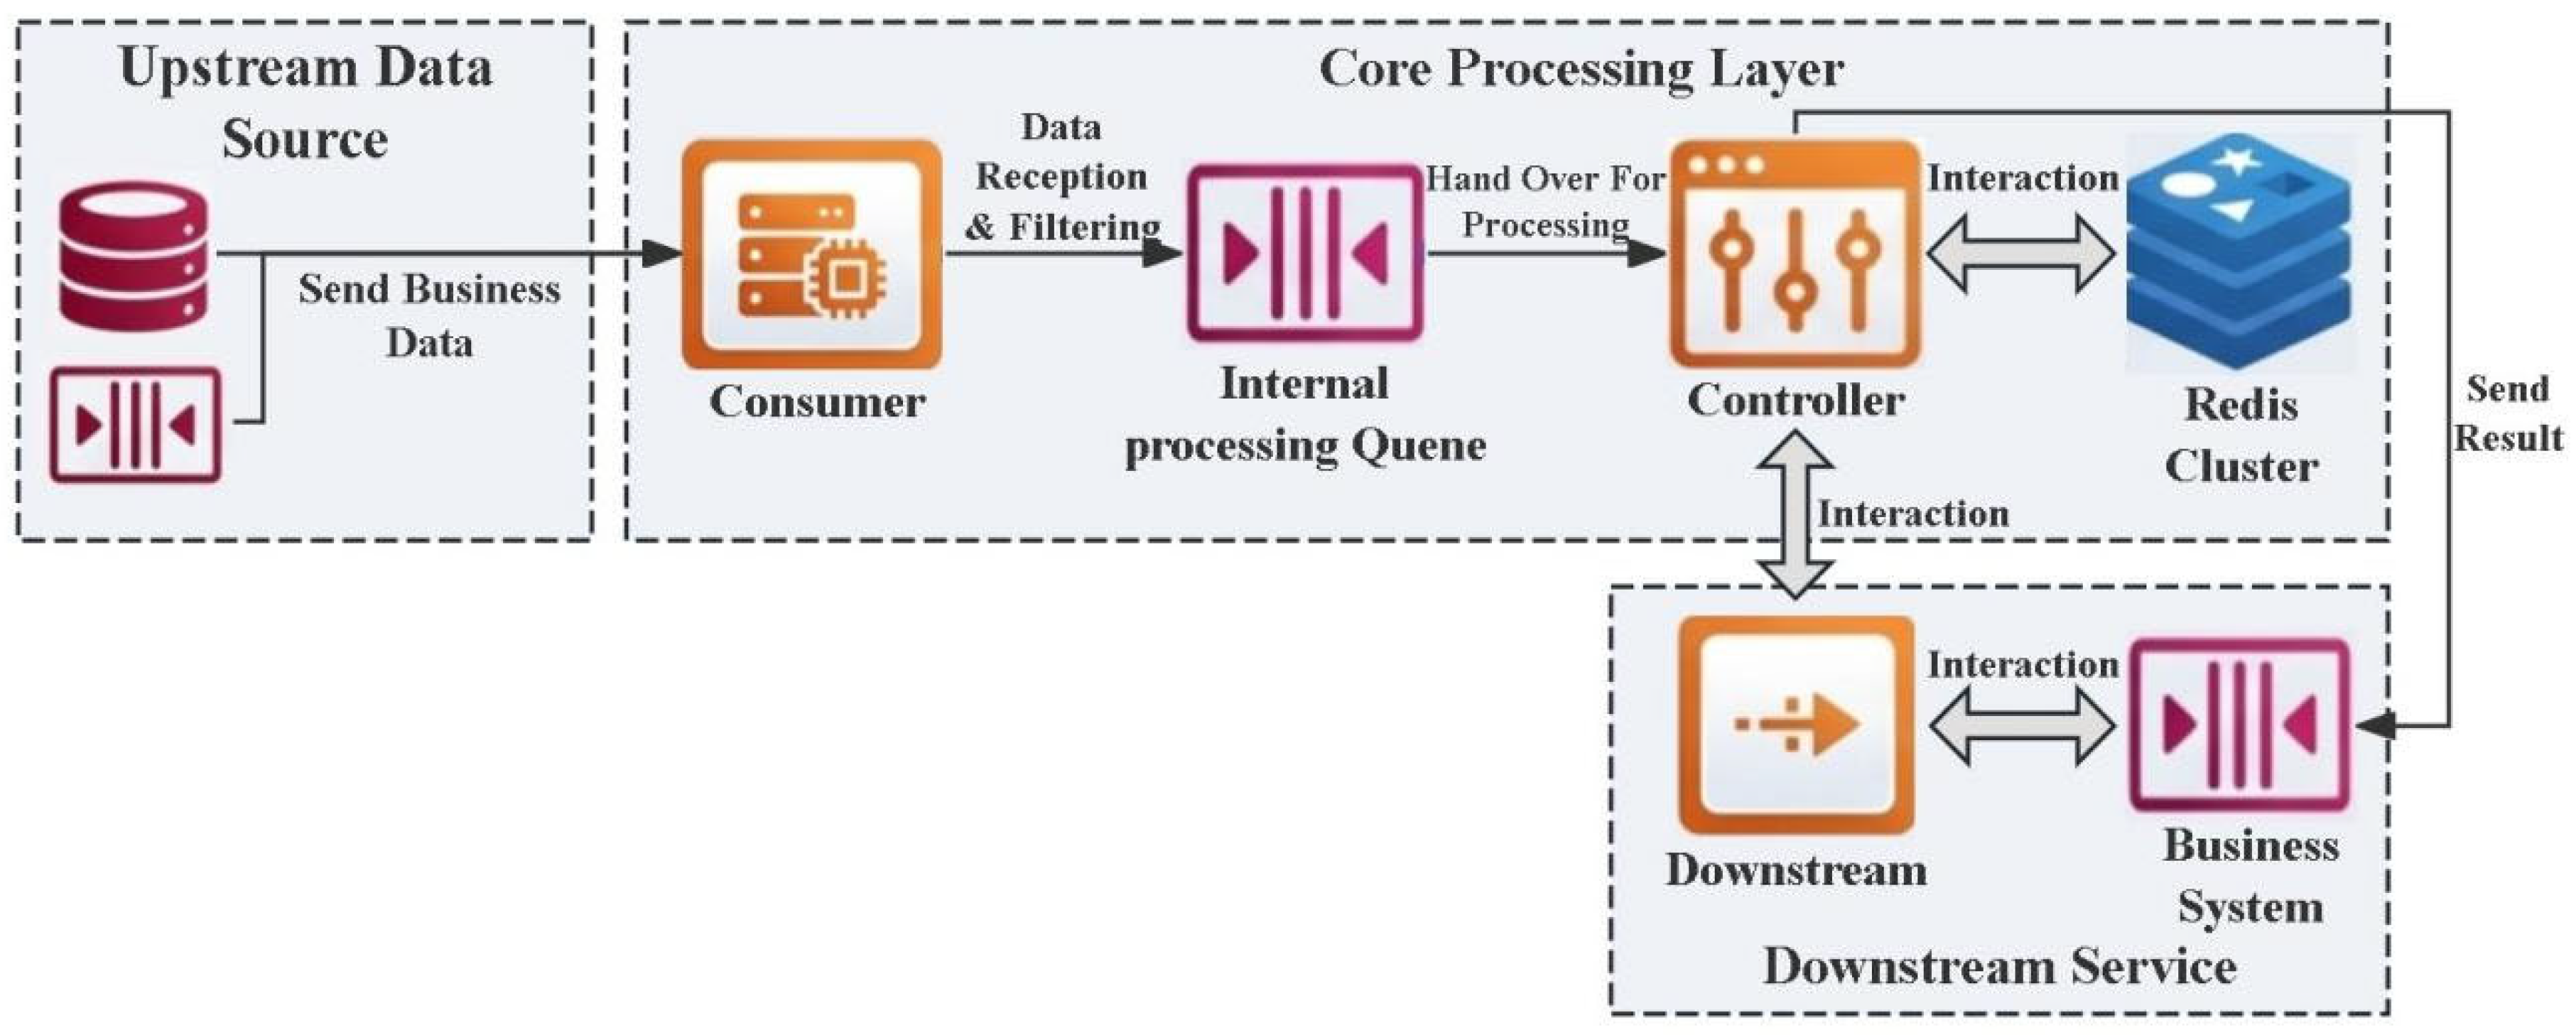
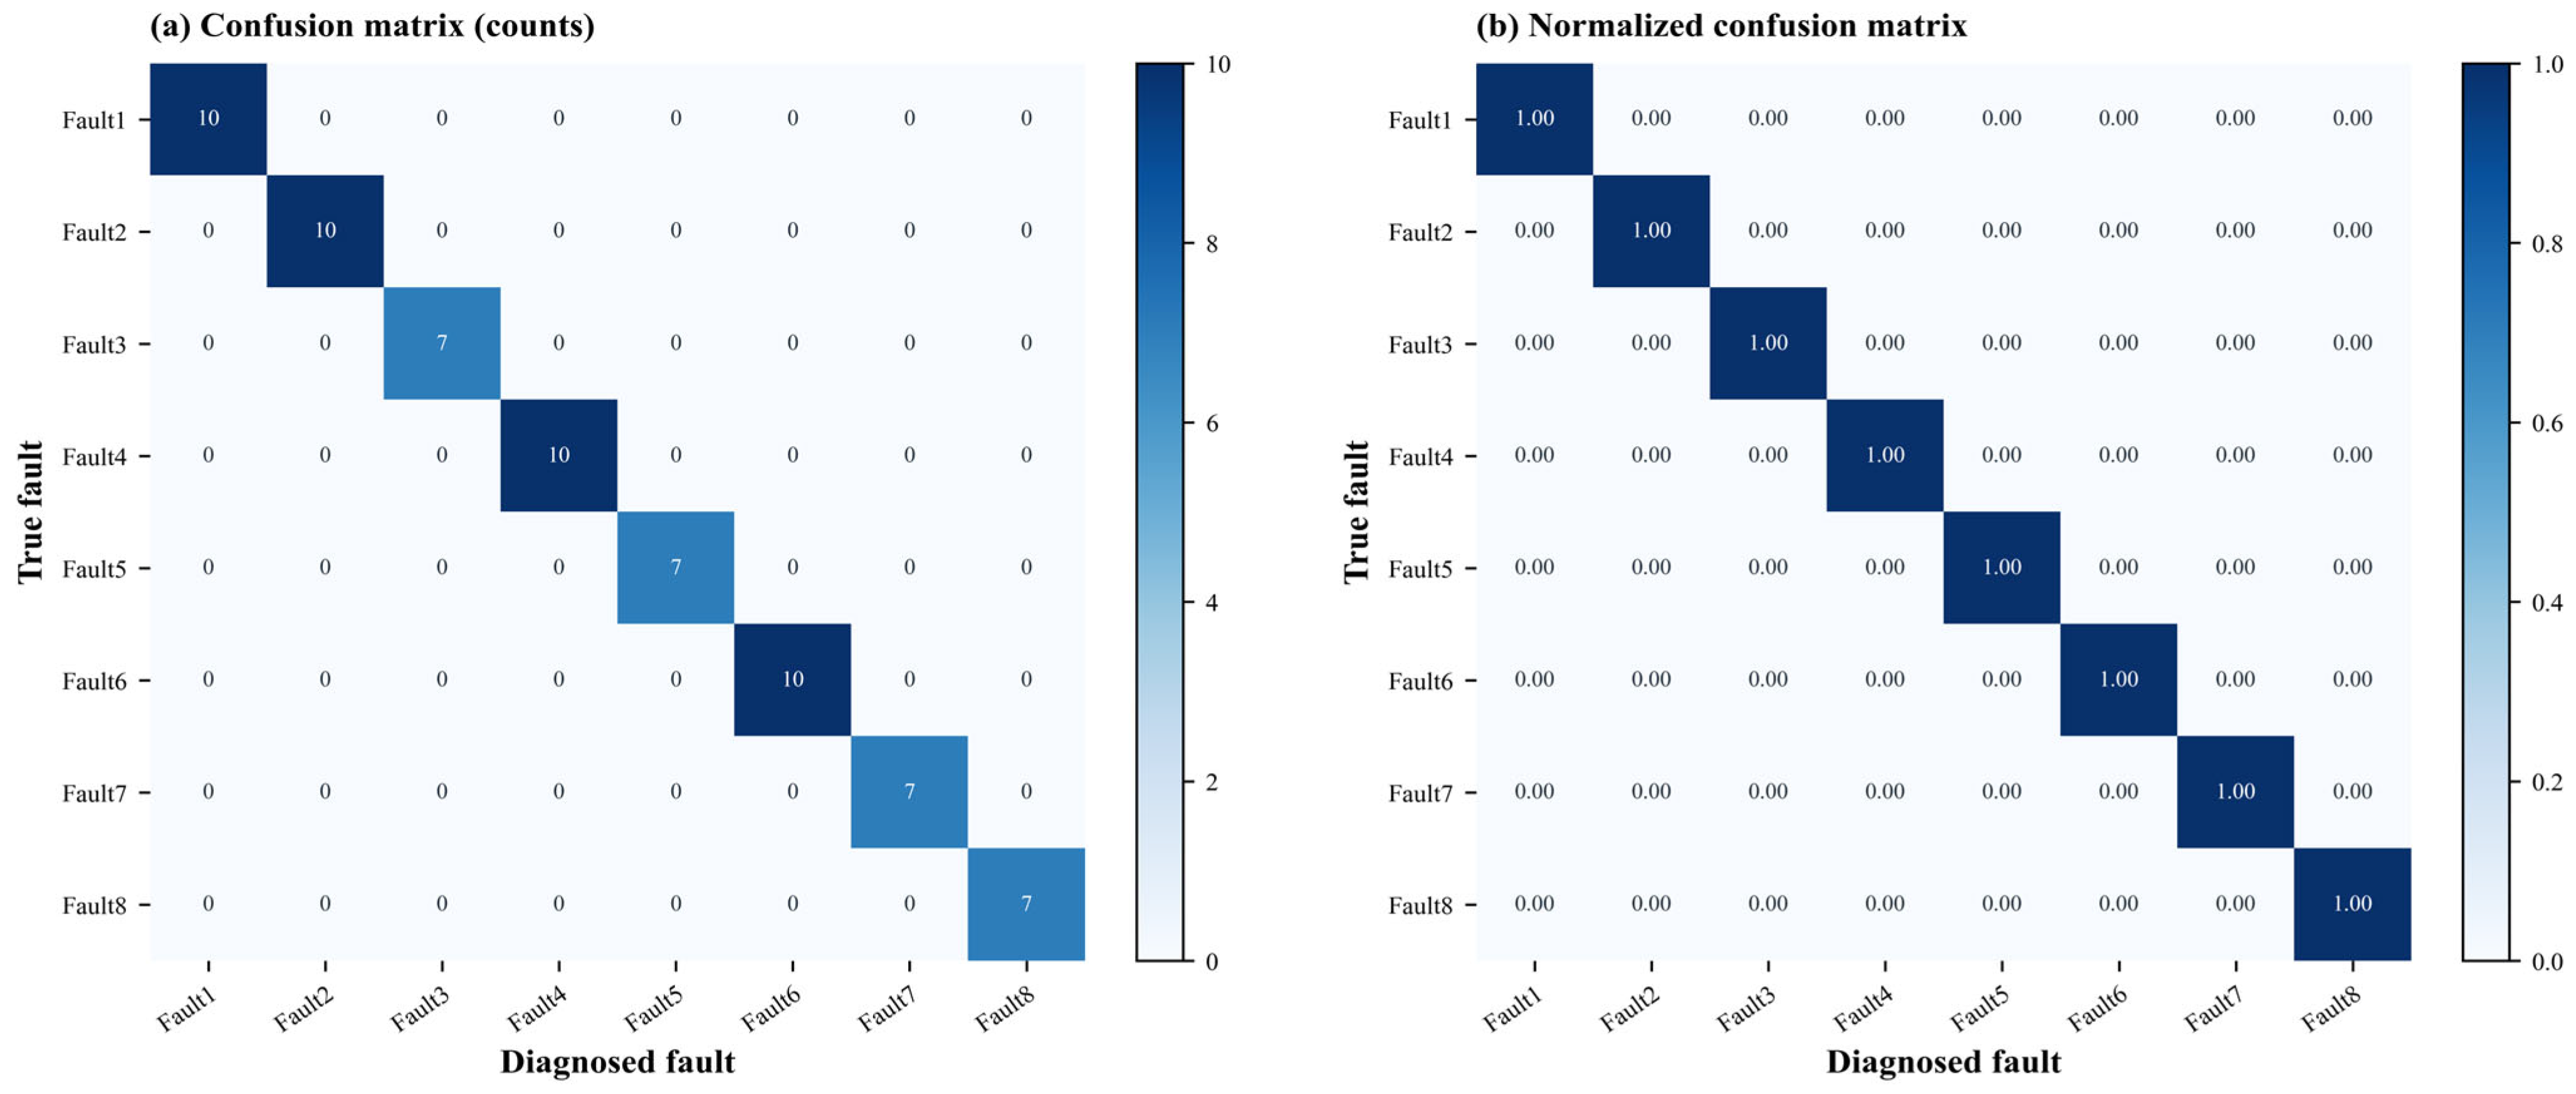
The current evaluation focuses on one Redis-based architecture and eight known single-root-cause fault classes under controlled injection. The 100% point estimates describe performance on these 68 complete test cases. Cross-system, cross-workload, unseen-fault, and concurrent multi-fault generalization remain to be evaluated. Future work will add a second distributed-service platform, grouped fault-event evaluation under workload shift, explicit unknown-fault rejection, and multi-hypothesis reasoning for overlapping propagation chains.
The numerical KG is currently built offline. As services, metrics, and operating regimes evolve, its intervals and relations may require revision. A deployment-oriented extension should combine drift detection, expert-verified incremental graph updates, and versioned provenance so that every numerical constraint remains auditable.
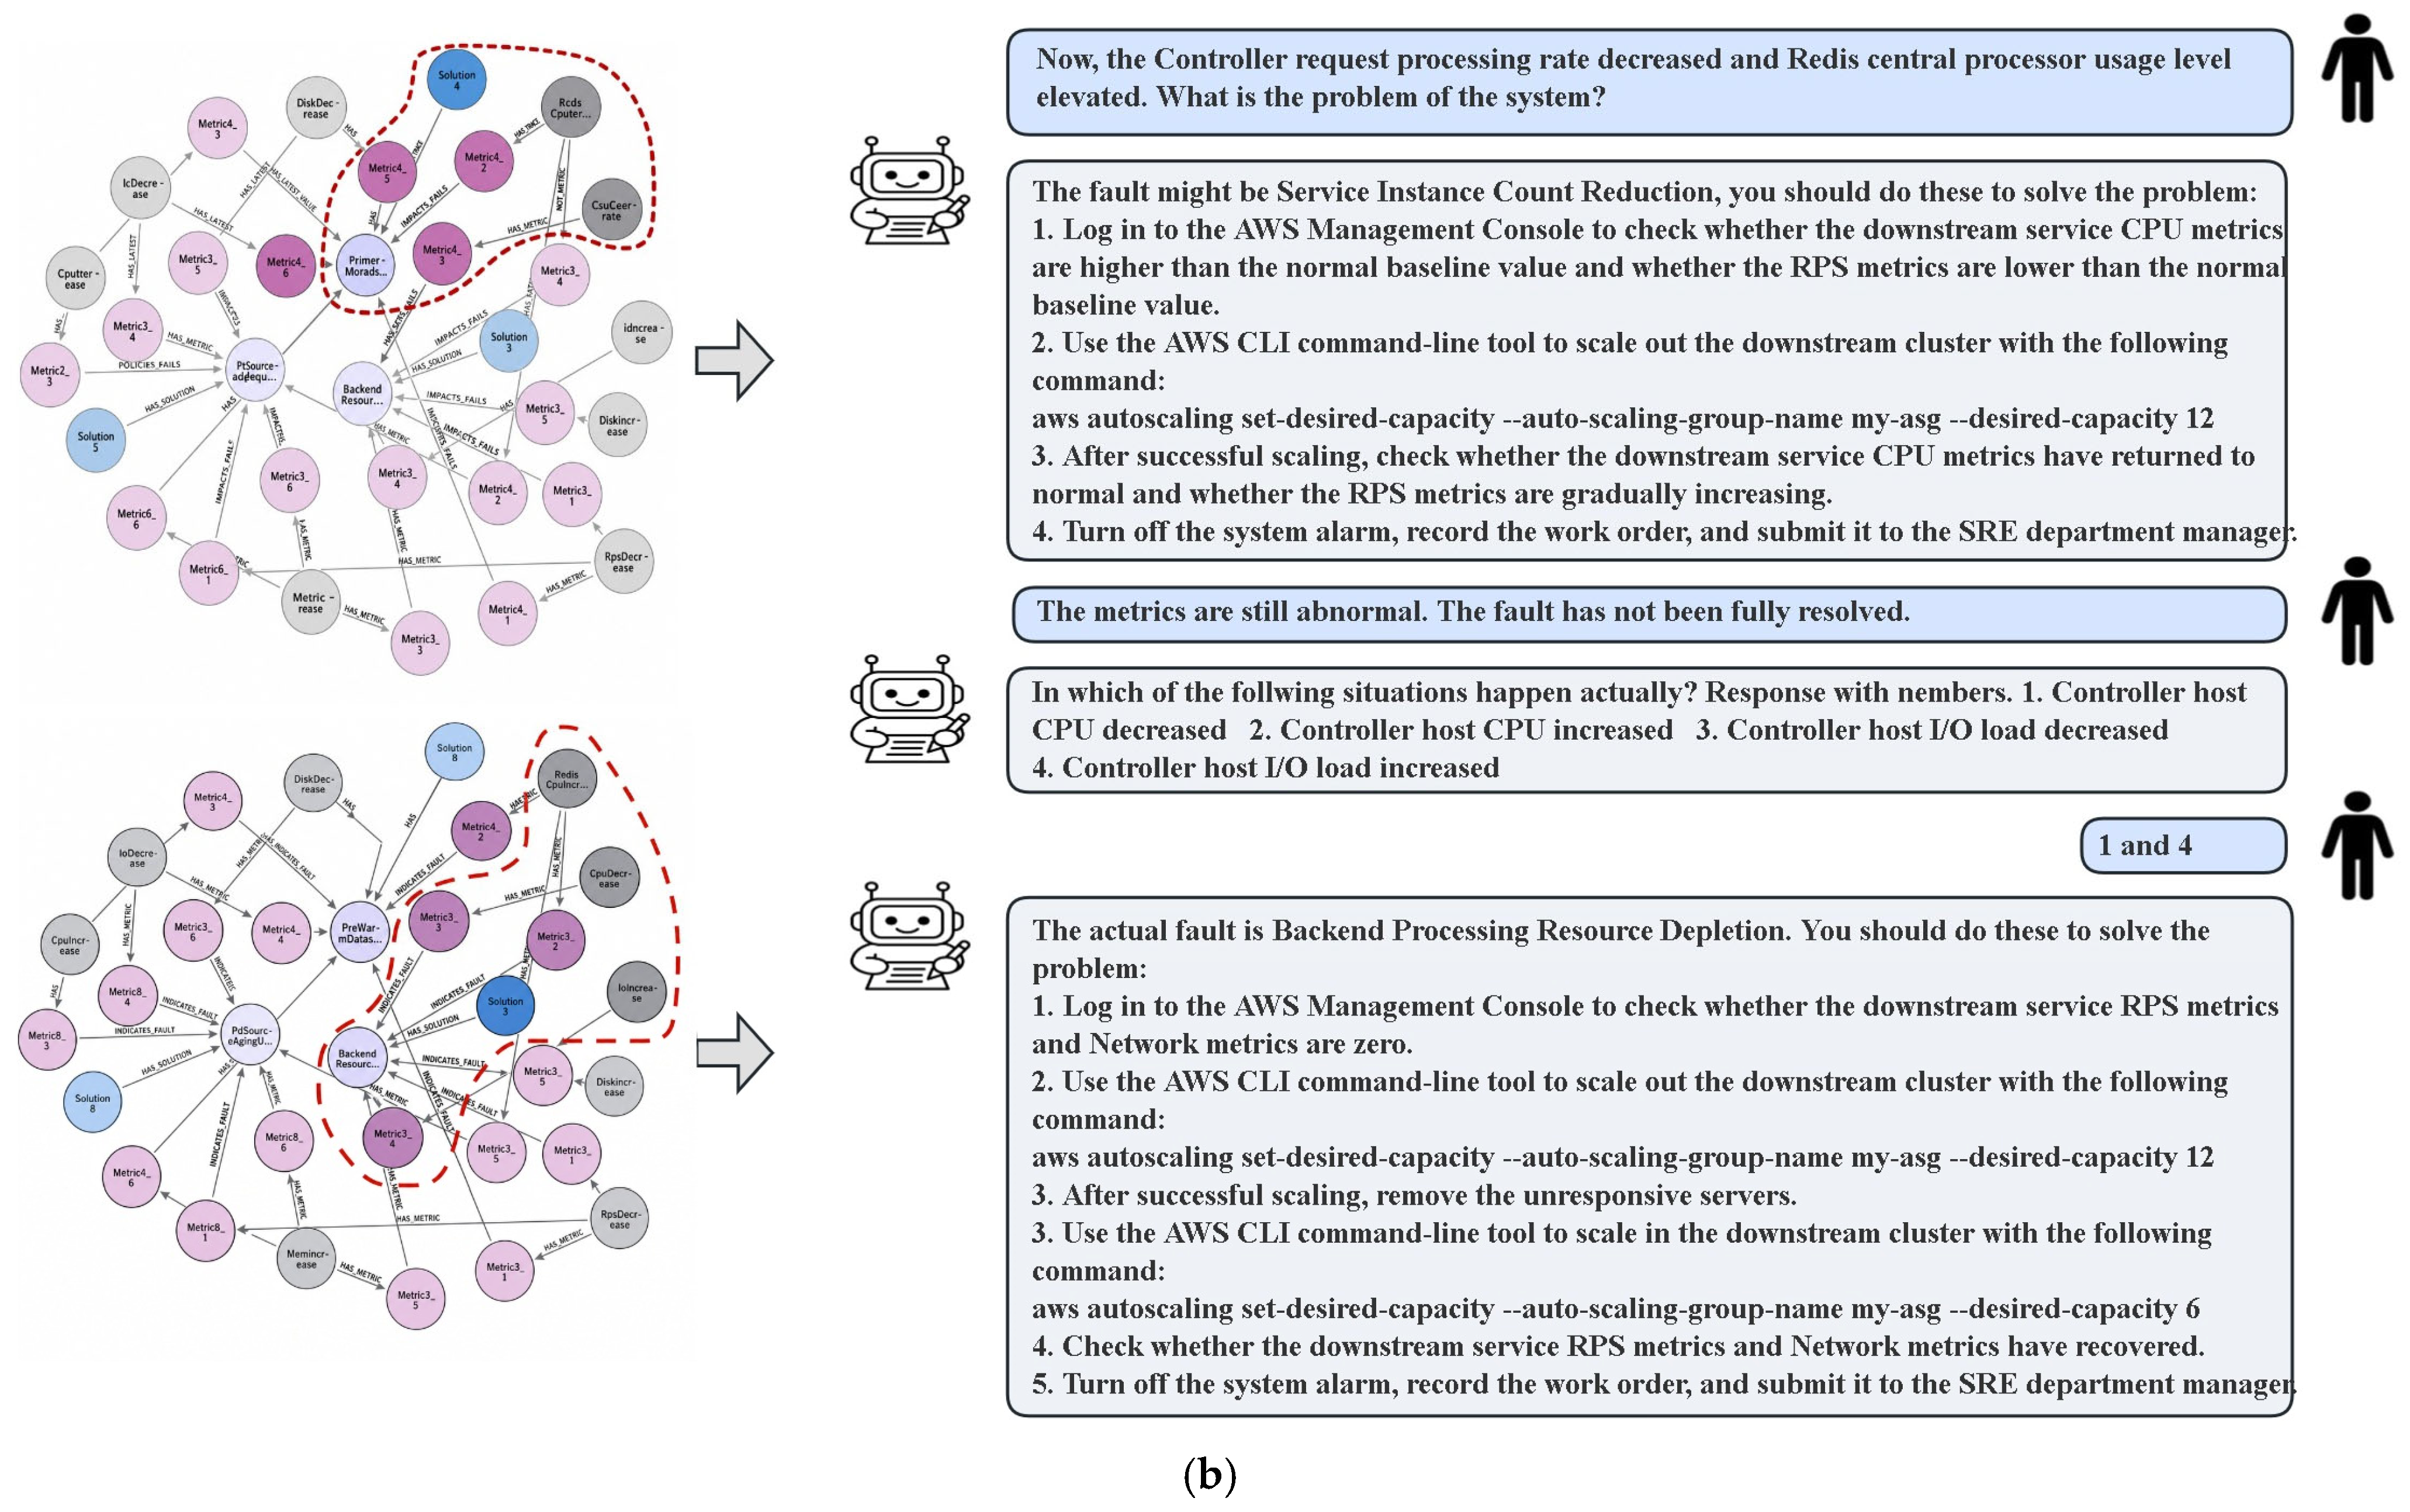
Finally, traceability is demonstrated through explicit intermediate reasoning artifacts, but operator benefit has not been quantified. The interaction prototype should be evaluated with diagnosis time, correction frequency, solution usefulness, and structured operator feedback before making claims about maintenance efficiency or usability.
Request-level latency, token usage, and API cost were not recorded for the final evaluation, so reliable numerical estimates for these engineering quantities cannot be reconstructed retrospectively. Future deployment benchmarking should record these measures under fixed model and API configurations.
5. Conclusions
This paper presents a knowledge-enhanced iterative reasoning framework for fault diagnosis in distributed service systems. A numerical KG encodes fault–symptom relations, anomaly directions, and training-derived mean and standard-deviation intervals. Four stages—candidate generation and interval verification, counterfactual causal-chain construction, KG refinement, and deterministic evidence scoring with iterative exclusion—form a traceable route from monitoring observations to root-cause decisions.
Under the common 68-case protocol for eight known single-root-cause faults in the controlled Redis-based testbed, KG + GPT-4o and KG + GPT-5.2 achieve 100.00% Accuracy, Macro-F1, and Balanced Accuracy, compared with 91.18% accuracy for KG-only and 85.29–89.71% for the conventional and Transformer baselines. GPT-3.5 reaches 98.53%. Repeated runs of the two best configurations yield 100.00% ± 0.00, and all tested sensitivity settings remain at 100.00%. These results support high accuracy and stability under the tested conditions.
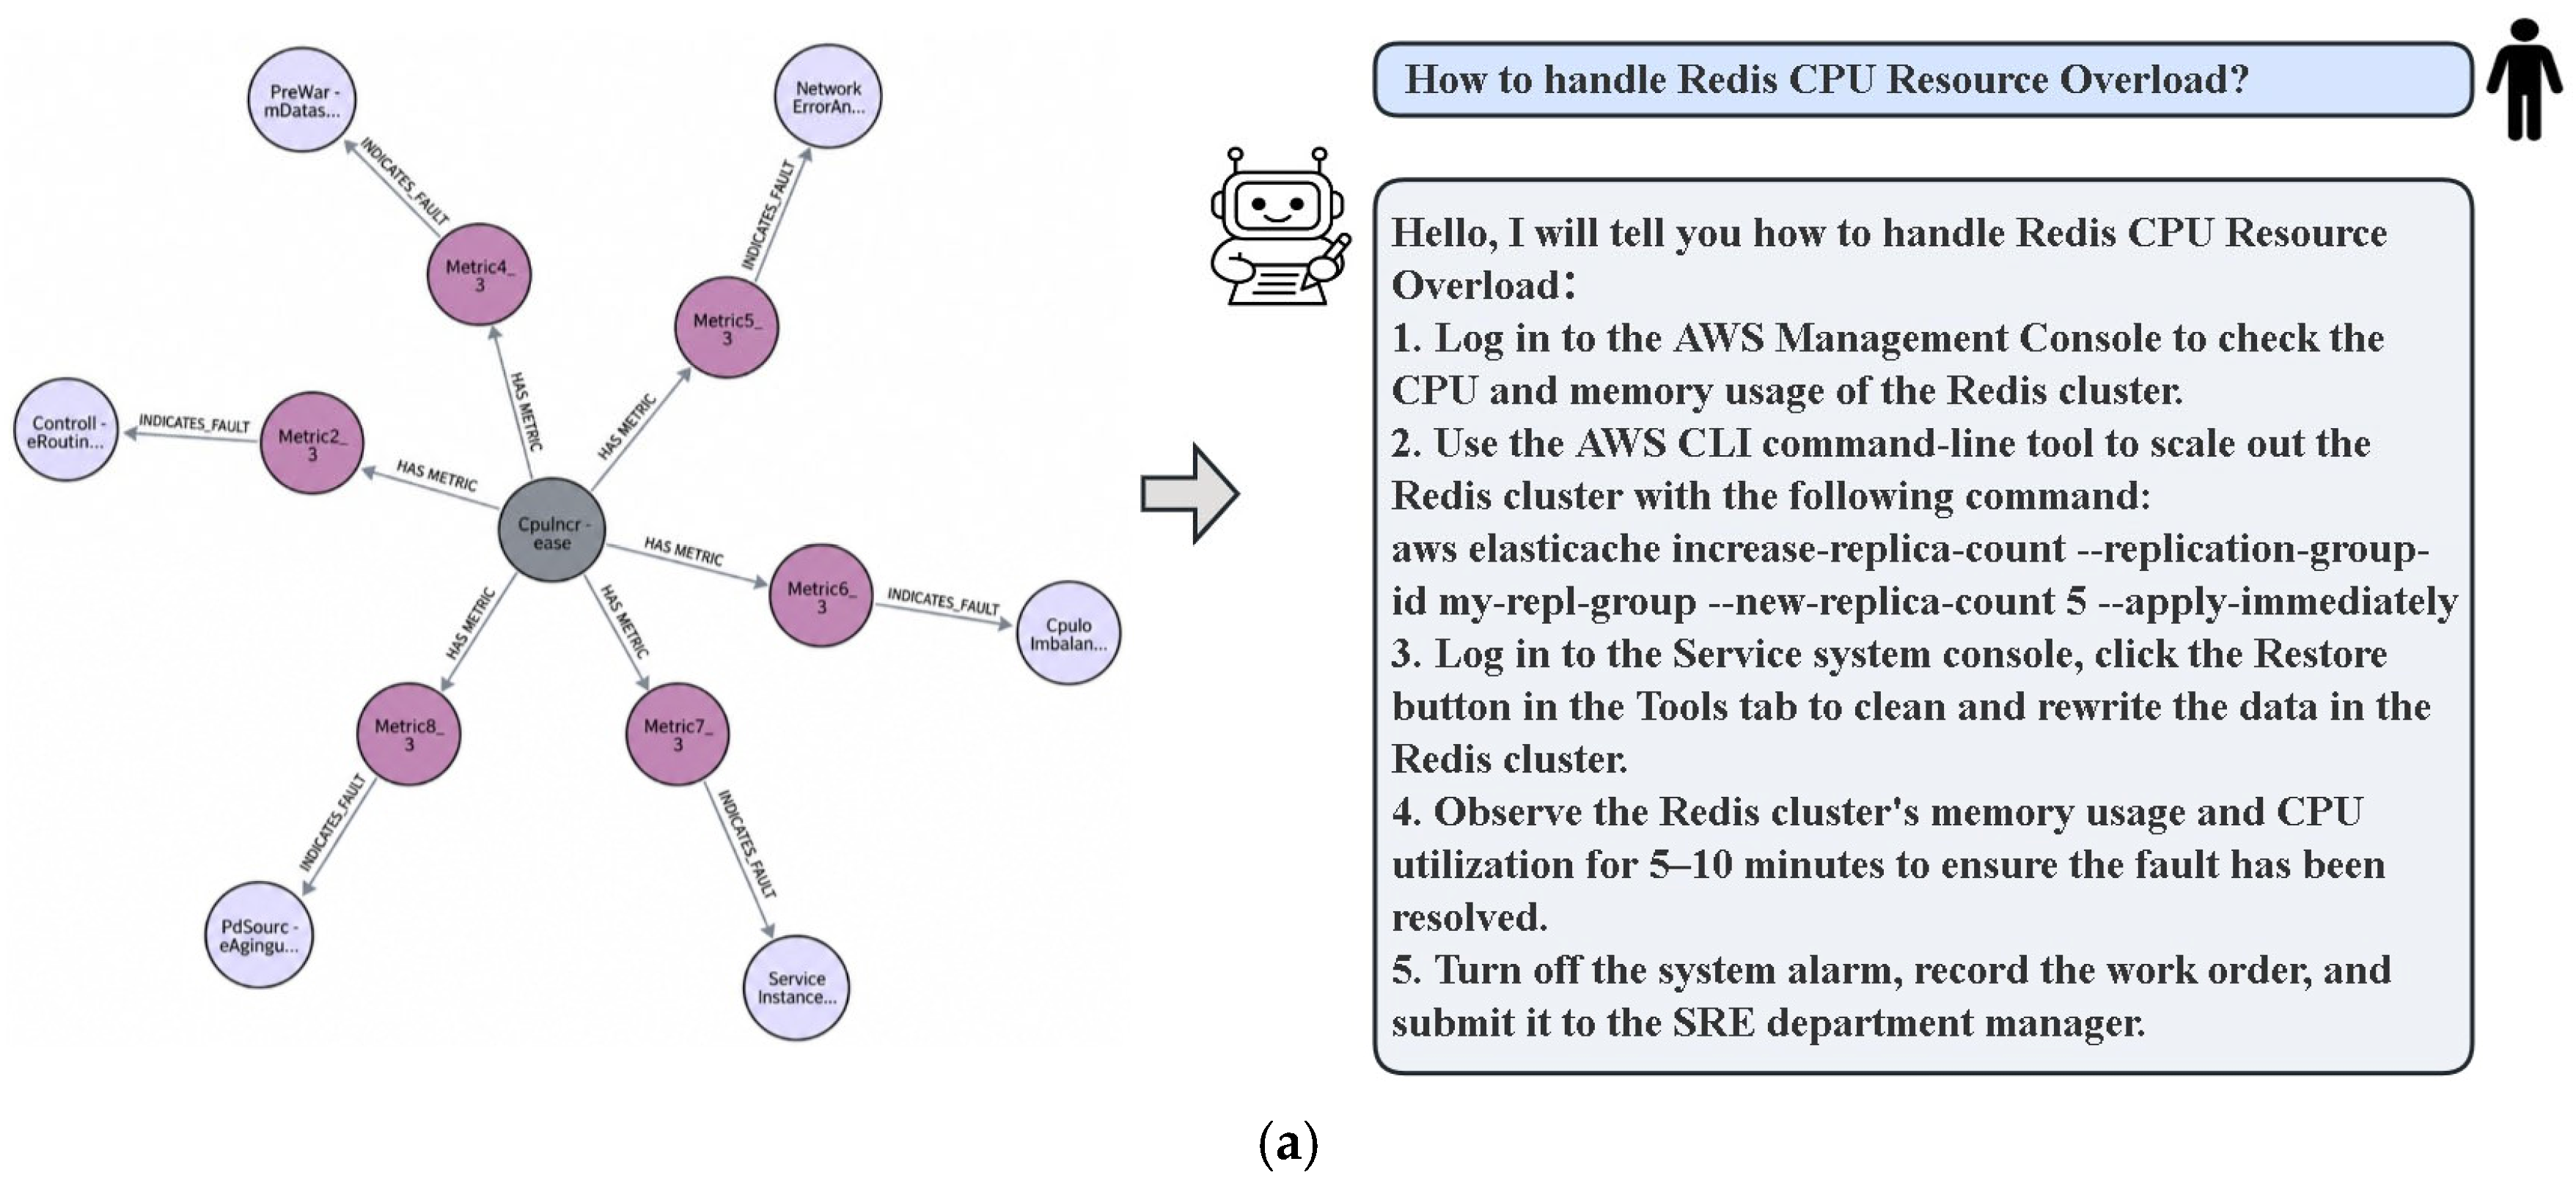
The ablation study further separates the contributions of numerical knowledge and LLM reasoning. Reliable GPT backbones improve on the strong KG-only baseline, while LLaMA-3.1-8B remains below KG-only, demonstrating that the incremental benefit is model-dependent. The framework retains a high standard of traceability because candidate, causal-chain, KG-correction, and score evidence can be inspected at every stage. The prototype interaction and solution-retrieval workflow show deployment-oriented potential; cross-system, unseen-fault, multi-fault, and human-in-the-loop evaluations remain the next steps toward broader operational validation.