Article

Cooperative Computation for Multiuser Task Offloading in Wireless-Powered MEC Systems

1
School of Integrated Circuits, Shenzhen Polytechnic University, Shenzhen 518055, China
2
School of Electronic and Communication Engineering, Shenzhen Polytechnic University, Shenzhen 518055, China
*
Authors to whom correspondence should be addressed.
Sensors 2026, 26(17), 5568; https://doi.org/10.3390/s26175568
Submission received: 29 July 2026 / Revised: 30 August 2026 / Accepted: 31 August 2026 / Published: 2 September 2026
(This article belongs to the Section Industrial Sensors)

Abstract

This paper investigates joint computing and relaying for multiuser task offloading in a wireless-powered mobile edge computing (MEC) system comprising an energy node (EN), an edge server (ES), and multiple energy-harvesting users. One user is selected as the helper for the remaining task users. Each task user partitions its workload among local computing, cooperative computing at the helper, and remote execution at the ES. During a parallel cooperation stage, the helper computes one portion of the uploaded tasks locally while forwarding the remaining portion to the ES and also processes its own task through local computing or edge offloading. The weighted sum computation rate (WSCR) is maximized by jointly optimizing helper selection, task partitioning, time allocation, transmission-energy allocation, and CPU-resource allocation under frame-duration, energy-neutrality, communication, and computation constraints. For each candidate helper, transmission-energy variables are introduced to decouple transmission time and power, and the perspective structure of the achievable-rate functions is exploited to reformulate the continuous resource-allocation problem as an equivalent convex problem. By solving the convex problem for all the candidate helpers, the globally optimal helper selection and resource allocation are obtained. The numerical results show that the proposed joint computing-and-relaying scheme consistently outperforms computing-only, relaying-only, and dedicated-helper cooperation. The performance gain stems from adaptively balancing helper computing and ES processing according to the prevailing communication, computation, and energy bottlenecks.

1. Introduction

The rapid growth of wireless sensor networks and Internet of Things (IoT) applications has imposed increasingly stringent requirements on real-time and computation-intensive data processing at energy-constrained wireless devices (WDs). However, many IoT devices, including sensors, wearable terminals, and embedded controllers, are constrained by limited battery capacity and modest on-device computing capability. Mobile edge computing (MEC) alleviates the computing limitation by deploying computing resources at the network edge, enabling WDs to offload intensive tasks to a nearby edge server (ES) for remote execution [1]. Compared with conventional cloud computing, MEC reduces backhaul latency and supports faster responses for delay-sensitive applications. Nevertheless, both local computation and wireless task offloading consume considerable device energy. The finite energy supply of WDs therefore remains a fundamental obstacle to sustainable MEC services in low-power IoT networks.
Wireless-powered MEC integrates radio frequency (RF) wireless power transfer (WPT) with MEC to jointly address the energy and computing limitations of WDs. In this paradigm, an energy transmitter delivers controllable RF energy to the WDs, which use the harvested energy for local task execution or computation offloading. Binary computation offloading was studied in [2], where each task is executed entirely either at the WD or the ES. Partial computation offloading was subsequently considered in [3], allowing each task to be partitioned between local and edge execution. These studies revealed that the computation performance of wireless-powered MEC depends on the coordinated allocation of energy, communication, and computing resources. In particular, extending the WPT duration increases the energy that is available for computation and transmission but leaves less time for task offloading. Meanwhile, the optimal task partition depends jointly on the harvested energy, offloading-channel quality, and local CPU capability. Such coupling makes WPT scheduling, task partitioning, and computation-resource allocation inseparable.
Recent studies have extended wireless-powered MEC toward dynamic resource management and more flexible offloading architectures. Online and learning-based approaches were developed in [4,5,6] to coordinate wireless charging, task execution, and resource allocation under stochastic system dynamics or incomplete future information. Reconfigurable intelligent surfaces were incorporated into wireless-powered MEC in [7] to enhance both energy transfer and task offloading. More flexible multiple-access designs were investigated through successive interference cancellation in [8] and non-orthogonal multiple access in [9]. In addition, data compression was jointly optimized with wireless charging and offloading in [10] to reduce the communication load of raw task data. These studies improve the adaptability and resource efficiency of wireless-powered MEC. However, most of them still rely on direct user-to-ES offloading. When the direct offloading link is weak, a task user may consume excessive transmission time and energy, thereby limiting the achievable computation gain from the harvested energy.
Cooperative-computation offloading provides an effective means of alleviating weak user-to-ES links and limited local computing capability. In [11], computation tasks are partitioned among local computing, helper computing, and ES execution in a multiuser cooperation-assisted wireless-powered MEC system. Opportunistic helper scheduling was investigated in [12], where a nearby user computes part of a task and forwards the remaining part to an MEC server. Helper selection was further coupled with user association, resource-block assignment, task allocation, and computing-resource allocation in [13]. User-centric cooperative offloading was considered in [14], allowing users to obtain communication and computing services from one or multiple MEC access points. Wireless-powered cooperative computing was also integrated with a beyond-diagonal reconfigurable intelligent surface in [15] to enhance energy transfer, task offloading, and cooperative task execution. These studies demonstrate that helper-assisted computing and cooperative offloading can expand the available task-processing resources and mitigate unfavorable direct offloading conditions in multiuser MEC systems.
These multiuser developments build on several foundational models of cooperative-computation offloading. Relay-assisted offloading was investigated in [16] for a two-user wireless-powered MEC system, where one user assists the other by forwarding its offloaded task to an edge cloud without performing cooperative task computation at the assisting user. Joint computation and communication cooperation was considered in [17], where a dedicated helper computes part of the workload of a single task user locally and relays the remaining part to an access point connected to an MEC server. In this dedicated-helper structure, the helper is not selected from the participating users, and multiuser sharing of the helper’s computation and communication resources does not arise. A more closely related wireless-powered model was studied in [18], where a predetermined helping user not only partitions the received workload between local computing and ES forwarding but also processes its own task. Nevertheless, the cooperation relationship is still limited to two users. These studies reveal the complementary roles of computing and relaying cooperation. Helper computing avoids additional helper-to-ES transmission but is constrained by the helper’s CPU capability, whereas relaying exploits the stronger computing capability of the ES at the cost of an additional communication hop and the associated time and energy consumption. Beyond computation offloading and resource allocation, secure and resilient coordination has also received increasing attention in networked intelligent systems. Digital-twin-based resilient consensus control was investigated for UAV systems under attacks in [19], while a data-driven twin-layer approach was developed in [20] for leader-following consensus of nonlinear multi-agent systems under composite attacks.
Despite this progress, joint computing and relaying in a multiuser wireless-powered MEC system has not been fully addressed. The existing wireless-powered cooperative offloading models mainly focus on two-user systems or predetermined cooperation relationships, while the recent helper-assisted MEC studies generally do not consider selecting one energy-harvesting user to simultaneously assist multiple task users and process its own task. In this setting, the helper’s harvested energy, CPU cycles, forwarding time, and transmission energy must be shared among multiple uploaded tasks and its own task. Moreover, helper selection simultaneously changes the EN-to-helper energy-transfer channel, the task-user-to-helper uploading links, the helper-to-ES forwarding link, and the user-specific computation parameters. The helper-computed and ES-forwarded task portions share the same harvested-energy budget, while their corresponding computing and forwarding operations proceed in parallel. Consequently, helper selection, task partitioning, and continuous resource allocation are tightly coupled and cannot be optimized independently.
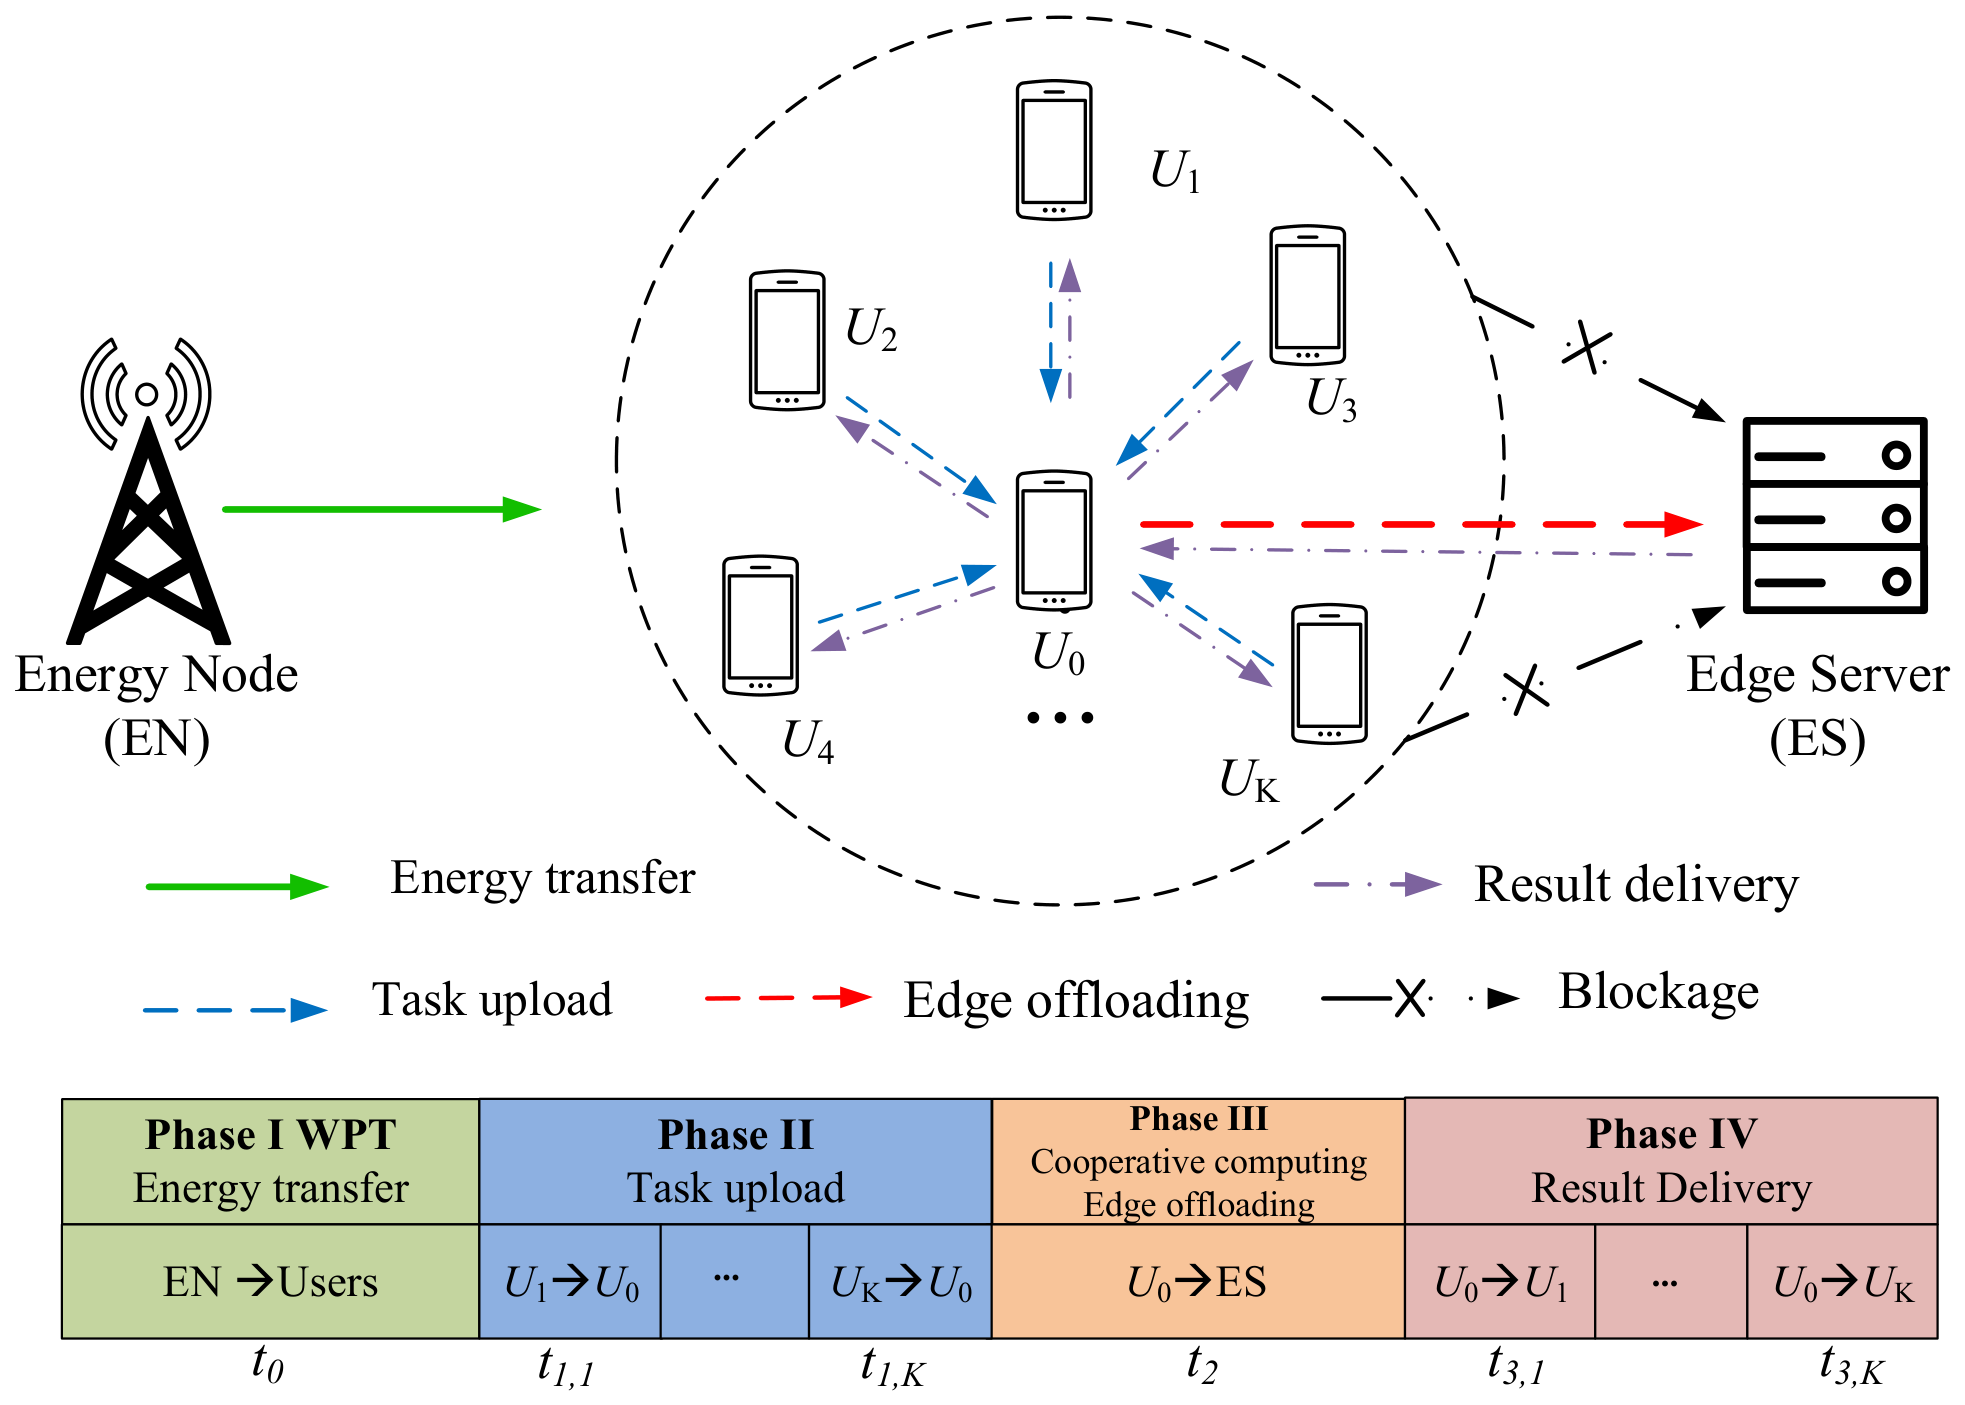
Motivated by these observations, this paper investigates a helper-assisted multiuser wireless-powered MEC system consisting of one EN, one ES, and multiple energy-harvesting users. As illustrated in Figure 1, one user is selected as the helper, while the remaining users act as task users. Each task user computes part of its task locally and uploads the remaining part to the helper. During a parallel cooperation stage, the helper computes one portion of the uploaded tasks locally and forwards the other portion to the ES for remote execution while also processing its own task through local computing or edge offloading. The helper subsequently delivers the corresponding computation results to the task users. Accordingly, each task user’s workload can be adaptively partitioned among local computing, cooperative computing at the helper, and remote processing at the ES according to the prevailing communication, computation, and energy conditions.
The main contributions of this paper are summarized as follows.
  • This paper develops a multiuser helper-selection architecture that jointly exploits computing and relaying cooperation in a wireless-powered MEC system. Unlike two-user or dedicated-helper cooperation models, one energy-harvesting user is dynamically selected as the helper for the remaining task users while also processing its own task. During a parallel cooperation stage, the selected helper computes part of the uploaded tasks locally and forwards the remaining part to the ES. Consequently, its harvested energy, CPU resources, forwarding time, and transmission energy are shared among multiple uploaded tasks and its own task. This architecture enables flexible task partitioning between helper computing and ES processing under coupled multiuser resource constraints.
  • A weighted sum computation rate (WSCR) maximization problem is formulated by jointly optimizing helper selection, task partitioning, time allocation, transmission-energy allocation, and CPU-resource allocation under frame-duration, energy-neutrality, communication, and computation constraints. For each candidate helper, transmission-energy variables are introduced to decouple transmission time and power, while the perspective structures of the communication-rate and computation-energy functions are exploited to transform the continuous resource-allocation problem into an equivalent convex problem. By solving this problem for all the candidate helpers, the globally optimal helper selection and resource allocation are obtained.
  • The numerical results reveal the complementary roles of computing and relaying cooperation under different energy, communication, and computation conditions. The proposed joint computing-and-relaying scheme consistently outperforms computing-only, relaying-only, and dedicated-helper cooperation, while the relative performance of the benchmark schemes varies with the prevailing system bottleneck. The performance gain results from adaptively allocating the uploaded tasks between helper computing and ES processing and selecting the helper according to the network conditions.
The remainder of this paper is organized as follows. Section 2 presents the system model and the proposed helper-assisted offloading protocol. Section 3 characterizes the computation performance and formulates the WSCR maximization problem. Section 4 develops the optimal helper-selection and resource-allocation method. Section 5 presents the simulation results, and Section 6 concludes the paper.

2. System Model

2.1. Network Model

As shown in Figure 1, this paper considers a multiuser wireless-powered MEC system consisting of one EN, one ES, and N energy-harvesting users indexed by N { 1 , , N } . One user U n , n N is selected as the helper to provide computing and relaying assistance for the remaining users. For each candidate helper, the system reindexes U n as U 0 and denotes the remaining K = N 1 task users by K { 1 , , K } . The paper further defines K 0 { 0 } K . All user-specific channel, energy-harvesting, computation, and priority parameters are relabeled accordingly. All nodes are equipped with a single antenna.
The EN continuously draws energy from a stable power supply and transfers radio frequency energy to the users. The users utilize the harvested energy for task computation and wireless transmission, whereas the ES has sufficient energy and computing resources to execute the offloaded tasks. Each user is equipped with a sufficiently large rechargeable energy buffer. The system is assumed to operate in a steady-state regime in which a certain amount of energy harvested in previous frames is available at the beginning of each frame. This stored energy supports transient energy expenditure before the current-frame WPT energy becomes fully available, thereby avoiding explicit intra-frame energy-causality constraints. Nevertheless, frame-level energy neutrality is strictly imposed such that the total energy consumed by each user in one frame cannot exceed the energy harvested during that frame. Therefore, the stored energy is not continuously depleted across frames. This model is appropriate for buffer-equipped wireless-powered devices operating over consecutive frames; an initially empty energy buffer would require additional cumulative intra-frame energy-causality constraints. This system considers helper-assisted computation offloading, where the task users do not directly offload tasks to the ES. Instead, U 0 receives the offloaded tasks, computes one portion of each uploaded task locally, and forwards the remaining portion to the ES. Accordingly, the task of each U k , k K can be executed locally at U k , cooperatively at U 0 , or remotely at the ES. Meanwhile, U 0 also processes its own task through local computation or edge offloading.
Let g ˜ i , i K 0 denote the complex channel coefficient from the EN to U i . Let h ˜ k denote the complex channel coefficient between U k and U 0 , and let h ˜ 0 denote that between U 0 and the ES. The corresponding channel power gains are given by
g i = g ˜ i 2 , i K 0 ,
h k = h ˜ k 2 , k K ,
and
h 0 = h ˜ 0 2 .
The user-to-user channels are assumed to be reciprocal. All wireless links follow a distance-dependent path-loss model and are quasi-static within each transmission frame, while the channel conditions may vary across frames. The instantaneous channel gains are assumed to be perfectly available at the system controller at the beginning of each frame such that helper selection and resource allocation can be updated on a frame-by-frame basis. Channel-estimation errors and the associated signaling overhead are not modeled in the present framework; accounting for these effects would require robust resource allocation and explicit modeling of channel-acquisition overhead. For high-mobility scenarios with significant channel variations within one frame, the quasi-static assumption may no longer be accurate, and mobility-aware prediction or robust helper selection would be required.
The ES is assumed to have sufficiently high computing capability and transmit power, together with a high-capacity downlink to U 0 . Therefore, the task-execution time at the ES and the result-return time from the ES to U 0 are neglected. In contrast, the result delivery from U 0 to the task users is explicitly modeled because U 0 is powered by harvested energy. A fixed circuit energy consumption E i cir is considered for each user U i to account for signal reception, control signaling, and circuit operation.

2.2. Transmission Protocol

The system considers a transmission frame of duration T, whose time allocation is illustrated in Figure 1. At the beginning of each frame, the EN transfers wireless energy to all users with a fixed transmit power P 0 for a duration of t 0 .
Following the WPT period, the task users sequentially upload their offloaded task portions to U 0 using time-division multiple access. During this phase, U 0 operates only as an information receiver, and energy harvesting from the task users’ uplink transmissions is not considered. Let t 1 , k denote the task-upload time allocated to U k , k K . The total task-upload duration is
t 1 = k K t 1 , k .
After receiving the uploaded tasks, U 0 enters a parallel cooperation stage during which it computes the task portions assigned to the helper while forwarding the remaining portions to the ES. Let t 2 , k c denote the time used by U 0 to compute the task portion of U k . Since the processor of U 0 can execute only one task at a time, the total cooperative-computation time is
t 2 c = k K t 2 , k c .
Let t 2 , k f denote the time used by U 0 to forward the task portion of U k to the ES, and let t 2 , 0 f denote the time used by U 0 to offload its own task. The total helper-to-ES transmission time is
t 2 f = t 2 , 0 f + k K t 2 , k f .
The processor and wireless transceiver of U 0 are modeled as separate functional units and are allowed to operate concurrently. Therefore, the single-processor constraint prevents U 0 from executing multiple computation tasks simultaneously but does not prevent CPU computation from proceeding in parallel with wireless transmission. Hence, cooperative computing and edge offloading can overlap in time, and the duration of this stage is determined by the longer of the two operations:
t 2 = max t 2 c , t 2 f .
After helper computing and ES processing are completed, the ES returns its computation results to U 0 . The helper aggregates the locally generated results and those returned by the ES and then sequentially delivers the corresponding results to the task users. Let t 3 , k denote the result-delivery time from U 0 to U k . The total result-delivery duration is
t 3 = k K t 3 , k .
Accordingly, the overall time allocation satisfies
t 0 + t 1 + t 2 + t 3 T ,
where all time-allocation variables are nonnegative.

3. Computation Model and Problem Formulation

During the WPT period, the EN broadcasts wireless energy with a fixed transmit power P 0 for a duration of t 0 . Let η i ( 0 , 1 ] denote the energy-conversion efficiency of U i . The energy harvested by U i is
Q i = η i P 0 g i t 0 , i K 0 .
The task users use their harvested energy for local computation and task uploading, whereas the helper U 0 uses its harvested energy for local computation, cooperative computing, edge offloading, and result delivery. It is assumed that each user has a sufficiently large task-input buffer such that the number of processed task bits is determined by the available communication, computation, and energy resources.
Under partial computation offloading, the task of each U k , k K is partitioned into three portions. Let b k , k , b k , 0 , and b k , E denote the numbers of task bits computed locally at U k , cooperatively at U 0 , and remotely at the ES, respectively. The total number of processed task bits of U k is
b k = b k , k + b k , 0 + b k , E , k K .
The task of U 0 is partitioned into a locally computed portion and an edge-computed portion. Let b 0 , 0 and b 0 , E denote the corresponding numbers of task bits. The total number of processed task bits of U 0 is
b 0 = b 0 , 0 + b 0 , E .

3.1. Local Computation

Let ϕ i denote the number of CPU cycles required to process one input bit of the task generated by U i , and let κ i denote the effective switched-capacitance coefficient of the processor at U i .
The processor and wireless transceiver of each task user are assumed to operate simultaneously. Therefore, each U k can perform local computation throughout the entire frame while participating in wireless transmission. Let f k [ 0 , f k max ] denote the CPU frequency of U k . The number of task bits locally computed by U k is
b k , k = f k T ϕ k , k K ,
and the corresponding energy consumption is
E k , k loc = κ k f k 3 T , k K .
The helper U 0 allocates part of its computing time to processing its own task. Let t 0 loc and f 0 loc denote the corresponding computation time and CPU frequency, respectively, where
0 f 0 loc f 0 max .
The number of task bits locally computed by U 0 is
b 0 , 0 = f 0 loc t 0 loc ϕ 0 ,
and the corresponding energy consumption is
E 0 , 0 loc = κ 0 f 0 loc 3 t 0 loc .

3.2. Cooperative Computing and Relaying

During t 1 , k , task user U k uploads the task portions assigned to U 0 and the ES to the helper. Let p 1 , k denote the corresponding transmit power. Since both portions must first be received by U 0 , the task-upload constraint is
b k , 0 + b k , E t 1 , k B log 2 1 + h k p 1 , k Γ N 0 , k K ,
where B denotes the system bandwidth, N 0 denotes the receiver noise power, and Γ 1 denotes the SNR gap from the Shannon capacity caused by practical modulation and coding.
The corresponding transmission-energy consumption of U k is
E k off = t 1 , k p 1 , k , k K .
After receiving the uploaded task data, U 0 forwards the b k , E bits assigned to the ES. Let p 2 , k f denote the forwarding power during t 2 , k f . The corresponding helper-to-ES transmission constraint is
b k , E t 2 , k f B log 2 1 + h 0 p 2 , k f Γ N 0 , k K .
In addition, U 0 offloads b 0 , E bits of its own task to the ES during t 2 , 0 f . Let p 2 , 0 f denote the corresponding transmit power. Thus,
b 0 , E t 2 , 0 f B log 2 1 + h 0 p 2 , 0 f Γ N 0 .
Accordingly, the total energy consumed by U 0 for forwarding the task users’ data and offloading its own task is
E 0 off = t 2 , 0 f p 2 , 0 f + k K t 2 , k f p 2 , k f .
Besides forwarding the ES-assigned task portions, U 0 computes b k , 0 bits for each task user U k . Let f k , 0 denote the CPU frequency used by U 0 to process the task of U k during t 2 , k c , where
0 f k , 0 f 0 max .
The number of task bits cooperatively computed at U 0 satisfies
b k , 0 = f k , 0 t 2 , k c ϕ k , k K .
The corresponding computation-energy consumption is
E k , 0 c = κ 0 f k , 0 3 t 2 , k c , k K .
Since the processor of U 0 can execute only one computation task at a time, the cooperative-computation tasks are processed sequentially. The local computation of U 0 ’s own task is not restricted to the cooperation stage and can be scheduled during CPU-idle intervals over the frame. Therefore, t 0 loc denotes the aggregate CPU time used for U 0 ’s own task, and the nonoverlap of its own local computation and the cooperative-computation tasks is enforced by
t 0 loc + k K t 2 , k c T .
After helper computing and ES processing are completed, U 0 delivers the corresponding computation results to the task users. Let ν k ( 0 , 1 ] denote the output-to-input data ratio of the nonlocally processed task of U k . The same ratio is assumed for the task portions processed at the helper and the ES. Let p 3 , k denote the transmit power used by U 0 during t 3 , k . The result-delivery constraint is
ν k b k , 0 + b k , E t 3 , k B log 2 1 + h k p 3 , k Γ N 0 , k K .
The total energy consumed by U 0 for result delivery is
E 0 d = k K t 3 , k p 3 , k .
Here, E i cir denotes the fixed circuit energy consumption of U i in each transmission frame. Accordingly, the energy-neutrality constraint of each task user is
E k , k loc + E k off + E k cir Q k , k K .
whereas the energy-neutrality constraint of U 0 is
E 0 , 0 loc + k K E k , 0 c + E 0 off + E 0 d + E 0 cir Q 0 .

3.3. Problem Formulation

The computation rates of task user U k and helper user U 0 are respectively defined as
R k = b k , k + b k , 0 + b k , E T , k K ,
and
R 0 = b 0 , 0 + b 0 , E T .
For a given helper candidate U n , which is reindexed as U 0 , task partitioning, time allocation, transmission powers, and CPU frequencies are jointly optimized to maximize the weighted sum computation rate. Define
b { b 0 , 0 , b 0 , E } { b k , k , b k , 0 , b k , E } k K ,
t { t 0 , t 2 , t 0 loc , t 2 , 0 f } { t 1 , k , t 2 , k c , t 2 , k f , t 3 , k } k K ,
p { p 2 , 0 f } { p 1 , k , p 2 , k f , p 3 , k } k K ,
and
f { f 0 loc } { f k , f k , 0 } k K .
The resource-allocation problem for candidate helper U n is formulated as
( P 1 ) : maximize b , t , p , f i K 0 w i R i subject to t 0 + k K t 1 , k + t 2 + k K t 3 , k T , k K t 2 , k c t 2 , t 2 , 0 f + k K t 2 , k f t 2 , ( 13 ) , ( 15 ) , ( 17 ) , ( 19 ) , ( 20 ) , ( 22 ) , ( 24 ) , ( 25 ) , ( 27 ) and ( 28 ) , b k , k , b k , 0 , b k , E 0 , k K , b 0 , 0 , b 0 , E 0 , t 0 , p 0 , 0 f k f k max , k K , 0 f 0 loc f 0 max , 0 f k , 0 f 0 max , k K .
The two constraints involving t 2 constitute the epigraph representation of the parallel cooperation duration defined in (7). Specifically, they ensure that t 2 is no smaller than either the total cooperative-computation time or the total helper-to-ES transmission time.
Here, w i > 0 denotes the computation-priority weight associated with the original identity of user U i . When U n is selected as the candidate helper, the weights are relabeled consistently with the corresponding users and normalized such that
i K 0 w i = 1 .
Although (P1) maximizes the WSCR rather than an energy-efficiency metric, the energy expenditure of each user is strictly constrained by the harvested-energy budgets in (27) and (28). Hence, the computation-rate improvement is achieved through efficient allocation of the available harvested energy rather than unrestricted energy consumption. For IoT applications where energy efficiency is the primary concern, the framework can be extended by adopting an energy-efficiency objective or an objective that jointly accounts for computation performance and energy consumption.
Let V n denote the optimal objective value of problem (P1). Problem (P1) is nonconvex because of the coupled time–power terms in the communication-rate constraints and the coupled computation-time–CPU-frequency terms in the computation model. An equivalent convex reformulation is developed in the next section.

4. Optimal Solution

4.1. Resource Allocation for a Given Helper

For a given helper candidate U n , problem (P1) is first transformed into an equivalent convex optimization problem. To eliminate the coupling between transmission time and power, define the transmission-energy variables
e 1 , k = t 1 , k p 1 , k , k K ,
e 2 , k f = t 2 , k f p 2 , k f , k K ,
e 2 , 0 f = t 2 , 0 f p 2 , 0 f ,
e 3 , k = t 3 , k p 3 , k , k K .
For notational convenience, define
e e 2 , 0 f e 1 , k , e 2 , k f , e 3 , k k K .
The transmission-rate function is further defined as
R ( t , e ; h ) t B log 2 1 + h e Γ N 0 t .
Its closed extension at t = 0 is defined as
R ( 0 , e ; h ) = 0 , e 0 .
When the transmission time is zero, any positive energy allocation produces no task transmission. Hence, an optimal solution can always be chosen with e = 0 whenever the corresponding transmission time is zero.
Using the transmission-energy variables, the task-upload, forwarding, edge-offloading, and result-delivery constraints can be respectively rewritten as
b k , 0 + b k , E R ( t 1 , k , e 1 , k ; h k ) , k K ,
b k , E R ( t 2 , k f , e 2 , k f ; h 0 ) , k K ,
b 0 , E R ( t 2 , 0 f , e 2 , 0 f ; h 0 ) ,
and
ν k ( b k , 0 + b k , E ) R ( t 3 , k , e 3 , k ; h k ) , k K .
Next, the CPU-frequency variables are eliminated using (13), (15) and (22). The local-computation energy consumption of task user U k can be expressed as
E k , k loc = κ k ϕ k 3 b k , k 3 T 2 , k K .
The energy consumed by U 0 for computing its own task becomes
E 0 , 0 loc = κ 0 ϕ 0 3 b 0 , 0 3 t 0 loc 2 ,
whereas the energy consumed by U 0 for cooperatively computing the task of U k becomes
E k , 0 c = κ 0 ϕ k 3 b k , 0 3 t 2 , k c 2 , k K .
The above computation-energy functions are interpreted in the extended-value sense. Each function equals zero when both the task size and the corresponding computation time are zero and equals positive infinity when the computation time is zero while the task size is positive.
The CPU-frequency constraints are equivalently rewritten as
ϕ k b k , k f k max T , k K ,
ϕ 0 b 0 , 0 f 0 max t 0 loc ,
and
ϕ k b k , 0 f 0 max t 2 , k c , k K .
Accordingly, the energy-neutrality constraint of each task user becomes
κ k ϕ k 3 b k , k 3 T 2 + e 1 , k + E k cir η k P 0 g k t 0 , k K ,
whereas the energy-neutrality constraint of the helper becomes
κ 0 ϕ 0 3 b 0 , 0 3 t 0 loc 2 + k K κ 0 ϕ k 3 b k , 0 3 t 2 , k c 2 + e 2 , 0 f + k K e 2 , k f + k K e 3 , k + E 0 cir η 0 P 0 g 0 t 0 .
Using the above transformations, problem (P1) is equivalently reformulated as
( P 2 ) : maximize b , t , e 1 T w 0 ( b 0 , 0 + b 0 , E ) + k K w k ( b k , k + b k , 0 + b k , E ) subject to b k , 0 + b k , E R ( t 1 , k , e 1 , k ; h k ) , k K , b k , E R ( t 2 , k f , e 2 , k f ; h 0 ) , k K , b 0 , E R ( t 2 , 0 f , e 2 , 0 f ; h 0 ) , ν k ( b k , 0 + b k , E ) R ( t 3 , k , e 3 , k ; h k ) , k K , κ k ϕ k 3 b k , k 3 T 2 + e 1 , k + E k cir η k P 0 g k t 0 , k K , κ 0 ϕ 0 3 b 0 , 0 3 t 0 loc 2 + k K κ 0 ϕ k 3 b k , 0 3 t 2 , k c 2 + e 2 , 0 f + k K e 2 , k f + k K e 3 , k + E 0 cir η 0 P 0 g 0 t 0 , t 0 + k K t 1 , k + t 2 + k K t 3 , k T , k K t 2 , k c t 2 , t 2 , 0 f + k K t 2 , k f t 2 , t 0 loc + k K t 2 , k c T , ϕ k b k , k f k max T , ϕ 0 b 0 , 0 f 0 max t 0 loc , ϕ k b k , 0 f 0 max t 2 , k c , k K , b k , k , b k , 0 , b k , E 0 , k K , b 0 , 0 , b 0 , E 0 , t 0 , e 0 .
Proposition 1.
For any given helper candidate U n , problem (P2) is a convex optimization problem.
Proof. 
The objective function of (P2) is affine. The function R ( t , e ; h ) is the perspective of the concave function
B log 2 1 + h x Γ N 0
and is therefore jointly concave in ( t , e ) . Consequently, the feasible sets defined by the communication constraints in (56) are convex.
Moreover, let f ( x ) = x 3 for x 0 . Since f ( x ) = 6 x 0 , f ( x ) is convex on its domain. For b 0 and t > 0 ,
b 3 t 2 = t b t 3 = t f b t ,
which is the perspective of the convex function f ( x ) = x 3 and is therefore jointly convex in ( b , t ) . Together with the extended-value definition given above, i.e., zero at ( b , t ) = ( 0 , 0 ) and positive infinity for b > 0 and t = 0 , this function forms a closed convex perspective over its entire domain. Hence, the computation-energy terms in the energy-neutrality constraints of (P2) are convex. All the remaining constraints are affine. Therefore, problem (P2) is convex, which completes the proof.    □
For a given helper candidate U n , problem (P2) can be solved globally using an interior-point method. Let
( b n , t n , e n )
denote its optimal solution. For notational simplicity, the candidate index n is omitted from the following recovery expressions.
The optimal transmission powers are recovered as
p 1 , k = e 1 , k t 1 , k , k K ,
p 2 , k f = e 2 , k f t 2 , k f , k K ,
p 2 , 0 f = e 2 , 0 f t 2 , 0 f ,
and
p 3 , k = e 3 , k t 3 , k , k K .
Similarly, the optimal CPU frequencies are recovered as
f k = ϕ k b k , k T , k K ,
f 0 loc = ϕ 0 b 0 , 0 t 0 loc ,
and
f k , 0 = ϕ k b k , 0 t 2 , k c , k K .
If a transmission-time variable equals zero, the corresponding transmitted task size is zero, and the associated transmission energy and transmit power are set to zero without loss of optimality. Similarly, if a computation-time variable equals zero, the corresponding computed task size and CPU frequency are defined as zero.

4.2. Helper Selection

Let V n denote the optimal WSCR obtained by solving problem (P2) when U n is selected as the helper. The optimal helper is determined by
n = arg max n N V n .
Accordingly, the globally optimal resource allocation is given by
( b , t , e ) = ( b n , t n , e n ) ,
and the corresponding transmit powers and CPU frequencies are recovered according to (60)–(66).
The joint helper-selection and resource-allocation procedure is summarized in Algorithm 1.
Proposition 2.
Algorithm 1 obtains a globally optimal solution to the joint helper-selection and resource-allocation problem.
Proof. 
For any fixed helper candidate U n , the transformed problem (P2) is equivalent to the corresponding continuous resource-allocation problem, with U n selected as the helper. By Proposition 1, problem (P2) is convex and can be solved globally. Let V n denote its optimal WSCR. Any feasible solution of the original joint problem must select exactly one helper U n , and its objective value cannot exceed V n for that candidate. Therefore, letting V denote the optimal value of the original joint problem, V max n N V n . Conversely, Algorithm 1 evaluates every feasible helper candidate and selects n according to (67). The globally optimal resource allocation associated with U n is feasible for the original joint problem and achieves max n N V n . Hence, V = max n N V n . Therefore, the resulting helper selection and resource allocation are globally optimal, which completes the proof.    □
Algorithm 1 Optimal Helper Selection and Resource Allocation
  •    Input: Channel gains, energy-harvesting parameters, computation parameters, priority weights, and the user set N .
  •   Output: Optimal helper index n , task-partitioning vector b , time allocation t , transmit-power allocation p , CPU-frequency allocation f , and maximum WSCR V best .
  1:
Set V best = and n = 0 .
  2:
for each n N  do
  3:
      Select U n as the candidate helper and reindex it as U 0 .
  4:
      Relabel the corresponding channel, energy-harvesting, computation, and priority parameters.
  5:
      Construct and solve ( P 2 ) using an interior-point method, and obtain b n , t n , e n , and V n .
  6:
      if  V n > V best  then
  7:
             Set V best = V n and n = n .
  8:
             Set b = b n , t = t n , and e = e n .
  9:
      end if
10:
end for
11:
Recover p according to (60)–(63).
12:
Recover f according to (64)–(66).
13:
return  n , b , t , p , f , and V best .
For each candidate helper, problem (P2) contains 10 K + 7 scalar optimization variables, and its number of constraints grows linearly with K = N 1 . Since Algorithm 1 solves one convex subproblem for each of the N candidate helpers, its computational burden increases with both the number and size of the subproblems. Algorithm 1 is designed to obtain the globally optimal solution and therefore primarily serves as an exact optimal-performance benchmark rather than a real-time optimization method. For practical online implementation, the candidate-helper set can be reduced using slowly varying information, such as large-scale channel gains, user locations, or available energy, while approximate resource-allocation methods can be adopted to further reduce the computational burden.

5. Simulation Results

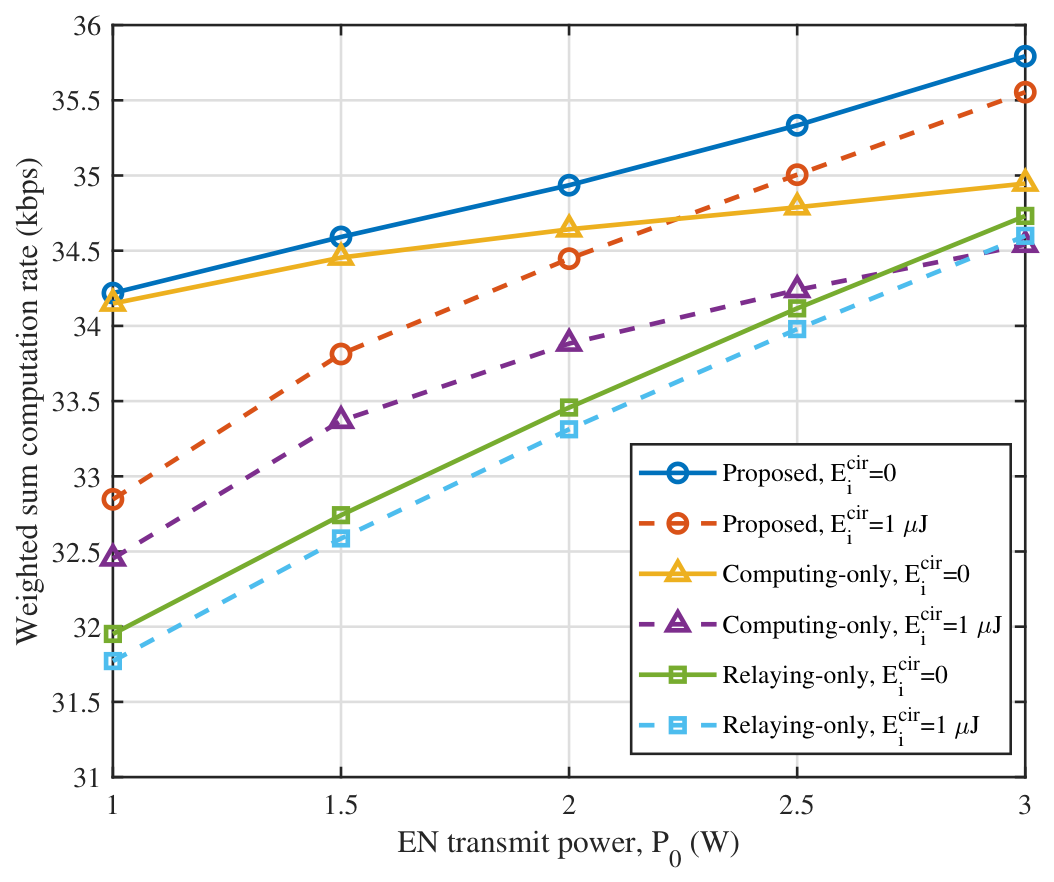
In this section, the numerical results are presented to evaluate the performance of the proposed joint computing-and-relaying scheme. The paper considers a wireless-powered MEC system consisting of one EN, one ES, and N = 6 users. The EN and the ES are located at ( 0 , 0 ) and ( 14 , 0 ) , respectively, while the users are randomly deployed within a circular region centered at ( 4 , 0 ) with a radius of 2 m and a minimum inter-user distance of 0.5 m. The frame duration is normalized to T = 1 s. The channel power gain of a link with distance d is modeled as h = G A c 4 π d f c α , where f c = 915 MHz, α = 2.5 , G A = 2 , and c = 3 × 10 8 m/s. Unless otherwise specified, the EN transmit power is P 0 = 3 W, the system bandwidth is B = 100 kHz, the receiver noise power is N 0 = 10 10 W, the implementation-loss factor is Γ = 1 , the energy-harvesting efficiency is η i = 0.7 , and the baseline circuit-energy consumption is E i cir = 0 for all users, while E i cir = 1 μ J per user per frame is separately evaluated in Figure 2.
The computation parameters are set to κ i = 10 26 , ϕ i = 100 cycles/bit, and f i max = 3 MHz, while the output-to-input data ratio is ν i = 0.5 . The user weights are set to w = [ 0.30 , 0.20 , 0.15 , 0.15 , 0.10 , 0.10 ] T , representing heterogeneous computation priorities. These weights remain associated with the original user identities when different helper candidates are evaluated. Each data point is averaged over 100 independent user deployments, and all the compared schemes use the same network realizations under each parameter setting.
The proposed scheme is compared with computing-only cooperation, relaying-only cooperation, and dedicated-helper cooperation. Under computing-only cooperation, the helper processes the tasks uploaded by the task users but does not forward them to the ES; i.e., b k , E = 0 for all k K . Under relaying-only cooperation, the helper forwards the uploaded tasks to the ES without processing them; i.e., b k , 0 = 0 for all k K . Under dedicated-helper cooperation, inspired by [17], the helper is predetermined, while both cooperative computing and relaying are retained. Local computing remains available to every user in all the benchmarks, and the helper can process its own task locally or offload it to the ES. Except for the dedicated-helper benchmark, helper selection and all the remaining resource-allocation variables are jointly optimized.
Before presenting the subsequent parametric studies, Figure 2 evaluates the impact of practical circuit-energy consumption. The proposed, computing-only, and relaying-only schemes are compared under E i cir = 0 and E i cir = 1 μ J per user per frame. Introducing nonzero circuit-energy consumption reduces the achievable WSCR of all three schemes, particularly at relatively low EN transmit power, where the fixed circuit expenditure accounts for a larger fraction of the harvested-energy budget. As P 0 increases, this relative impact gradually decreases. More importantly, the proposed joint cooperation scheme consistently achieves the highest WSCR over the entire considered range, confirming that the main comparative conclusion remains unchanged when practical circuit-energy consumption is taken into account.
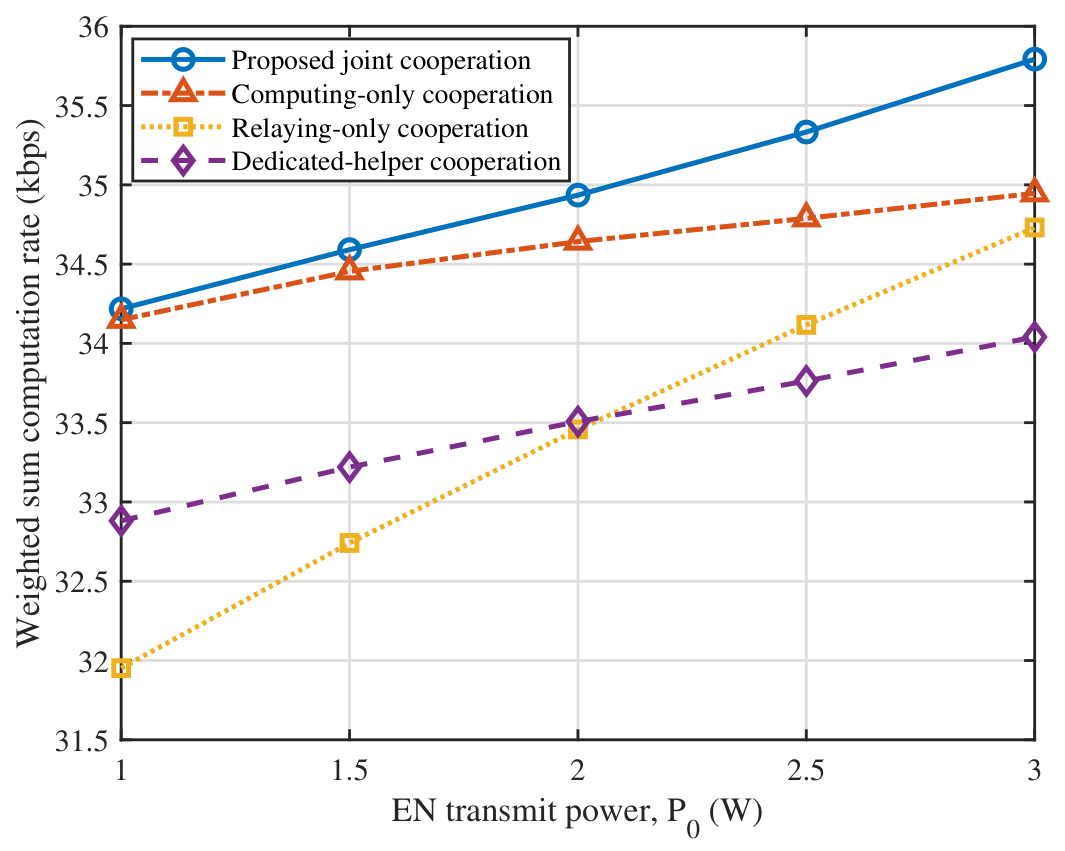
Figure 3 further examines the impact of the EN transmit power P 0 on the WSCR under the baseline circuit-energy setting. A larger P 0 increases the harvested-energy budgets of both the task users and the selected helper, thereby supporting more local computing, task uploading, helper computing, task forwarding, and result delivery. Relaying-only cooperation exhibits the strongest sensitivity to P 0 because each task bit processed at the ES consumes energy for both user-to-helper uploading and helper-to-ES forwarding. It therefore performs poorly under a tight energy budget but improves rapidly when more wireless energy becomes available. Computing-only cooperation increases more moderately because the number of task bits processed at the helper is additionally limited by its CPU capability. Dedicated-helper cooperation also improves with P 0 but remains constrained by the predetermined helper; notably, relaying-only cooperation overtakes it as the available energy increases. The proposed scheme achieves the highest WSCR throughout the considered range. As P 0 increases, it assigns more uploaded task bits to ES processing when helper computing becomes CPU-limited while retaining helper computing for task portions whose forwarding cost is relatively high. Consequently, its advantage over computing-only cooperation becomes more pronounced at higher EN transmit powers. Its consistent gain over dedicated-helper cooperation further confirms the benefit of adaptive helper selection.
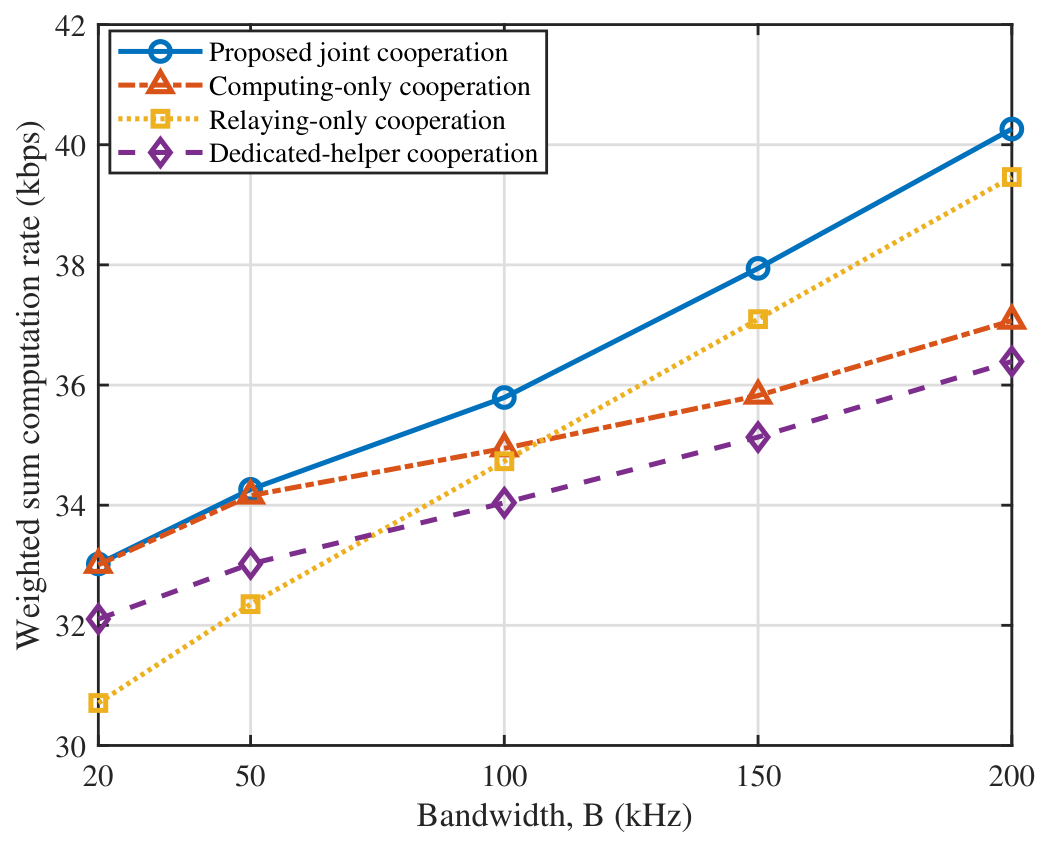
Communication bandwidth directly affects the time required for task uploading, forwarding, and result delivery. Figure 4 compares the four schemes as the system bandwidth B varies. Under a narrow bandwidth, computing-only cooperation nearly matches the proposed scheme, whereas relaying-only cooperation incurs a clear performance loss. This is because ES processing introduces an additional helper-to-ES transmission stage, while both cooperation modes require user-to-helper task uploading and helper-to-user result delivery. When B is small, these communication operations occupy a substantial fraction of the frame. The close performance of the proposed and computing-only schemes therefore indicates that helper computing is the dominant cooperative mode under a narrow bandwidth. As B increases, the durations required for task uploading, forwarding, and result delivery are reduced. Relaying-only cooperation consequently improves faster than computing-only cooperation and overtakes it between 100 and 150 kHz. It also overtakes dedicated-helper cooperation as the bandwidth increases, indicating that a predetermined helper limits the benefit of joint cooperation. The proposed scheme remains superior because it adaptively partitions the uploaded tasks between helper computing and ES processing instead of relying exclusively on either mode. Its additional gain over dedicated-helper cooperation further demonstrates the benefit of adaptive helper selection. The result demonstrates a transition from computing-dominant cooperation at low bandwidth to relaying-dominant cooperation at high bandwidth.
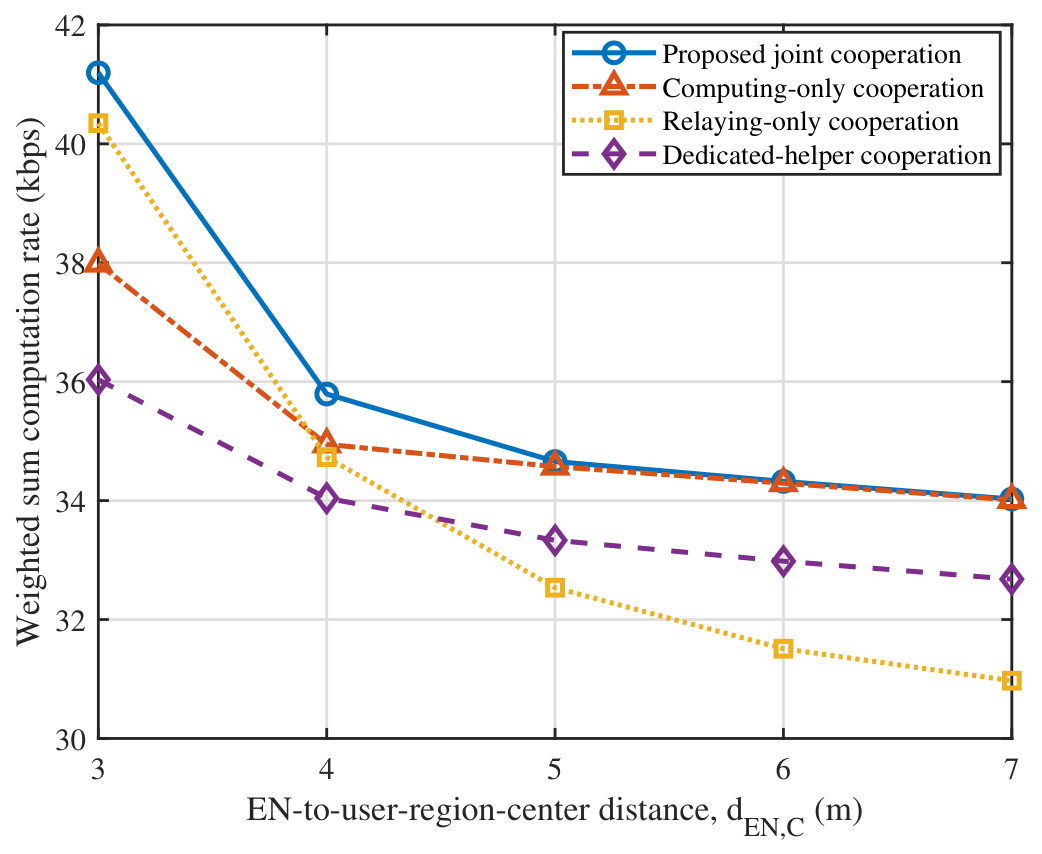
Figure 5 examines the effect of the distance d EN , C between the EN and the center of the user region. In this experiment, the user region and the ES remain fixed. Therefore, increasing d EN , C weakens only the wireless-energy-transfer links without changing the user-to-helper or helper-to-ES information links. The resulting reduction in harvested energy lowers the feasible CPU frequencies and transmission energies of all users. Relaying-only cooperation deteriorates most rapidly because the helper must allocate part of its limited harvested energy to the additional forwarding stage in addition to processing its own task and delivering computation results. When the EN is close to the user region, this forwarding cost can be supported, and relaying-only cooperation outperforms computing-only cooperation. Their ordering reverses as d EN , C increases and the energy budget becomes tighter. Dedicated-helper cooperation degrades more slowly than relaying-only cooperation and eventually outperforms it since joint computing and relaying allow the fixed helper to reduce its reliance on energy-intensive forwarding. Meanwhile, the proposed curve gradually approaches the computing-only curve, indicating that the optimizer reduces the ES-processed task portions when the harvested energy can no longer justify the additional forwarding expenditure. The proposed scheme therefore avoids using an energy-intensive processing route under unfavorable WPT conditions while retaining an advantage over dedicated-helper cooperation through adaptive helper selection.
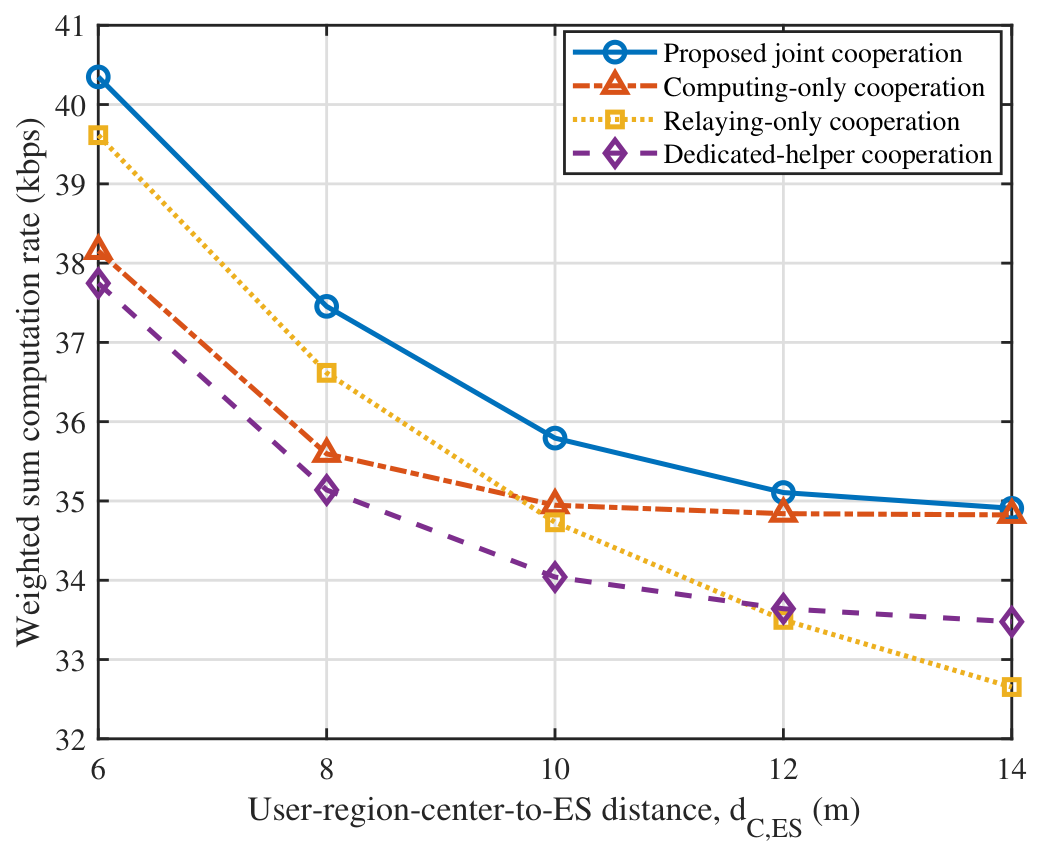
To isolate the helper-to-ES communication bottleneck, d C , ES is varied while the EN and the user deployment region remain unchanged, as reported in Figure 6. Hence, the harvested-energy levels and user-to-helper channels remain statistically unchanged, whereas the helper-to-ES link weakens as d C , ES increases. Relaying-only cooperation is particularly sensitive to this change because every task bit assigned to ES processing must pass through the degraded helper-to-ES link. The helper must therefore allocate more forwarding time or transmission energy to support the same number of task bits, reducing the resources available for other operations. Computing-only cooperation is much less sensitive because its uploaded task portions are processed at the helper and do not depend on the helper-to-ES link. Relaying-only cooperation performs better when the ES is sufficiently close but falls below computing-only cooperation between 8 and 10 m. Dedicated-helper cooperation degrades more slowly than relaying-only cooperation and overtakes it between 10 and 12 m by shifting more workload toward helper computing as the helper-to-ES link deteriorates. As the helper-to-ES link degrades, the proposed scheme increasingly benefits from helper computing, which explains why its performance approaches that of computing-only cooperation at large d C , ES . Its consistently higher WSCR than dedicated-helper cooperation also confirms the benefit of adaptive helper selection.
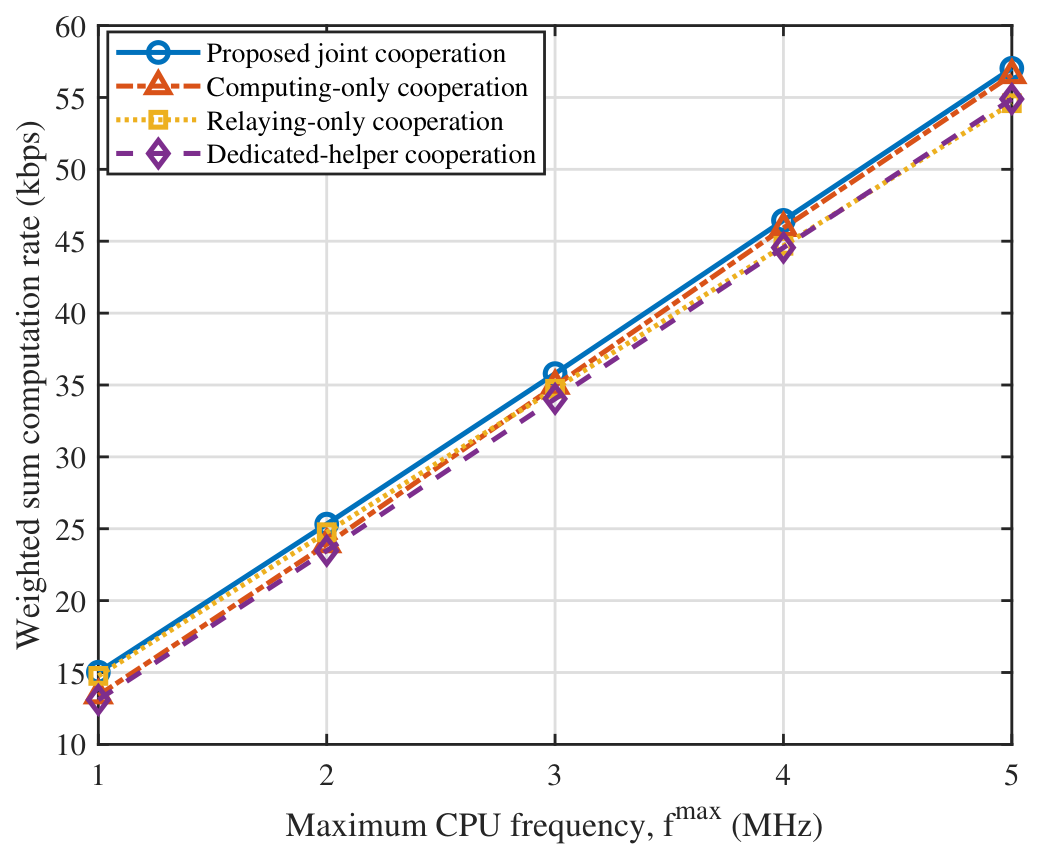
The role of computation capability is investigated next by varying the common maximum CPU frequency f max . The results are reported in Figure 7. Increasing f max enlarges the number of CPU cycles available to all the users within one frame, thereby improving both local computing and helper computing. Over the considered range, the WSCR curves increase almost linearly because a larger CPU-frequency limit enables more local computing and helper computing. More importantly, computing-only and relaying-only cooperation exhibit a performance crossover between 1 and 2 MHz. At low CPU frequencies, the helper cannot efficiently process a large number of uploaded task bits, making ES processing more advantageous. As f max increases, the helper can process more task bits during the parallel cooperation stage and avoid the time and energy required for helper-to-ES forwarding. Computing-only cooperation therefore overtakes relaying-only cooperation. Dedicated-helper cooperation also improves substantially with f max but remains inferior to the proposed scheme because the helper cannot adapt to the network realization. The proposed scheme adapts its task partition accordingly: it relies more on ES processing when CPU resources are scarce and shifts more workload to the helper as the available computing capability increases. The relatively small performance gaps at high f max also arise because all users receive the same CPU-frequency improvement, causing local computing to contribute an increasingly large common portion of the total WSCR.
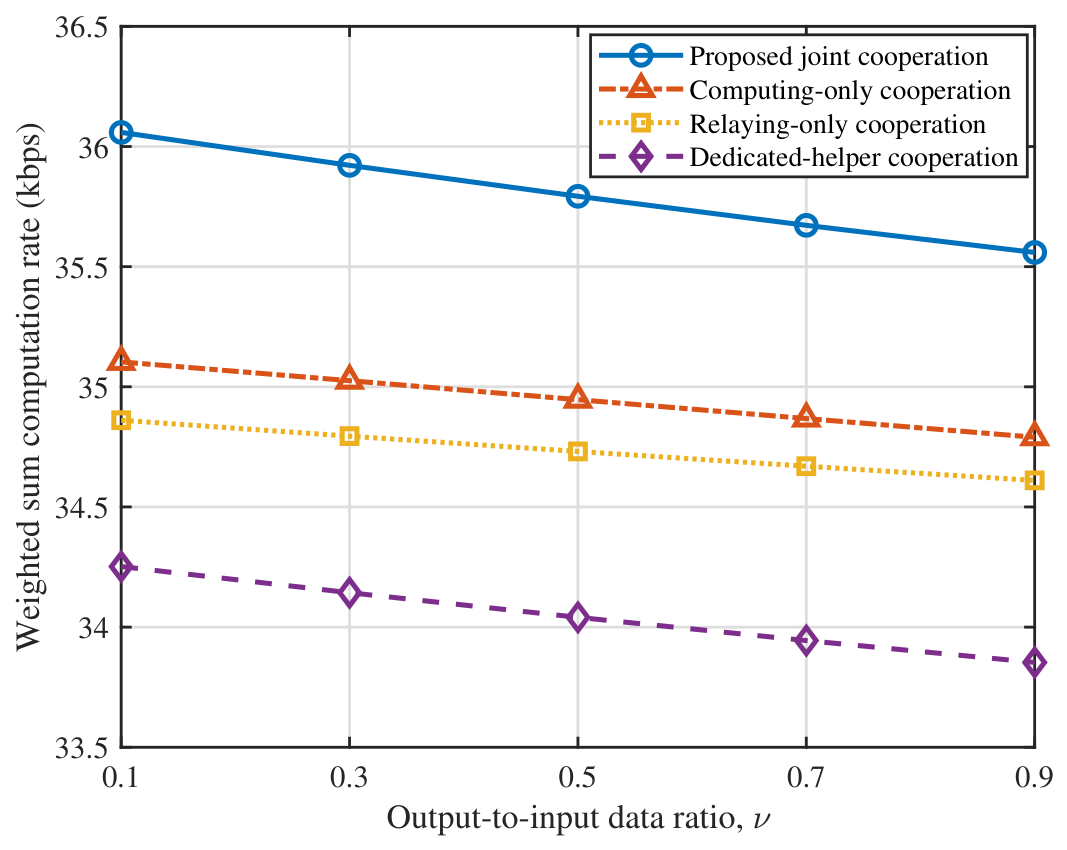
Figure 8 evaluates the effect of the output-to-input data ratio ν . A larger ν increases the amount of result data that must be delivered to each task user for every task bit processed at the helper or the ES. Consequently, result delivery consumes more frame time and helper transmission energy, and the WSCR decreases for all four schemes. The degradation remains moderate because locally computed task bits do not require wireless result delivery. As ν increases, each scheme can reduce the nonlocally processed task portion and allocate more workload to local computing, thereby partially compensating for the increased result-delivery overhead. The proposed scheme experiences a slightly larger absolute reduction because it processes more task bits through the helper and the ES when ν is small. A larger portion of its computation gain is therefore affected by the result-delivery constraint. Nevertheless, the proposed scheme remains superior by jointly adjusting local computing, helper computing, and ES processing according to the output-data load. Dedicated-helper cooperation exhibits a similar decreasing trend but remains inferior because the helper cannot adapt to the network realization.
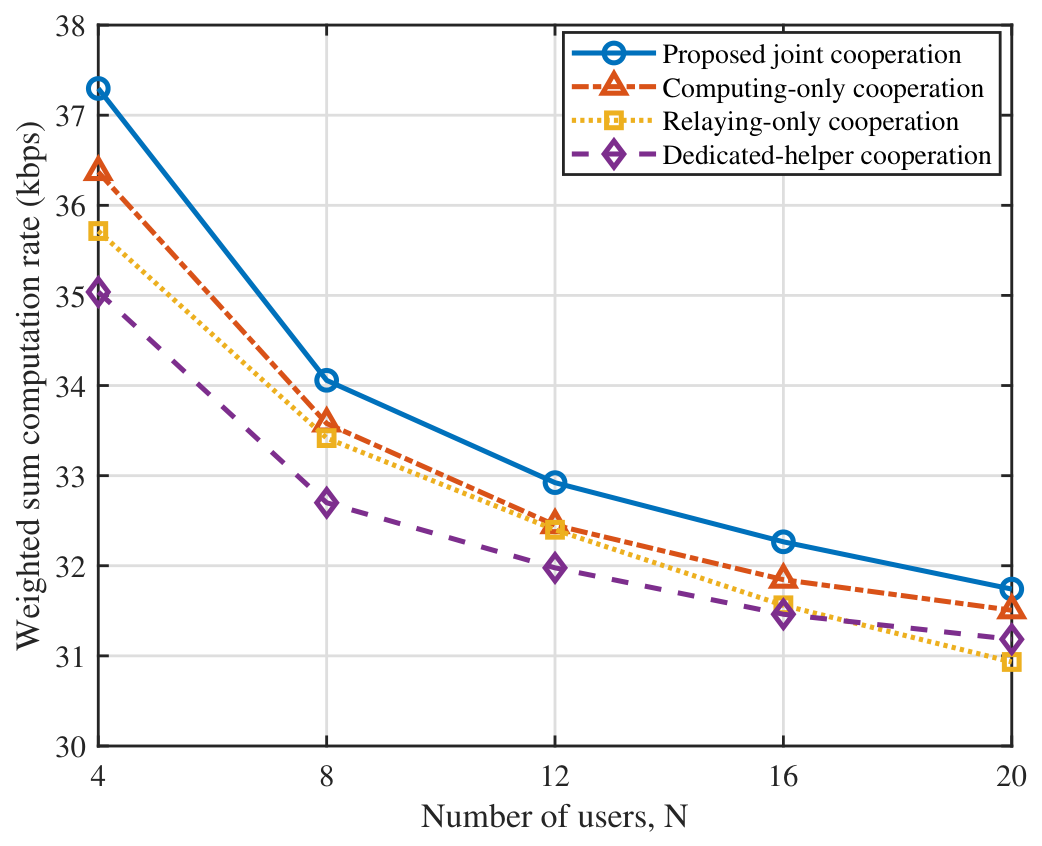
Figure 9 evaluates the scalability of the four schemes as the number of users increases from 4 to 20. The WSCR of all the schemes decreases with N since more task users share the limited frame duration, harvested energy, communication resources, and helper computing capability. The proposed joint cooperation scheme consistently achieves the highest WSCR over the entire range, showing that its performance advantage is maintained as the network size increases. Among the benchmark schemes, computing-only cooperation generally performs better, while the relative performance of relaying-only and dedicated-helper cooperation varies with N because of their different communication and computation limitations.
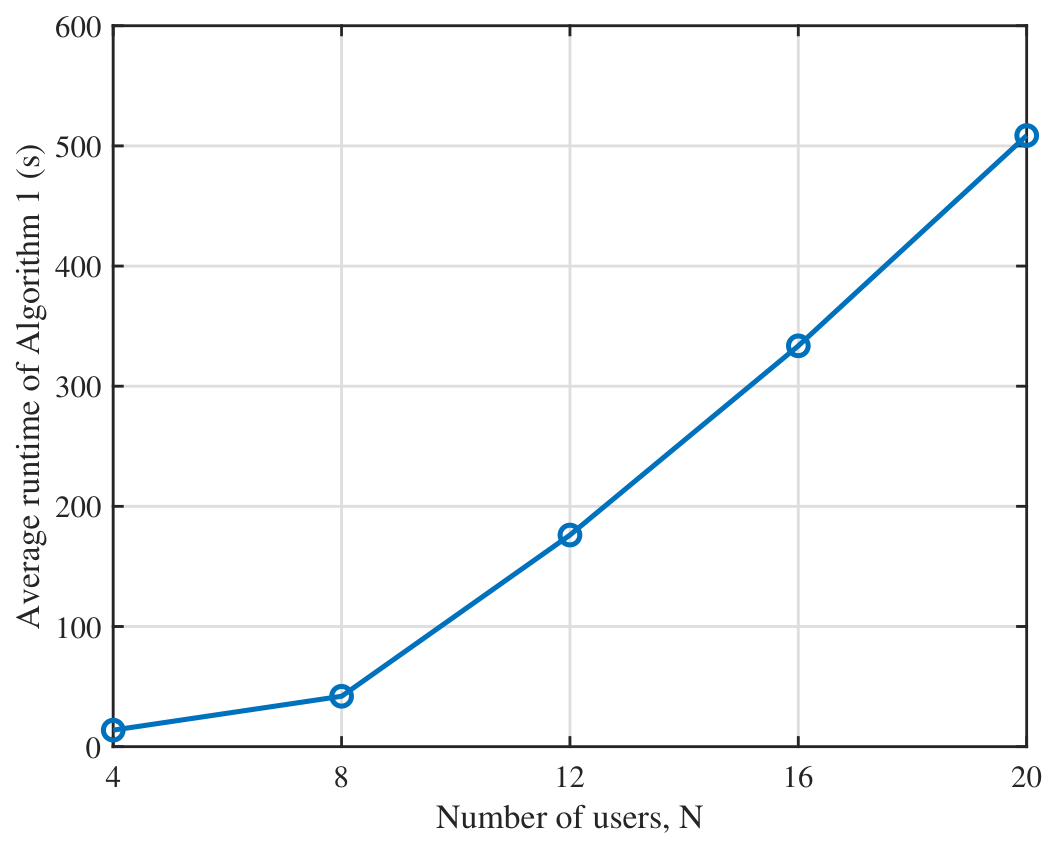
Figure 10 evaluates the computational runtime of Algorithm 1. For each network realization, the reported runtime represents one complete execution of Algorithm 1, including all the candidate-helper subproblems and the final helper selection. Under the MATLAB R2024b with CVX 2.2 implementation used in the simulations, the average runtime increases from approximately 13 s at N = 4 to approximately 510 s at N = 20 . The absolute runtime is implementation-dependent and is reported here to illustrate the computational growth of the exact method. This computational runtime is distinct from the transmission-frame duration T = 1 s, which characterizes the communication and computation scheduling interval rather than the solver execution time. Nevertheless, if helper selection and resource allocation are recomputed online for every frame, the measured optimization latency substantially exceeds the corresponding one-second decision interval and therefore prevents direct real-time implementation of the current exact MATLAB/CVX solution. Therefore, Algorithm 1 primarily provides an exact optimal-performance benchmark, while real-time implementation requires lower-complexity helper screening or approximate resource-allocation methods.
Overall, neither computing-only cooperation nor relaying-only cooperation is uniformly preferable. Their relative performance depends on the harvested-energy budget, available bandwidth, helper-to-ES channel quality, and CPU capability. By jointly optimizing helper selection, task partitioning, and resource allocation, the proposed scheme adapts the cooperation mode to the prevailing system bottleneck and consistently achieves the highest WSCR.


6. Conclusions

This paper investigated joint computing and relaying for multiuser task offloading in a wireless-powered MEC system. One energy-harvesting user was selected as the helper to assist the remaining task users while processing its own task. The uploaded tasks were flexibly partitioned between cooperative computing at the helper and remote processing at the ES, with helper computing and task forwarding performed in parallel. To fully exploit this cooperation architecture, the weighted sum computation rate was maximized by jointly optimizing helper selection, task partitioning, time allocation, transmission-energy allocation, and CPU-resource allocation. For each candidate helper, the continuous resource-allocation problem was transformed into an equivalent convex problem by introducing transmission-energy variables and exploiting the perspective properties of the communication-rate and computation-energy functions. The globally optimal solution was then obtained by evaluating all the feasible helper candidates. The simulation results verify that the proposed joint computing-and-relaying scheme consistently outperforms computing-only, relaying-only, and dedicated-helper cooperation. The gain arises from its ability to adaptively balance helper computing and ES processing while selecting the helper according to the network conditions. These results demonstrate the effectiveness of jointly coordinating helper selection, task partitioning, and resource allocation in multiuser wireless-powered MEC systems.

Author Contributions

Conceptualization, Y.Z.; methodology, Y.Z. and F.T.; software, Y.Z. and F.T.; validation, Y.Z. and D.L.; formal analysis, Y.Z. and Y.W.; investigation, D.L. and Y.W.; resources, Y.W.; data curation, F.T. and Y.W.; writing—original draft preparation, Y.Z.; writing—review and editing, Y.Z. and D.L.; visualization, D.L. and Y.W.; supervision, Y.Z. and D.L.; project administration, Y.W.; funding acquisition, D.L. and Y.W. All authors have read and agreed to the published version of the manuscript.

Funding

This research was funded by the Scientific Research Project of Shenzhen Polytechnic University under Grant Nos. 6024310011K, 6026310056K, and 1055-6024210101K1, in part by Research Projects of Shenzhen Science and Technology Program under Grant RCBS20231211090733053, the Department of Education of Guangdong Province under Grant 2024KQNCX035, and National Natural Science Foundation of China under Grant No. 62501411.

Institutional Review Board Statement

Not applicable.

Informed Consent Statement

Not applicable.

Data Availability Statement

The data will be made available on request.

Conflicts of Interest

The authors declare no conflicts of interest.

References

  1. Mao, Y.; You, C.; Zhang, J.; Huang, K.; Letaief, K.B. A survey on mobile edge computing: The communication perspective. IEEE Commun. Surv. Tutor. 2017, 19, 2322–2358. [Google Scholar] [CrossRef] [Scilit]
  2. Bi, S.; Zhang, Y.J. Computation rate maximization for wireless powered mobile-edge computing with binary computation offloading. IEEE Trans. Wirel. Commun. 2018, 17, 4177–4190. [Google Scholar] [CrossRef] [Scilit]
  3. Wang, F.; Xu, J.; Wang, X.; Cui, S. Joint offloading and computing optimization in wireless powered mobile-edge computing systems. IEEE Trans. Wirel. Commun. 2018, 17, 1784–1797. [Google Scholar] [CrossRef] [Scilit]
  4. Li, X.; Bi, S.; Zheng, Y.; Wang, H. Energy-efficient online data sensing and processing in wireless powered edge computing systems. IEEE Trans. Commun. 2022, 70, 5612–5628. [Google Scholar] [CrossRef] [Scilit]
  5. Jiao, X.; Wang, Y.; Guo, S.; Zhang, H.; Dai, H.; Li, M.; Zhou, P. Deep reinforcement learning empowers wireless powered mobile edge computing: Towards energy-aware online offloading. IEEE Trans. Commun. 2023, 71, 5214–5227. [Google Scholar] [CrossRef] [Scilit]
  6. Chen, X.; Dai, W.; Ni, W.; Wang, X.; Zhang, S.; Xu, S.; Sun, Y. Augmented deep reinforcement learning for online energy minimization of wireless powered mobile edge computing. IEEE Trans. Commun. 2023, 71, 2698–2710. [Google Scholar] [CrossRef] [Scilit]
  7. Qin, X.; Song, Z.; Hou, T.; Yu, W.; Wang, J.; Sun, X. Joint resource allocation and configuration design for STAR-RIS-enhanced wireless-powered MEC. IEEE Trans. Commun. 2023, 71, 2381–2395. [Google Scholar] [CrossRef] [Scilit]
  8. Jiao, X.; Chen, Y.; Chen, Y.; Wu, X.; Guo, S.; Zhu, W.; Lou, W. SIC-enabled intelligent online task concurrent offloading for wireless powered MEC. IEEE Internet Things J. 2024, 11, 22684–22696. [Google Scholar] [CrossRef] [Scilit]
  9. Chen, W.; Wei, X.; Chi, K.; Yu, K.; Tolba, A.; Mumtaz, S.; Guizani, M. Computation time minimized offloading in NOMA-enabled wireless powered mobile edge computing. IEEE Trans. Commun. 2024, 72, 7182–7197. [Google Scholar] [CrossRef] [Scilit]
  10. Jiao, X.; Chen, Y.; Wu, X.; Li, R.; Guo, S.; Ma, Y.; Cao, J. Intelligent compression offloading and adaptive resource allocation for wireless powered MEC. IEEE Trans. Serv. Comput. 2025, 18, 3904–3917. [Google Scholar] [CrossRef] [Scilit]
  11. Wu, X.; He, Y.; Saleem, A. Computation rate maximization in multi-user cooperation-assisted wireless-powered mobile edge computing with OFDMA. China Commun. 2023, 20, 218–229. [Google Scholar] [CrossRef] [Scilit]
  12. Yang, L.; Jiang, H.; Shi, J.; Xue, X.; Ren, P.; Feng, Y.; Chen, J. Achieving cooperative mobile-edge computing using helper scheduling. IEEE Trans. Commun. 2023, 71, 3419–3436. [Google Scholar] [CrossRef] [Scilit]
  13. Ren, M.; Chen, J.; Yang, L.; Zhou, Y.; He, B.; Jiang, H. Energy-delay tradeoff in helper-assisted NOMA-MEC systems: A four-sided matching algorithm. IEEE Trans. Commun. 2024, 72, 2835–2850. [Google Scholar] [CrossRef] [Scilit]
  14. Gu, Y.; Zeng, D.; Guo, Y.; Xia, B.; Chen, Z.; Wang, J. A user-centric cooperative offloading scheme for stochastic MEC networks. IEEE Internet Things J. 2025, 12, 34582–34594. [Google Scholar] [CrossRef] [Scilit]
  15. Qin, X.; Yu, W.; Ni, Q.; Song, Z.; Hou, T.; Sun, X. Joint resource allocation and beamforming design for BD-RIS-assisted wireless-powered cooperative mobile edge computing. IEEE Commun. Lett. 2025, 29, 1042–1046. [Google Scholar] [CrossRef] [Scilit]
  16. Hu, X.; Wong, K.-K.; Yang, K. Wireless powered cooperation-assisted mobile edge computing. IEEE Trans. Wirel. Commun. 2018, 17, 2375–2388. [Google Scholar] [CrossRef] [Scilit]
  17. Cao, X.; Wang, F.; Xu, J.; Zhang, R.; Cui, S. Joint computation and communication cooperation for energy-efficient mobile edge computing. IEEE Internet Things J. 2019, 6, 4188–4200. [Google Scholar] [CrossRef] [Scilit]
  18. He, B.; Bi, S.; Xing, H.; Lin, X. Collaborative computation offloading in wireless powered mobile-edge computing systems. In Proceedings of the IEEE Global Communications Conference Workshops (GLOBECOM Workshops), Waikoloa, HI, USA, 9–13 December 2019; pp. 1–7. [Google Scholar]
  19. Ahmed, Z.; Lu, Y.; Nasir, M.; Iqbal, R. Digital Twin-Based Resilient Consensus Control of Unmanned Aerial Vehicles under Attack. IEEE Internet Things J. 2026. early access. [Google Scholar] [CrossRef] [Scilit]
  20. Gong, X.; Zhang, Z.; Shen, J. Data-driven leader-following consensus for nonlinear multi-agent systems against composite attacks: A twins layer approach. J. Frankl. Inst. 2024, 361, 107067. [Google Scholar] [CrossRef] [Scilit]
Figure 1. System model and transmission protocol of the proposed system.
Sensors 26 05568 g001
Figure 2. Weighted sum computation rate versus the EN transmit power under different circuit-energy settings.
Sensors 26 05568 g002
Figure 3. Weighted sum computation rate versus the EN transmit power P 0 .
Sensors 26 05568 g003
Figure 4. Weighted sum computation rate versus the system bandwidth B.
Sensors 26 05568 g004
Figure 5. Weighted sum computation rate versus the distance d EN , C between the EN and the center of the user region.
Sensors 26 05568 g005
Figure 6. Weighted sum computation rate versus the distance d C , ES between the center of the user region and the ES.
Sensors 26 05568 g006
Figure 7. Weighted sum computation rate versus the maximum CPU frequency f max .
Sensors 26 05568 g007
Figure 8. Weighted sum computation rate versus the output-to-input data ratio ν .
Sensors 26 05568 g008
Figure 9. Weighted sum computation rate versus the number of users N.
Sensors 26 05568 g009
Figure 10. Average runtime of Algorithm 1 versus the number of users N.
Sensors 26 05568 g010
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content.